Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
Cardiff 12-5-2017
Search
Daniel Lakens
May 12, 2017
Science
74
1
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
Cardiff 12-5-2017
Invited Colloquium on Designing Efficient and Informative Studies
Daniel Lakens
May 12, 2017
Other Decks in Science
See All in Science
[Webinaire presse] Sécheresse 2026 : quelles conséquences techniques en élevage de ruminants et quels leviers d'action ?
institutdelelevage
PRO
0
300
Note agro-climatique et prairies - Numéro 7
institutdelelevage
PRO
0
610
機械学習 - SVM
trycycle
PRO
2
1.3k
知能とはなにか -ヒトとAIのあいだ-
tagtag
PRO
0
230
機械学習 - K-means & 階層的クラスタリング
trycycle
PRO
0
2.3k
機械学習 - DBSCAN
trycycle
PRO
0
2.2k
プロジェクト「Azayaka」のSARの数式とジオメトリ
syuchimu
0
490
Cognitive Debt - What AI will do to us
martinlippert
1
120
AlgorithAlgorihms for Decision Making
mickey_kubo
0
170
Conwayの法則を"ちゃんと"使うために — 原典でConwayは何を言っていたのか
bonotake
10
7.5k
JSAI2026企画セッションKS-14 インタビュー集『⼈⼯知能と哲学と四つの問い』が提起する⼈⼯知能のこれからの課題 趣旨説明 / JSAI2026 Special Session: A Collection of Interviews, “Artificial Intelligence, Philosophy, and Four Questions”
ykiyota
0
470
Webinaire : Valorisez les résultats de vos projets européens avec EU-FarmBook
institutdelelevage
PRO
0
180
Featured
See All Featured
Between Models and Reality
mayunak
4
500
RailsConf & Balkan Ruby 2019: The Past, Present, and Future of Rails at GitHub
eileencodes
141
35k
AI Search: Where Are We & What Can We Do About It?
aleyda
0
8.1k
Navigating the Design Leadership Dip - Product Design Week Design Leaders+ Conference 2024
apolaine
2
480
30 Presentation Tips
portentint
PRO
1
430
10 Git Anti Patterns You Should be Aware of
lemiorhan
PRO
659
62k
Typedesign – Prime Four
hannesfritz
42
3.2k
Marketing Yourself as an Engineer | Alaka | Gurzu
gurzu
0
330
Building the Perfect Custom Keyboard
takai
2
910
Testing 201, or: Great Expectations
jmmastey
46
8.3k
Building an army of robots
kneath
307
47k
What the history of the web can teach us about the future of AI
inesmontani
PRO
2
740
Transcript
Designing Efficient and Informative Studies Daniel Lakens @Lakens Eindhoven University
of Technology
How do you determine the sample size for a new
study?
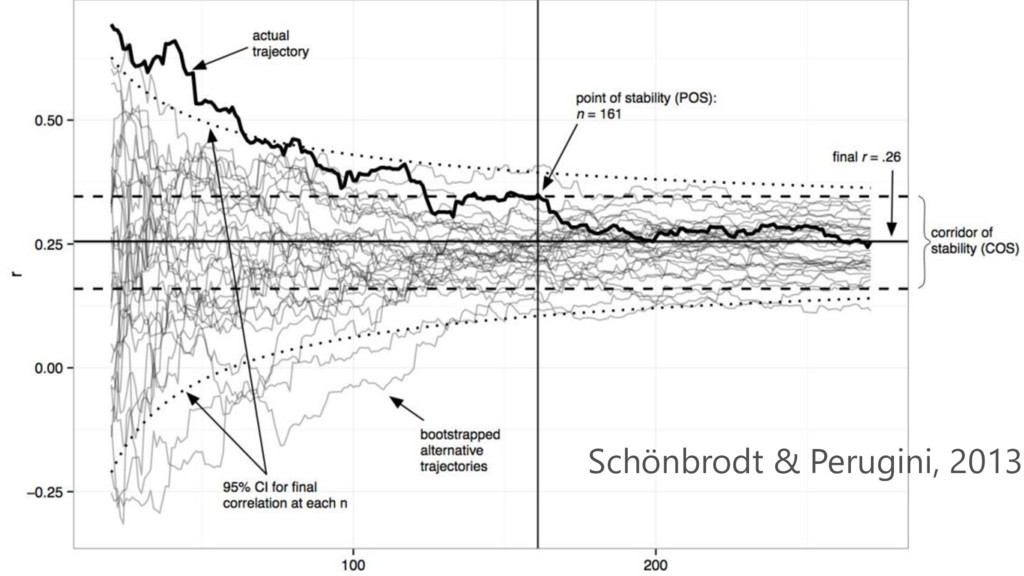
Small samples have large variation, more Type 2 errors, and
inaccurate estimates.
Schönbrodt & Perugini, 2013
None
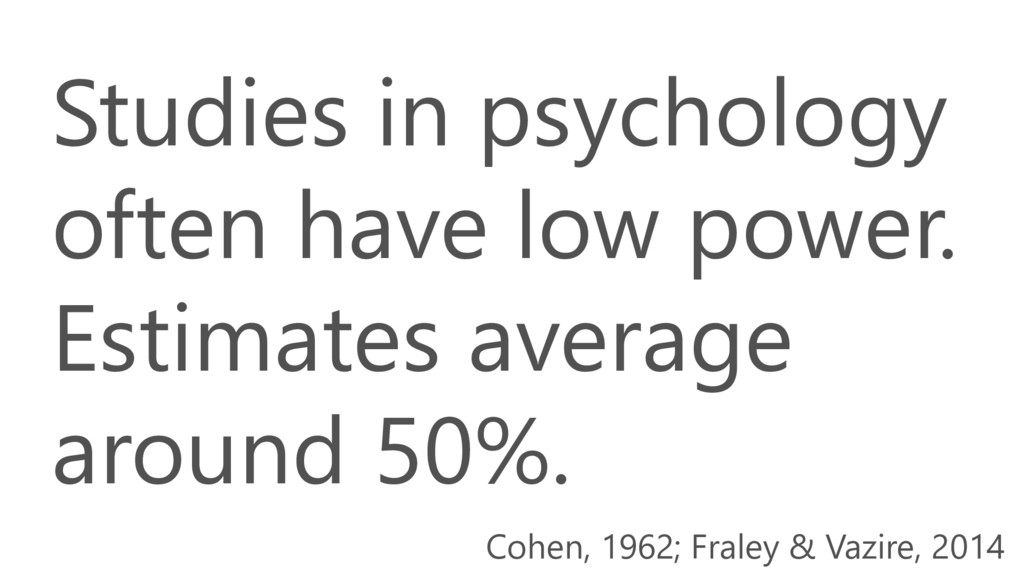
Studies in psychology often have low power. Estimates average around
50%. Cohen, 1962; Fraley & Vazire, 2014
One reason for low power is that people use heuristics
to plan their sample size.
You need to justify the sample size of a study.
What goal do you want to achieve?
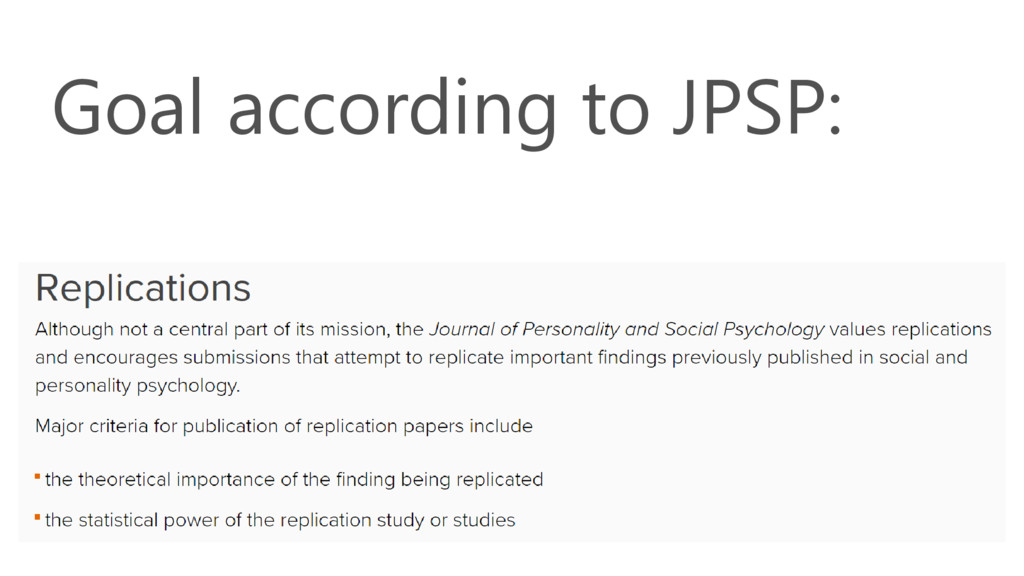
Goal according to JPSP:
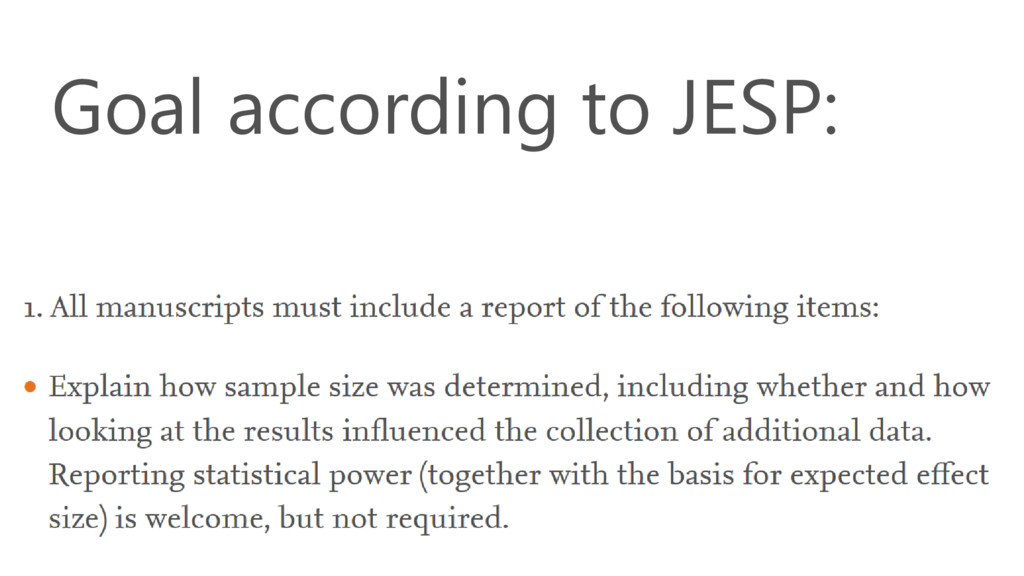
Goal according to JESP:
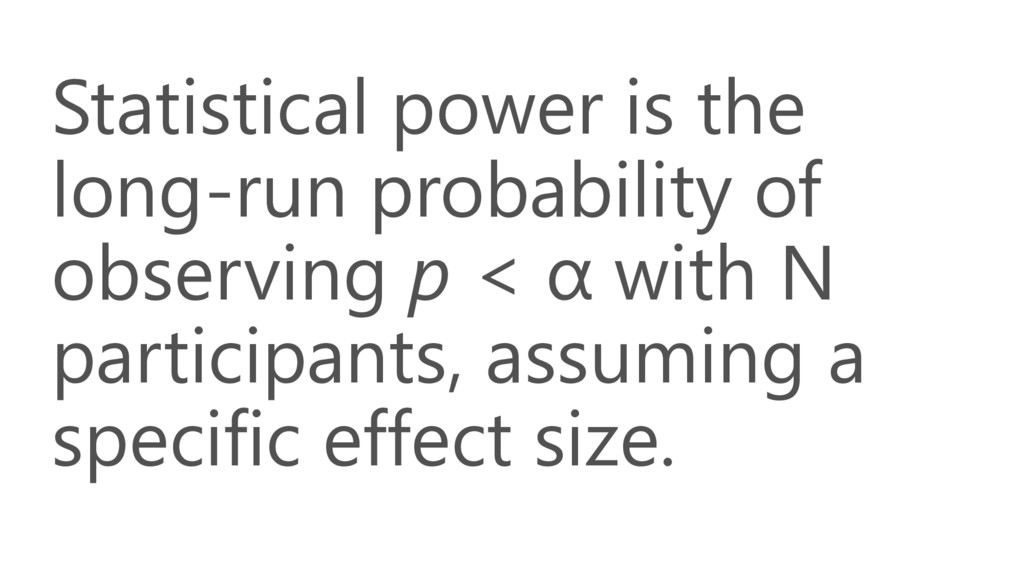
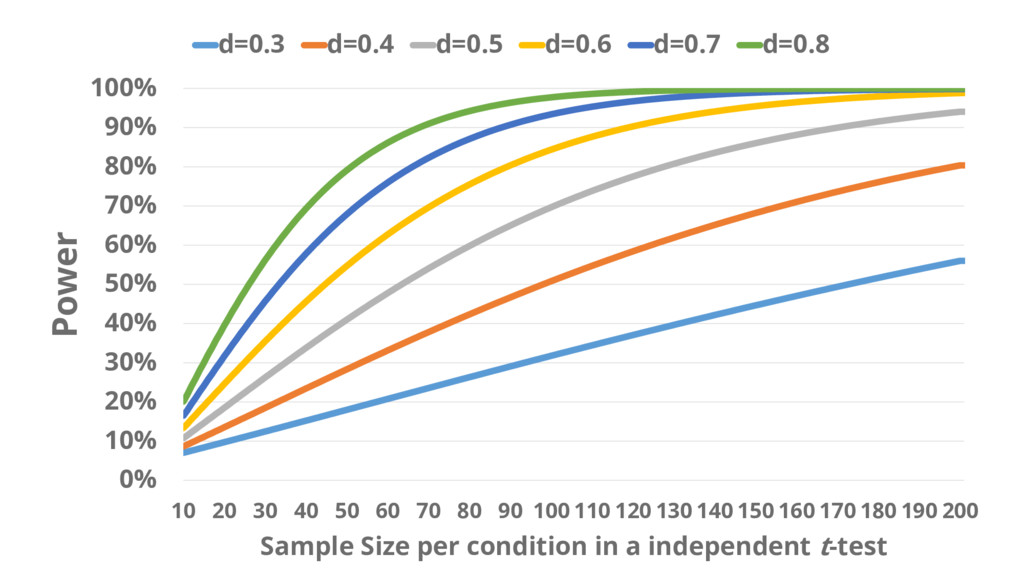
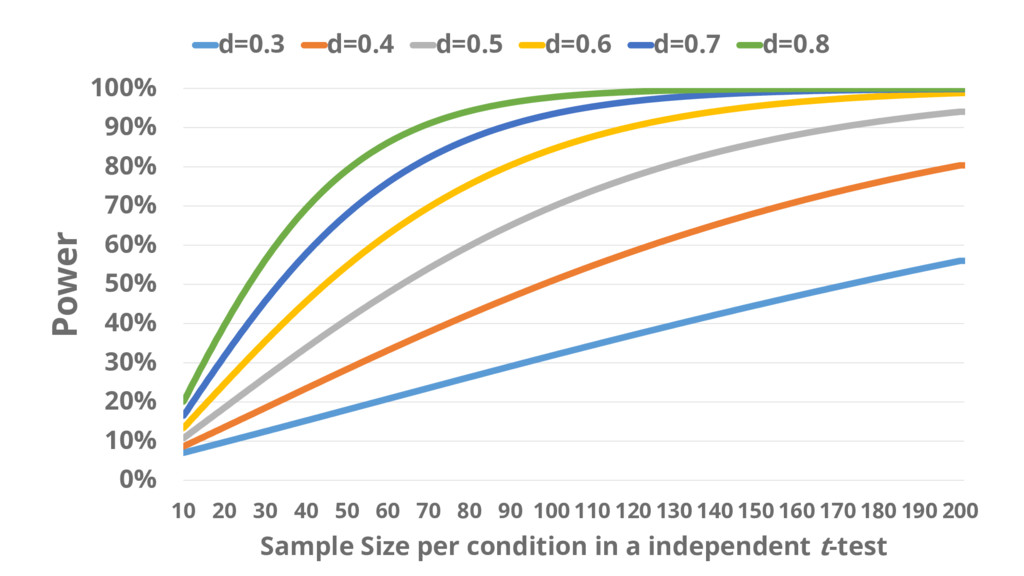
Statistical power is the long-run probability of observing p <
α with N participants, assuming a specific effect size.
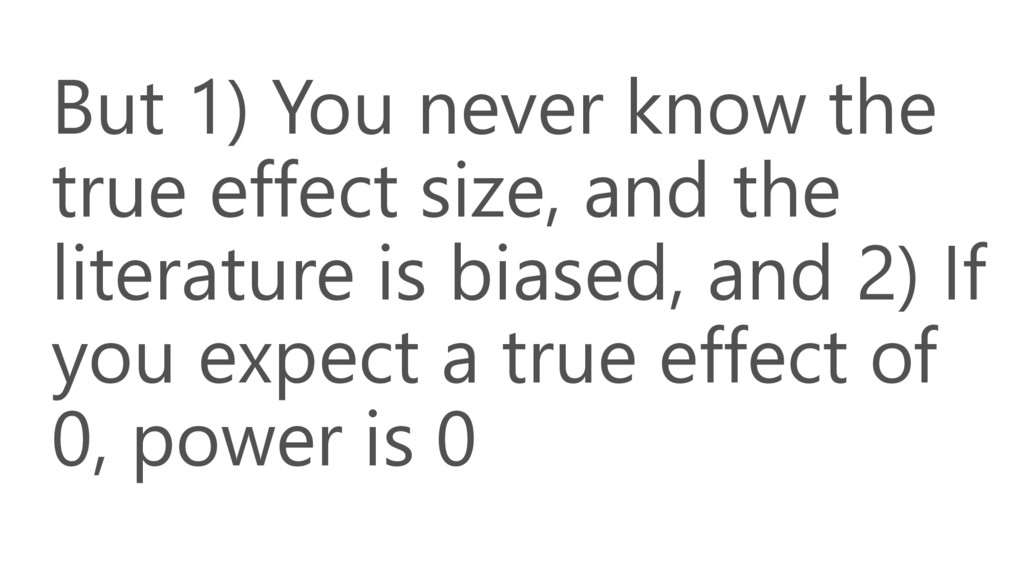
But 1) You never know the true effect size, and
the literature is biased, and 2) If you expect a true effect of 0, power is 0
0% 10% 20% 30% 40% 50% 60% 70% 80% 90%
100% 10 20 30 40 50 60 70 80 90 100 110 120 130 140 150 160 170 180 190 200 Power Sample Size per condition in a independent t-test d=0.3 d=0.4 d=0.5 d=0.6 d=0.7 d=0.8
My department requires sample size justification before funding a study.
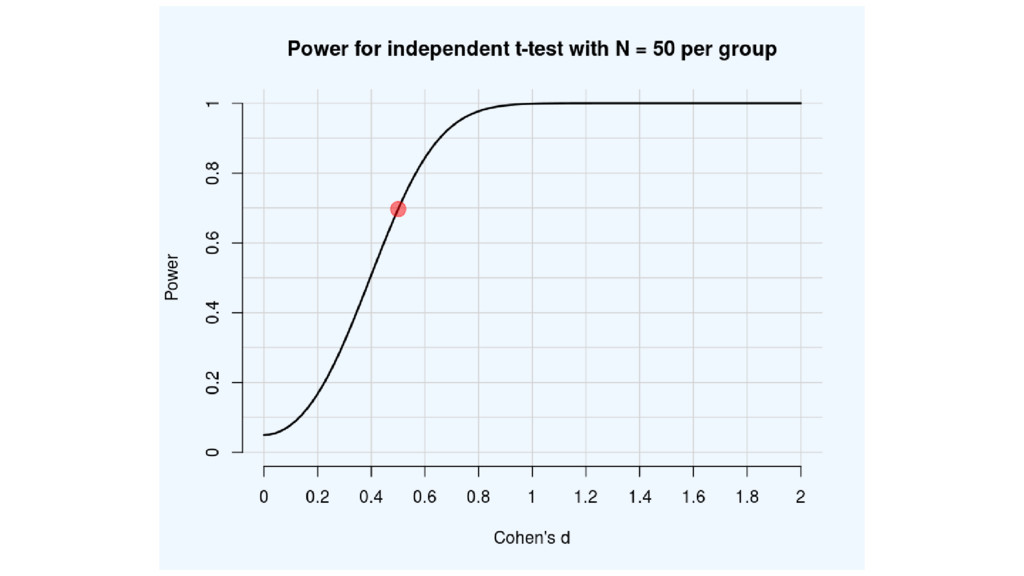
One justification the IRB accepts is 90% power.
What is ‘evidence’?
Evidence is always relative. You want a higher likelihood of
p<0.05 when H1 is true than when H0 is true.
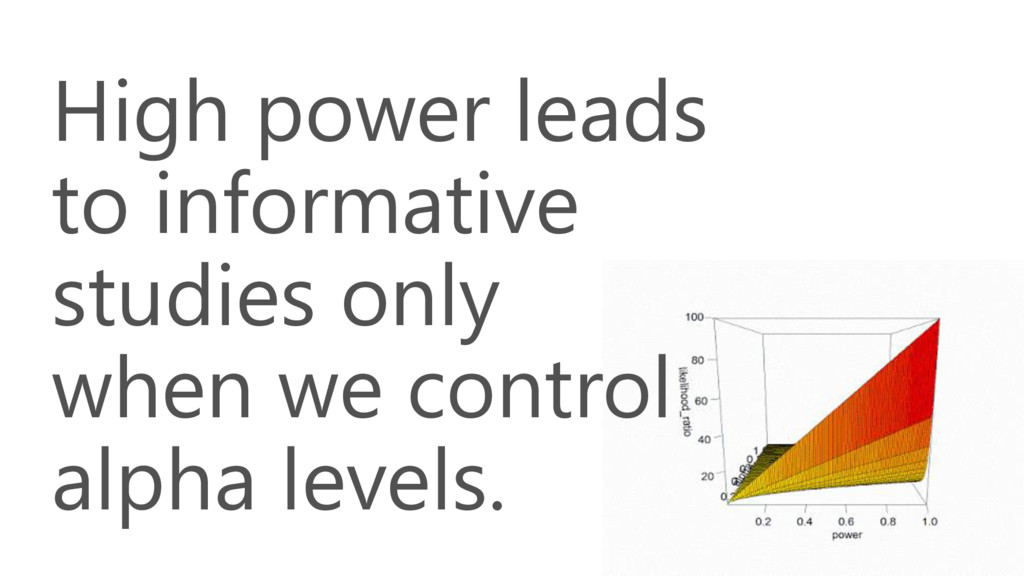
High power leads to informative studies only when we control
alpha levels.
What we have been doing wrong: Using previous studies as
an effect size estimate
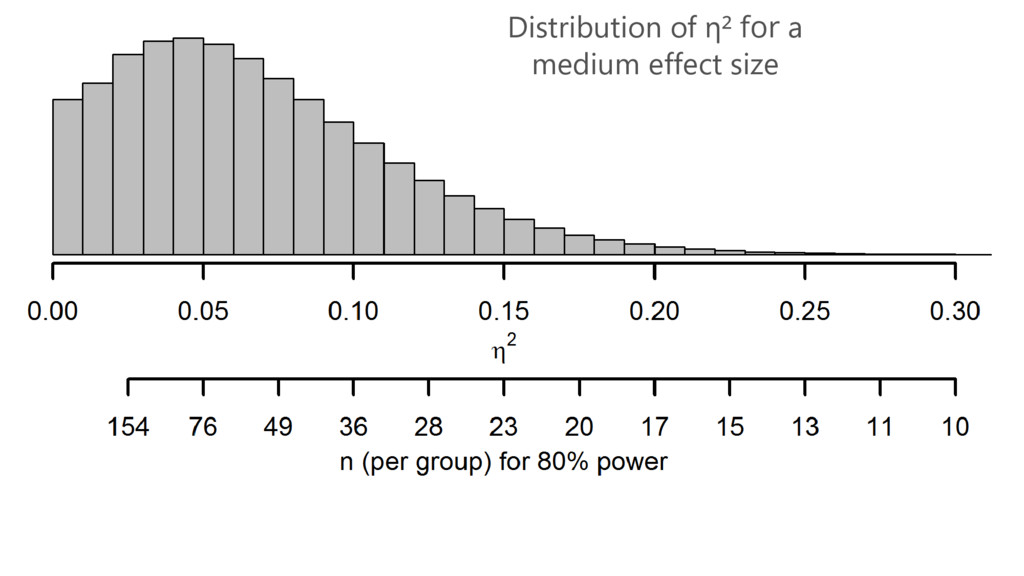
Distribution of η² for a medium effect size
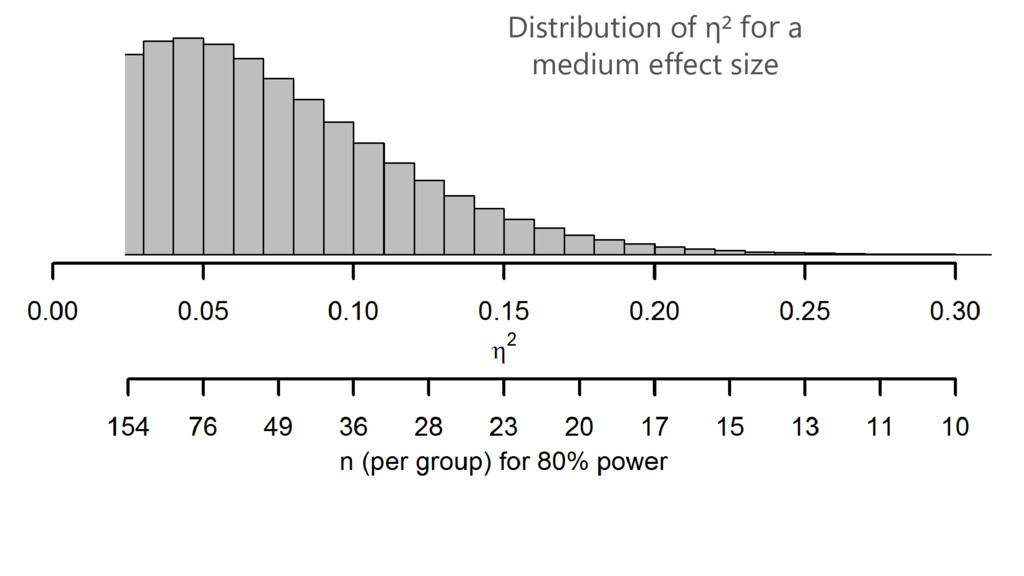
Distribution of η² for a medium effect size
A pilot study does not provide a meaningful effect size
estimate for planning subsequent studies. Leon, Davis, & Kraemer, 2011
Power analysis based on significant studies need to be based
on a truncated F distribution. Taylor & Muller, 1996
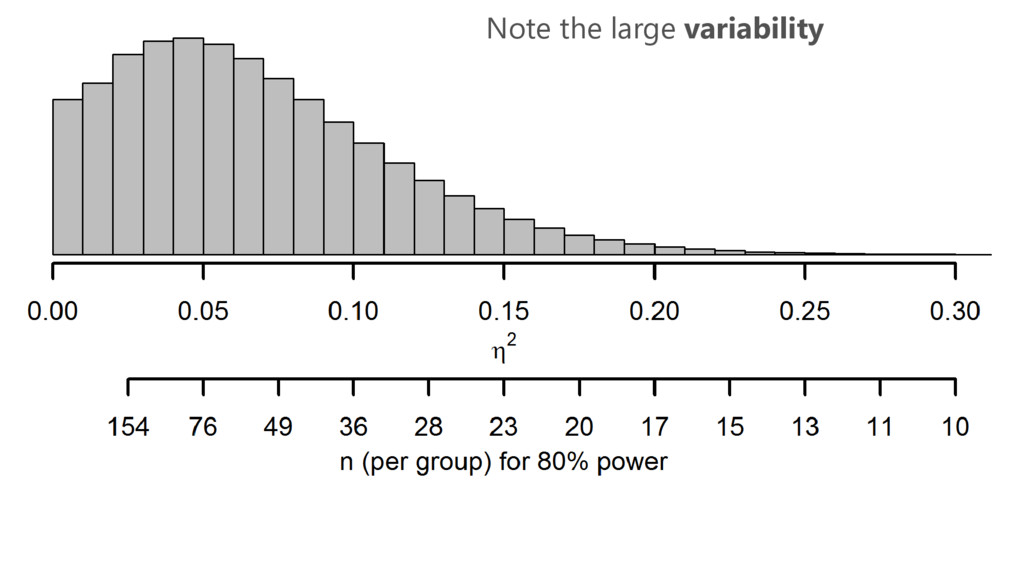
Note the large variability
You can also take into account variability (‘assurance’) – e.g.,
using safeguard power. Perugini, Gallucci, & Constantini, 2014
Effect sizes from the published literature are always smaller than
you expect, even when you take into account that effect sizes from the published literature are always smaller than you expect.
Plan for the change you would like to see in
the world. Ask yourself: What is your smallest effect size of interest?
Requires you to specify H1! That’s a good thing. What
does you theory predict, or what do you care about if H0 is false?
If we don’t, science becomes unfalsifiable. We can never ‘accept
the null’.
But ‘I’m not interested in the size of the effect
– the presence of any effect supports my theory!’ Really?
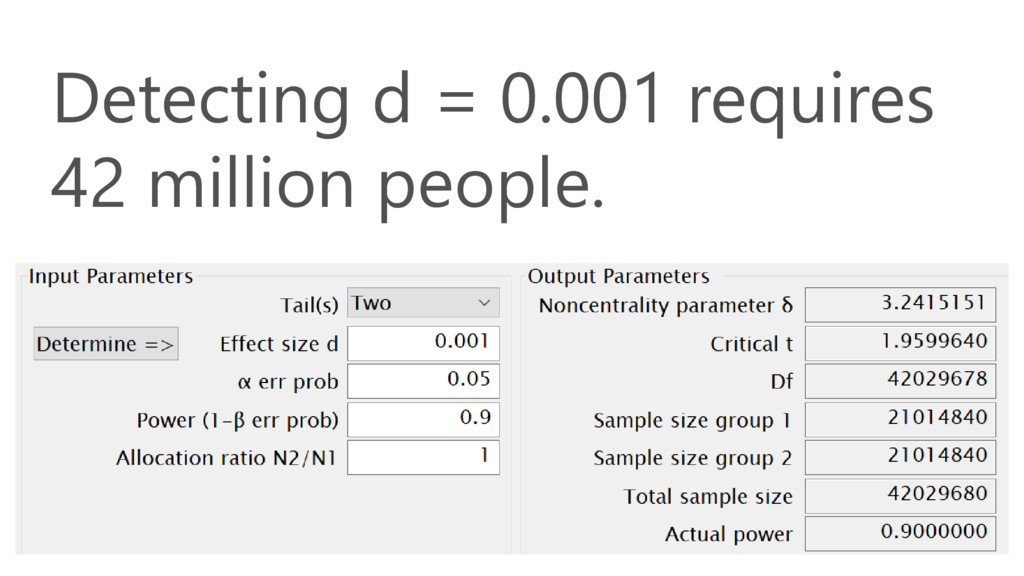
Detecting d = 0.001 requires 42 million people.
You make implicit choices about which effects are too small
to matter all the time.
None
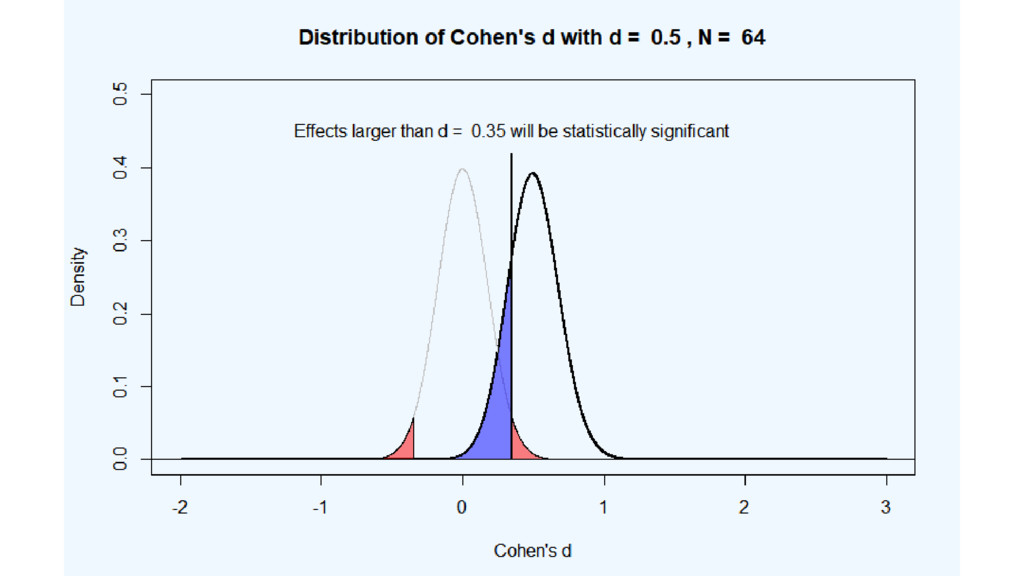
If you expect a ‘medium’ effect size and plan for
80% power, d<0.35 will never be significant.
If nothing else, the maximum sample you are willing to
collect determines your SESOI.
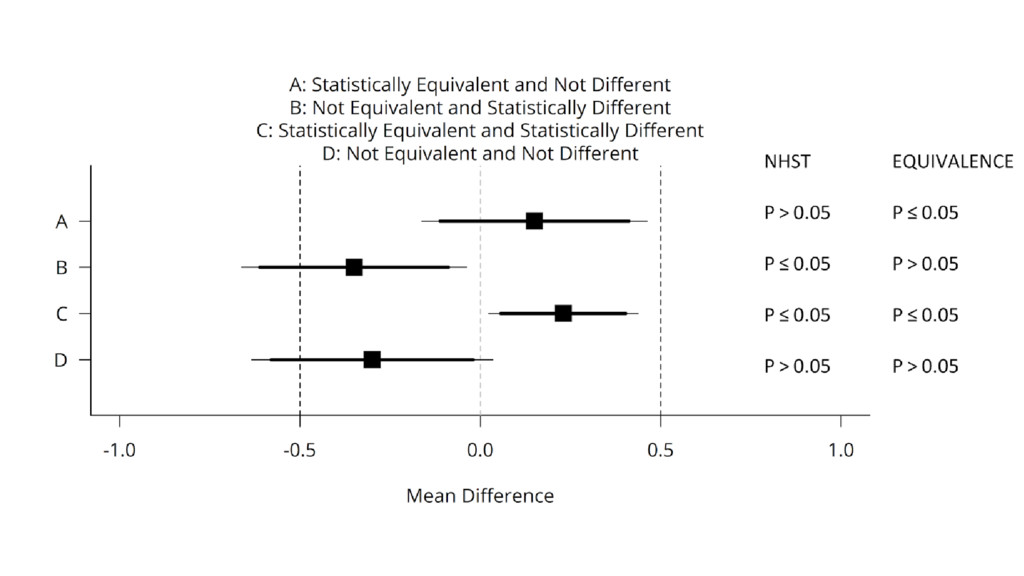
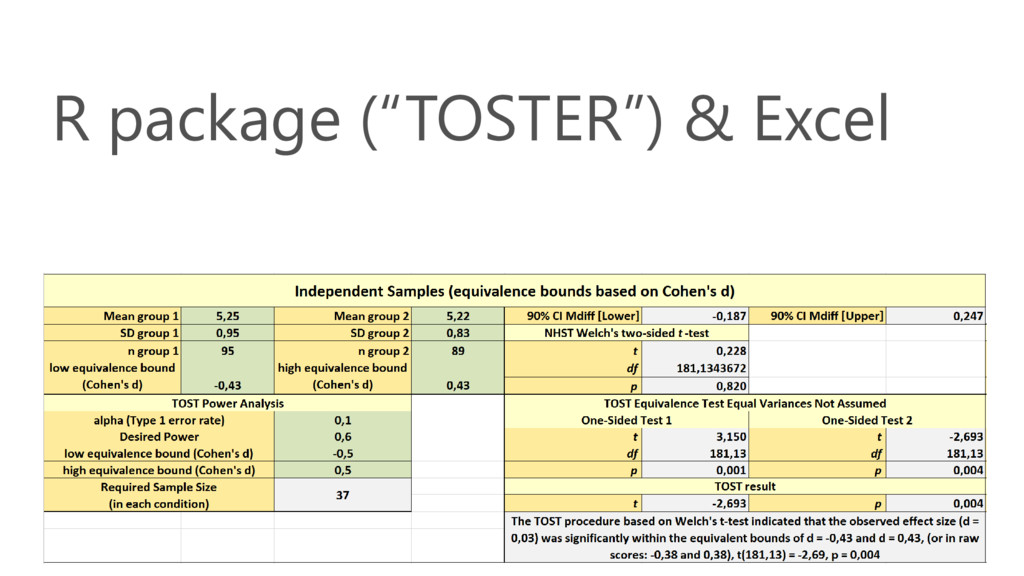
Now you can also reject effects as large as, or
larger than, your SESOI, using an equivalence test.
None
R package (“TOSTER”) & Excel
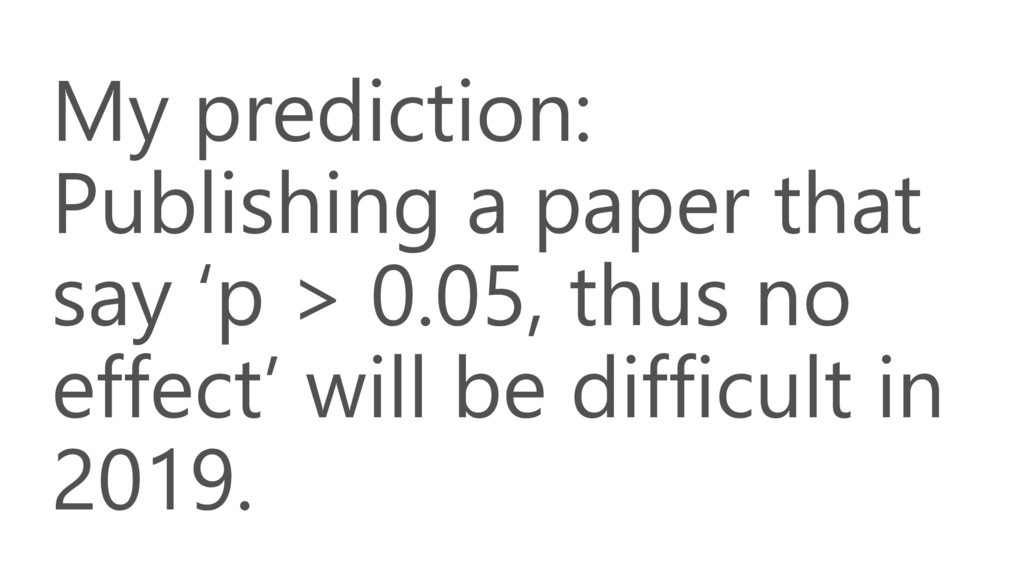
My prediction: Publishing a paper that say ‘p > 0.05,
thus no effect’ will be difficult in 2019.
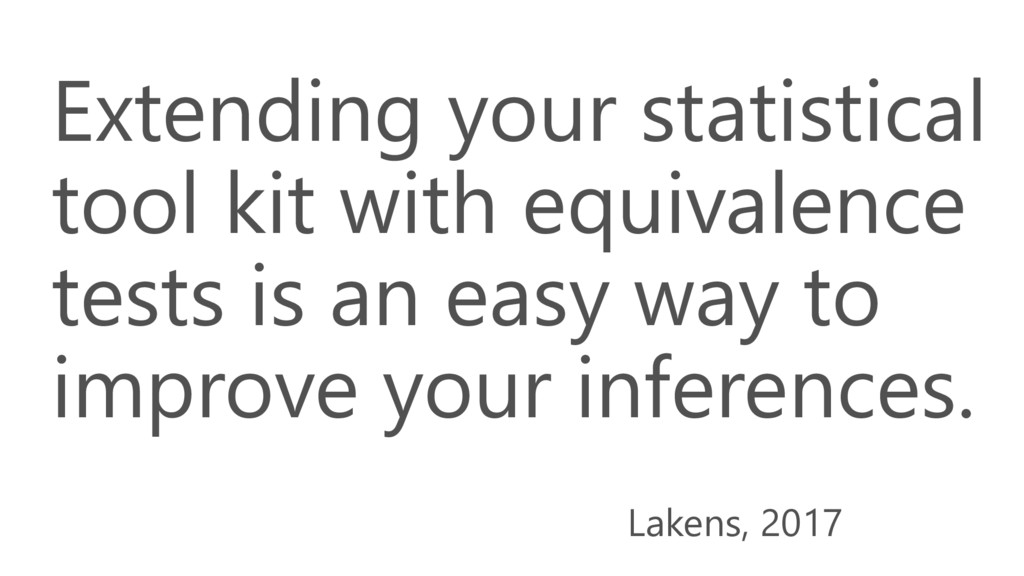
Extending your statistical tool kit with equivalence tests is an
easy way to improve your inferences. Lakens, 2017
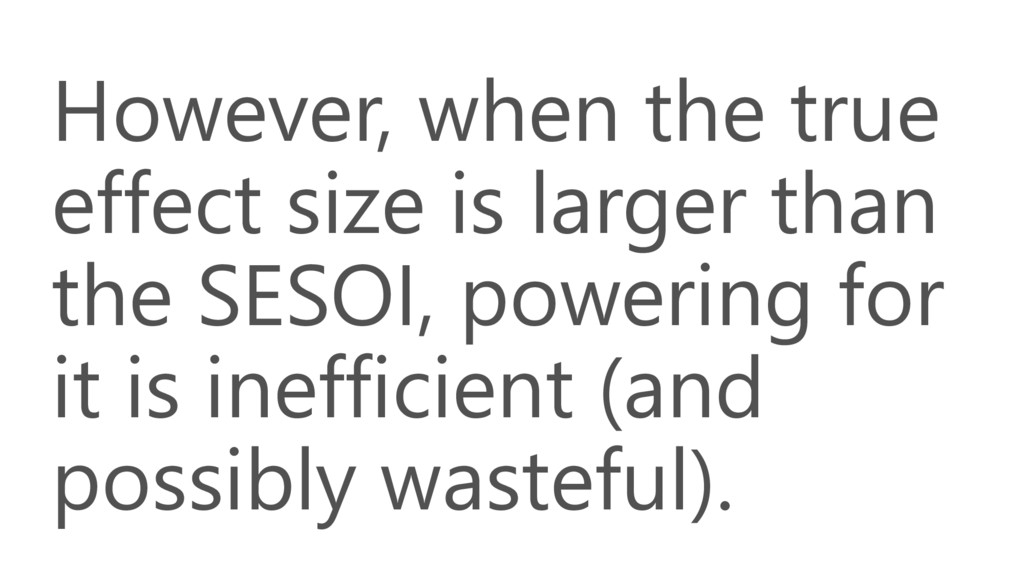
However, when the true effect size is larger than the
SESOI, powering for it is inefficient (and possibly wasteful).
Social Sciences Replication Project
0% 10% 20% 30% 40% 50% 60% 70% 80% 90%
100% 10 20 30 40 50 60 70 80 90 100 110 120 130 140 150 160 170 180 190 200 Power Sample Size per condition in a independent t-test d=0.3 d=0.4 d=0.5 d=0.6 d=0.7 d=0.8
None
When effect sizes are uncertain (=always), a better approach is
sequential analyses.
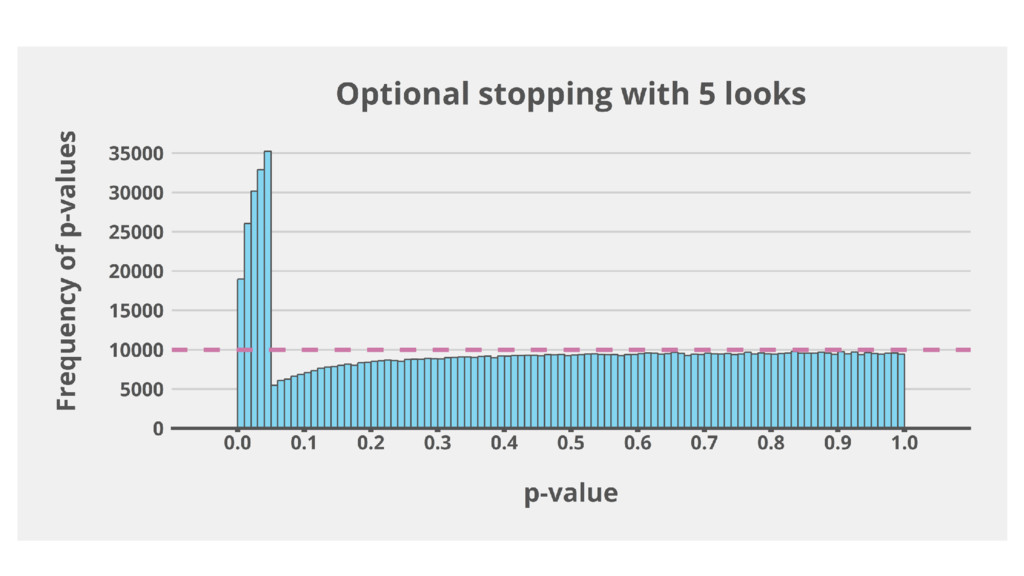
Optional stopping: Collecting data until p < 0.05 inflates the
Type 1 error.
A user of NHST could always obtain a significant result
through optional stopping. Wagenmakers, 2007
None
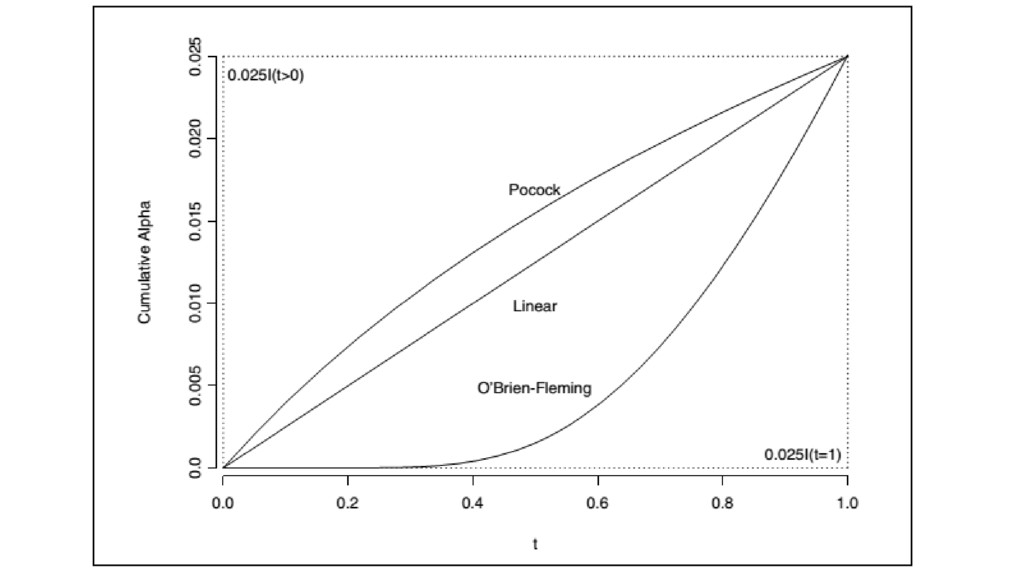
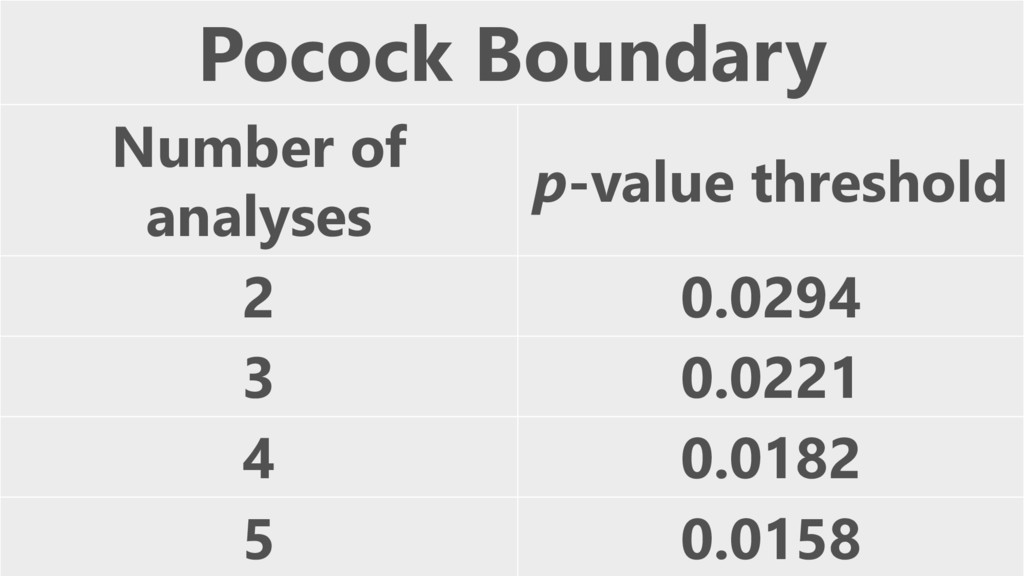
Sequential analysis controls Type 1 error rates (e.g., Pocock correction).
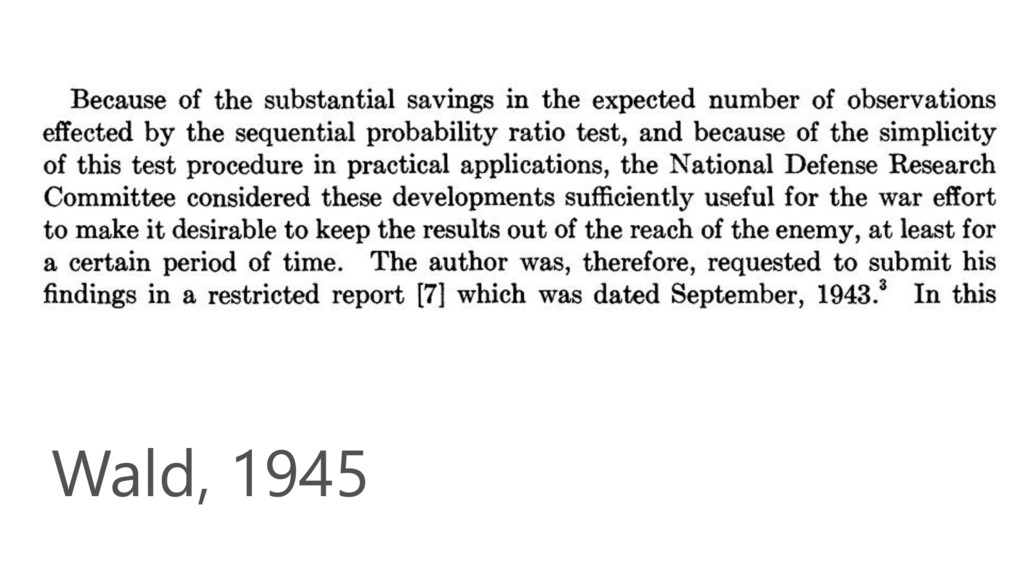
Wald, 1945
None
Pocock Boundary Number of analyses p-value threshold 2 0.0294 3
0.0221 4 0.0182 5 0.0158
None
None
You also correct alpha levels for equivalence tests (and can
calculate power for equivalence).
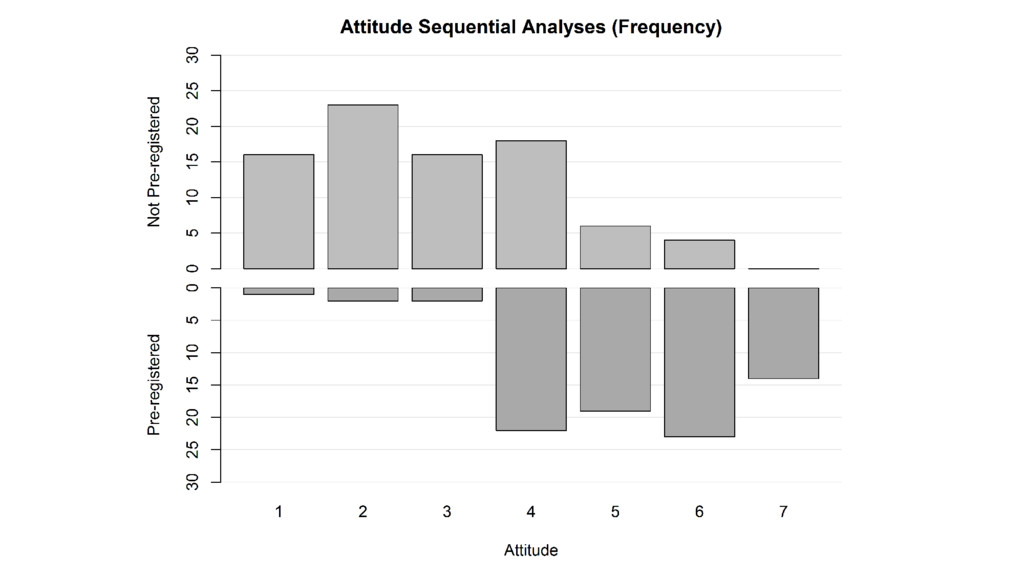
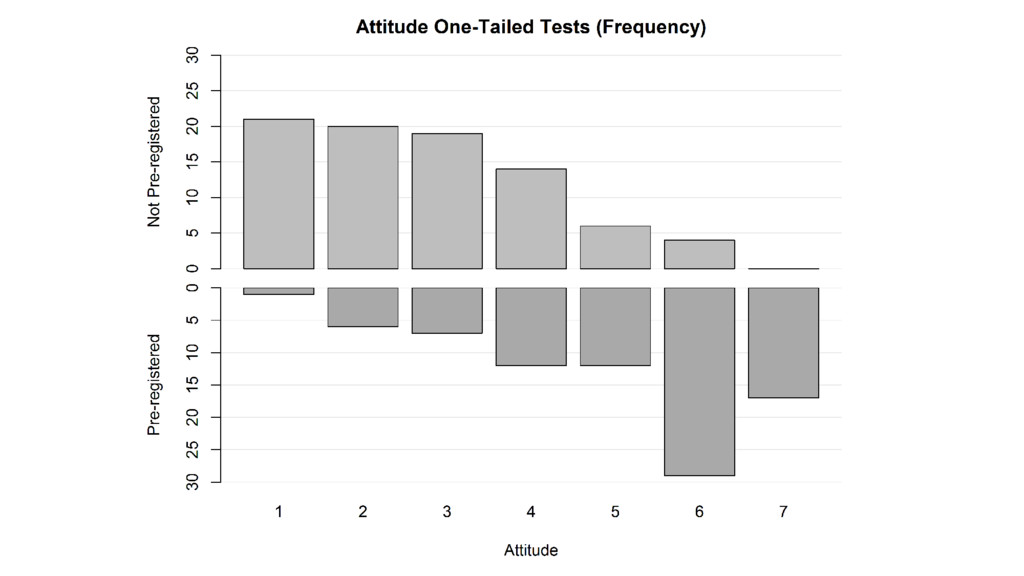
If you pre-register anyway, you can use one-sided tests (more
logical & more efficient)
None
Use decision rules based on p-values or Bayes factors, but
check Frequentist properties. Schonbrodt, Wagenmakers, Zehetleitner, & Perugini, 2015
The SESOI for the Higgs boson was not based on
feasibility, but theory.
If you think the current reproducibility crisis was bad, wait
till the theory crisis in psychology starts.
Thanks! @lakens https://www.coursera.org/learn/statistical-inferences


 institutdelelevage
 trycycle
 tagtag
 syuchimu
 martinlippert
 mickey_kubo
 bonotake
 ykiyota
 mayunak
 eileencodes
 aleyda
 apolaine
 portentint
 lemiorhan
 hannesfritz
 gurzu
 takai
 jmmastey
 kneath
 inesmontani