Share
Embed
Transcript
38 slides
-
GoDataDriven PROUDLY PART OF THE XEBIA GROUP Real time data
driven applications Giovanni Lanzani Data Whisperer Using Python + pandas as back end -
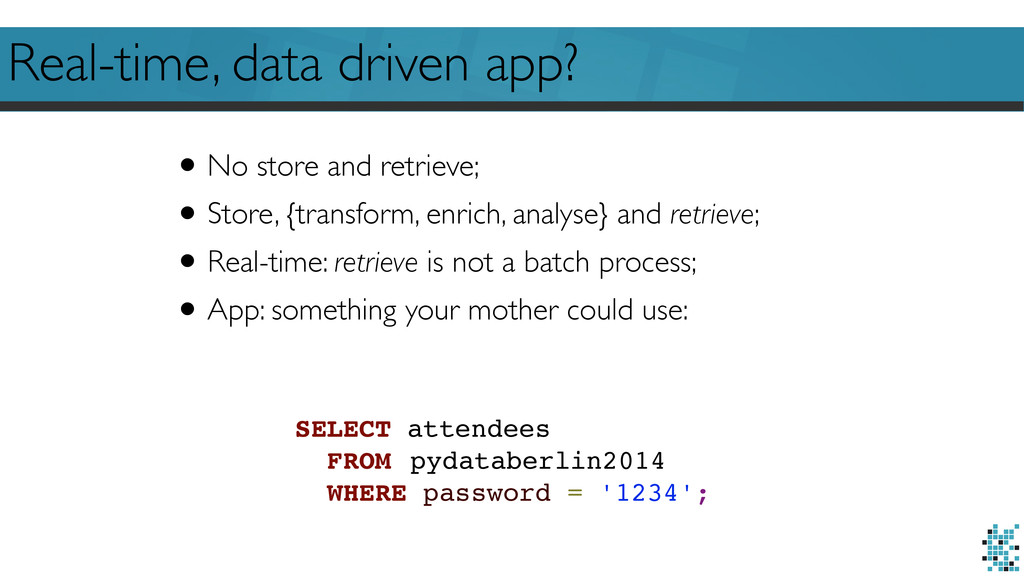
Real-time, data driven app? •No store and retrieve; •Store, {transform,
enrich, analyse} and retrieve; •Real-time: retrieve is not a batch process; •App: something your mother could use: SELECT attendees FROM pydataberlin2014 WHERE password = '1234'; -
Is it Big Data? •Raw logs are in the order
of 40TB; •We use Hadoop for storing, enriching and pre- processing; •(10 nodes, 24TB per nodes) -
Challenges 1. Privacy; 2. Huge pile of data; 3. Real-time
retrieval; 4. Some real-time analysis. -
3. Real-time retrieval •Harder than it looks; •Large data; •Retrieval
is by giving date, center location + radius. -
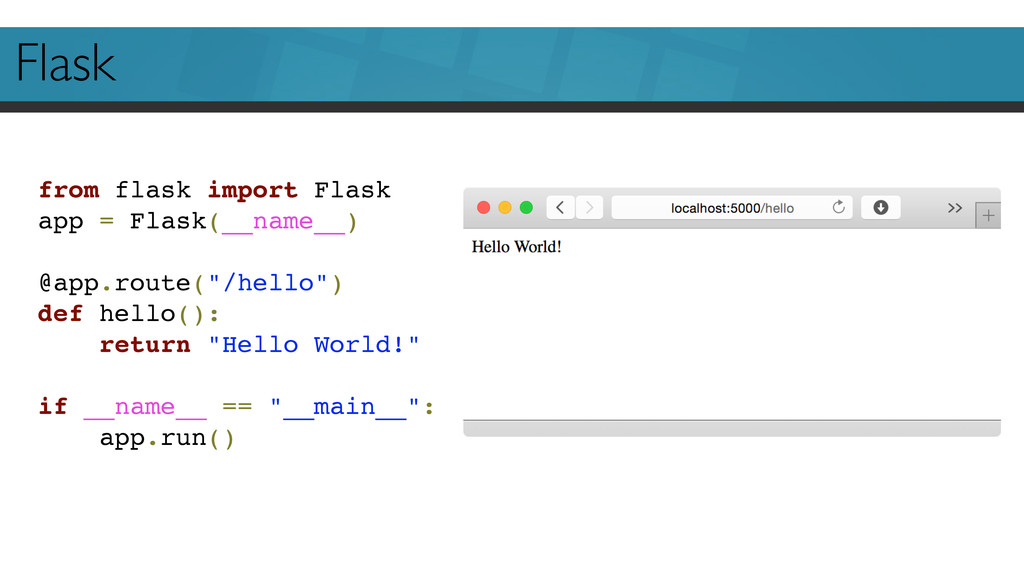
Flask from flask import Flask app = Flask(__name__) @app.route("/hello") def
hello(): return "Hello World!" if __name__ == "__main__": app.run() -
app.py example @app.route('/api/<postcode>/<date>/<radius>', methods=['GET']) @app.route('/api/<postcode>/<date>', methods=['GET']) def datapoints(postcode, date, radius=1.0):
... stats, timeline, points = helper.get_json(postcode, date, radius) return … # returns a JSON object for AngularJS -
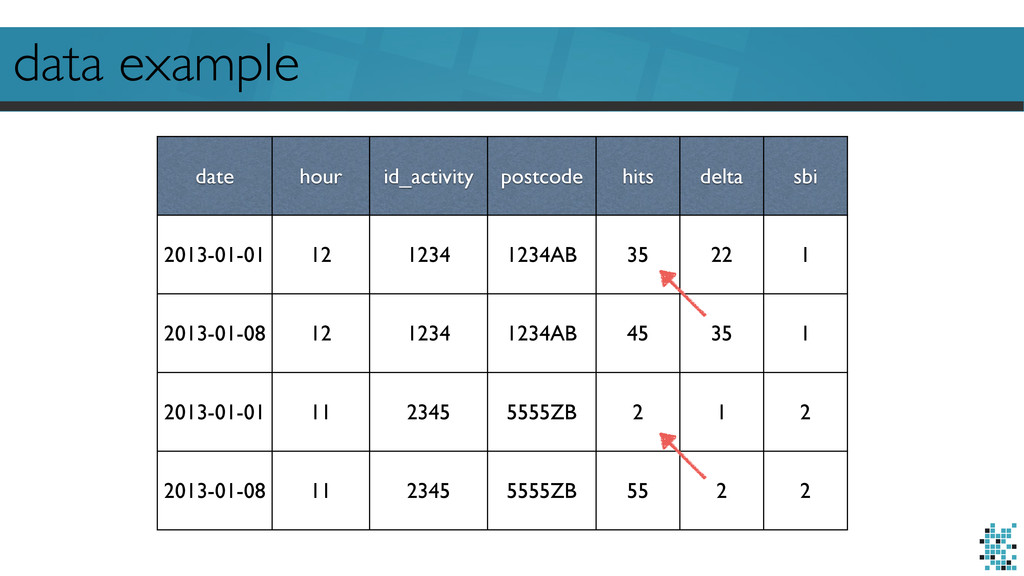
data example date hour id_activity postcode hits delta sbi 2013-01-01
12 1234 1234AB 35 22 1 2013-01-08 12 1234 1234AB 45 35 1 2013-01-01 11 2345 5555ZB 2 1 2 2013-01-08 11 2345 5555ZB 55 2 2 -
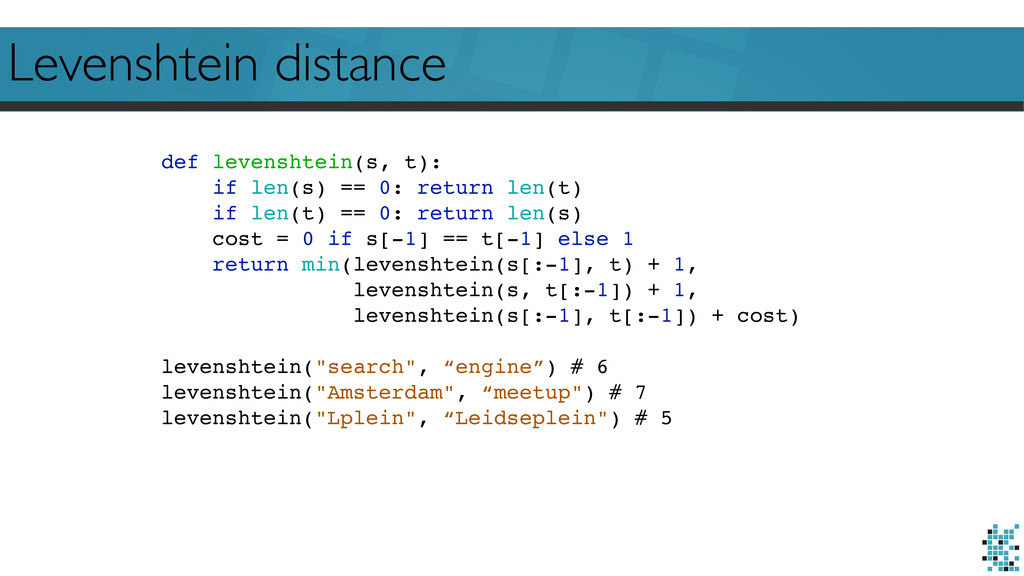
Levenshtein distance def levenshtein(s, t): if len(s) == 0: return
len(t) if len(t) == 0: return len(s) cost = 0 if s[-1] == t[-1] else 1 return min(levenshtein(s[:-1], t) + 1, levenshtein(s, t[:-1]) + 1, levenshtein(s[:-1], t[:-1]) + cost) levenshtein("search", “engine”) # 6 levenshtein("Amsterdam", “meetup") # 7 levenshtein("Lplein", “Leidseplein") # 5 -
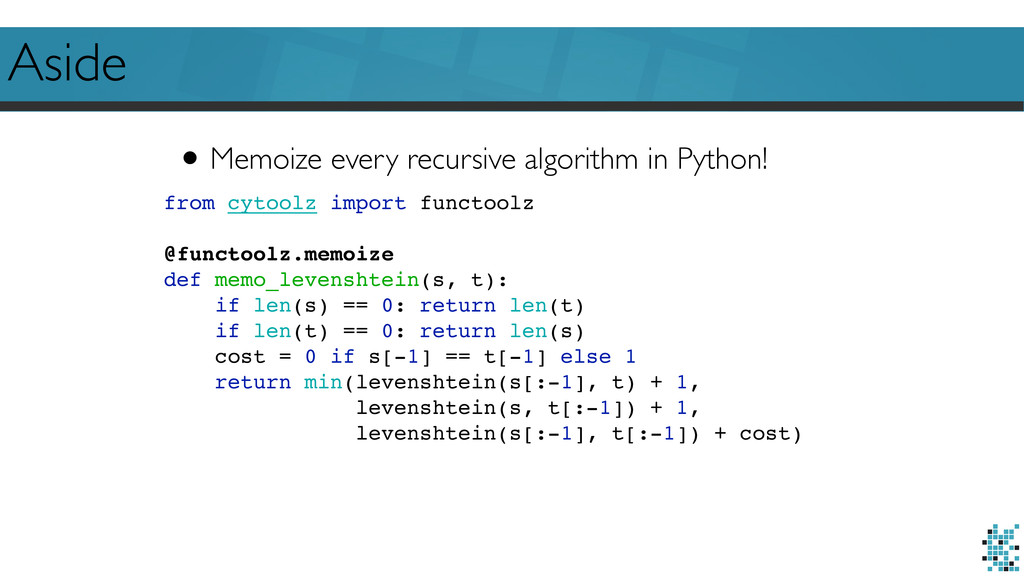
Aside •Memoize every recursive algorithm in Python! from cytoolz import
functoolz @functoolz.memoize def memo_levenshtein(s, t): if len(s) == 0: return len(t) if len(t) == 0: return len(s) cost = 0 if s[-1] == t[-1] else 1 return min(levenshtein(s[:-1], t) + 1, levenshtein(s, t[:-1]) + 1, levenshtein(s[:-1], t[:-1]) + cost) -
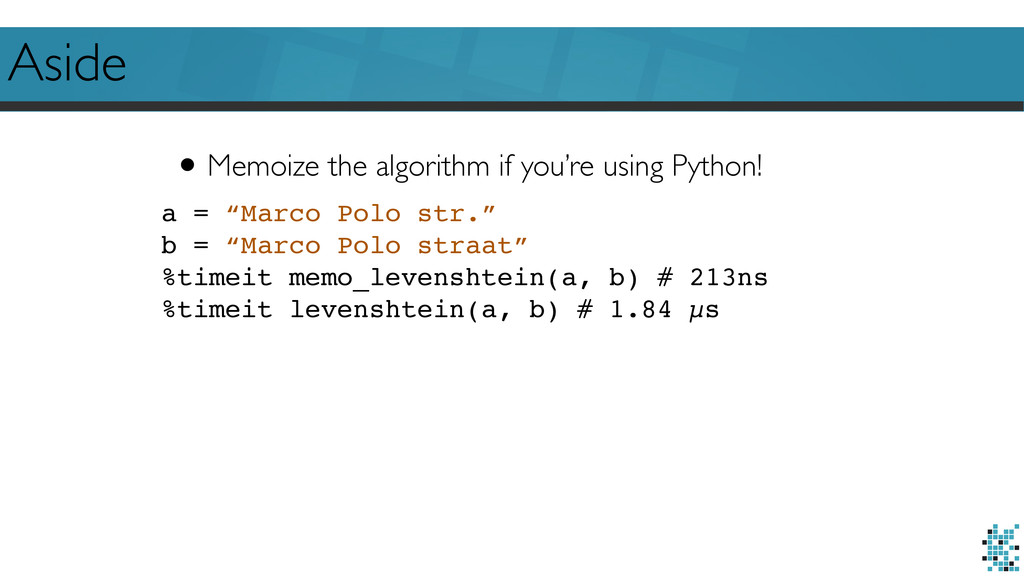
Aside •Memoize the algorithm if you’re using Python! a =
“Marco Polo str.” b = “Marco Polo straat” %timeit memo_levenshtein(a, b) # 213ns %timeit levenshtein(a, b) # 1.84 µs -
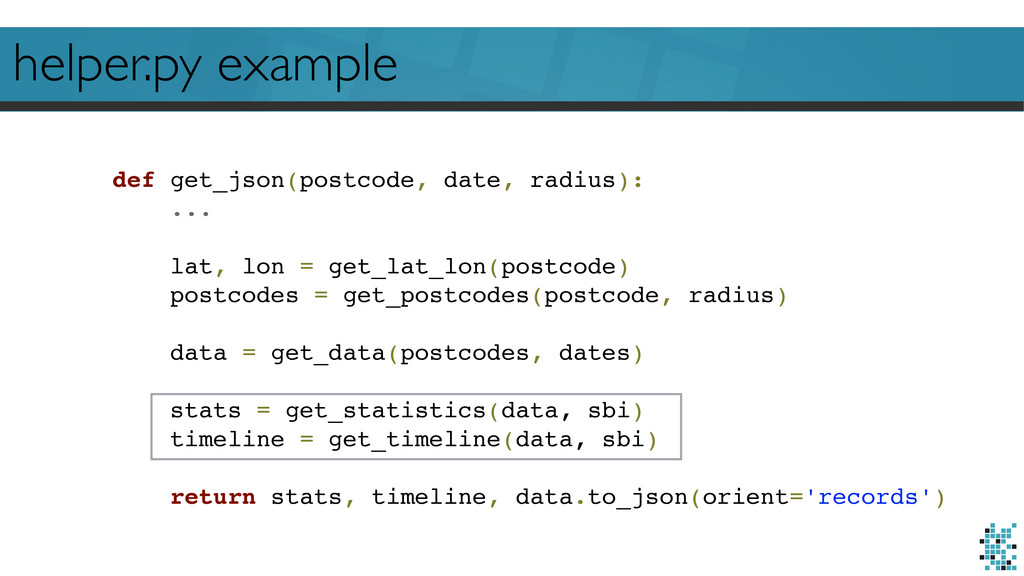
helper.py example def get_json(postcode, date, radius): ... lat, lon =
get_lat_lon(postcode) postcodes = get_postcodes(postcode, radius) data = get_data(postcodes, dates) stats = get_statistics(data, sbi) timeline = get_timeline(data, sbi) return stats, timeline, data.to_json(orient='records') -
helper.py example def get_statistics(data, sbi): sbi_df = data[data.sbi == sbi]
# select * from data where sbi = sbi hits = sbi_df.hits.sum() # select sum(hits) from … delta_hits = sbi_df.delta.sum() # select sum(delta) from … if delta_hits: percentage = (hits - delta_hits) / delta_hits else: percentage = 0 return {"sbi": sbi, "total": hits, "percentage": percentage} -
helper.py example def get_timeline(data, sbi): df_sbi = data.groupby([“date”, “hour", “sbi"]).aggregate(sum)
# select sum(hits), sum(delta) from data group by date, hour, sbi return df_sbi -
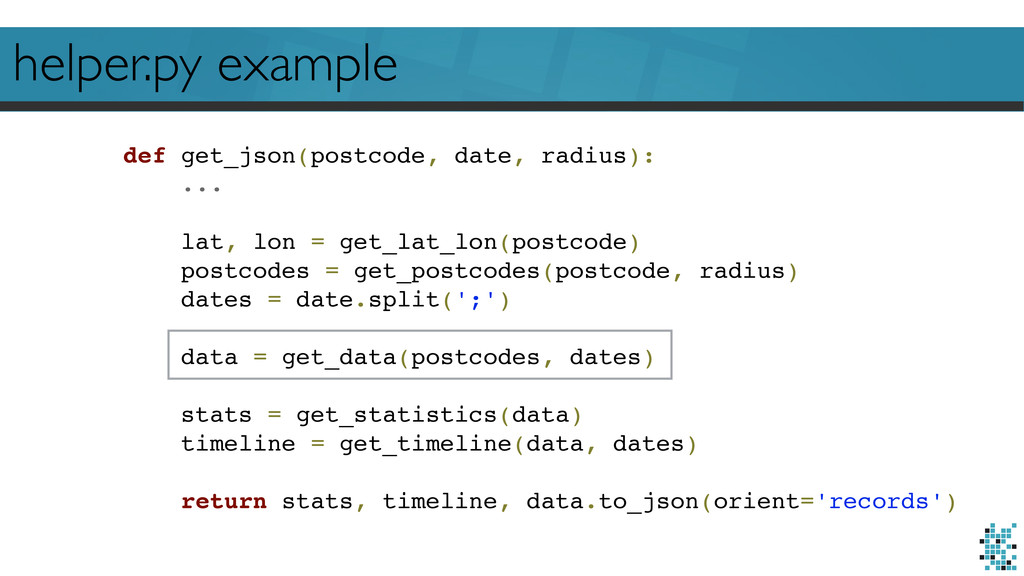
helper.py example def get_json(postcode, date, radius): ... lat, lon =
get_lat_lon(postcode) postcodes = get_postcodes(postcode, radius) dates = date.split(';') data = get_data(postcodes, dates) stats = get_statistics(data) timeline = get_timeline(data, dates) return stats, timeline, data.to_json(orient='records') -
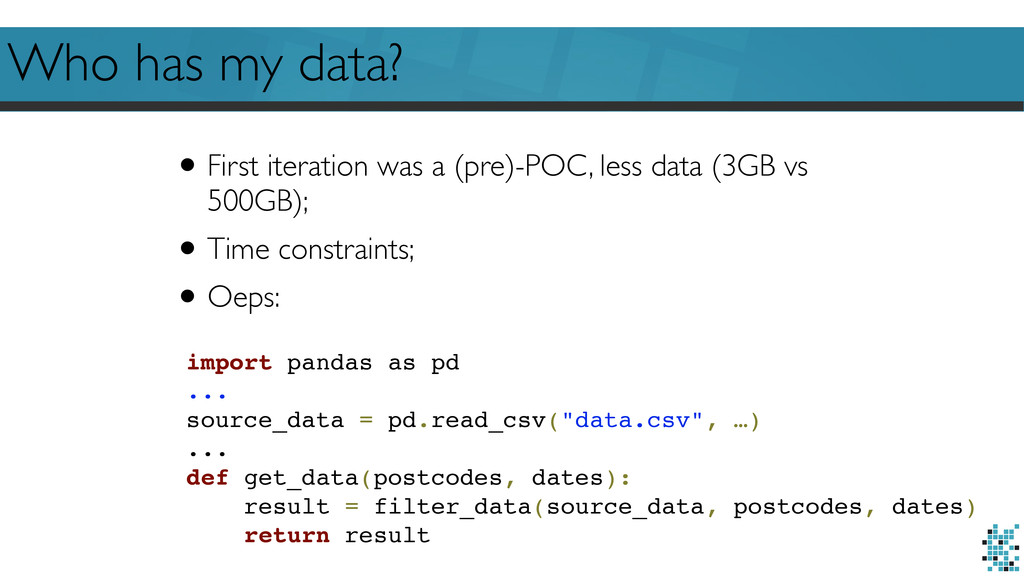
Who has my data? •First iteration was a (pre)-POC, less
data (3GB vs 500GB); •Time constraints; •Oeps: import pandas as pd ... source_data = pd.read_csv("data.csv", …) ... def get_data(postcodes, dates): result = filter_data(source_data, postcodes, dates) return result -
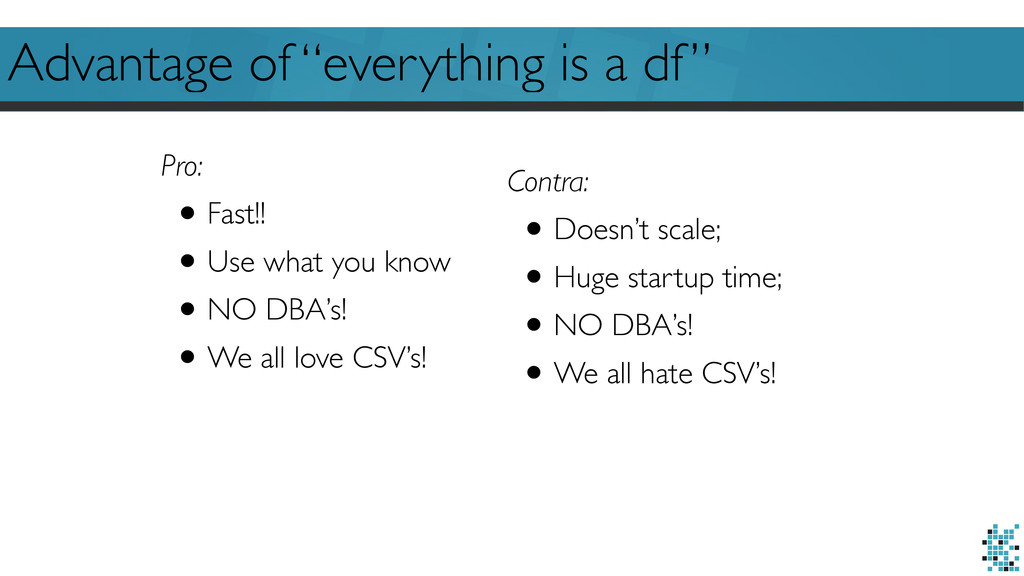
Advantage of “everything is a df” Pro: •Fast!! •Use what
you know •NO DBA’s! •We all love CSV’s! Contra: •Doesn’t scale; •Huge startup time; •NO DBA’s! •We all hate CSV’s! -
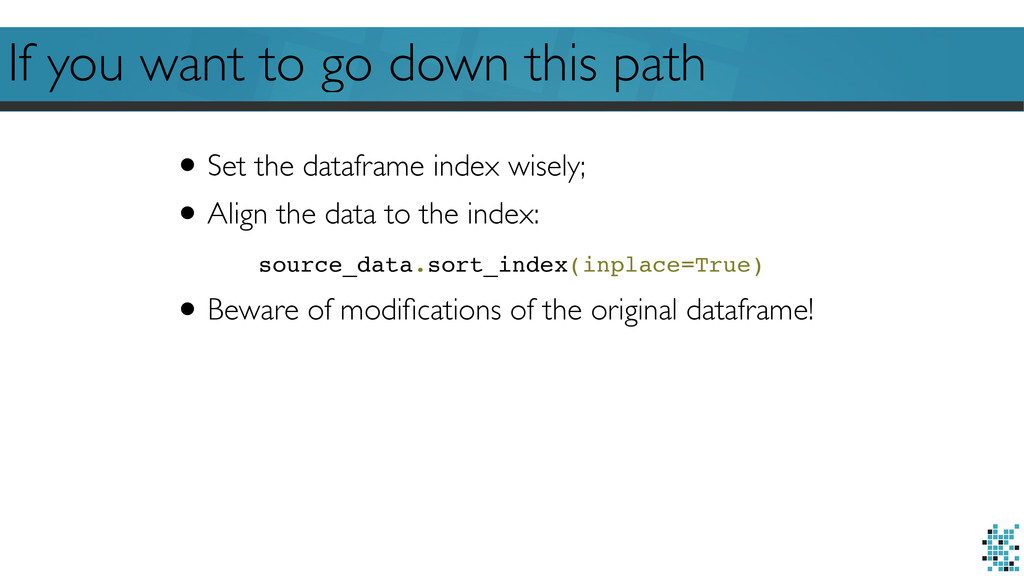
If you want to go down this path •Set the
dataframe index wisely; •Align the data to the index: •Beware of modifications of the original dataframe! source_data.sort_index(inplace=True) -
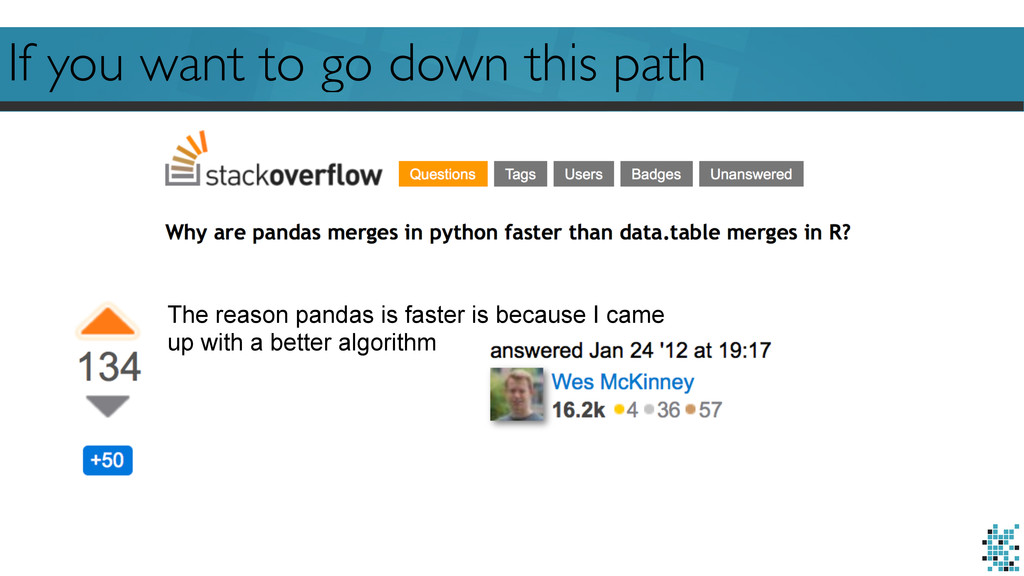
If you want to go down this path The reason
pandas is faster is because I came up with a better algorithm -
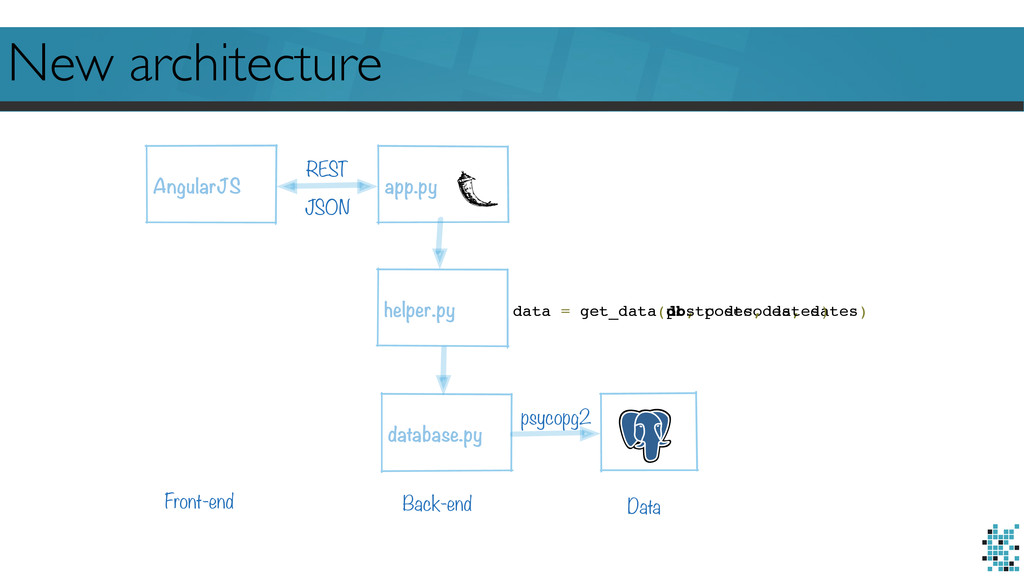
New architecture data = get_data(db, postcodes, dates) data = get_data(postcodes,
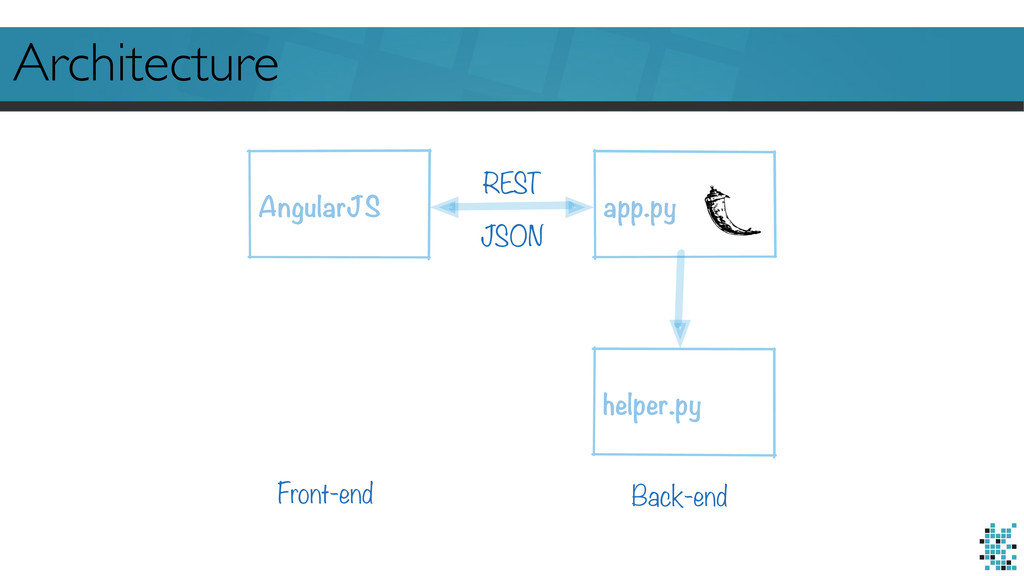
dates) database.py Data psycopg2 AngularJS app.py helper.py REST Front-end Back-end JSON -
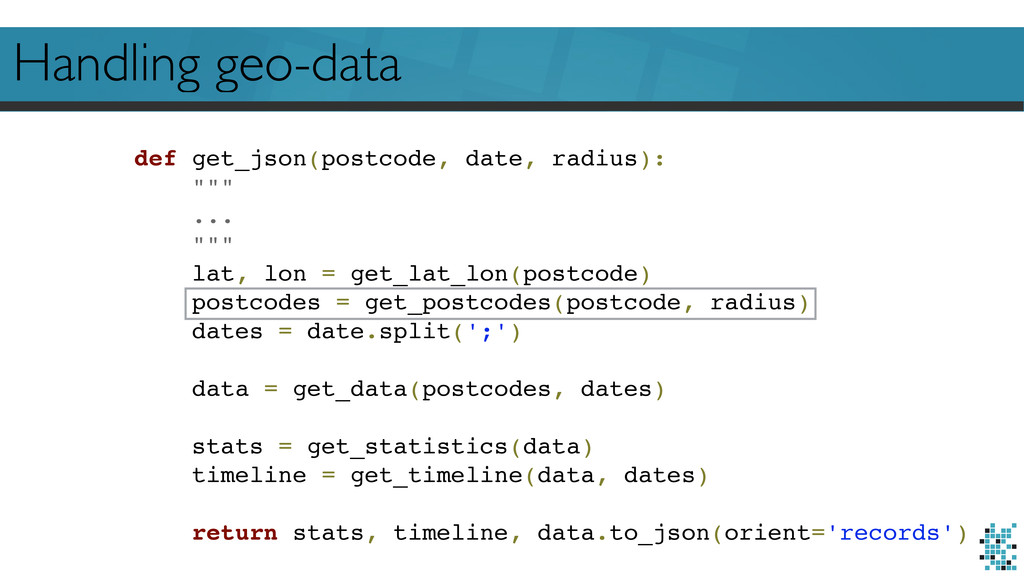
Handling geo-data def get_json(postcode, date, radius): """ ... """ lat,
lon = get_lat_lon(postcode) postcodes = get_postcodes(postcode, radius) dates = date.split(';') data = get_data(postcodes, dates) stats = get_statistics(data) timeline = get_timeline(data, dates) return stats, timeline, data.to_json(orient='records') -
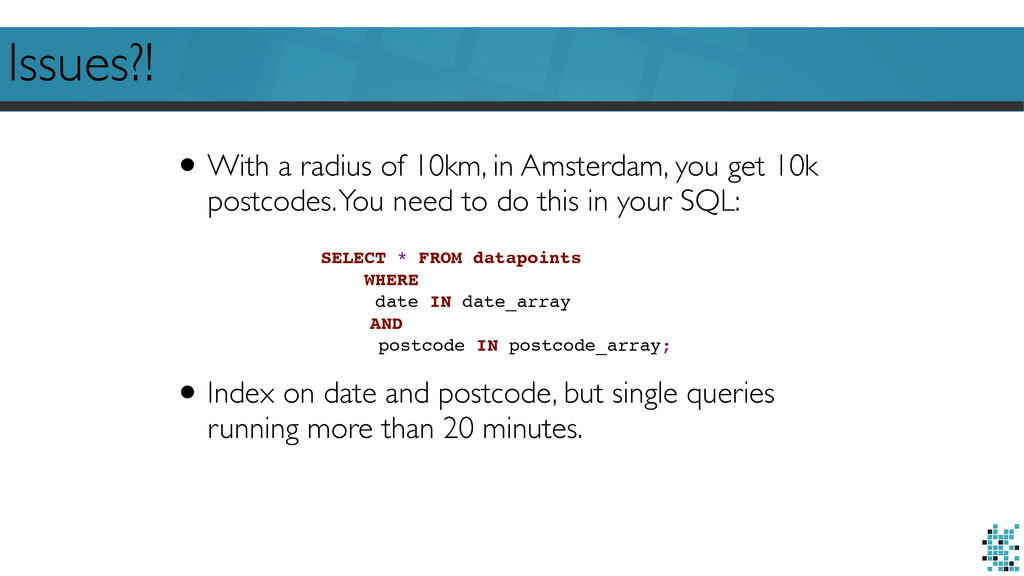
Issues?! •With a radius of 10km, in Amsterdam, you get
10k postcodes. You need to do this in your SQL: •Index on date and postcode, but single queries running more than 20 minutes. SELECT * FROM datapoints WHERE date IN date_array AND postcode IN postcode_array; -
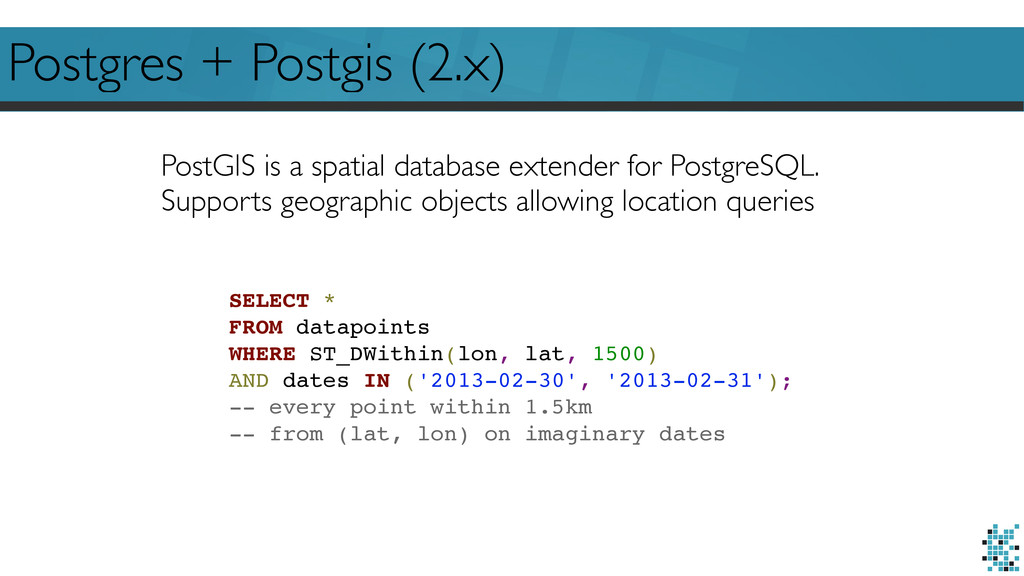
Postgres + Postgis (2.x) PostGIS is a spatial database extender
for PostgreSQL. Supports geographic objects allowing location queries SELECT * FROM datapoints WHERE ST_DWithin(lon, lat, 1500) AND dates IN ('2013-02-30', '2013-02-31'); -- every point within 1.5km -- from (lat, lon) on imaginary dates -
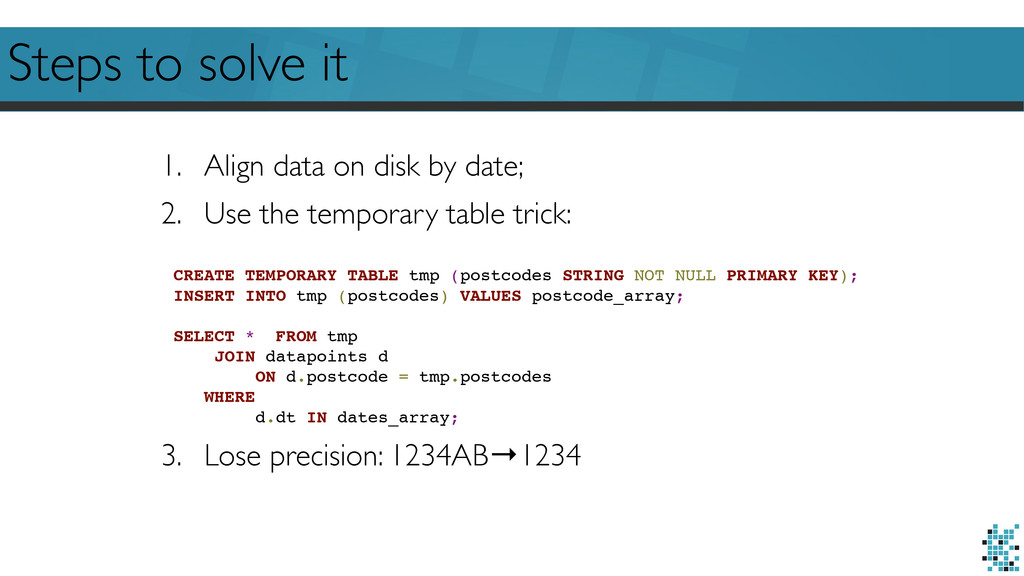
Steps to solve it 1. Align data on disk by
date; 2. Use the temporary table trick: 3. Lose precision: 1234AB→1234 CREATE TEMPORARY TABLE tmp (postcodes STRING NOT NULL PRIMARY KEY); INSERT INTO tmp (postcodes) VALUES postcode_array; SELECT * FROM tmp JOIN datapoints d ON d.postcode = tmp.postcodes WHERE d.dt IN dates_array; -
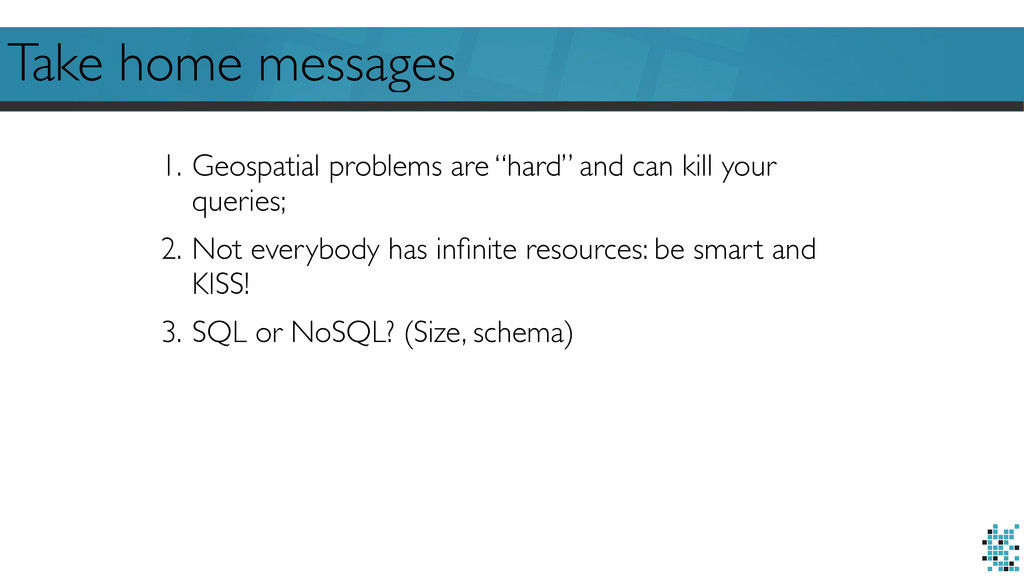
Take home messages 1. Geospatial problems are “hard” and can
kill your queries; 2. Not everybody has infinite resources: be smart and KISS! 3. SQL or NoSQL? (Size, schema) -
GoDataDriven We’re hiring / Questions? / Thank you! @gglanzani [email protected]
Giovanni Lanzani Data Whisperer