Share
Embed
大規模本番環境における HDFS Erasure Coding の運用について / Using HDFS Erasure Coding for Growth
内田早俊 (LINE)
LINE Developer Meetup #68 - Big Data Platformでの登壇資料です
https://line.connpass.com/event/188176/
LINE Developers
September 17, 2020
Transcript
33 slides
-
USING ERASURE CODING FOR GROWTH Toshihiko Uchida Site Reliability Engineer
Data Platform Data Science and Engineering Center -
• Name • Toshihiko Uchida • Role • Site Reliability
Engineer • Data Infrastructure Team / Data Platform / Data Science and Engineering Center • History • Working at LINE since 02/2018 • Hadoop ecosystems, Kafka and Flink • Interest • Distributed systems • Program verification theory • Dependent type systems • Model checking • Facebook: https://www.facebook.com/toshihiko.uchida.7 PROFILE -
• LINE Data Platform • Unifying Hadoop Clusters • Erasure
Coding • Erasure Coding Reconstruction Agenda -
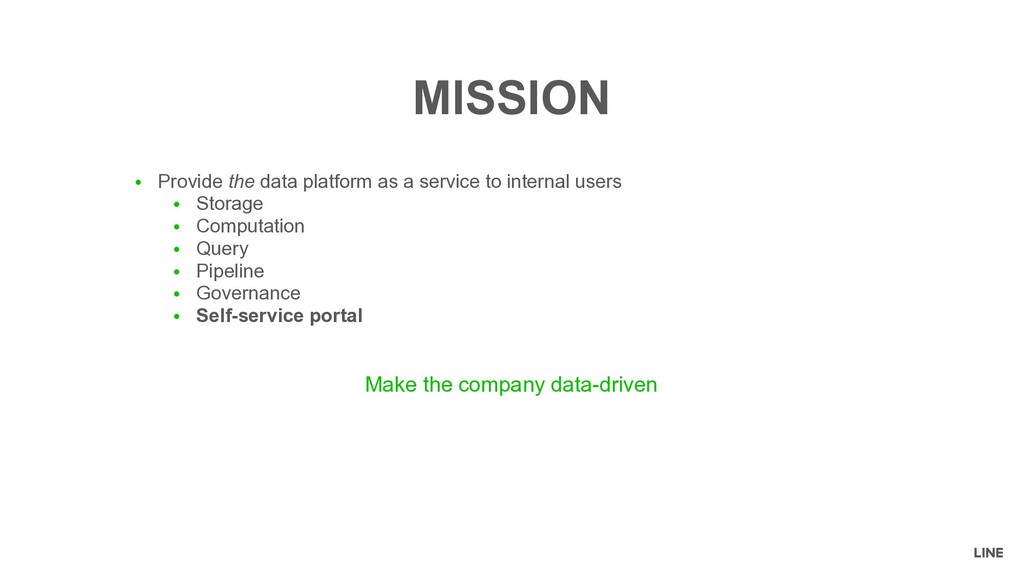
• Provide the data platform as a service to internal
users • Storage • Computation • Query • Pipeline • Governance • Self-service portal MISSION Make the company data-driven -
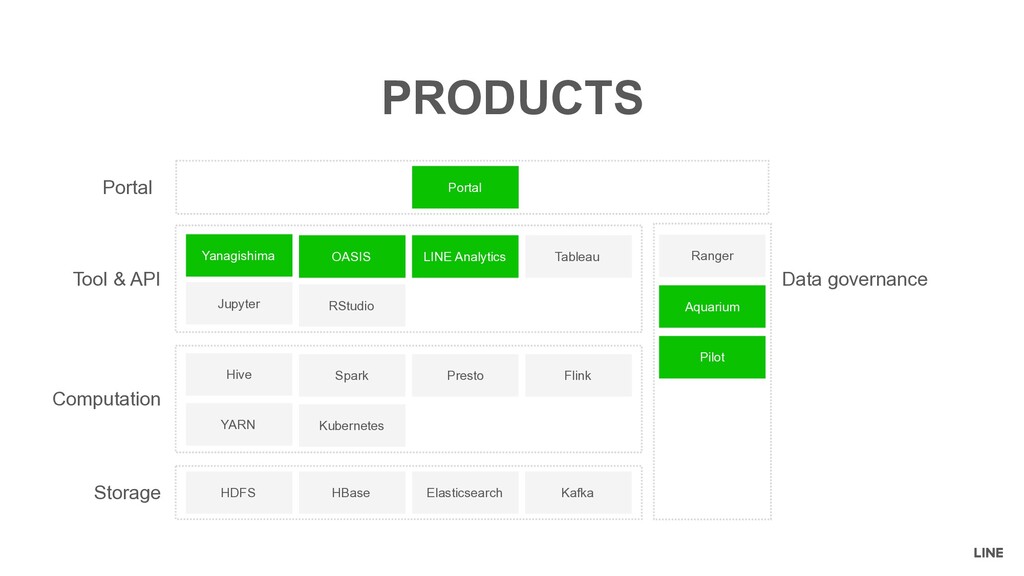
PRODUCTS HDFS HBase Elasticsearch YARN Kubernetes Flink Spark Hive Presto
Ranger Yanagishima OASIS Jupyter Tableau LINE Analytics Aquarium RStudio Portal Portal Storage Computation Tool & API Kafka Data governance Pilot -
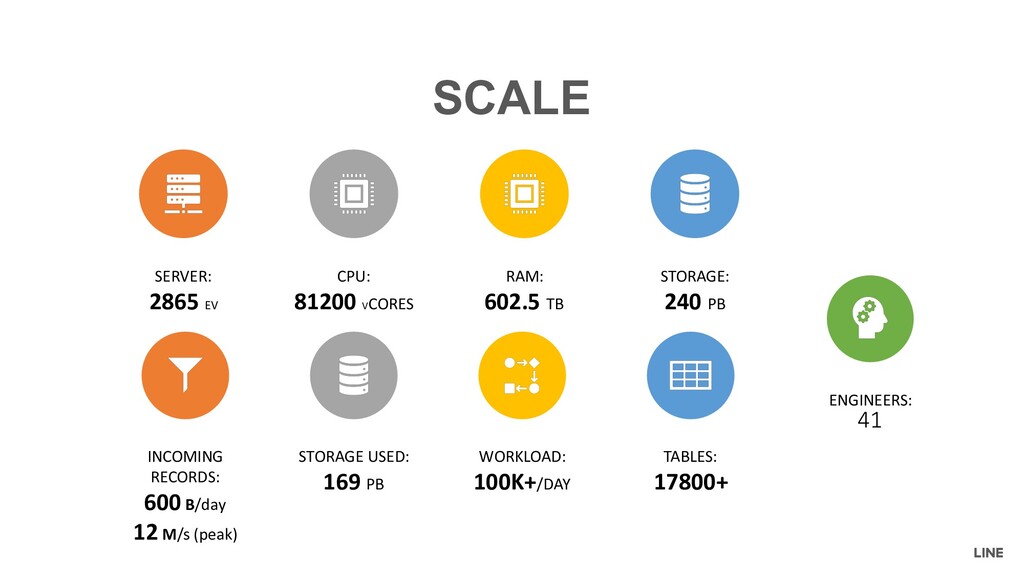
SCALE SERVER: 2865 EV CPU: 81200 VCORES RAM: 602.5 TB
STORAGE: 240 PB INCOMING RECORDS: 600 B/day 12 M/s (peak) STORAGE USED: 169 PB WORKLOAD: 100K+/DAY TABLES: 17800+ ENGINEERS: 41 -
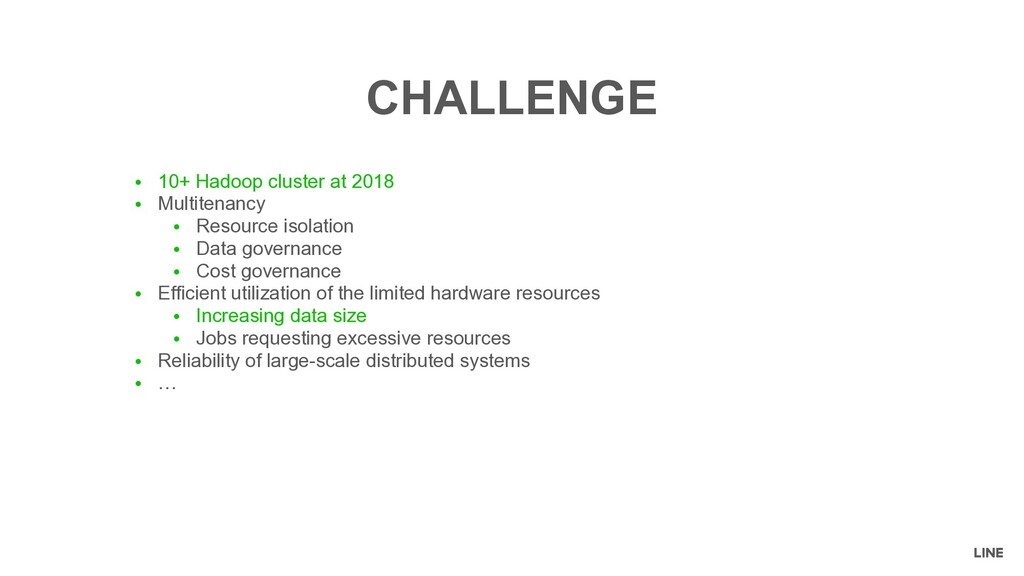
• 10+ Hadoop cluster at 2018 • Multitenancy • Resource
isolation • Data governance • Cost governance • Efficient utilization of the limited hardware resources • Increasing data size • Jobs requesting excessive resources • Reliability of large-scale distributed systems • … CHALLENGE -
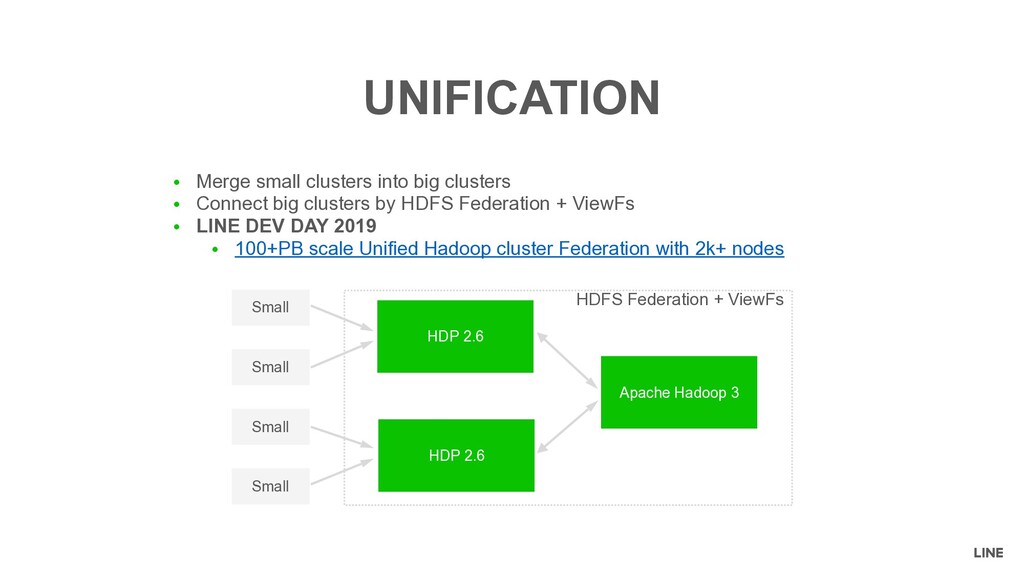
• Merge small clusters into big clusters • Connect big
clusters by HDFS Federation + ViewFs • LINE DEV DAY 2019 • 100+PB scale Unified Hadoop cluster Federation with 2k+ nodes UNIFICATION Small HDP 2.6 Small Small HDP 2.6 Small Apache Hadoop 3 HDFS Federation + ViewFs -
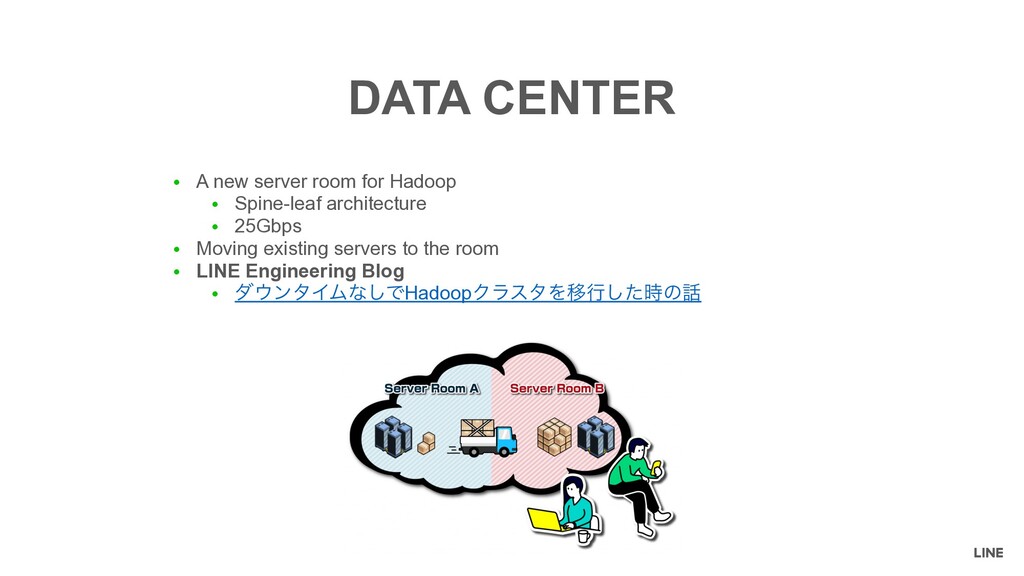
• A new server room for Hadoop • Spine-leaf architecture
• 25Gbps • Moving existing servers to the room • LINE Engineering Blog • μϯλΠϜͳ͠ͰHadoopΫϥελΛҠߦͨ࣌͠ͷ DATA CENTER -
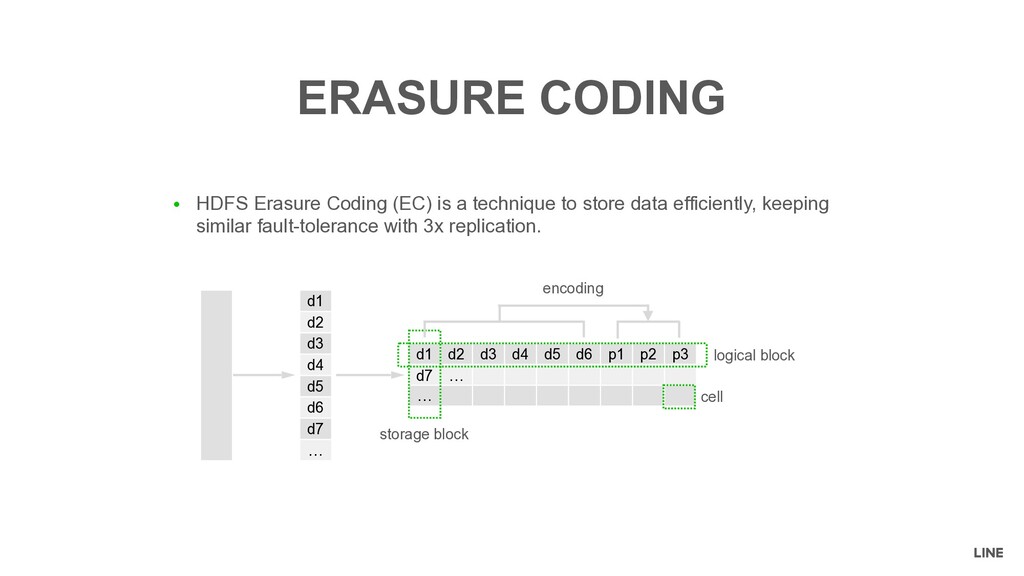
• HDFS Erasure Coding (EC) is a technique to store
data efficiently, keeping similar fault-tolerance with 3x replication. ERASURE CODING d1 d2 d3 d4 d5 d6 p1 p2 p3 d7 … … d1 d2 d3 d4 d5 d6 d7 … storage block logical block encoding cell -
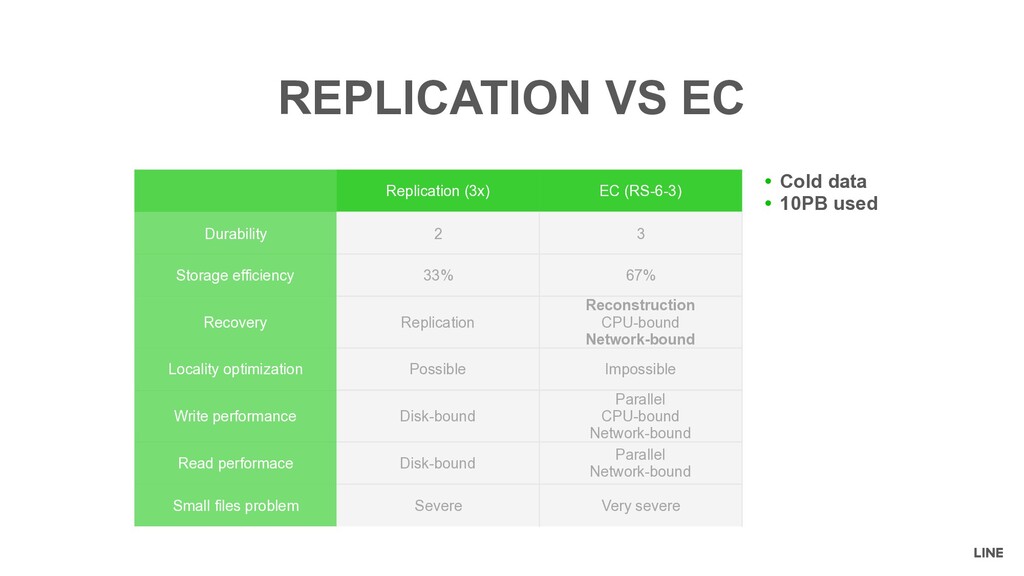
REPLICATION VS EC Replication (3x) EC (RS-6-3) Durability 2 3
Storage efficiency 33% 67% Recovery Replication Reconstruction CPU-bound Network-bound Locality optimization Possible Impossible Write performance Disk-bound Parallel CPU-bound Network-bound Read performace Disk-bound Parallel Network-bound Small files problem Severe Very severe • Cold data • 10PB used -
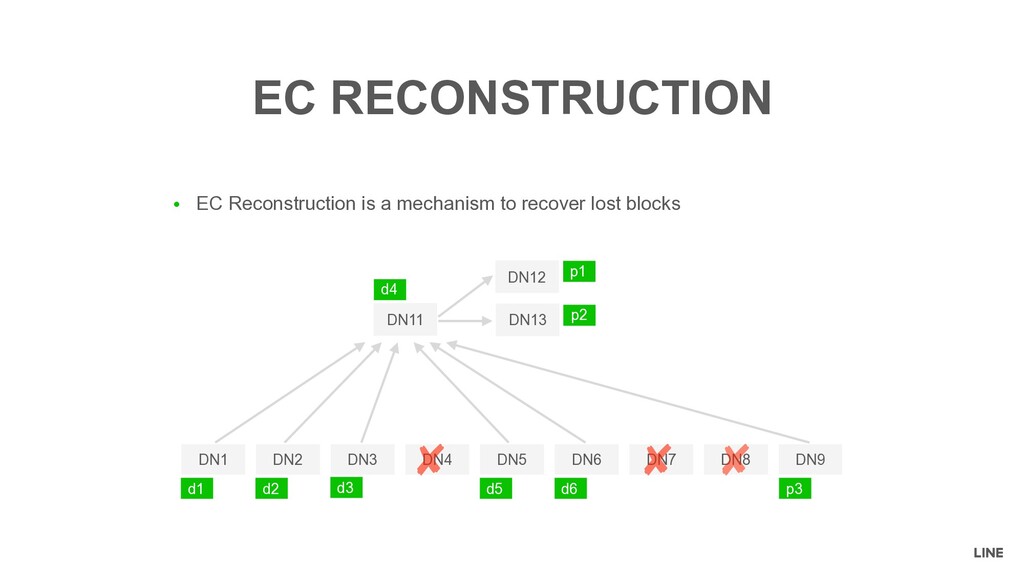
• EC Reconstruction is a mechanism to recover lost blocks
EC RECONSTRUCTION DN1 DN2 DN3 DN4 DN5 DN6 DN7 DN8 DN9 d1 d2 d3 d5 d6 p3 d4 p1 p2 DN12 DN13 DN11 -
• Network congestion between data centers NETWORK CONGESTION New server
room Old server room DN1 DN2 DN3 DN4 DN5 DN6 DN7 DN8 DN9 d1 d2 d3 d5 d6 p3 d4 p1 p2 DN12 DN13 DN11 -
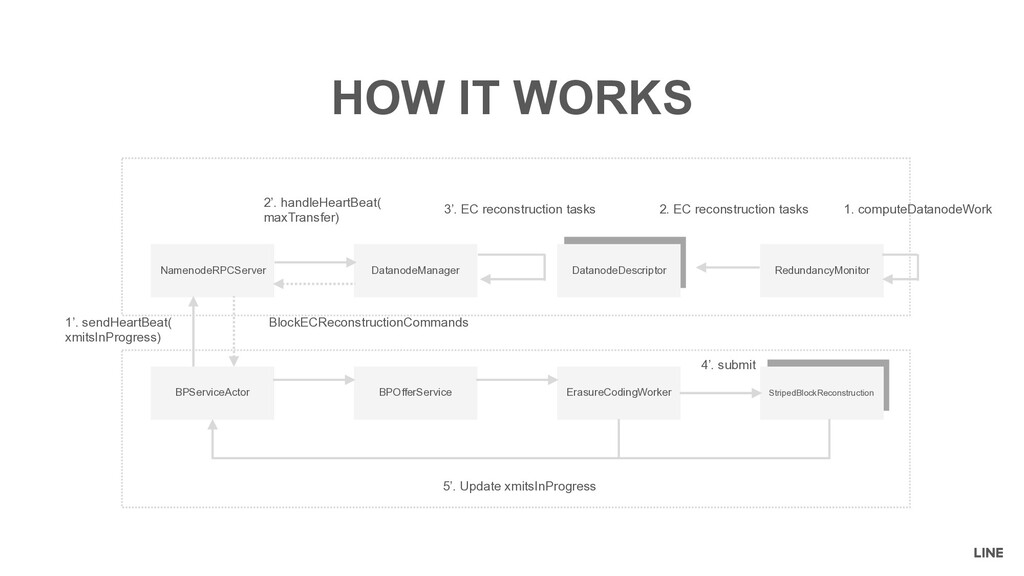
StripedBlockReconstruction DatanodeDescriptor HOW IT WORKS NamenodeRPCServer BPServiceActor DatanodeManager BPOfferService ErasureCodingWorker
StripedBlockReconstruction DatanodeDescriptor RedundancyMonitor 1. computeDatanodeWork 2. EC reconstruction tasks 1’. sendHeartBeat( xmitsInProgress) 2’. handleHeartBeat( maxTransfer) 3’. EC reconstruction tasks BlockECReconstructionCommands 5’. Update xmitsInProgress 4’. submit -
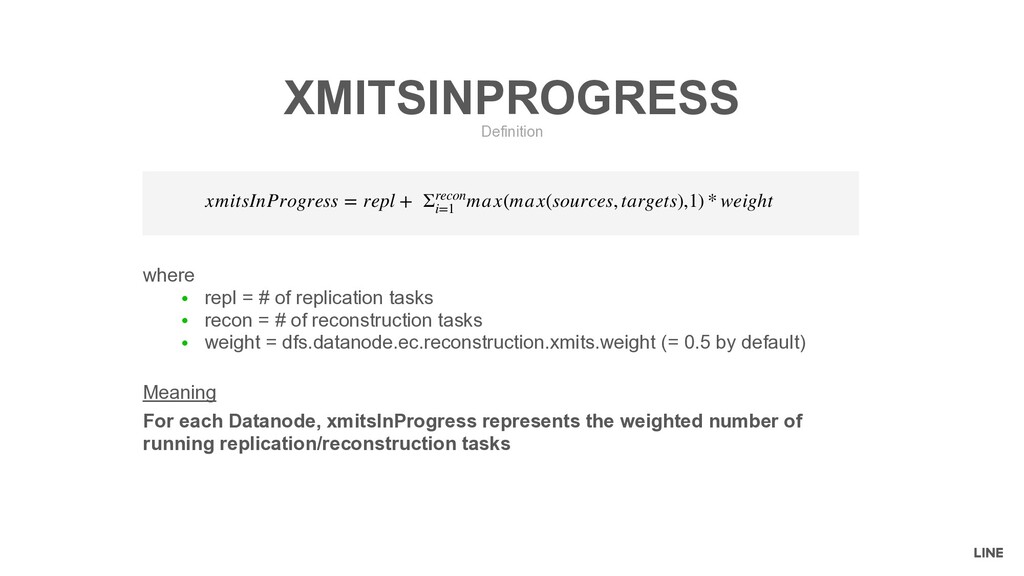
where • repl = # of replication tasks • recon
= # of reconstruction tasks • weight = dfs.datanode.ec.reconstruction.xmits.weight (= 0.5 by default) Definition XMITSINPROGRESS xmitsInProgress = repl + Σrecon i=1 max(max(sources, targets),1) * weight Meaning For each Datanode, xmitsInProgress represents the weighted number of running replication/reconstruction tasks -
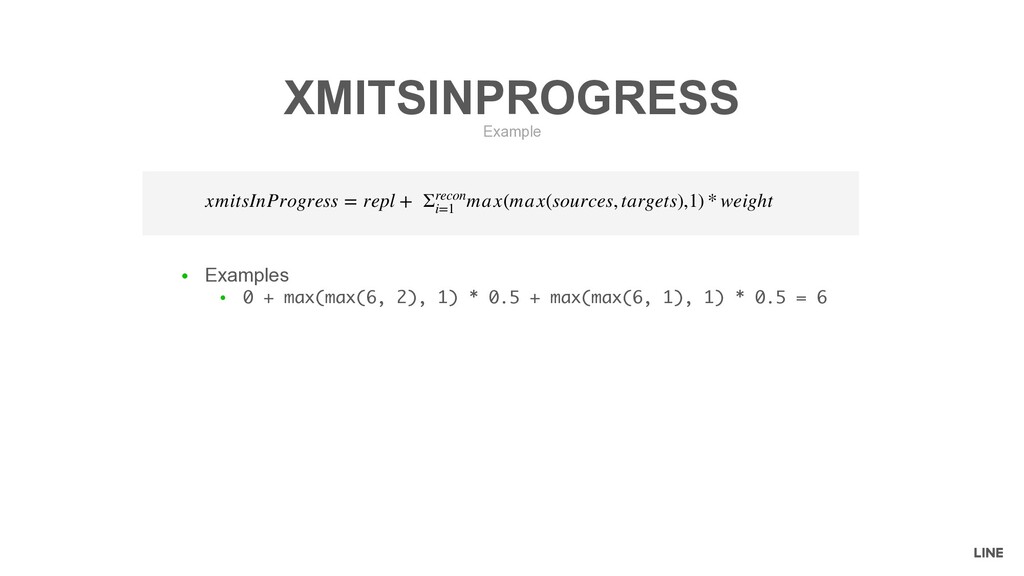
• Examples • 0 + max(max(6, 2), 1) * 0.5
+ max(max(6, 1), 1) * 0.5 = 6 Example XMITSINPROGRESS xmitsInProgress = repl + Σrecon i=1 max(max(sources, targets),1) * weight -
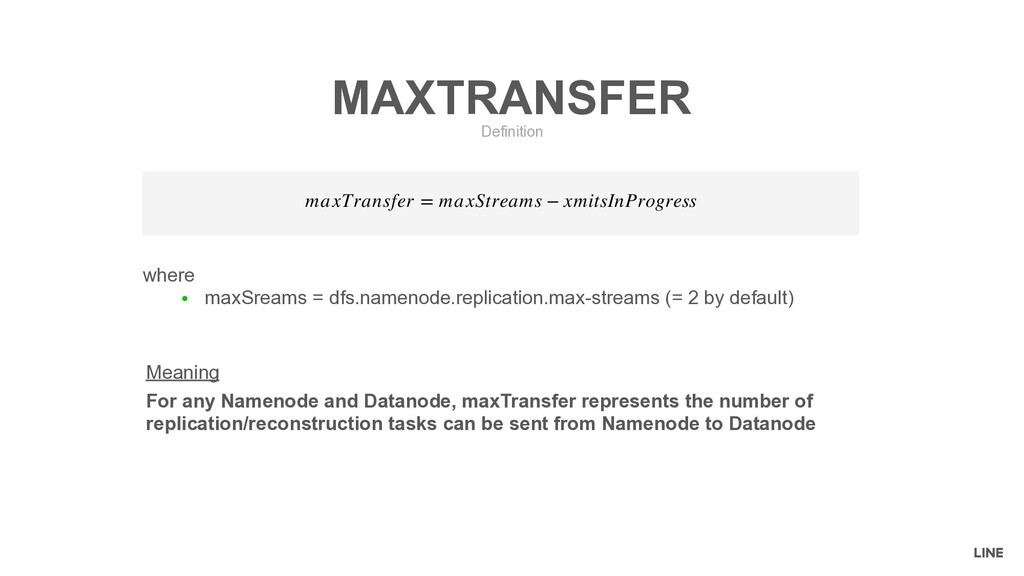
where • maxSreams = dfs.namenode.replication.max-streams (= 2 by default) Definition
MAXTRANSFER maxTransfer = maxStreams − xmitsInProgress Meaning For any Namenode and Datanode, maxTransfer represents the number of replication/reconstruction tasks can be sent from Namenode to Datanode -
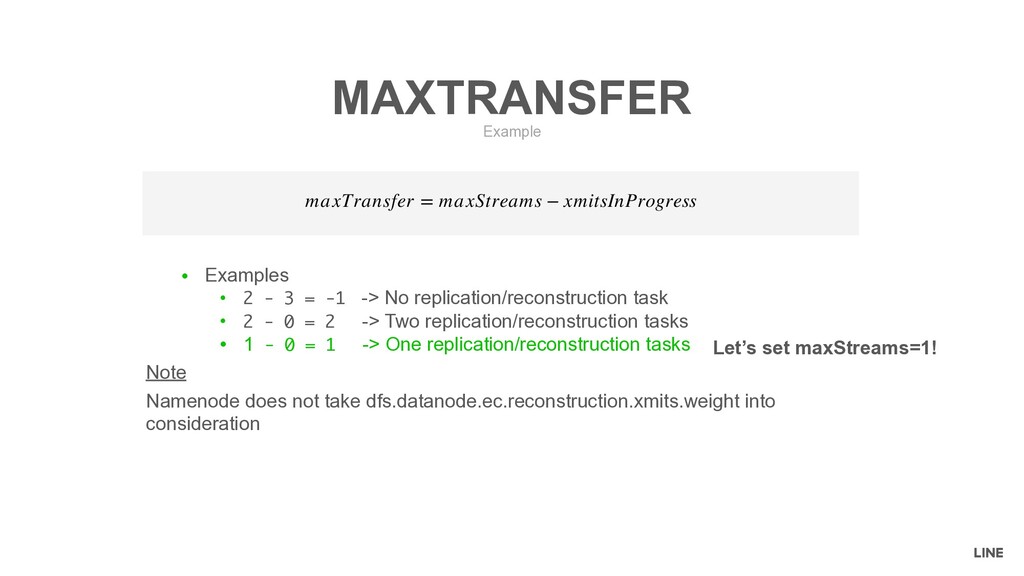
• Examples • 2 - 3 = -1 -> No
replication/reconstruction task • 2 - 0 = 2 -> Two replication/reconstruction tasks • 1 - 0 = 1 -> One replication/reconstruction tasks Example MAXTRANSFER maxTransfer = maxStreams − xmitsInProgress Note Namenode does not take dfs.datanode.ec.reconstruction.xmits.weight into consideration Let’s set maxStreams=1! -
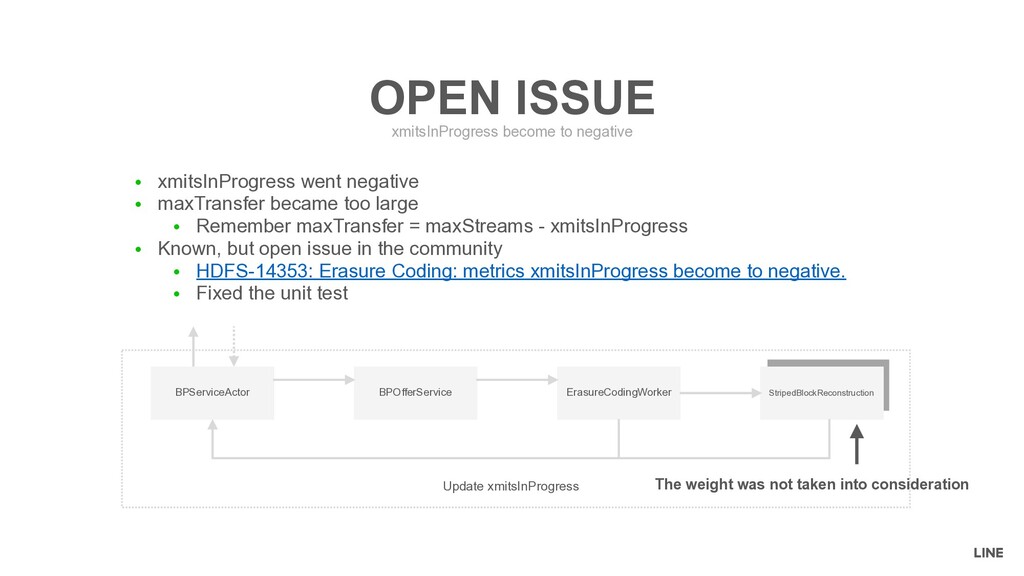
• xmitsInProgress went negative • maxTransfer became too large •
Remember maxTransfer = maxStreams - xmitsInProgress • Known, but open issue in the community • HDFS-14353: Erasure Coding: metrics xmitsInProgress become to negative. • Fixed the unit test xmitsInProgress become to negative OPEN ISSUE StripedBlockReconstruction BPServiceActor BPOfferService ErasureCodingWorker StripedBlockReconstruction The weight was not taken into consideration Update xmitsInProgress -
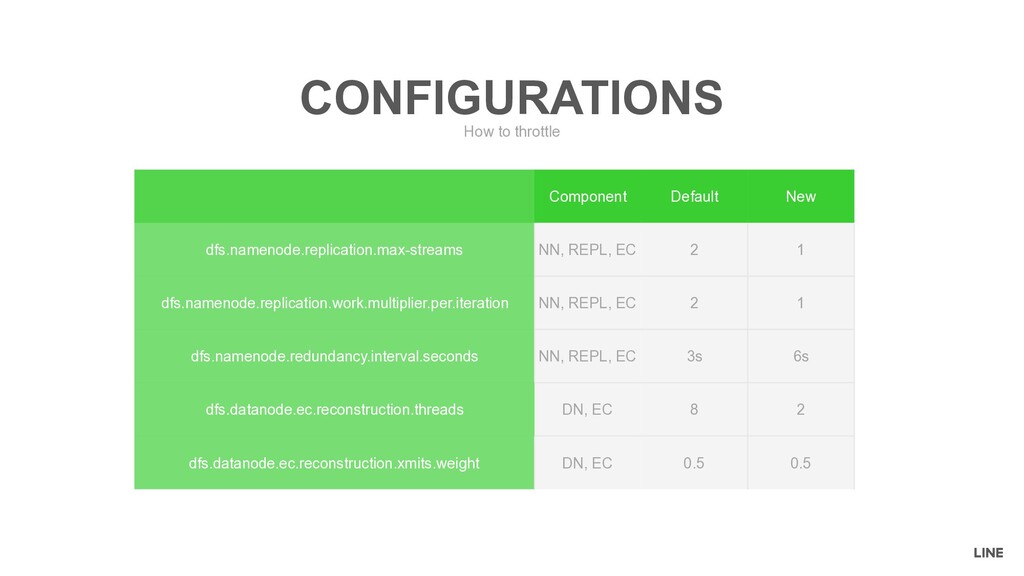
Component Default New dfs.namenode.replication.max-streams NN, REPL, EC 2 1 dfs.namenode.replication.work.multiplier.per.iteration
NN, REPL, EC 2 1 dfs.namenode.redundancy.interval.seconds NN, REPL, EC 3s 6s dfs.datanode.ec.reconstruction.threads DN, EC 8 2 dfs.datanode.ec.reconstruction.xmits.weight DN, EC 0.5 0.5 How to throttle CONFIGURATIONS -
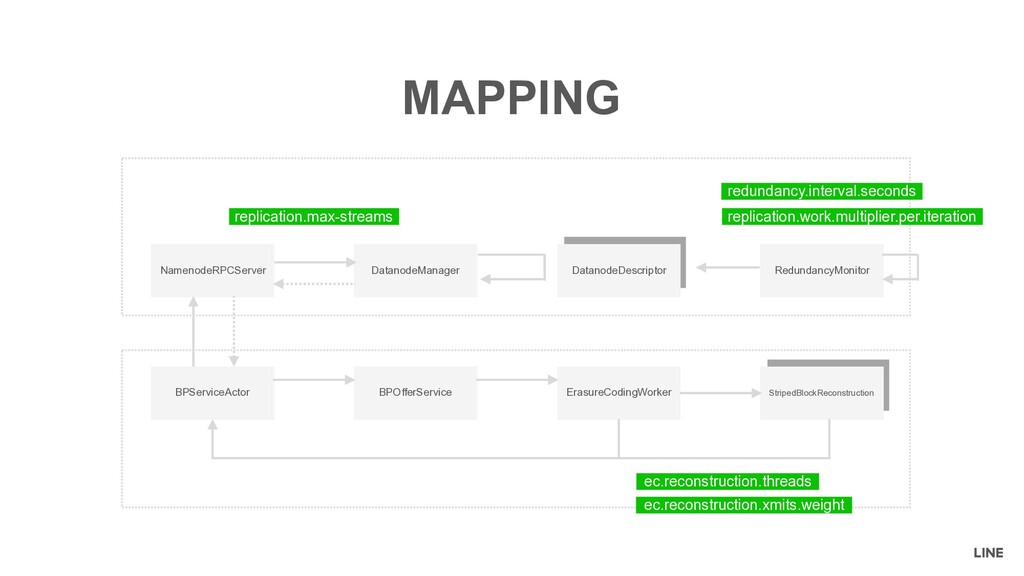
StripedBlockReconstruction DatanodeDescriptor MAPPING NamenodeRPCServer BPServiceActor DatanodeManager BPOfferService ErasureCodingWorker StripedBlockReconstruction DatanodeDescriptor
RedundancyMonitor redundancy.interval.seconds replication.work.multiplier.per.iteration replication.max-streams ec.reconstruction.threads ec.reconstruction.xmits.weight -
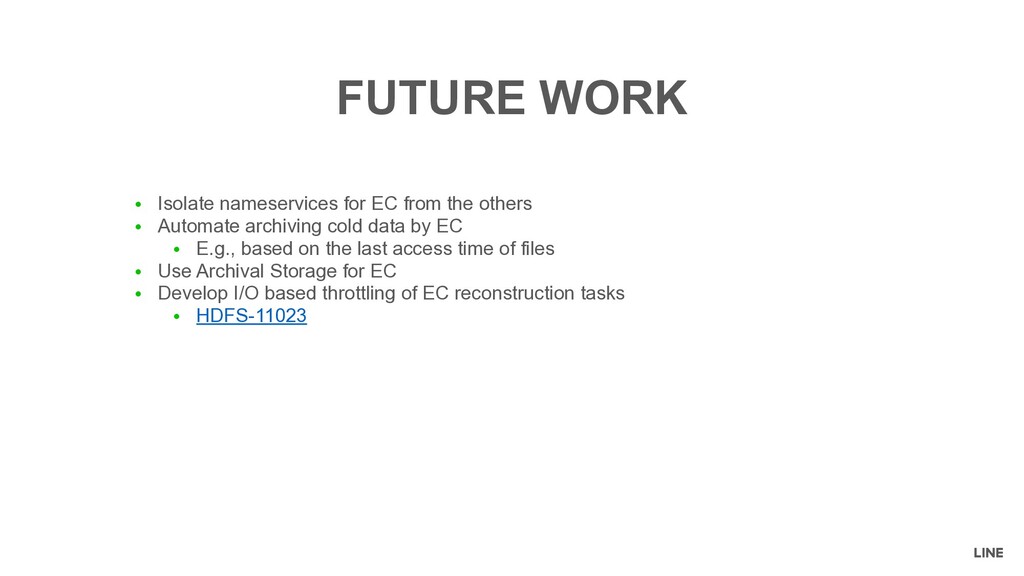
• Isolate nameservices for EC from the others • Automate
archiving cold data by EC • E.g., based on the last access time of files • Use Archival Storage for EC • Develop I/O based throttling of EC reconstruction tasks • HDFS-11023 FUTURE WORK -
• Blog • Cloudera: HDFS Erasure Coding in Production •
Yahoo!: HDFS Erasure CodingͷհͱYahoo! JAPANʹ͓͚Δӡ༻ࣄྫ • Book • Architecting Modern Data Platforms • Designing Data-Intensive Applications REFERENCE