Share
Embed
AutoML in Clova Chatbot Builder Framework
by Jaewon Lee / Penny Sun @LINE TECHPULSE 2019 https://techpulse.line.me/
LINE Developers Taiwan PRO
December 04, 2019
Transcript
70 slides
-
Clova Chatbot Builder Framework > Jaewon Lee / NAVER Clova
Data Scientist > Penny Sun/ LINE Taiwan Data Engineer -
Agenda > Chatbot ?? Chatbot !! > Clova Chatbot Builder
Framework > What is in our Chatbot Builder Framework? > How can we provide a high performance Chatbot? > Chinese Chatbot Use Case -
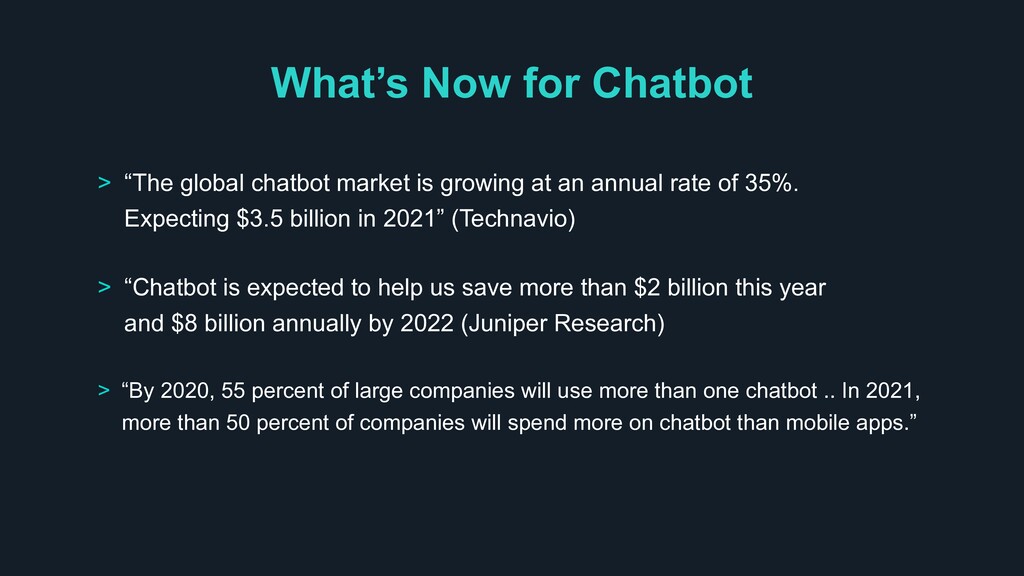
What’s Now for Chatbot > “The global chatbot market is
growing at an annual rate of 35%. Expecting $3.5 billion in 2021” (Technavio) > “By 2020, 55 percent of large companies will use more than one chatbot .. In 2021, more than 50 percent of companies will spend more on chatbot than mobile apps.” > “Chatbot is expected to help us save more than $2 billion this year and $8 billion annually by 2022 (Juniper Research) -
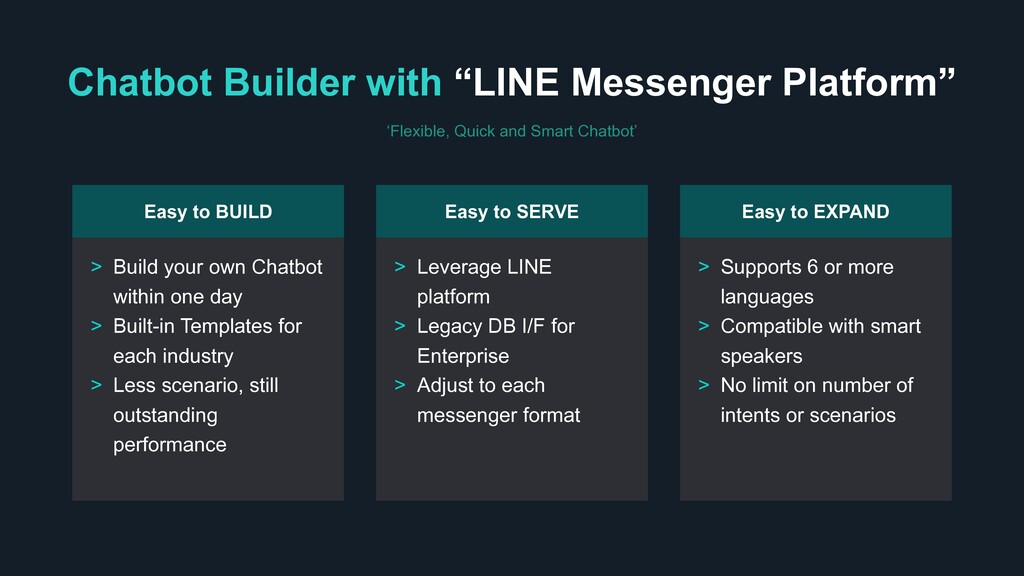
Chatbot Builder with “LINE Messenger Platform” ‘Flexible, Quick and Smart
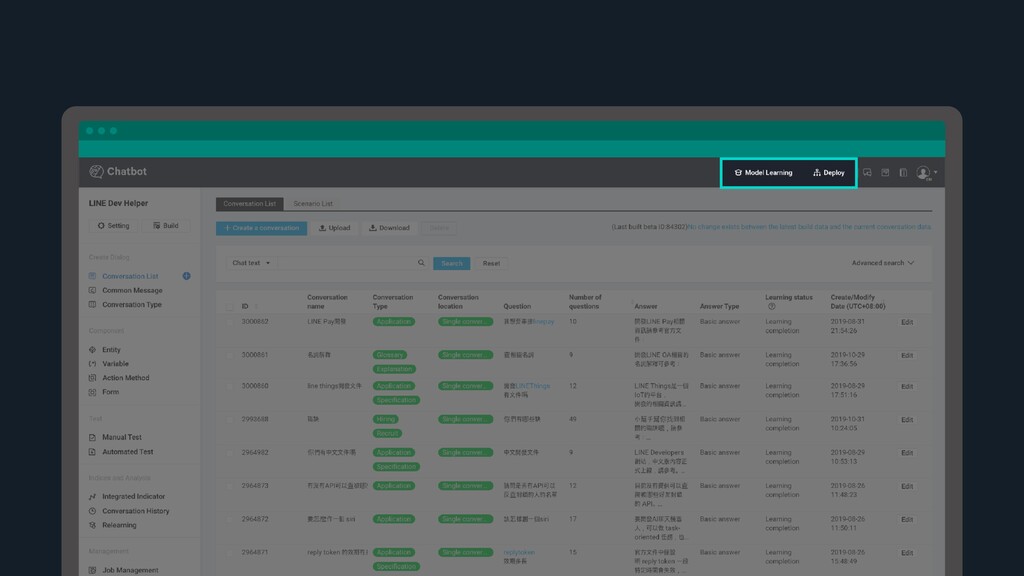
Chatbot’ Easy to BUILD > Build your own Chatbot within one day > Built-in Templates for each industry > Less scenario, still outstanding performance Easy to SERVE > Leverage LINE platform > Legacy DB I/F for Enterprise > Adjust to each messenger format Easy to EXPAND > Supports 6 or more languages > Compatible with smart speakers > No limit on number of intents or scenarios -
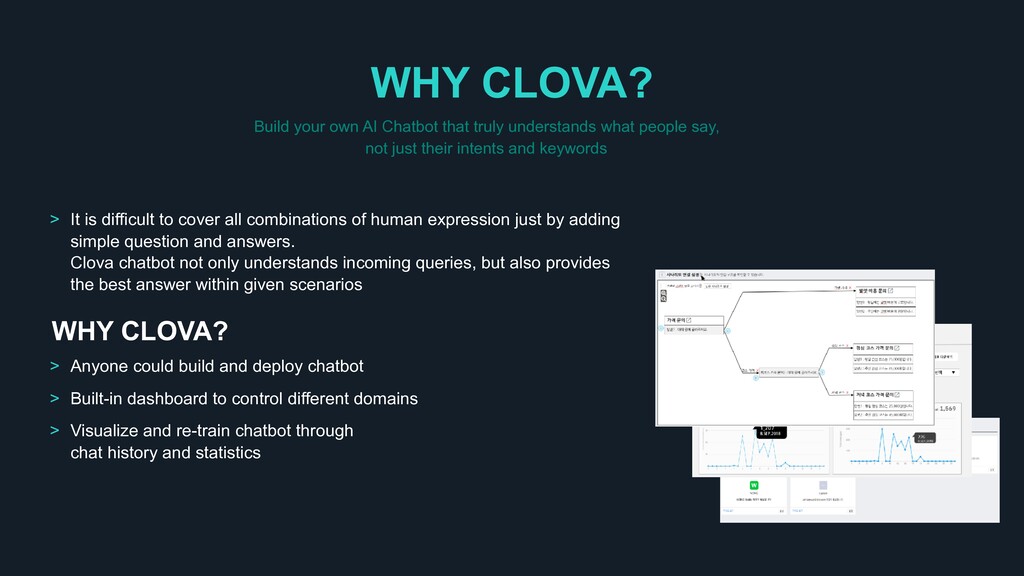
WHY CLOVA? > Anyone could build and deploy chatbot >
Built-in dashboard to control different domains > Visualize and re-train chatbot through chat history and statistics WHY CLOVA? Build your own AI Chatbot that truly understands what people say, not just their intents and keywords > It is difficult to cover all combinations of human expression just by adding simple question and answers. Clova chatbot not only understands incoming queries, but also provides the best answer within given scenarios -
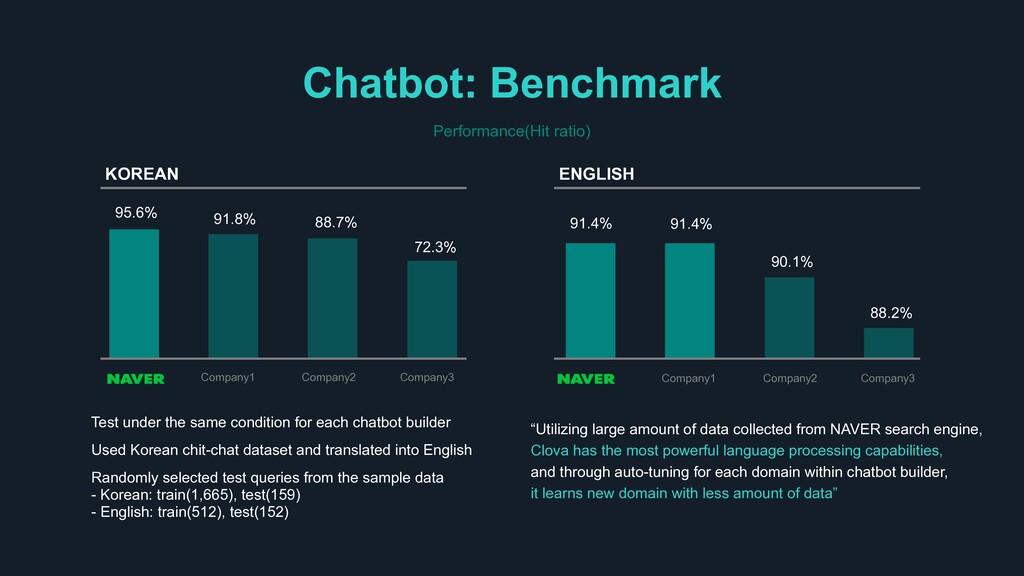
Chatbot: Benchmark Performance(Hit ratio) Test under the same condition for
each chatbot builder Used Korean chit-chat dataset and translated into English Randomly selected test queries from the sample data - Korean: train(1,665), test(159) - English: train(512), test(152) 95.6% 91.8% 88.7% 72.3% KOREAN 91.4% 90.1% 88.2% ENGLISH 91.4% “Utilizing large amount of data collected from NAVER search engine, Clova has the most powerful language processing capabilities, and through auto-tuning for each domain within chatbot builder, it learns new domain with less amount of data” Company1 Company2 Company3 Company1 Company2 Company3 -
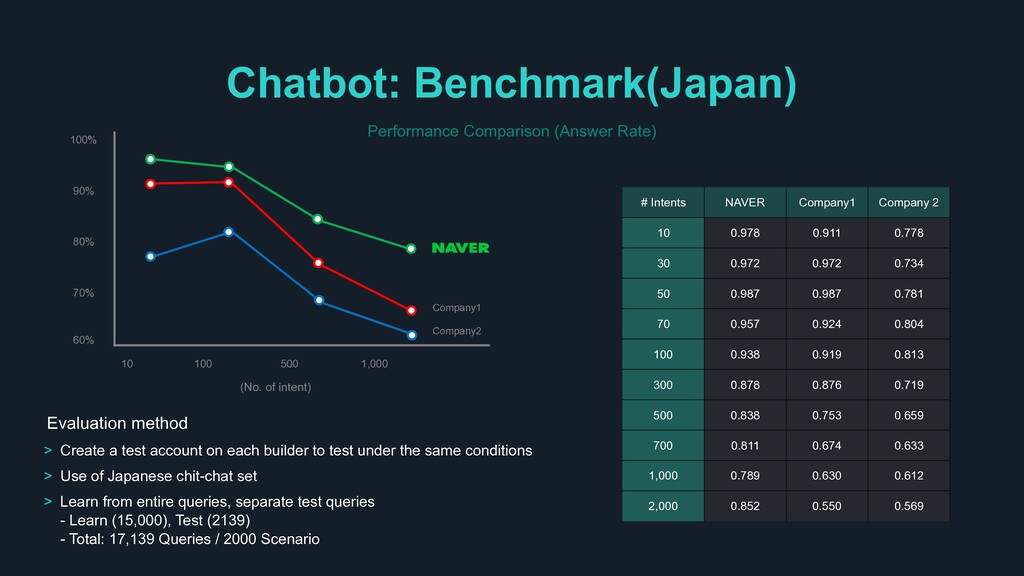
Chatbot: Benchmark(Japan) Performance Comparison (Answer Rate) Evaluation method > Create
a test account on each builder to test under the same conditions > Use of Japanese chit-chat set > Learn from entire queries, separate test queries - Learn (15,000), Test (2139) - Total: 17,139 Queries / 2000 Scenario # Intents NAVER Company1 Company 2 10 0.978 0.911 0.778 30 0.972 0.972 0.734 50 0.987 0.987 0.781 70 0.957 0.924 0.804 100 0.938 0.919 0.813 300 0.878 0.876 0.719 500 0.838 0.753 0.659 700 0.811 0.674 0.633 1,000 0.789 0.630 0.612 2,000 0.852 0.550 0.569 (No. of intent) 10 100 500 1,000 70% 80% 90% 100% 60% Company1 Company2 -
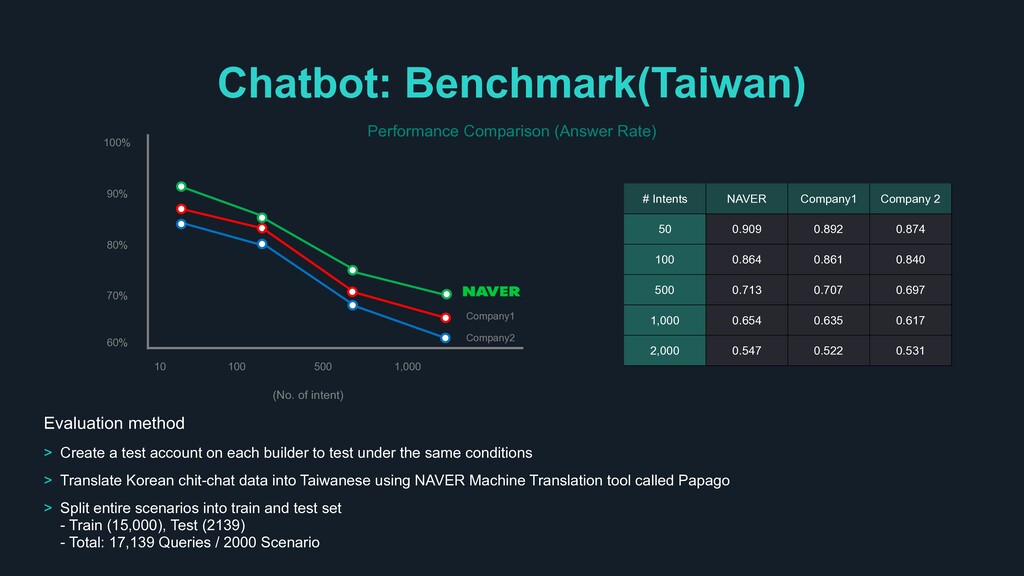
Chatbot: Benchmark(Taiwan) # Intents NAVER Company1 Company 2 50 0.909
0.892 0.874 100 0.864 0.861 0.840 500 0.713 0.707 0.697 1,000 0.654 0.635 0.617 2,000 0.547 0.522 0.531 Evaluation method > Create a test account on each builder to test under the same conditions > Translate Korean chit-chat data into Taiwanese using NAVER Machine Translation tool called Papago > Split entire scenarios into train and test set - Train (15,000), Test (2139) - Total: 17,139 Queries / 2000 Scenario (No. of intent) 10 100 500 1,000 70% 80% 90% 100% 60% Company1 Company2 Performance Comparison (Answer Rate) -
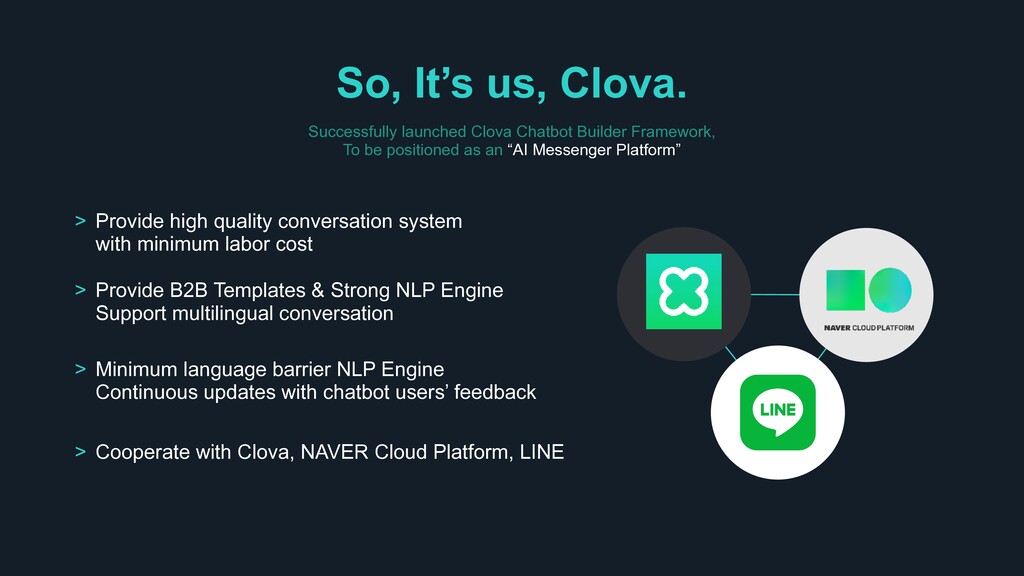
So, It’s us, Clova. Successfully launched Clova Chatbot Builder Framework,
To be positioned as an “AI Messenger Platform” > Minimum language barrier NLP Engine Continuous updates with chatbot users’ feedback > Cooperate with Clova, NAVER Cloud Platform, LINE > Provide B2B Templates & Strong NLP Engine Support multilingual conversation > Provide high quality conversation system with minimum labor cost -
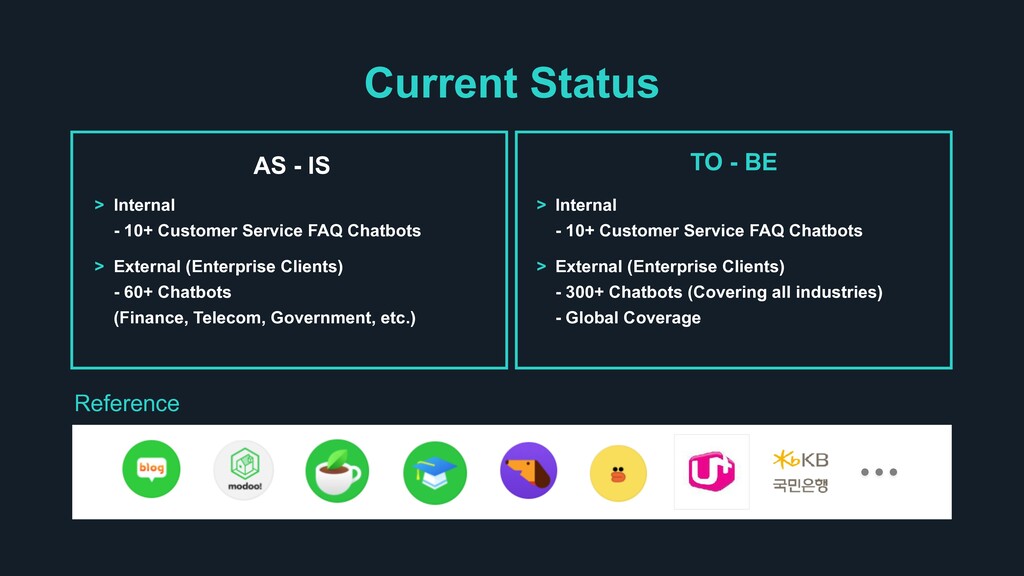
Current Status AS - IS > Internal - 10+ Customer
Service FAQ Chatbots > External (Enterprise Clients) - 60+ Chatbots (Finance, Telecom, Government, etc.) > Internal - 10+ Customer Service FAQ Chatbots > External (Enterprise Clients) - 300+ Chatbots (Covering all industries) - Global Coverage TO - BE Reference -
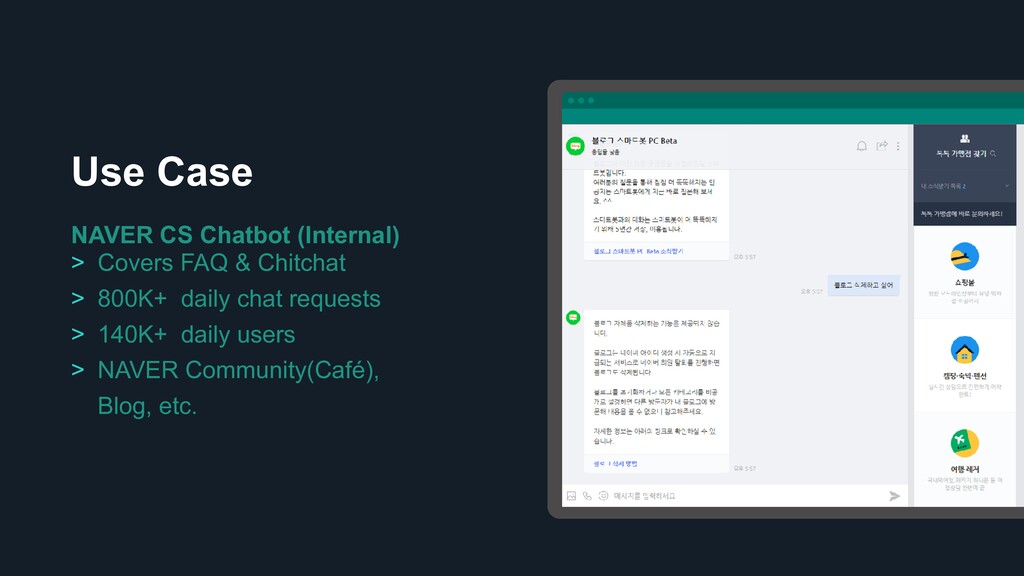
Ƃ Use Case NAVER CS Chatbot (Internal) > Covers FAQ
& Chitchat > 800K+ daily chat requests > 140K+ daily users > NAVER Community(Café), Blog, etc. -
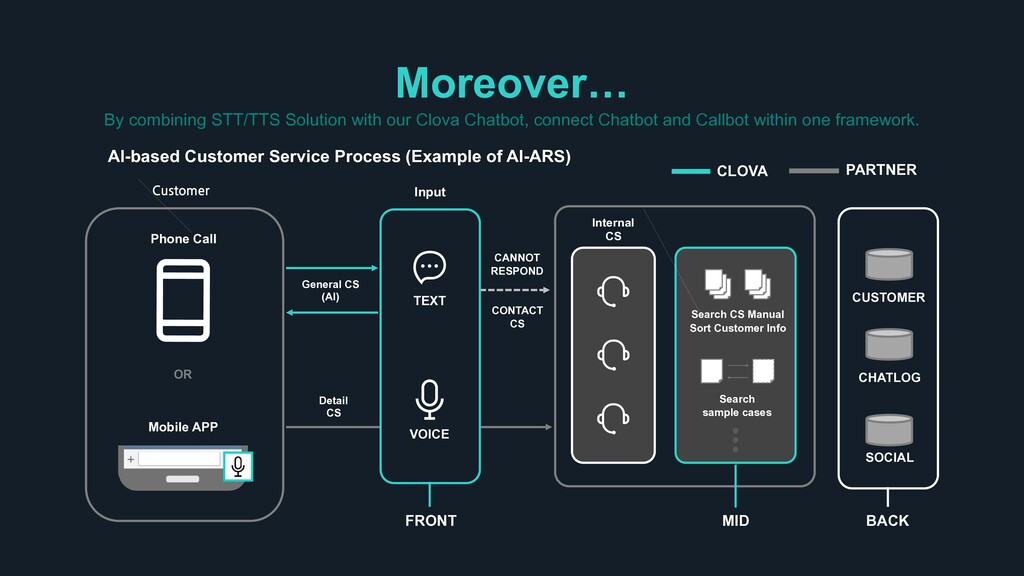
Moreover… By combining STT/TTS Solution with our Clova Chatbot, connect
Chatbot and Callbot within one framework. OR Phone Call Mobile APP , CA: CLOVA PARTNER CUSTOMER CHATLOG SOCIAL Search CS Manual Sort Customer Info Search sample cases A A’ Internal CS MID BACK General CS (AI) Detail CS Input TEXT VOICE FRONT CANNOT RESPOND CONTACT CS AI-based Customer Service Process (Example of AI-ARS) -
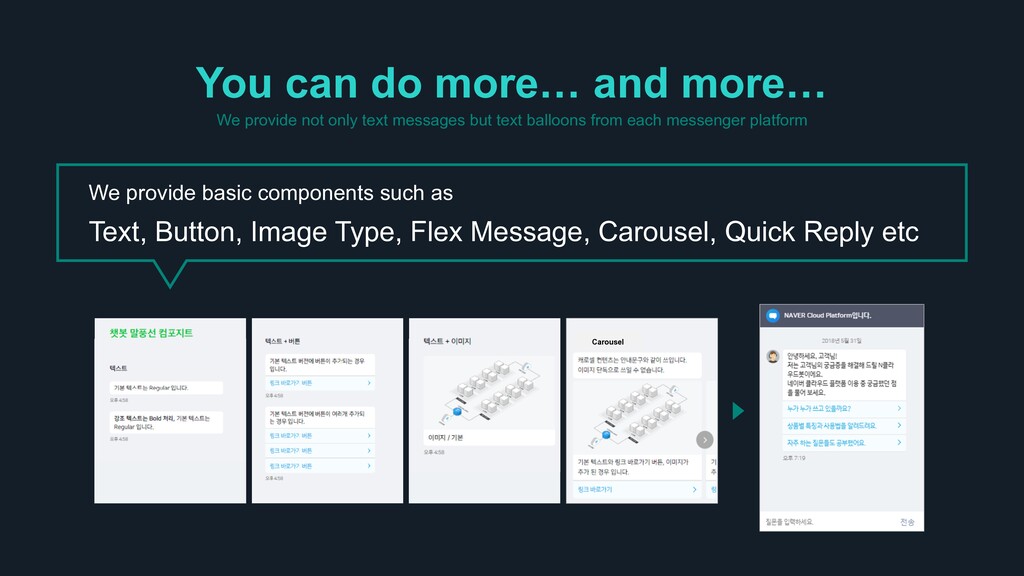
You can do more… We provide various functions with conversational
components 1. Use External API to provide answers ${ActionMethod} Answer : Today’s weather in Taipei is ${weather} Example : ${Weather} = http://weather.com?location=#{Bangkok} 2. Provide Mutiple-Choice Type or Short Answer Type ${Form} 3. Complicated customer order & Slot filling to complete such actions from each customer ${Task} , C 2: : , CB 2:C CB : , C : $ 2 BB 2: : , : : : $ 2 BB 2 C N : : ) 2 B ?C? -
Carousel You can do more… and more… We provide not
only text messages but text balloons from each messenger platform We provide basic components such as Text, Button, Image Type, Flex Message, Carousel, Quick Reply etc -
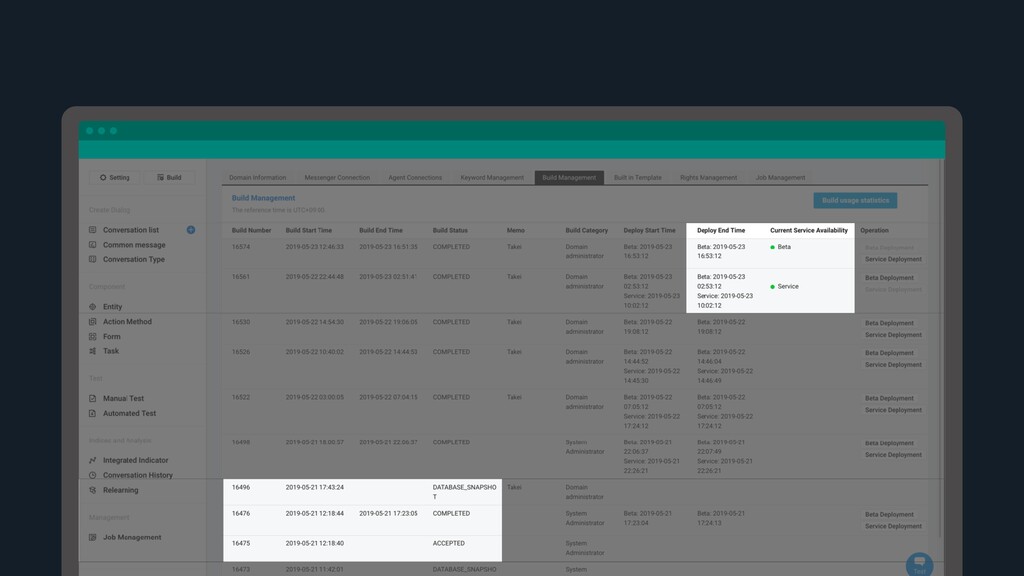
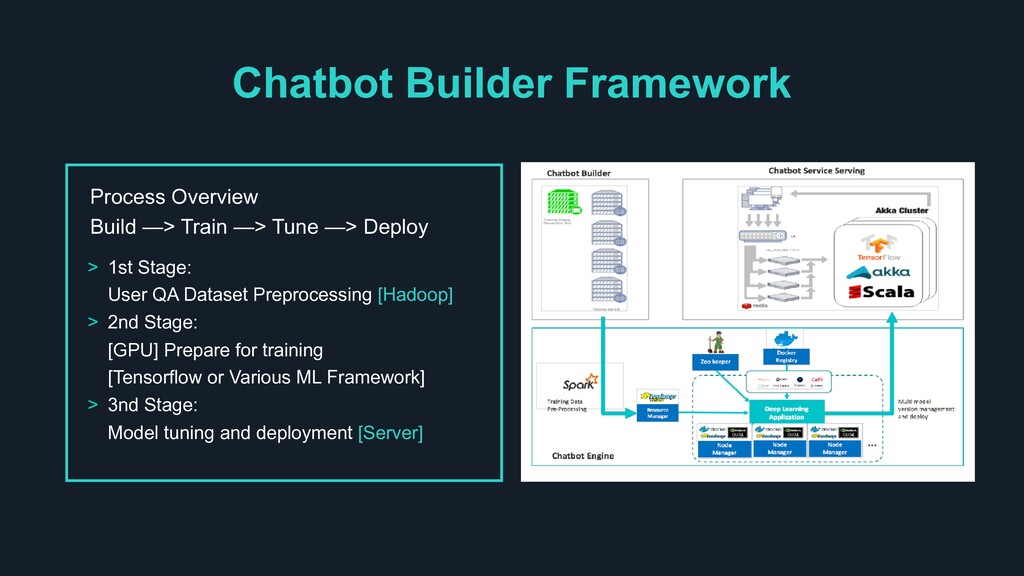
Process Overview Build —> Train —> Tune —> Deploy >
1st Stage: User QA Dataset Preprocessing [Hadoop] > 2nd Stage: [GPU] Prepare for training [Tensorflow or Various ML Framework] > 3nd Stage: Model tuning and deployment [Server] Chatbot Builder Framework -
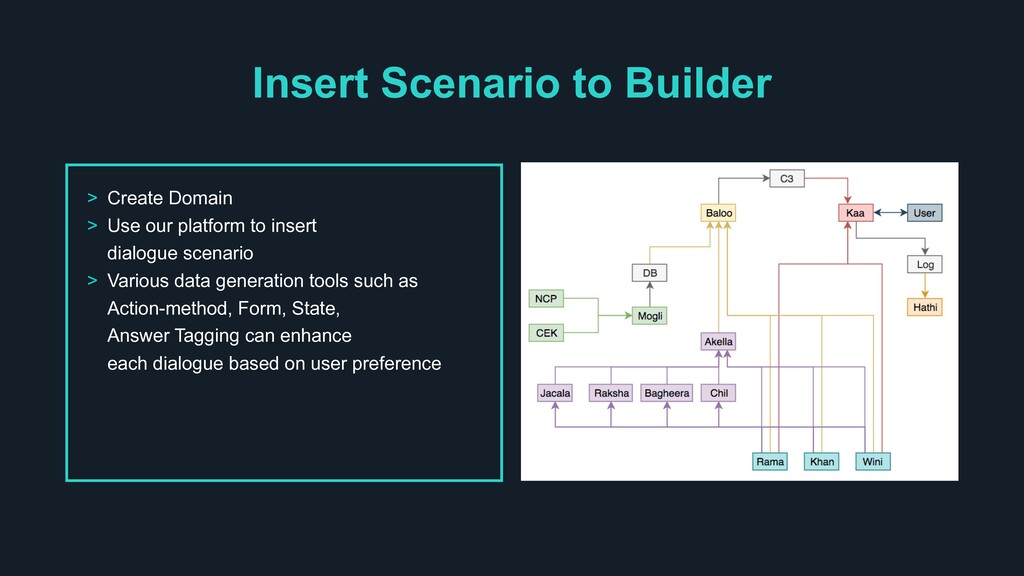
Insert Scenario to Builder > Create Domain > Use our
platform to insert dialogue scenario > Various data generation tools such as Action-method, Form, State, Answer Tagging can enhance each dialogue based on user preference -
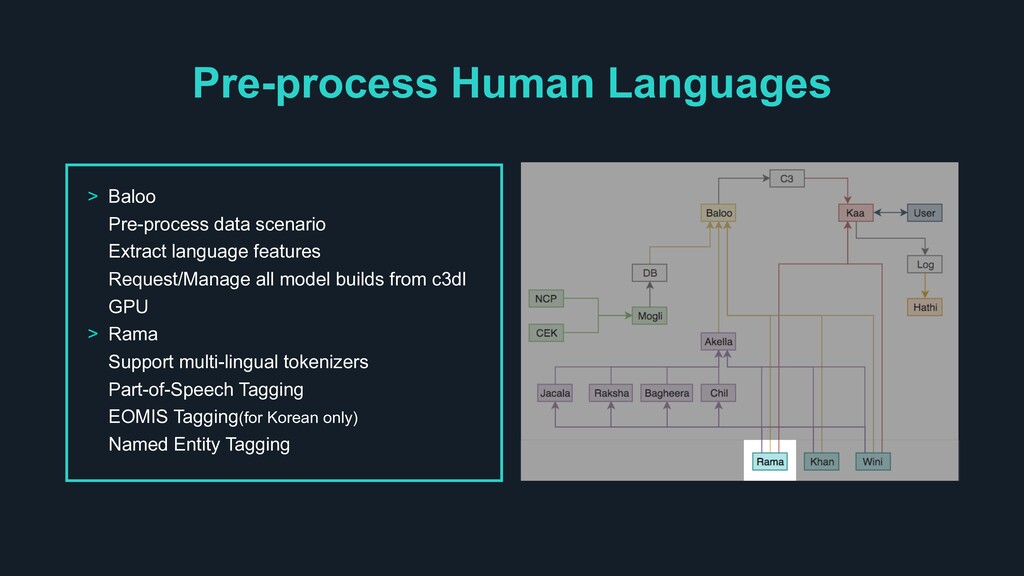
Pre-process Human Languages > Baloo Pre-process data scenario Extract language
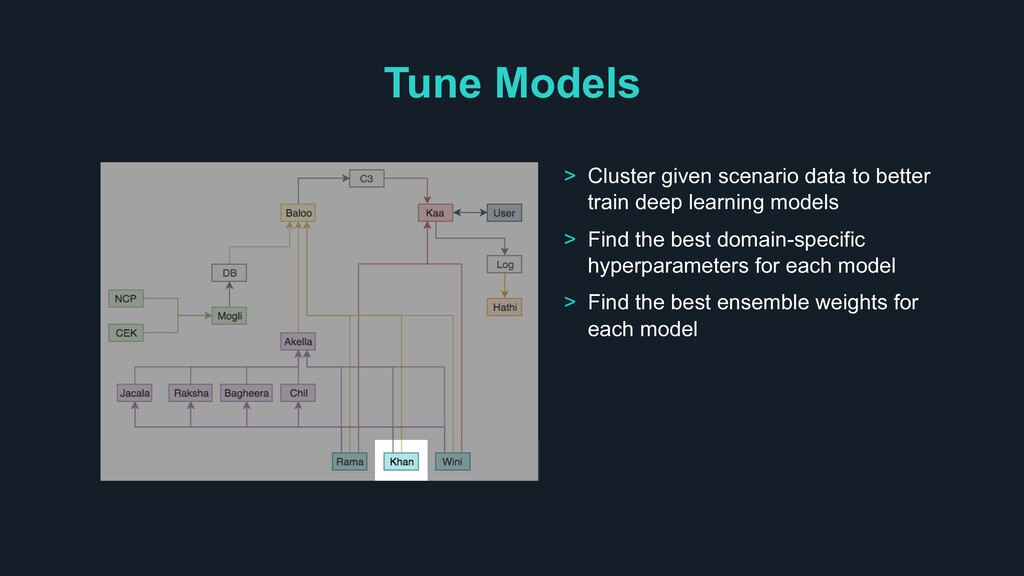
features Request/Manage all model builds from c3dl GPU > Rama Support multi-lingual tokenizers Part-of-Speech Tagging EOMIS Tagging(for Korean only) Named Entity Tagging -
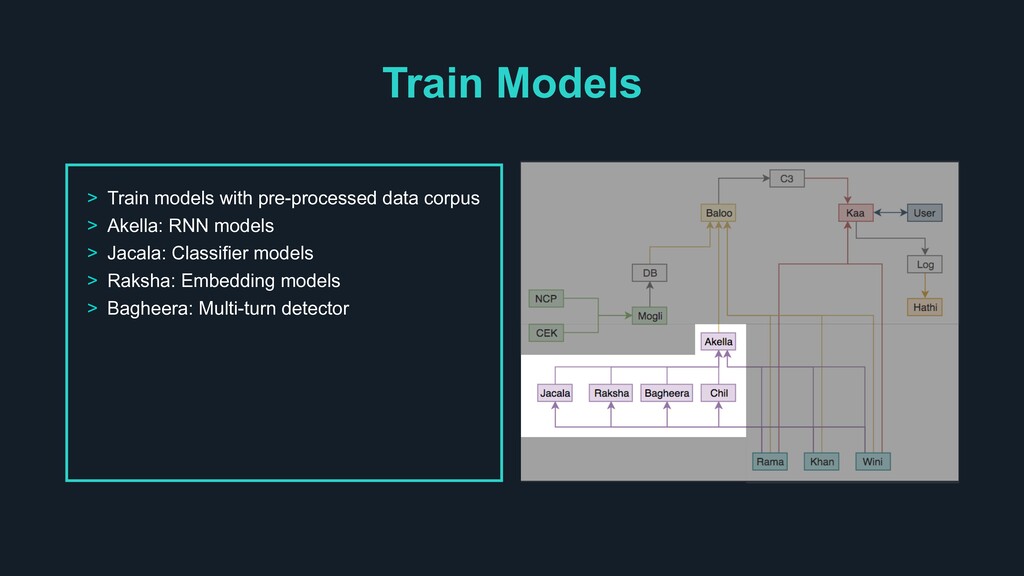
Train Models > Train models with pre-processed data corpus >
Akella: RNN models > Jacala: Classifier models > Raksha: Embedding models > Bagheera: Multi-turn detector -
Tune Models > Cluster given scenario data to better
train deep learning models > Find the best domain-specific hyperparameters for each model > Find the best ensemble weights for each model -
Serve Chatbot Engine > Provide the most appropriate ensemble answer
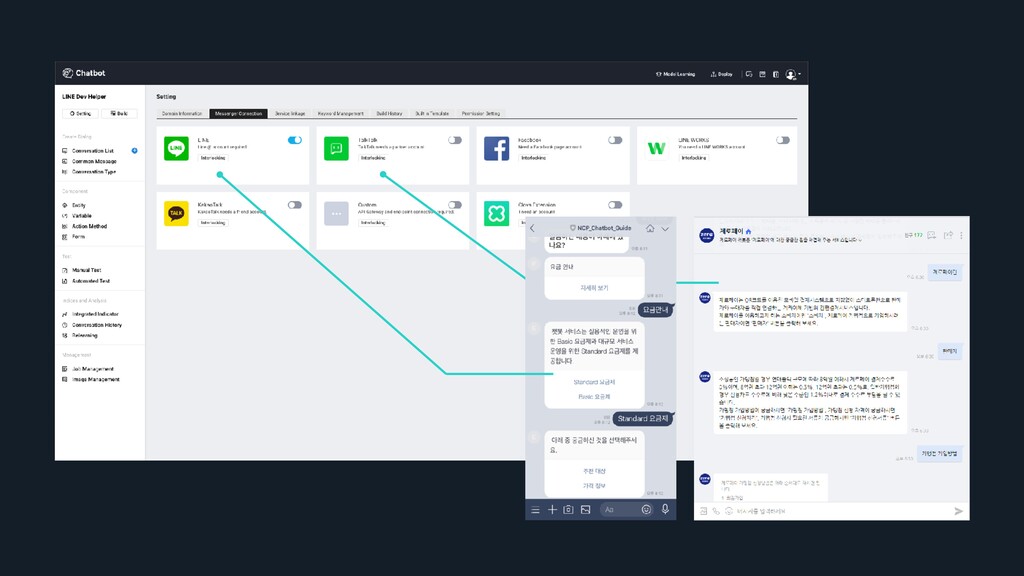
to one specific platform > Serve multiple messenger platforms such as LINE, facebook messenger, etc. > Use Akka Sharding to provide non-stop service by communicating with each server -
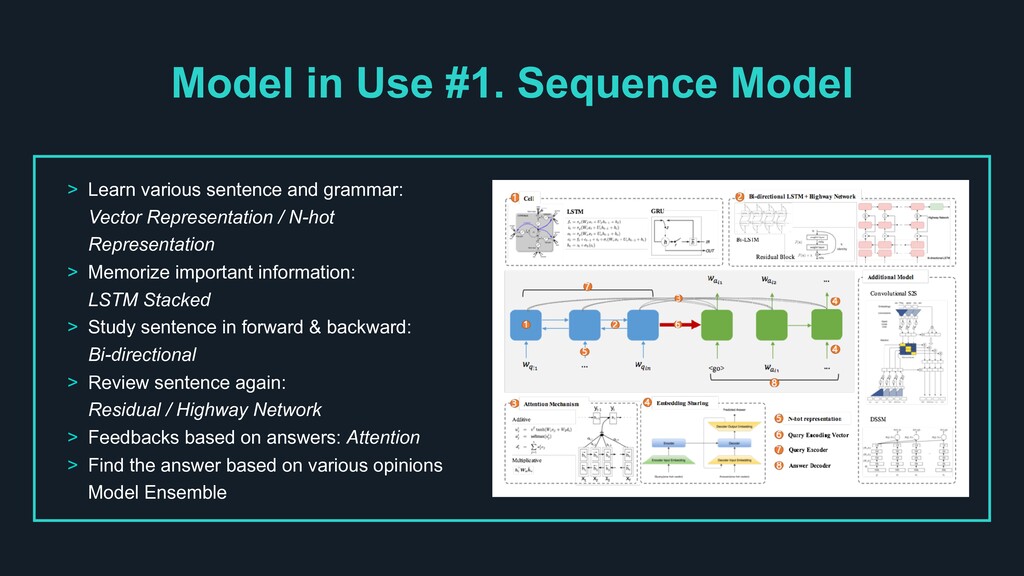
Model in Use #1. Sequence Model > Learn various sentence
and grammar: Vector Representation / N-hot Representation > Memorize important information: LSTM Stacked > Study sentence in forward & backward: Bi-directional > Review sentence again: Residual / Highway Network > Feedbacks based on answers: Attention > Find the answer based on various opinions Model Ensemble -
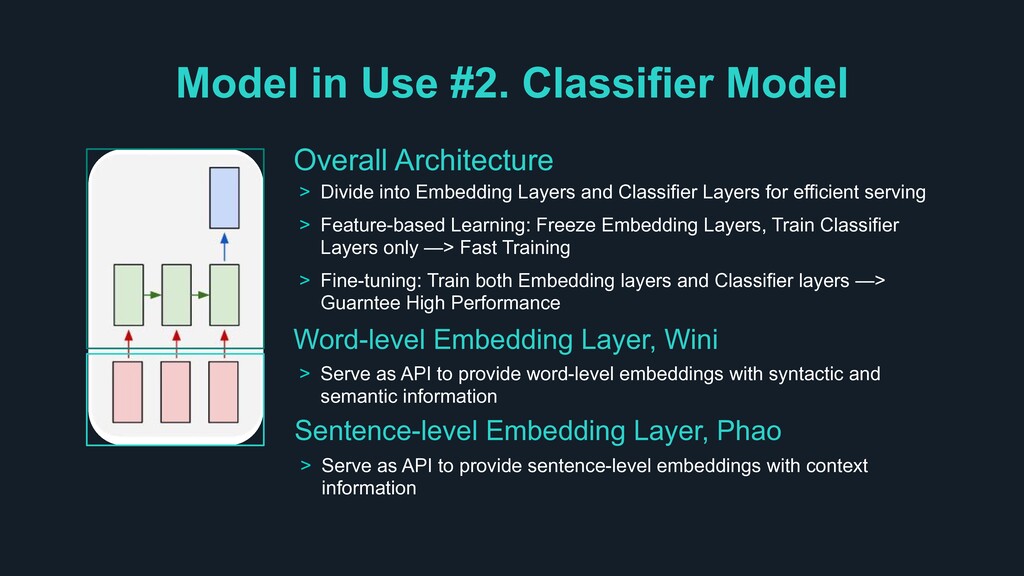
Model in Use #2. Classifier Model Word-level Embedding Layer, Wini
> Serve as API to provide word-level embeddings with syntactic and semantic information Overall Architecture > Divide into Embedding Layers and Classifier Layers for efficient serving > Feature-based Learning: Freeze Embedding Layers, Train Classifier Layers only —> Fast Training > Fine-tuning: Train both Embedding layers and Classifier layers —> Guarntee High Performance Sentence-level Embedding Layer, Phao > Serve as API to provide sentence-level embeddings with context information -
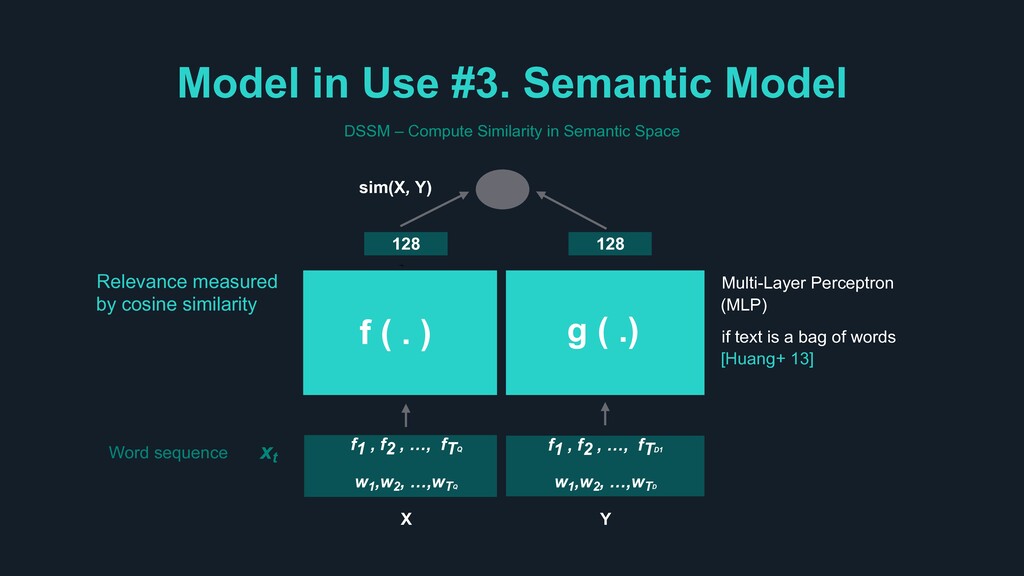
Model in Use #3. Semantic Model xt Word sequence Relevance
measured by cosine similarity f1 , f2 , …, fTQ w1,w2, …,wTQ 128 sim(X, Y) f1 , f2 , …, fTD1 w1,w2, …,wTD 128 X Y g ( .) f ( . ) Multi-Layer Perceptron (MLP) if text is a bag of words [Huang+ 13] DSSM – Compute Similarity in Semantic Space -
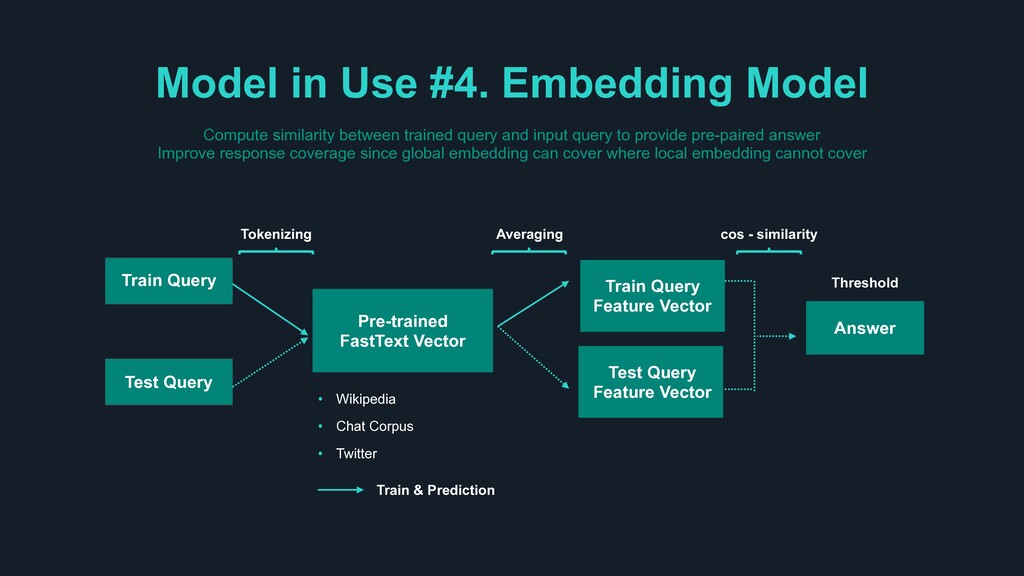
Model in Use #4. Embedding Model Pre-trained FastText Vector Train
Query Train Query Feature Vector Tokenizing Answer Test Query Test Query Feature Vector Averaging cos - similarity Train & Prediction Threshold • Wikipedia • Chat Corpus • Twitter Compute similarity between trained query and input query to provide pre-paired answer Improve response coverage since global embedding can cover where local embedding cannot cover -
In short Please recommend a nice restaurant around here -B
: : CB : I: : : BC B I: : C : C : B 1 , C N A:B CB -B :B : : : : CAA:B B : : B : # ,CA : A # C : C CI : B : C : AC : I: C B : : : C -B :B Please recommend a nice restaurant around here Please recommend a nice restaurant around here Please recommend a nice restaurant around here -
AI learn languages by… > Vector Representation • N-hot Embedding
Vectors from given data corpus • Global Embedding Vectors from Glove, fastText, TAPI, etc. > Locate all words/sentence properly within given vector space > N elements in N-dimensions represent characteristics of each sentence > The Closer embedding vectors, The More Semantically matching -
I can learn by myself?! Give me some time... Then
I can do better and I can do by myself !!! Embedding Vectors Are For Me To Understand Languages. -
Now Let’s Apply AutoML > The process of automated end-to-end
process by applying machine learning algorithms > AI-based solution to the ever-growing challenge by applying machine learning algorithms > Data Preprocessing, Algorithm Selection, Hyperparameter Optimization, etc. -
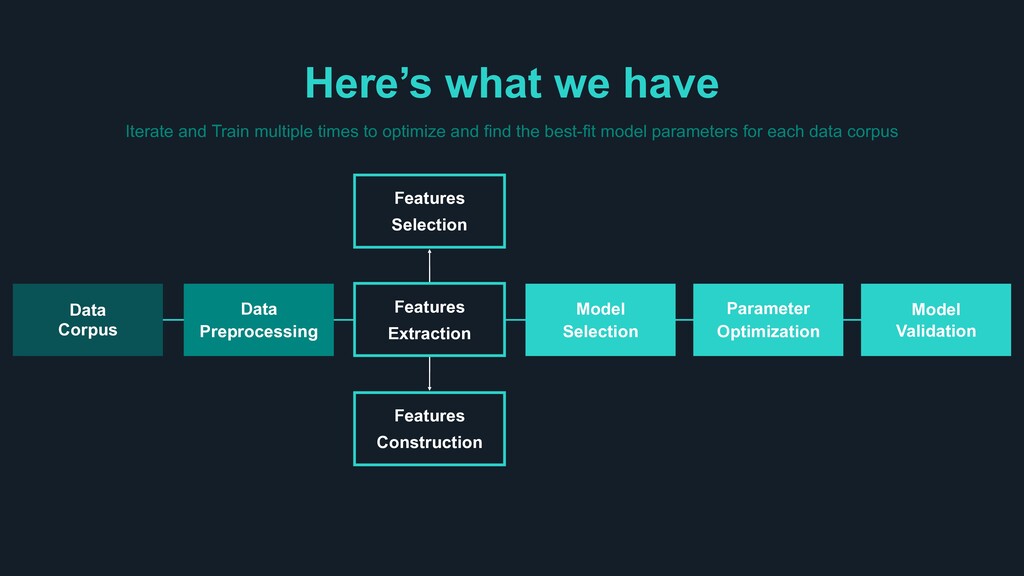
Here’s what we have Iterate and Train multiple times to
optimize and find the best-fit model parameters for each data corpus Model Selection Features Construction Features Selection Parameter Optimization Model Validation Features Extraction Data Corpus Data Preprocessing -
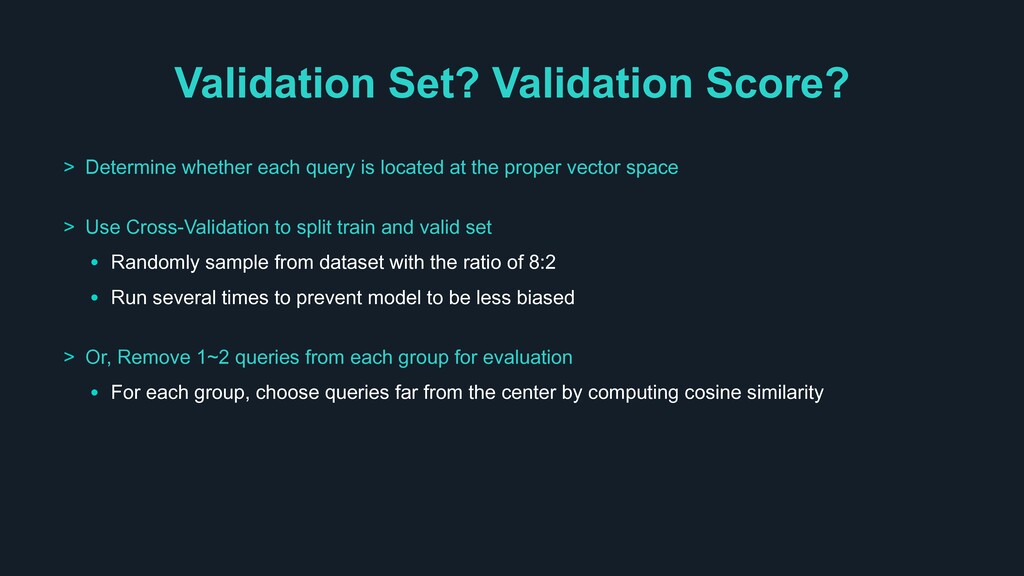
Validation Set? Validation Score? > Determine whether each query is
located at the proper vector space > Use Cross-Validation to split train and valid set • Randomly sample from dataset with the ratio of 8:2 • Run several times to prevent model to be less biased > Or, Remove 1~2 queries from each group for evaluation • For each group, choose queries far from the center by computing cosine similarity -
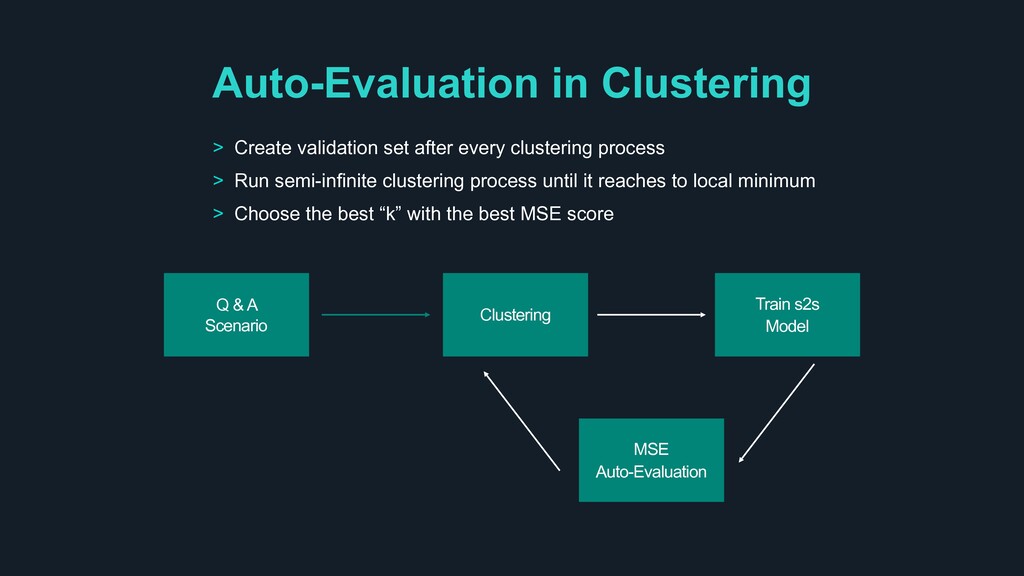
Auto-Evaluation in Clustering Q & A Scenario Clustering Train s2s
Model MSE Auto-Evaluation > Create validation set after every clustering process > Run semi-infinite clustering process until it reaches to local minimum > Choose the best “k” with the best MSE score -
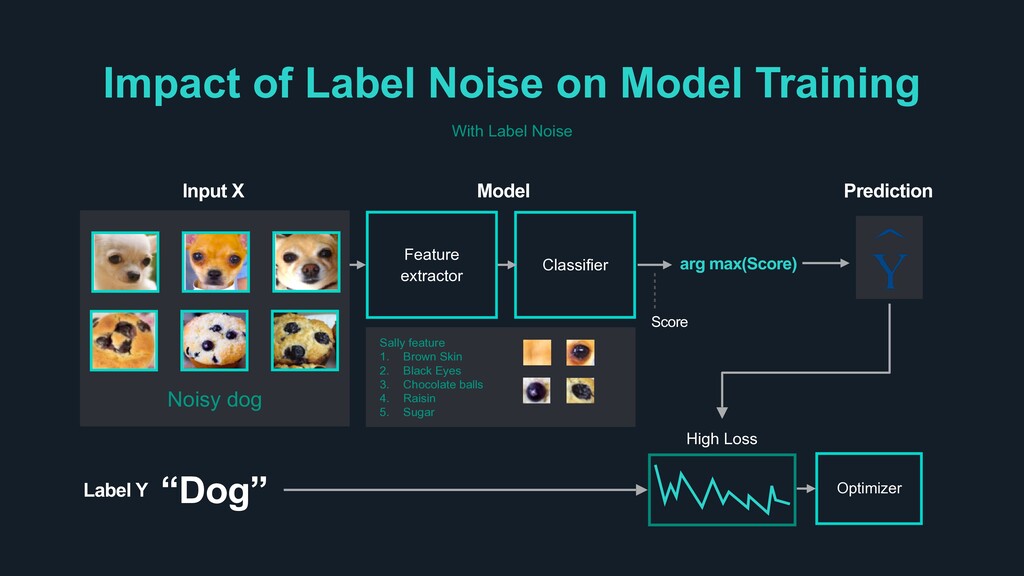
With Label Noise Impact of Label Noise on Model Training
Score Label Y “Dog” Input X Noisy dog arg max(Score) Prediction Feature extractor Classifier Model High Loss Optimizer Sally feature 1. Brown Skin 2. Black Eyes 3. Chocolate balls 4. Raisin 5. Sugar -
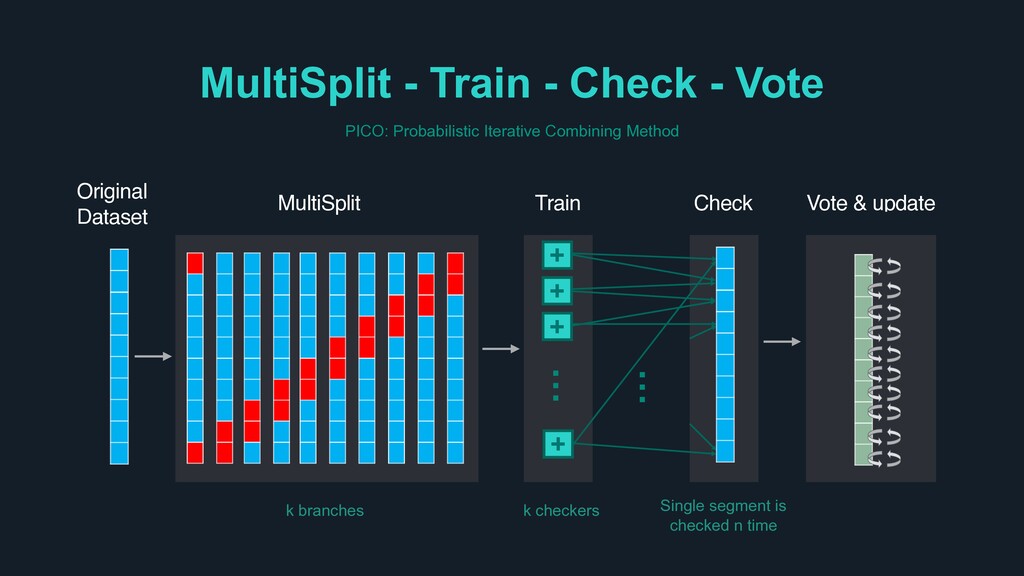
MultiSplit - Train - Check - Vote Train MultiSplit Original
Dataset … Check Vote & update k branches k checkers Single segment is checked n time + + + + … PICO: Probabilistic Iterative Combining Method -
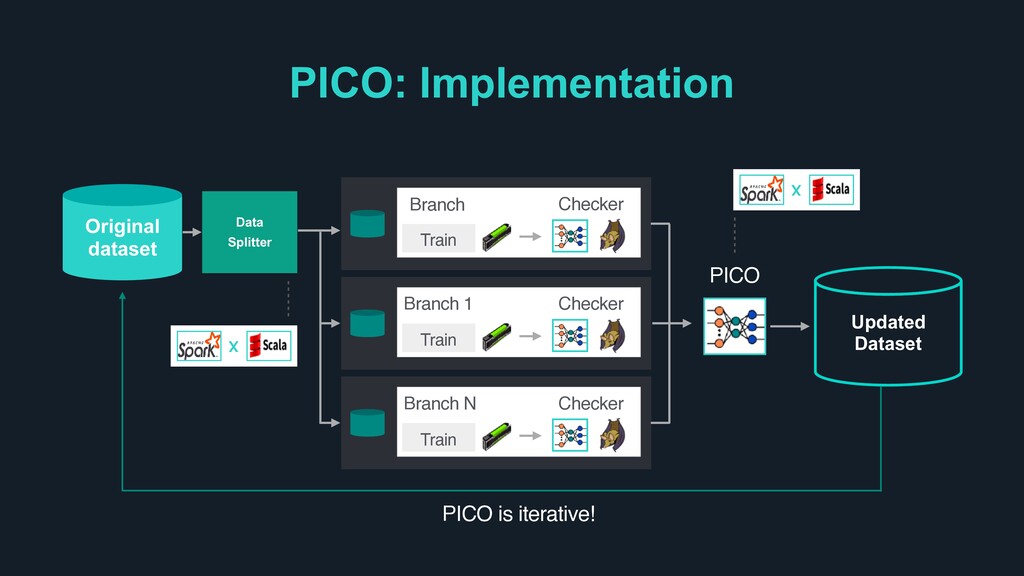
PICO: Implementation … Original dataset Data Splitter Train Checker Branch
Train Checker Branch 1 Train Checker Branch N PICO Updated Dataset PICO is iterative! x x -
Auto-Evaluation in Hyperparameter Tuning > Suppose each clusters are well-organized
by models > More Efficiently? More Accurately? • Coordinate Search, Random Search, Genetic Algorithms • Bayesian Hyper-parameter Optimization > Use Cosine Similarity, MSE or Hit Ratio for validation score -
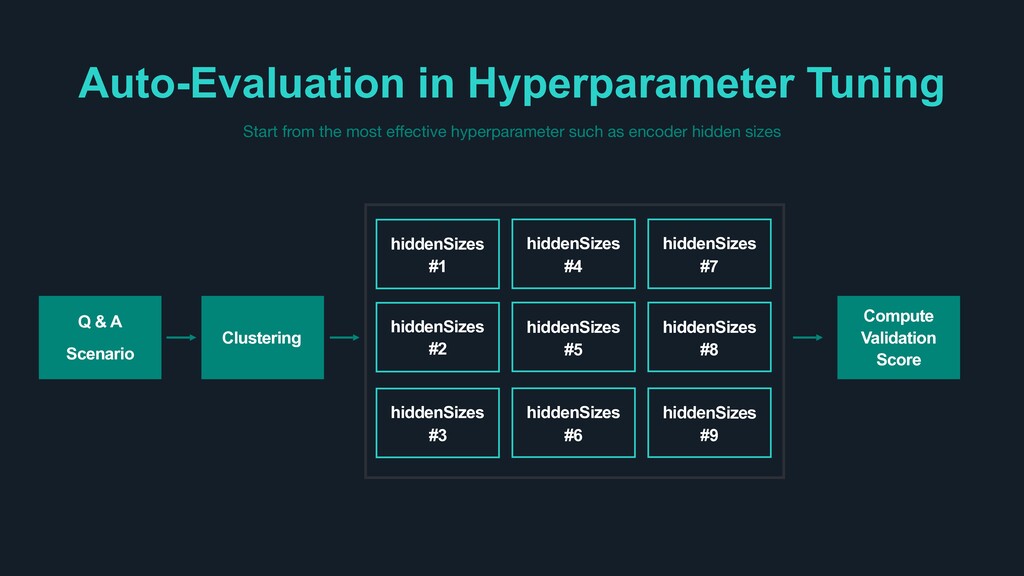
Auto-Evaluation in Hyperparameter Tuning Start from the most effective hyperparameter
such as encoder hidden sizes Q & A Scenario Clustering Compute Validation Score hiddenSizes #1 hiddenSizes #2 hiddenSizes #3 hiddenSizes #4 hiddenSizes #5 hiddenSizes #6 hiddenSizes #7 hiddenSizes #8 hiddenSizes #9 -
> Assume there exists a model that answers better than
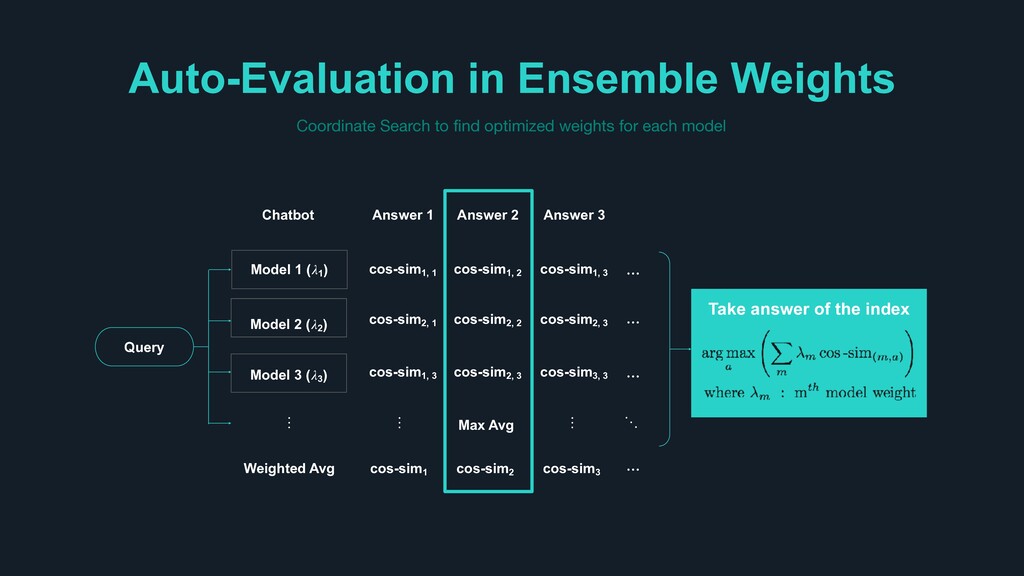
the others > For the given query, Response Selector provides final answer that maximizes the linear combination of each model’s prediction intensity such as cosine similarity and the accuracy of each model as the selection strength so-called ensemble weights Auto-Evaluation in Ensemble Weights -
Auto-Evaluation in Ensemble Weights Coordinate Search to find optimized weights
for each model Query Model 1 ( 1 ) Model 2 ( 2 ) Model 3 ( 3 ) ⋮ Answer 1 Answer 2 Answer 3 cos-sim1, 1 cos-sim1, 2 cos-sim1, 3 cos-sim3, 3 Chatbot Weighted Avg cos-sim1 cos-sim2 cos-sim3 ⋮ ⋮ ꔇ ꔇ ꔇ ꔇ ⋱ Take answer of the index Max Avg cos-sim2, 1 cos-sim2, 2 cos-sim2, 3 cos-sim2, 3 cos-sim1, 3 -
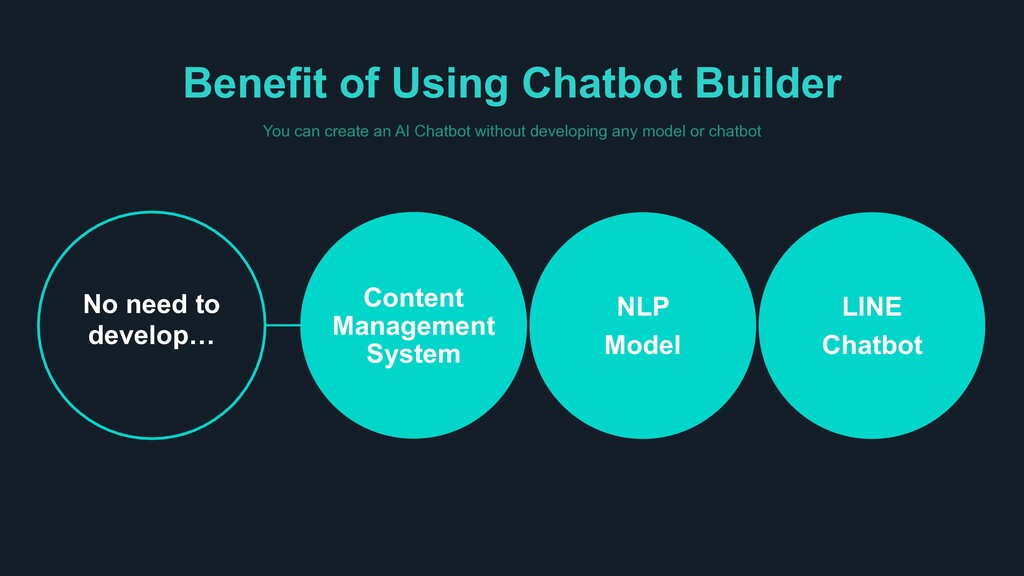
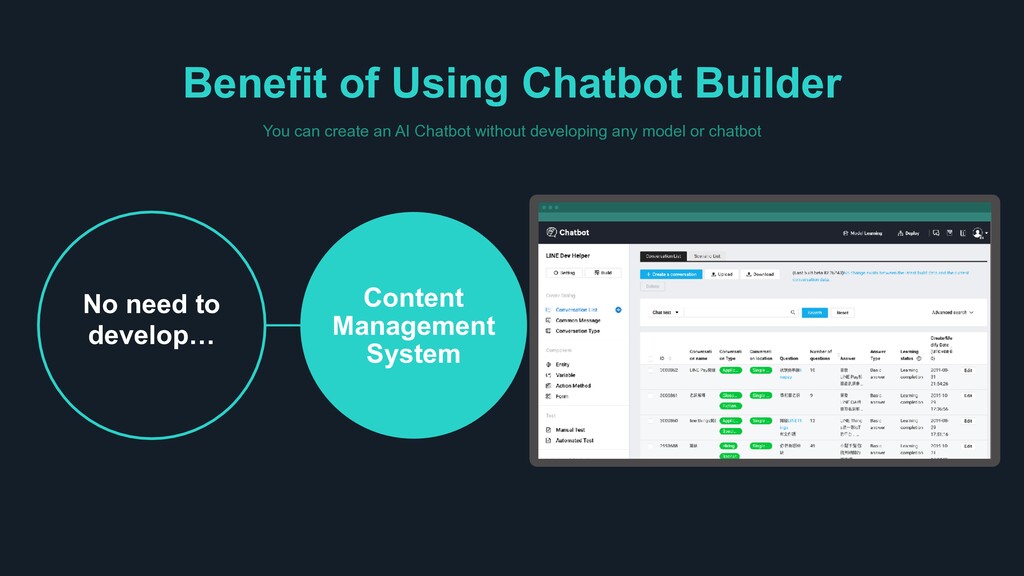
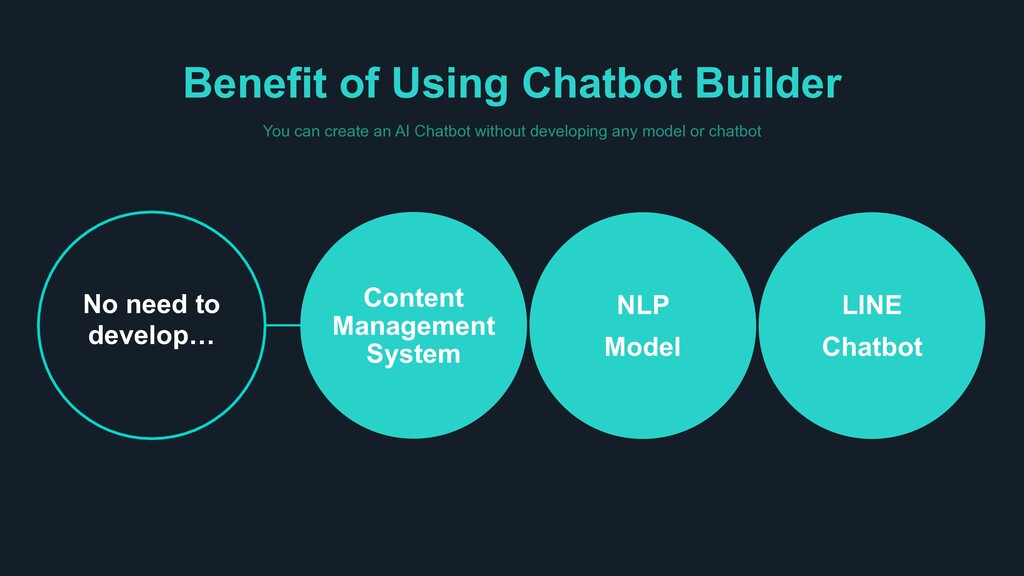
Benefit of Using Chatbot Builder You can create an AI
Chatbot without developing any model or chatbot Content Management System NLP Model LINE Chatbot No need to develop… -
Benefit of Using Chatbot Builder You can create an AI
Chatbot without developing any model or chatbot No need to develop… NLP Model LINE Chatbot Ƃ Content Management System -
Benefit of Using Chatbot Builder You can create an AI
Chatbot without developing any model or chatbot No need to develop… NLP Model LINE Chatbot Content Management System -
Benefit of Using Chatbot Builder You can create an AI
Chatbot without developing any model or chatbot No need to develop… NLP Model LINE Chatbot Content Management System -
Benefit of Using Chatbot Builder You can create an AI
Chatbot without developing any model or chatbot No need to develop… NLP Model LINE Chatbot Content Management System -
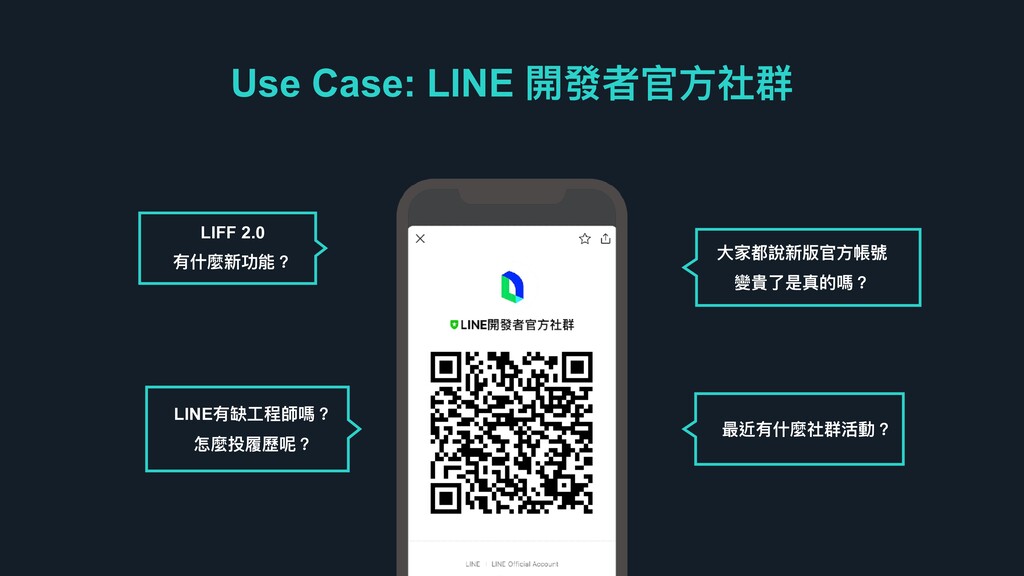
Use Case: LINE 樄咳ᘏਥොᐒᗭ LIFF 2.0 磪Ջ讕碝ۑ胼牫 य़疑᮷藯碝粚ਥො癱蒈 虋揫ԧฎ፥ጱ㻟牫 磧蜱磪Ջ讕ᐒᗭၚ㵕牫
LINE磪耬ૡ纷䒍㻟牫 ெ讕ಭ疾稲珌牫 -
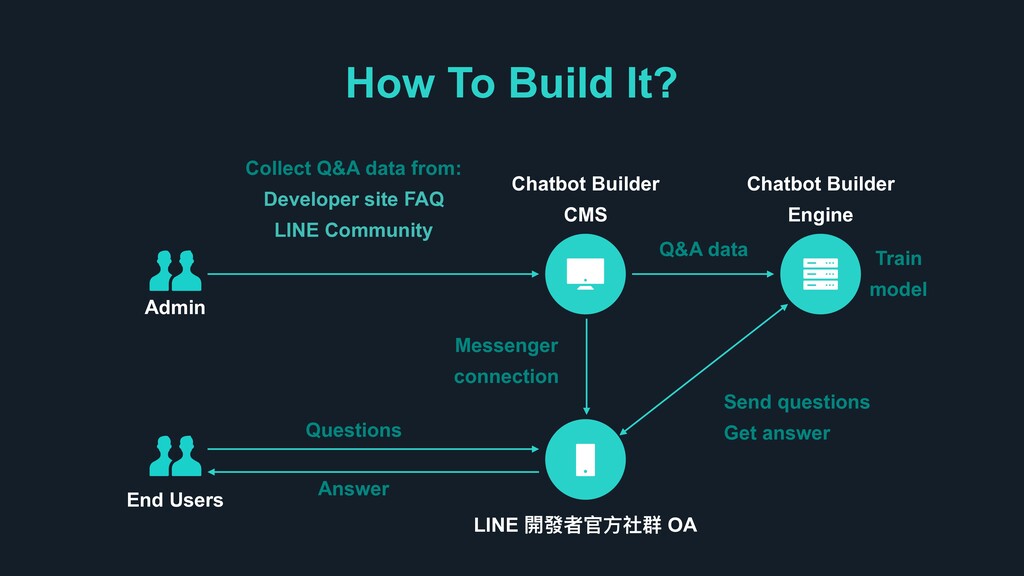
How To Build It? Collect Q&A data from: Developer site
FAQ LINE Community Admin End Users Chatbot Builder CMS Chatbot Builder Engine LINE 樄咳ᘏਥොᐒᗭ OA Questions Answer Q&A data Messenger connection Send questions Get answer Train model -
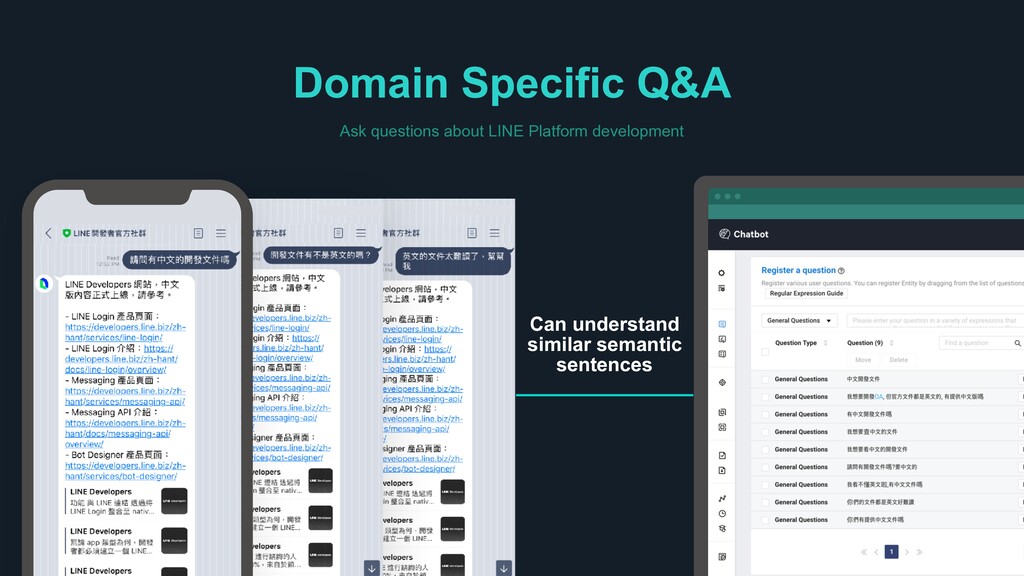
Domain Specific Q&A Ask questions about LINE Platform development Can
understand similar semantic sentences -
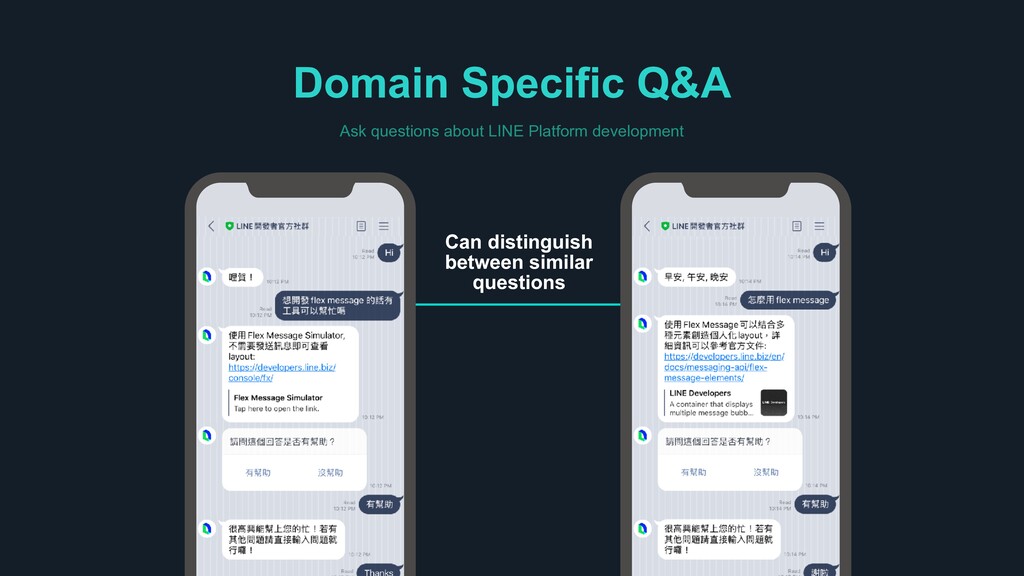
Domain Specific Q&A Ask questions about LINE Platform development Can
distinguish between similar questions -
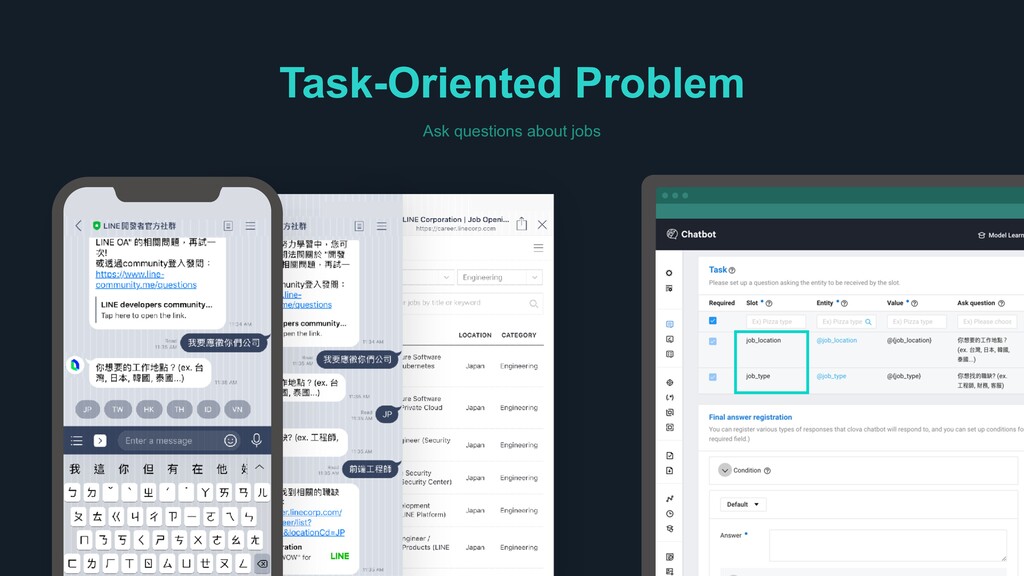
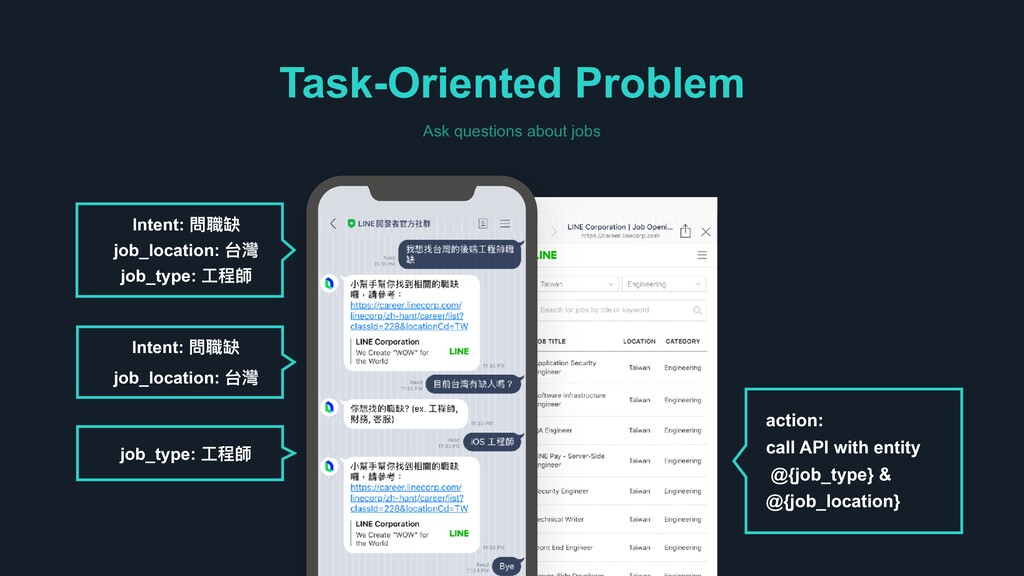
Task-Oriented Problem Ask questions about jobs Intent: 㺔肬耬 job_location: ݣ傀
job_type: ૡ纷䒍 Intent: 㺔肬耬 job_location: ݣ傀 job_type: ૡ纷䒍 action: call API with entity @{job_type} & @{job_location} -
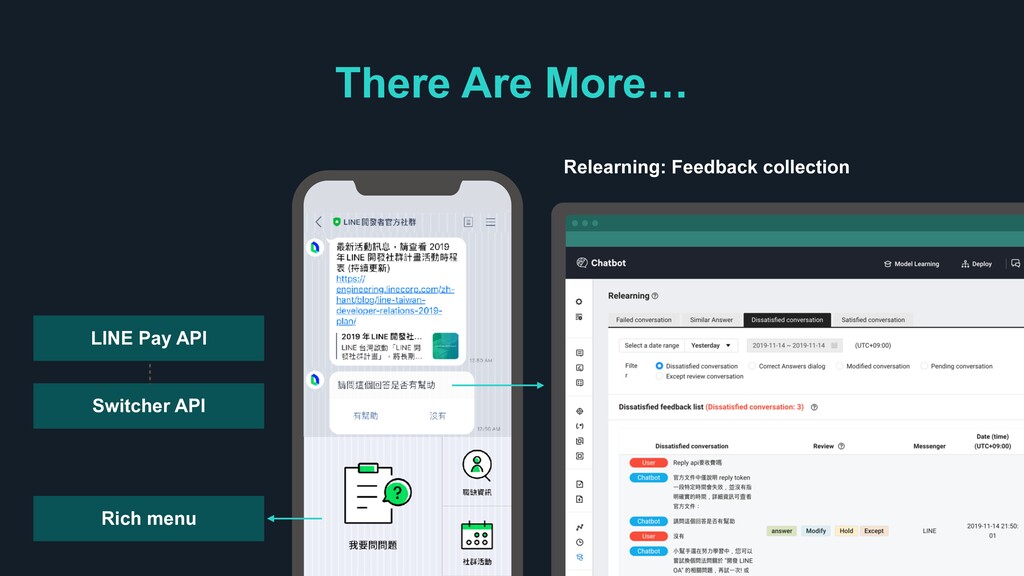
There Are More… Rich menu Switcher API LINE Pay API
Ƃ Relearning: Feedback collection