Share
Embed
Event Driven Machine Learning avec Publicis Sapient
Le serving de modèle de Machine Learning pour la prédiction en temps réel présente des défis tant en Data Engineering qu'en Data Science. Comment construire un pipeline moderne qui permet de réaliser des prédictions en continu ? Dans le cas d'un exercice supervisé, comment allier tracing et tracking des performances ? Comment récupérer un feedback pour déclencher un réentraînement réactif ?
Dans ce talk nous vous proposons de dresser, ensemble, une proposition concrète de pipeline, qui prend en compte les phases d'exploration et de monitoring dans un contexte temps réel. Les ingrédients : un event log, une plateforme notebook et d'autres surprises nous venant tout droit du Cloud.
Loïc DIVAD
June 01, 2020
Transcript
64 slides
-
@Giuliabianchl @Loicmdivad Giulia Bianchi Loïc Divad Data Scientist @PubSapientEng @Giuliabianchl
Software Engineer @PubSapientEng @Loicmdivad -
@Giuliabianchl @Loicmdivad Data Scientist @PubSapientEng Data Lover & Community Contributor
Co-Founder and Organizer of @DataXDay Machine Learning with Spark at PS Engineering Training @Giuliabianchl Giulia Bianchi -
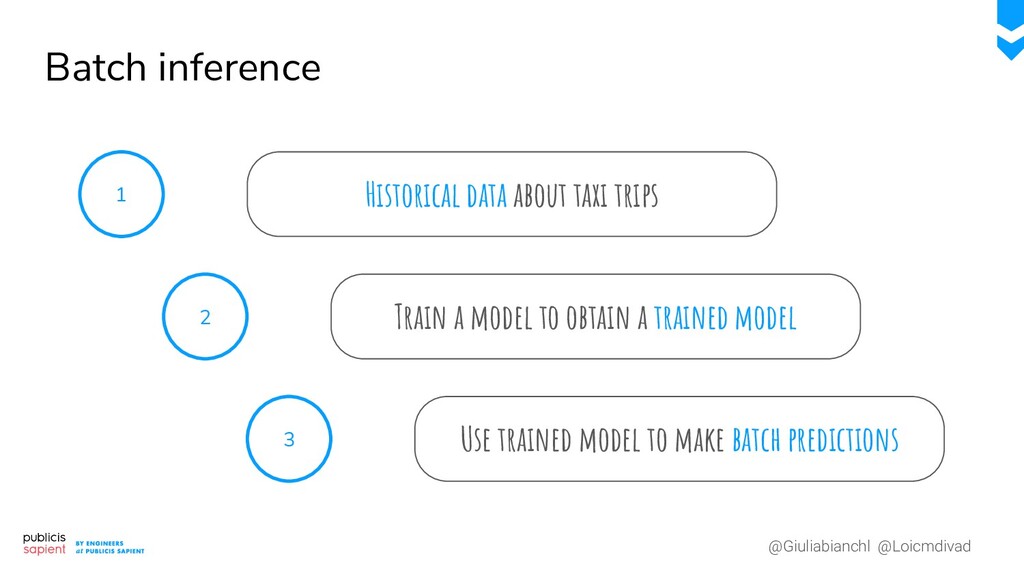
@Giuliabianchl @Loicmdivad Batch inference 1 Historical data about taxi trips
2 Train a model to obtain a trained model 3 Use trained model to make batch predictions -
@Giuliabianchl @Loicmdivad Trip duration estimation Given current location and destination
estimate trip duration • New data comes in each time someone orders a taxi ◦ NOT IN BATCHES • Continuous predictions -
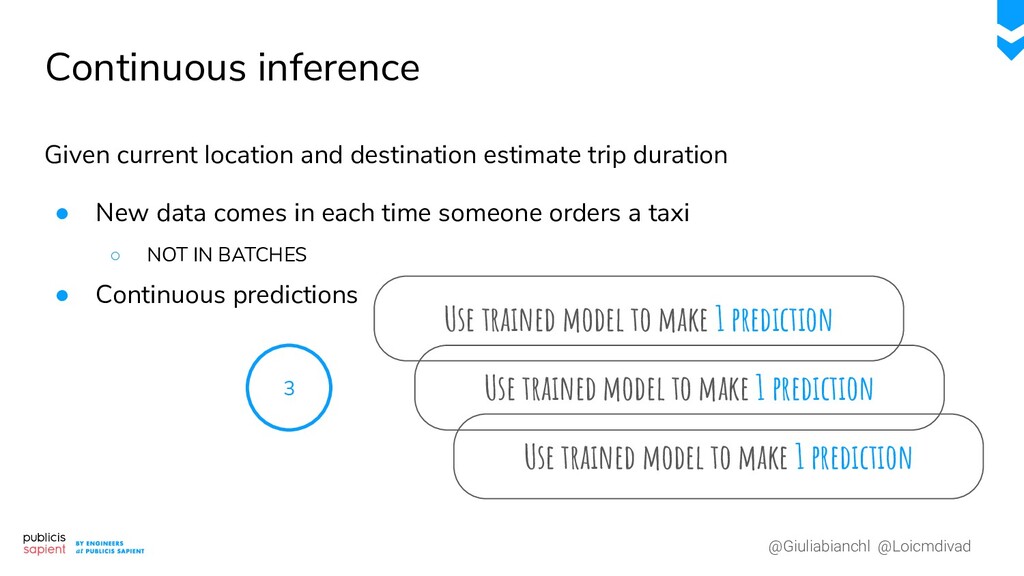
@Giuliabianchl @Loicmdivad Continuous inference Given current location and destination estimate
trip duration • New data comes in each time someone orders a taxi ◦ NOT IN BATCHES • Continuous predictions 3 Use trained model to make 1 prediction Use trained model to make 1 prediction Use trained model to make 1 prediction -
@Giuliabianchl @Loicmdivad Hello data engineer, I could use some help
• How to build the pipeline? • What is a possible technical solution? • What is the impact on my machine learning routine? Streaming is the new batch -
@Giuliabianchl @Loicmdivad Software Engineer @PubSapientEng Confluent Community Catalyst Scala Developer
and Apache Kafka Lover Co-Founder and Organizer of @DataXDay Spark and Kafka Streams trainer at PS Engineering Training @Loicmdivad Loïc Divad -
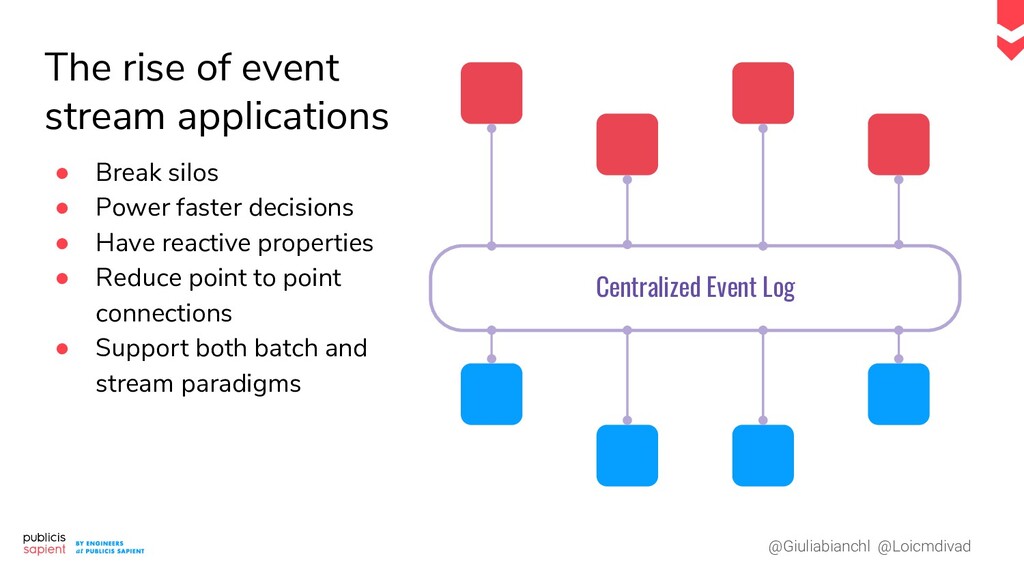
@Giuliabianchl @Loicmdivad The rise of event stream applications • Break
silos • Power faster decisions • Have reactive properties • Reduce point to point connections • Support both batch and stream paradigms Centralized Event Log -
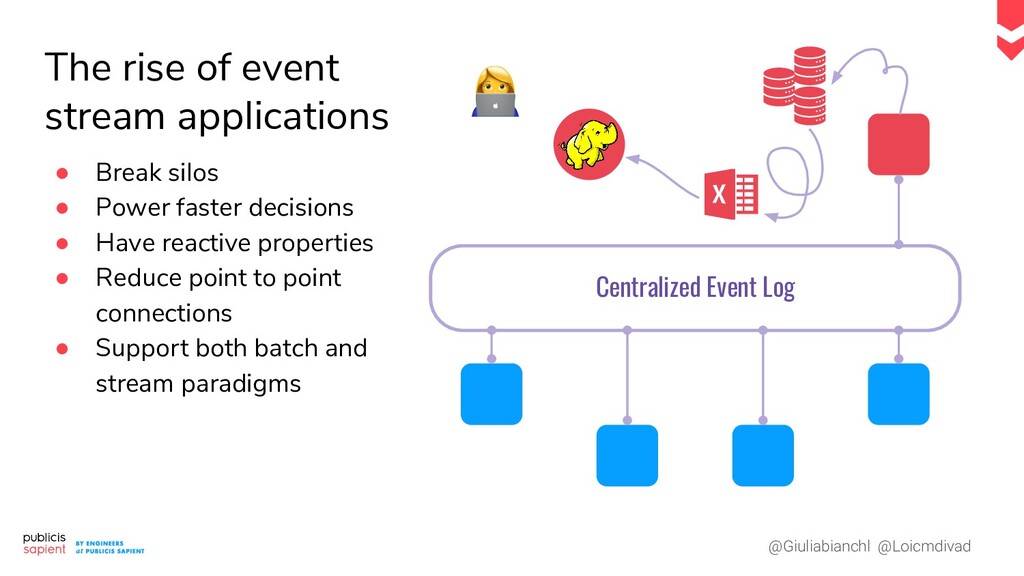
@Giuliabianchl @Loicmdivad The rise of event stream applications • Break
silos • Power faster decisions • Have reactive properties • Reduce point to point connections • Support both batch and stream paradigms Centralized Event Log -
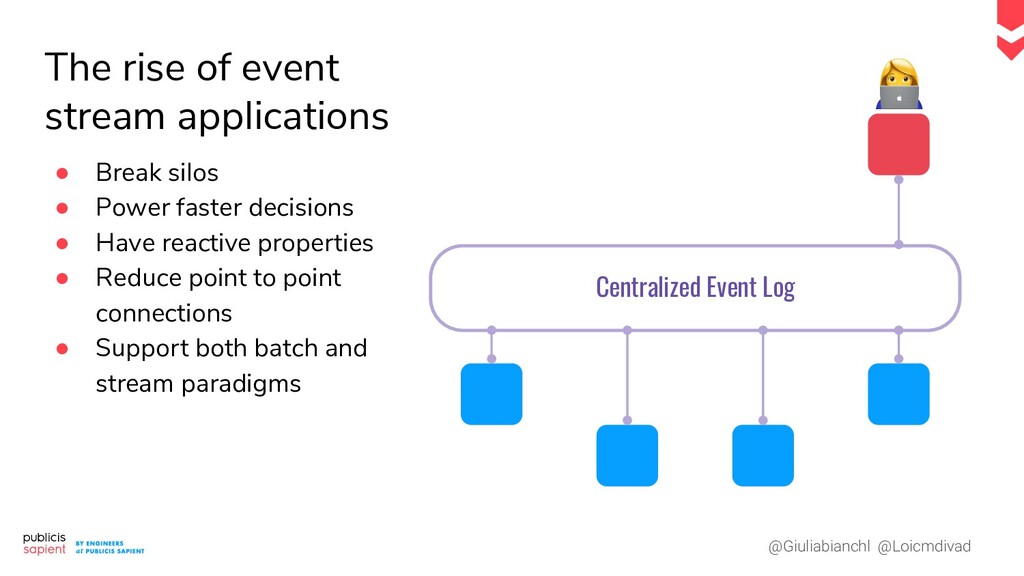
@Giuliabianchl @Loicmdivad The rise of event stream applications • Break
silos • Power faster decisions • Have reactive properties • Reduce point to point connections • Support both batch and stream paradigms Centralized Event Log -
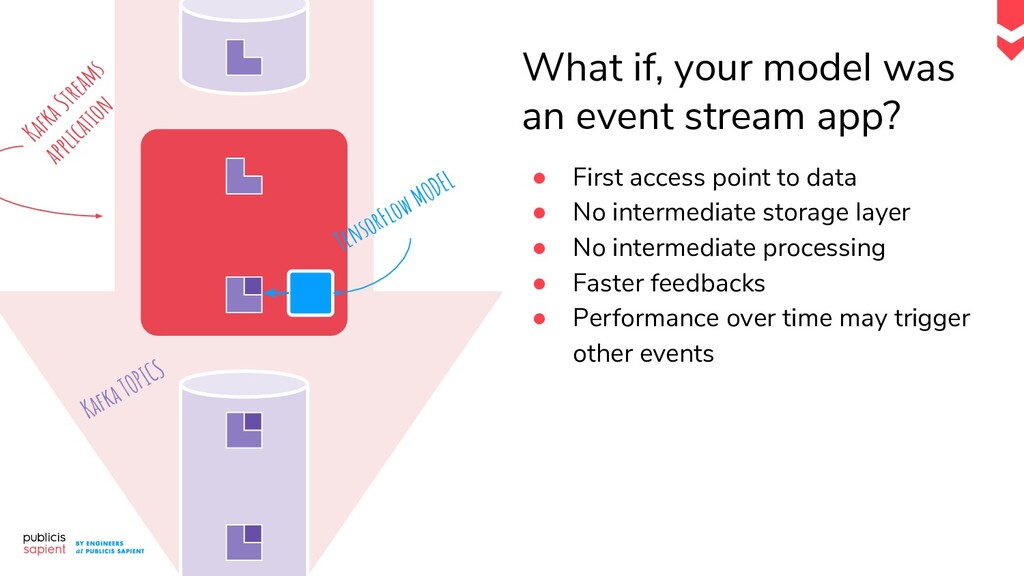
What if, your model was an event stream app? •
First access point to data • No intermediate storage layer • No intermediate processing • Faster feedbacks • Performance over time may trigger other events Kafka Streams application TensorFlow MODEL Kafka TOPICS -
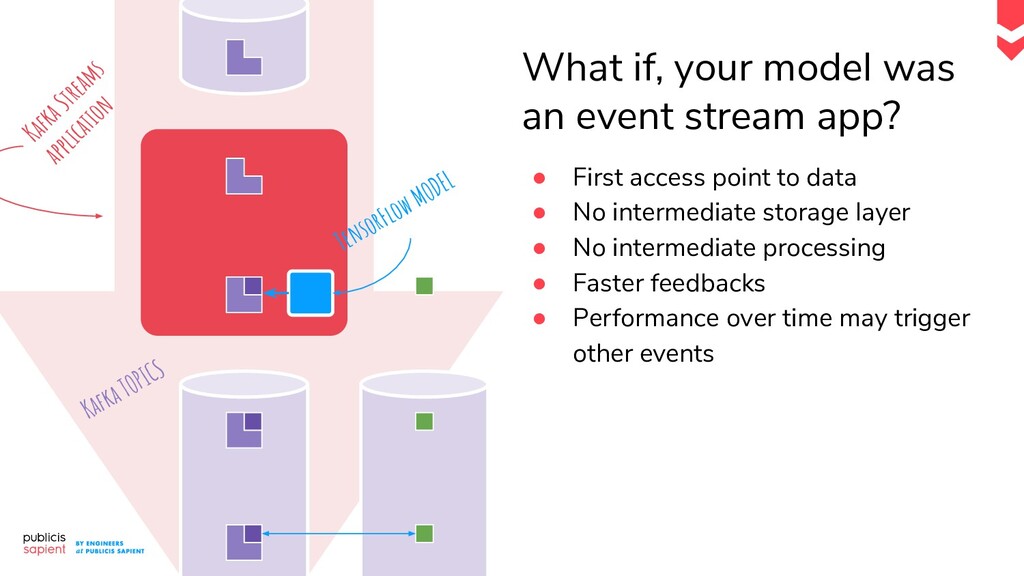
What if, your model was an event stream app? •
First access point to data • No intermediate storage layer • No intermediate processing • Faster feedbacks • Performance over time may trigger other events Kafka Streams application TensorFlow MODEL Kafka TOPICS -
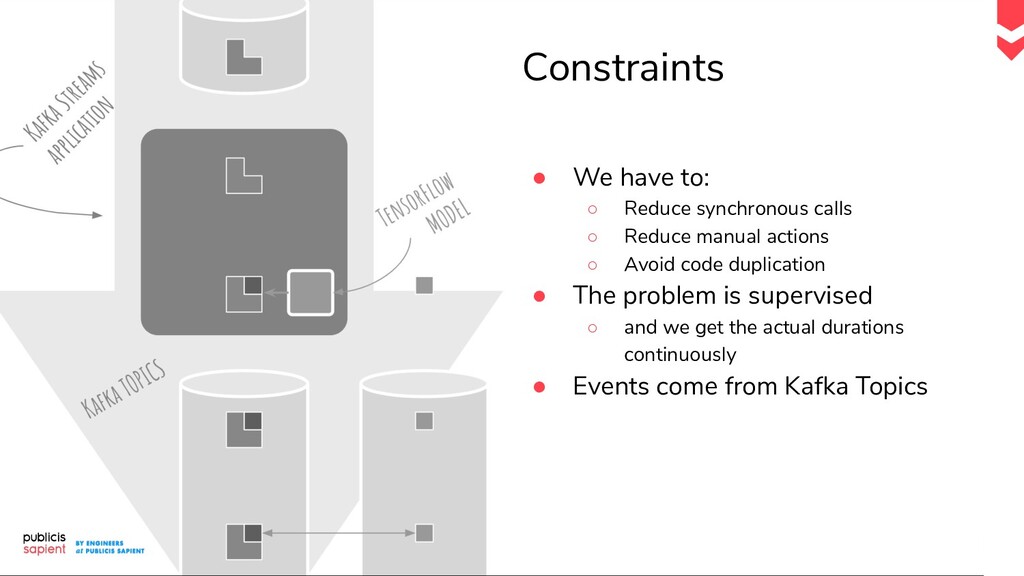
Constraints • We have to: ◦ Reduce synchronous calls ◦
Reduce manual actions ◦ Avoid code duplication • The problem is supervised ◦ and we get the actual durations continuously • Events come from Kafka Topics -
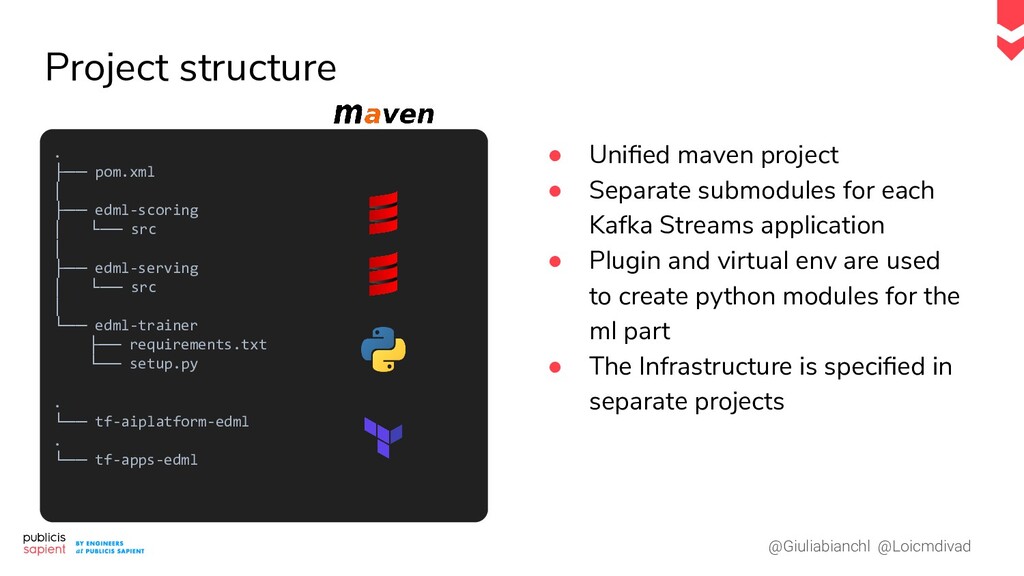
@Giuliabianchl @Loicmdivad Project structure • Unified maven project • Separate
submodules for each Kafka Streams application • Plugin and virtual env are used to create python modules for the ml part • The Infrastructure is specified in separate projects . ├── pom.xml │ ├── edml-scoring │ └── src │ ├── edml-serving │ └── src │ └── edml-trainer ├── requirements.txt └── setup.py . └── tf-aiplatform-edml . └── tf-apps-edml -
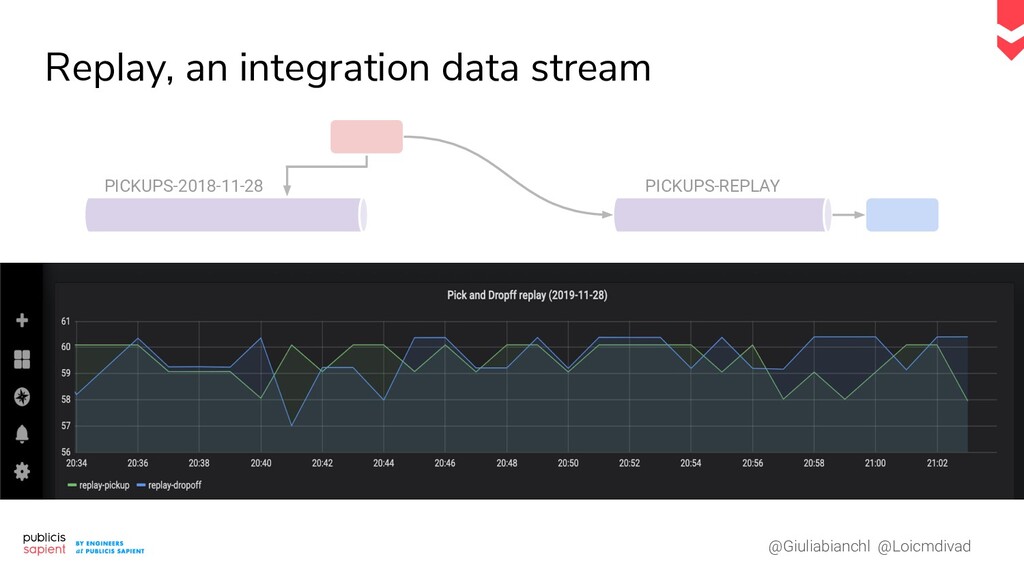
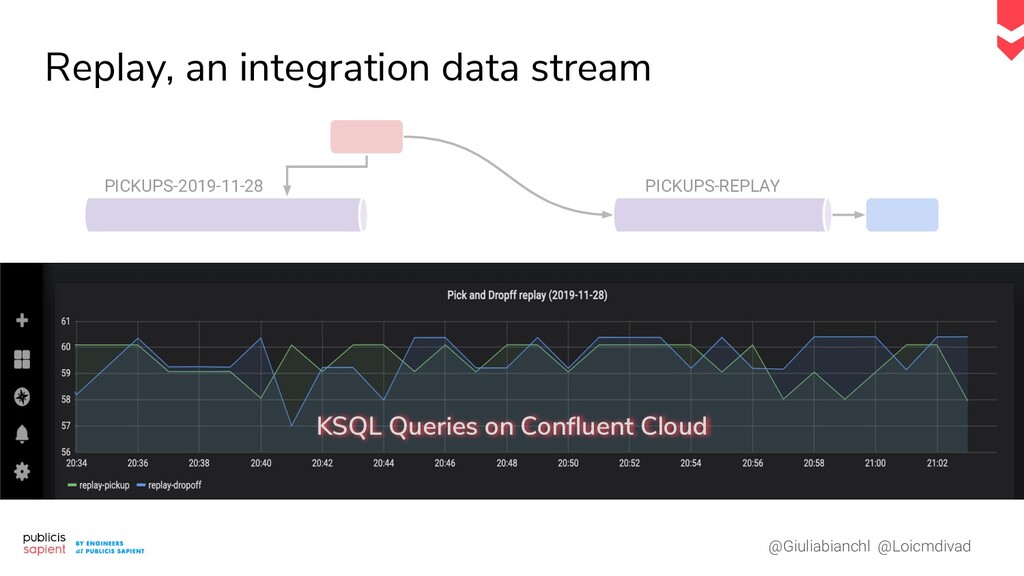
@Giuliabianchl @Loicmdivad Replay, an integration data stream PICKUPS-2019-11-28 PICKUPS-REPLAY KSQL
Queries on Confluent Cloud -
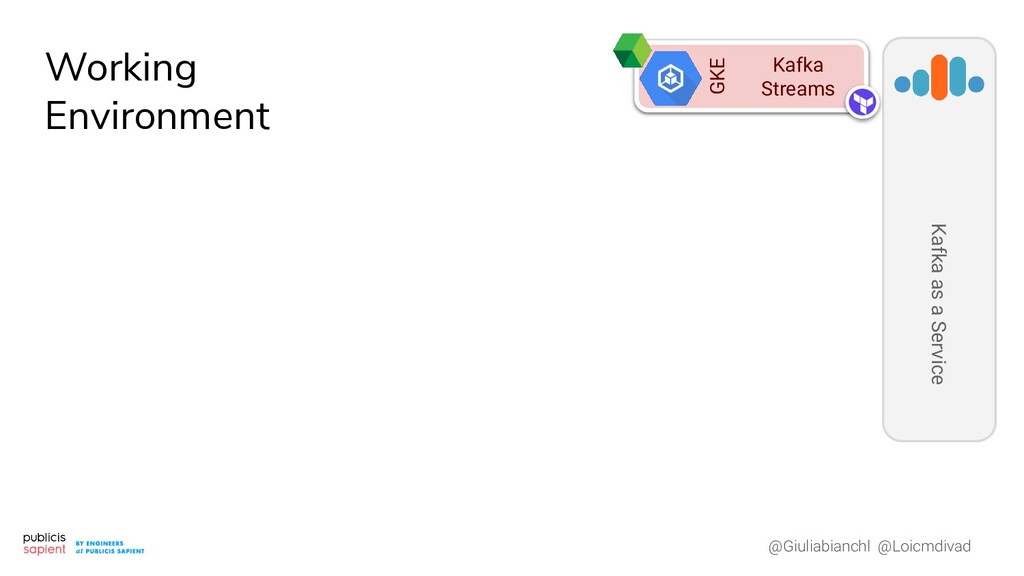
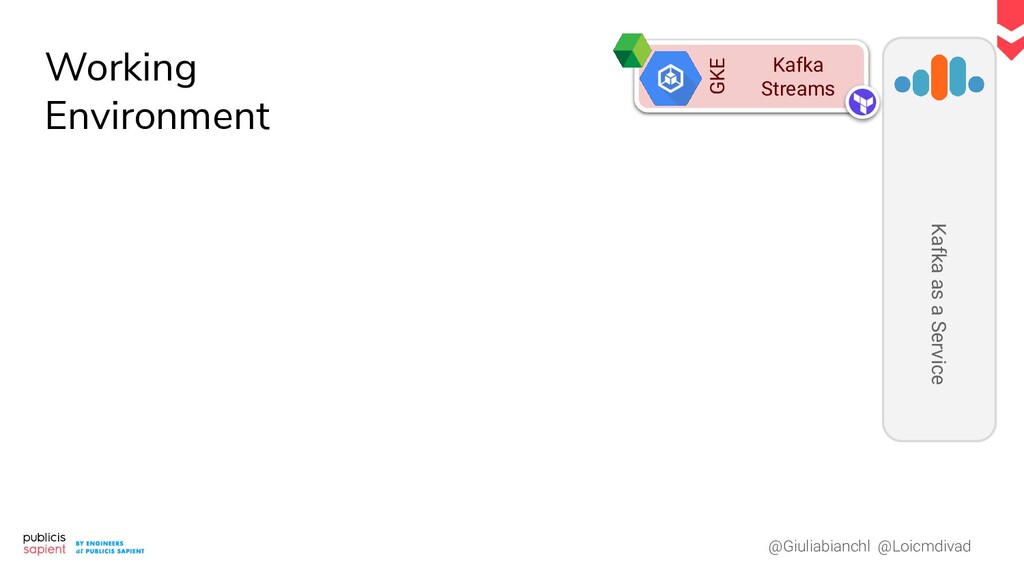
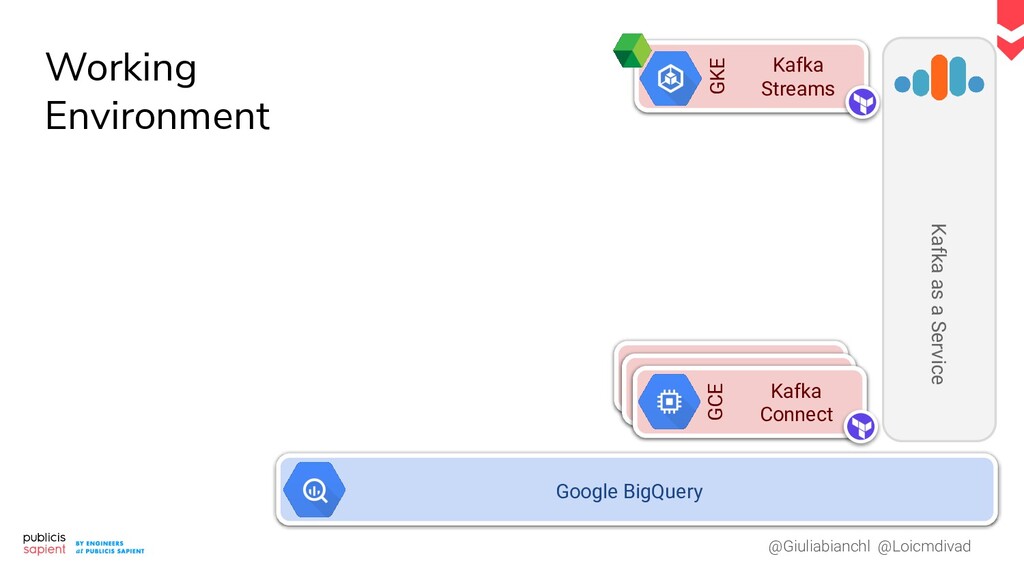
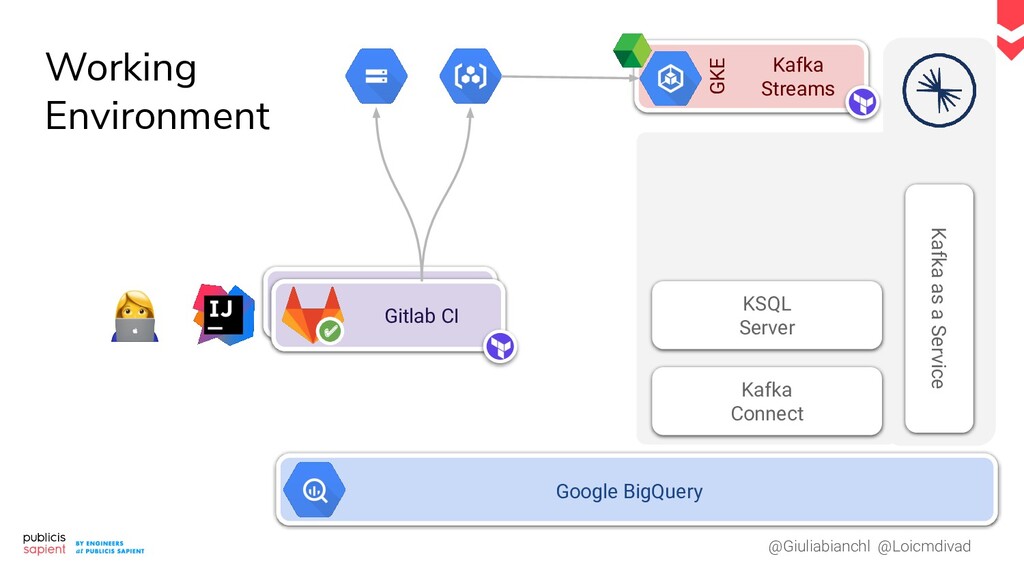
@Giuliabianchl @Loicmdivad Kafka as a Service Kafka Streams GKE Kafka
Connect GCE Google BigQuery Working Environment -
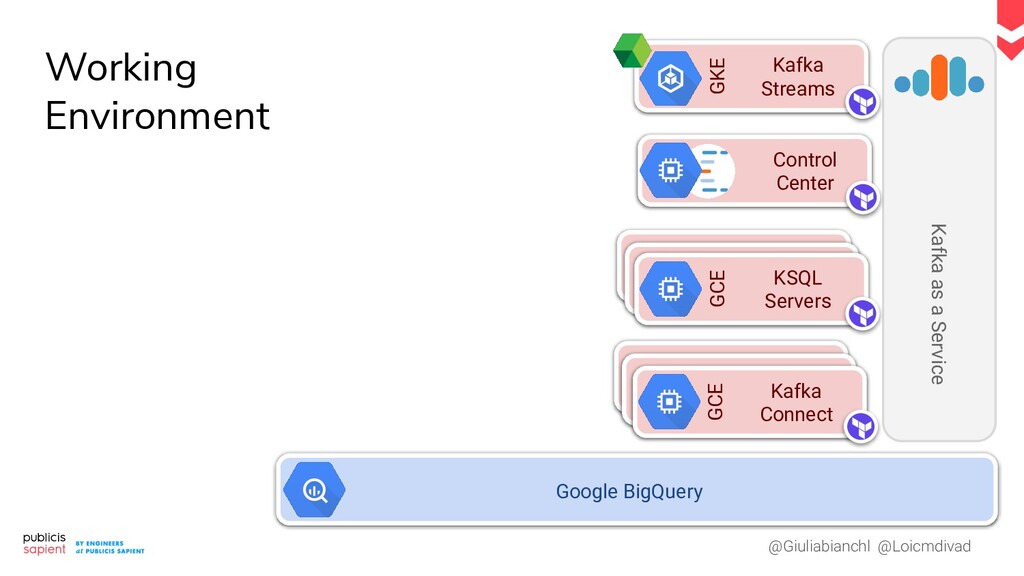
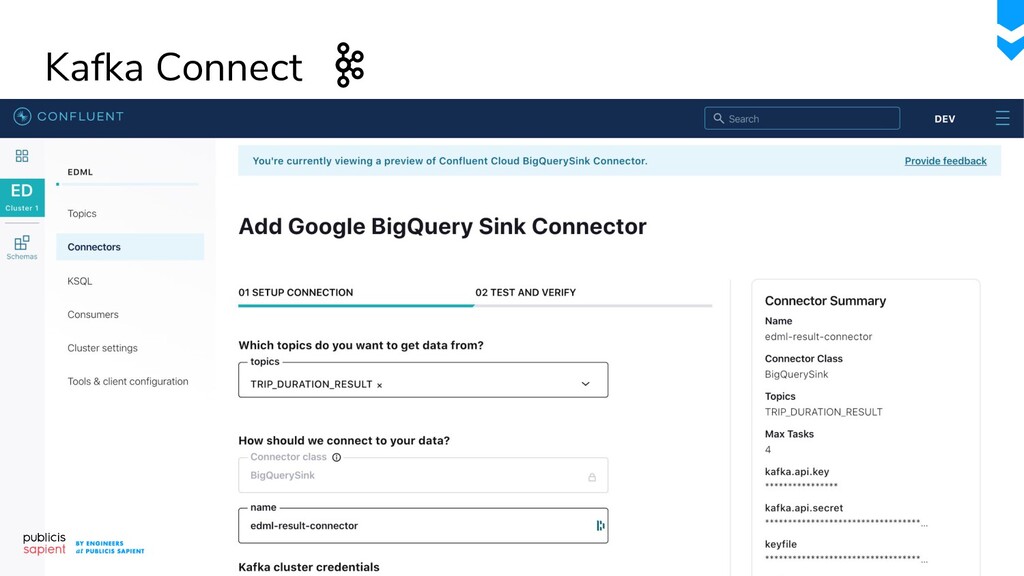
@Giuliabianchl @Loicmdivad Kafka as a Service Control Center Kafka Streams
GKE Google BigQuery KSQL Servers GCE Kafka Connect GCE Working Environment -
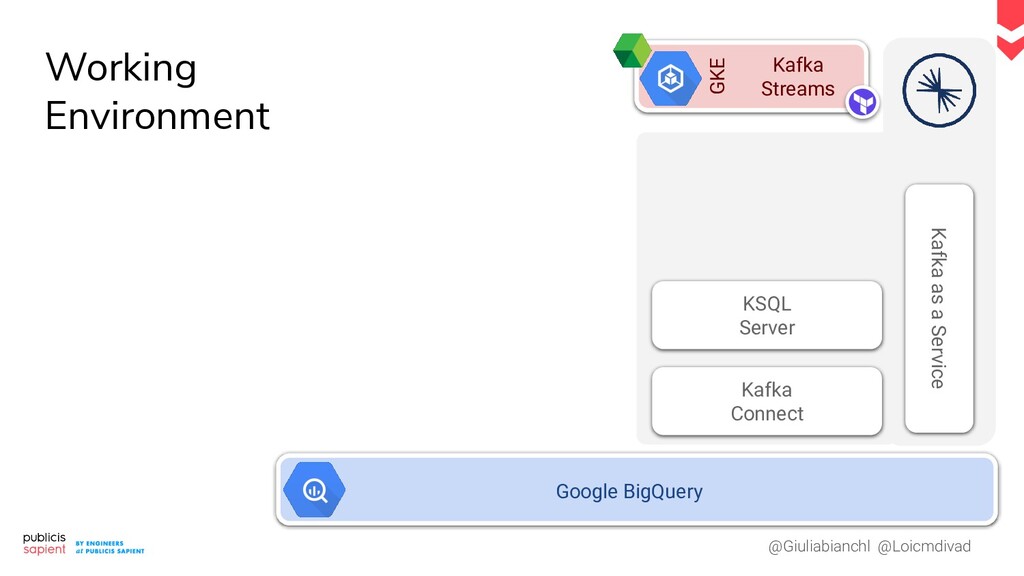
@Giuliabianchl @Loicmdivad Kafka as a Service Kafka Streams GKE Google
BigQuery Kafka Connect KSQL Server Working Environment -
@Giuliabianchl @Loicmdivad Kafka as a Service Kafka Streams GKE Google
BigQuery Gitlab CI ✔ Kafka Connect KSQL Server Working Environment -
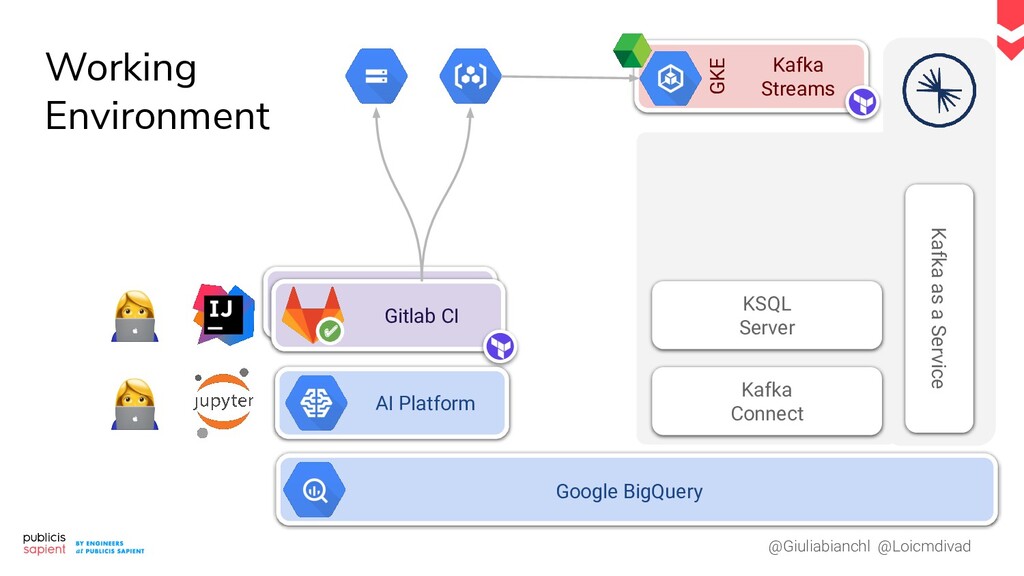
@Giuliabianchl @Loicmdivad Kafka as a Service Kafka Streams GKE Google
BigQuery Gitlab CI ✔ AI Platform Kafka Connect KSQL Server Working Environment -
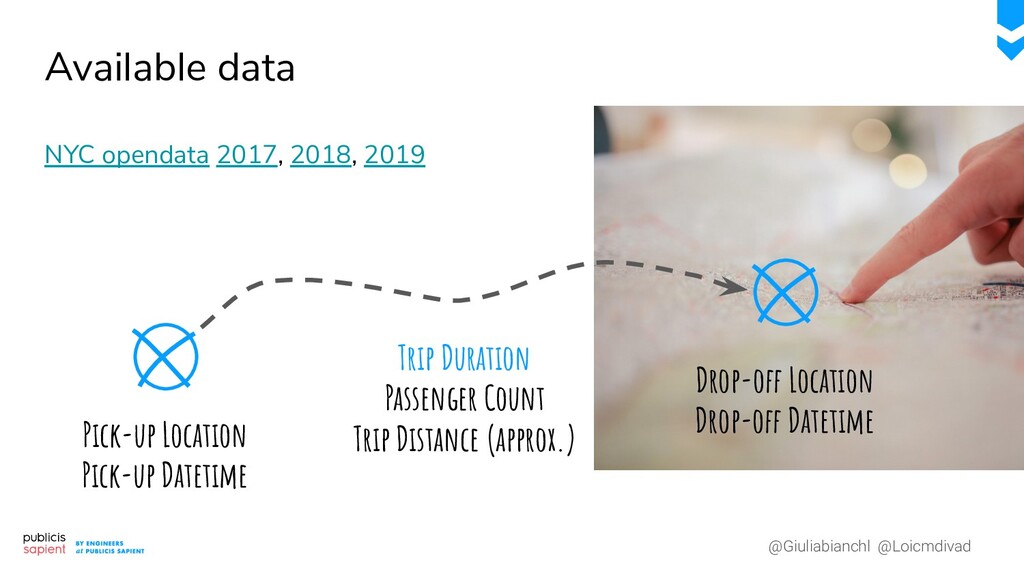
@Giuliabianchl @Loicmdivad Available data NYC opendata 2017, 2018, 2019 Pick-up
Location Pick-up Datetime Drop-off Location Drop-off Datetime Trip Duration Passenger Count Trip Distance (approx.) -
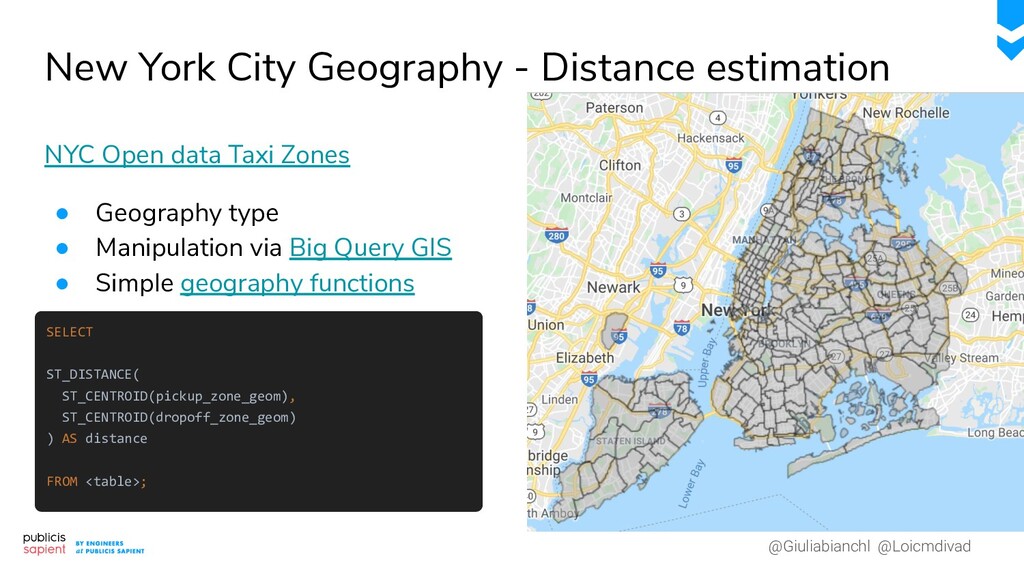
@Giuliabianchl @Loicmdivad New York City Geography - Distance estimation NYC
Open data Taxi Zones • Geography type • Manipulation via Big Query GIS • Simple geography functions SELECT ST_DISTANCE( ST_CENTROID(pickup_zone_geom), ST_CENTROID(dropoff_zone_geom) ) AS distance FROM <table>; -
@Giuliabianchl @Loicmdivad Wide features Sparse features for linear model •
One hot encoded features ◦ pick-up day of week ◦ pick-up hour of day ◦ pick-up day of year ✖pick-up hour of day ◦ pick-up zone ◦ drop-off zone ◦ pick-up zone ✖drop-off zone Pick-up Location Pick-up Datetime Drop-off Location Passenger Count Trip distance Approximation -
@Giuliabianchl @Loicmdivad Deep features Dense features for deep neural network
• Embedded Features ◦ pick-up day of year ◦ pick-up hour of day ◦ pick-up zone ◦ drop-off zone ◦ passenger count ◦ approximated distance Pick-up Location Pick-up Datetime Drop-off Location Passenger Count Trip distance approximation -
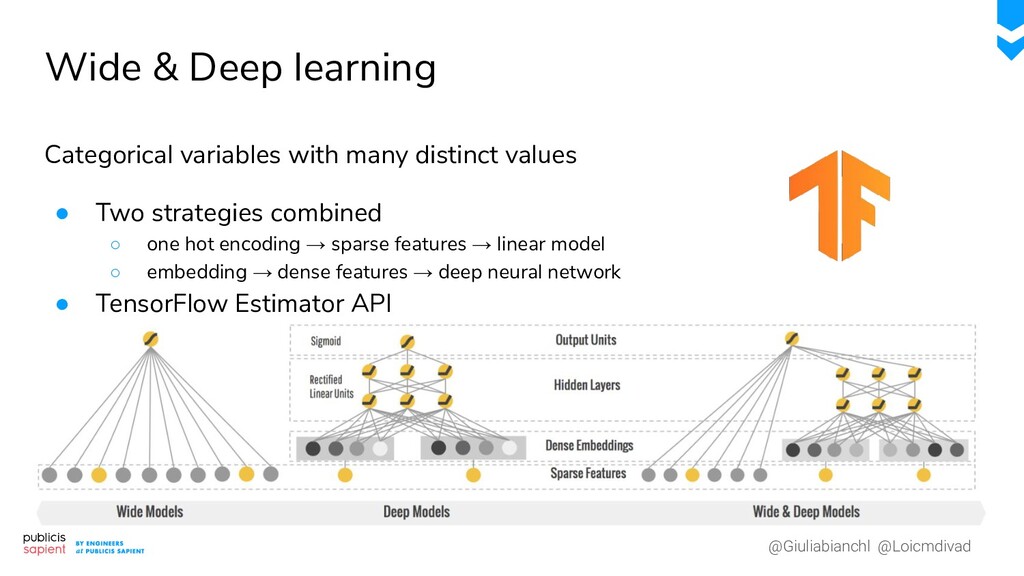
@Giuliabianchl @Loicmdivad Wide & Deep learning Categorical variables with many
distinct values • Two strategies combined ◦ one hot encoding → sparse features → linear model ◦ embedding → dense features → deep neural network • TensorFlow Estimator API -
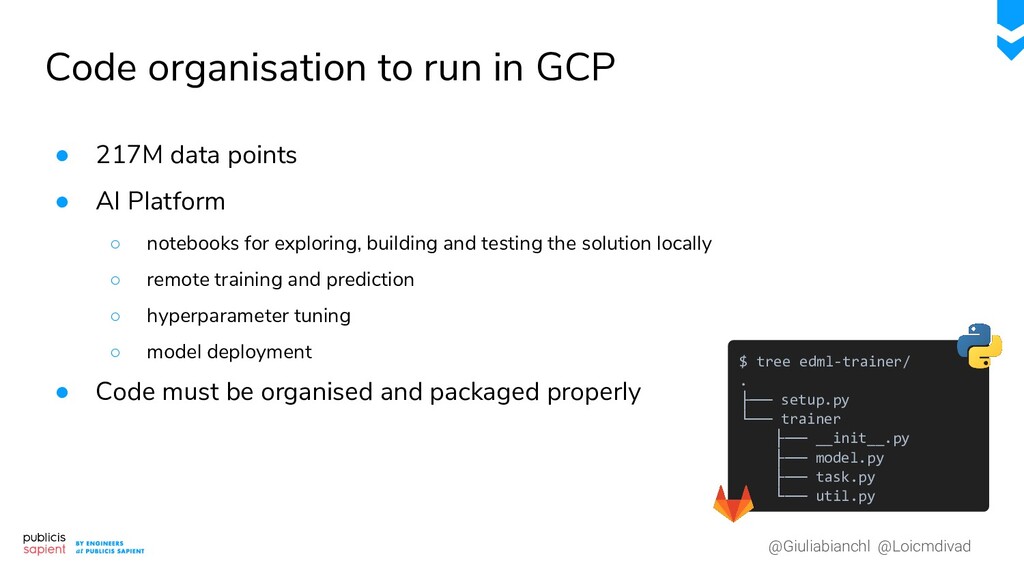
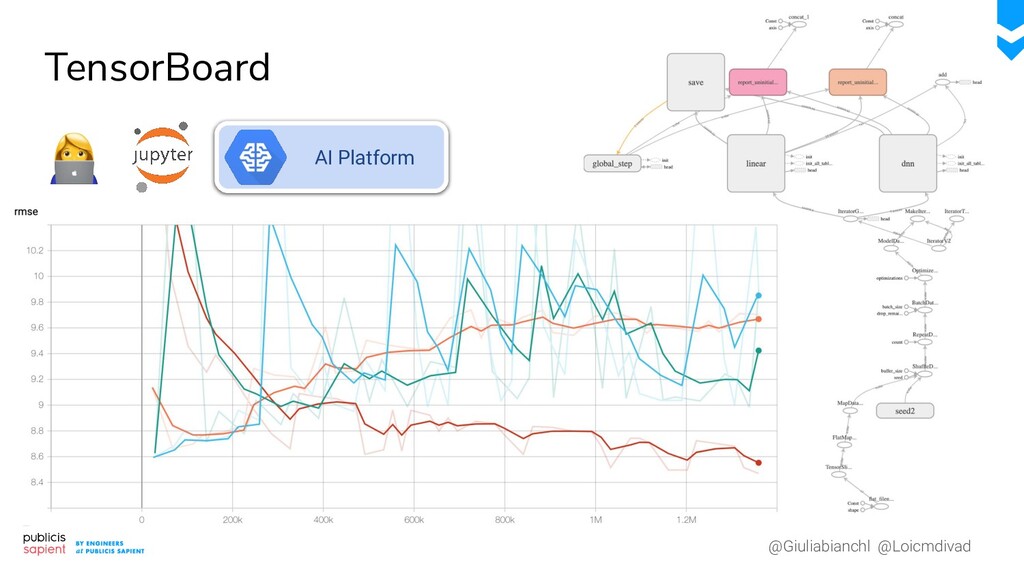
@Giuliabianchl @Loicmdivad Code organisation to run in GCP • 217M
data points • AI Platform ◦ notebooks for exploring, building and testing the solution locally ◦ remote training and prediction ◦ hyperparameter tuning ◦ model deployment • Code must be organised and packaged properly $ tree edml-trainer/ . ├── setup.py └── trainer ├── __init__.py ├── model.py ├── task.py └── util.py -
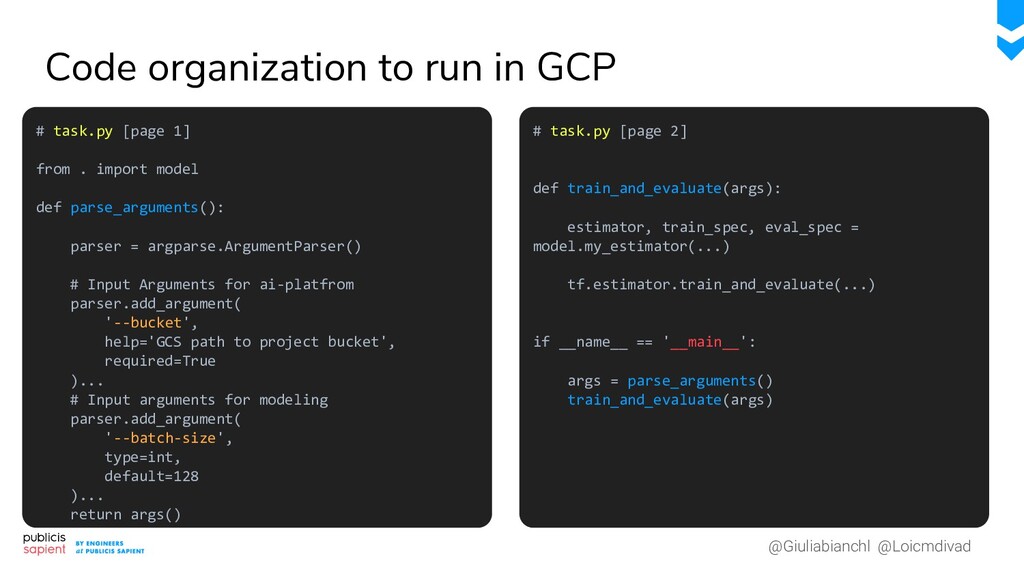
@Giuliabianchl @Loicmdivad Code organization to run in GCP # task.py
[page 1] from . import model def parse_arguments(): parser = argparse.ArgumentParser() # Input Arguments for ai-platfrom parser.add_argument( '--bucket', help='GCS path to project bucket', required=True )... # Input arguments for modeling parser.add_argument( '--batch-size', type=int, default=128 )... return args() # task.py [page 2] def train_and_evaluate(args): estimator, train_spec, eval_spec = model.my_estimator(...) tf.estimator.train_and_evaluate(...) if __name__ == '__main__': args = parse_arguments() train_and_evaluate(args) -
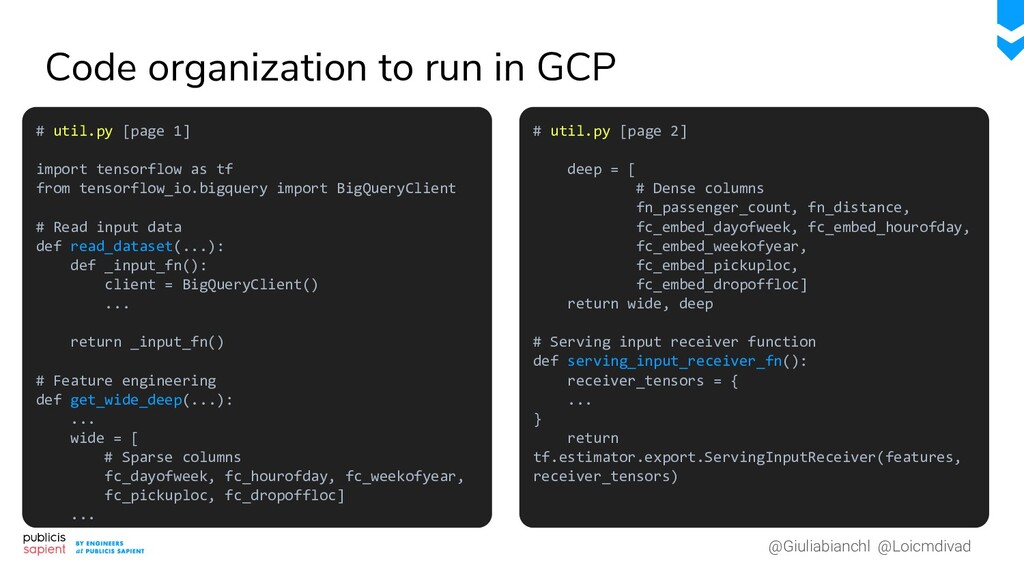
@Giuliabianchl @Loicmdivad Code organization to run in GCP # util.py
[page 1] import tensorflow as tf from tensorflow_io.bigquery import BigQueryClient # Read input data def read_dataset(...): def _input_fn(): client = BigQueryClient() ... return _input_fn() # Feature engineering def get_wide_deep(...): ... wide = [ # Sparse columns fc_dayofweek, fc_hourofday, fc_weekofyear, fc_pickuploc, fc_dropoffloc] ... # util.py [page 2] deep = [ # Dense columns fn_passenger_count, fn_distance, fc_embed_dayofweek, fc_embed_hourofday, fc_embed_weekofyear, fc_embed_pickuploc, fc_embed_dropoffloc] return wide, deep # Serving input receiver function def serving_input_receiver_fn(): receiver_tensors = { ... } return tf.estimator.export.ServingInputReceiver(features, receiver_tensors) -
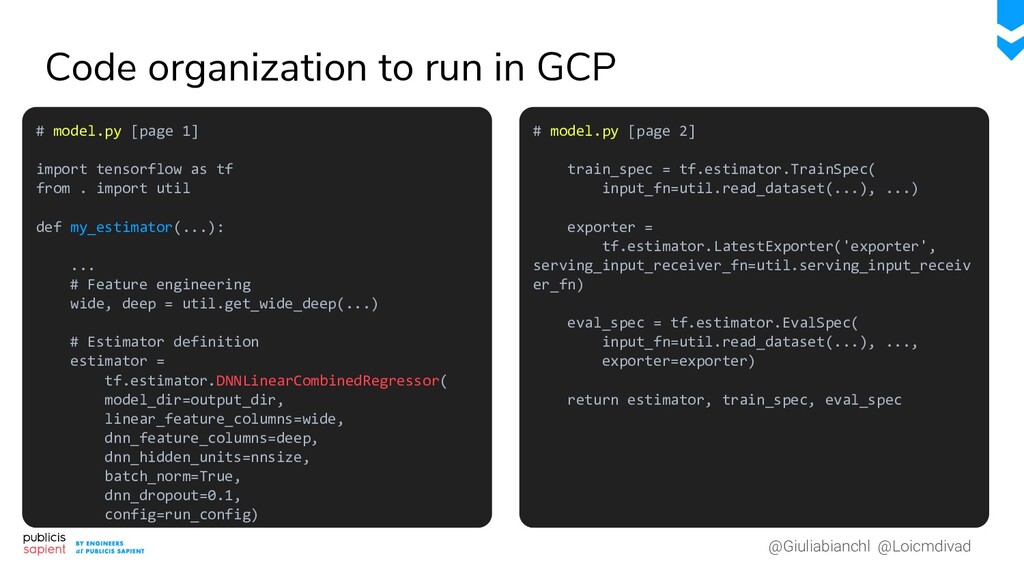
@Giuliabianchl @Loicmdivad Code organization to run in GCP # model.py
[page 1] import tensorflow as tf from . import util def my_estimator(...): ... # Feature engineering wide, deep = util.get_wide_deep(...) # Estimator definition estimator = tf.estimator.DNNLinearCombinedRegressor( model_dir=output_dir, linear_feature_columns=wide, dnn_feature_columns=deep, dnn_hidden_units=nnsize, batch_norm=True, dnn_dropout=0.1, config=run_config) # model.py [page 2] train_spec = tf.estimator.TrainSpec( input_fn=util.read_dataset(...), ...) exporter = tf.estimator.LatestExporter('exporter', serving_input_receiver_fn=util.serving_input_receiv er_fn) eval_spec = tf.estimator.EvalSpec( input_fn=util.read_dataset(...), ..., exporter=exporter) return estimator, train_spec, eval_spec -
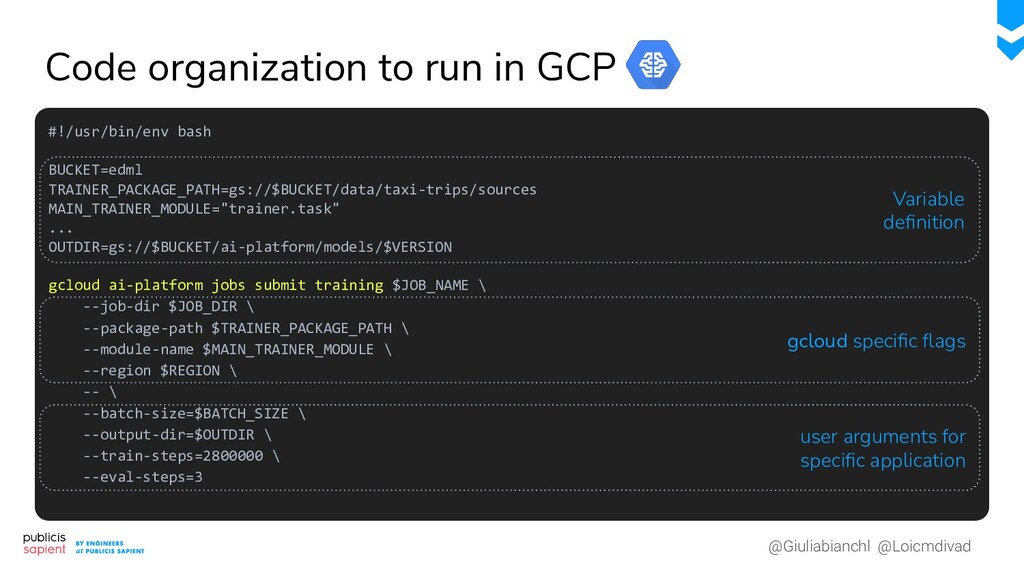
@Giuliabianchl @Loicmdivad #!/usr/bin/env bash BUCKET=edml TRAINER_PACKAGE_PATH=gs://$BUCKET/data/taxi-trips/sources MAIN_TRAINER_MODULE="trainer.task" ... OUTDIR=gs://$BUCKET/ai-platform/models/$VERSION gcloud
ai-platform jobs submit training $JOB_NAME \ --job-dir $JOB_DIR \ --package-path $TRAINER_PACKAGE_PATH \ --module-name $MAIN_TRAINER_MODULE \ --region $REGION \ -- \ --batch-size=$BATCH_SIZE \ --output-dir=$OUTDIR \ --train-steps=2800000 \ --eval-steps=3 Code organization to run in GCP Variable definition gcloud specific flags user arguments for specific application -
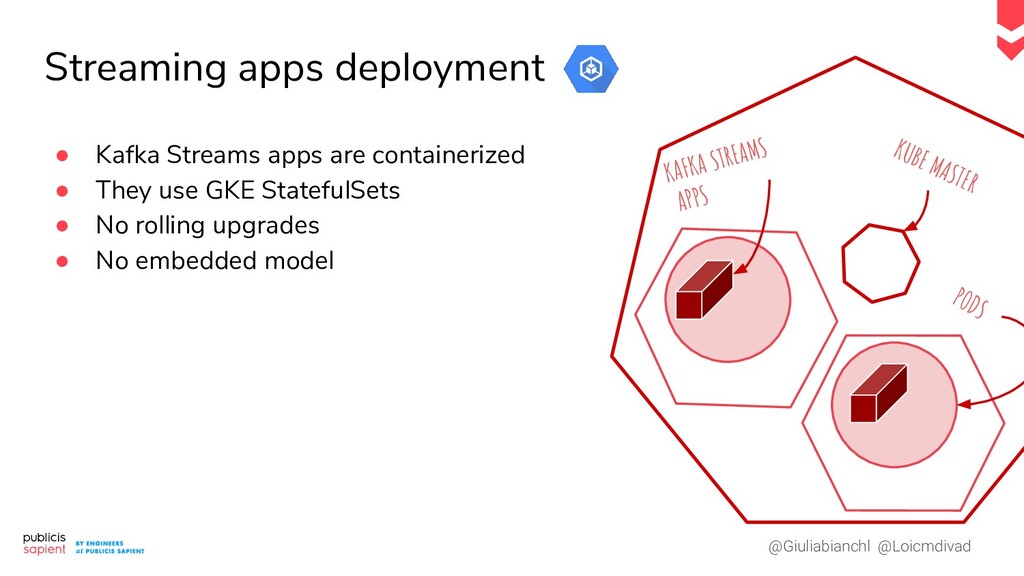
@Giuliabianchl @Loicmdivad KAFKA STREAMS APPS PODS KUBE MASTER Streaming apps
deployment • Kafka Streams apps are containerized • They use GKE StatefulSets • No rolling upgrades • No embedded model -
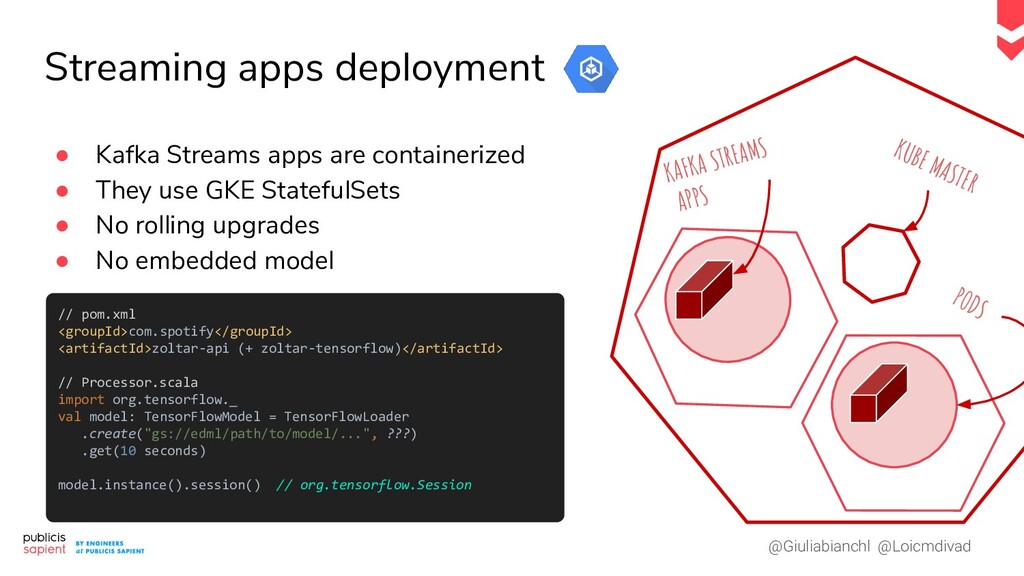
@Giuliabianchl @Loicmdivad • Kafka Streams apps are containerized • They
use GKE StatefulSets • No rolling upgrades • No embedded model Streaming apps deployment // pom.xml <groupId>com.spotify</groupId> <artifactId>zoltar-api (+ zoltar-tensorflow)</artifactId> // Processor.scala import org.tensorflow._ val model: TensorFlowModel = TensorFlowLoader .create("gs://edml/path/to/model/...", ???) .get(10 seconds) model.instance().session() // org.tensorflow.Session KAFKA STREAMS APPS PODS KUBE MASTER -
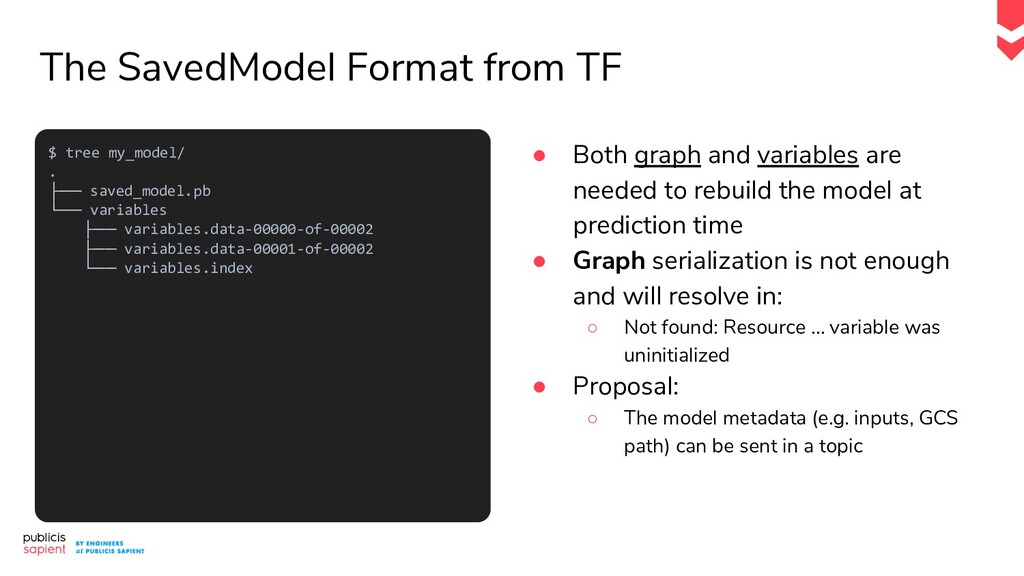
The SavedModel Format from TF • Both graph and variables
are needed to rebuild the model at prediction time • Graph serialization is not enough and will resolve in: ◦ Not found: Resource … variable was uninitialized • Proposal: ◦ The model metadata (e.g. inputs, GCS path) can be sent in a topic $ tree my_model/ . ├── saved_model.pb └── variables ├── variables.data-00000-of-00002 ├── variables.data-00001-of-00002 └── variables.index -
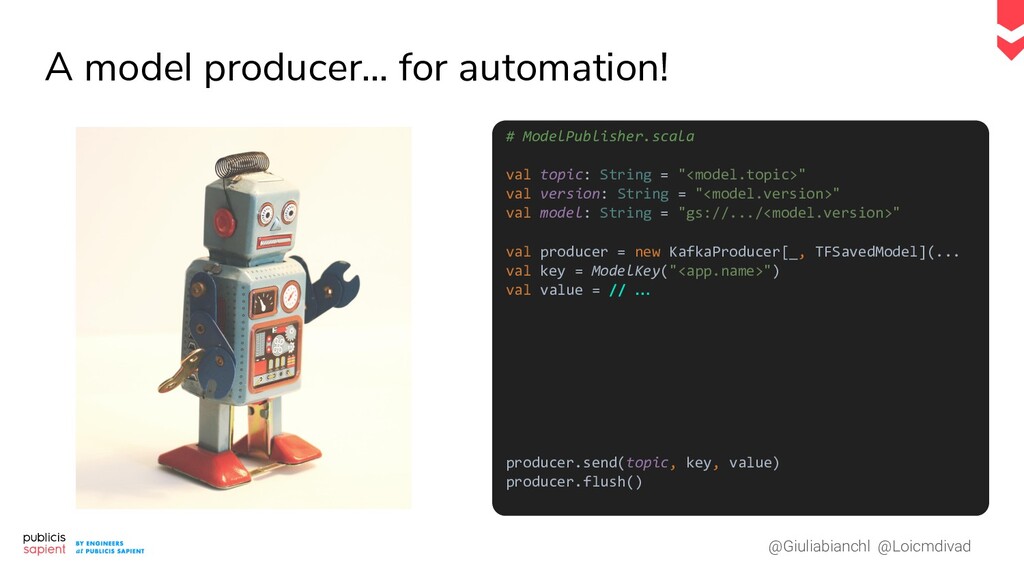
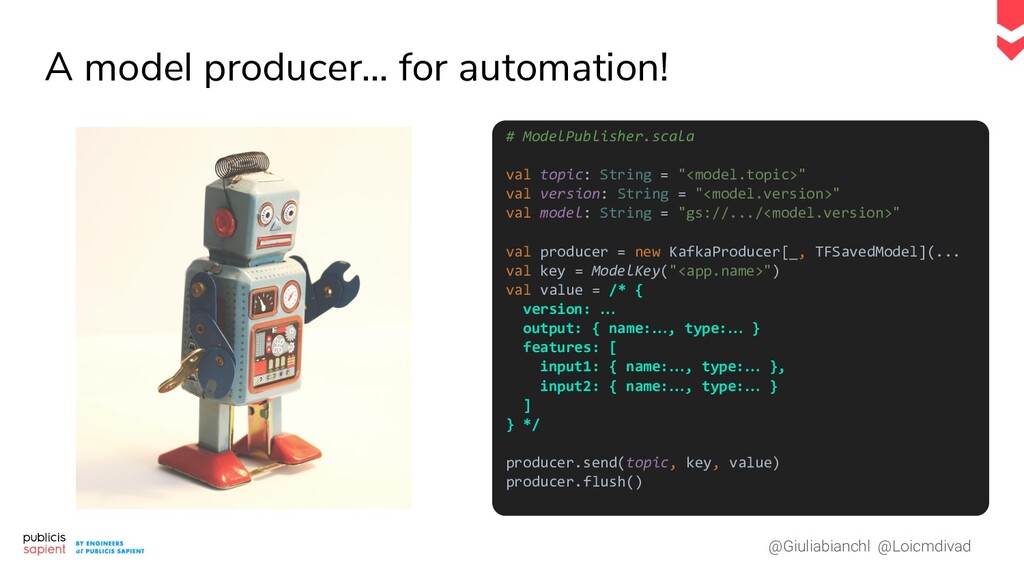
@Giuliabianchl @Loicmdivad A model producer… for automation! # ModelPublisher.scala val
topic: String = "<model.topic>" val version: String = "<model.version>" val model: String = "gs://.../<model.version>" val producer = new KafkaProducer[_, TFSavedModel](... val key = ModelKey("<app.name>") val value = // … producer.send(topic, key, value) producer.flush() -
@Giuliabianchl @Loicmdivad A model producer… for automation! # ModelPublisher.scala val
topic: String = "<model.topic>" val version: String = "<model.version>" val model: String = "gs://.../<model.version>" val producer = new KafkaProducer[_, TFSavedModel](... val key = ModelKey("<app.name>") val value = /* { version: … output: { name:…, type:… } features: [ input1: { name:…, type:… }, input2: { name:…, type:… } ] } */ producer.send(topic, key, value) producer.flush() -
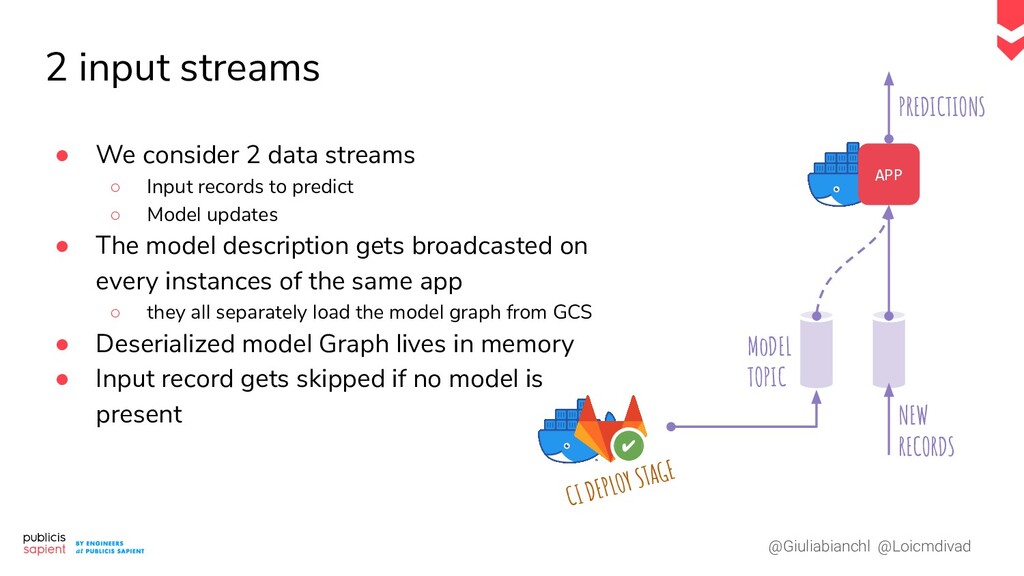
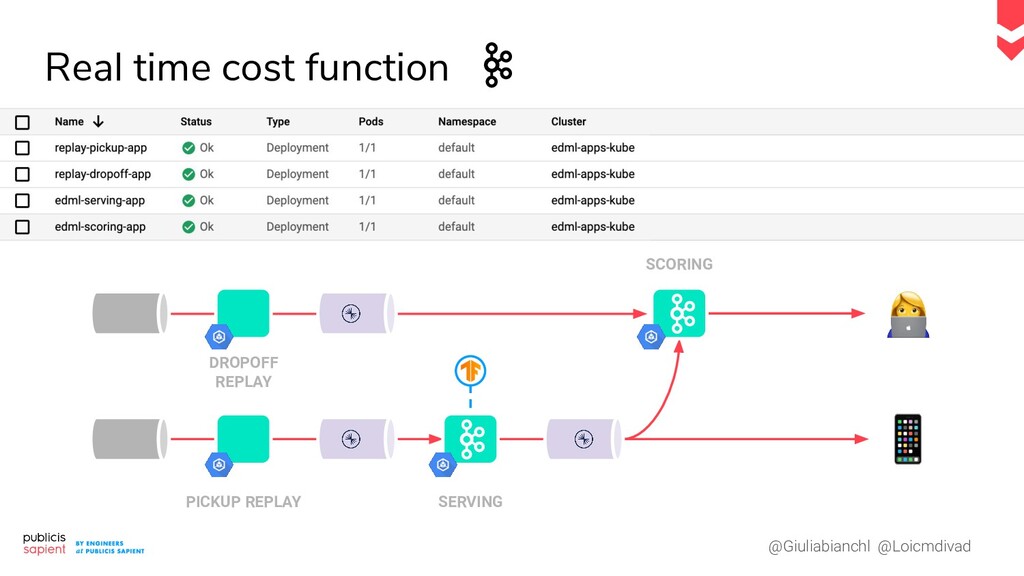
@Giuliabianchl @Loicmdivad 2 input streams • We consider 2 data
streams ◦ Input records to predict ◦ Model updates • The model description gets broadcasted on every instances of the same app ◦ they all separately load the model graph from GCS • Deserialized model Graph lives in memory • Input record gets skipped if no model is present APP CI DEPLOY STAGE MoDEL TOPIC NEW RECORDS PREDICTIONS -
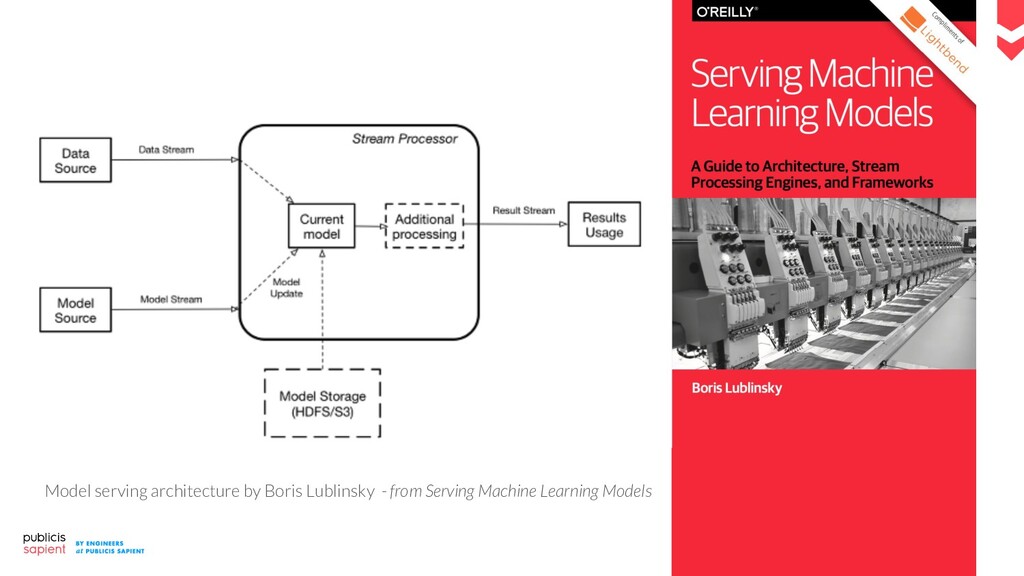
@Giuliabianchl @Loicmdivad Model serving architecture by Boris Lublinsky - from
Serving Machine Learning Models -
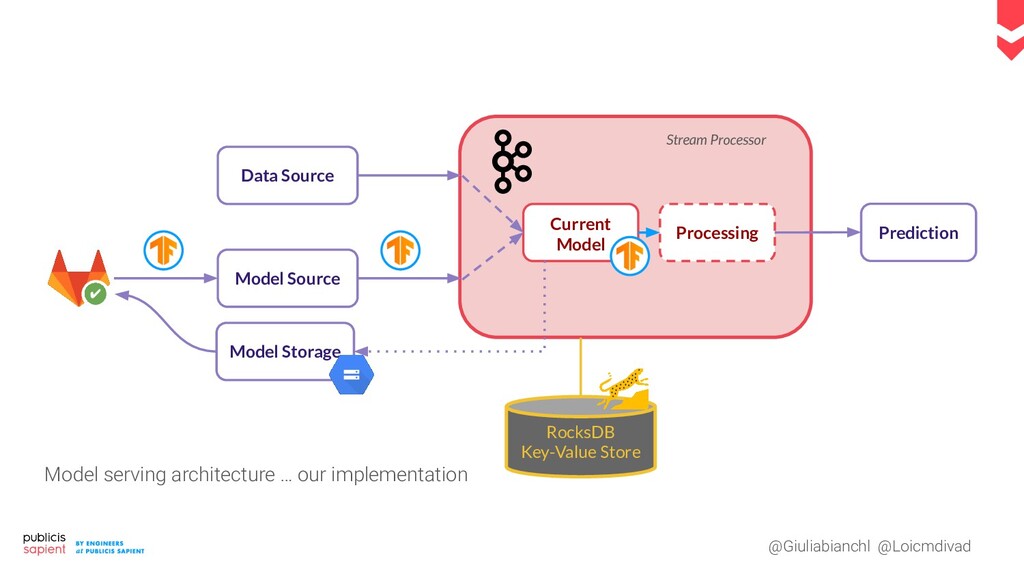
@Giuliabianchl @Loicmdivad Model serving architecture … our implementation Data Source
Model Source Model Storage Current Model Processing Prediction Stream Processor RocksDB Key-Value Store -
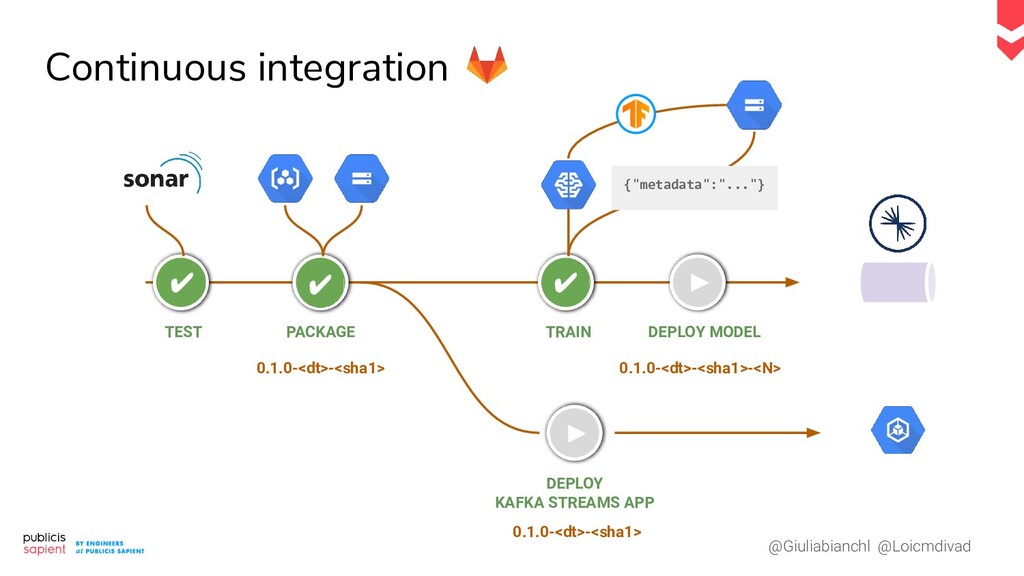
@Giuliabianchl @Loicmdivad Continuous integration TEST ► ► PACKAGE TRAIN DEPLOY
MODEL 0.1.0-<dt>-<sha1> 0.1.0-<dt>-<sha1>-<N> 0.1.0-<dt>-<sha1> {"metadata":"..."} DEPLOY KAFKA STREAMS APP -
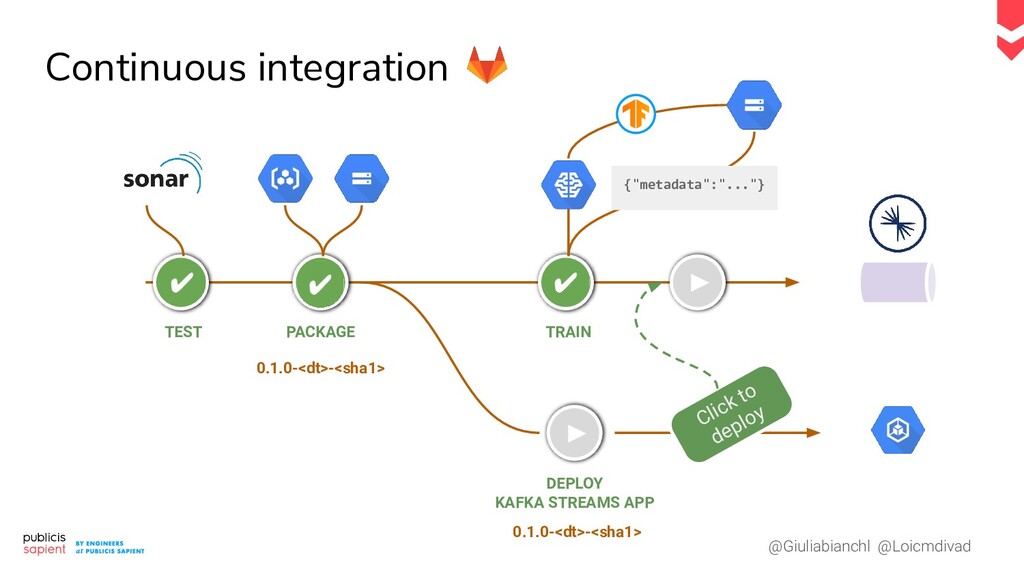
@Giuliabianchl @Loicmdivad Continuous integration TEST ► ► PACKAGE TRAIN 0.1.0-<dt>-<sha1>
0.1.0-<dt>-<sha1> {"metadata":"..."} DEPLOY KAFKA STREAMS APP Click to deploy -
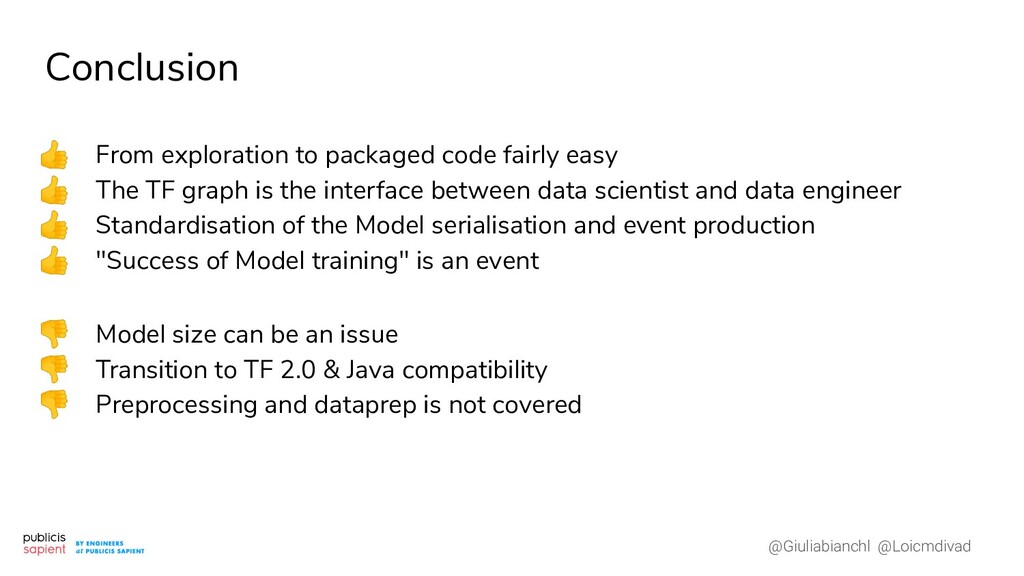
@Giuliabianchl @Loicmdivad Conclusion 👍 From exploration to packaged code fairly
easy 👍 The TF graph is the interface between data scientist and data engineer 👍 Standardisation of the Model serialisation and event production 👍 "Success of Model training" is an event 👎 Model size can be an issue 👎 Transition to TF 2.0 & Java compatibility 👎 Preprocessing and dataprep is not covered -
@Giuliabianchl @Loicmdivad PICTURES • Photo by Dimon Blr on Unsplash
• Photo by Miryam León on Unsplash • Photo by Negative Space from Pexels • Photo by Gerrie van der Walt on Unsplash • Photo by Todd DeSantis on Unsplash • Photo by Rock'n Roll Monkey on Unsplash • Photo by Denys Nevozhai on Unsplash • Photo by Denys Nevozhai on Unsplash