as an inverse search or searching backwards. • Usually you store documents and and execute a query to get back the matching subset of the documents. • With the percolator you store the queries and use a document to get back the matching subset of queries.
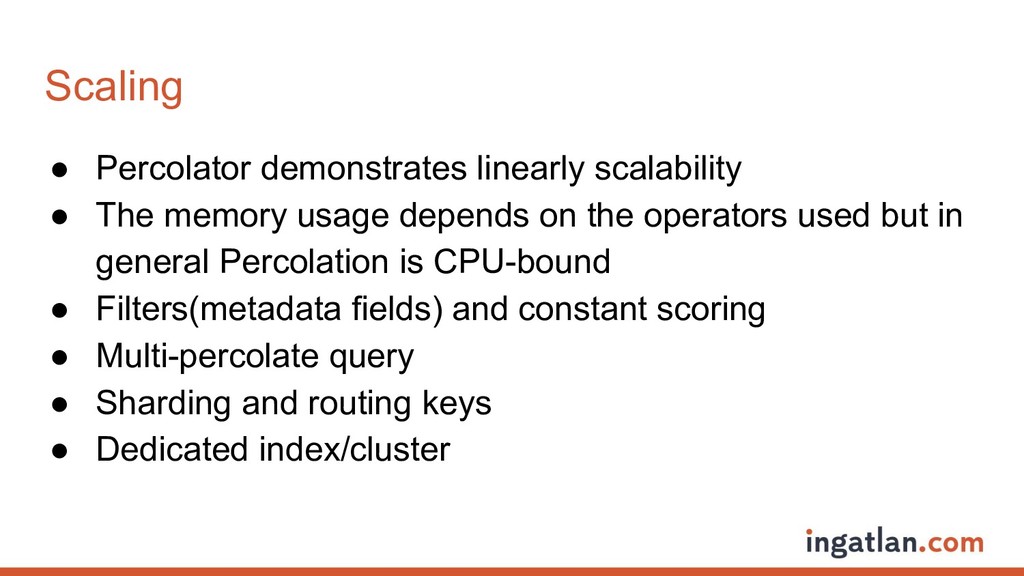
depends on the operators used but in general Percolation is CPU-bound • Filters(metadata fields) and constant scoring • Multi-percolate query • Sharding and routing keys • Dedicated index/cluster


 masakiokuda
 odashi
 shogo4131
 ueponx
 tetsuya28
 yut0naga1_fa
 rfdnxbro
 nttcom
 pfn
 colopl
 mohab1
 takuroabe
 sergeychernyshev
 bkeepers
 axbom
 csswizardry
 lara
 frankvandijk
 khoart
 soudai
 inesmontani
 joshbly
 jeffersonlam