Share
Embed
Accelerated Haskell Arrays
This talk provides on overview over the embedded array language Accelerate, which enables the programming of GPUs in Haskell. See also https://github.com/AccelerateHS/accelerate-examples
Manuel Chakravarty PRO
December 18, 2012
Transcript
56 slides
-
ACCELERATED HASKELL ARRAYS Manuel M T Chakravarty University of New
South Wales INCLUDES JOINT WORK WITH Gabriele Keller Sean Lee Ben Lippmeier Trevor McDonell Simon Peyton Jones Thursday, 16 August 12 -
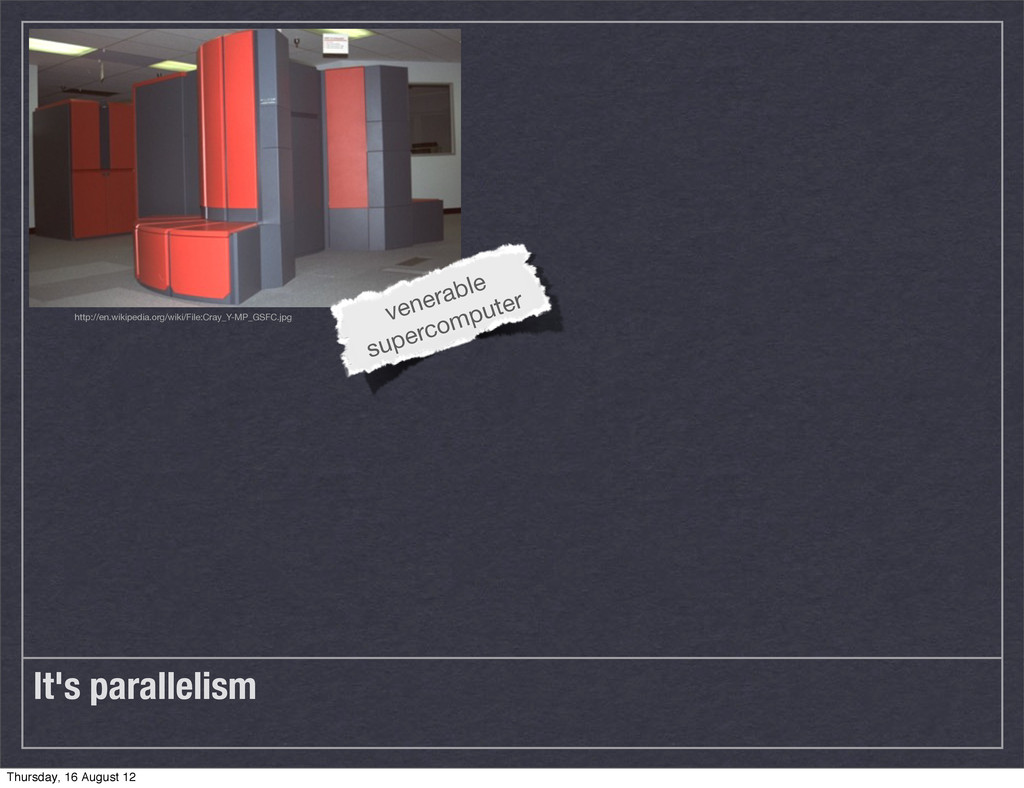
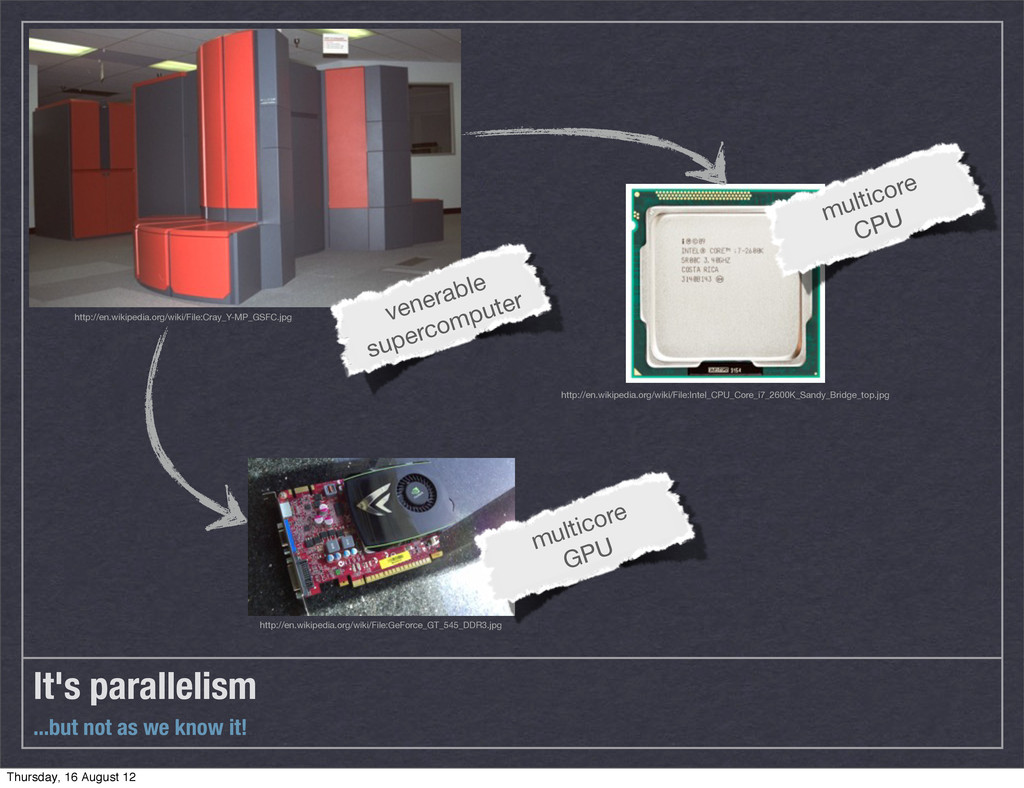
It's parallelism ...but not as we know it! http://en.wikipedia.org/wiki/File:Cray_Y-MP_GSFC.jpg http://en.wikipedia.org/wiki/File:GeForce_GT_545_DDR3.jpg
http://en.wikipedia.org/wiki/File:Intel_CPU_Core_i7_2600K_Sandy_Bridge_top.jpg venerable supercomputer multicore GPU multicore CPU Thursday, 16 August 12 -
Our goals Exploit parallelism of commodity hardware easily: ‣ Performance
is important, but… ‣ …productivity is more important. Thursday, 16 August 12 -
Our goals Exploit parallelism of commodity hardware easily: ‣ Performance
is important, but… ‣ …productivity is more important. Semi-automatic parallelism ‣ Programmer supplies a parallel algorithm ‣ No explicit concurrency (no concurrency control, no races, no deadlocks) Thursday, 16 August 12 -
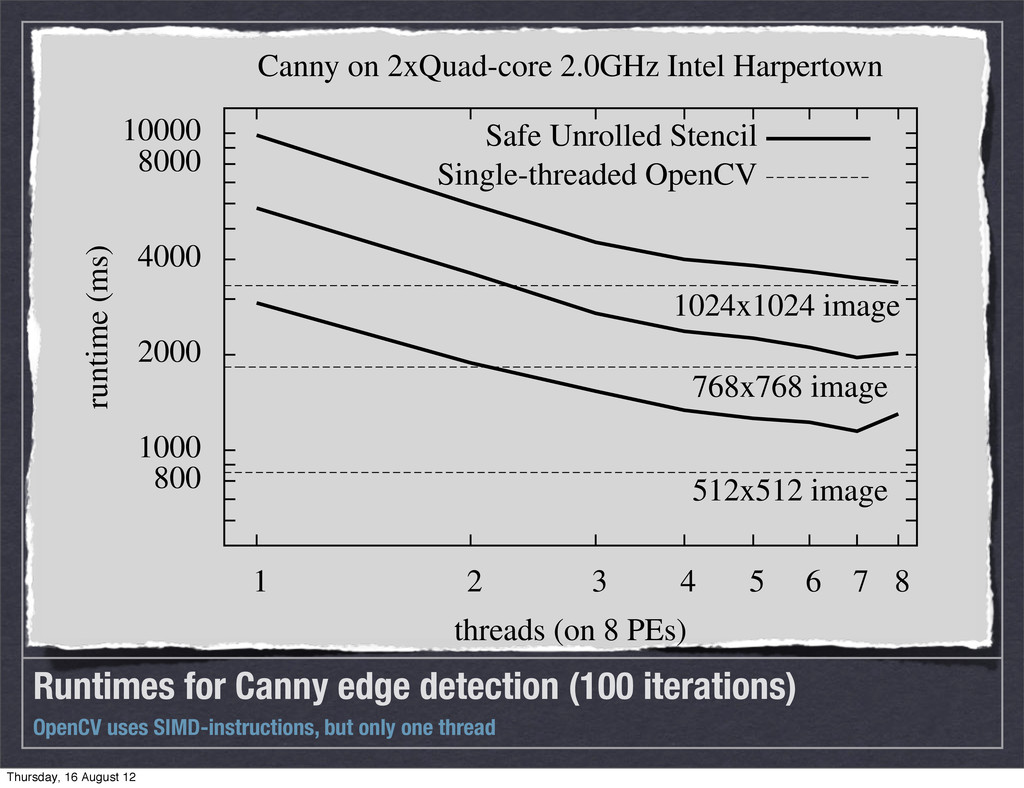
1 2 3 4 5 6 7 8 800 1000
2000 4000 8000 10000 1 2 3 4 5 6 7 8 runtime (ms) threads (on 8 PEs) Canny on 2xQuad-core 2.0GHz Intel Harpertown 1024x1024 image 768x768 image 512x512 image Safe Unrolled Stencil Single-threaded OpenCV Figure 15. Sobel and Canny runtimes, 100 iterations Runtimes for Canny edge detection (100 iterations) OpenCV uses SIMD-instructions, but only one thread Thursday, 16 August 12 -
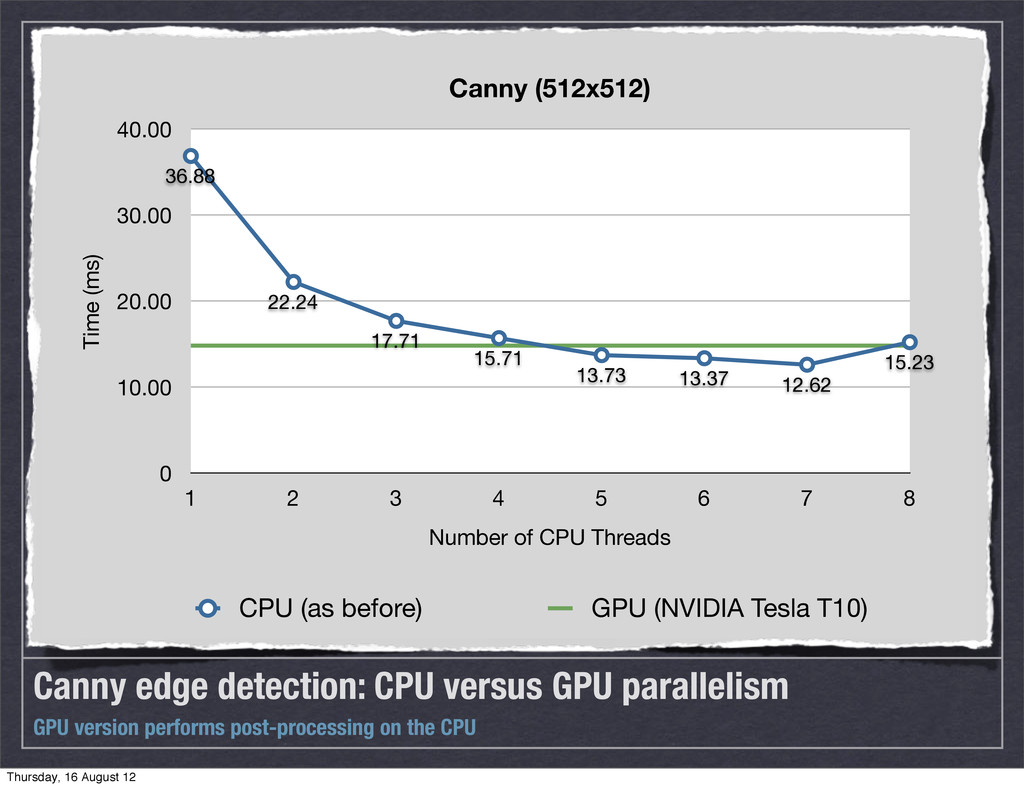
Canny edge detection: CPU versus GPU parallelism GPU version performs
post-processing on the CPU 0 10.00 20.00 30.00 40.00 1 2 3 4 5 6 7 8 36.88 22.24 17.71 15.71 13.73 13.37 12.62 15.23 Canny (512x512) Time (ms) Number of CPU Threads CPU (as before) GPU (NVIDIA Tesla T10) Thursday, 16 August 12 -
0 0.5 1 1.5 2 2.5 64 96 128 192
256 384 512 768 1024 relative runtime matrix width C Gauss-Seidel C Jacobi Repa -N1 Repa -N2 Repa -N8 Figure 12. Runtimes for Fluid Flow Solver Runtimes for Jos Stam's Fluid Flow Solver We can beat C! Thursday, 16 August 12 -
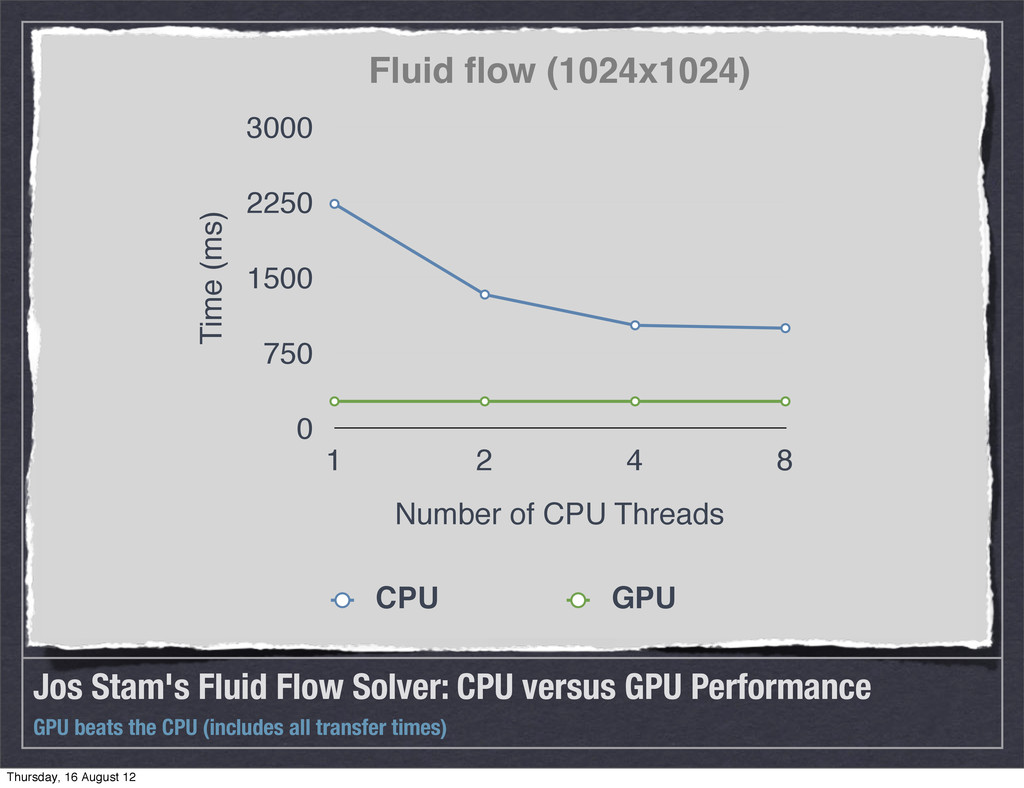
Jos Stam's Fluid Flow Solver: CPU versus GPU Performance GPU
beats the CPU (includes all transfer times) 0 750 1500 2250 3000 1 2 4 8 Fluid flow (1024x1024) Time (ms) Number of CPU Threads CPU GPU Thursday, 16 August 12 -
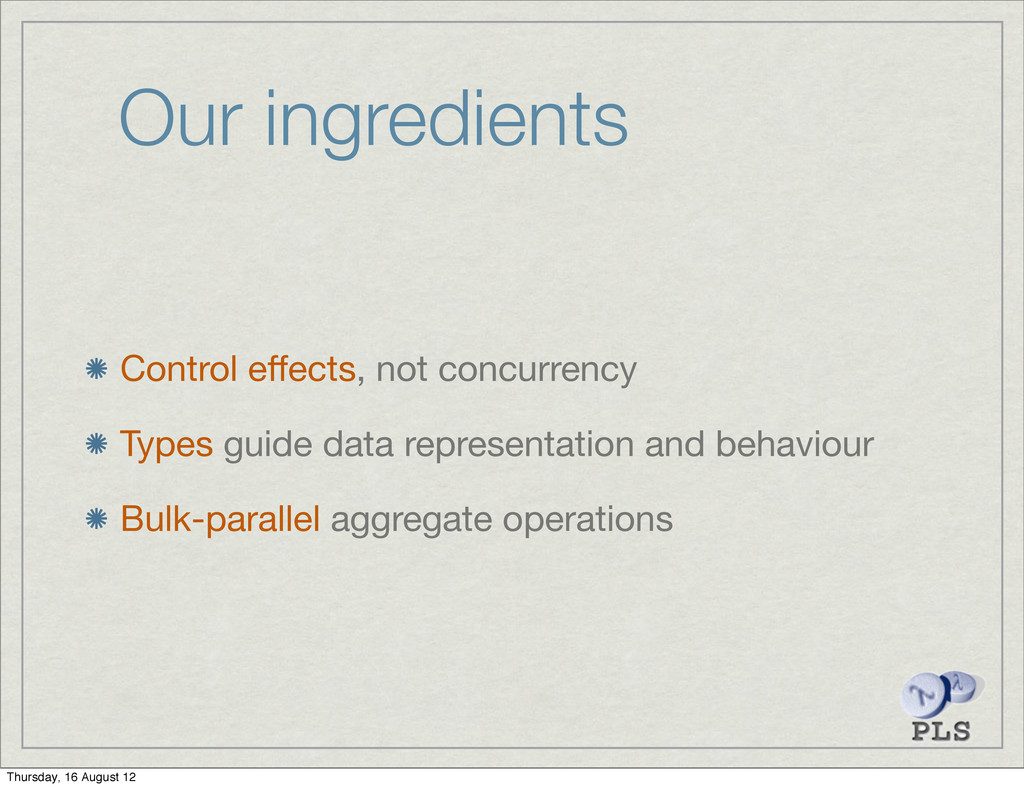
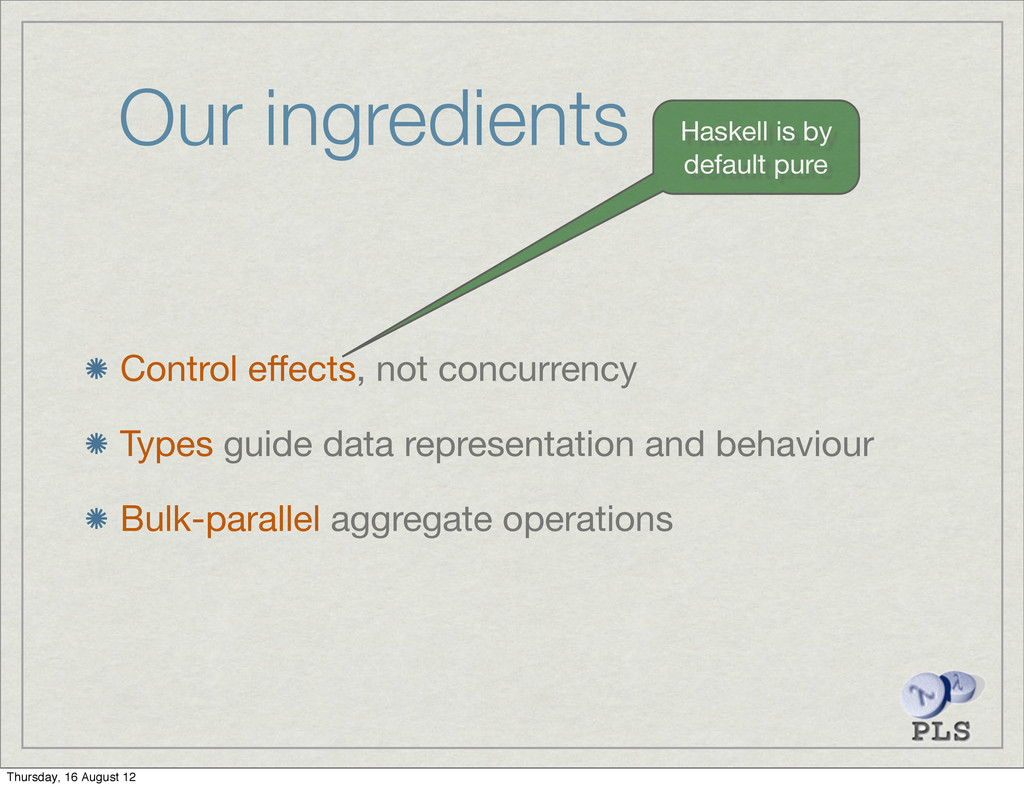
Our ingredients Control effects, not concurrency Types guide data representation
and behaviour Bulk-parallel aggregate operations Thursday, 16 August 12 -
Our ingredients Control effects, not concurrency Types guide data representation
and behaviour Bulk-parallel aggregate operations Haskell is by default pure Thursday, 16 August 12 -
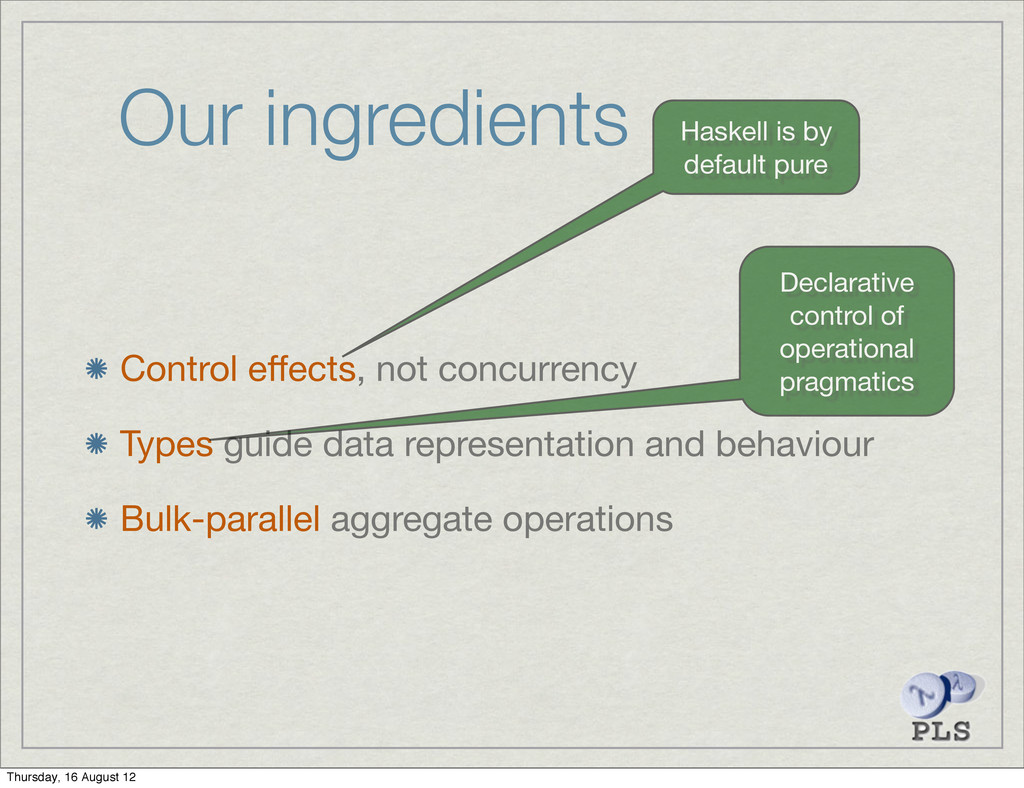
Our ingredients Control effects, not concurrency Types guide data representation
and behaviour Bulk-parallel aggregate operations Haskell is by default pure Declarative control of operational pragmatics Thursday, 16 August 12 -
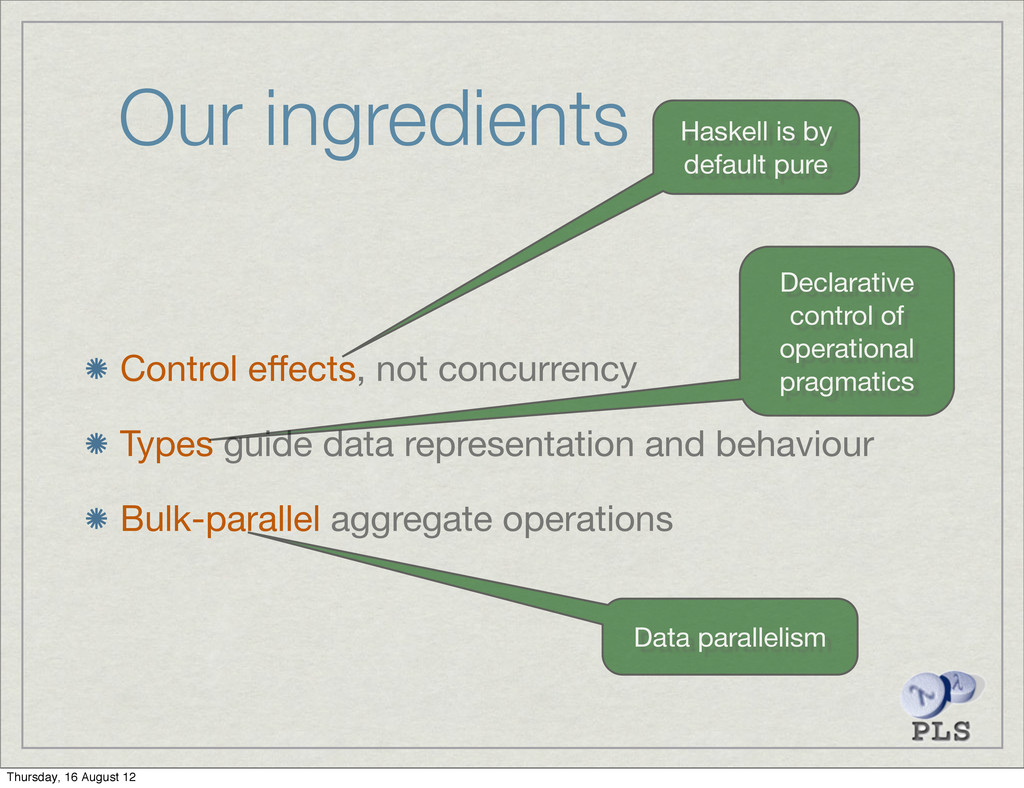
Our ingredients Control effects, not concurrency Types guide data representation
and behaviour Bulk-parallel aggregate operations Haskell is by default pure Declarative control of operational pragmatics Data parallelism Thursday, 16 August 12 -
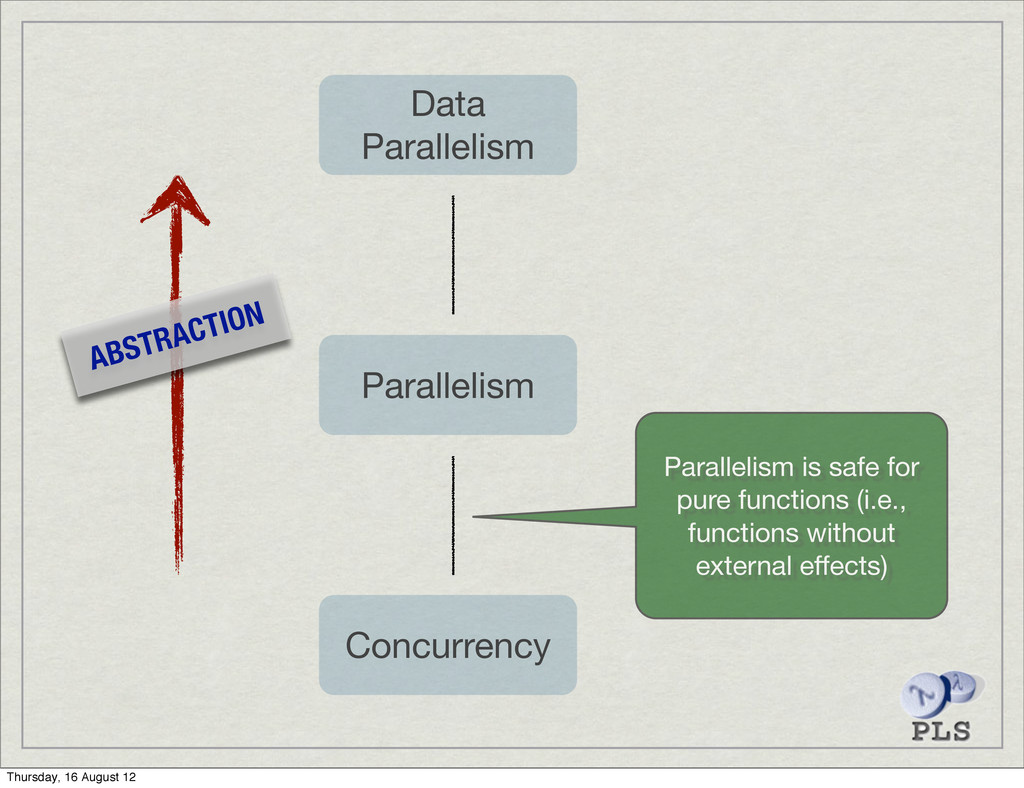
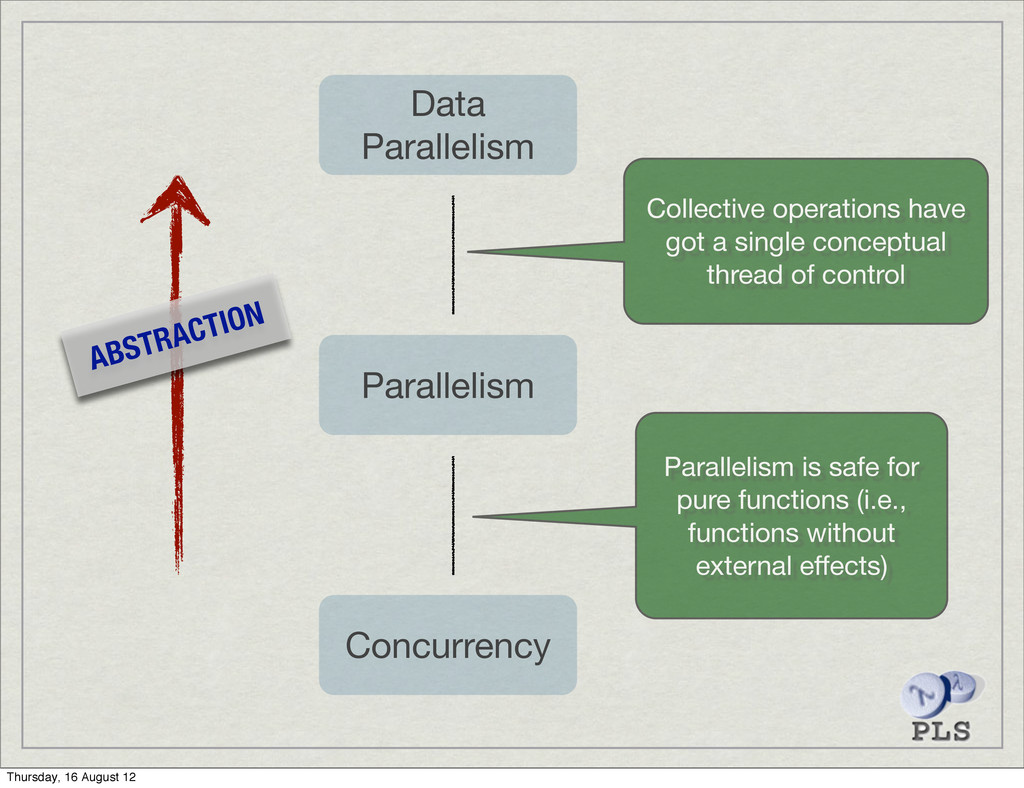
Concurrency Parallelism Data Parallelism ABSTRACTION Parallelism is safe for pure
functions (i.e., functions without external effects) Thursday, 16 August 12 -
Concurrency Parallelism Data Parallelism ABSTRACTION Parallelism is safe for pure
functions (i.e., functions without external effects) Collective operations have got a single conceptual thread of control Thursday, 16 August 12 -
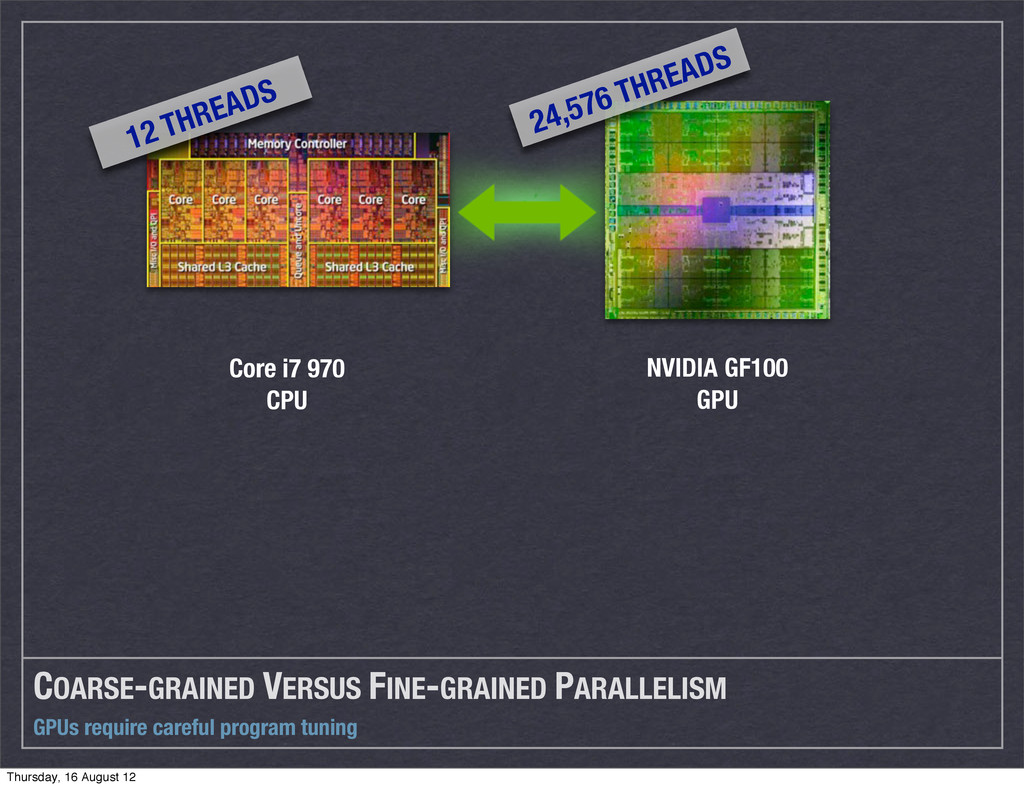
GPUs require careful program tuning COARSE-GRAINED VERSUS FINE-GRAINED PARALLELISM Core
i7 970 CPU NVIDIA GF100 GPU 12 THREADS 24,576 THREADS Thursday, 16 August 12 -
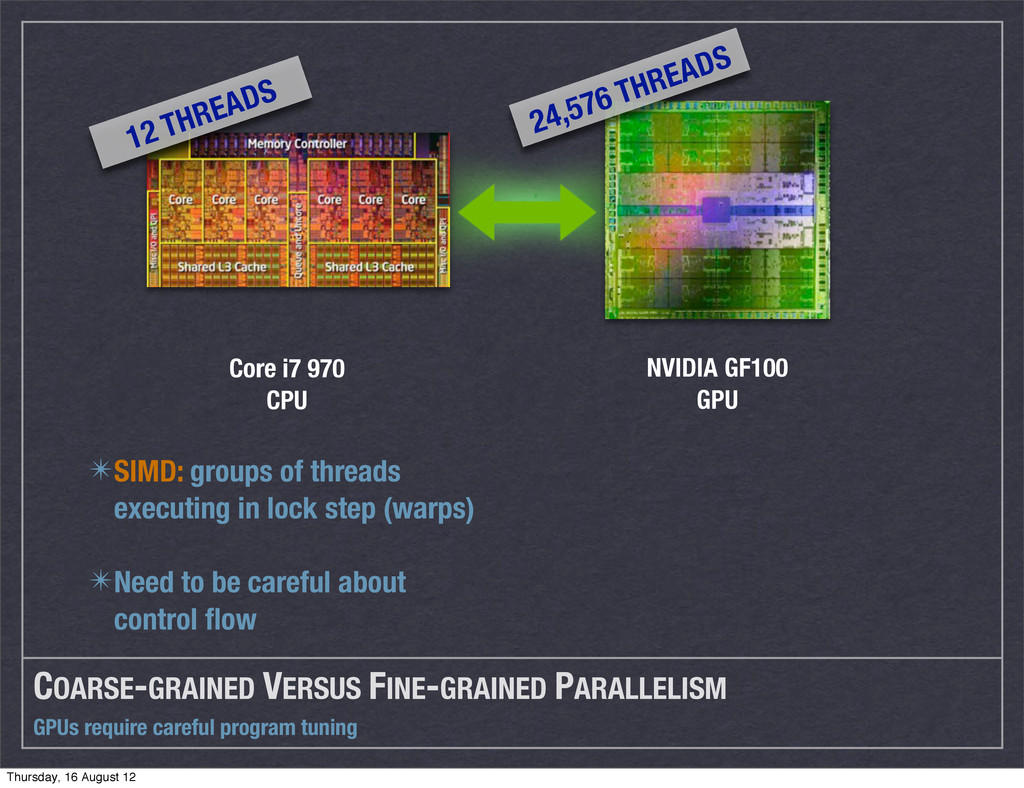
GPUs require careful program tuning COARSE-GRAINED VERSUS FINE-GRAINED PARALLELISM Core
i7 970 CPU NVIDIA GF100 GPU 12 THREADS 24,576 THREADS ✴SIMD: groups of threads executing in lock step (warps) ✴Need to be careful about control flow Thursday, 16 August 12 -
GPUs require careful program tuning COARSE-GRAINED VERSUS FINE-GRAINED PARALLELISM Core
i7 970 CPU NVIDIA GF100 GPU 12 THREADS 24,576 THREADS ✴Latency hiding: optimised for regular memory access patterns ✴Optimise memory access ✴SIMD: groups of threads executing in lock step (warps) ✴Need to be careful about control flow Thursday, 16 August 12 -
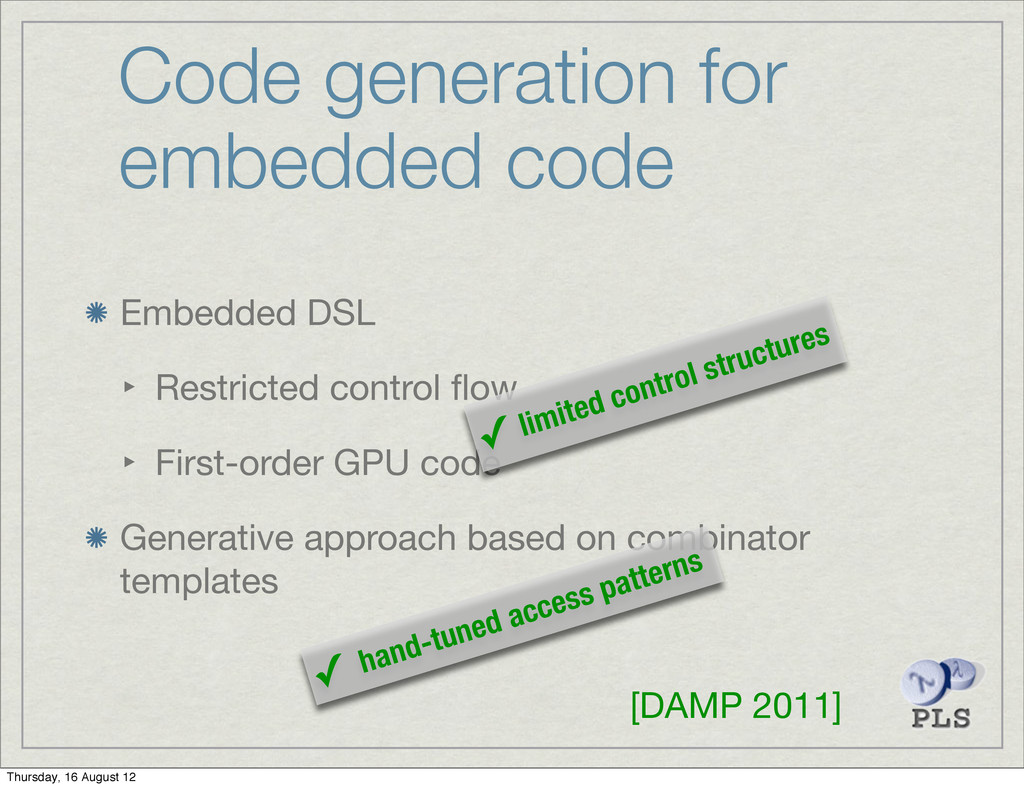
Code generation for embedded code Embedded DSL ‣ Restricted control
flow ‣ First-order GPU code Generative approach based on combinator templates Thursday, 16 August 12 -
Code generation for embedded code Embedded DSL ‣ Restricted control
flow ‣ First-order GPU code Generative approach based on combinator templates ✓ limited control structures Thursday, 16 August 12 -
Code generation for embedded code Embedded DSL ‣ Restricted control
flow ‣ First-order GPU code Generative approach based on combinator templates ✓ limited control structures ✓ hand-tuned access patterns [DAMP 2011] Thursday, 16 August 12 -
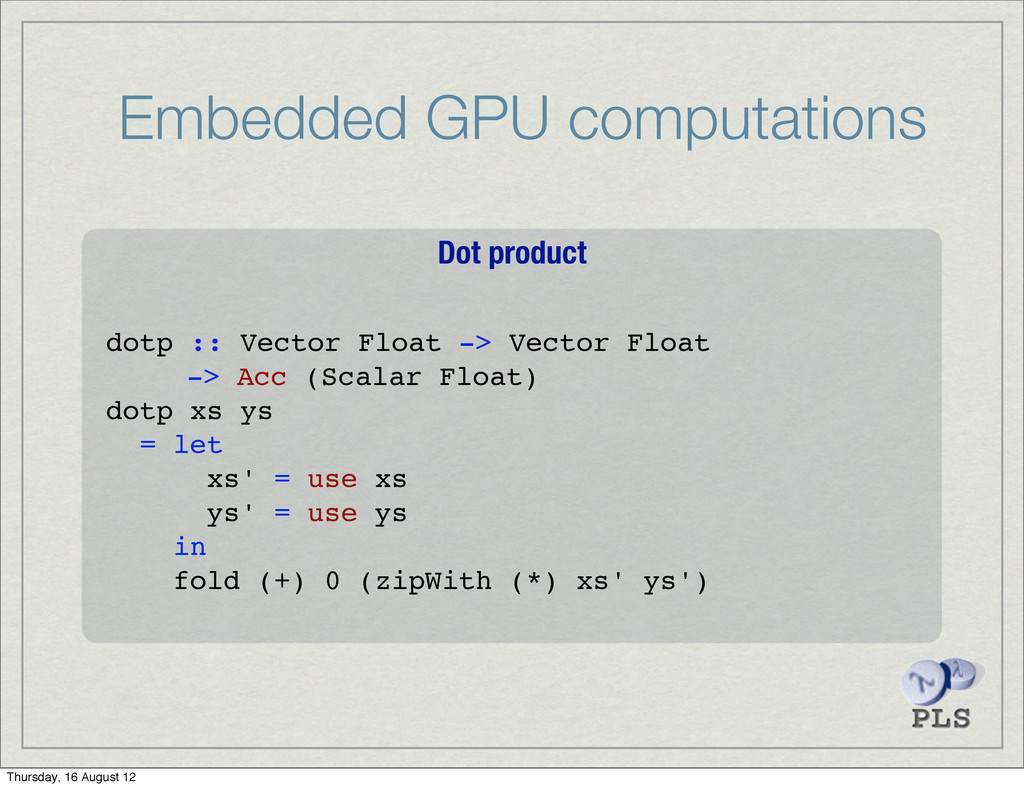
Embedded GPU computations Dot product dotp :: Vector Float ->
Vector Float -> Acc (Scalar Float) dotp xs ys = let xs' = use xs ys' = use ys in fold (+) 0 (zipWith (*) xs' ys') Thursday, 16 August 12 -
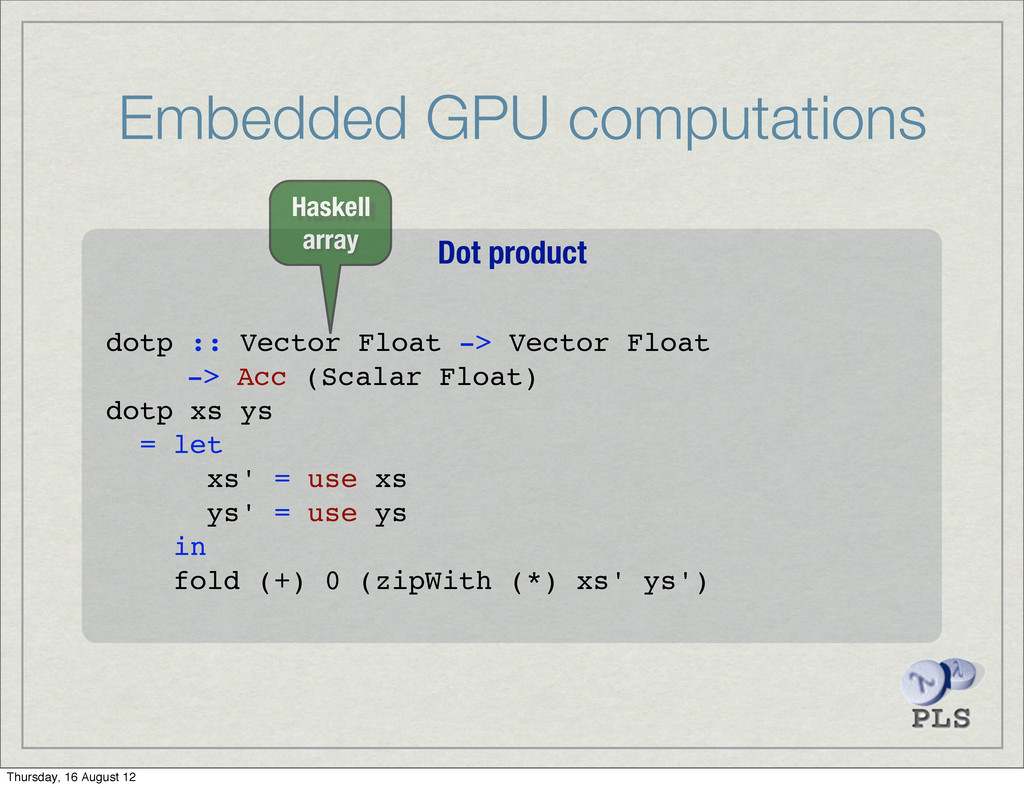
Embedded GPU computations Dot product dotp :: Vector Float ->
Vector Float -> Acc (Scalar Float) dotp xs ys = let xs' = use xs ys' = use ys in fold (+) 0 (zipWith (*) xs' ys') Haskell array Thursday, 16 August 12 -
Embedded GPU computations Dot product dotp :: Vector Float ->
Vector Float -> Acc (Scalar Float) dotp xs ys = let xs' = use xs ys' = use ys in fold (+) 0 (zipWith (*) xs' ys') Haskell array Embedded array = desc. of array comps Thursday, 16 August 12 -
Embedded GPU computations Dot product dotp :: Vector Float ->
Vector Float -> Acc (Scalar Float) dotp xs ys = let xs' = use xs ys' = use ys in fold (+) 0 (zipWith (*) xs' ys') Haskell array Embedded array = desc. of array comps Lift Haskell arrays into EDSL — may trigger host➙device transfer Thursday, 16 August 12 -
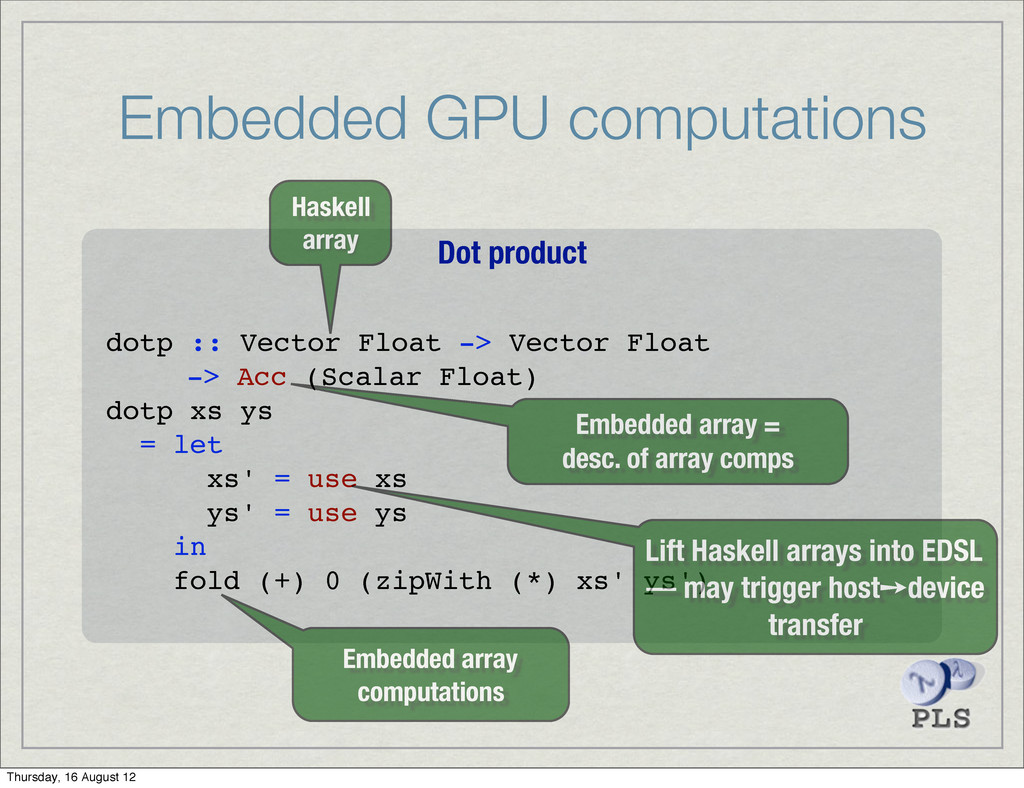
Embedded GPU computations Dot product dotp :: Vector Float ->
Vector Float -> Acc (Scalar Float) dotp xs ys = let xs' = use xs ys' = use ys in fold (+) 0 (zipWith (*) xs' ys') Haskell array Embedded array = desc. of array comps Lift Haskell arrays into EDSL — may trigger host➙device transfer Embedded array computations Thursday, 16 August 12 -
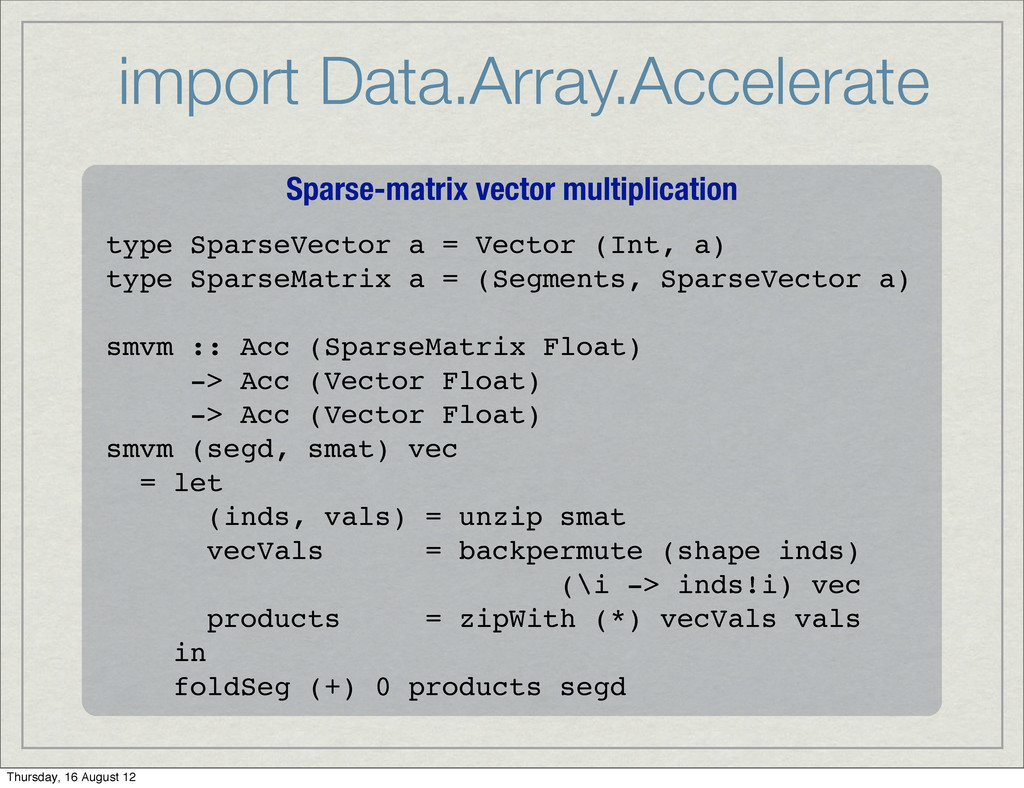
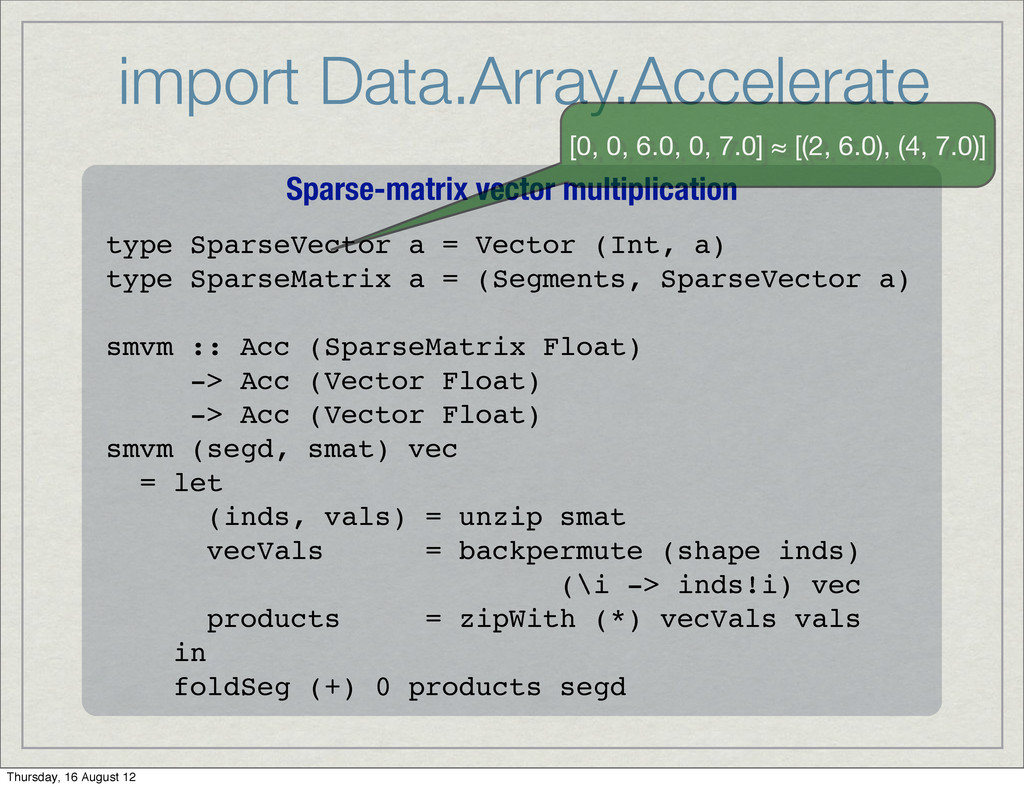
import Data.Array.Accelerate Sparse-matrix vector multiplication type SparseVector a = Vector
(Int, a) type SparseMatrix a = (Segments, SparseVector a) smvm :: Acc (SparseMatrix Float) -> Acc (Vector Float) -> Acc (Vector Float) smvm (segd, smat) vec = let (inds, vals) = unzip smat vecVals = backpermute (shape inds) (\i -> inds!i) vec products = zipWith (*) vecVals vals in foldSeg (+) 0 products segd Thursday, 16 August 12 -
import Data.Array.Accelerate Sparse-matrix vector multiplication type SparseVector a = Vector
(Int, a) type SparseMatrix a = (Segments, SparseVector a) smvm :: Acc (SparseMatrix Float) -> Acc (Vector Float) -> Acc (Vector Float) smvm (segd, smat) vec = let (inds, vals) = unzip smat vecVals = backpermute (shape inds) (\i -> inds!i) vec products = zipWith (*) vecVals vals in foldSeg (+) 0 products segd [0, 0, 6.0, 0, 7.0] ≈ [(2, 6.0), (4, 7.0)] Thursday, 16 August 12 -
import Data.Array.Accelerate Sparse-matrix vector multiplication type SparseVector a = Vector
(Int, a) type SparseMatrix a = (Segments, SparseVector a) smvm :: Acc (SparseMatrix Float) -> Acc (Vector Float) -> Acc (Vector Float) smvm (segd, smat) vec = let (inds, vals) = unzip smat vecVals = backpermute (shape inds) (\i -> inds!i) vec products = zipWith (*) vecVals vals in foldSeg (+) 0 products segd [0, 0, 6.0, 0, 7.0] ≈ [(2, 6.0), (4, 7.0)] [[10, 20], [], [30]] ≈ ([2, 0, 1], [10, 20, 30]) Thursday, 16 August 12 -
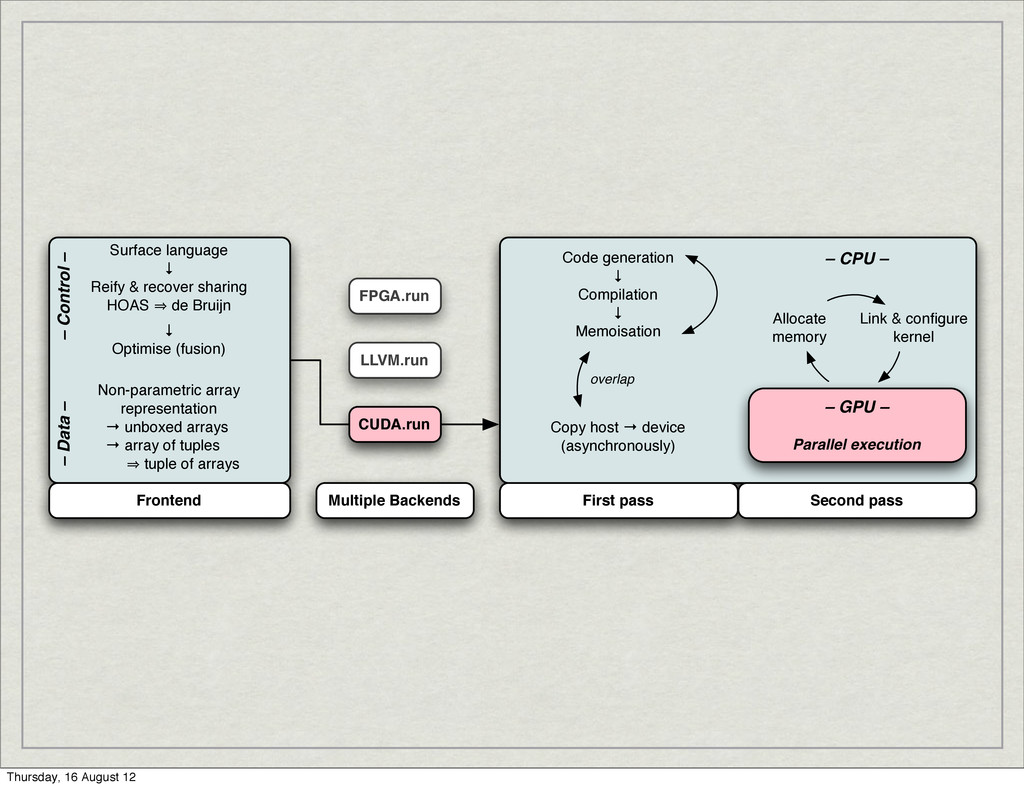
Frontend Multiple Backends First pass Second pass CUDA.run LLVM.run FPGA.run
– Data – – Control – Non-parametric array representation → unboxed arrays → array of tuples 㱺 tuple of arrays Surface language ↓ Reify & recover sharing HOAS 㱺 de Bruijn ↓ Optimise (fusion) Code generation ↓ Compilation ↓ Memoisation Copy host → device (asynchronously) overlap – GPU – Parallel execution – CPU – Allocate memory Link & configure kernel Thursday, 16 August 12 -
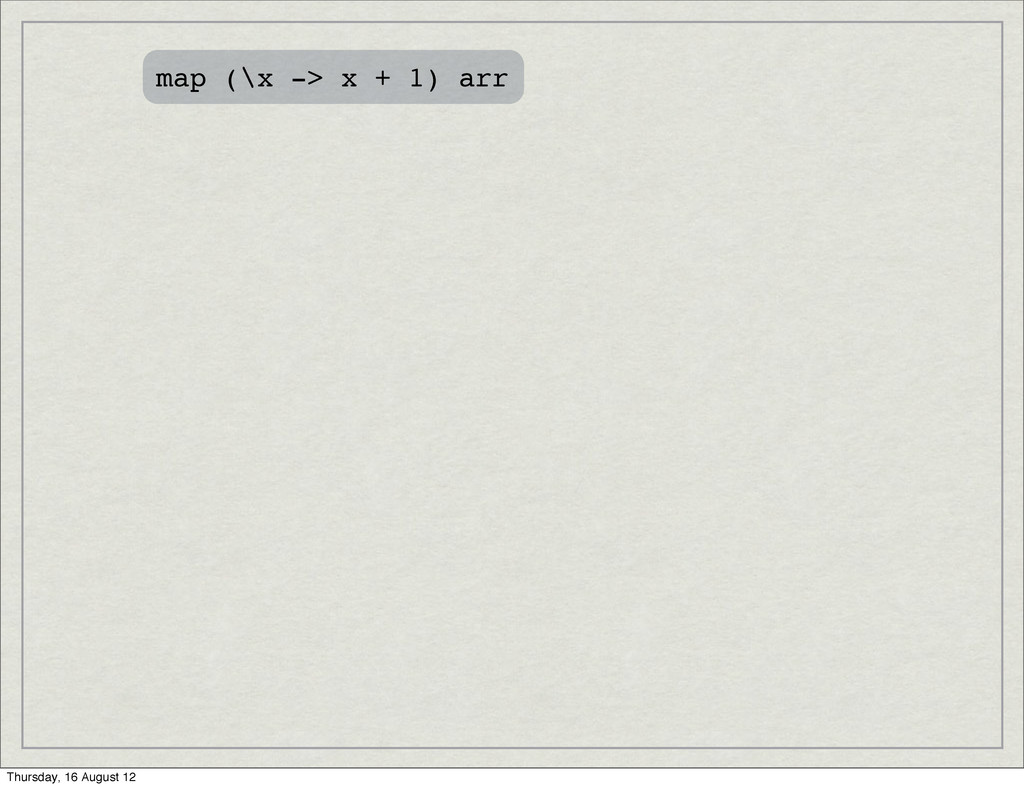
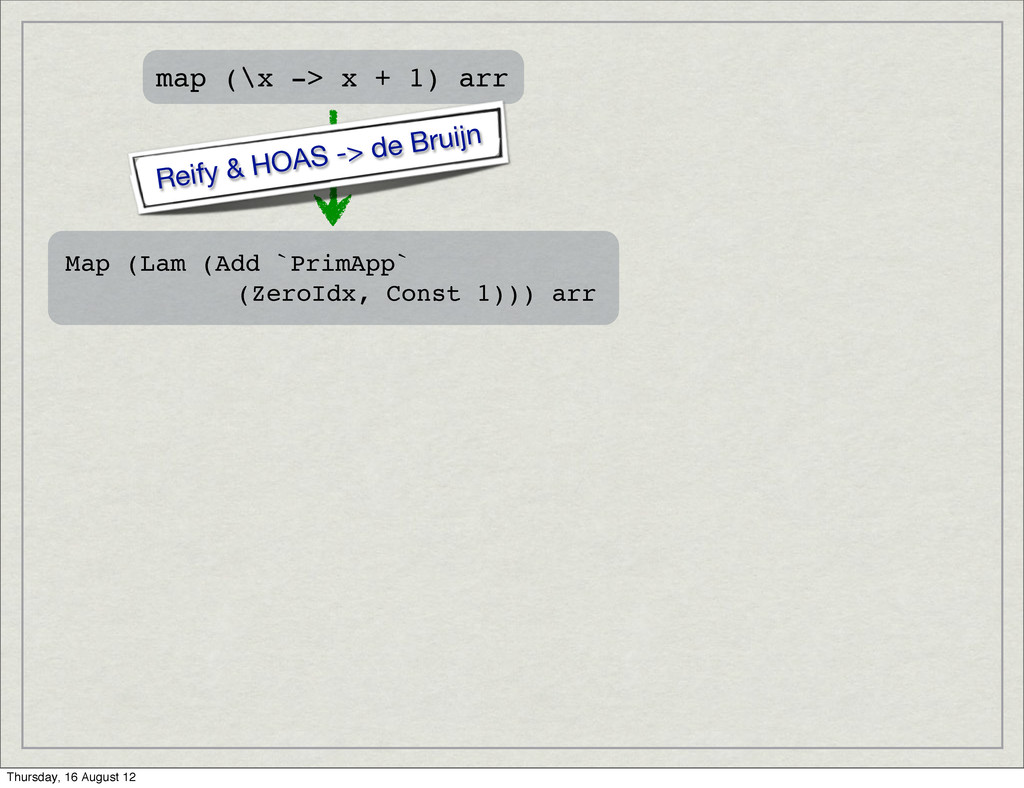
map (\x -> x + 1) arr Reify & HOAS
-> de Bruijn Map (Lam (Add `PrimApp` (ZeroIdx, Const 1))) arr Thursday, 16 August 12 -
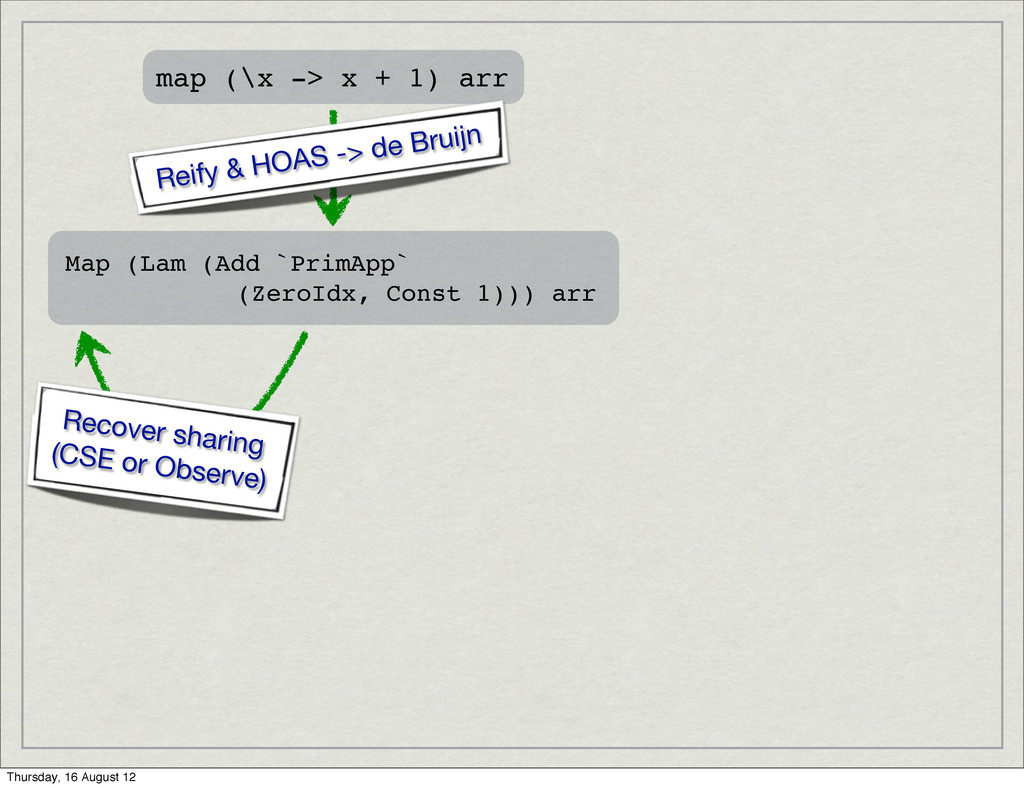
map (\x -> x + 1) arr Reify & HOAS
-> de Bruijn Map (Lam (Add `PrimApp` (ZeroIdx, Const 1))) arr Recover sharing (CSE or Observe) Thursday, 16 August 12 -
map (\x -> x + 1) arr Reify & HOAS
-> de Bruijn Map (Lam (Add `PrimApp` (ZeroIdx, Const 1))) arr Recover sharing (CSE or Observe) Optimisation (Fusion) Thursday, 16 August 12 -
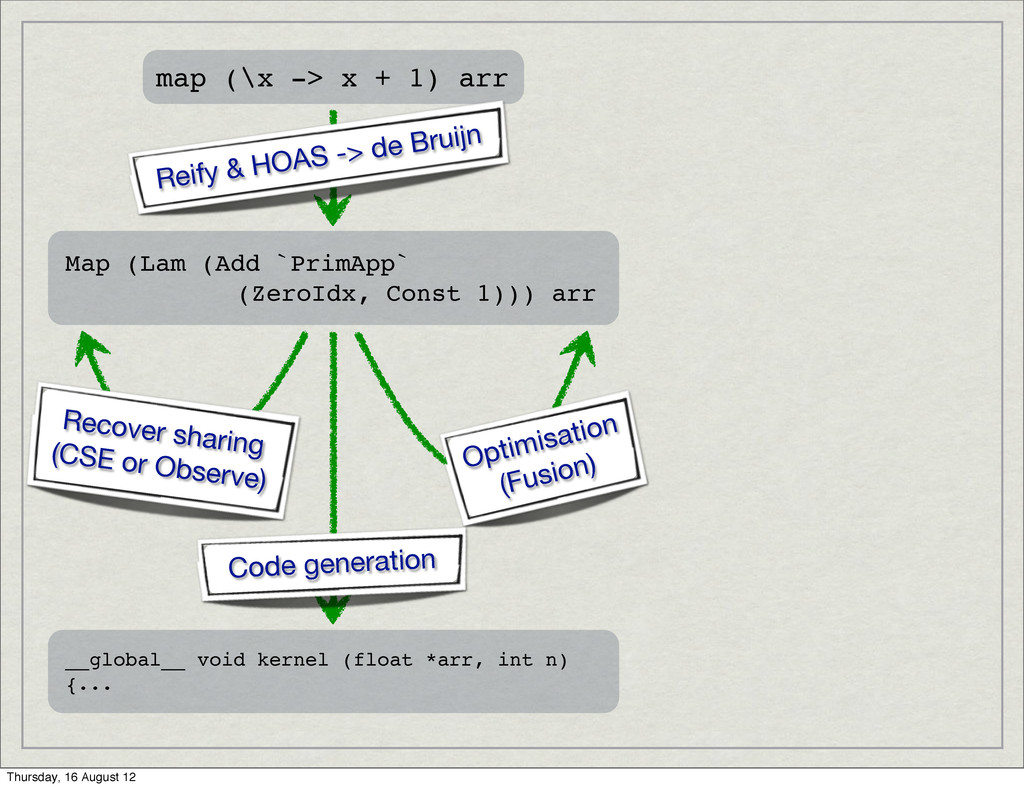
map (\x -> x + 1) arr Reify & HOAS
-> de Bruijn Map (Lam (Add `PrimApp` (ZeroIdx, Const 1))) arr Recover sharing (CSE or Observe) Optimisation (Fusion) __global__ void kernel (float *arr, int n) {... Code generation Thursday, 16 August 12 -
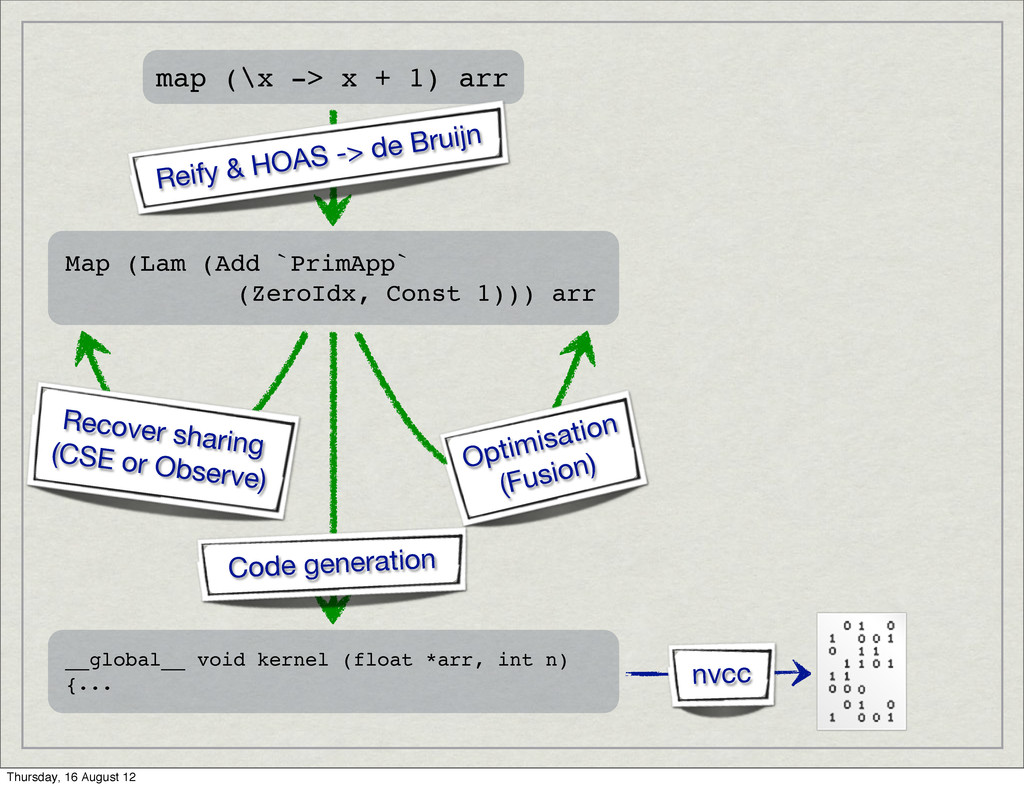
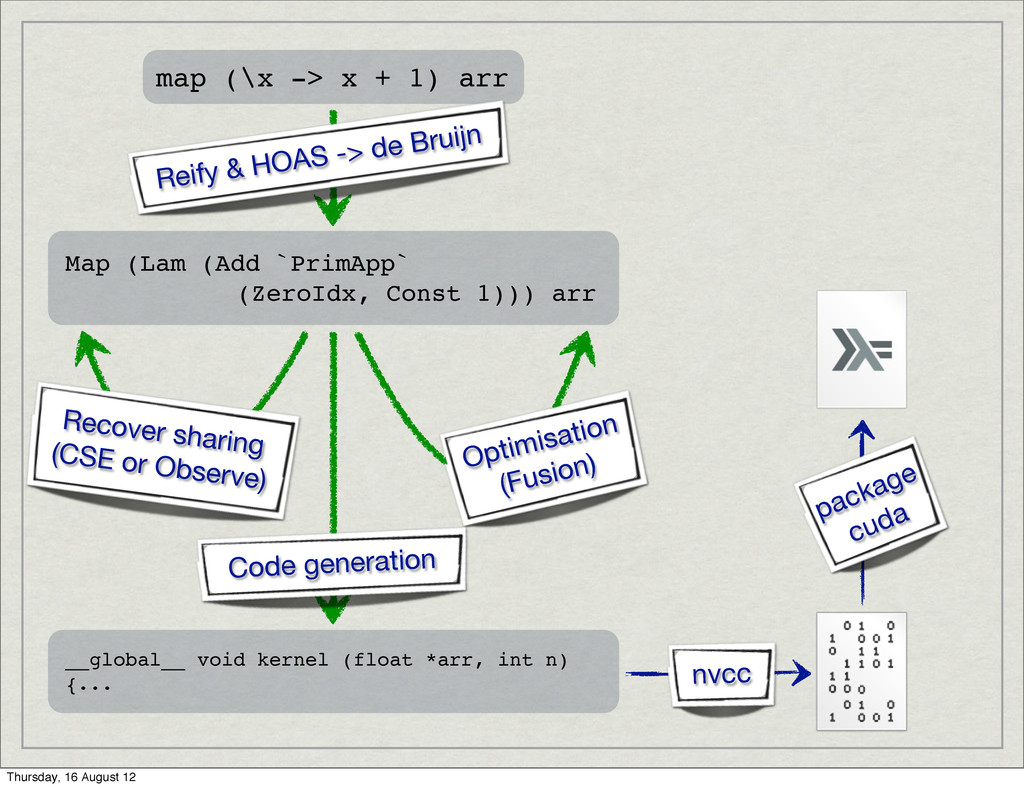
map (\x -> x + 1) arr Reify & HOAS
-> de Bruijn Map (Lam (Add `PrimApp` (ZeroIdx, Const 1))) arr Recover sharing (CSE or Observe) Optimisation (Fusion) __global__ void kernel (float *arr, int n) {... Code generation nvcc Thursday, 16 August 12 -
map (\x -> x + 1) arr Reify & HOAS
-> de Bruijn Map (Lam (Add `PrimApp` (ZeroIdx, Const 1))) arr Recover sharing (CSE or Observe) Optimisation (Fusion) __global__ void kernel (float *arr, int n) {... Code generation nvcc package cuda Thursday, 16 August 12 -
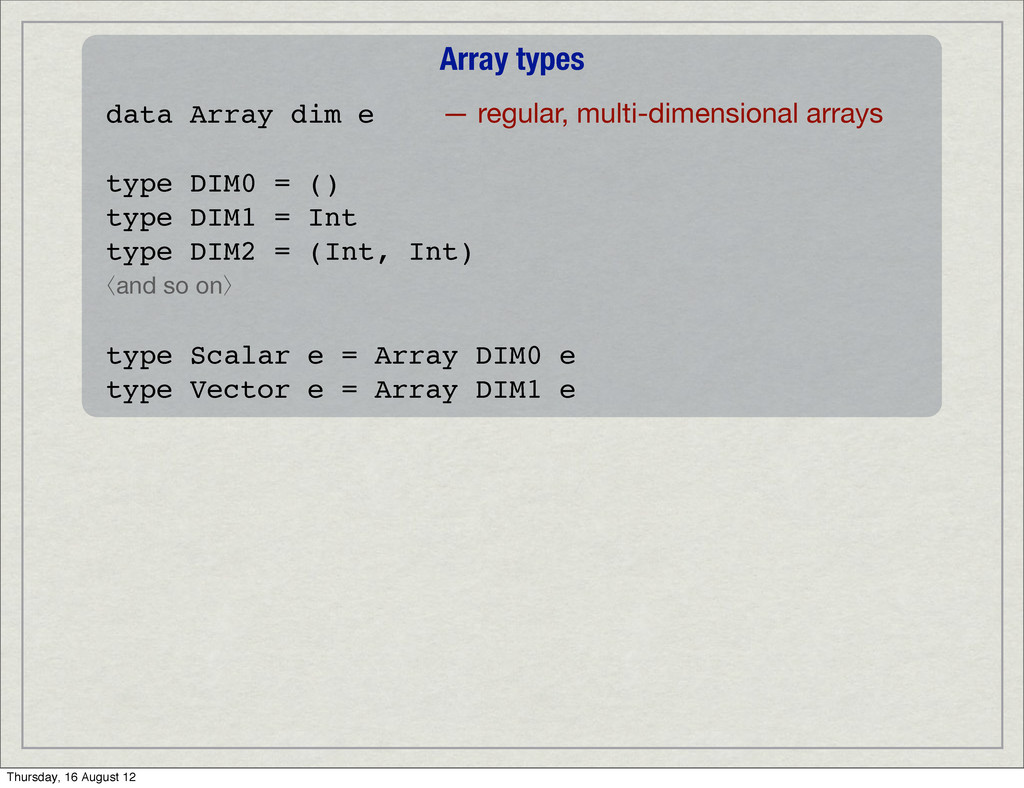
Array types data Array dim e — regular, multi-dimensional arrays
type DIM0 = () type DIM1 = Int type DIM2 = (Int, Int) ⟨and so on⟩ type Scalar e = Array DIM0 e type Vector e = Array DIM1 e Thursday, 16 August 12 -
Array types data Array dim e — regular, multi-dimensional arrays
type DIM0 = () type DIM1 = Int type DIM2 = (Int, Int) ⟨and so on⟩ type Scalar e = Array DIM0 e type Vector e = Array DIM1 e EDSL forms data Exp e — scalar expression form data Acc a — array expression form Thursday, 16 August 12 -
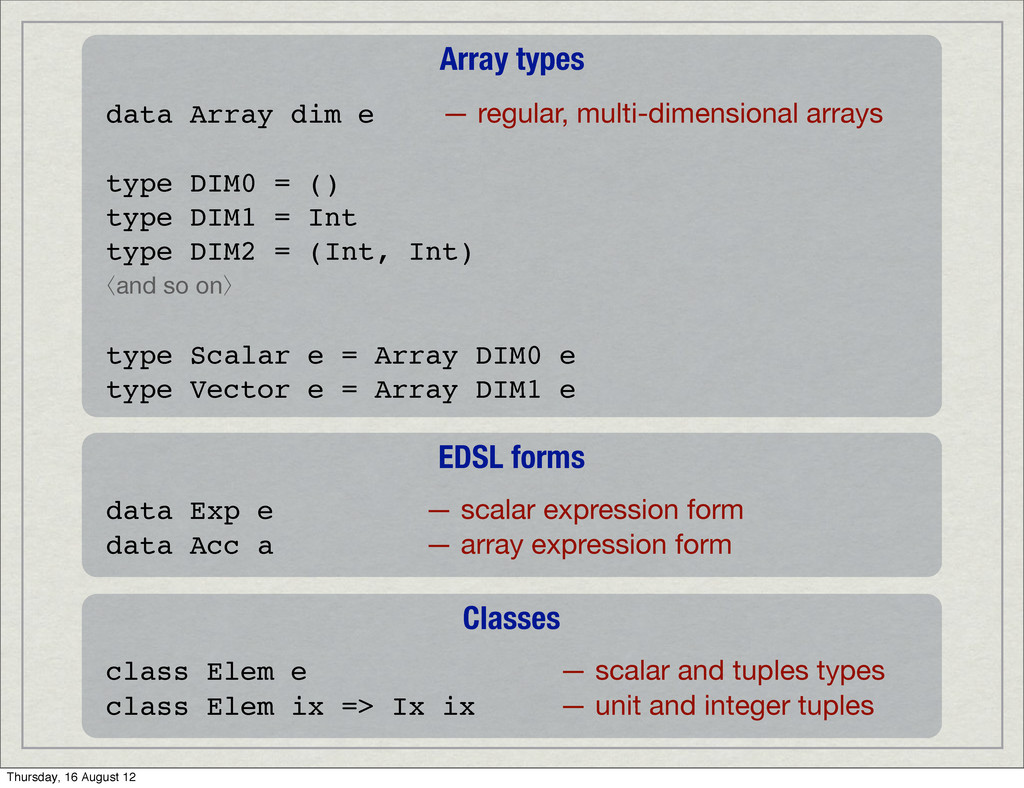
Array types data Array dim e — regular, multi-dimensional arrays
type DIM0 = () type DIM1 = Int type DIM2 = (Int, Int) ⟨and so on⟩ type Scalar e = Array DIM0 e type Vector e = Array DIM1 e EDSL forms data Exp e — scalar expression form data Acc a — array expression form Classes class Elem e — scalar and tuples types class Elem ix => Ix ix — unit and integer tuples Thursday, 16 August 12 -
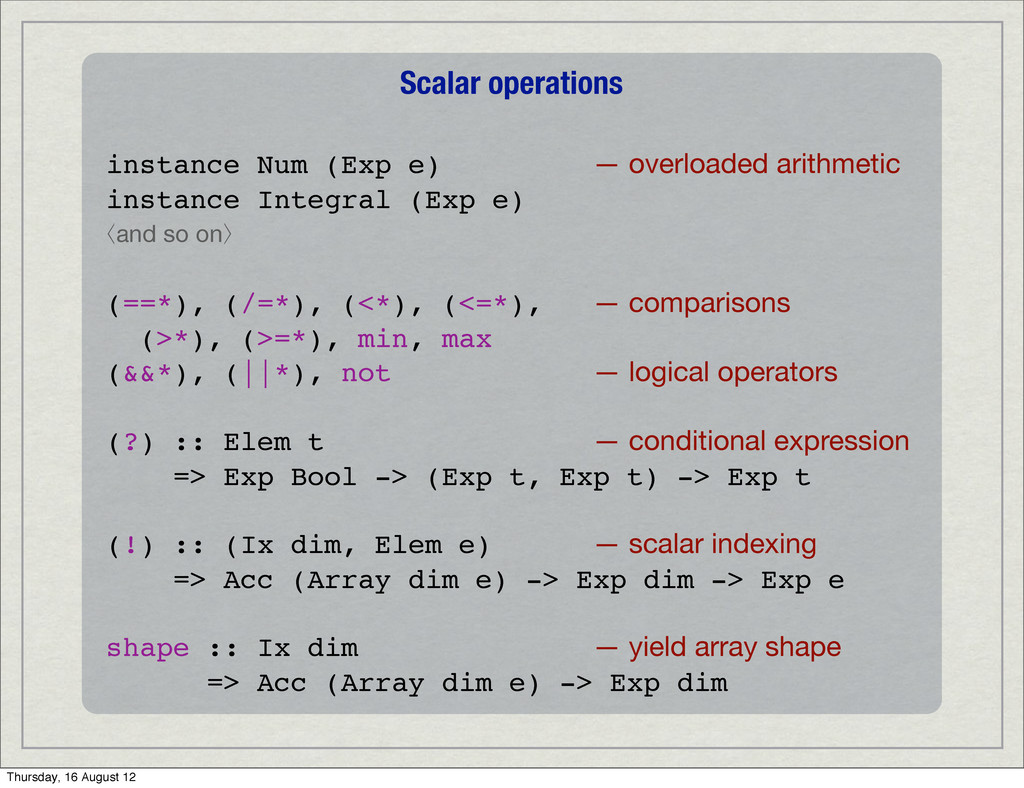
Scalar operations instance Num (Exp e) — overloaded arithmetic instance
Integral (Exp e) ⟨and so on⟩ (==*), (/=*), (<*), (<=*), — comparisons (>*), (>=*), min, max (&&*), (||*), not — logical operators (?) :: Elem t — conditional expression => Exp Bool -> (Exp t, Exp t) -> Exp t (!) :: (Ix dim, Elem e) — scalar indexing => Acc (Array dim e) -> Exp dim -> Exp e shape :: Ix dim — yield array shape => Acc (Array dim e) -> Exp dim Thursday, 16 August 12 -
Collective array operations — creation — use an array from
Haskell land use :: (Ix dim, Elem e) => Array dim e -> Acc (Array dim e) — create a singleton unit :: Elem e => Exp e -> Acc (Scalar e) — multi-dimensional replication replicate :: (SliceIx slix, Elem e) => Exp slix -> Acc (Array (Slice slix) e) -> Acc (Array (SliceDim slix) e) — Example: replicate (All, 10, All) twoDimArr Thursday, 16 August 12 -
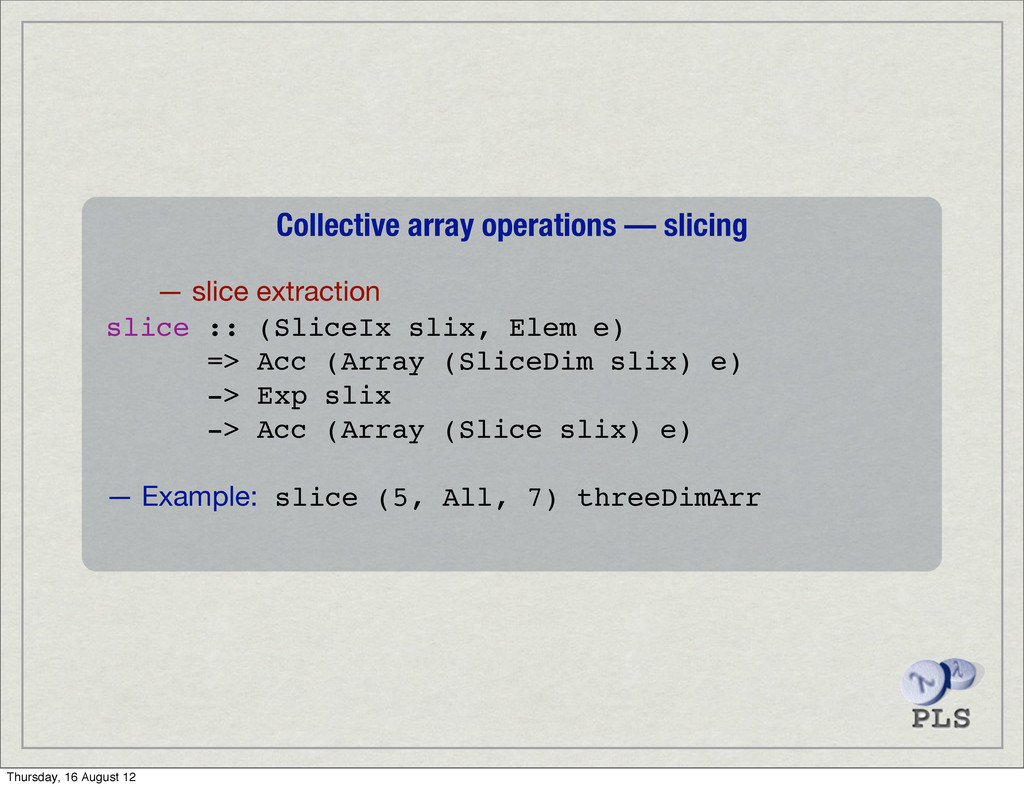
Collective array operations — slicing — slice extraction slice ::
(SliceIx slix, Elem e) => Acc (Array (SliceDim slix) e) -> Exp slix -> Acc (Array (Slice slix) e) — Example: slice (5, All, 7) threeDimArr Thursday, 16 August 12 -
Collective array operations — mapping map :: (Ix dim, Elem
a, Elem b) => (Exp a -> Exp b) -> Acc (Array dim a) -> Acc (Array dim b) zipWith :: (Ix dim, Elem a, Elem b, Elem c) => (Exp a -> Exp b -> Exp c) -> Acc (Array dim a) -> Acc (Array dim b) -> Acc (Array dim c) Thursday, 16 August 12 -
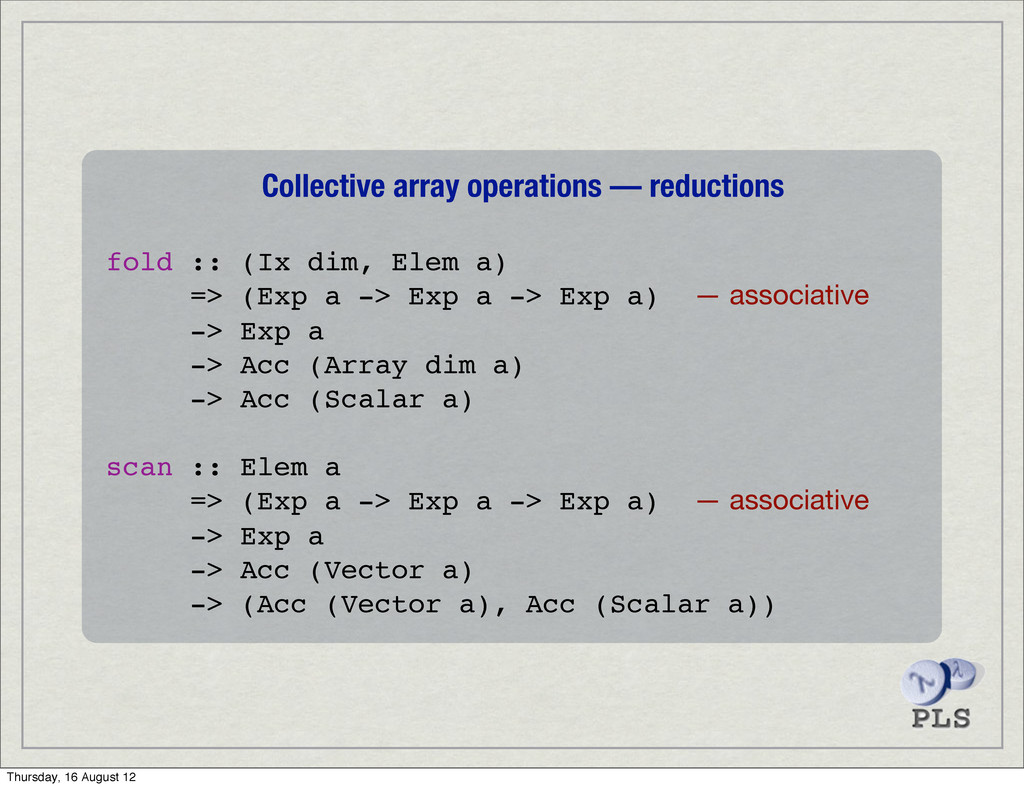
Collective array operations — reductions fold :: (Ix dim, Elem
a) => (Exp a -> Exp a -> Exp a) — associative -> Exp a -> Acc (Array dim a) -> Acc (Scalar a) scan :: Elem a => (Exp a -> Exp a -> Exp a) — associative -> Exp a -> Acc (Vector a) -> (Acc (Vector a), Acc (Scalar a)) Thursday, 16 August 12 -
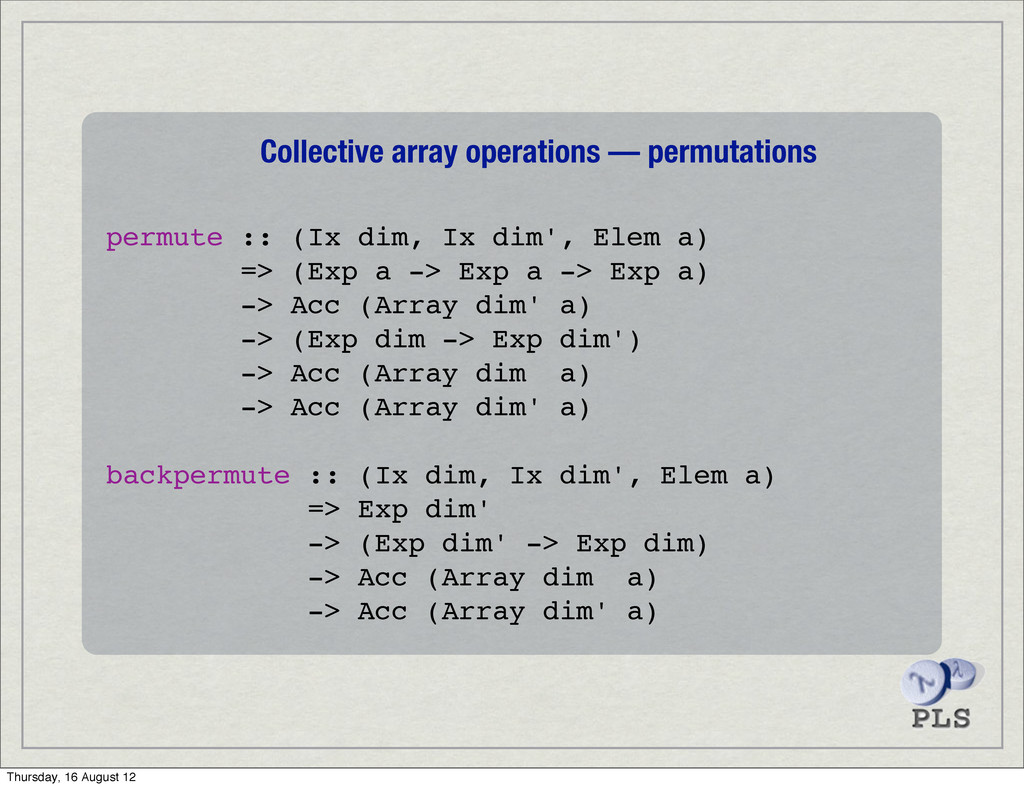
Collective array operations — permutations permute :: (Ix dim, Ix
dim', Elem a) => (Exp a -> Exp a -> Exp a) -> Acc (Array dim' a) -> (Exp dim -> Exp dim') -> Acc (Array dim a) -> Acc (Array dim' a) backpermute :: (Ix dim, Ix dim', Elem a) => Exp dim' -> (Exp dim' -> Exp dim) -> Acc (Array dim a) -> Acc (Array dim' a) Thursday, 16 August 12 -
Conclusion EDSL for processing multi-dimensional arrays Collective array operations (highly
data parallel) Support for multiple backends Status: ‣ On GitHub: https://github.com/AccelerateHS/accelerate ‣ Under active development Thursday, 16 August 12