Upgrade to Pro — share decks privately, control downloads, hide ads and more …

Doing SRE the right way

Doing SRE the right way

Site Reliability Engineering (SRE) is an expensive proposition for small and large organizations alike. You can mitigate the costs by:

Setting up the right organizational structure for SRE
Hiring for the right team composition
Building the SRE culture

Piyush Verma, co-founder of Last9 Inc shares practical insights and wisdom, from accumulated successful and not-so-successful experiences.

Piyush Verma

June 16, 2020

Transcript

44 slides
  1. 1. What is SRE? 2. Vs DevOps? 3. How much

    does reliability cost? 4. How long before I am reliable? 5. Isn’t it too early to automate? 6. What does an SRE code? 7. Is Reliability achieved before/after release? 8. What is the right SRE organization structure? .. .. .. .. ask in comments FAQs
  2. Some approaches to build reliability • Ignorance • Throw more

    engineers at the problem • Recovery Blocks • NVersion Programming
  3. Instead, what we need is... Self-checking software [Michael Lyu] Observability

    Comprehensive metrics And, Control Policies that adhere to Production
  4. Software Products vs Software Operations? Product • Product Manager •

    Customer feedback • Product metrics • Google analytics • Conversion funnels Operations • One failure at a time • Ad-hoc increments • On-call softwares • Re-write • Kubernetes • Data driven decisions • Prioritize your failures • Put a value to the loss
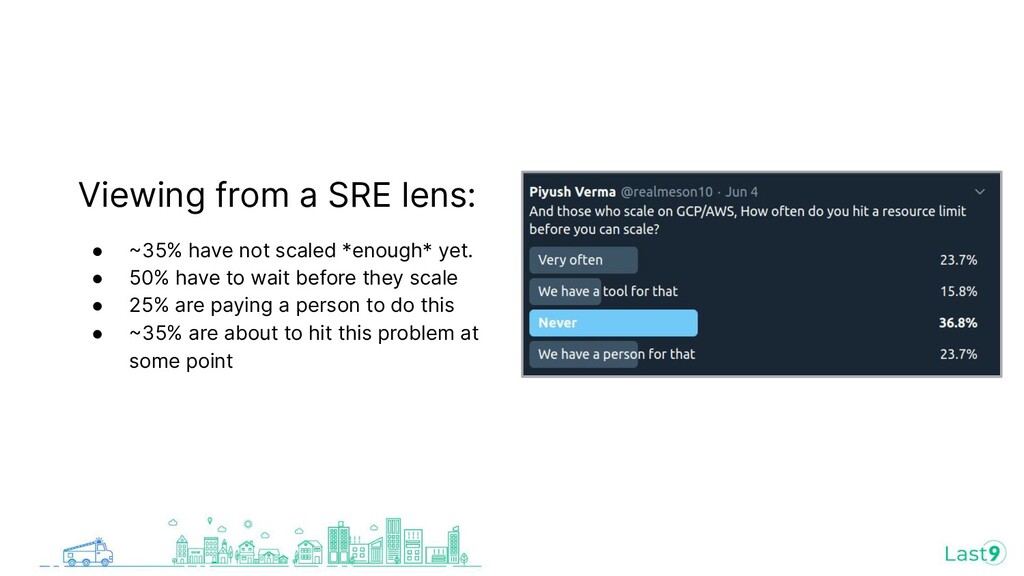
  5. Viewing from a SRE lens: • 35% have not scaled

    *enough* yet. • 50% have to wait before they scale • 25% are paying a person to do this • 35% are about to hit this problem at some point
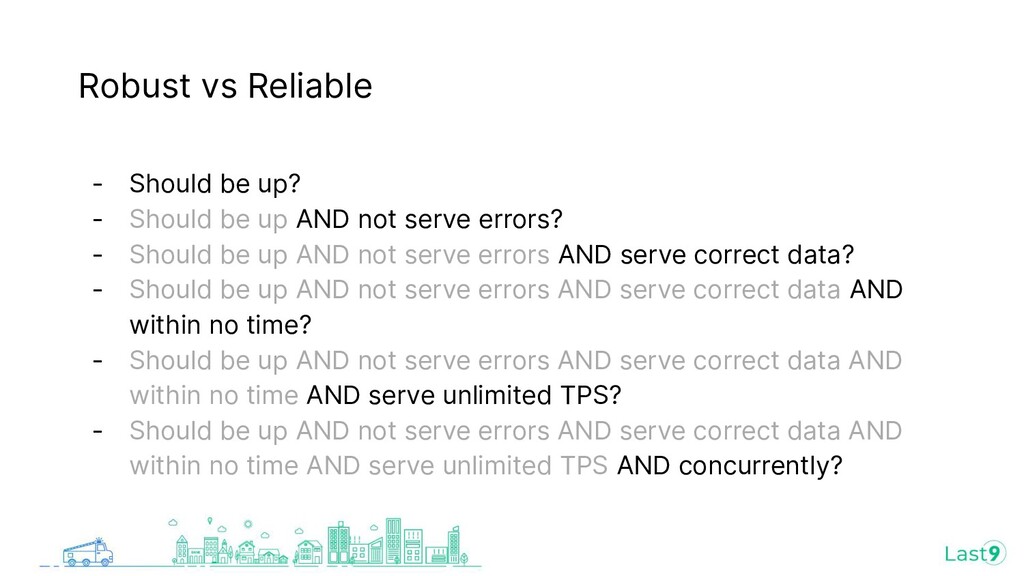
  6. Robust vs Reliable - Should be up? - Should be

    up AND not serve errors? - Should be up AND not serve errors AND serve correct data? - Should be up AND not serve errors AND serve correct data AND within no time? - Should be up AND not serve errors AND serve correct data AND within no time AND serve unlimited TPS? - Should be up AND not serve errors AND serve correct data AND within no time AND serve unlimited TPS AND concurrently?
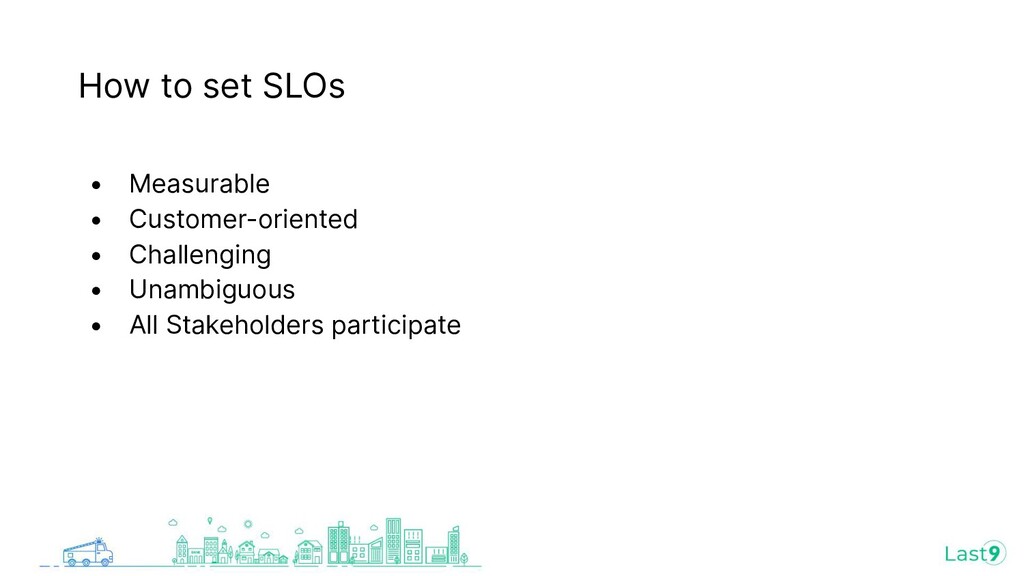
  7. How to set SLOs • Measurable • Customer-oriented • Challenging

    • Unambiguous • All Stakeholders participate
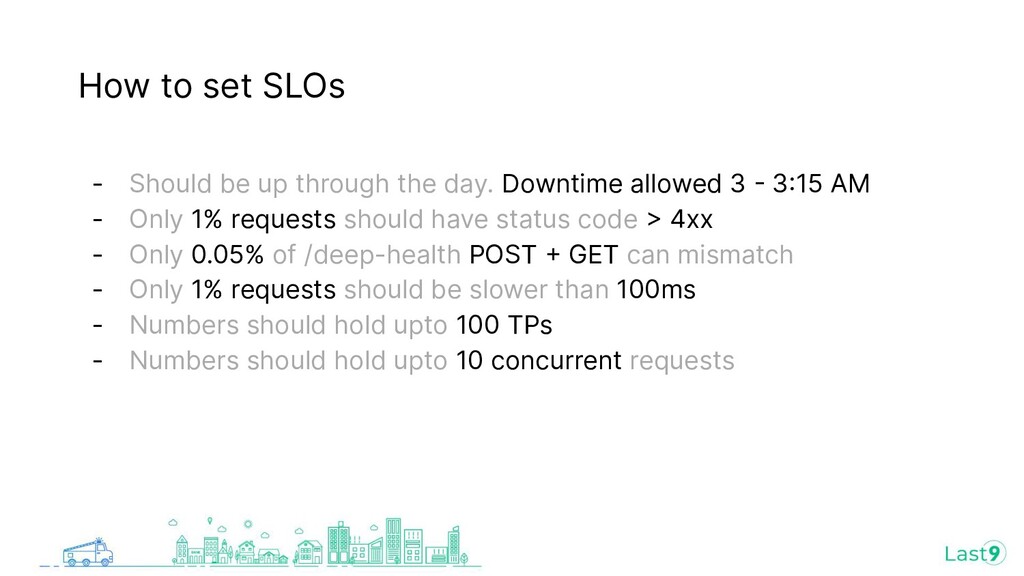
  8. How to set SLOs - Should be up through the

    day. Downtime allowed 3  315 AM - Only 1% requests should have status code  4xx - Only 0.05% of /deep-health POST  GET can mismatch - Only 1% requests should be slower than 100ms - Numbers should hold upto 100 TPs - Numbers should hold upto 10 concurrent requests
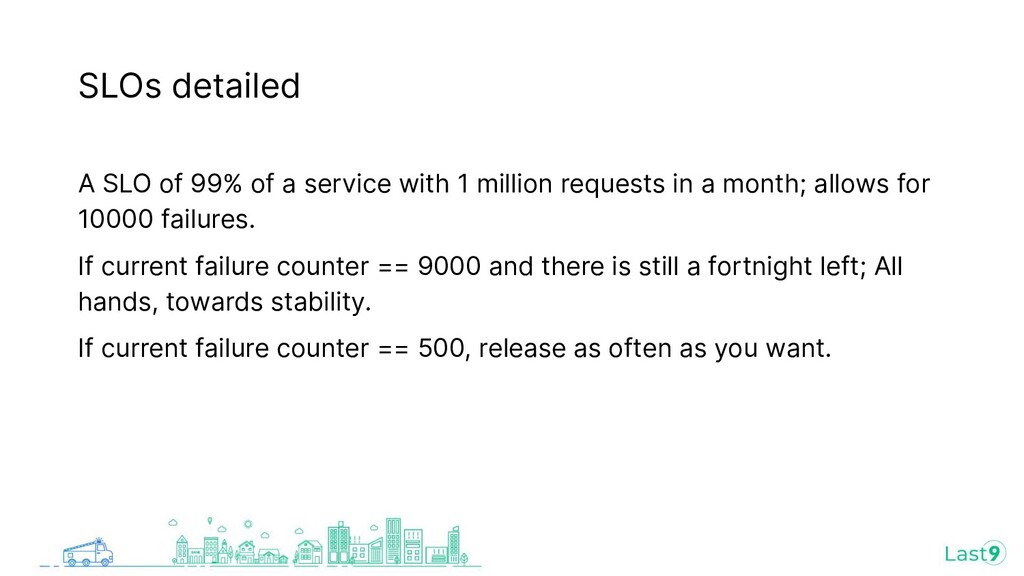
  9. SLOs detailed A SLO of 99% of a service with

    1 million requests in a month; allows for 10000 failures. If current failure counter == 9000 and there is still a fortnight left; All hands, towards stability. If current failure counter == 500, release as often as you want.
  10. So what does a SRE do? • When an outage

    happens, minimize the downtime • Where else is this happening? • Prevent repetition
  11. The SRE Recipe • Observability - 2 tbsp • Control

    - 2 tbsp • Automation - 1 tbsp • Root Cause Analysis - 3 tbsp • Cross-org collaboration - 3 tbsp • Guard Rails/Frameworks - 4 tbsp
  12. Isn’t K8s and cloud already automated? • If a human

    does a thing 3x over • 3 different results • 3 different bugs • 1 highly demotivated employee
  13. But that’s exactly how they sold DevOps! DevOps is the

    goal. SRE is a way to get there. Functional Programming: Software Development :: SRE : DevOps
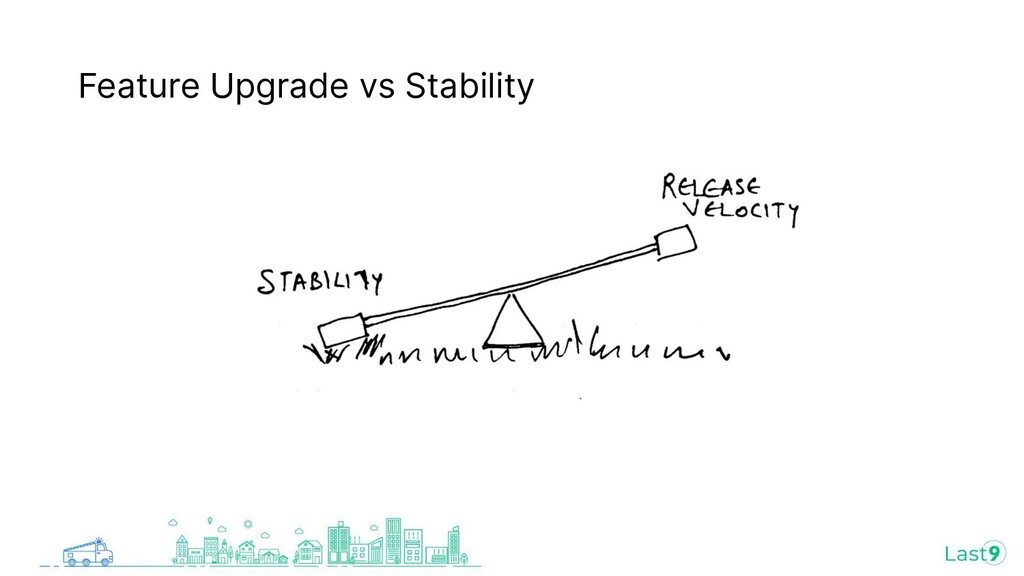
  14. So, what did SRE change? • Feature development is owned

    by Product Developers • Quality is owned by QA / Release Managers • Who owned the Uptime? • Especially when choosing between Stability vs Feature Release • Uptime didn’t have owners • Who owns Capacity Plan and spend? • More felt over the last 2 decades • Shops remain open 247 • Consumption is 247
  15. SRE brings to software development what assembly line brought to

    manufacturing. Over 60% failures were bad deployments and 38% issues were repeated. SRE practice helped cut down operations cost by 60% within a year.
  16. Tiered SRE approach Sporadic work, no dedicated SRE staffing (Tier

    0 Put observability in place Projects, some dedicated SRE time (Tier 1 Aim to unify dataset across services to build common improvements. Onboard one service and on-call time (Tier 2 Setup on-call and escalation matrix. See how teams and services adopt Onboard other services. Reuse SRE tooling and practices (Tier 3 Go org-wide
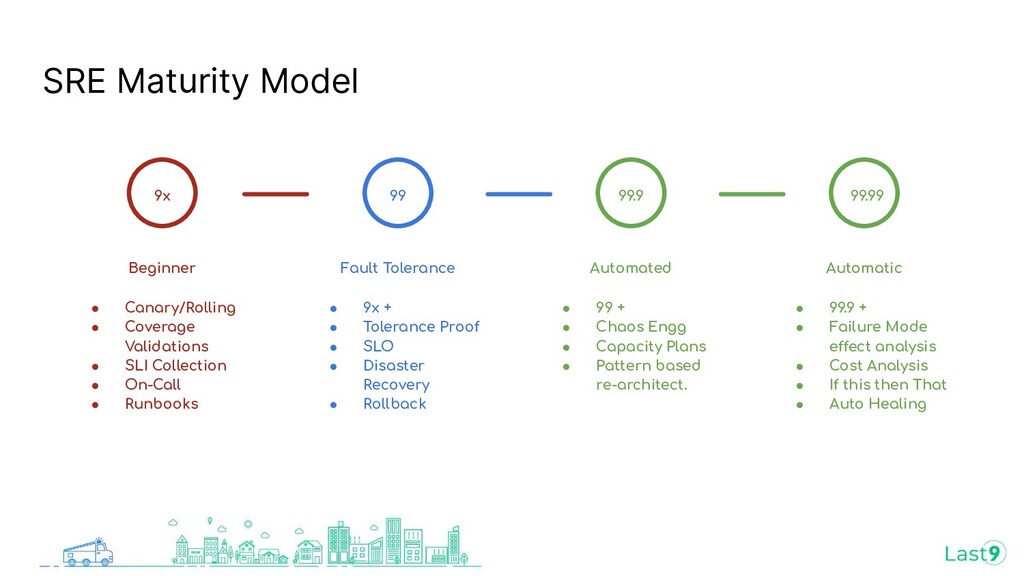
  17. SRE Maturity Model 9x Beginner • Canary/Rolling • Coverage Validations

    • SLI Collection • On-Call • Runbooks Fault Tolerance • 9x + • Tolerance Proof • SLO • Disaster Recovery • Rollback 99 Automated • 99 + • Chaos Engg • Capacity Plans • Pattern based re-architect. 99.9 Automatic • 99.9 + • Failure Mode effect analysis • Cost Analysis • If this then That • Auto Healing 99.99
  18. Key Skills of an SRE • Withstand Boredom • Attention

    towards detail • *nix • Programming • Shell scripting • On-call experience (real or assisted) • Statistics
  19. How do you train SREs Based on organizational size and

    maturity • Train on Job • Self-Learn • Throw them in the Ocean SRE
  20. • There is a cost to reliability • 100% reliability

    is a myth • Reliability can (and should) be achieved incrementally • Reliability is improved in Dev sprints • Reliability needs participation from every stakeholder • Reliability is a function. Someone happened to call it SRE. Things to take away

More Decks by Piyush Verma

Other Decks in Programming