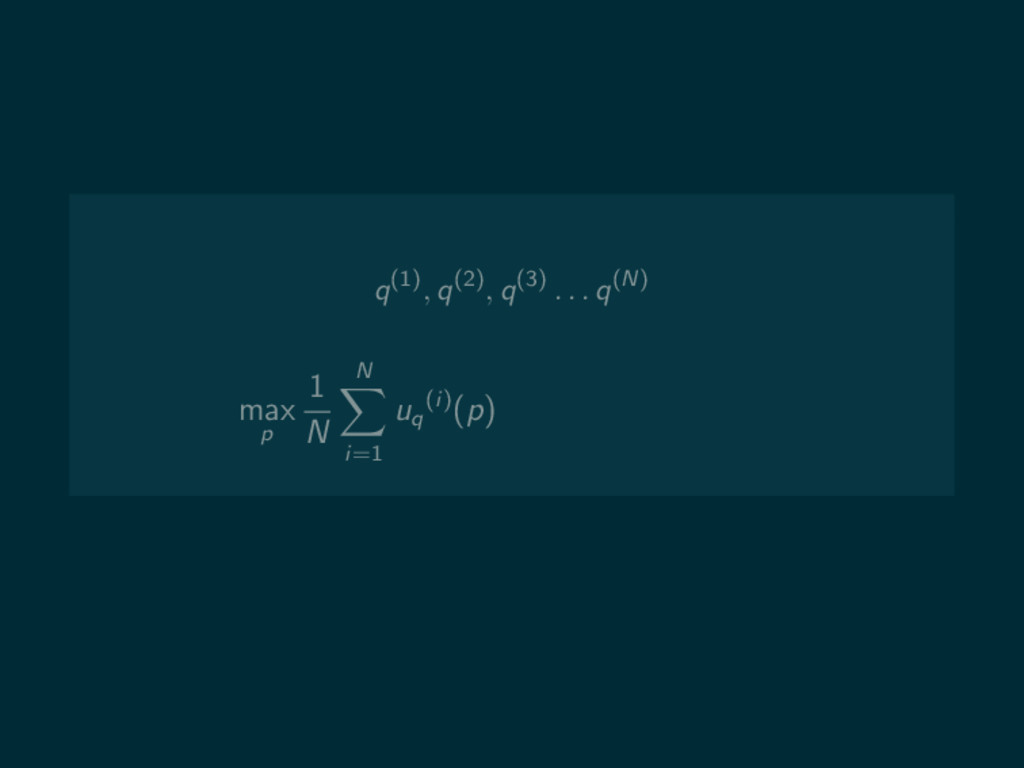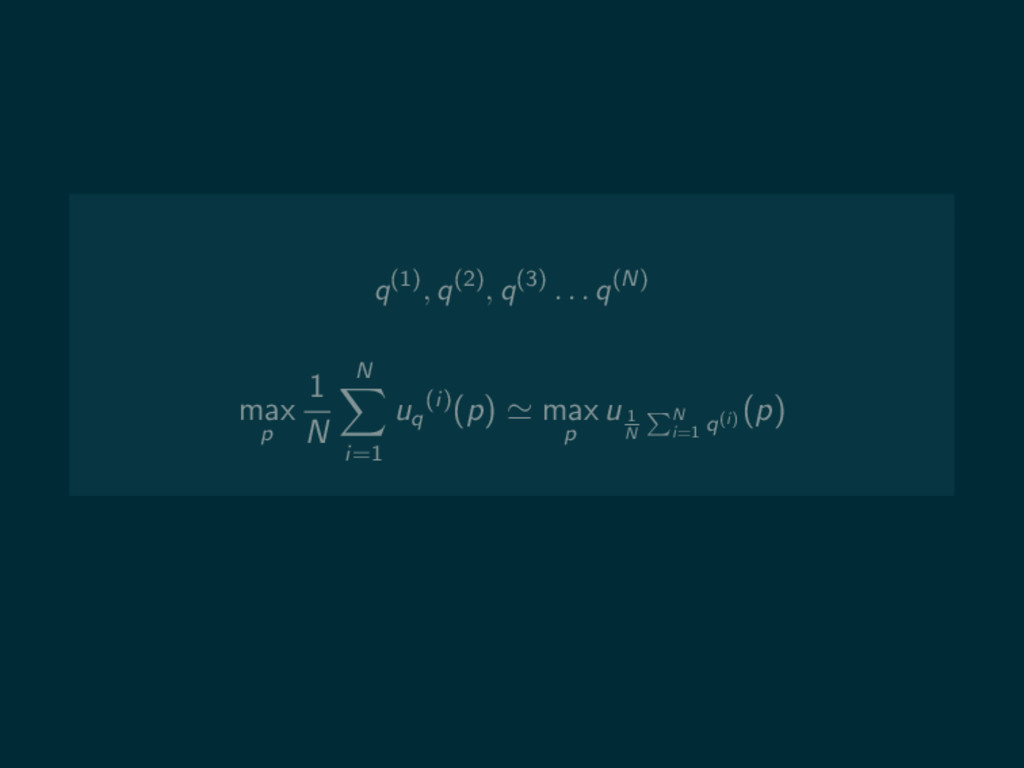Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
Optimisation of short memory strategies in the ...
Search
Nikoleta
June 04, 2017
Science
62
0
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
Optimisation of short memory strategies in the Iterated Prisoners Dilemma
Wales Mathematics Colloquium 2017.
Nikoleta
June 04, 2017
More Decks by Nikoleta
See All by Nikoleta
A trip to earth science with python as a companion
nikoletav3
0
57
Arcas: Using Python to access open research literature
nikoletav3
1
190
Testing Research Software
nikoletav3
0
350
Arcas
nikoletav3
0
530
SSI Selection Day
nikoletav3
0
440
SWORDS-03-10-2016
nikoletav3
0
58
PyCon UK 2016
nikoletav3
0
180
Other Decks in Science
See All in Science
SAT ソルバーの仕組みと制約ソルバーへの応用
tsoh
3
750
データベース14: B+木 & ハッシュ索引
trycycle
PRO
0
1k
機械学習 - ニューラルネットワーク入門
trycycle
PRO
0
1.4k
はじめてのグラフ信号サンプリング
arthur1
0
150
Génétique moléculaire de la mortalité
institutdelelevage
PRO
0
360
20260820_アウトカムが二値のデータに対するCausal Impact@LINEヤフー Data Science Share #2 / Causal Impact for Binary Outcomes
brainpadpr
3
1.6k
データベース12: 正規化(2/2) - データ従属性に基づく正規化
trycycle
PRO
0
1.9k
医療 LLM ベンチマークの現在地:多面的評価 と日本ローカライズ
analokmaus
1
790
[Webinaire InnOvin] Coup de Chaud : Comment préserver la santé des animaux
institutdelelevage
PRO
0
270
Anomalies de terrain remontées à l'ONAB
institutdelelevage
PRO
0
360
「念のためのログ保存」を組織全体でやめるためのポリシーと仕組み作り
i2tsuki
4
430
AI(人工知能)の過去・現在・未来 ~AIは人類を越えるのか~
tagtag
PRO
0
190
Featured
See All Featured
Mozcon NYC 2025: Stop Losing SEO Traffic
samtorres
1
600
sira's awesome portfolio website redesign presentation
elsirapls
0
500
The Mindset for Success: Future Career Progression
greggifford
PRO
0
560
The Psychology of Web Performance [Beyond Tellerrand 2023]
tammyeverts
49
3.6k
Agile Actions for Facilitating Distributed Teams - ADO2019
mkilby
0
340
How to Get Subject Matter Experts Bought In and Actively Contributing to SEO & PR Initiatives.
livdayseo
0
240
Rails Girls Zürich Keynote
gr2m
96
14k
Done Done
chrislema
187
17k
How to Align SEO within the Product Triangle To Get Buy-In & Support - #RIMC
aleyda
2
1.9k
SEO for Brand Visibility & Recognition
aleyda
0
4.9k
Bridging the Design Gap: How Collaborative Modelling removes blockers to flow between stakeholders and teams @FastFlow conf
baasie
0
760
Templates, Plugins, & Blocks: Oh My! Creating the theme that thinks of everything
marktimemedia
31
2.9k
Transcript
Optimisation of short memory strategies in the Iterated Prisoners Dilemma
Nikoleta E. Glynatsi Supervised by: Dr. Vincent Knight Dr. Jonathan Gillard
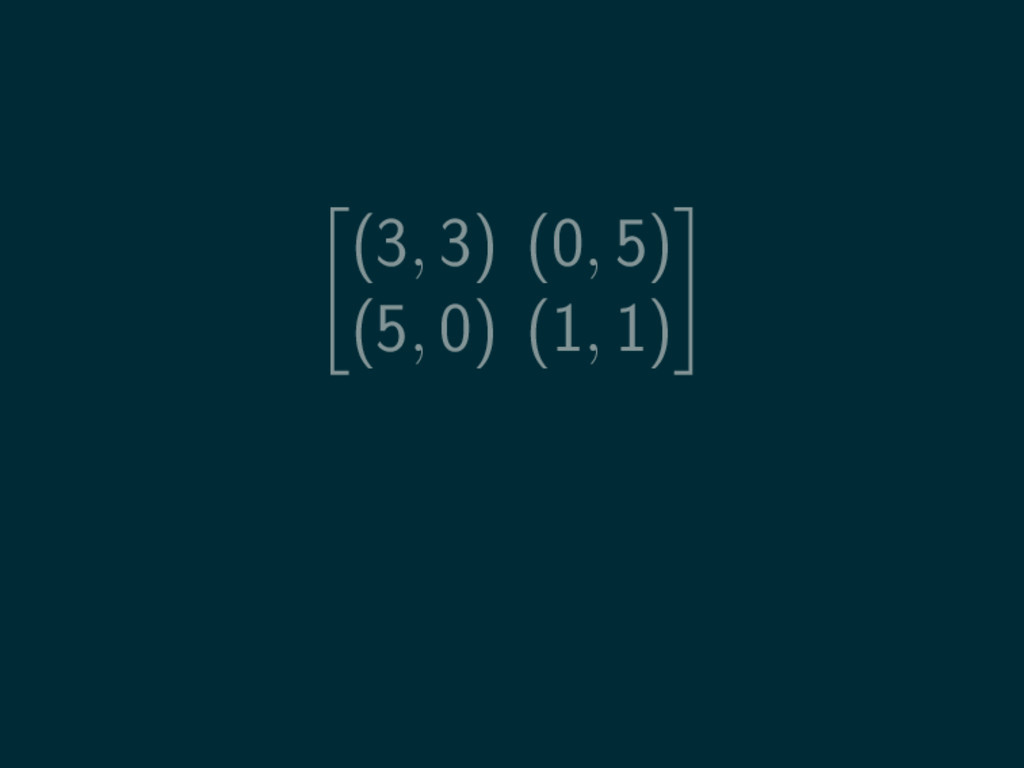
(3, 3) (0, 5) (5, 0) (1, 1)
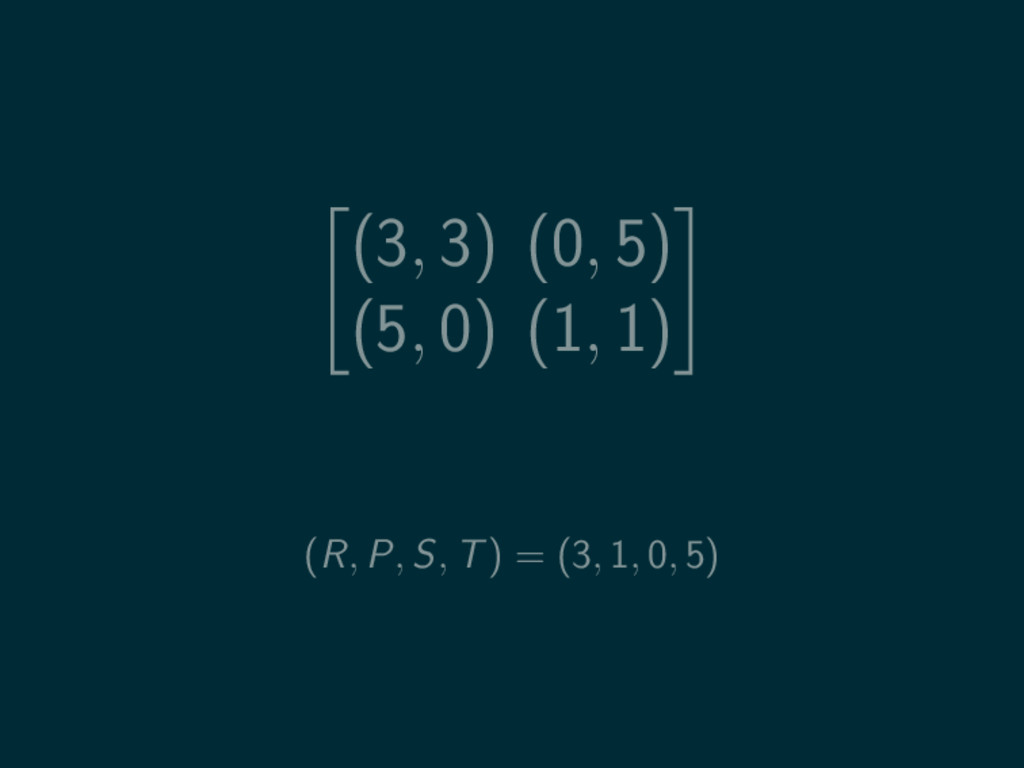
(3, 3) (0, 5) (5, 0) (1, 1) (R, P,
S, T) = (3, 1, 0, 5)
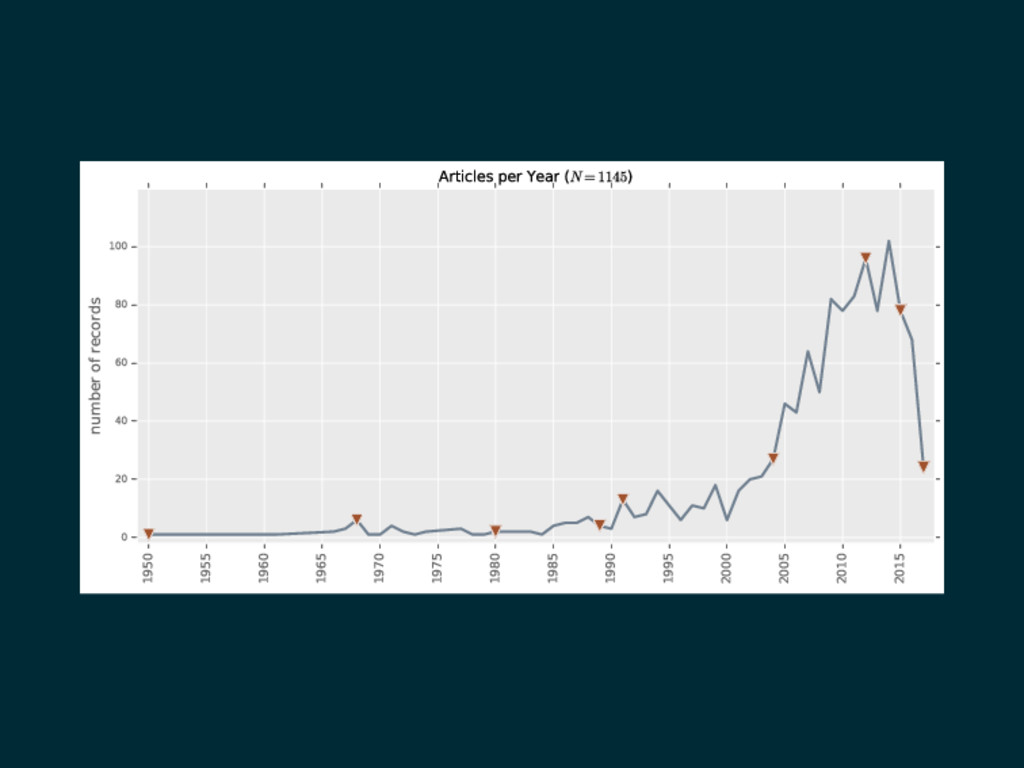
1950 1955 1960 1965 1970 1975 1980 1985 1990 1995
2000 2005 2010 2015 0 20 40 60 80 100 number of records Articles per Year (N=1145)
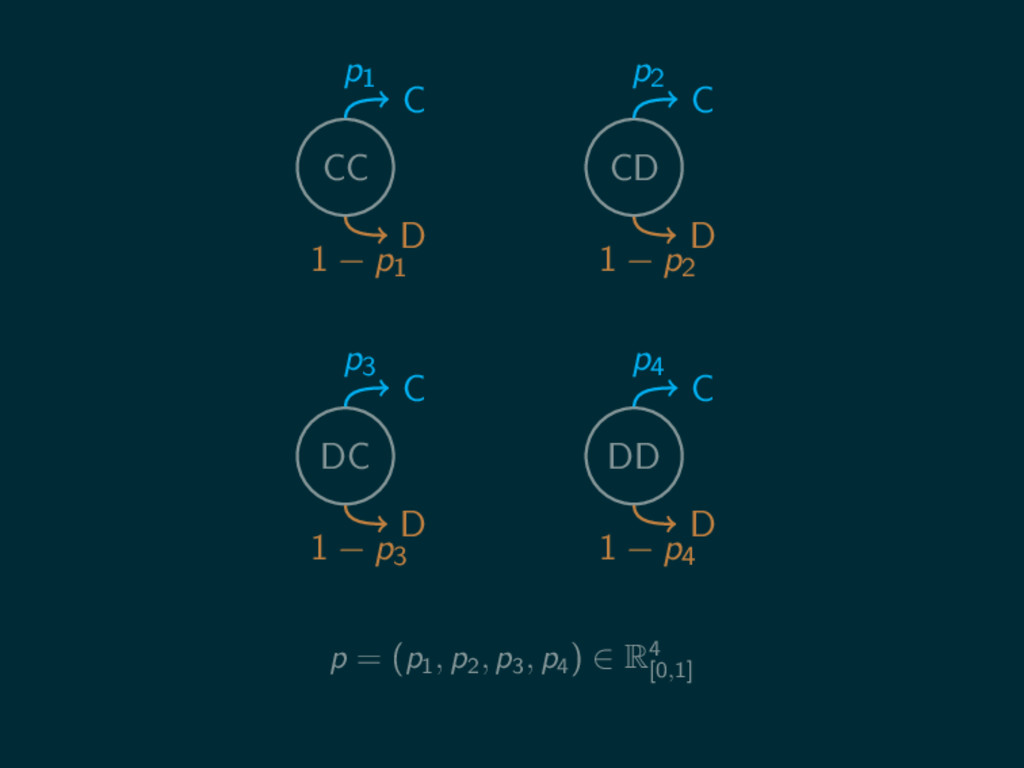
CC CD DC DD C D C D C D
C D p1 1 − p1 p2 1 − p2 p3 1 − p3 p4 1 − p4 p = (p1 , p2 , p3 , p4 ) ∈ R4 [0,1]
Christopher Lee, Marc Harper, and Dashiell Fryer. The art of
war: Beyond memory-one strategies in population games. 2015.
How good are memory one strategies ?
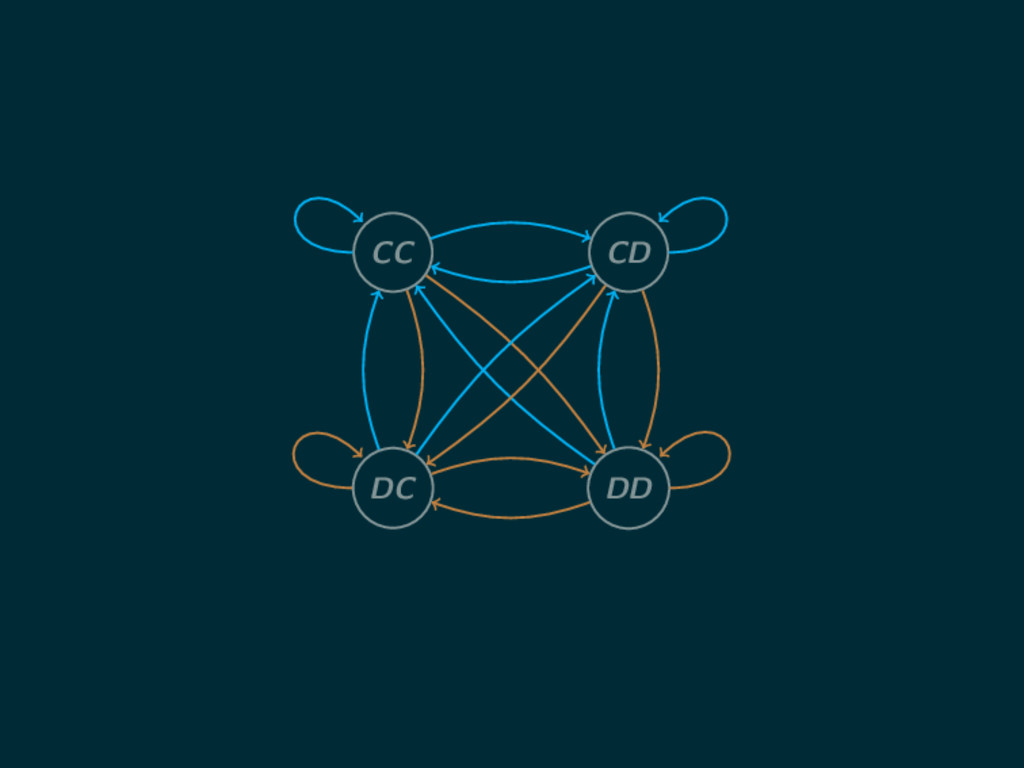
CC CD DC DD
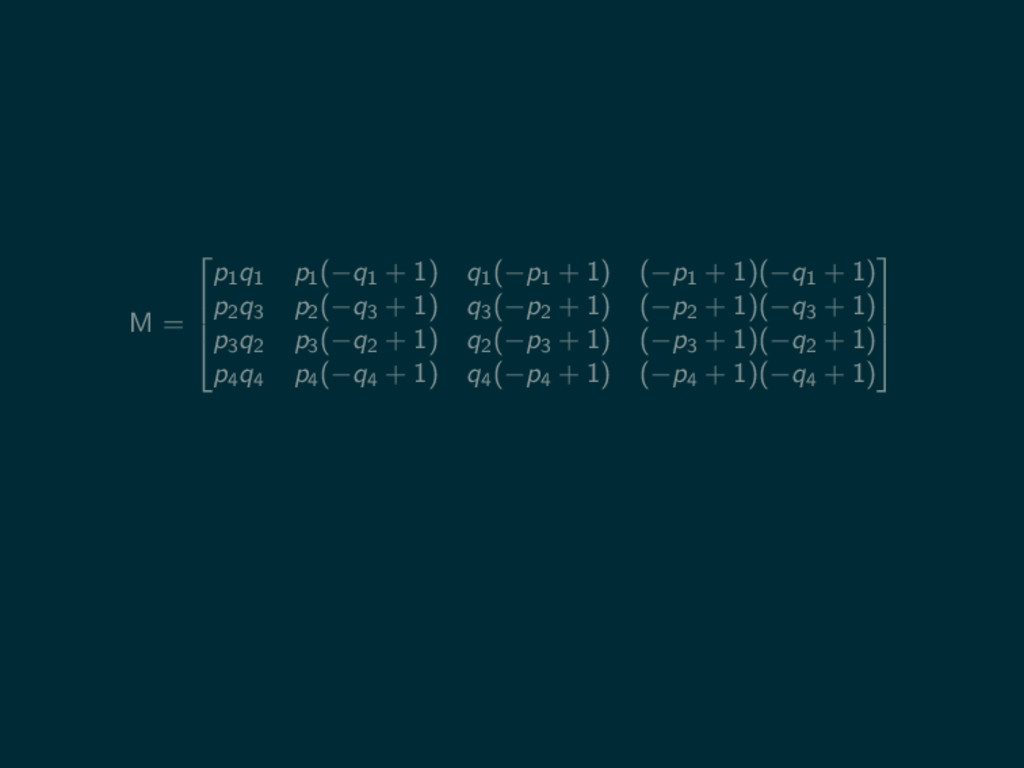
M = p1 q1 p1 (−q1
+ 1) q1 (−p1 + 1) (−p1 + 1)(−q1 + 1) p2 q3 p2 (−q3 + 1) q3 (−p2 + 1) (−p2 + 1)(−q3 + 1) p3 q2 p3 (−q2 + 1) q2 (−p3 + 1) (−p3 + 1)(−q2 + 1) p4 q4 p4 (−q4 + 1) q4 (−p4 + 1) (−p4 + 1)(−q4 + 1)
maxp uq (p) such that p ∈ R4 [0,1]
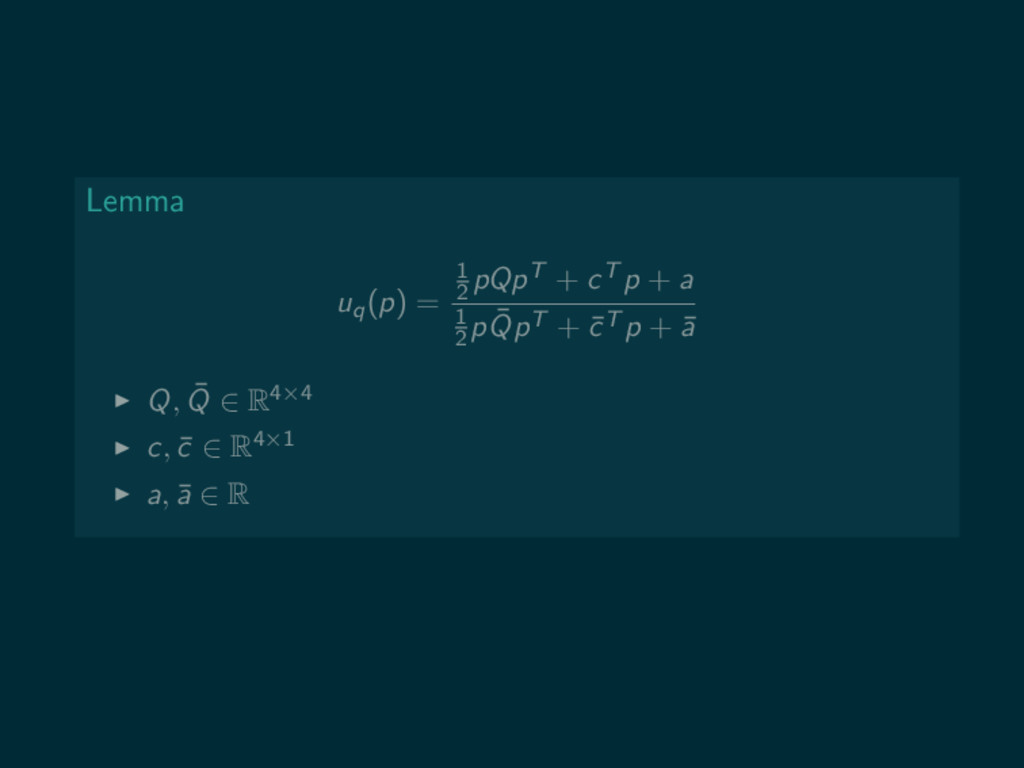
Lemma uq(p) = 1 2 pQpT + cT p +
a 1 2 p ¯ QpT + ¯ cT p + ¯ a Q, ¯ Q ∈ R4×4 c, ¯ c ∈ R4×1 a, ¯ a ∈ R
maxp uq (p) such that p ∈ R4 [0,1]
maxp uq (p) such that p ∈ R4 [0,1] subject
to p1 = p2 = p3 = p4 = p
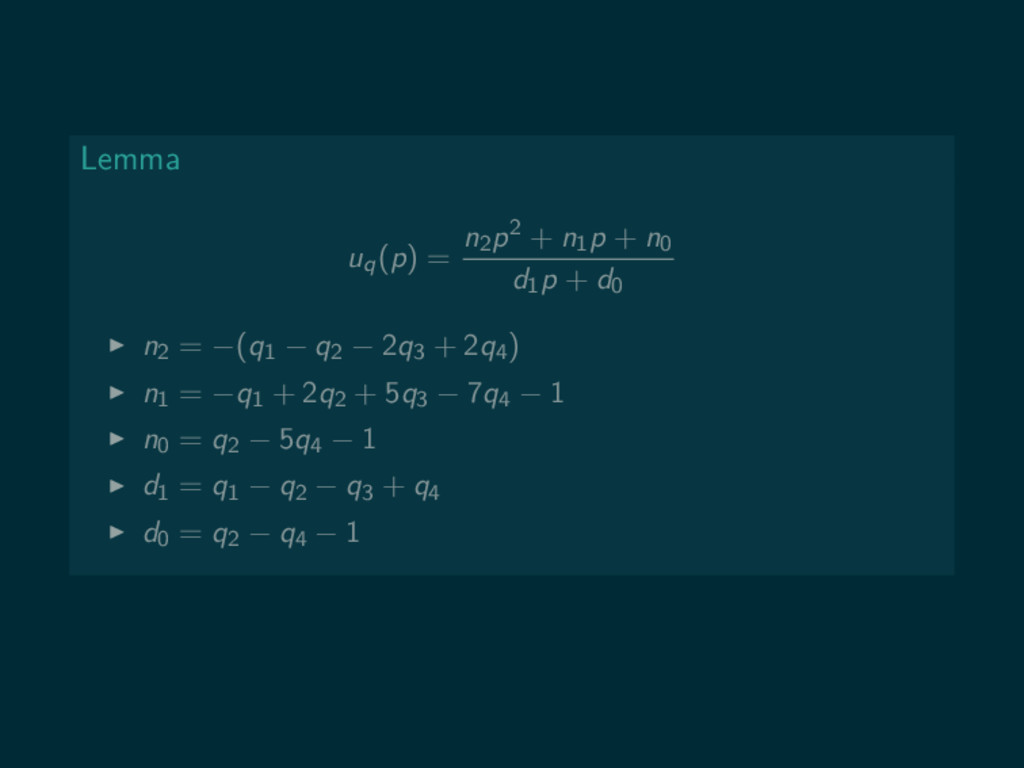
Lemma uq(p) = n2p2 + n1p + n0 d1p +
d0 n2 = −(q1 − q2 − 2q3 + 2q4) n1 = −q1 + 2q2 + 5q3 − 7q4 − 1 n0 = q2 − 5q4 − 1 d1 = q1 − q2 − q3 + q4 d0 = q2 − q4 − 1
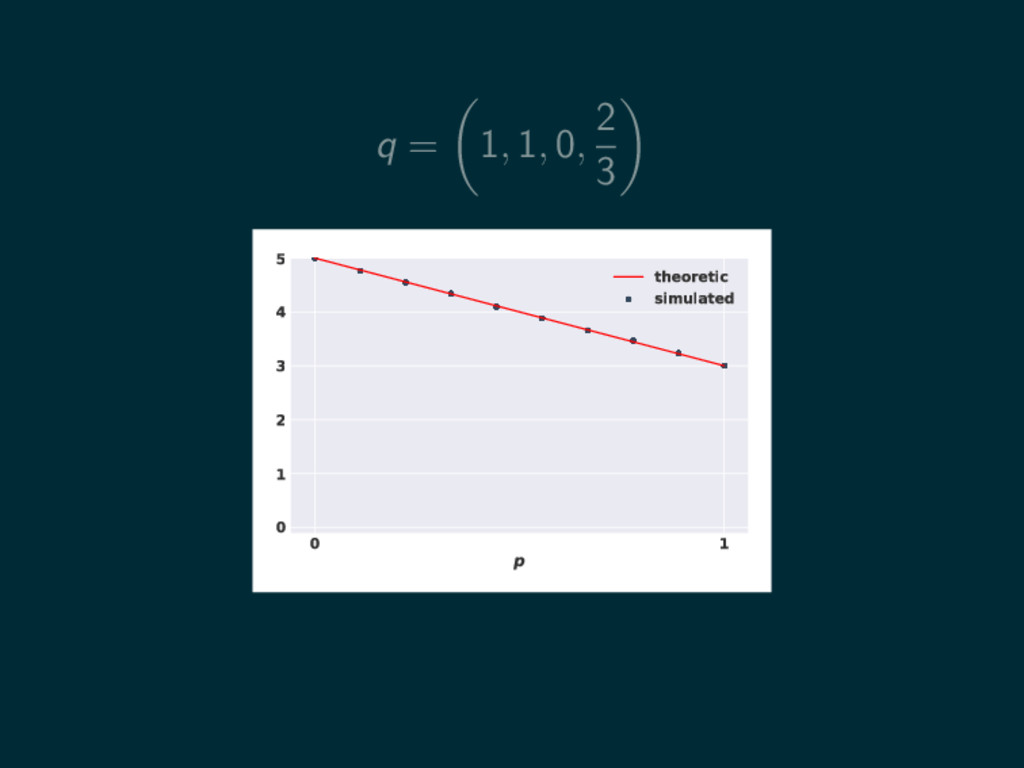
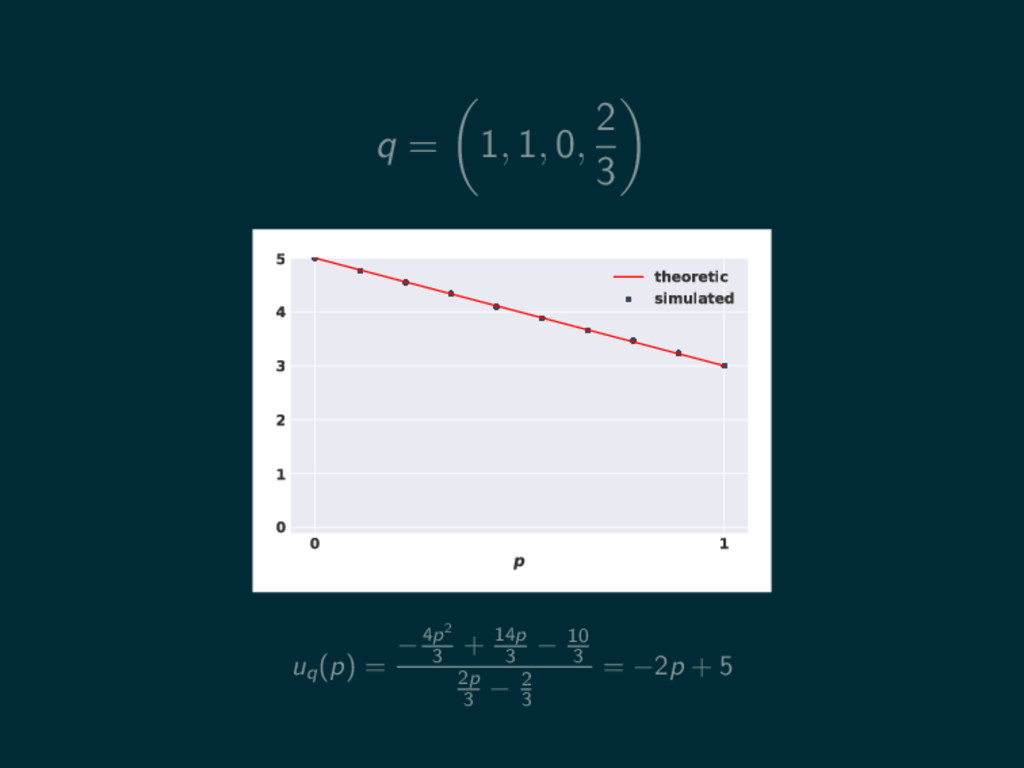
q = 1, 1, 0, 2 3 0 1 p
0 1 2 3 4 5 theoretic simulated
q = 1, 1, 0, 2 3 0 1 p
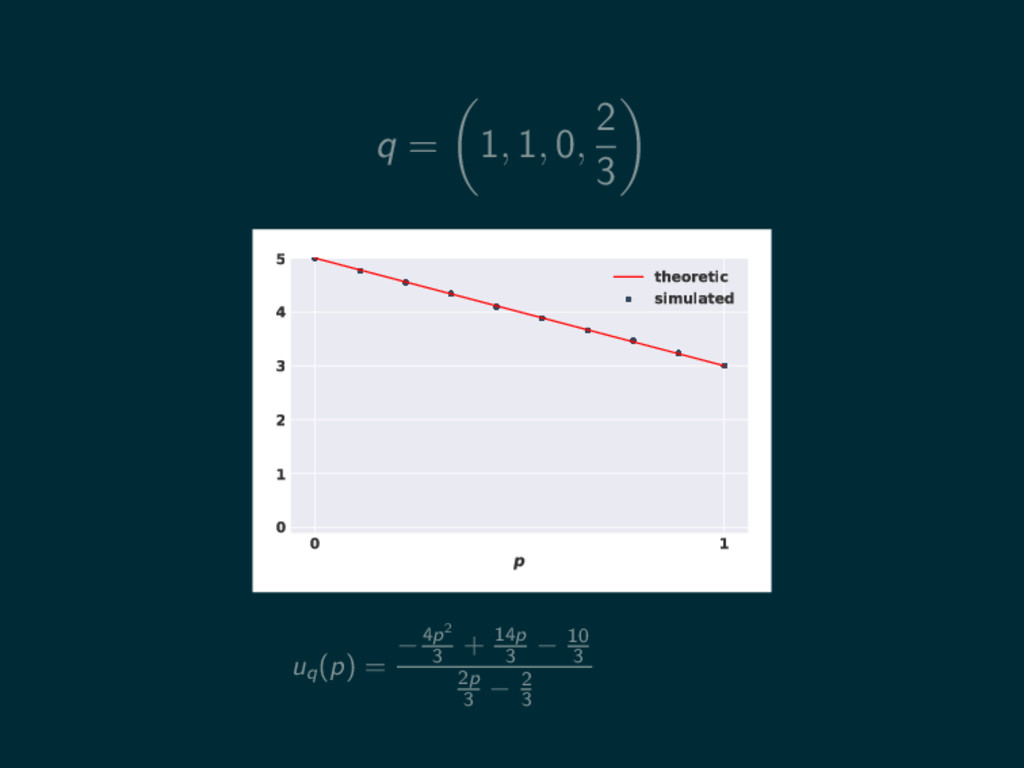
0 1 2 3 4 5 theoretic simulated uq (p) = −4p2 3 + 14p 3 − 10 3 2p 3 − 2 3
q = 1, 1, 0, 2 3 0 1 p
0 1 2 3 4 5 theoretic simulated uq (p) = −4p2 3 + 14p 3 − 10 3 2p 3 − 2 3 = −2p + 5
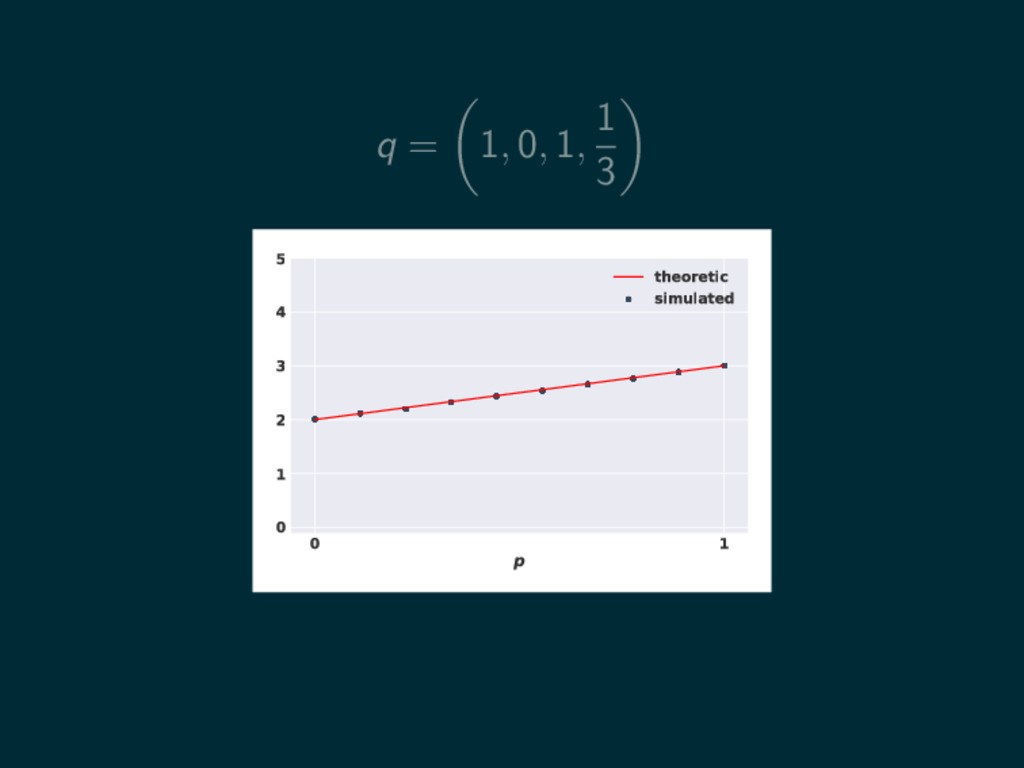
q = 1, 0, 1, 1 3 0 1 p
0 1 2 3 4 5 theoretic simulated
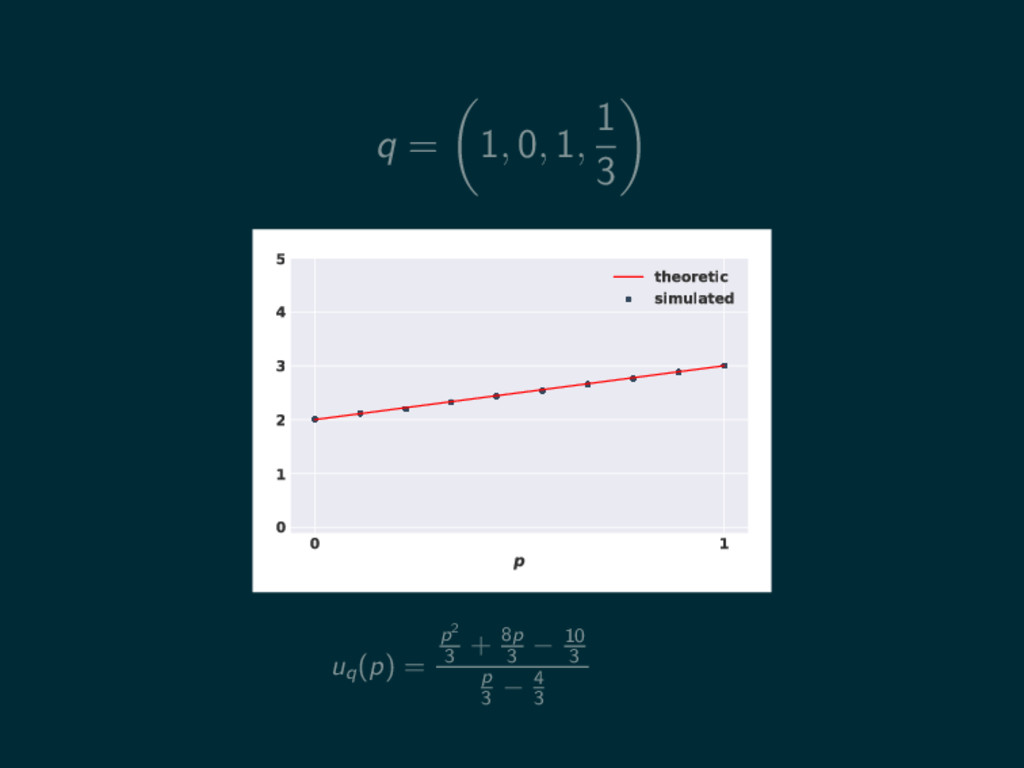
q = 1, 0, 1, 1 3 0 1 p
0 1 2 3 4 5 theoretic simulated uq (p) = p2 3 + 8p 3 − 10 3 p 3 − 4 3
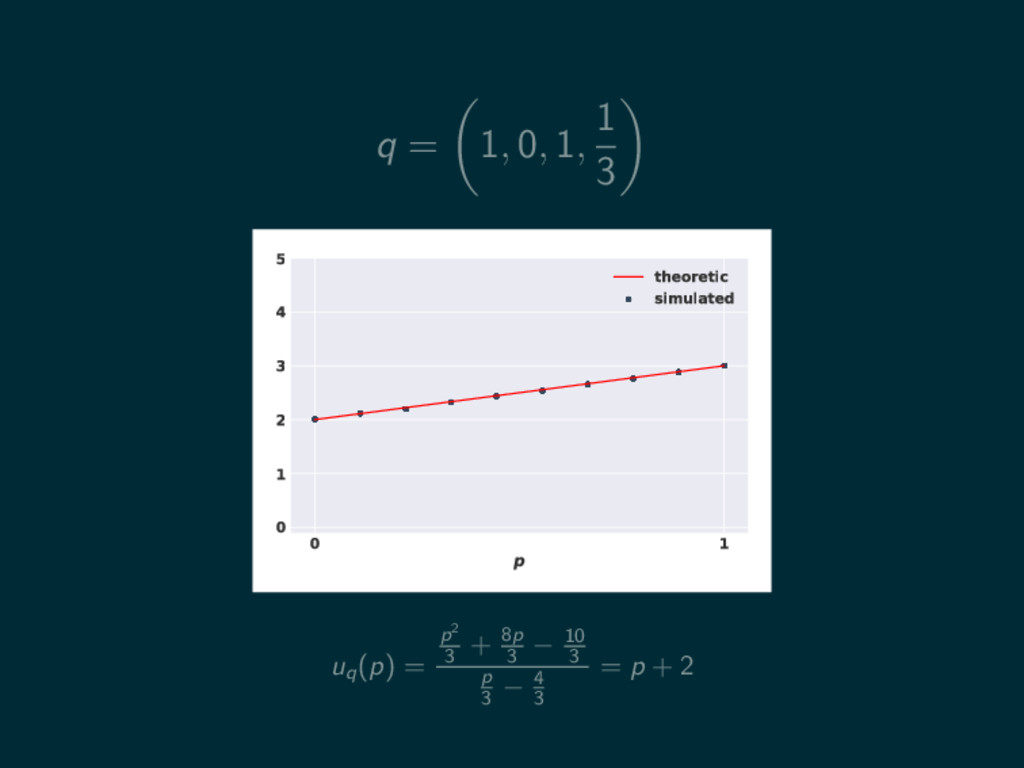
q = 1, 0, 1, 1 3 0 1 p
0 1 2 3 4 5 theoretic simulated uq (p) = p2 3 + 8p 3 − 10 3 p 3 − 4 3 = p + 2
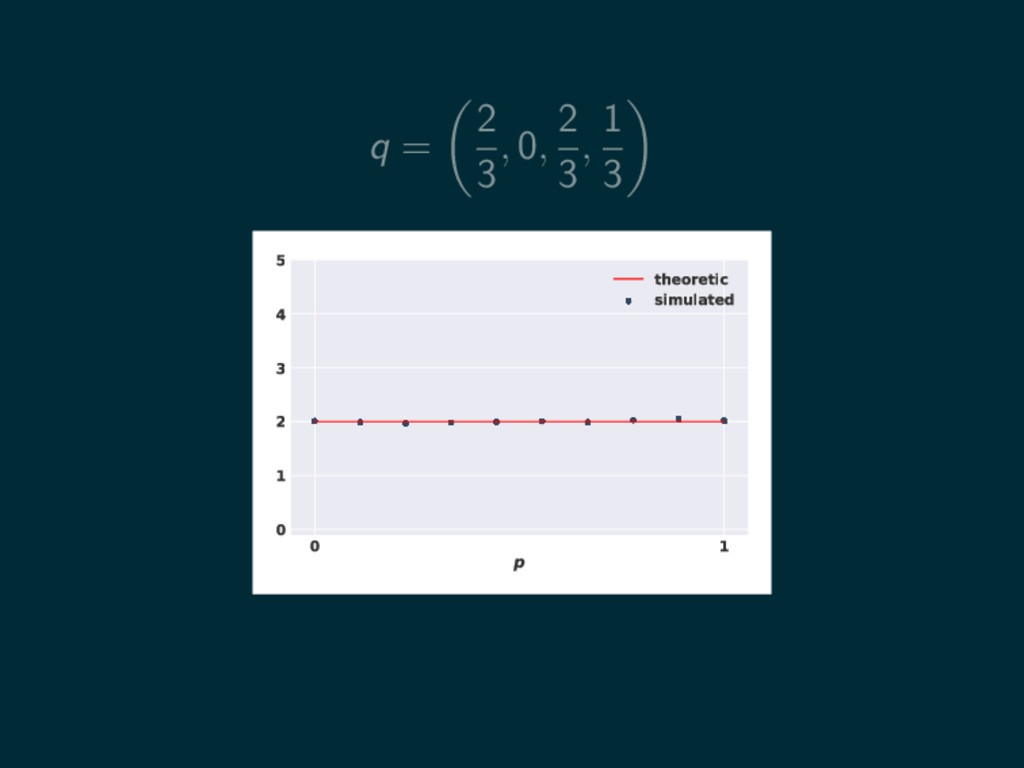
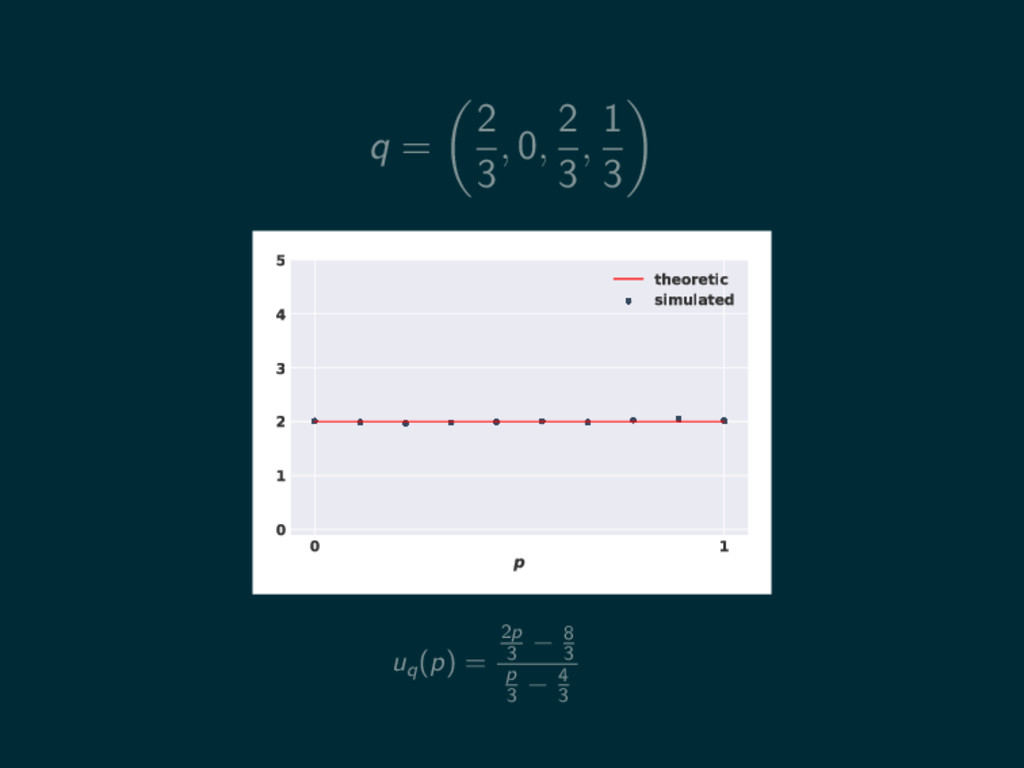
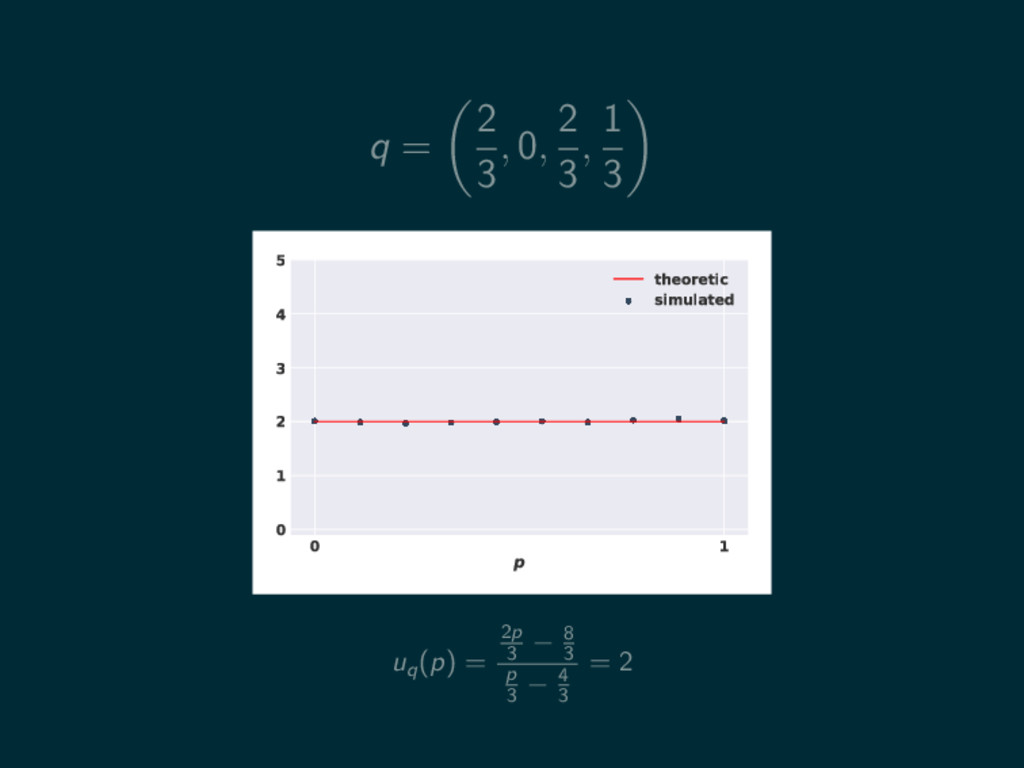
q = 2 3 , 0, 2 3 , 1
3 0 1 p 0 1 2 3 4 5 theoretic simulated
q = 2 3 , 0, 2 3 , 1
3 0 1 p 0 1 2 3 4 5 theoretic simulated uq (p) = 2p 3 − 8 3 p 3 − 4 3
q = 2 3 , 0, 2 3 , 1
3 0 1 p 0 1 2 3 4 5 theoretic simulated uq (p) = 2p 3 − 8 3 p 3 − 4 3 = 2
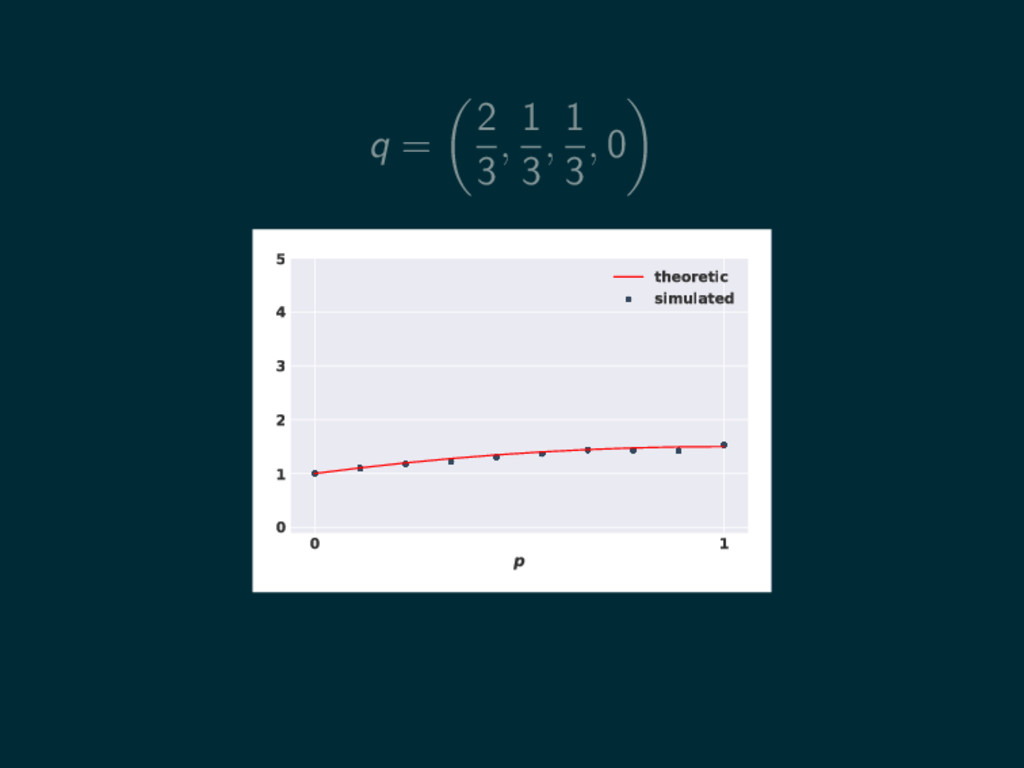
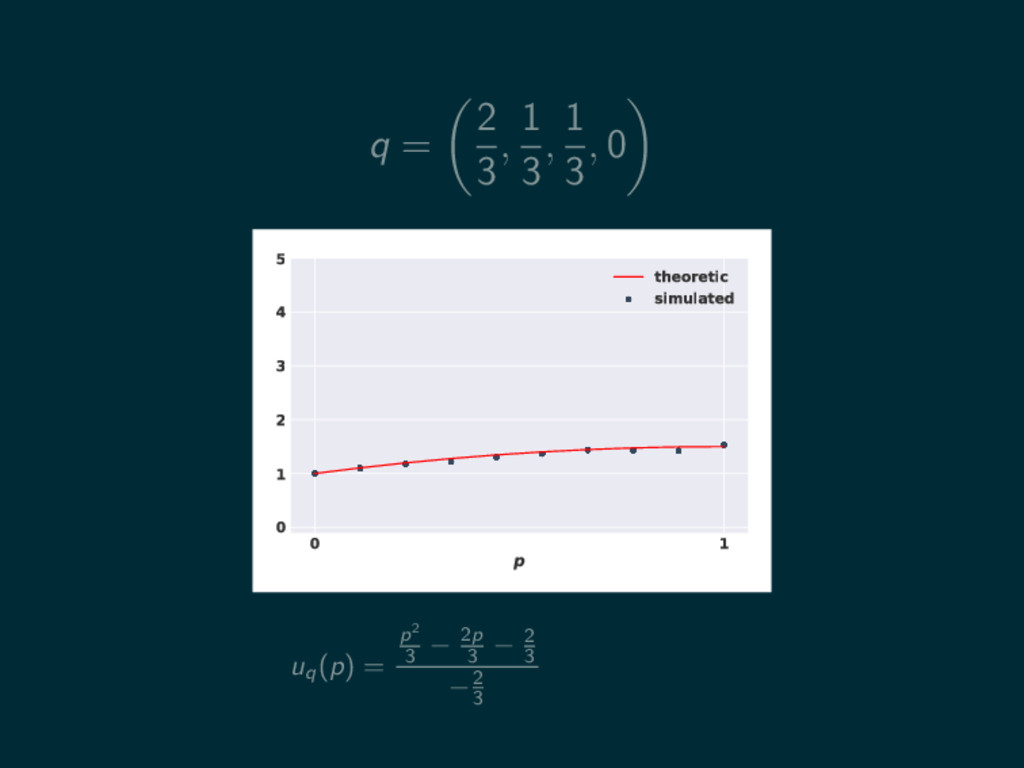
q = 2 3 , 1 3 , 1 3
, 0 0 1 p 0 1 2 3 4 5 theoretic simulated
q = 2 3 , 1 3 , 1 3
, 0 0 1 p 0 1 2 3 4 5 theoretic simulated uq (p) = p2 3 − 2p 3 − 2 3 −2 3
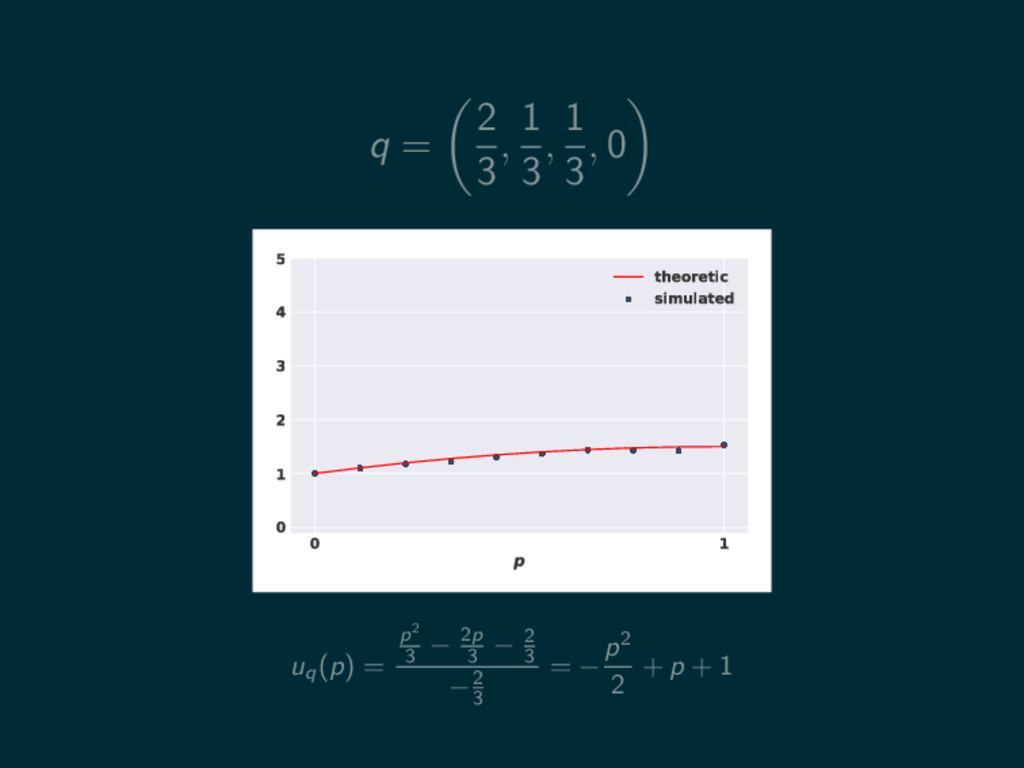
q = 2 3 , 1 3 , 1 3
, 0 0 1 p 0 1 2 3 4 5 theoretic simulated uq (p) = p2 3 − 2p 3 − 2 3 −2 3 = − p2 2 + p + 1
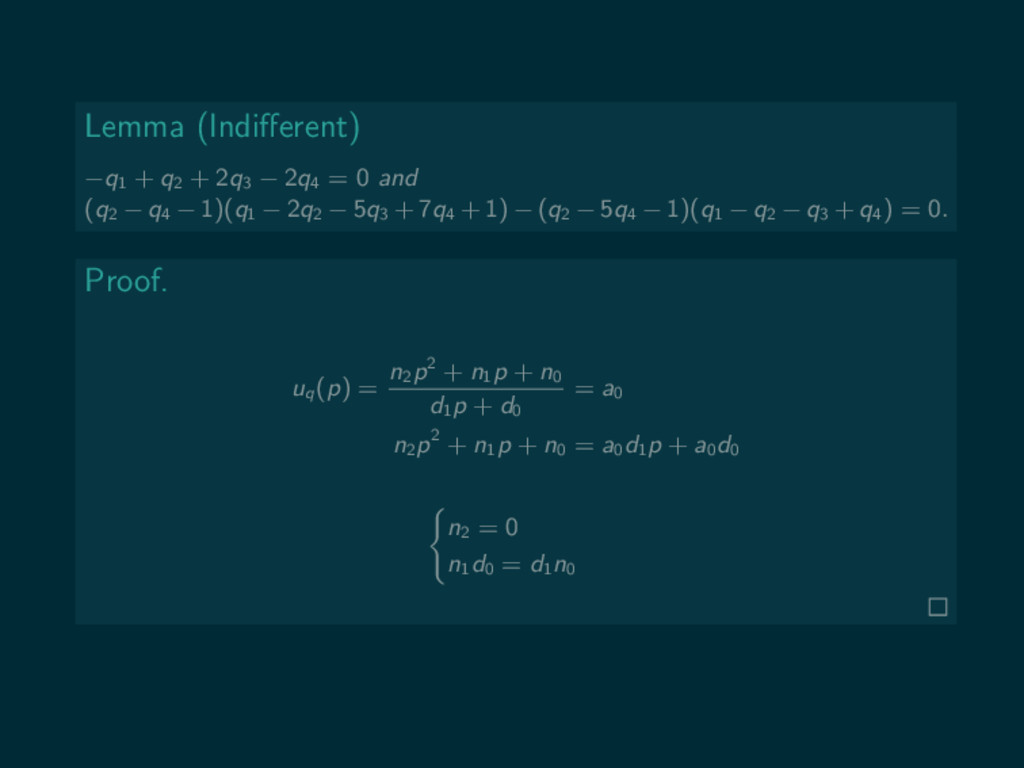
Lemma (Indifferent) −q1 + q2 + 2q3 − 2q4 =
0 and (q2 − q4 − 1)(q1 − 2q2 − 5q3 + 7q4 + 1) − (q2 − 5q4 − 1)(q1 − q2 − q3 + q4 ) = 0. Proof. uq (p) = n2 p2 + n1 p + n0 d1 p + d0 = a0 n2 p2 + n1 p + n0 = a0 d1 p + a0 d0 n2 = 0 n1 d0 = d1 n0
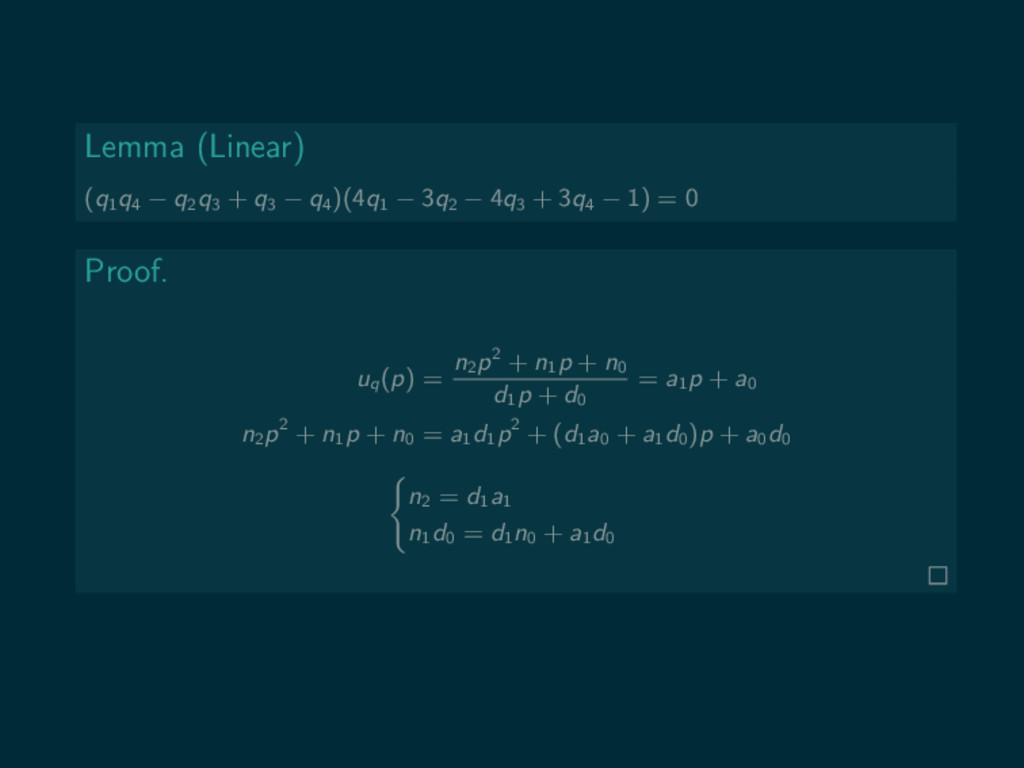
Lemma (Linear) (q1 q4 − q2 q3 + q3 −
q4 )(4q1 − 3q2 − 4q3 + 3q4 − 1) = 0 Proof. uq (p) = n2 p2 + n1 p + n0 d1 p + d0 = a1 p + a0 n2 p2 + n1 p + n0 = a1 d1 p2 + (d1 a0 + a1 d0 )p + a0 d0 n2 = d1 a1 n1 d0 = d1 n0 + a1 d0
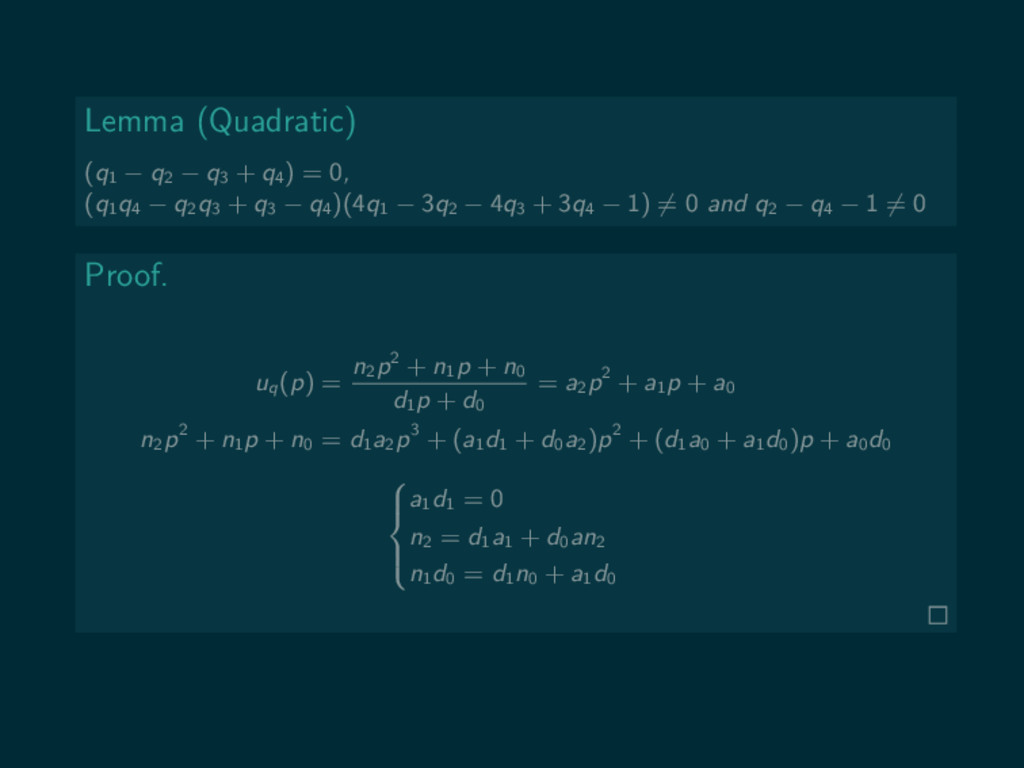
Lemma (Quadratic) (q1 − q2 − q3 + q4 )
= 0, (q1 q4 − q2 q3 + q3 − q4 )(4q1 − 3q2 − 4q3 + 3q4 − 1) = 0 and q2 − q4 − 1 = 0 Proof. uq (p) = n2 p2 + n1 p + n0 d1 p + d0 = a2 p2 + a1 p + a0 n2 p2 + n1 p + n0 = d1 a2 p3 + (a1 d1 + d0 a2 )p2 + (d1 a0 + a1 d0 )p + a0 d0 a1 d1 = 0 n2 = d1 a1 + d0 an2 n1 d0 = d1 n0 + a1 d0
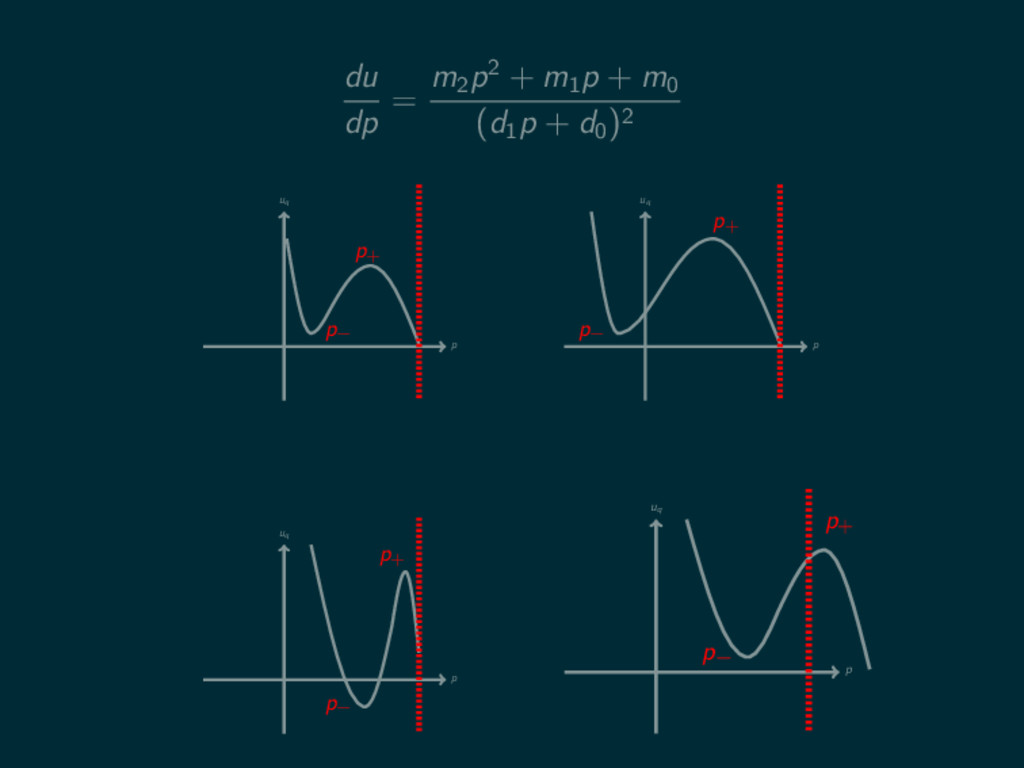
du dp = m2 p2 + m1 p + m0
(d1 p + d0 )2 p uq p− p+ p uq p− p+ p uq p− p+ p uq p− p+
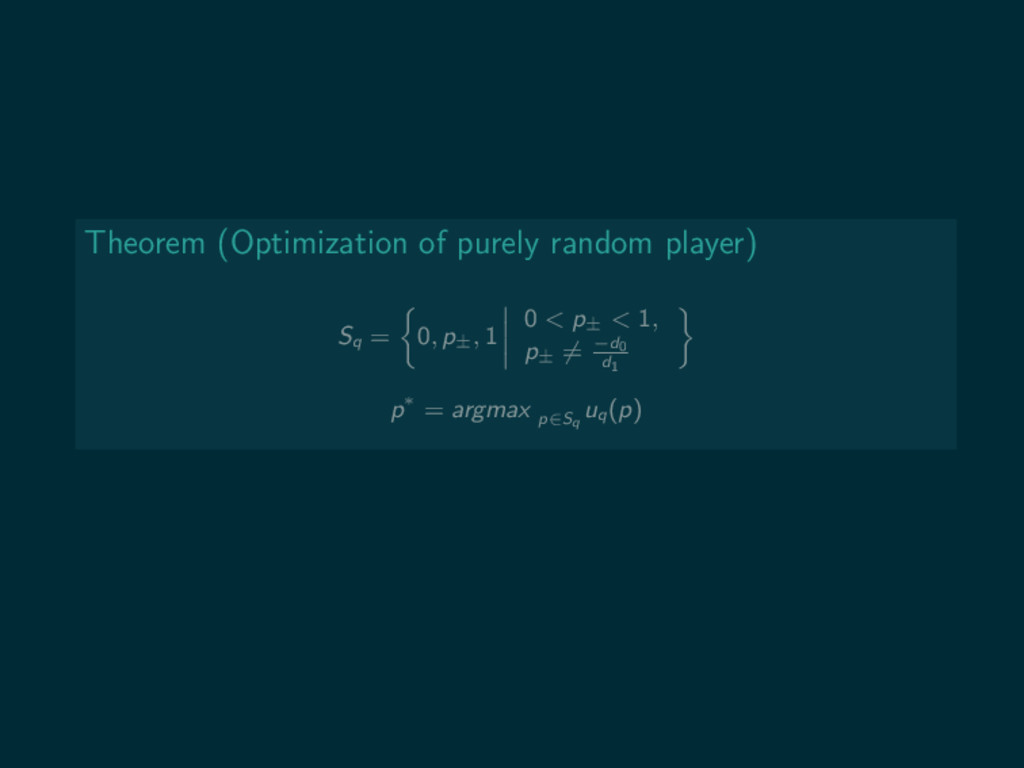
Theorem (Optimization of purely random player) Sq = 0, p±
, 1 0 < p± < 1, p± = −d0 d1 p∗ = argmax p∈Sq uq (p)
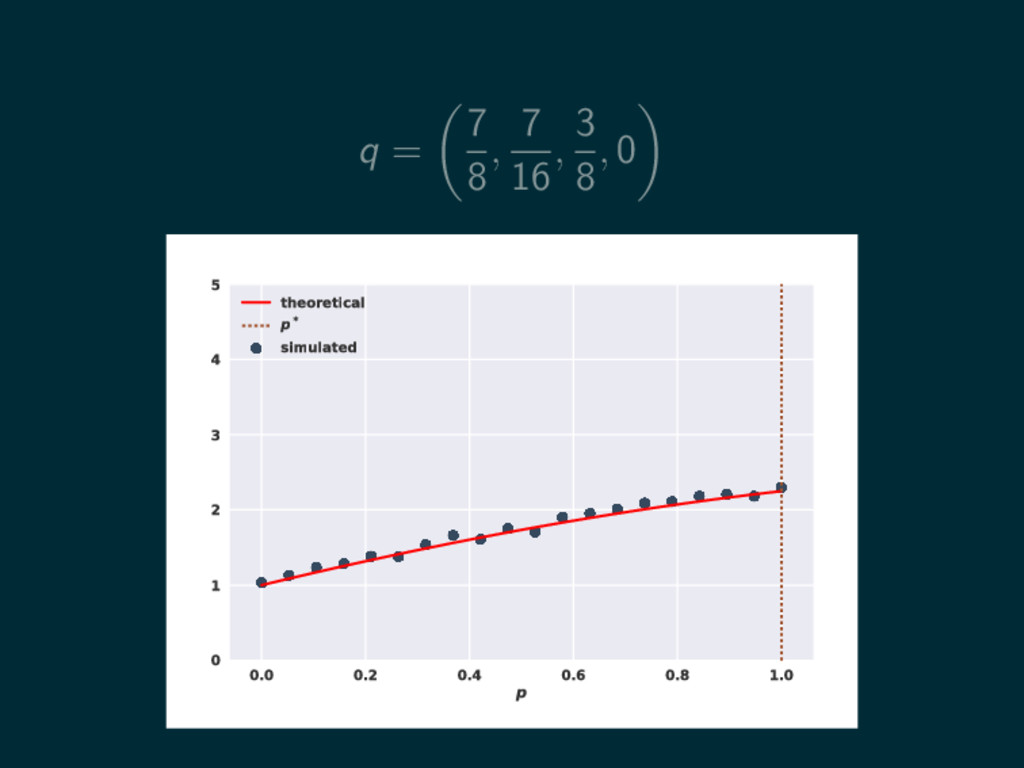
q = 7 8 , 7 16 , 3 8
, 0 0.0 0.2 0.4 0.6 0.8 1.0 p 0 1 2 3 4 5 theoretical p* simulated
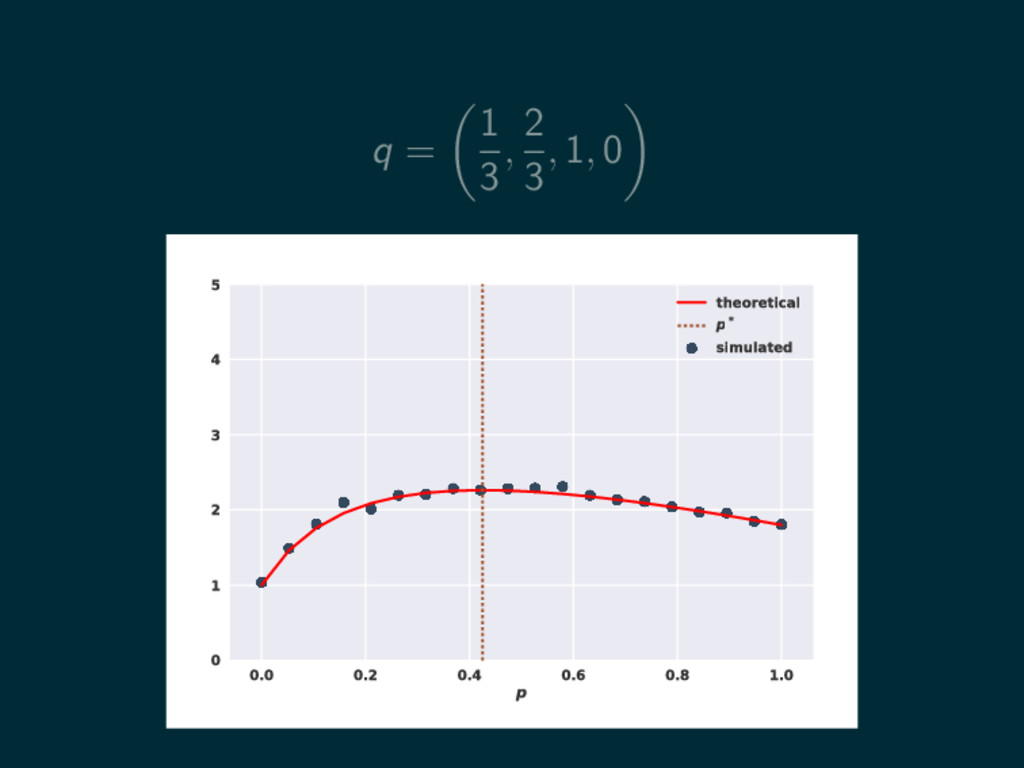
q = 1 3 , 2 3 , 1, 0
0.0 0.2 0.4 0.6 0.8 1.0 p 0 1 2 3 4 5 theoretical p* simulated
q(1), q(2), q(3) . . . q(N) max p 1
N N i=1 uq (i)(p)
q(1), q(2), q(3) . . . q(N) max p 1
N N i=1 uq (i)(p) max p u 1 N N i=1 q(i) (p)
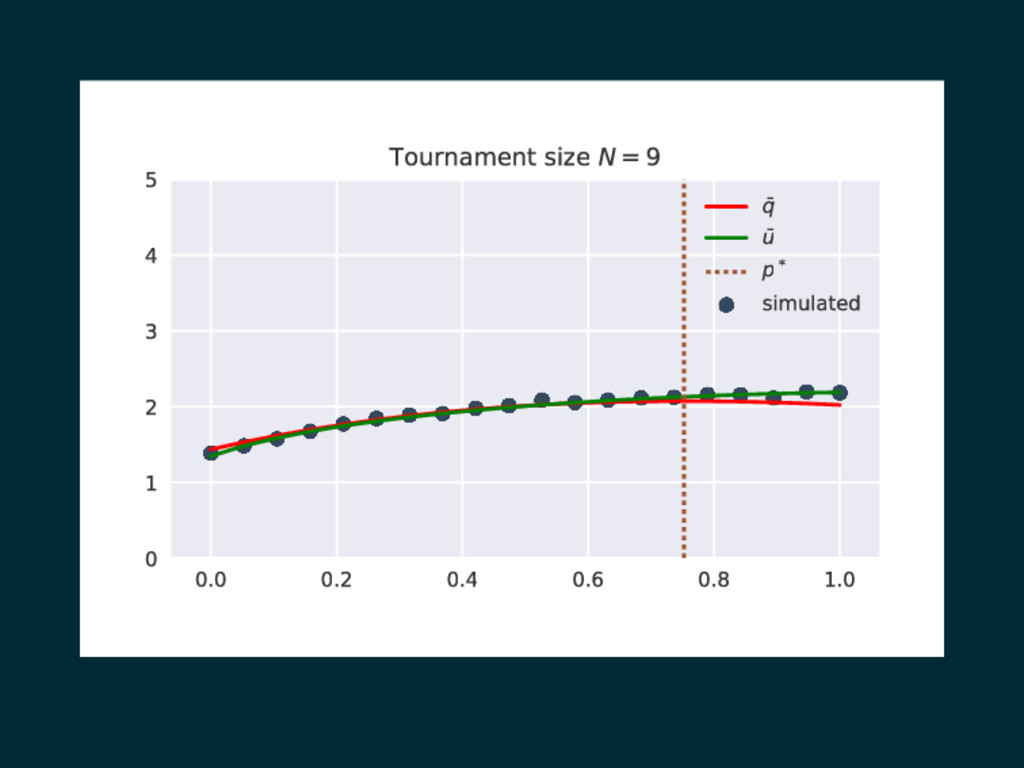
0.0 0.2 0.4 0.6 0.8 1.0 0 1 2 3
4 5 Tournament size N=9 q u p* simulated
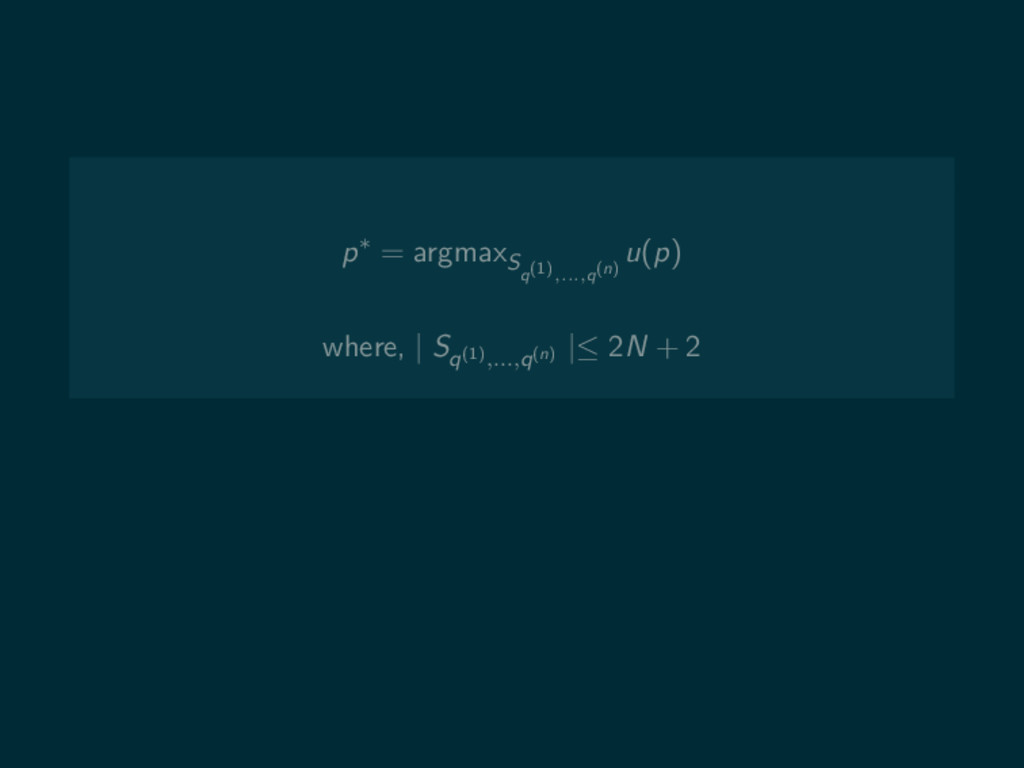
p∗ = argmaxS q(1),...,q(n) u(p) where, | Sq(1),...,q(n) |≤ 2N
+ 2
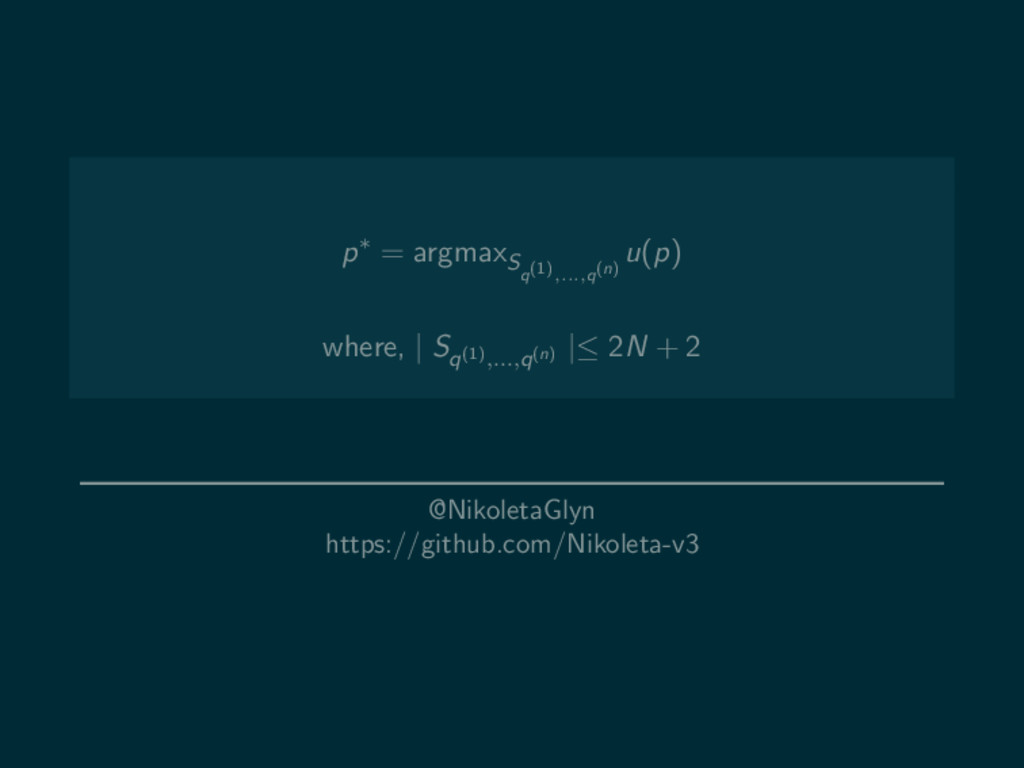
p∗ = argmaxS q(1),...,q(n) u(p) where, | Sq(1),...,q(n) |≤ 2N
+ 2 @NikoletaGlyn https://github.com/Nikoleta-v3


 nikoletav3
 tsoh
 trycycle
 arthur1
 institutdelelevage
 brainpadpr
 analokmaus
 i2tsuki
 tagtag
 samtorres
 elsirapls
 greggifford
 tammyeverts
 mkilby
 livdayseo
 gr2m
 chrislema
 aleyda
 baasie
 marktimemedia