Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
Lightning-fast Machine Learning with Spark
Search
Sponsored
·
Your Podcast. Everywhere. Effortlessly.
Share. Educate. Inspire. Entertain. You do you. We'll handle the rest.
→
Probst Ludwine
November 11, 2014
Programming
1k
6
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
Lightning-fast Machine Learning with Spark
Probst Ludwine
November 11, 2014
Transcript
36 slides
@nivdul #DV14 #MLwithSpark Lightning fast Machine Learning with Spark Ludwine
Probst
@nivdul #Devoxx #MLwithSpark me Data engineer at Leader of Duchess
France
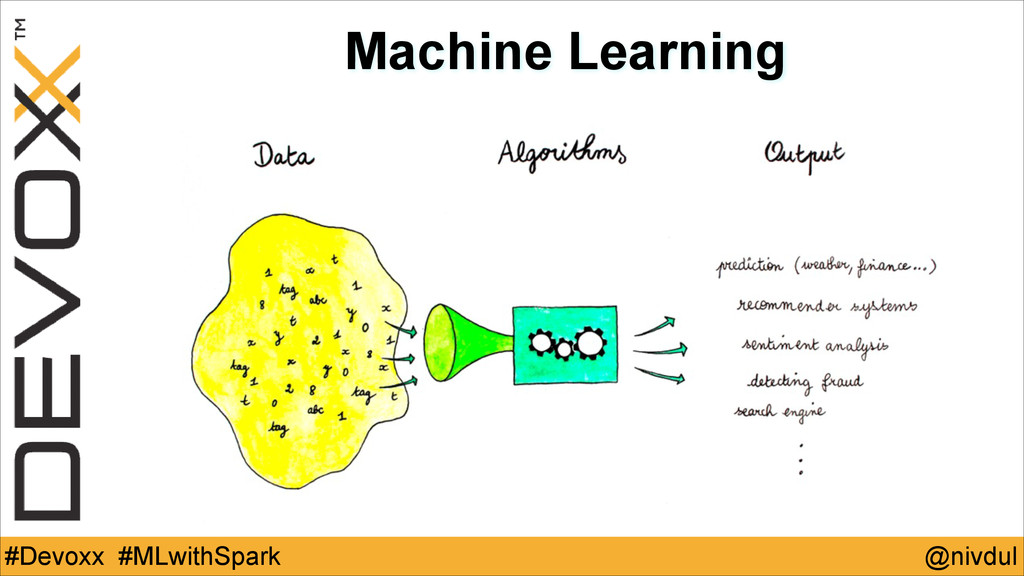
@nivdul #Devoxx #MLwithSpark Machine Learning
@nivdul #DV14 #MLwithSpark MapReduce Lay of the land
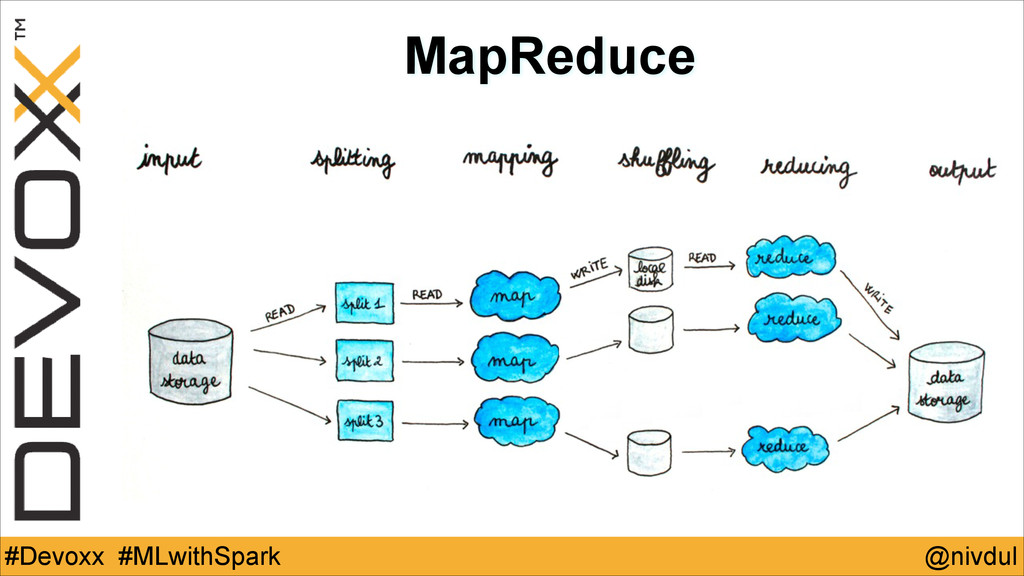
@nivdul #Devoxx #MLwithSpark MapReduce
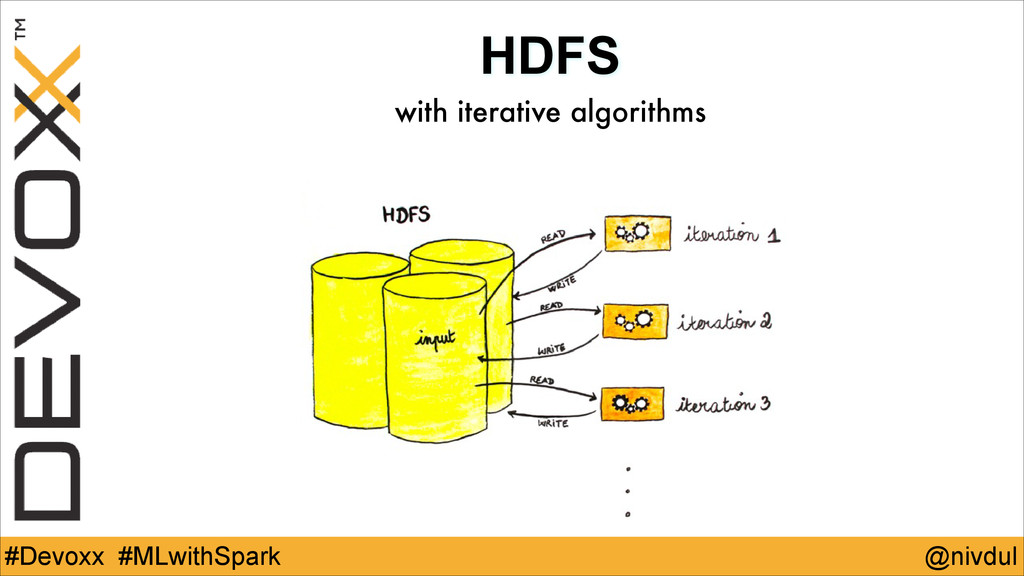
@nivdul #Devoxx #MLwithSpark HDFS with iterative algorithms
@nivdul #Devoxx #MLwithSpark
@nivdul #Devoxx #MLwithSpark is a fast and general engine for
large-scale data processing
@nivdul #DV14 #MLwithSpark •big data analytics in memory/disk •complements Hadoop
•fast and more flexible •Resilient Distributed Datasets (RDD) •shared variables
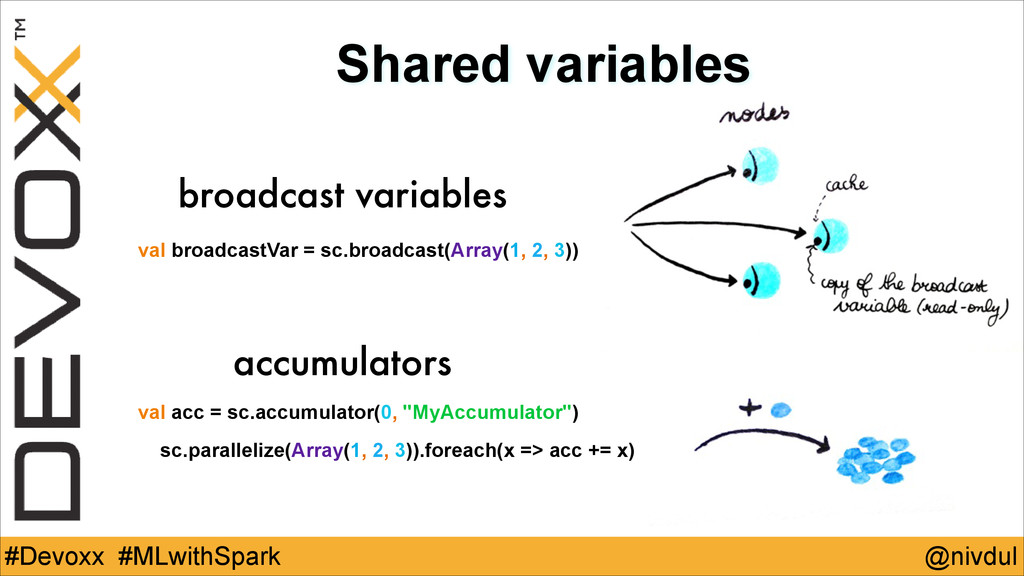
@nivdul #Devoxx #MLwithSpark Shared variables broadcast variables accumulators val broadcastVar
= sc.broadcast(Array(1, 2, 3)) val acc = sc.accumulator(0, "MyAccumulator") sc.parallelize(Array(1, 2, 3)).foreach(x => acc += x)
@nivdul #DV14 #MLwithSpark RDD (Resilient Distributed Datasets) •process in parallel
•controllable persistence (memory, disk…) •higher-level operations (transformation & actions) •rebuilt automatically using lineage
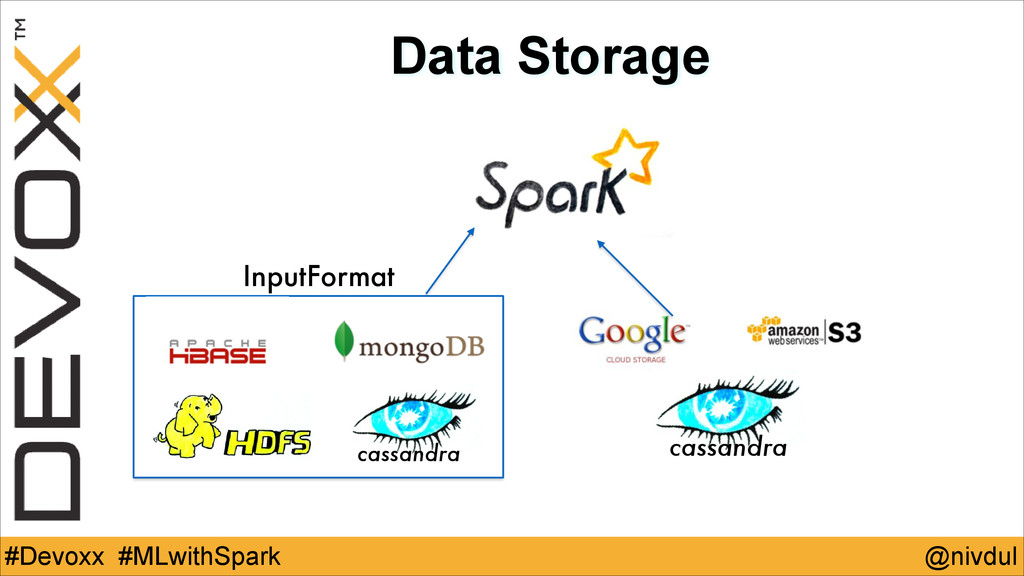
@nivdul #Devoxx #MLwithSpark Data Storage InputFormat cassandra cassandra
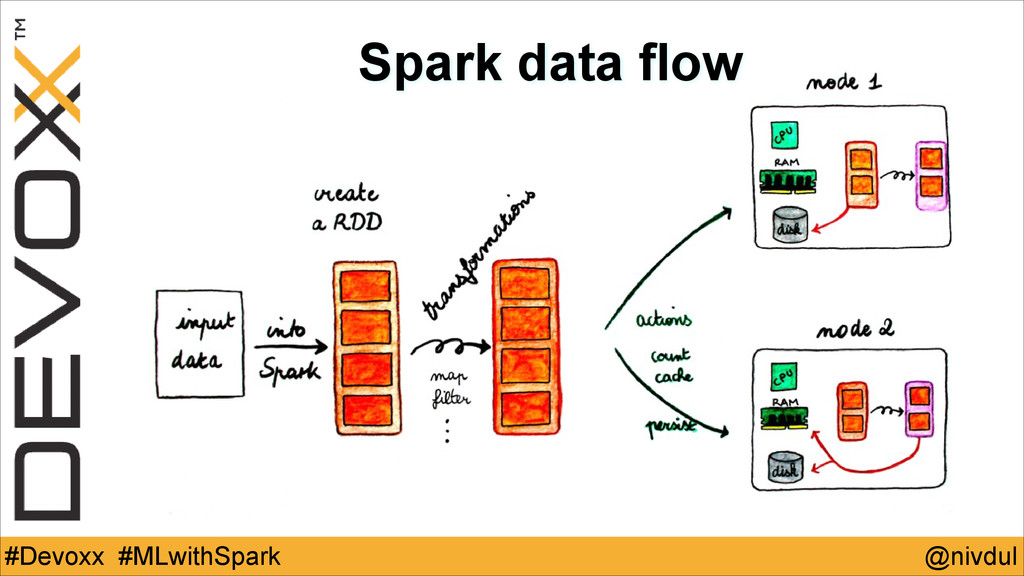
@nivdul #Devoxx #MLwithSpark Spark data flow
@nivdul #Devoxx #MLwithSpark Languages interactive shell (scala & python) Lambda
(Java 8)
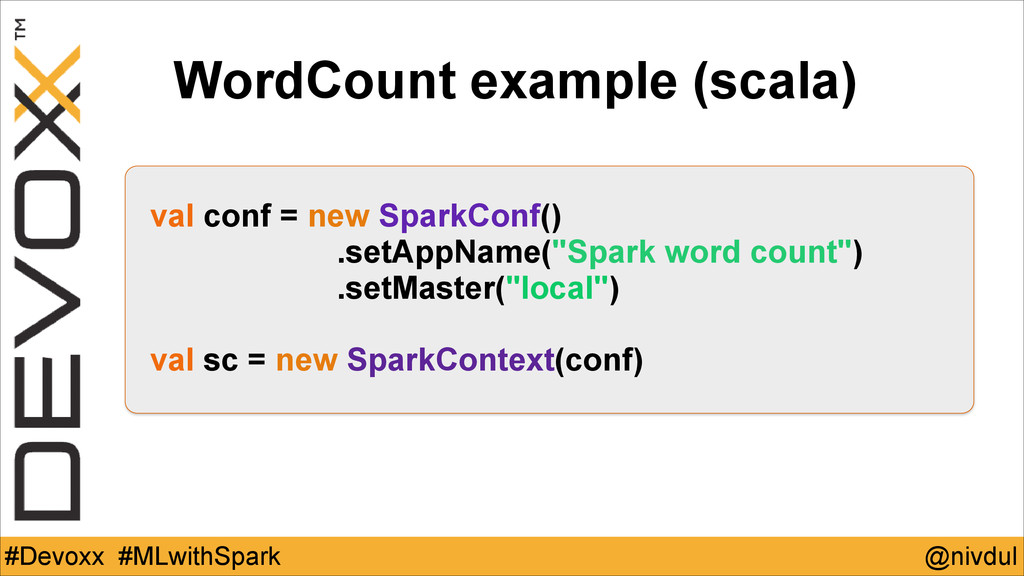
@nivdul #Devoxx #MLwithSpark val conf = new SparkConf() .setAppName("Spark word
count") .setMaster("local") ! val sc = new SparkContext(conf) WordCount example (scala)
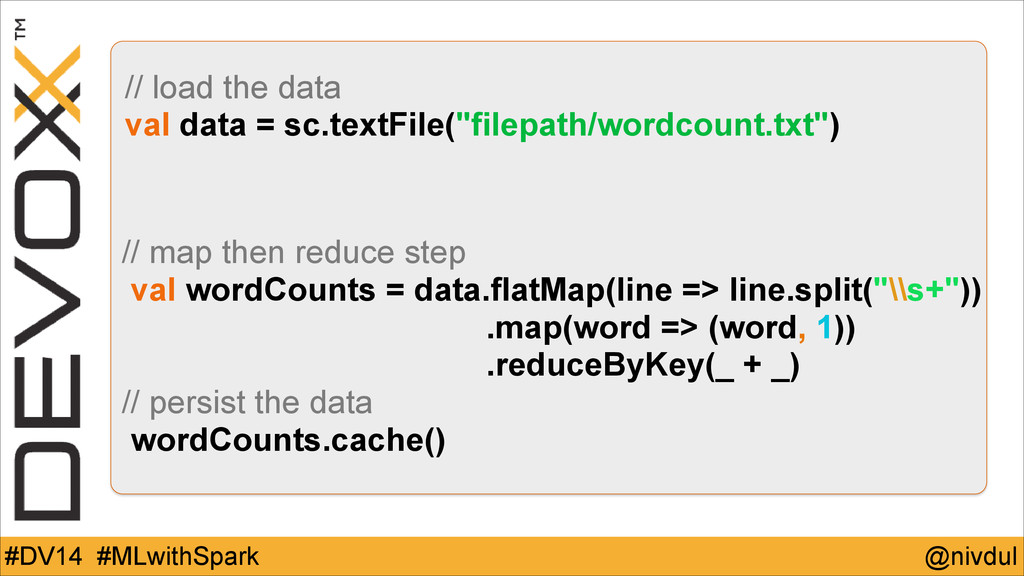
@nivdul #DV14 #MLwithSpark // load the data val data =
sc.textFile("filepath/wordcount.txt") // map then reduce step val wordCounts = data.flatMap(line => line.split("\\s+")) .map(word => (word, 1)) .reduceByKey(_ + _) // persist the data wordCounts.cache()
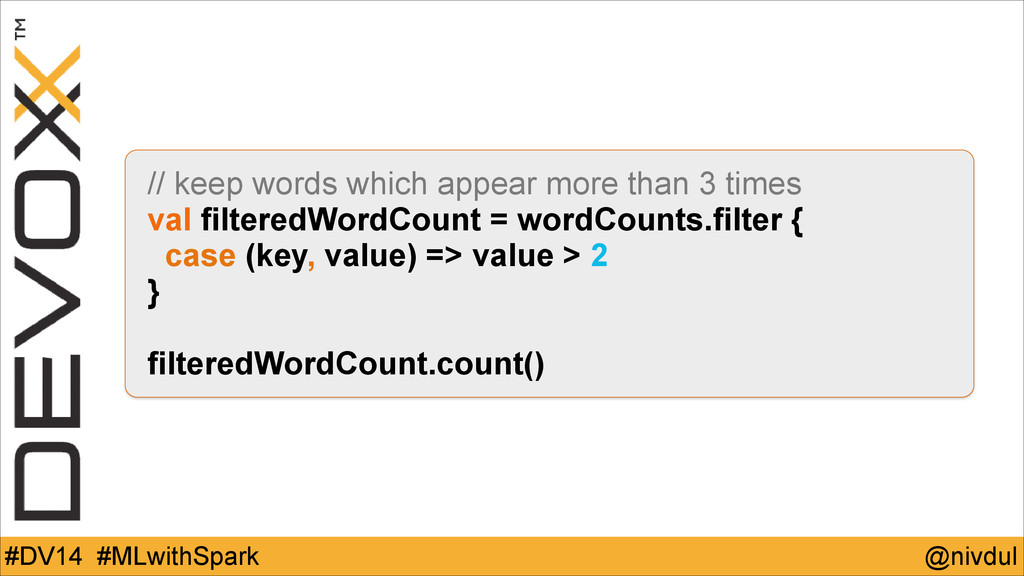
@nivdul #DV14 #MLwithSpark // keep words which appear more than
3 times val filteredWordCount = wordCounts.filter { case (key, value) => value > 2 } ! filteredWordCount.count()
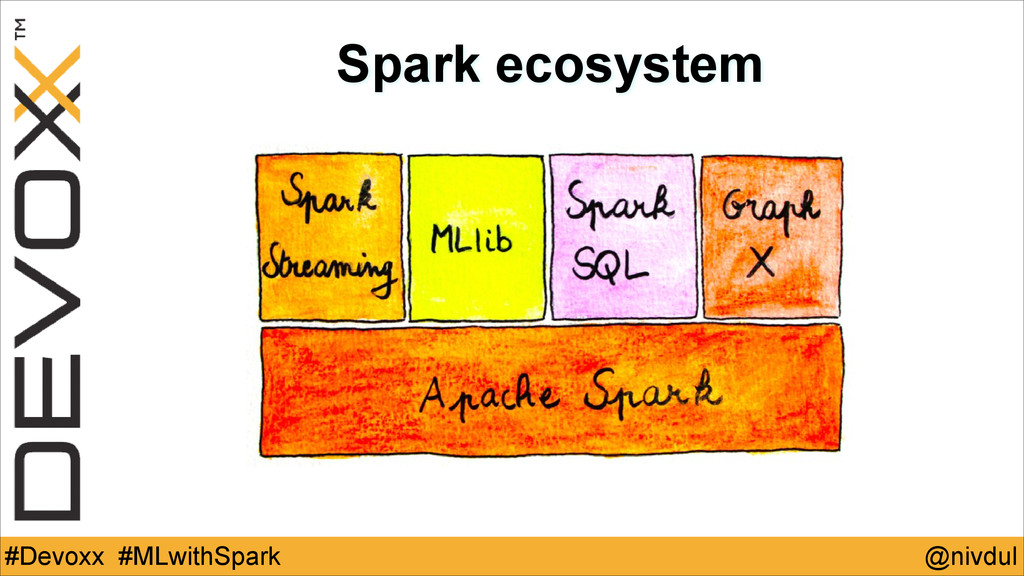
@nivdul #Devoxx #MLwithSpark Spark ecosystem
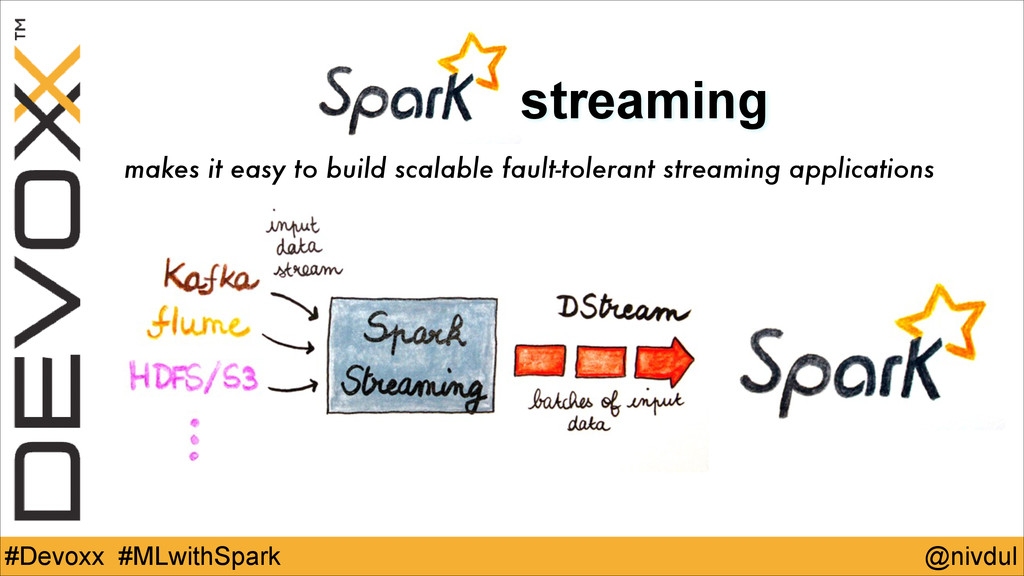
@nivdul #Devoxx #MLwithSpark streaming makes it easy to build scalable
fault-tolerant streaming applications
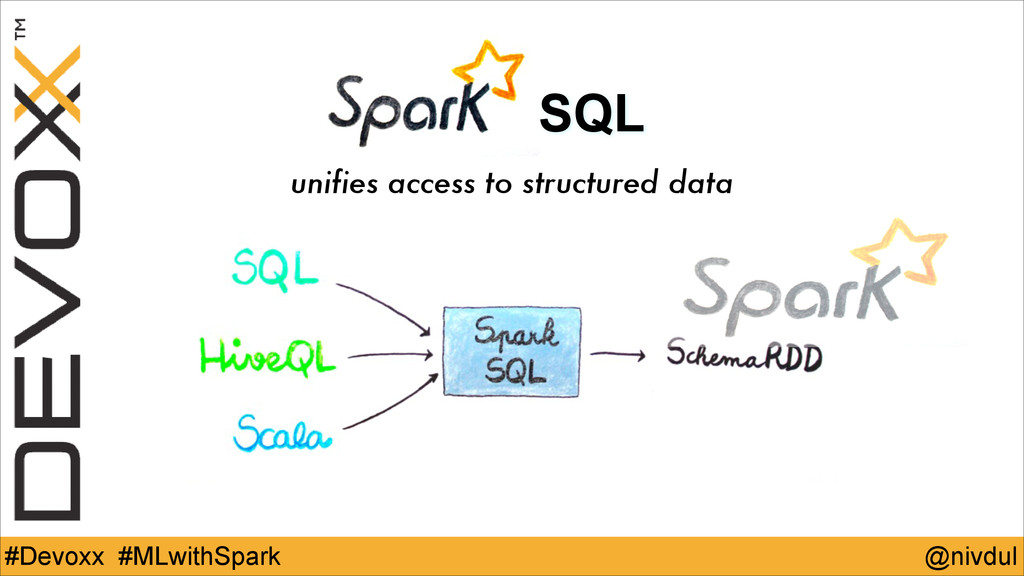
@nivdul #Devoxx #MLwithSpark SQL unifies access to structured data
@nivdul #Devoxx #MLwithSpark is Apache Spark's API for graphs and
graph-parallel computation
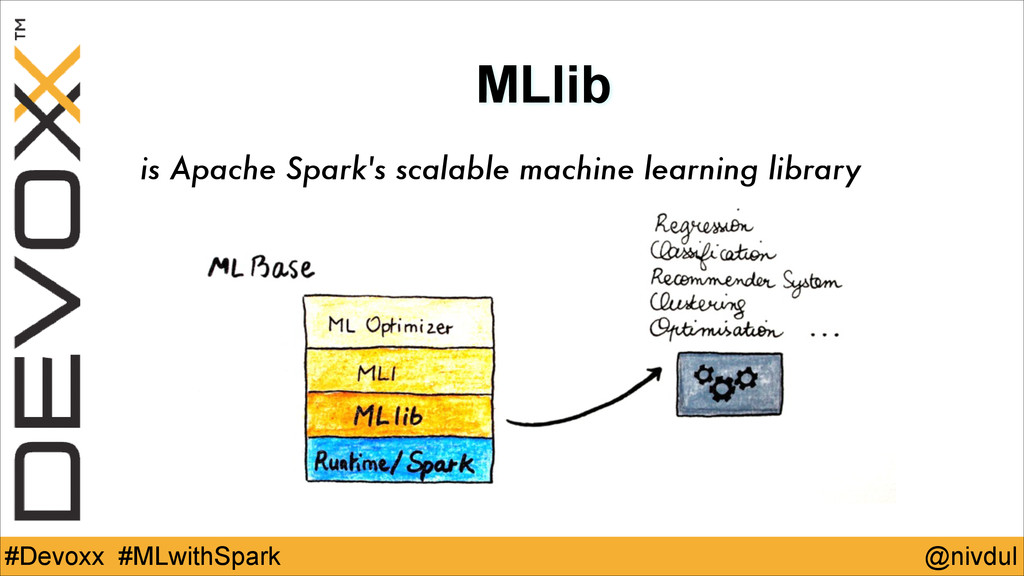
@nivdul #Devoxx #MLwithSpark MLlib is Apache Spark's scalable machine learning
library
@nivdul #Devoxx #MLwithSpark Machine learning with Spark / MLlib
@nivdul #Devoxx #MLwithSpark Machine learning libraries scikit
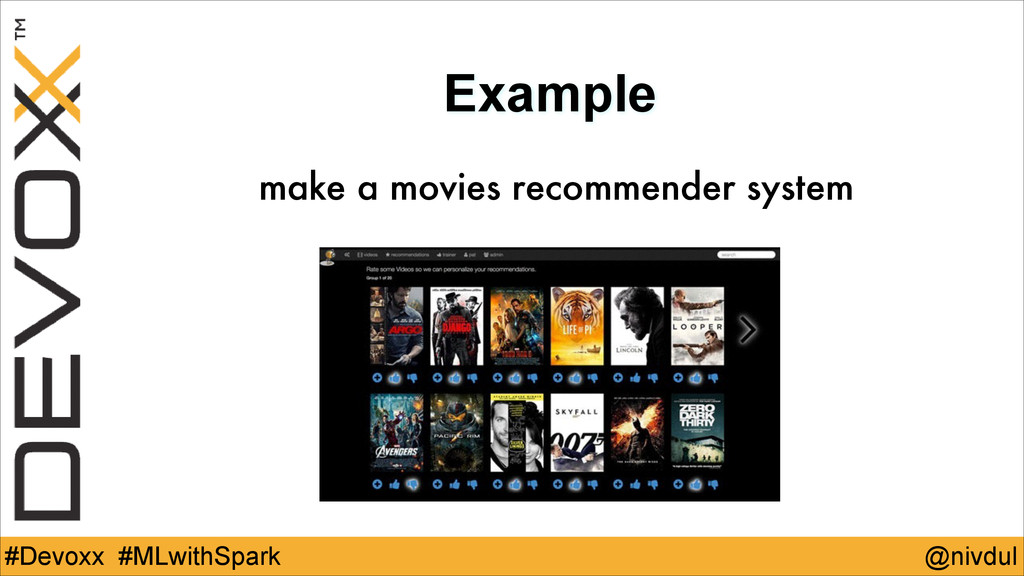
@nivdul #Devoxx #MLwithSpark Example make a movies recommender system
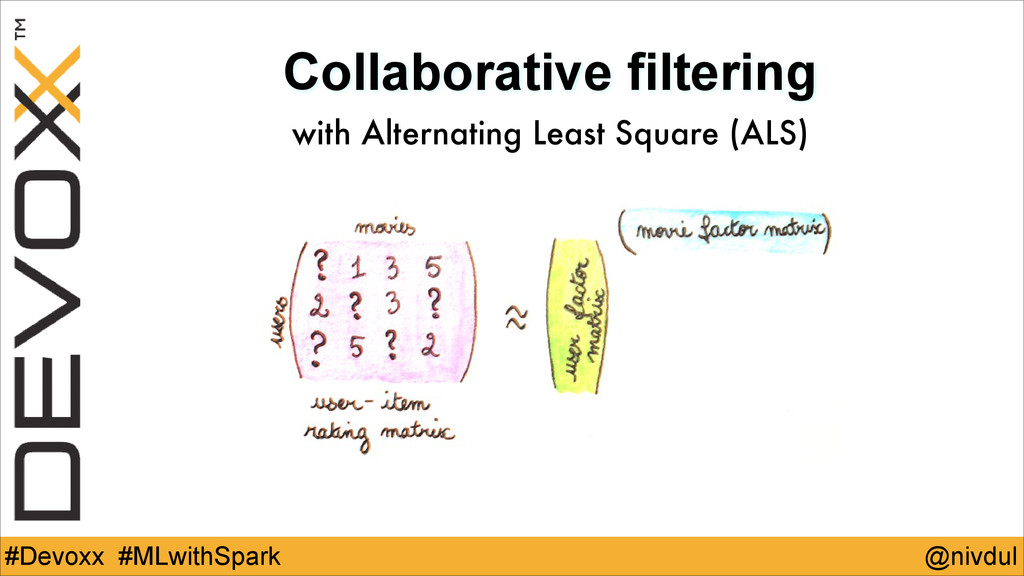
@nivdul #Devoxx #MLwithSpark Collaborative filtering with Alternating Least Square (ALS)
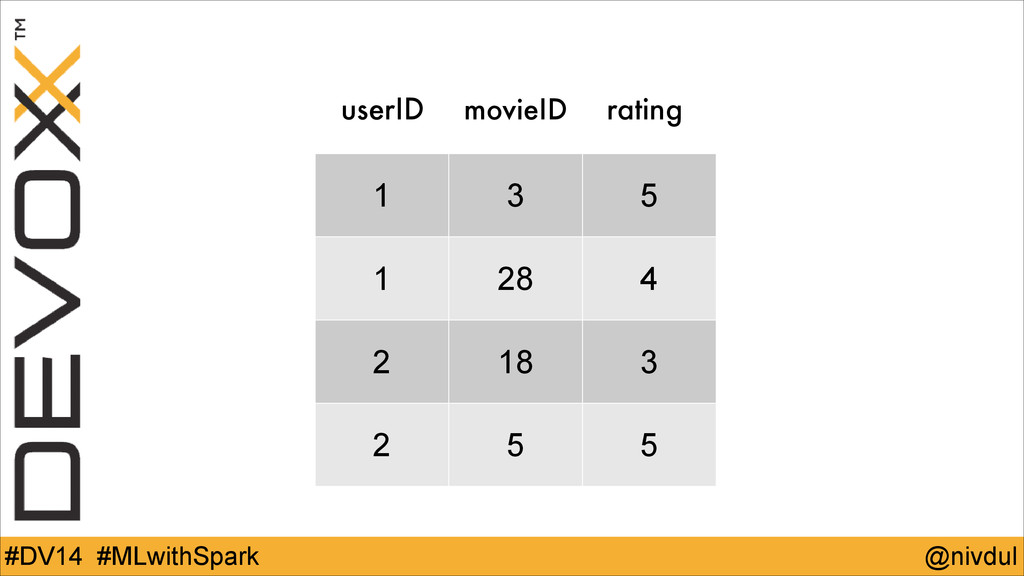
@nivdul #DV14 #MLwithSpark 1 3 5 1 28 4 2
18 3 2 5 5 userID movieID rating
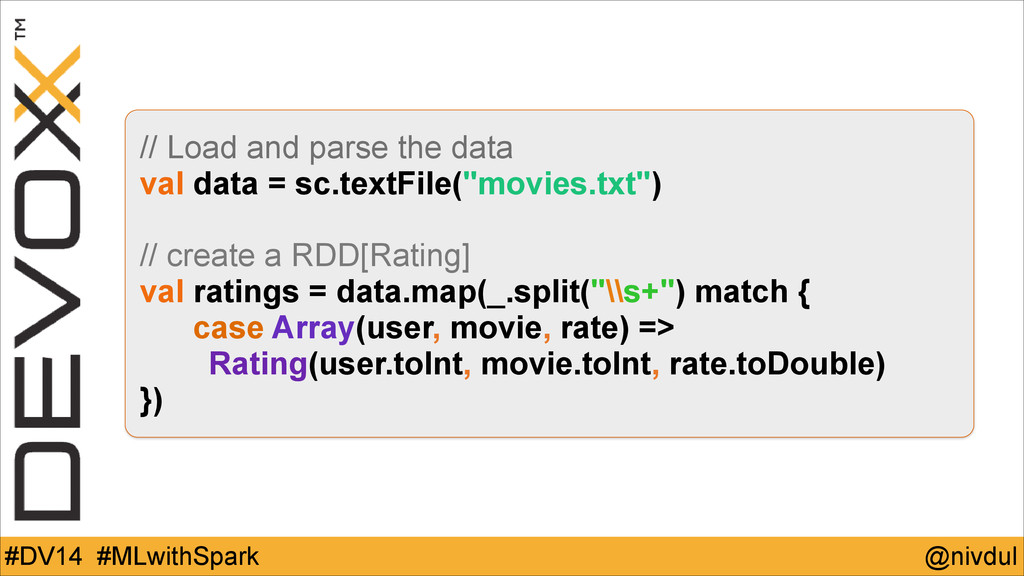
@nivdul #DV14 #MLwithSpark // Load and parse the data val
data = sc.textFile("movies.txt") ! // create a RDD[Rating] val ratings = data.map(_.split("\\s+") match { case Array(user, movie, rate) => Rating(user.toInt, movie.toInt, rate.toDouble) })
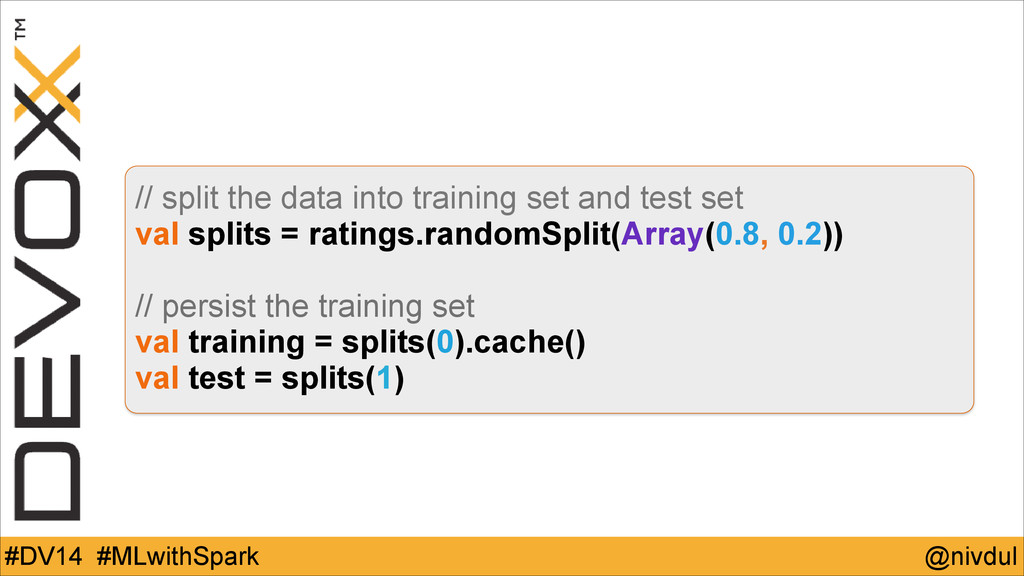
@nivdul #DV14 #MLwithSpark // split the data into training set
and test set val splits = ratings.randomSplit(Array(0.8, 0.2)) ! // persist the training set val training = splits(0).cache() val test = splits(1)
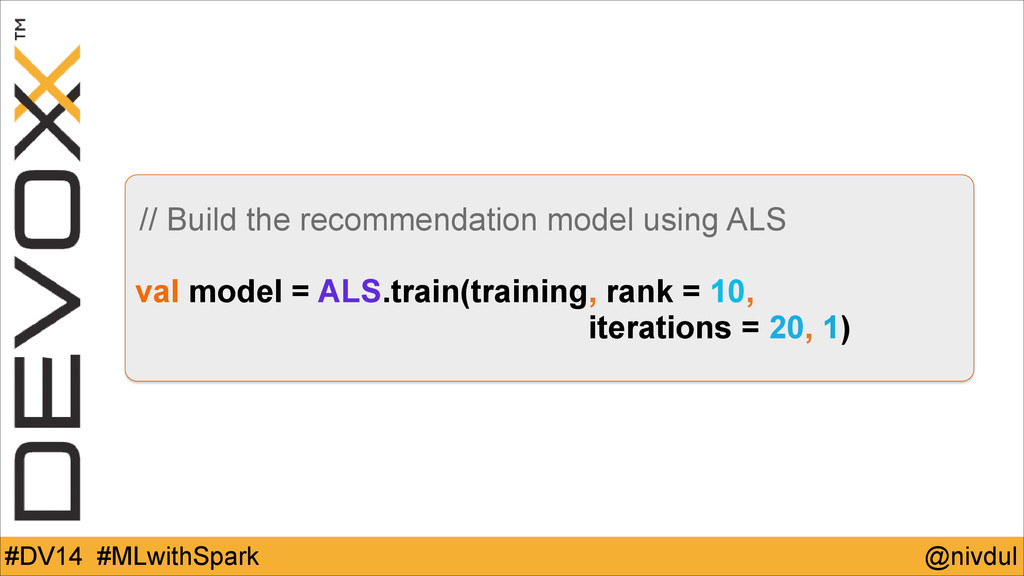
@nivdul #DV14 #MLwithSpark // Build the recommendation model using ALS
! val model = ALS.train(training, rank = 10, iterations = 20, 1)
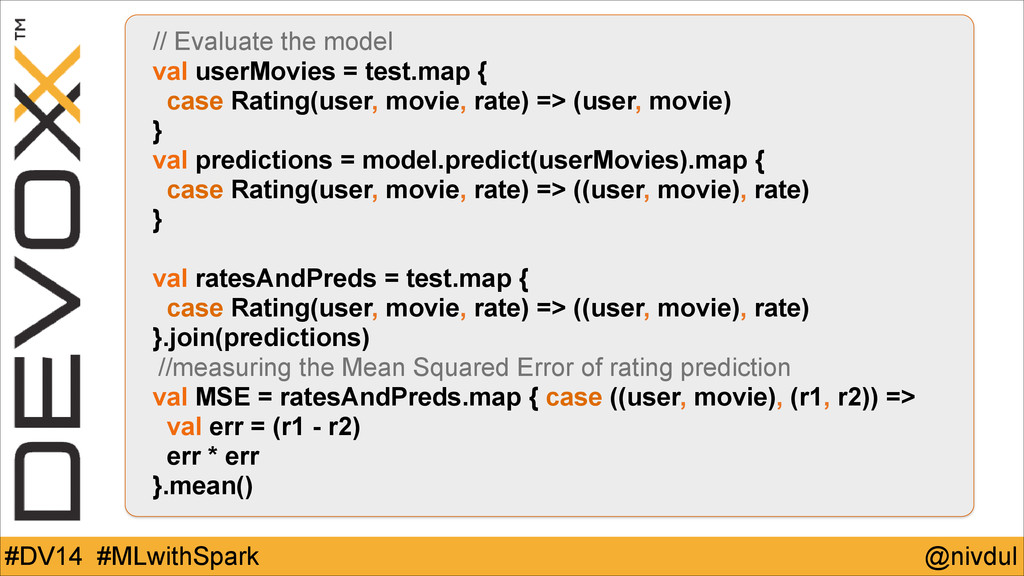
@nivdul #DV14 #MLwithSpark // Evaluate the model val userMovies =
test.map { case Rating(user, movie, rate) => (user, movie) } val predictions = model.predict(userMovies).map { case Rating(user, movie, rate) => ((user, movie), rate) } ! val ratesAndPreds = test.map { case Rating(user, movie, rate) => ((user, movie), rate) }.join(predictions) //measuring the Mean Squared Error of rating prediction val MSE = ratesAndPreds.map { case ((user, movie), (r1, r2)) => val err = (r1 - r2) err * err }.mean()
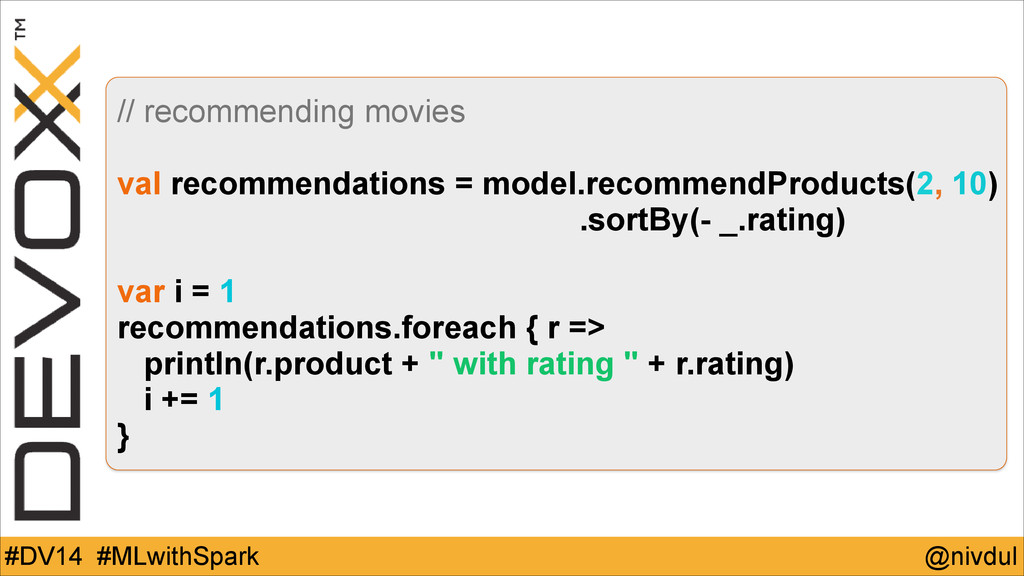
@nivdul #DV14 #MLwithSpark // recommending movies ! val recommendations =
model.recommendProducts(2, 10) .sortBy(- _.rating) ! var i = 1 recommendations.foreach { r => println(r.product + " with rating " + r.rating) i += 1 }
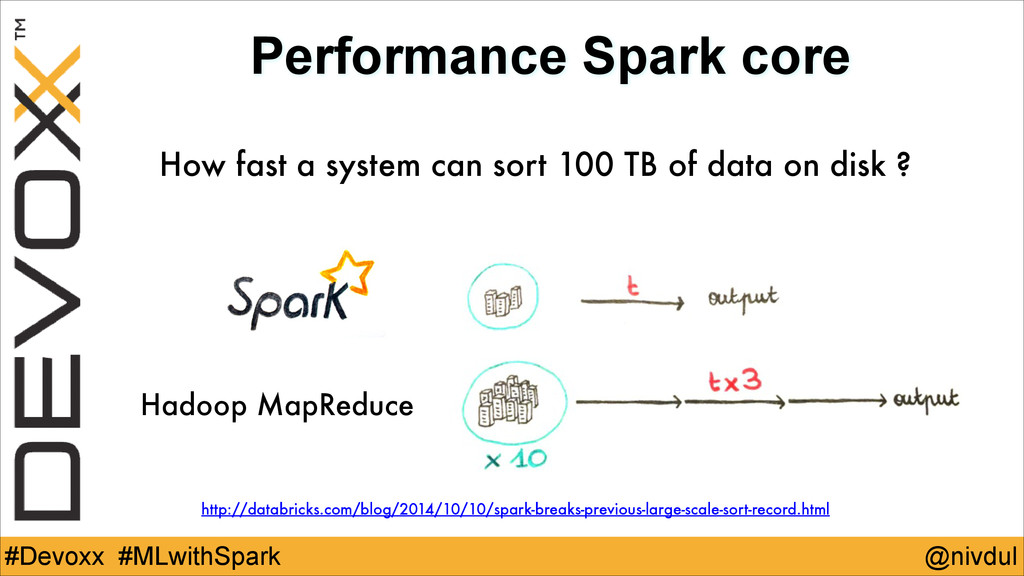
@nivdul #Devoxx #MLwithSpark Performance Spark core Hadoop MapReduce http://databricks.com/blog/2014/10/10/spark-breaks-previous-large-scale-sort-record.html How
fast a system can sort 100 TB of data on disk ?
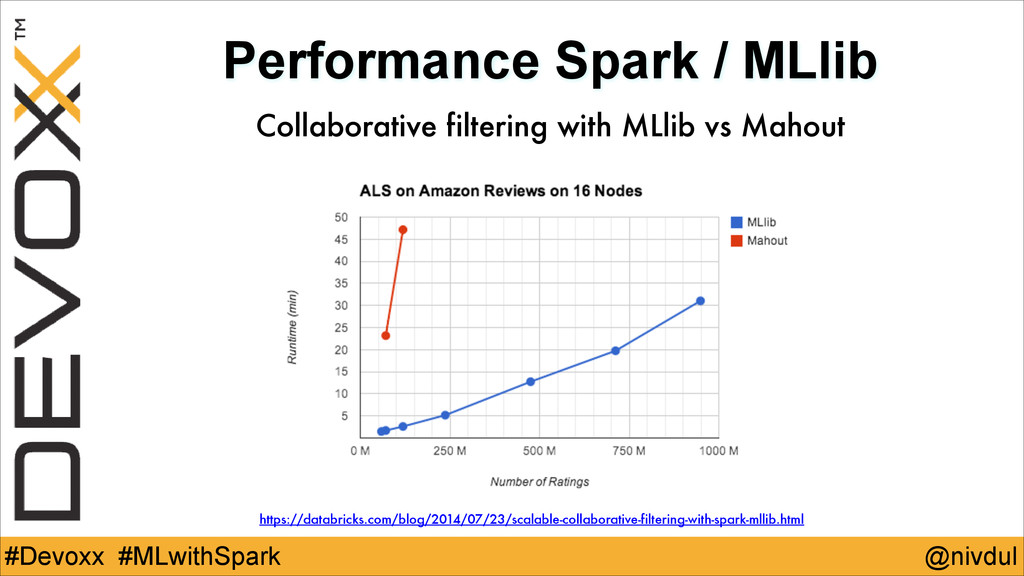
@nivdul #Devoxx #MLwithSpark Performance Spark / MLlib Collaborative filtering with
MLlib vs Mahout https://databricks.com/blog/2014/07/23/scalable-collaborative-filtering-with-spark-mllib.html
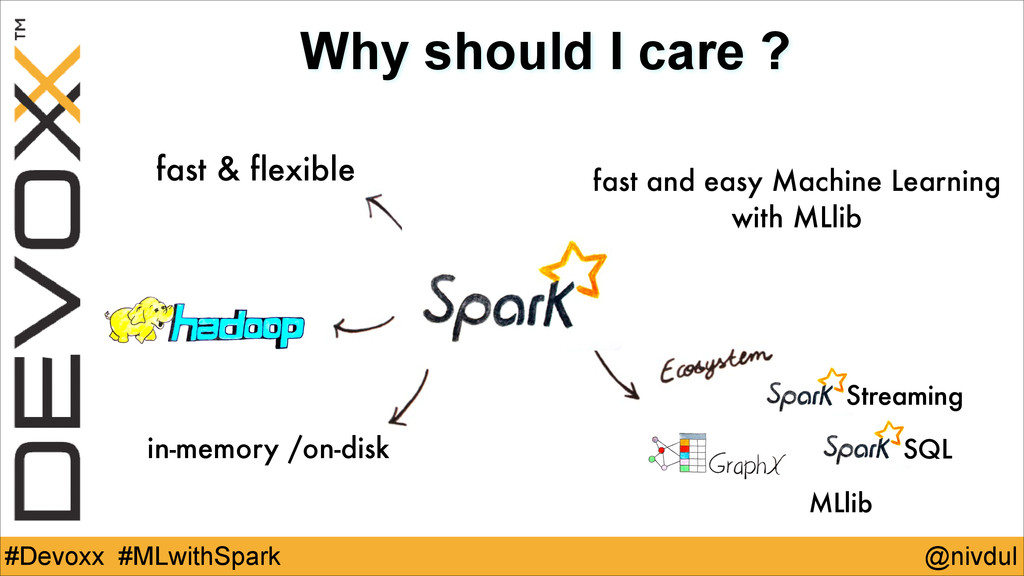
@nivdul #Devoxx #MLwithSpark Why should I care ? fast and
easy Machine Learning with MLlib fast & flexible in-memory /on-disk SQL Streaming MLlib
None
More Decks by Probst Ludwine
See All by Probst Ludwine
Tech Beyond Borders
nivdul
0
250
Tech Beyond Borders
nivdul
0
110
Analytics in the age of the Internet of Things
nivdul
1
270
Lightning-fast Machine Learning with Spark
nivdul
15
5.4k
Introduction to Spark
nivdul
4
660
Other Decks in Programming
See All in Programming
Goコンパイラを作ってGoをもっと理解する / Build a Go compiler to better understand Go
ikura_hamu
0
130
S3 TablesのIcebergデータに、AIエージェントからアクセスしてみた / 20261016developersio2026joetsu-accessing-iceberg-in-s3tables-via-agent
kasacchiful
PRO
0
310
Kawaiicon: Kubernetes, it's no longer cool, but let's secure it anyway!
barnbarn
0
130
クラウドエージェントは、 何がそんなに便利なのか / what makes cloud agents so useful
rkaga
5
850
PumaからFalconに移行したRailsアプリケーションでの実践
falcon8823
0
380
Railsバージョンを4倍にした話
optim
0
1k
プロジェクトコードをキレイキレイしよう!暗黙的な参照を読み解く静的解析
ostk0069
0
210
Spec-driven Development with AI
simas
PRO
0
2.3k
flutter_test のその先へ — Flutter アプリの LLM 機能に「評価」という品質保証を
kosukesaigusa
0
200
LLM 101
dalinaum
0
480
Vapor Mode でアクセシビリティは 壊れないか検証した話
fuqda
1
340
仕様駆動開発入門 (何を作るかを先に決めて渡す) | 目指せ Kiro マスター 05
inariku
PRO
2
130
Featured
See All Featured
Build your cross-platform service in a week with App Engine
jlugia
234
19k
Measuring Dark Social's Impact On Conversion and Attribution
stephenakadiri
2
330
Ecommerce SEO: The Keys for Success Now & Beyond - #SERPConf2024
aleyda
1
2.3k
What's in a price? How to price your products and services
michaelherold
247
13k
The B2B funnel & how to create a winning content strategy
katarinadahlin
PRO
1
610
Bash Introduction
62gerente
615
220k
HTML-Aware ERB: The Path to Reactive Rendering @ RubyCon 2026, Rimini, Italy
marcoroth
6
920
Redefining SEO in the New Era of Traffic Generation
szymonslowik
1
530
WCS-LA-2024
lcolladotor
0
990
Tell your own story through comics
letsgokoyo
1
1.1k
Performance Is Good for Brains [We Love Speed 2024]
tammyeverts
12
1.9k
Bioeconomy Workshop: Dr. Julius Ecuru, Opportunities for a Bioeconomy in West Africa
akademiya2063
PRO
1
460


 nivdul
 ikura_hamu
 kasacchiful
 barnbarn
 rkaga
 falcon8823
 optim
 ostk0069
 simas
 kosukesaigusa
 dalinaum
 fuqda
 inariku
 jlugia
 stephenakadiri
 aleyda
 michaelherold
 katarinadahlin
 62gerente
 marcoroth
 szymonslowik
 lcolladotor
 letsgokoyo
 tammyeverts
 akademiya2063