Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
TUT Python スクレイピングハンズオン
Search
panakuma
February 03, 2018
Education
460
0
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
TUT Python スクレイピングハンズオン
panakuma
February 03, 2018
More Decks by panakuma
See All by panakuma
jsnog-lt-1_イベントNOCの裏側
panakuma
0
300
DTCP-IPをVPNで
panakuma
0
3.2k
TUT Python 初心者入門
panakuma
0
450
Other Decks in Education
See All in Education
DRONEGEOGRAFÍA: INNOVACIÓN DIDÁCTICA Y FOTOGRAMETRÍA 3D PARA LA COHESIÓN TERRITORIAL Y LA CIUDADANÍA ACTIVA
juanmartin2026
0
8k
[2026前期火5] 論理学(京都大学文学部 前期 第13回)「走って、止まって、積み上がる」
yatabe
0
280
Introduction to M&A
bvr7352
0
230
Introduction - Lecture 1 - Web Technologies (1019888BNR)
signer
PRO
0
6.5k
医療事務養成の専門学校でのAI教育 非エンジニアの学生にAIを1年間使ってもらって、感じたこと
naochim2026
0
140
日本における応用言語学・言語教育学 これまでとこれから
terasawat
0
120
DecisionesEjecutivasCrisis
mariooc
0
420
2026年7月15日情報メディア入門Ⅰ・情報可視化とは
imash
0
110
生成AIとの付き合い方/ How to work with AI
kaityo256
PRO
3
790
Plano urbano de Madrid desde el Ensanche al s. XXI (2ª parte).
juanmartin2026
1
100k
第2部-高校生とAI活用/high-school2026-2
okana2ki
0
210
Sekolah Sabat - Triwulan 4 2026 - Pelajaran 1
hiola
0
12k
Featured
See All Featured
Skip the Path - Find Your Career Trail
mkilby
1
240
Exploring the relationship between traditional SERPs and Gen AI search
raygrieselhuber
PRO
4
4.3k
Impact Scores and Hybrid Strategies: The future of link building
tamaranovitovic
0
450
KATA
mclloyd
PRO
35
16k
[RailsConf 2023] Rails as a piece of cake
palkan
59
7.1k
Designing Dashboards & Data Visualisations in Web Apps
destraynor
232
55k
How to Create Impact in a Changing Tech Landscape [PerfNow 2023]
tammyeverts
56
3.5k
A Tale of Four Properties
chriscoyier
163
24k
Building Flexible Design Systems
yeseniaperezcruz
330
41k
A Guide to Academic Writing Using Generative AI - A Workshop
ks91
PRO
1
510
Prompt Engineering for Job Search
mfonobong
0
490
How to optimise 3,500 product descriptions for ecommerce in one day using ChatGPT
katarinadahlin
PRO
3
3.9k
Transcript
Python Boot Camp in TUT Python 初心者入門 第2回 スクレイピング
スクレイピングとは • ウェブサイトから情報を抽出するコンピュータソフトウェア技術のこと。 (Wikipedia 日本語版 ウェブスクレイピング より引用)
スクレイピングに必要なモノ(ライブラリ) •urlilb5 •beautifulsoup4
ライブラリのインストール (1) •pipyというライブラリ管理ツールを使います。 •ubuntu でいうaptitude(apt)と同じような感じのものと思って下さい。
ライブラリのインストール (2) •まず、pip3をaptでインストールします。 •sudo apt install python3-pip •pip3でurlli5とbeautifulsoup4をインストールします。 •sudo pip3
install urllib5 beautifulsoup4
ライブラリの使い方 (1) •プログラム内でライブラリを使うときにはimportをします。 • importの仕方 ライブラリ全体をimport import ライブラリ名 ライブラリの一部をimport from
ライブラリ名 import 関数名など
ライブラリの使い方 (2) •importしたものに別の名前をつけることもできます。 •例えば長い関数名を省略したいときなんかに便利です。 from ライブラリ名 import 関数名 as 別名
スクレイピングの基本 •まずスクレイピングするサイトの構造を観察します。 •自分が取得したい情報が入っているタグなどを見つけます。 •またタグに振ってあるクラスやIDも手がかりになります。
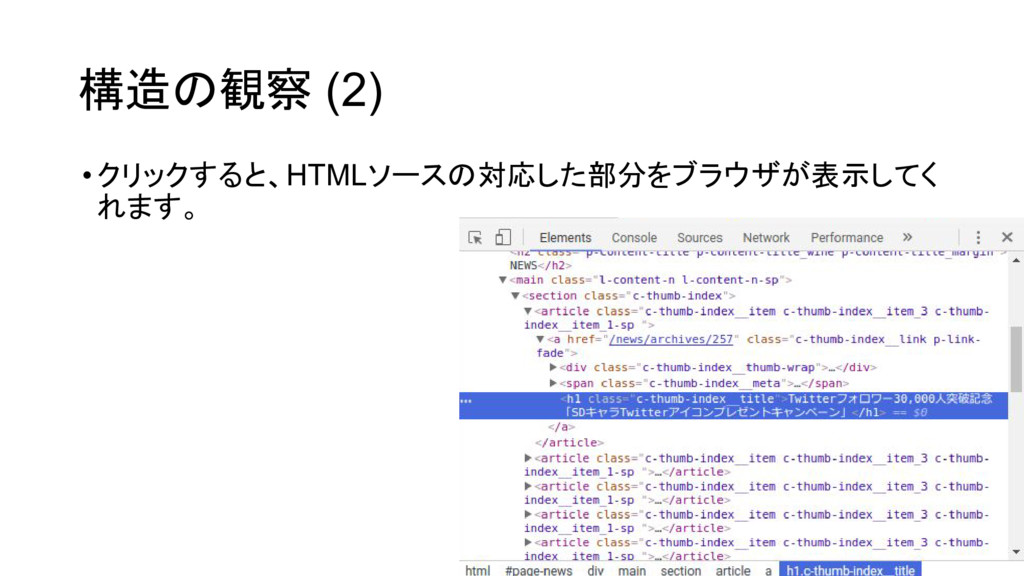
構造の観察 (1) •今回、「妹さえいればいい。」のニュースページをスクレイピングして いきたいと思いますので、まずそのサイトを開き、キーボードの[F12] を押して下さい。 •開発者ツールが開きますので、開発者ツール左上の要素選択ツー ルをクリックして、拾いたい要素(今回はニュースのタイトル)をクリッ クします。
構造の観察 (2) •クリックすると、HTMLソースの対応した部分をブラウザが表示してく れます。
構造の観察 (3) •この要素は h1タグで 「c-thumb-index__title」というクラスである •ということがわかります。 •これを手がかりに、データを抽出していきます。
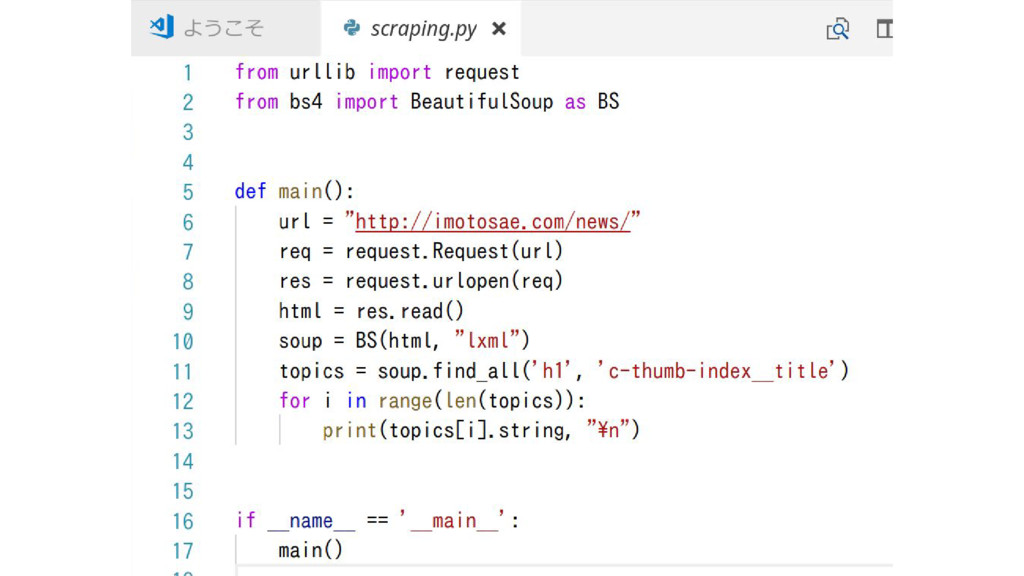
スクレイピング (1) •まずは以下のサイトのコードを「scraping.py」というファイルに入力し て実行してみたください。 https://goo.gl/mDyxXU
None
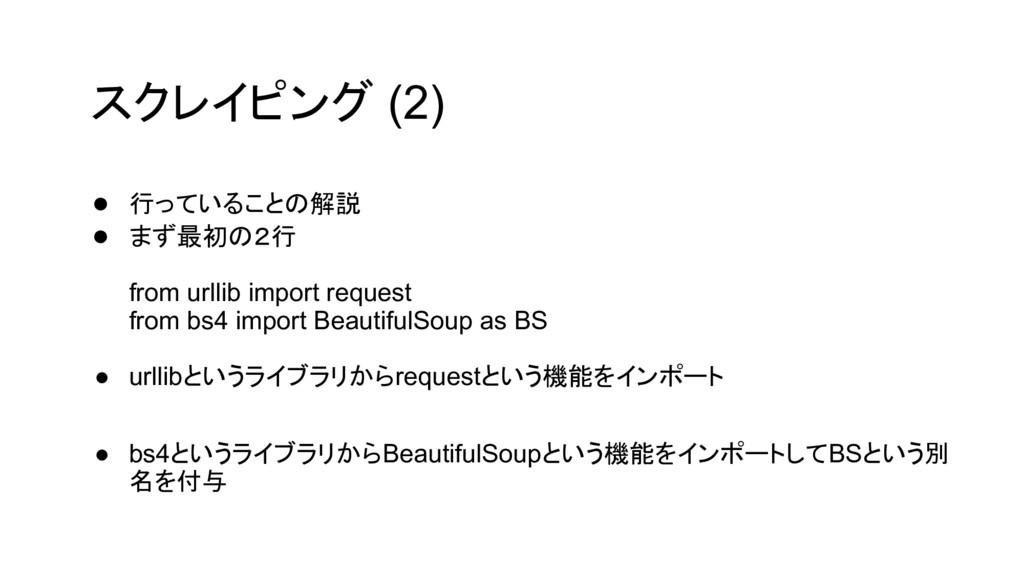
スクレイピング (2) • 行っていることの解説 • まず最初の2行 from urllib import request
from bs4 import BeautifulSoup as BS • urllibというライブラリからrequestという機能をインポート • bs4というライブラリからBeautifulSoupという機能をインポートしてBSという別 名を付与
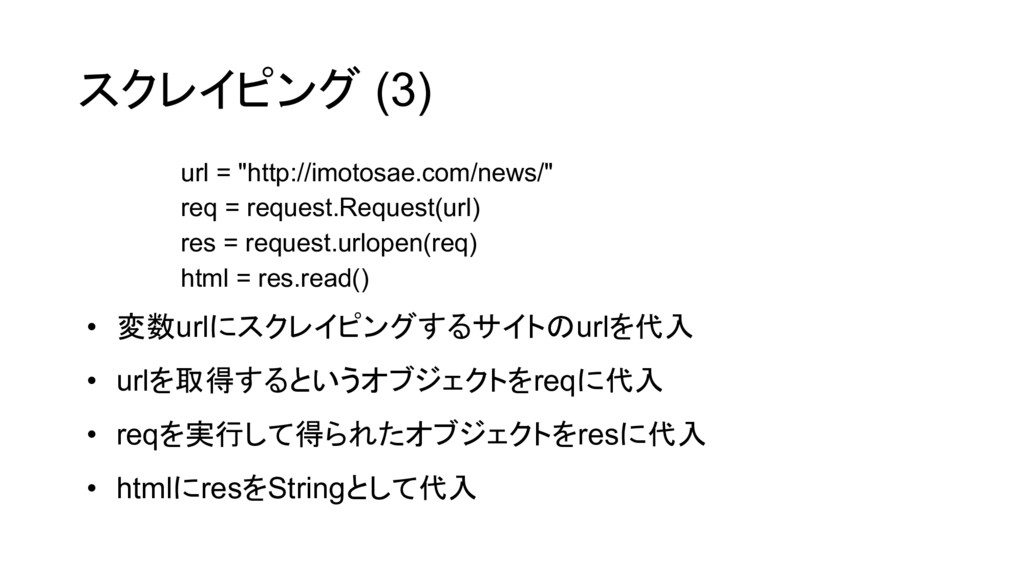
スクレイピング (3) url = "http://imotosae.com/news/" req = request.Request(url) res =
request.urlopen(req) html = res.read() • 変数urlにスクレイピングするサイトのurlを代入 • urlを取得するというオブジェクトをreqに代入 • reqを実行して得られたオブジェクトをresに代入 • htmlにresをStringとして代入
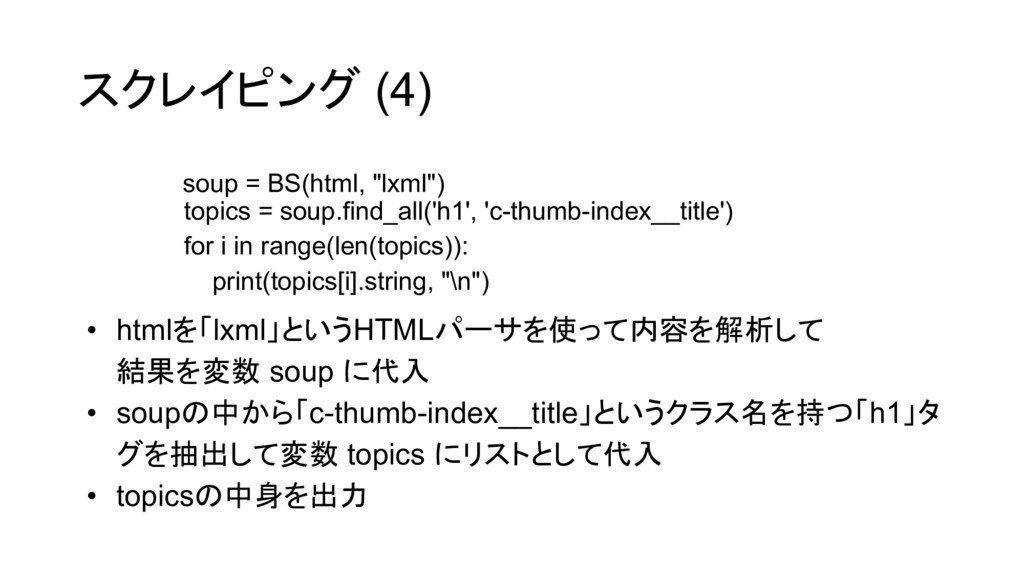
スクレイピング (4) soup = BS(html, "lxml") topics = soup.find_all('h1', 'c-thumb-index__title')
for i in range(len(topics)): print(topics[i].string, "\n") • htmlを「lxml」というHTMLパーサを使って内容を解析して 結果を変数 soup に代入 • soupの中から「c-thumb-index__title」というクラス名を持つ「h1」タ グを抽出して変数 topics にリストとして代入 • topicsの中身を出力


 panakuma
 juanmartin2026
 yatabe
 bvr7352
 signer
 naochim2026
 terasawat
 mariooc
 imash
 kaityo256
 okana2ki
 hiola
 mkilby
 raygrieselhuber
 tamaranovitovic
 mclloyd
 palkan
 destraynor
 tammyeverts
 chriscoyier
 yeseniaperezcruz
 ks91
 mfonobong
 katarinadahlin