Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
第三回 全日本コンピュータビジョン勉強会(後編)
Search
Sponsored
·
Ship Features Fearlessly
Turn features on and off without deploys. Used by thousands of Ruby developers.
→
TSUKAMOTO Kenji
July 18, 2020
Technology
1k
1
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
第三回 全日本コンピュータビジョン勉強会(後編)
論文:RandLA-Net: Efficient Semantic Segmentation of Large-Scale Point Clouds
TSUKAMOTO Kenji
July 18, 2020
More Decks by TSUKAMOTO Kenji
See All by TSUKAMOTO Kenji
第67回コンピュータビジョン勉強会CVPR2026読会前編
tsukamotokenji
0
240
第65回コンピュータビジョン勉強会
tsukamotokenji
0
290
第64回コンピュータビジョン勉強会@関東(後編)
tsukamotokenji
0
360
DynIBaR (第60回CV勉強会@関東)
tsukamotokenji
0
280
DeepSFM: Structure from Motion Via Deep Bundle Adjustment
tsukamotokenji
2
670
Other Decks in Technology
See All in Technology
AIで選択肢が広がった組織設計の理想と現実
konifar
16
7.3k
Jev の中身は50行で再現できる。でも本物との差はどこにあるのか
hisuzuya
0
260
AIコーディングエージェント開発_全体像
happysamurai294
0
140
cdk deployとcdkd deploy、実際にデプロイして5倍速近くの差を実測した
yama3133
1
150
[General] 개발자로 해외 기업에서 일하기
skydoves
1
200
AIに任せられるFlutterコードベースを作る 〜仕様をコードで表し、ハーネスで守る〜
myohei
1
590
AI秘書と毎日働くのはもう当たり前。開発以外の業務に足りない機能をどう埋める?
minorun365
PRO
4
2k
kintoneで在庫管理システムを作るときの要件定義・設計ポイント
kai0707
0
190
AIエージェントに 権限と鍵をどこまで渡すか
nrinetcom
PRO
2
160
"AWSはちょっと苦手"でも大丈夫。AWS Blocks で手軽に作る Flutter のバックエンド #FlutterKaigi
tacck
PRO
0
110
AIエージェント時代、Kaggleにどう取り組むか
takanao
2
450
生き様としてのSRE
hokkai7go
1
140
Featured
See All Featured
Heart Work Chapter 1 - Part 1
lfama
PRO
10
37k
Designing for humans not robots
tammielis
254
26k
The innovator’s Mindset - Leading Through an Era of Exponential Change - McGill University 2025
jdejongh
PRO
1
380
The State of eCommerce SEO: How to Win in Today's Products SERPs - #SEOweek
aleyda
2
12k
How People are Using Generative and Agentic AI to Supercharge Their Products, Projects, Services and Value Streams Today
helenjbeal
2
380
職位にかかわらず全員がリーダーシップを発揮するチーム作り / Building a team where everyone can demonstrate leadership regardless of position
madoxten
70
68k
For a Future-Friendly Web
brad_frost
184
11k
We Are The Robots
honzajavorek
0
420
Deep Space Network (abreviated)
tonyrice
0
400
Lessons Learnt from Crawling 1000+ Websites
charlesmeaden
PRO
1
1.7k
From π to Pie charts
rasagy
1
430
Color Theory Basics | Prateek | Gurzu
gurzu
1
510
Transcript
RandLA-Net: Efficient Semantic Segmentation of Large-Scale Point Clouds 2020/07/18 第三回
全日本コンピュータビジョン勉強会(後編)
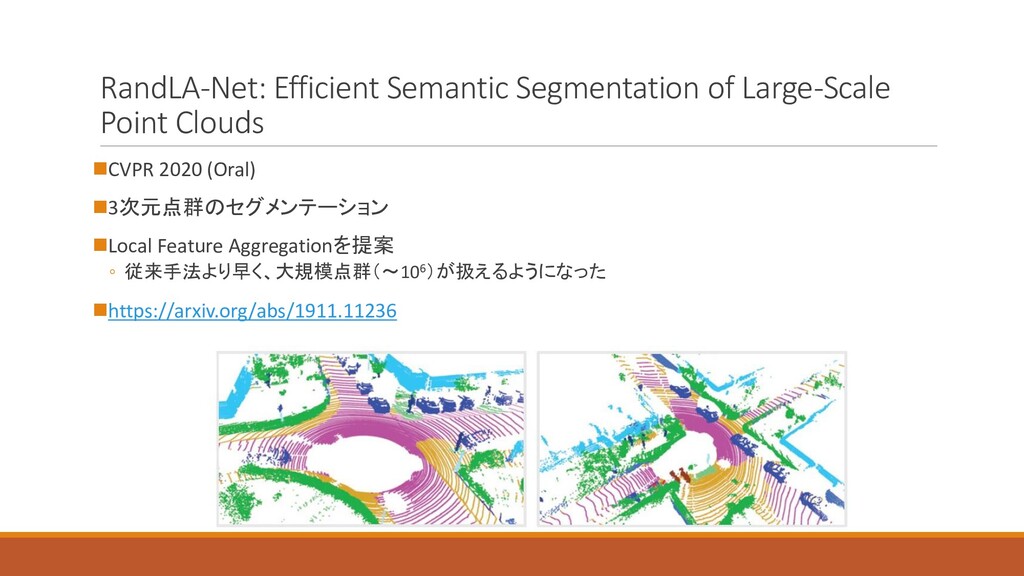
RandLA-Net: Efficient Semantic Segmentation of Large-Scale Point Clouds ◼CVPR 2020
(Oral) ◼3次元点群のセグメンテーション ◼Local Feature Aggregationを提案 ◦ 従来手法より早く、大規模点群(~106)が扱えるようになった ◼https://arxiv.org/abs/1911.11236
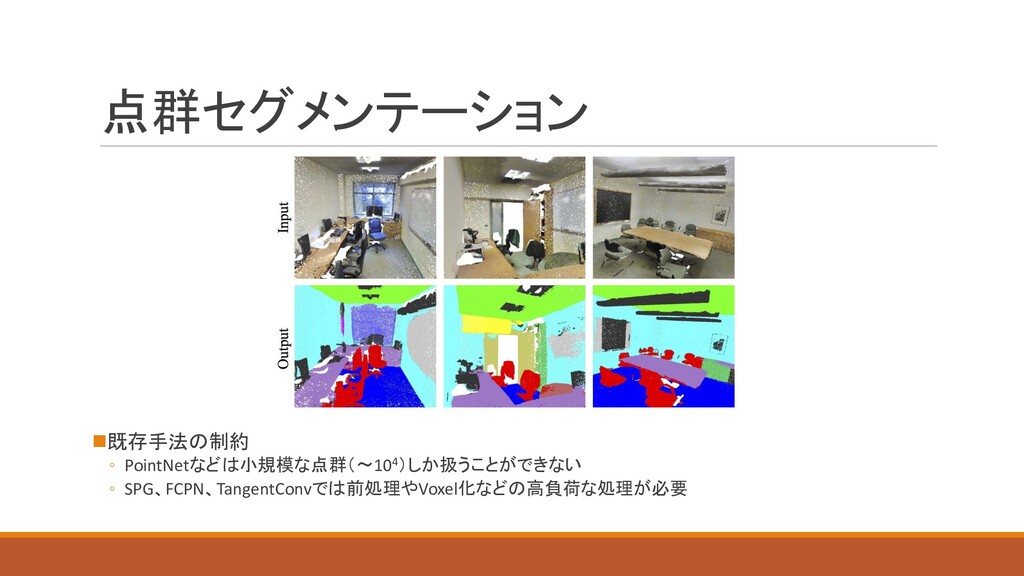
点群セグメンテーション ◼既存手法の制約 ◦ PointNetなどは小規模な点群(~104)しか扱うことができない ◦ SPG、FCPN、TangentConvでは前処理やVoxel化などの高負荷な処理が必要
目的 ◼大規模な点群を直接処理する ◦ ブロック分割やブロック統合といった前処理を行わない ◦ 出来る限り本来の幾何構造を保持 ◼計算・メモリ効率性 ◦ 高負荷な前処理やメモリ容量が必要なVoxel化は行わない ◦
大規模点群をsingle passで推論する ◼正確性&可用性 ◦ 複雑な幾何学的構造物から顕著な特徴を保持する ◦ 空間サイズや点数の異なる入力点群を処理できる
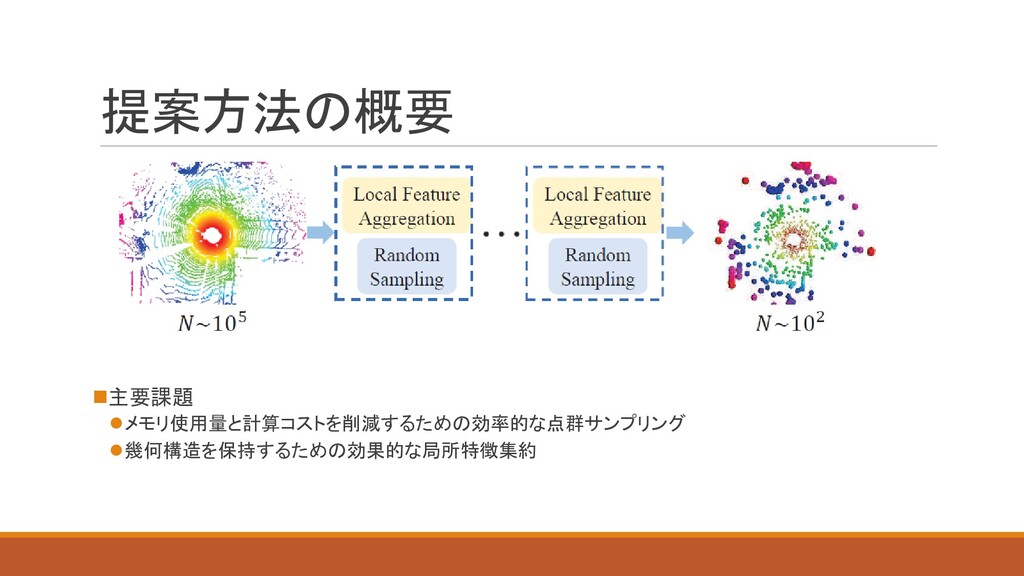
提案方法の概要 ◼主要課題 ⚫メモリ使用量と計算コストを削減するための効率的な点群サンプリング ⚫幾何構造を保持するための効果的な局所特徴集約
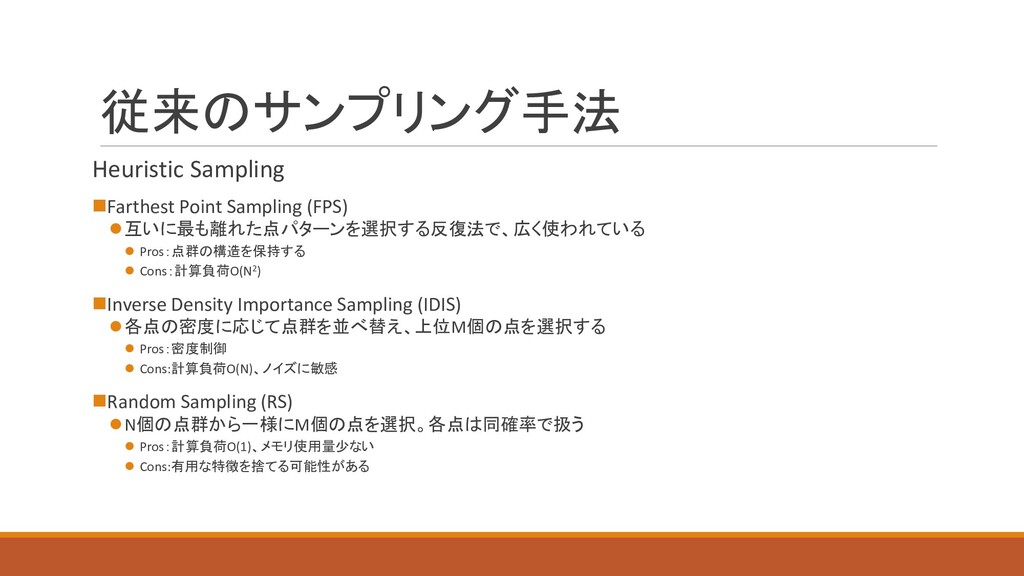
従来のサンプリング手法 Heuristic Sampling ◼Farthest Point Sampling (FPS) ⚫互いに最も離れた点パターンを選択する反復法で、広く使われている ⚫ Pros:点群の構造を保持する
⚫ Cons:計算負荷O(N2) ◼Inverse Density Importance Sampling (IDIS) ⚫各点の密度に応じて点群を並べ替え、上位M個の点を選択する ⚫ Pros:密度制御 ⚫ Cons:計算負荷O(N)、ノイズに敏感 ◼Random Sampling (RS) ⚫N個の点群から一様にM個の点を選択。各点は同確率で扱う ⚫ Pros:計算負荷O(1)、メモリ使用量少ない ⚫ Cons:有用な特徴を捨てる可能性がある
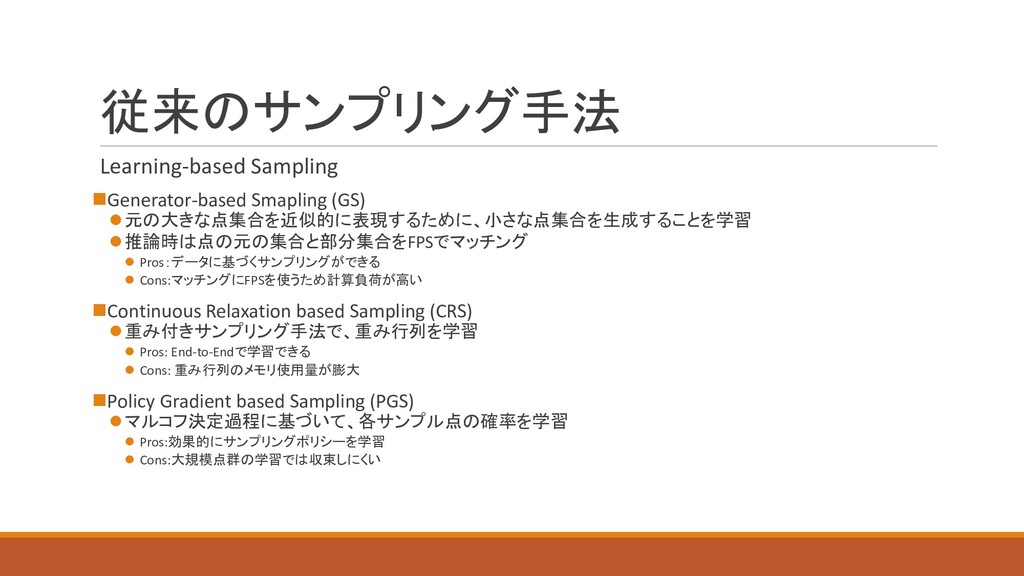
従来のサンプリング手法 Learning-based Sampling ◼Generator-based Smapling (GS) ⚫元の大きな点集合を近似的に表現するために、小さな点集合を生成することを学習 ⚫推論時は点の元の集合と部分集合をFPSでマッチング ⚫ Pros:データに基づくサンプリングができる
⚫ Cons:マッチングにFPSを使うため計算負荷が高い ◼Continuous Relaxation based Sampling (CRS) ⚫重み付きサンプリング手法で、重み行列を学習 ⚫ Pros: End-to-Endで学習できる ⚫ Cons: 重み行列のメモリ使用量が膨大 ◼Policy Gradient based Sampling (PGS) ⚫マルコフ決定過程に基づいて、各サンプル点の確率を学習 ⚫ Pros:効果的にサンプリングポリシーを学習 ⚫ Cons:大規模点群の学習では収束しにくい
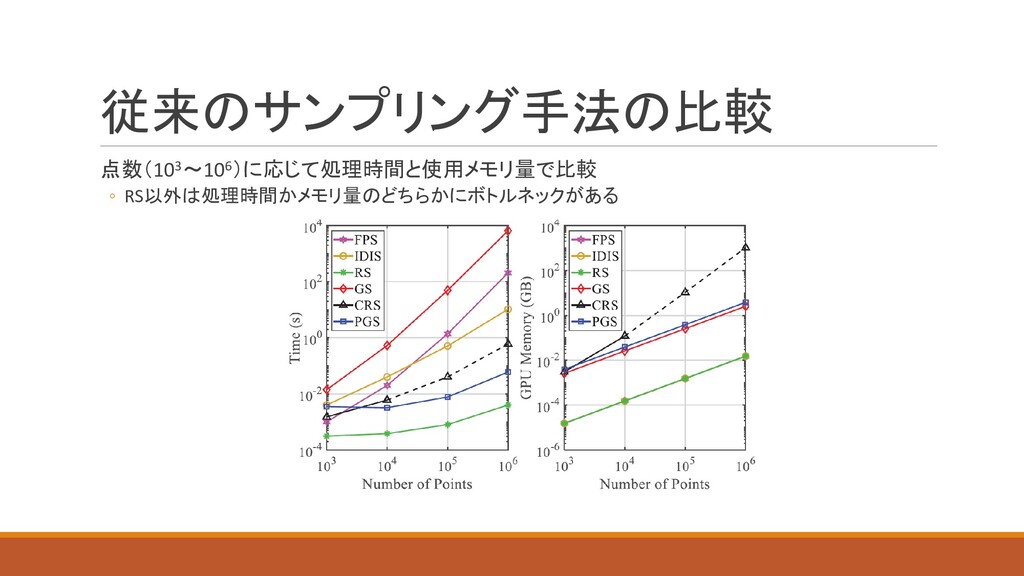
従来のサンプリング手法の比較 点数(103~106)に応じて処理時間と使用メモリ量で比較 ◦ RS以外は処理時間かメモリ量のどちらかにボトルネックがある
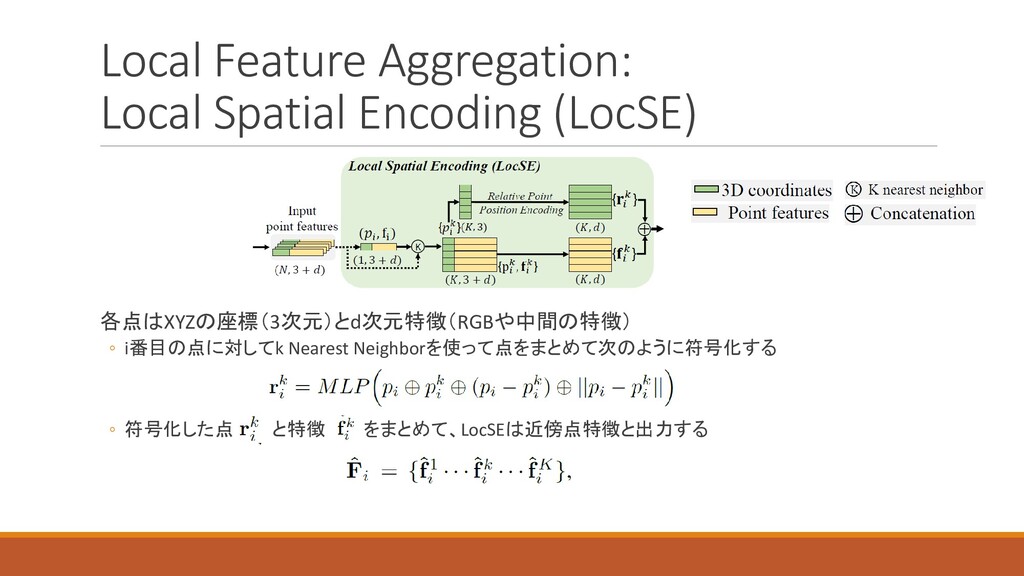
各点はXYZの座標(3次元)とd次元特徴(RGBや中間の特徴) ◦ i番目の点に対してk Nearest Neighborを使って点をまとめて次のように符号化する ◦ 符号化した点 と特徴 をまとめて、LocSEは近傍点特徴と出力する Local
Feature Aggregation: Local Spatial Encoding (LocSE)
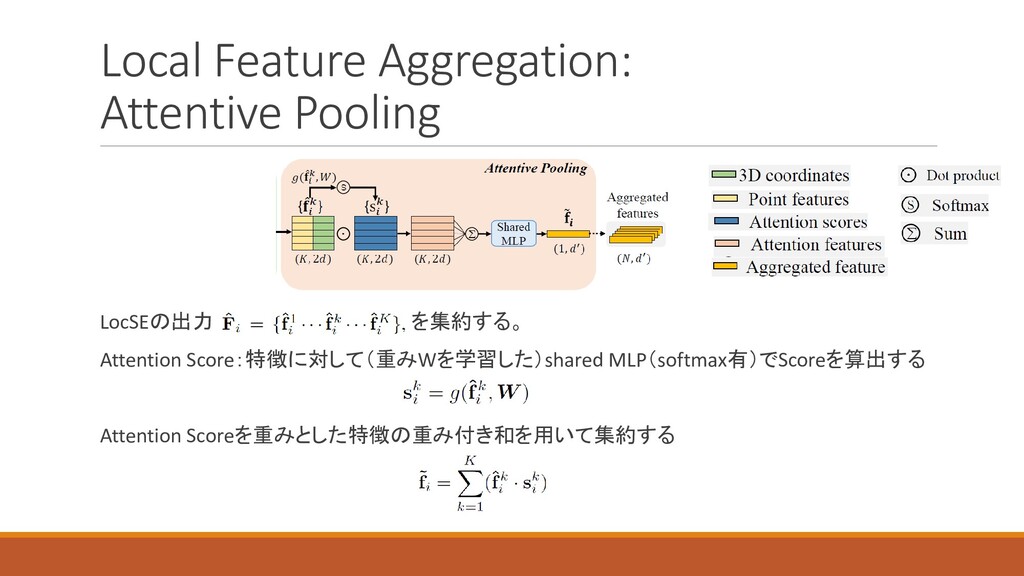
Local Feature Aggregation: Attentive Pooling LocSEの出力 を集約する。 Attention Score:特徴に対して(重みWを学習した)shared MLP(softmax有)でScoreを算出する
Attention Scoreを重みとした特徴の重み付き和を用いて集約する
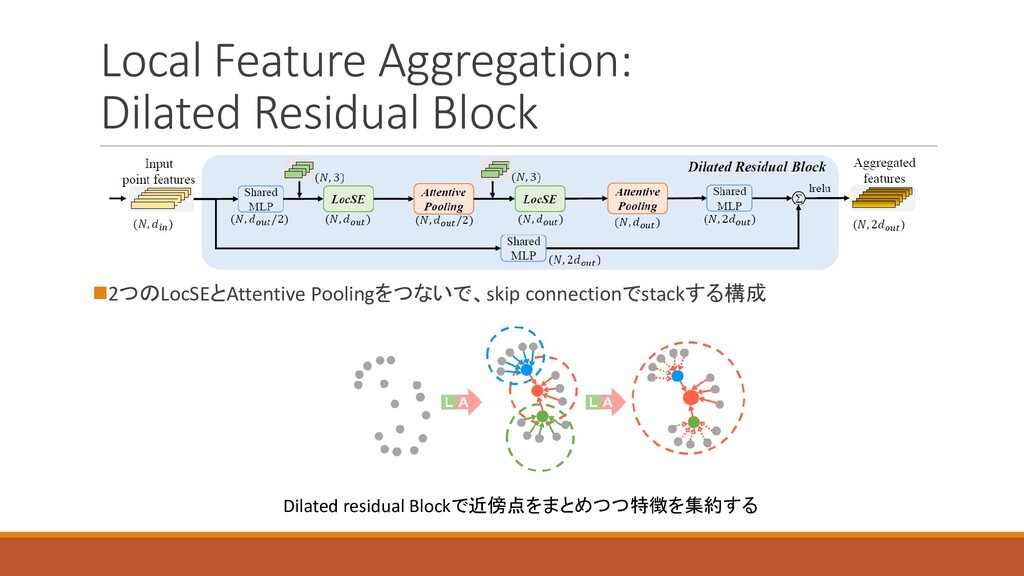
Local Feature Aggregation: Dilated Residual Block ◼2つのLocSEとAttentive Poolingをつないで、skip connectionでstackする構成 Dilated
residual Blockで近傍点をまとめつつ特徴を集約する
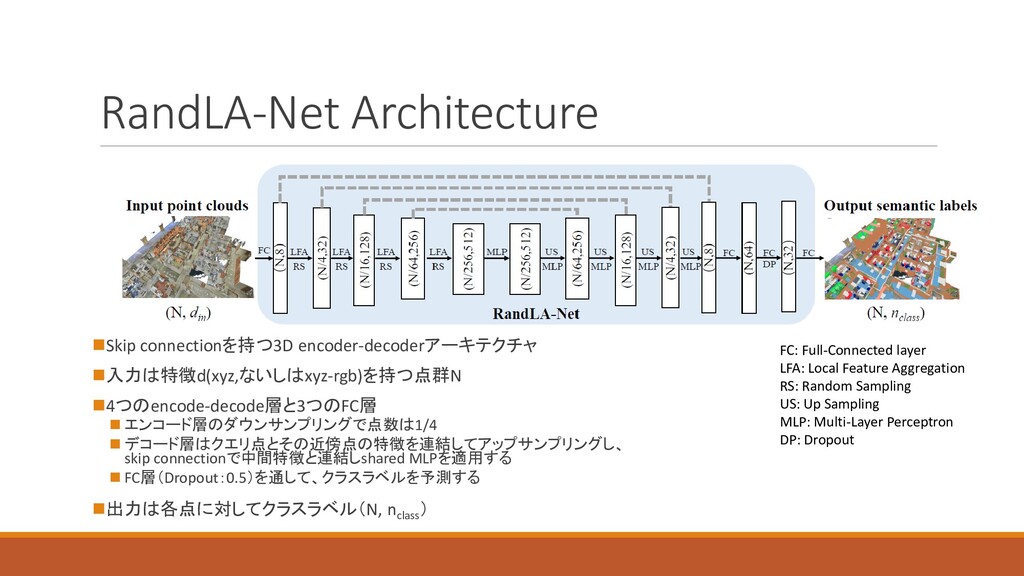
RandLA-Net Architecture ◼Skip connectionを持つ3D encoder-decoderアーキテクチャ ◼入力は特徴d(xyz,ないしはxyz-rgb)を持つ点群N ◼4つのencode-decode層と3つのFC層 ◼ エンコード層のダウンサンプリングで点数は1/4 ◼
デコード層はクエリ点とその近傍点の特徴を連結してアップサンプリングし、 skip connectionで中間特徴と連結しshared MLPを適用する ◼ FC層(Dropout:0.5)を通して、クラスラベルを予測する ◼出力は各点に対してクラスラベル(N, nclass ) FC: Full-Connected layer LFA: Local Feature Aggregation RS: Random Sampling US: Up Sampling MLP: Multi-Layer Perceptron DP: Dropout
実験 ◼実験 ◦ CPU:AMD 3700X @3.6GHz ◦ GPU:RTX2080Ti ◼データセット ◦
SemanticKITTI ◦ Semantic3D ◦ S3DIS ◼評価 ◦ 効率性:処理時間、メモリ使用量 ◦ セグメンテーション精度 ◼コード ◦ https://github.com/QingyongHu/RandLA-Net
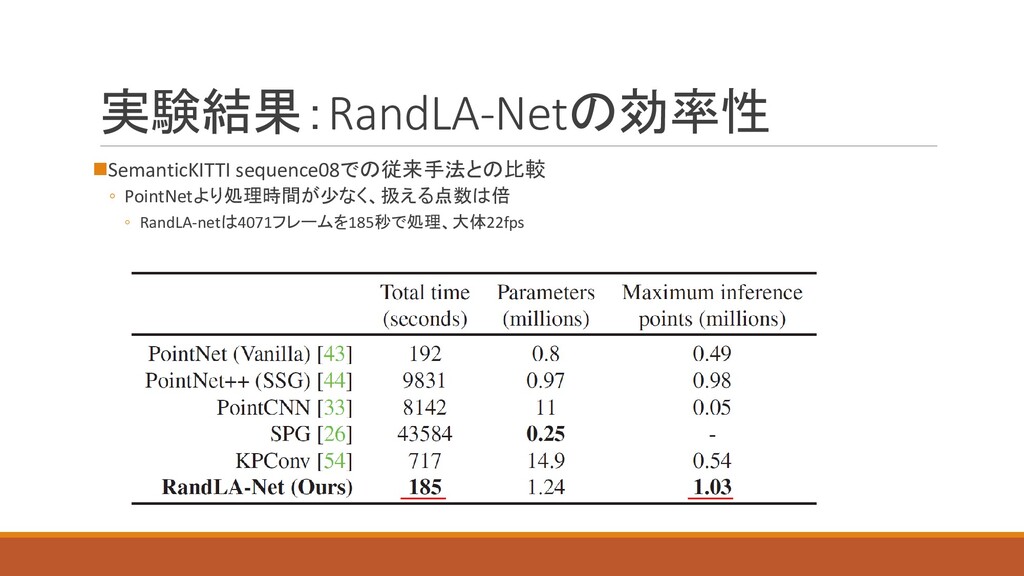
実験結果:RandLA-Netの効率性 ◼SemanticKITTI sequence08での従来手法との比較 ◦ PointNetより処理時間が少なく、扱える点数は倍 ◦ RandLA-netは4071フレームを185秒で処理、大体22fps
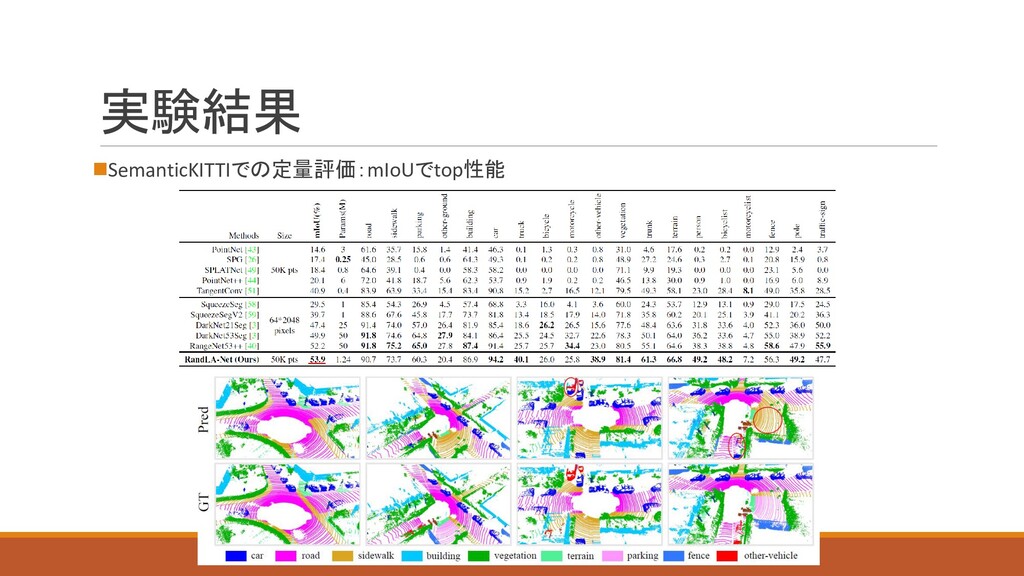
実験結果 ◼SemanticKITTIでの定量評価:mIoUでtop性能
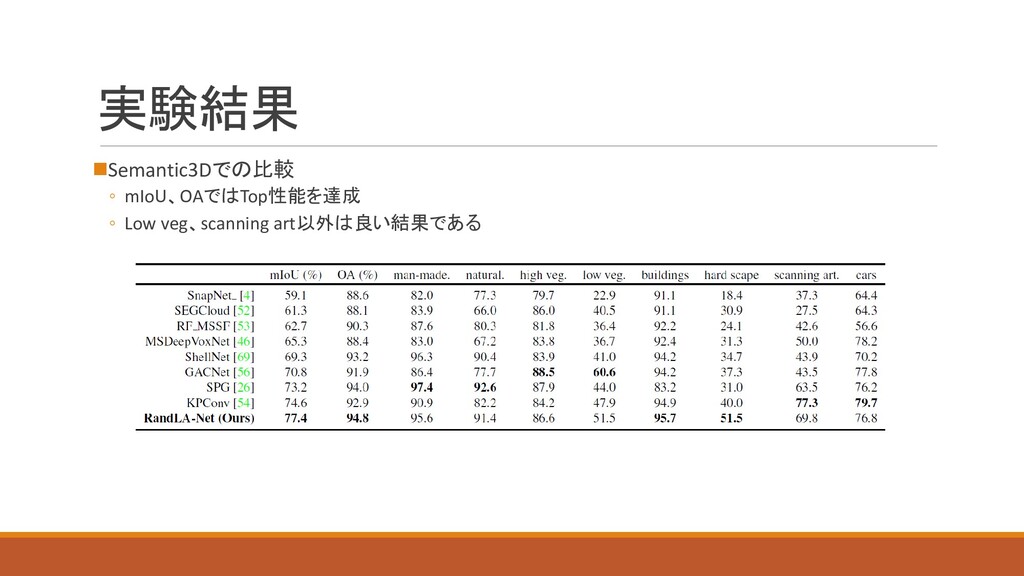
実験結果 ◼Semantic3Dでの比較 ◦ mIoU、OAではTop性能を達成 ◦ Low veg、scanning art以外は良い結果である
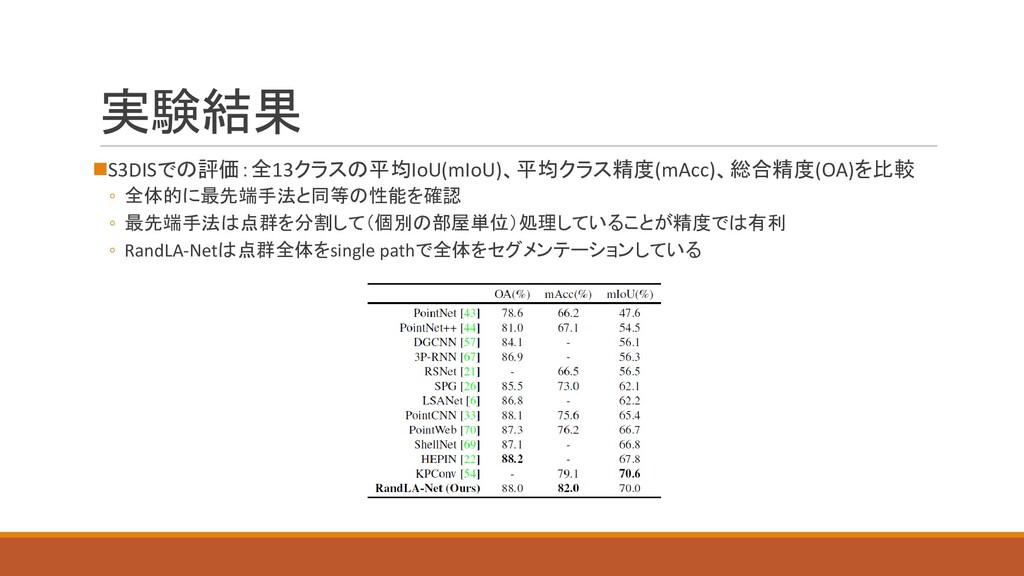
実験結果 ◼S3DISでの評価:全13クラスの平均IoU(mIoU)、平均クラス精度(mAcc)、総合精度(OA)を比較 ◦ 全体的に最先端手法と同等の性能を確認 ◦ 最先端手法は点群を分割して(個別の部屋単位)処理していることが精度では有利 ◦ RandLA-Netは点群全体をsingle pathで全体をセグメンテーションしている
セグメンテーション結果 https://www.youtube.com/watch?v=Ar3eY_lwzMk
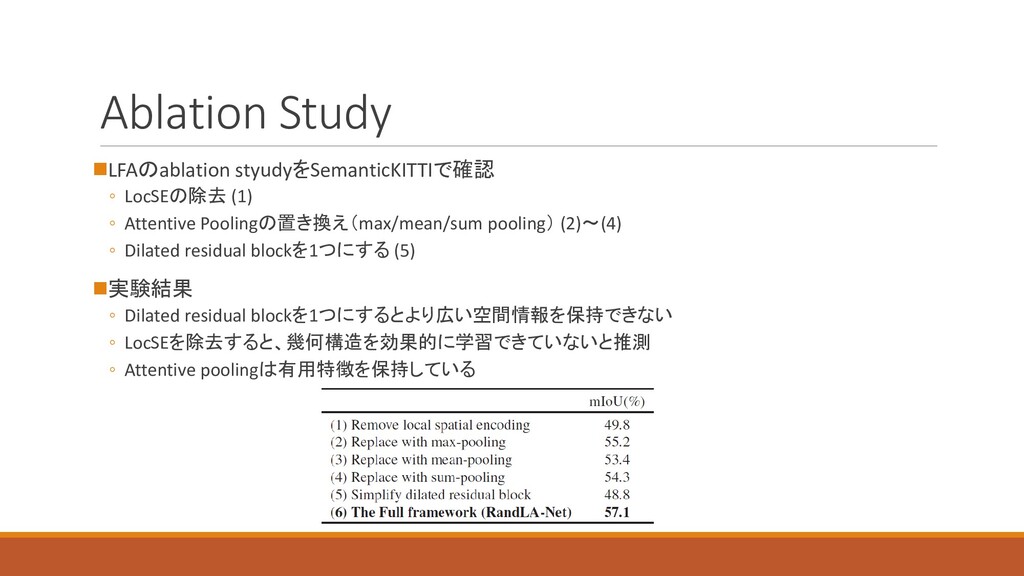
Ablation Study ◼LFAのablation styudyをSemanticKITTIで確認 ◦ LocSEの除去 (1) ◦ Attentive Poolingの置き換え(max/mean/sum
pooling) (2)~(4) ◦ Dilated residual blockを1つにする (5) ◼実験結果 ◦ Dilated residual blockを1つにするとより広い空間情報を保持できない ◦ LocSEを除去すると、幾何構造を効果的に学習できていないと推測 ◦ Attentive poolingは有用特徴を保持している
まとめ ◼提案手法 ◦ 前処理なしの点群セグメンテーション ◦ 大規模点群を扱うことが出来る ◦ 局所空間で点群の特徴を集約する手法を提案 ◦ Random
samplingを活用 ◼結果 ◦ 最先端手法と同等性能 ◦ 大規模点群(~106 )をsingle pathで高速に処理可能
None
点群処理の資料 PointNet ◦ https://www.slideshare.net/FujimotoKeisuke/point-net LiDARで取得した道路上点群に対するsemantic segmentation ◦ https://www.slideshare.net/takmin/20181228-lidarsemantic-segmentation 点群深層学習の研究動向 ◦
https://www.slideshare.net/SSII_Slides/ssii2019ps2 点群CNN、3D CNN入門 ◦ https://qiita.com/arutema47/items/cda262c61baa953a97e9
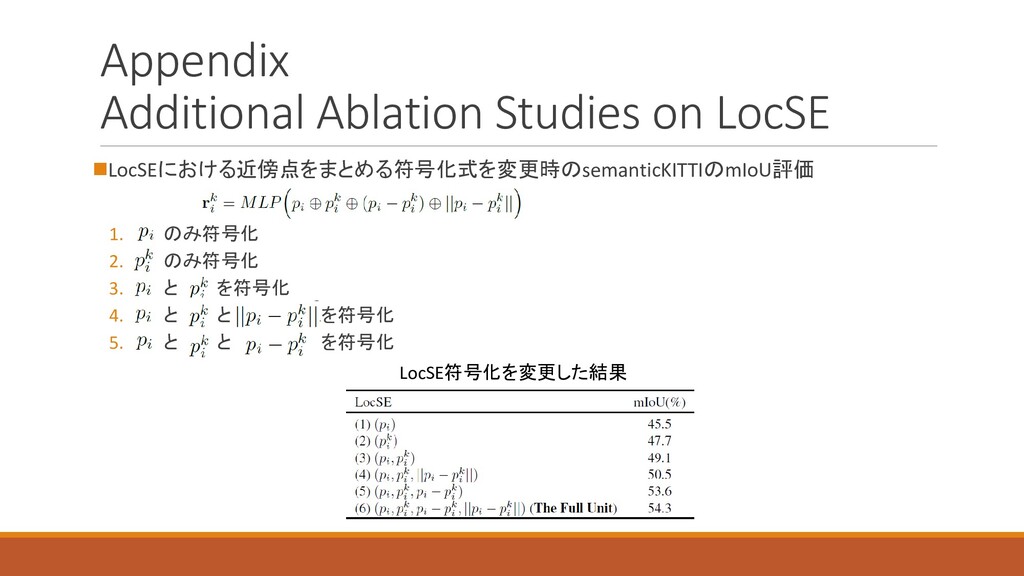
Appendix Additional Ablation Studies on LocSE ◼LocSEにおける近傍点をまとめる符号化式を変更時のsemanticKITTIのmIoU評価 1. のみ符号化 2.
のみ符号化 3. と を符号化 4. と と を符号化 5. と と を符号化 LocSE符号化を変更した結果
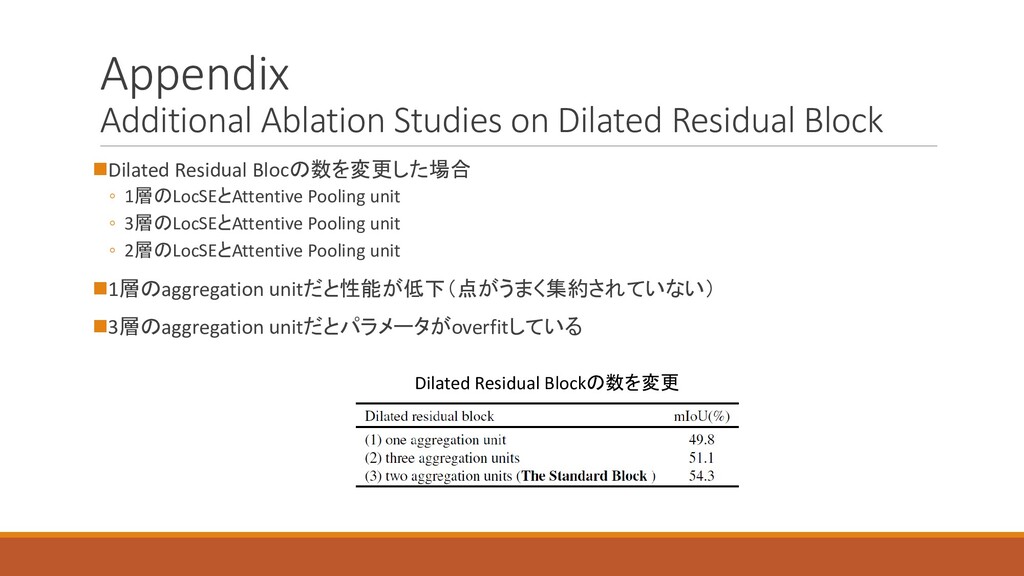
Appendix Additional Ablation Studies on Dilated Residual Block ◼Dilated Residual
Blocの数を変更した場合 ◦ 1層のLocSEとAttentive Pooling unit ◦ 3層のLocSEとAttentive Pooling unit ◦ 2層のLocSEとAttentive Pooling unit ◼1層のaggregation unitだと性能が低下(点がうまく集約されていない) ◼3層のaggregation unitだとパラメータがoverfitしている Dilated Residual Blockの数を変更
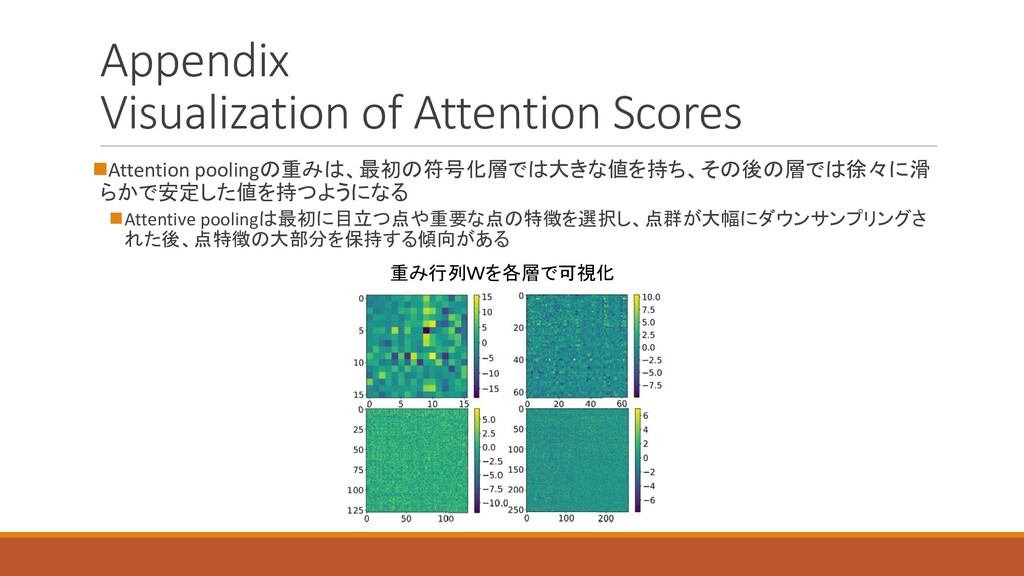
Appendix Visualization of Attention Scores ◼Attention poolingの重みは、最初の符号化層では大きな値を持ち、その後の層では徐々に滑 らかで安定した値を持つようになる ◼Attentive poolingは最初に目立つ点や重要な点の特徴を選択し、点群が大幅にダウンサンプリングさ
れた後、点特徴の大部分を保持する傾向がある 重み行列Wを各層で可視化


 tsukamotokenji
 konifar
 hisuzuya
 happysamurai294
 yama3133
 skydoves
 myohei
 minorun365
 kai0707
 nrinetcom
 tacck
 takanao
 hokkai7go
 lfama
 tammielis
 jdejongh
 aleyda
 helenjbeal
 madoxten
 brad_frost
 honzajavorek
 tonyrice
 charlesmeaden
 rasagy
 gurzu