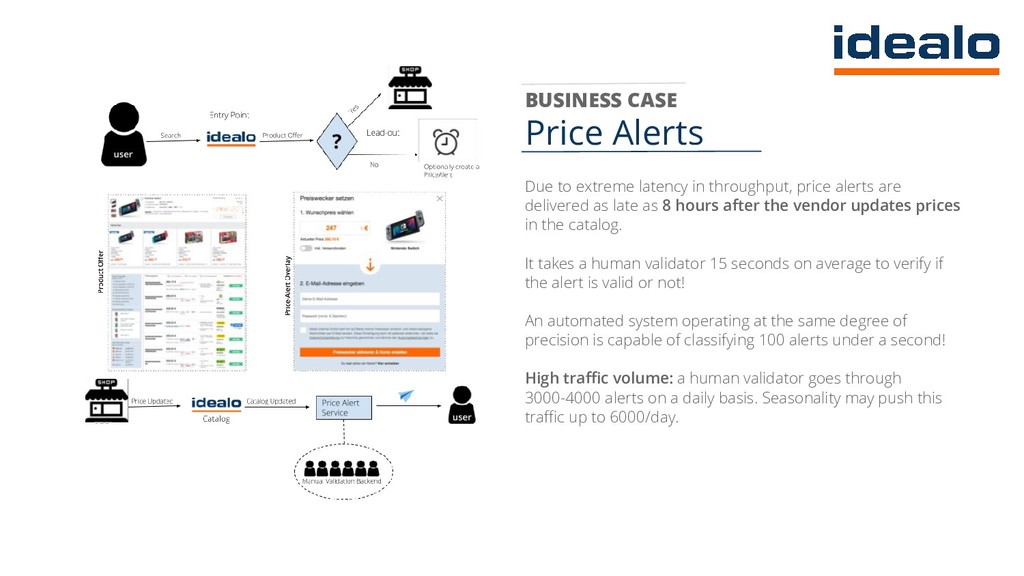
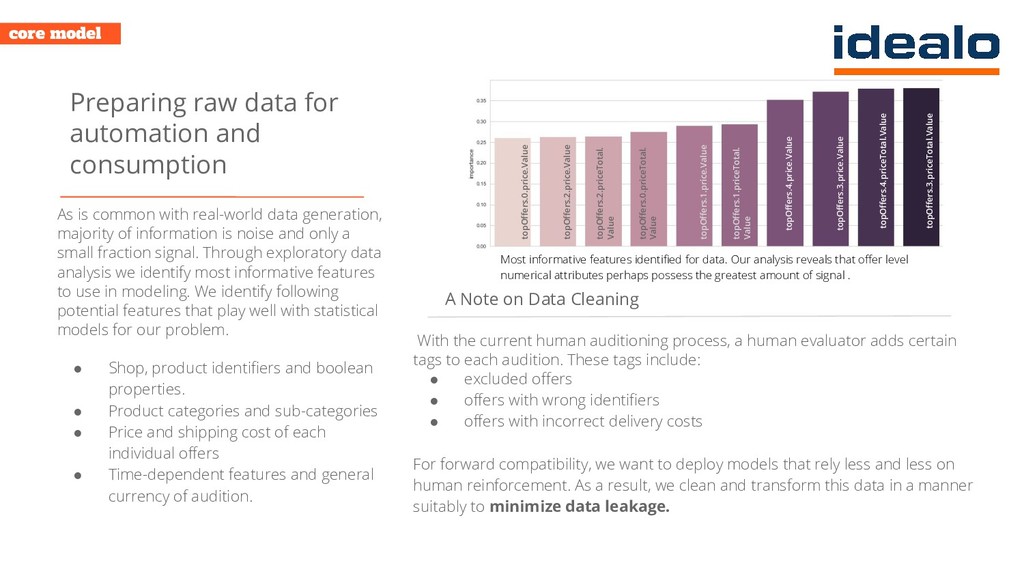
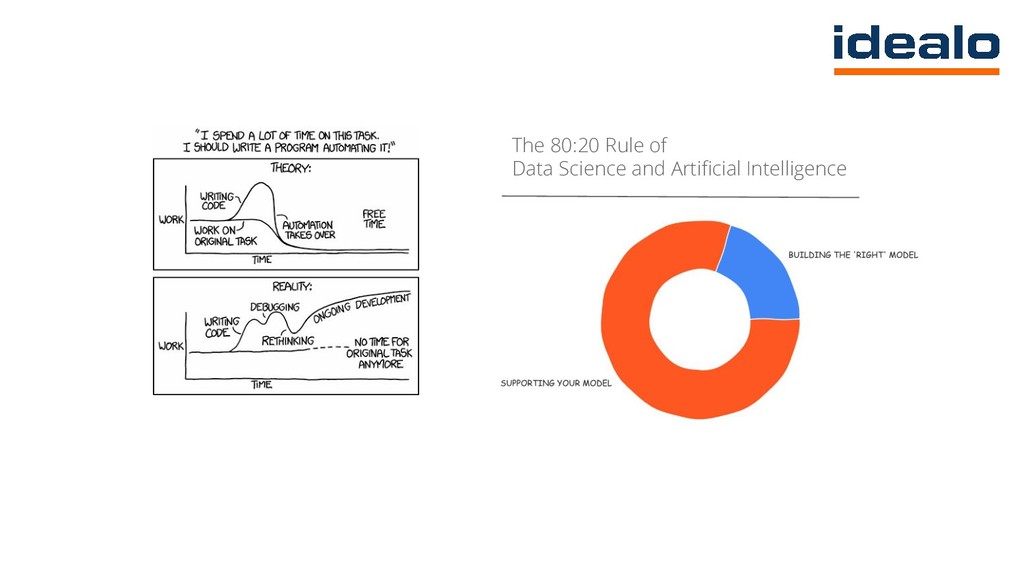
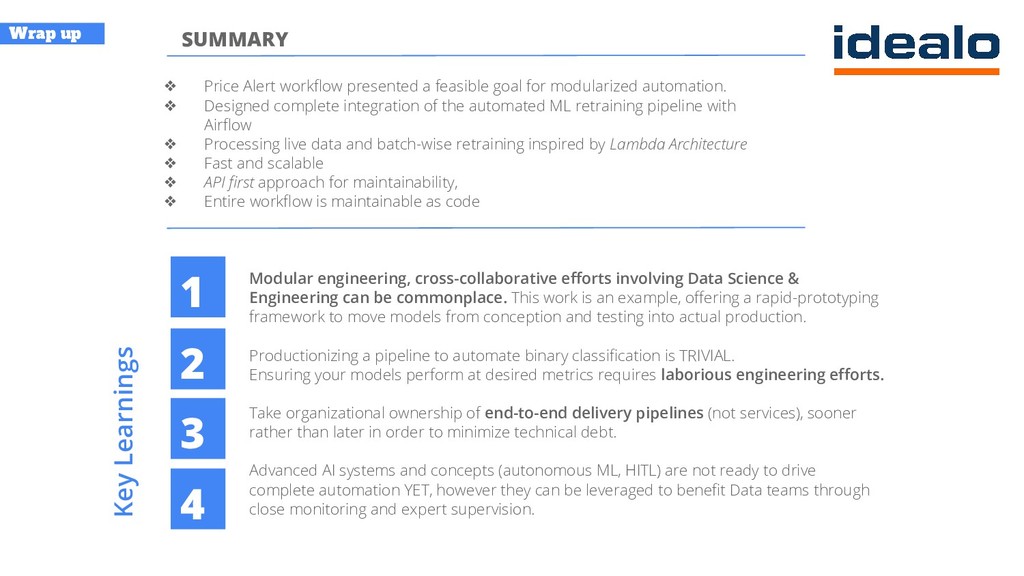
Repetitive human tasks (flagging, tagging, annotating) can start to drain organizational resources especially when they may be required to scale up infinitely
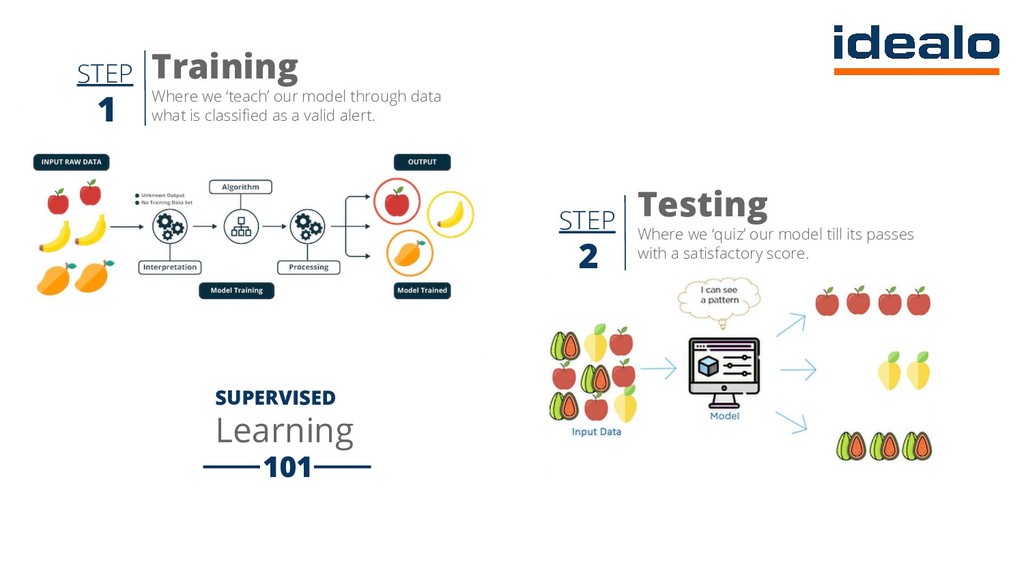
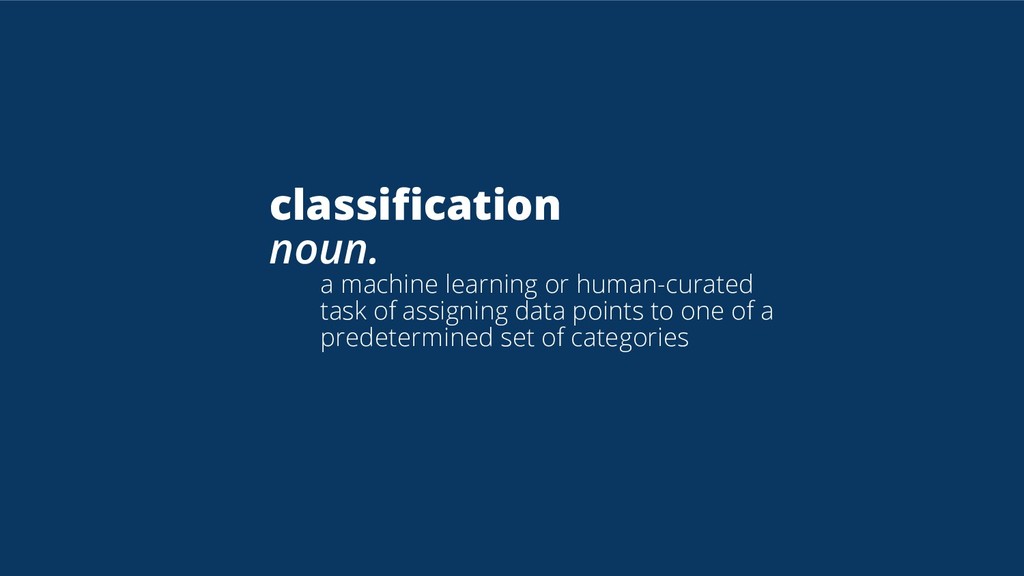
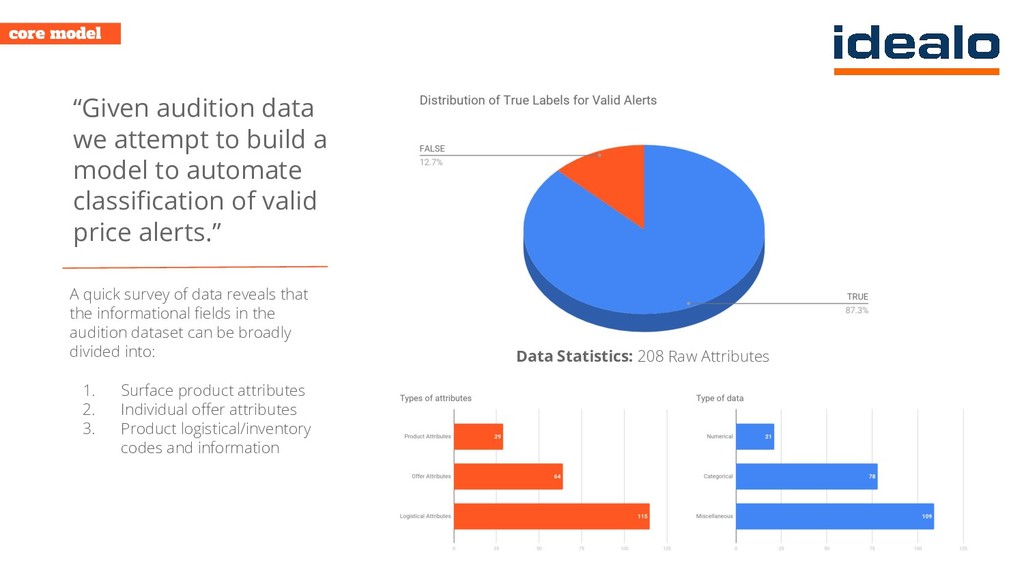
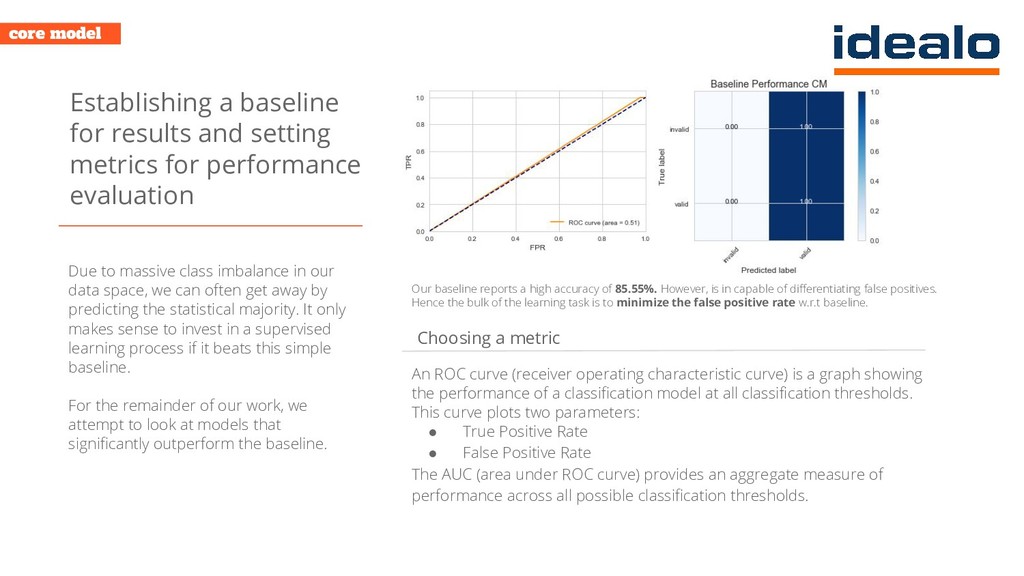
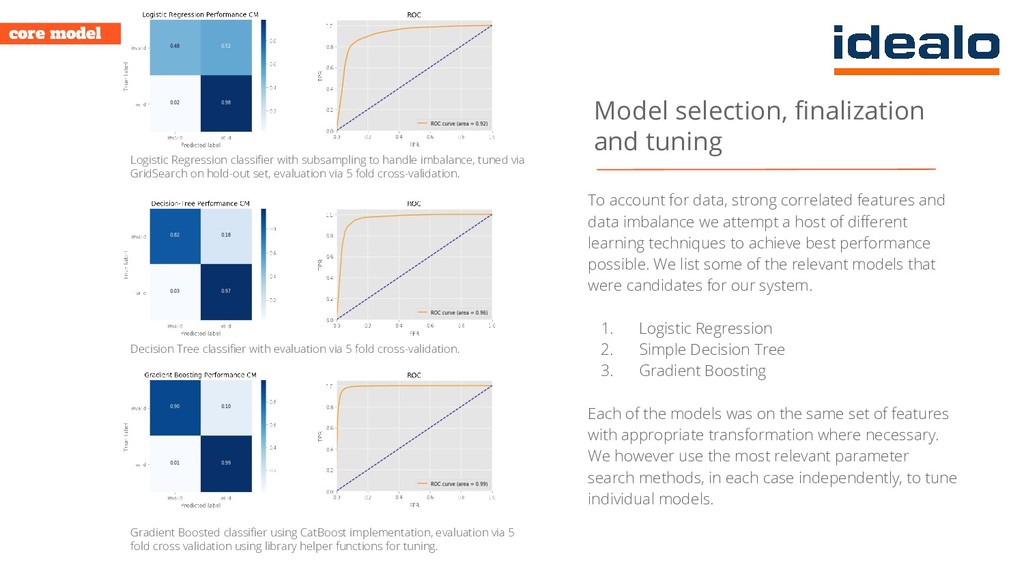
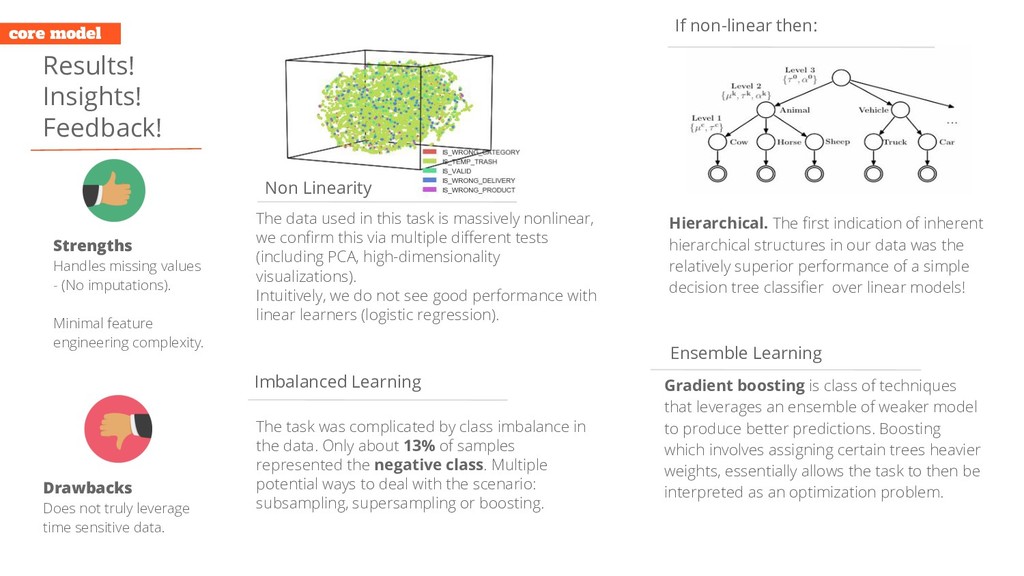
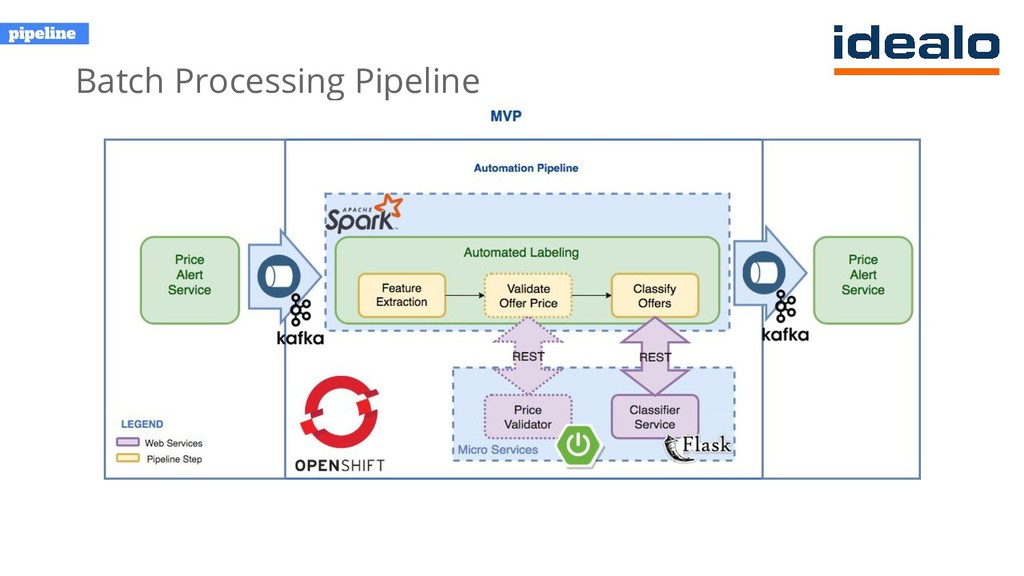
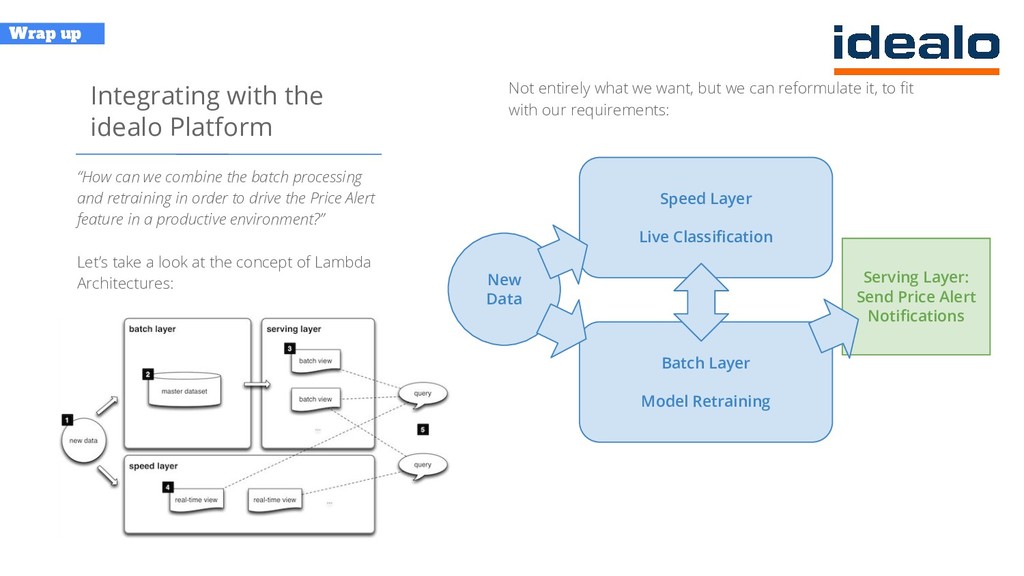
Novel framework proposed addresses tackling trivial binary decision-making with supervised classification pipelines
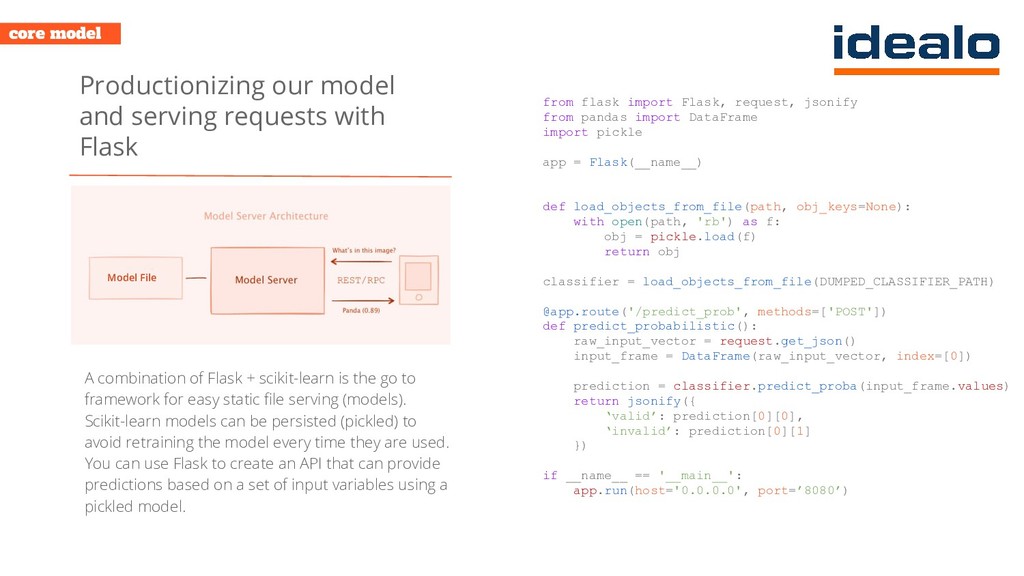
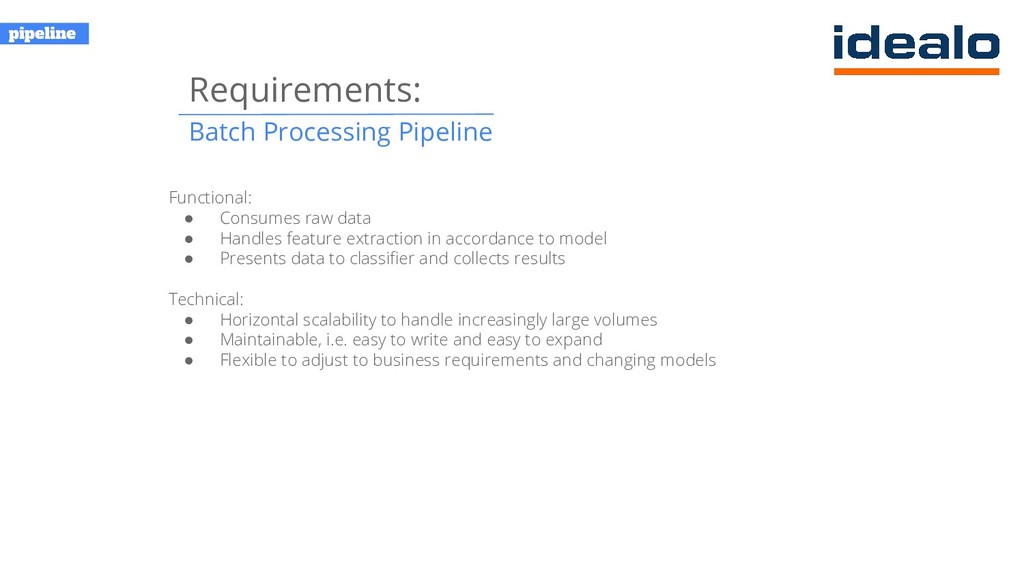
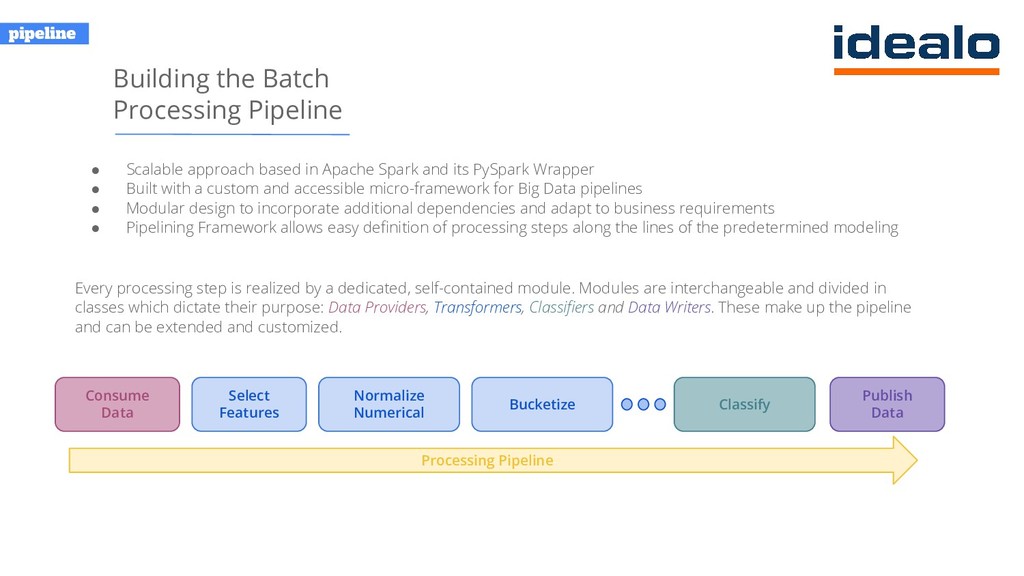
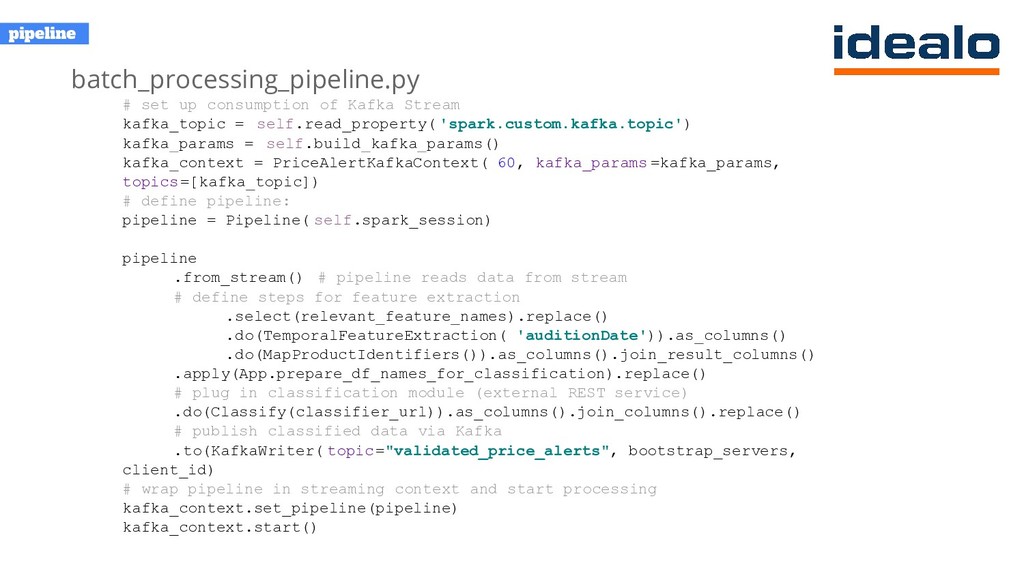
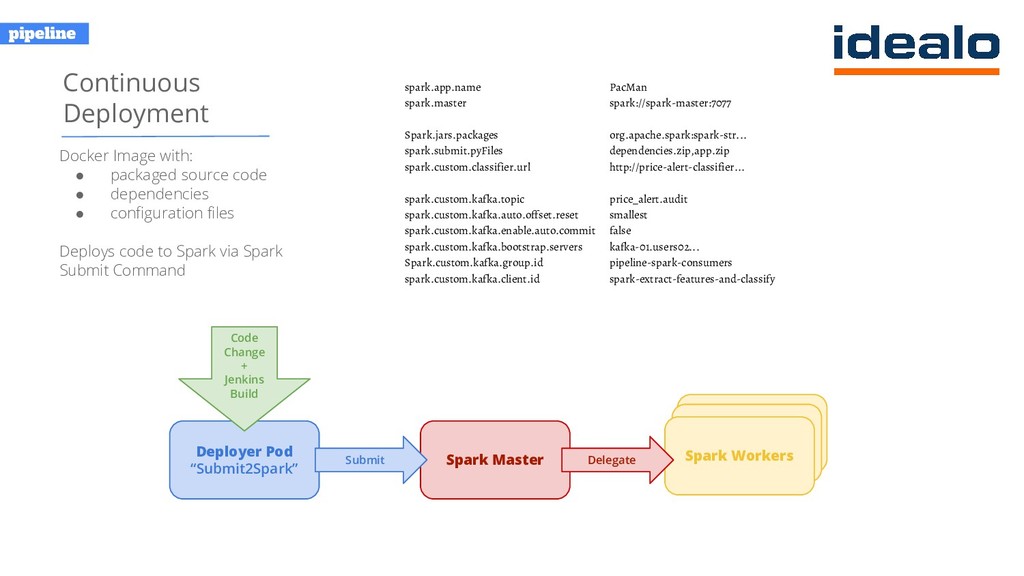
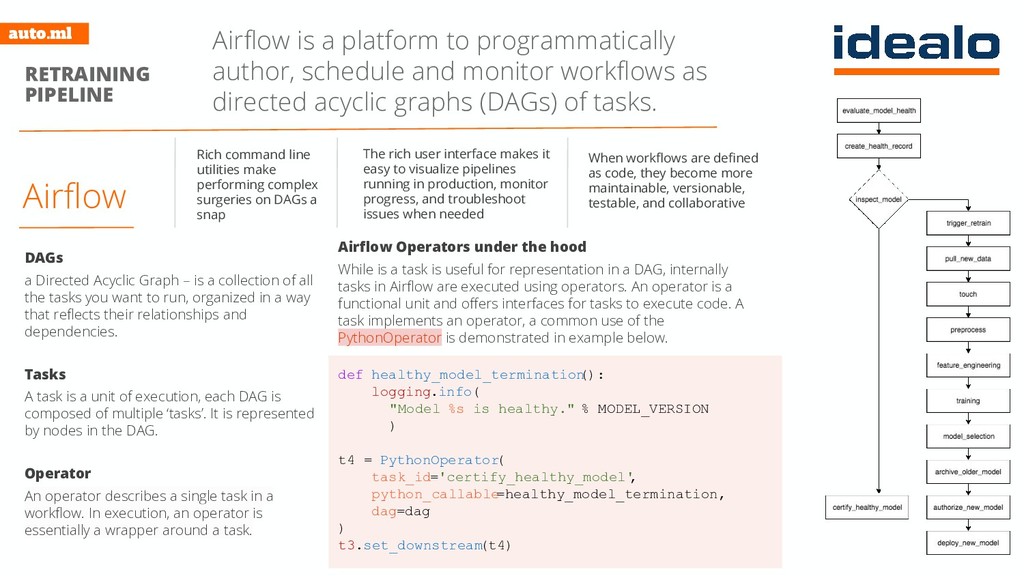
Demonstrate design, implementation and best practices to maintain big-data pipelines for automation, as code
On-demand scaling, reusability and version control
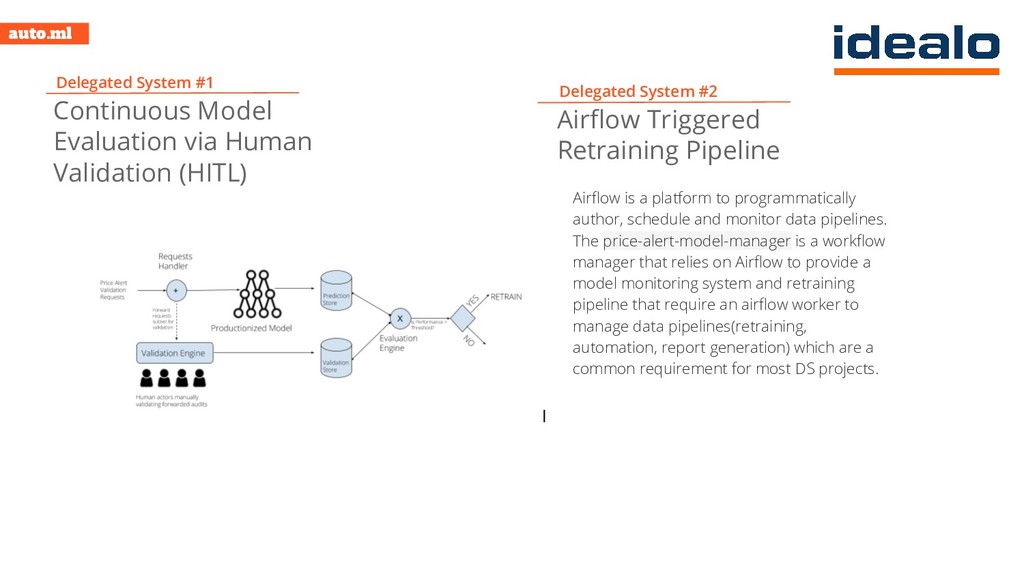
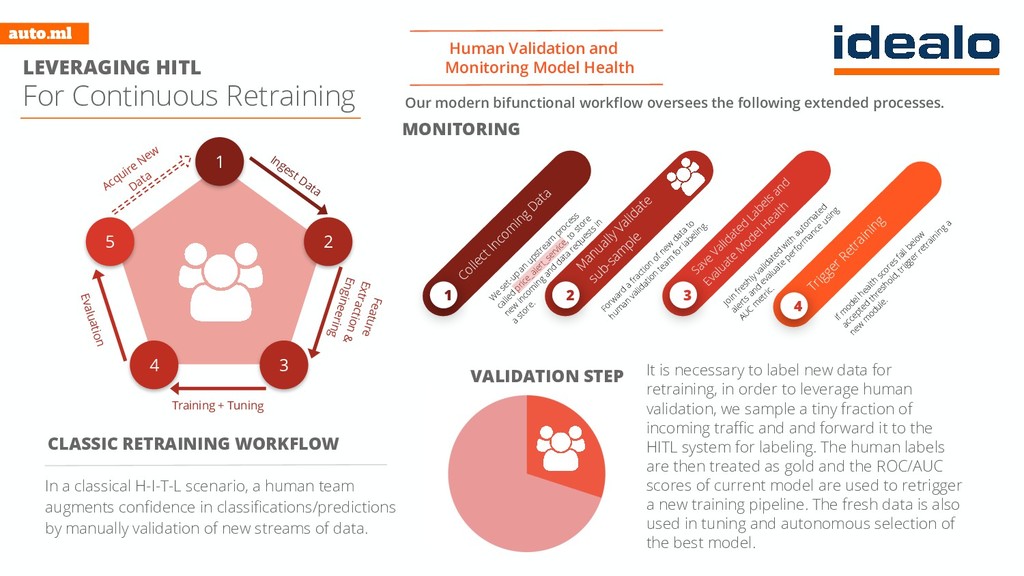
Tightly coupled Human-in-the-loop (HITL) system for validation and monitoring of model health


 valiantone
 shugo
 occhi
 onk
 nttcom
 teamlab
 iktakahiro
 yahonda
 satoshi7
 yamad
 shuta13
 tetsuya28
 reverentgeek
 madoxten
 bcantrill
 stuffmc
 katiecoart
 tammyeverts
 chriscoyier
 destraynor
 bluesmoon
 hatefulcrawdad
 csswizardry
 raygrieselhuber