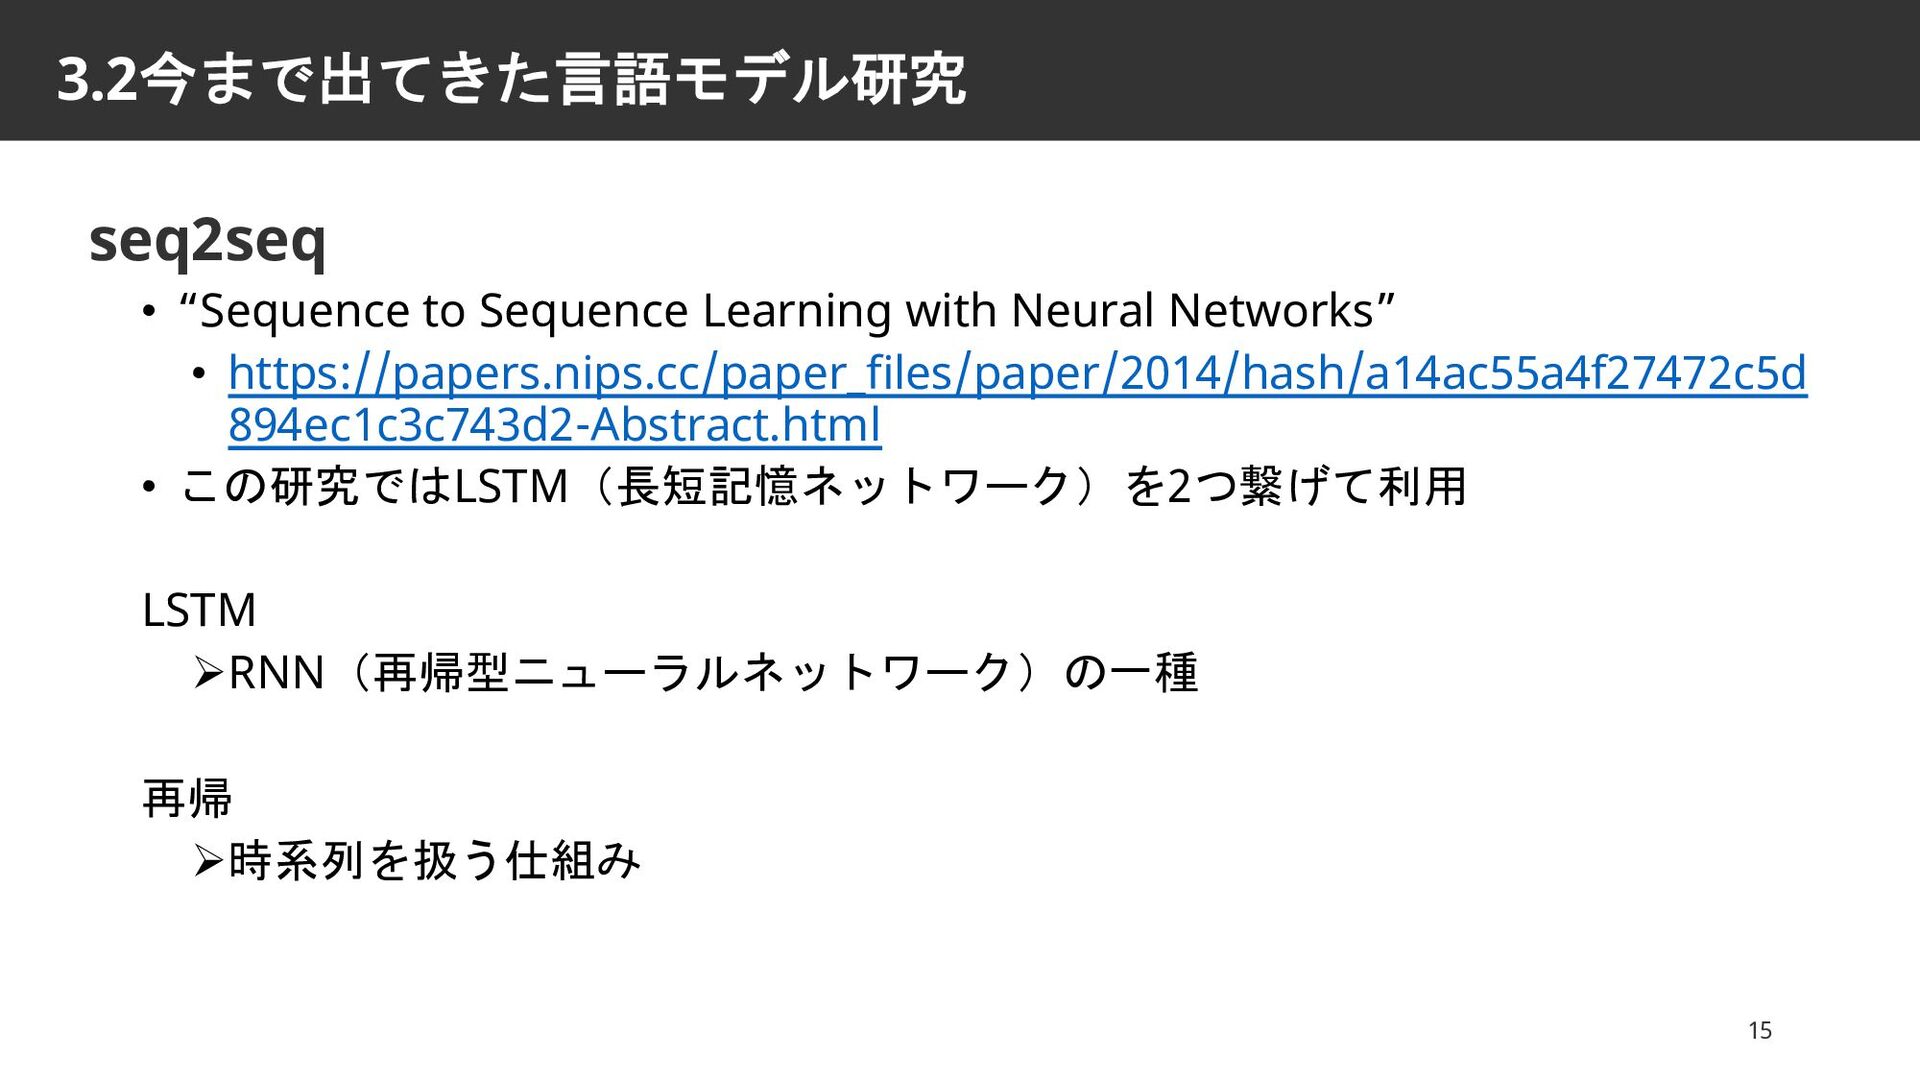
Ming-Wei Chang, Kenton Lee, and Kristina Toutanova(2019)BERT: pre-training of deep bidirectional transformers for language understanding, ” In Proc. of NAACL-HLT, pp. 4171-4186. Jared Kaplan, Sam McCandlish, Tom Henighan, Tom B. Brown, Benjamin Chess, Rewon Child, Scott Gray, Alec Radford, Jeffrey Wu, and Dario Amodei(2020) Scaling Laws for Neural Language Models. arXiv preprint arXiv:2001.08361, Alec Radford, Karthik Narasimhan, Time Salimans, and Ilya Sutskever(2018). Improving language understanding by generative pre-training. Technical report, OpenAI. Ilya Sutskever, Oriol Vinyals, and Quoc V Le.(2014). Sequence to Sequence Learning with Neural Networks. Proc. of the 27th Int. Conf. on Neural Information Processing Systems, pp. 3104-3112. Ashish Vaswani, Noam Shazeer, Niki Parmar, Jakob Uszkoreit, Llion Jones, Aidan N Gomez, Lukasz Kaiser, and Illia Polosukhin(2017). Attention is all you need. Advances in Neural Information Processing Systems, Vol. 30, pp. 6000–6010.


 ayatokanada
 hotchpotch
 naok615
 tattaka
 polipoli
 nzw0301
 institutdelelevage
 imai448
 kohlerjohannes
 junkashihara
 baasie
 trishagee
 stephenakadiri
 takai
 eileencodes
 aleyda
 addyosmani
 nikkihalliwell
 soudai
 helenjbeal
 letsgokoyo
 maltzj