Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
論文紹介:∞-former: Infinite Memory Transformer
Search
Sponsored
·
Your Podcast. Everywhere. Effortlessly.
Share. Educate. Inspire. Entertain. You do you. We'll handle the rest.
→
yuri
September 20, 2022
Research
450
0
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
論文紹介:∞-former: Infinite Memory Transformer
第14回最先端NLP勉強会(2022年9月26日、27日)@お茶大 発表用資料
yuri
September 20, 2022
More Decks by yuri
See All by yuri
データ指向モデリング「テキストマイニングの基礎」
yuri00
0
44
論文紹介:What In-Context Learning “Learns” In-Context: Disentangling Task Recognition and Task Learning
yuri00
0
660
論文紹介:Learning Dependency-Based Compositional Semantics
yuri00
0
170
論文紹介:What Context Features Can Transformer Language Models Use?
yuri00
0
490
Other Decks in Research
See All in Research
VLMの推論を高速化する視覚トークン削減の仕組み
tattaka
2
380
Adapter les bergeries aux fortes chaleurs
institutdelelevage
PRO
0
140
JICA QUEST 共創×革新プログラム Impact Report(海ノ向こうコーヒー)
ontheslope
0
850
JPA2026_NetworkTutorial_JunKashihara
junkashihara
0
230
GLIM とMegaParticles:正規分布近似の限界とタイトカップリング&パーティクルフィルタの進展 / GLIM and MegaParticles : Progress of the distribution representation in SLAM
koide3
0
960
COMETAを用いたデータ民主化運動の歴史
sazimai
0
290
[SNLP2026] Scaling up Test-Time Compute with Latent Reasoning: A Recurrent Depth Approach
wataruuuuu
0
350
SAM3を用いたコマ・吹き出しの 領域検出と分割構造からの読み順推定
kzmssk
0
190
[IEICE-Soceity-Conf2026] セマンティック通信を見据えたマルチスケールセンシングと 学習の融合によるデジタルツイン基盤 / Digital Twin Infrastructure via the Fusion of Multi-Scale Sensing and Learning toward Semantic Communications
pman0214
0
110
Empreinte carbone des ovins : une approche globale (technique, économique, environnementale) – 4 années de résultats avec LIFE GREEN SHEEP
institutdelelevage
PRO
0
110
Développer des solutions de réduction des émissions de méthane entérique : 1ers résultats Méthane 2030
institutdelelevage
PRO
0
260
生成AIなんでも展示会vol6 LT登壇資料 NexteraBERT
rikkabotan7
0
190
Featured
See All Featured
Amusing Abliteration
ianozsvald
1
350
AI in Enterprises - Java and Open Source to the Rescue
ivargrimstad
0
1.5k
Leadership Guide Workshop - DevTernity 2021
reverentgeek
1
400
A Guide to Academic Writing Using Generative AI - A Workshop
ks91
PRO
1
520
Designing Dashboards & Data Visualisations in Web Apps
destraynor
232
55k
Claude Code のすすめ
schroneko
67
230k
Keith and Marios Guide to Fast Websites
keithpitt
413
23k
Redefining SEO in the New Era of Traffic Generation
szymonslowik
1
480
Heart Work Chapter 1 - Part 1
lfama
PRO
10
37k
Technical Leadership for Architectural Decision Making
baasie
3
600
Why Your Marketing Sucks and What You Can Do About It - Sophie Logan
marketingsoph
0
430
RailsConf 2023
tenderlove
30
1.6k
Transcript
∞-former: Infinite Memory Transformer Pedro Henrique Martins, Zita Marinho, André
F. T. Martins ACL 2022 お茶大 村山友理
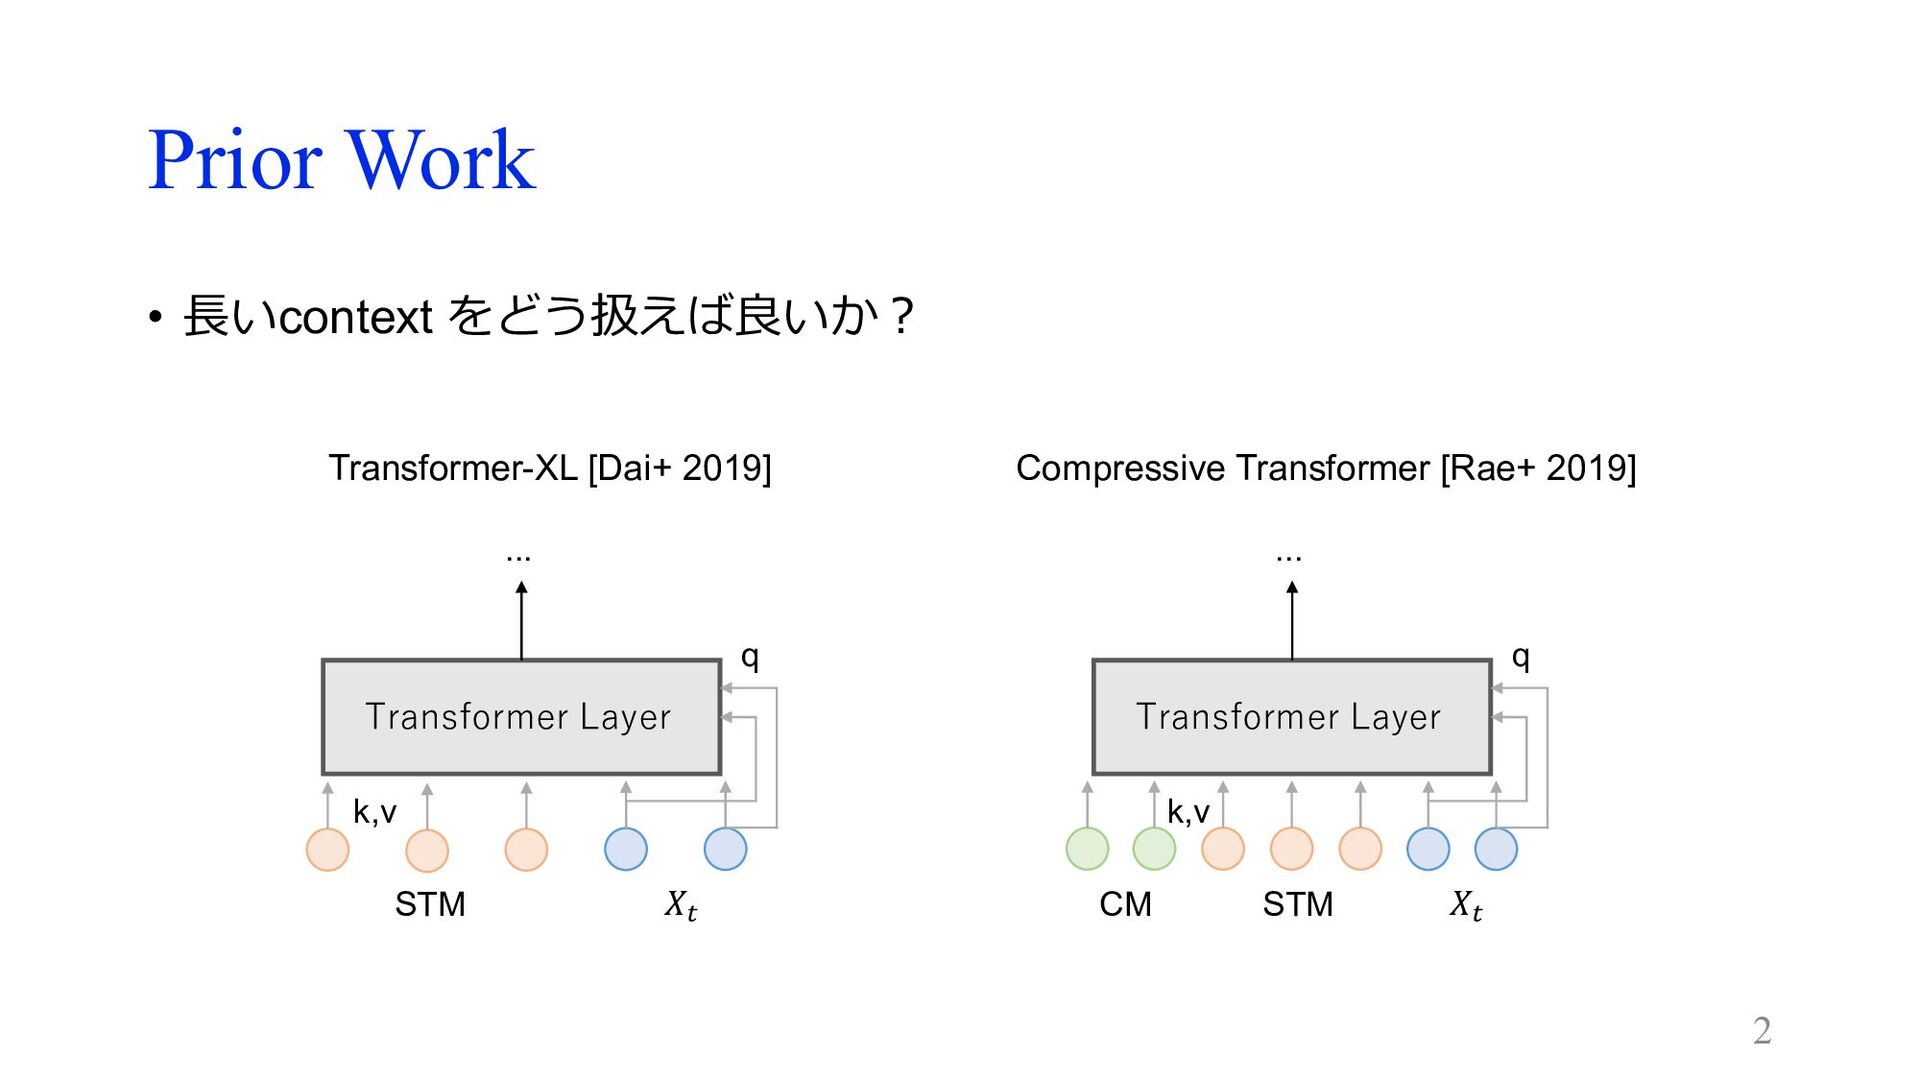
Prior Work • ⻑いcontext をどう扱えば良いか︖ 2 Transformer Layer 𝑋! STM
q k,v ... Transformer Layer 𝑋! STM CM q k,v ... Compressive Transformer [Rae+ 2019] Transformer-XL [Dai+ 2019]
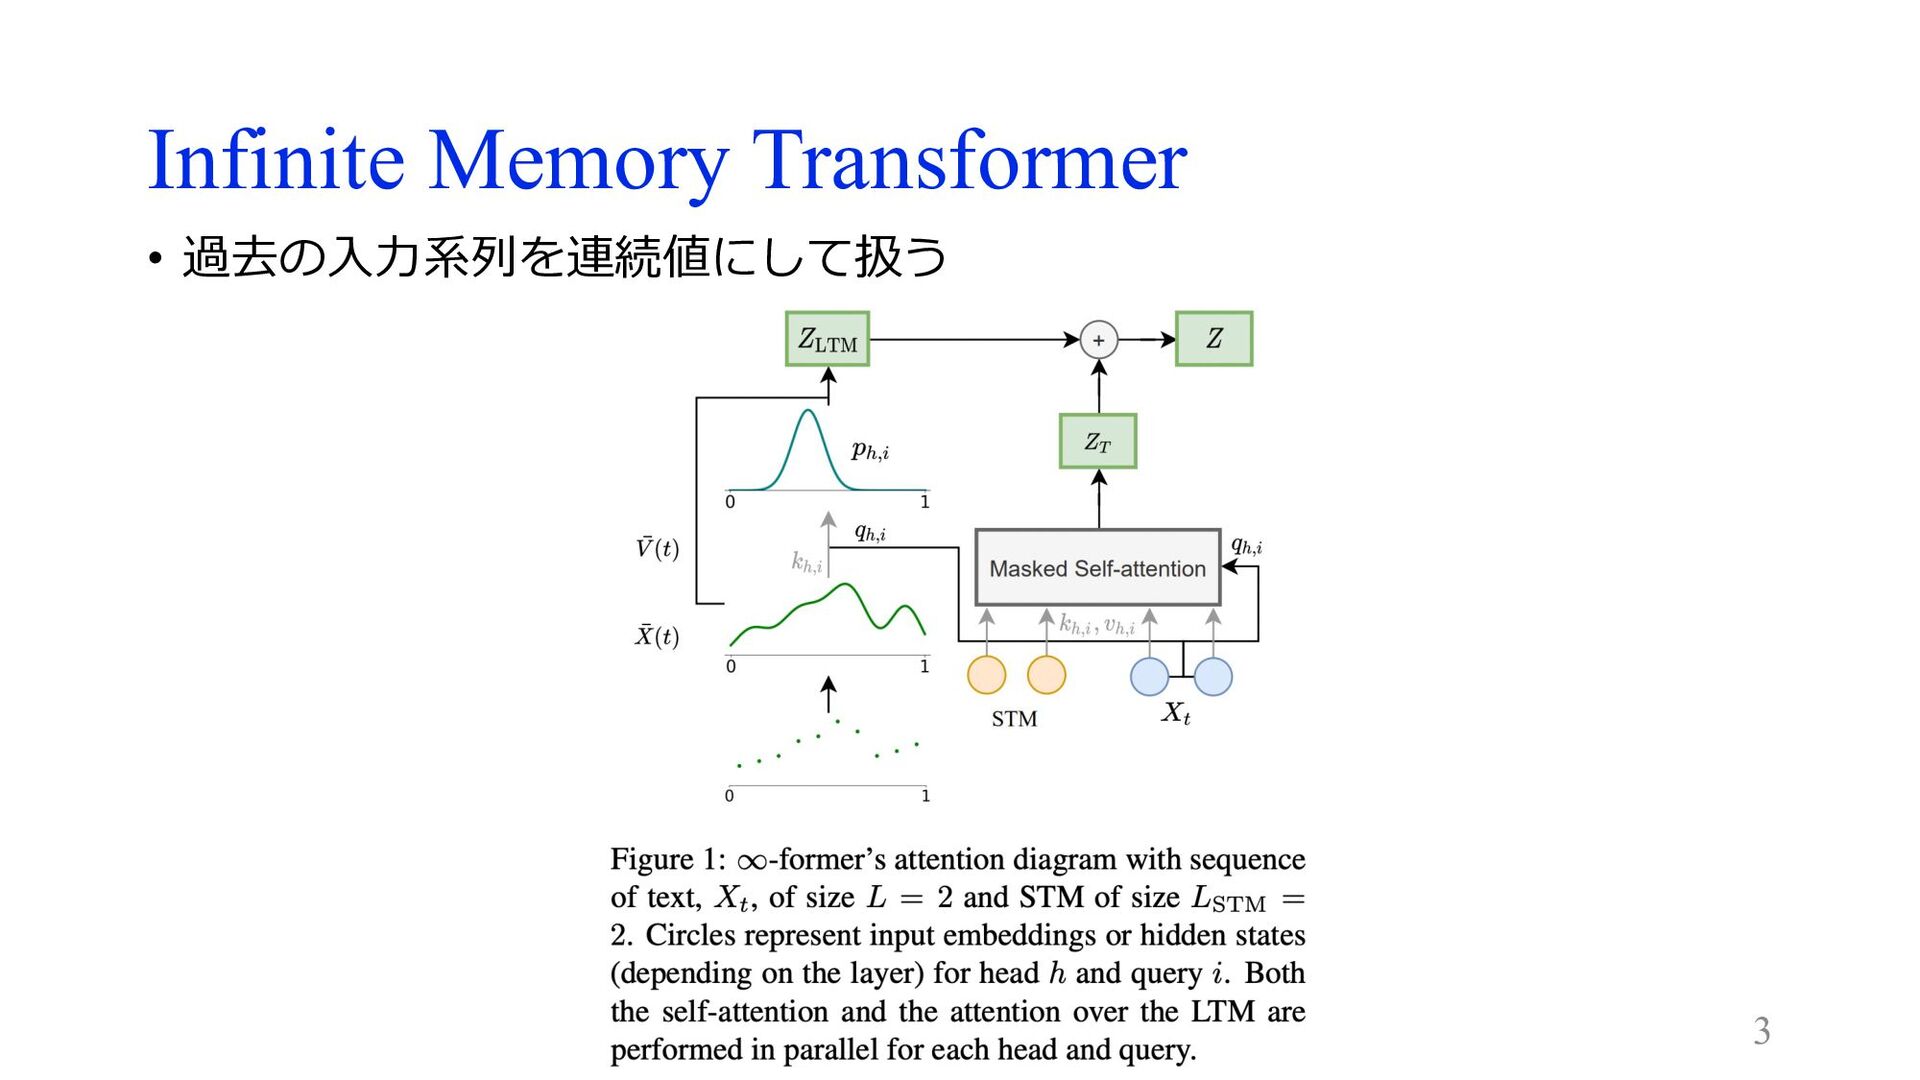
Infinite Memory Transformer • 過去の⼊⼒系列を連続値にして扱う 3
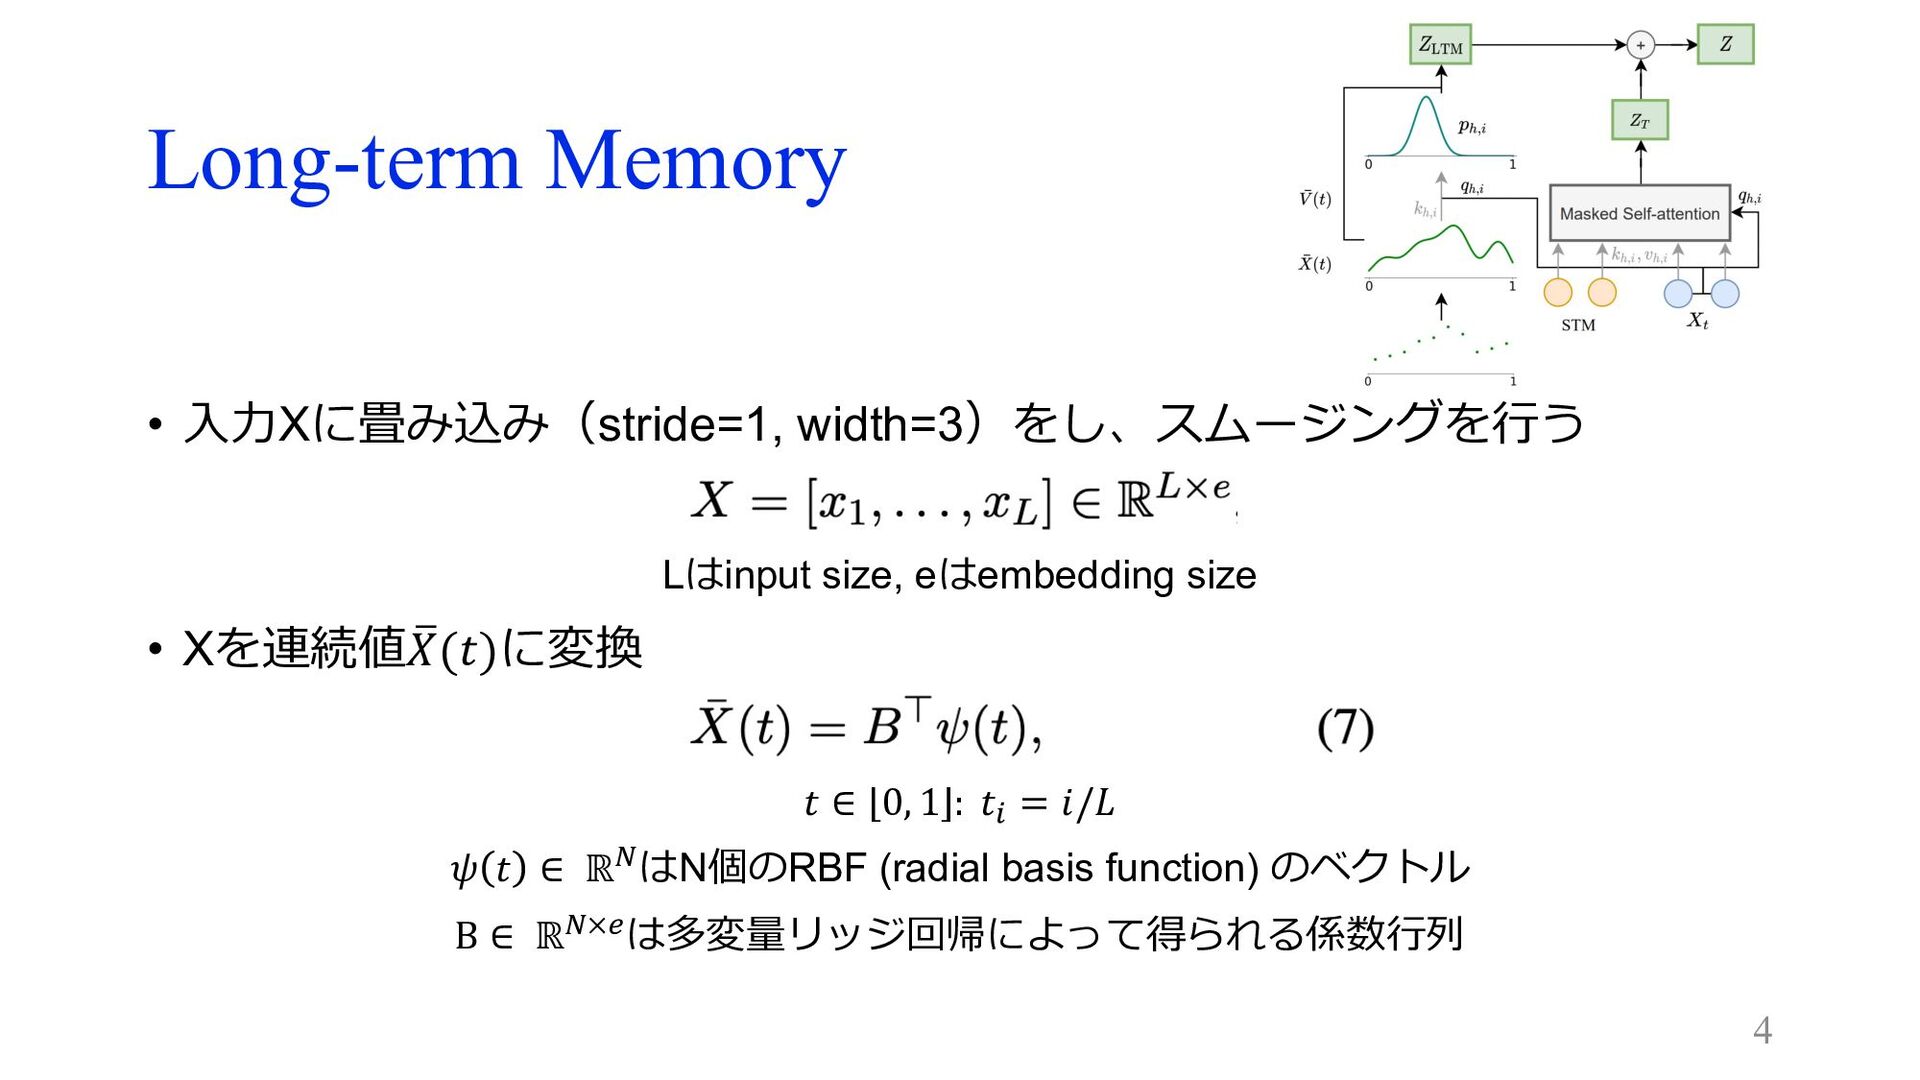
Long-term Memory • ⼊⼒Xに畳み込み(stride=1, width=3)をし、スムージングを⾏う Lはinput size, eはembedding size •
Xを連続値 ! 𝑋(𝑡)に変換 𝑡 ∈ 0, 1 : 𝑡! = 𝑖/𝐿 𝜓 𝑡 ∈ ℝ"はN個のRBF (radial basis function) のベクトル B ∈ ℝ"×$は多変量リッジ回帰によって得られる係数⾏列 4
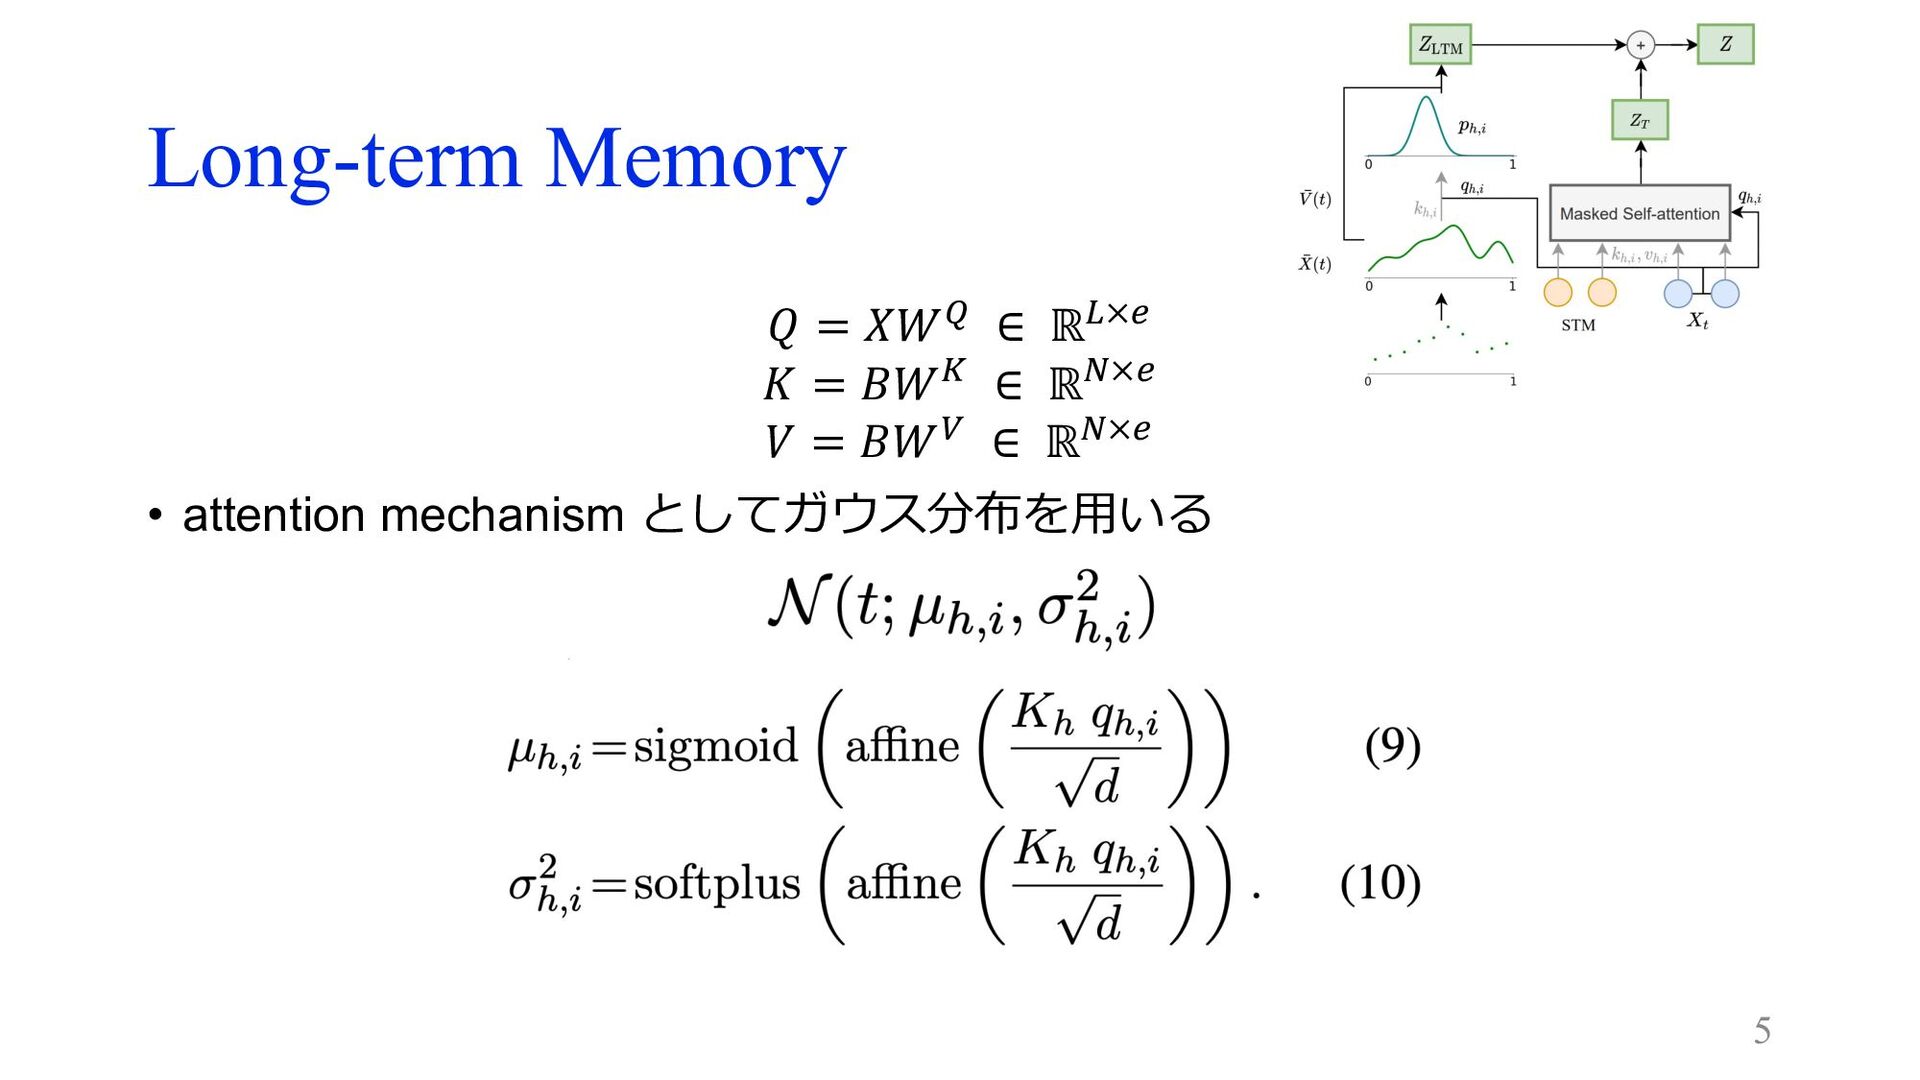
Long-term Memory 𝑄 = 𝑋𝑊" ∈ ℝ#×% 𝐾 = 𝐵𝑊&
∈ ℝ'×% 𝑉 = 𝐵𝑊( ∈ ℝ'×% • attention mechanism としてガウス分布を⽤いる 5
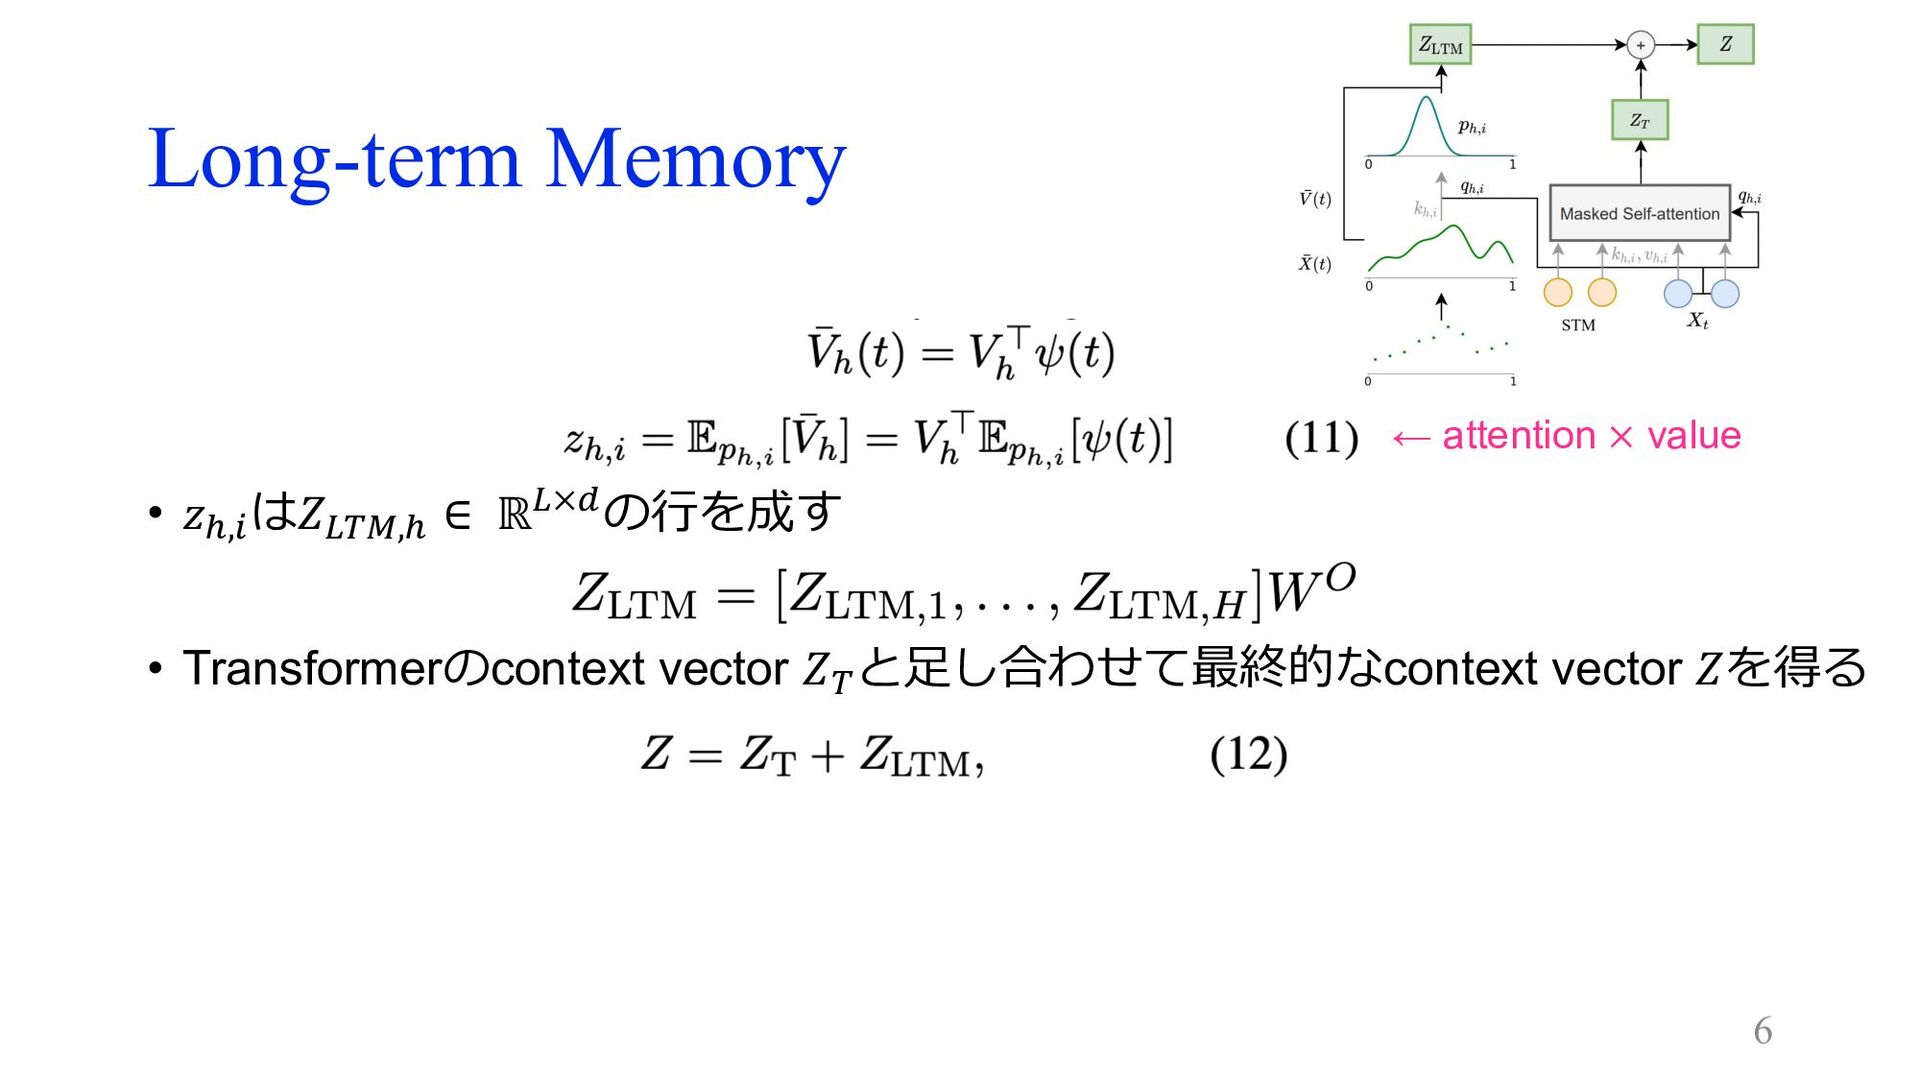
Long-term Memory • 𝑧),+ は𝑍#,-,) ∈ ℝ#×.の⾏を成す • Transformerのcontext vector
𝑍, と⾜し合わせて最終的なcontext vector 𝑍を得る 6 ← attention × value
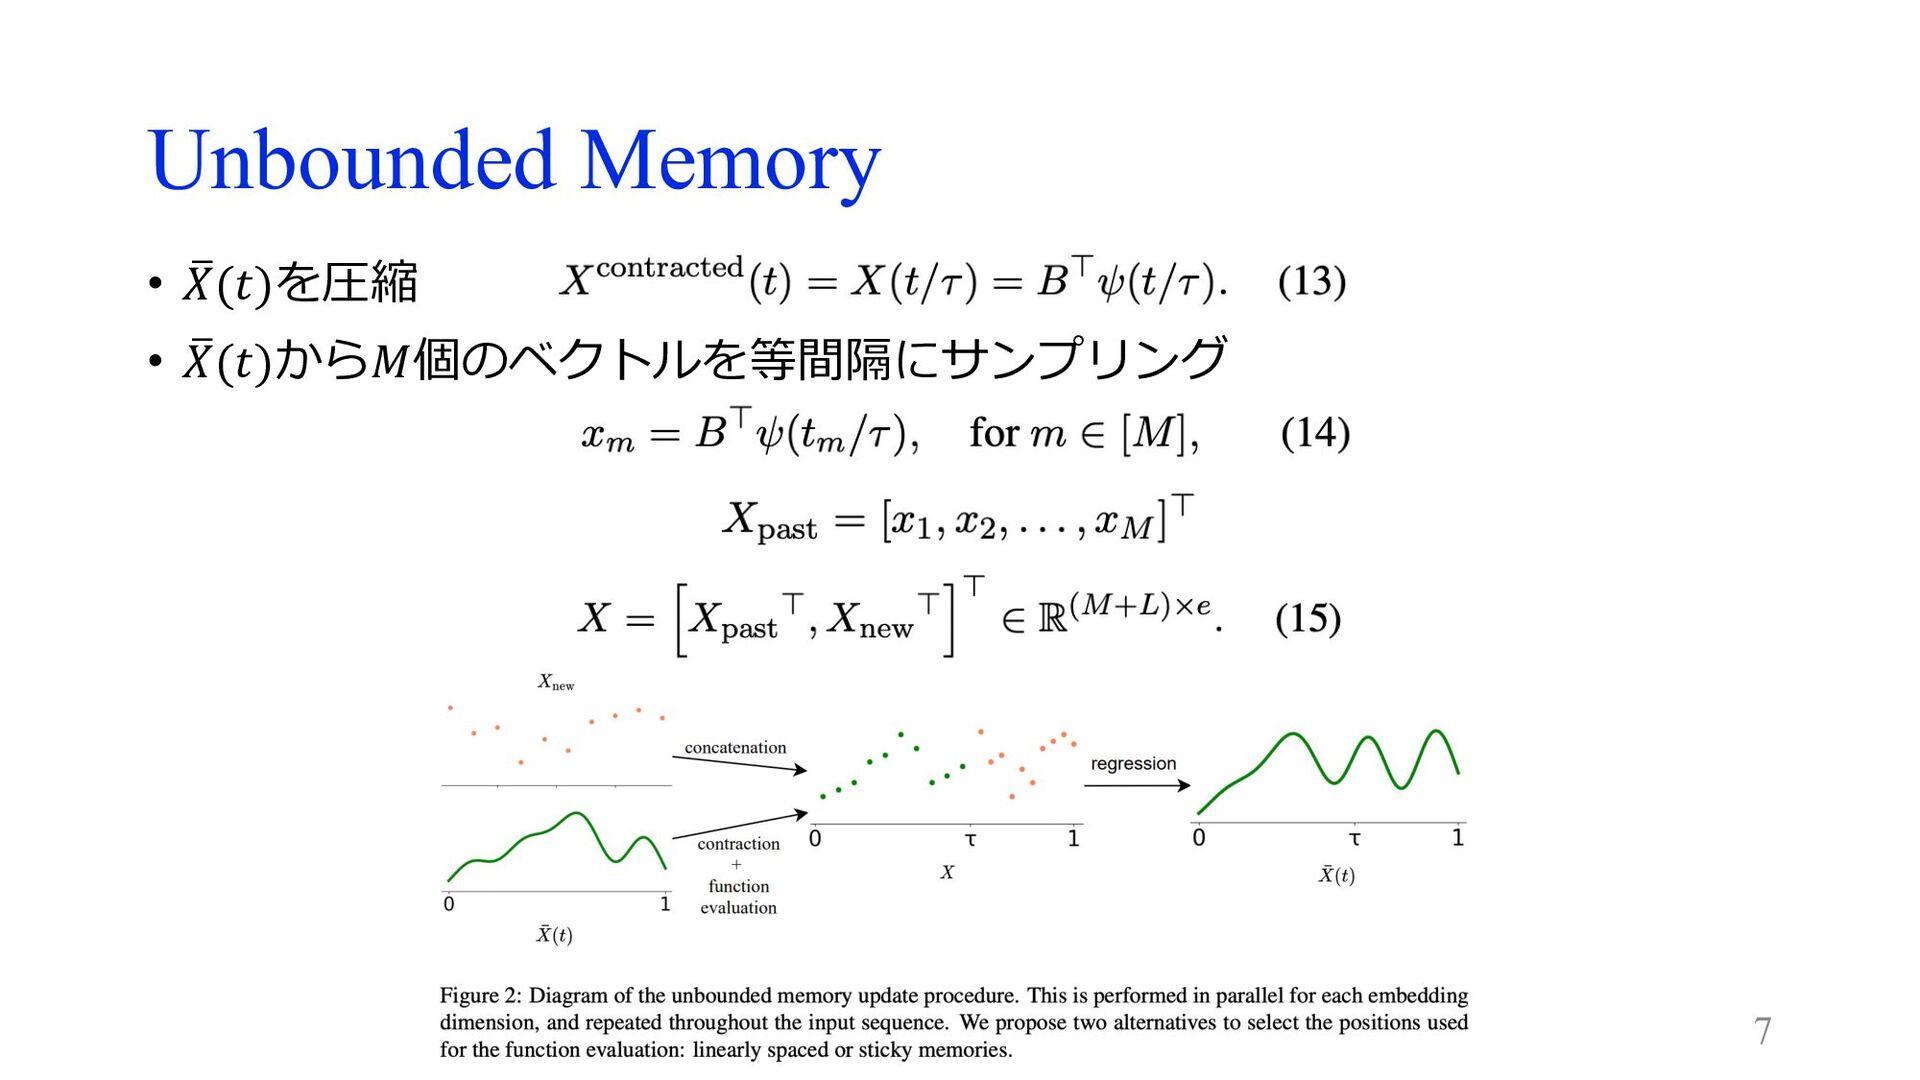
Unbounded Memory 7 • ! 𝑋(𝑡)を圧縮 • ! 𝑋(𝑡)から𝑀個のベクトルを等間隔にサンプリング
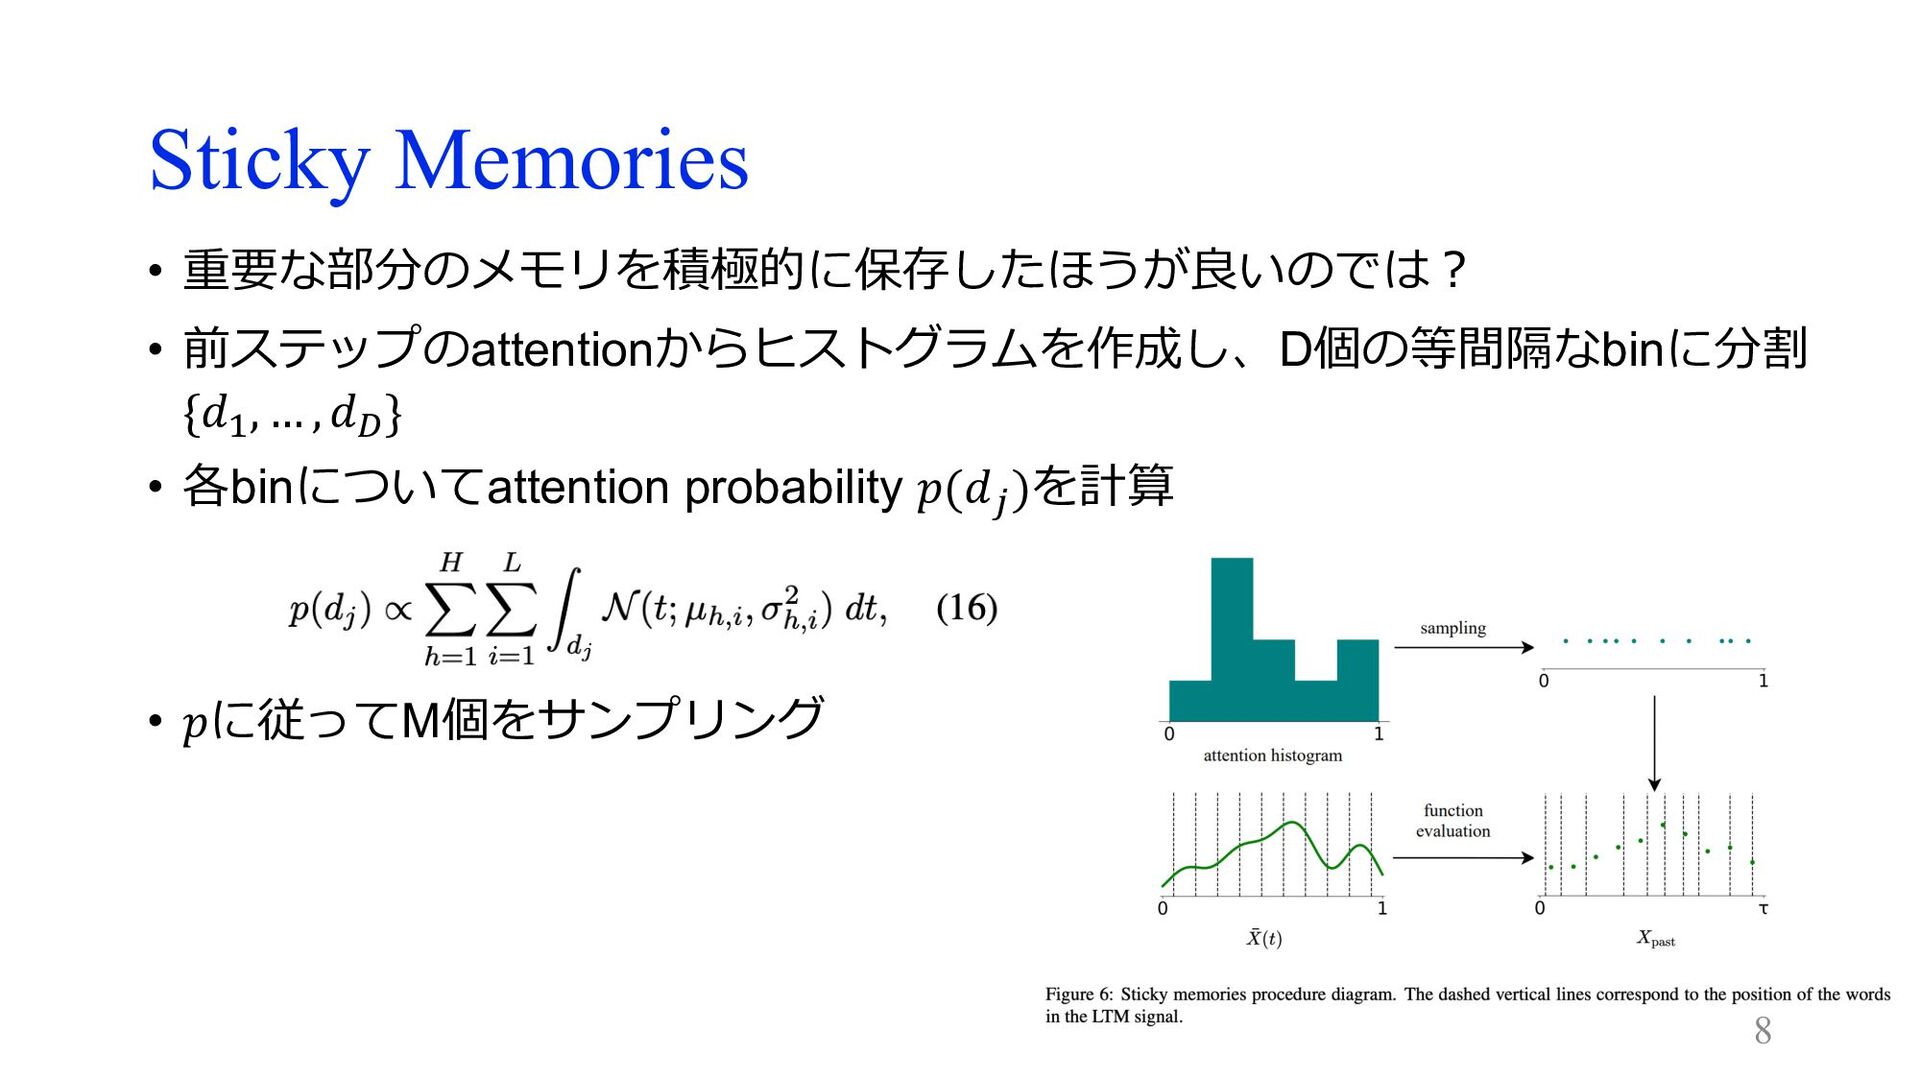
Sticky Memories • 重要な部分のメモリを積極的に保存したほうが良いのでは︖ • 前ステップのattentionからヒストグラムを作成し、D個の等間隔なbinに分割 {𝑑/, … , 𝑑0}
• 各binについてattention probability 𝑝(𝑑1 )を計算 • 𝑝に従ってM個をサンプリング 8
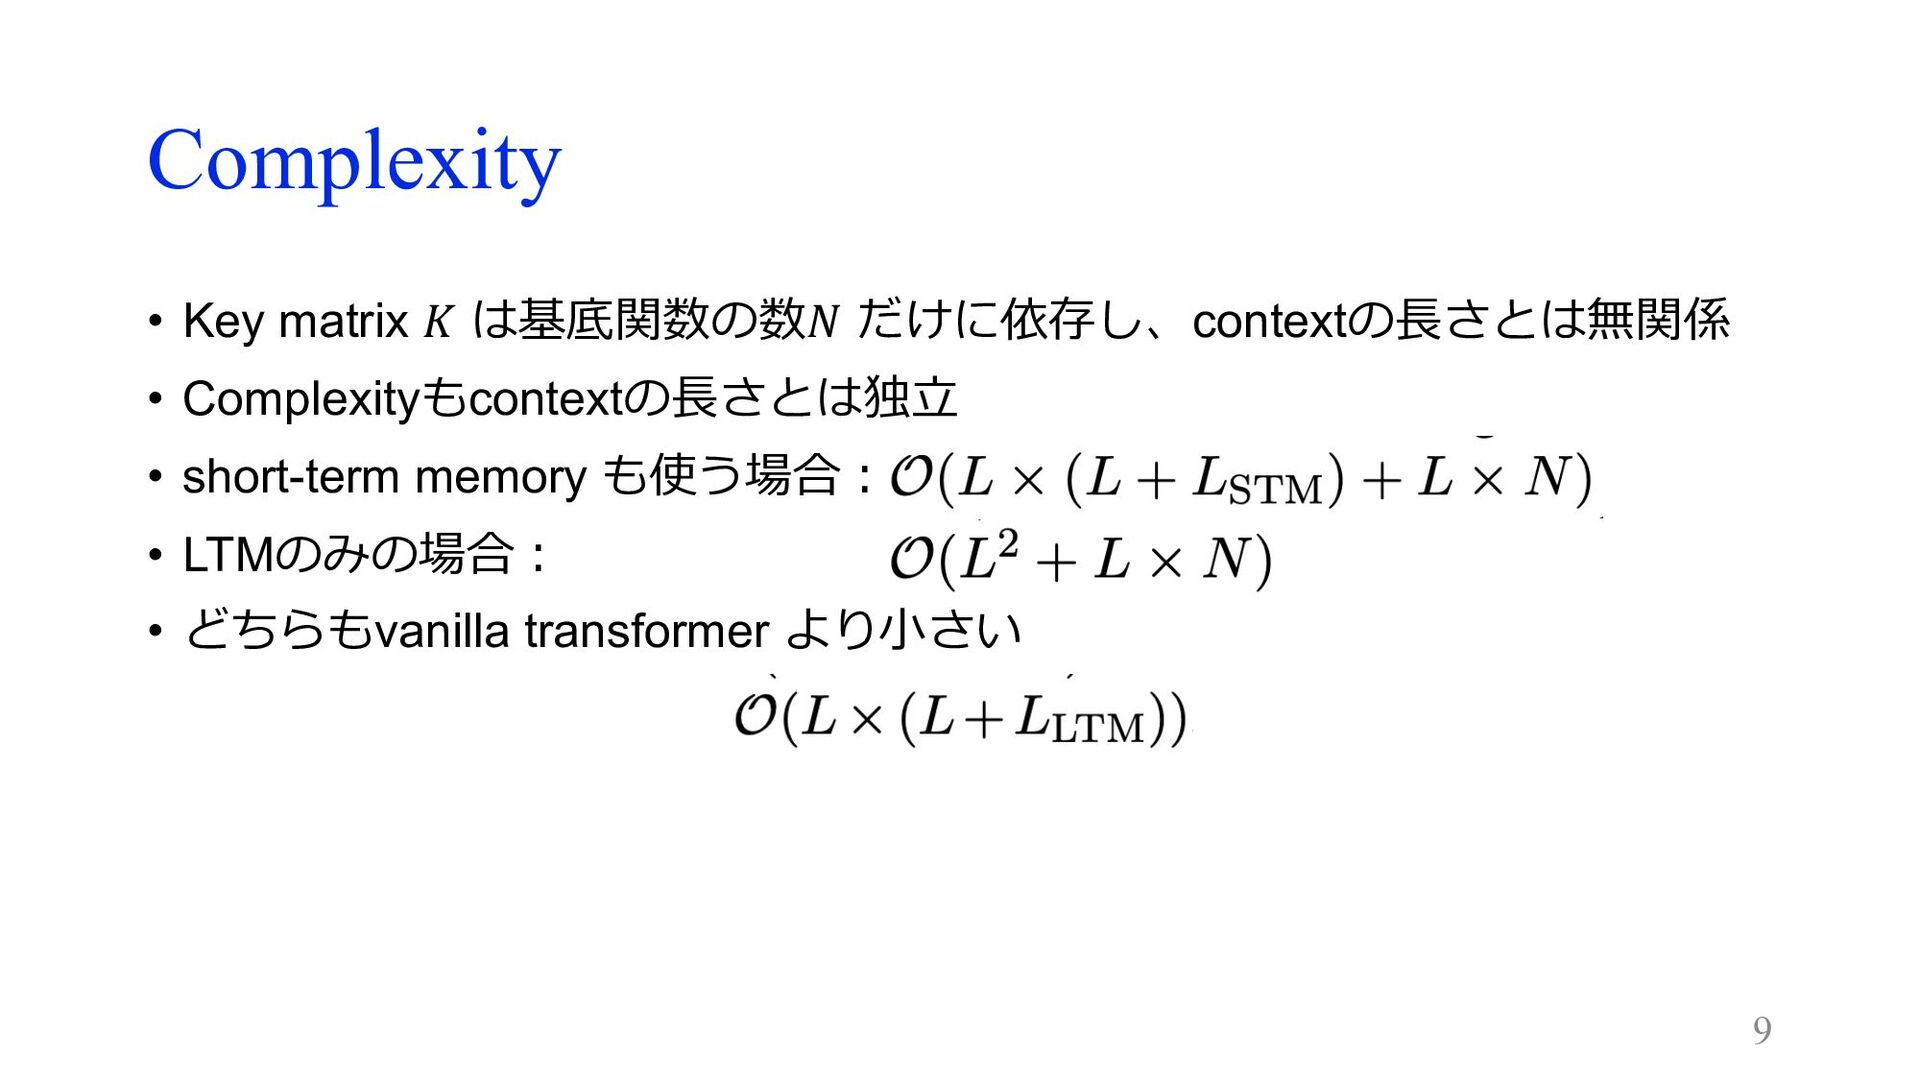
Complexity • Key matrix 𝐾 は基底関数の数𝑁 だけに依存し、contextの⻑さとは無関係 • Complexityもcontextの⻑さとは独⽴ •
short-term memory も使う場合︓ • LTMのみの場合︓ • どちらもvanilla transformer より⼩さい 9
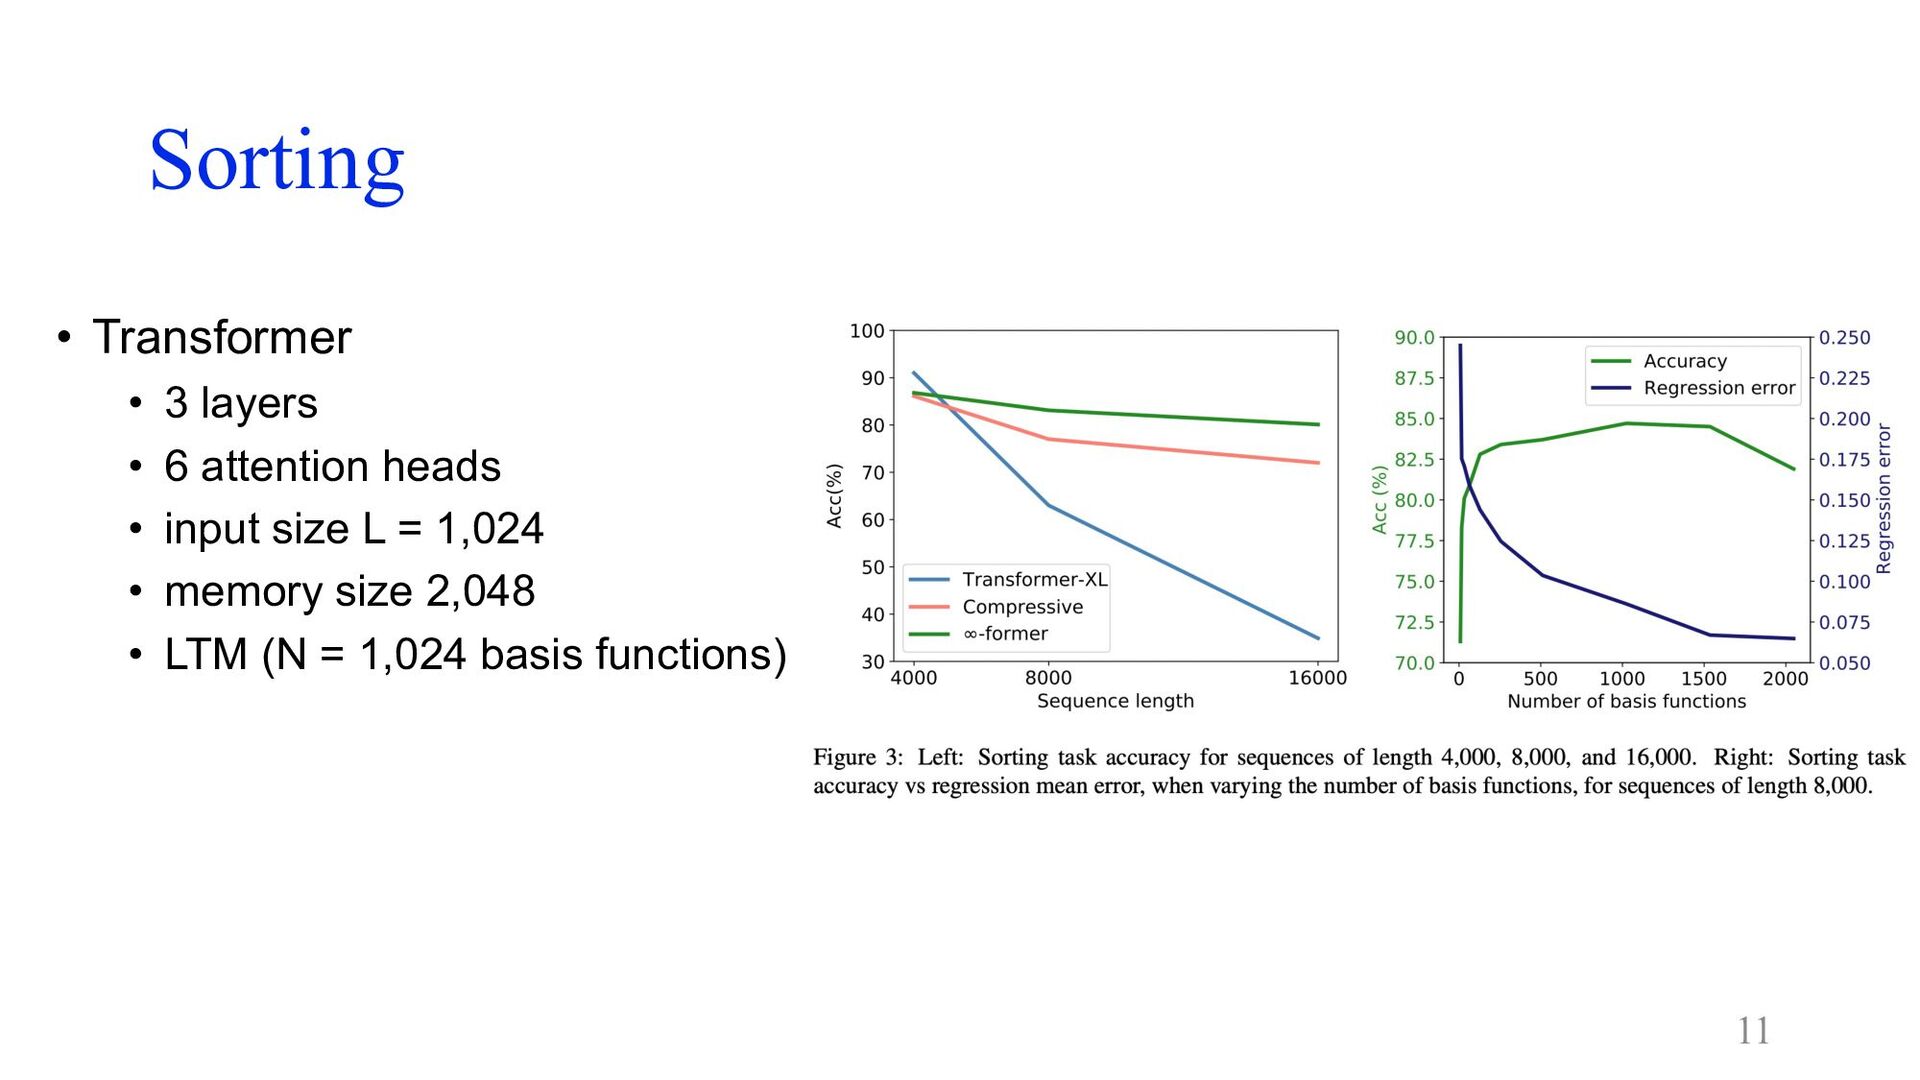
Sorting • 系列のトークンを頻度順に並べる • モデルが直近のトークンだけでなく⻑期記憶も⾒ているか調べるために、 トークンの確率分布を変化させていく • 系列が⻑くなるほど𝛼 ∈ [0,1]は0から1に徐々に増加
• vocabulary size 20 • 4,000, 8,000, 16,000トークンで実験 10
Sorting • Transformer • 3 layers • 6 attention heads
• input size L = 1,024 • memory size 2,048 • LTM (N = 1,024 basis functions) 11
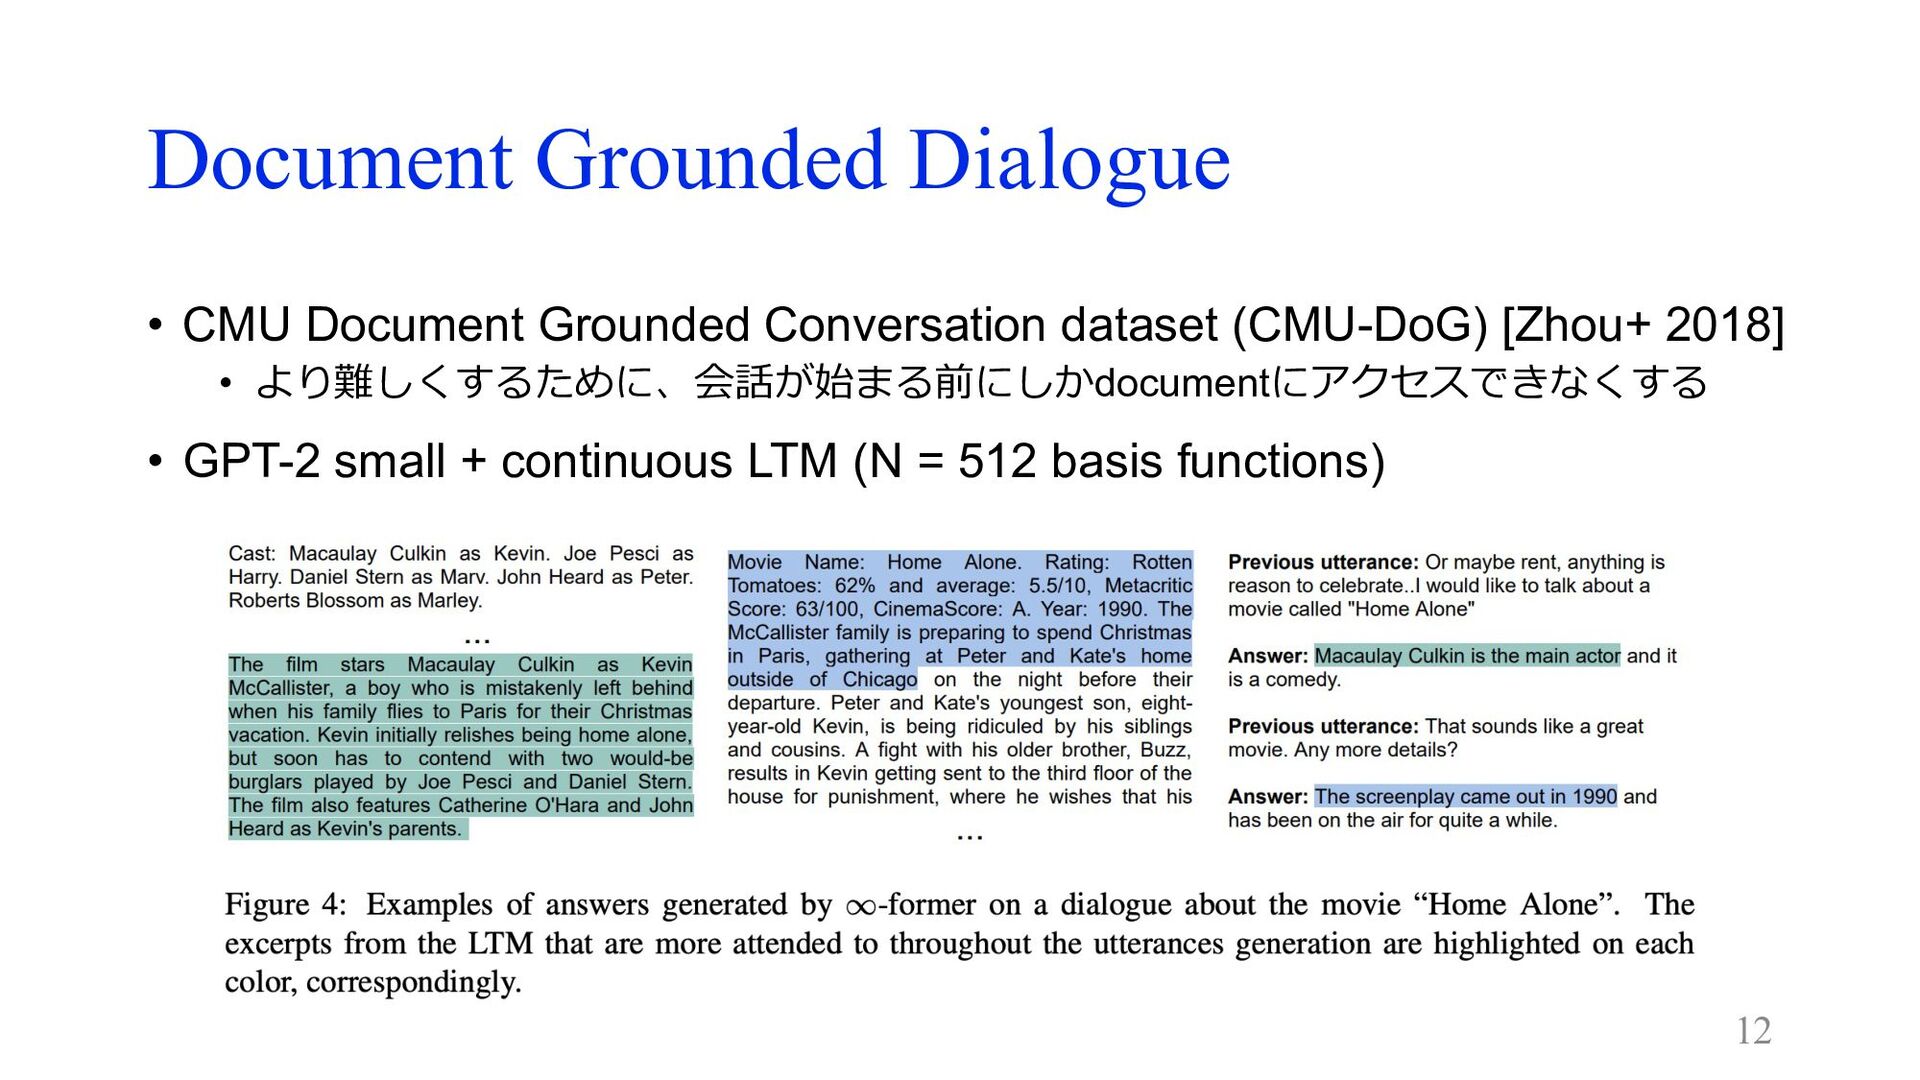
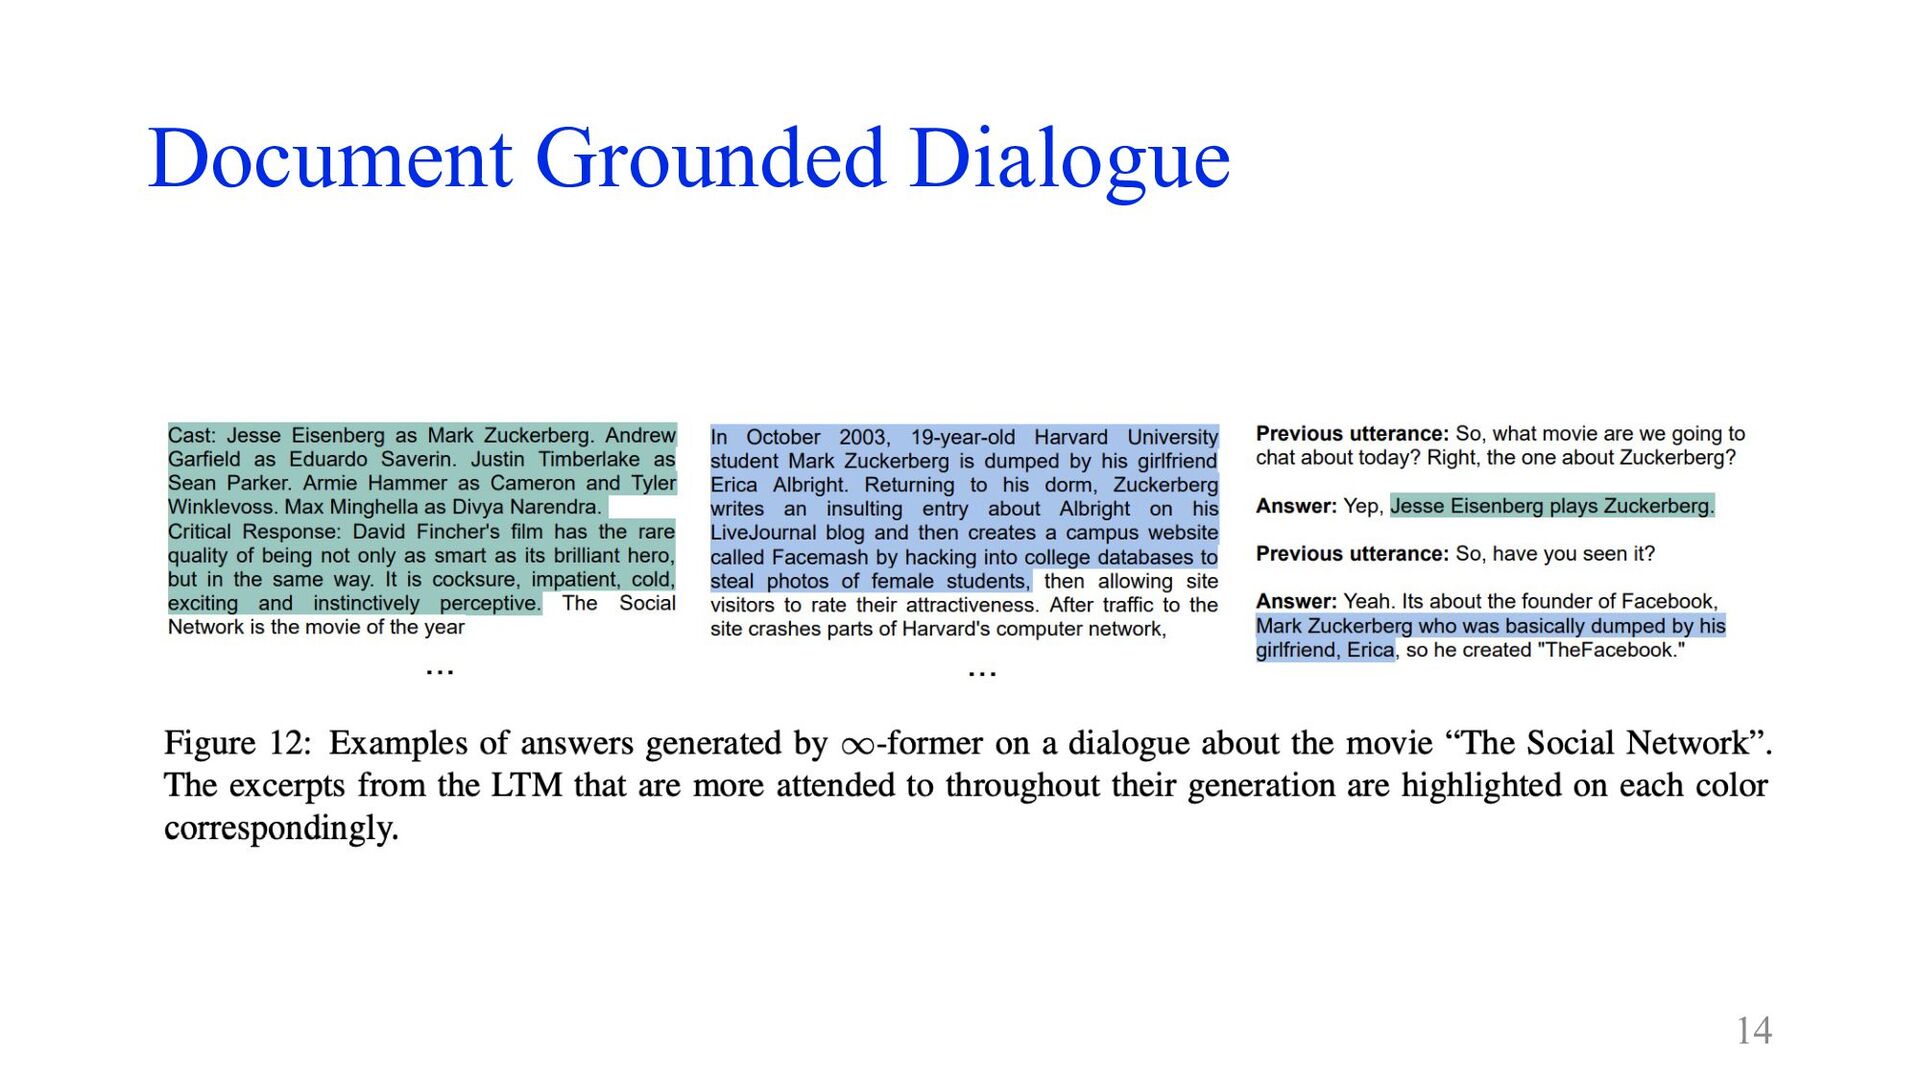
Document Grounded Dialogue • CMU Document Grounded Conversation dataset (CMU-DoG)
[Zhou+ 2018] • より難しくするために、会話が始まる前にしかdocumentにアクセスできなくする • GPT-2 small + continuous LTM (N = 512 basis functions) 12
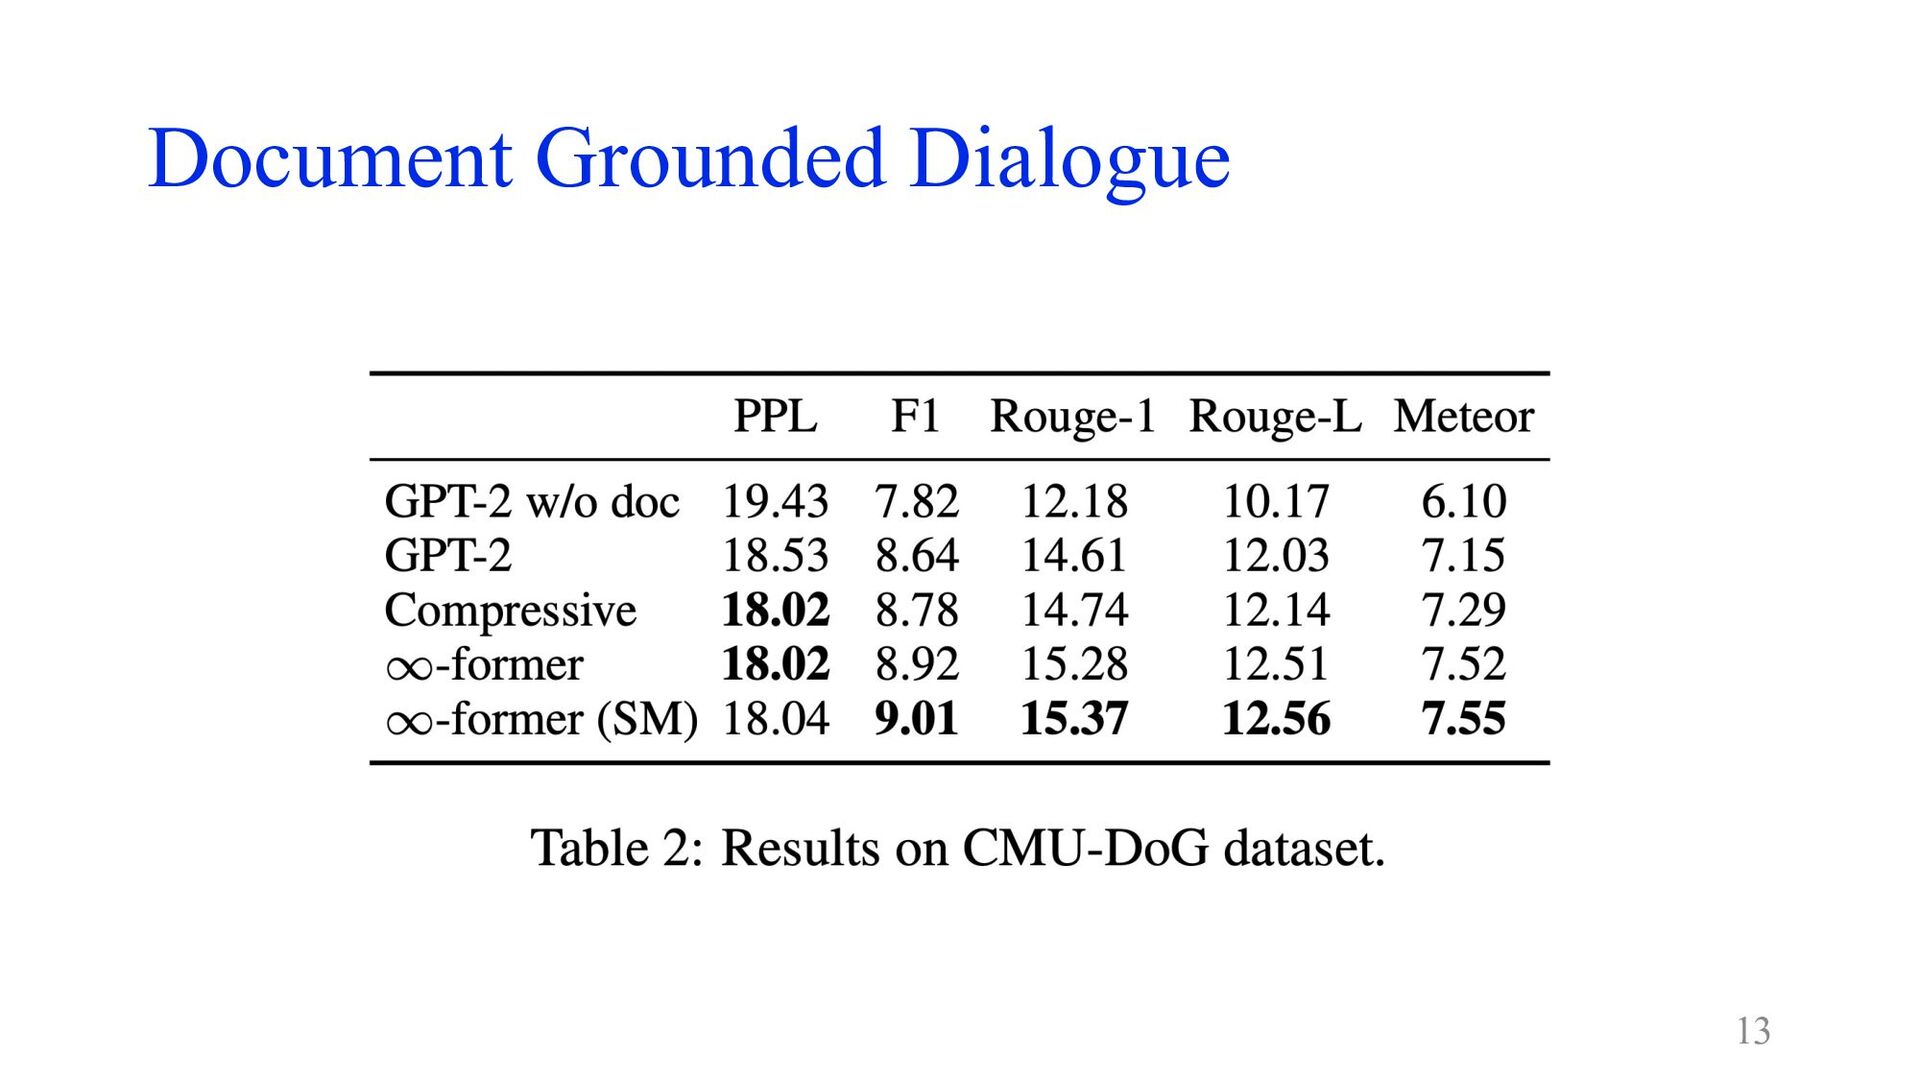
Document Grounded Dialogue 13
Document Grounded Dialogue 14
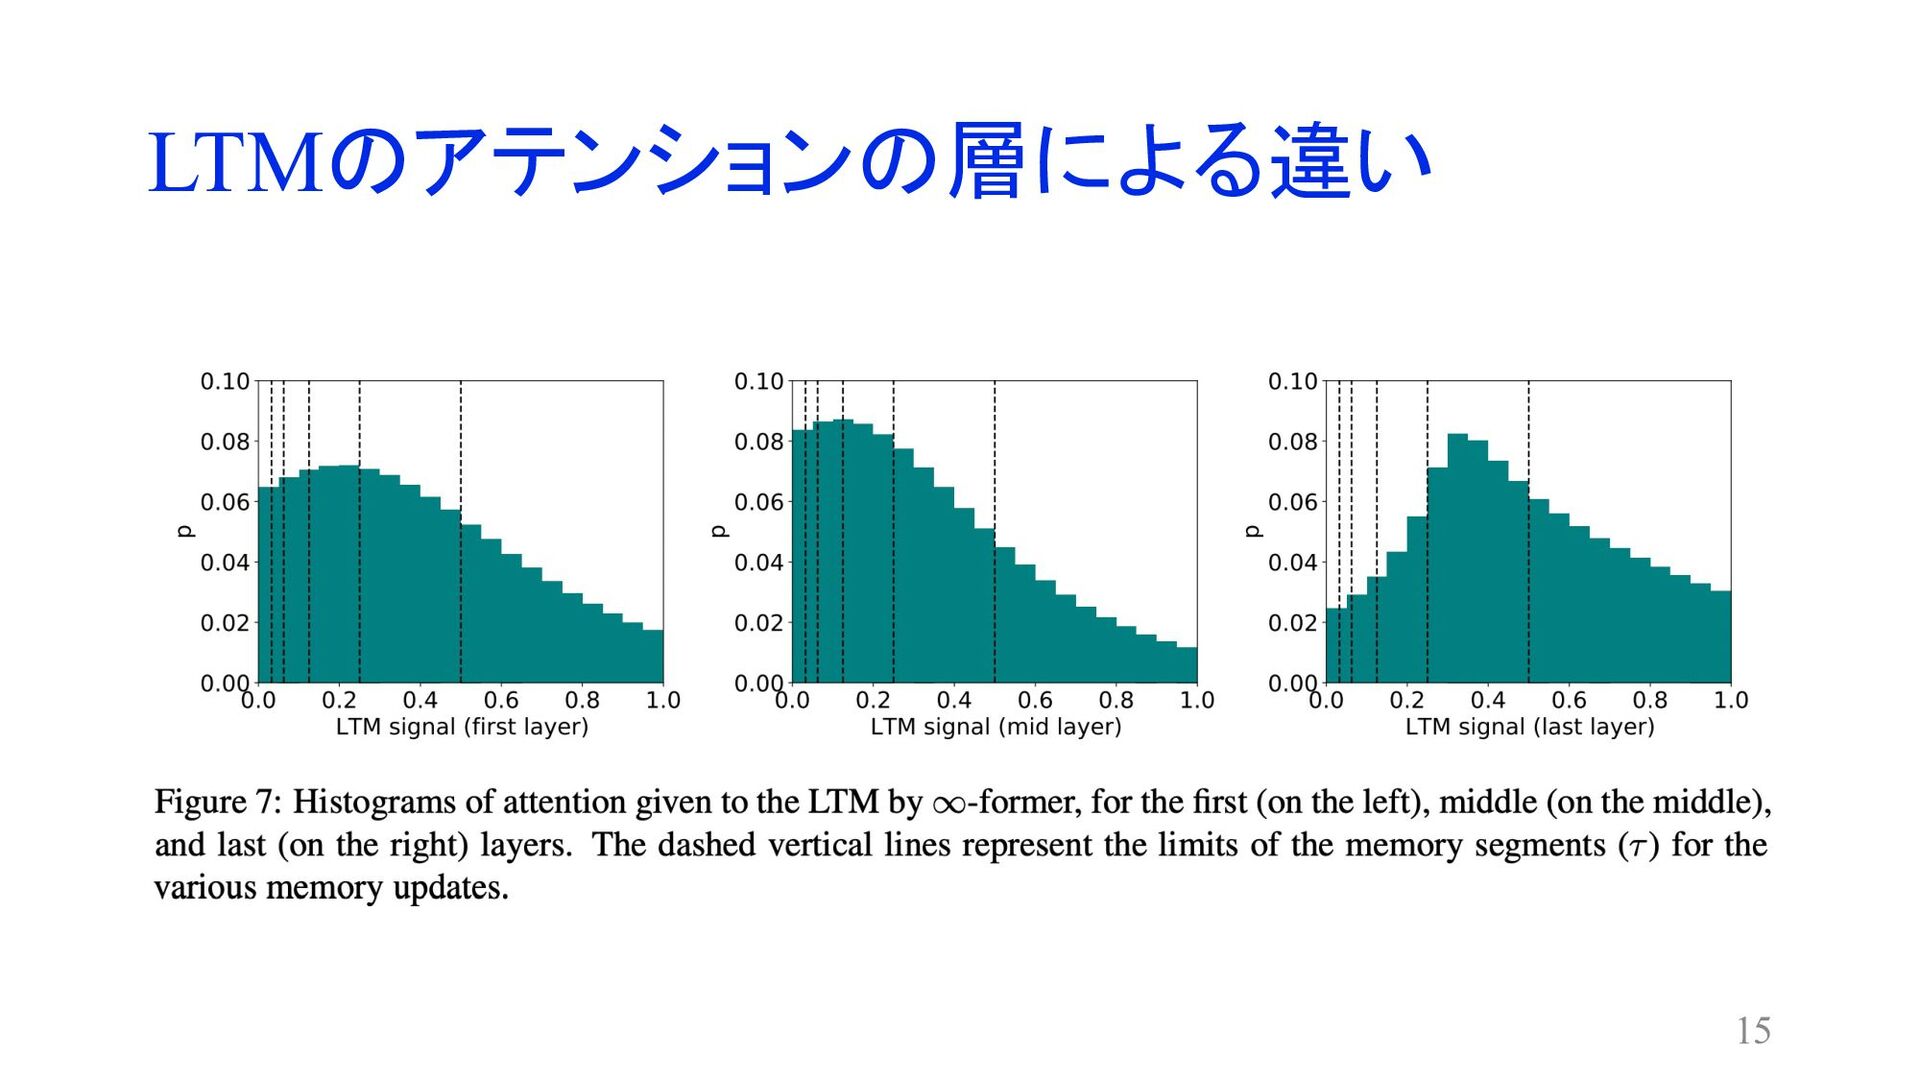
LTMのアテンションの層による違い 15
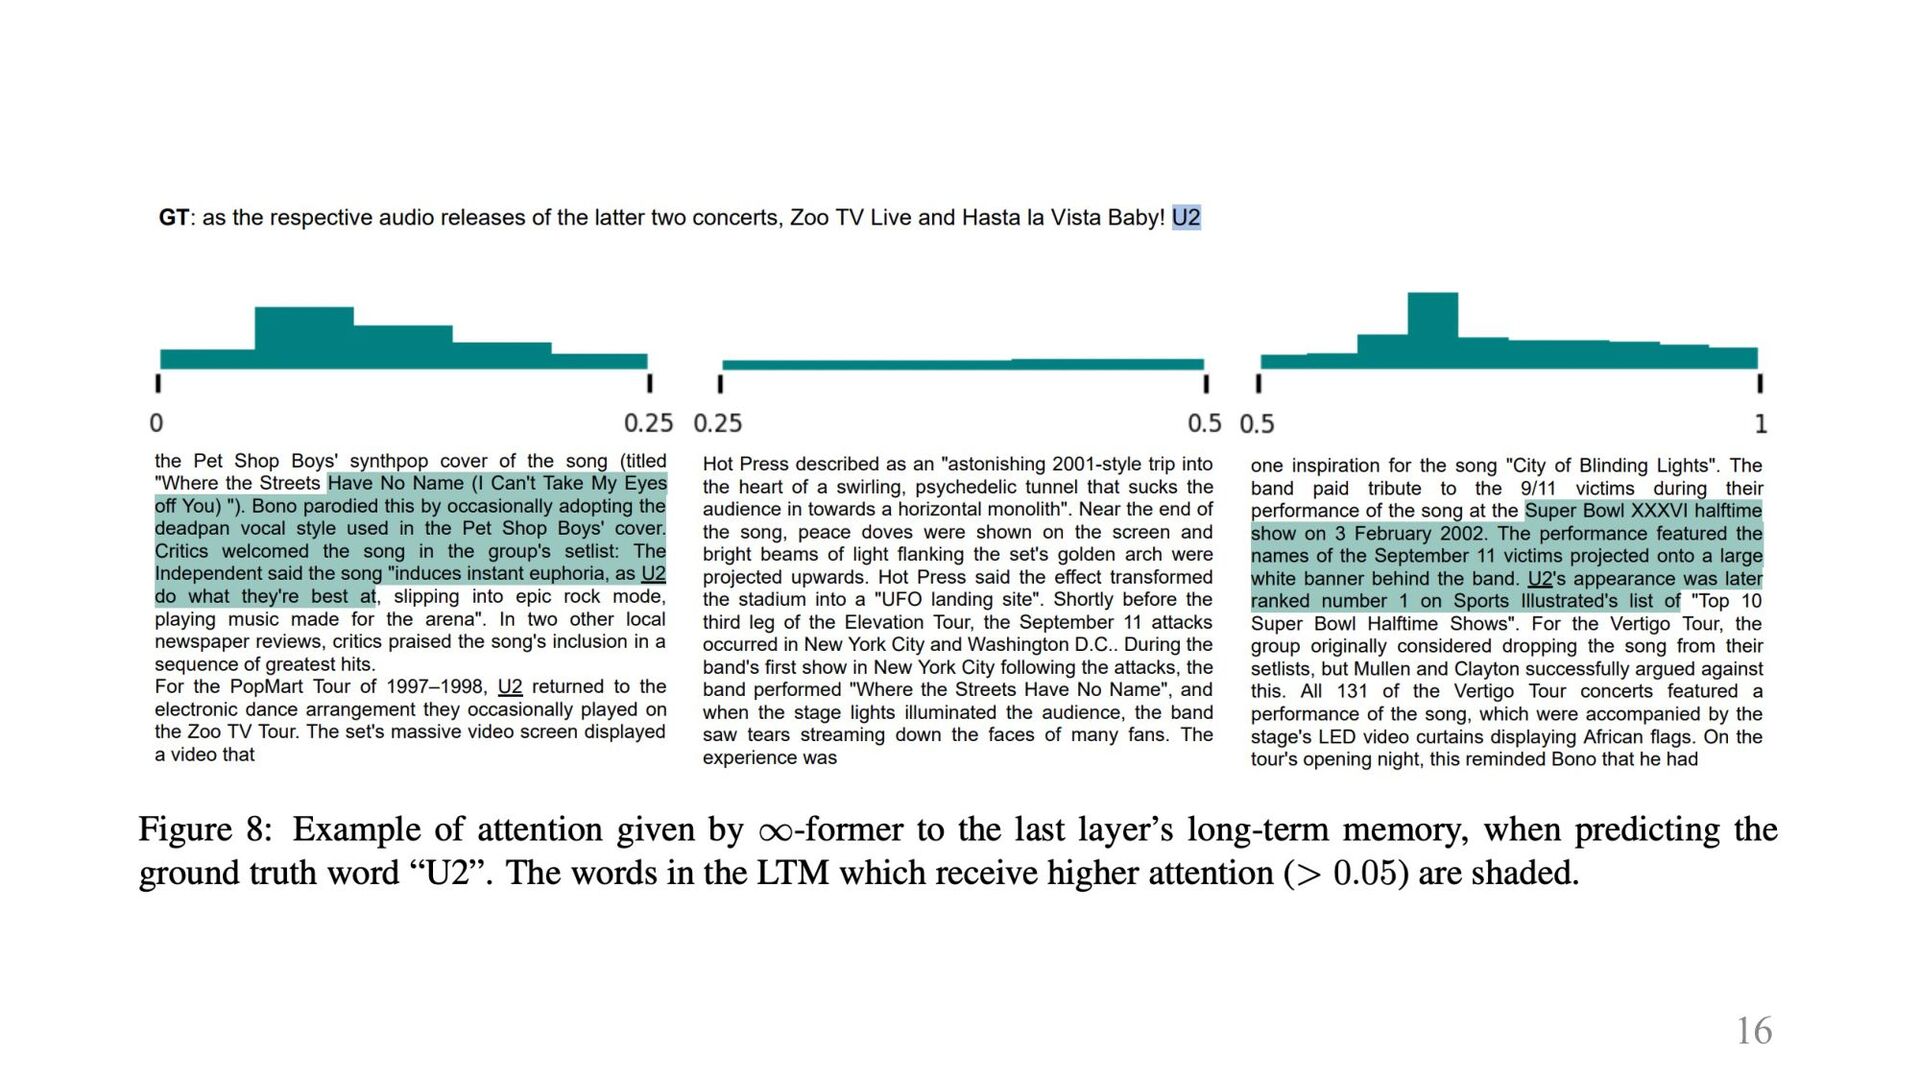
16
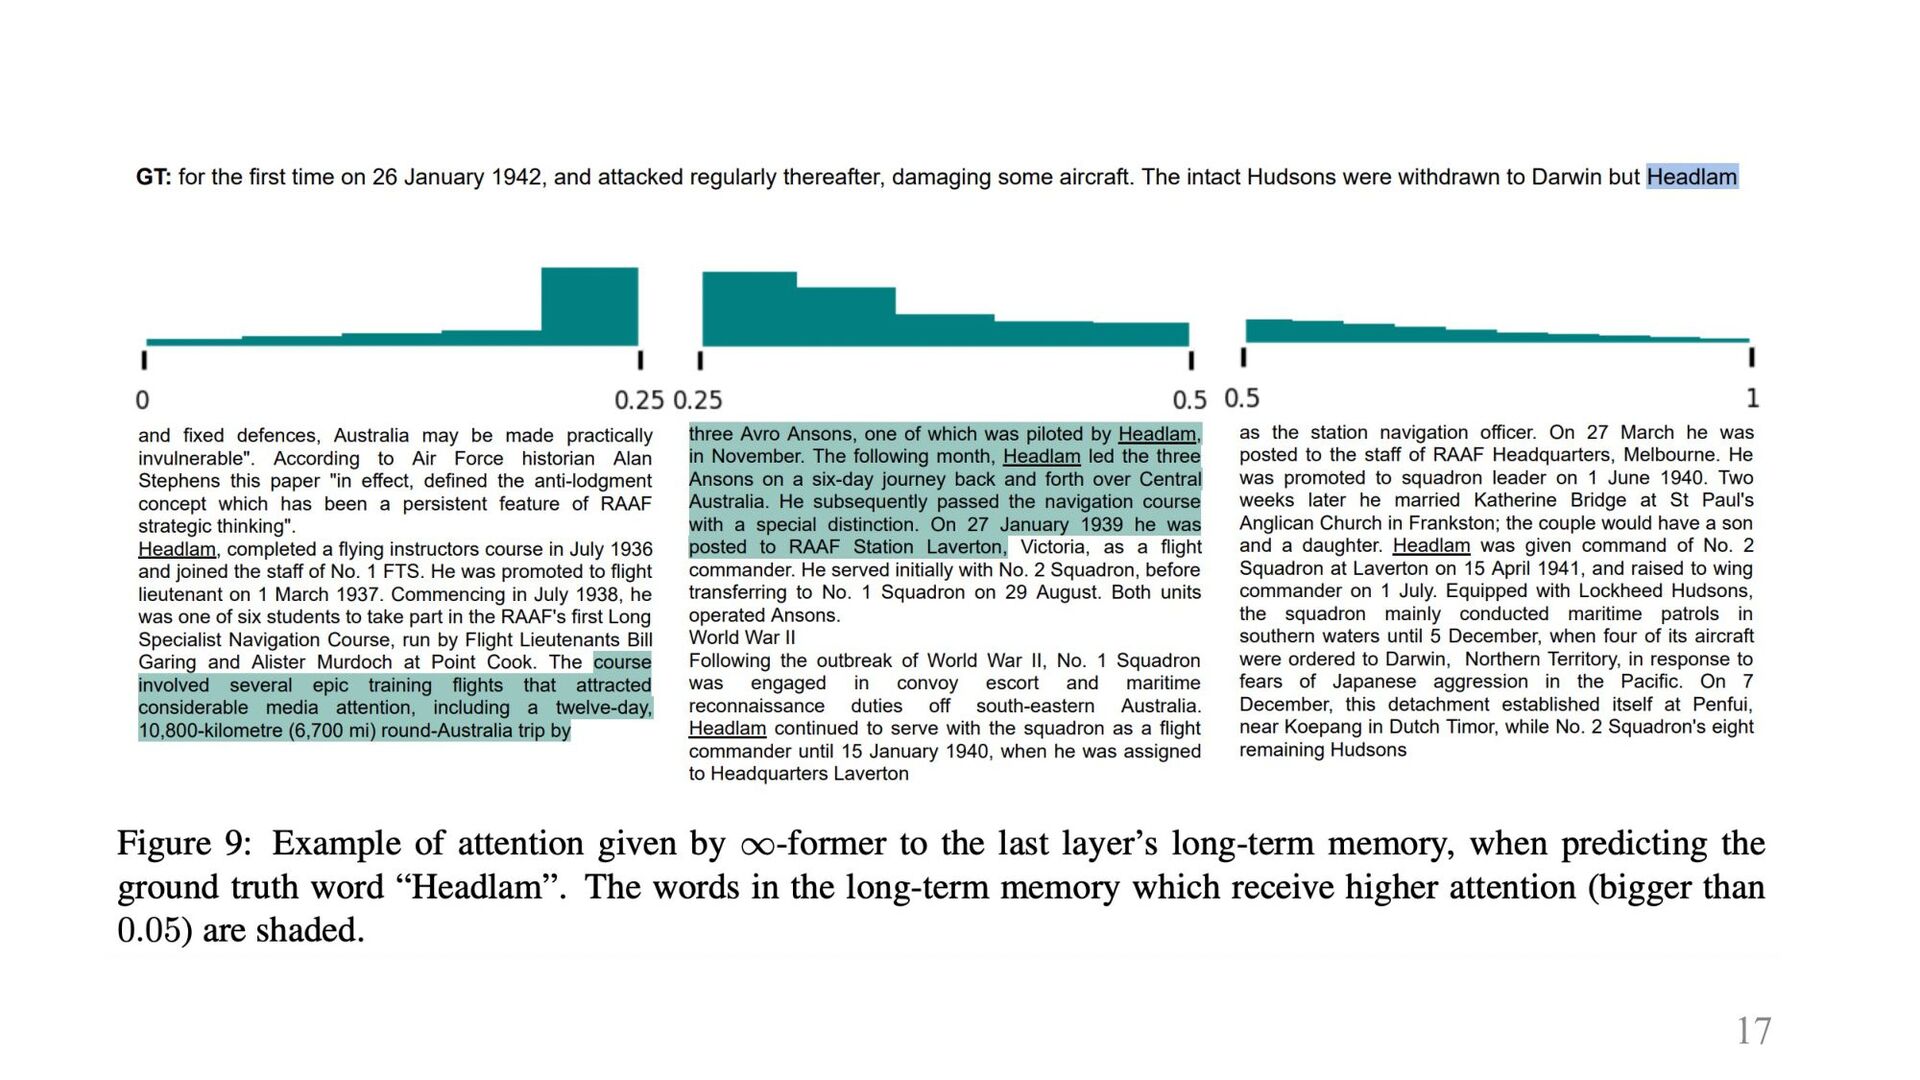
17
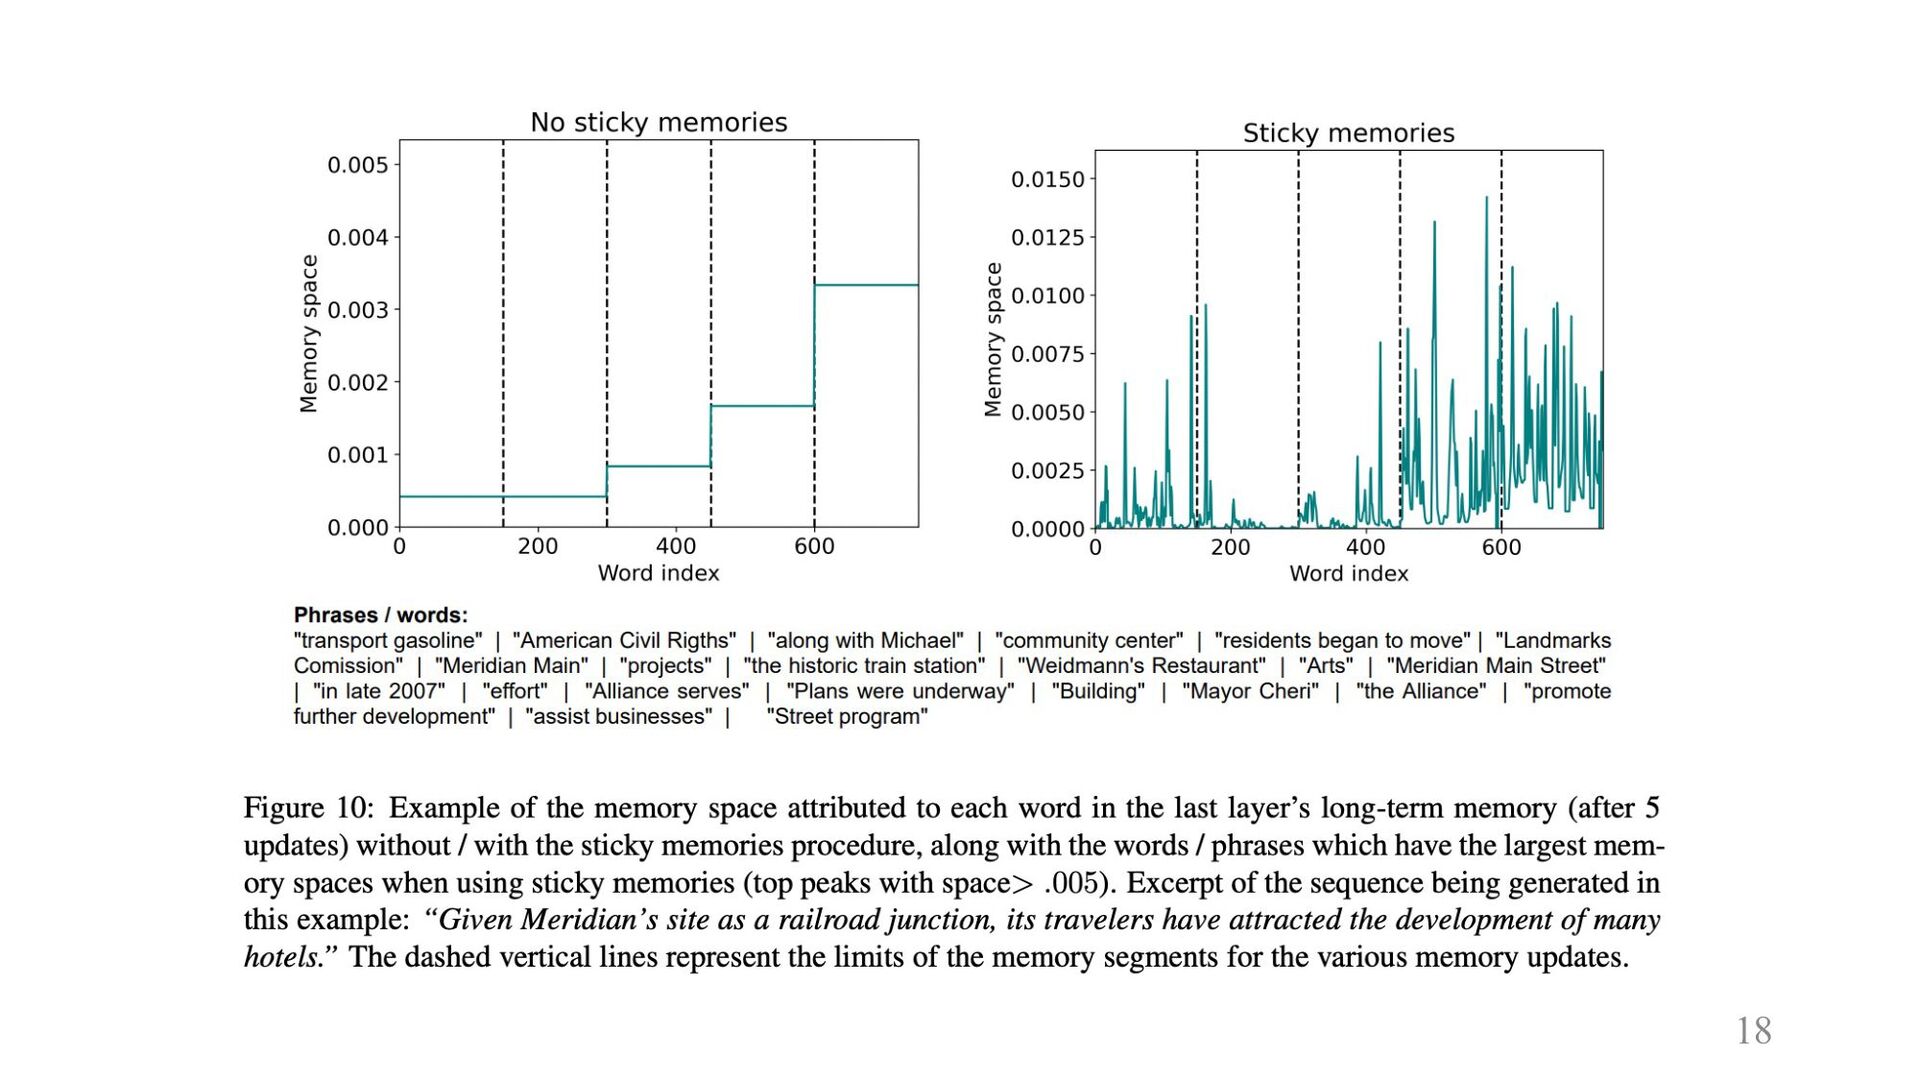
18
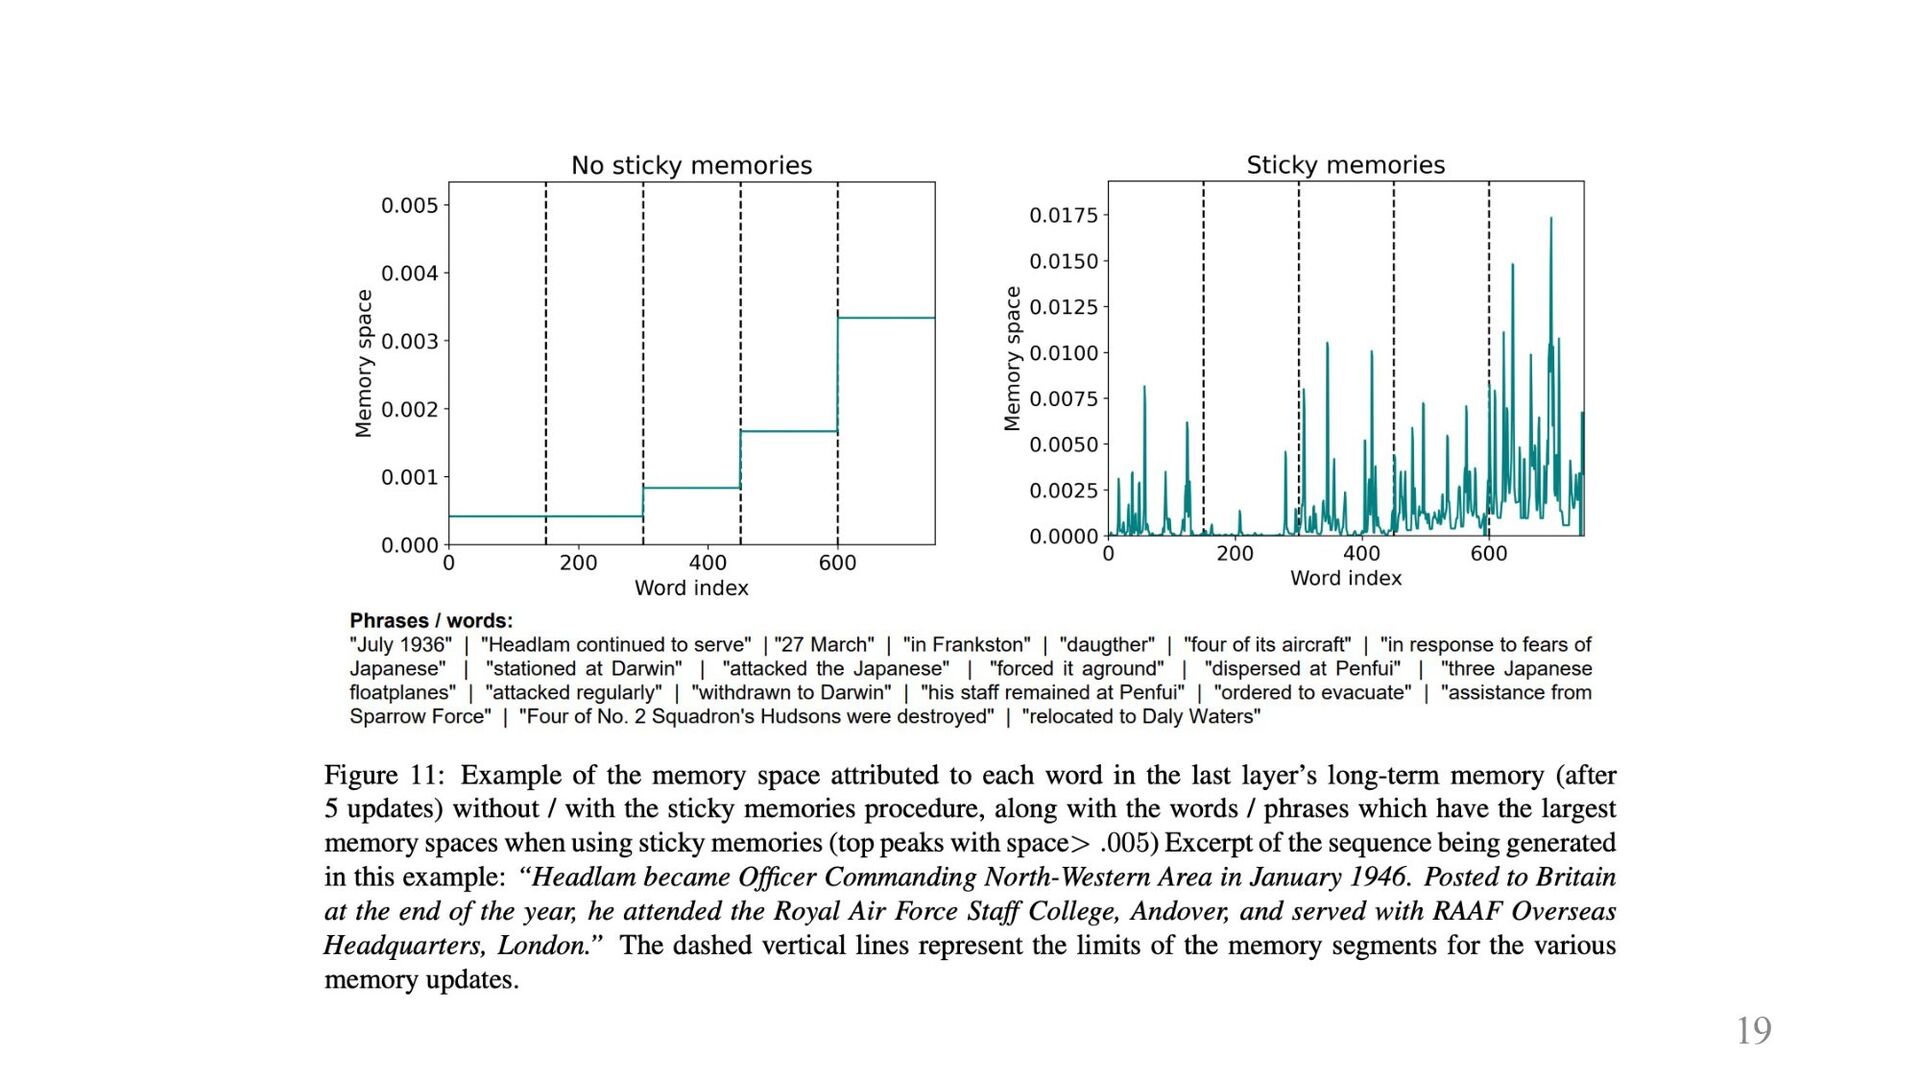
19
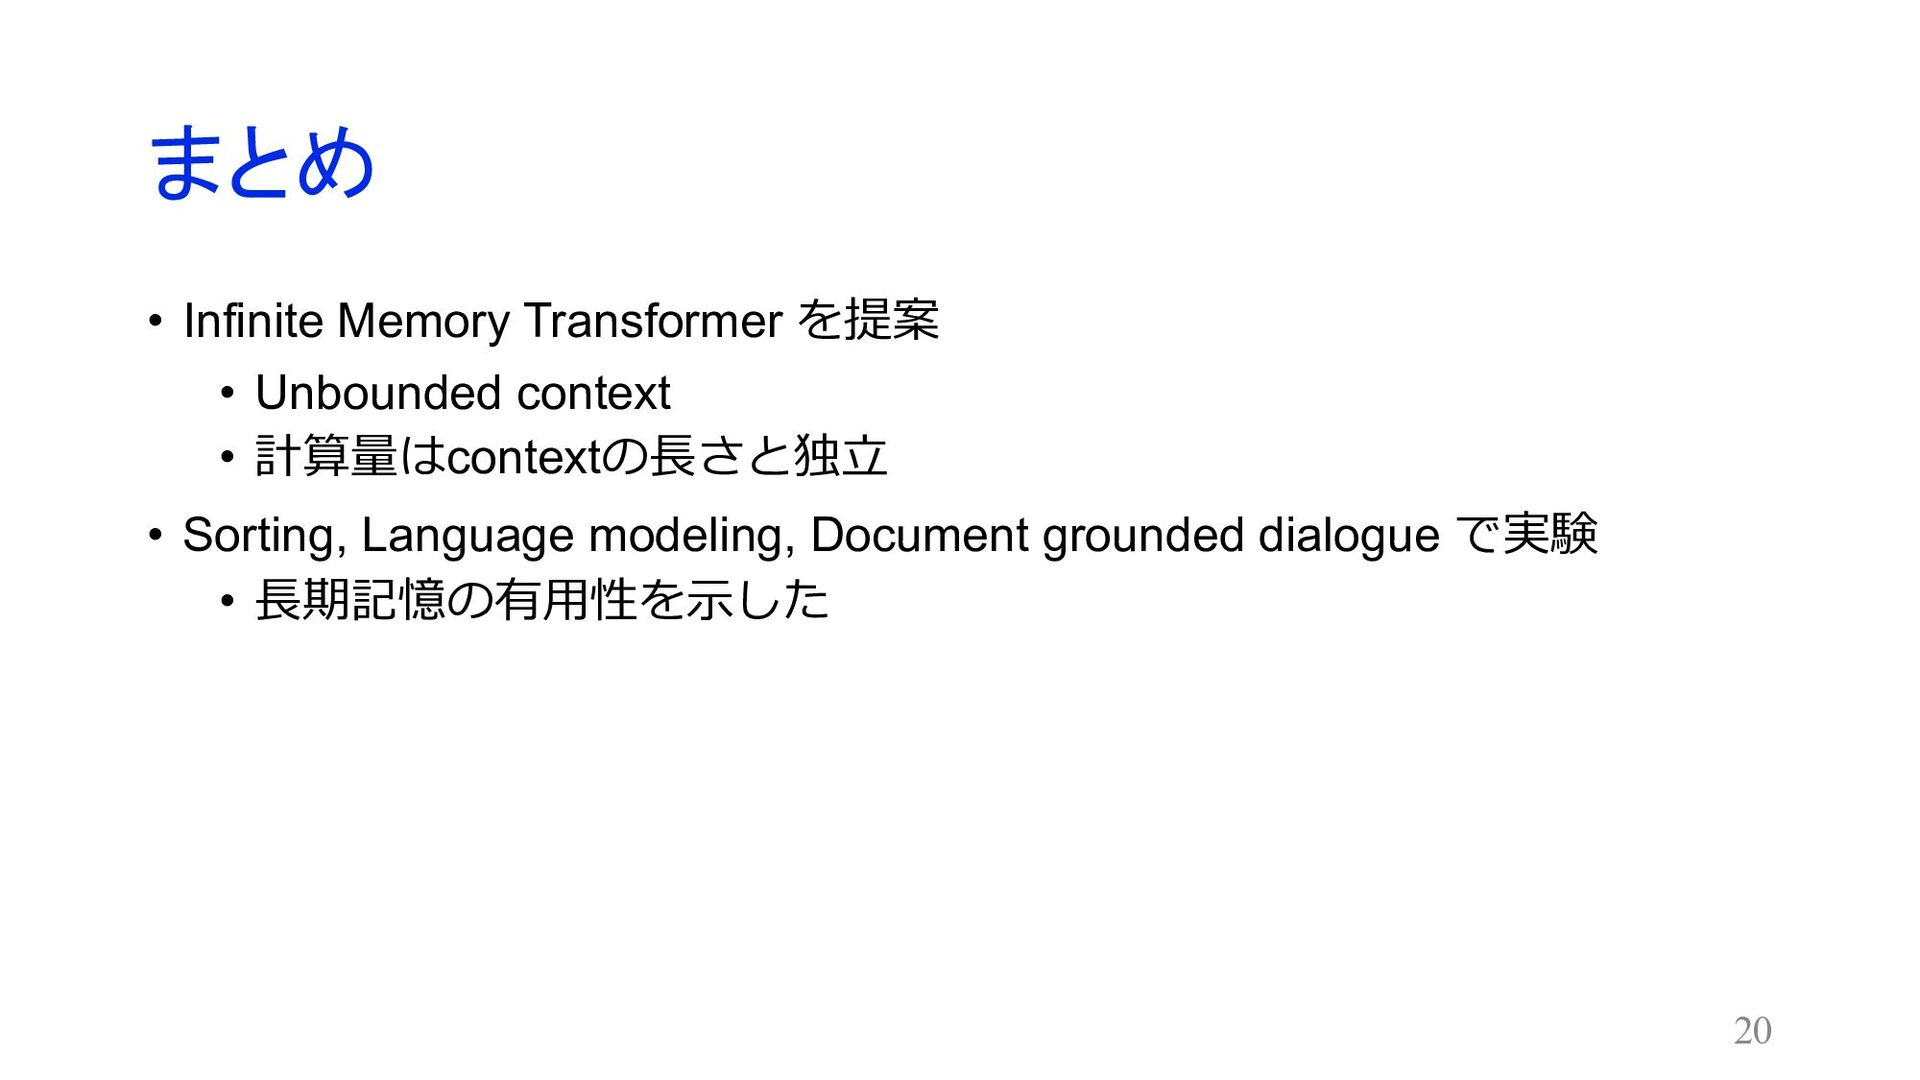
まとめ • Infinite Memory Transformer を提案 • Unbounded context •
計算量はcontextの⻑さと独⽴ • Sorting, Language modeling, Document grounded dialogue で実験 • ⻑期記憶の有⽤性を⽰した 20

 Your Podcast. Everywhere. Effortlessly.


 yuri00
 tattaka
 institutdelelevage
 ontheslope
 junkashihara
 koide3
 sazimai
 wataruuuuu
 kzmssk
 pman0214
 rikkabotan7
 ianozsvald
 ivargrimstad
 reverentgeek
 ks91
 destraynor
 schroneko
 keithpitt
 szymonslowik
 lfama
 baasie
 marketingsoph
 tenderlove