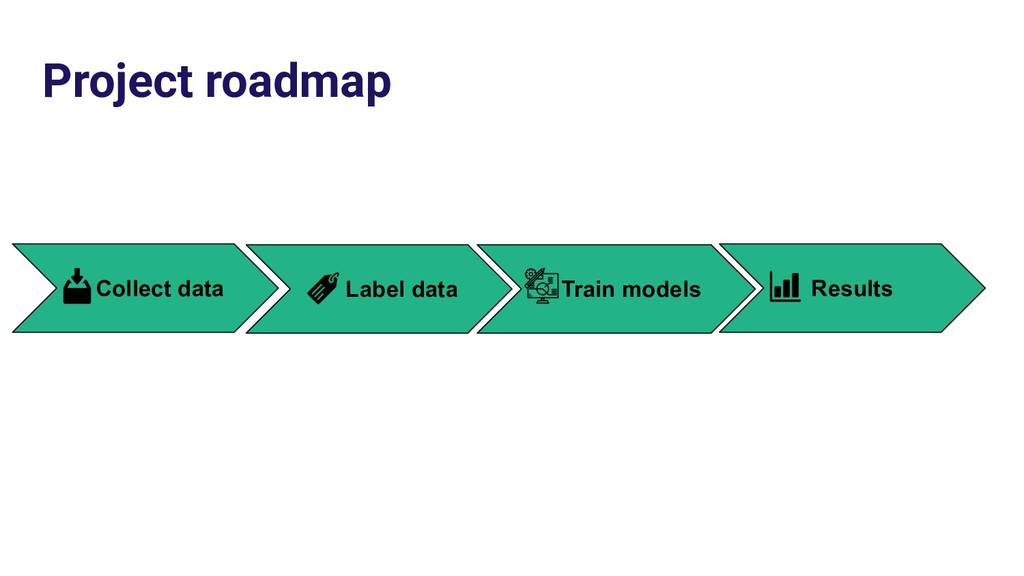
· STOCKHOLM · STUTTGART · TAMPERE 1. Status quo of NLP 2. Blood, sweat and tears behind data labeling 3. (Language) model zoo 4. Where do we go from here? What you can expect from this talk:
and hate speech in Romania last year [2018]” according to the “Annual report on the intolerant and hate speech in Romania – 2018” released on June 13th by ActiveWatch. @alucardna
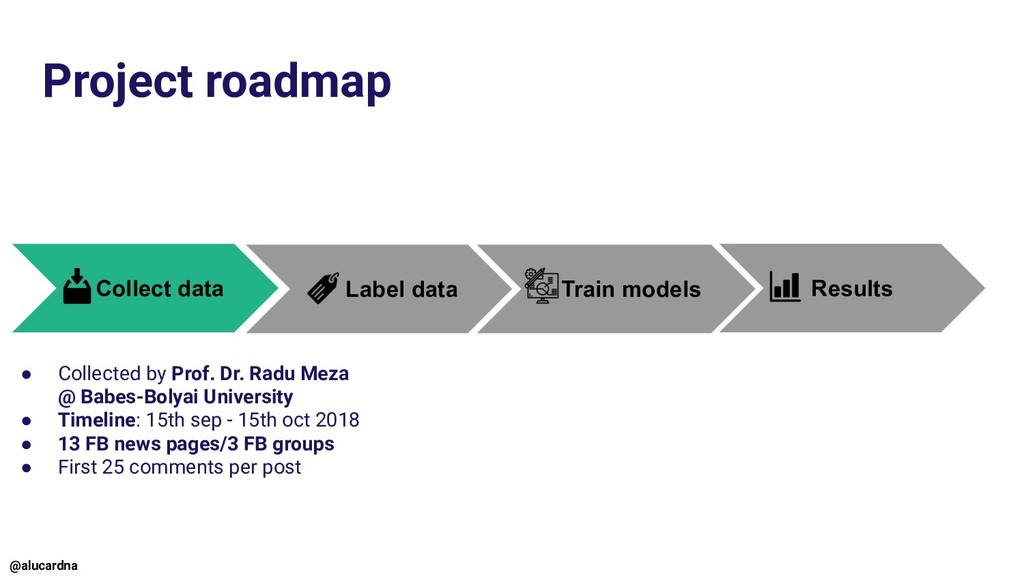
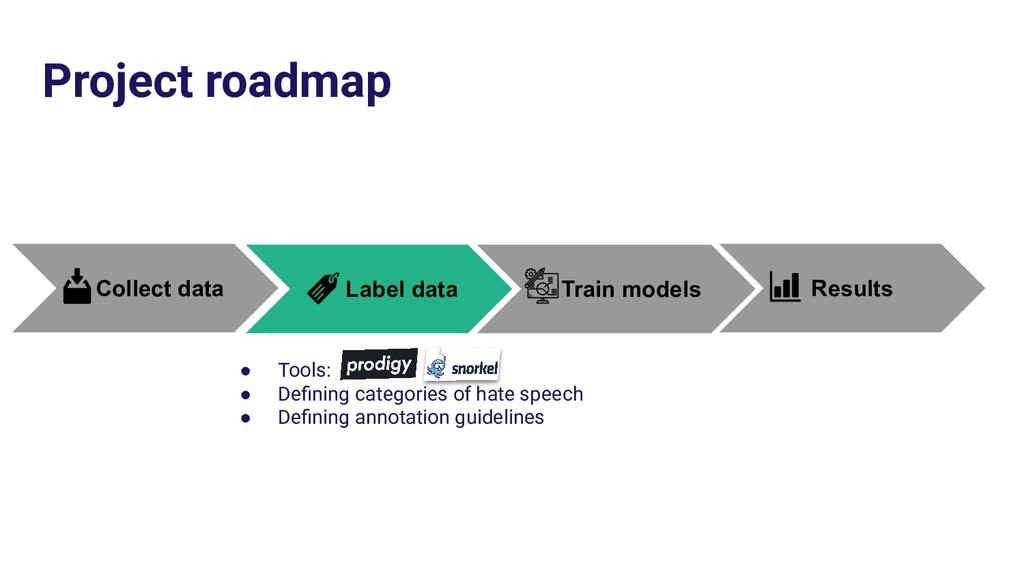
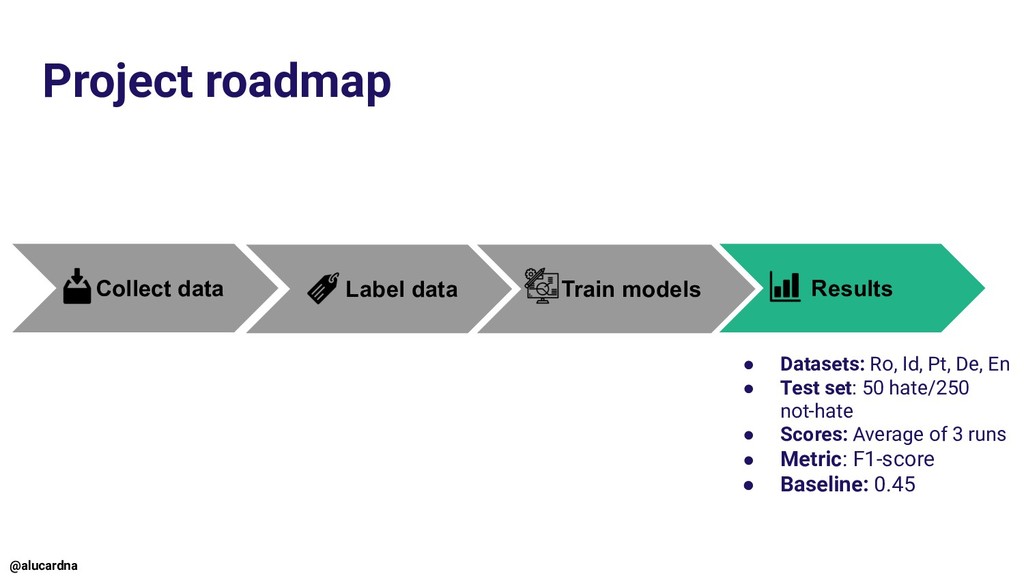
Meza @ Babes-Bolyai University • Timeline: 15th sep - 15th oct 2018 • 13 FB news pages/3 FB groups • First 25 comments per post Label data Train models Results @alucardna
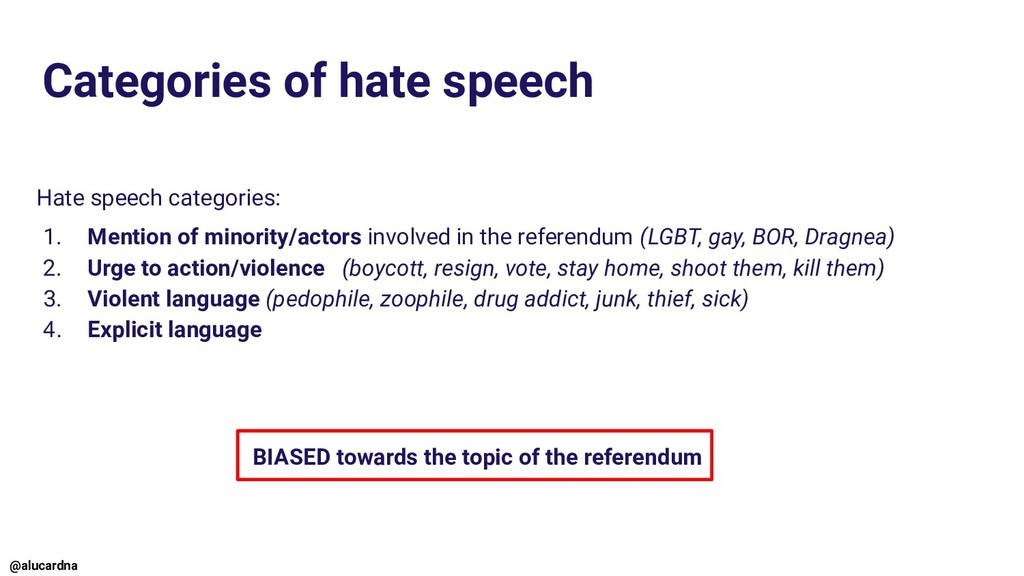
minority/actors involved in the referendum (LGBT, gay, BOR, Dragnea) 2. Urge to action/violence (boycott, resign, vote, stay home, shoot them, kill them) 3. Violent language (pedophile, zoophile, drug addict, junk, thief, sick) 4. Explicit language BIASED towards the topic of the referendum @alucardna
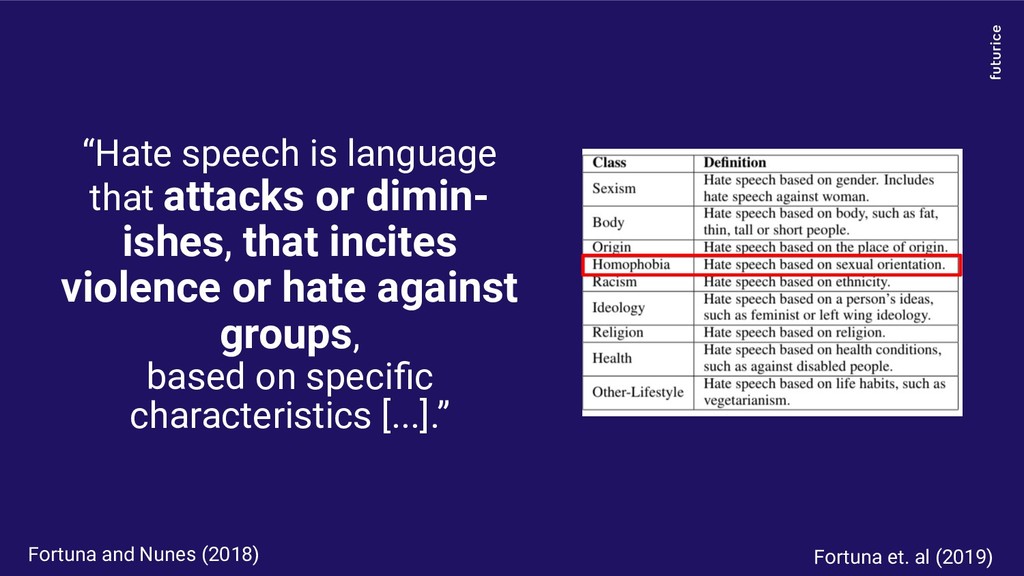
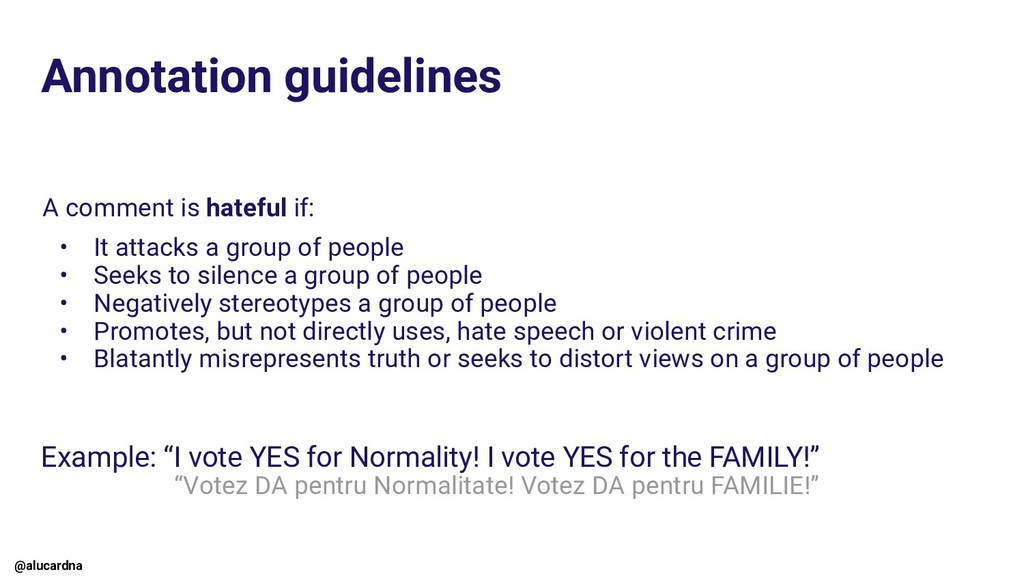
a group of people • Seeks to silence a group of people • Negatively stereotypes a group of people • Promotes, but not directly uses, hate speech or violent crime • Blatantly misrepresents truth or seeks to distort views on a group of people @alucardna Example: “I vote YES for Normality! I vote YES for the FAMILY!” “Votez DA pentru Normalitate! Votez DA pentru FAMILIE!”
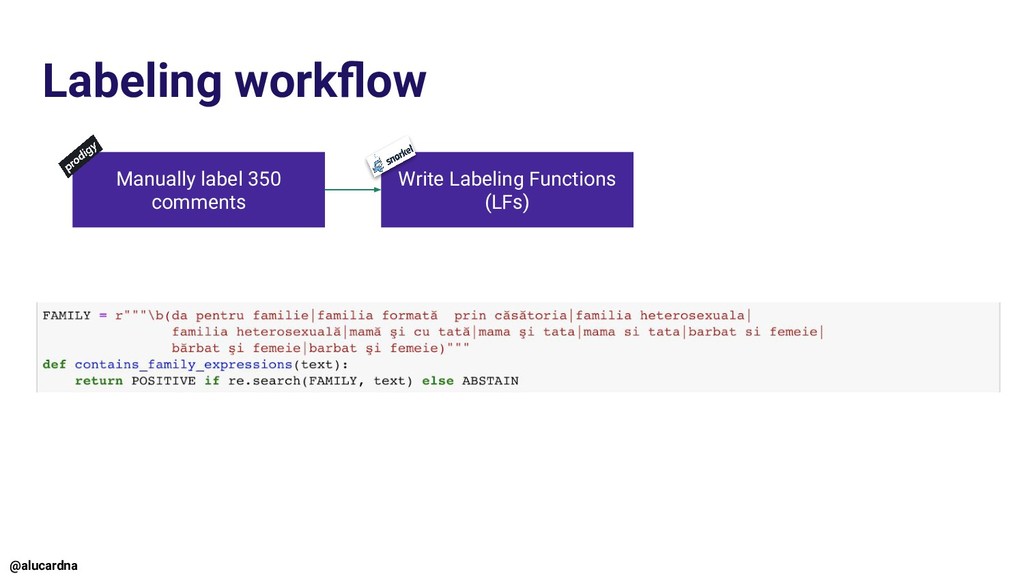
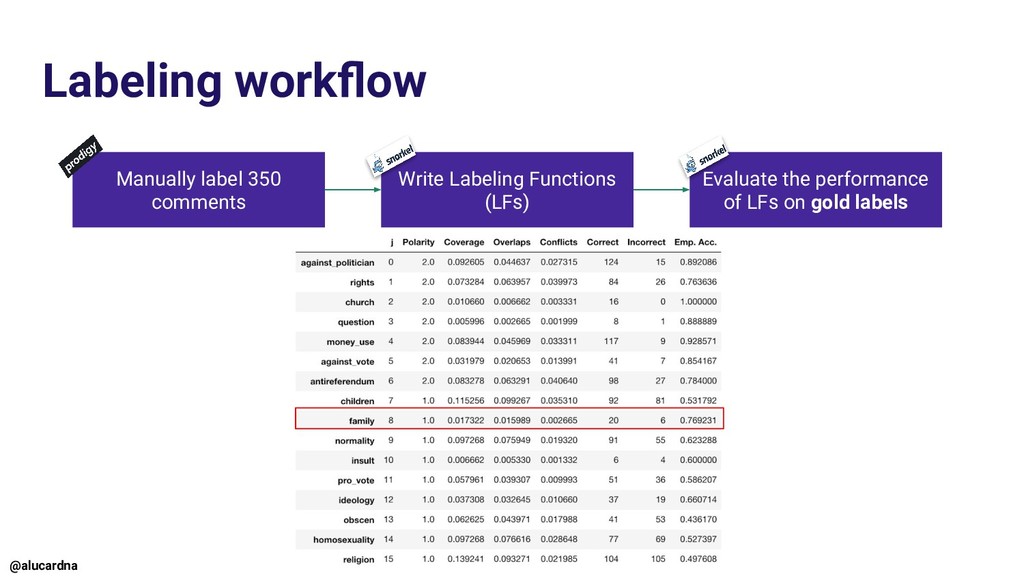
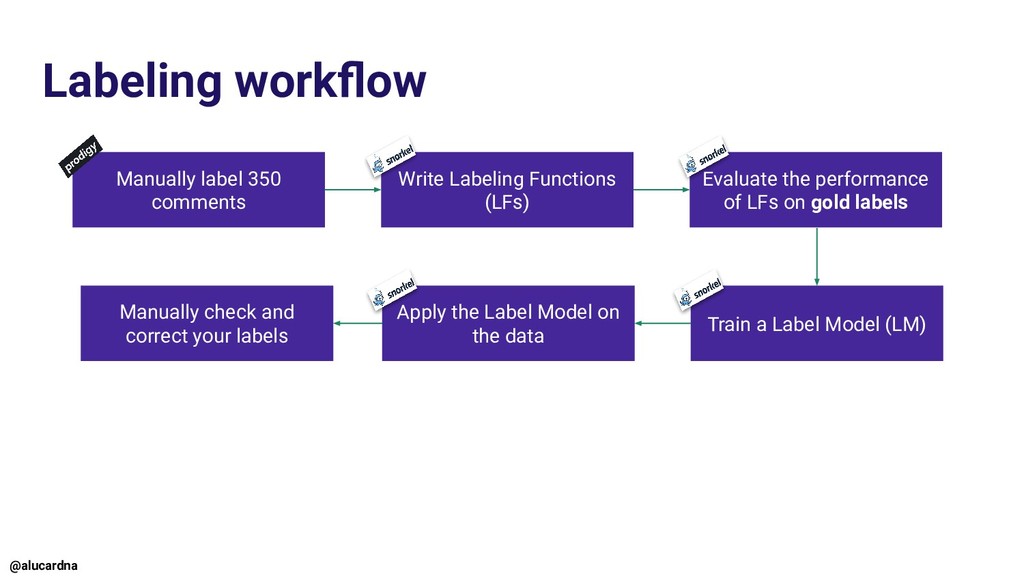
Evaluate the performance of LFs on gold labels Train a Label Model (LM) Apply the Label Model on the data Manually check and correct your labels @alucardna
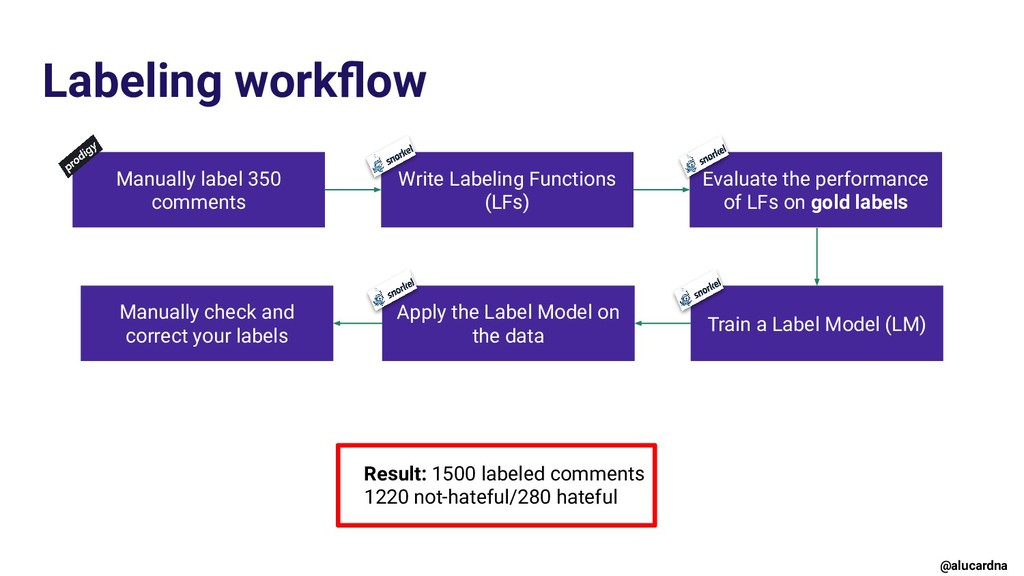
Evaluate the performance of LFs on gold labels @alucardna Train a Label Model (LM) Apply the Label Model on the data Manually check and correct your labels Result: 1500 labeled comments 1220 not-hateful/280 hateful
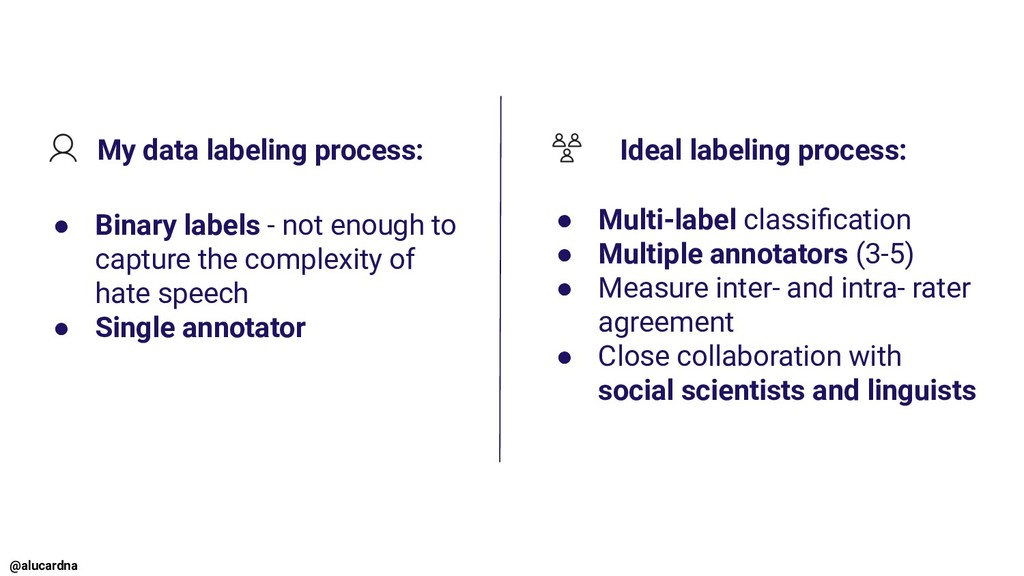
to capture the complexity of hate speech • Single annotator Ideal labeling process: • Multi-label classification • Multiple annotators (3-5) • Measure inter- and intra- rater agreement • Close collaboration with social scientists and linguists @alucardna
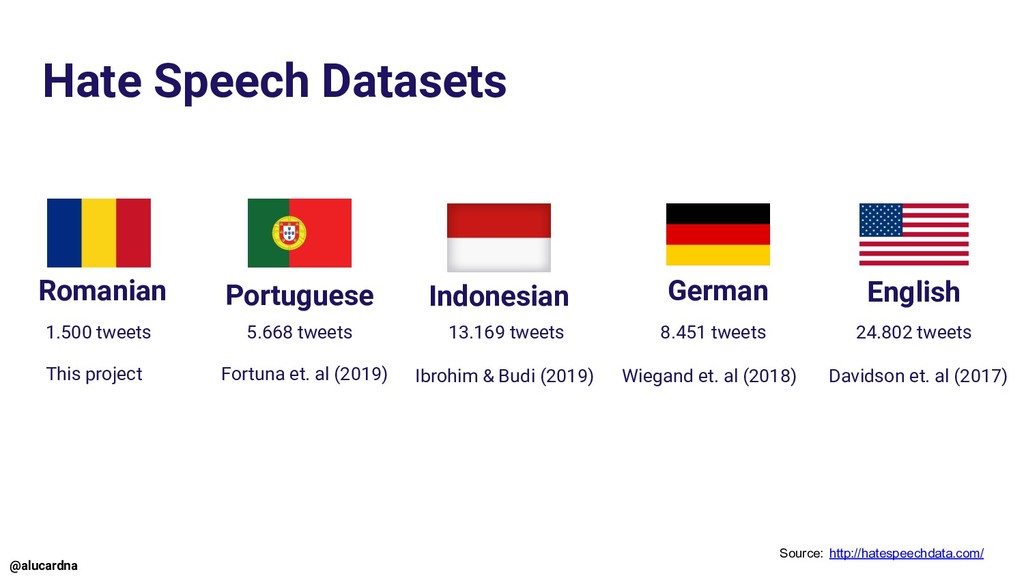
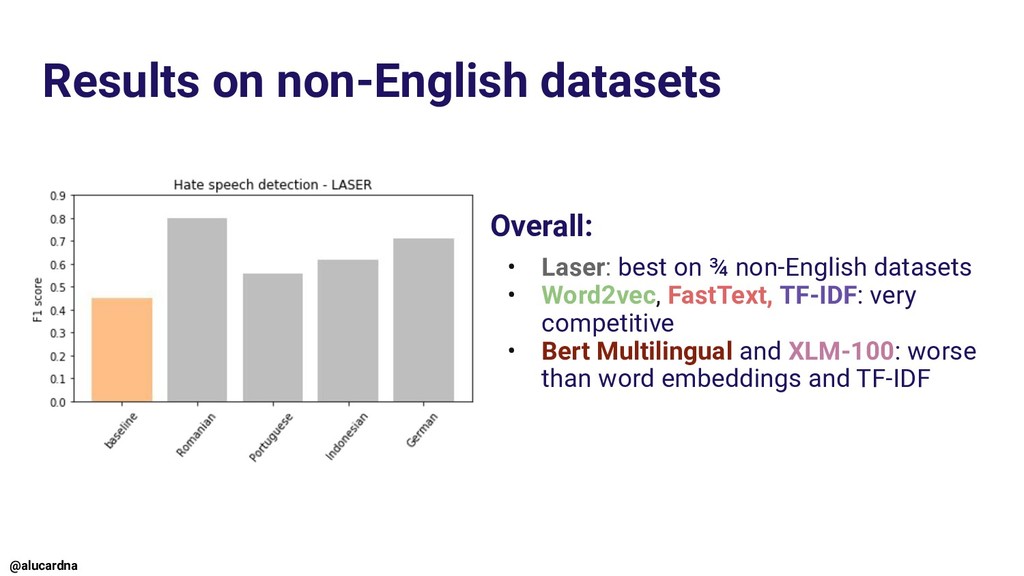
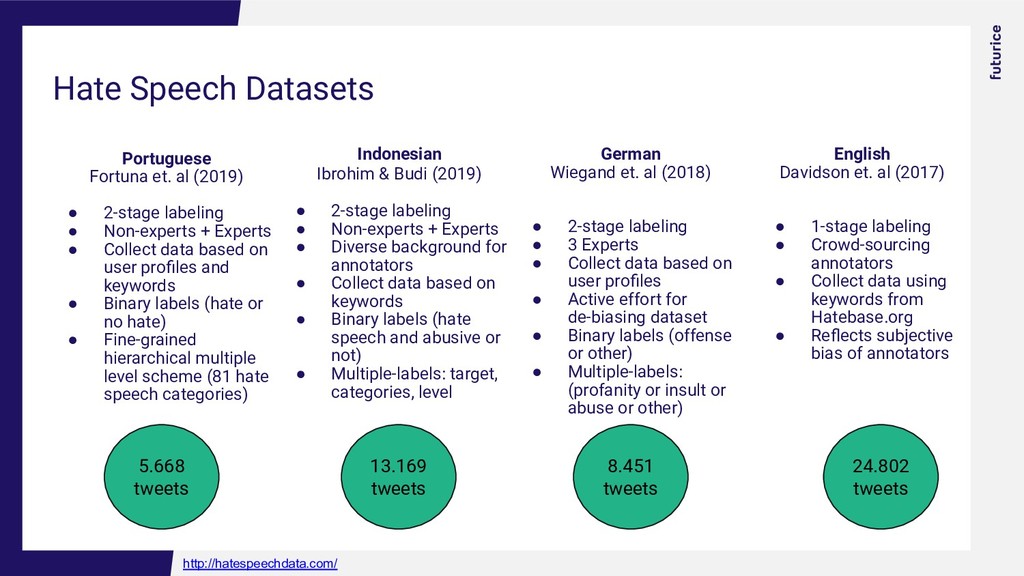
13.169 tweets 8.451 tweets 24.802 tweets German Romanian 1.500 tweets @alucardna Fortuna et. al (2019) Ibrohim & Budi (2019) Wiegand et. al (2018) Davidson et. al (2017) This project
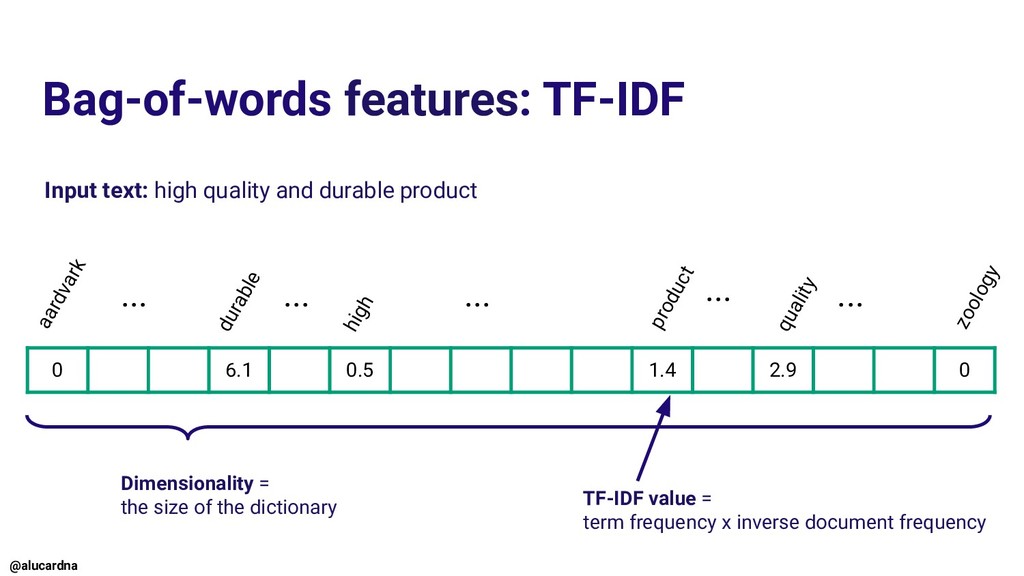
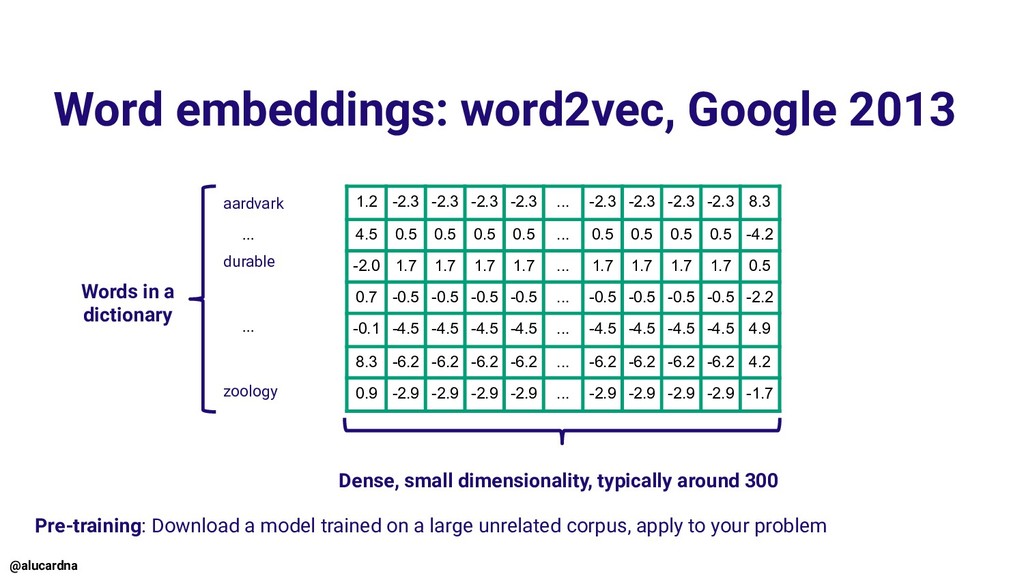
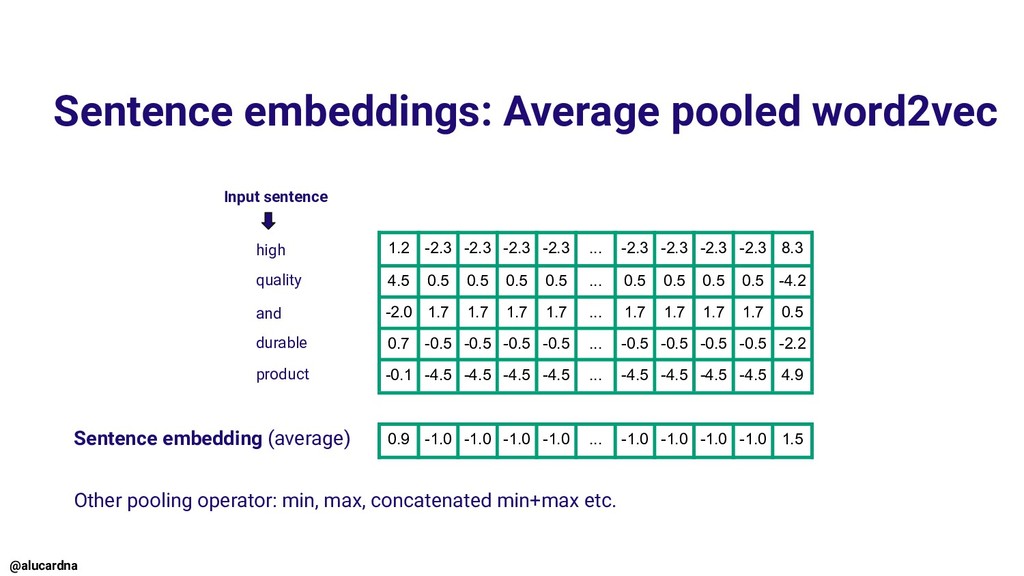
and durable product aardvark durable quality zoology high product ... ... ... ... ... TF-IDF value = term frequency x inverse document frequency Dimensionality = the size of the dictionary Bag-of-words features: TF-IDF @alucardna
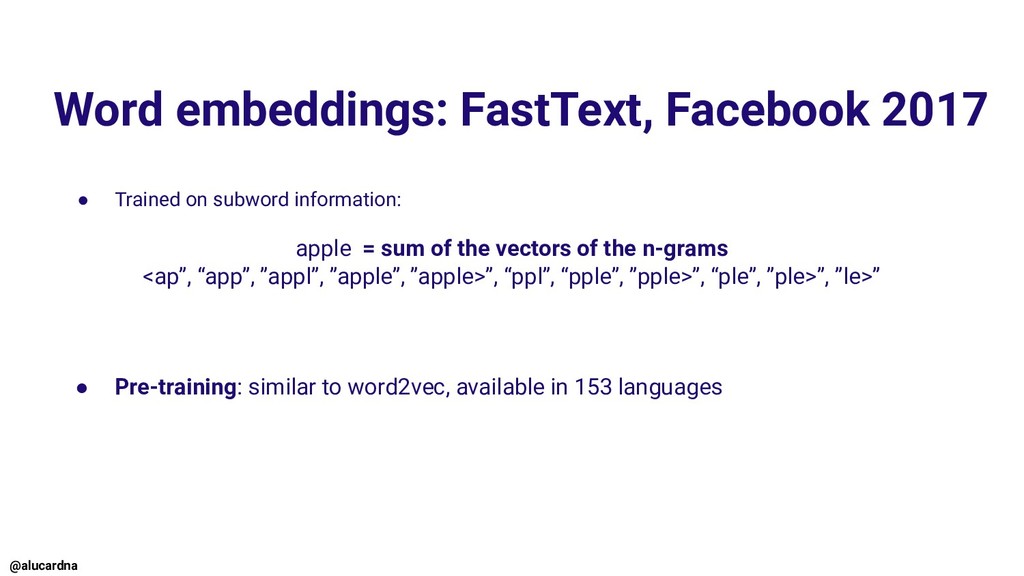
apple = sum of the vectors of the n-grams <ap”, “app”, ”appl”, ”apple”, ”apple>”, “ppl”, “pple”, ”pple>”, “ple”, ”ple>”, ”le>” • Pre-training: similar to word2vec, available in 153 languages @alucardna
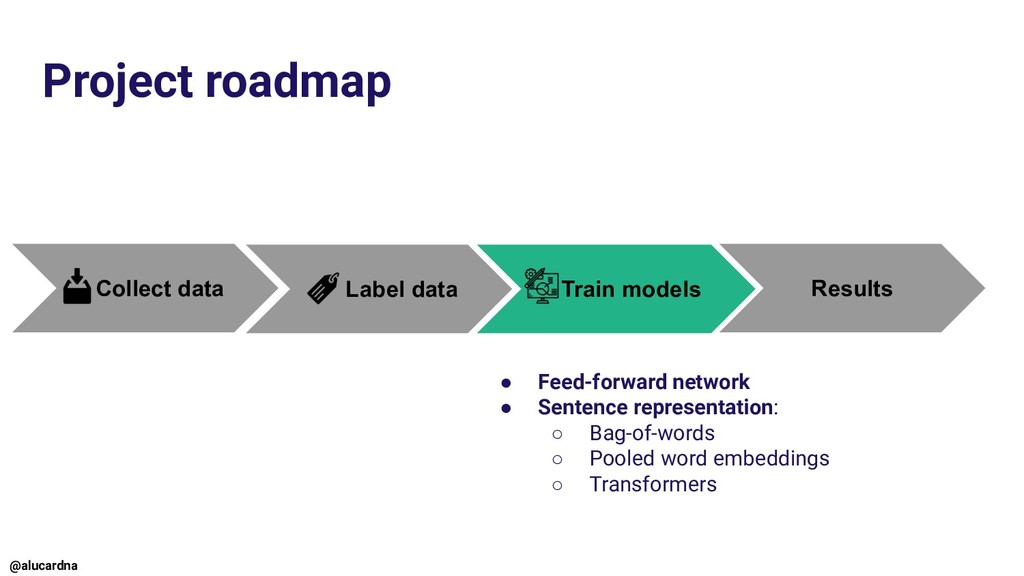
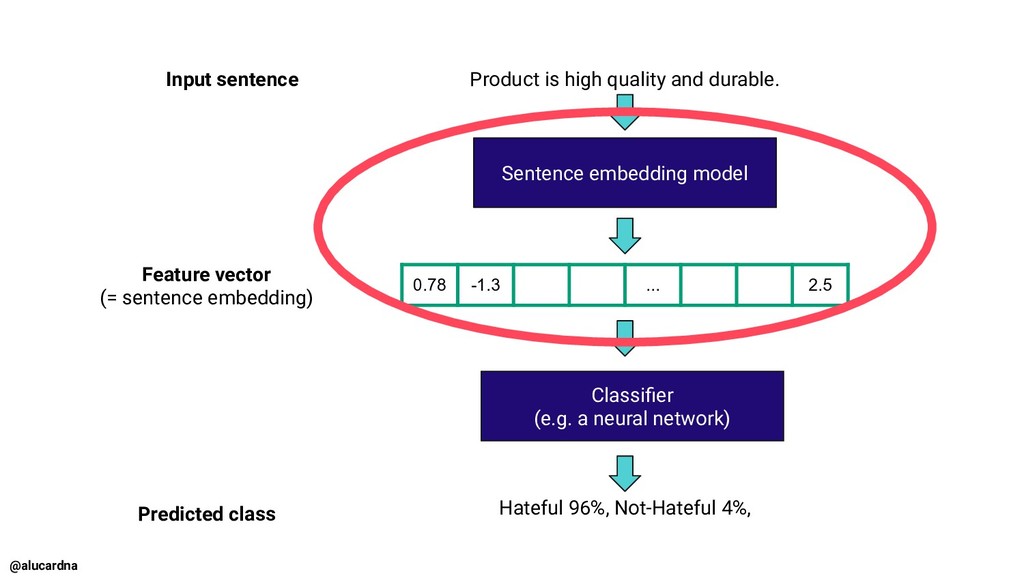
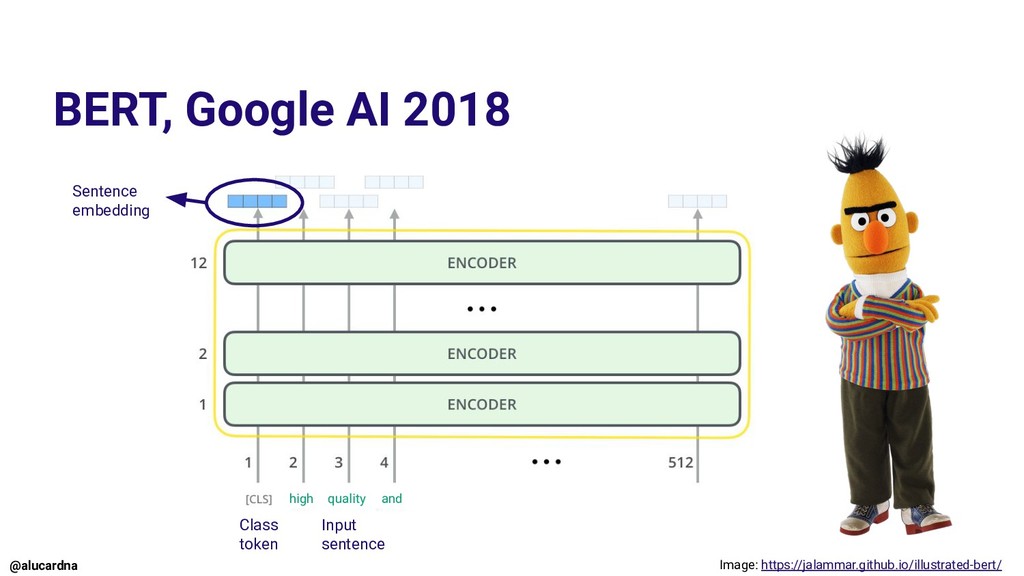
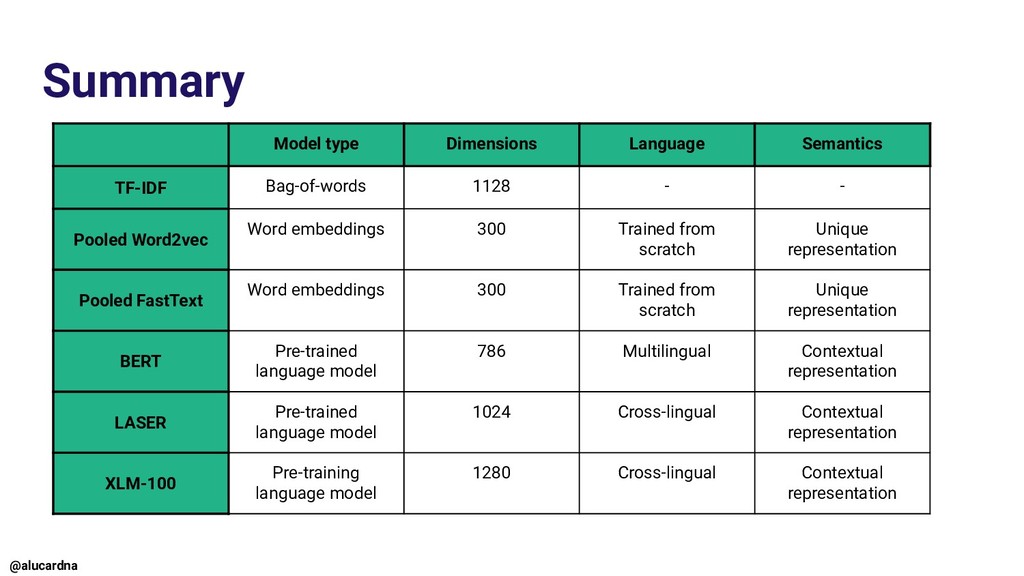
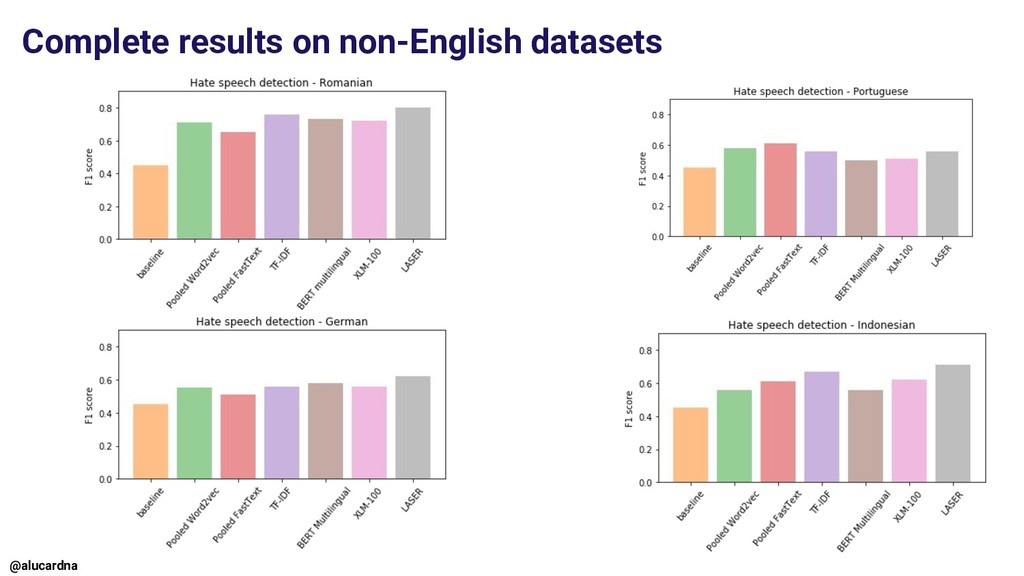
- Pooled Word2vec Word embeddings 300 Trained from scratch Unique representation Pooled FastText Word embeddings 300 Trained from scratch Unique representation BERT Pre-trained language model 786 Multilingual Contextual representation LASER Pre-trained language model 1024 Cross-lingual Contextual representation XLM-100 Pre-training language model 1280 Cross-lingual Contextual representation @alucardna
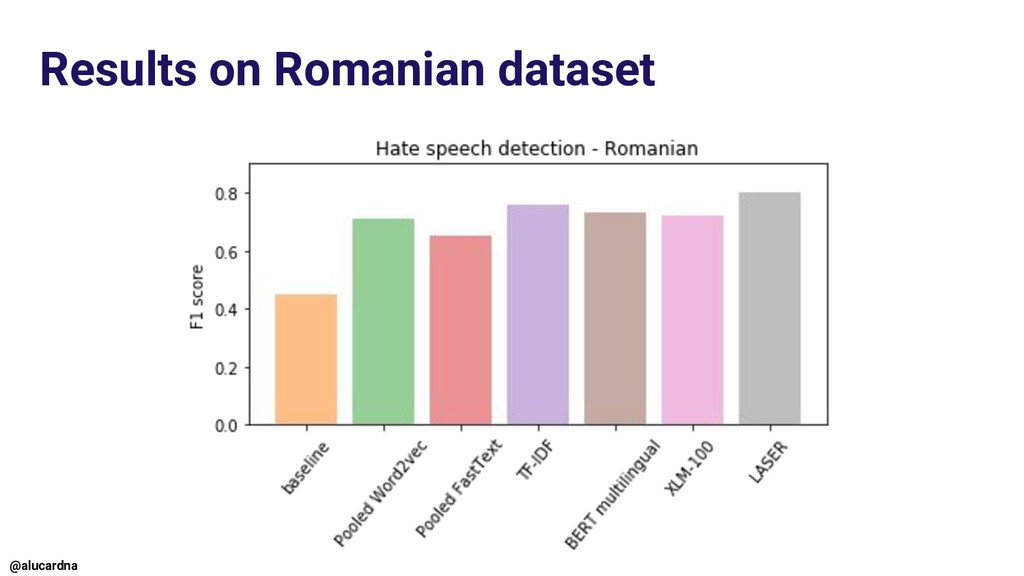
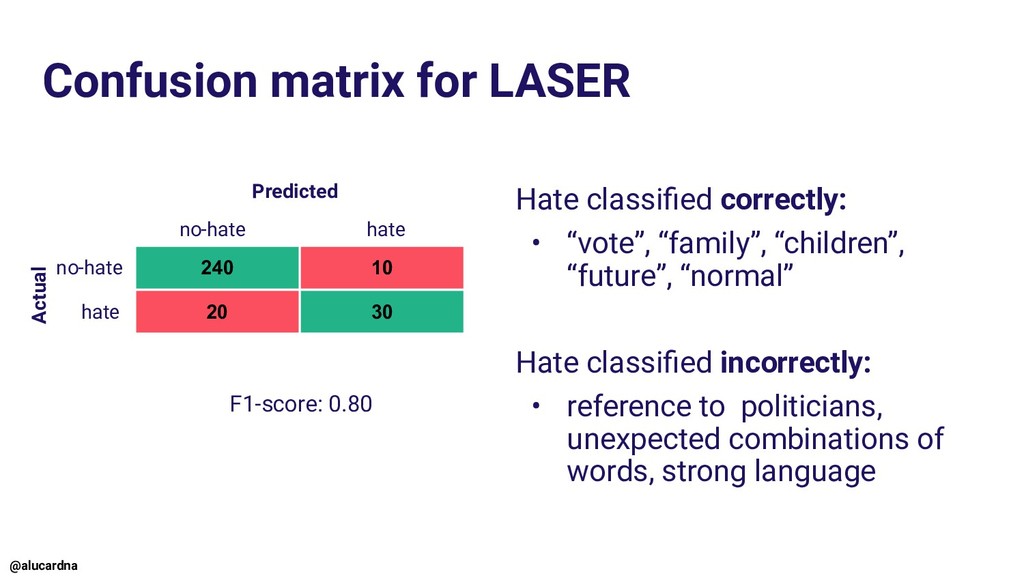
“children”, “future”, “normal” Hate classified incorrectly: • reference to politicians, unexpected combinations of words, strong language 240 10 20 30 Predicted Actual no-hate hate hate no-hate F1-score: 0.80 @alucardna
Hanna Orsolya Vincze, and ANDREEA MOGOȘ. "Targets of Online Hate Speech in Context. A Comparative Digital Social Science Analysis of Comments on Public Facebook Pages from Romania and Hungary." East European Journal of Society and Politics (2018): 26. Mikolov, Tomas, et al. "Efficient estimation of word representations in vector space." arXiv preprint arXiv:1301.3781 (2013). Bojanowski, Piotr, et al. "Enriching word vectors with subword information." Transactions of the Association for Computational Linguistics 5 (2017): 135-146. Devlin, Jacob, et al. "Bert: Pre-training of deep bidirectional transformers for language understanding." arXiv preprint arXiv:1810.04805 (2018). Artetxe, Mikel, and Holger Schwenk. "Massively multilingual sentence embeddings for zero-shot cross-lingual transfer and beyond." arXiv preprint arXiv:1812.10464 (2018). @alucardna
the problem of offensive language." Eleventh international aaai conference on web and social media. 2017. Wiegand, Michael, Melanie Siegel, and Josef Ruppenhofer. "Overview of the germeval 2018 shared task on the identification of offensive language." (2018). Ibrohim, Muhammad Okky, and Indra Budi. "Multi-label Hate Speech and Abusive Language Detection in Indonesian Twitter." Proceedings of the Third Workshop on Abusive Language Online. 2019. Fortuna, Paula, et al. "A Hierarchically-Labeled Portuguese Hate Speech Dataset." Proceedings of the Third Workshop on Abusive Language Online. 2019. How transformers broke NLP leaderboards: https://hackingsemantics.xyz/2019/leaderboards/?utm_campaign=NLP%20News&utm_medium=email&utm_source=Revue%20newsletter Current Issues with Transfer Learning in NLP: https://mohammadkhalifa.github.io/2019/09/06/Issues-With-Transfer-Learning-in-NLP/ The #BenderRule: On naming the languages we study and why it matters: https://thegradient.pub/the-benderrule-on-naming-the-languages-we-study-and-why-it-matters/ The Digital Language Divide: http://labs.theguardian.com/digital-language-divide/ @alucardna
labeling • Non-experts + Experts • Collect data based on user profiles and keywords • Binary labels (hate or no hate) • Fine-grained hierarchical multiple level scheme (81 hate speech categories) Indonesian Ibrohim & Budi (2019) • 2-stage labeling • Non-experts + Experts • Diverse background for annotators • Collect data based on keywords • Binary labels (hate speech and abusive or not) • Multiple-labels: target, categories, level German Wiegand et. al (2018) • 2-stage labeling • 3 Experts • Collect data based on user profiles • Active effort for de-biasing dataset • Binary labels (offense or other) • Multiple-labels: (profanity or insult or abuse or other) English Davidson et. al (2017) • 1-stage labeling • Crowd-sourcing annotators • Collect data using keywords from Hatebase.org • Reflects subjective bias of annotators 5.668 tweets 13.169 tweets 8.451 tweets 24.802 tweets http://hatespeechdata.com/
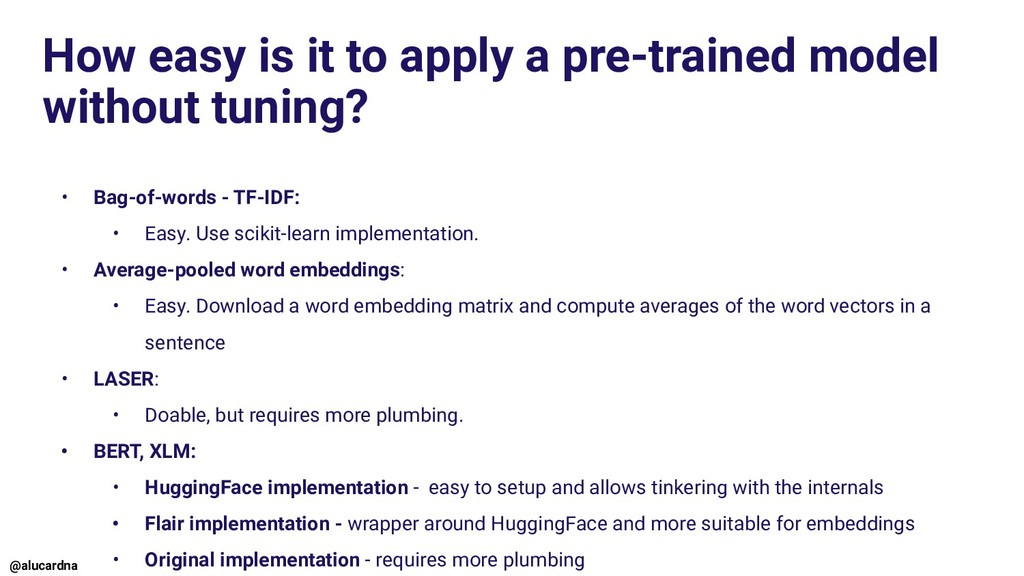
tuning? • Bag-of-words - TF-IDF: • Easy. Use scikit-learn implementation. • Average-pooled word embeddings: • Easy. Download a word embedding matrix and compute averages of the word vectors in a sentence • LASER: • Doable, but requires more plumbing. • BERT, XLM: • HuggingFace implementation - easy to setup and allows tinkering with the internals • Flair implementation - wrapper around HuggingFace and more suitable for embeddings • Original implementation - requires more plumbing @alucardna
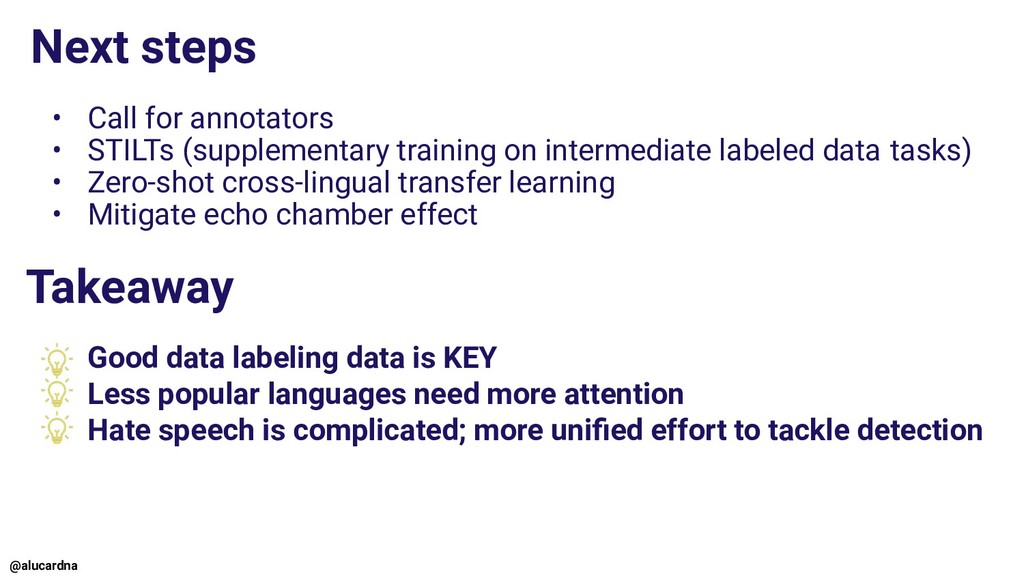
on intermediate labeled data tasks) • Zero-shot cross-lingual transfer learning • Mitigate echo chamber effect @alucardna Takeaway Good data labeling data is KEY Less popular languages need more attention Hate speech is complicated; more unified effort to tackle detection


 kintotechdev
 sanghyuk
 mrmtsu
 oracle4engineer
 yohyamasaki
 kurazuuuuuu
 kaidouji85
 sansantech
 yutanonaka
 x5gtrn
 shunsock
 andyhume
 jonoalderson
 madoxten
 inesmontani
 caitiem20
 oripsolob
 axbom
 cassininazir
 uxyall
 katarinadahlin
 mza
 vanstee