Share
Embed

Transcript
136 slides
-
Code Review What is a code review? Goals of a
code review. 17 things to check during a review. How well do we do as reviewers? Beyond the code. -
a process that takes as input original source code and
outputs accepted source code “ ” Modern code Review Moritz Beller, Elmar Juergens -
Modern code Review “ ” Moritz Beller, Elmar Juergens the
original source code is a work that stemmed solely from the author, so that everybody is satisfied with the result whereas in the accepted source code the author incorporated the reviewers’ suggestions -
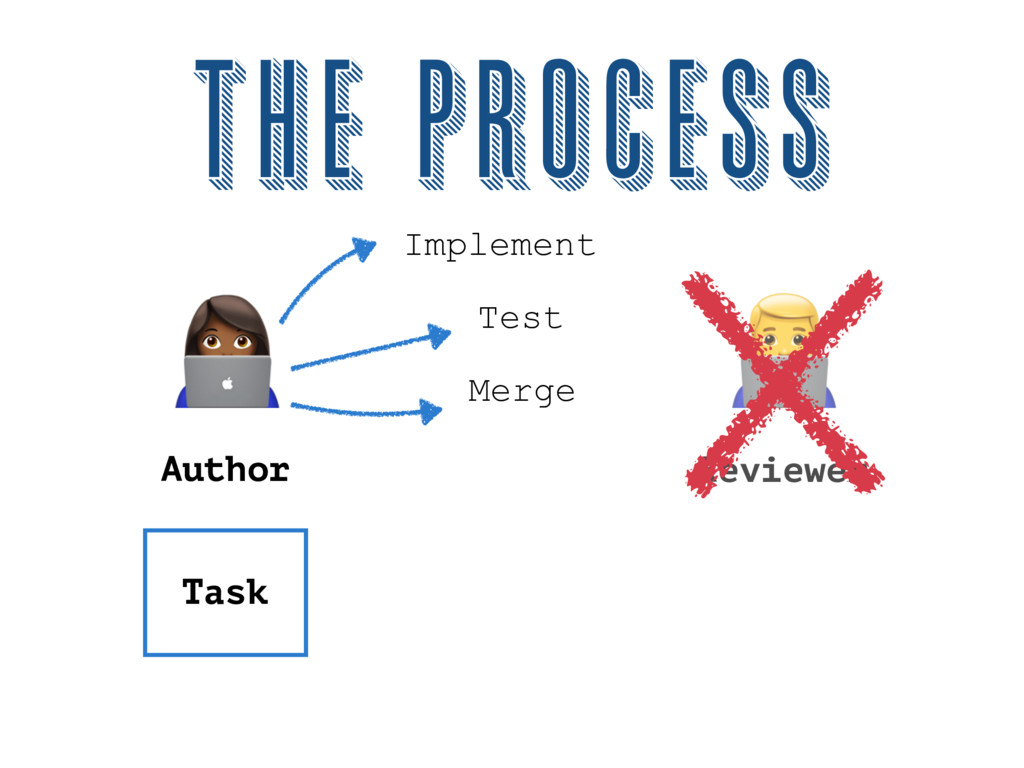
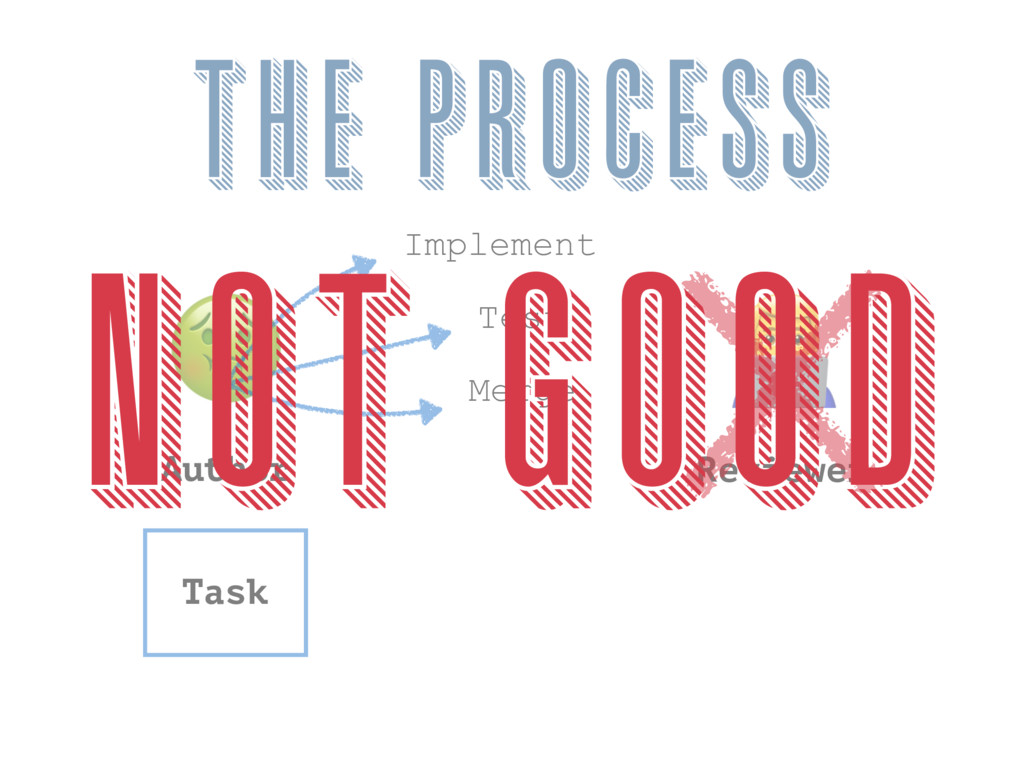
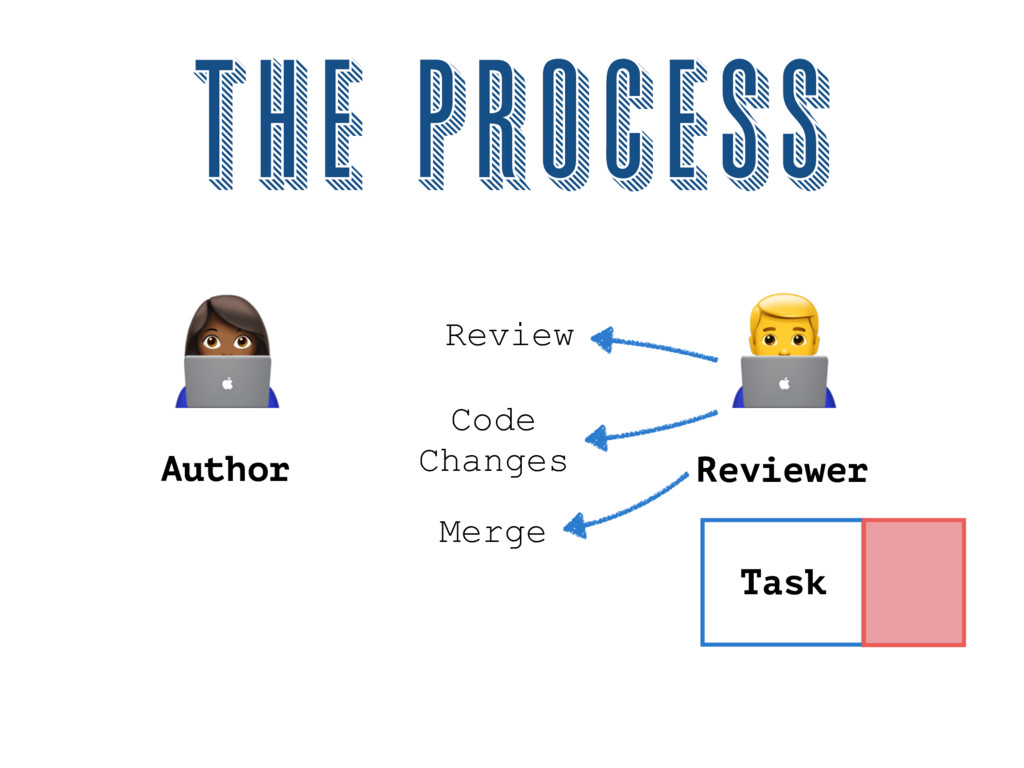
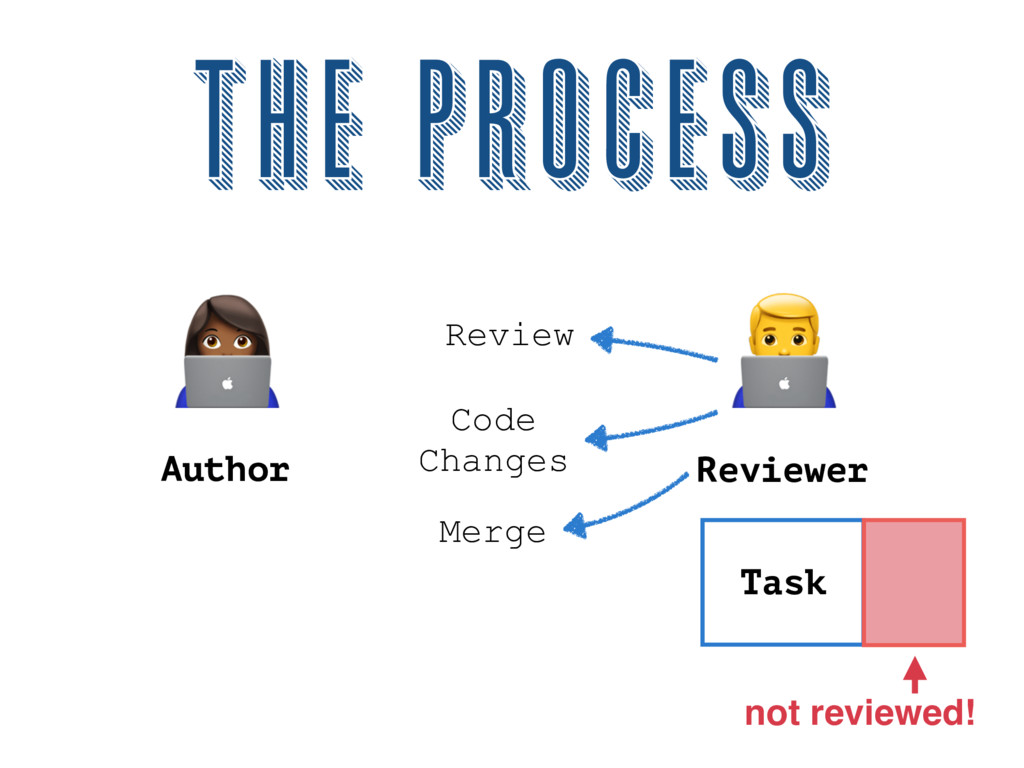
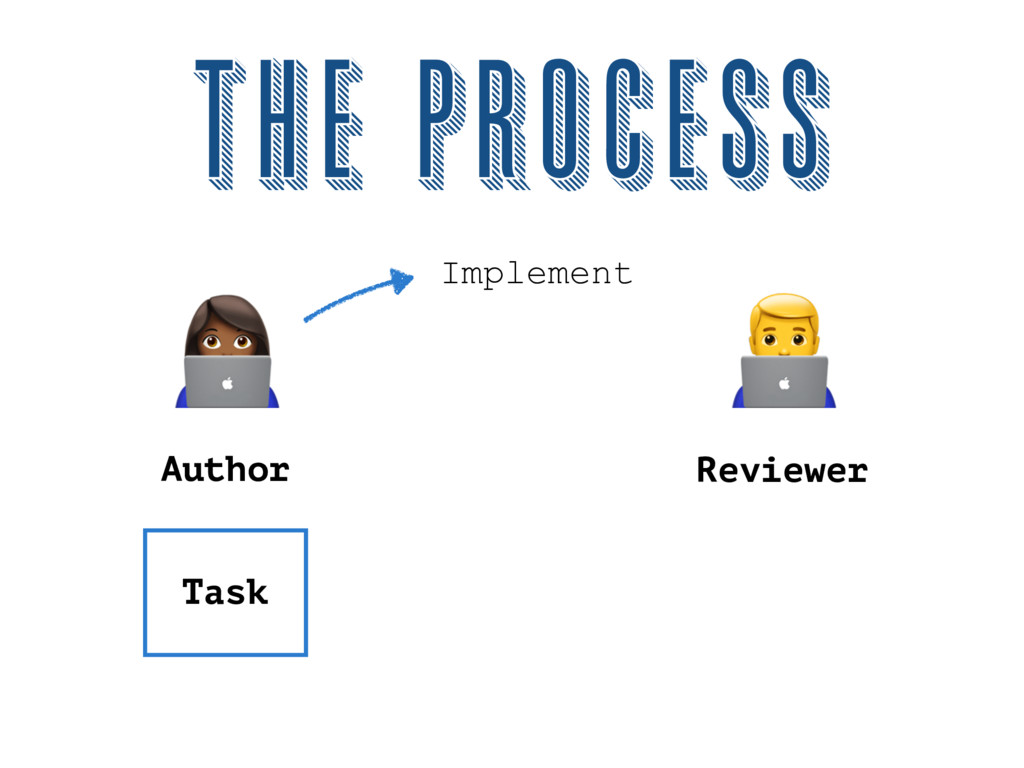
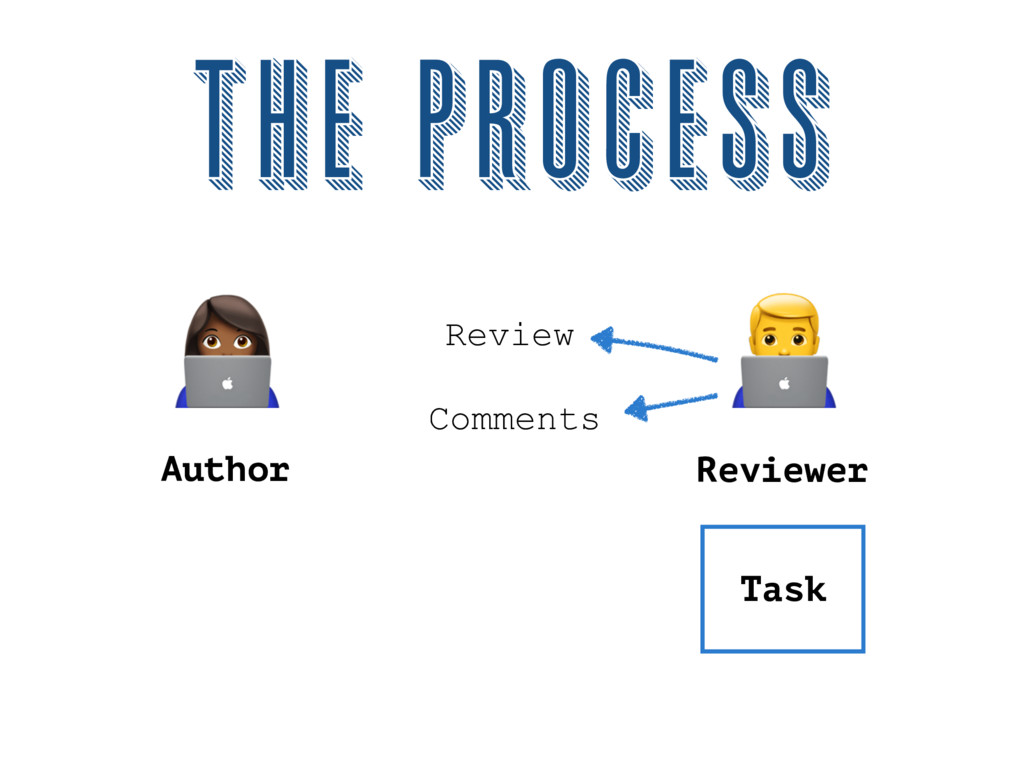
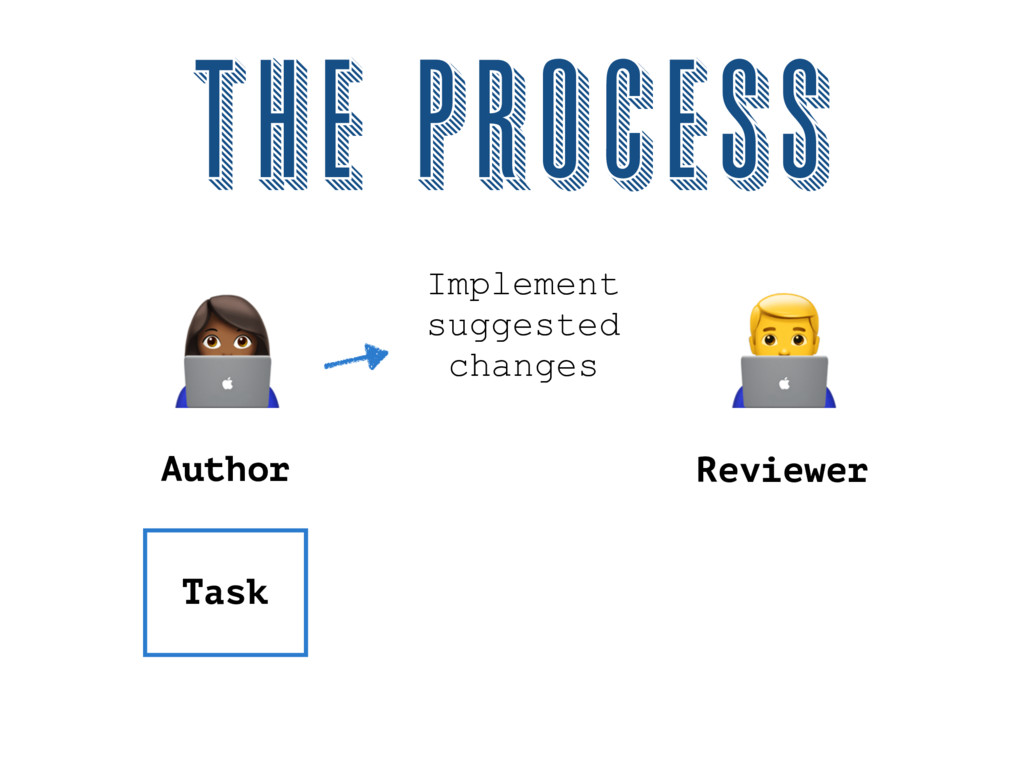
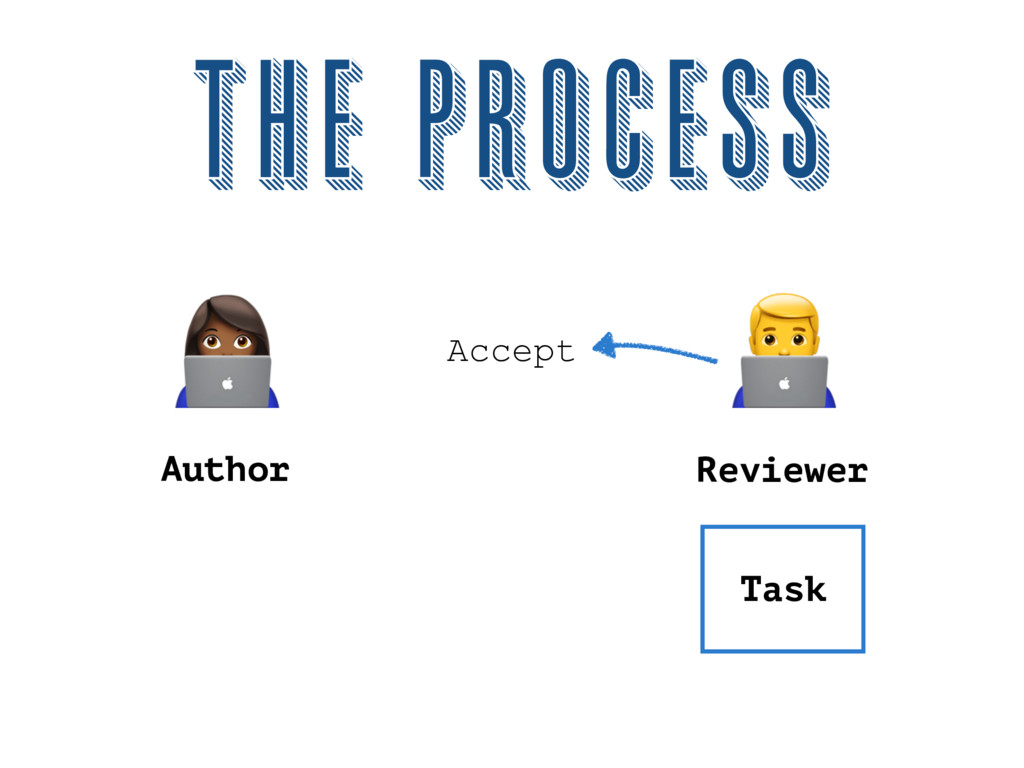
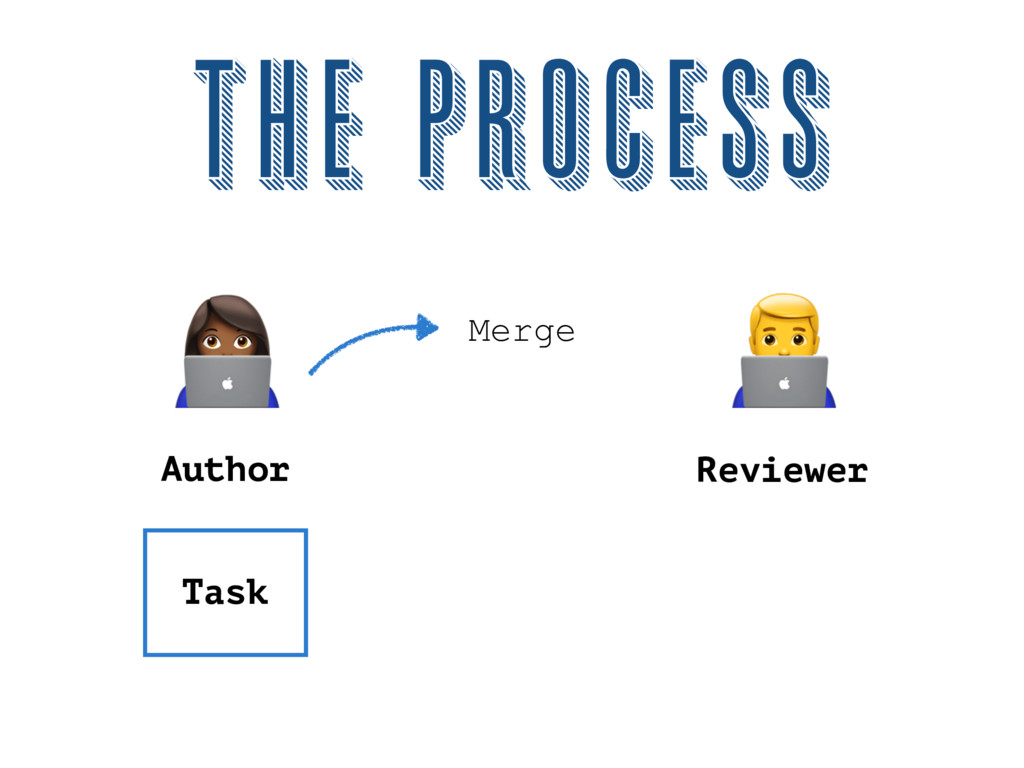
the process Author ! " Reviewer Task Review Code Changes
Merge not reviewed! -
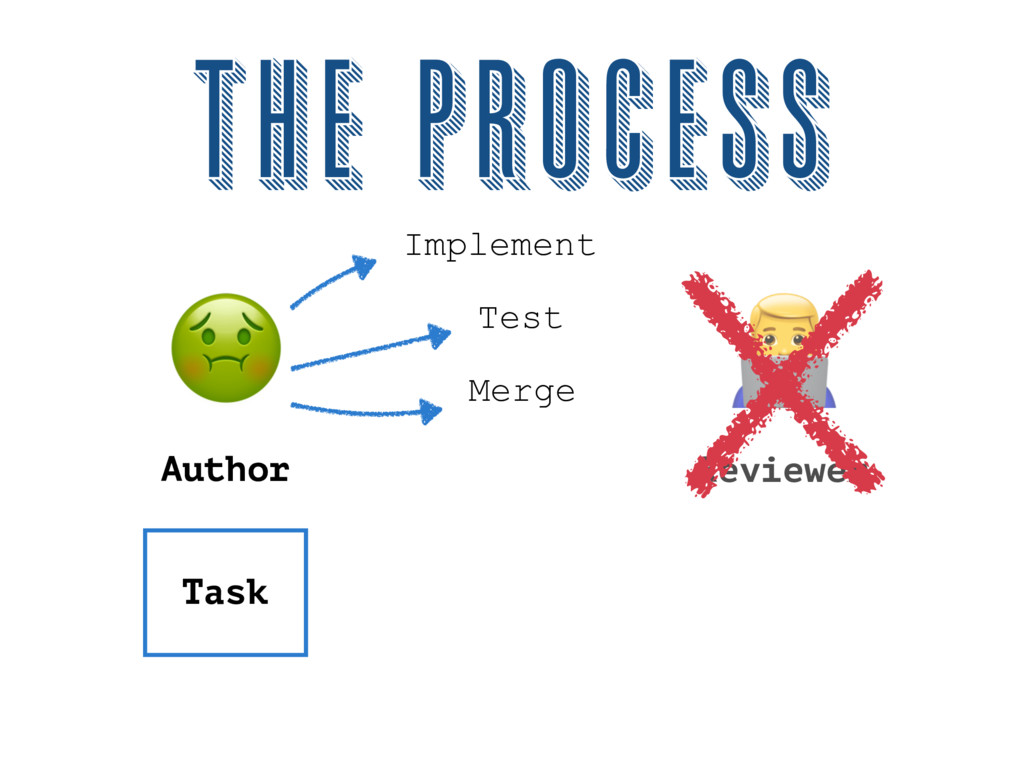
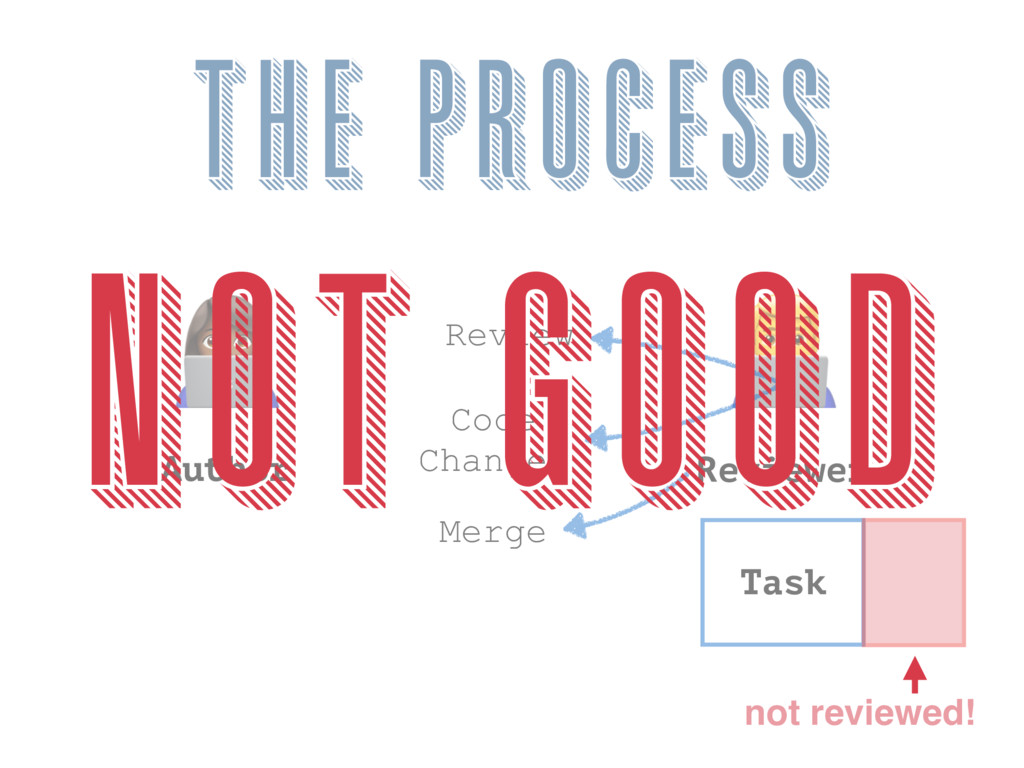
the process Author ! " Reviewer Task Review Code Changes
Merge not reviewed! NOT GOOD -
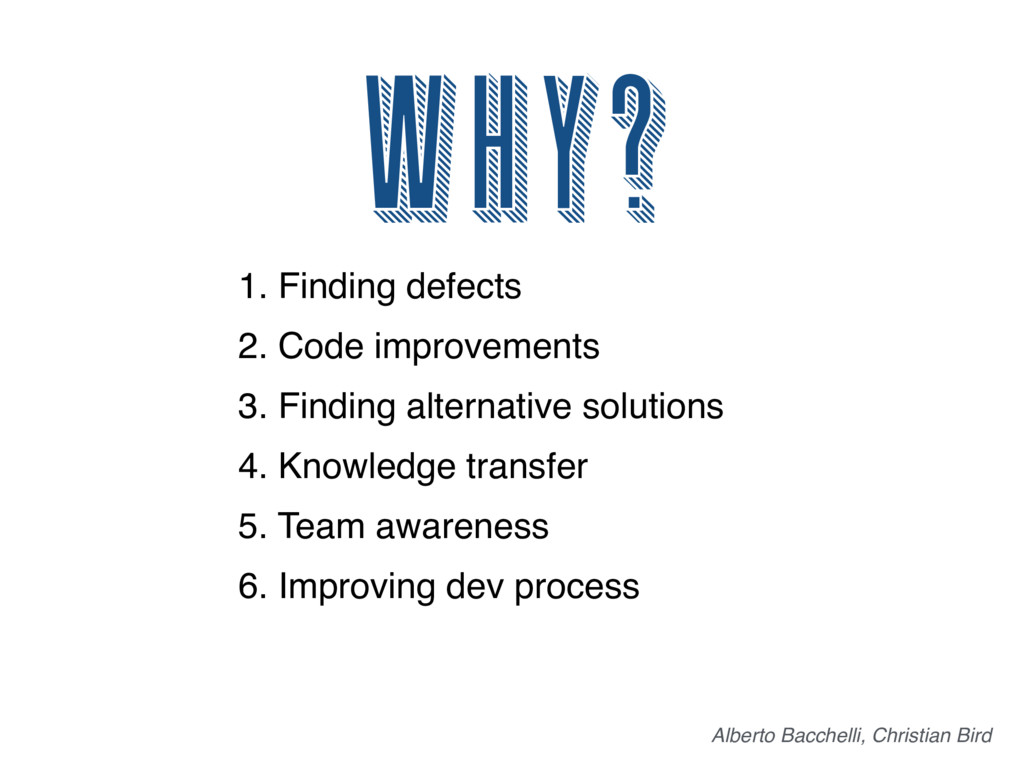
Why? 1. Finding defects 2. Code improvements 3. Finding alternative
solutions 4. Knowledge transfer 5. Team awareness 6. Improving dev process Alberto Bacchelli, Christian Bird -
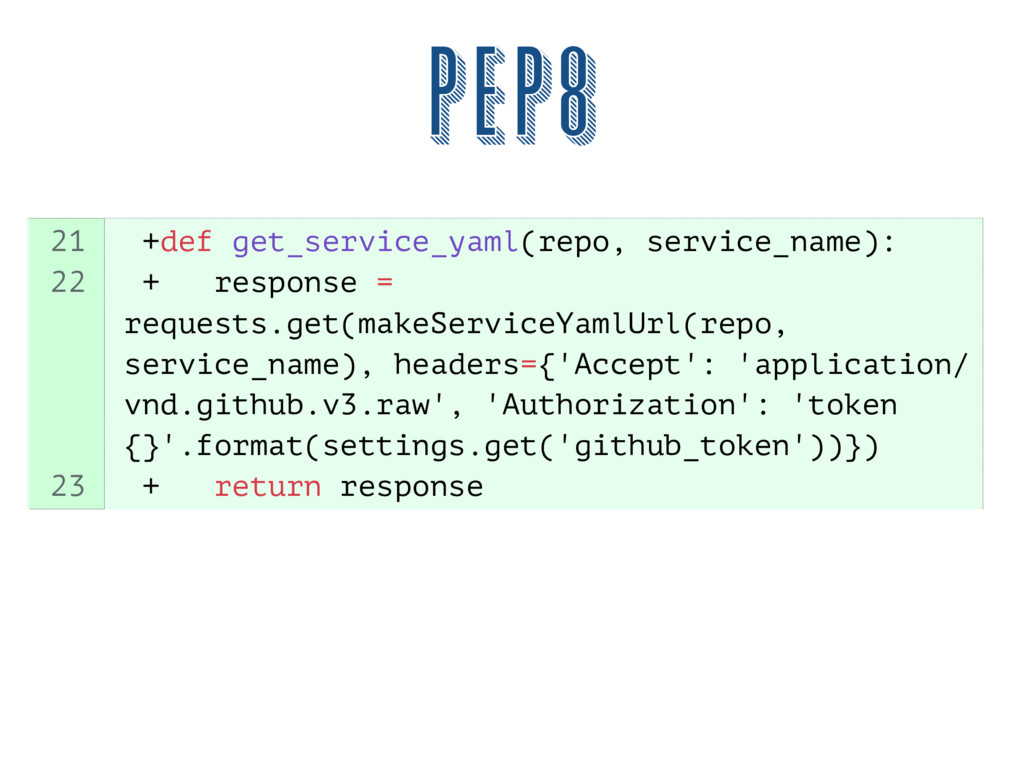
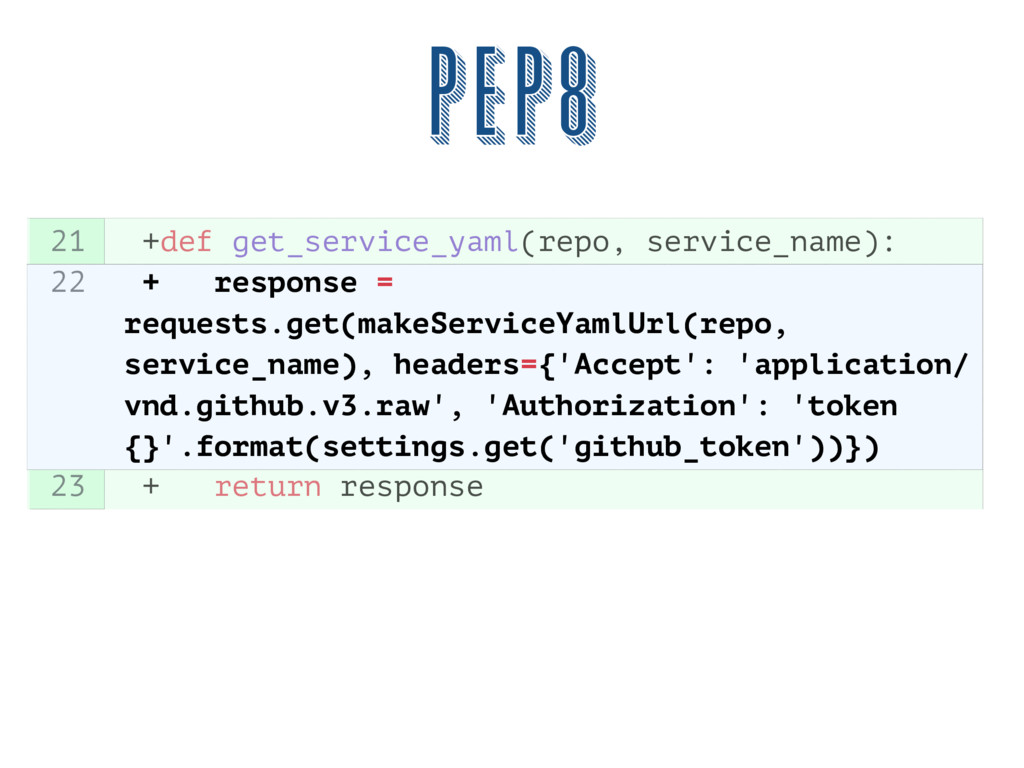
PEP8 +def get_service_yaml(repo, service_name): + response = requests.get(makeServiceYamlUrl(repo, service_name), headers={'Accept':
'application/ vnd.github.v3.raw', 'Authorization': 'token {}'.format(settings.get('github_token'))}) + return response 21 22 23 -
PEP8 +def get_service_yaml(repo, service_name): + response = requests.get(makeServiceYamlUrl(repo, service_name), headers={'Accept':
'application/ vnd.github.v3.raw', 'Authorization': 'token {}'.format(settings.get('github_token'))}) + return response 21 22 23 + response = requests.get(makeServiceYamlUrl(repo, service_name), headers={'Accept': 'application/ vnd.github.v3.raw', 'Authorization': 'token {}'.format(settings.get('github_token'))}) -
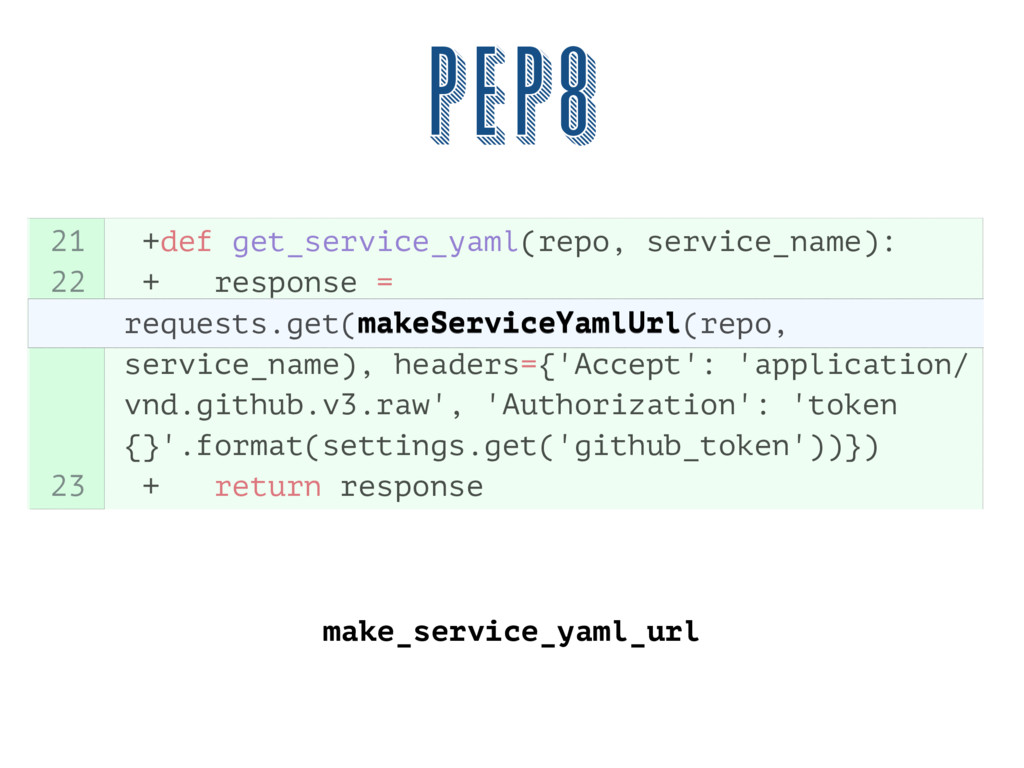
PEP8 +def get_service_yaml(repo, service_name): + response = requests.get(makeServiceYamlUrl(repo, service_name), headers={'Accept':
'application/ vnd.github.v3.raw', 'Authorization': 'token {}'.format(settings.get('github_token'))}) + return response 21 22 23 make_service_yaml_url makeServiceYamlUrl -
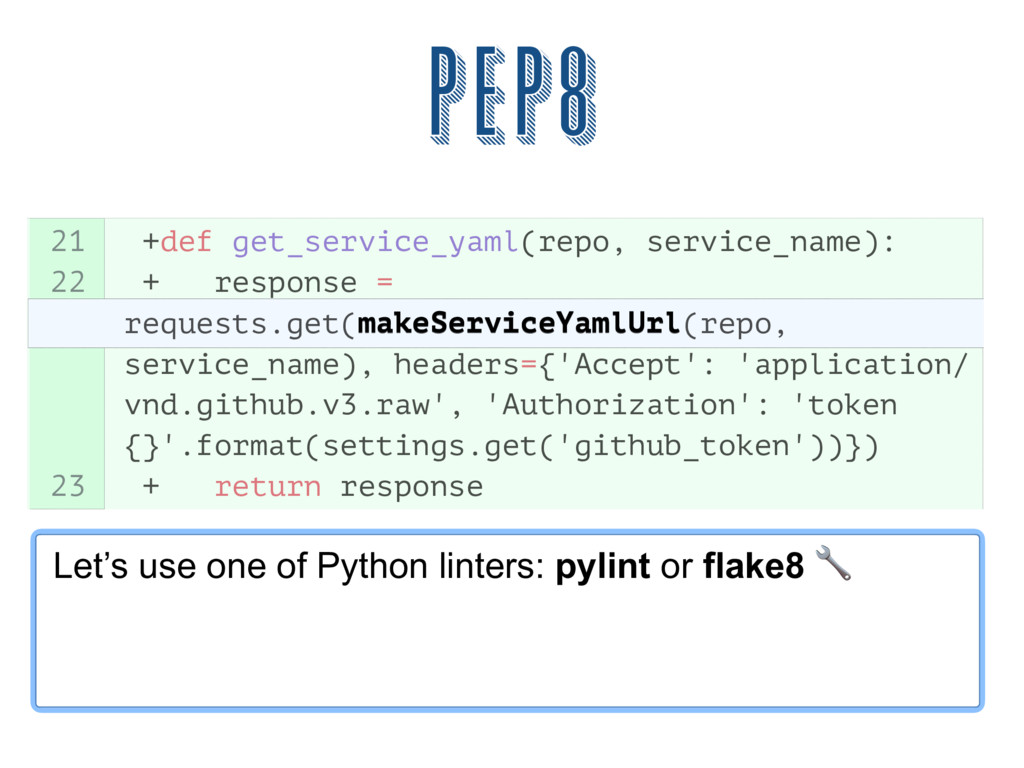
PEP8 +def get_service_yaml(repo, service_name): + response = requests.get(makeServiceYamlUrl(repo, service_name), headers={'Accept':
'application/ vnd.github.v3.raw', 'Authorization': 'token {}'.format(settings.get('github_token'))}) + return response 21 22 23 Let’s use one of Python linters: pylint or flake8 $ makeServiceYamlUrl -
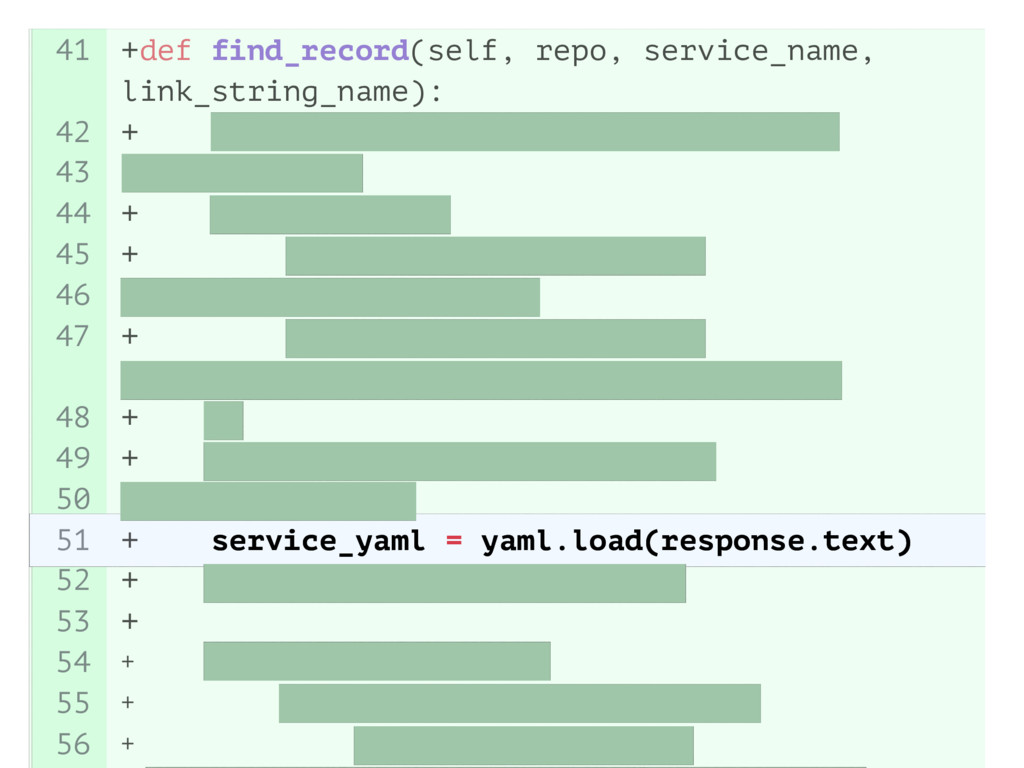
41 42 43 44 45 46 47 48 49 50
51 52 53 54 55 56 +def find_record(self, repo, service_name, link_string_name): + url = SERVICE_YAML_URL.format(repo, service_name) + headers = { + 'Accept': 'application/ vnd.github.v3.raw', + 'Authorization': 'token {}'.format(settings.get('github_token')) + } + response = requests.get(url, headers=headers) + service_yaml = yaml.load(response.text) + doc = response.get('docs') + + if doc is not None: + if link_string_name in doc: + self.attachments = -
41 42 43 44 45 46 47 48 49 50
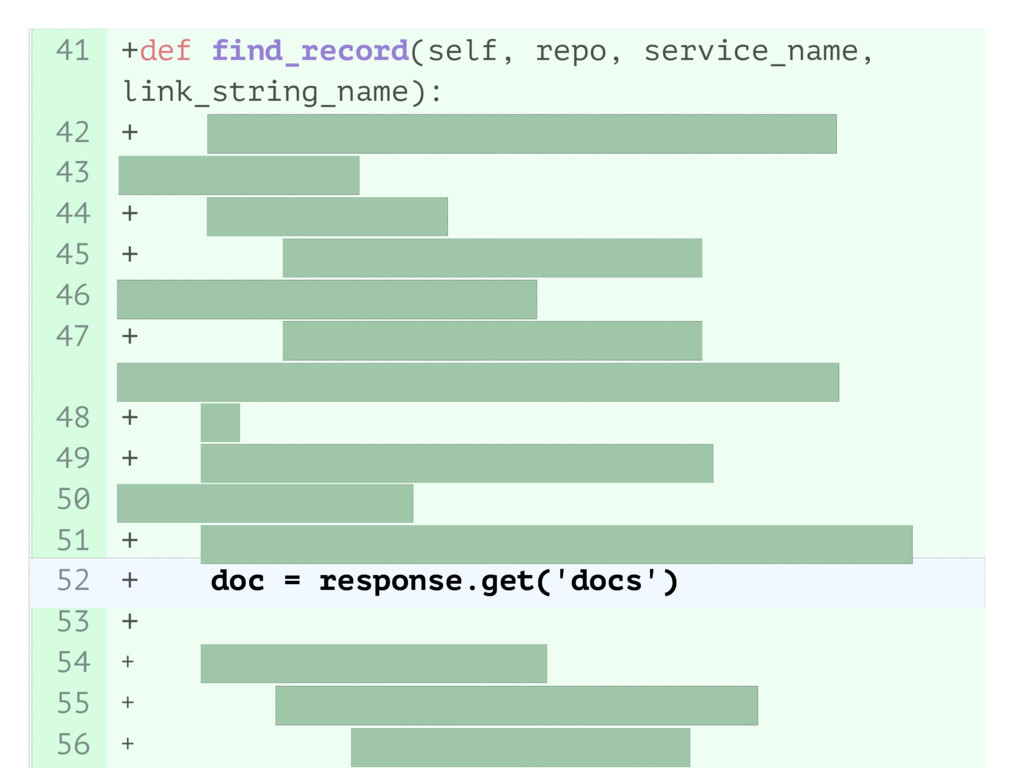
51 52 +def find_record(self, repo, service_name, link_string_name): + url = SERVICE_YAML_URL.format(repo, service_name) + headers = { + 'Accept': 'application/ vnd.github.v3.raw', + 'Authorization': 'token {}'.format(settings.get('github_token')) + } + response = requests.get(url, headers=headers) + service_yaml = yaml.load(response.text) + doc = response.get('docs') find_record what does the code do? -
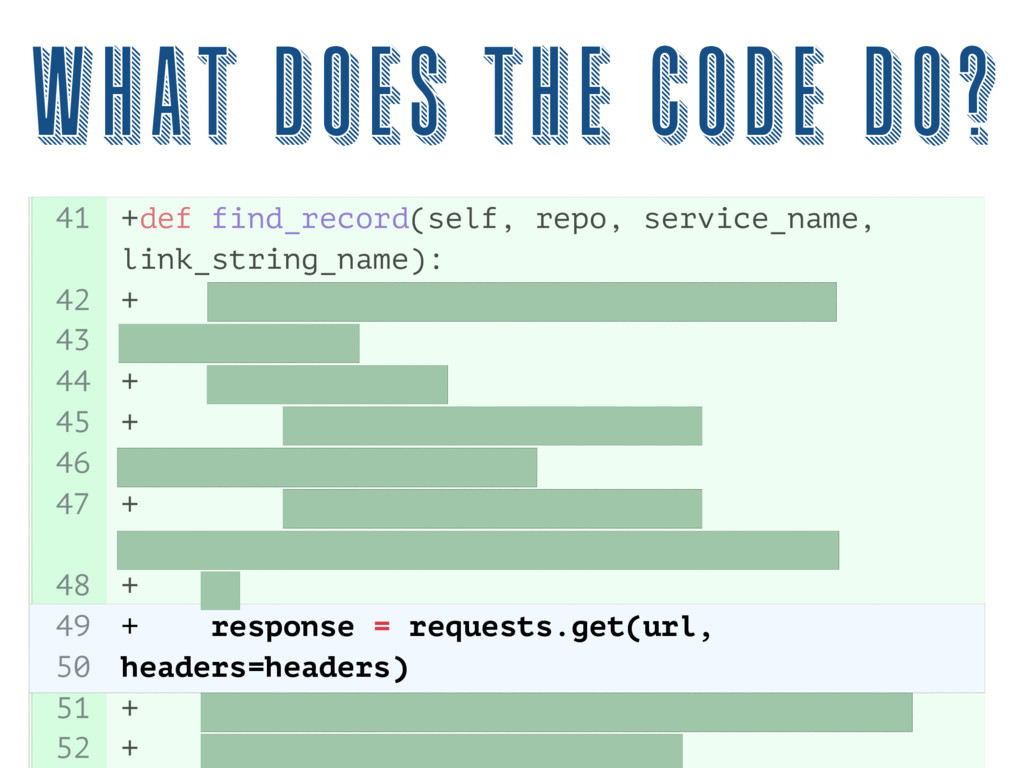
+def find_record(self, repo, service_name, link_string_name): + url = SERVICE_YAML_URL.format(repo, service_name)
+ headers = { + 'Accept': 'application/ vnd.github.v3.raw', + 'Authorization': 'token {}'.format(settings.get('github_token')) + } + response = requests.get(url, headers=headers) + service_yaml = yaml.load(response.text) + doc = response.get('docs') 41 42 43 44 45 46 47 48 49 50 51 52 + response = requests.get(url, headers=headers) what does the code do? -
41 42 43 44 45 46 47 48 49 50
51 52 53 54 55 56 +def find_record(self, repo, service_name, link_string_name): + url = SERVICE_YAML_URL.format(repo, service_name) + headers = { + 'Accept': 'application/ vnd.github.v3.raw', + 'Authorization': 'token {}'.format(settings.get('github_token')) + } + response = requests.get(url, headers=headers) + service_yaml = yaml.load(response.text) + doc = response.get('docs') + + if doc is not None: + if link_string_name in doc: + self.attachments = service_yaml = yaml.load(response.text) -
41 42 43 44 45 46 47 48 49 50
51 52 53 54 55 56 +def find_record(self, repo, service_name, link_string_name): + url = SERVICE_YAML_URL.format(repo, service_name) + headers = { + 'Accept': 'application/ vnd.github.v3.raw', + 'Authorization': 'token {}'.format(settings.get('github_token')) + } + response = requests.get(url, headers=headers) + service_yaml = yaml.load(response.text) + doc = response.get('docs') + + if doc is not None: + if link_string_name in doc: + self.attachments = doc = response.get('docs') -
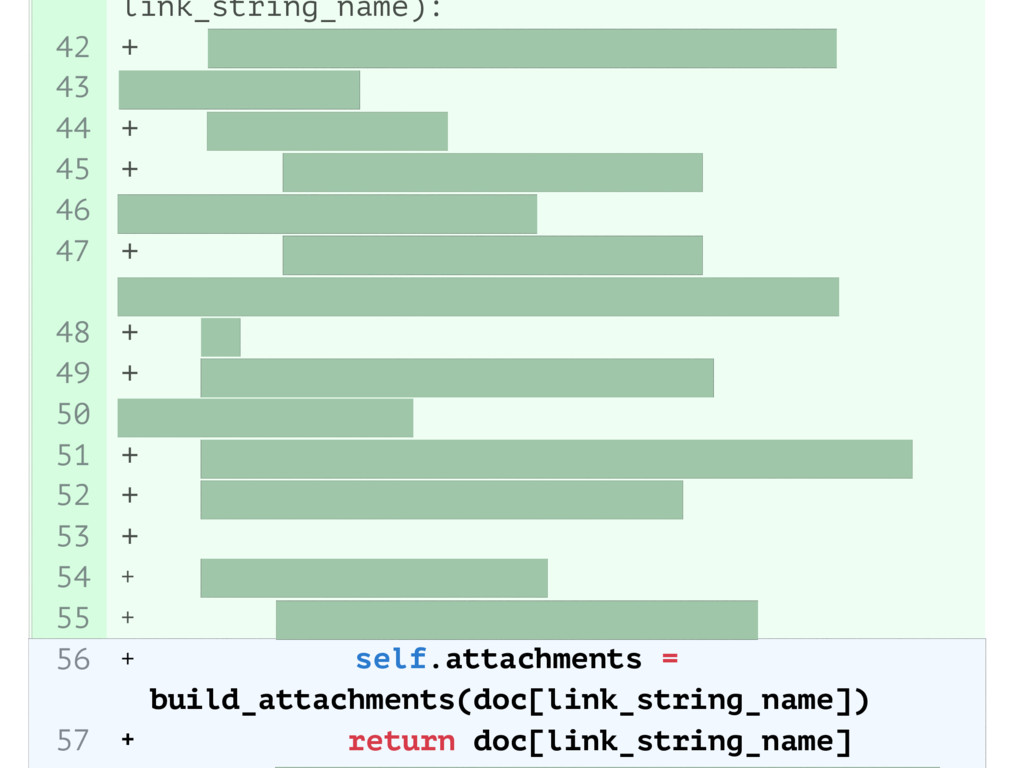
link_string_name): + url = SERVICE_YAML_URL.format(repo, service_name) + headers = {
+ 'Accept': 'application/ vnd.github.v3.raw', + 'Authorization': 'token {}'.format(settings.get('github_token')) + } + response = requests.get(url, headers=headers) + service_yaml = yaml.load(response.text) + doc = response.get('docs') + + if doc is not None: + if link_string_name in doc: + self.attachments = build_attachments(doc[link_string_name]) + return doc[link_string_name] + self.attachments = build_attachments(doc[link_string_name]) + return doc[link_string_name] 42 43 44 45 46 47 48 49 50 51 52 53 54 55 56 57 -
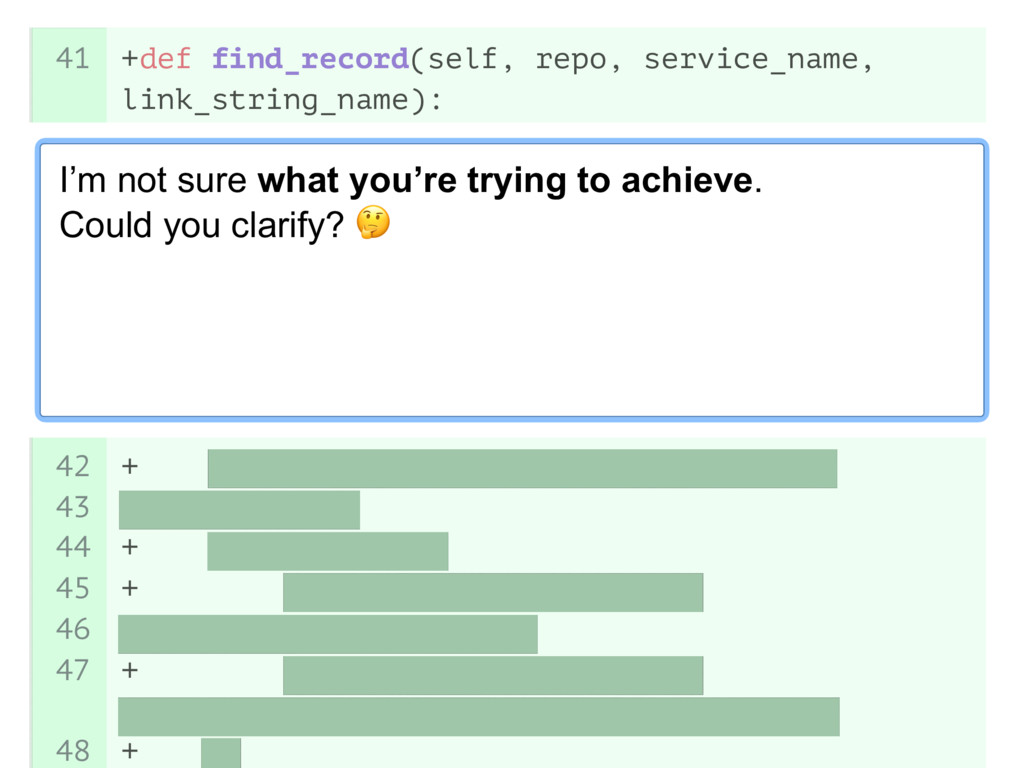
41 42 43 44 45 46 47 48 +def find_record(self,
repo, service_name, link_string_name): + url = SERVICE_YAML_URL.format(repo, service_name) + headers = { + 'Accept': 'application/ vnd.github.v3.raw', + 'Authorization': 'token {}'.format(settings.get('github_token')) + } I’m not sure what you’re trying to achieve. Could you clarify? & -
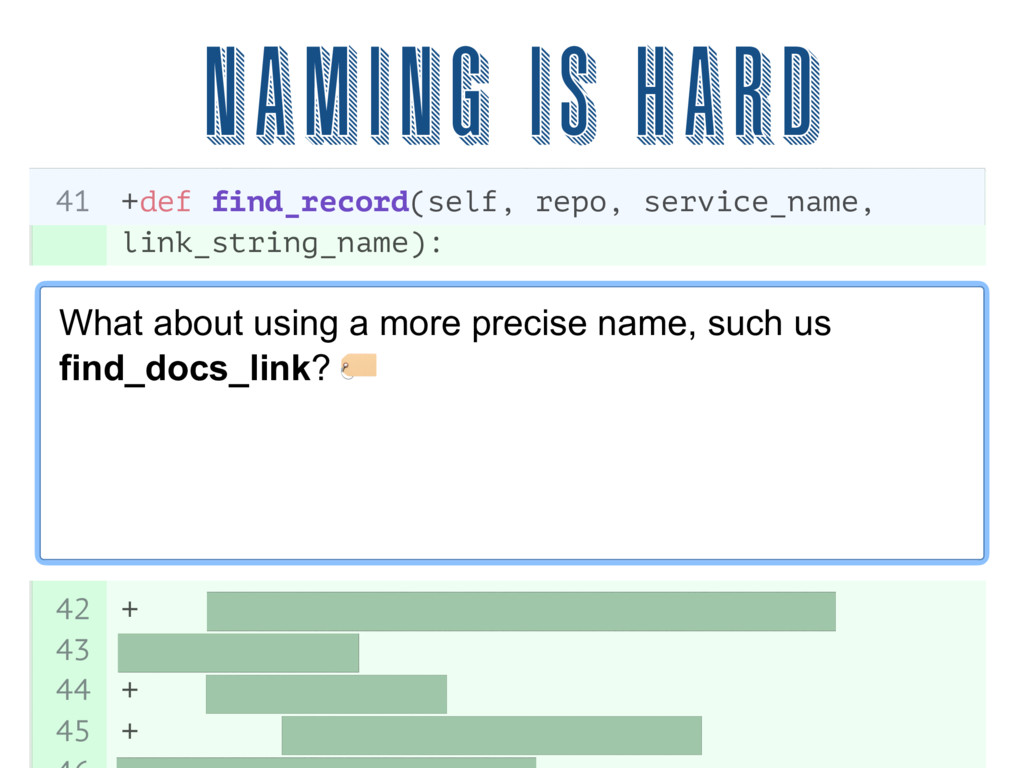
41 42 43 44 45 +def find_record(self, repo, service_name, link_string_name):
+ url = SERVICE_YAML_URL.format(repo, service_name) + headers = { + 'Accept': 'application/ What about using a more precise name, such us find_docs_link? ' find_record NAMING is hard -
47 48 49 50 51 52 53 54 55 56
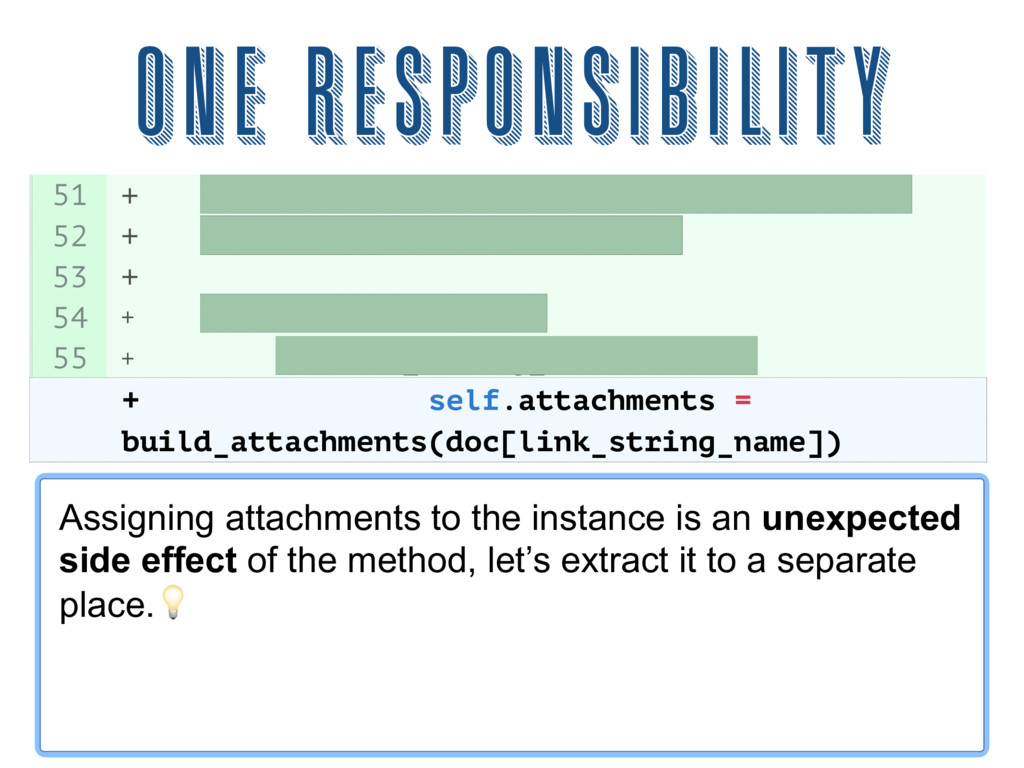
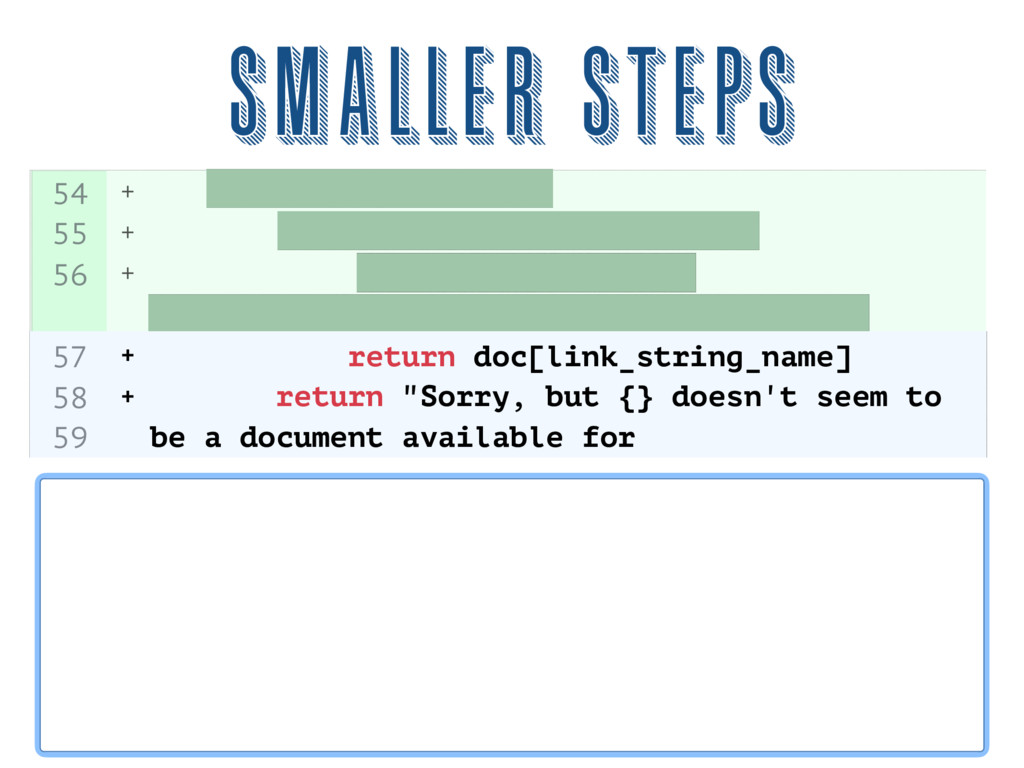
57 58 59 60 61 + 'Authorization': 'token {}'.format(settings.get('github_token')) + } + response = requests.get(url, headers=headers) + service_yaml = yaml.load(response.text) + doc = response.get('docs') + + if doc is not None: + if link_string_name in doc: + self.attachments = build_attachments(doc[link_string_name]) + return doc[link_string_name] + return "Sorry, but {} doesn't seem to be a document available for {}.".format(link_string_name, service_name) + else: + return "Sorry, but it seems like we can't find the documentation you're looking Assigning attachments to the instance is an unexpected side effect of the method, let’s extract it to a separate place.( one responsibility + self.attachments = build_attachments(doc[link_string_name]) -
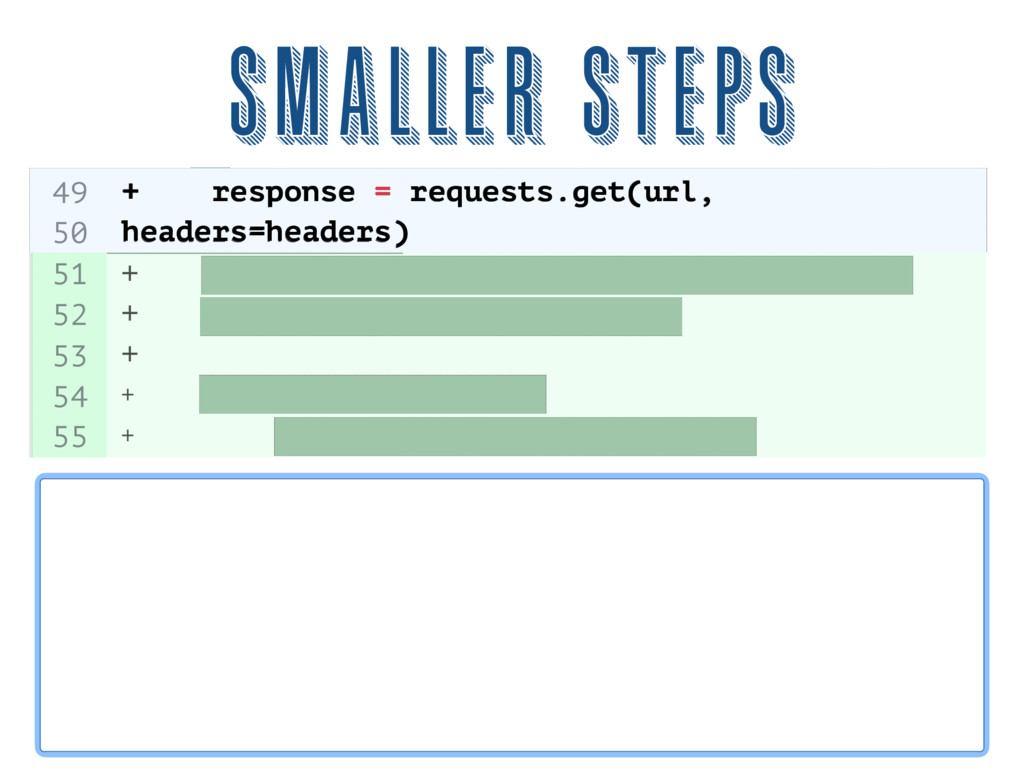
+ response = requests.get(url, headers=headers) 46 47 48 49 50
51 52 53 54 55 56 57 58 59 60 vnd.github.v3.raw', + 'Authorization': 'token {}'.format(settings.get('github_token')) + } + response = requests.get(url, headers=headers) + service_yaml = yaml.load(response.text) + doc = response.get('docs') + + if doc is not None: + if link_string_name in doc: + self.attachments = build_attachments(doc[link_string_name]) + return doc[link_string_name] + return "Sorry, but {} doesn't seem to be a document available for {}.".format(link_string_name, service_name) + else: Smaller steps -
46 47 48 49 50 51 52 53 54 55
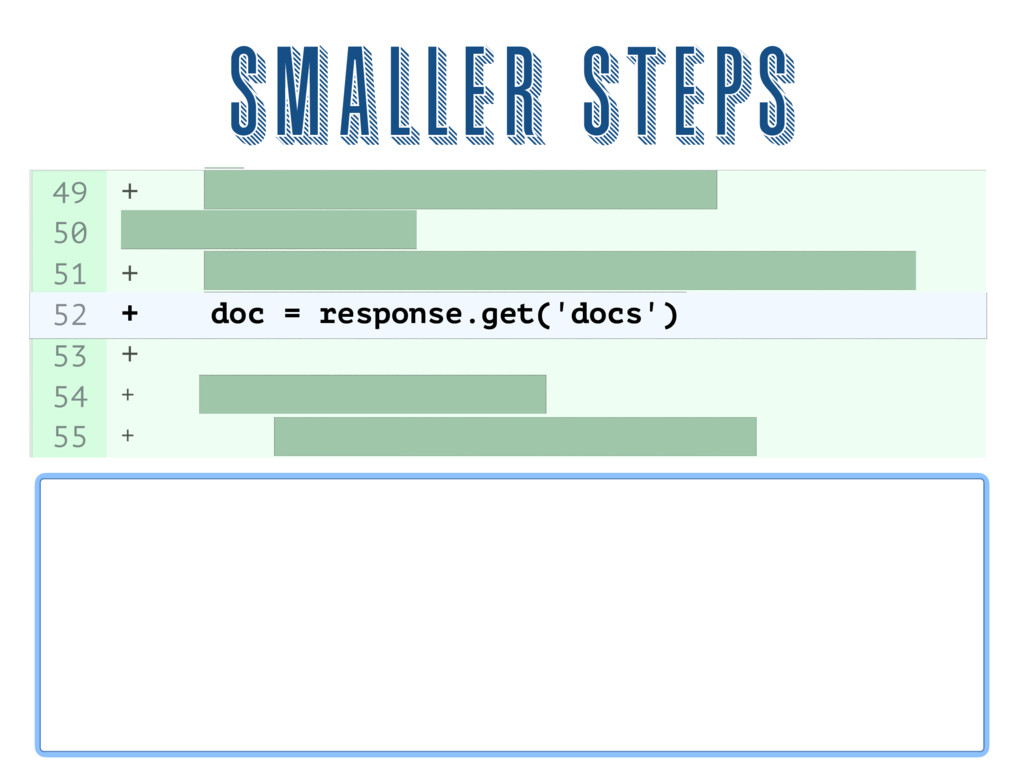
56 57 58 59 60 vnd.github.v3.raw', + 'Authorization': 'token {}'.format(settings.get('github_token')) + } + response = requests.get(url, headers=headers) + service_yaml = yaml.load(response.text) + doc = response.get('docs') + + if doc is not None: + if link_string_name in doc: + self.attachments = build_attachments(doc[link_string_name]) + return doc[link_string_name] + return "Sorry, but {} doesn't seem to be a document available for {}.".format(link_string_name, service_name) + else: Smaller steps + doc = response.get('docs') -
headers=headers) + service_yaml = yaml.load(response.text) + doc = response.get('docs') +
+ if doc is not None: + if link_string_name in doc: + self.attachments = build_attachments(doc[link_string_name]) + return doc[link_string_name] + return "Sorry, but {} doesn't seem to be a document available for {}.".format(link_string_name, service_name) + else: + return "Sorry, but it seems like we can't find the documentation you're looking for." 49 50 51 52 53 54 55 56 57 58 59 60 61 Smaller steps + return doc[link_string_name] + return "Sorry, but {} doesn't seem to be a document available for -
49 50 51 52 53 54 55 56 57 58
59 60 61 headers=headers) + service_yaml = yaml.load(response.text) + doc = response.get('docs') + + if doc is not None: + if link_string_name in doc: + self.attachments = build_attachments(doc[link_string_name]) + return doc[link_string_name] + return "Sorry, but {} doesn't seem to be a document available for {}.".format(link_string_name, service_name) + else: + return "Sorry, but it seems like we can't find the documentation you're looking for." Smaller steps This method is long. Let’s split it into smaller steps: one for fetching the yaml file from Github and one that builds attachments. ) -
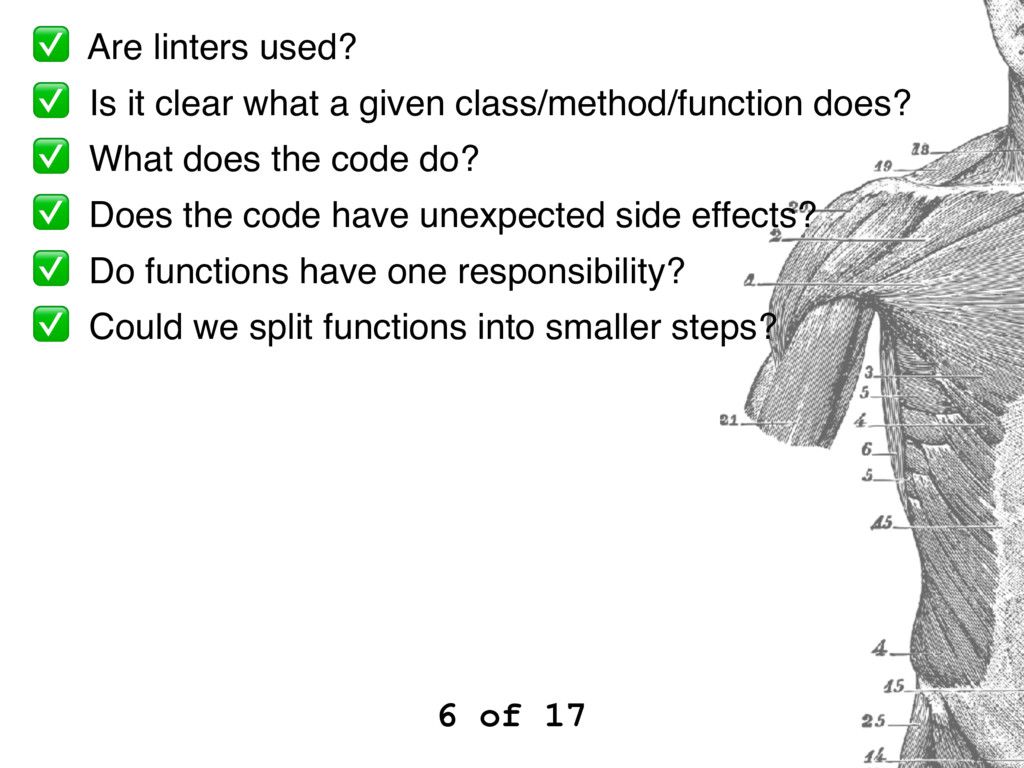
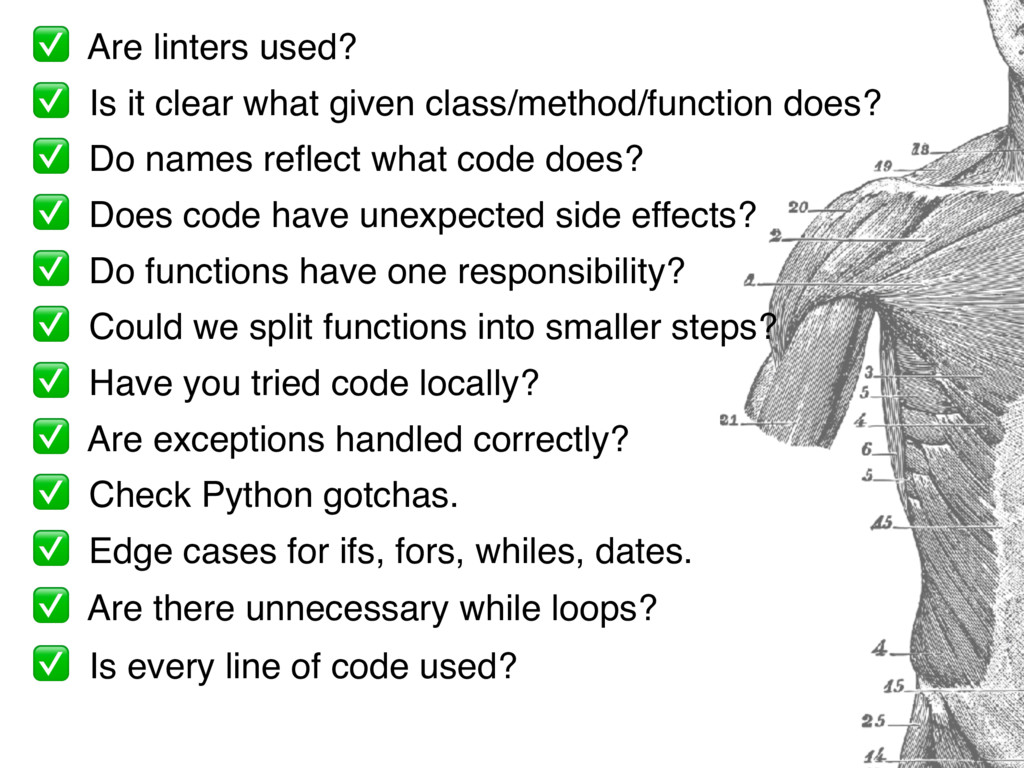
✅ Are linters used? ✅ Is it clear what a
given class/method/function does? ✅ What does the code do? ✅ Does the code have unexpected side effects? ✅ Do functions have one responsibility? ✅ Could we split functions into smaller steps? 6 of 17 -
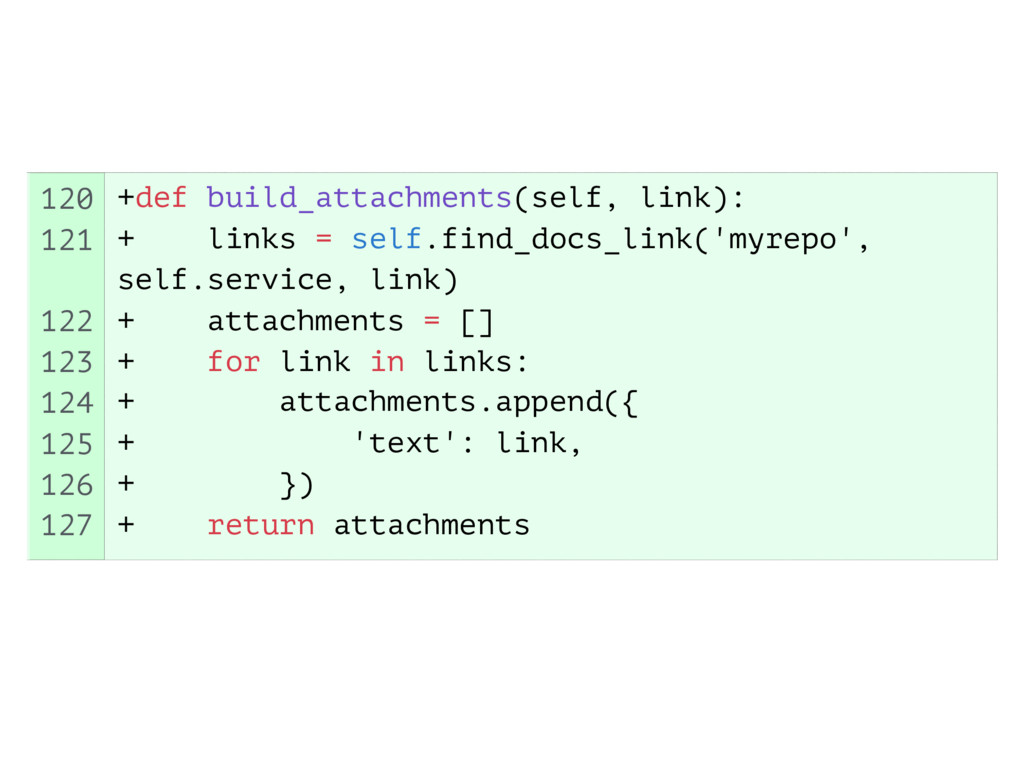
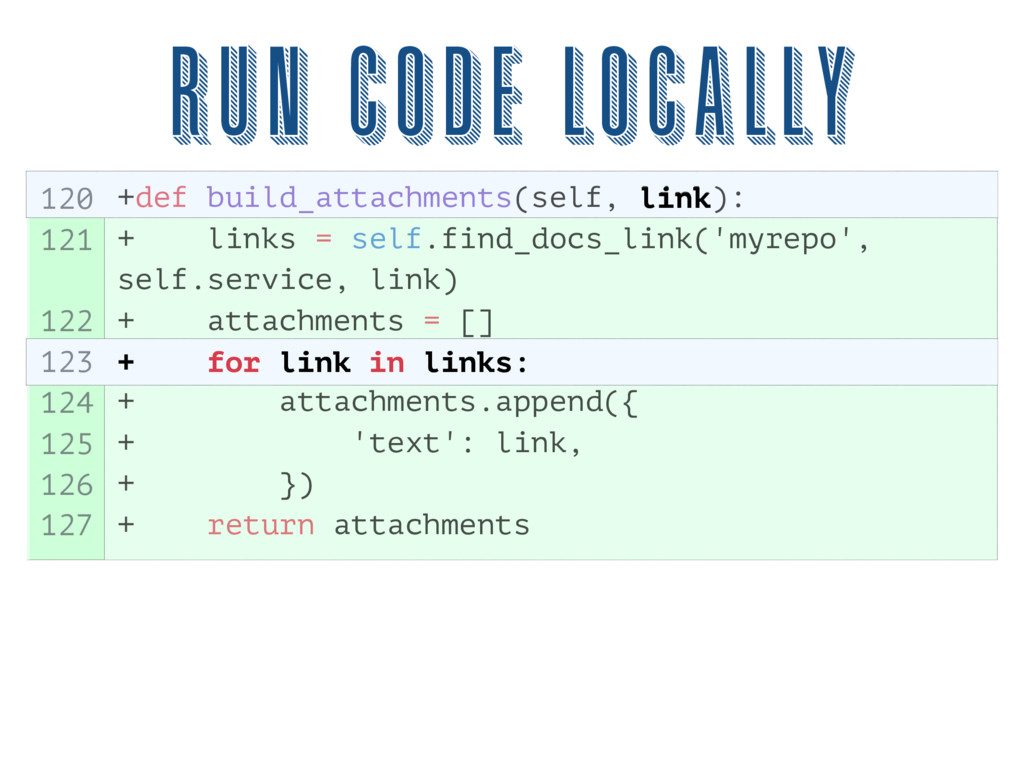
120 121 122 123 124 125 126 127 +def build_attachments(self,
link): + links = self.find_docs_link('myrepo', self.service, link) + attachments = [] + for link in links: + attachments.append({ + 'text': link, + }) + return attachments -
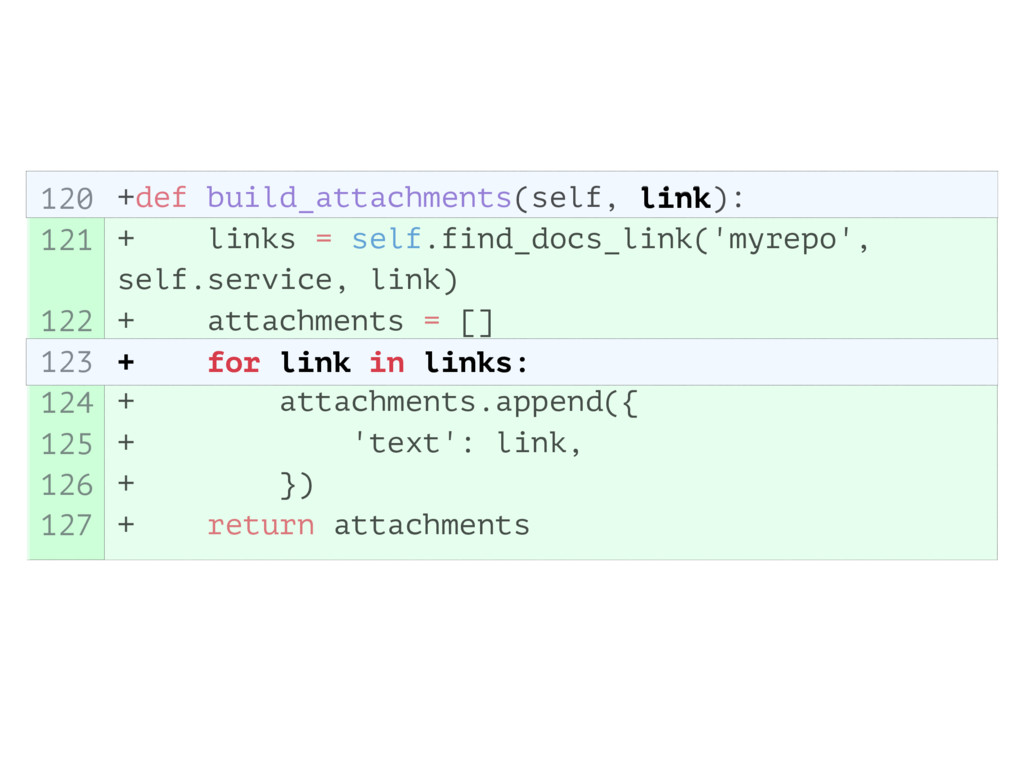
+def build_attachments(self, link): + links = self.find_docs_link('myrepo', self.service, link) +
attachments = [] + for link in links: + attachments.append({ + 'text': link, + }) + return attachments 120 121 122 123 124 125 126 127 + for link in links: link -
run code locally +def build_attachments(self, link): + links = self.find_docs_link('myrepo',
self.service, link) + attachments = [] + for link in links: + attachments.append({ + 'text': link, + }) + return attachments + for link in links: 120 121 122 123 124 125 126 127 link -
✅ Are linters used? ✅ Is it clear what given
class/method/function does? ✅ Do names reflect what code does? ✅ Does code have unexpected side effects? ✅ Do functions have one responsibility? ✅ Could we split functions into smaller steps? ✅ Have you tried code locally? 7 of 17 -
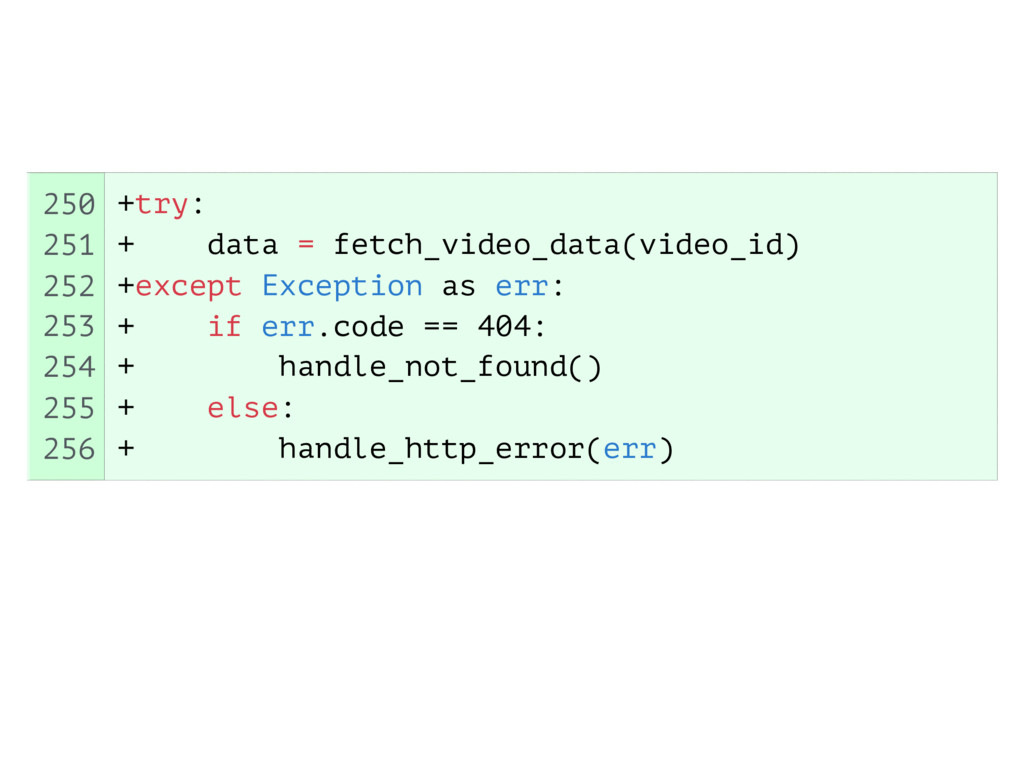
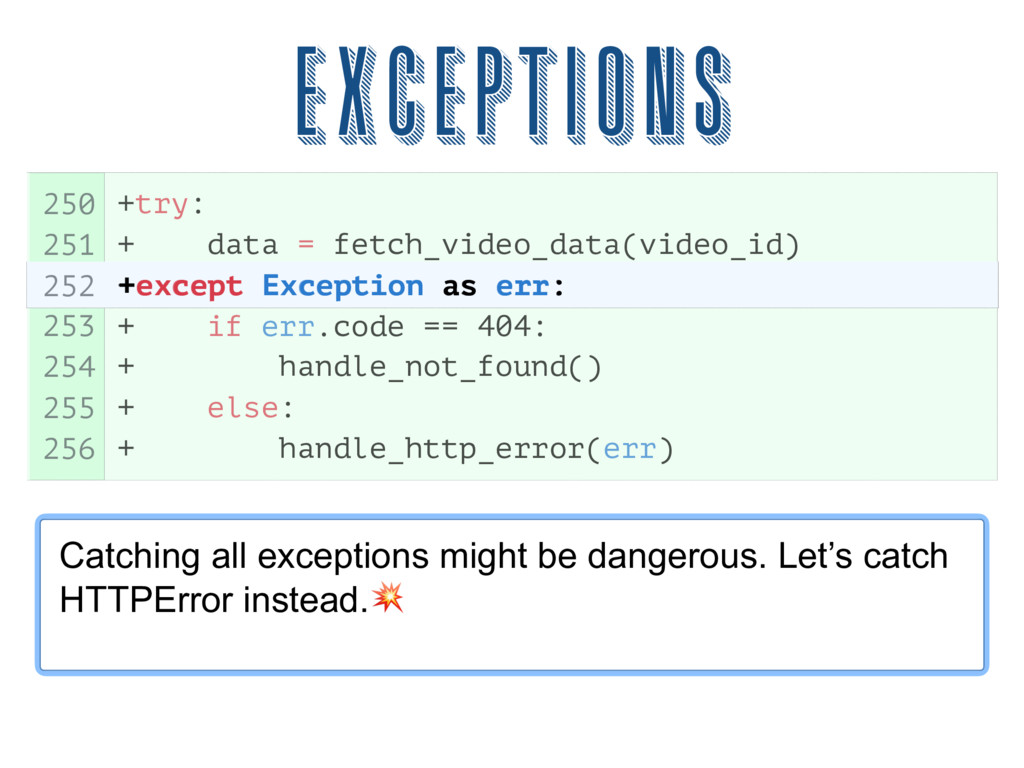
250 251 252 253 254 255 256 +try: + data
= fetch_video_data(video_id) +except Exception as err: + if err.code == 404: + handle_not_found() + else: + handle_http_error(err) -
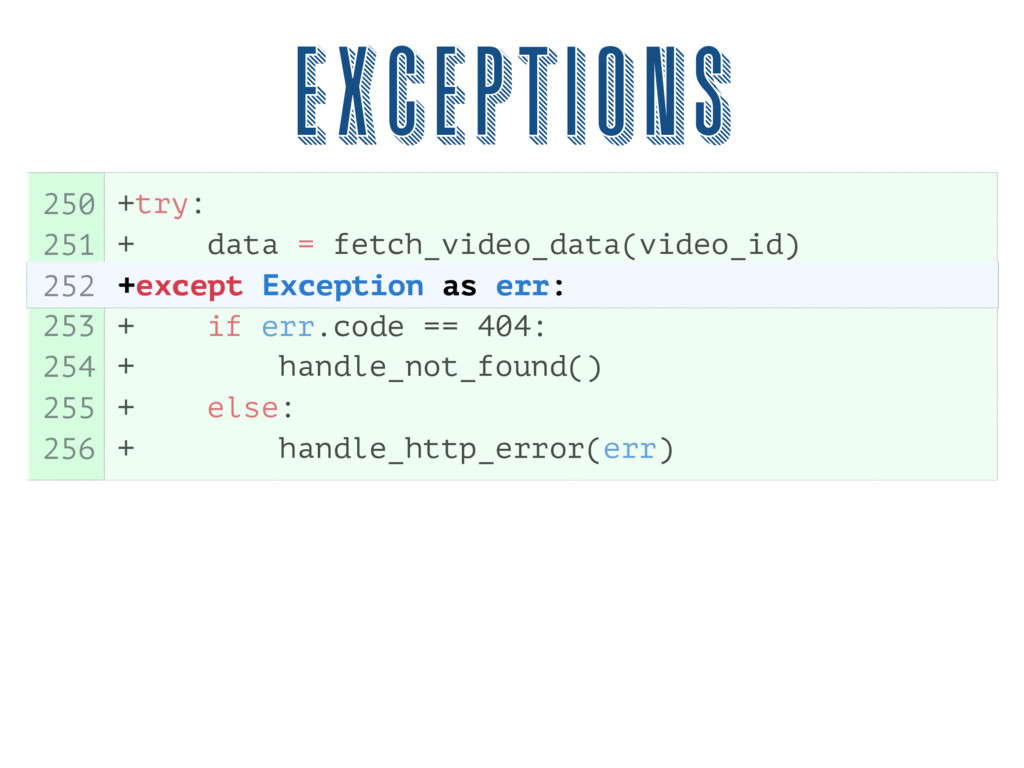
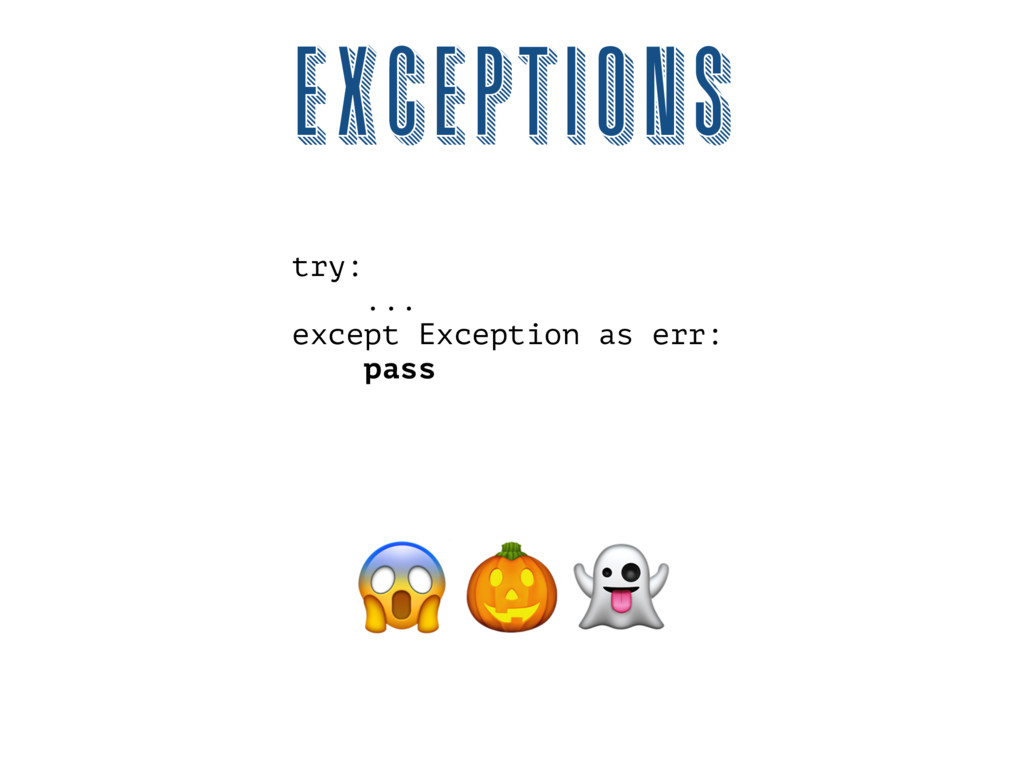
Exceptions +except Exception as err: 250 251 252 253 254
255 256 +try: + data = fetch_video_data(video_id) +except Exception as err: + if err.code == 404: + handle_not_found() + else: + handle_http_error(err) -
Exceptions Catching all exceptions might be dangerous. Let’s catch HTTPError
instead.* +except Exception as err: 250 251 252 253 254 255 256 +try: + data = fetch_video_data(video_id) +except Exception as err: + if err.code == 404: + handle_not_found() + else: + handle_http_error(err) -
✅ Are linters used? ✅ Is it clear what given
class/method/function does? ✅ Do names reflect what code does? ✅ Does code have unexpected side effects? ✅ Do functions have one responsibility? ✅ Could we split functions into smaller steps? ✅ Have you tried code locally? ✅ Are exceptions handled correctly? 8 of 17 -
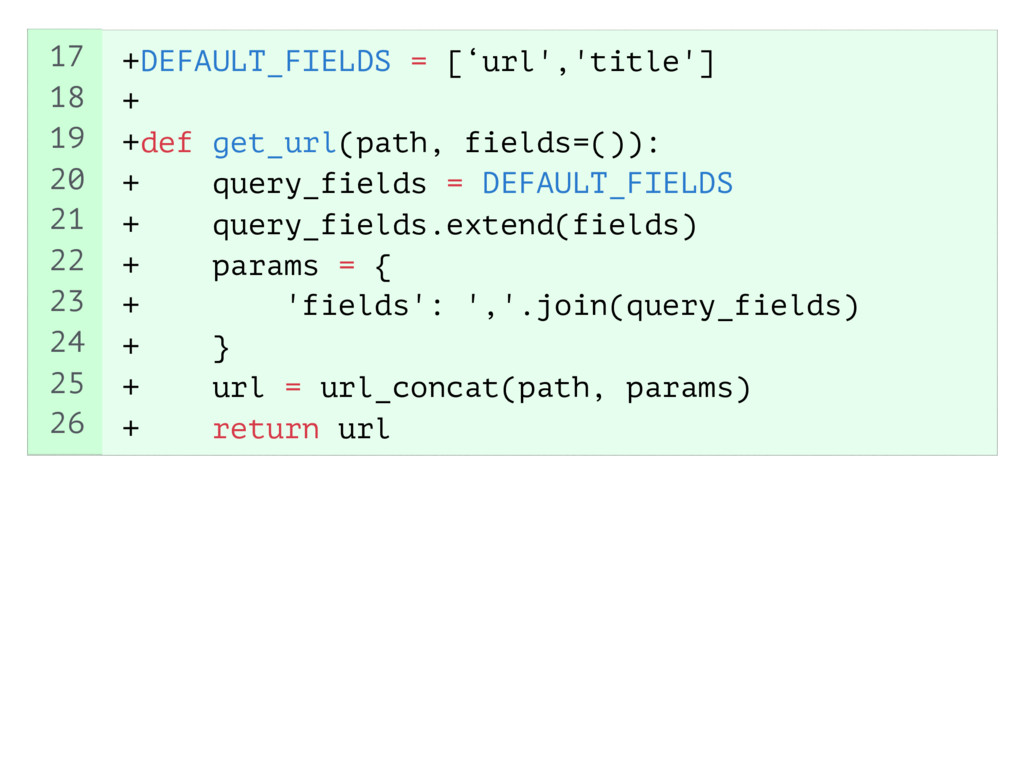
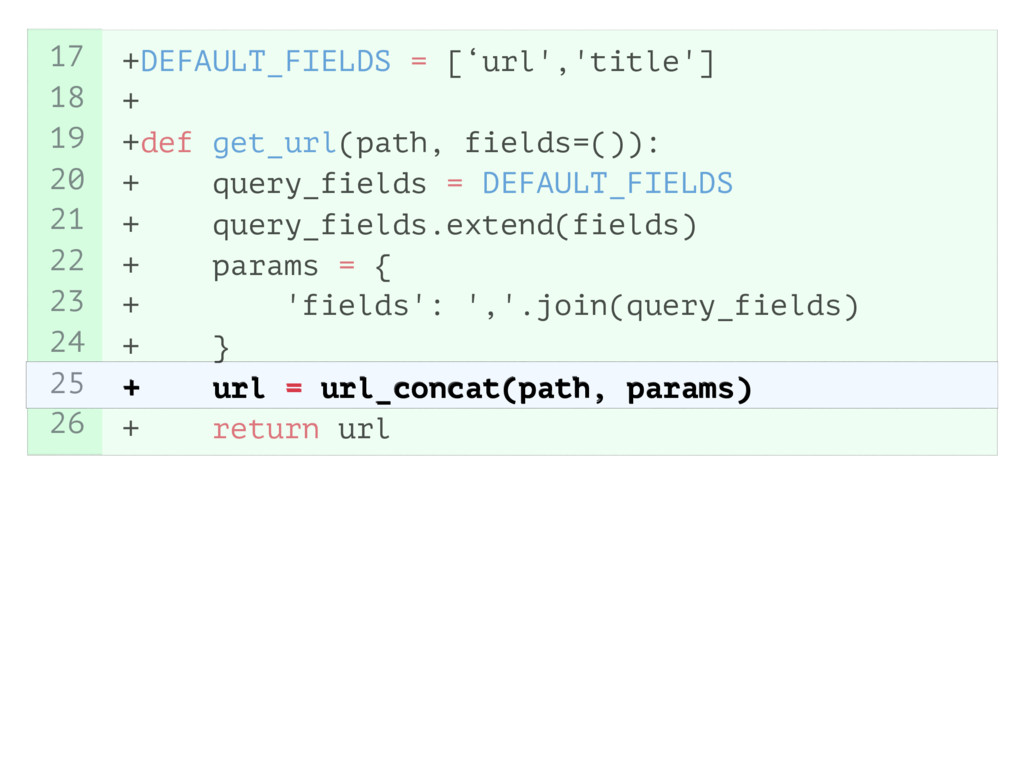
17 18 19 20 21 22 23 24 25 26
+DEFAULT_FIELDS = [‘url','title'] + +def get_url(path, fields=()): + query_fields = DEFAULT_FIELDS + query_fields.extend(fields) + params = { + 'fields': ','.join(query_fields) + } + url = url_concat(path, params) + return url -
17 18 19 20 21 22 23 24 25 26
+DEFAULT_FIELDS = [‘url','title'] + +def get_url(path, fields=()): + query_fields = DEFAULT_FIELDS + query_fields.extend(fields) + params = { + 'fields': ','.join(query_fields) + } + url = url_concat(path, params) + return url + url = url_concat(path, params) -
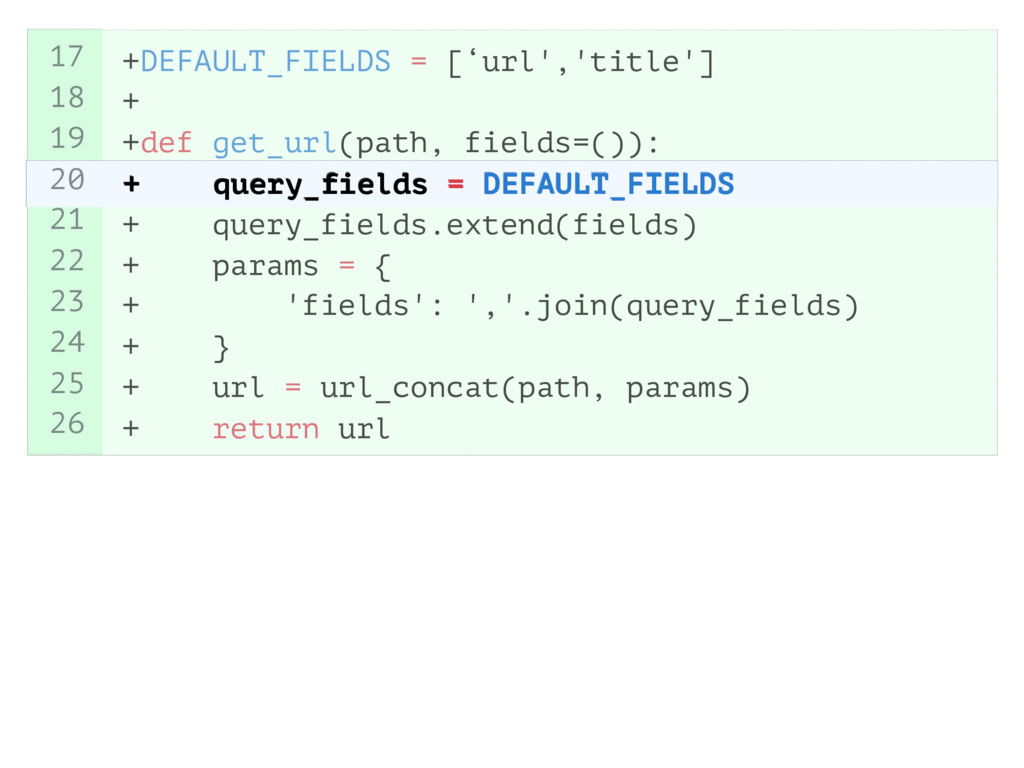
17 18 19 20 21 22 23 24 25 26
+ query_fields = DEFAULT_FIELDS +DEFAULT_FIELDS = [‘url','title'] + +def get_url(path, fields=()): + query_fields = DEFAULT_FIELDS + query_fields.extend(fields) + params = { + 'fields': ','.join(query_fields) + } + url = url_concat(path, params) + return url -
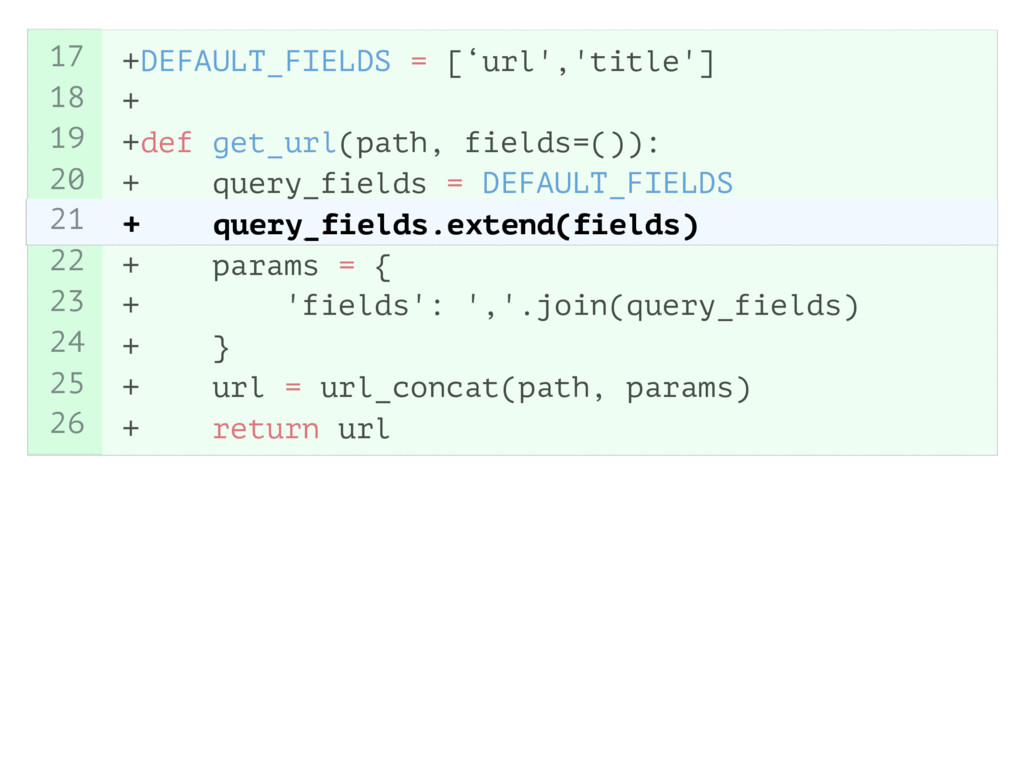
17 18 19 20 21 22 23 24 25 26
+ query_fields.extend(fields) +DEFAULT_FIELDS = [‘url','title'] + +def get_url(path, fields=()): + query_fields = DEFAULT_FIELDS + query_fields.extend(fields) + params = { + 'fields': ','.join(query_fields) + } + url = url_concat(path, params) + return url -
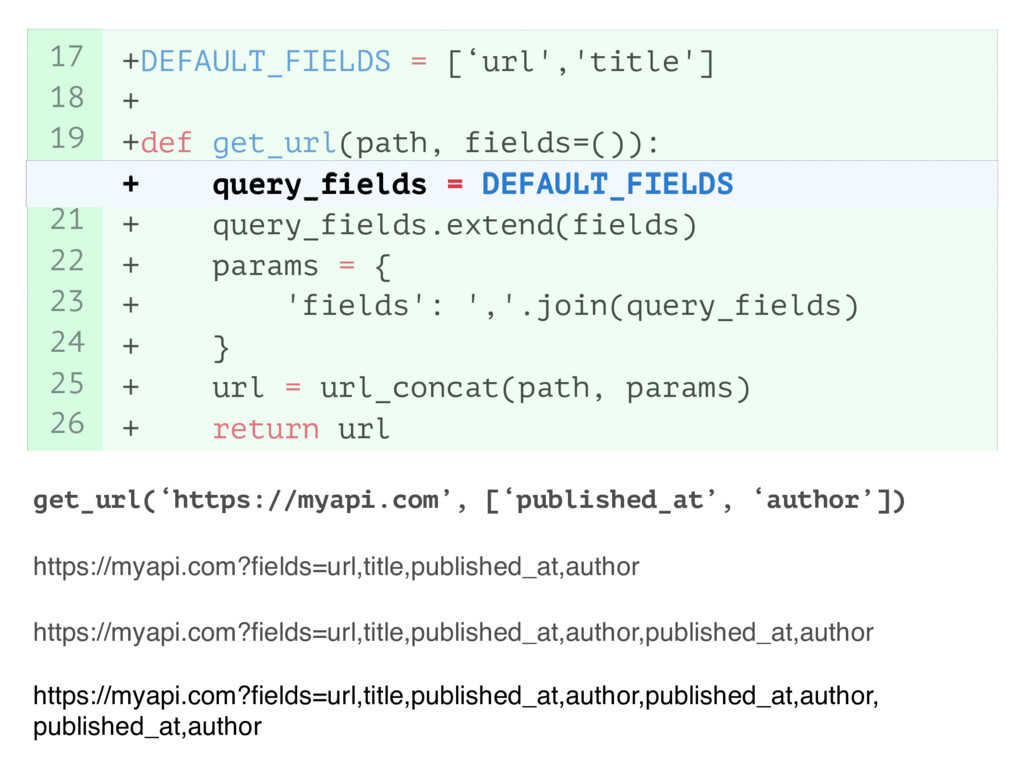
get_url(‘https://myapi.com’, [‘published_at’, ‘author’]) 17 18 19 20 21 22 23
24 25 26 +DEFAULT_FIELDS = [‘url','title'] + +def get_url(path, fields=()): + query_fields = DEFAULT_FIELDS + query_fields.extend(fields) + params = { + 'fields': ','.join(query_fields) + } + url = url_concat(path, params) + return url -
get_url(‘https://myapi.com’, [‘published_at’, ‘author’]) https://myapi.com?fields=url,title,published_at,author 17 18 19 20 21 22
23 24 25 26 +DEFAULT_FIELDS = [‘url','title'] + +def get_url(path, fields=()): + query_fields = DEFAULT_FIELDS + query_fields.extend(fields) + params = { + 'fields': ','.join(query_fields) + } + url = url_concat(path, params) + return url -
get_url(‘https://myapi.com’, [‘published_at’, ‘author’]) 17 18 19 20 21 22 23
24 25 26 https://myapi.com?fields=url,title,published_at,author,published_at,author https://myapi.com?fields=url,title,published_at,author +DEFAULT_FIELDS = [‘url','title'] + +def get_url(path, fields=()): + query_fields = DEFAULT_FIELDS + query_fields.extend(fields) + params = { + 'fields': ','.join(query_fields) + } + url = url_concat(path, params) + return url -
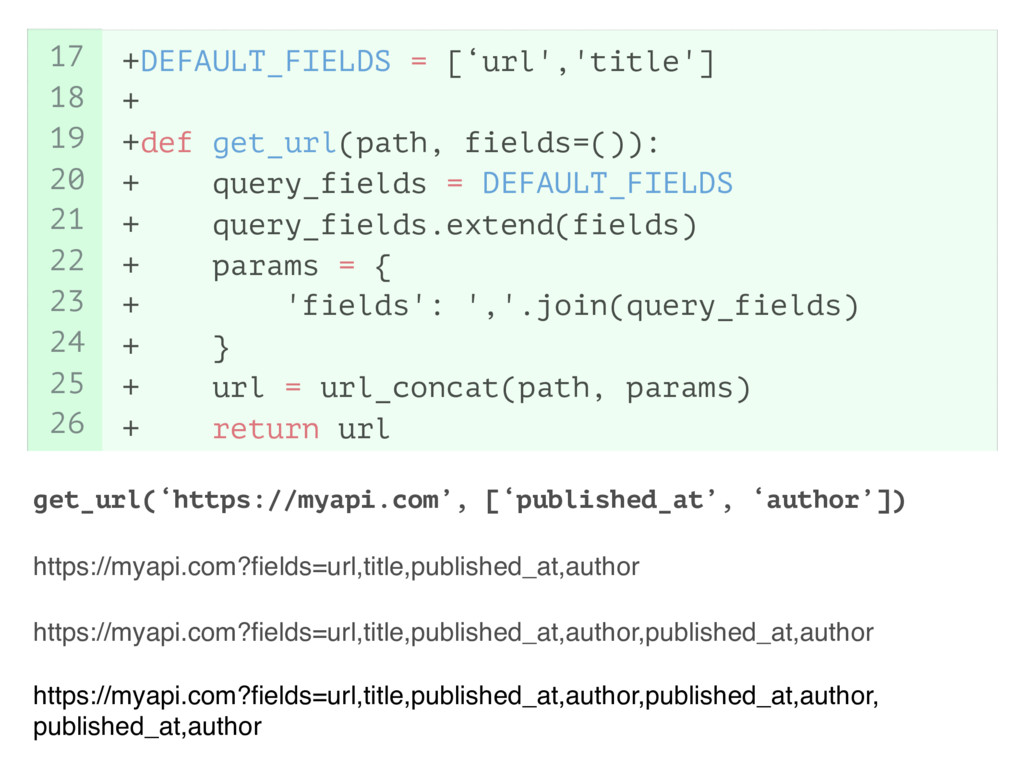
17 18 19 20 21 22 23 24 25 26
get_url(‘https://myapi.com’, [‘published_at’, ‘author’]) https://myapi.com?fields=url,title,published_at,author,published_at,author https://myapi.com?fields=url,title,published_at,author https://myapi.com?fields=url,title,published_at,author,published_at,author, published_at,author +DEFAULT_FIELDS = [‘url','title'] + +def get_url(path, fields=()): + query_fields = DEFAULT_FIELDS + query_fields.extend(fields) + params = { + 'fields': ','.join(query_fields) + } + url = url_concat(path, params) + return url -
17 18 19 20 21 22 23 24 25 26
get_url(‘https://myapi.com’, [‘published_at’, ‘author’]) + query_fields = DEFAULT_FIELDS https://myapi.com?fields=url,title,published_at,author,published_at,author https://myapi.com?fields=url,title,published_at,author https://myapi.com?fields=url,title,published_at,author,published_at,author, published_at,author +DEFAULT_FIELDS = [‘url','title'] + +def get_url(path, fields=()): + query_fields = DEFAULT_FIELDS + query_fields.extend(fields) + params = { + 'fields': ','.join(query_fields) + } + url = url_concat(path, params) + return url -
get_url(‘https://myapi.com’, [‘published_at’, ‘author’]) 17 18 19 20 21 22 23
24 25 26 + query_fields.extend(fields) https://myapi.com?fields=url,title,published_at,author,published_at,author https://myapi.com?fields=url,title,published_at,author https://myapi.com?fields=url,title,published_at,author,published_at,author, published_at,author +DEFAULT_FIELDS = [‘url','title'] + +def get_url(path, fields=()): + query_fields = DEFAULT_FIELDS + query_fields.extend(fields) + params = { + 'fields': ','.join(query_fields) + } + url = url_concat(path, params) + return url -
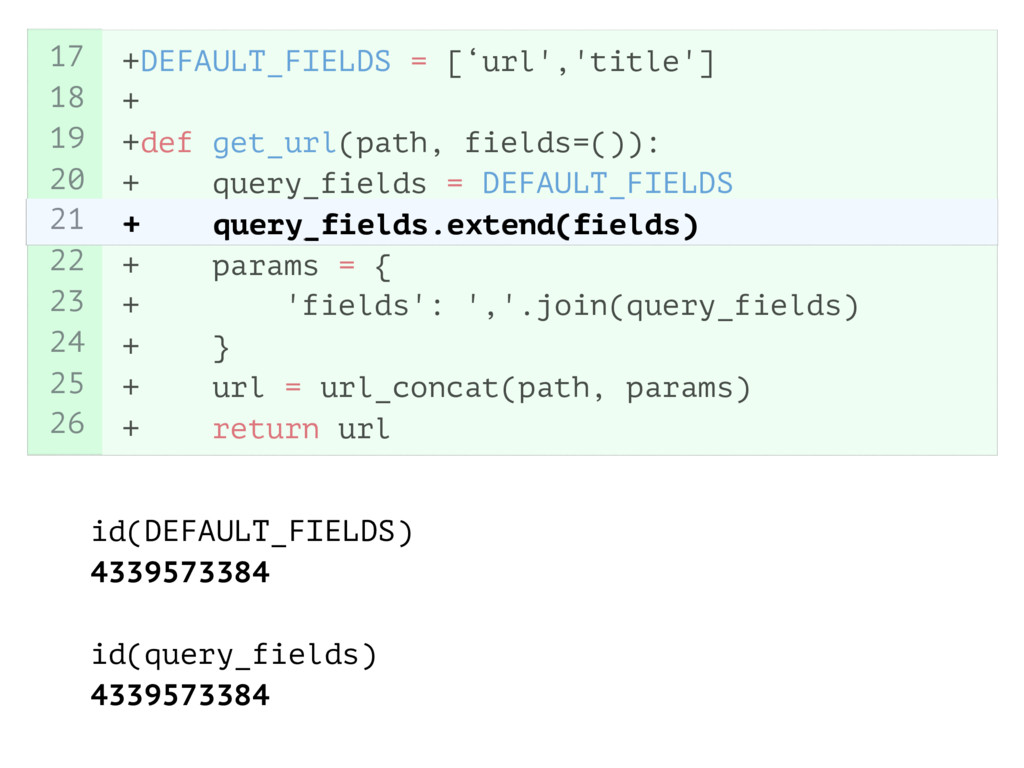
id(DEFAULT_FIELDS) 4339573384 id(query_fields) 4339573384 17 18 19 20 21 22
23 24 25 26 + query_fields.extend(fields) +DEFAULT_FIELDS = [‘url','title'] + +def get_url(path, fields=()): + query_fields = DEFAULT_FIELDS + query_fields.extend(fields) + params = { + 'fields': ','.join(query_fields) + } + url = url_concat(path, params) + return url -
+def add_to_list(element, current_list=[]): + current_list.append(element) + return current_list 87 88
89 +def add_to_list(element, current_list=[]): -
+def add_to_list(element, current_list=[]): + current_list.append(element) + return current_list 87 88
89 +def add_to_list(element, current_list=[]): >>> add_to_list(1) [1] -
+def add_to_list(element, current_list=[]): + current_list.append(element) + return current_list 87 88
89 +def add_to_list(element, current_list=[]): >>> add_to_list(1) [1] >>> add_to_list(1) [1, 1] -
+def add_to_list(element, current_list=[]): + current_list.append(element) + return current_list 87 88
89 +def add_to_list(element, current_list=[]): >>> add_to_list(1) [1] >>> add_to_list(1) [1, 1] >>> add_to_list(1) [1, 1, 1] -
+def add_to_list(element, current_list=[]): + current_list.append(element) + return current_list 87 88
89 +def add_to_list(element, current_list=[]): >>> add_to_list(1) [1] >>> add_to_list(1) [1, 1] >>> add_to_list(1) [1, 1, 1] Python gotchas -
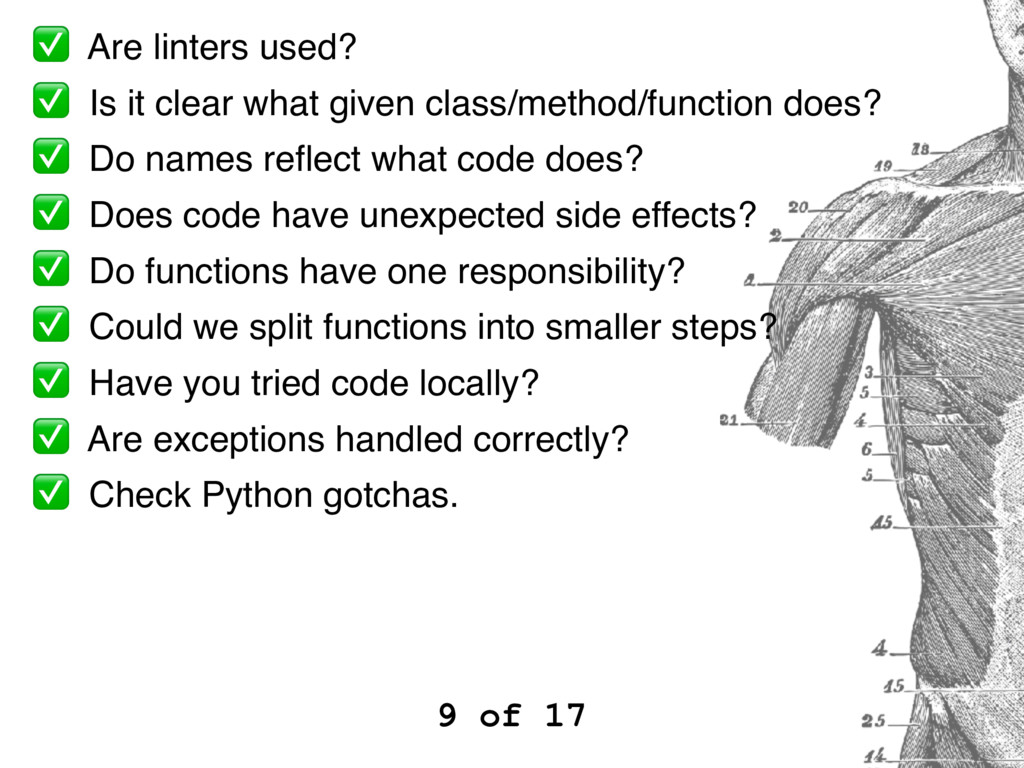
✅ Are linters used? ✅ Is it clear what given
class/method/function does? ✅ Do names reflect what code does? ✅ Does code have unexpected side effects? ✅ Do functions have one responsibility? ✅ Could we split functions into smaller steps? ✅ Have you tried code locally? ✅ Are exceptions handled correctly? ✅ Check Python gotchas. 9 of 17 -
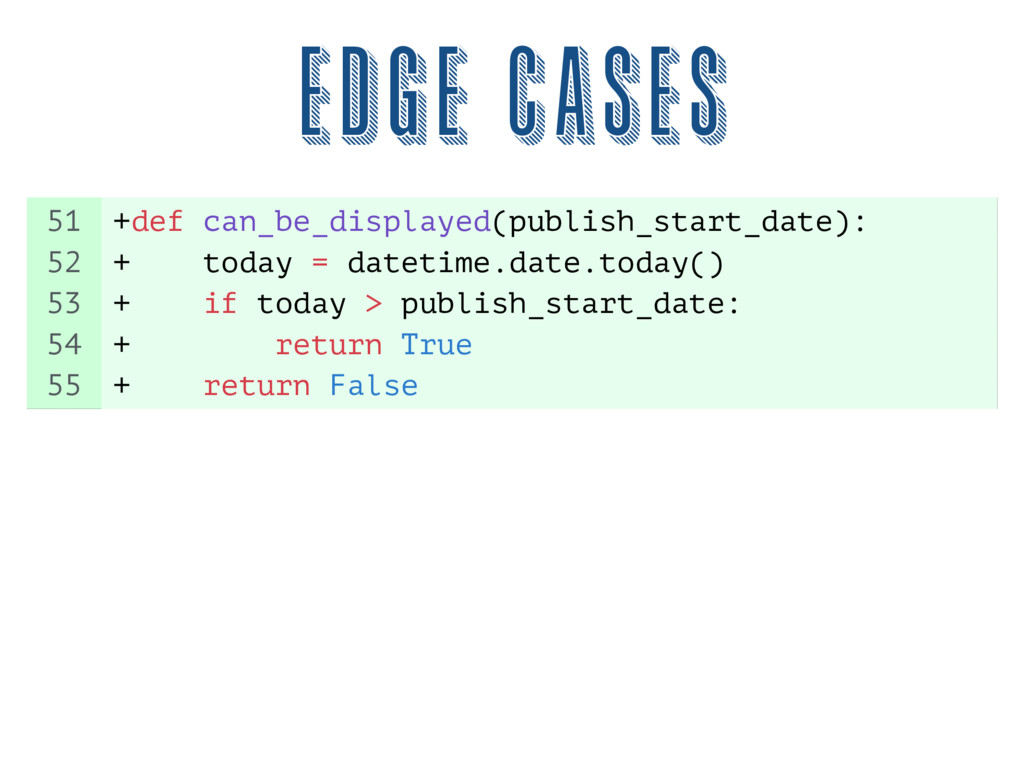
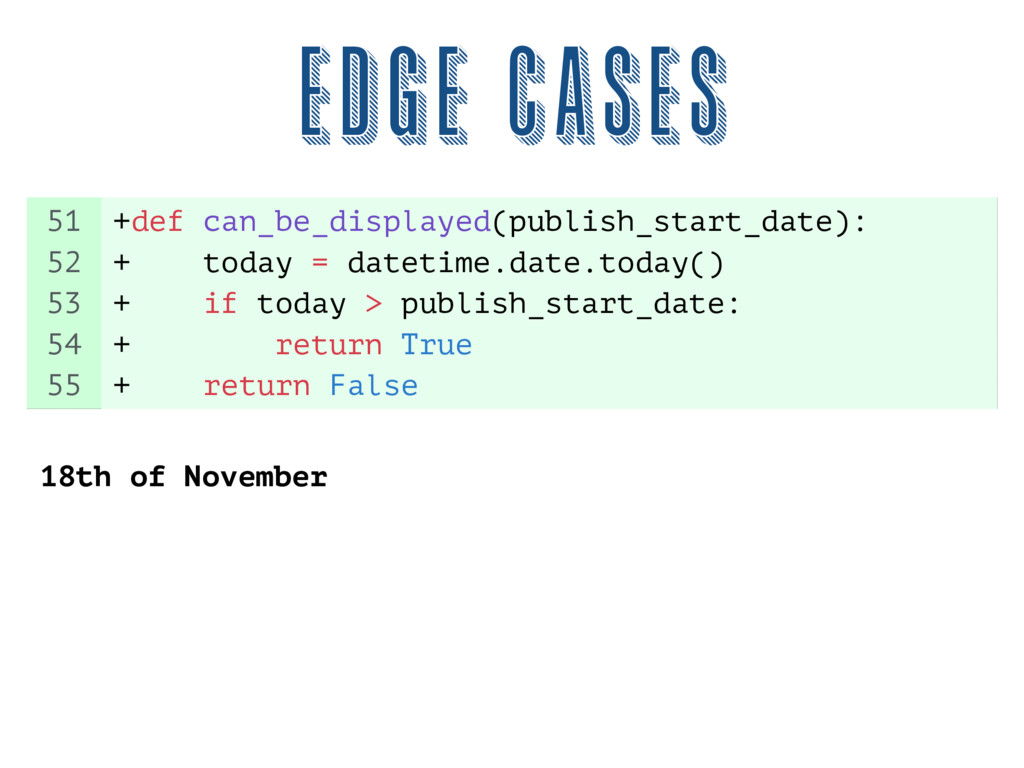
+def can_be_displayed(publish_start_date): + today = datetime.date.today() + if today >
publish_start_date: + return True + return False 51 52 53 54 55 Edge cases -
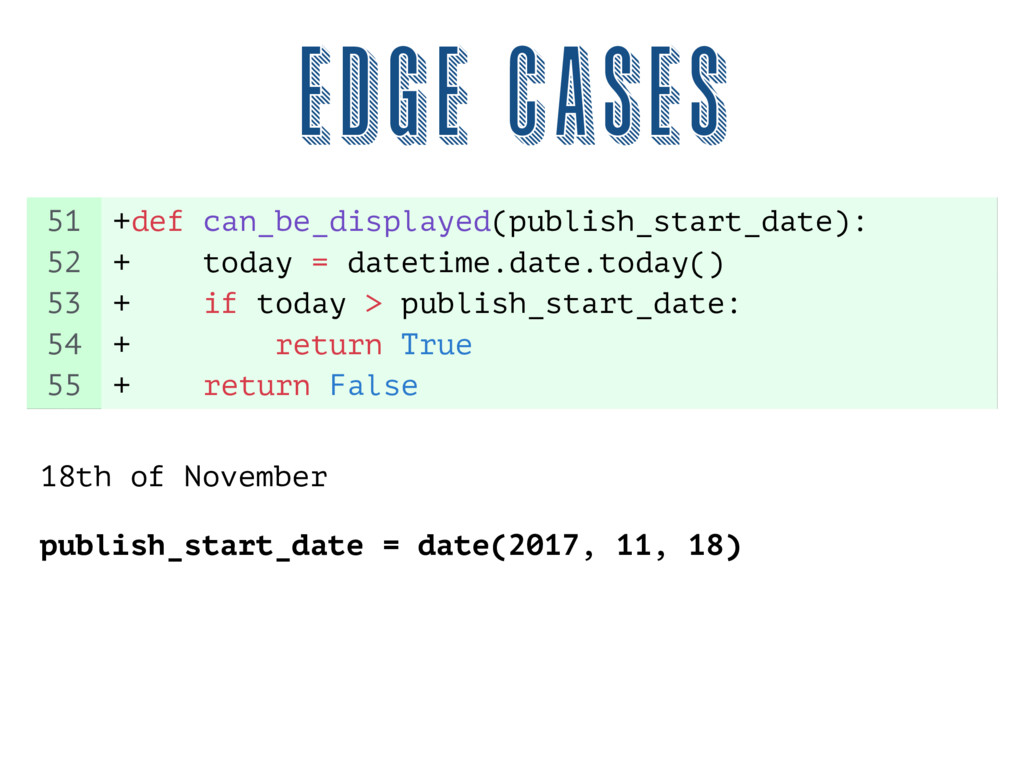
+def can_be_displayed(publish_start_date): + today = datetime.date.today() + if today >
publish_start_date: + return True + return False 51 52 53 54 55 18th of November Edge cases -
+def can_be_displayed(publish_start_date): + today = datetime.date.today() + if today >
publish_start_date: + return True + return False 51 52 53 54 55 18th of November publish_start_date = date(2017, 11, 18) Edge cases -
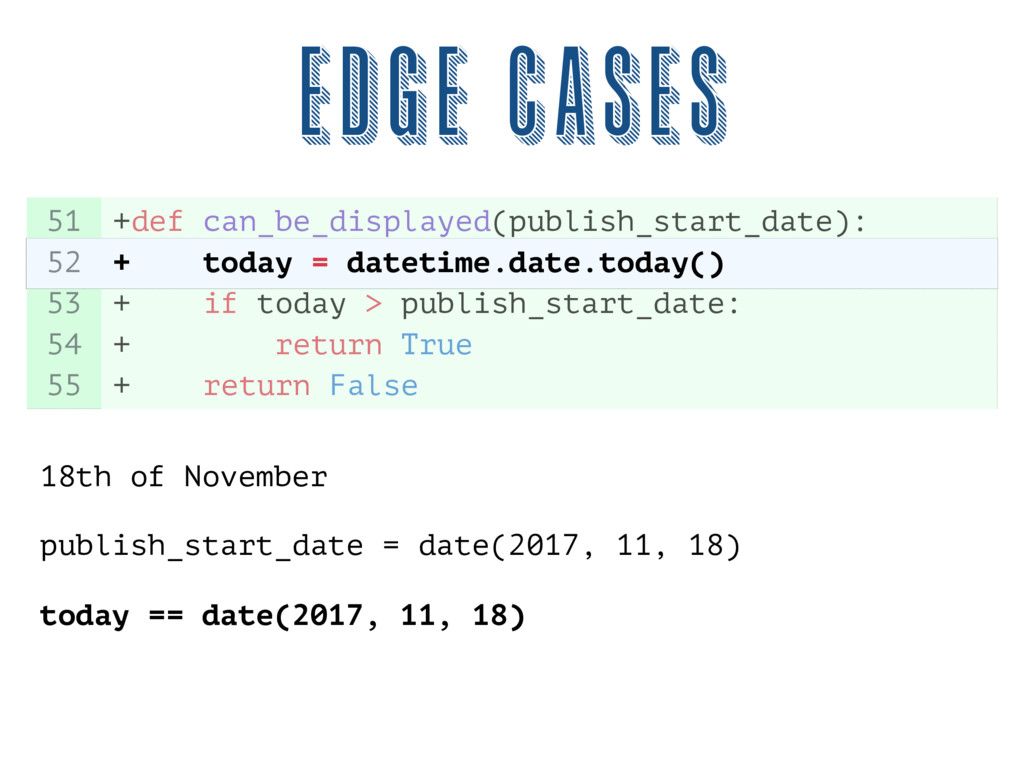
+def can_be_displayed(publish_start_date): + today = datetime.datetime.utcnow().date() + if today >
publish_start_date: + return True + return False 51 52 53 54 55 + today = datetime.date.today() 18th of November publish_start_date = date(2017, 11, 18) today == date(2017, 11, 18) Edge cases -
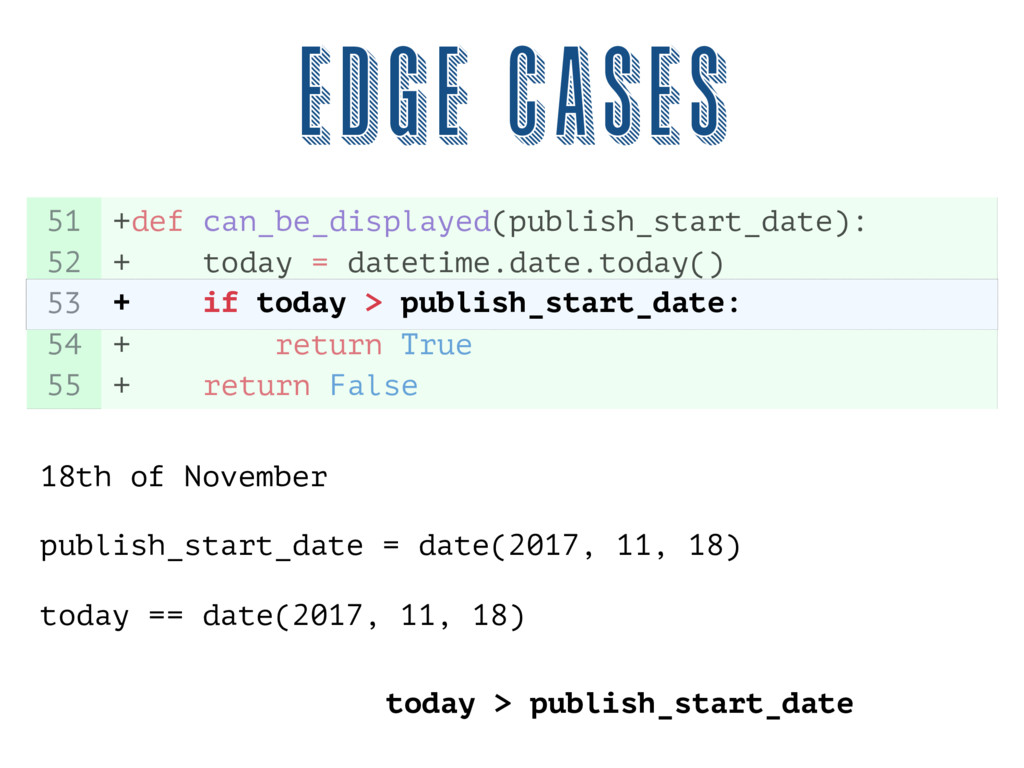
+def can_be_displayed(publish_start_date): + today = datetime.date.today() + if today >
publish_start_date: + return True + return False 51 52 53 54 55 + if today > publish_start_date: 18th of November publish_start_date = date(2017, 11, 18) today == date(2017, 11, 18) today > publish_start_date Edge cases -
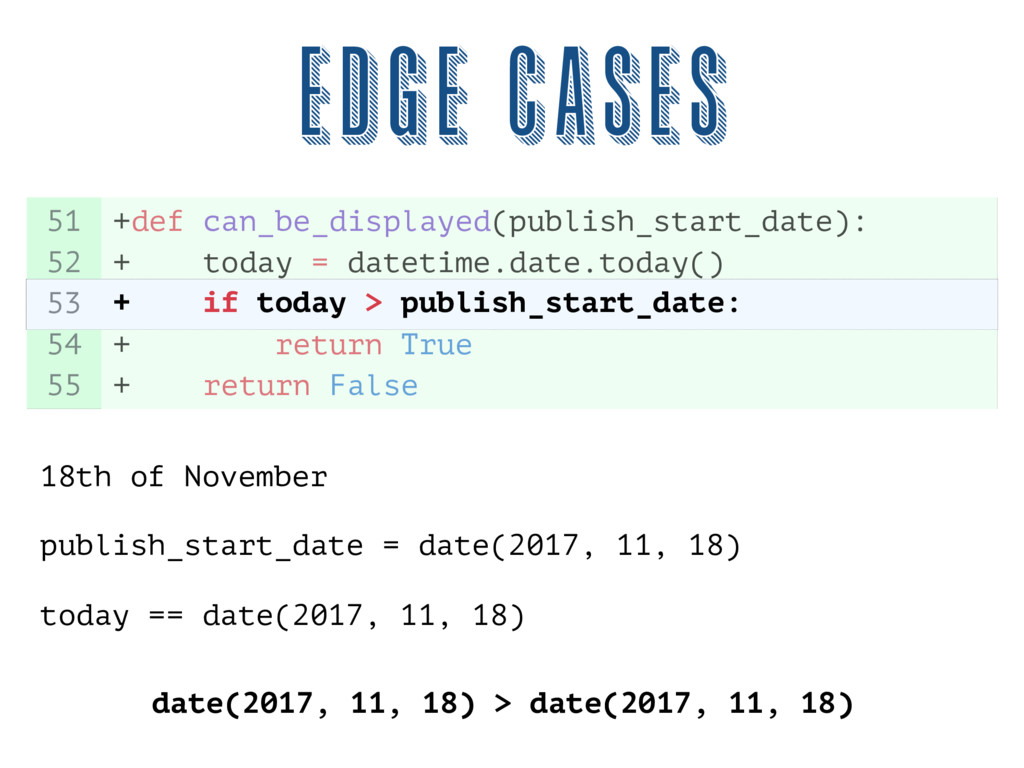
+def can_be_displayed(publish_start_date): + today = datetime.date.today() + if today >
publish_start_date: + return True + return False 51 52 53 54 55 + if today > publish_start_date: 18th of November publish_start_date = date(2017, 11, 18) today == date(2017, 11, 18) date(2017, 11, 18) > date(2017, 11, 18) Edge cases -
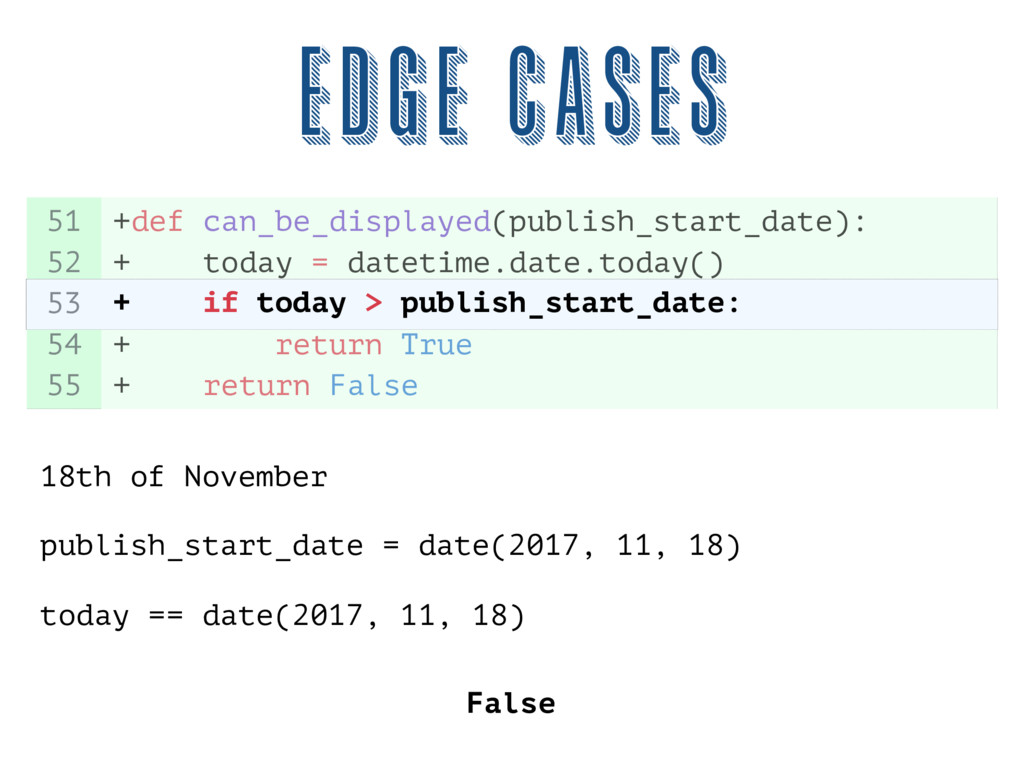
+def can_be_displayed(publish_start_date): + today = datetime.date.today() + if today >
publish_start_date: + return True + return False 51 52 53 54 55 + if today > publish_start_date: 18th of November publish_start_date = date(2017, 11, 18) today == date(2017, 11, 18) False Edge cases -
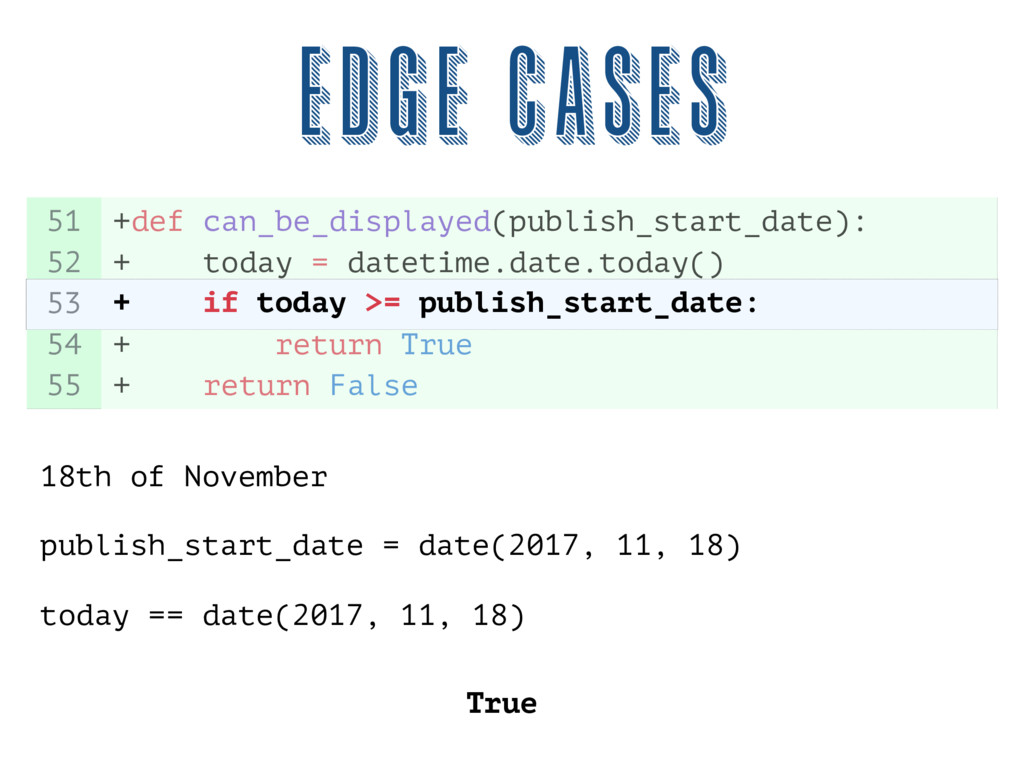
+def can_be_displayed(publish_start_date): + today = datetime.date.today() + if today >
publish_start_date: + return True + return False 51 52 53 54 55 + if today >= publish_start_date: 18th of November publish_start_date = date(2017, 11, 18) today == date(2017, 11, 18) True Edge cases -
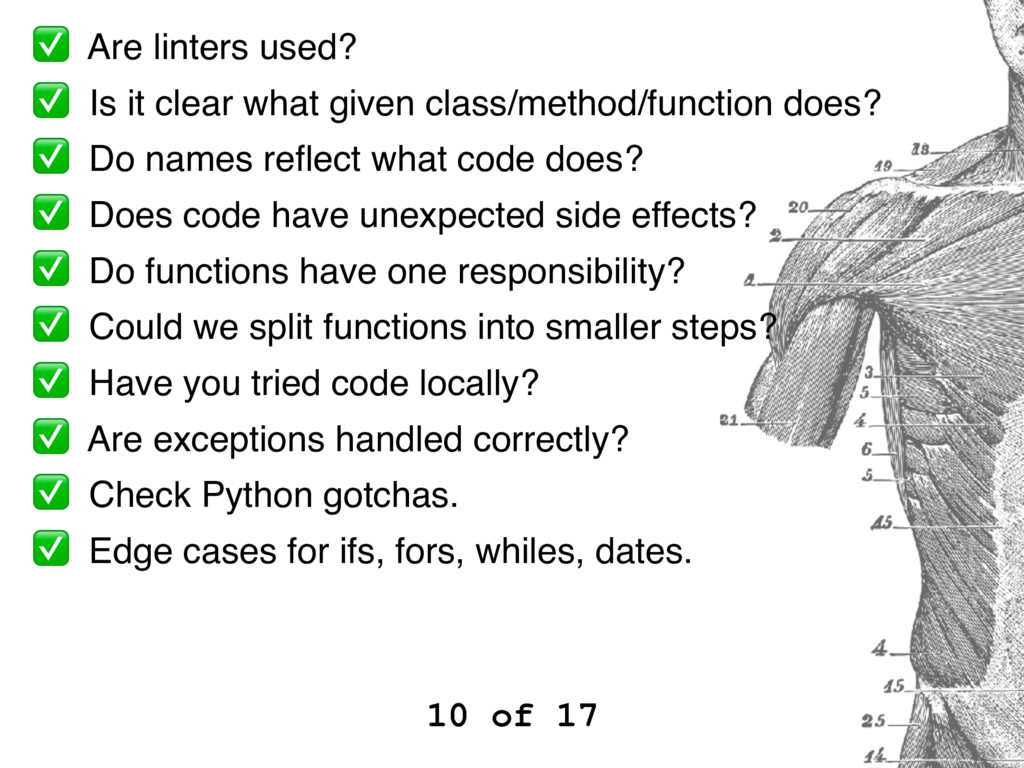
✅ Are linters used? ✅ Is it clear what given
class/method/function does? ✅ Do names reflect what code does? ✅ Does code have unexpected side effects? ✅ Do functions have one responsibility? ✅ Could we split functions into smaller steps? ✅ Have you tried code locally? ✅ Are exceptions handled correctly? ✅ Check Python gotchas. ✅ Edge cases for ifs, fors, whiles, dates. 10 of 17 -
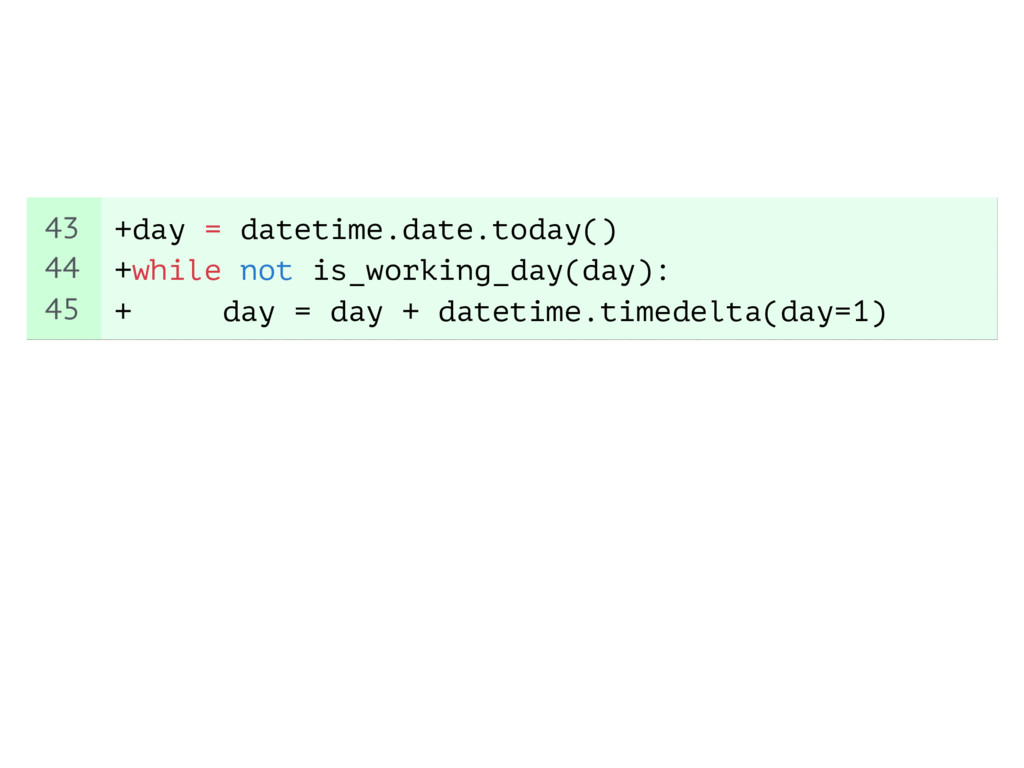
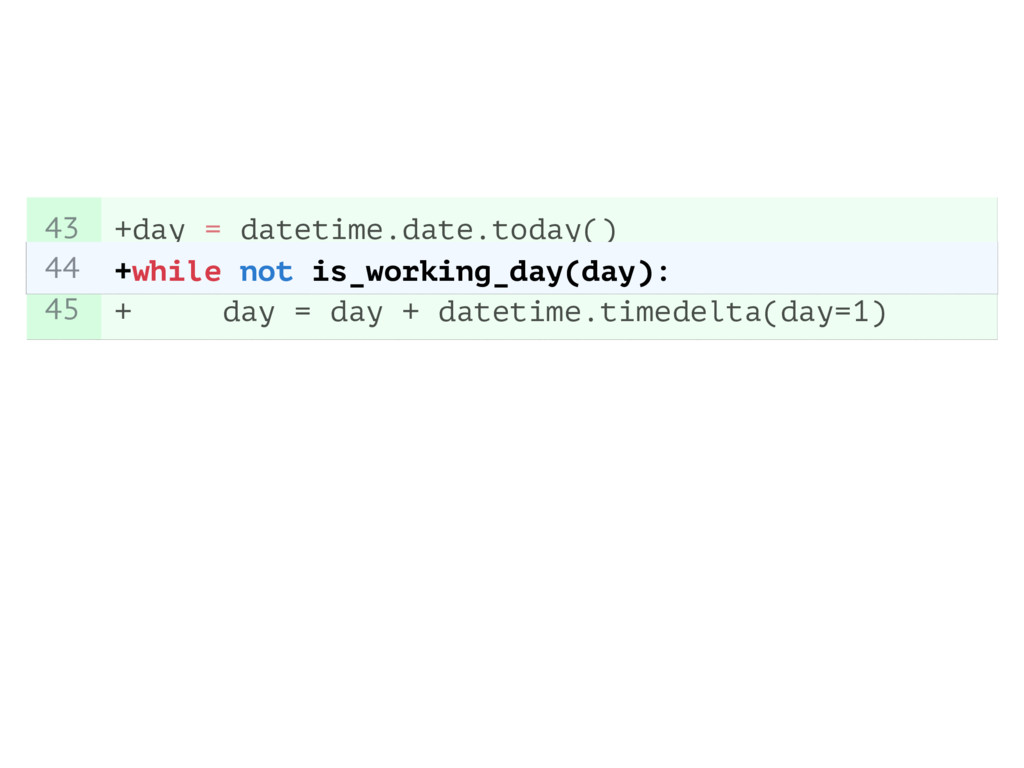
+day = datetime.date.today() +while not is_working_day(day): + day = day
+ datetime.timedelta(day=1) 43 44 45 -
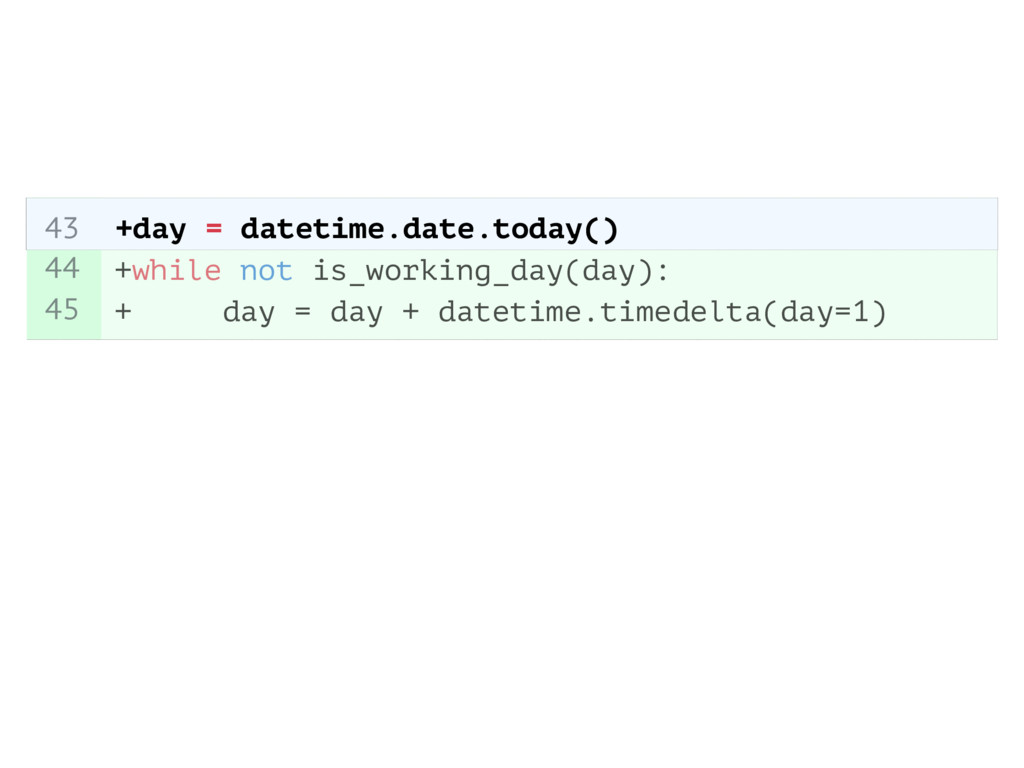
+day = datetime.date.today() +while not is_working_day(day): + day = day
+ datetime.timedelta(day=1) 43 44 45 +day = datetime.date.today() -
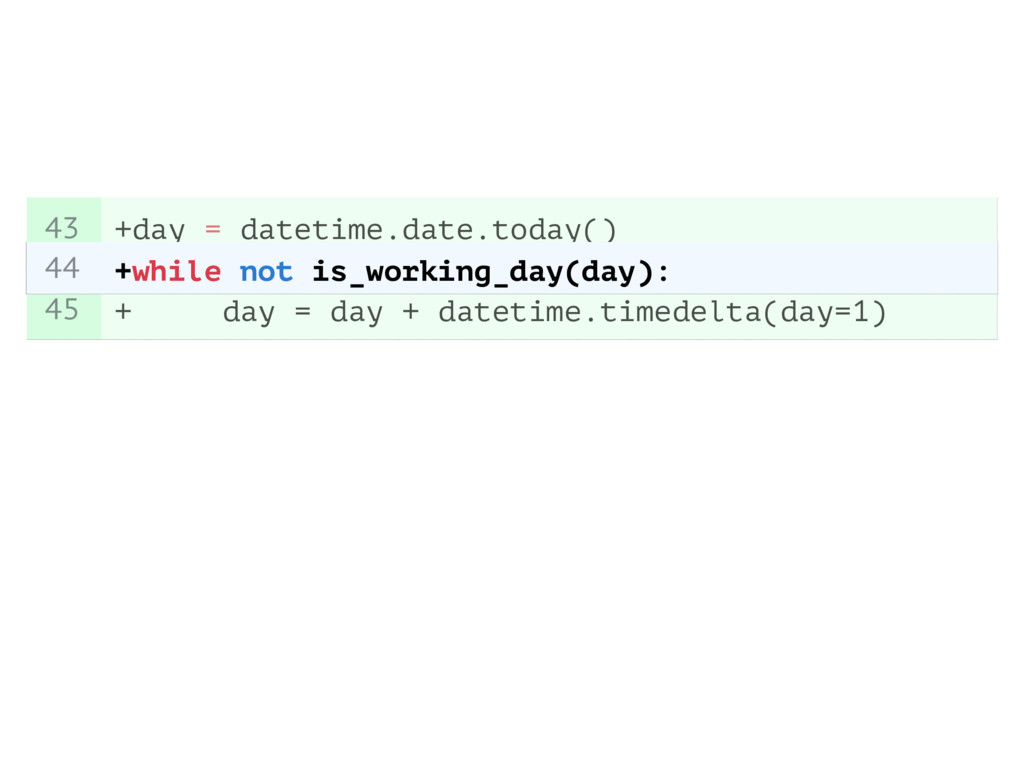
+day = datetime.date.today() +while not is_working_day(day): + day = day
+ datetime.timedelta(day=1) 43 44 45 +while not is_working_day(day): -
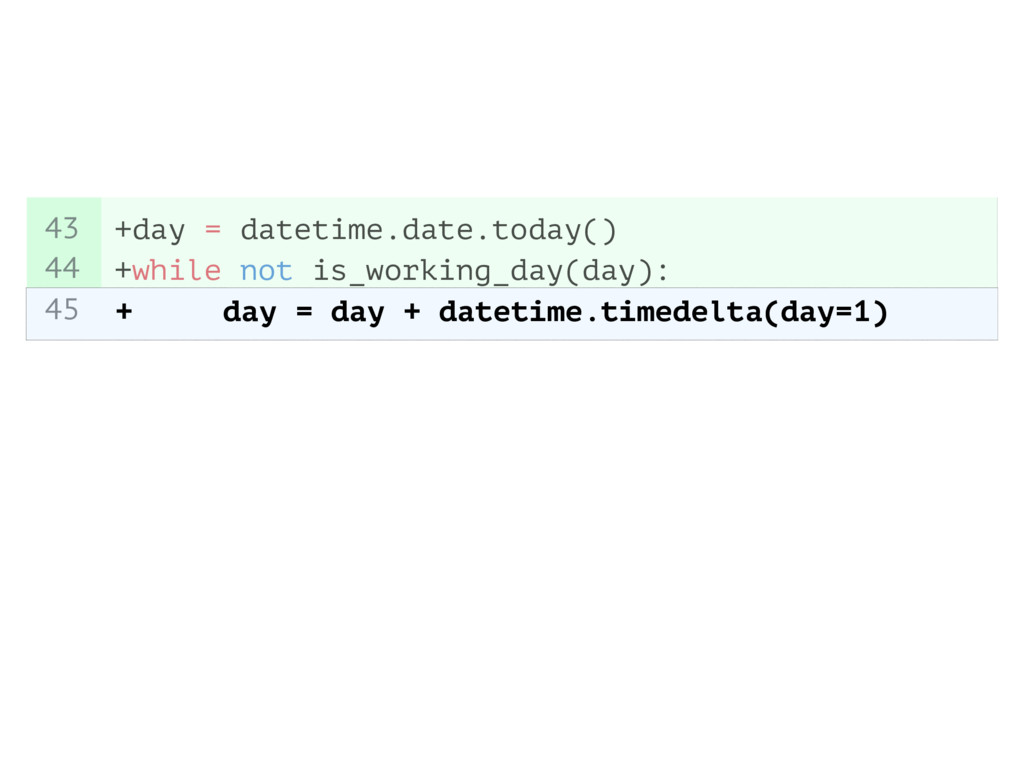
+day = datetime.date.today() +while not is_working_day(day): + day = day
+ datetime.timedelta(day=1) 43 44 45 + day = day + datetime.timedelta(day=1) -
+day = datetime.date.today() +while not is_working_day(day): + day = day
+ datetime.timedelta(day=1) 43 44 45 +while not is_working_day(day): -
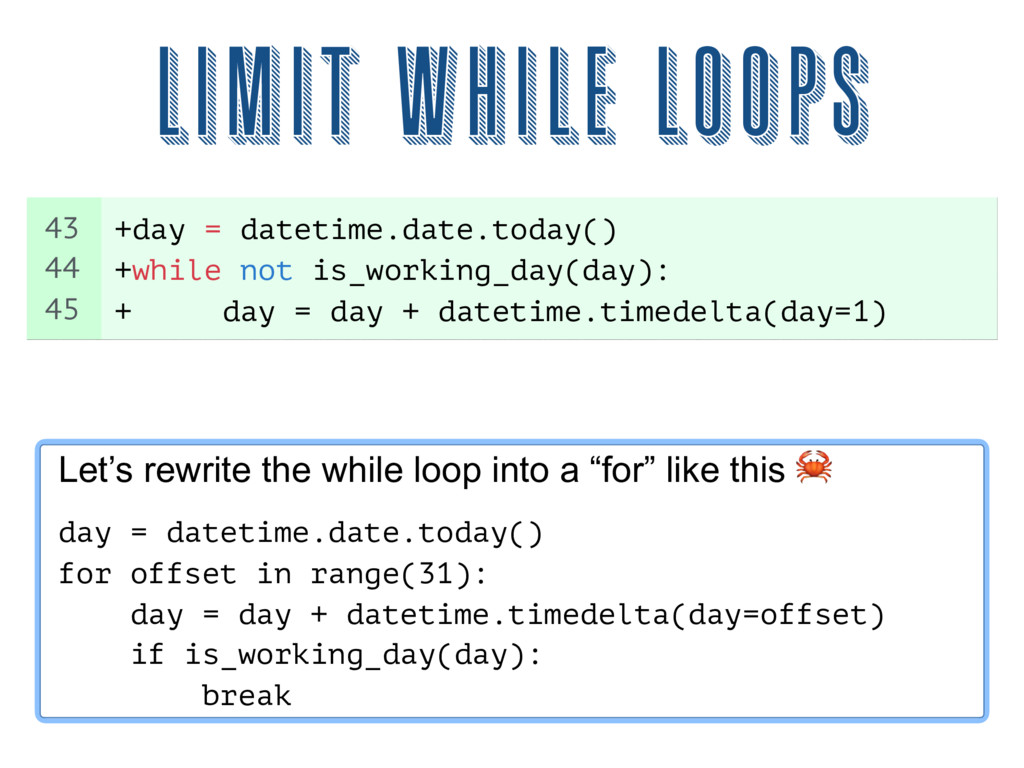
Let’s rewrite the while loop into a “for” like this
. day = datetime.date.today() for offset in range(31): day = day + datetime.timedelta(day=offset) if is_working_day(day): break Limit while loops +day = datetime.date.today() +while not is_working_day(day): + day = day + datetime.timedelta(day=1) 43 44 45 -
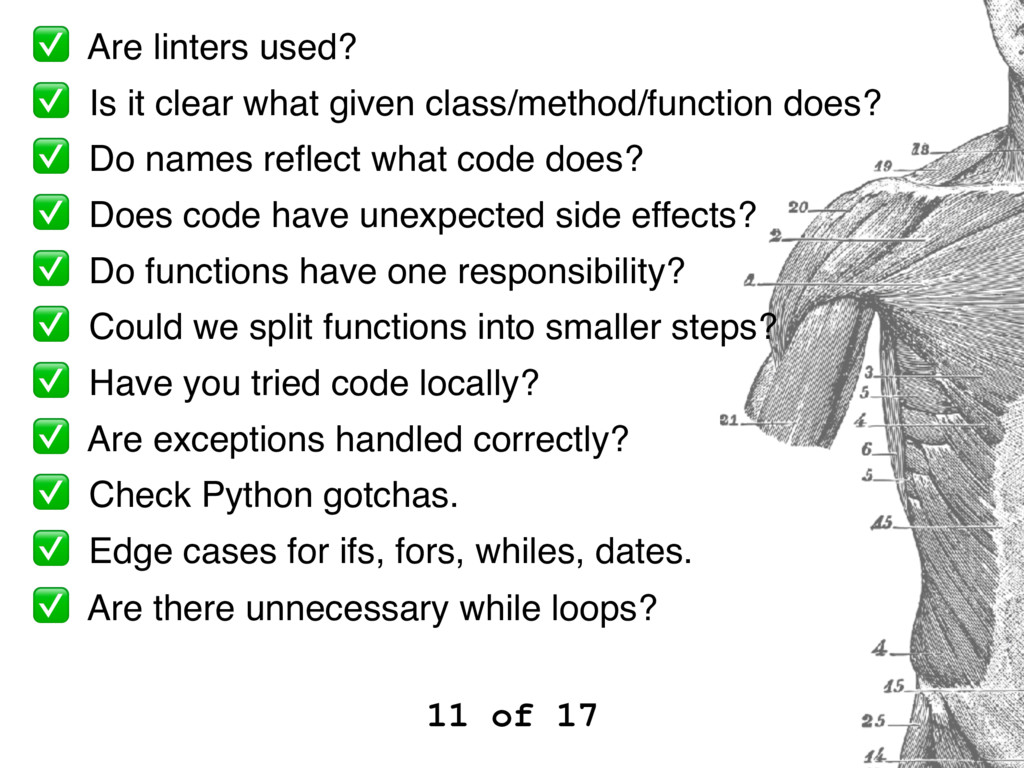
✅ Are linters used? ✅ Is it clear what given
class/method/function does? ✅ Do names reflect what code does? ✅ Does code have unexpected side effects? ✅ Do functions have one responsibility? ✅ Could we split functions into smaller steps? ✅ Have you tried code locally? ✅ Are exceptions handled correctly? ✅ Check Python gotchas. ✅ Edge cases for ifs, fors, whiles, dates. ✅ Are there unnecessary while loops? 11 of 17 -
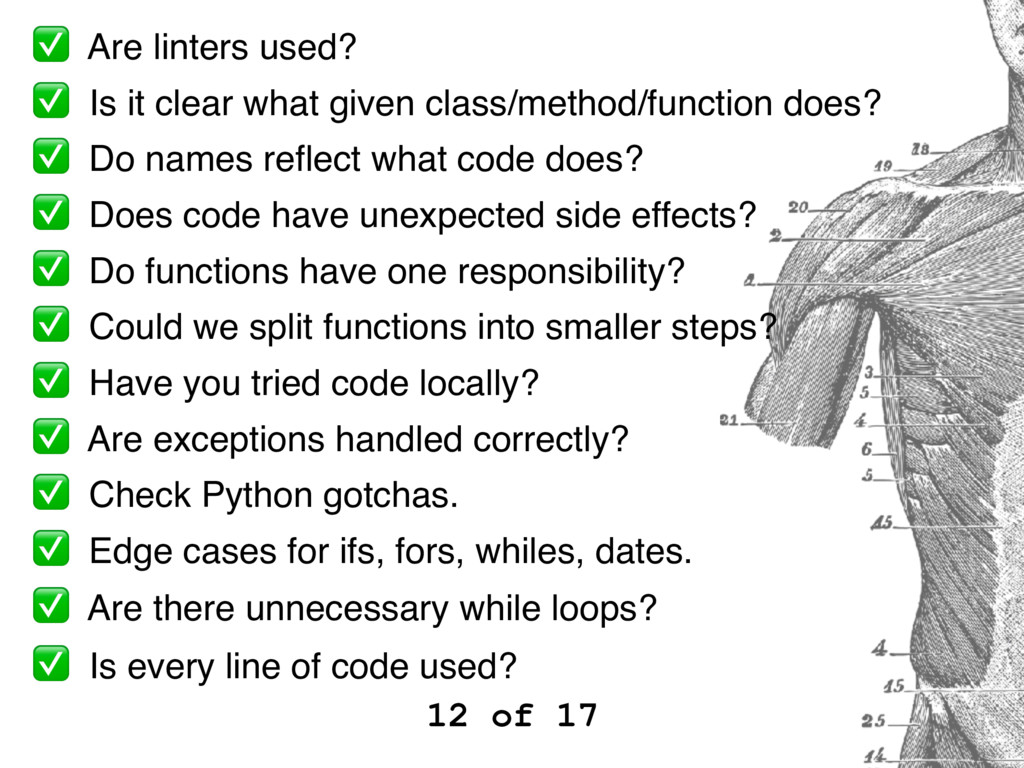
✅ Are linters used? ✅ Is it clear what given
class/method/function does? ✅ Do names reflect what code does? ✅ Does code have unexpected side effects? ✅ Do functions have one responsibility? ✅ Could we split functions into smaller steps? ✅ Have you tried code locally? ✅ Are exceptions handled correctly? ✅ Check Python gotchas. ✅ Edge cases for ifs, fors, whiles, dates. ✅ Are there unnecessary while loops? ✅ Is every line of code used? 12 of 17 -
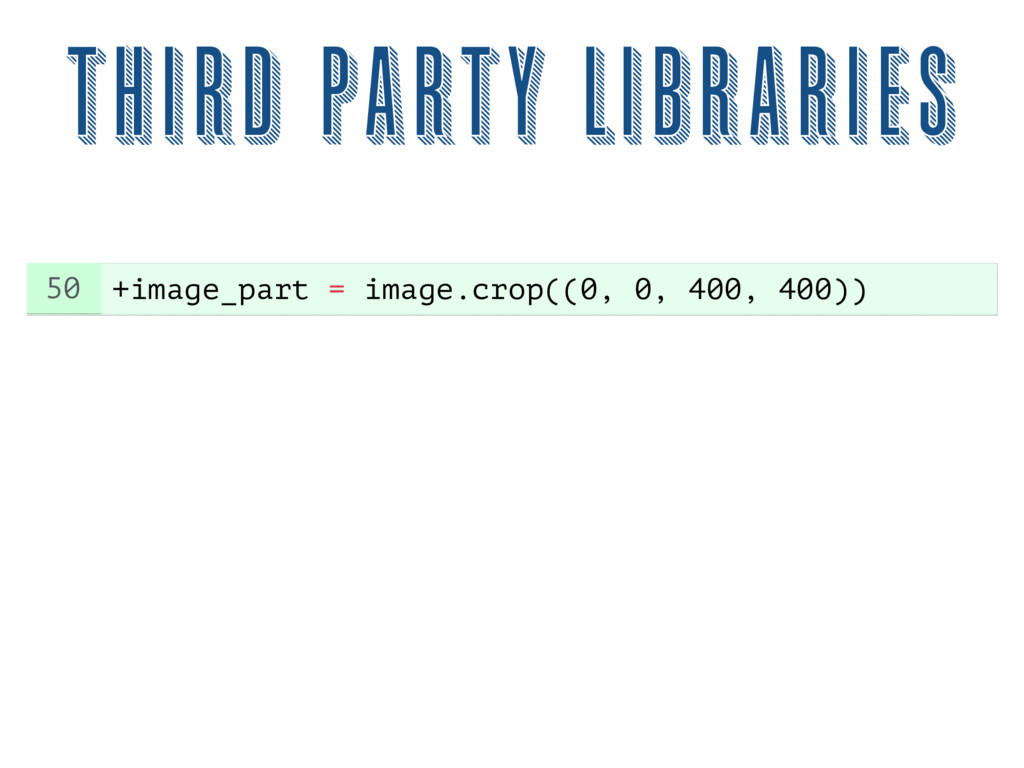
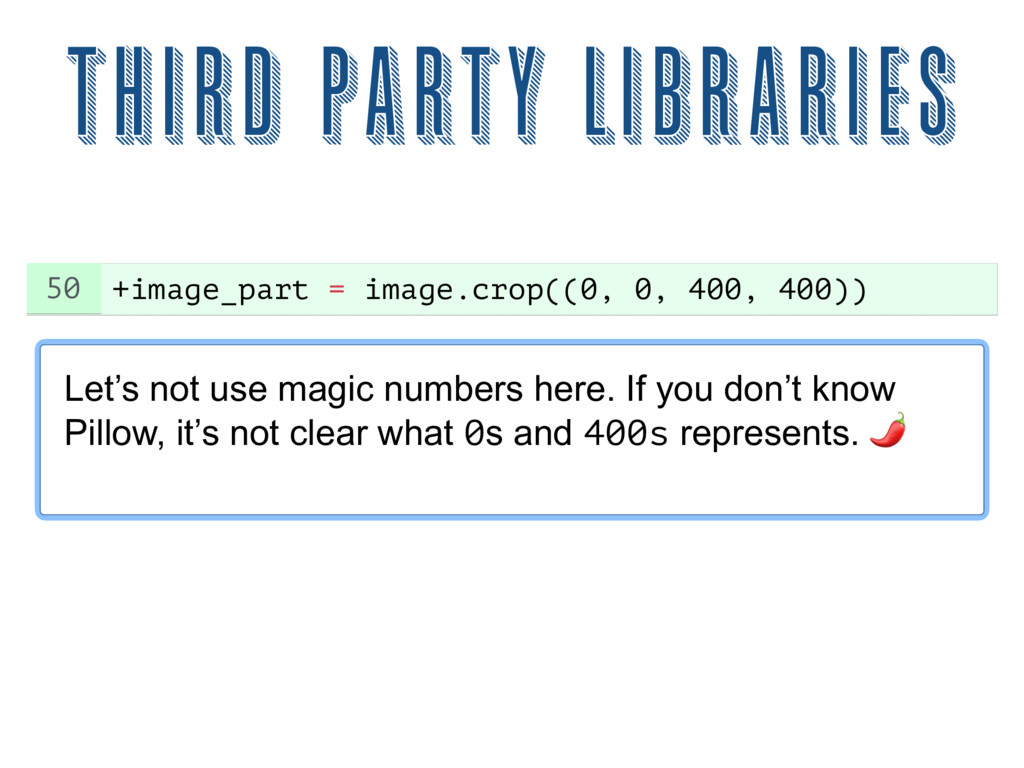
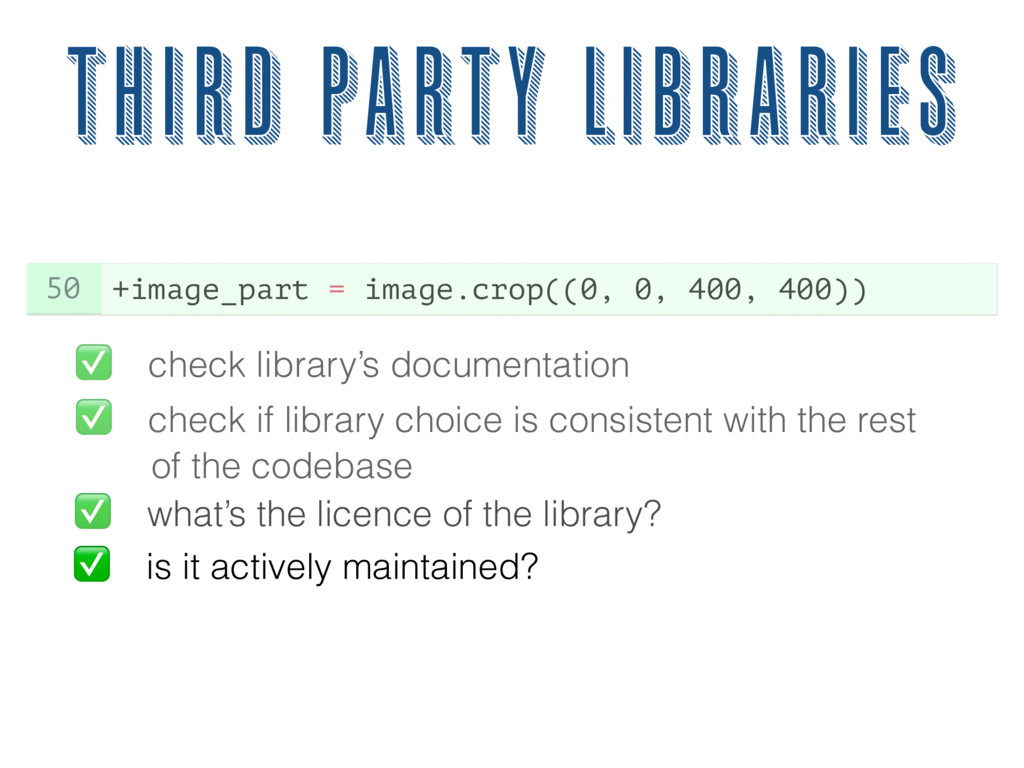
+image_part = image.crop((0, 0, 400, 400)) 50 Let’s not use
magic numbers here. If you don’t know Pillow, it’s not clear what 0s and 400s represents. 0 Third party libraries -
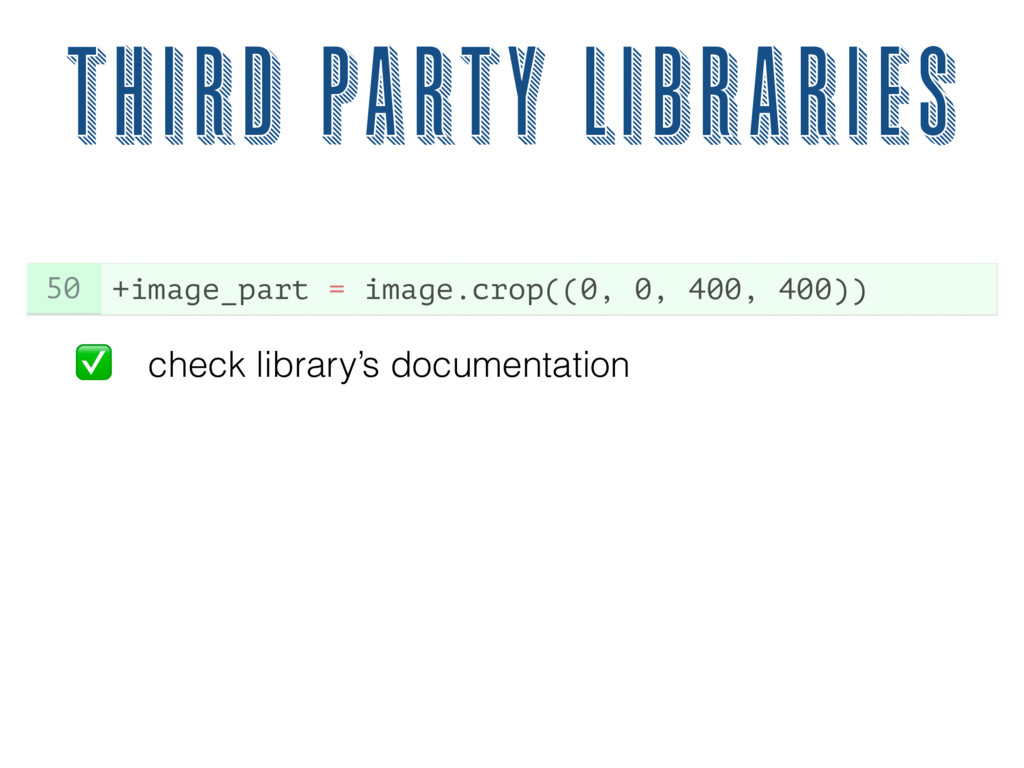
+image_part = image.crop((0, 0, 400, 400)) 50 Third party libraries
✅ check library’s documentation -
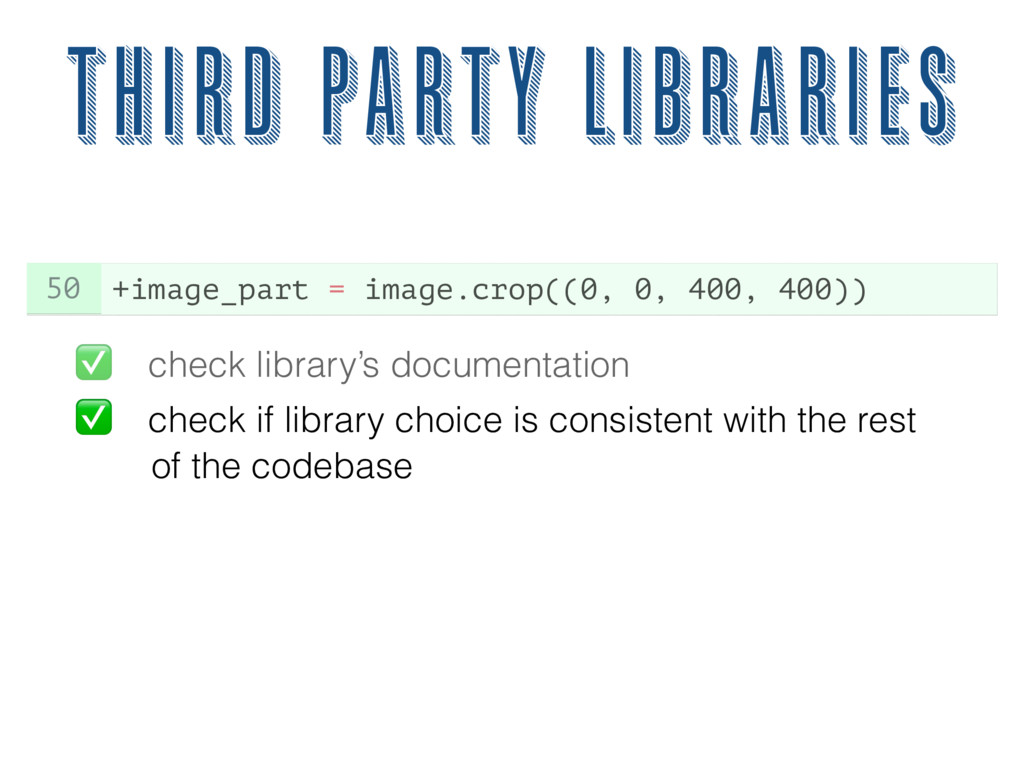
+image_part = image.crop((0, 0, 400, 400)) 50 Third party libraries
✅ check library’s documentation ✅ check if library choice is consistent with the rest of the codebase -
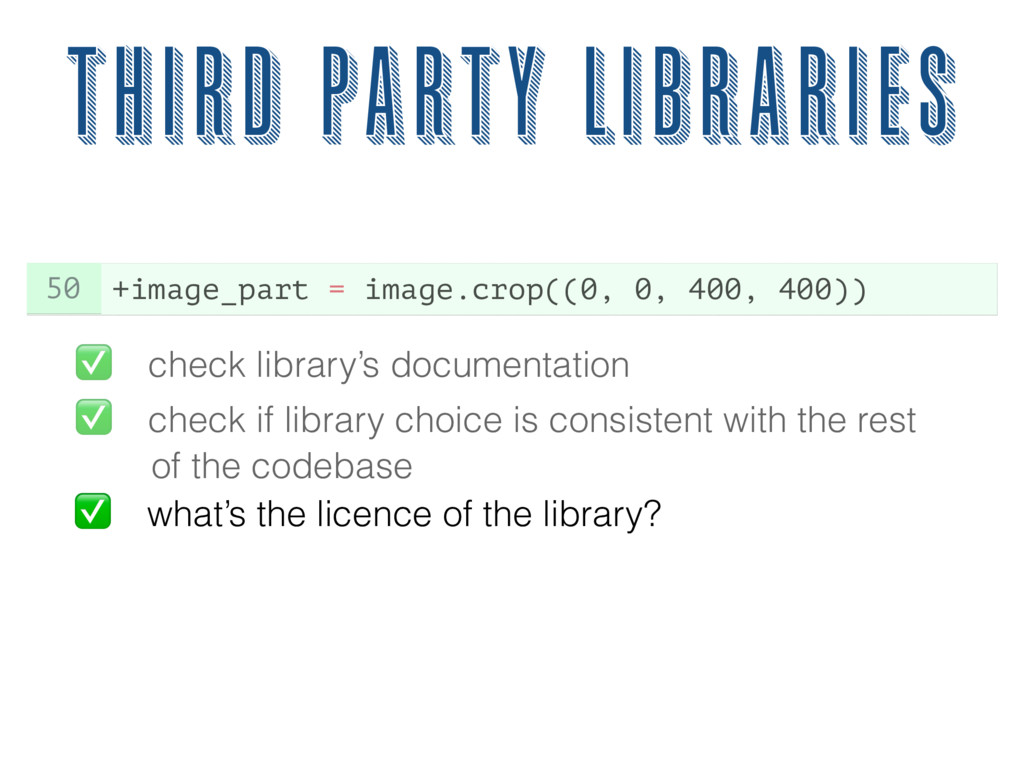
+image_part = image.crop((0, 0, 400, 400)) 50 Third party libraries
✅ check library’s documentation ✅ check if library choice is consistent with the rest of the codebase ✅ what’s the licence of the library? -
+image_part = image.crop((0, 0, 400, 400)) 50 Third party libraries
✅ check library’s documentation ✅ check if library choice is consistent with the rest of the codebase ✅ what’s the licence of the library? ✅ is it actively maintained? -
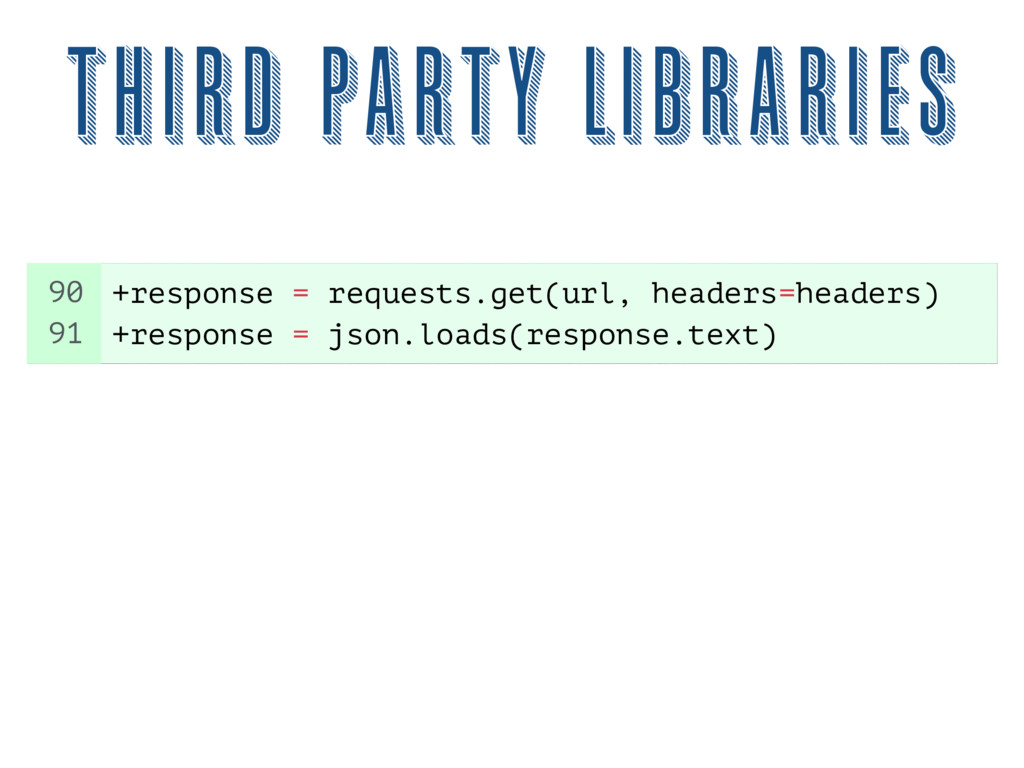
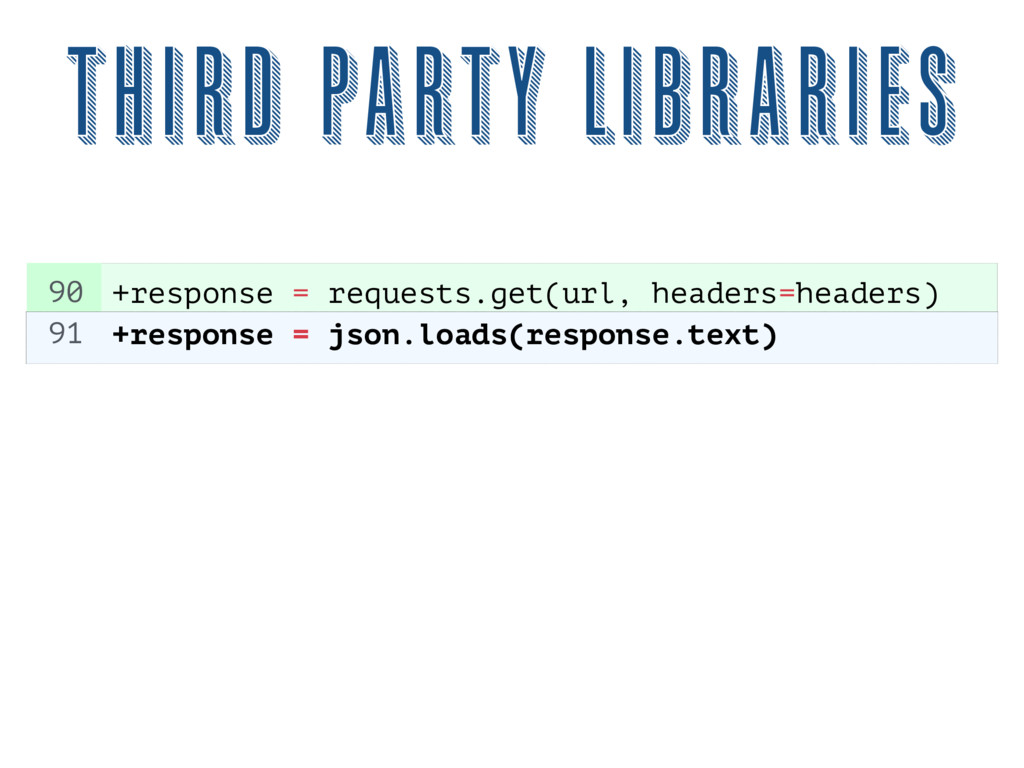
+response = requests.get(url, headers=headers) +response = json.loads(response) 90 91 Third
party libraries +response = json.loads(response.text) -
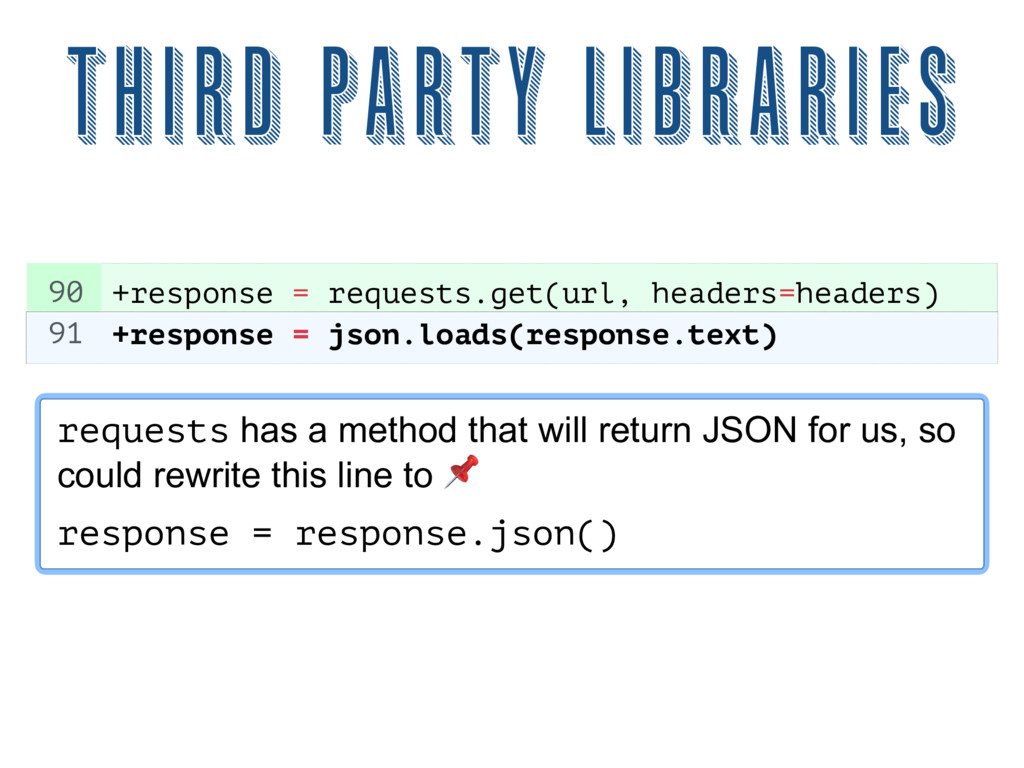
+response = requests.get(url, headers=headers) +response = json.loads(response) 90 91 Third
party libraries +response = json.loads(response.text) requests has a method that will return JSON for us, so could rewrite this line to 1 response = response.json() -
✅ Are linters used? ✅ Is it clear what given
class/method/function does? ✅ Do names reflect what code does? ✅ Does code have unexpected side effects? ✅ Do functions have one responsibility? ✅ Could we split functions into smaller steps? ✅ Have you tried code locally? ✅ Are exceptions handled correctly? ✅ Check Python gotchas. ✅ Edge cases for ifs, fors, whiles, dates. ✅ Are there unnecessary while loops? ✅ Is every line of code used? -
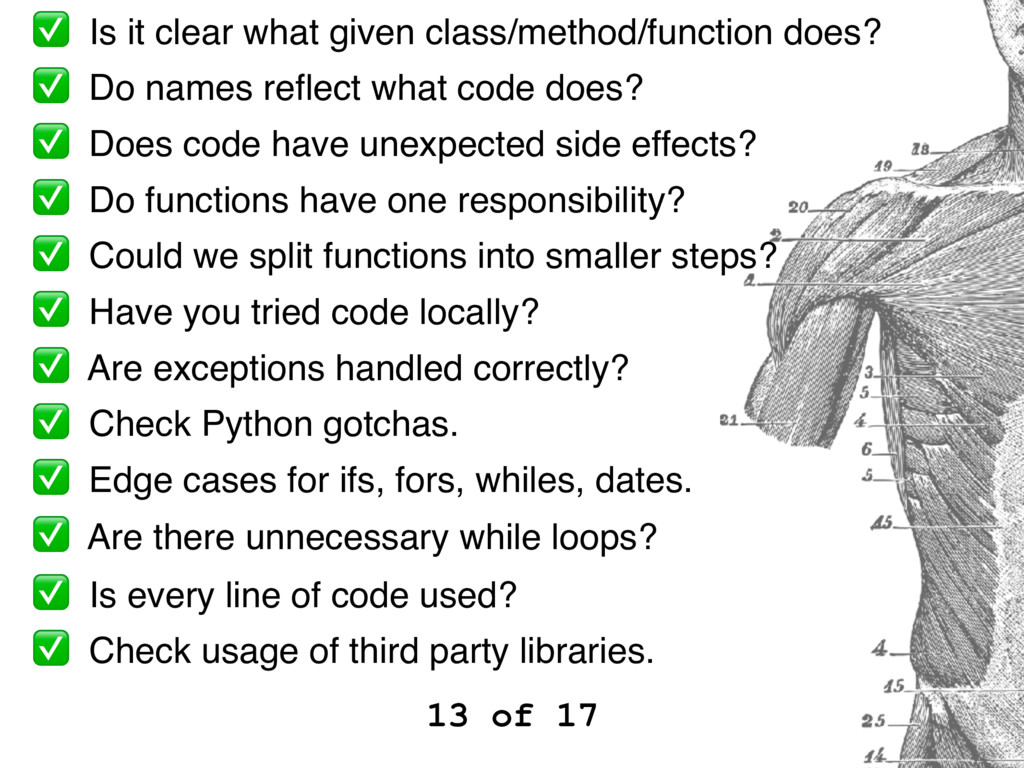
✅ Is it clear what given class/method/function does? ✅ Do
names reflect what code does? ✅ Does code have unexpected side effects? ✅ Do functions have one responsibility? ✅ Could we split functions into smaller steps? ✅ Have you tried code locally? ✅ Are exceptions handled correctly? ✅ Check Python gotchas. ✅ Edge cases for ifs, fors, whiles, dates. ✅ Are there unnecessary while loops? ✅ Is every line of code used? ✅ Check usage of third party libraries. 13 of 17 -
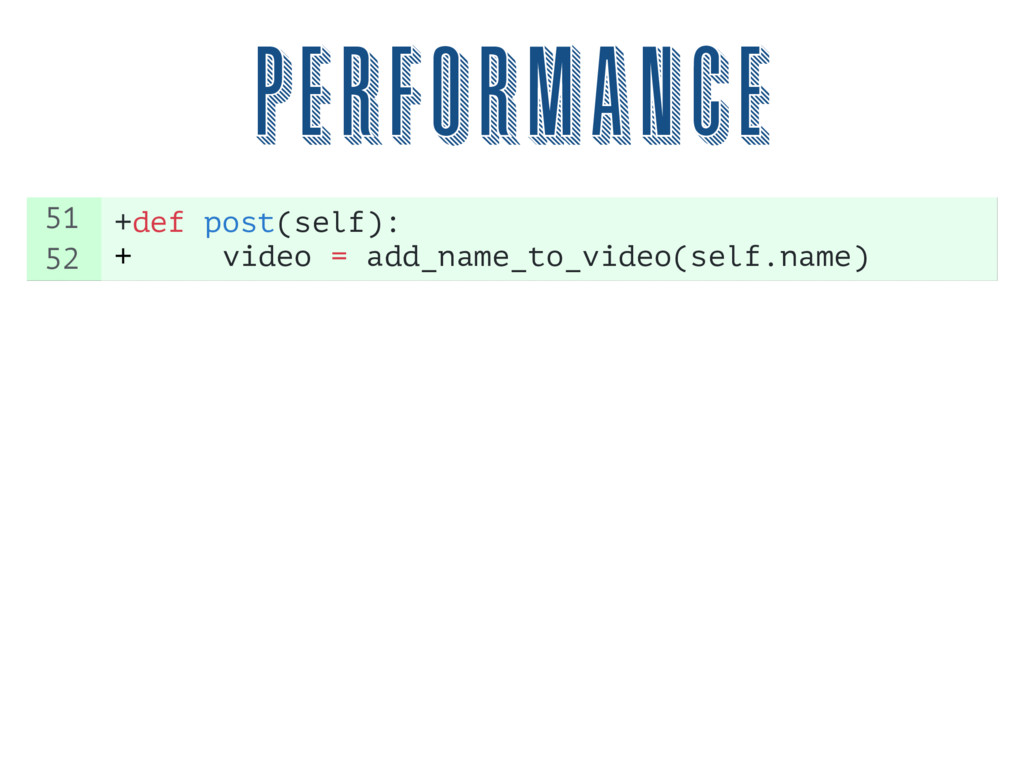
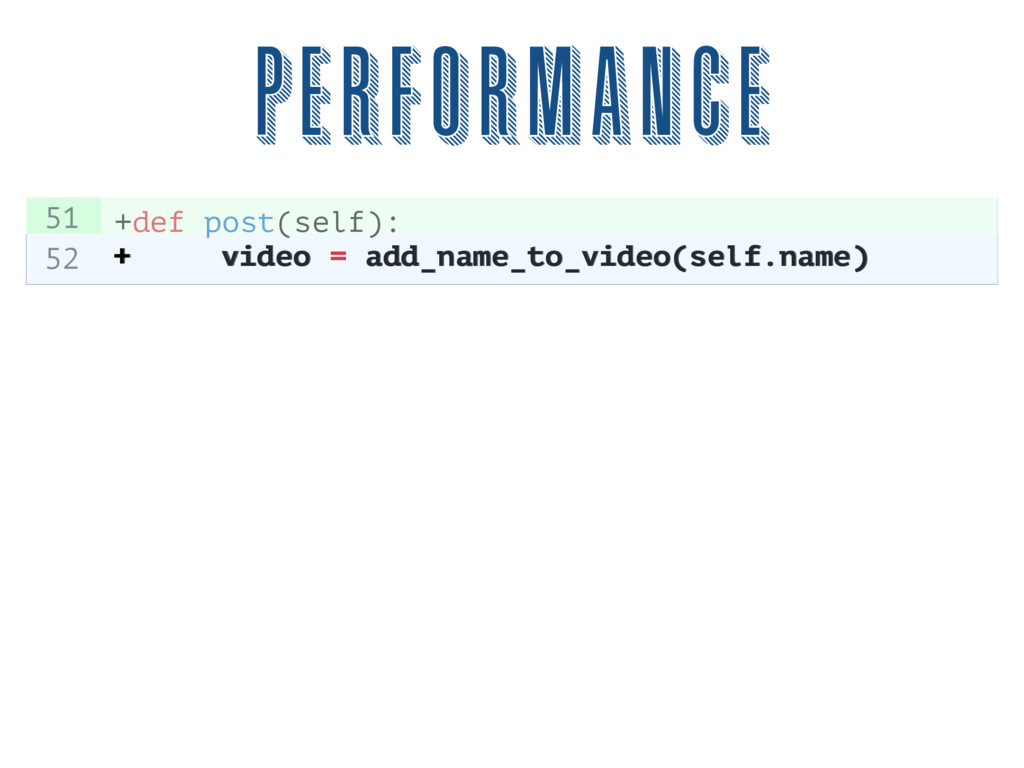
51 52 Performance +def post(self): + video = add_name_to_video(self.name) +
video = add_name_to_video(self.name) -
✅ Are linters used? ✅ Is it clear what given
class/method/function does? ✅ Do names reflect what code does? ✅ Does code have unexpected side effects? ✅ Do functions have one responsibility? ✅ Could we split functions into smaller steps? ✅ Have you tried code locally? ✅ Are exceptions handled correctly? ✅ Check Python gotchas. ✅ Edge cases for ifs, fors, whiles, dates. ✅ Are there unnecessary while loops? ✅ Is every line of code used? ✅ Check usage of third party libraries. -
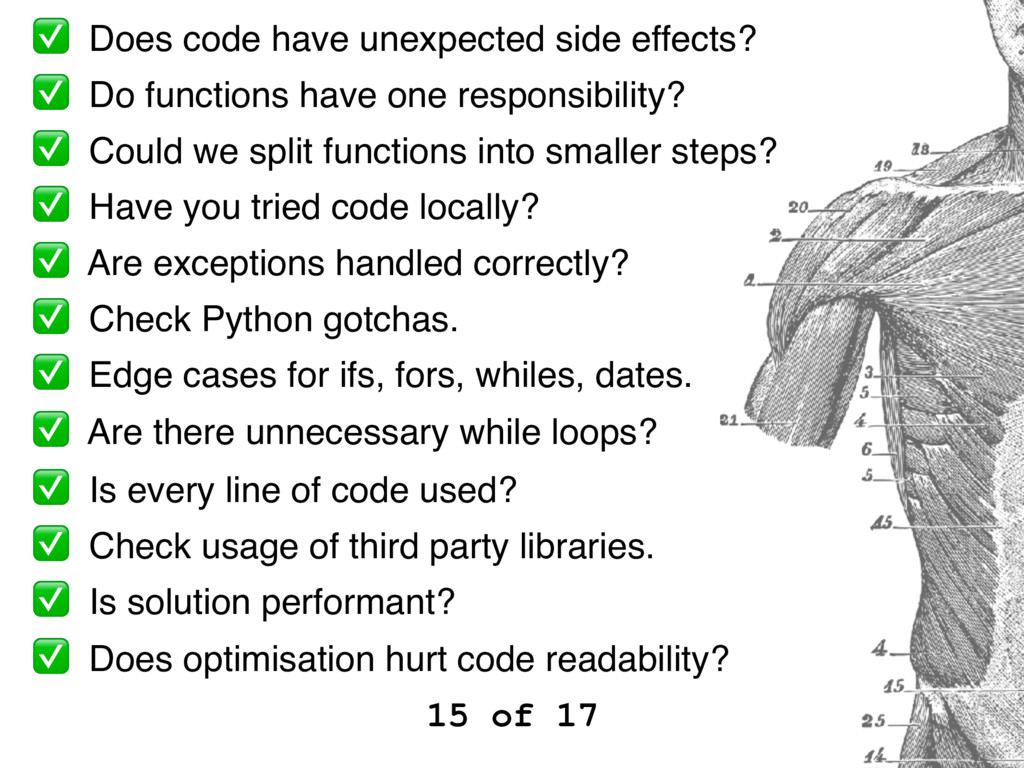
✅ Does code have unexpected side effects? ✅ Do functions
have one responsibility? ✅ Could we split functions into smaller steps? ✅ Have you tried code locally? ✅ Are exceptions handled correctly? ✅ Check Python gotchas. ✅ Edge cases for ifs, fors, whiles, dates. ✅ Are there unnecessary while loops? ✅ Is every line of code used? ✅ Check usage of third party libraries. ✅ Is solution performant? ✅ Does optimisation hurt code readability? 15 of 17 -
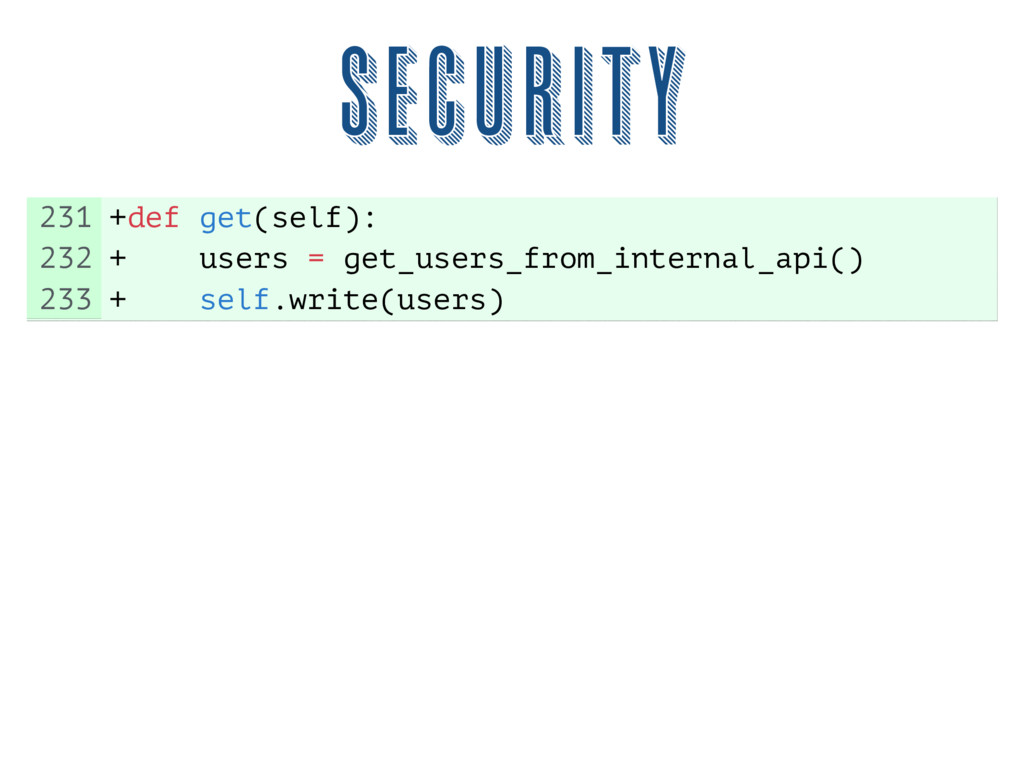
231 232 233 Security +def get(self): + users = get_users_from_internal_api()
+ self.write(users) -
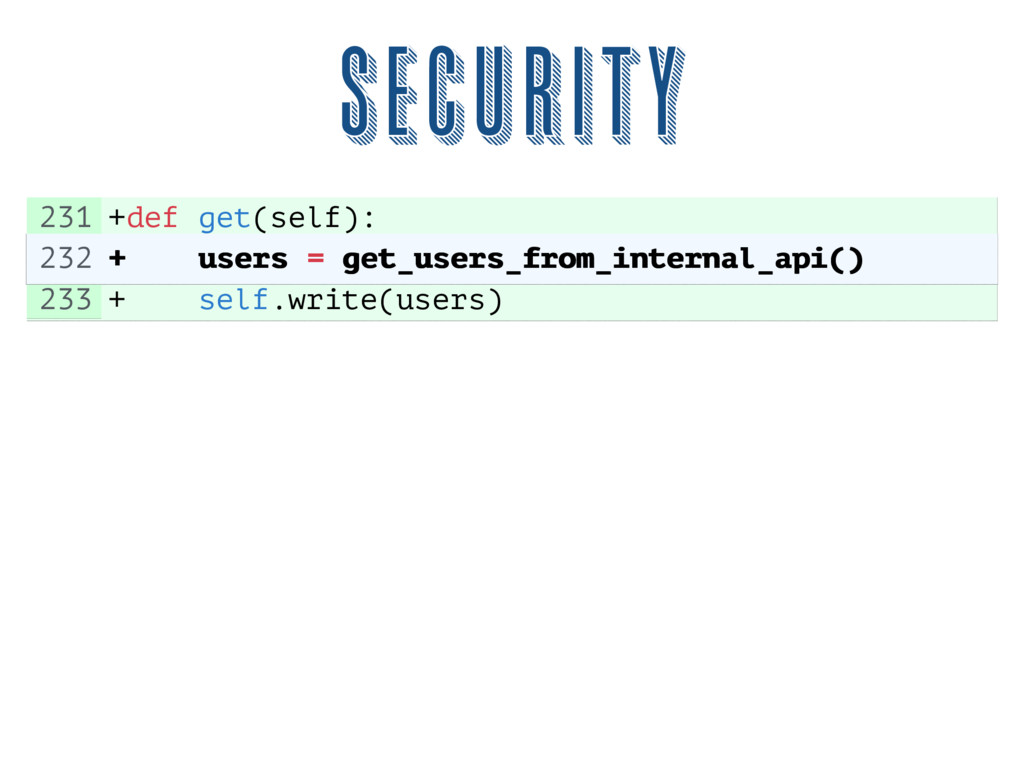
231 232 233 Security +def get(self): + users = get_users_from_internal_api()
+ self.write(users) + users = get_users_from_internal_api() -
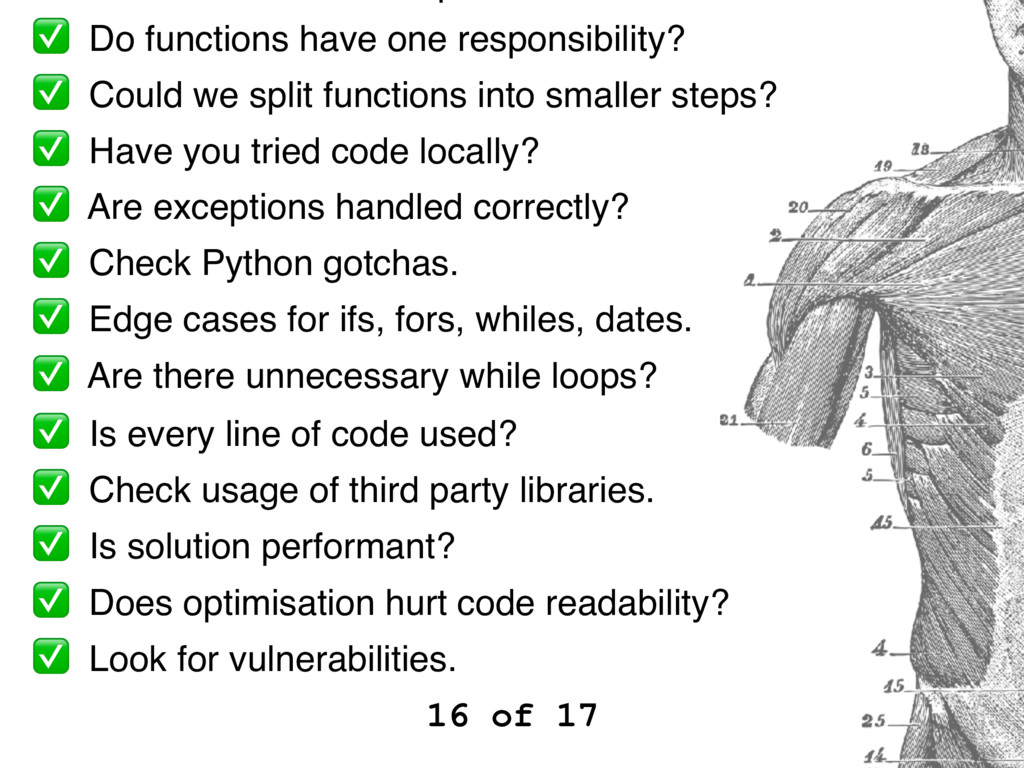
✅ Do functions have one responsibility? ✅ Could we split
functions into smaller steps? ✅ Have you tried code locally? ✅ Are exceptions handled correctly? ✅ Check Python gotchas. ✅ Edge cases for ifs, fors, whiles, dates. ✅ Are there unnecessary while loops? ✅ Is every line of code used? ✅ Check usage of third party libraries. ✅ Is solution performant? ✅ Does optimisation hurt code readability? ✅ Look for vulnerabilities. 16 of 17 -
what is missing? ✅ Tests ✅ Cache ✅ Metrics ✅
Logging errors ✅ Documentation -
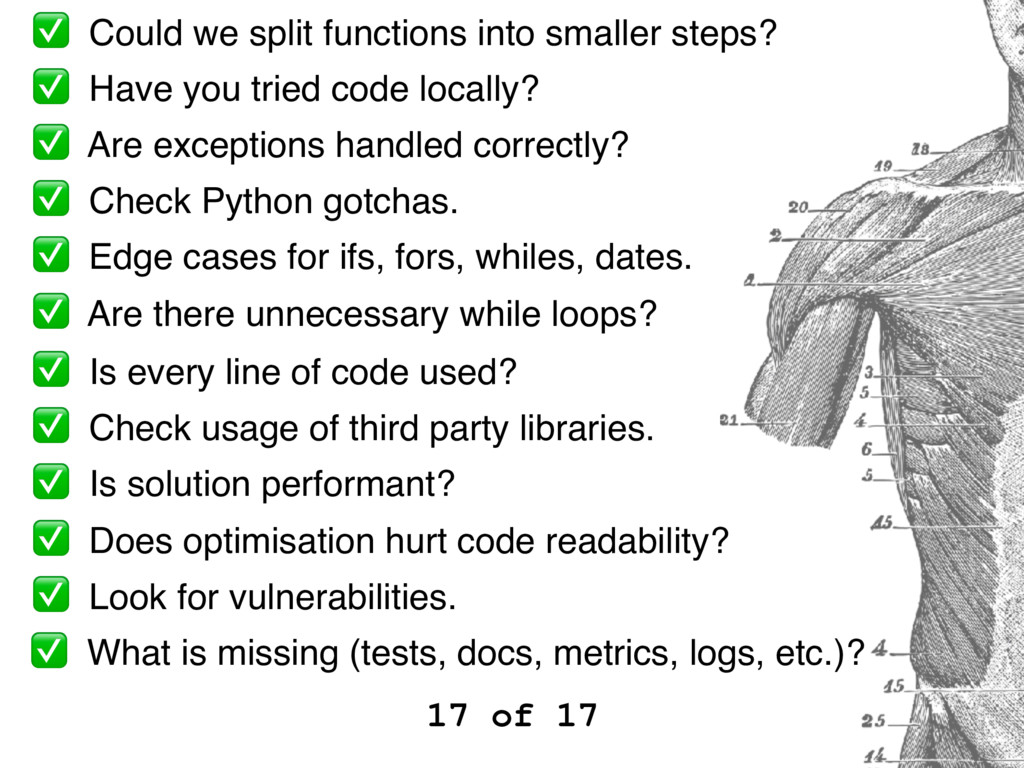
✅ Could we split functions into smaller steps? ✅ Have
you tried code locally? ✅ Are exceptions handled correctly? ✅ Check Python gotchas. ✅ Edge cases for ifs, fors, whiles, dates. ✅ Are there unnecessary while loops? ✅ Is every line of code used? ✅ Check usage of third party libraries. ✅ Is solution performant? ✅ Does optimisation hurt code readability? ✅ Look for vulnerabilities. ✅ What is missing (tests, docs, metrics, logs, etc.)? 17 of 17 -
Why? Alberto Bacchelli, Christian Bird 1. Finding defects 2. Code
improvements 3. Finding alternative solutions 4. Knowledge transfer 5. Team awareness 6. Improving dev process -
Why? Alberto Bacchelli, Christian Bird 1. Finding defects 2. Code
improvements 3. Finding alternative solutions 4. Knowledge transfer 5. Team awareness 6. Improving dev process -
Why? Alberto Bacchelli, Christian Bird 1. Finding defects 2. Code
improvements 3. Finding alternative solutions 4. Knowledge transfer 5. Team awareness 6. Improving dev process -
Why? Alberto Bacchelli, Christian Bird 1. Finding defects 2. Code
improvements 3. Finding alternative solutions 4. Knowledge transfer 5. Team awareness 6. Improving dev process -
Why? Alberto Bacchelli, Christian Bird 1. Finding defects 2. Code
improvements 3. Finding alternative solutions 4. Knowledge transfer 5. Team awareness 6. Improving dev process -
Why? Alberto Bacchelli, Christian Bird 1. Finding defects 2. Code
improvements 3. Finding alternative solutions 4. Knowledge transfer 5. Team awareness 6. Improving dev process -
Why? Alberto Bacchelli, Christian Bird 1. Finding defects 2. Code
improvements 3. Finding alternative solutions 4. Knowledge transfer 5. Team awareness 6. Improving dev process -
Why? Alberto Bacchelli, Christian Bird 1. Finding defects 2. Code
improvements 3. Finding alternative solutions 4. Knowledge transfer 5. Team awareness 6. Improving dev process -
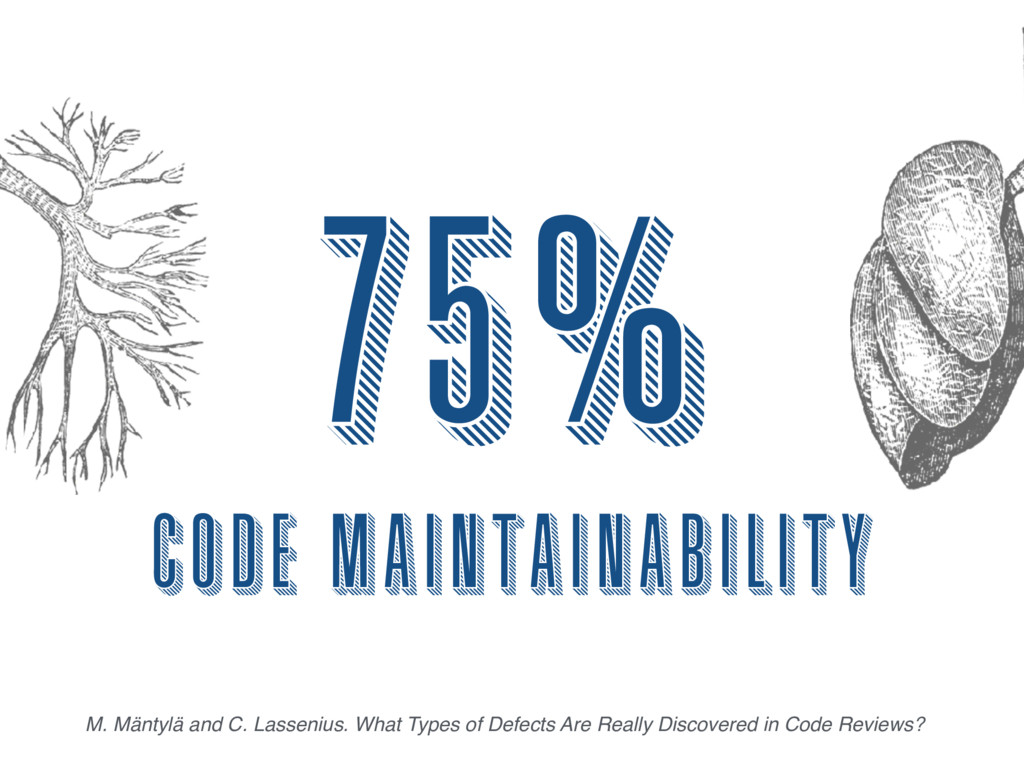
75% code maintainability M. Mäntylä and C. Lassenius. What Types
of Defects Are Really Discovered in Code Reviews? -
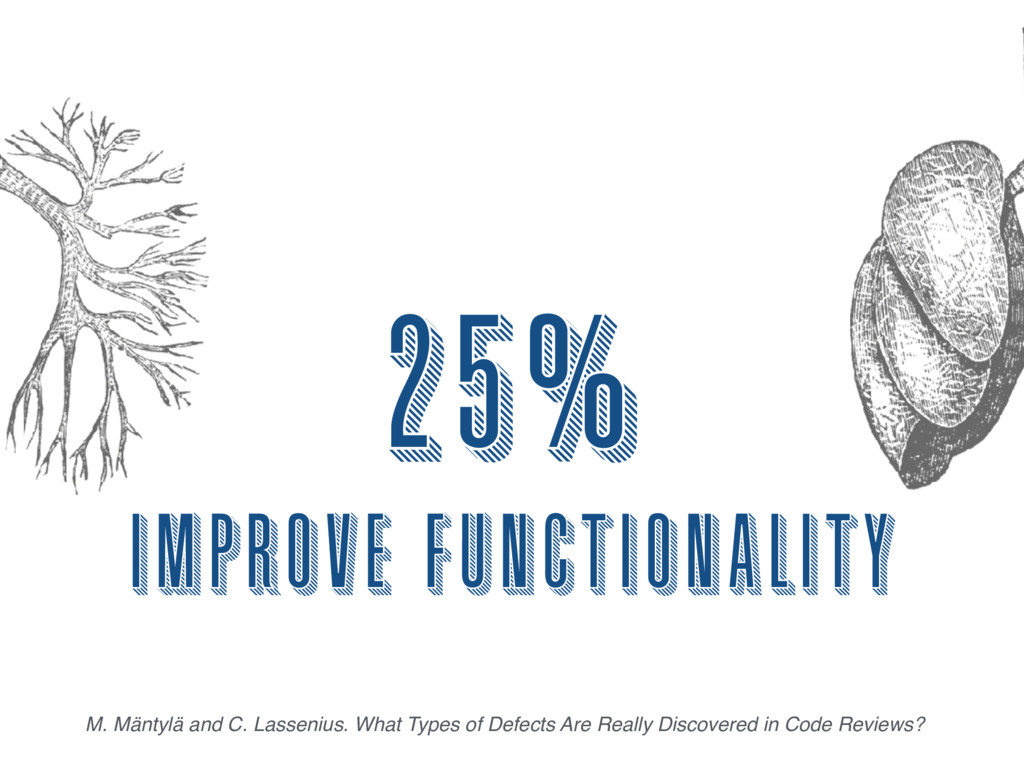
25% improve functionality M. Mäntylä and C. Lassenius. What Types
of Defects Are Really Discovered in Code Reviews? -
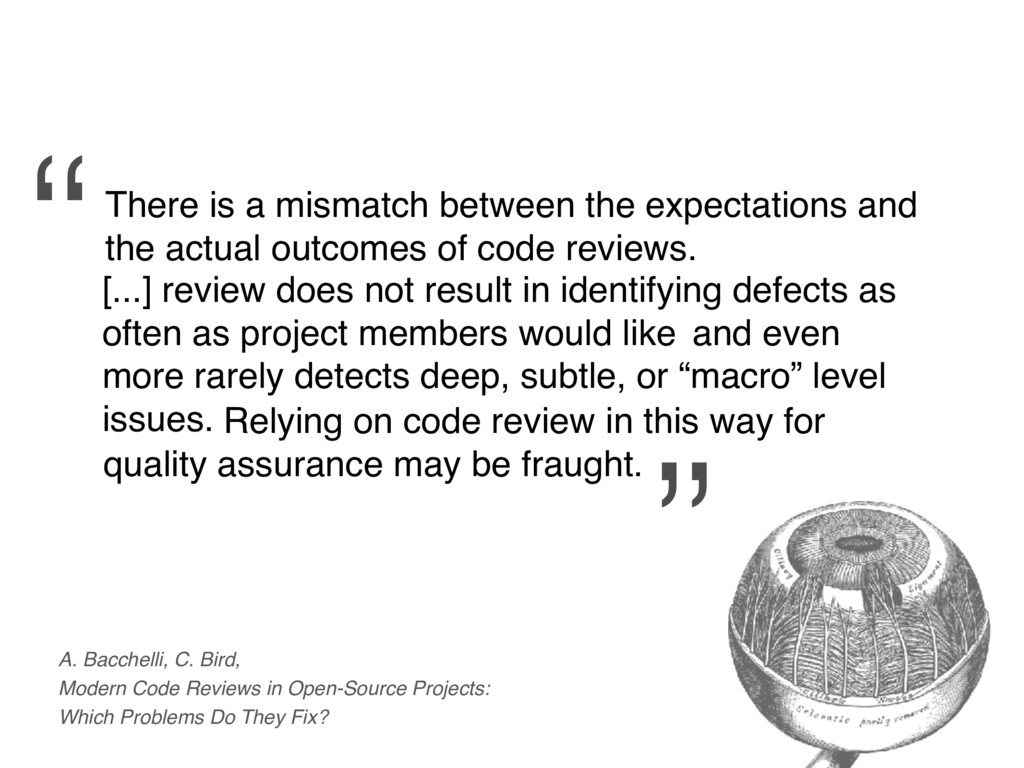
A. Bacchelli, C. Bird, Modern Code Reviews in Open-Source Projects:
Which Problems Do They Fix? There is a mismatch between the expectations and the actual outcomes of code reviews. “ ” [...] review does not result in identifying defects as often as project members would like and even more rarely detects deep, subtle, or “macro” level issues. Relying on code review in this way for quality assurance may be fraught. -
Modern code reviews provide benefits beyond finding defects. “ ”
Code review can be used to improve code style, find alternative solutions, increase learning, share code ownership, etc.. This should guide code review policies. A. Bacchelli, C. Bird, Modern Code Reviews in Open-Source Projects: Which Problems Do They Fix? -
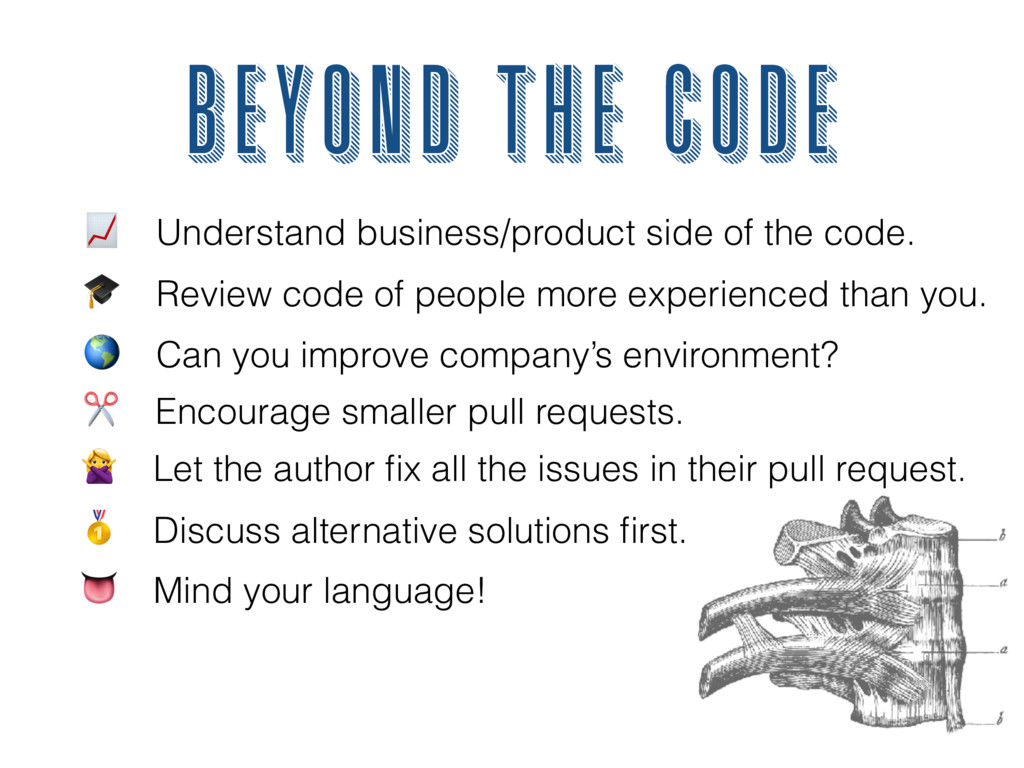
4 Can you improve company’s environment? 6 Let the author
fix all the issues in their pull request. 8 Mind your language! 2 Understand business/product side of the code. 3 Review code of people more experienced than you. beyond the code ✂ Encourage smaller pull requests. 7 Discuss alternative solutions first.
 asendecka
 grimoh
 ginjihayashi
 amarelo_n24
 nicholsjasper
 takano0131
 carta_engineering
 ren8k
 ryutakondo
 jcabot
 nealle
 knwoop
 pauli
 trishagee
 inesmontani
 afnizarnur
 elsirapls
 retrage
 jnunemaker
 baasie
 eileencodes
 tammyeverts
 signer
 auna