Share
Embed
Transcript
44 slides
-
Introduction • Benjamin Darfler o @bdarfler o http://bdarfler.com o Senior
Software Engineer at Localytics • Localytics o Real time analytics for mobile applications o 100M+ datapoints a day o More than 2x growth over the past 4 months o Heavy users of Scala, MongoDB and AWS • This Talk o Revised and updated from MongoNYC 2011 -
MongoDB at Localytics • Use cases o Anonymous loyalty information
o De-duplication of incoming data • Scale today o Hundreds of GBs of data per shard o Thousands of ops per second per shard • History o In production for ~8 months o Increased load 10x in that time o Reduced shard count by more than a half -
Disclaimer These steps worked for us and our data We
verified them by testing early and often You should too -
Quick Poll • Who is using MongoDB in production? •
Who is deployed on AWS? • Who has a sharded deployment? o More than 2 shards? o More than 4 shards? o More than 8 shards? -
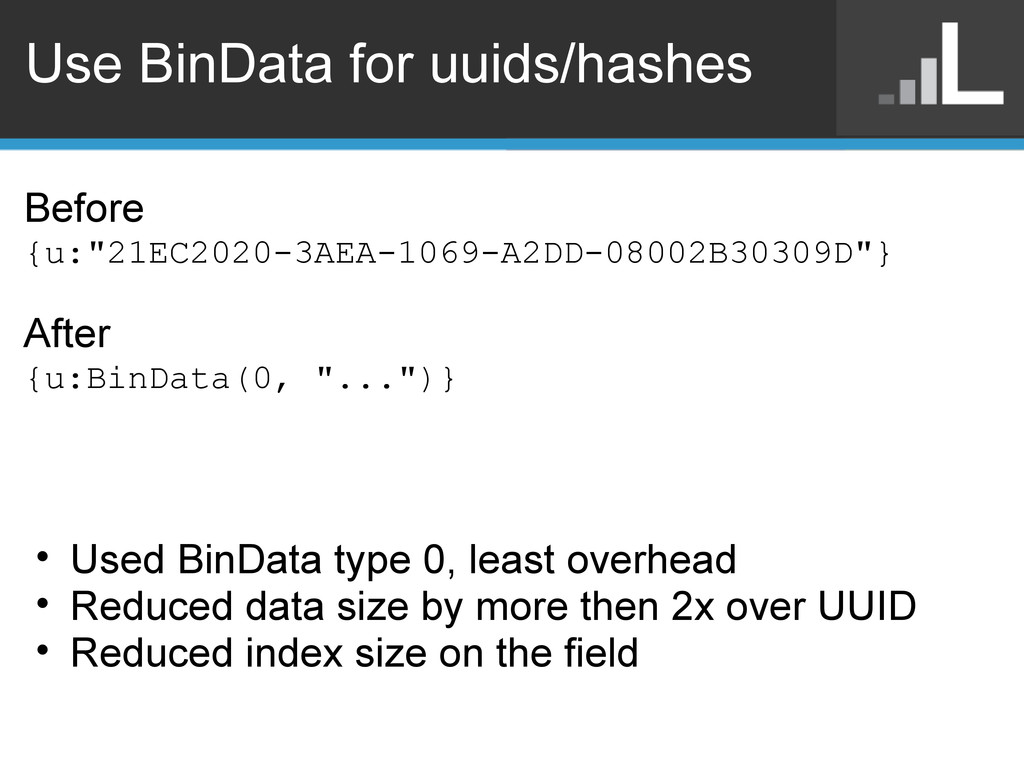
Use BinData for uuids/hashes Before {u:"21EC2020-3AEA-1069-A2DD-08002B30309D"} After {u:BinData(0, "...")} •
Used BinData type 0, least overhead • Reduced data size by more then 2x over UUID • Reduced index size on the field -
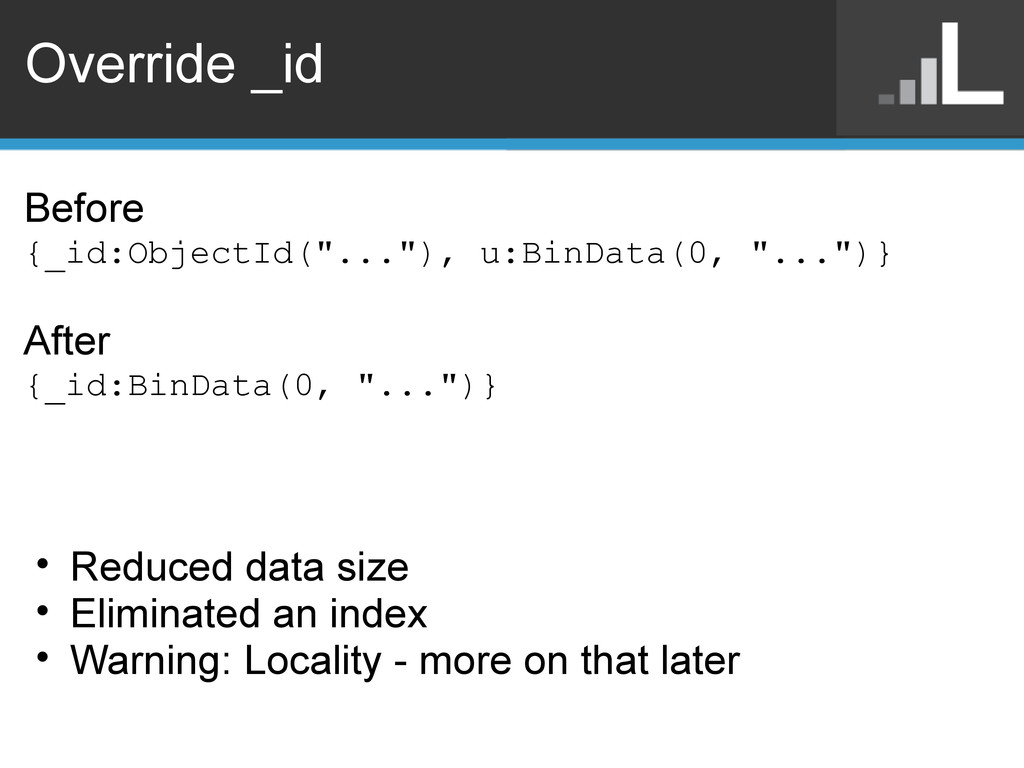
Override _id Before {_id:ObjectId("..."), u:BinData(0, "...")} After {_id:BinData(0, "...")} •
Reduced data size • Eliminated an index • Warning: Locality - more on that later -
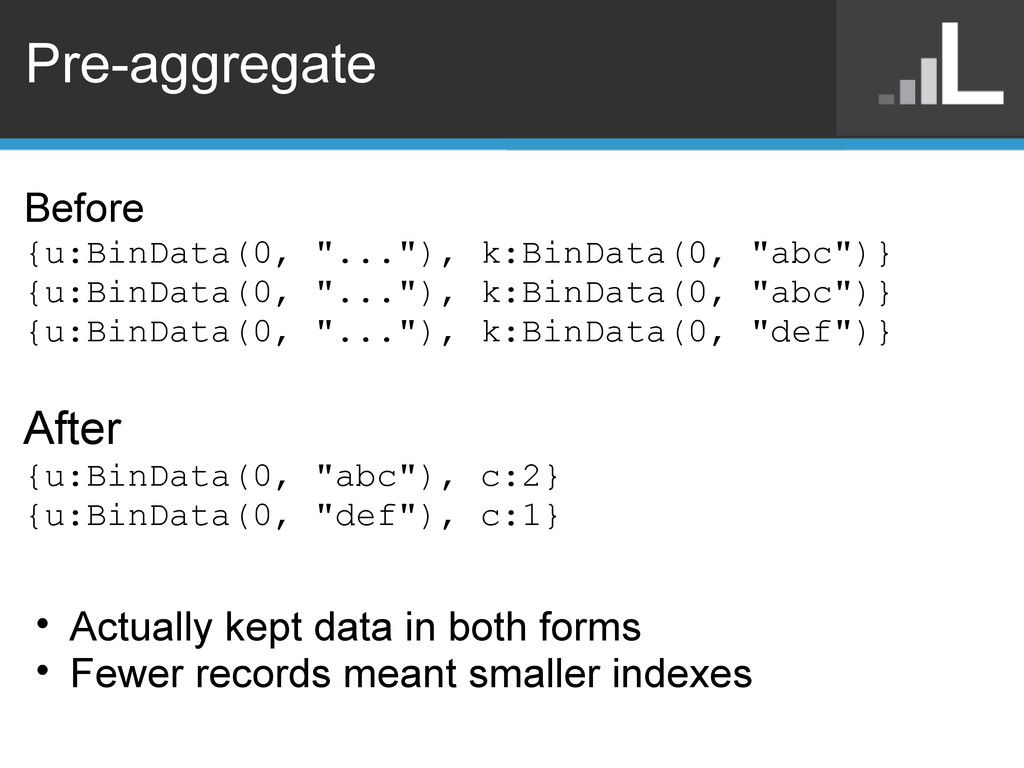
Pre-aggregate Before {u:BinData(0, "..."), k:BinData(0, "abc")} {u:BinData(0, "..."), k:BinData(0, "abc")}
{u:BinData(0, "..."), k:BinData(0, "def")} After {u:BinData(0, "abc"), c:2} {u:BinData(0, "def"), c:1} • Actually kept data in both forms • Fewer records meant smaller indexes -
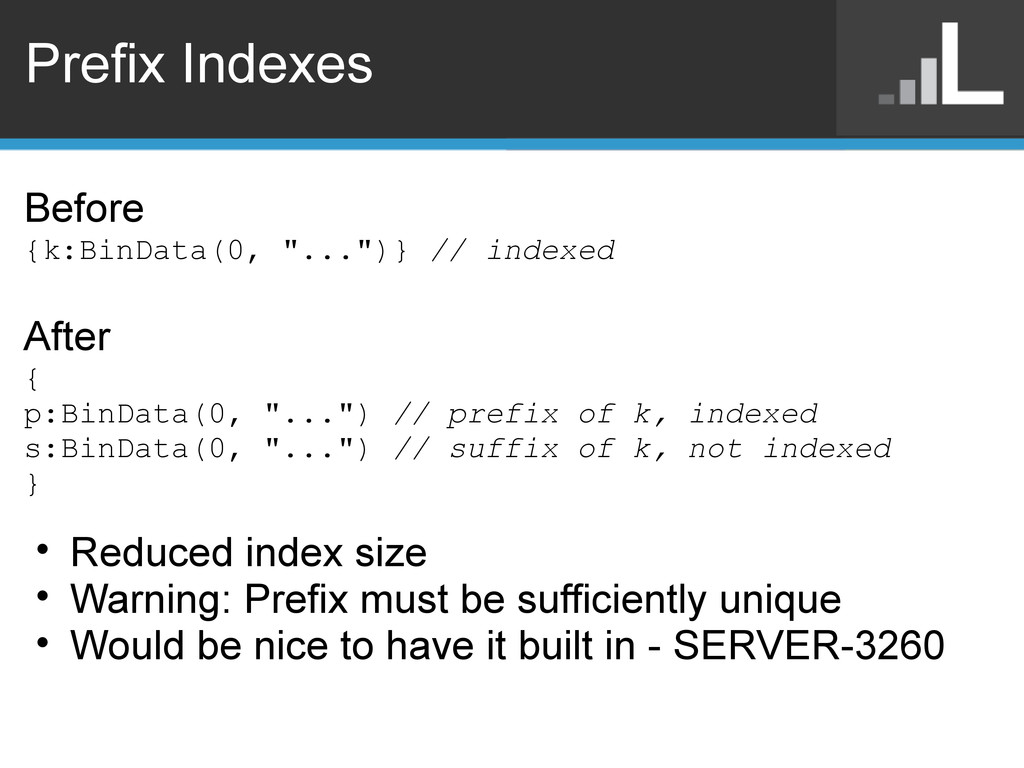
Prefix Indexes Before {k:BinData(0, "...")} // indexed After { p:BinData(0,
"...") // prefix of k, indexed s:BinData(0, "...") // suffix of k, not indexed } • Reduced index size • Warning: Prefix must be sufficiently unique • Would be nice to have it built in - SERVER-3260 -
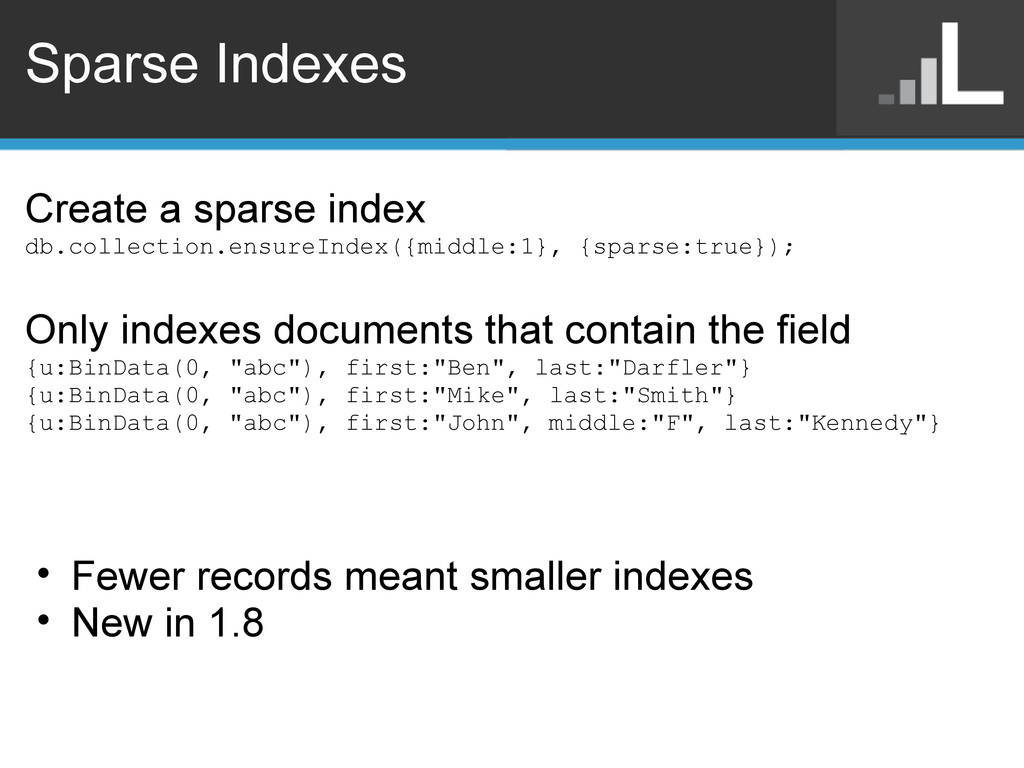
Sparse Indexes Create a sparse index db.collection.ensureIndex({middle:1}, {sparse:true}); Only indexes
documents that contain the field {u:BinData(0, "abc"), first:"Ben", last:"Darfler"} {u:BinData(0, "abc"), first:"Mike", last:"Smith"} {u:BinData(0, "abc"), first:"John", middle:"F", last:"Kennedy"} • Fewer records meant smaller indexes • New in 1.8 -
Upgrade to {v:1} indexes • Upto 25% smaller • Upto
25% faster • New in 2.0 • Must reindex after upgrade -
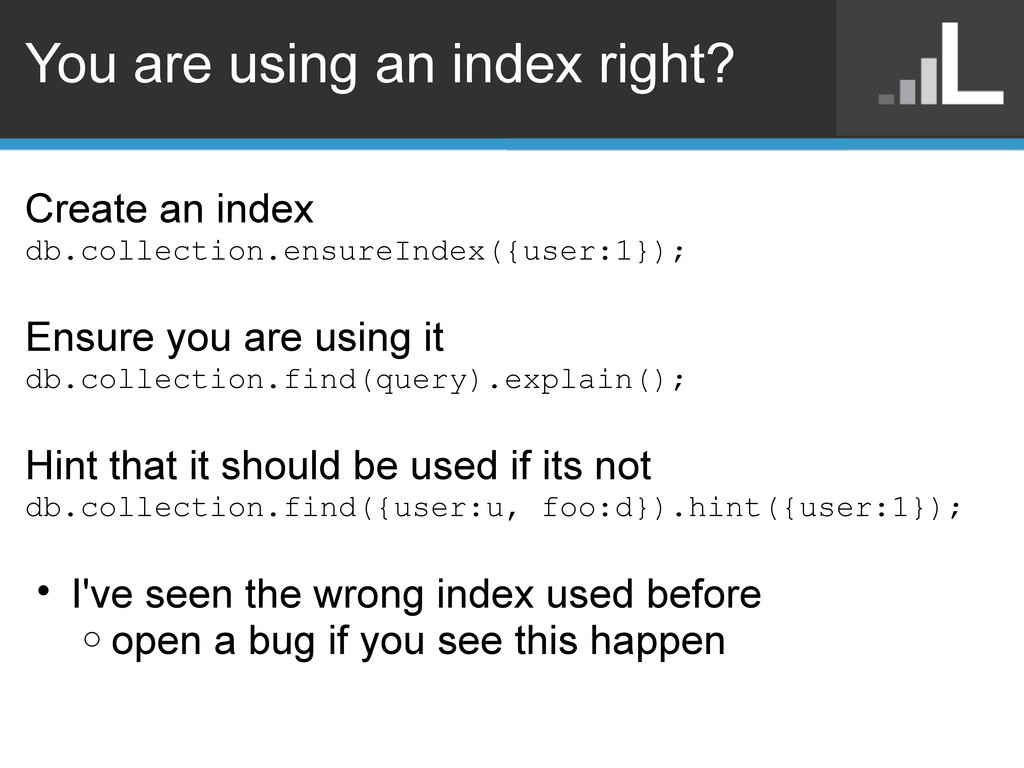
You are using an index right? Create an index db.collection.ensureIndex({user:1});
Ensure you are using it db.collection.find(query).explain(); Hint that it should be used if its not db.collection.find({user:u, foo:d}).hint({user:1}); • I've seen the wrong index used before o open a bug if you see this happen -
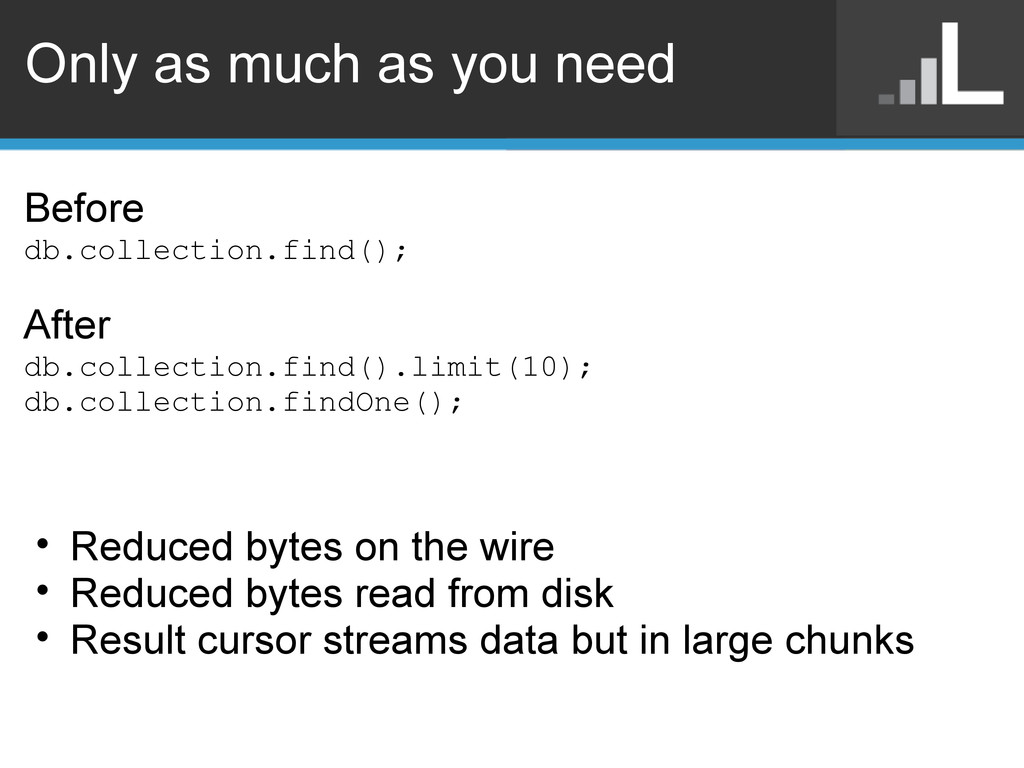
Only as much as you need Before db.collection.find(); After db.collection.find().limit(10);
db.collection.findOne(); • Reduced bytes on the wire • Reduced bytes read from disk • Result cursor streams data but in large chunks -
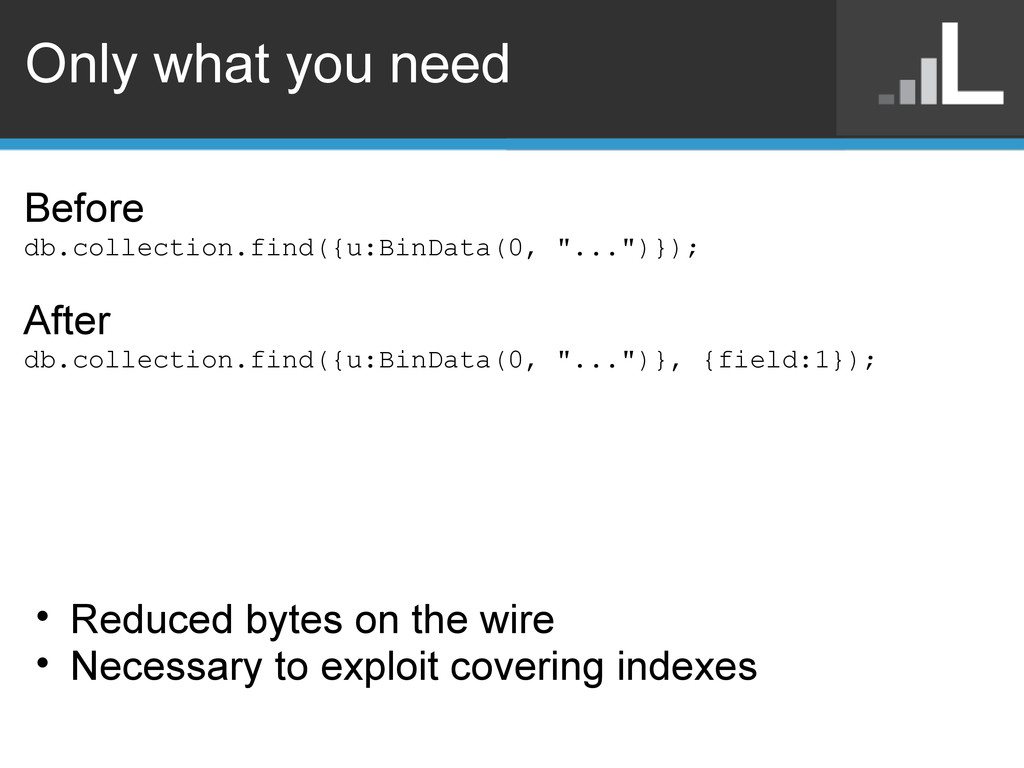
Only what you need Before db.collection.find({u:BinData(0, "...")}); After db.collection.find({u:BinData(0, "...")},
{field:1}); • Reduced bytes on the wire • Necessary to exploit covering indexes -
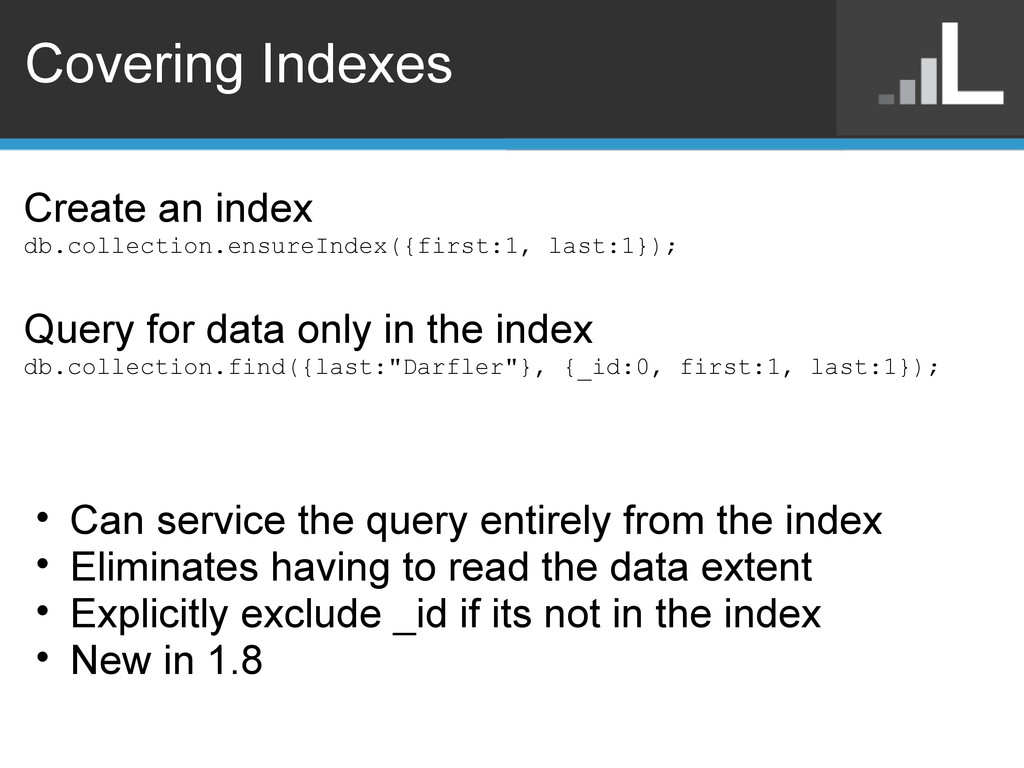
Covering Indexes Create an index db.collection.ensureIndex({first:1, last:1}); Query for data
only in the index db.collection.find({last:"Darfler"}, {_id:0, first:1, last:1}); • Can service the query entirely from the index • Eliminates having to read the data extent • Explicitly exclude _id if its not in the index • New in 1.8 -
Prefetch Before db.collection.update({u:BinData(0, "...")}, {$inc:{c:1}}); After db.collection.find({u:BinData(0, "...")}); db.collection.update({u:BinData(0, "...")},
{$inc:{c:1}}); • Prevents holding a write lock while paging in data • Most updates fit this pattern anyhow • Less necessary with yield improvements in 2.0 -
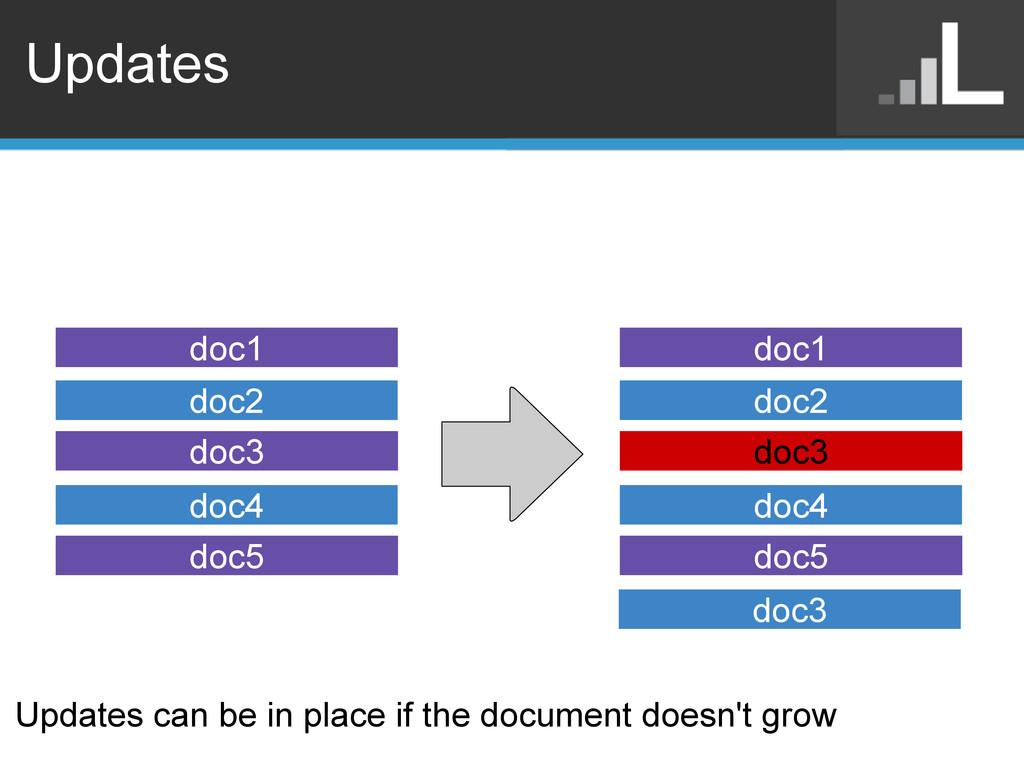
Updates doc1 doc2 doc3 doc4 doc5 doc1 doc2 doc3 doc4
doc5 doc3 Updates can be in place if the document doesn't grow -
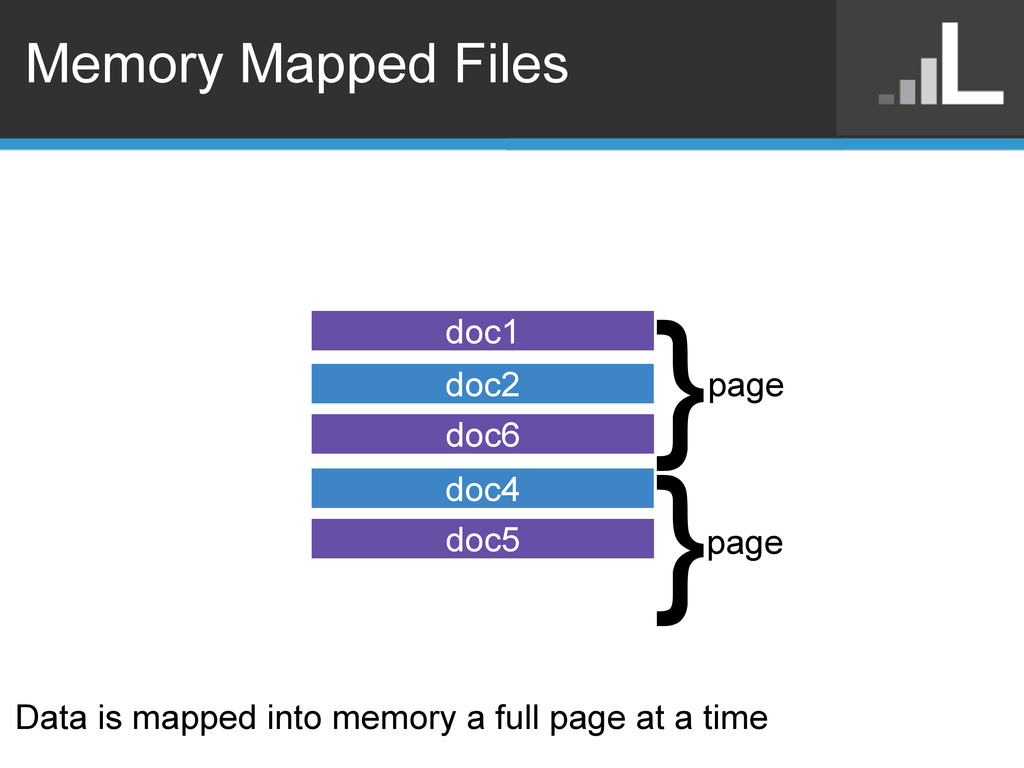
Memory Mapped Files doc1 doc2 doc6 doc4 doc5 } }
page page Data is mapped into memory a full page at a time -
Fragmentation RAM used to be filled with useful data Now
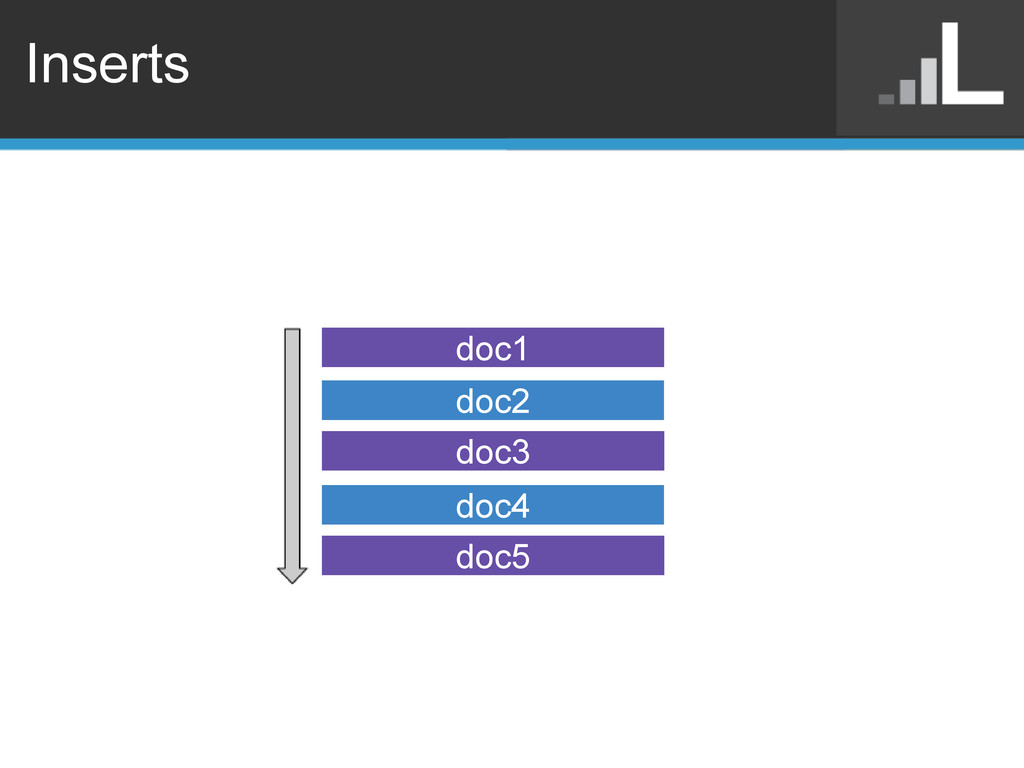
it contains useless space or useless data Inserts used to cause sequential writes Now inserts cause random writes -
Fragmentation Mitigation • Automatic Padding o MongoDB auto-pads records o
Manual tuning scheduled for 2.2 • Manual Padding o Pad arrays that are known to grow o Pad with a BinData field, then remove it • Free list improvement in 2.0 and scheduled in 2.2 -
Fragmentation Fixes • Repair o db.repairDatabase(); o Run on secondary,
swap with primary o Requires 2x disk space • Compact o db.collection.runCommand( "compact" ); o Run on secondary, swap with primary o Faster than repair o Requires minimal extra disk space o New in 2.0 • Repair, compact and import remove padding -
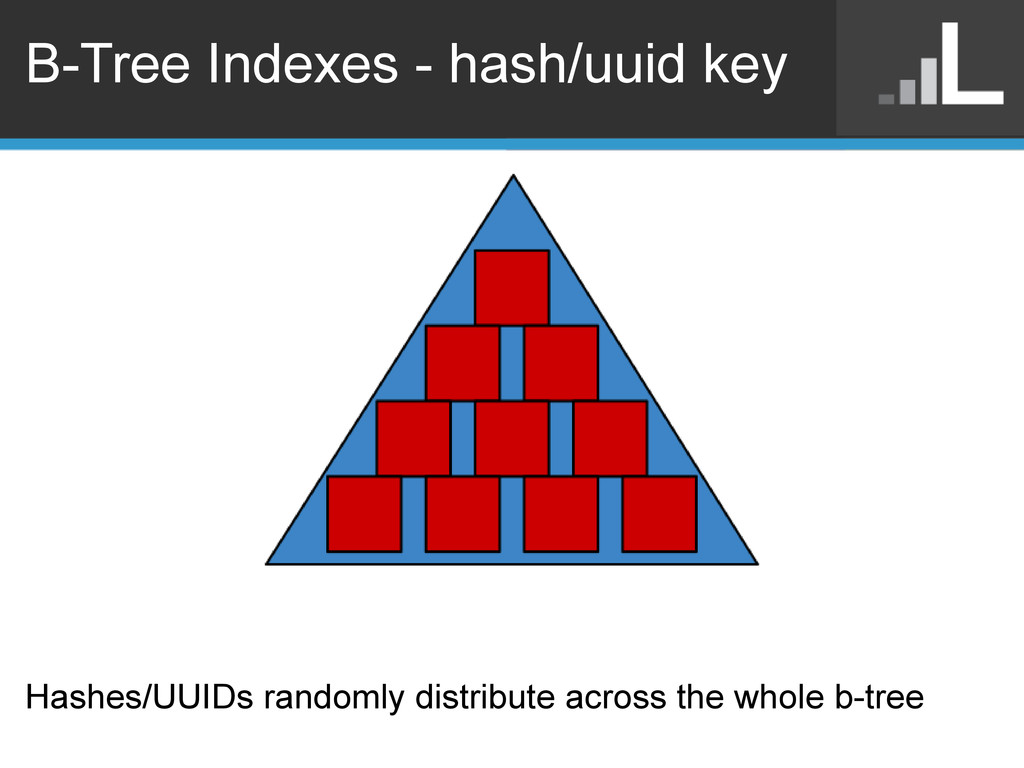
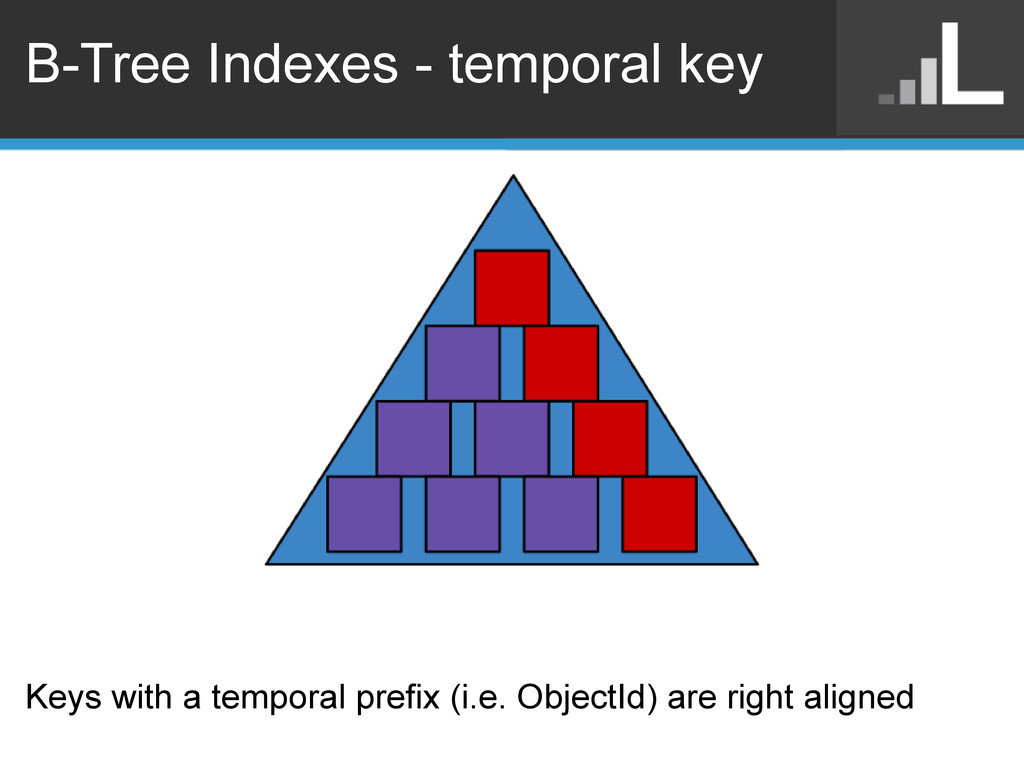
B-Tree Indexes - temporal key Keys with a temporal prefix
(i.e. ObjectId) are right aligned -
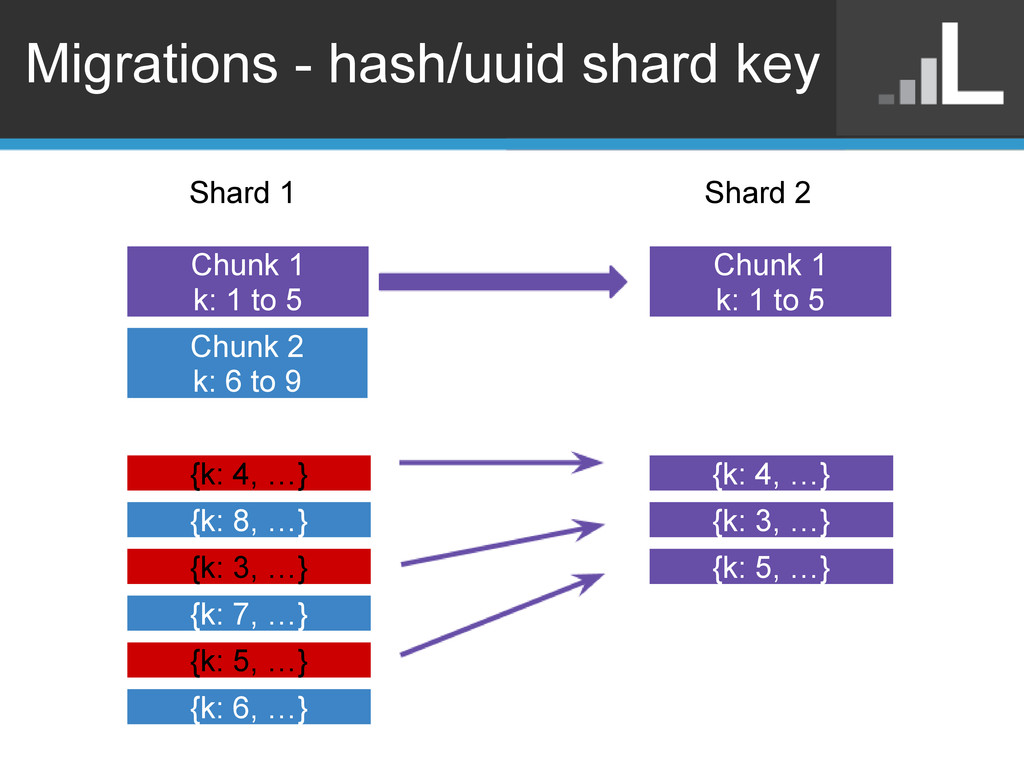
Migrations - hash/uuid shard key Chunk 1 k: 1 to
5 Chunk 2 k: 6 to 9 Shard 1 Shard 2 Chunk 1 k: 1 to 5 {k: 4, …} {k: 8, …} {k: 3, …} {k: 7, …} {k: 5, …} {k: 6, …} {k: 4, …} {k: 3, …} {k: 5, …} -
Hash/uuid shard key • Distributes read/write load evenly across nodes
• Migrations cause random I/O and fragmentation o Makes it harder to add new shards • Pre-split o db.runCommand({split:"db.collection", middle:{_id:99}}); • Pre-move o db.adminCommand({moveChunk:"db.collection", find:{_id:5}, to:"s2"}); • Turn off balancer o db.settings.update({_id:"balancer"}, {$set:{stopped:true}}, true}); -
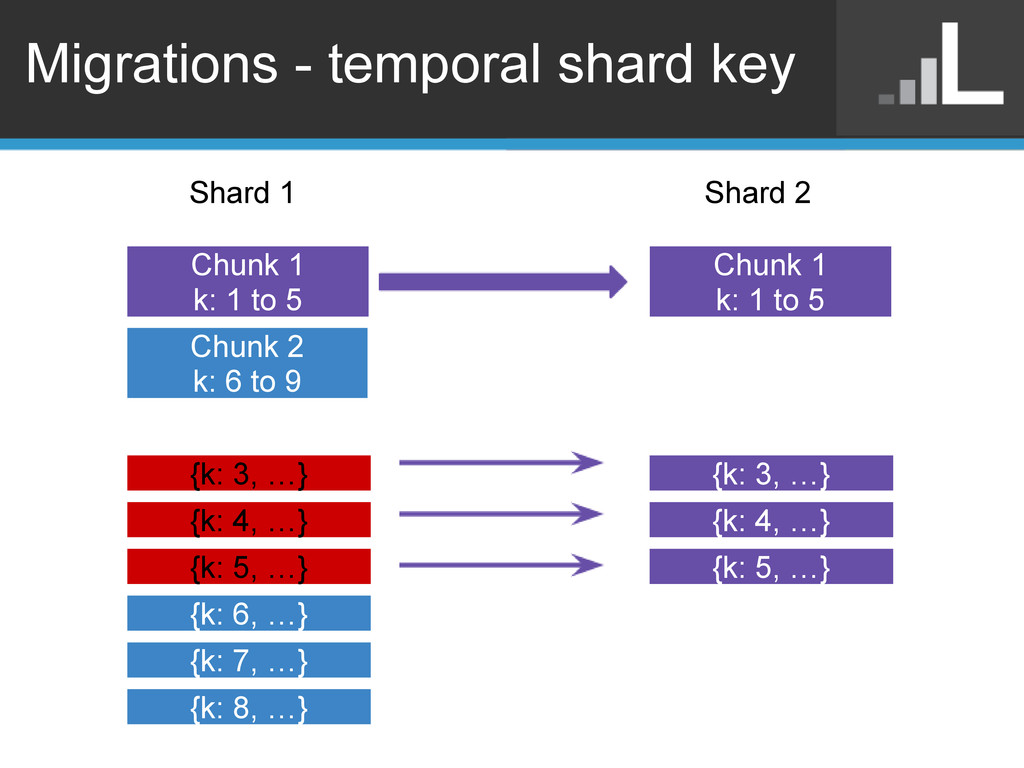
Migrations - temporal shard key Chunk 1 k: 1 to
5 Chunk 2 k: 6 to 9 Shard 1 Shard 2 Chunk 1 k: 1 to 5 {k: 3, …} {k: 4, …} {k: 5, …} {k: 6, …} {k: 7, …} {k: 8, …} {k: 3, …} {k: 4, …} {k: 5, …} -
Temporal shard key • Can cause hot chunks • Migrations
are less destructive o Makes it easier to add new shards • Include a temporal prefix in your shard key o {day: ..., id: ...} • Choose prefix granularity based on insert rate o low 100s of chunks (64MB) per "unit" of prefix o i.e. 10 GB per day => ~150 chunks per day -
Elastic Compute Cloud • Noisy Neighbor o Used largest instance
in a family (m1 or m2) • Used m2 family for mongods o Best RAM to dollar ratio • Used micros for arbiters and config servers -
Elastic Block Storage • Noisy Neighbor o Netflix claims to
only use 1TB disks • RAID'ed our disks o Minimum of 4-8 disks o Recommended 8-16 disks o RAID0 for write heavy workload o RAID10 for read heavy workload -
Pathological Test • What happens when data far exceeds RAM?
o 10:1 read/write ratio o Reads evenly distributed over entire key space -
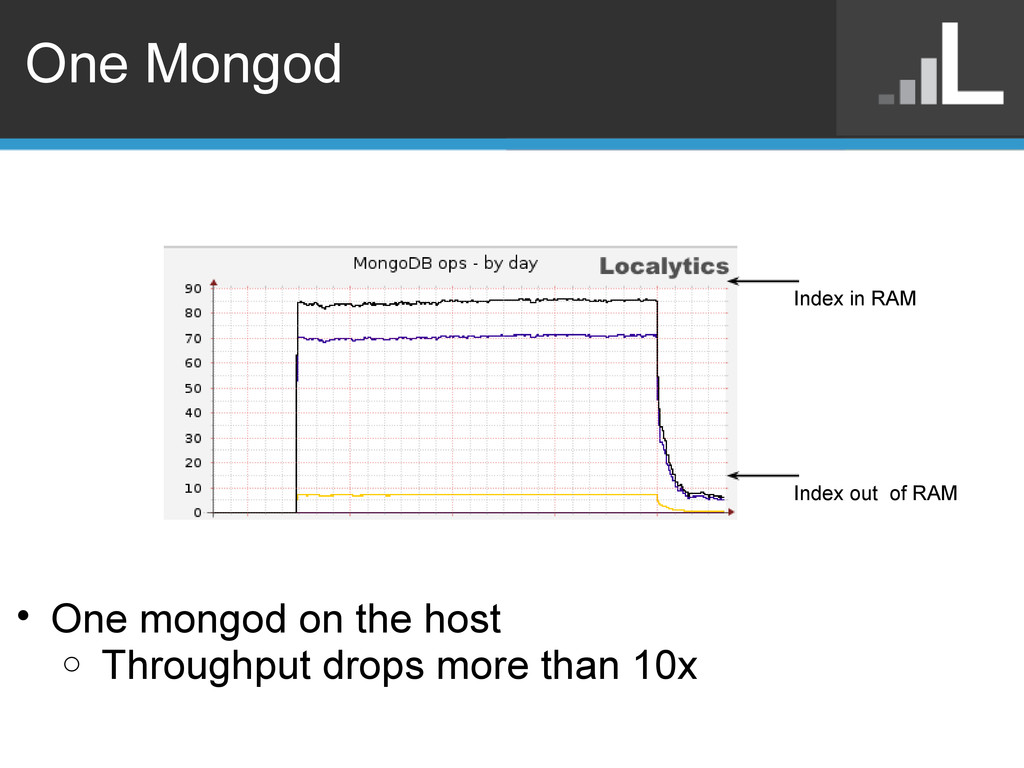
One Mongod Index out of RAM Index in RAM •
One mongod on the host o Throughput drops more than 10x -
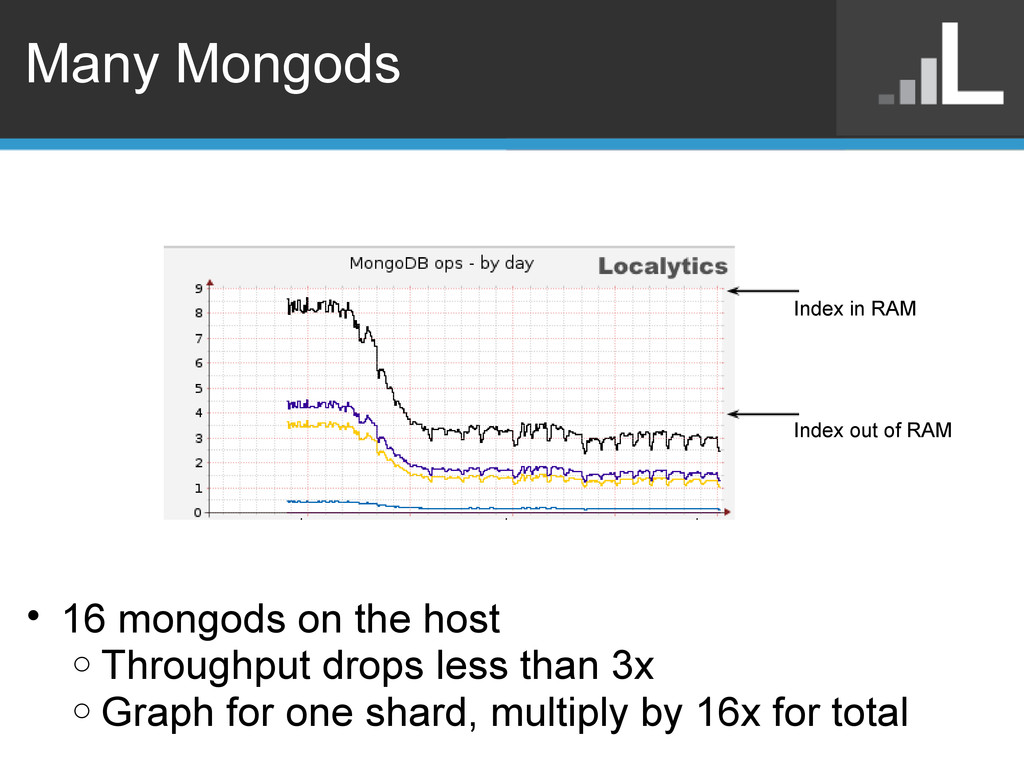
Many Mongods Index out of RAM Index in RAM •
16 mongods on the host o Throughput drops less than 3x o Graph for one shard, multiply by 16x for total -
Sharding within a node • One read/write lock per mongod
o Ticket for lock per collection - SERVER-1240 o Ticket for lock per extent - SERVER-1241 • For in memory work load o Shard per core • For out of memory work load o Shard per disk • Warning: Must have shard key in every query o Otherwise scatter gather across all shards o Requires manually managing secondary keys • Less necessary in 2.0 with yield improvements -
Reminder These steps worked for us and our data We
verified them by testing early and often You should too