Share
Embed
Scaling Elasticsearch; Washington DC Meetup
Slides from my talk at Washington DC Elasticsearch meetup on Dec 11th 2014, about scaling Elasticsearch for production scale data.
Event Details :-
http://www.meetup.com/Elasticsearch-Washington-DC/events/218806074/
Video of the Talk :
http://www.elasticsearch.org/videos/washington-d-c-meetup-december-11-2014/
Bhaskar V. Karambelkar
December 12, 2014
Transcript
19 slides
-
Scaling Elasticsearch for Production Scale Data by Bhaskar V. Karambelkar
Elasticsearch Washington DC Meetup Dec. 11, 2014 -
Introduction • Security Data Scientist / Tech Lead @ Verizon.
• Avid Elasticsearch user and advocate since 2012. • Interested in information security and data analytics. -
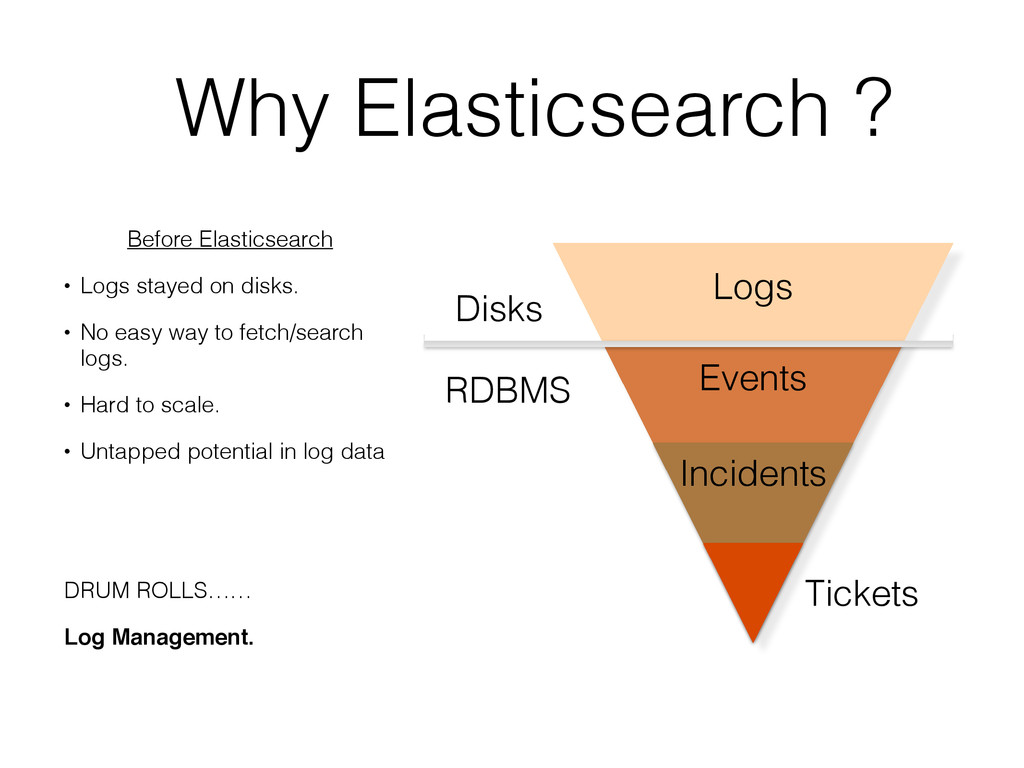
Why Elasticsearch ? Before Elasticsearch • Logs stayed on disks.
• No easy way to fetch/search logs. • Hard to scale. • Untapped potential in log data DRUM ROLLS…… Log Management. Logs Events Incidents Tickets Disks RDBMS -
Expectations • Must be able to store massive amounts of
data. • Must be able to get data in at a very high rate and get data out at an acceptable rate. • Should be schema agnostic. • Must be able to search/filter/analyze data. • Must support MULTI-TENANCY. • Distributed/fault-tolerant/load-balanced/etc. -
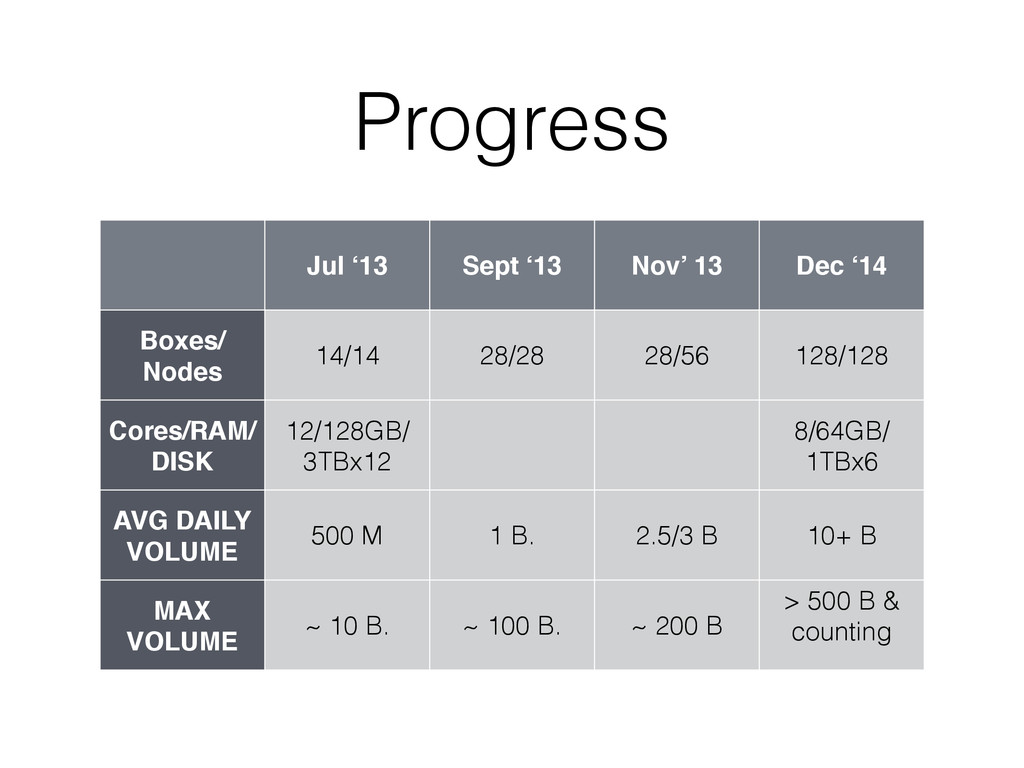
Progress Jul ‘13 Sept ‘13 Nov’ 13 Dec ‘14 Boxes/
Nodes 14/14 28/28 28/56 128/128 Cores/RAM/ DISK 12/128GB/ 3TBx12 8/64GB/ 1TBx6 AVG DAILY VOLUME 500 M 1 B. 2.5/3 B 10+ B MAX VOLUME ~ 10 B. ~ 100 B. ~ 200 B > 500 B & counting -
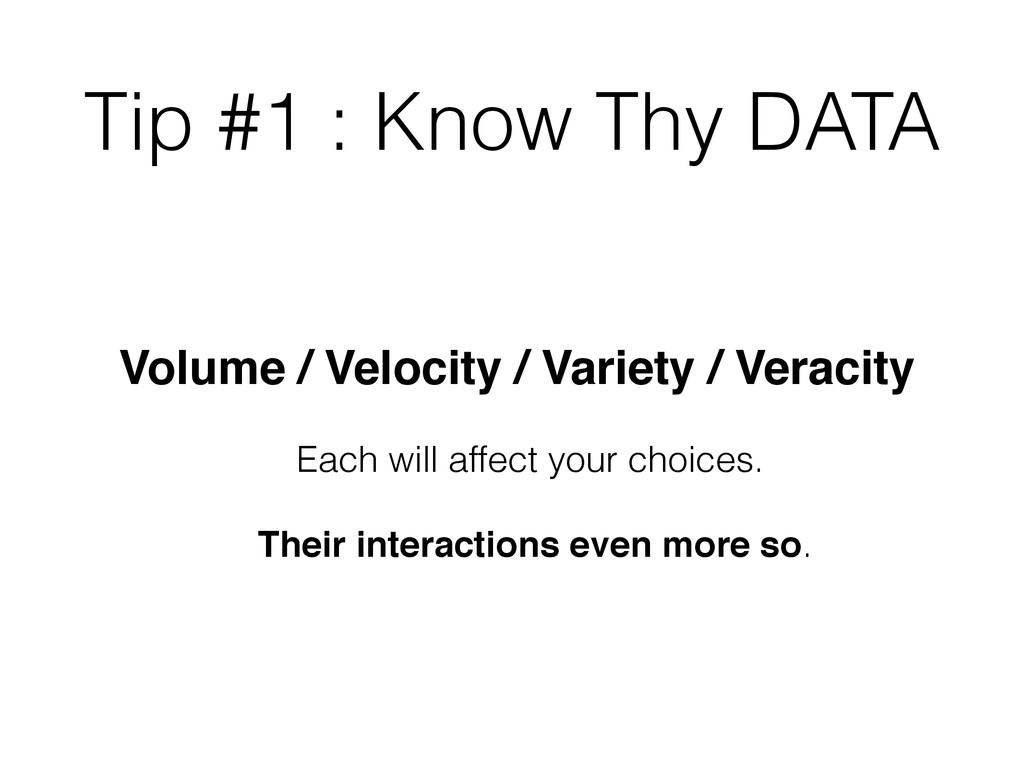
Tip #1 : Know Thy DATA Volume / Velocity /
Variety / Veracity Each will affect your choices. Their interactions even more so. -
Tip #2 : Know Your Platform • Depending on your
data, select a proper base config for your nodes. Get the CPU-Cores x RAM x Disk ratio right. • Decide on self hosted vs. cloud hosted. • Prefer JBODs for data disks over RAID, SAN/NAS. • Virtualization vs. bare metal: know the tradeoffs. • SSDs vs. Spinning Disks, (Speed vs. Capacity). -
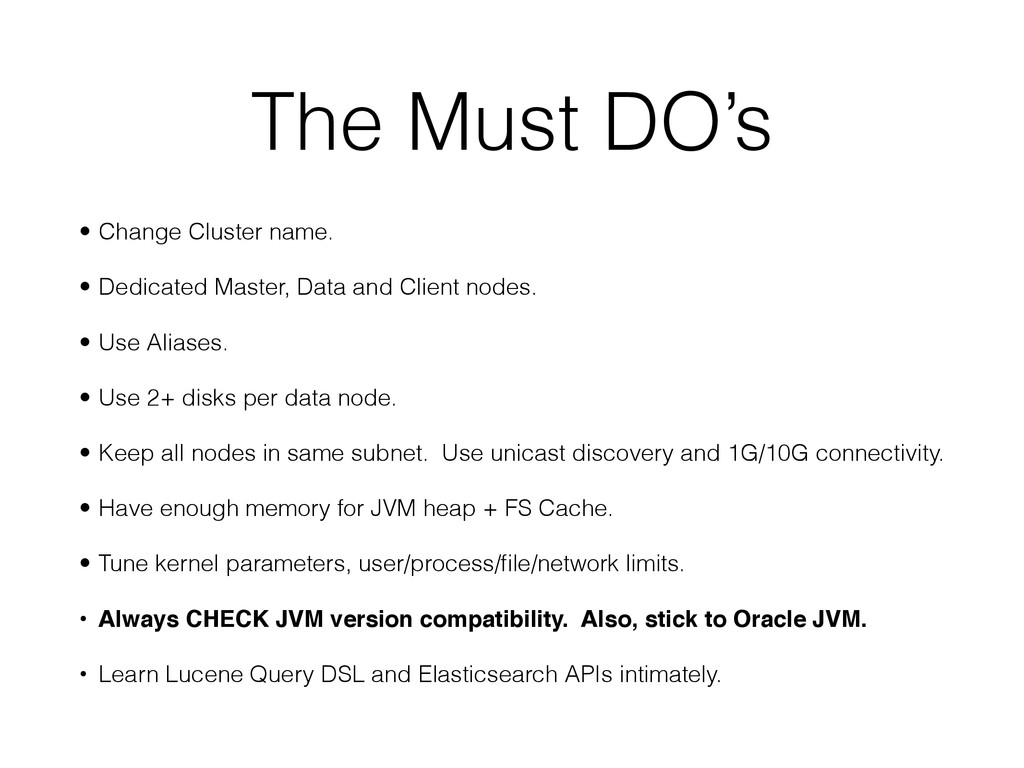
The Must DO’s • Change Cluster name. • Dedicated Master,
Data and Client nodes. • Use Aliases. • Use 2+ disks per data node. • Keep all nodes in same subnet. Use unicast discovery and 1G/10G connectivity. • Have enough memory for JVM heap + FS Cache. • Tune kernel parameters, user/process/file/network limits. • Always CHECK JVM version compatibility. Also, stick to Oracle JVM. • Learn Lucene Query DSL and Elasticsearch APIs intimately. -
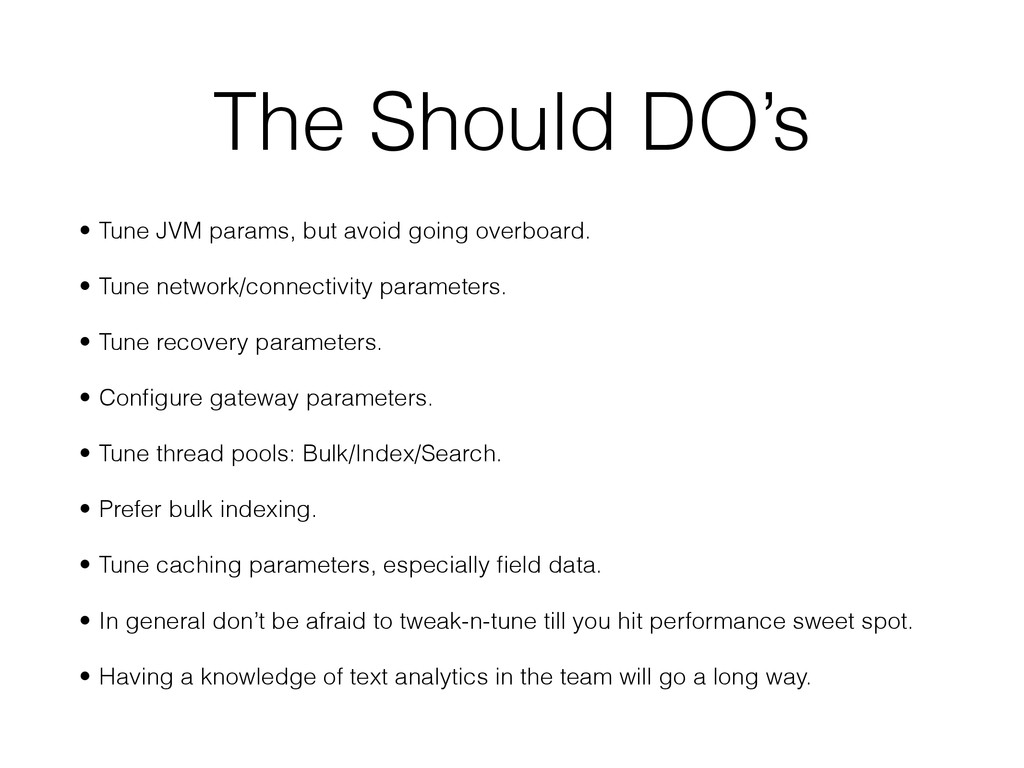
The Should DO’s • Tune JVM params, but avoid going
overboard. • Tune network/connectivity parameters. • Tune recovery parameters. • Configure gateway parameters. • Tune thread pools: Bulk/Index/Search. • Prefer bulk indexing. • Tune caching parameters, especially field data. • In general don’t be afraid to tweak-n-tune till you hit performance sweet spot. • Having a knowledge of text analytics in the team will go a long way. -
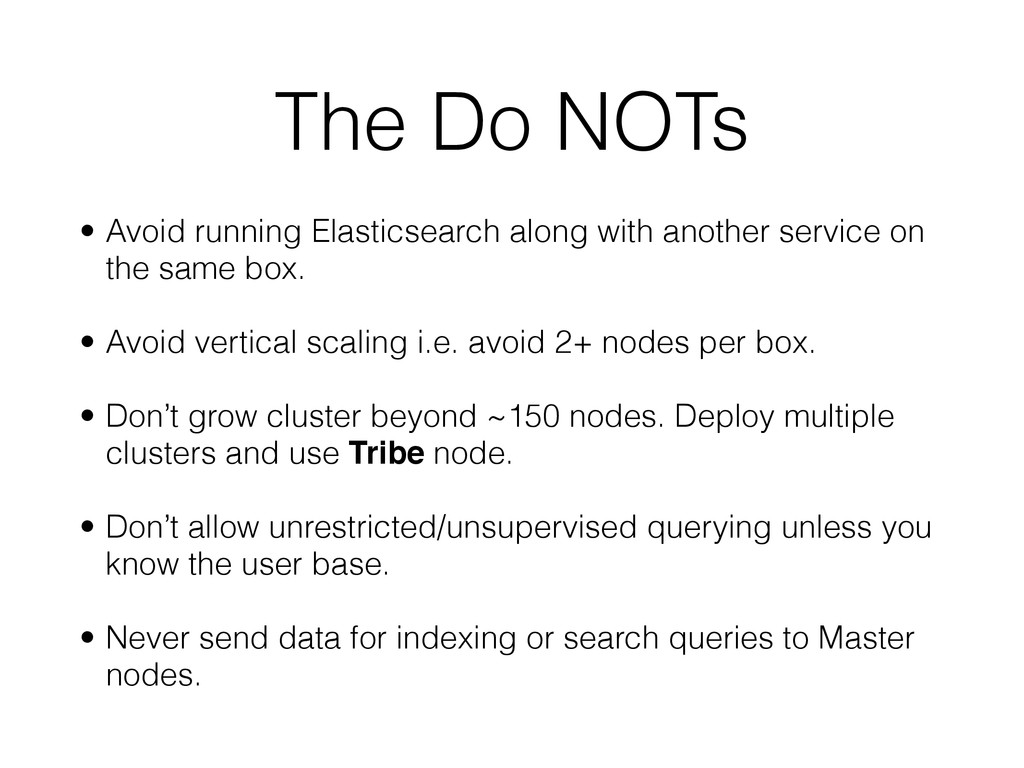
The Do NOTs • Avoid running Elasticsearch along with another
service on the same box. • Avoid vertical scaling i.e. avoid 2+ nodes per box. • Don’t grow cluster beyond ~150 nodes. Deploy multiple clusters and use Tribe node. • Don’t allow unrestricted/unsupervised querying unless you know the user base. • Never send data for indexing or search queries to Master nodes. -
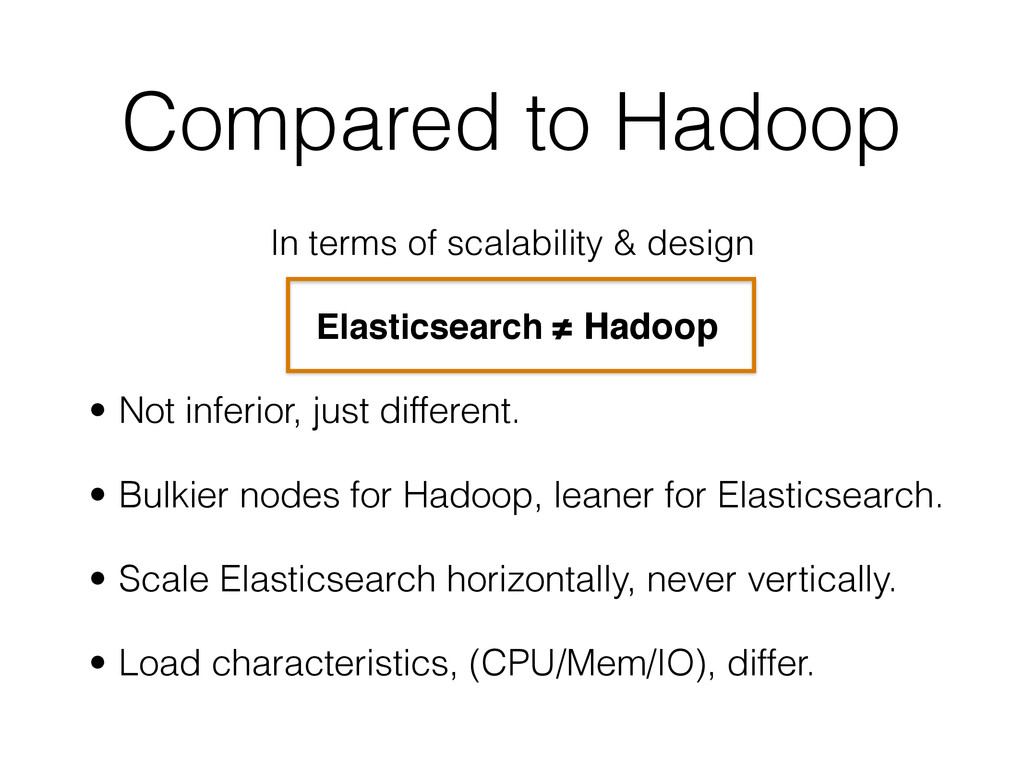
Compared to Hadoop In terms of scalability & design Elasticsearch
≠ Hadoop • Not inferior, just different. • Bulkier nodes for Hadoop, leaner for Elasticsearch. • Scale Elasticsearch horizontally, never vertically. • Load characteristics, (CPU/Mem/IO), differ. -
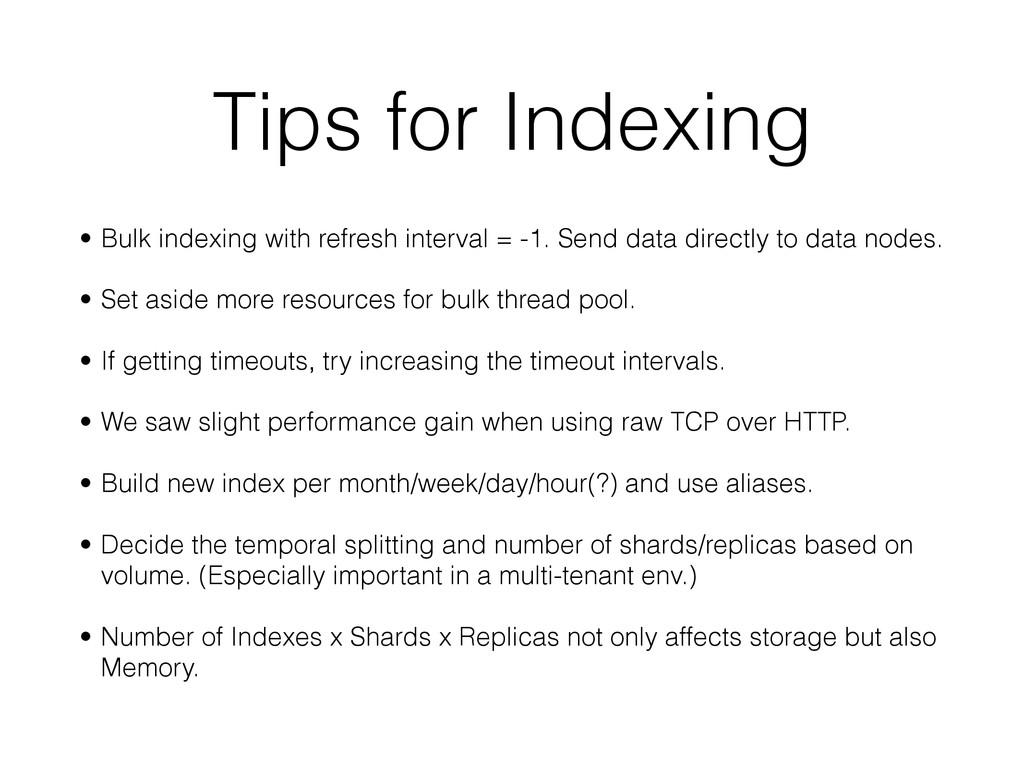
Tips for Indexing • Bulk indexing with refresh interval =
-1. Send data directly to data nodes. • Set aside more resources for bulk thread pool. • If getting timeouts, try increasing the timeout intervals. • We saw slight performance gain when using raw TCP over HTTP. • Build new index per month/week/day/hour(?) and use aliases. • Decide the temporal splitting and number of shards/replicas based on volume. (Especially important in a multi-tenant env.) • Number of Indexes x Shards x Replicas not only affects storage but also Memory. -
• Don’t use a lot of “types” in a single
index. • Use mappings/templates for pre-defining field types. • Disable ‘_all’ field unless really needed. Avoid ‘storing’ fields outside of ‘_source’. • Know which fields to NOT index. Decide which analyzer/token-filter/char-filter works best. -
Tips for Searching • Use filters. • Avoid ‘query string’
query. • Know difference between “bool” and ‘and/or/not’ filters. • Know the impact of faceting/aggregations/sorting on field data cache, especially for high cardinality fields like “timestamp”. • For bulk searching use ‘scroll’. • Rely on explain/validate queries for performance tuning. • Know search preferences and search types. • Named queries/filters for when you want to know which query matched. • Search Templates for simplified queries. • Send searches to client nodes. Not to data nodes and never ever to Master nodes. -
Monitoring / Management • For monitoring we prefer Nagios, but
Marvel works really well too. • Use automated deployment / configuration management via Chef/Puppet/Salt/Ansible. • Prefer to share a single config file for all node types. • We retain raw data in HDFS for a year in case of data loss / re-indexing required. Data in Elasticsearch retained for max 90 days. • Know when to use rolling upgrades vs full upgrades. -
Our Outlook for Next Year and Beyond • Incoming volume
expected grow 5x-10x: 50-100 Billion/ day. • Cross customer / cross cluster searching. • Kibana integration in GUIs. • More automation, monitoring, and management. • More search power to analysts/customers curtsey of circuit breakers & shield. • Include in both real time and retrospective data analysis.