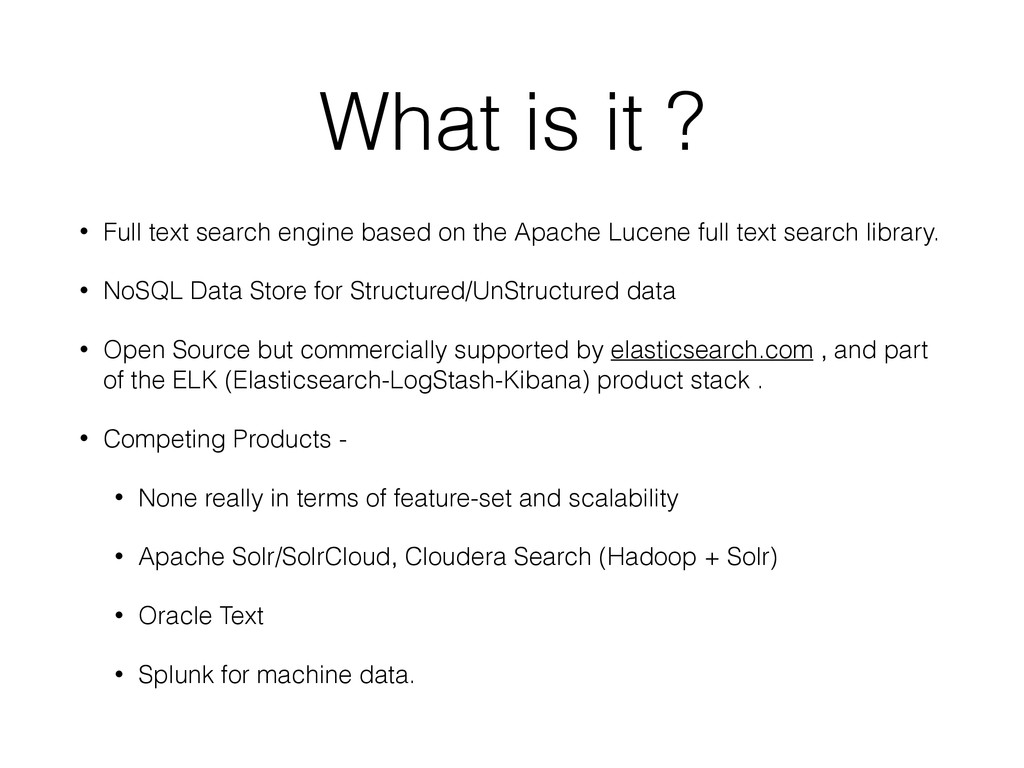
on the Apache Lucene full text search library. • NoSQL Data Store for Structured/UnStructured data • Open Source but commercially supported by elasticsearch.com , and part of the ELK (Elasticsearch-LogStash-Kibana) product stack . • Competing Products - • None really in terms of feature-set and scalability • Apache Solr/SolrCloud, Cloudera Search (Hadoop + Solr) • Oracle Text • Splunk for machine data.
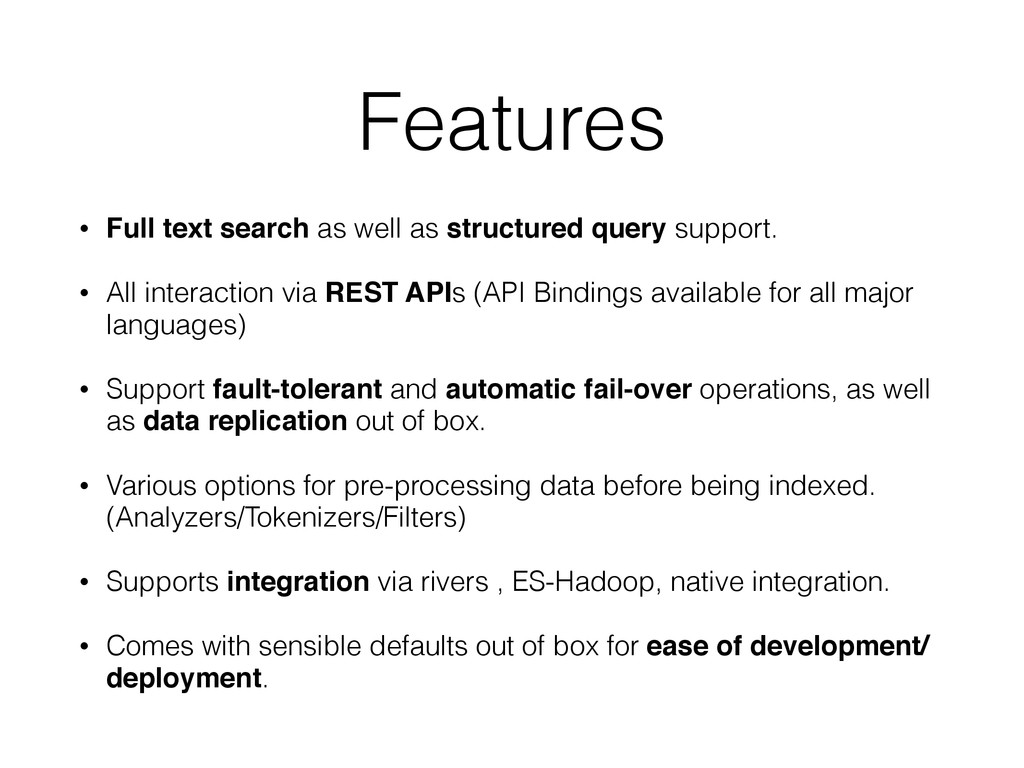
support. • All interaction via REST APIs (API Bindings available for all major languages) • Support fault-tolerant and automatic fail-over operations, as well as data replication out of box. • Various options for pre-processing data before being indexed. (Analyzers/Tokenizers/Filters) • Supports integration via rivers , ES-Hadoop, native integration. • Comes with sensible defaults out of box for ease of development/ deployment.
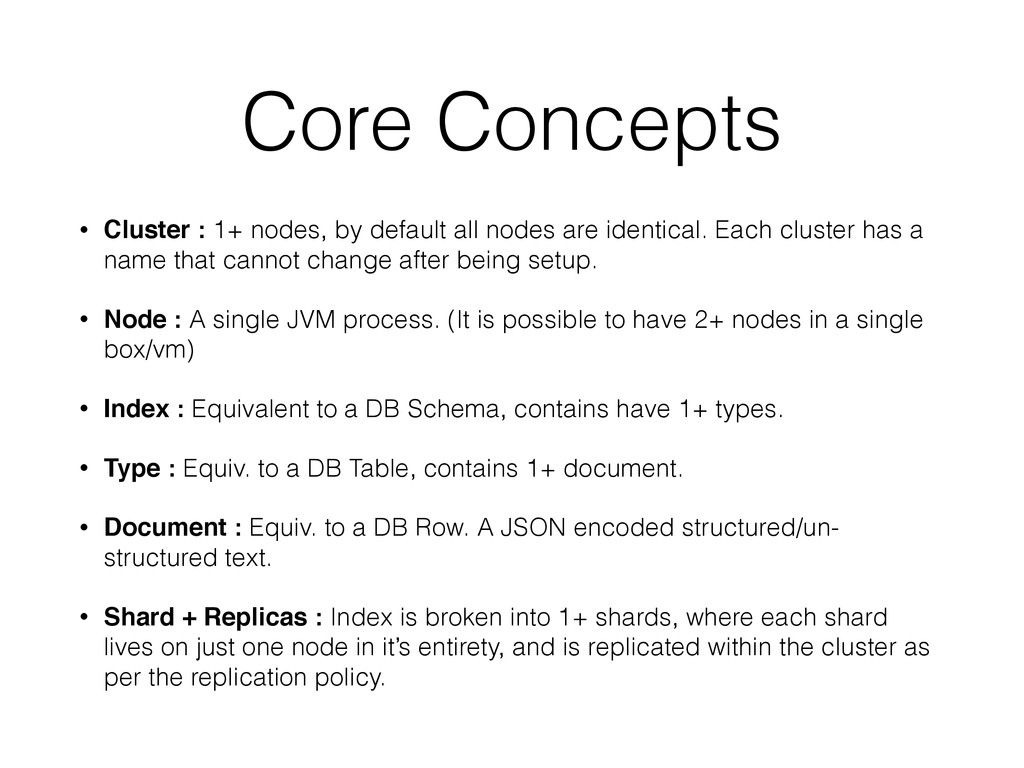
nodes are identical. Each cluster has a name that cannot change after being setup. • Node : A single JVM process. (It is possible to have 2+ nodes in a single box/vm) • Index : Equivalent to a DB Schema, contains have 1+ types. • Type : Equiv. to a DB Table, contains 1+ document. • Document : Equiv. to a DB Row. A JSON encoded structured/un- structured text. • Shard + Replicas : Index is broken into 1+ shards, where each shard lives on just one node in it’s entirety, and is replicated within the cluster as per the replication policy.
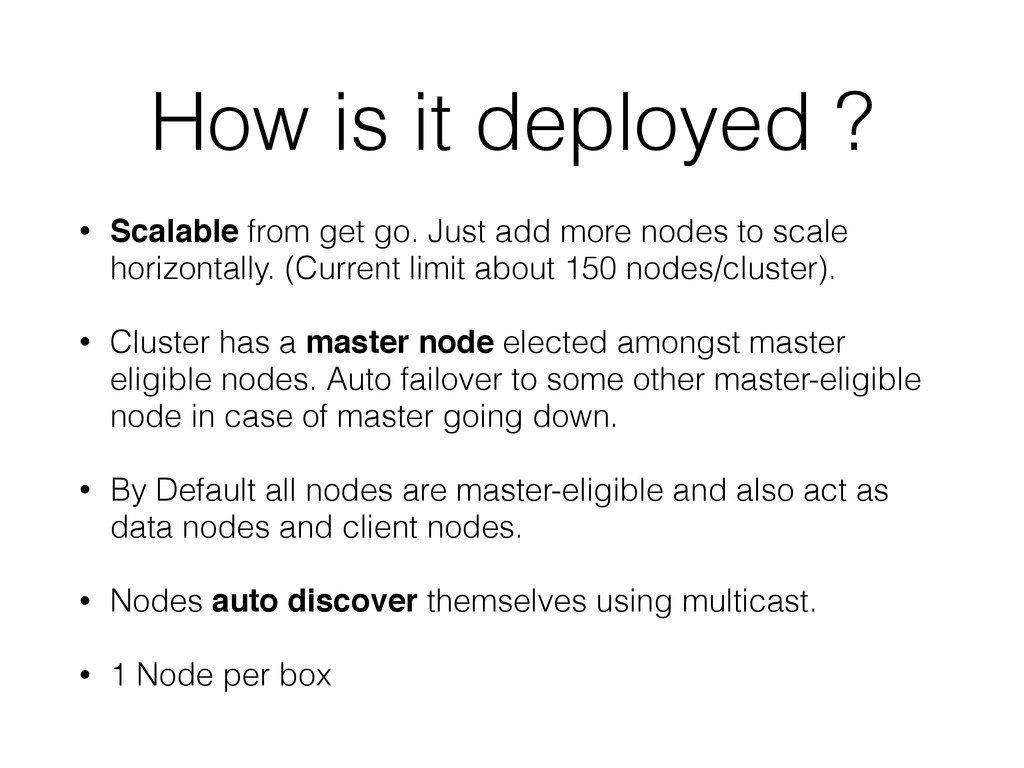
Just add more nodes to scale horizontally. (Current limit about 150 nodes/cluster). • Cluster has a master node elected amongst master eligible nodes. Auto failover to some other master-eligible node in case of master going down. • By Default all nodes are master-eligible and also act as data nodes and client nodes. • Nodes auto discover themselves using multicast. • 1 Node per box
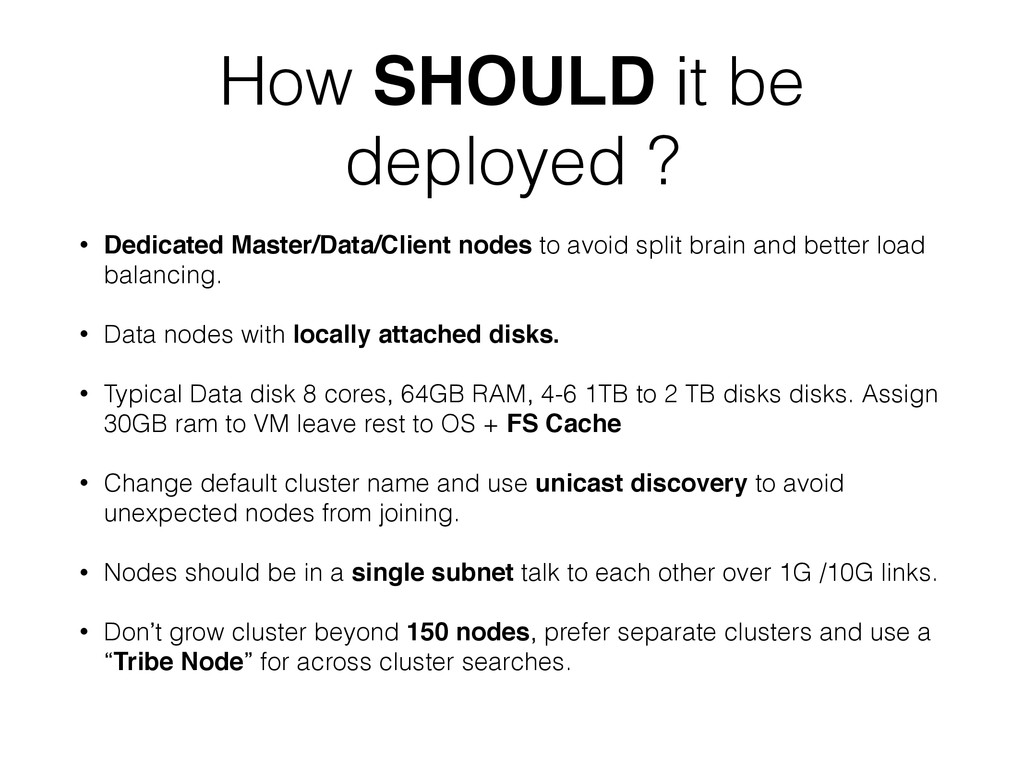
to avoid split brain and better load balancing. • Data nodes with locally attached disks. • Typical Data disk 8 cores, 64GB RAM, 4-6 1TB to 2 TB disks disks. Assign 30GB ram to VM leave rest to OS + FS Cache • Change default cluster name and use unicast discovery to avoid unexpected nodes from joining. • Nodes should be in a single subnet talk to each other over 1G /10G links. • Don’t grow cluster beyond 150 nodes, prefer separate clusters and use a “Tribe Node” for across cluster searches.
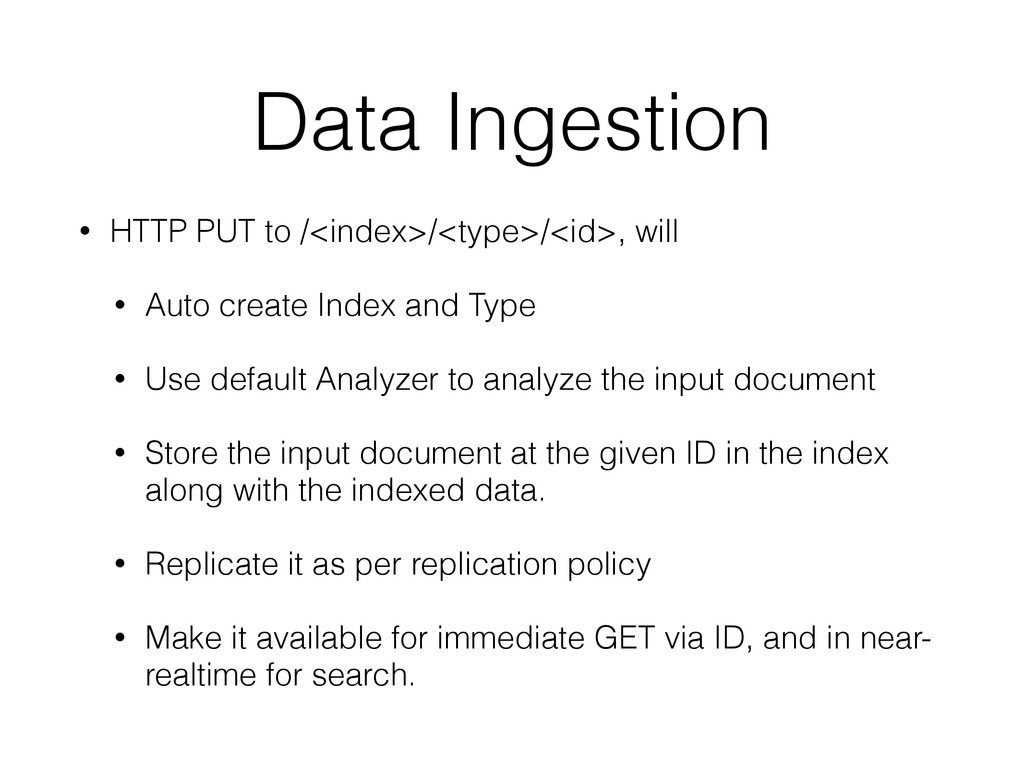
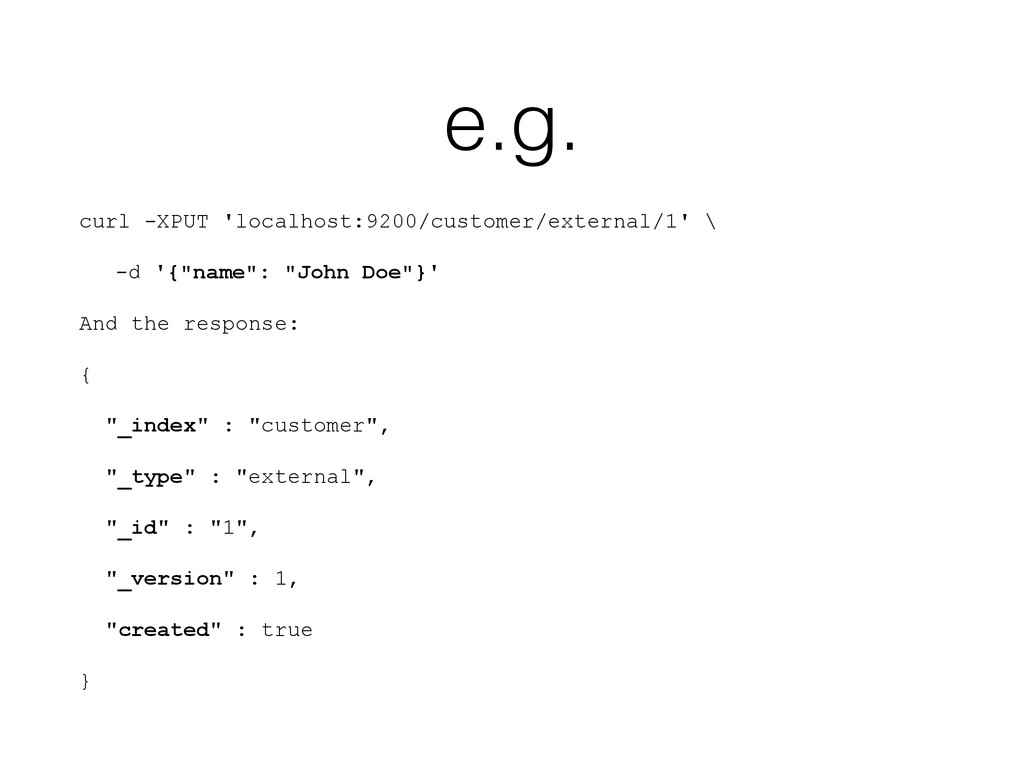
create Index and Type • Use default Analyzer to analyze the input document • Store the input document at the given ID in the index along with the indexed data. • Replicate it as per replication policy • Make it available for immediate GET via ID, and in near- realtime for search.
• Tokenizer can be preceded by 1+ Char Filter • Tokenizer breaks down strings in to stream of Tokens. e.g. “one two three” becomes ‘one’, ‘two’, ‘three’. Standard/Edge-ngram/keyword/pattern • Token Filters modify/delete/add tokens • Char Filters strip out /replace characters
• Use Mapping API to pre populate the metadata about documents belonging to a certain index/type. • Used for specifying Analyzer, Field data types, transformations etc. • Highly recommended to use even if default mappings are good enough.
query_string , field:’one or two or three’ • query string not recommended for prod. use. • query can comprise of search + filter. • search assigns a score , filter is just that a boolean gate. • Query DSL can be quite daunting at first, learn it like SQL.


 bhaskarvk
 everpeace
 goyoki
 hagino3000
 ota1022
 oracle4engineer
 jirtosterone
 atalie2m
 xkxaxkx
 say_no_w
 kworkdev
 sansantech
 ttelltte
 rkaga
 akashhashmi
 427marketing
 portentint
 tamaranovitovic
 davetheseo
 inesmontani
 cassininazir
 greggifford
 rkendrick25
 colly
 sferik