Share
Embed
Transcript
58 slides
-
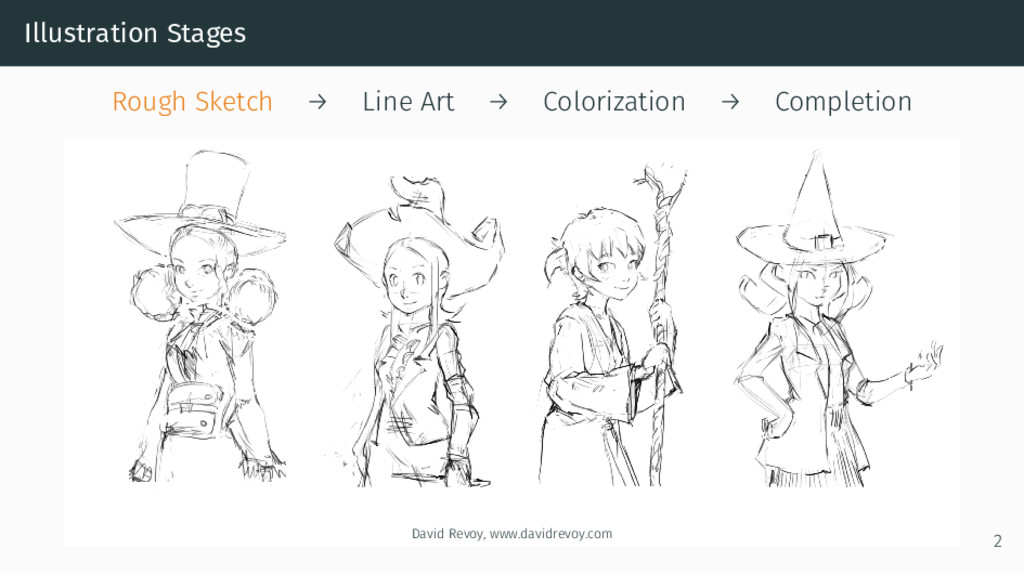
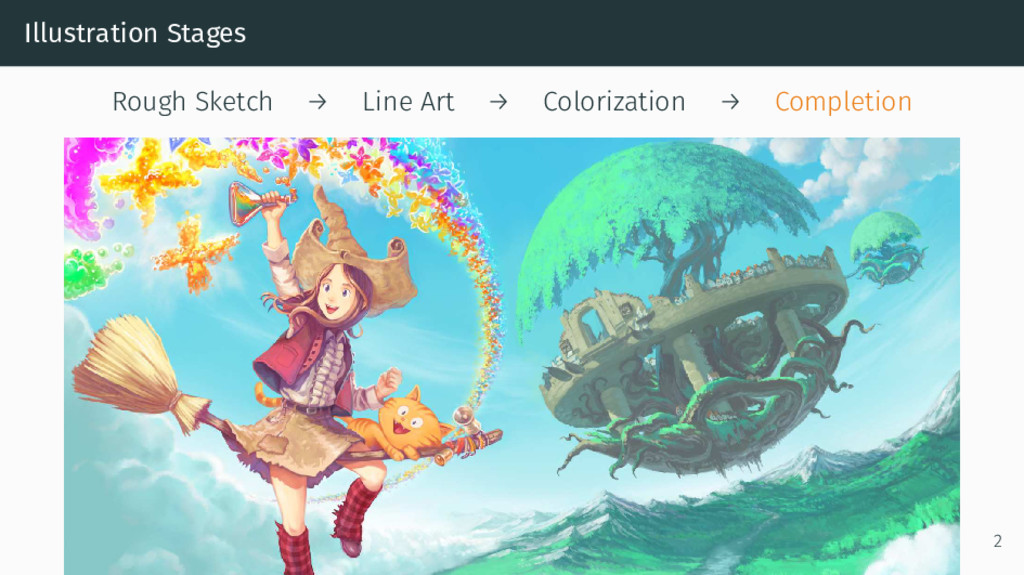
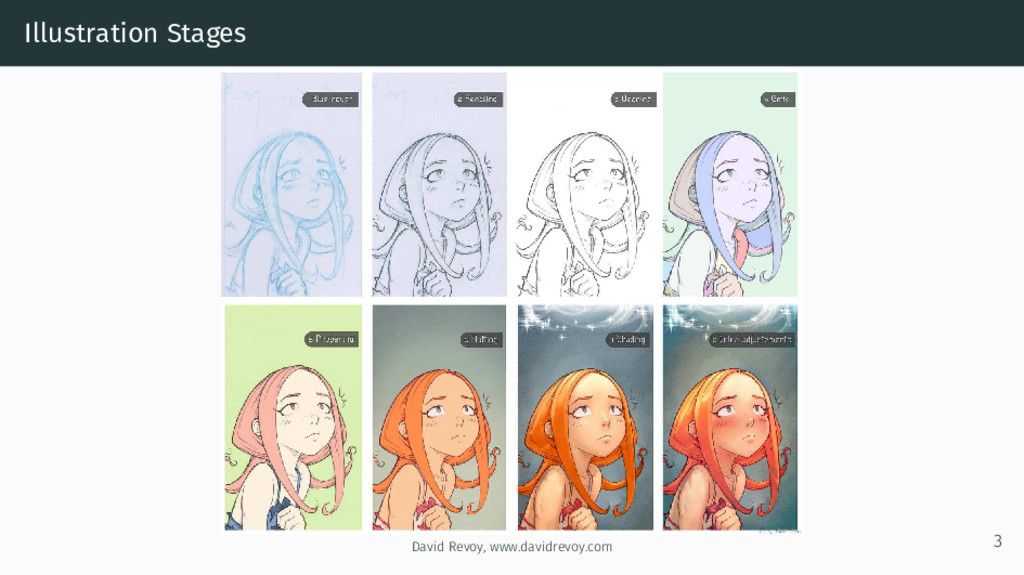
Illustration Stages Rough Sketch → Line Art → Colorization →
Completion David Revoy, www.davidrevoy.com 2 -
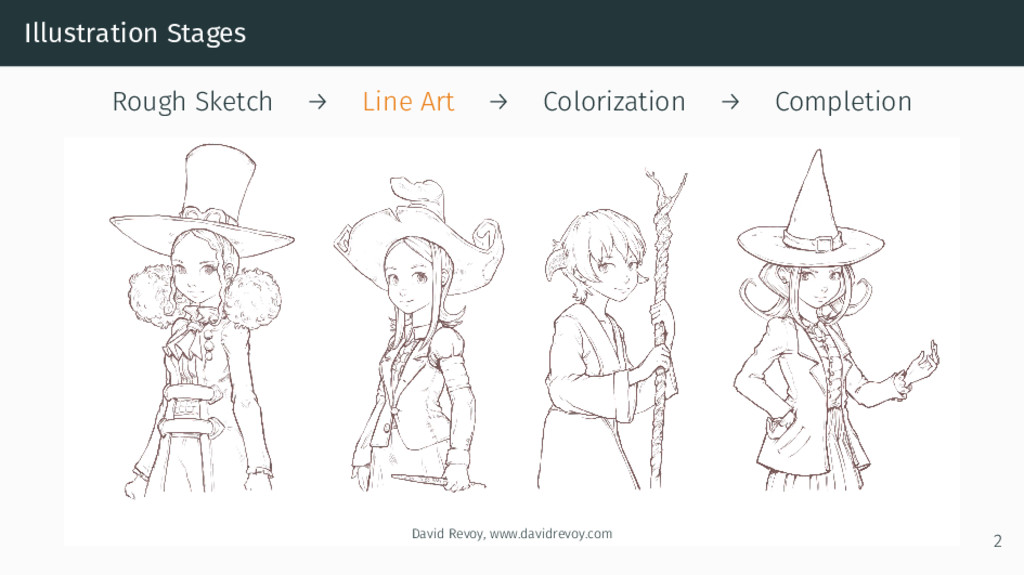
Illustration Stages Rough Sketch → Line Art → Colorization →
Completion David Revoy, www.davidrevoy.com 2 -
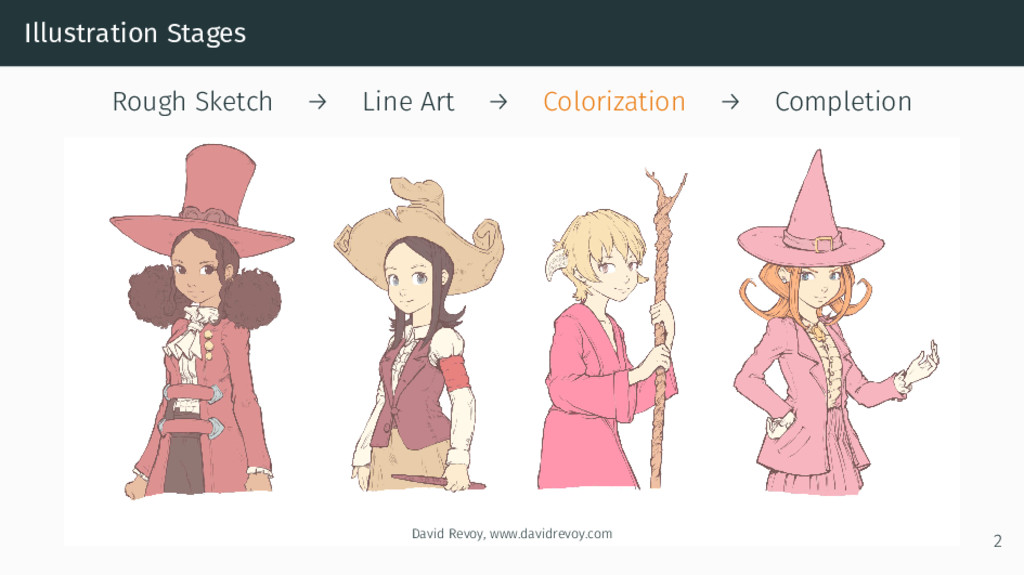
Illustration Stages Rough Sketch → Line Art → Colorization →
Completion David Revoy, www.davidrevoy.com 2 -
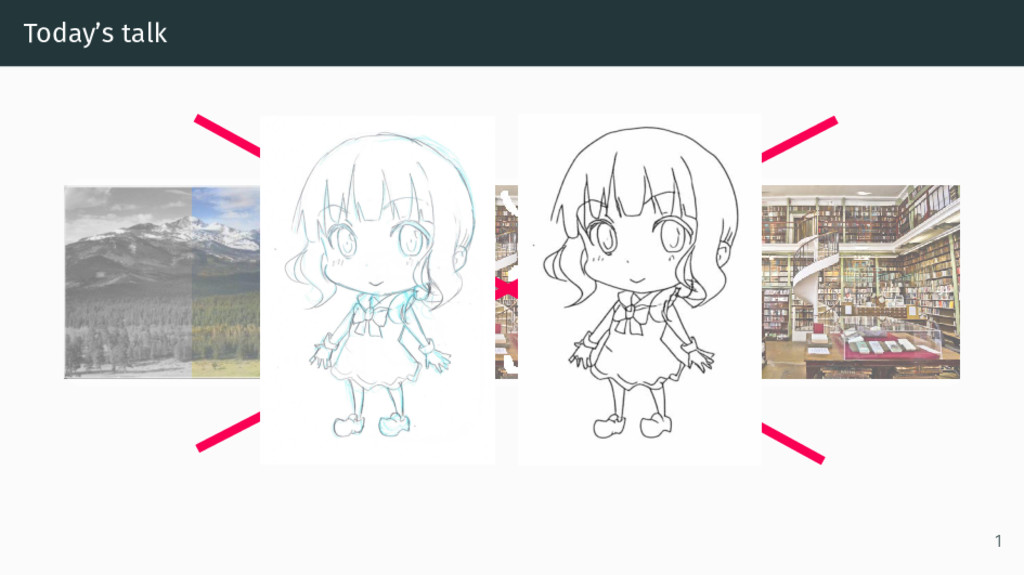
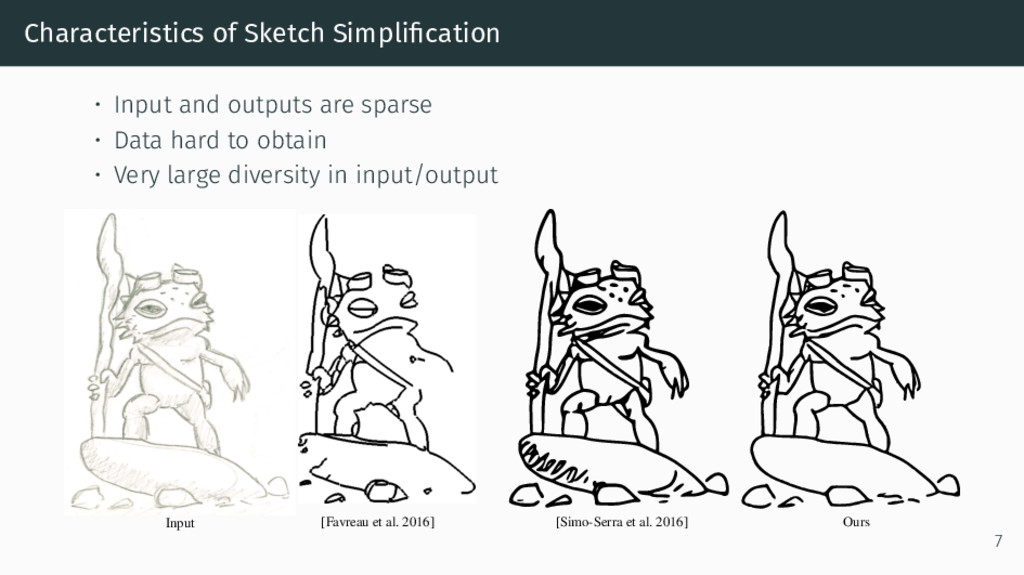
Characteristics of Sketch Simplification • Input and outputs are sparse
• Data hard to obtain • Very large diversity in input/output Input [Simo-Serra et al. 2016] Ours [Favreau et al. 2016] 7 -
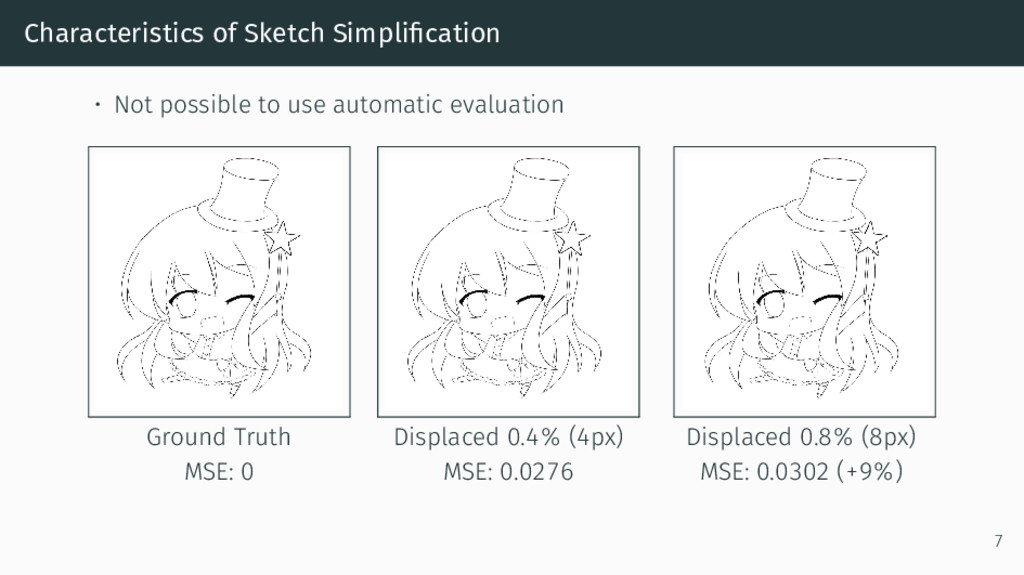
Characteristics of Sketch Simplification • Not possible to use automatic
evaluation Ground Truth Displaced 0.4% (4px) Displaced 0.8% (8px) MSE: 0 MSE: 0.0276 MSE: 0.0302 (+9%) 7 -
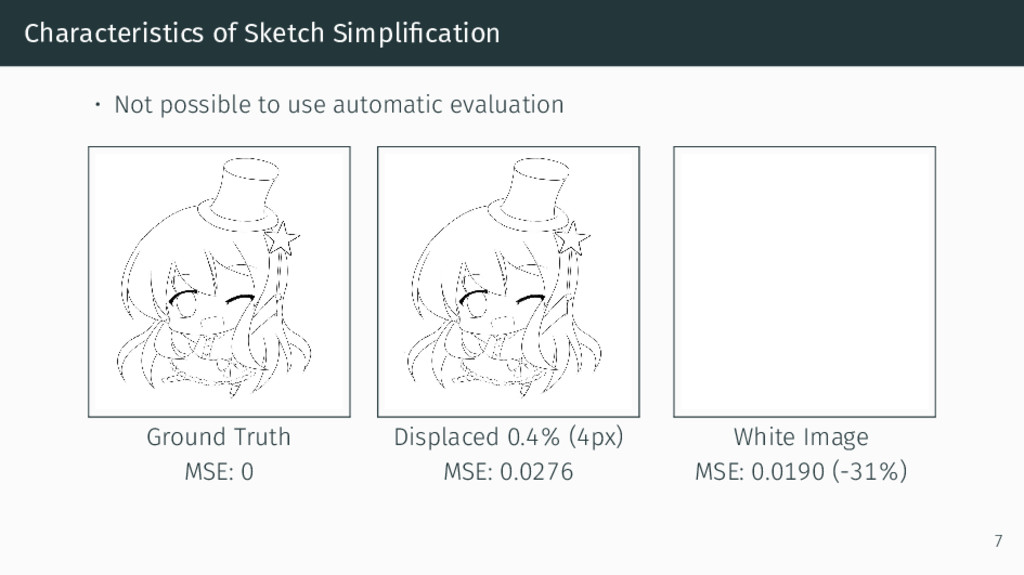
Characteristics of Sketch Simplification • Not possible to use automatic
evaluation Ground Truth Displaced 0.4% (4px) White Image MSE: 0 MSE: 0.0276 MSE: 0.0190 (-31%) 7 -
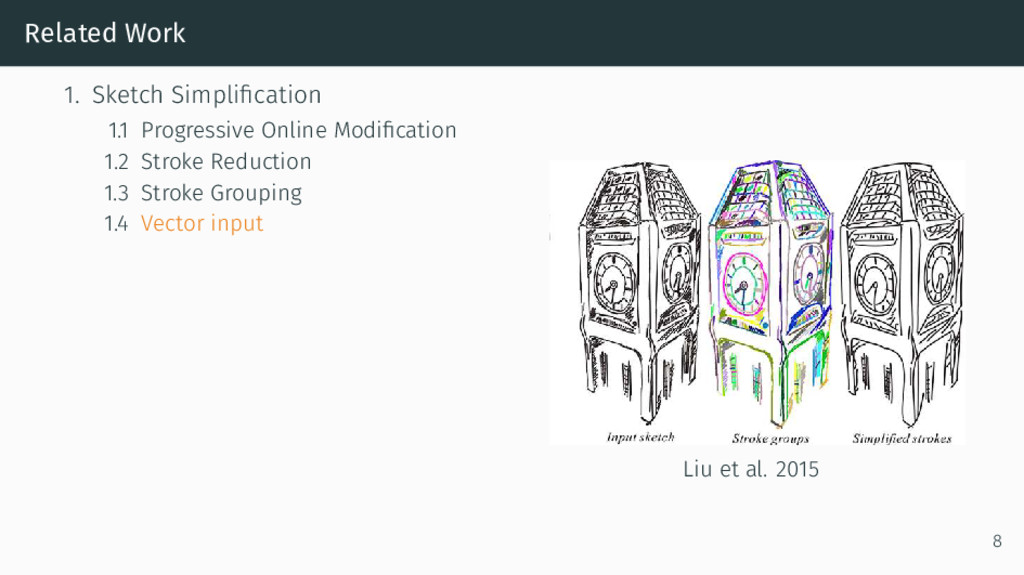
Related Work 1. Sketch Simplification 1.1 Progressive Online Modification 1.2
Stroke Reduction 1.3 Stroke Grouping 1.4 Vector input Liu et al. 2015 8 -
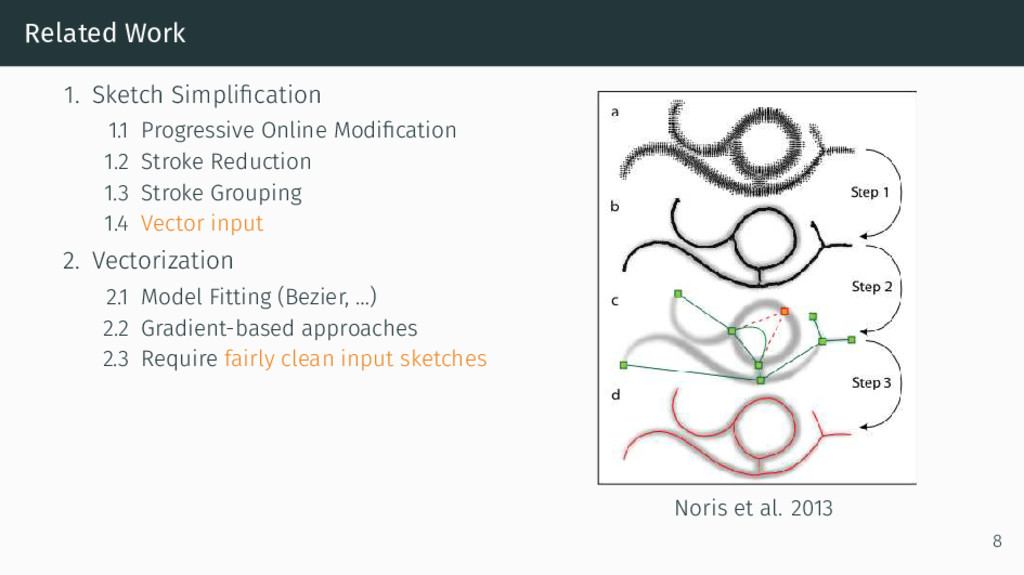
Related Work 1. Sketch Simplification 1.1 Progressive Online Modification 1.2
Stroke Reduction 1.3 Stroke Grouping 1.4 Vector input 2. Vectorization 2.1 Model Fitting (Bezier, …) 2.2 Gradient-based approaches 2.3 Require fairly clean input sketches Noris et al. 2013 8 -
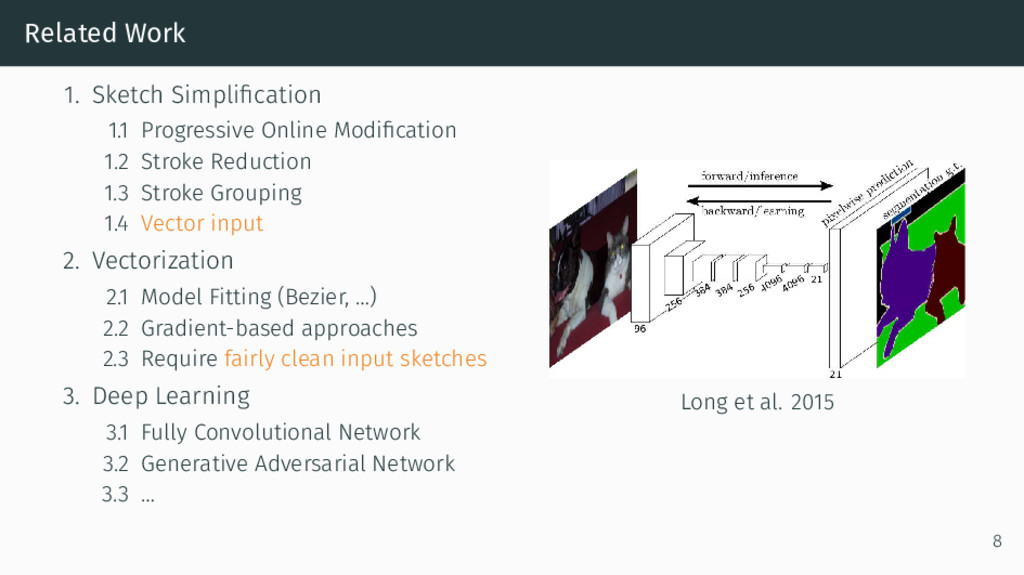
Related Work 1. Sketch Simplification 1.1 Progressive Online Modification 1.2
Stroke Reduction 1.3 Stroke Grouping 1.4 Vector input 2. Vectorization 2.1 Model Fitting (Bezier, …) 2.2 Gradient-based approaches 2.3 Require fairly clean input sketches 3. Deep Learning 3.1 Fully Convolutional Network 3.2 Generative Adversarial Network 3.3 … Long et al. 2015 8 -
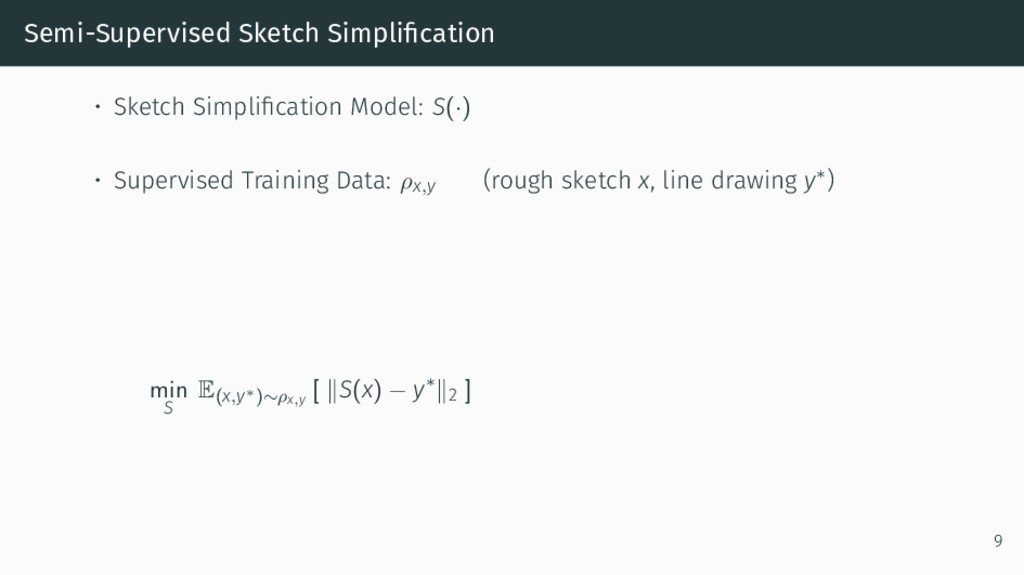
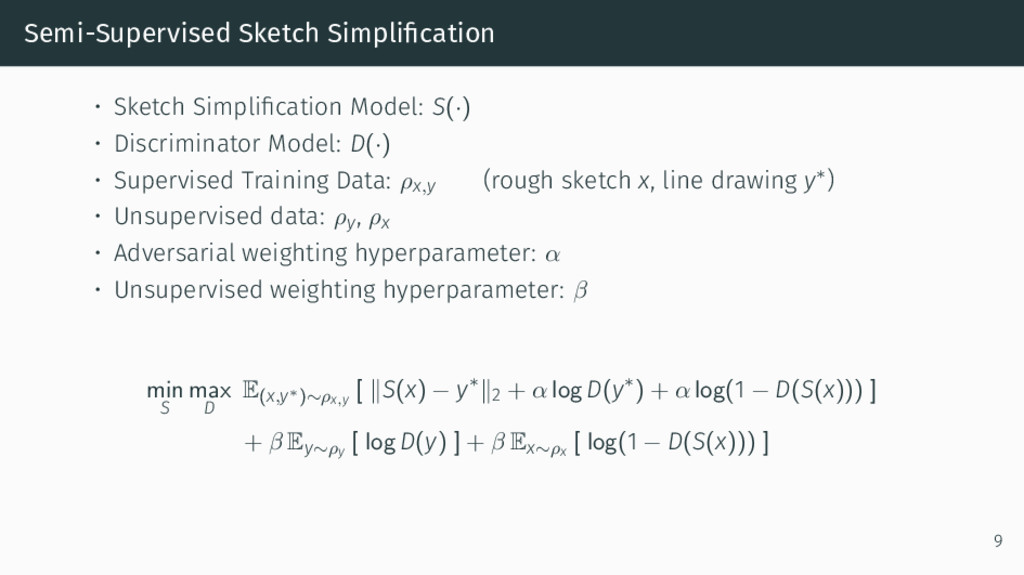
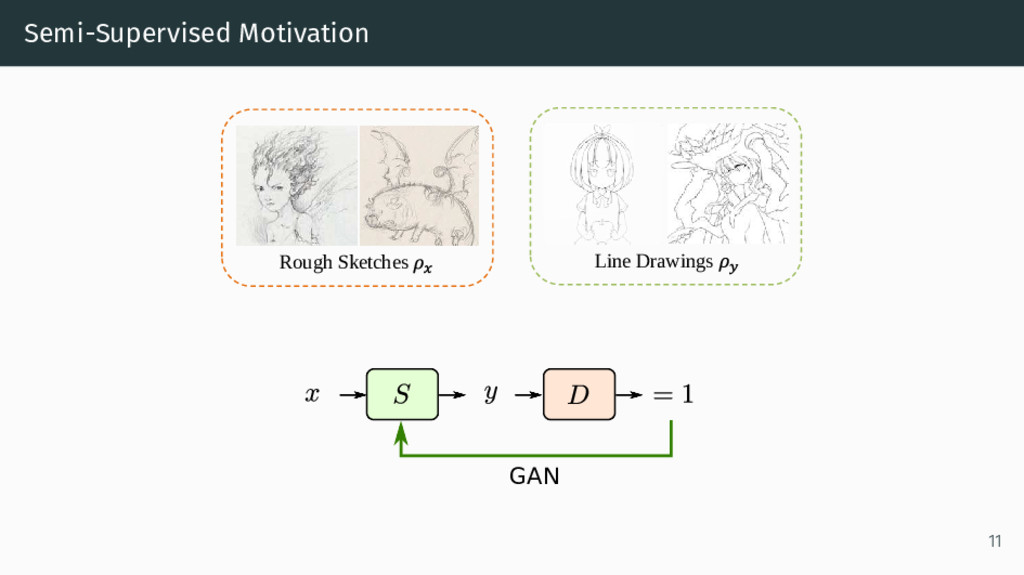
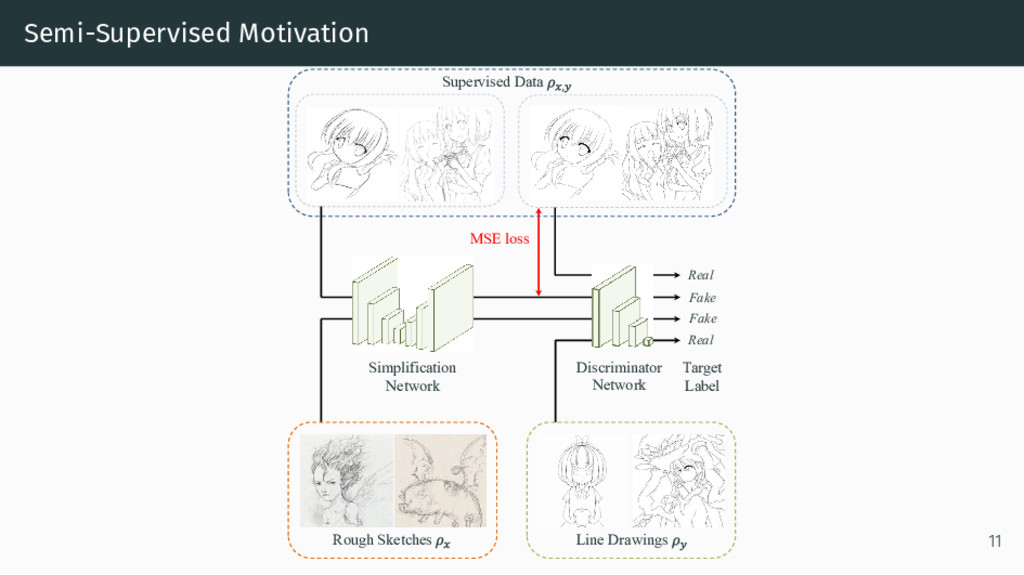
Semi-Supervised Sketch Simplification • Sketch Simplification Model: S(·) • Supervised
Training Data: ρx,y (rough sketch x, line drawing y∗) min S E(x,y∗)∼ρx , y [ S(x) − y∗ 2 ] 9 -
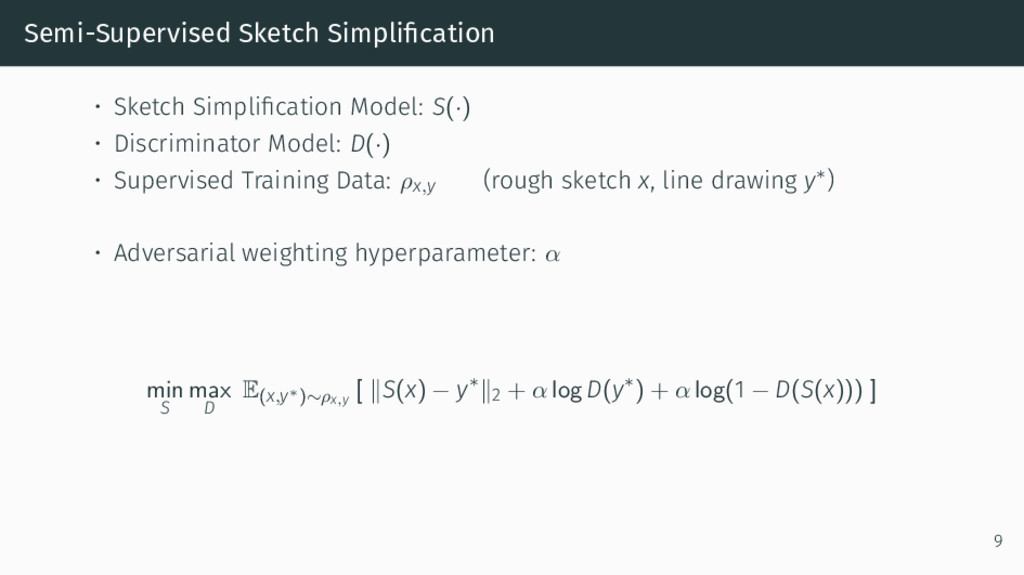
Semi-Supervised Sketch Simplification • Sketch Simplification Model: S(·) • Discriminator
Model: D(·) • Supervised Training Data: ρx,y (rough sketch x, line drawing y∗) • Adversarial weighting hyperparameter: α min S max D E(x,y∗)∼ρx , y [ S(x) − y∗ 2 + α log D(y∗) + α log(1 − D(S(x))) ] 9 -
Semi-Supervised Sketch Simplification • Sketch Simplification Model: S(·) • Discriminator
Model: D(·) • Supervised Training Data: ρx,y (rough sketch x, line drawing y∗) • Unsupervised data: ρy, ρx • Adversarial weighting hyperparameter: α • Unsupervised weighting hyperparameter: β min S max D E(x,y∗)∼ρx , y [ S(x) − y∗ 2 + α log D(y∗) + α log(1 − D(S(x))) ] + β Ey∼ρy [ log D(y) ] + β Ex∼ρx [ log(1 − D(S(x))) ] 9 -
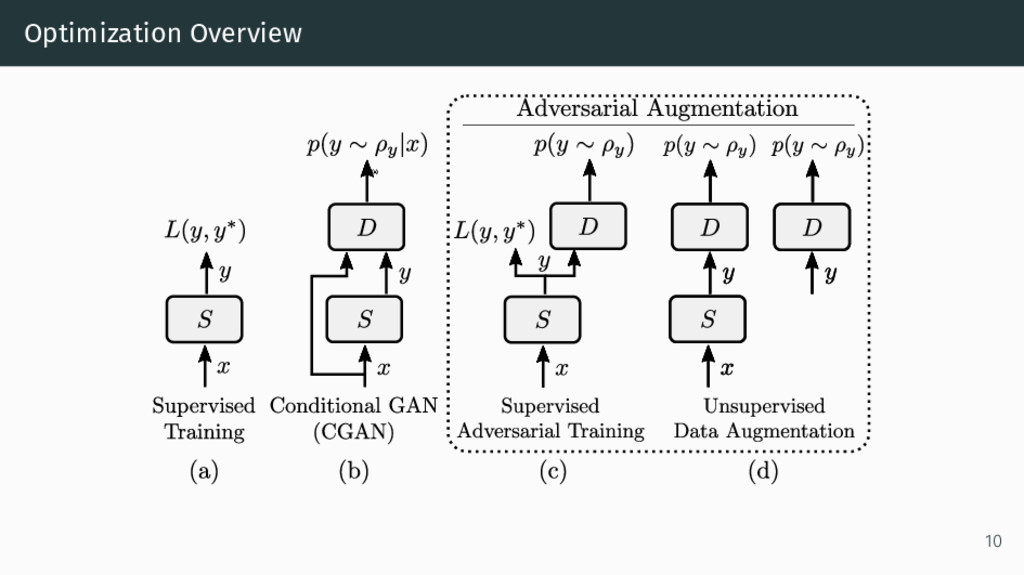
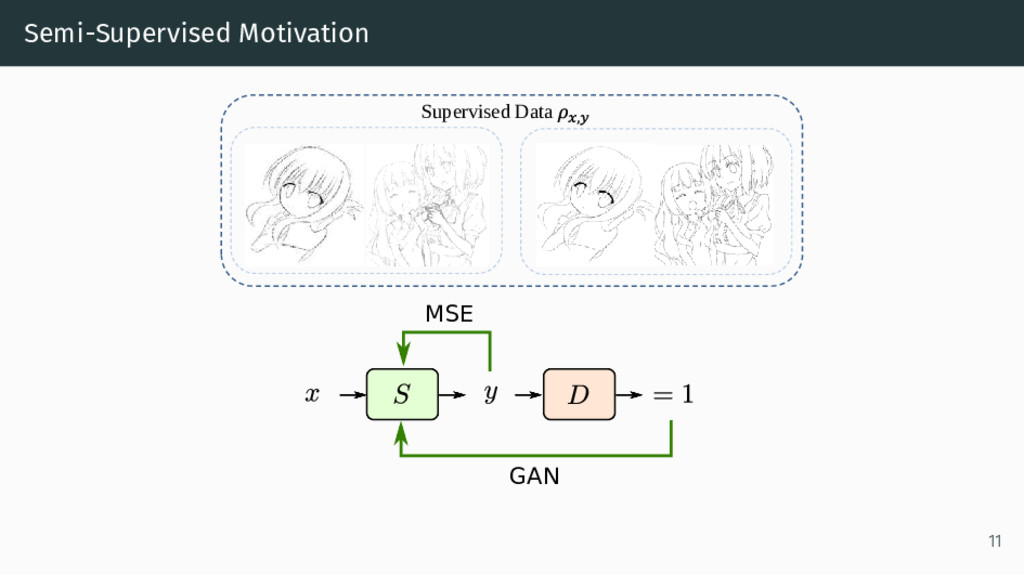
Semi-Supervised Motivation Rough Sketches Supervised Data Discriminator Network Line Drawings
Simplification Network Real Real Fake Fake Target Label MSE loss 11 -
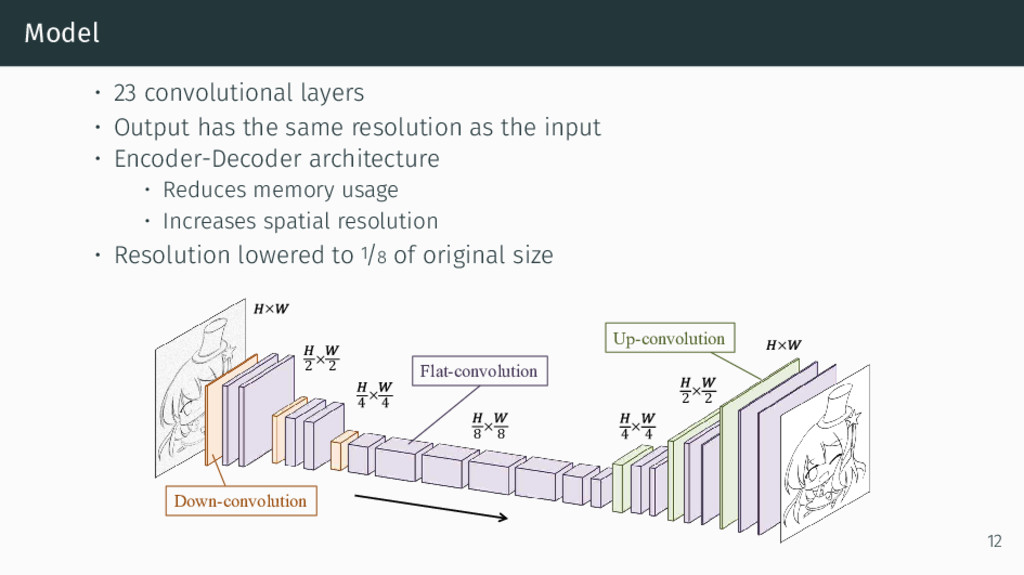
Model • 23 convolutional layers • Output has the same
resolution as the input • Encoder-Decoder architecture • Reduces memory usage • Increases spatial resolution • Resolution lowered to 1/8 of original size Flat-convolution Up-convolution 2 × 2 4 × 4 8 × 8 4 × 4 2 × 2 × × Down-convolution 12 -
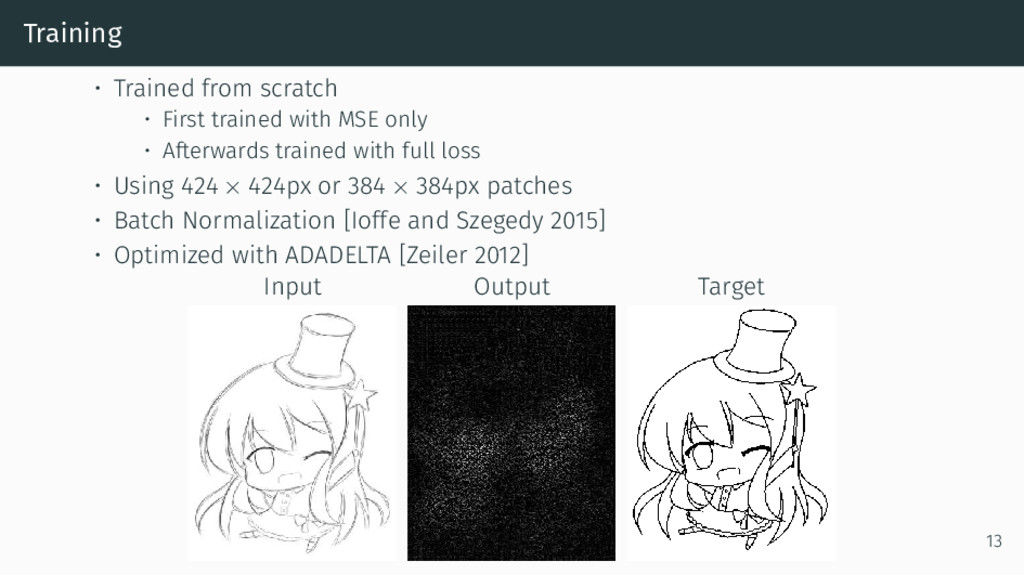
Training • Trained from scratch • First trained with MSE
only • Afterwards trained with full loss • Using 424 × 424px or 384 × 384px patches • Batch Normalization [Ioffe and Szegedy 2015] • Optimized with ADADELTA [Zeiler 2012] Input Output Target 13 -
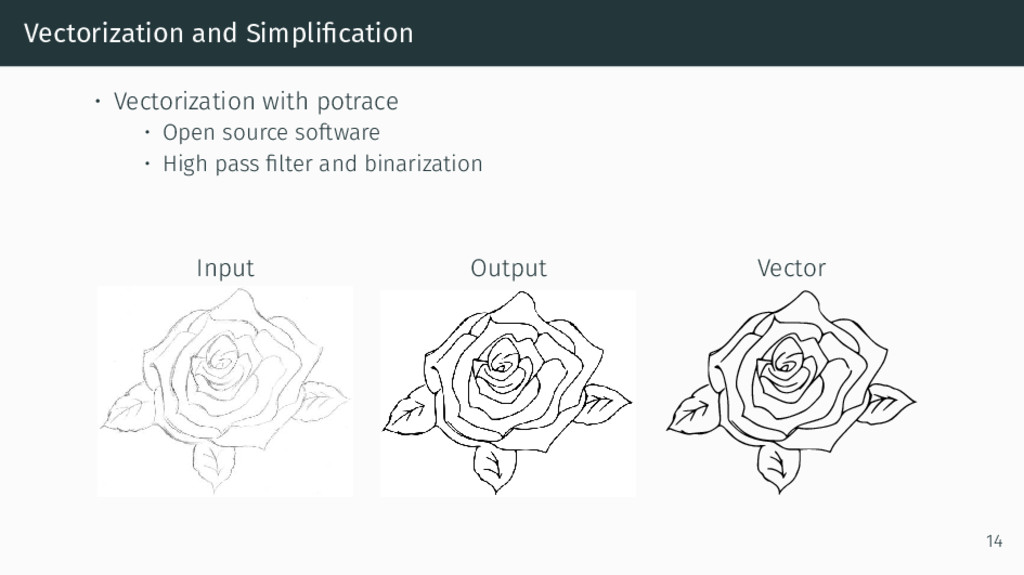
Vectorization and Simplification • Vectorization with potrace • Open source
software • High pass filter and binarization Input Output Vector 14 -
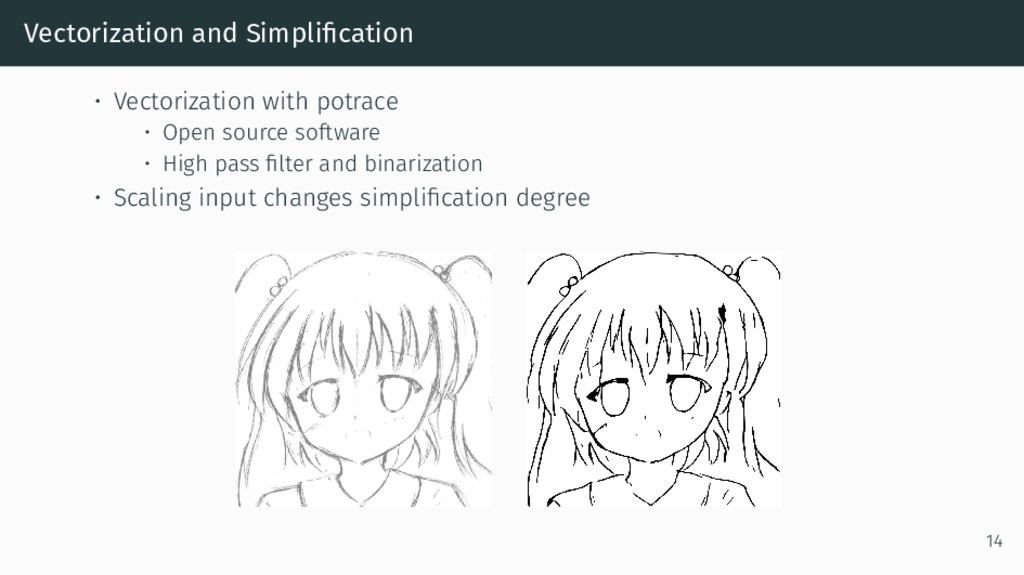
Vectorization and Simplification • Vectorization with potrace • Open source
software • High pass filter and binarization • Scaling input changes simplification degree 14 -
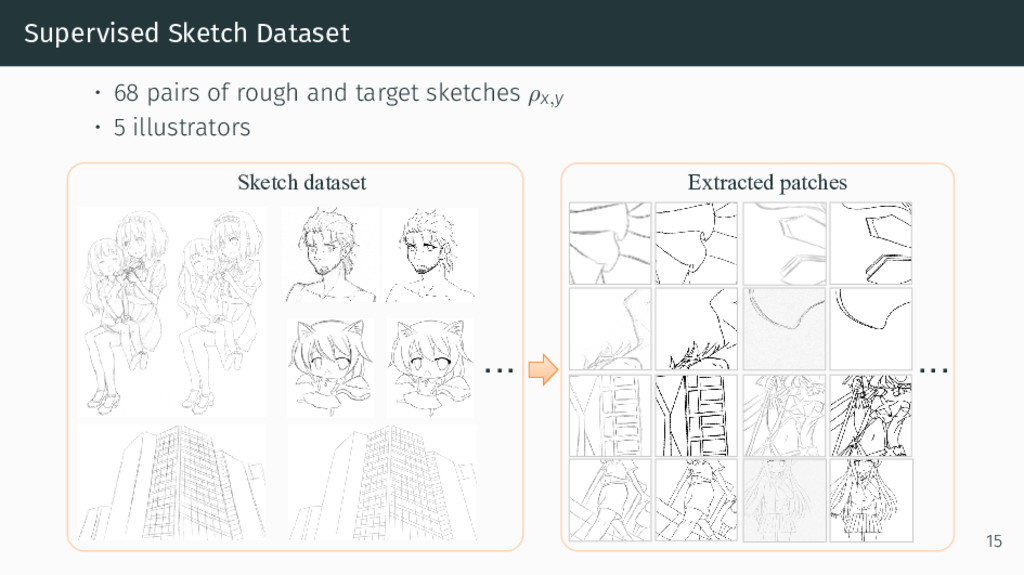
Supervised Sketch Dataset • 68 pairs of rough and target
sketches ρx,y • 5 illustrators ・・・ Extracted patches Sketch dataset ・・・ 15 -
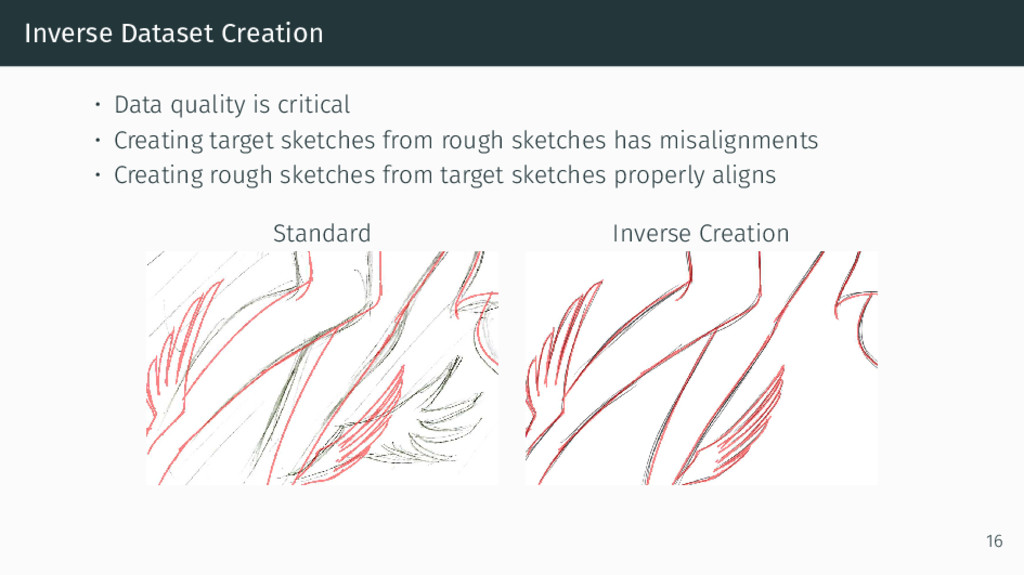
Inverse Dataset Creation • Data quality is critical • Creating
target sketches from rough sketches has misalignments • Creating rough sketches from target sketches properly aligns Standard Inverse Creation 16 -
Inverse Dataset Creation • Data quality is critical • Creating
target sketches from rough sketches has misalignments • Creating rough sketches from target sketches properly aligns 16 -
Data Augmentation • 68 pairs is insufficient • Scaling training
data • Random cropping, flipping and rotation • Additional augmentation: tone, slur, and noise input tone slur noise 17 -
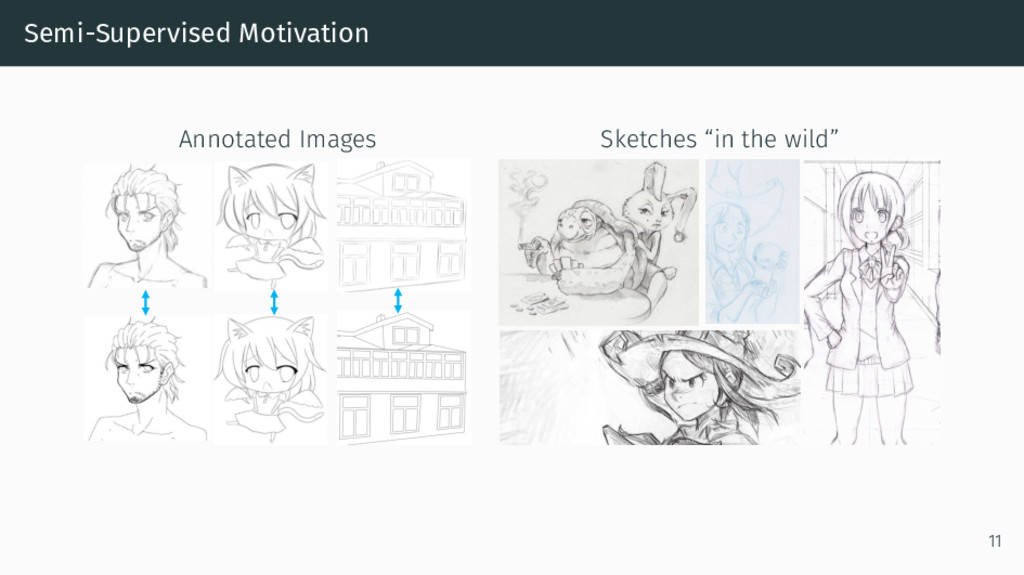
Unsupervised Data • Obtained from a diversity of sources •
Known illustrators • Web search • All manually verified • All from different authors than training data • 109 unsupervised clean sketches ρy • 85 unsupervised rough sketches ρx 18 -
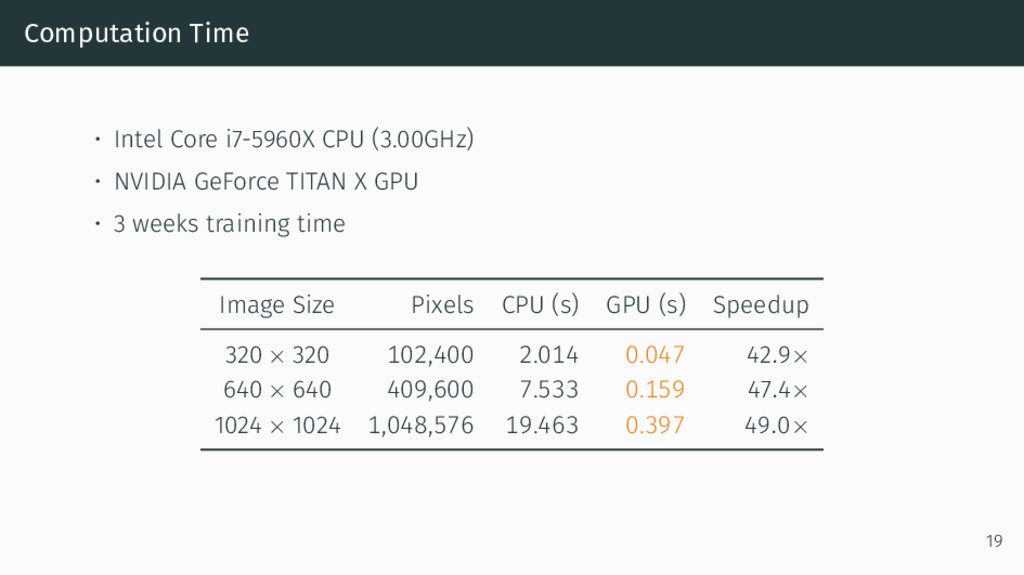
Computation Time • Intel Core i7-5960X CPU (3.00GHz) • NVIDIA
GeForce TITAN X GPU • 3 weeks training time Image Size Pixels CPU (s) GPU (s) Speedup 320 × 320 102,400 2.014 0.047 42.9× 640 × 640 409,600 7.533 0.159 47.4× 1024 × 1024 1,048,576 19.463 0.397 49.0× 19 -
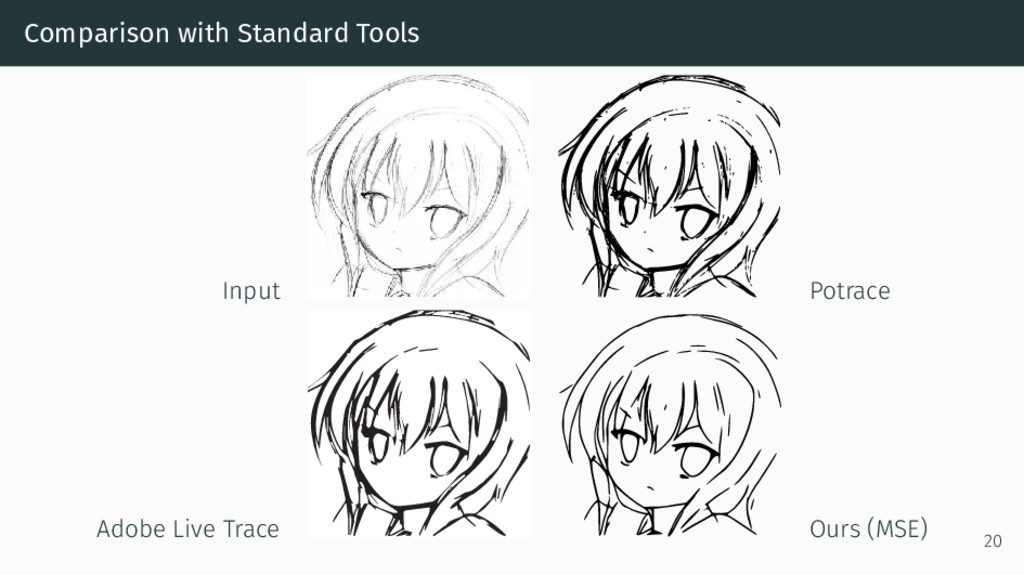
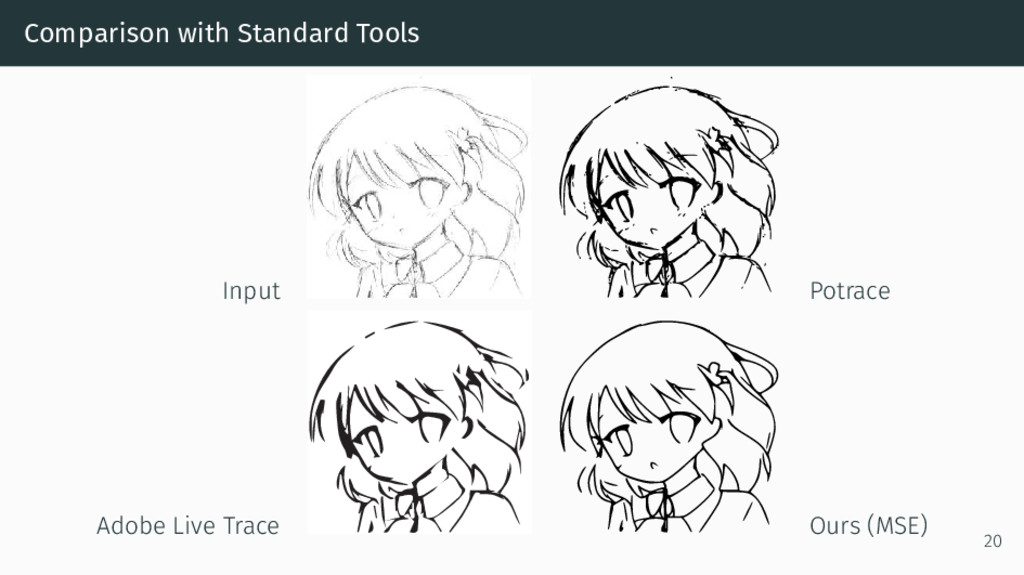
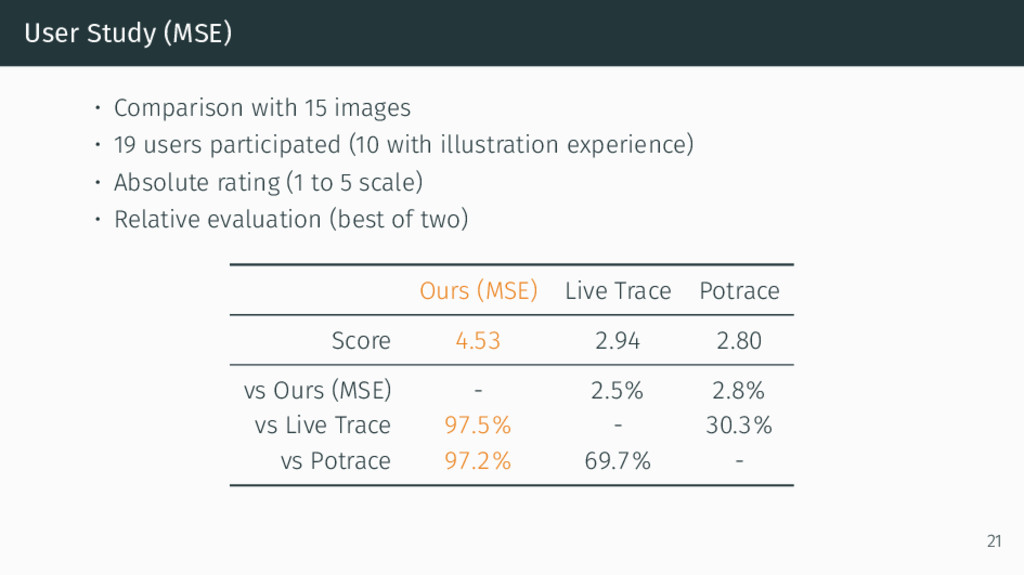
User Study (MSE) • Comparison with 15 images • 19
users participated (10 with illustration experience) • Absolute rating (1 to 5 scale) • Relative evaluation (best of two) Ours (MSE) Live Trace Potrace Score 4.53 2.94 2.80 vs Ours (MSE) - 2.5% 2.8% vs Live Trace 97.5% - 30.3% vs Potrace 97.2% 69.7% - 21 -
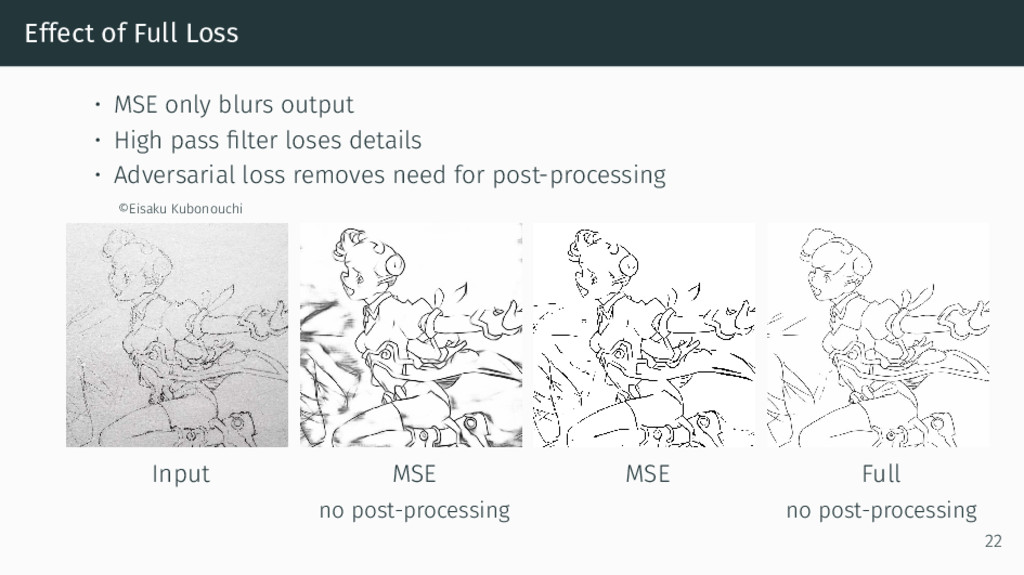
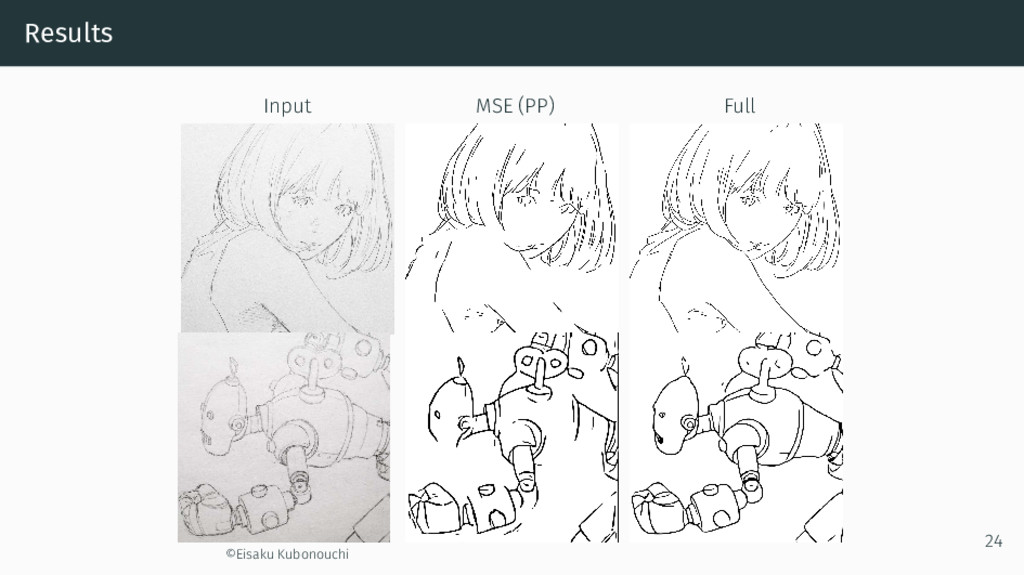
Effect of Full Loss • MSE only blurs output •
High pass filter loses details • Adversarial loss removes need for post-processing ©Eisaku Kubonouchi Input MSE MSE Full no post-processing no post-processing 22 -
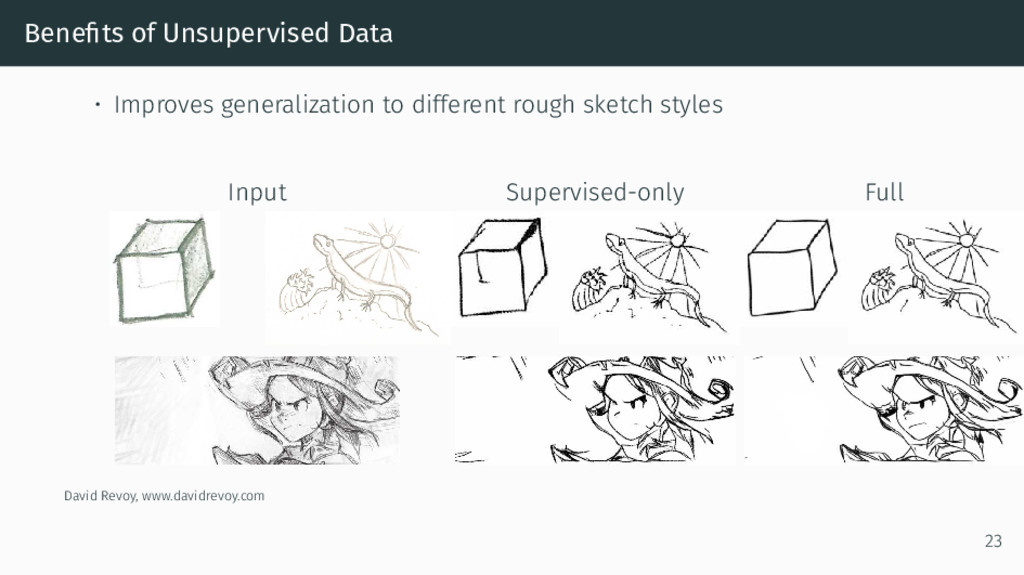
Benefits of Unsupervised Data • Improves generalization to different rough
sketch styles Input Supervised-only Full David Revoy, www.davidrevoy.com 23 -
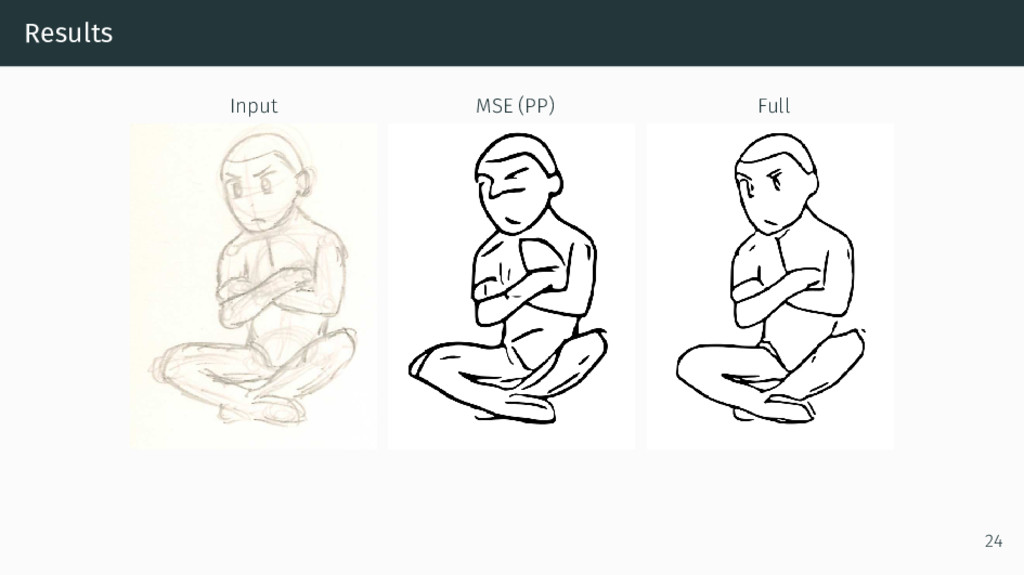
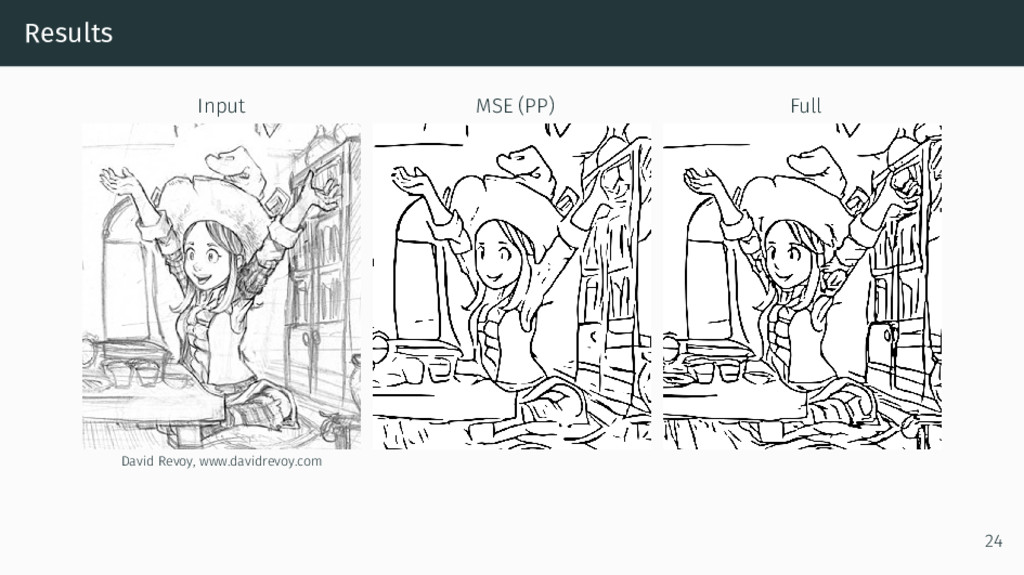
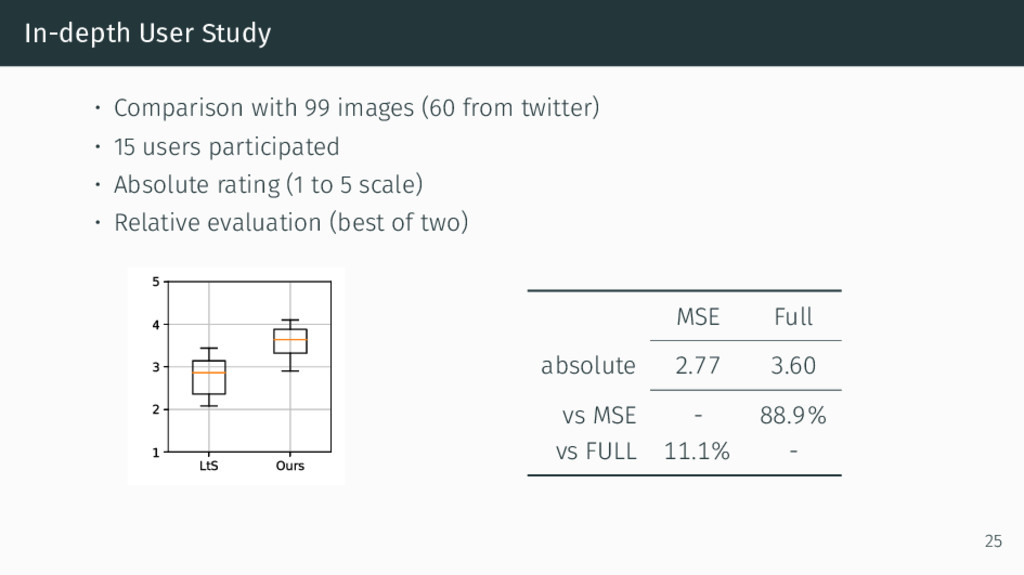
In-depth User Study • Comparison with 99 images (60 from
twitter) • 15 users participated • Absolute rating (1 to 5 scale) • Relative evaluation (best of two) LtS Ours 1 2 3 4 5 MSE Full absolute 2.77 3.60 vs MSE - 88.9% vs FULL 11.1% - 25 -
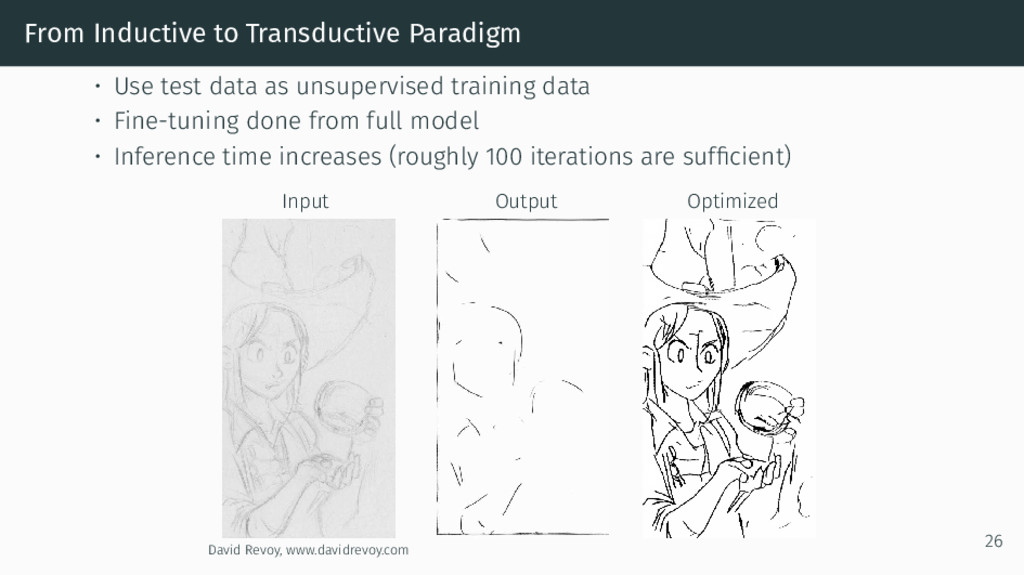
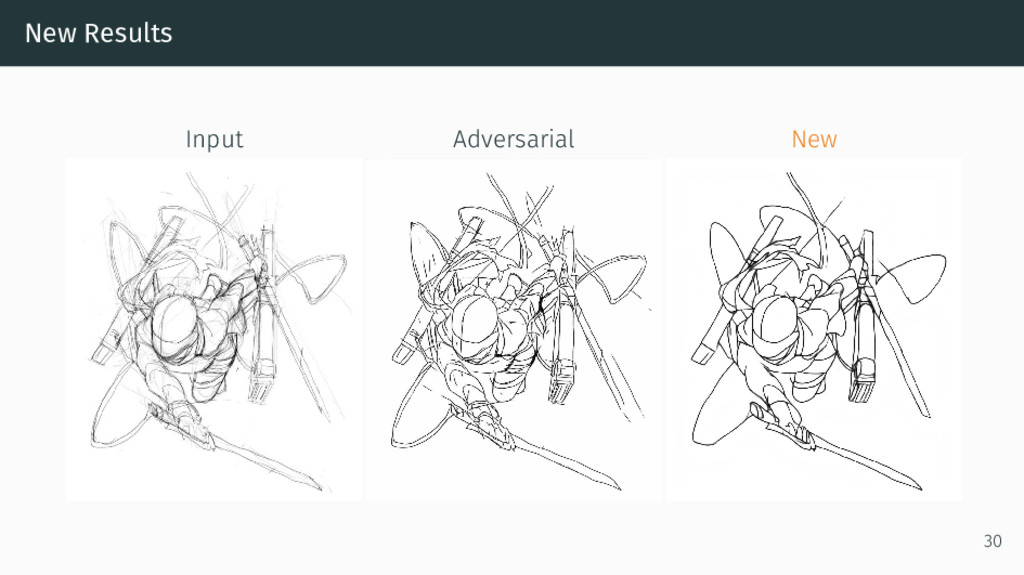
From Inductive to Transductive Paradigm • Use test data as
unsupervised training data • Fine-tuning done from full model • Inference time increases (roughly 100 iterations are sufficient) Input Output Optimized David Revoy, www.davidrevoy.com 26 -
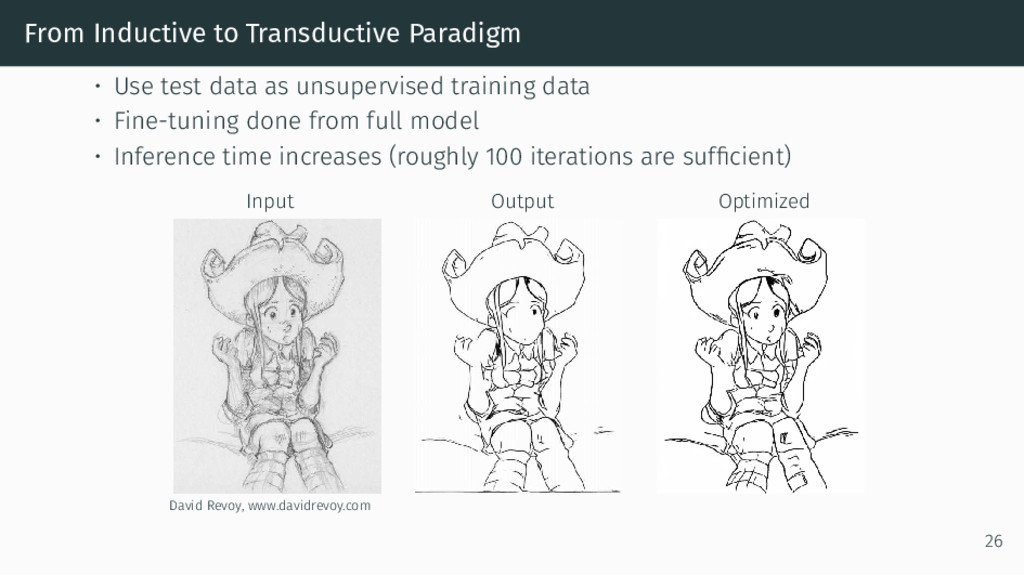
From Inductive to Transductive Paradigm • Use test data as
unsupervised training data • Fine-tuning done from full model • Inference time increases (roughly 100 iterations are sufficient) Input Output Optimized David Revoy, www.davidrevoy.com 26 -
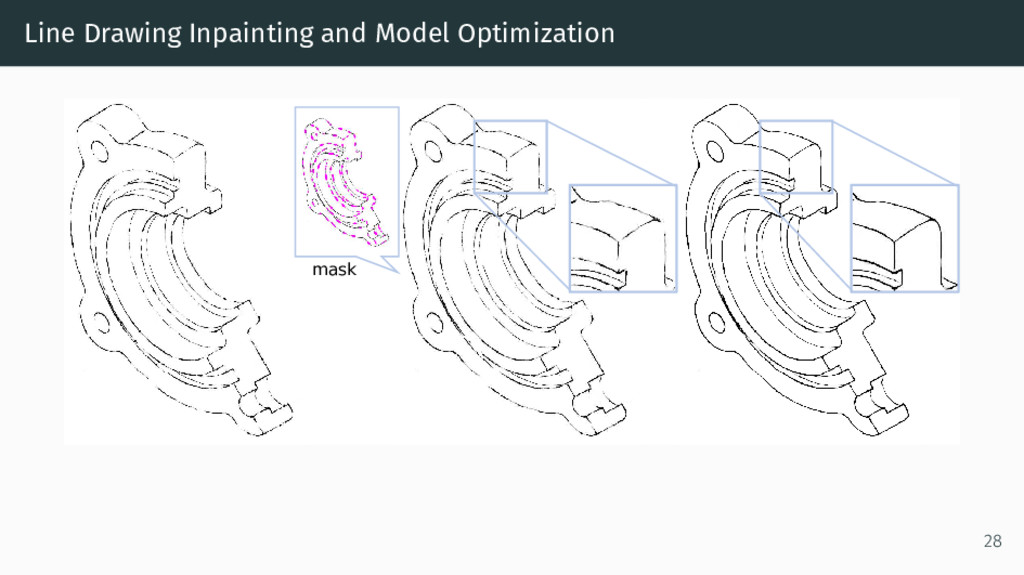
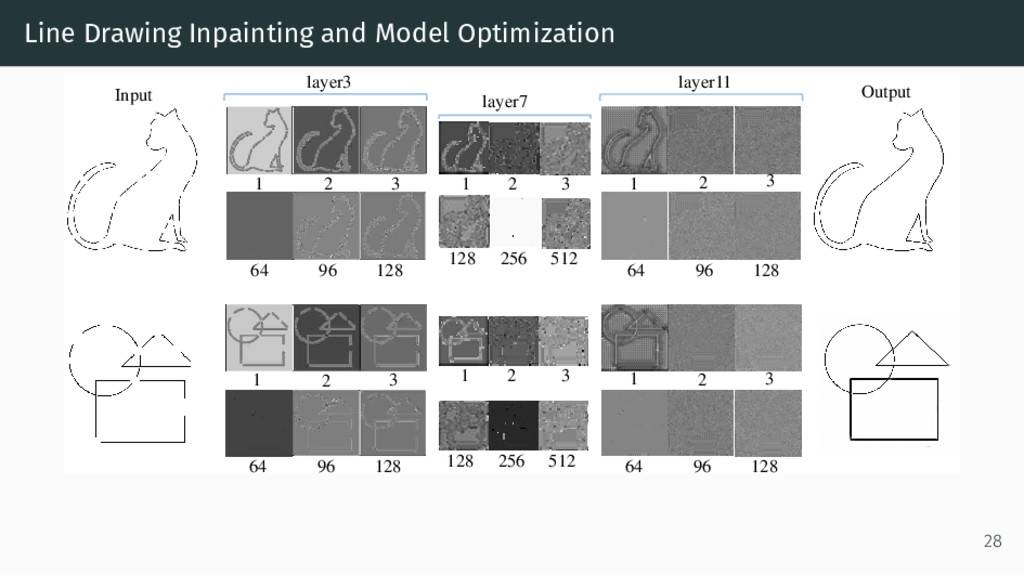
Line Drawing Inpainting and Model Optimization 1 2 3 64
96 128 1 2 3 128 256 512 1 2 3 64 96 128 layer3 layer7 layer11 1 2 3 64 96 128 1 2 3 128 256 512 1 2 3 64 96 128 Input Output 28 -
Conclusions • Sketch simplification is a hard problem • Adversarial
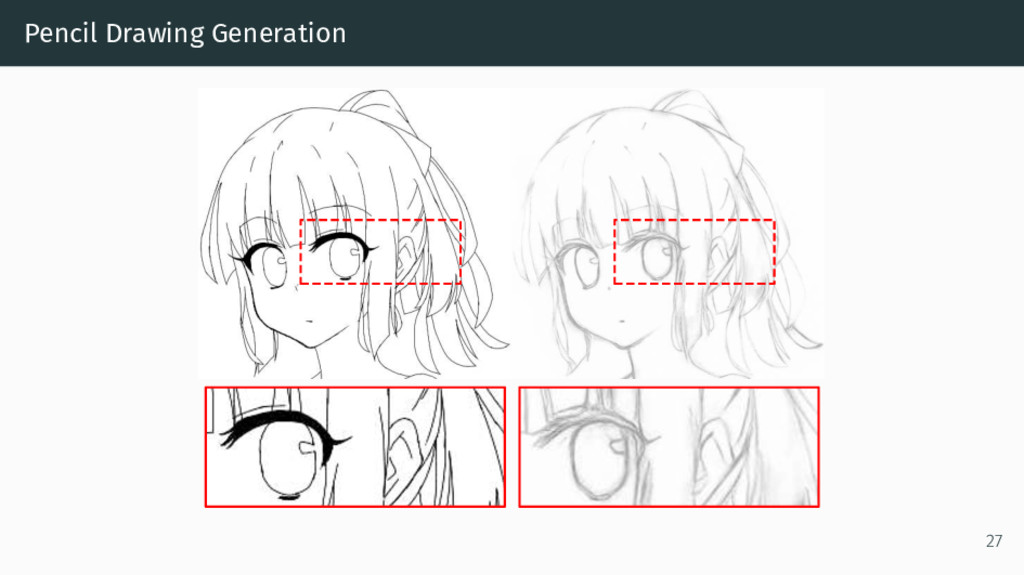
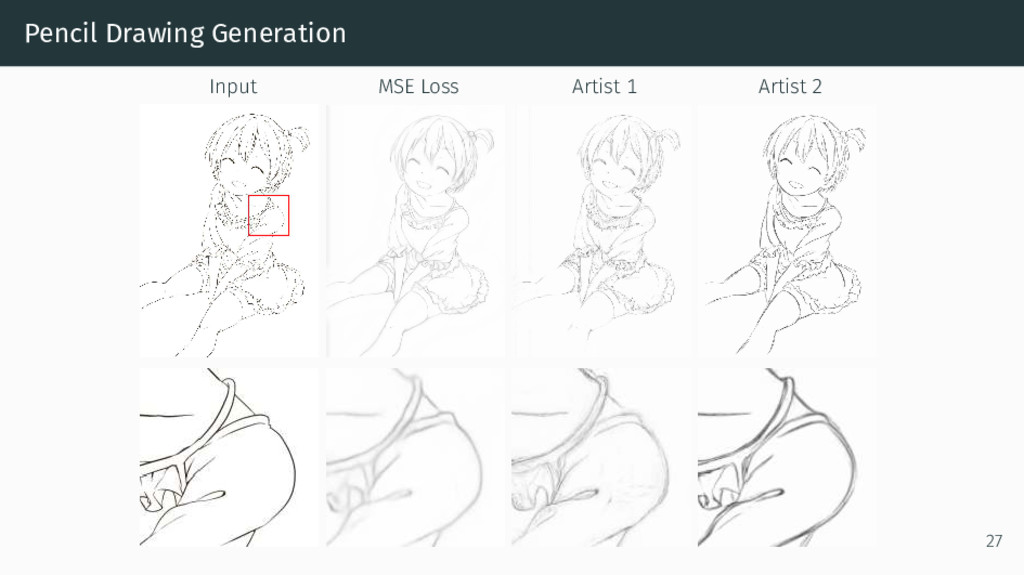
learning beneficial • Eliminates post-processing • Semi-supervised training • Transductive learning • Pencil drawing generation 29 -
Conclusions • Sketch simplification is a hard problem • Adversarial
learning beneficial • Eliminates post-processing • Semi-supervised training • Transductive learning • Pencil drawing generation • Limitations • Training data • Adversarial (in)stability 29 -
Conclusions • Sketch simplification is a hard problem • Adversarial
learning beneficial • Eliminates post-processing • Semi-supervised training • Transductive learning • Pencil drawing generation • Limitations • Training data • Adversarial (in)stability • Future directions • Graphical model post-processing • Colorization • Improving transductive learning 29 -
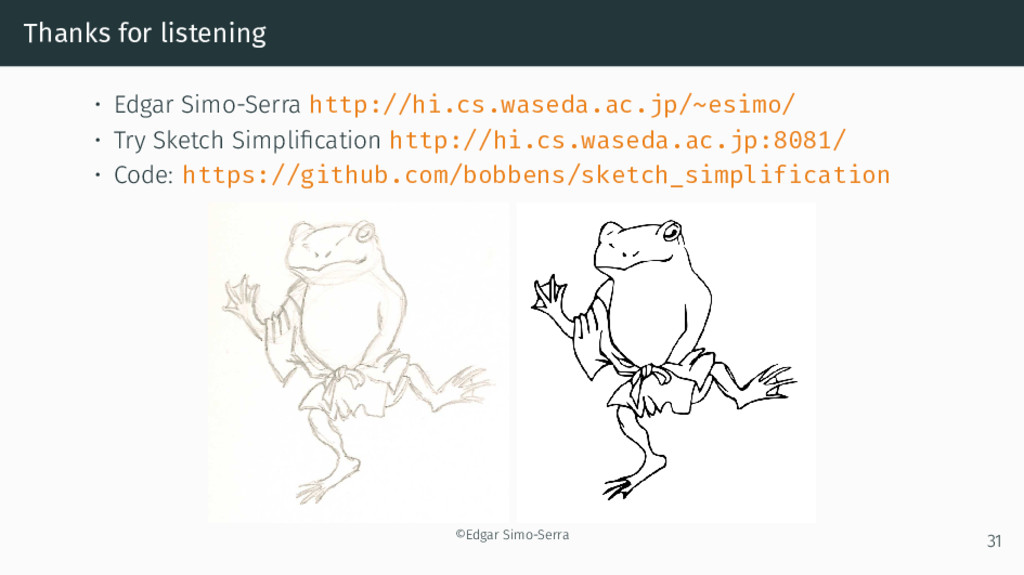
Thanks for listening • Edgar Simo-Serra http://hi.cs.waseda.ac.jp/~esimo/ • Try Sketch
Simplification http://hi.cs.waseda.ac.jp:8081/ • Code: https://github.com/bobbens/sketch_simplification ©Edgar Simo-Serra 31