Share
Distributing Queries the Citus Way | PostgresConf US 2018 | Marco Slot
Citus is a sharding extension for Postgres that can efficiently distribute a wide range of SQL queries. It uses Postgres' planner hook to transparently intercept and plan queries on "distributed" tables. Citus then executes the queries in parallel across many servers, in a way that delegates most of the heavy lifting back to Postgres.
Within Citus, we distinguish between several types of SQL queries, which each have their own planning logic:
Local-only queries
Single-node “router” queries
Multi-node “real-time” queries
Multi-stage queries
Each type of query corresponds to a different use case, and Citus implements several planners and executors using different techniques to accommodate the performance requirements and trade-offs for each use case.
This talk will discuss the internals of the different types of planners and executors for distributing SQL on top of Postgres, and how they can be applied to different use cases.
Citus Data
Transcript
53 slides
-
Citus is an open source extension to Postgres (9.6, 10,
11) for transparently distributing tables across many Postgres servers. What is Citus? 2 Marco Slot | Citus Data | PostgresConf US 2018 Coordinator data_1 data create_distributed_table('data', 'tenant_id'); data_4 data_2 data_5 data_3 data_6 -
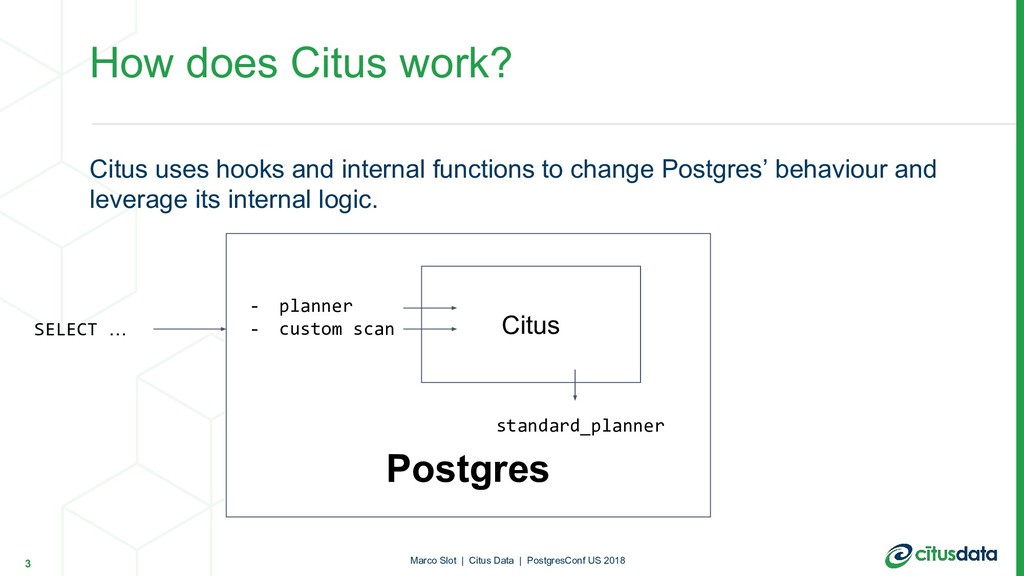
Citus uses hooks and internal functions to change Postgres’ behaviour
and leverage its internal logic. How does Citus work? 3 Marco Slot | Citus Data | PostgresConf US 2018 Postgres Citus - planner - custom scan SELECT … standard_planner -
There are different use cases that can take advantage of
distributed databases, in different ways. Examples: • Multi-tenant SaaS app needs to scale beyond a single server • Real-time analytics dashboards with high data volumes • Advanced search across large, dynamic data sets • Business intelligence Different use cases for scaling out 4 Marco Slot | Citus Data | PostgresConf US 2018 -
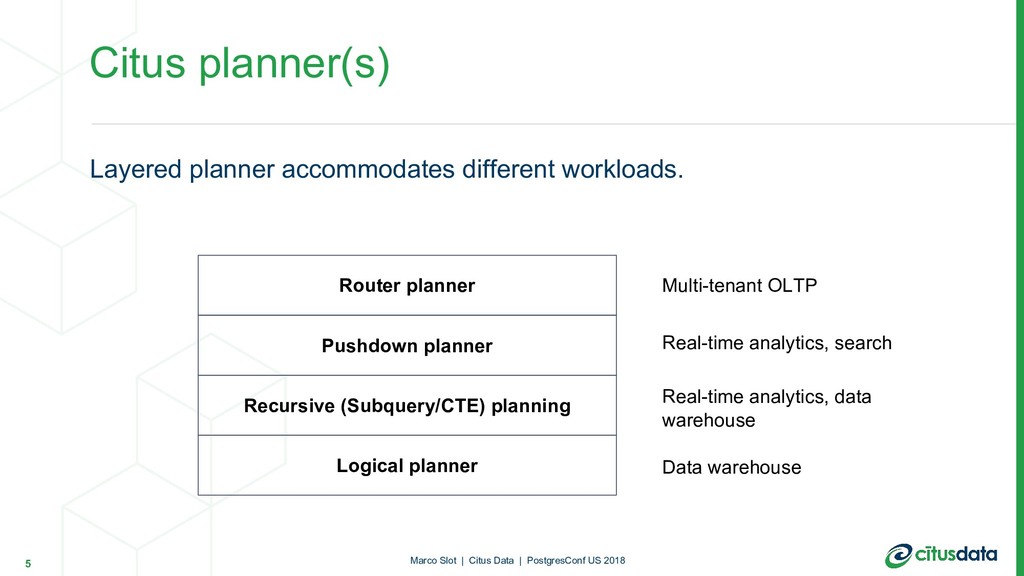
Layered planner accommodates different workloads. Citus planner(s) 5 Marco Slot
| Citus Data | PostgresConf US 2018 Router planner Pushdown planner Recursive (Subquery/CTE) planning Logical planner Multi-tenant OLTP Real-time analytics, search Real-time analytics, data warehouse Data warehouse -
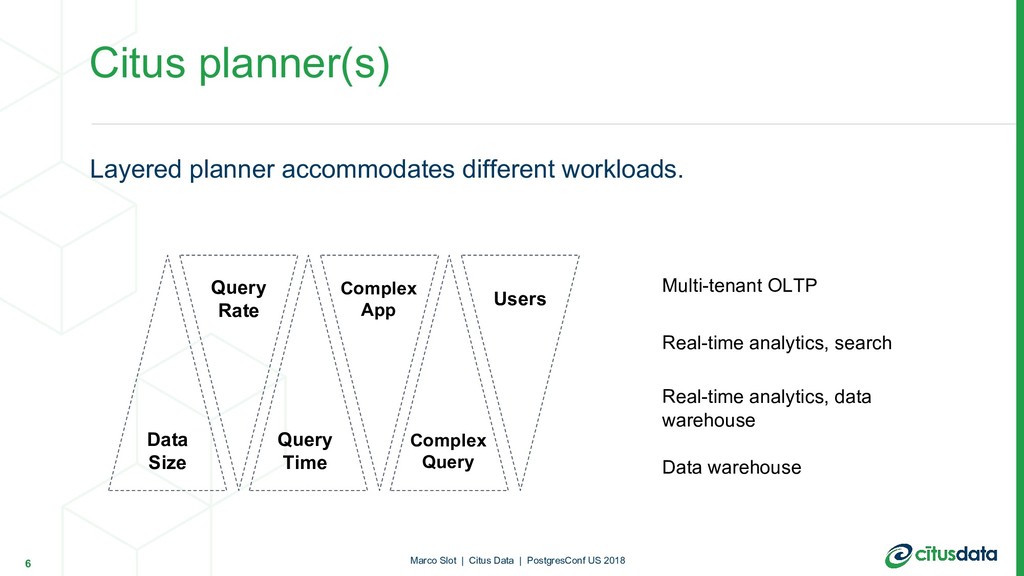
Layered planner accommodates different workloads. Citus planner(s) 6 Marco Slot
| Citus Data | PostgresConf US 2018 Query Rate Query Time Data Size Complex App Complex Query Users Multi-tenant OLTP Real-time analytics, search Real-time analytics, data warehouse Data warehouse -
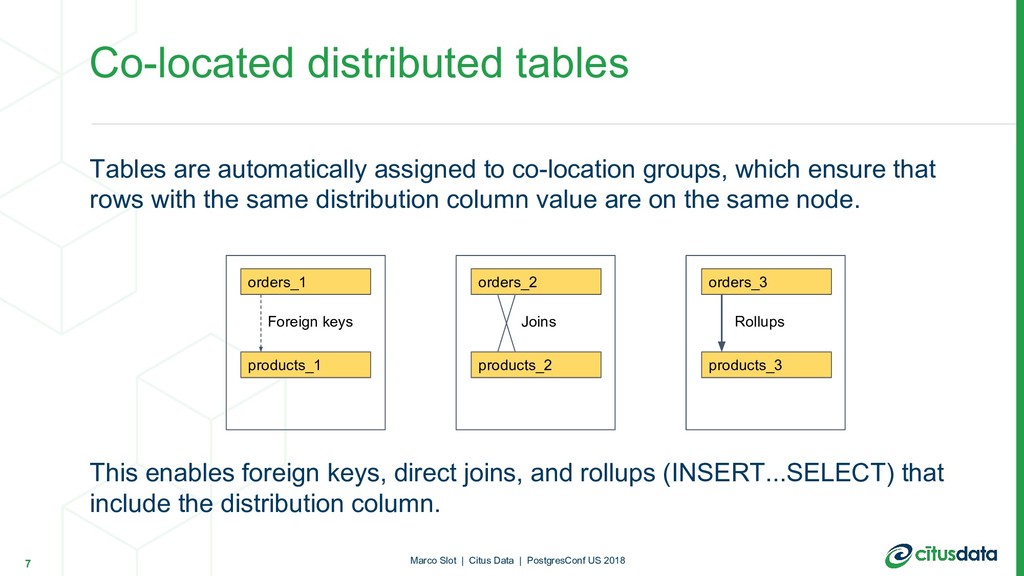
Tables are automatically assigned to co-location groups, which ensure that
rows with the same distribution column value are on the same node. This enables foreign keys, direct joins, and rollups (INSERT...SELECT) that include the distribution column. Co-located distributed tables 7 Marco Slot | Citus Data | PostgresConf US 2018 orders_1 products_1 Foreign keys orders_2 products_2 Joins orders_3 products_3 Rollups -
Reference tables are replicated to all nodes such that they
can be joined with distributed tables on any column. Reference tables 8 Marco Slot | Citus Data | PostgresConf US 2018 orders_1 products_1 orders_2 products_2 orders_3 products_3 category_1 category_1 category_1 Joins Joins Joins -
Routable queries Technical observation: If a query has <distribution column>
= <value> filters that (transitively) apply to all tables, it can be “routed” to a particular node. Efficiently provides full SQL support, since full query can be handled by Postgres. 10 SELECT … SELECT … -
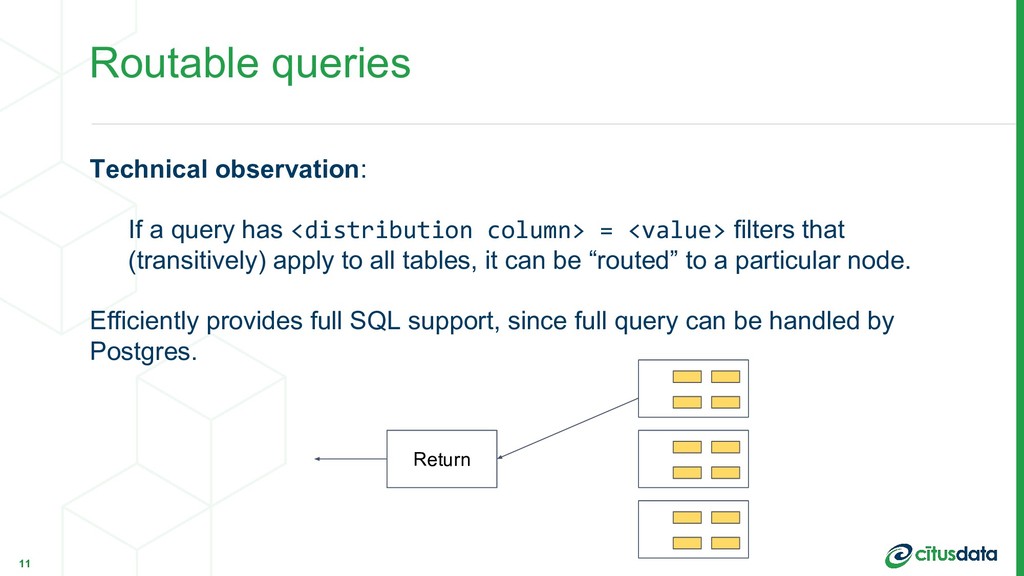
Routable queries Technical observation: If a query has <distribution column>
= <value> filters that (transitively) apply to all tables, it can be “routed” to a particular node. Efficiently provides full SQL support, since full query can be handled by Postgres. 11 Return -
Use case observation: In a SaaS (B2B) application, most queries
are specific to a particular tenant. Can add tenant ID column to all tables and distribute by tenant ID. Most queries are router plannable: Low overhead, low latency, full SQL capabilities of Postgres, scales out Scaling Multi-tenant Applications 12 Marco Slot | Citus Data | PostgresConf US 2018 -
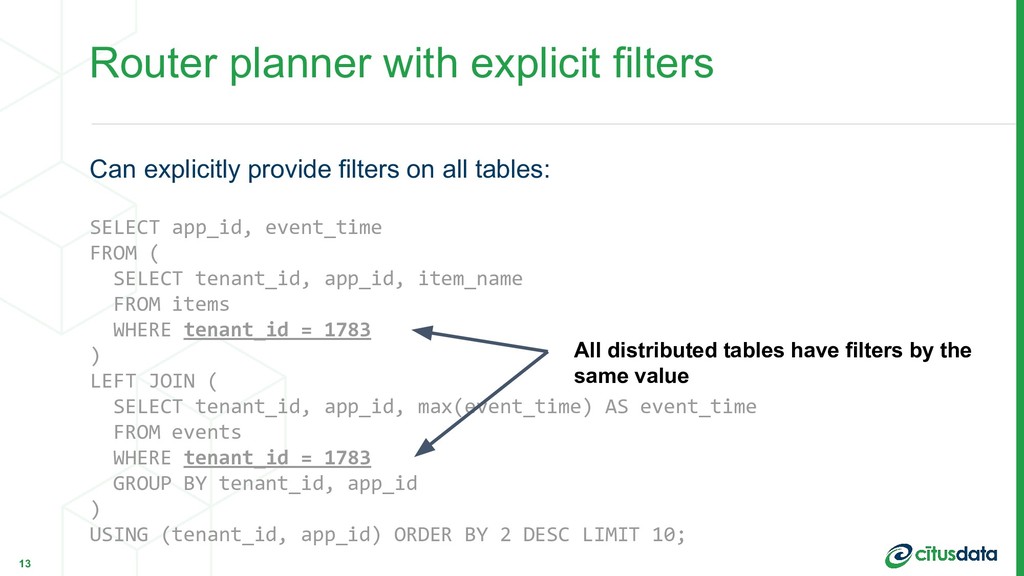
Can explicitly provide filters on all tables: SELECT app_id, event_time
FROM ( SELECT tenant_id, app_id, item_name FROM items WHERE tenant_id = 1783 ) LEFT JOIN ( SELECT tenant_id, app_id, max(event_time) AS event_time FROM events WHERE tenant_id = 1783 GROUP BY tenant_id, app_id ) USING (tenant_id, app_id) ORDER BY 2 DESC LIMIT 10; Router planner with explicit filters 13 All distributed tables have filters by the same value -
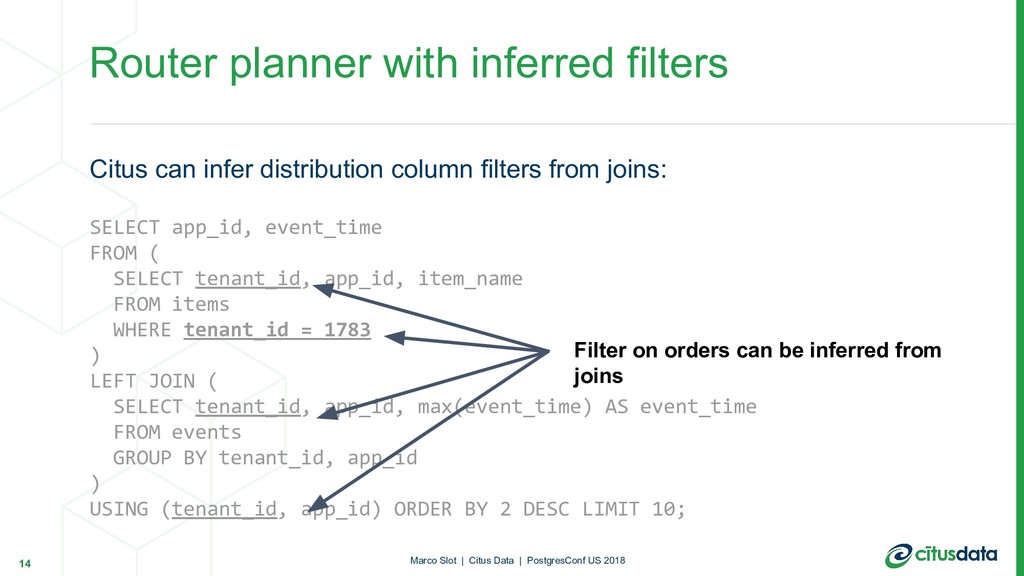
Citus can infer distribution column filters from joins: SELECT app_id,
event_time FROM ( SELECT tenant_id, app_id, item_name FROM items WHERE tenant_id = 1783 ) LEFT JOIN ( SELECT tenant_id, app_id, max(event_time) AS event_time FROM events GROUP BY tenant_id, app_id ) USING (tenant_id, app_id) ORDER BY 2 DESC LIMIT 10; Router planner with inferred filters 14 Marco Slot | Citus Data | PostgresConf US 2018 Filter on orders can be inferred from joins -
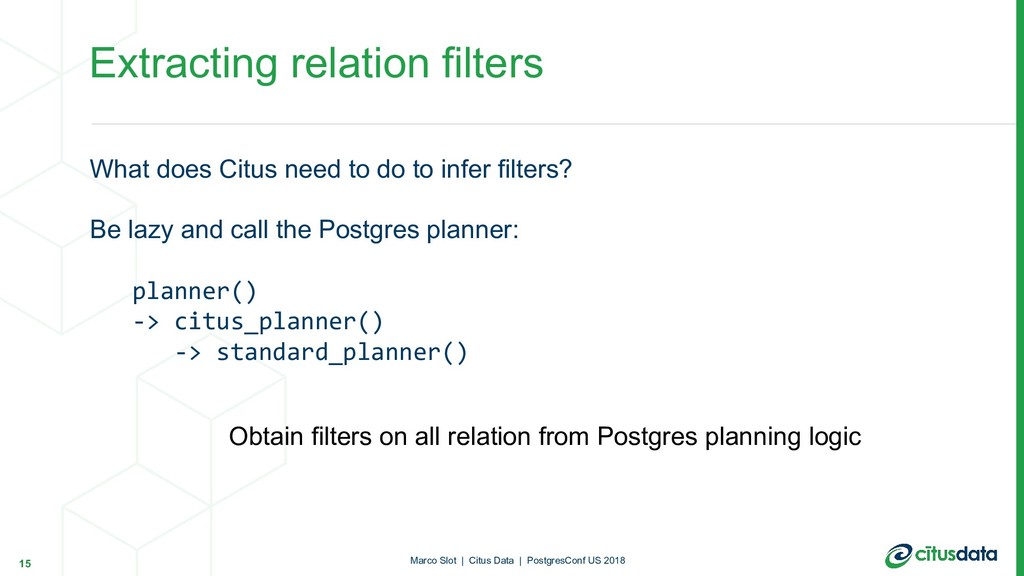
Extracting relation filters What does Citus need to do to
infer filters? Be lazy and call the Postgres planner: planner() -> citus_planner() -> standard_planner() 15 Marco Slot | Citus Data | PostgresConf US 2018 Obtain filters on all relation from Postgres planning logic -
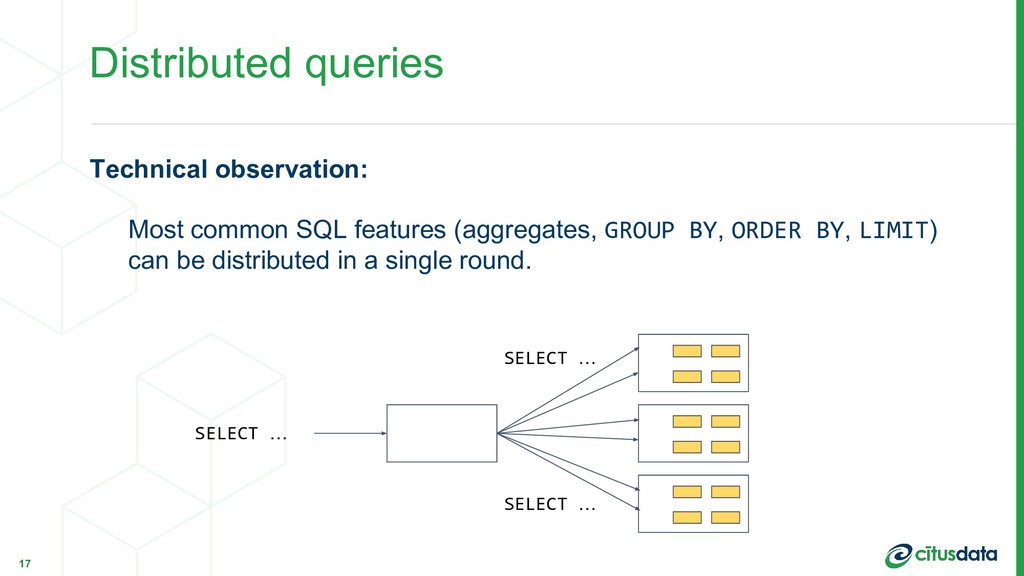
Distributed queries Technical observation: Most common SQL features (aggregates, GROUP
BY, ORDER BY, LIMIT) can be distributed in a single round. 17 SELECT … SELECT … SELECT … -
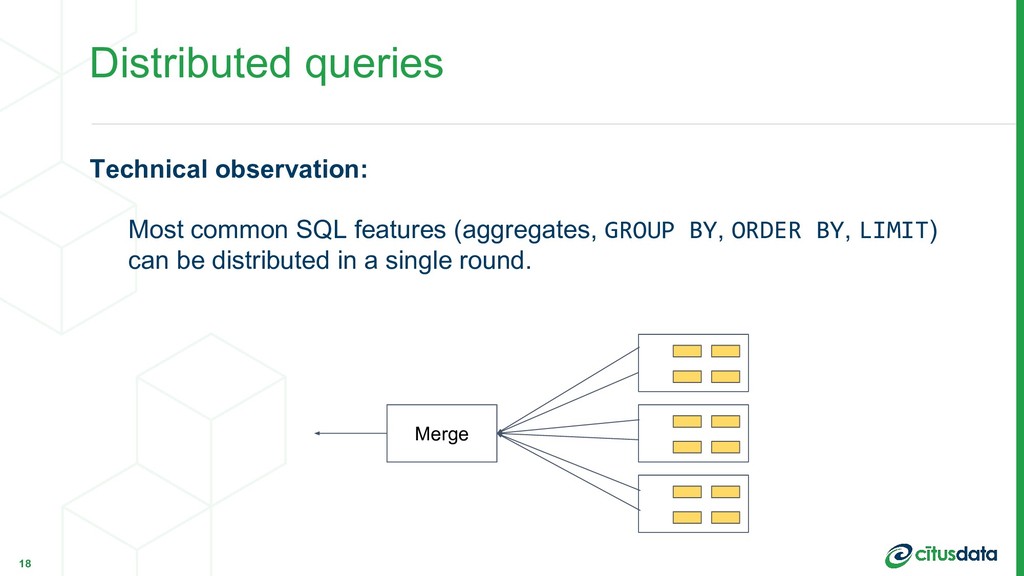
Distributed queries Technical observation: Most common SQL features (aggregates, GROUP
BY, ORDER BY, LIMIT) can be distributed in a single round. 18 Merge -
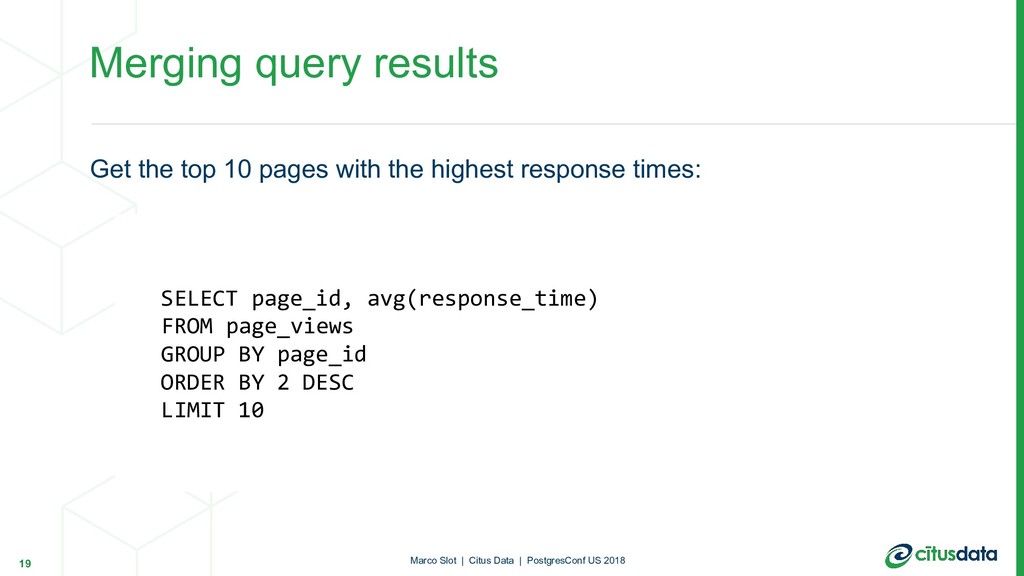
Get the top 10 pages with the highest response times:
Merging query results 19 SELECT page_id, avg(response_time) FROM page_views GROUP BY page_id ORDER BY 2 DESC LIMIT 10 Marco Slot | Citus Data | PostgresConf US 2018 -
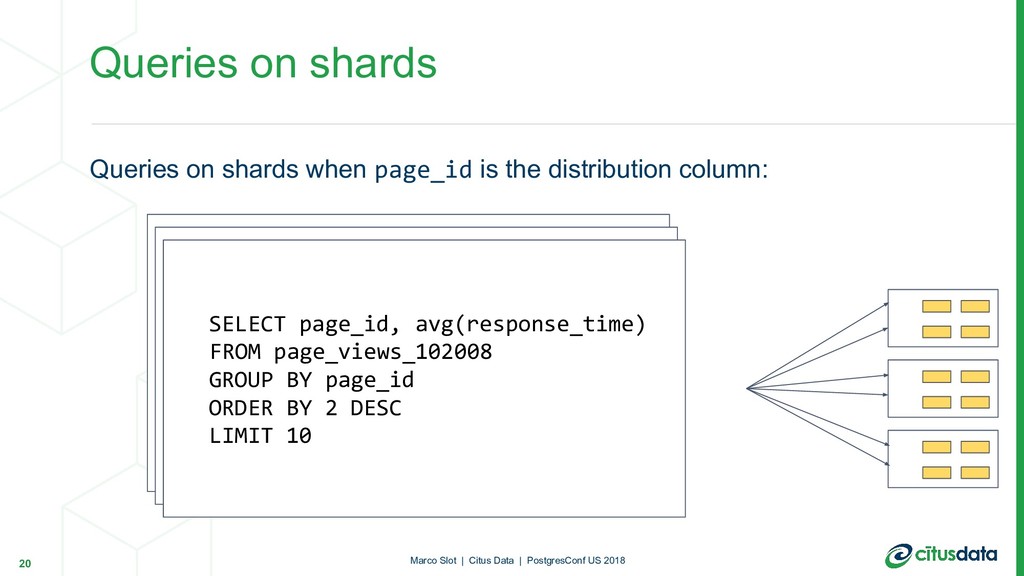
Queries on shards when page_id is the distribution column: Queries
on shards 20 Marco Slot | Citus Data | PostgresConf US 2018 SELECT page_id, avg(response_time) FROM page_views_102008 GROUP BY page_id ORDER BY 2 DESC LIMIT 10 -
When page_id is the distribution column: get top 10 of
top 10s. Merging query results 21 SELECT page_id, avg FROM ORDER BY 2 DESC LIMIT 10 Marco Slot | Citus Data | PostgresConf US 2018 Concatenated results of queries on shards -
Queries on shards when page_id is not the distribution column:
Queries on shards 22 Marco Slot | Citus Data | PostgresConf US 2018 SELECT page_id, sum(response_time), count(response_time) FROM page_views_102008 GROUP BY page_id -
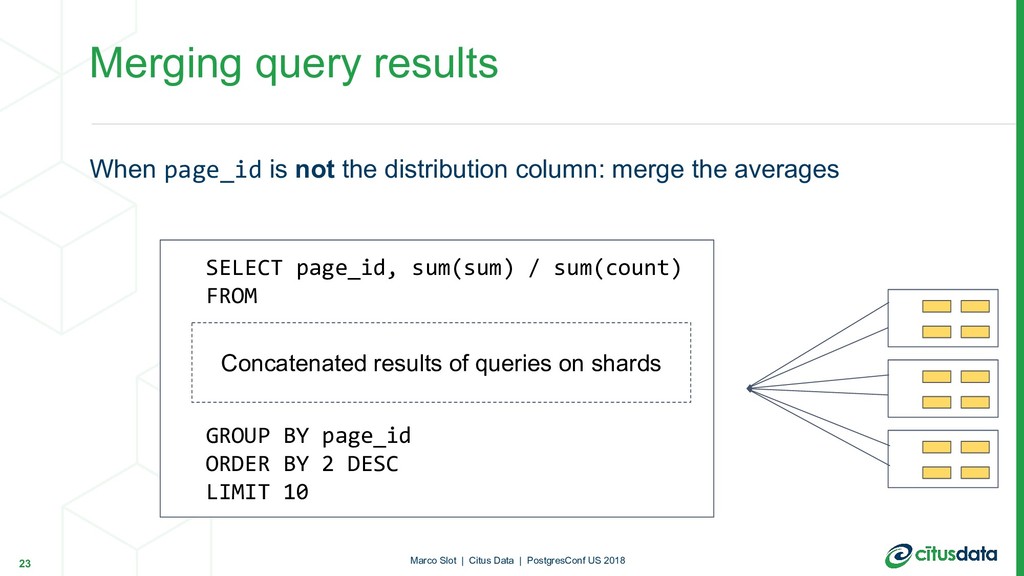
When page_id is not the distribution column: merge the averages
Merging query results 23 SELECT page_id, sum(sum) / sum(count) FROM GROUP BY page_id ORDER BY 2 DESC LIMIT 10 Marco Slot | Citus Data | PostgresConf US 2018 Concatenated results of queries on shards -
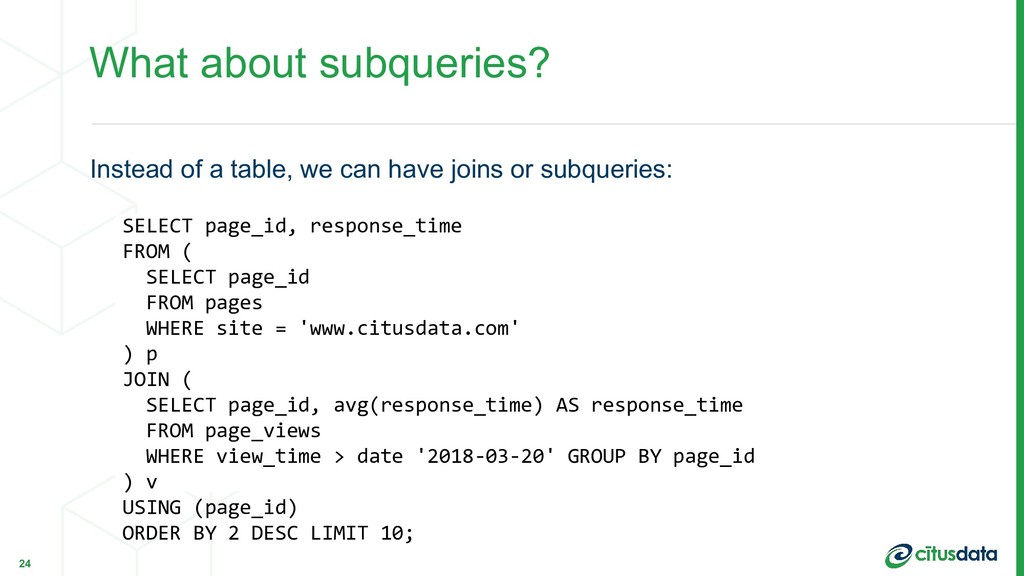
Instead of a table, we can have joins or subqueries:
What about subqueries? 24 SELECT page_id, response_time FROM ( SELECT page_id FROM pages WHERE site = 'www.citusdata.com' ) p JOIN ( SELECT page_id, avg(response_time) AS response_time FROM page_views WHERE view_time > date '2018-03-20' GROUP BY page_id ) v USING (page_id) ORDER BY 2 DESC LIMIT 10; -
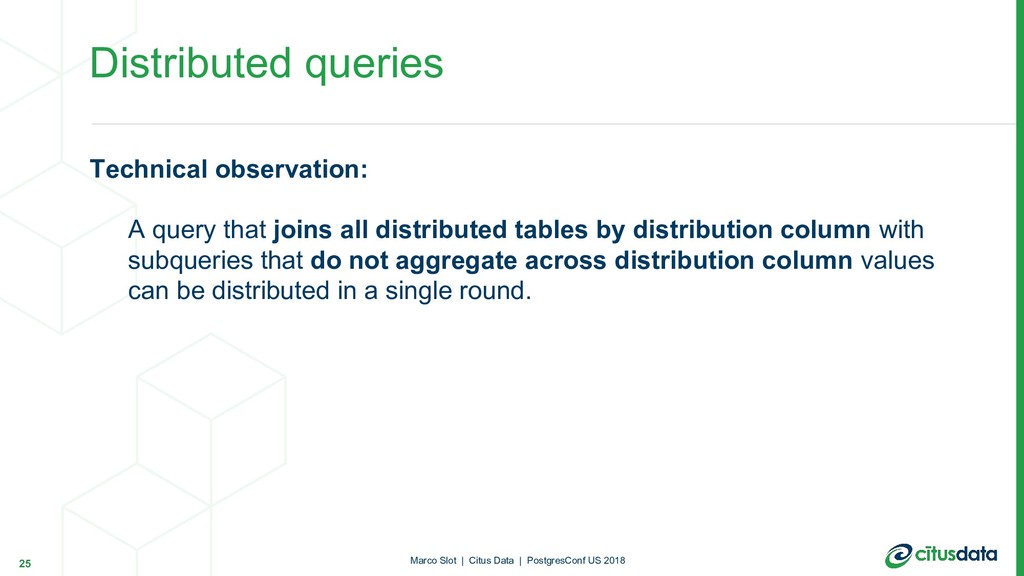
Distributed queries Technical observation: A query that joins all distributed
tables by distribution column with subqueries that do not aggregate across distribution column values can be distributed in a single round. 25 Marco Slot | Citus Data | PostgresConf US 2018 -
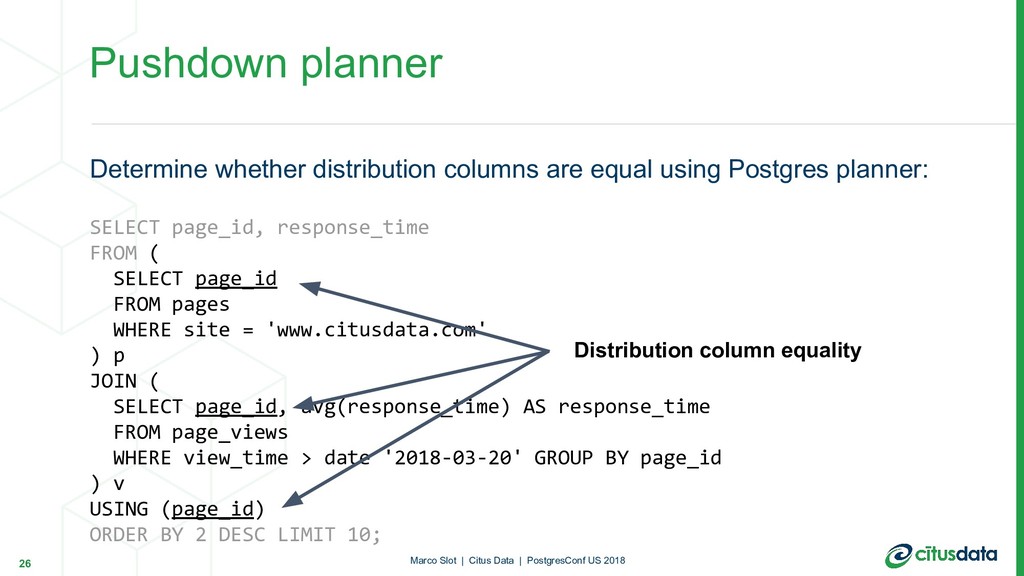
Pushdown planner Determine whether distribution columns are equal using Postgres
planner: SELECT page_id, response_time FROM ( SELECT page_id FROM pages WHERE site = 'www.citusdata.com' ) p JOIN ( SELECT page_id, avg(response_time) AS response_time FROM page_views WHERE view_time > date '2018-03-20' GROUP BY page_id ) v USING (page_id) ORDER BY 2 DESC LIMIT 10; 26 Marco Slot | Citus Data | PostgresConf US 2018 Distribution column equality -
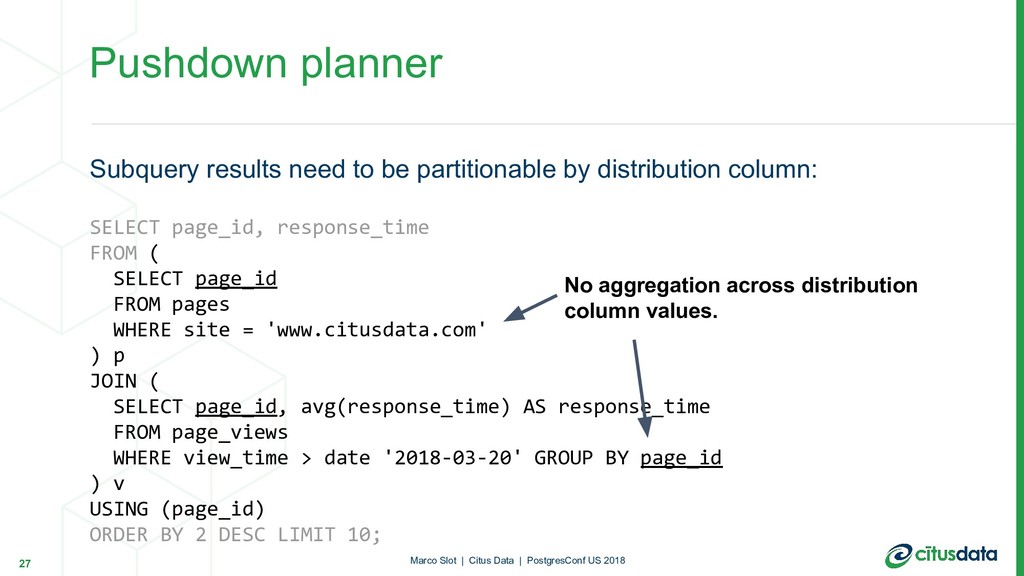
Pushdown planner Subquery results need to be partitionable by distribution
column: SELECT page_id, response_time FROM ( SELECT page_id FROM pages WHERE site = 'www.citusdata.com' ) p JOIN ( SELECT page_id, avg(response_time) AS response_time FROM page_views WHERE view_time > date '2018-03-20' GROUP BY page_id ) v USING (page_id) ORDER BY 2 DESC LIMIT 10; 27 Marco Slot | Citus Data | PostgresConf US 2018 No aggregation across distribution column values. -
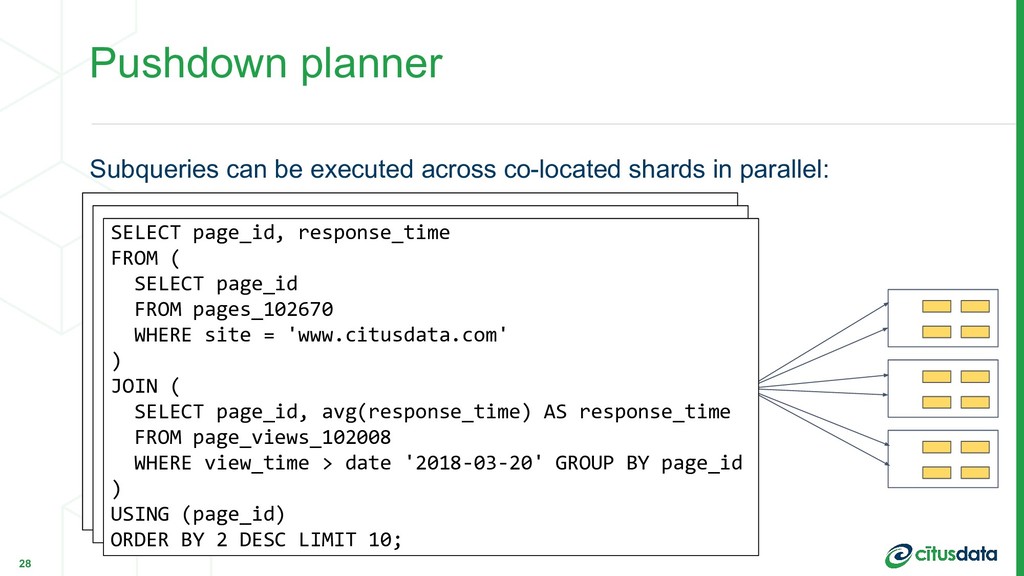
Pushdown planner Subqueries can be executed across co-located shards in
parallel: 28 SELECT page_id, response_time FROM ( SELECT page_id FROM pages_102670 WHERE site = 'www.citusdata.com' ) JOIN ( SELECT page_id, avg(response_time) AS response_time FROM page_views_102008 WHERE view_time > date '2018-03-20' GROUP BY page_id ) USING (page_id) ORDER BY 2 DESC LIMIT 10; -
Merge the results on the coordinator: Merging query results 29
SELECT page_id, response_time FROM ORDER BY 2 DESC LIMIT 10 Marco Slot | Citus Data | PostgresConf US 2018 Concatenated results of queries on shards -
Use case observation: Real-time analytics dashboards need sub-second response time,
regardless of data size. Single-round distributed queries are powerful, fast and scalable. In practice: • Maintain aggregation tables using parallel INSERT...SELECT • Dashboard selects from the aggregation table Scaling Real-time Analytics Applications 30 Marco Slot | Citus Data | PostgresConf US 2018 -
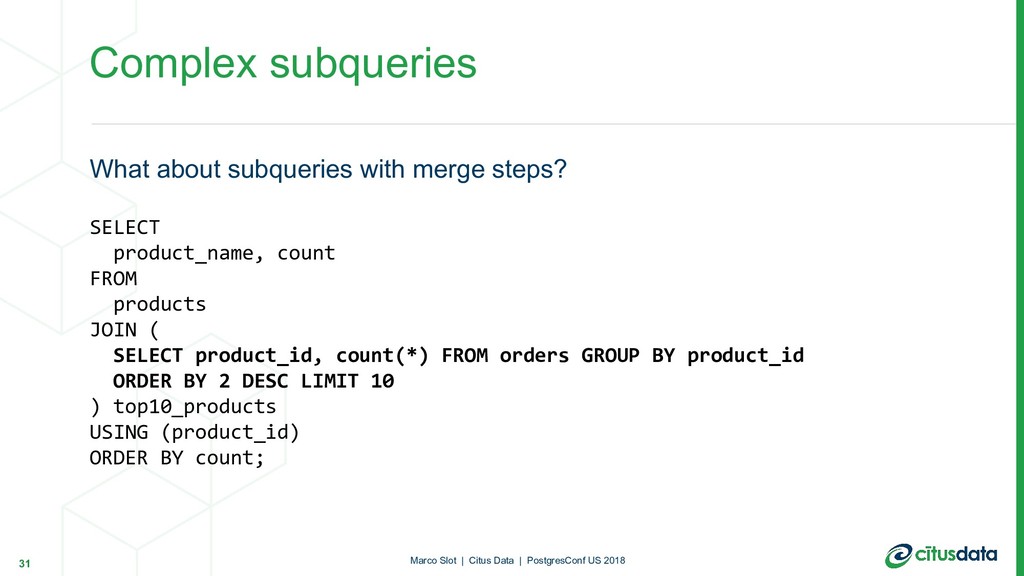
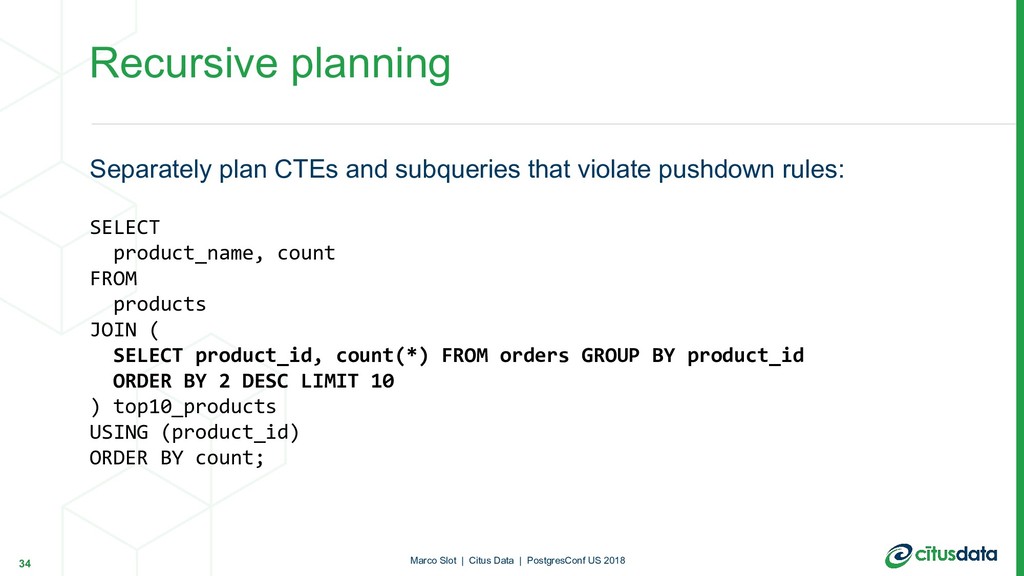
Complex subqueries What about subqueries with merge steps? SELECT product_name,
count FROM products JOIN ( SELECT product_id, count(*) FROM orders GROUP BY product_id ORDER BY 2 DESC LIMIT 10 ) top10_products USING (product_id) ORDER BY count; 31 Marco Slot | Citus Data | PostgresConf US 2018 -
Have a query you can’t solve? Call the Postgres planner!
Recursive planning 32 -
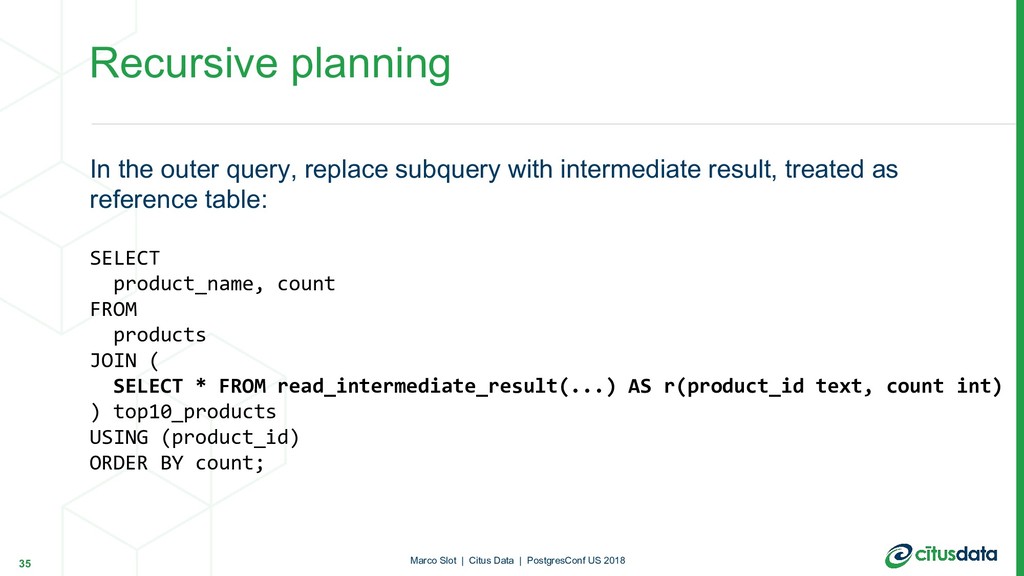
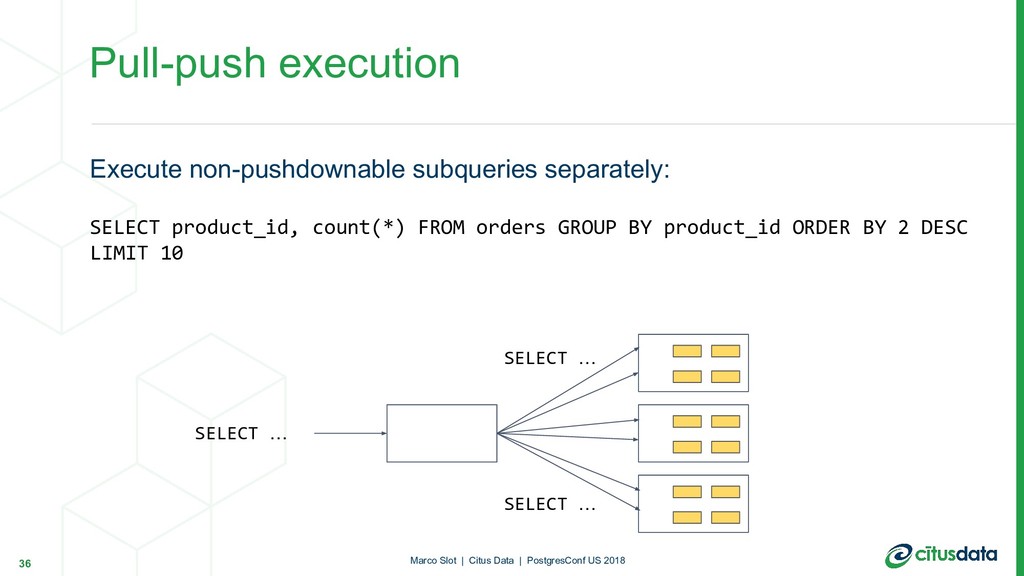
Technical observation: Subqueries and CTEs that cannot be pushed down
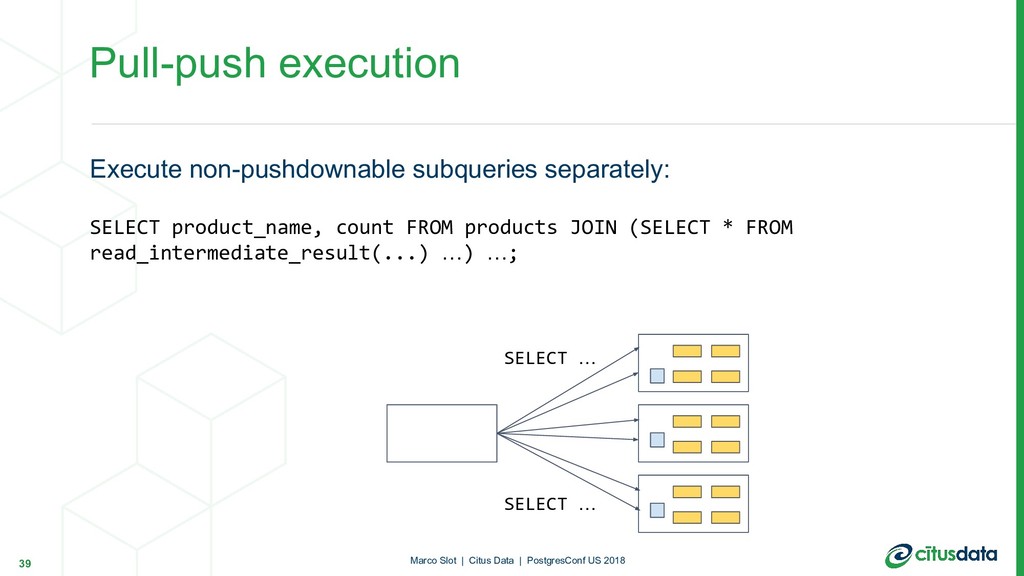
can often be executed as distributed queries. Pull-push execution: - Recursively call planner() on the subquery - During execution, stream results back into worker nodes - Replace the subquery with a function call that acts as a reference table Recursive planning 33 Marco Slot | Citus Data | PostgresConf US 2018 -
Recursive planning Separately plan CTEs and subqueries that violate pushdown
rules: SELECT product_name, count FROM products JOIN ( SELECT product_id, count(*) FROM orders GROUP BY product_id ORDER BY 2 DESC LIMIT 10 ) top10_products USING (product_id) ORDER BY count; 34 Marco Slot | Citus Data | PostgresConf US 2018 -
Recursive planning In the outer query, replace subquery with intermediate
result, treated as reference table: SELECT product_name, count FROM products JOIN ( SELECT * FROM read_intermediate_result(...) AS r(product_id text, count int) ) top10_products USING (product_id) ORDER BY count; 35 Marco Slot | Citus Data | PostgresConf US 2018 -
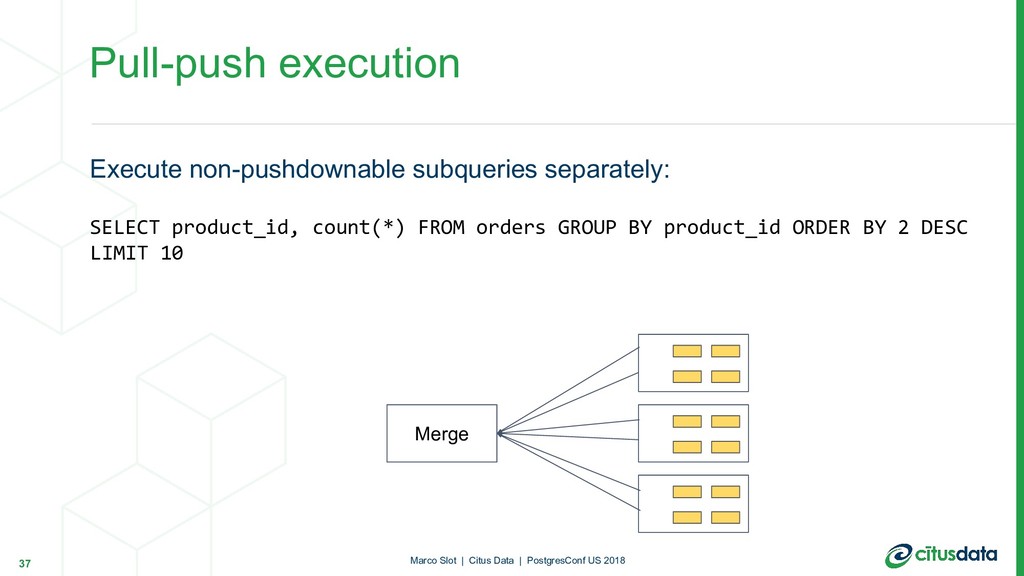
Pull-push execution Execute non-pushdownable subqueries separately: SELECT product_id, count(*) FROM
orders GROUP BY product_id ORDER BY 2 DESC LIMIT 10 36 Marco Slot | Citus Data | PostgresConf US 2018 SELECT … SELECT … SELECT … -
Pull-push execution Execute non-pushdownable subqueries separately: SELECT product_id, count(*) FROM
orders GROUP BY product_id ORDER BY 2 DESC LIMIT 10 37 Marco Slot | Citus Data | PostgresConf US 2018 Merge -
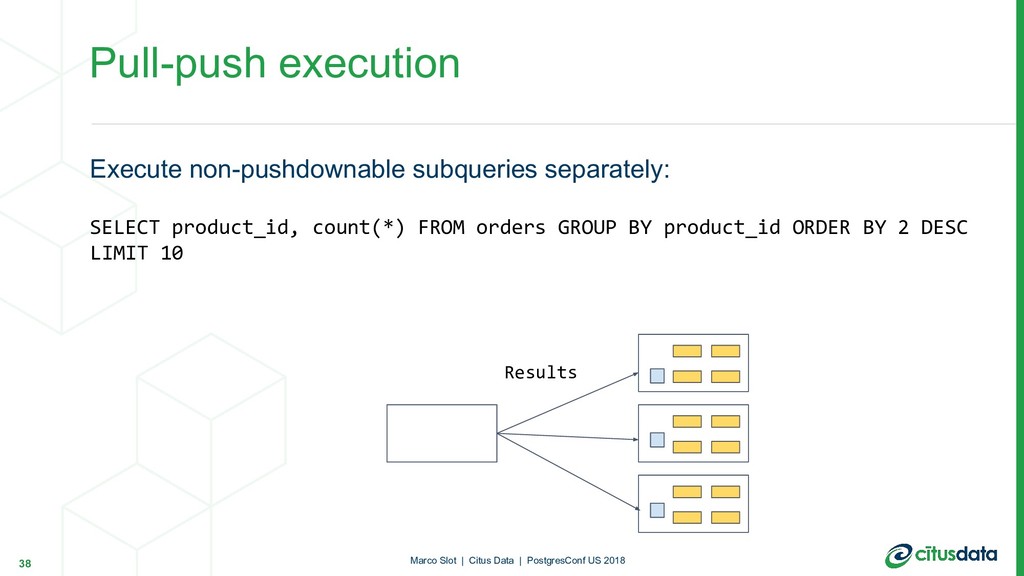
Pull-push execution Execute non-pushdownable subqueries separately: SELECT product_id, count(*) FROM
orders GROUP BY product_id ORDER BY 2 DESC LIMIT 10 38 Marco Slot | Citus Data | PostgresConf US 2018 Results -
Pull-push execution Execute non-pushdownable subqueries separately: SELECT product_name, count FROM
products JOIN (SELECT * FROM read_intermediate_result(...) …) …; 39 Marco Slot | Citus Data | PostgresConf US 2018 SELECT … SELECT … -
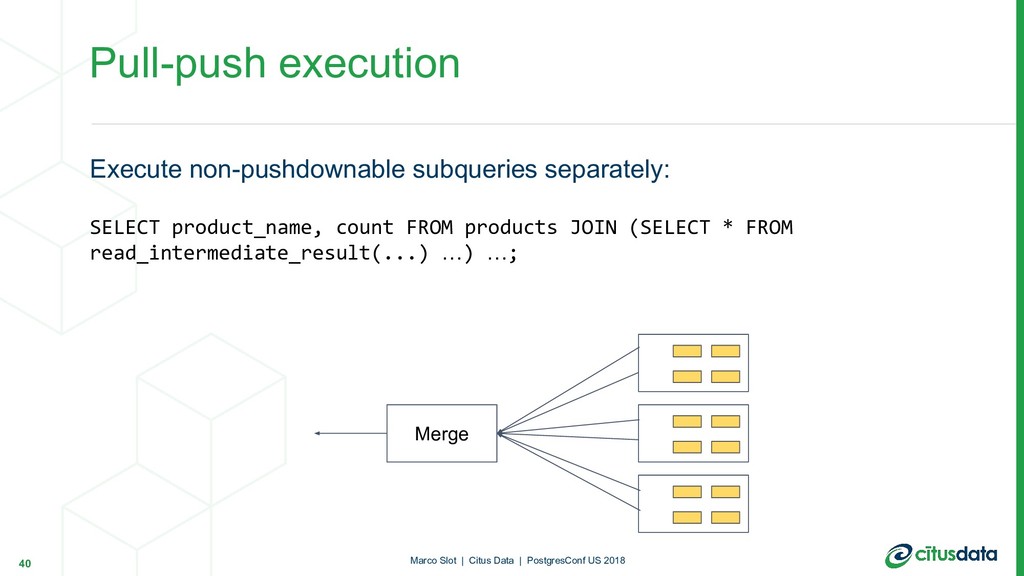
Pull-push execution Execute non-pushdownable subqueries separately: SELECT product_name, count FROM
products JOIN (SELECT * FROM read_intermediate_result(...) …) …; 40 Marco Slot | Citus Data | PostgresConf US 2018 Merge -
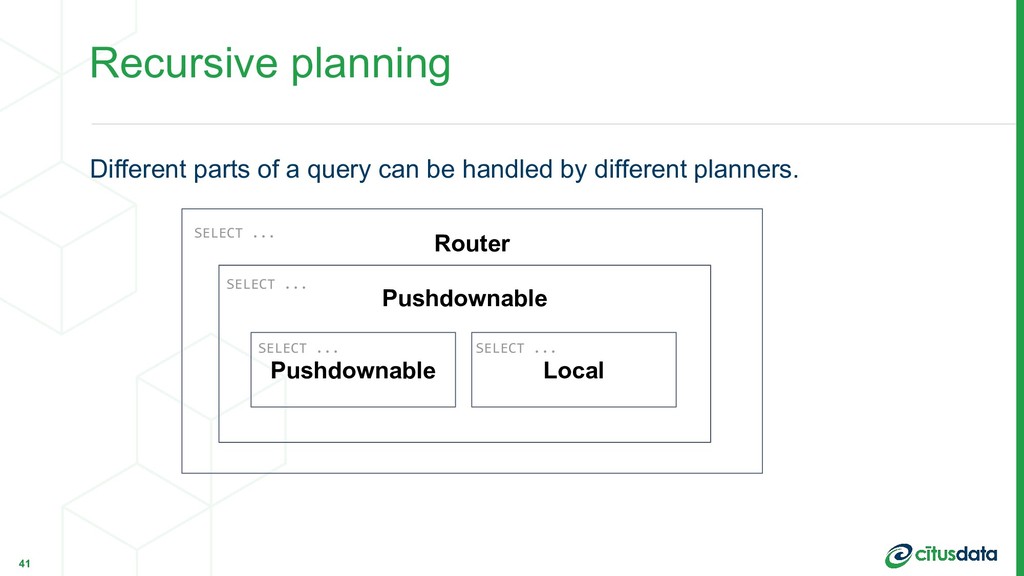
Different parts of a query can be handled by different
planners. Recursive planning 41 Router Pushdownable Local Pushdownable SELECT ... SELECT ... SELECT ... SELECT ... -
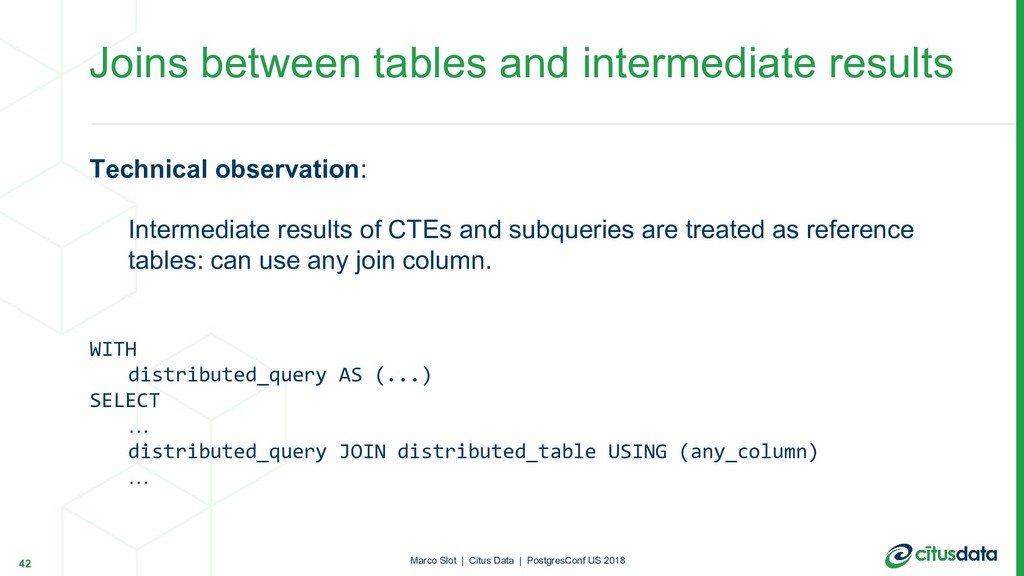
Technical observation: Intermediate results of CTEs and subqueries are treated
as reference tables: can use any join column. WITH distributed_query AS (...) SELECT … distributed_query JOIN distributed_table USING (any_column) … Joins between tables and intermediate results 42 Marco Slot | Citus Data | PostgresConf US 2018 -
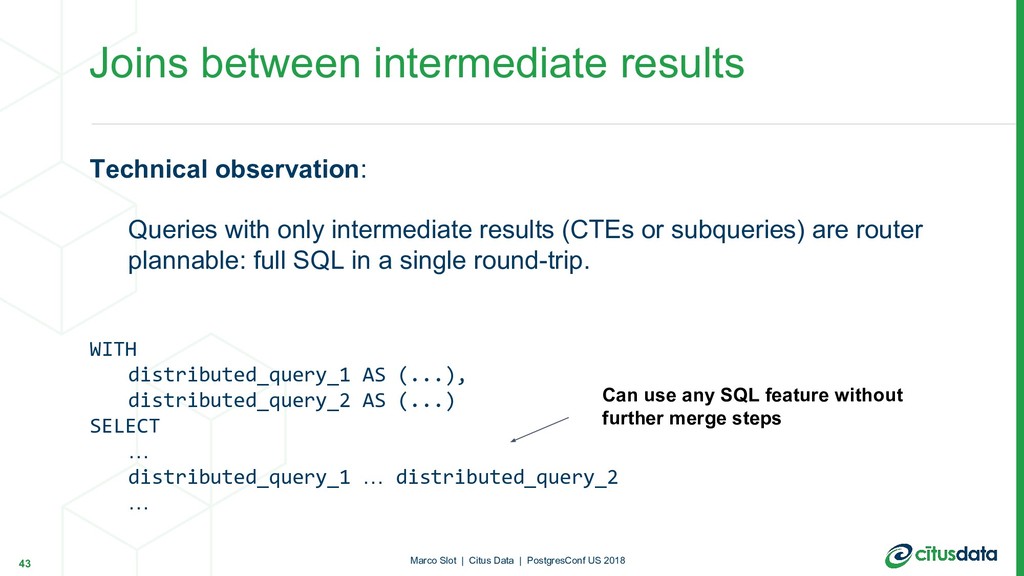
Technical observation: Queries with only intermediate results (CTEs or subqueries)
are router plannable: full SQL in a single round-trip. WITH distributed_query_1 AS (...), distributed_query_2 AS (...) SELECT … distributed_query_1 … distributed_query_2 … Joins between intermediate results 43 Marco Slot | Citus Data | PostgresConf US 2018 Can use any SQL feature without further merge steps -
Use case observation: Real-time analytics applications want versatile distributed SQL
support Recursive planning provides nearly full, distributed SQL support in a small number of network round trips. Scaling Real-time Analytics Applications 44 Marco Slot | Citus Data | PostgresConf US 2018 -
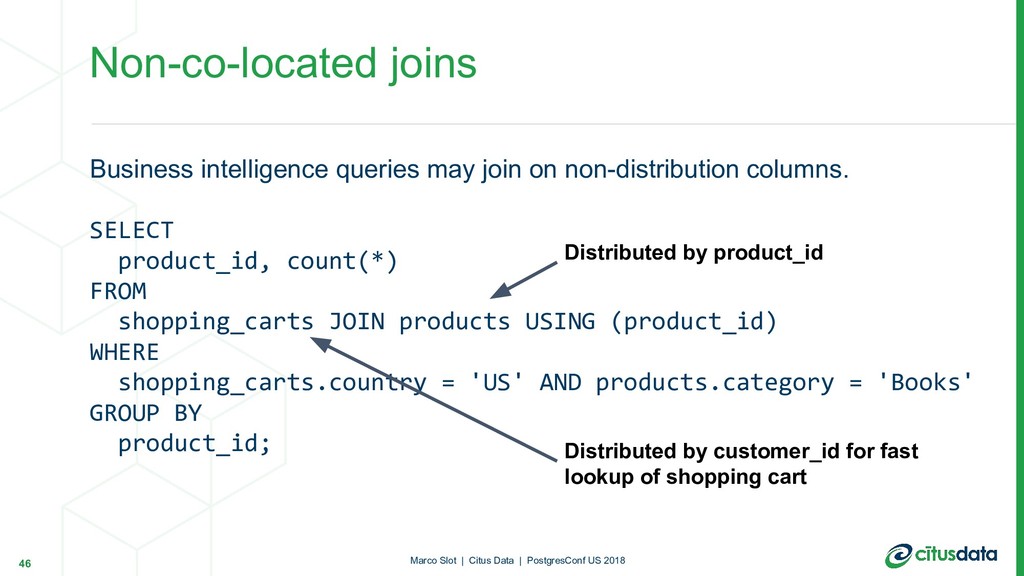
Business intelligence queries may join on non-distribution columns. SELECT product_id,
count(*) FROM shopping_carts JOIN products USING (product_id) WHERE shopping_carts.country = 'US' AND products.category = 'Books' GROUP BY product_id; Non-co-located joins 46 Marco Slot | Citus Data | PostgresConf US 2018 Distributed by customer_id for fast lookup of shopping cart Distributed by product_id -
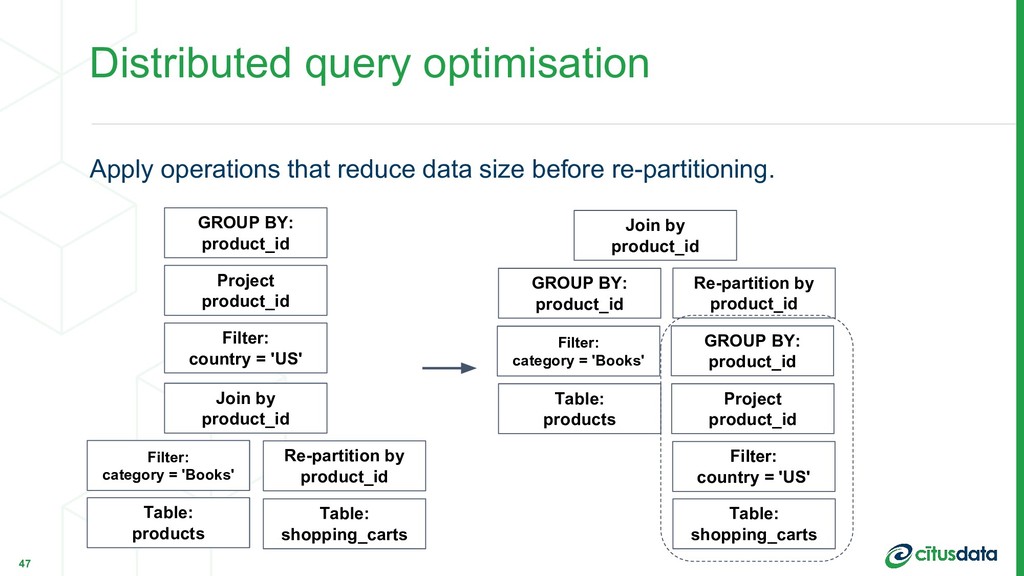
Distributed query optimisation Apply operations that reduce data size before
re-partitioning. 47 Join by product_id Re-partition by product_id Filter: country = 'US' Table: products Table: shopping_carts GROUP BY: product_id Project product_id Join by product_id Re-partition by product_id Filter: country = 'US' Table: products Table: shopping_carts GROUP BY: product_id Project product_id GROUP BY: product_id Filter: category = 'Books' Filter: category = 'Books' -
Re-partitioning Split query results into buckets based on product_id SELECT
partition_query_result($$ SELECT product_id, count(*) FROM shopping_carts_1028 WHERE country = 'US' GROUP BY product_id $$, 'product_id'); 48 SELECT … SELECT … -
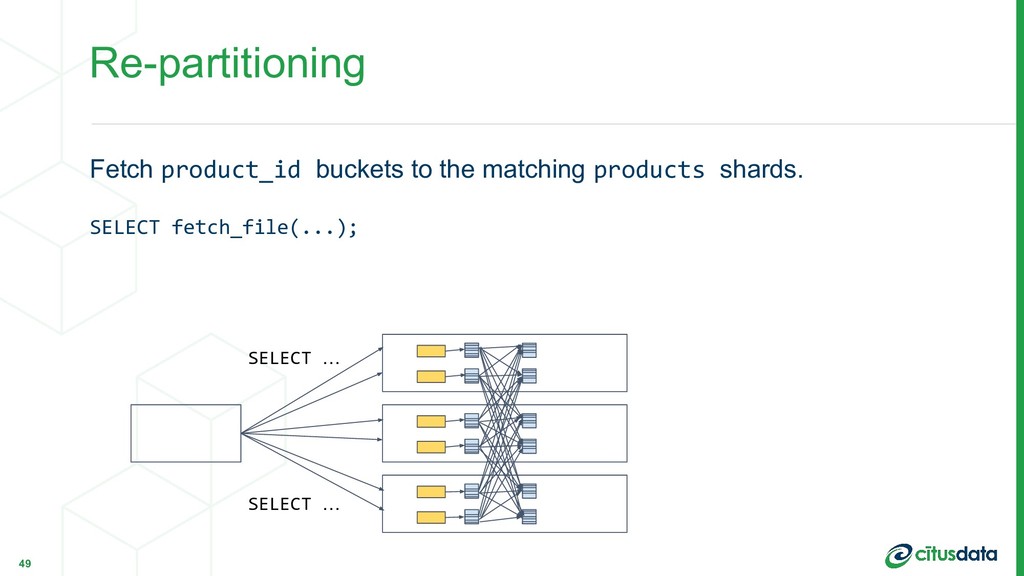
Re-partitioning Fetch product_id buckets to the matching products shards. SELECT
fetch_file(...); 49 SELECT … SELECT … -
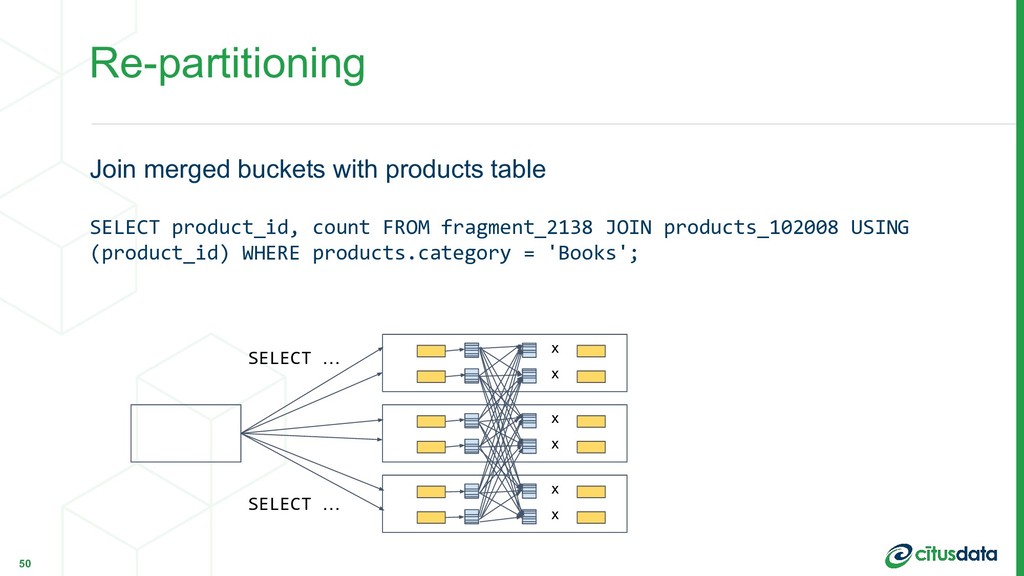
Re-partitioning Join merged buckets with products table SELECT product_id, count
FROM fragment_2138 JOIN products_102008 USING (product_id) WHERE products.category = 'Books'; 50 SELECT … SELECT … x x x x x x -
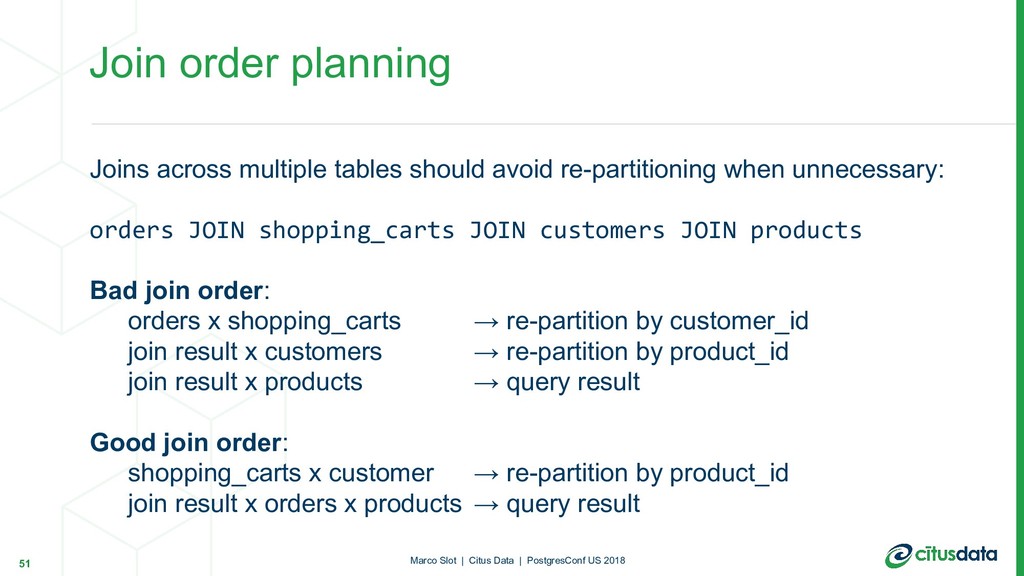
Join order planning Joins across multiple tables should avoid re-partitioning
when unnecessary: orders JOIN shopping_carts JOIN customers JOIN products Bad join order: orders x shopping_carts → re-partition by customer_id join result x customers → re-partition by product_id join result x products → query result Good join order: shopping_carts x customer → re-partition by product_id join result x orders x products → query result 51 Marco Slot | Citus Data | PostgresConf US 2018 -
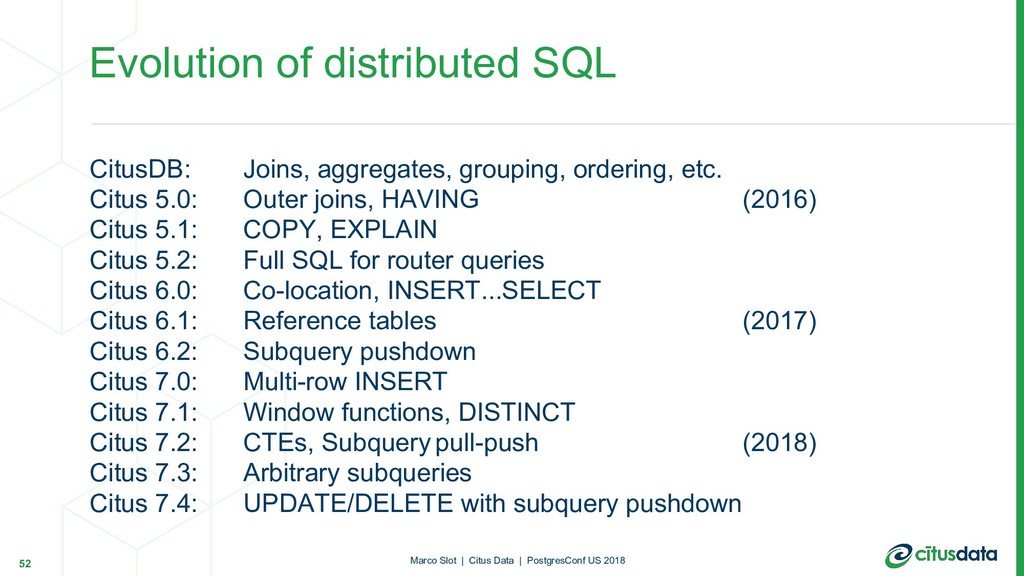
CitusDB: Joins, aggregates, grouping, ordering, etc. Citus 5.0: Outer joins,
HAVING (2016) Citus 5.1: COPY, EXPLAIN Citus 5.2: Full SQL for router queries Citus 6.0: Co-location, INSERT...SELECT Citus 6.1: Reference tables (2017) Citus 6.2: Subquery pushdown Citus 7.0: Multi-row INSERT Citus 7.1: Window functions, DISTINCT Citus 7.2: CTEs, Subquery pull-push (2018) Citus 7.3: Arbitrary subqueries Citus 7.4: UPDATE/DELETE with subquery pushdown Evolution of distributed SQL 52 Marco Slot | Citus Data | PostgresConf US 2018