Upgrade to Pro — share decks privately, control downloads, hide ads and more …

Кто такой Production Engineer в Facebook?

Кто такой Production Engineer в Facebook?

DevOpsDaysMoscow, 07-12-2019, Сергей Пузырев

Моя команда работает над внутренним сервисом распределенных очередей в Facebook. Мы предоставляем низкоуровневый сервис передачи и сохранения сообщений для множества пользователей внутри Facebook по всей планете.

Команда Production Engineer'ов обеспечивает весь жизненный цикл нашего сервиса, поддерживает всю автоматизацию, необходимую для сервиса и изредка тушим пожары.

Я расскажу, как мы работаем в целом, как устроен процесс работы с командой разработки, какие инструменты мы используем и какого рода автоматизацию мы создаём и поддерживаем.

DevOpsDaysMoscow

December 07, 2019

Transcript

39 slides
  1. • Good coder in at least non-shell language • Linux

    systems knowledge • Networking knowledge • Distributed systems design, operating and design • Usually some “reliability engineering” background • Ready to be oncall Who do we hire as PE? Who is Production Engineer @ Facebook?
  2. • Strong in coding and software design • Usually some

    other different specialized skills • Usually no “reliability engineering” background • Ready to be oncall What is the essential difference to SWE? Who is Software Engineer @ Facebook?
  3. • Large scale • Rapid pace of changes • High

    growth rate Let’s make the task more complicated Environment @ Facebook
  4. • SWE:PE ratio is approximately 10:1 SWE: | PE: •

    Not every team can have PE support, even if they want • Sometimes teams don’t know what to do with PEs PEs are a scarce, often misunderstood resource Putting it all together: PEs and SWEs
  5. Turn your piece of code into a working service in

    prod? https://upload.wikimedia.org/wikipedia/commons/a/ac/Dr_Chau_Chak_Wing_Building_7906.jpg
  6. NO!

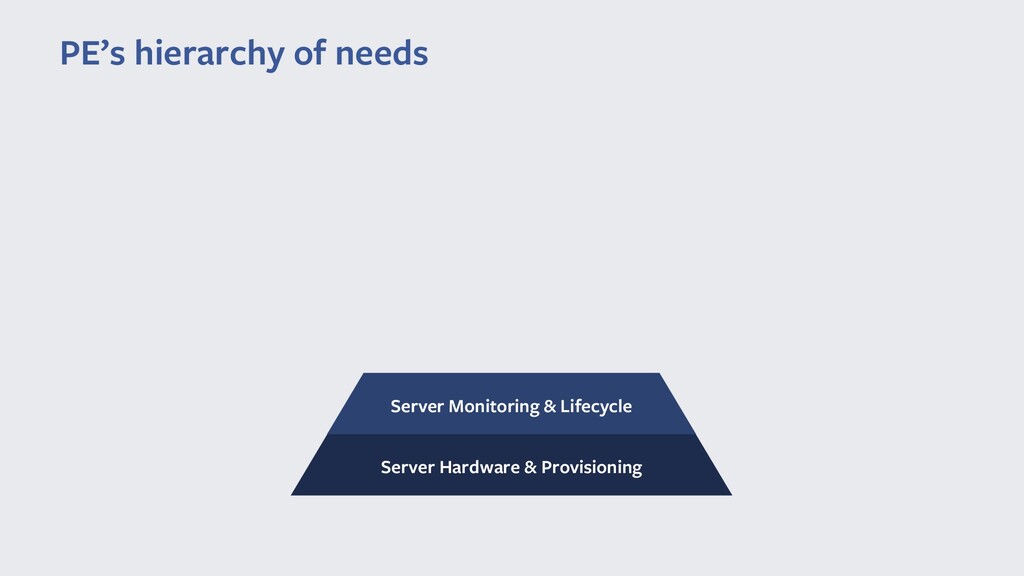
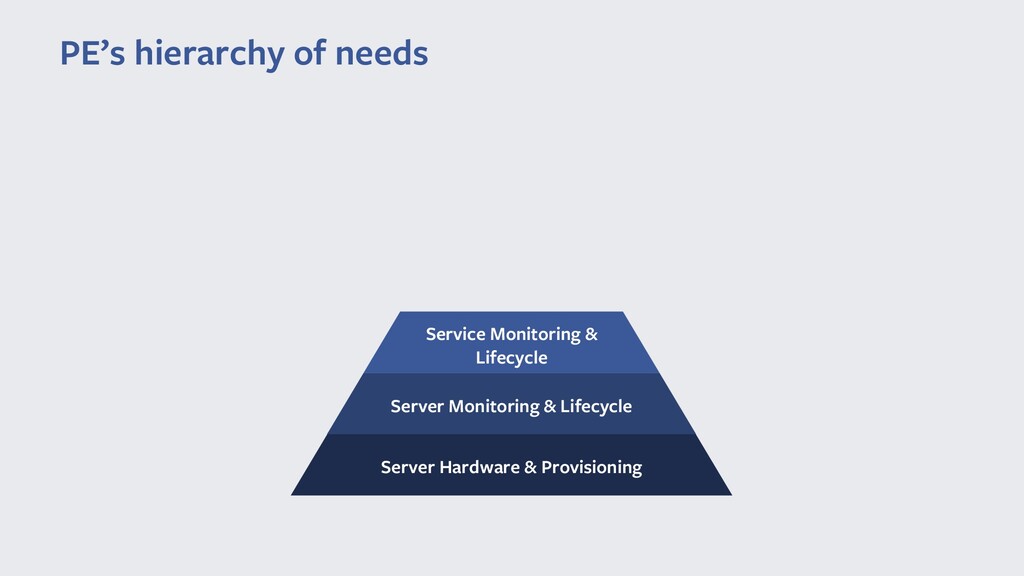
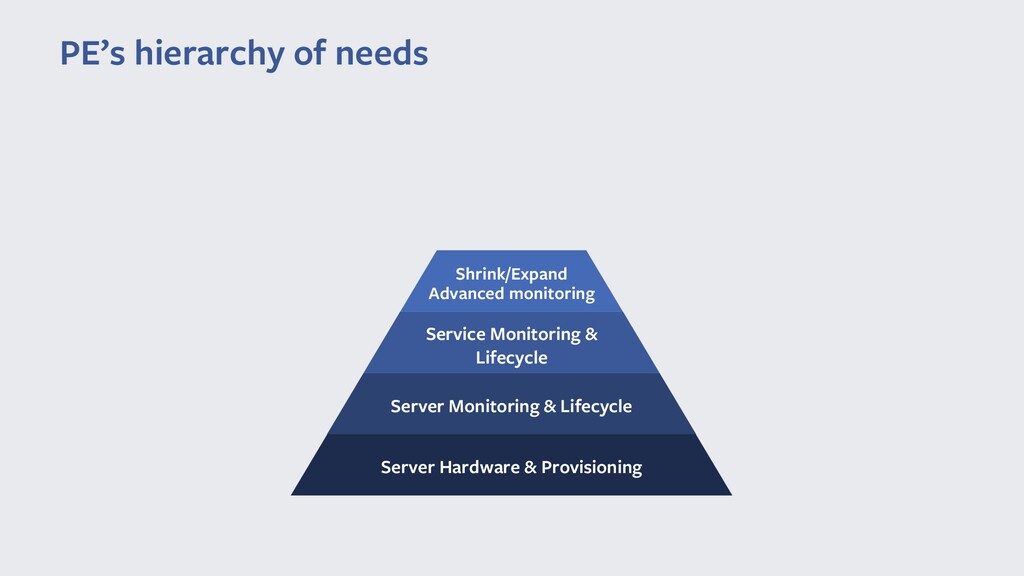
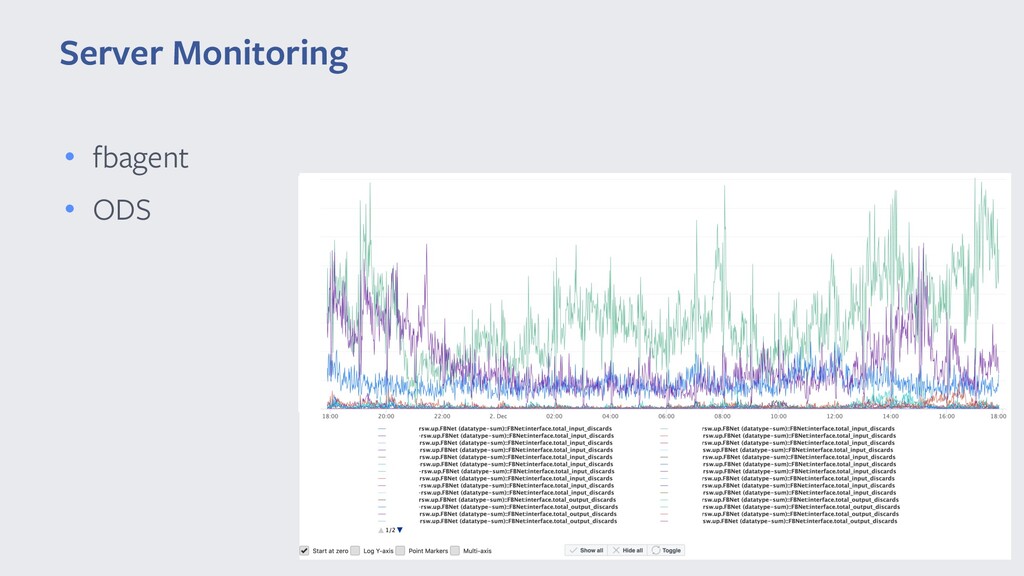
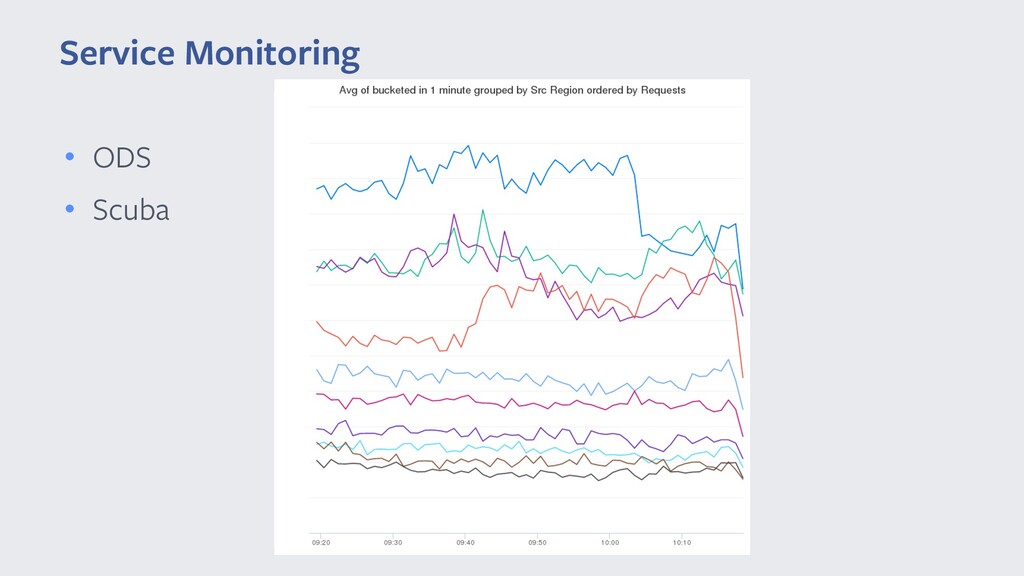
  7. PE’s hierarchy of needs Server Hardware & Provisioning Server Monitoring

    & Lifecycle Service Monitoring & Lifecycle Shrink/Expand Advanced monitoring
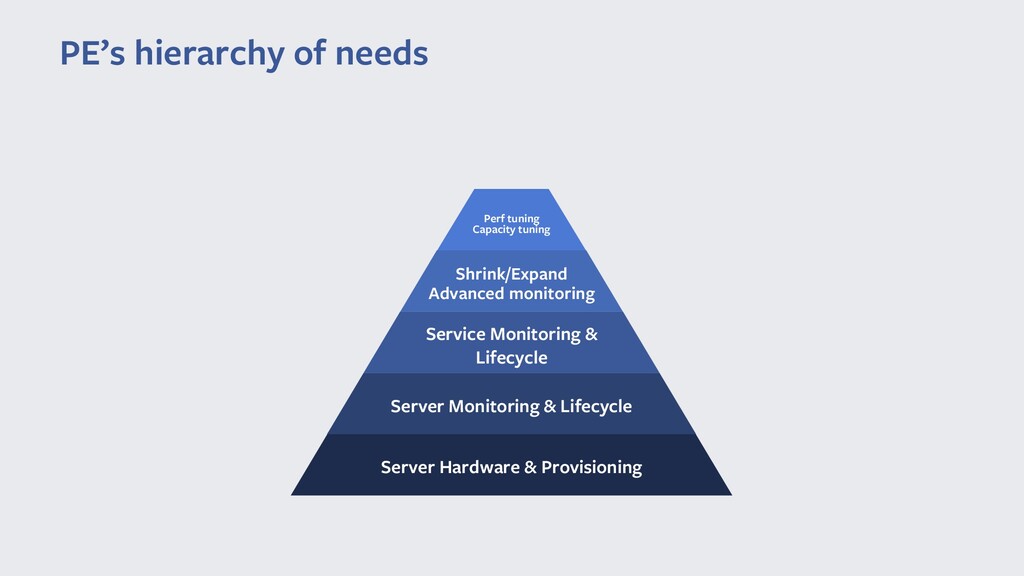
  8. PE’s hierarchy of needs Server Hardware & Provisioning Server Monitoring

    & Lifecycle Service Monitoring & Lifecycle Shrink/Expand Advanced monitoring Perf tuning Capacity tuning
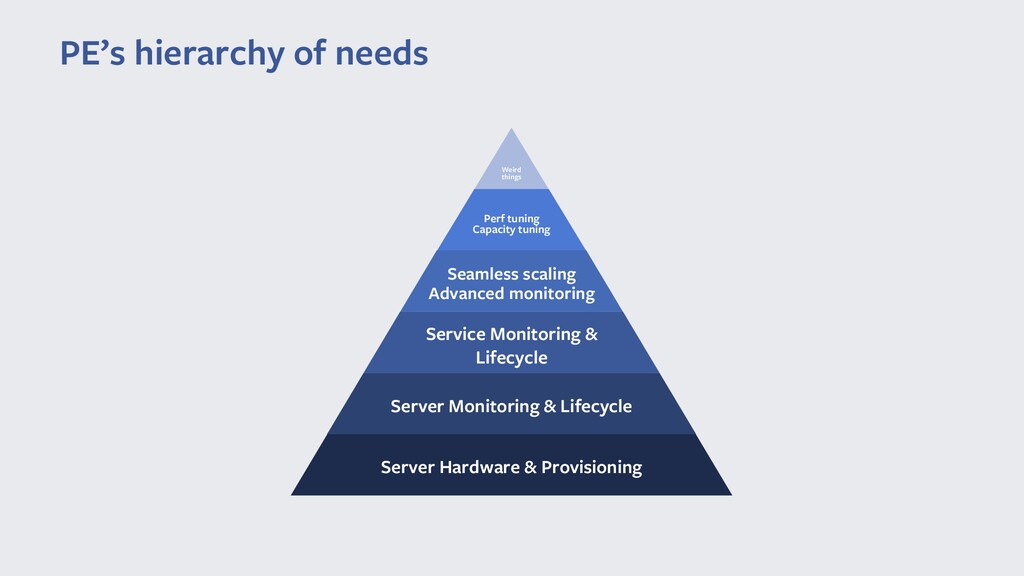
  9. PE’s hierarchy of needs Server Hardware & Provisioning Server Monitoring

    & Lifecycle Service Monitoring & Lifecycle Seamless scaling Advanced monitoring Perf tuning Capacity tuning Weird things
  10. Cyborg - automation for your servers. How to deal with

    hardware @ Facebook scale Server Hardware & Provisioning https://commons.wikimedia.org/wiki/File:Terminator_Exhibition_T-800_-_Menacing_looking_shoot.jpg
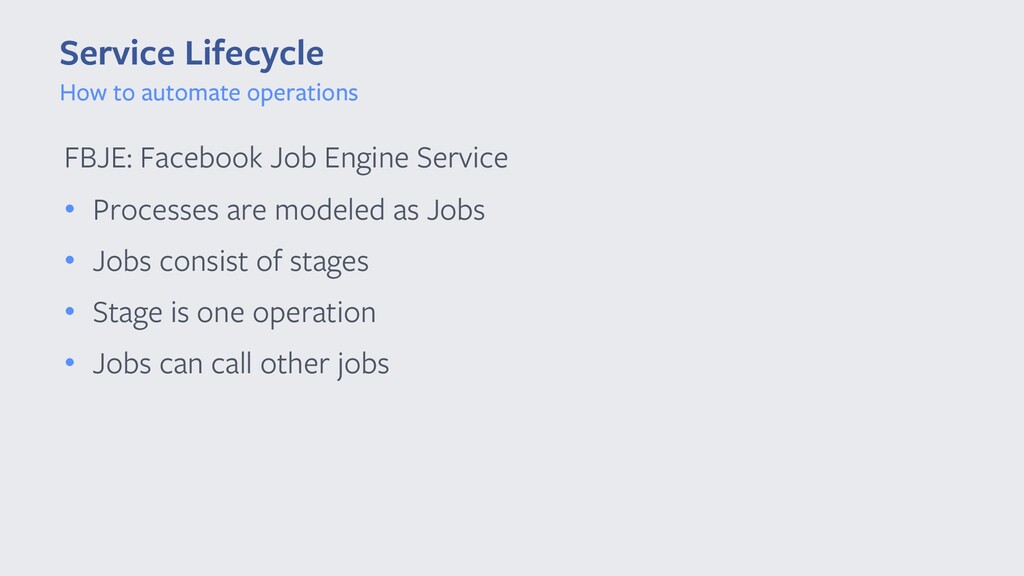
  11. FBJE: Facebook Job Engine Service • Processes are modeled as

    Jobs • Jobs consist of stages • Stage is one operation • Jobs can call other jobs How to automate operations Service Lifecycle
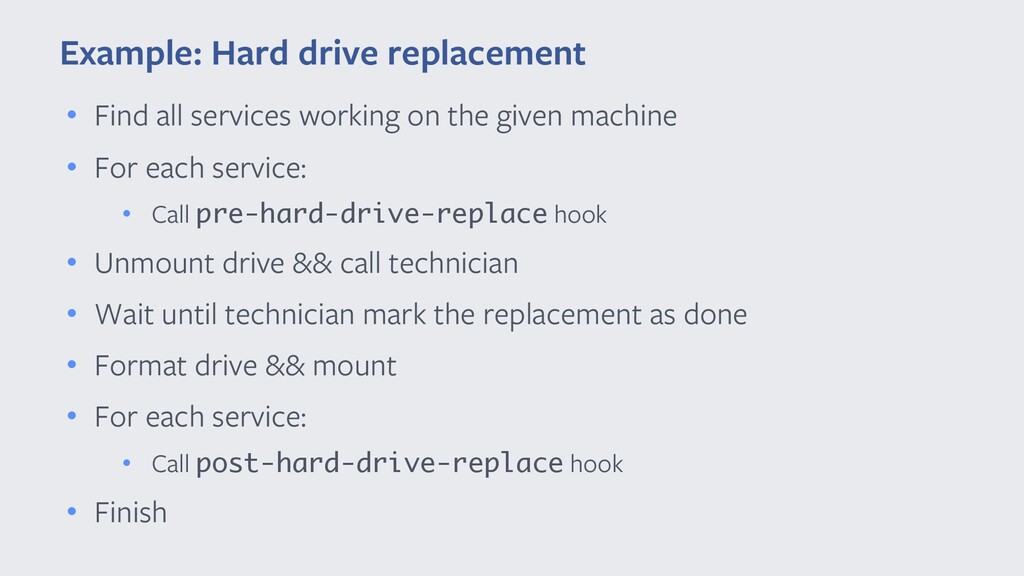
  12. • Find all services working on the given machine •

    For each service: • Call pre-hard-drive-replace hook • Unmount drive && call technician • Wait until technician mark the replacement as done • Format drive && mount • For each service: • Call post-hard-drive-replace hook • Finish Example: Hard drive replacement
  13. • Spinning up new clusters • Decommissioning of clusters •

    Decommissioning of hardware • Drains (they are underrated!) Service Lifecycle
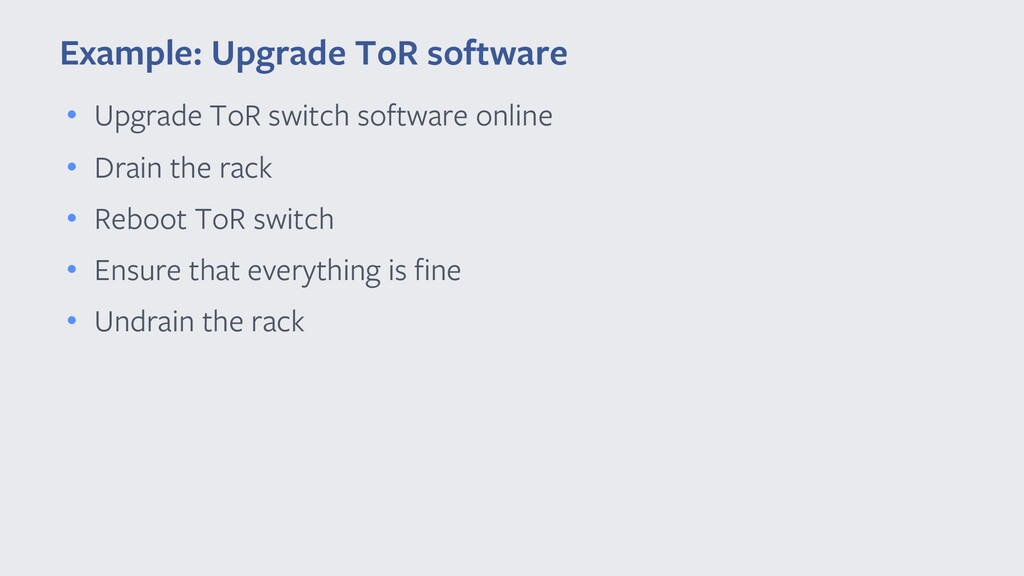
  14. • Upgrade ToR switch software online • Drain the rack

    • Reboot ToR switch • Ensure that everything is fine • Undrain the rack Example: Upgrade ToR software
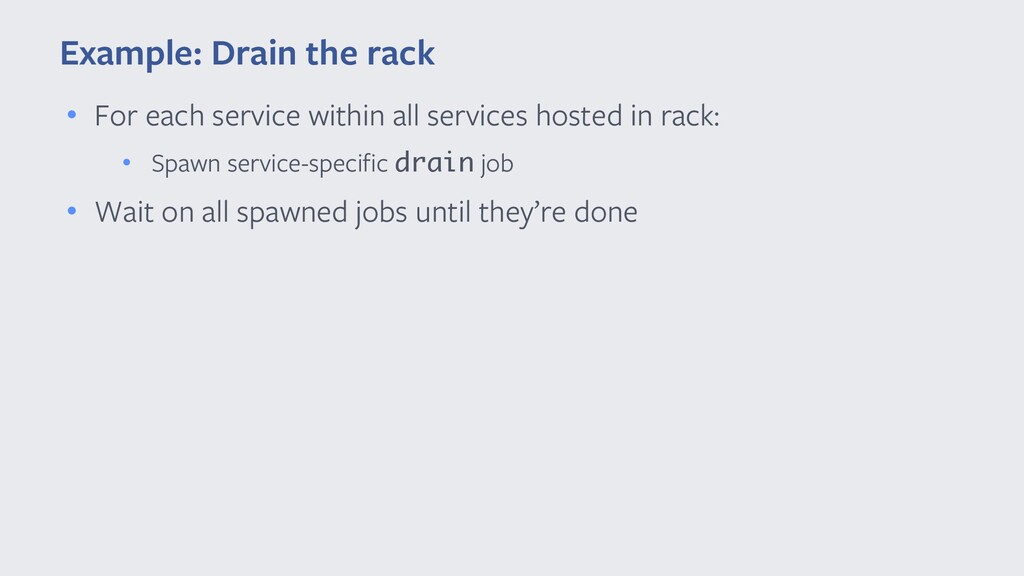
  15. • For each service within all services hosted in rack:

    • Spawn service-specific drain job • Wait on all spawned jobs until they’re done Example: Drain the rack
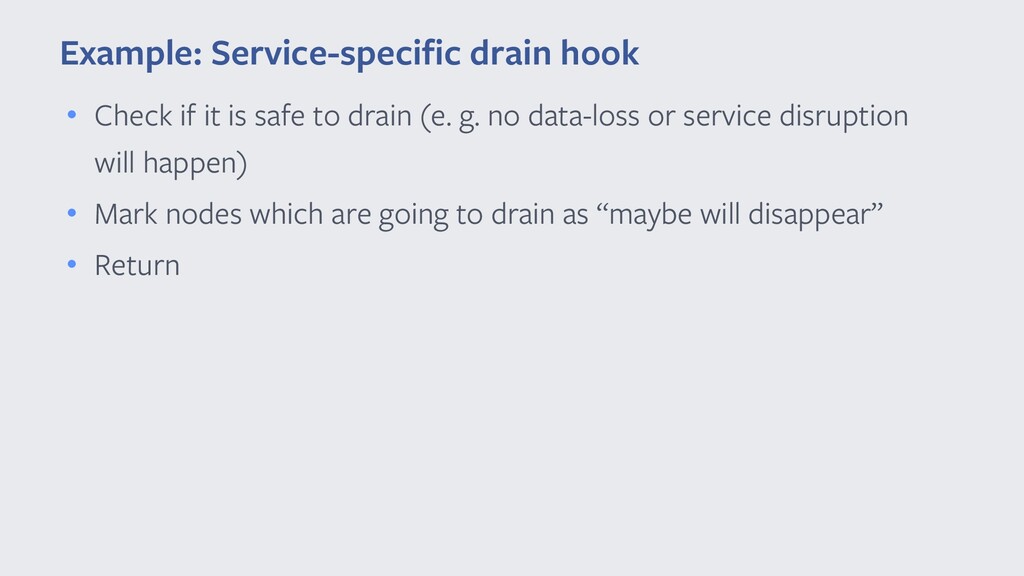
  16. • Check if it is safe to drain (e. g.

    no data-loss or service disruption will happen) • Mark nodes which are going to drain as “maybe will disappear” • Return Example: Service-specific drain hook
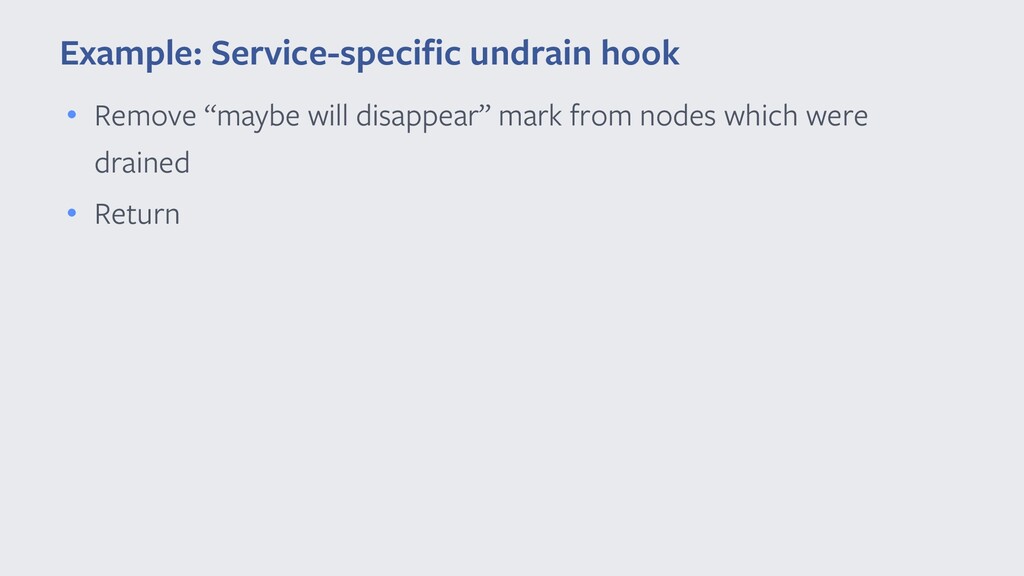
  17. • Remove “maybe will disappear” mark from nodes which were
    drained • Return Example: Service-specific undrain hook
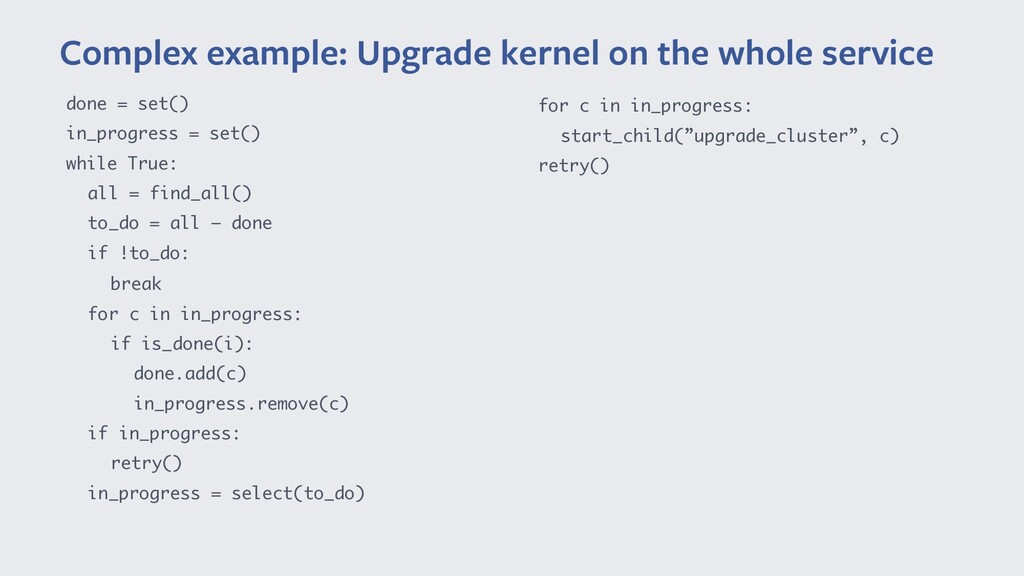
  18. done = set() in_progress = set() while True: all =

    find_all() to_do = all – done if !to_do: break for c in in_progress: if is_done(i): done.add(c) in_progress.remove(c) if in_progress: retry() in_progress = select(to_do) Complex example: Upgrade kernel on the whole service for c in in_progress: start_child(”upgrade_cluster”, c) retry()
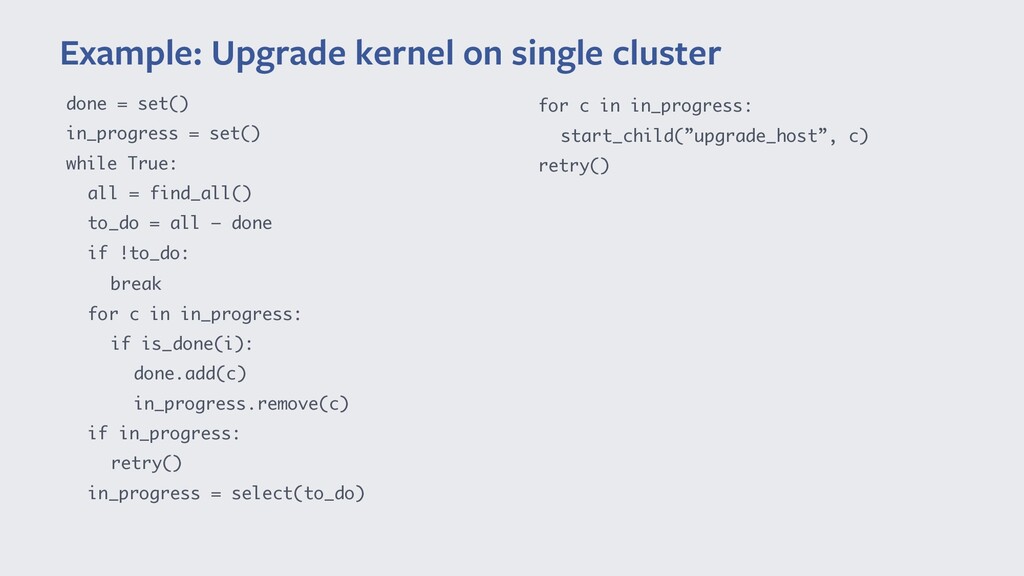
  19. done = set() in_progress = set() while True: all =

    find_all() to_do = all – done if !to_do: break for c in in_progress: if is_done(i): done.add(c) in_progress.remove(c) if in_progress: retry() in_progress = select(to_do) Example: Upgrade kernel on single cluster for c in in_progress: start_child(”upgrade_host”, c) retry()
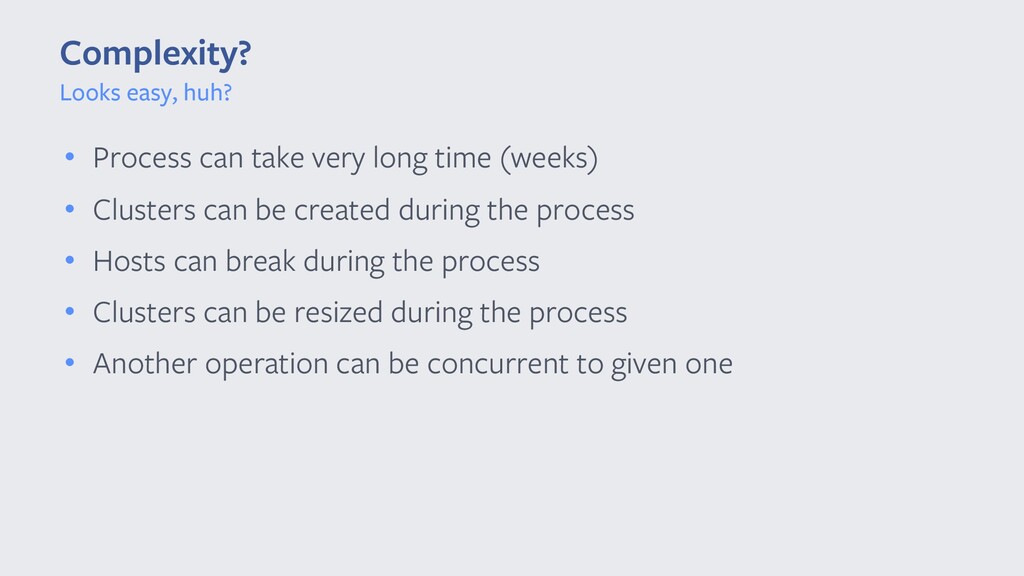
  20. • Process can take very long time (weeks) • Clusters

    can be created during the process • Hosts can break during the process • Clusters can be resized during the process • Another operation can be concurrent to given one Looks easy, huh? Complexity?
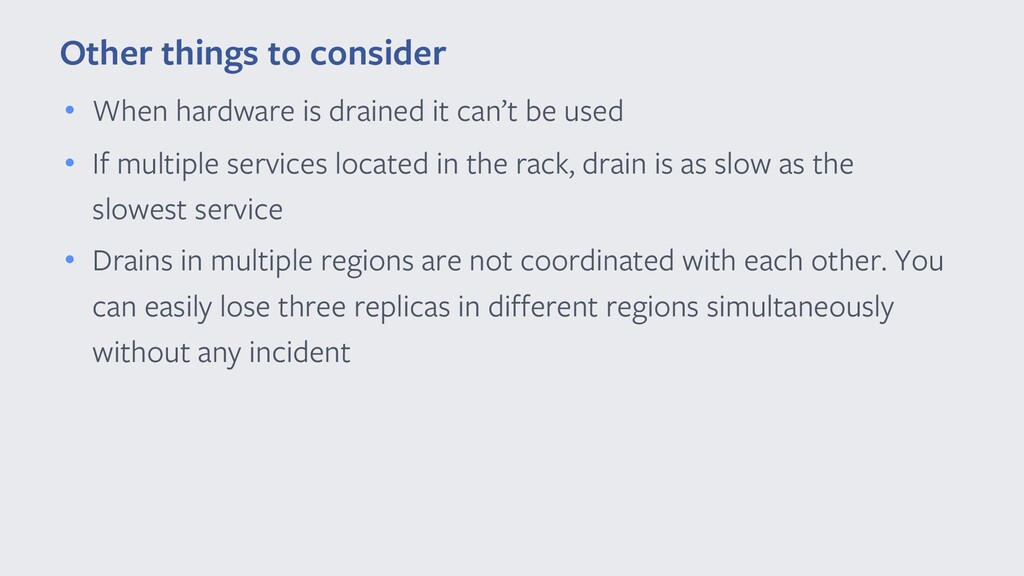
  21. • When hardware is drained it can’t be used •

    If multiple services located in the rack, drain is as slow as the slowest service • Drains in multiple regions are not coordinated with each other. You can easily lose three replicas in different regions simultaneously without any incident Other things to consider

More Decks by DevOpsDaysMoscow

Other Decks in Technology