Share
Embed
Transcript
110 slides
-
“Imagine a world in which every single human being can
freely share in the sum of all knowledge.” -
Senior Systems Engineer I have been with Wikimedia since 2012,
mostly on infrastructure for analytics. Previously Lead SysAdmin at CouchSurfing.org http://www.mediawiki.org/wiki/User:Ottomata Andrew Otto -
Fangjin Yang Druid Engineer One of the original authors behind
Druid. Co-founder @ Imply. -
Wikipedia is ranked the 6th largest website when it comes
to pageviews [Alexa] Scale is an obvious issue ... -
Complexity is less obvious MediaWiki is not designed for analytics.
It is hard to know the pages that were created by users with more than 5 edits in German wikipedia in 2016. -
Privacy We do not send data to third parties. Commercial
solutions to gather user data are not an option. -
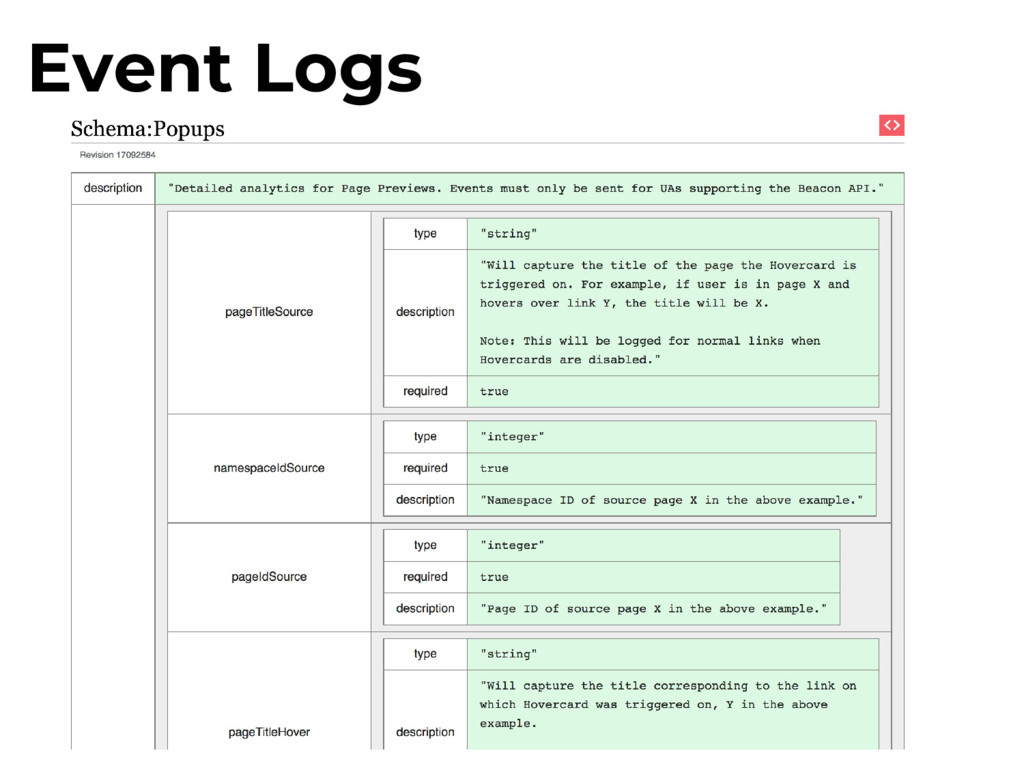
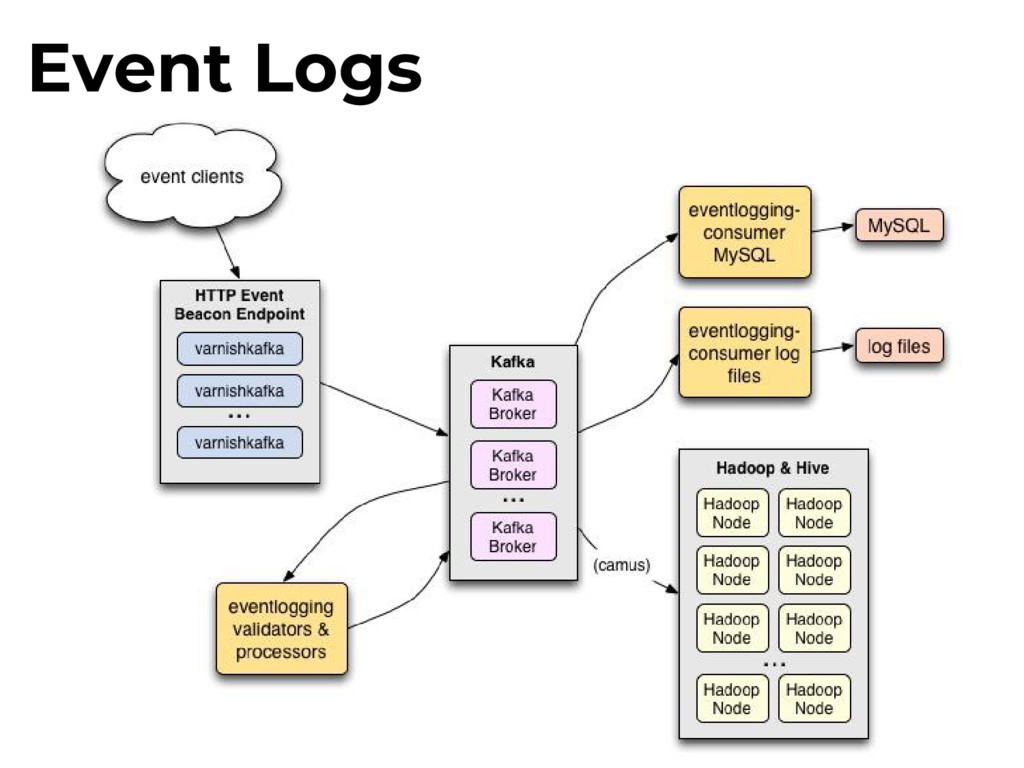
Captures rich events of JSON schema-ed data. Events are validated
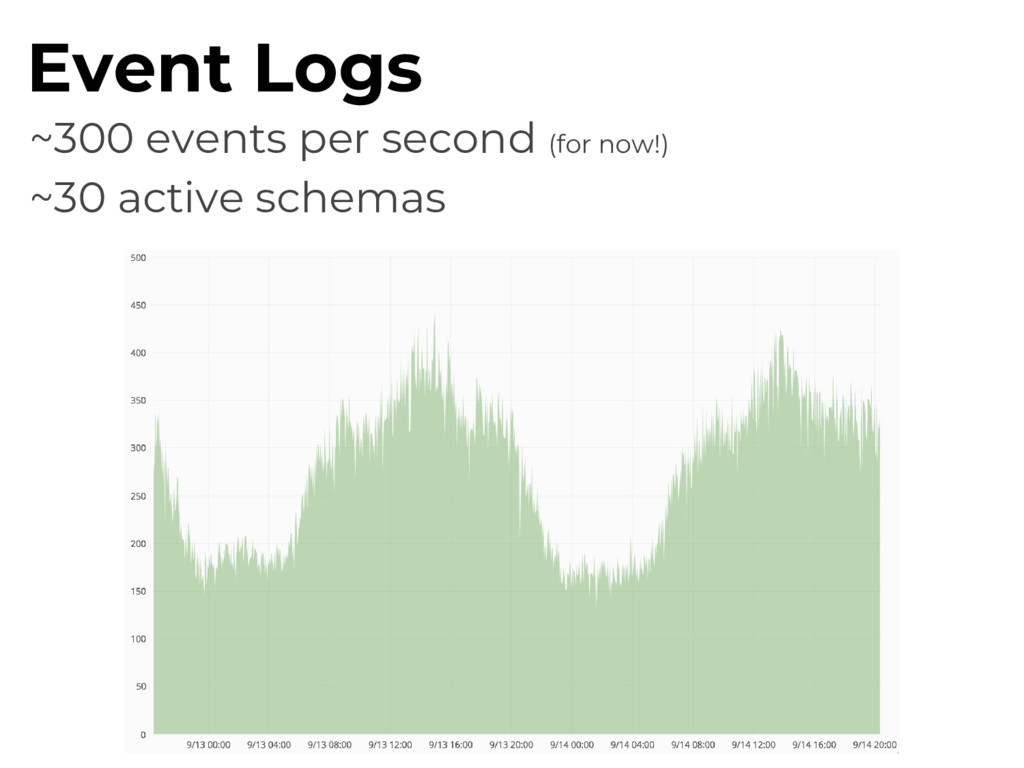
and sent off to various data stores. EventLogging Event Logs -
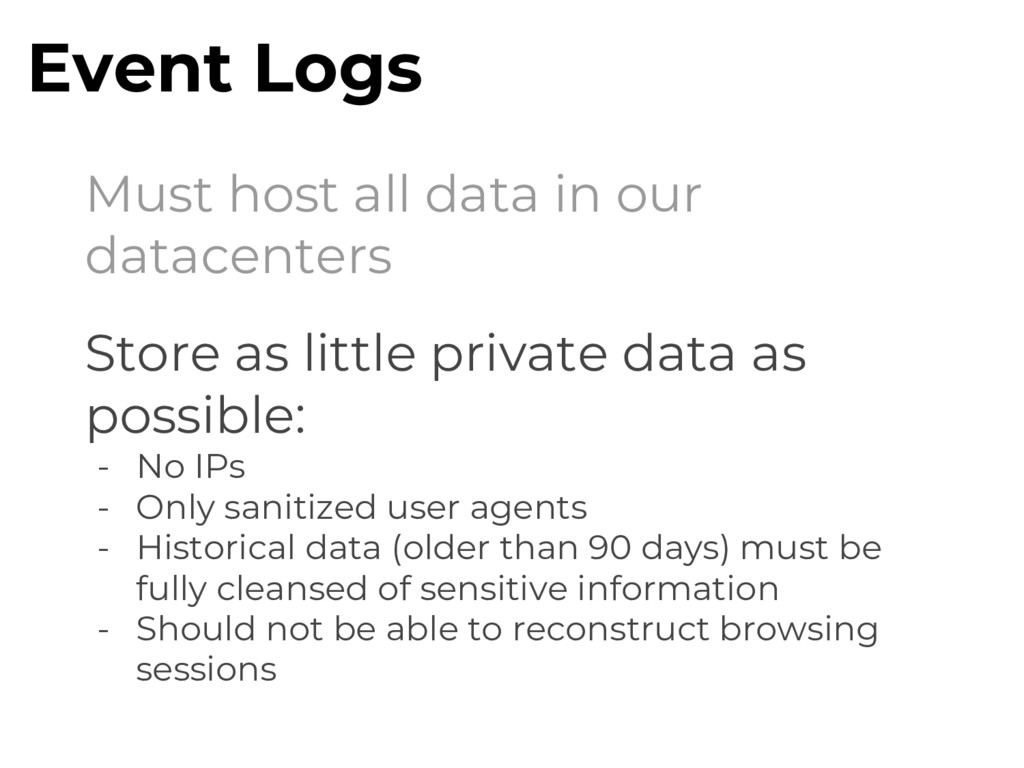
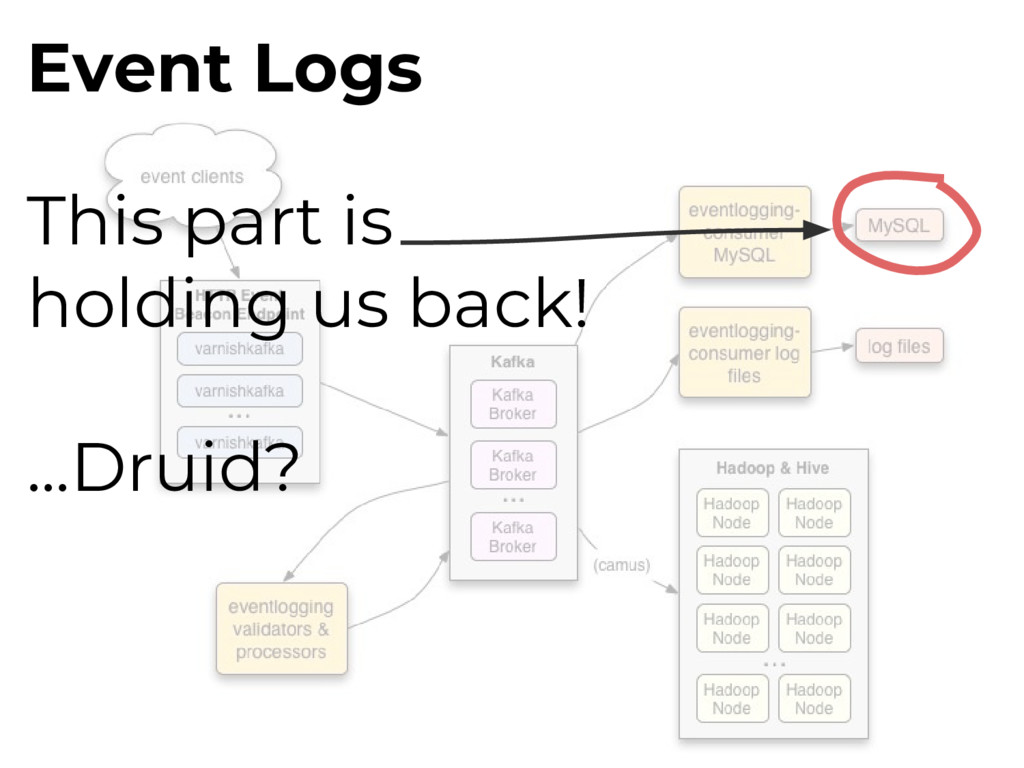
Must host all data in our datacenters Event Logs Store
as little private data as possible: - No IPs - Only sanitized user agents - Historical data (older than 90 days) must be fully cleansed of sensitive information - Should not be able to reconstruct browsing sessions -
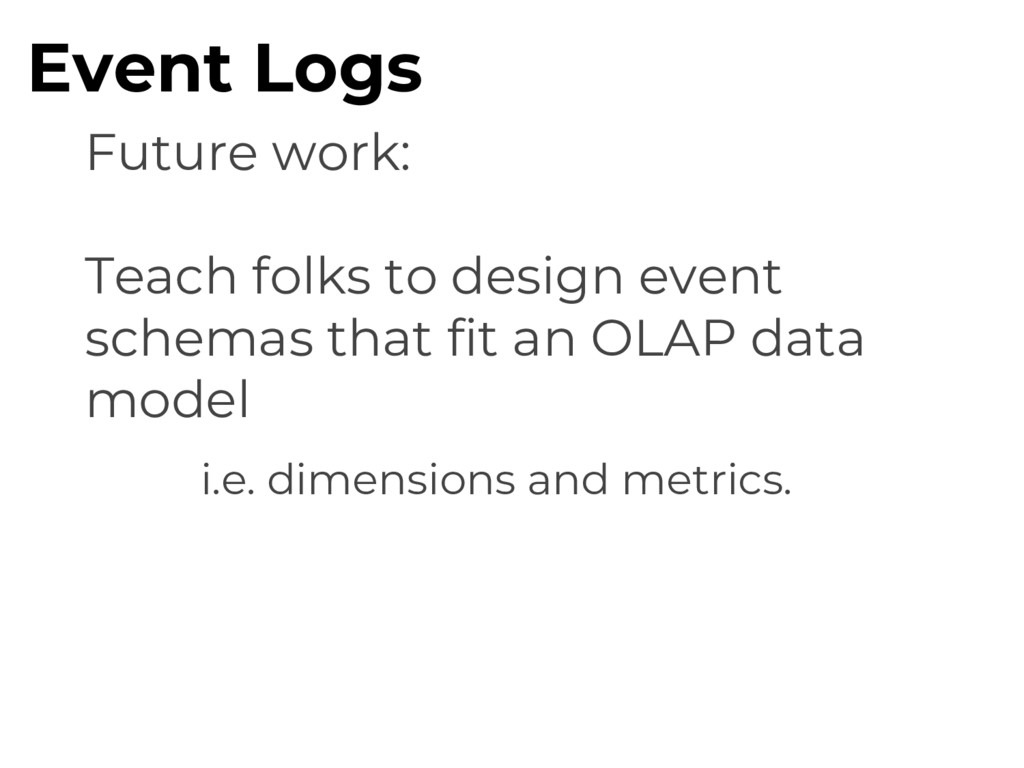
Future work: Teach folks to design event schemas that fit
an OLAP data model Event Logs i.e. dimensions and metrics. -
Future work: Teach folks to design event schemas that fit
an OLAP data model Event Logs i.e. dimensions and metrics. Auto ingest these into Druid to allow for use with nice GUIs (Pivot / Superset) -
MediaWiki databases MediaWiki metadata is not huge, but analytics of
edit history since the beginning of wiki time is dimensionally complex. -
We want to learn about users and edit history. -
How many new users over time? - How many edits over time? - How many edits do new users make? - How do editors stay active? - How many edits are made by bots? - Etc. etc. etc. MediaWiki databases -
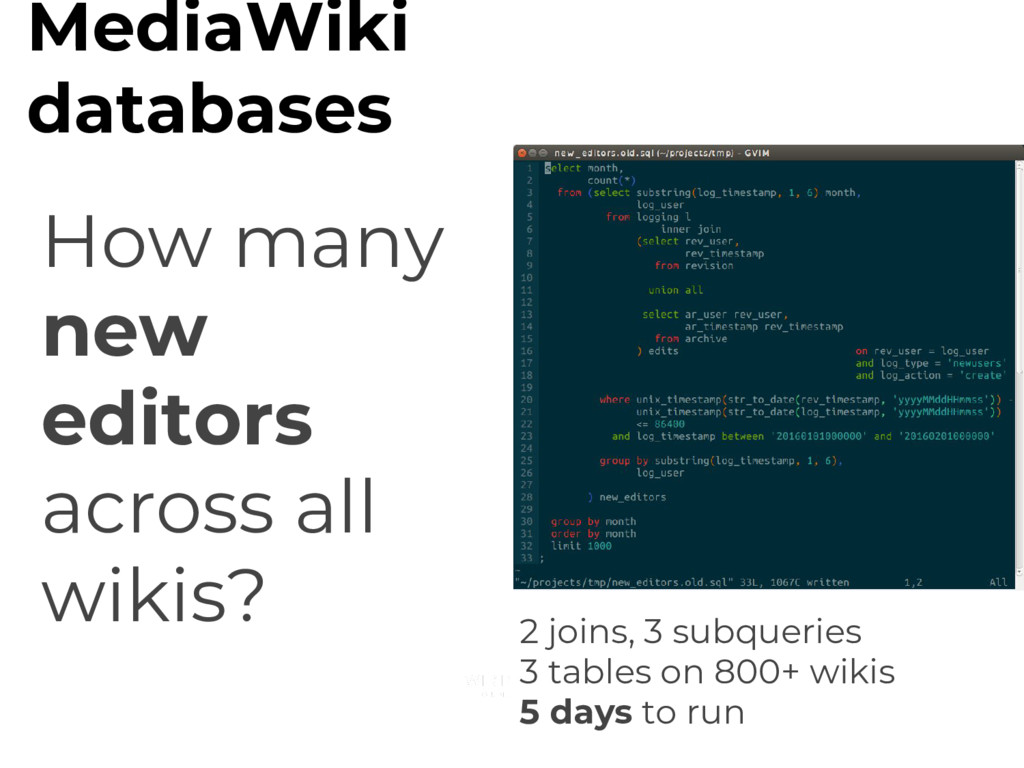
MediaWiki databases How many new editors across all wikis? 2
joins, 3 subqueries 3 tables on 800+ wikis 5 days to run -
MySQL (OLTP) works fine as a application storage but not
so great for historical analytics. MediaWiki databases -
MySQL (OLTP) works fine as a application storage but not
so great for historical analytics. Can only query current state. MediaWiki databases -
However... Historical events are saved in a ‘log’ table. Log
has juicy information about: MediaWiki databases -
page (AKA article) events (move, delete and restore) user events
(rename, block, rights) ...which both go back to the almost beginning of wiki-time MediaWiki databases However... Historical events are saved in a ‘log’ table. Log has juicy information about: -
MediaWiki databases However...HOWEVER! MediaWiki is an old(ish) popular open source
project. Super cool! But this also leads us to the land of database design insanity! -
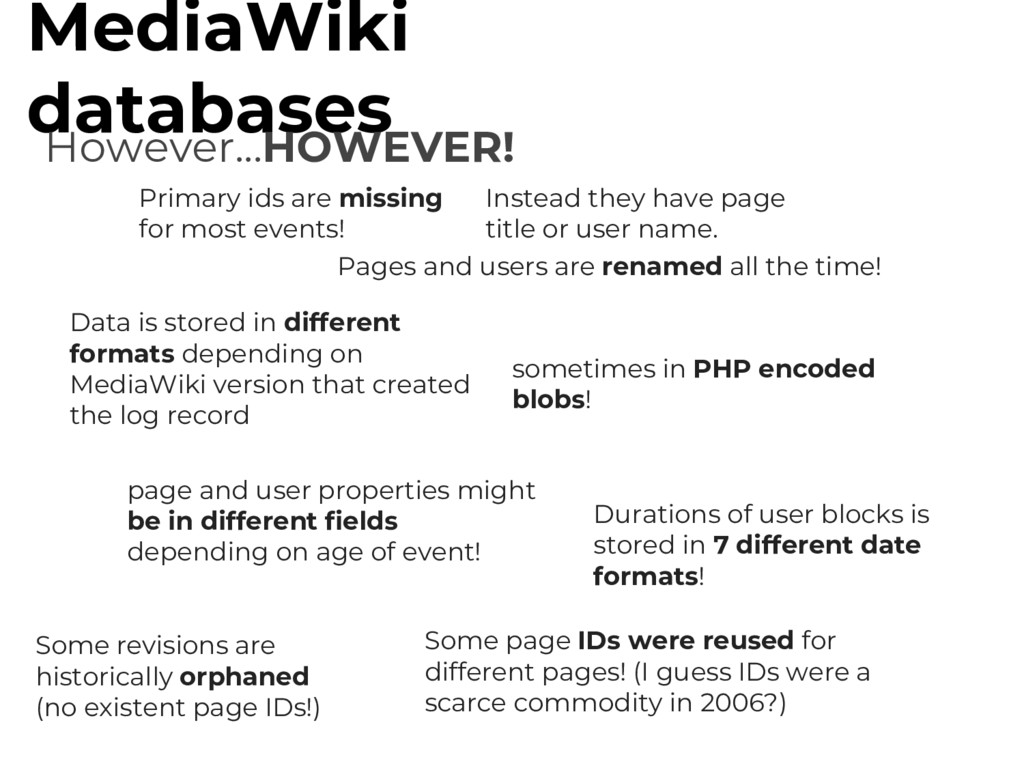
MediaWiki databases However...HOWEVER! Primary ids are missing for most events!
Instead they have page title or user name. -
MediaWiki databases However...HOWEVER! Primary ids are missing for most events!
Instead they have page title or user name. Pages and users are renamed all the time! -
MediaWiki databases However...HOWEVER! Primary ids are missing for most events!
Instead they have page title or user name. Pages and users are renamed all the time! Data is stored in different formats depending on MediaWiki version that created the log record -
MediaWiki databases However...HOWEVER! Primary ids are missing for most events!
Instead they have page title or user name. Pages and users are renamed all the time! Data is stored in different formats depending on MediaWiki version that created the log record sometimes in PHP encoded blobs! -
MediaWiki databases However...HOWEVER! Primary ids are missing for most events!
Instead they have page title or user name. Pages and users are renamed all the time! Data is stored in different formats depending on MediaWiki version that created the log record page and user properties might be in different fields depending on age of event! sometimes in PHP encoded blobs! -
MediaWiki databases However...HOWEVER! Primary ids are missing for most events!
Instead they have page title or user name. Pages and users are renamed all the time! Data is stored in different formats depending on MediaWiki version that created the log record Durations of user blocks is stored in 7 different date formats! page and user properties might be in different fields depending on age of event! sometimes in PHP encoded blobs! -
MediaWiki databases However...HOWEVER! Primary ids are missing for most events!
Instead they have page title or user name. Pages and users are renamed all the time! Data is stored in different formats depending on MediaWiki version that created the log record Durations of user blocks is stored in 7 different date formats! page and user properties might be in different fields depending on age of event! Some revisions are historically orphaned (no existent page IDs!) sometimes in PHP encoded blobs! -
MediaWiki databases However...HOWEVER! Primary ids are missing for most events!
Instead they have page title or user name. Pages and users are renamed all the time! Data is stored in different formats depending on MediaWiki version that created the log record Durations of user blocks is stored in 7 different date formats! page and user properties might be in different fields depending on age of event! Some revisions are historically orphaned (no existent page IDs!) Some page IDs were reused for different pages! (I guess IDs were a scarce commodity in 2006?) sometimes in PHP encoded blobs! -
MediaWiki history Solution: history reconstruction Complex series of Spark jobs
that iterate over imported snapshot of all MediaWiki databases. Final output: large denormalized history Hive table of all MediaWiki events across all Wikimedia sites -
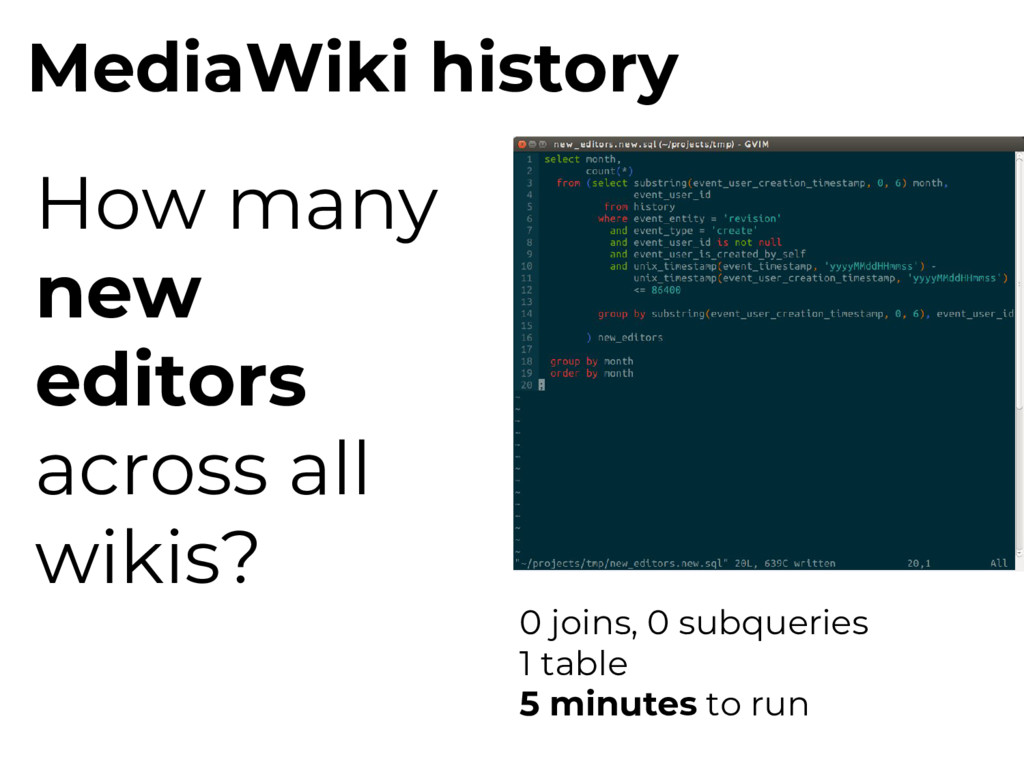
MediaWiki history How many new editors across all wikis? 0
joins, 0 subqueries 1 table 5 minutes to run -
Webrequests Unlike MediaWiki data, webrequest data is huge, but dimensionally
simple (url, http status, user agent, etc.) -
Webrequests We want to know - How many HTTP requests?
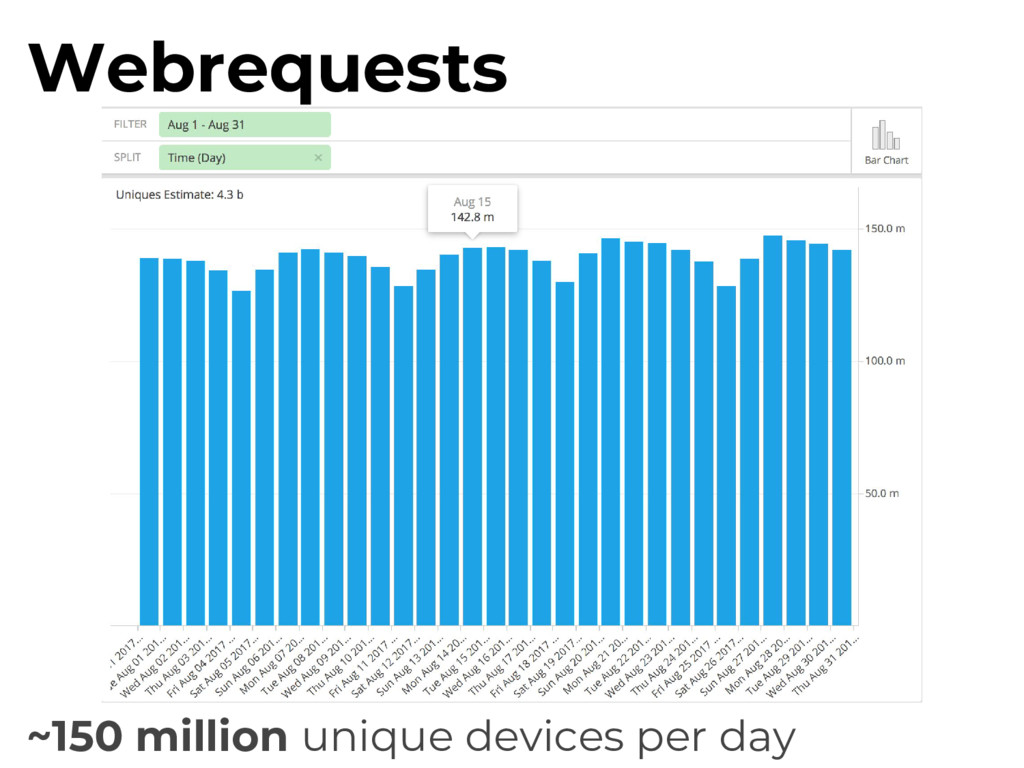
- What browsers do people use? - How many of those requests actual article page views? - How many of those are unique devices? -
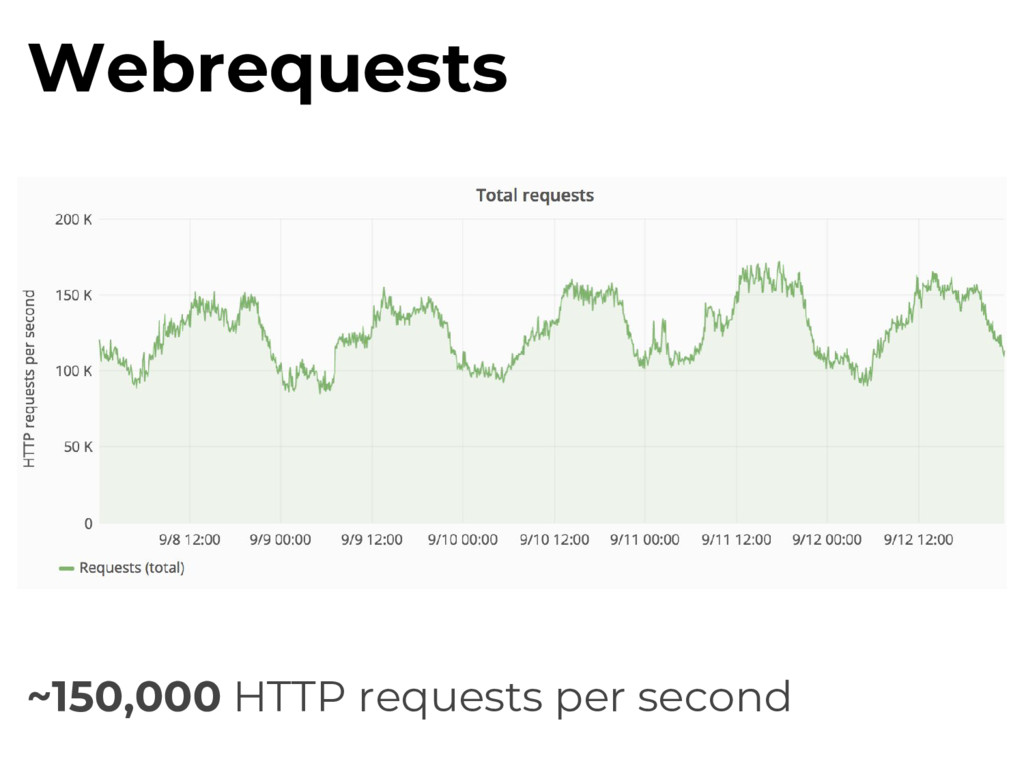
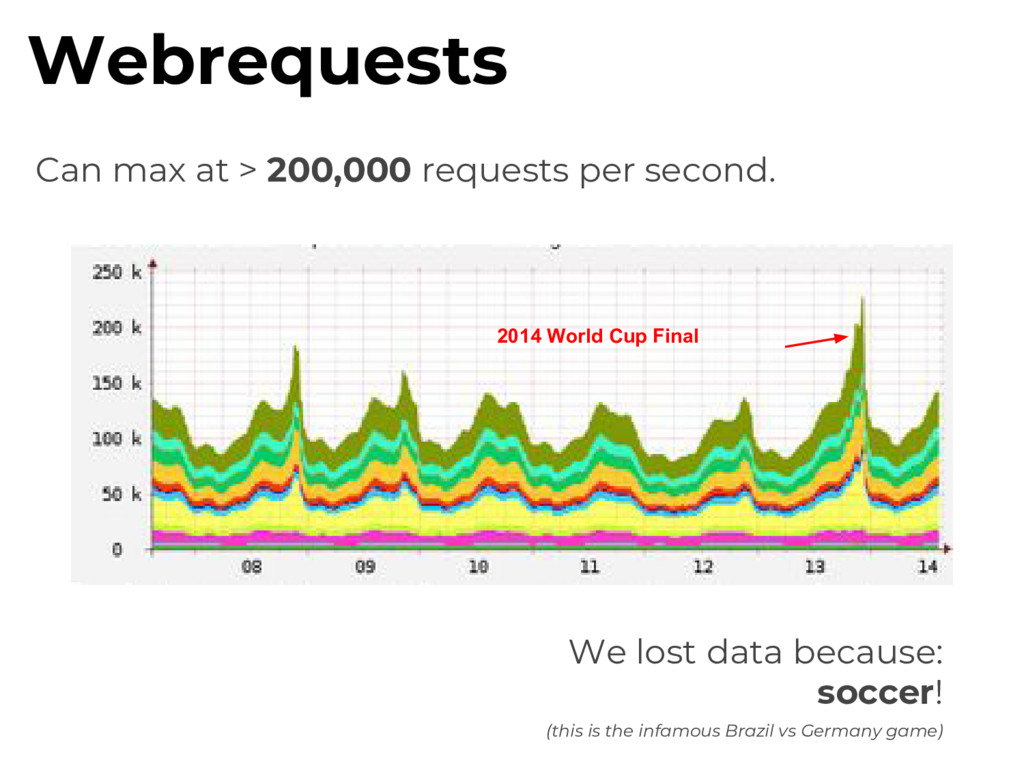
Can max at > 200,000 requests per second. 2014 World
Cup Final Webrequests We lost data because: soccer! (this is the infamous Brazil vs Germany game) -
Varnish Webrequests handled by Varnish in multiple datacenters. Shared memory
log varnishlog apps can access in Varnish’s logs in memory. Varnishncsa Varnishlog -> stdout formatter Wikimedia patched this to send logs over UDP. Webrequests -
udp2log Listens for UDP traffic stream. Delimits messages by newlines.
Tees out and samples traffic to custom filters. multicast relay socat relay sends varnishncsa traffic to a multicast group, allowing for multiple udp2log consumers. Webrequests -
doesn’t scale - every udp2log instance must see every network
packet. Works for simple use cases and lower traffic scenarios. Webrequests - udp2log -
What we want: all requests saved for easy and fast
analysis. Webrequests -
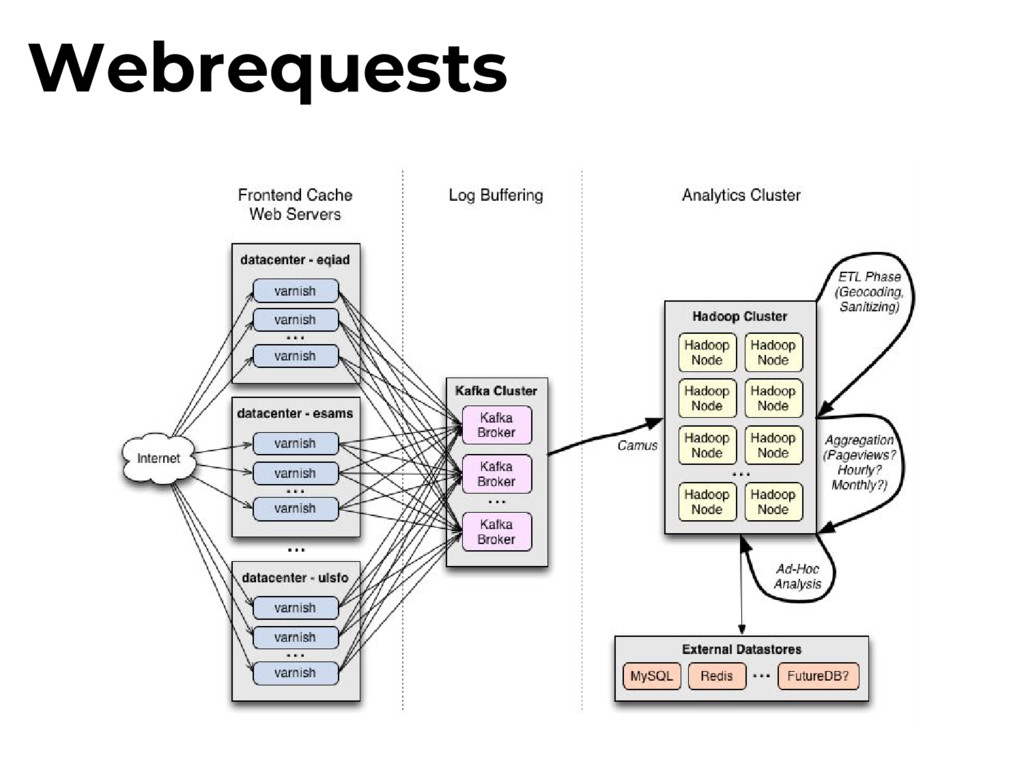
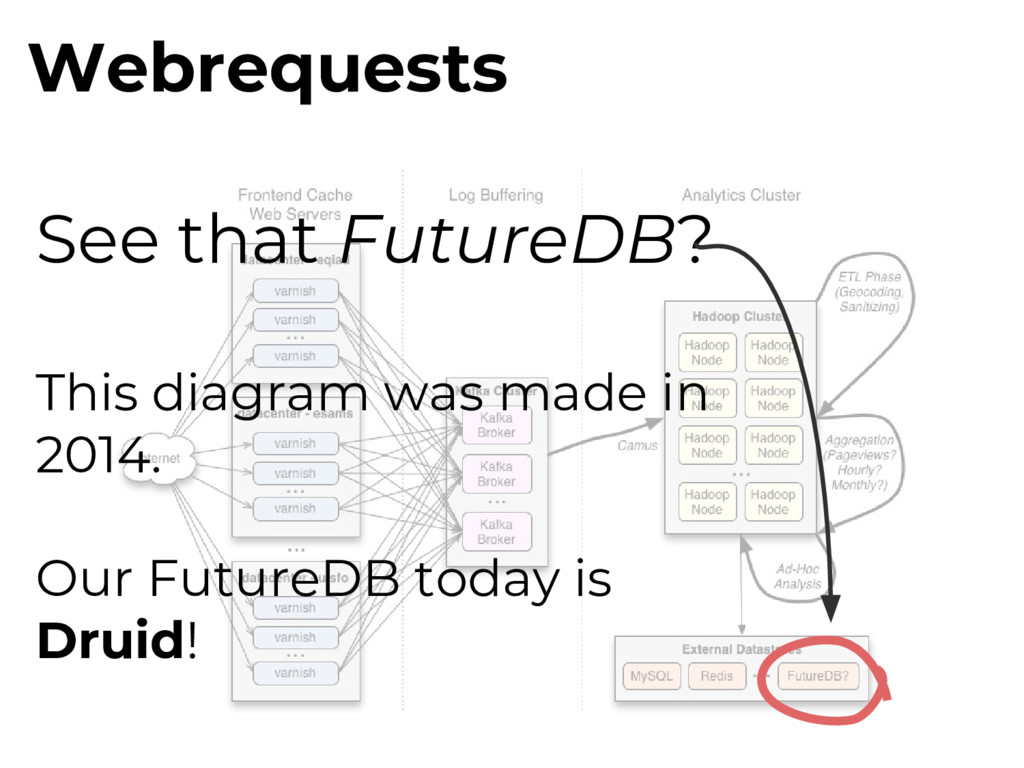
Webrequests See that FutureDB? This diagram was made in 2014.
Our FutureDB today is Druid! -
Why? Druid Can’t use proprietary software (No Tableu) Druid works
with some really nice GUIs (Pivot, Superset, etc.), which provide a lot of value for us. -
Why? Druid Can’t use proprietary software (No Tableu) Druid works
with some really nice GUIs (Pivot, Superset, etc.), which provides a lot of value for us. and we get a fast scalable OLAP database, with realtime support -
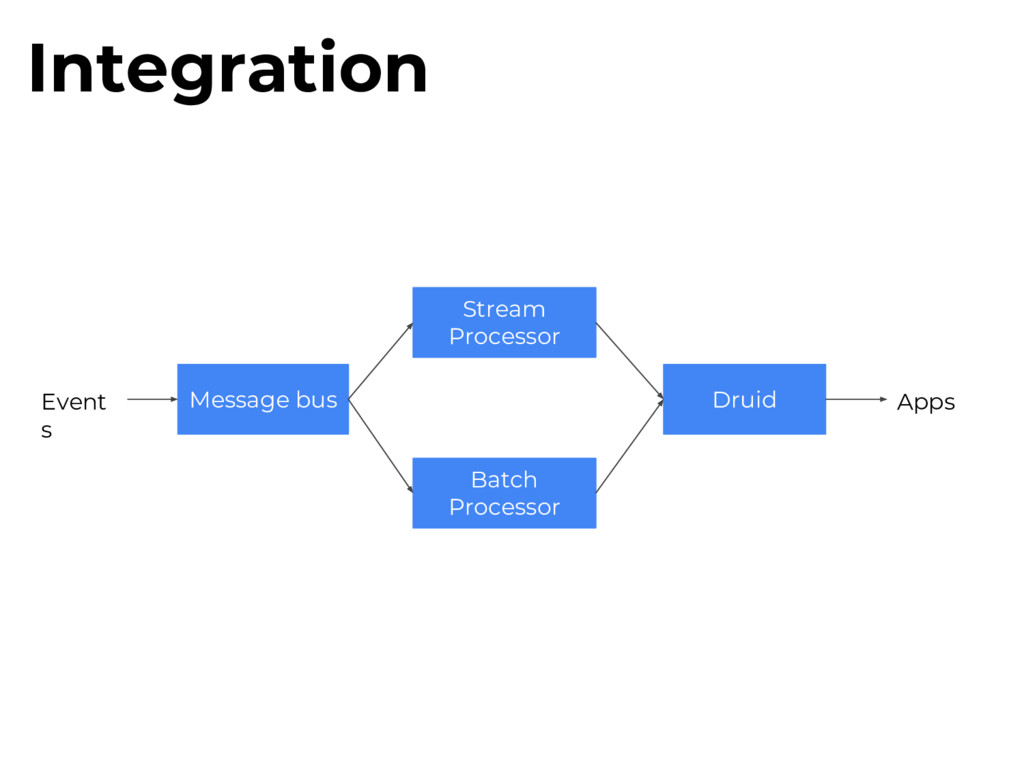
Ingestion Druid Batch Data is partially pre-aggregated in Hadoop into
useful Hive tables (e.g. Mediawiki History, Pageview counts, etc.) This is then regularly loaded into Druid using custom tooling and Oozie -
Ingestion Druid Streaming Spark Streaming job consumes from Kafka and
crunches dimensions and metrics. Spark-Tranquility used to beam directly to Druid for indexing (WIP) -
Druid July 2016 - Issue T141506 is submitted: “Suddenly outrageous
higher pageviews for main pages” -
Druid Suddenly outrageous higher pageviews for main pages Lots of
slicing and dicing in Hive, but we didn’t see a trend. -
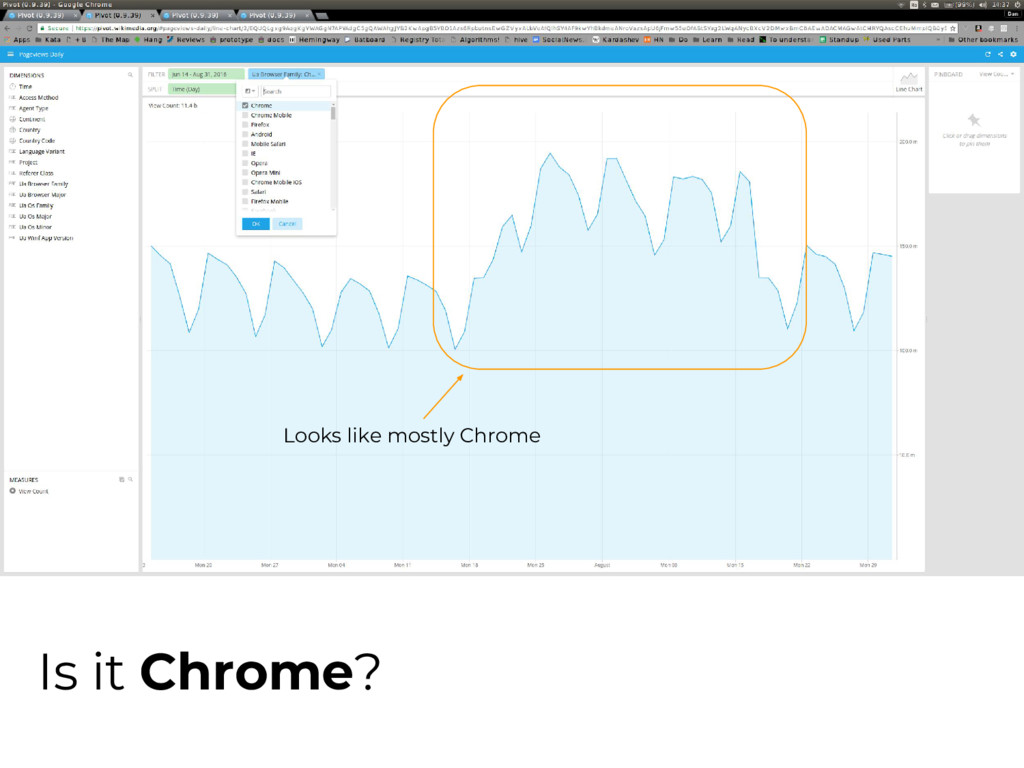
Druid Suddenly outrageous higher pageviews for main pages Suspicion about
browsers. Used Druid/Pivot to slice Lots of slicing and dicing in Hive, but we didn’t see a trend. -
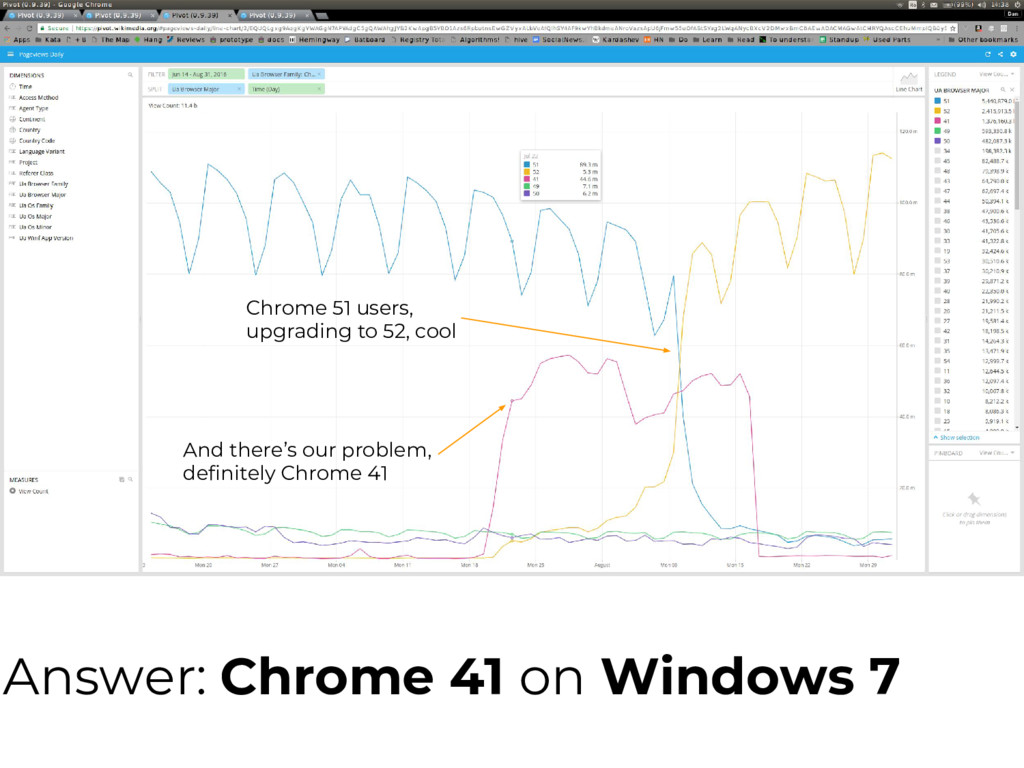
Answer: Chrome 41 on Windows 7 Chrome 51 users, upgrading
to 52, cool And there’s our problem, definitely Chrome 41 -
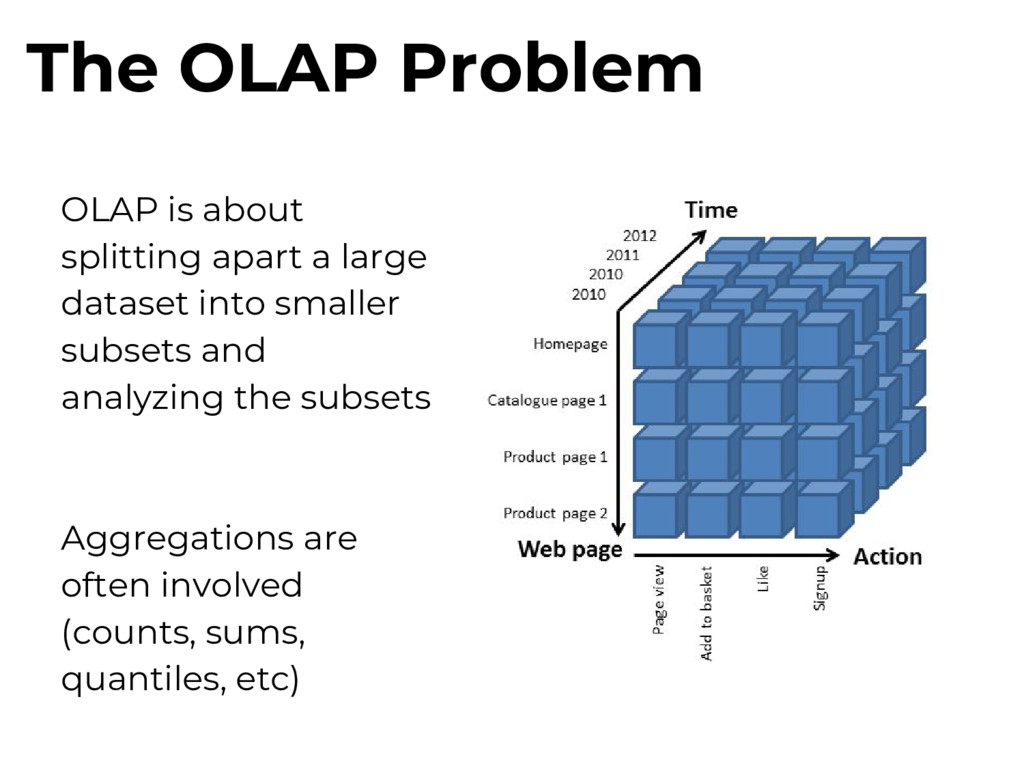
OLAP is about splitting apart a large dataset into smaller
subsets and analyzing the subsets Aggregations are often involved (counts, sums, quantiles, etc) The OLAP Problem -
High dimensionality: 10s, 100s, or even 1000s of columns High
cardinality: each column may have millions of unique values Multi-tenancy: many concurrent users Freshness: load from streams, not batch files OLAP at scale is hard -
How Druid tackles OLAP Column storage format Compression & encoding
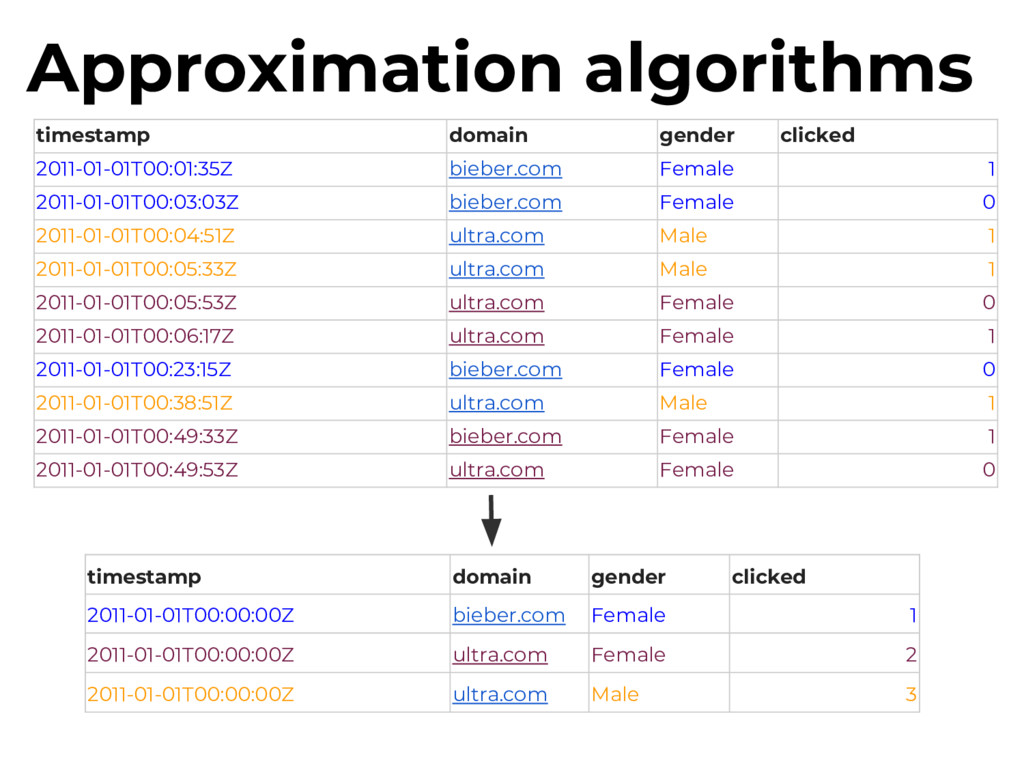
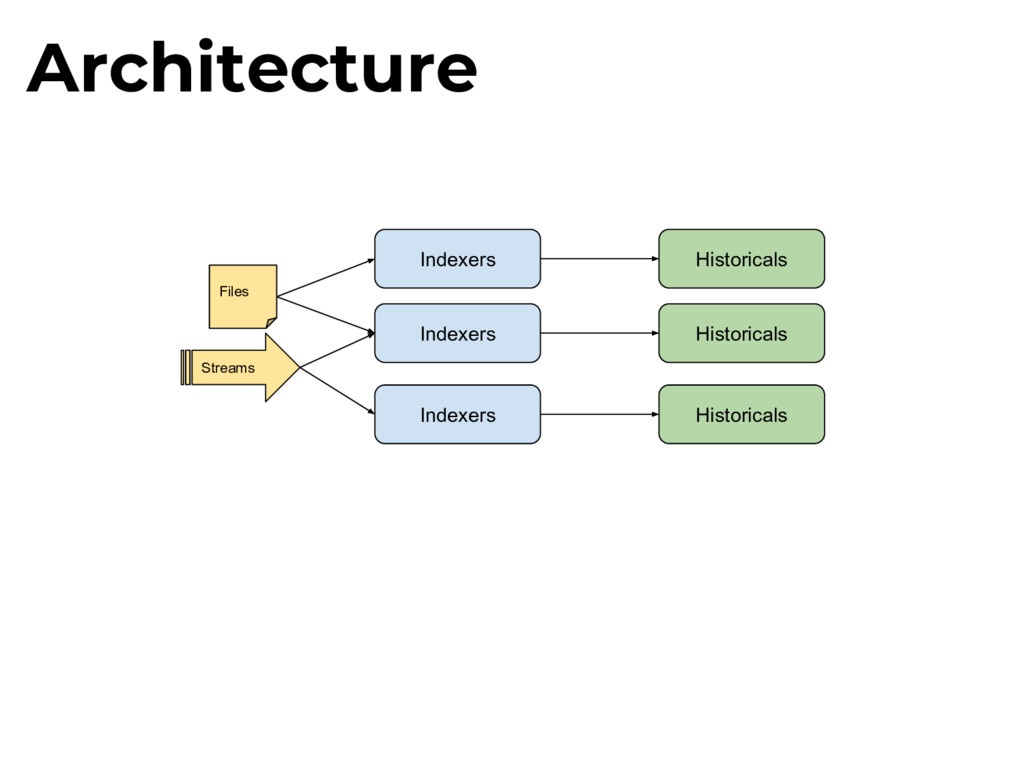
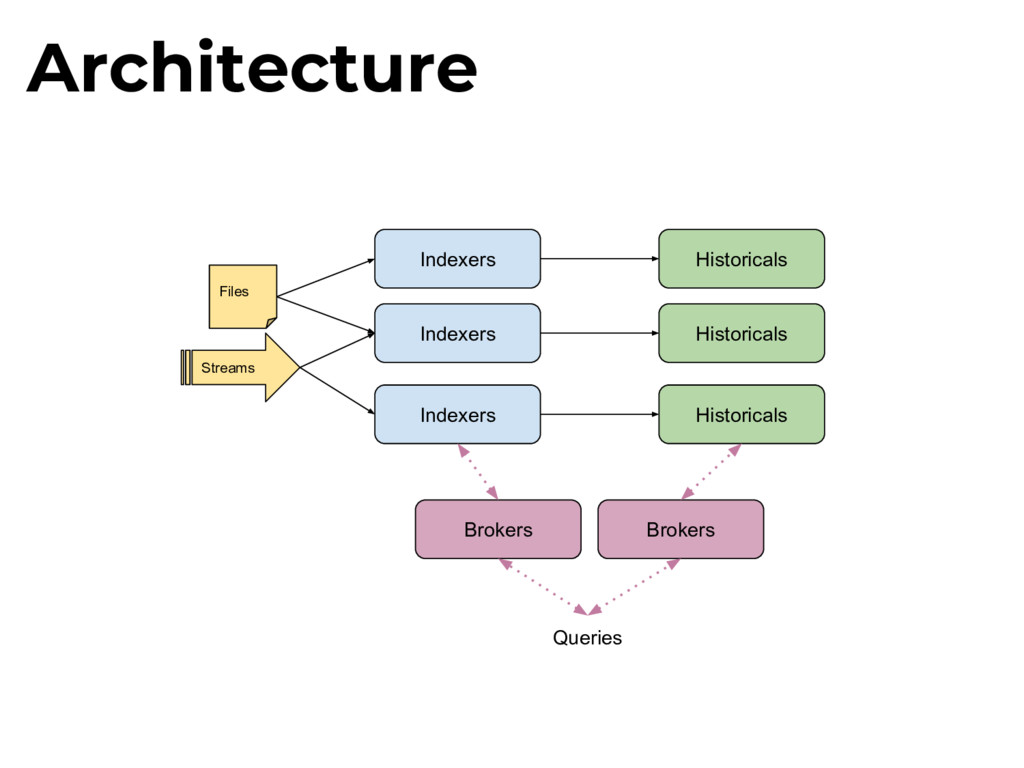
Intelligent search filters Approximate algorithms Distributed architecture -
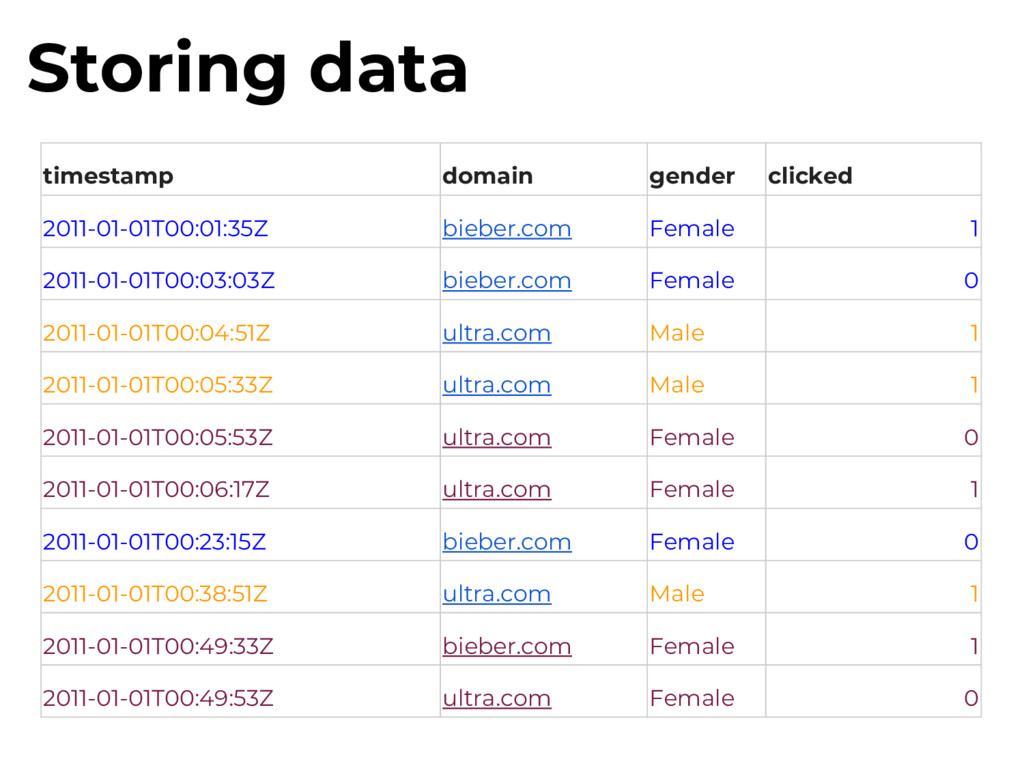
Storing data timestamp domain gender clicked 2011-01-01T00:01:35Z bieber.com Female 1
2011-01-01T00:03:03Z bieber.com Female 0 2011-01-01T00:04:51Z ultra.com Male 1 2011-01-01T00:05:33Z ultra.com Male 1 2011-01-01T00:05:53Z ultra.com Female 0 2011-01-01T00:06:17Z ultra.com Female 1 2011-01-01T00:23:15Z bieber.com Female 0 2011-01-01T00:38:51Z ultra.com Male 1 2011-01-01T00:49:33Z bieber.com Female 1 2011-01-01T00:49:53Z ultra.com Female 0 -
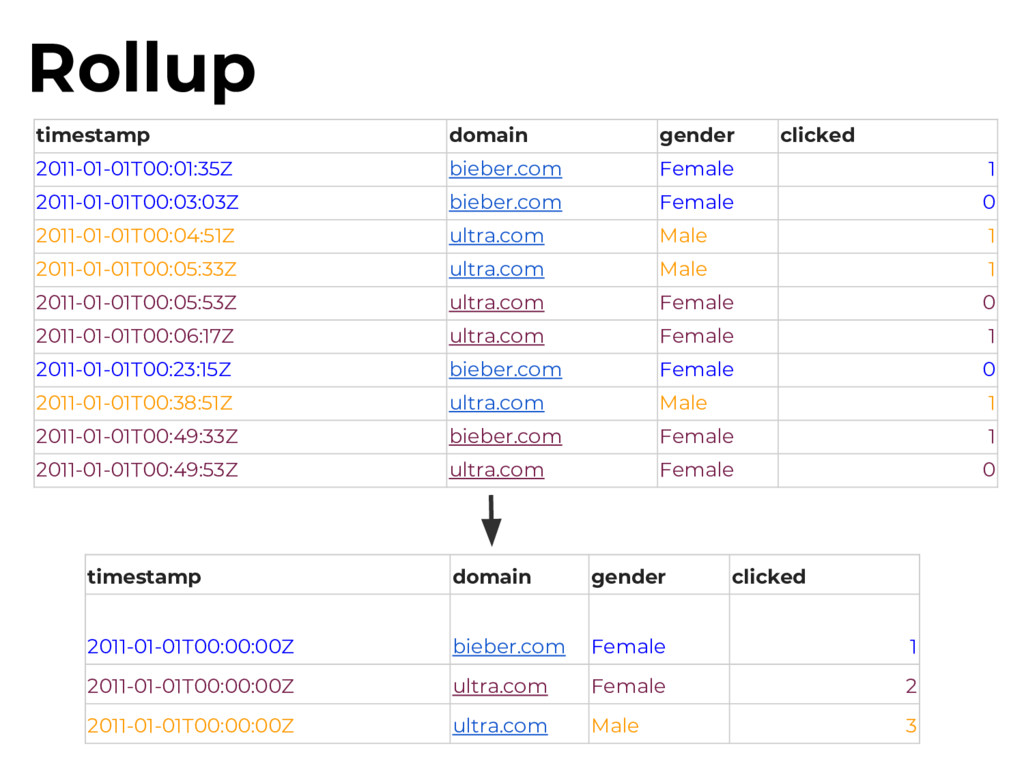
timestamp domain gender clicked 2011-01-01T00:00:00Z bieber.com Female 1 2011-01-01T00:00:00Z ultra.com
Female 2 2011-01-01T00:00:00Z ultra.com Male 3 timestamp domain gender clicked 2011-01-01T00:01:35Z bieber.com Female 1 2011-01-01T00:03:03Z bieber.com Female 0 2011-01-01T00:04:51Z ultra.com Male 1 2011-01-01T00:05:33Z ultra.com Male 1 2011-01-01T00:05:53Z ultra.com Female 0 2011-01-01T00:06:17Z ultra.com Female 1 2011-01-01T00:23:15Z bieber.com Female 0 2011-01-01T00:38:51Z ultra.com Male 1 2011-01-01T00:49:33Z bieber.com Female 1 2011-01-01T00:49:53Z ultra.com Female 0 Rollup -
Segments Fundamental storage unit in Druid No contention between reads
and writes One thread scans one segment -
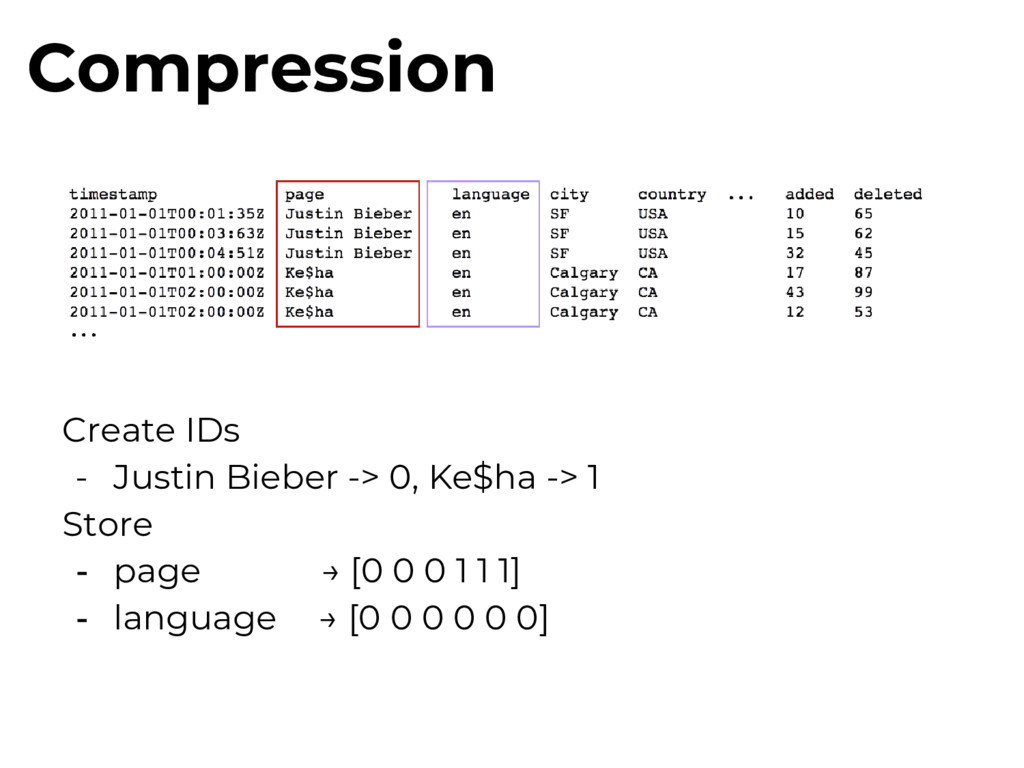
Create IDs - Justin Bieber -> 0, Ke$ha -> 1
Store - page → [0 0 0 1 1 1] - language → [0 0 0 0 0 0] Compression -
Justin Bieber → [0, 1, 2] → [111000] Ke$ha →
[3, 4, 5] → [000111] Justin Bieber OR Ke$ha → [111111] Compression! Fast filters -
timestamp domain gender clicked 2011-01-01T00:00:00Z bieber.com Female 1 2011-01-01T00:00:00Z ultra.com
Female 2 2011-01-01T00:00:00Z ultra.com Male 3 timestamp domain gender clicked 2011-01-01T00:01:35Z bieber.com Female 1 2011-01-01T00:03:03Z bieber.com Female 0 2011-01-01T00:04:51Z ultra.com Male 1 2011-01-01T00:05:33Z ultra.com Male 1 2011-01-01T00:05:53Z ultra.com Female 0 2011-01-01T00:06:17Z ultra.com Female 1 2011-01-01T00:23:15Z bieber.com Female 0 2011-01-01T00:38:51Z ultra.com Male 1 2011-01-01T00:49:33Z bieber.com Female 1 2011-01-01T00:49:53Z ultra.com Female 0 Approximation algorithms -
Approximation algorithms timestamp domain user gender clicked 2011-01-01T00:01:35Z bieber.com 4312345532
Female 1 2011-01-01T00:03:03Z bieber.com 3484920241 Female 0 2011-01-01T00:04:51Z ultra.com 9530174728 Male 1 2011-01-01T00:05:33Z ultra.com 4098310573 Male 1 2011-01-01T00:05:53Z ultra.com 5832058870 Female 0 2011-01-01T00:06:17Z ultra.com 5789283478 Female 1 2011-01-01T00:23:15Z bieber.com 4730093842 Female 0 2011-01-01T00:38:51Z ultra.com 9530174728 Male 1 2011-01-01T00:49:33Z bieber.com 4930097162 Female 1 2011-01-01T00:49:53Z ultra.com 3081837193 Female 0 -
timestamp domain gender clicked unique_users 2011-01-01T00:00:00Z bieber.com Female 1 [approximate_sketch]
2011-01-01T00:00:00Z ultra.com Female 2 [approximate_sketch] 2011-01-01T00:00:00Z ultra.com Male 3 [approximate_sketch] timestamp domain gender clicked 2011-01-01T00:01:35Z bieber.com Female 1 2011-01-01T00:03:03Z bieber.com Female 0 2011-01-01T00:04:51Z ultra.com Male 1 2011-01-01T00:05:33Z ultra.com Male 1 2011-01-01T00:05:53Z ultra.com Female 0 2011-01-01T00:06:17Z ultra.com Female 1 2011-01-01T00:23:15Z bieber.com Female 0 2011-01-01T00:38:51Z ultra.com Male 1 2011-01-01T00:49:33Z bieber.com Female 1 2011-01-01T00:49:53Z ultra.com Female 0 Approximation algorithms -
Scale (largest cluster I know about – not a hard
limit) >3M events/sec ingested (peak) 10 – 100k events/sec/cpu >500 TB of segments (>50 trillion raw events, >50 PB raw data) mean 500ms query time 90%ile < 1s, 95%ile < 5s, 99%ile < 10s -
Works well with: - Kafka - Hadoop - S3 -
Spark Streaming - Storm - Samza - I bet some other things that also start with S Connect