Upgrade to Pro — share decks privately, control downloads, hide ads and more …

Building a Realtime Analytic Stack with Kafka, ...

Sponsored · Ship Features Fearlessly Turn features on and off without deploys. Used by thousands of Ruby developers. →
Druid
October 02, 2015

Building a Realtime Analytic Stack with Kafka, Samza, and Druid

Presented at Strata and Hadoop World 2015.

Druid

October 02, 2015

Transcript

51 slides
  1. BUILDING A REAL-TIME ANALYTIC STACK WITH KAFKA, SAMZA, AND DRUID

    FANGJIN YANG (@FANGJIN) · GIAN MERLINO (@GIANMERLINO) DRUID COMMITTERS
  2. PROBLEM BUSINESS INTELLIGENCE ANALYTICS POSSIBILITIES CHOOSING THE RIGHT TOOLS FOR

    THE JOB ARCHITECTURE COMBINING TECHNOLOGIES NEXT STEPS TRY IT OUT FOR YOURSELF OVERVIEW
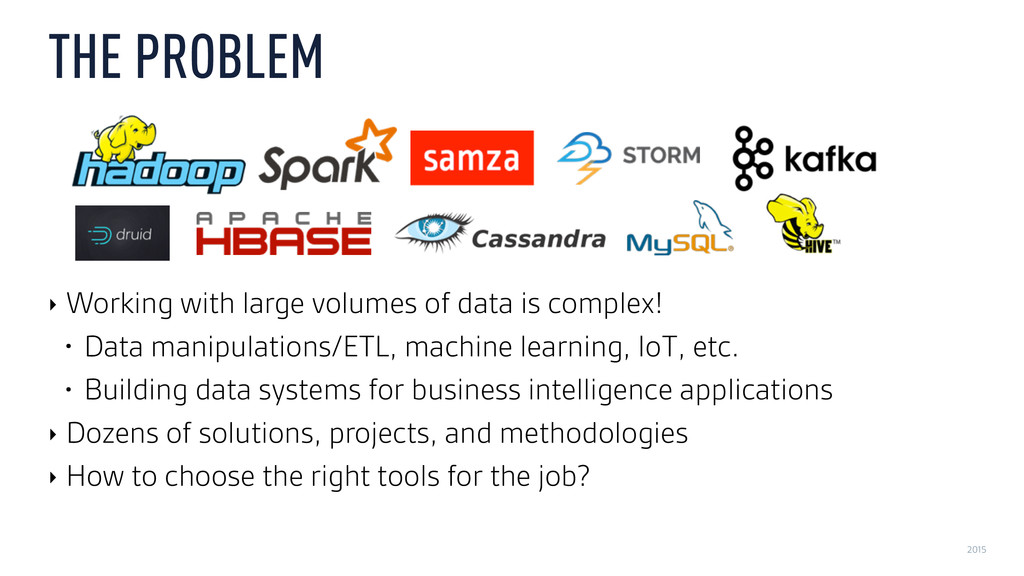
  3. 2015 THE PROBLEM ‣ Working with large volumes of data

    is complex! • Data manipulations/ETL, machine learning, IoT, etc. • Building data systems for business intelligence applications ‣ Dozens of solutions, projects, and methodologies ‣ How to choose the right tools for the job?
  4. 2015 A GENERAL SOLUTION? ‣ Load all your data into

    Hadoop/Spark. Query it. Done! ‣ Good job guys, let’s go home
  5. 2015 GENERAL SOLUTION LIMITATIONS ‣ When one technology becomes widely

    adopted, its limitations also become more well known ‣ General computing frameworks can handle many different distributed computing problems ‣ They are also sub-optimal for many use cases ‣ Analytic queries are inefficient ‣ Specialized technologies are adopted to address these inefficiencies
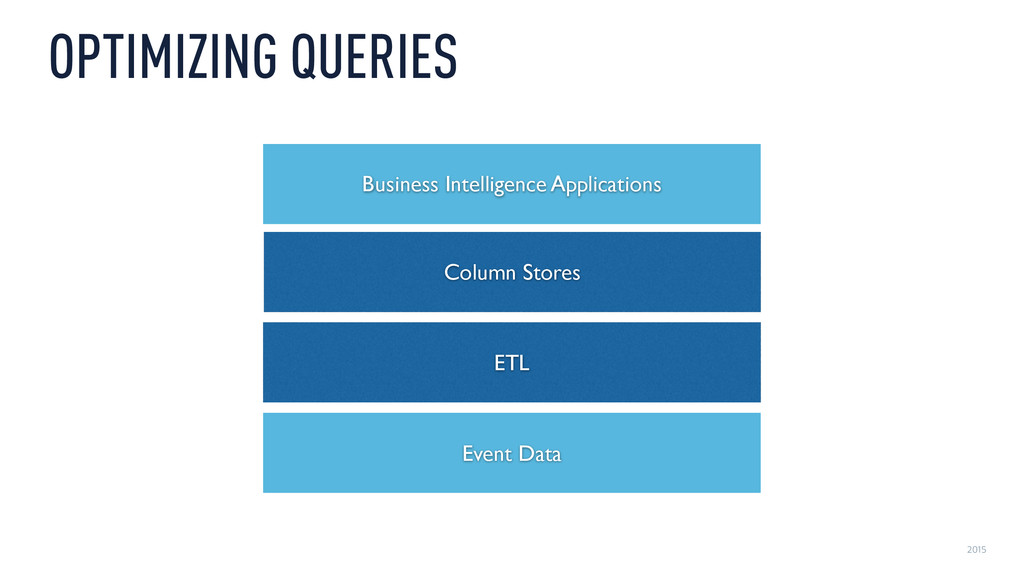
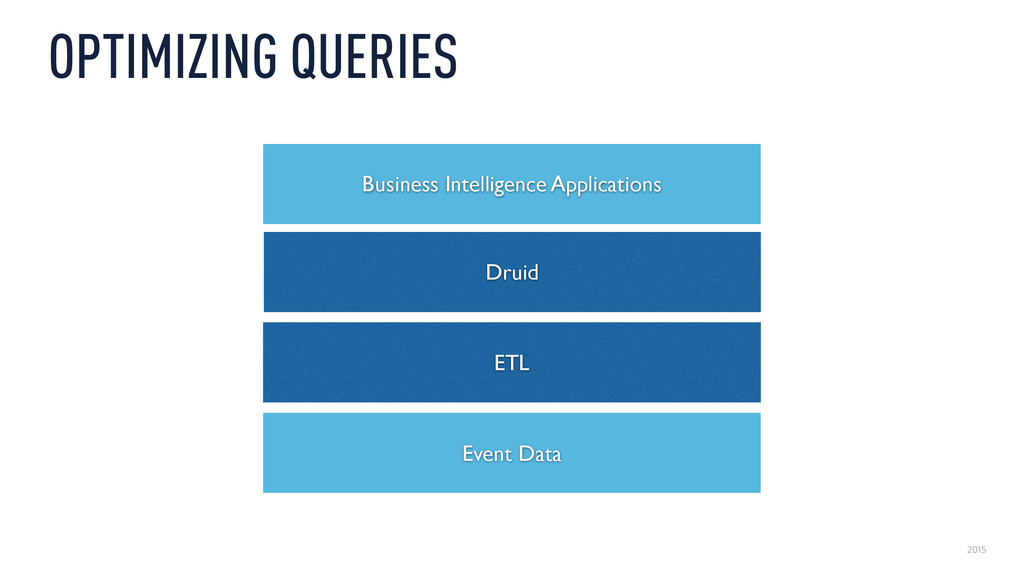
  6. 2015 MAKE QUERIES FASTER ‣ Optimizing business intelligence (OLAP) queries

    • Aggregate measures over time, broken down by dimensions • Revenue over time broken down by product type • Top selling products by volume in San Francisco • Number of unique visitors broken down by age • Not dumping the entire dataset • Not examining individual events
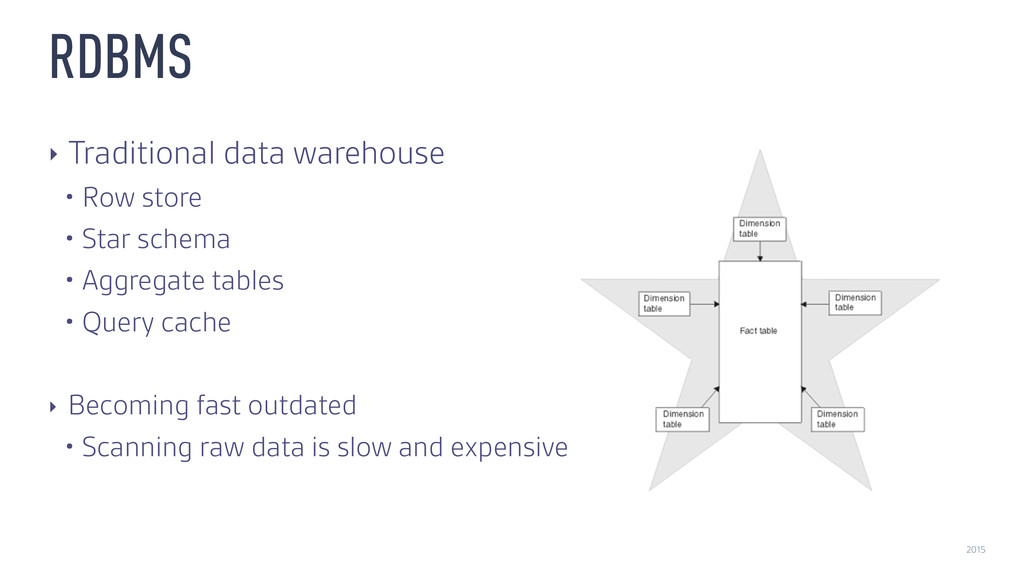
  7. 2015 ‣ Traditional data warehouse • Row store • Star

    schema • Aggregate tables • Query cache ‣ Becoming fast outdated • Scanning raw data is slow and expensive RDBMS
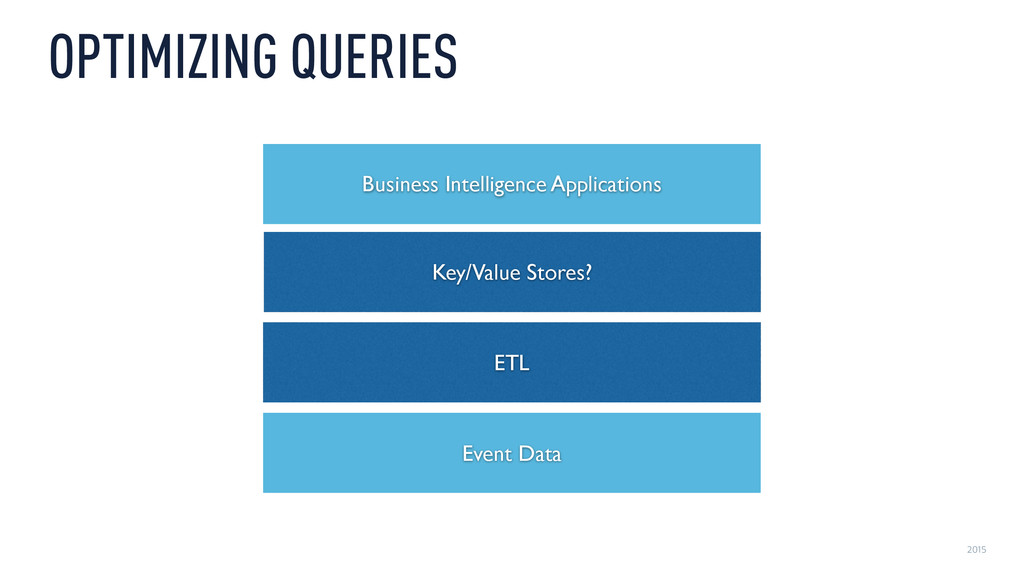
  8. 2015 ‣ Pre-computation • Pre-compute every possible query • Pre-compute

    a subset of queries • Exponential scaling costs ‣ Range scans • Primary key: dimensions/attributes • Value: measures/metrics (things to aggregate) • Still too slow! KEY/VALUE STORES
  9. 2015 ‣ Load/scan exactly what you need for a query

    ‣ Different compression algorithms for different columns ‣ Encoding for string columns ‣ Compression for measure columns ‣ Different indexes for different columns COLUMN STORES
  10. 2015 DRUID ‣ Open source column store ‣ Unique optimizations

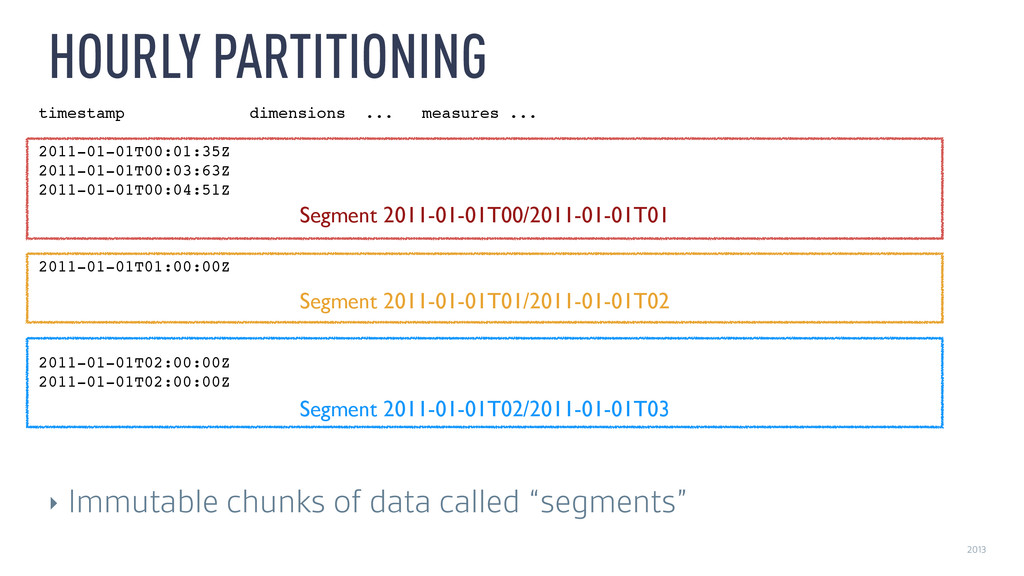
    for event data ‣ Data partitioning/sharding first done on time ‣ Data is partitioned into defined time buckets (hour/day/etc)
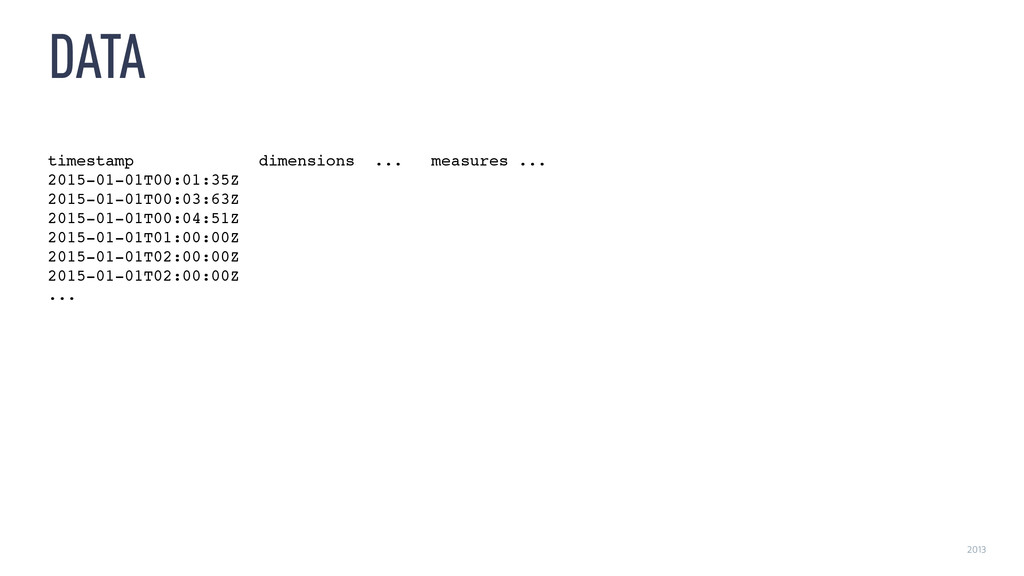
  11. 2013 HOURLY PARTITIONING timestamp dimensions ... measures ... 2011-01-01T00:01:35Z 2011-01-01T00:03:63Z

    2011-01-01T00:04:51Z 2011-01-01T01:00:00Z 2011-01-01T02:00:00Z 2011-01-01T02:00:00Z ‣ Immutable chunks of data called “segments” Segment 2011-01-01T02/2011-01-01T03 Segment 2011-01-01T01/2011-01-01T02 Segment 2011-01-01T00/2011-01-01T01
  12. 2013 IMMUTABLE SEGMENTS ‣ No contention between reads and writes

    ‣ Simple parallelization: one thread scans one segment ‣ Multiple threads can access same underlying data ‣ Supports lots of concurrent reads
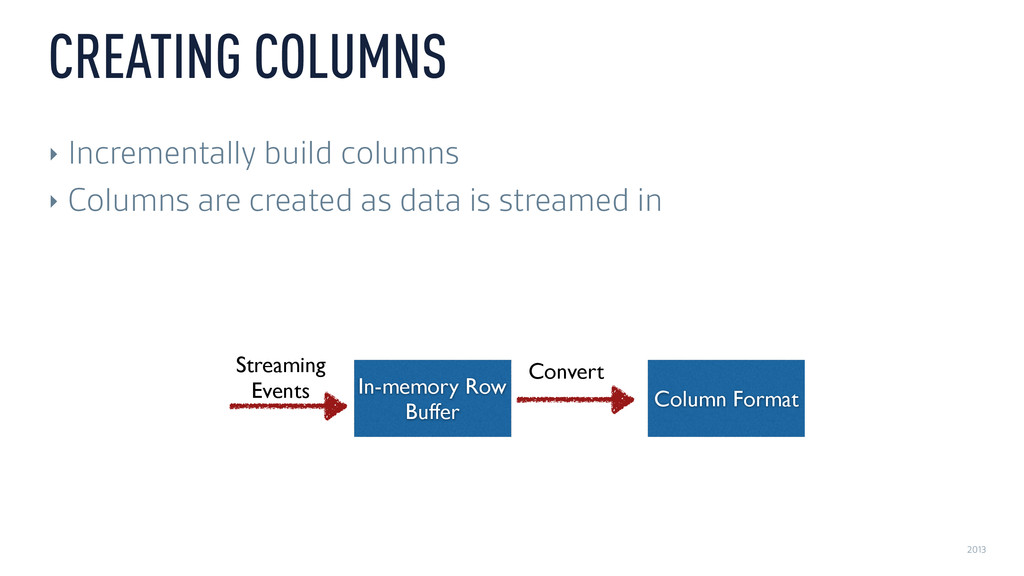
  13. 2013 CREATING COLUMNS ‣ Incrementally build columns ‣ Columns are

    created as data is streamed in In-memory Row Buffer Column Format Streaming Events Convert
  14. 2013 INDEXES ‣ Druid can translate any Boolean predicate into

    rows to be scanned ‣ Creates inverted indexes for dimension values WHERE user = ‘alice’ OR user = ‘bob’ 0 1 0 0 1 0 1 1 0 0 0 1 OR 1 1 0 0 1 1 =
  15. 2015 DRUID - KEY FEATURES ‣ Column store optimized for

    event data and BI queries ‣ Supports lots of concurrent reads ‣ Streaming data ingestion ‣ Supports extremely fast filters ‣ Ideal for powering user-facing analytic applications
  16. 2015 DRUID ‣ Production ready ‣ Scale • 60+ trillion

    events • Over 3M events/s • 90% of queries < 1 second ‣ Growing Community • 120+ contributors • Many client libraries and UIs: R, Python, Perl, Node.js, Grafana, etc. • Used in production at numerous large and small organizations
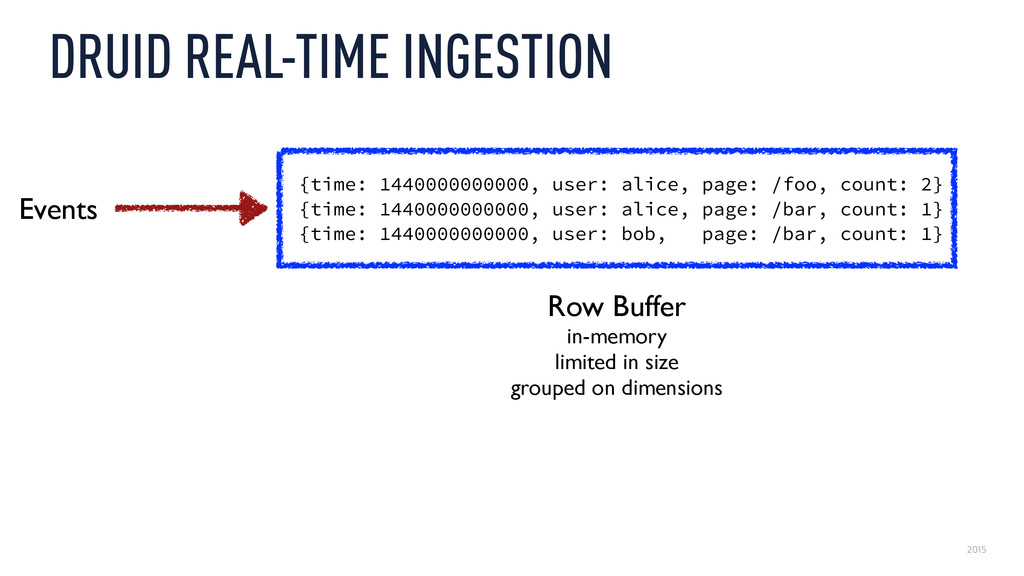
  17. 2015 DRUID REAL-TIME INGESTION {time: 1440000000000, user: alice, page: /foo,

    count: 2} {time: 1440000000000, user: alice, page: /bar, count: 1} {time: 1440000000000, user: bob, page: /bar, count: 1} Row Buffer in-memory limited in size
 grouped on dimensions Events
  18. 2015 DRUID REAL-TIME INGESTION Events [144e10, 144e10, 144e10] [alice, alice,

    bob] [/foo, /bar, /bar] [2, 1, 1] Column Store memory-mapped
 persisted async from row buffer
  19. 2015 DRUID REAL-TIME INGESTION Events [144e10, 144e10, 144e10] [alice, alice,

    bob] [/foo, /bar, /bar] [2, 1, 1] {time: 1450000000000, user: carol, page: /baz, count: 1} Reads use row buffer
 and all column stores
  20. 2015 DRUID REAL-TIME INGESTION [144e10, 144e10, 144e10] [alice, alice, bob]

    [/foo, /bar, /bar] [2, 1, 1] [145e10] [carol] [/baz] [1] Final persist all data now in column stores
  21. 2015 DRUID REAL-TIME INGESTION [144e10, 144e10, 144e10] [alice, alice, bob]

    [/foo, /bar, /bar] [2, 1, 1] [145e10] [carol] [/baz] [1] [144e10, 144e10, 144e10, 145e10] [alice, alice, bob, carol] [/foo, /bar, /bar, /baz] [2, 1, 1, 1] Merge all data in a single segment queried along with all existing data
 target size 500MB–1GB
  22. 2015 LOAD FROM HADOOP [144e10, 144e10, 144e10, 145e10] [alice, alice,

    bob, carol] [/foo, /bar, /bar, /baz] [2, 1, 1, 1] [144e10, 145e10] [carol, dave] [/qux, /baz] [1, 3] DeterminePartitionsJob IndexGeneratorJob Events Hadoop M/R Loader create a set of segments, each 500MB–1GB one reducer creates one segment can replace or append to existing data
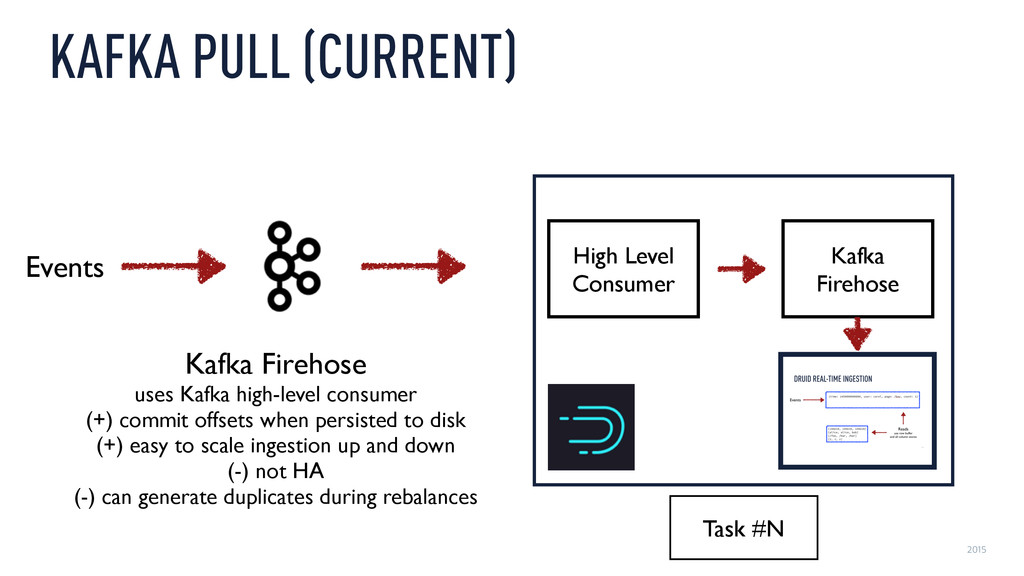
  23. 2015 KAFKA PULL (CURRENT) Kafka Firehose uses Kafka high-level consumer

    (+) commit offsets when persisted to disk (+) easy to scale ingestion up and down (-) not HA (-) can generate duplicates during rebalances High Level Consumer Kafka Firehose Events Task #N
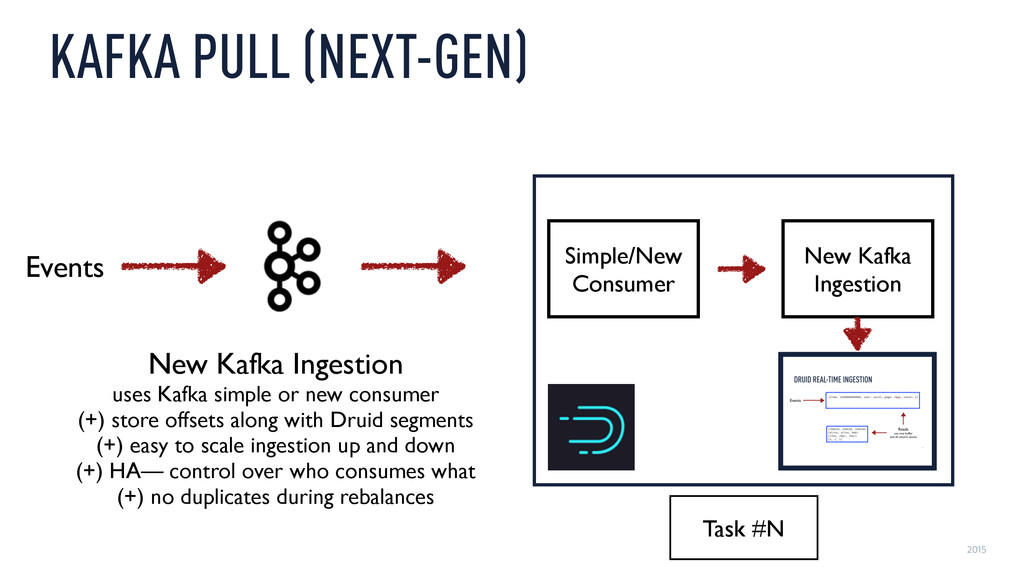
  24. 2015 KAFKA PULL (NEXT-GEN) New Kafka Ingestion uses Kafka simple

    or new consumer (+) store offsets along with Druid segments (+) easy to scale ingestion up and down (+) HA— control over who consumes what (+) no duplicates during rebalances Simple/New Consumer New Kafka Ingestion Events Task #N
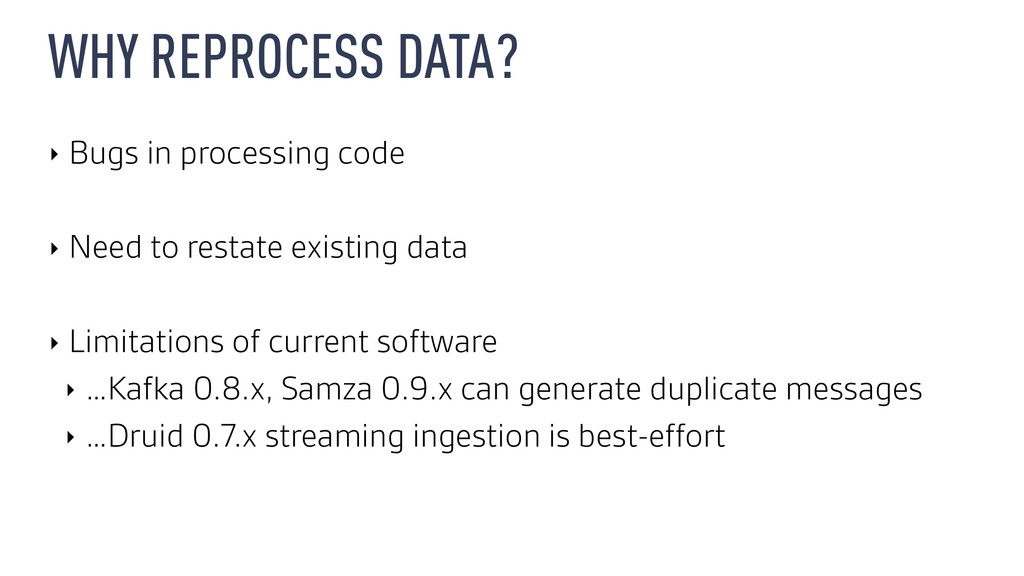
  25. WHY REPROCESS DATA? ‣ Bugs in processing code ‣ Need

    to restate existing data ‣ Limitations of current software ‣ …Kafka 0.8.x, Samza 0.9.x can generate duplicate messages ‣ …Druid 0.7.x streaming ingestion is best-effort
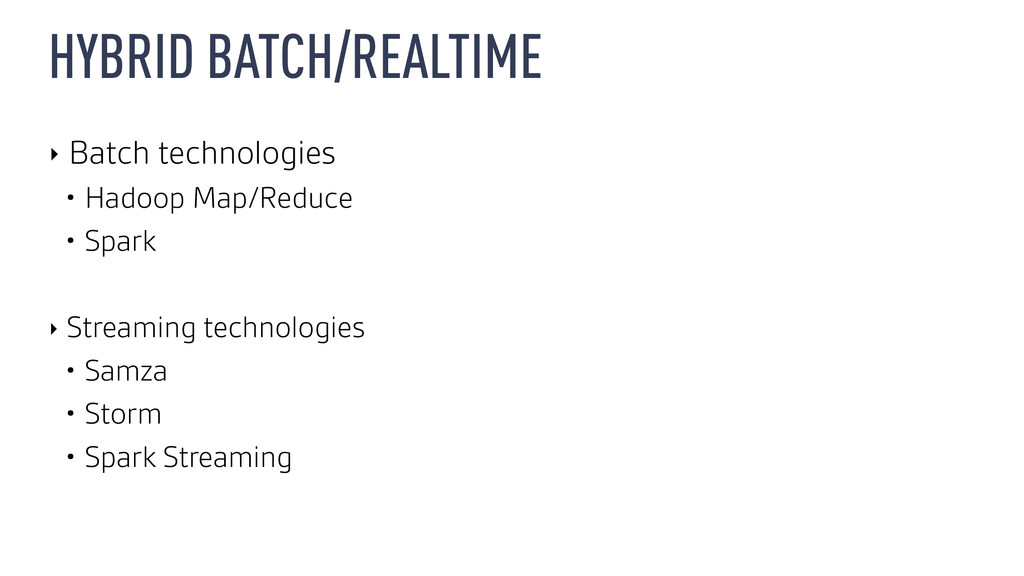
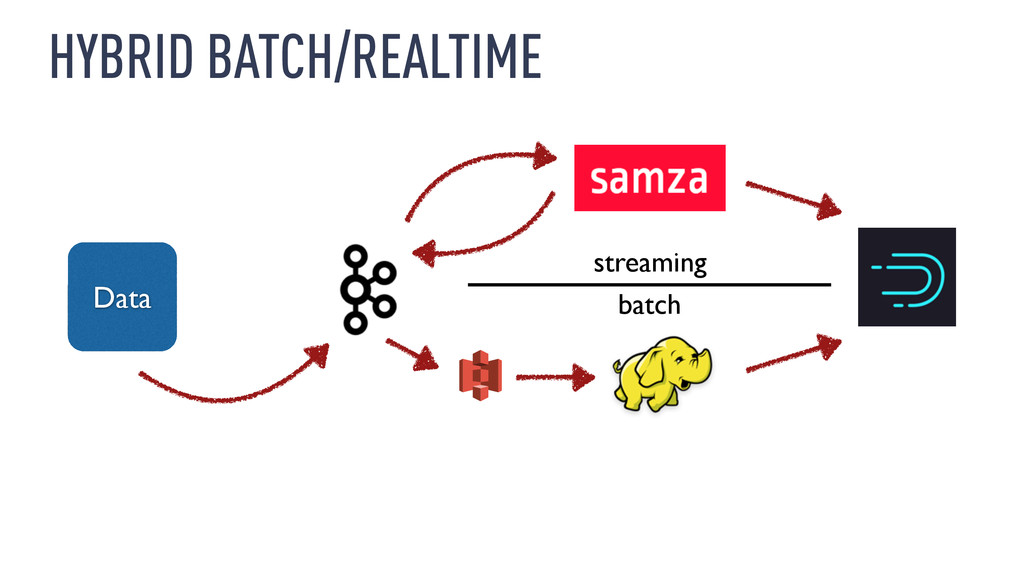
  26. HYBRID BATCH/REALTIME ‣ Batch technologies • Hadoop Map/Reduce • Spark

    ‣ Streaming technologies • Samza • Storm • Spark Streaming
  27. HYBRID BATCH/REALTIME ‣ Advantages? • Works as advertised • Works

    with a huge variety of open software • Druid supports realtime ingest of streams • Druid supports batch replace with Hadoop
  28. KAPPA ARCHITECTURE ‣ Pure streaming ‣ Reprocess data by replaying

    the input stream from the start ‣ Doesn’t require operating two systems ‣ I don’t have much experience with this ‣ http://radar.oreilly.com/2014/07/questioning-the-lambda- architecture.html
  29. 2015 CORNERSTONES ‣ Druid - druid.io - @druidio ‣ Samza

    - samza.apache.org - @samzastream ‣ Kafka - kafka.apache.org - @apachekafka ‣ Hadoop - hadoop.apache.org
  30. TAKE AWAYS ‣ Consider Kafka for making your streams available

    ‣ Consider Samza for streaming data integration ‣ Consider Druid for interactive exploration of streams ‣ Have a reprocessing strategy if you’re interested in historical data

More Decks by Druid

Other Decks in Technology