Share
Embed
Sky - Hadoop & Distributed Computing
Federico Cargnelutti
August 04, 2009
Transcript
25 slides
-
Distributed compu<ng uses so=ware to divide pieces of a
program among several computers. One project in par<cular has proven that the concept works extremely well. -
SETI@Home Search for Extra-‐Terrestrial Intelligence • Prove the
viability of the distributed grid compu<ng concept (succeeded) • Detect intelligent life outside Earth (failed) -
Counts of all the dis6nct word • in a
file? • in a directory? • on the Web? -
We need to process 100TB datasets • On 1
node: o Scanning @ 50MB/s = 23 days • On 1000 node cluster: o Scanning @ 50MB/s = 33 min -
Hadoop is an open-‐source Java framework for running applica<ons
on large clusters of commodity hardware -
Scalable Hadoop can reliably store and process petabytes of
data. Economical Hadoop distributes the data and processing across clusters of commonly available computers. These clusters can number into the thousands of nodes. Efficient Hadoop can process the distributed data in parallel on the nodes where the data is located. Reliable Hadoop automa<cally maintains mul<ple copies of data and automa<cally redeploys compu<ng tasks based on failures. -
Hadoop Components Hadoop Distributed File System (HDFS) •
Java, Shell, C and HTTP API’s Hadoop MapReduce • Java and Streaming API’s Hadoop on Demand • Tools to manage dynamic setup and teardown of Hadoop nodes -
HBase Table storage on top of HDFS, modeled a=er
Google’s Big Table Pig Language for dataflow programming Hive SQL interface to structured data stored in HDFS Other Tools -
• Mappers and Reducers are allocated • Code is
shipped to nodes • Mappers and Reducers are run on same machines as DataNodes • Two major daemons: JobTracker and TaskTracker Hadoop MapReduce -
JobTracker • Long-‐lived master daemon which distributes tasks
• Maintains a job history of job execu<on sta<s<cs TaskTrackers • Long-‐lived client daemon which executes Map and Reduce tasks Hadoop MapReduce -
• Setup a mul<-‐node Hadoop cluster using the Hadoop
Distributed File System (HDFS) • Create a hierarchical HDFS with directories and files. • Use Hadoop API to store a large text file. • Create a MapReduce applica<on. Hadoop MapReduce -
• Mapper takes input key/value pair • Does something
to its input • Emits intermediate key/value pair • One call per input record • Fully data-‐parallel Map -
(in, 1) (in, 1) (sunt, 1)
(in, 1) (elit, 1) (sed, 1) (eiusmod, 1) Map -
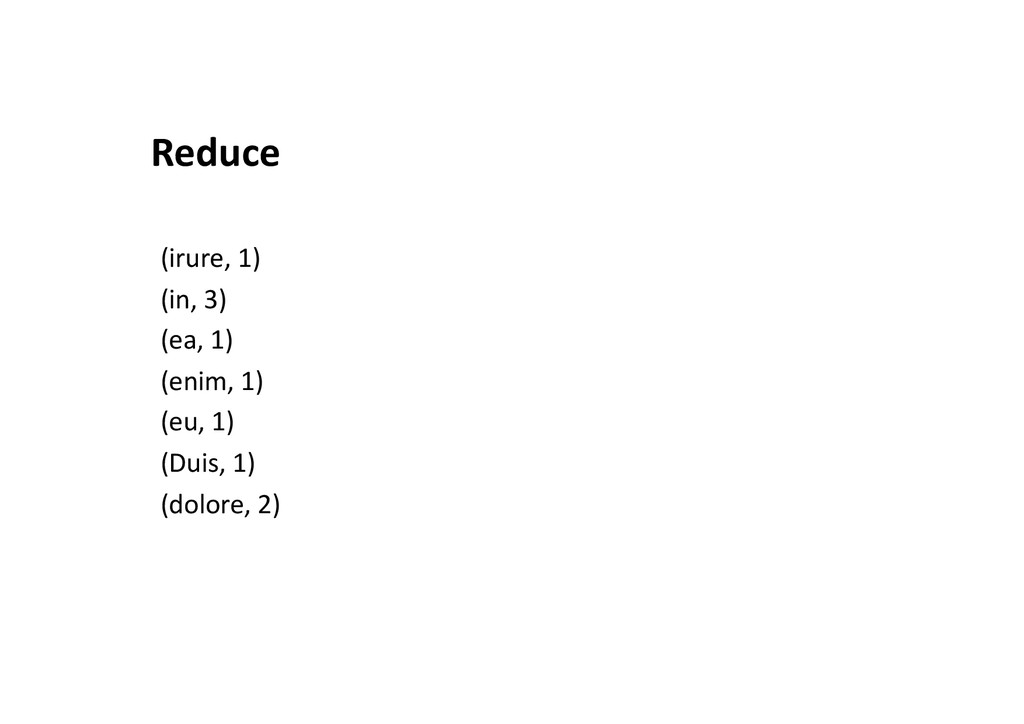
• Input is all list of intermediate values for a
given key • Reducer aggregates list of intermediate values • Returns a final key/value pair for output Reduce -
(irure, 1) (in, 3) (ea, 1)
(enim, 1) (eu, 1) (Duis, 1) (dolore, 2) Reduce Reduce -
Adobe -‐ Use for data storage and processing
-‐ 30 nodes Facebook -‐ Use for repor<ng and analy<cs -‐ 320 nodes FOX -‐ Use for log analysis and data mining -‐ 140 nodes Last.fm -‐ Use for chart calcula<on and log analysis -‐ 27 nodes New York Times -‐ Use for large scale image conversion -‐ 100 nodes Yahoo! -‐ Use for Ad systems and Web search -‐ 10.000 nodes Who is using it? -
• Video and Image processing • Log analysis
• Spam/BOT analysis • Behavioral analy<cs (CRM) • Sequen<al paiern analysis (eg. Understanding long-‐term customer buying behavior for cross selling and target marke<ng) Use Cases -
Commodity servers • 1 RU • 2 x
4 core CPU • 4-‐8GB of RAM using ECC memory • 4 x 1TB SATA drives • 1-‐5TB external storage Typically arranged in 2 level architecture • 30/40 nodes per rack Recommended Hardware -
• No version and dependency management. • Configura<on: more
than 150 parameters. • No security against accidents. User iden<fica<on added a=er Last.fm deleted a fileystem by accident. • HDFS is primarily designed for streaming access of large files. Reading through small files normally causes lots of seeks and lots of hopping from datanode to datanode to retrieve each small file. • Steep learning curve. According to Facebook, using Hadoop was not easy for end users, especially for the ones who were not familiar with MapReduce. Challenges