Upgrade to Pro — share decks privately, control downloads, hide ads and more …

Big Data Computation Architecture

Big Data Computation Architecture

It talks about the evolution of big data computation architecture

Gang Tao

May 10, 2016

Transcript

38 slides
  1. Hadoop the Limitation • Map/Reduce is hard to use •

    Latency is high • inevitable data movement
  2. Design Principle human fault-tolerance – the system is unsusceptible to

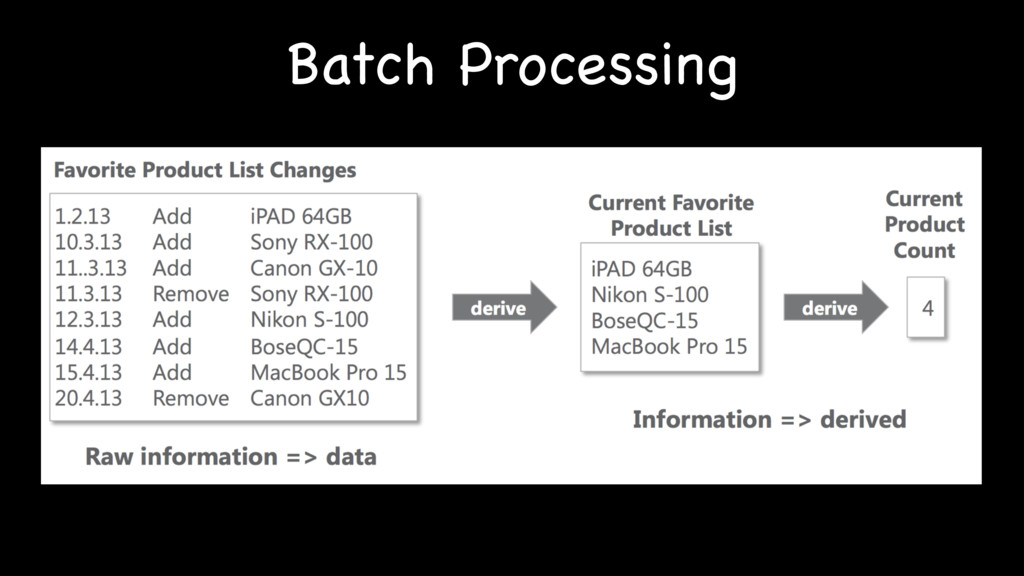
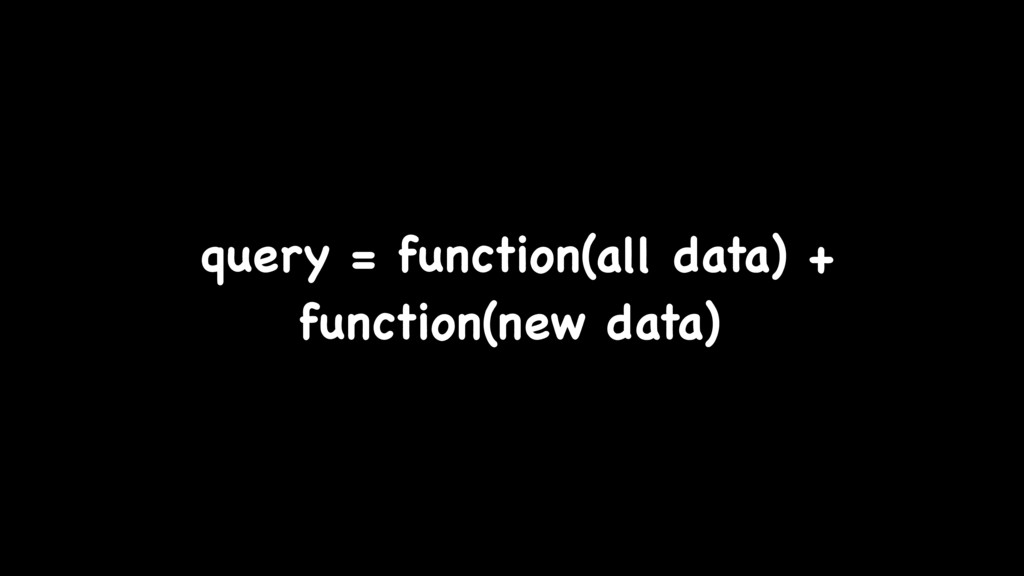
    data loss or data corruption because at scale it could be irreparable. data immutability – store data in it’s rawest form immutable and for perpetuity. (INSERT/ SELECT/DELETE but no UPDATE !) recomputation – with the two principles above it is always possible to (re)-compute results by running a function on the raw data.
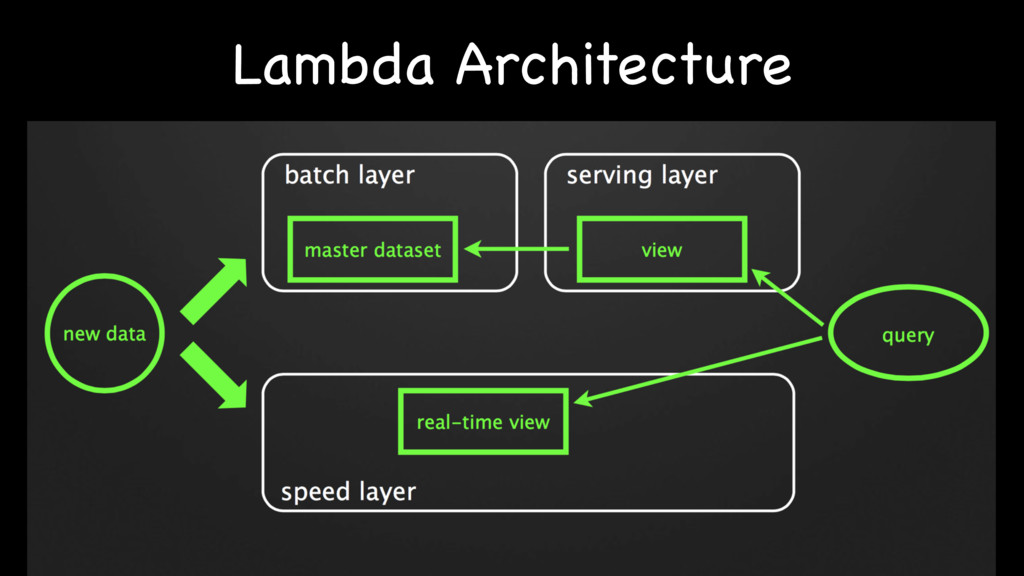
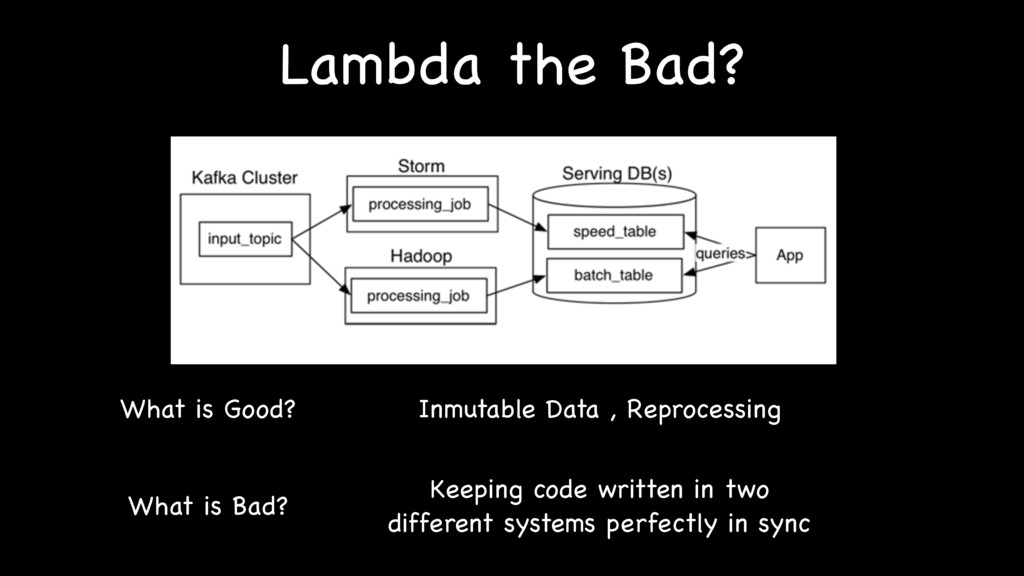
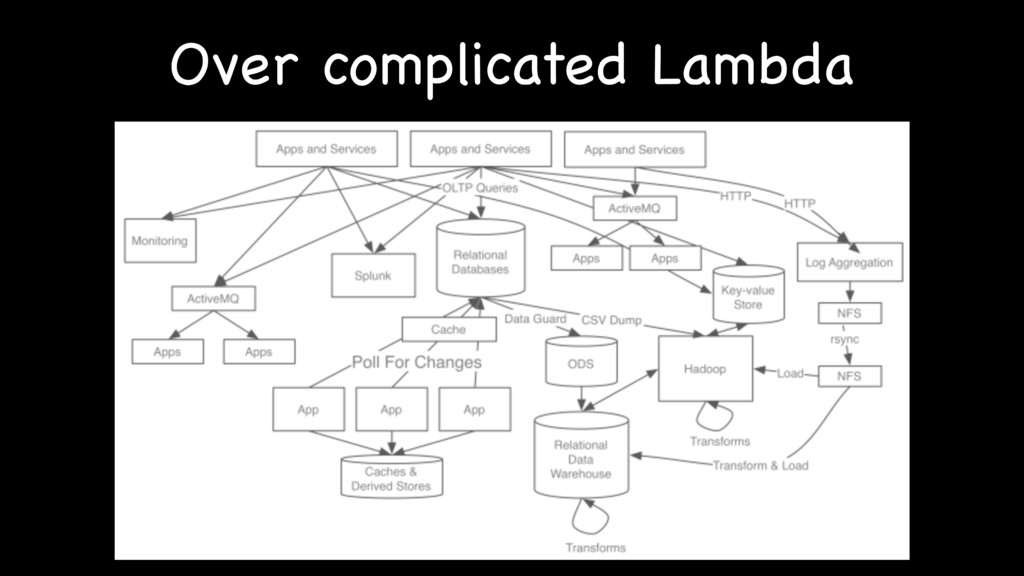
  3. Lambda the Bad? What is Good? What is Bad? Inmutable

    Data , Reprocessing Keeping code written in two different systems perfectly in sync
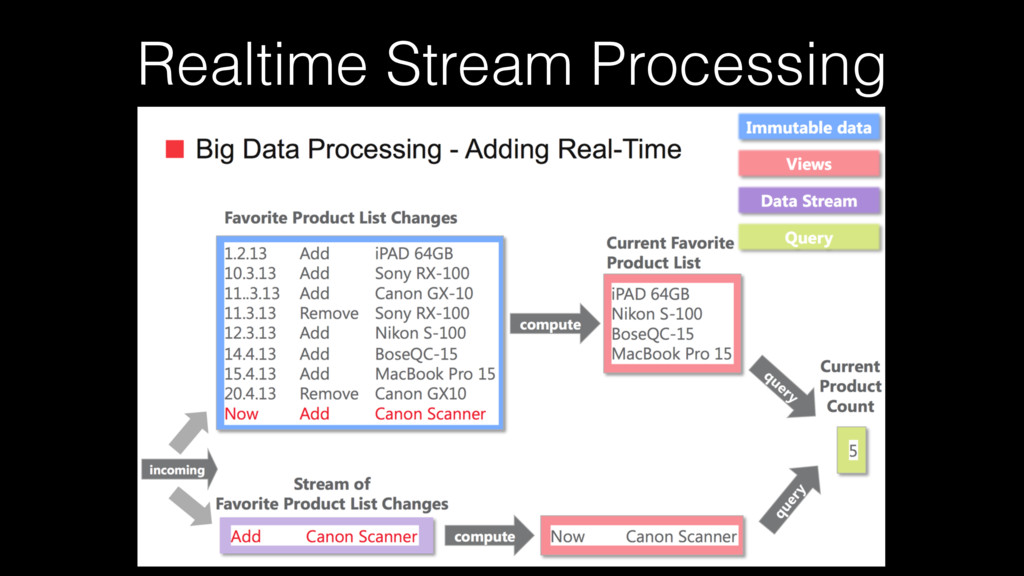
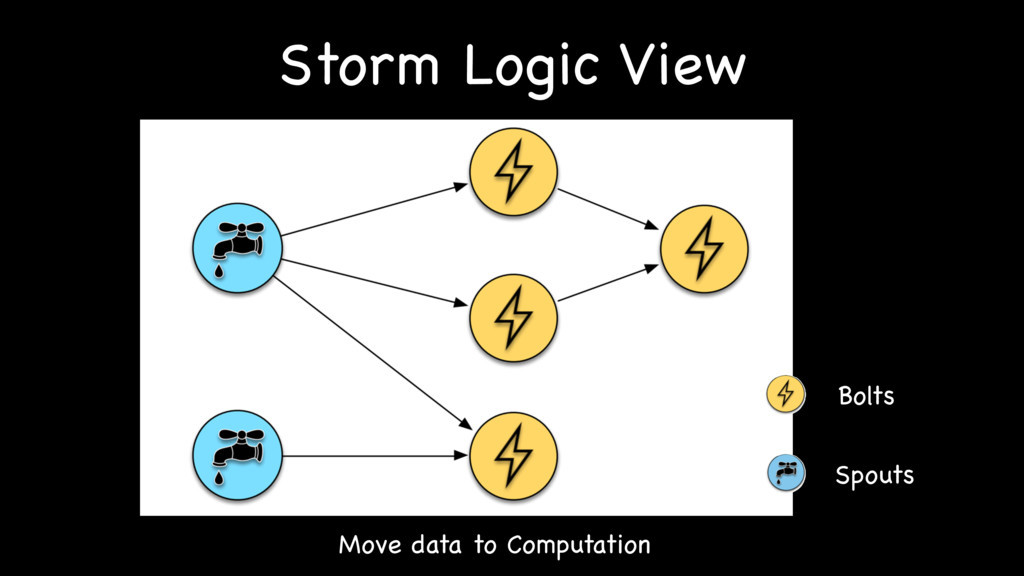
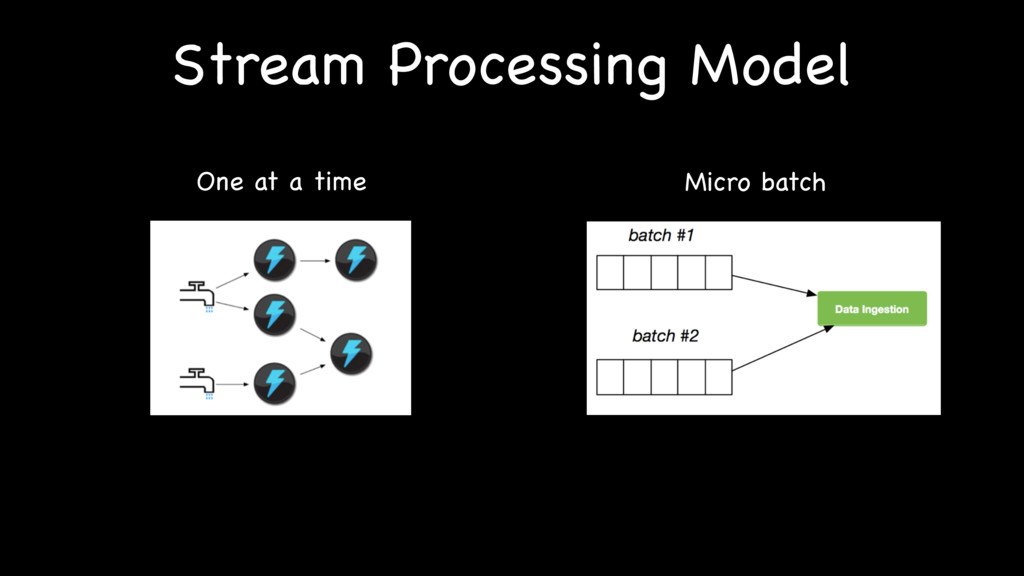
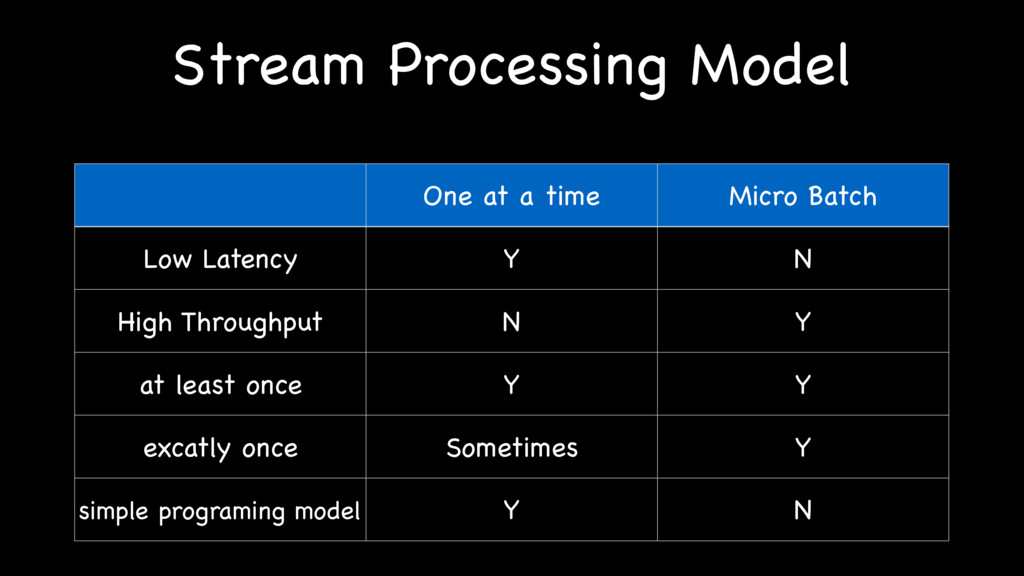
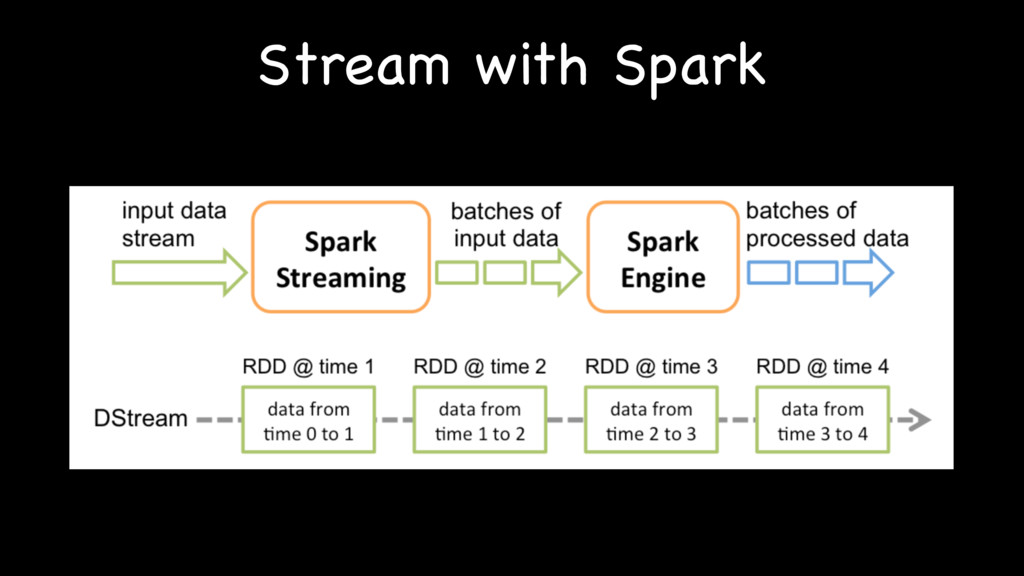
  4. Stream Processing Model One at a time Micro Batch Low
    Latency Y N High Throughput N Y at least once Y Y excatly once Sometimes Y simple programing model Y N
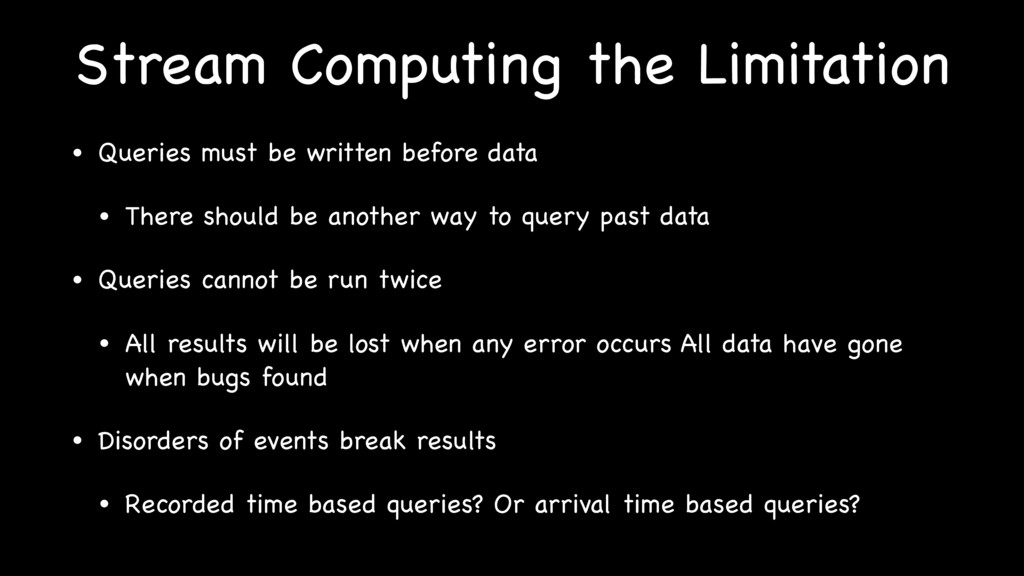
  5. Stream Computing the Limitation • Queries must be written before

    data • There should be another way to query past data • Queries cannot be run twice • All results will be lost when any error occurs All data have gone when bugs found • Disorders of events break results • Recorded time based queries? Or arrival time based queries?
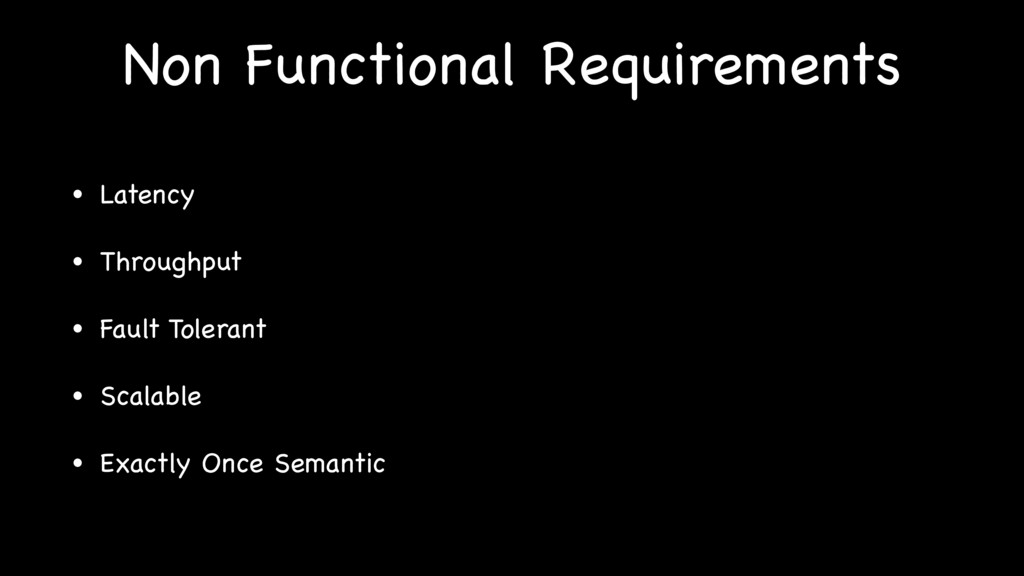
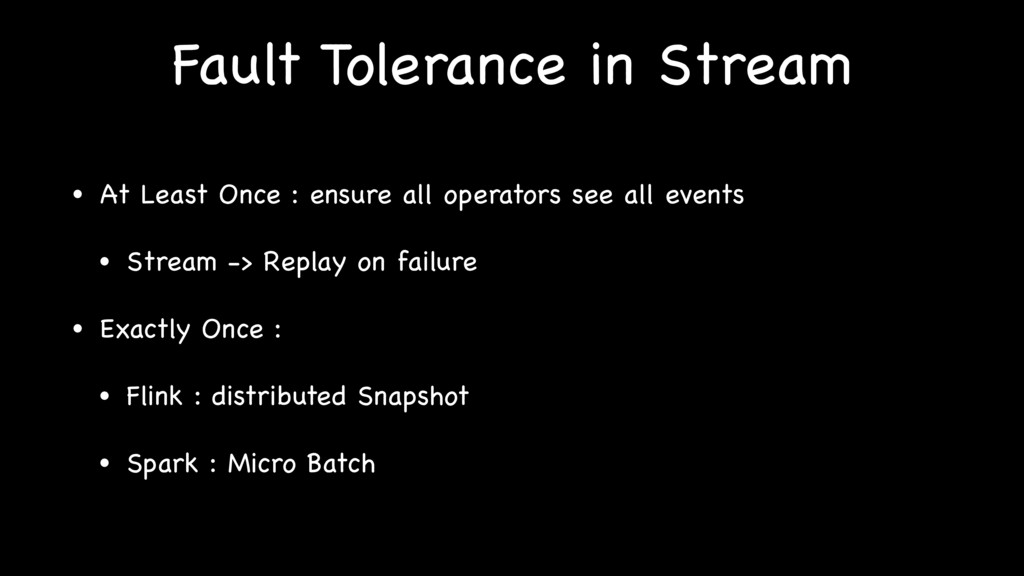
  6. Fault Tolerance in Stream • At Least Once : ensure

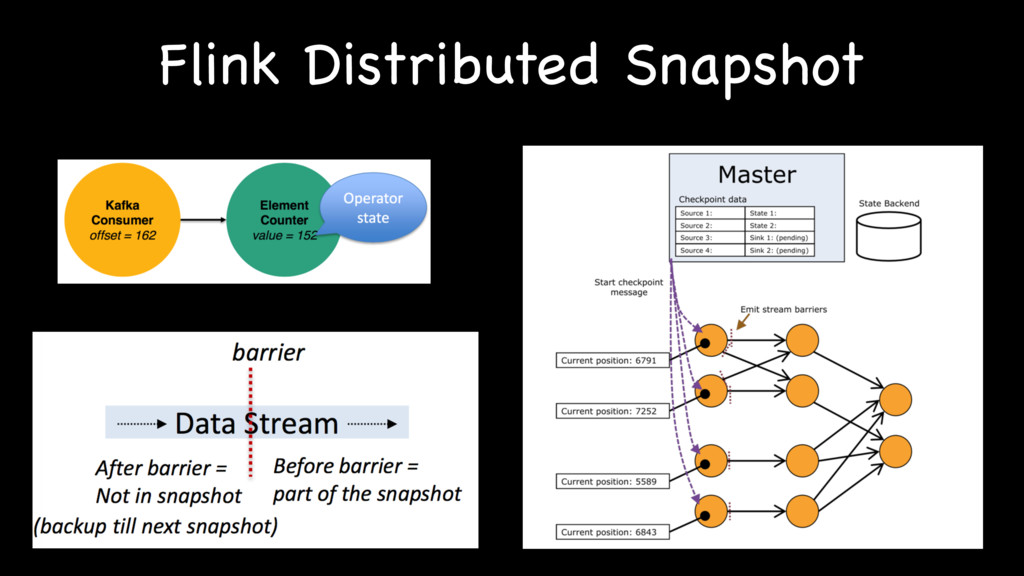
    all operators see all events • Stream -> Replay on failure • Exactly Once : • Flink : distributed Snapshot • Spark : Micro Batch

More Decks by Gang Tao

Other Decks in Technology