Share
Embed

Transcript
17 slides
-
Scaling Up Subset Selection and the Microbiome Gregory Ditzler Drexel
University Dept. of Electrical & Computer Engineering [email protected] http://gregoryditzler.com http://gitbub.com/gditzler -
central research themes & overview • Subset selection and why
big data is a problem - What does big data mean for the future of machine learning? - Scalability is extremely important! • How can we help the life sciences? - What is it and how can we reduce is affects? • Where are the open problems? - Where are the applications? - What are the fundamental challenges we still face? http://venturebeat.files.wordpress.com/2012/01/big-data.jpg -
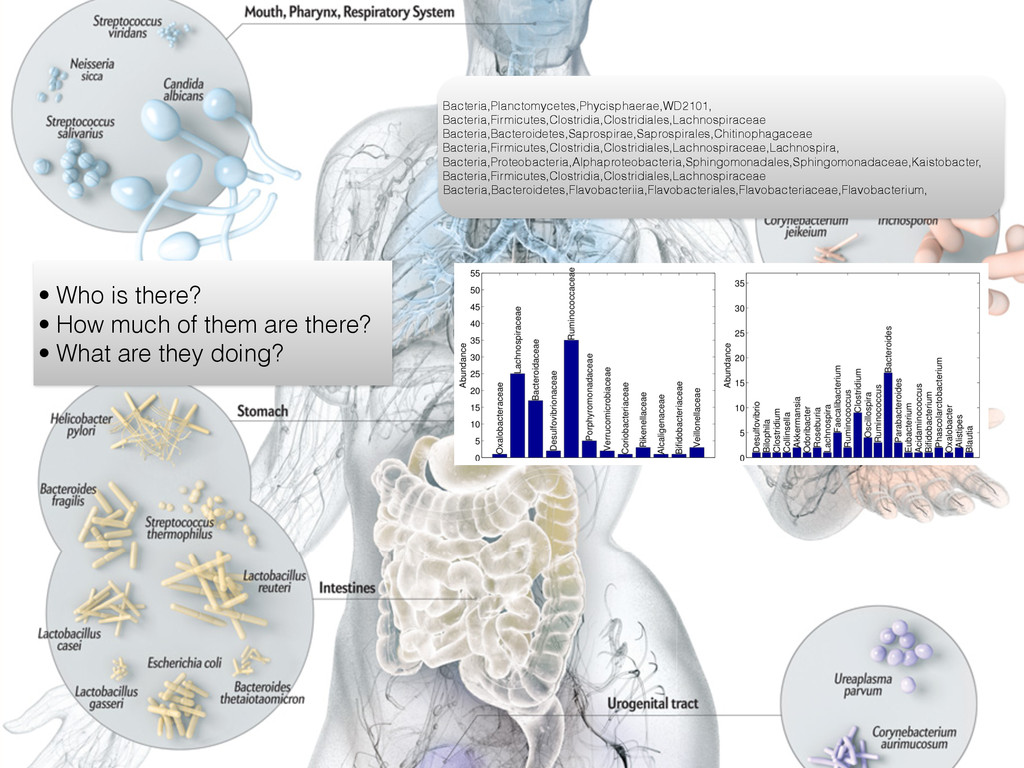
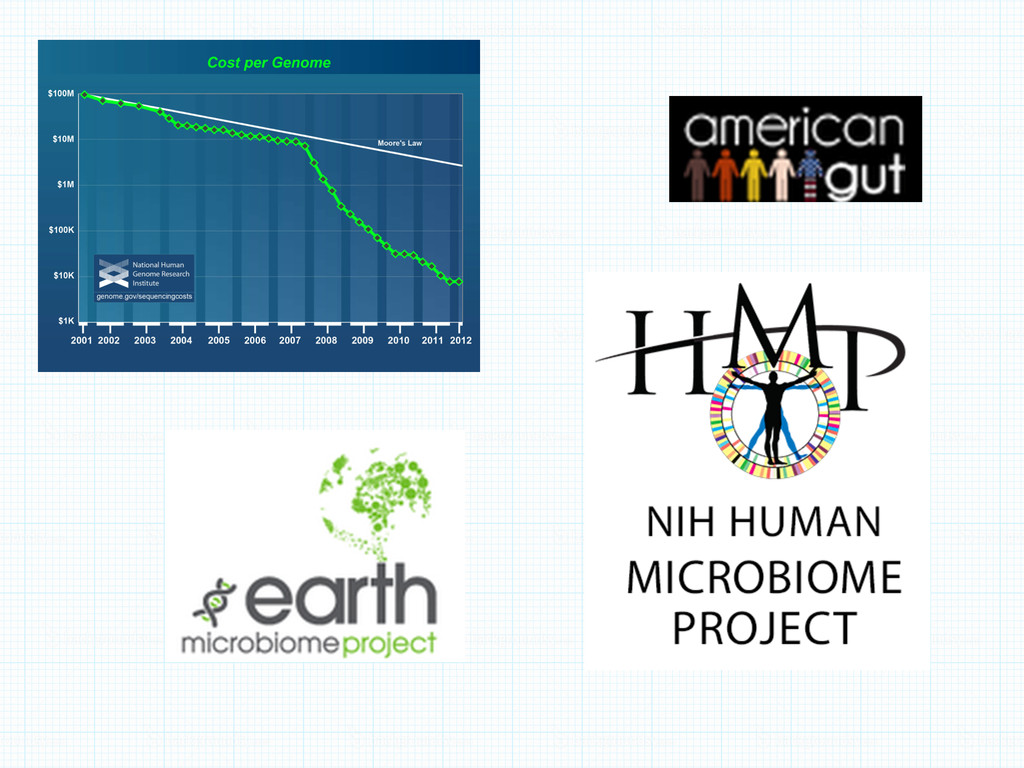
• Who is there? • How much of them are
there? • What are they doing? Bacteria,Planctomycetes,Phycisphaerae,WD2101, Bacteria,Firmicutes,Clostridia,Clostridiales,Lachnospiraceae Bacteria,Bacteroidetes,Saprospirae,Saprospirales,Chitinophagaceae Bacteria,Firmicutes,Clostridia,Clostridiales,Lachnospiraceae,Lachnospira, Bacteria,Proteobacteria,Alphaproteobacteria,Sphingomonadales,Sphingomonadaceae,Kaistobacter, Bacteria,Firmicutes,Clostridia,Clostridiales,Lachnospiraceae Bacteria,Bacteroidetes,Flavobacteriia,Flavobacteriales,Flavobacteriaceae,Flavobacterium, -
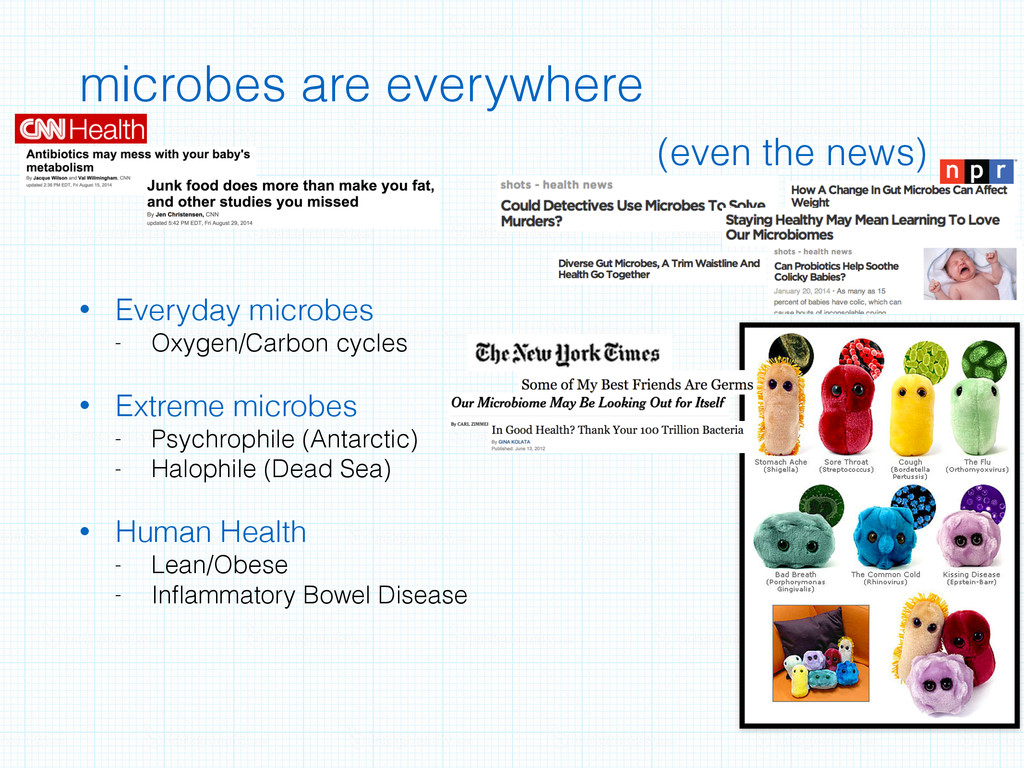
microbes are everywhere • Everyday microbes - Oxygen/Carbon cycles •
Extreme microbes - Psychrophile (Antarctic) - Halophile (Dead Sea) • Human Health - Lean/Obese - Inflammatory Bowel Disease (even the news) -
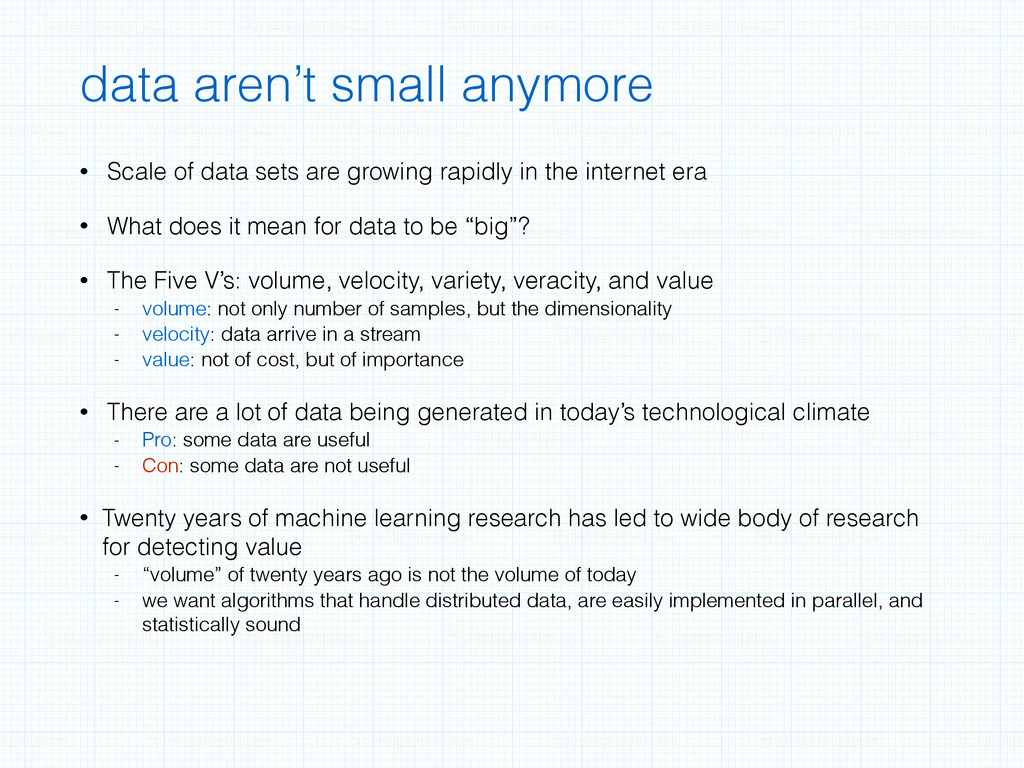
data aren’t small anymore • Scale of data sets are
growing rapidly in the internet era • What does it mean for data to be “big”? • The Five V’s: volume, velocity, variety, veracity, and value - volume: not only number of samples, but the dimensionality - velocity: data arrive in a stream - value: not of cost, but of importance • There are a lot of data being generated in today’s technological climate - Pro: some data are useful - Con: some data are not useful • Twenty years of machine learning research has led to wide body of research for detecting value - “volume” of twenty years ago is not the volume of today - we want algorithms that handle distributed data, are easily implemented in parallel, and statistically sound -
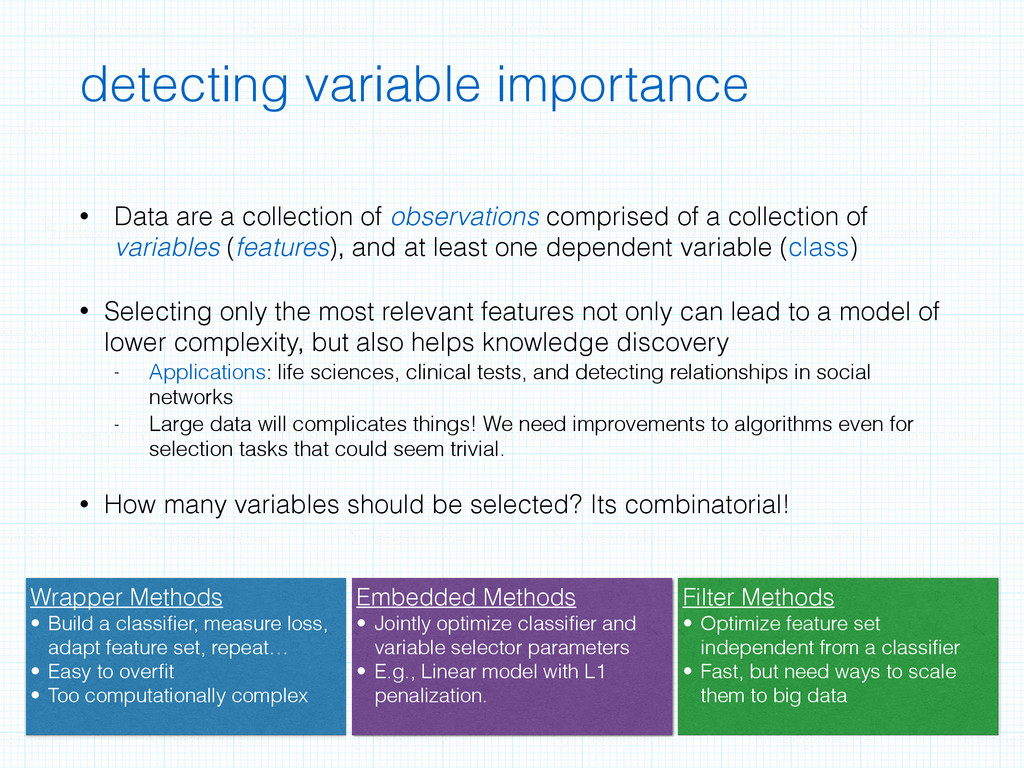
detecting variable importance • Data are a collection of observations
comprised of a collection of variables (features), and at least one dependent variable (class) • Selecting only the most relevant features not only can lead to a model of lower complexity, but also helps knowledge discovery - Applications: life sciences, clinical tests, and detecting relationships in social networks - Large data will complicates things! We need improvements to algorithms even for selection tasks that could seem trivial. • How many variables should be selected? Its combinatorial! Wrapper Methods • Build a classifier, measure loss, adapt feature set, repeat… • Easy to overfit • Too computationally complex Embedded Methods • Jointly optimize classifier and variable selector parameters • E.g., Linear model with L1 penalization. Filter Methods • Optimize feature set independent from a classifier • Fast, but need ways to scale them to big data -
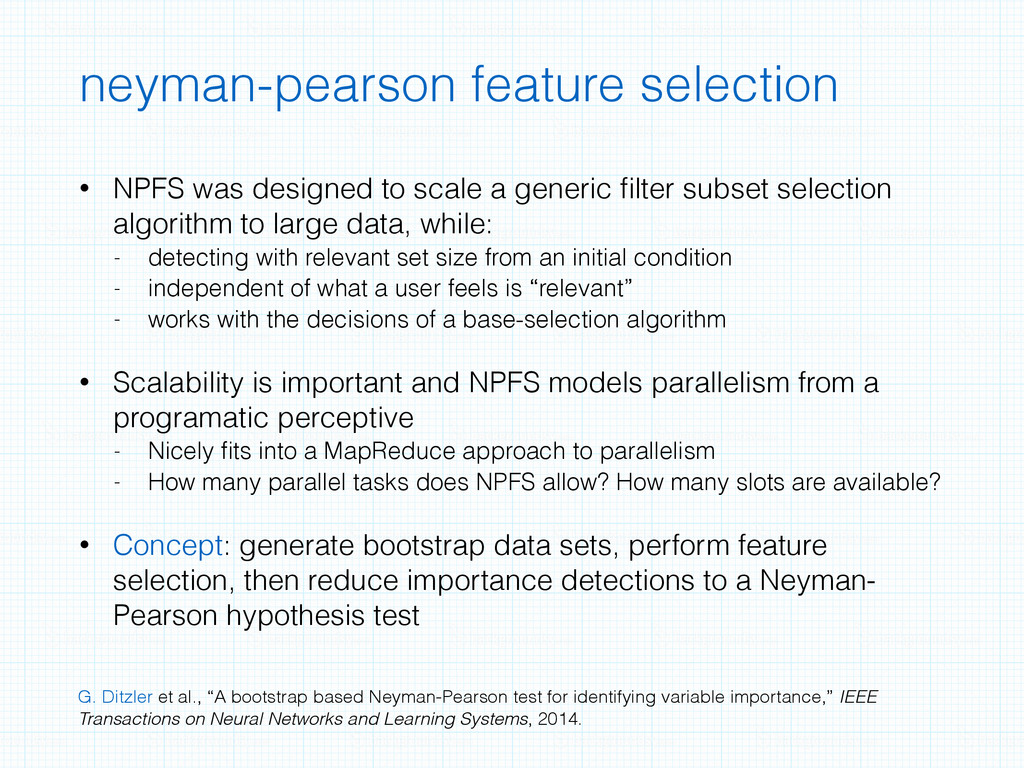
neyman-pearson feature selection • NPFS was designed to scale a
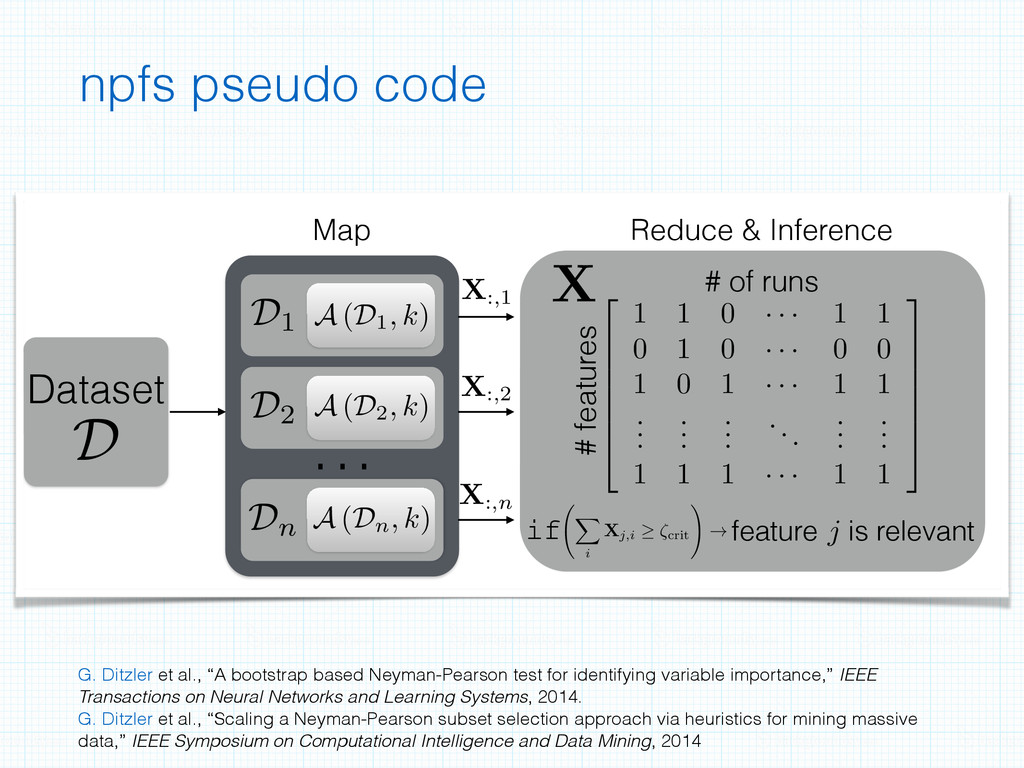
generic filter subset selection algorithm to large data, while: - detecting with relevant set size from an initial condition - independent of what a user feels is “relevant” - works with the decisions of a base-selection algorithm • Scalability is important and NPFS models parallelism from a programatic perceptive - Nicely fits into a MapReduce approach to parallelism - How many parallel tasks does NPFS allow? How many slots are available? • Concept: generate bootstrap data sets, perform feature selection, then reduce importance detections to a Neyman- Pearson hypothesis test G. Ditzler et al., “A bootstrap based Neyman-Pearson test for identifying variable importance,” IEEE Transactions on Neural Networks and Learning Systems, 2014. -
npfs pseudo code G. Ditzler et al., “A bootstrap based
Neyman-Pearson test for identifying variable importance,” IEEE Transactions on Neural Networks and Learning Systems, 2014. G. Ditzler et al., “Scaling a Neyman-Pearson subset selection approach via heuristics for mining massive data,” IEEE Symposium on Computational Intelligence and Data Mining, 2014 D Dataset Map D1 D2 Dn A (Dn, k) A (D2, k) A (D1, k) X:,2 X:,1 X:,n … 2 6 6 6 6 6 4 1 1 0 · · · 1 1 0 1 0 · · · 0 0 1 0 1 · · · 1 1 . . . . . . . . . ... . . . . . . 1 1 1 · · · 1 1 3 7 7 7 7 7 5 # features # of runs Reduce & Inference X i Xj,i ⇣crit ! ! if feature is relevant j X -
npfs results 20 40 60 80 100 5 10 15
20 25 bootstrap feature 20 40 60 80 100 5 10 15 20 25 bootstrap feature 20 40 60 80 100 5 10 15 20 25 bootstrap feature 20 40 60 80 100 5 10 15 20 25 bootstrap feature select 10 select 15 select 24 select 20 25 features with only 5 being relevant white: selected by base black: not selected orange: NPFS detection 0 20 40 60 80 100 0.4 0.5 0.6 0.7 0.8 0.9 1 data processed (GB) stability Jaccard Lustgarten 0 1 2 0.4 0.6 0.8 1 100 200 300 400 500 600 0 100 200 300 400 500 600 data processed (MB) runtime (sec) LASSO NPFS 20 40 60 80 100 120 10 20 30 40 data processed (GB) runtime (min) NPFS NPFS on 120GB+ • NPFS streamlines parallelization while keeping statistical rigor • Scales well to massive sets of observations represented in a high dimensional space • Provides improvements to classification accuracy on UCI • Open-source implementations are available in Python & Matlab G. Ditzler, R. Polikar, and G. Rosen, “A bootstrap based Neyman-Pearson test for identifying variable importance,” IEEE Transactions on Neural Networks and Learning Systems, 2014. G. Ditzler, M. Austen, G. Rosen, and R. Polikar, “Scaling a Neyman-Pearson subset selection approach via heuristics for mining massive data,” IEEE Symposium on Computational Intelligence and Data Mining, 2014 -
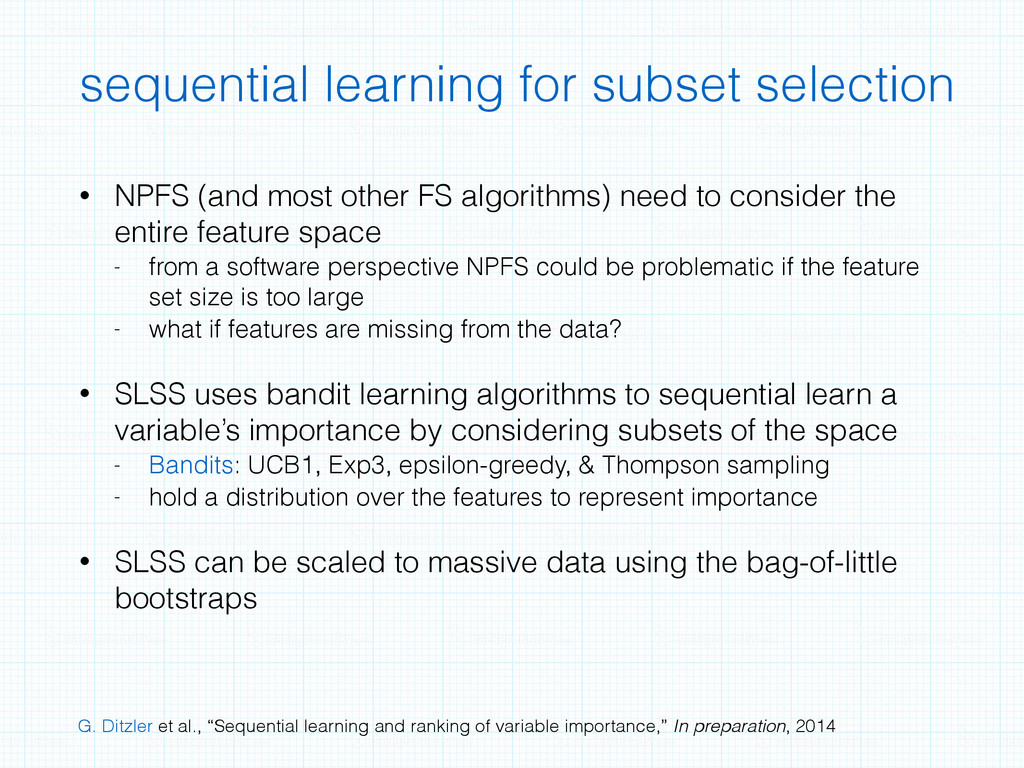
sequential learning for subset selection • NPFS (and most other
FS algorithms) need to consider the entire feature space - from a software perspective NPFS could be problematic if the feature set size is too large - what if features are missing from the data? • SLSS uses bandit learning algorithms to sequential learn a variable’s importance by considering subsets of the space - Bandits: UCB1, Exp3, epsilon-greedy, & Thompson sampling - hold a distribution over the features to represent importance • SLSS can be scaled to massive data using the bag-of-little bootstraps G. Ditzler et al., “Sequential learning and ranking of variable importance,” In preparation, 2014 -
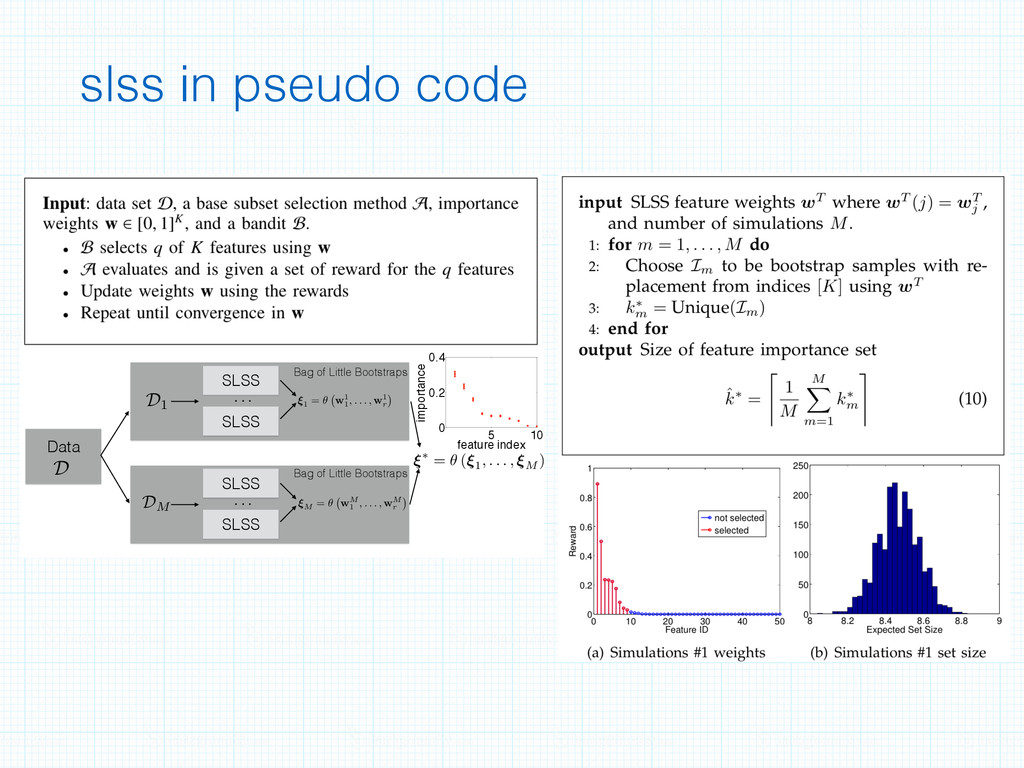
slss in pseudo code Data D w(1) SLSS SLSS .
. . D1 ⇠1 = ✓ w1 1 , . . . , w1 r ⇠⇤ = ✓ (⇠1 , . . . , ⇠M ) SLSS SLSS . . . ⇠M = ✓ wM 1 , . . . , wM r DM Bag of Little Bootstraps Bag of Little Bootstraps 5 10 0 0.2 0.4 feature index importance -
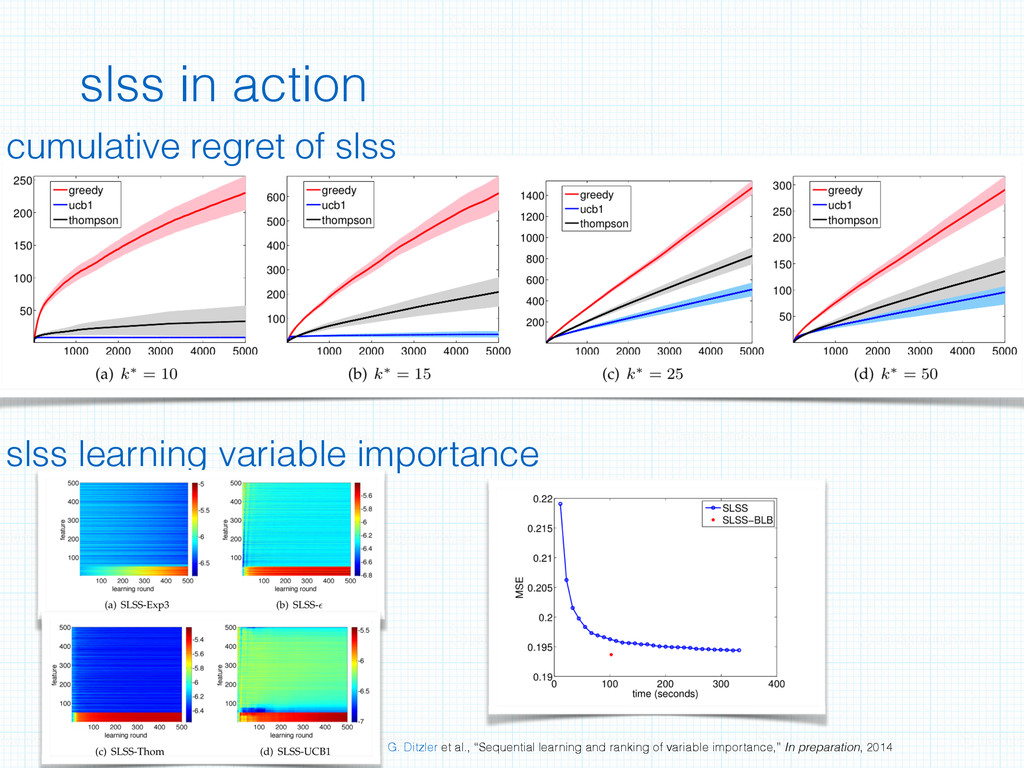
slss in action cumulative regret of slss slss learning variable
importance G. Ditzler et al., “Sequential learning and ranking of variable importance,” In preparation, 2014 -
ibd & obesity • ABC transporter is known to mediate
fatty acid transport that is associated with obesity and insulin resistant states • ATPases catalyze dephosphorylation reactions to release energy • Glycosyl transferase is hypothesized to result in recruitment of bacteria to the gut mucosa and increased inflammation G. Ditzler et al., “Feature selection for metagenomic data analysis,” Encyclopedia of Metagenomics, 2014. G. Ditzler et al., “Fizzy: Feature Selection for Metagenomics,” In preparation, 2014. -
conclusions & future work Conclusions • Scalable Machine Learning is
of Utmost Importance - NPFS & SLSS are scalable to large data sets, and have served the microbial ecology community through open-source implementations - The fields of life science are generating a tremendous amount of data and need help from the fields of computational science for analysis Future Work • Advanced Frameworks for Big Data Subset Selection - CIM recently published a special issue on Big Data and the curse of big dimensionality - Millions of features & beyond while being mindful of veracity - Migrating from a batch-based learning setting to a pure online setting with non-linear selection techniques • Calibrated Prediction for Domain Adaptation in Time-Series - Tuning model parameters in changing domains using unlabeled data (inspired by Ditzler et al., 2014-IJCNN), and accessing the stability of predictions in uncertain environments G. Ditzler et al., “Domain adaptation bounds for multiple expert systems under concept drift,” in International Joint Conference on Neural Networks, Beijing, China, 2014. (Best Paper Award) -
my fantastic collaborators Gail Rosen (Drexel) Calvin Morrison (Temple) Erin
Reichenberger (Drexel) Diamantino Caseiro (Google) Robi Polikar (Rowan) Steve Essinger (Pandora) Yemin Lan (Drexel) Steve Pastor (Drexel) Steve Woloszynek (Drexel)
 gditzler
 addyosmani
 letsgokoyo
 malarkey
 maggiecrowley
 matthewcrist
 akihiro_kokubo
 bluesmoon
 cassininazir
 tamaranovitovic
 axbom
 raygrieselhuber
 aki_iinuma