Share
Embed
Big Data with Arrow and DuckDB
Approaches to bigger-than-RAM data in R, using Arrow, DuckDB, and a bit of data.table. Presented at R/Medicine 2022
Peter Higgins
August 26, 2022
Transcript
39 slides
-
Using the {arrow} and {duckdb} packages to wrangle Bigger-Than-RAM Medical
Datasets of > 60M rows Peter D.R. Higgins, MD, PhD, MSc (CRDSA) University of Michigan -
Agenda • The motivating problem • Limits of R in
speed and RAM • Arrow • DuckDB • Wrangling very large data -
Starting Point • I usually analyze small-ish datasets • Carefully
collected and validated data • 500-1000 rows • 10,000 rows on a big project • But digital data – from CMS or Clinical Data Warehouses can give us MUCH bigger data • > 100M rows easily, often > 50GB – does not fit in an email… • This does not always work well in R -
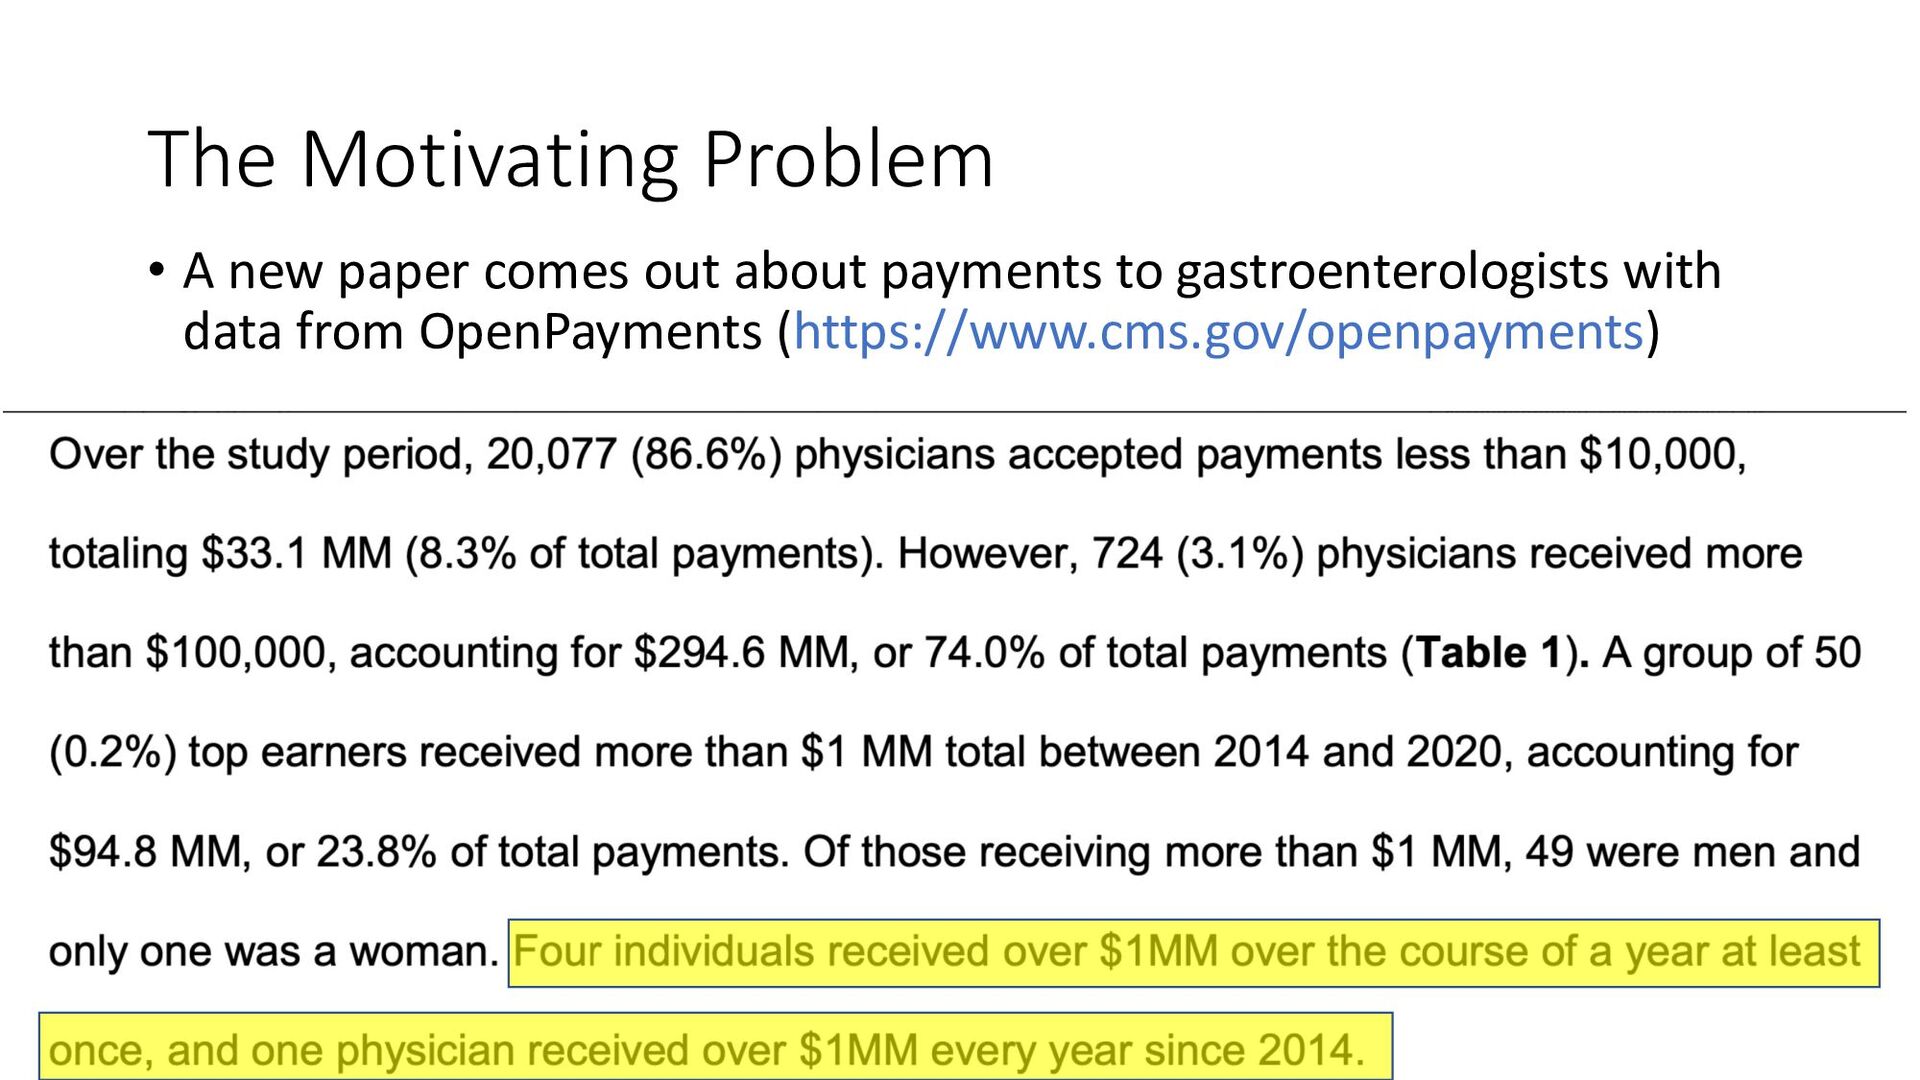
The Motivating Problem • A new paper comes out about
payments to gastroenterologists with data from OpenPayments (https://www.cms.gov/openpayments) -
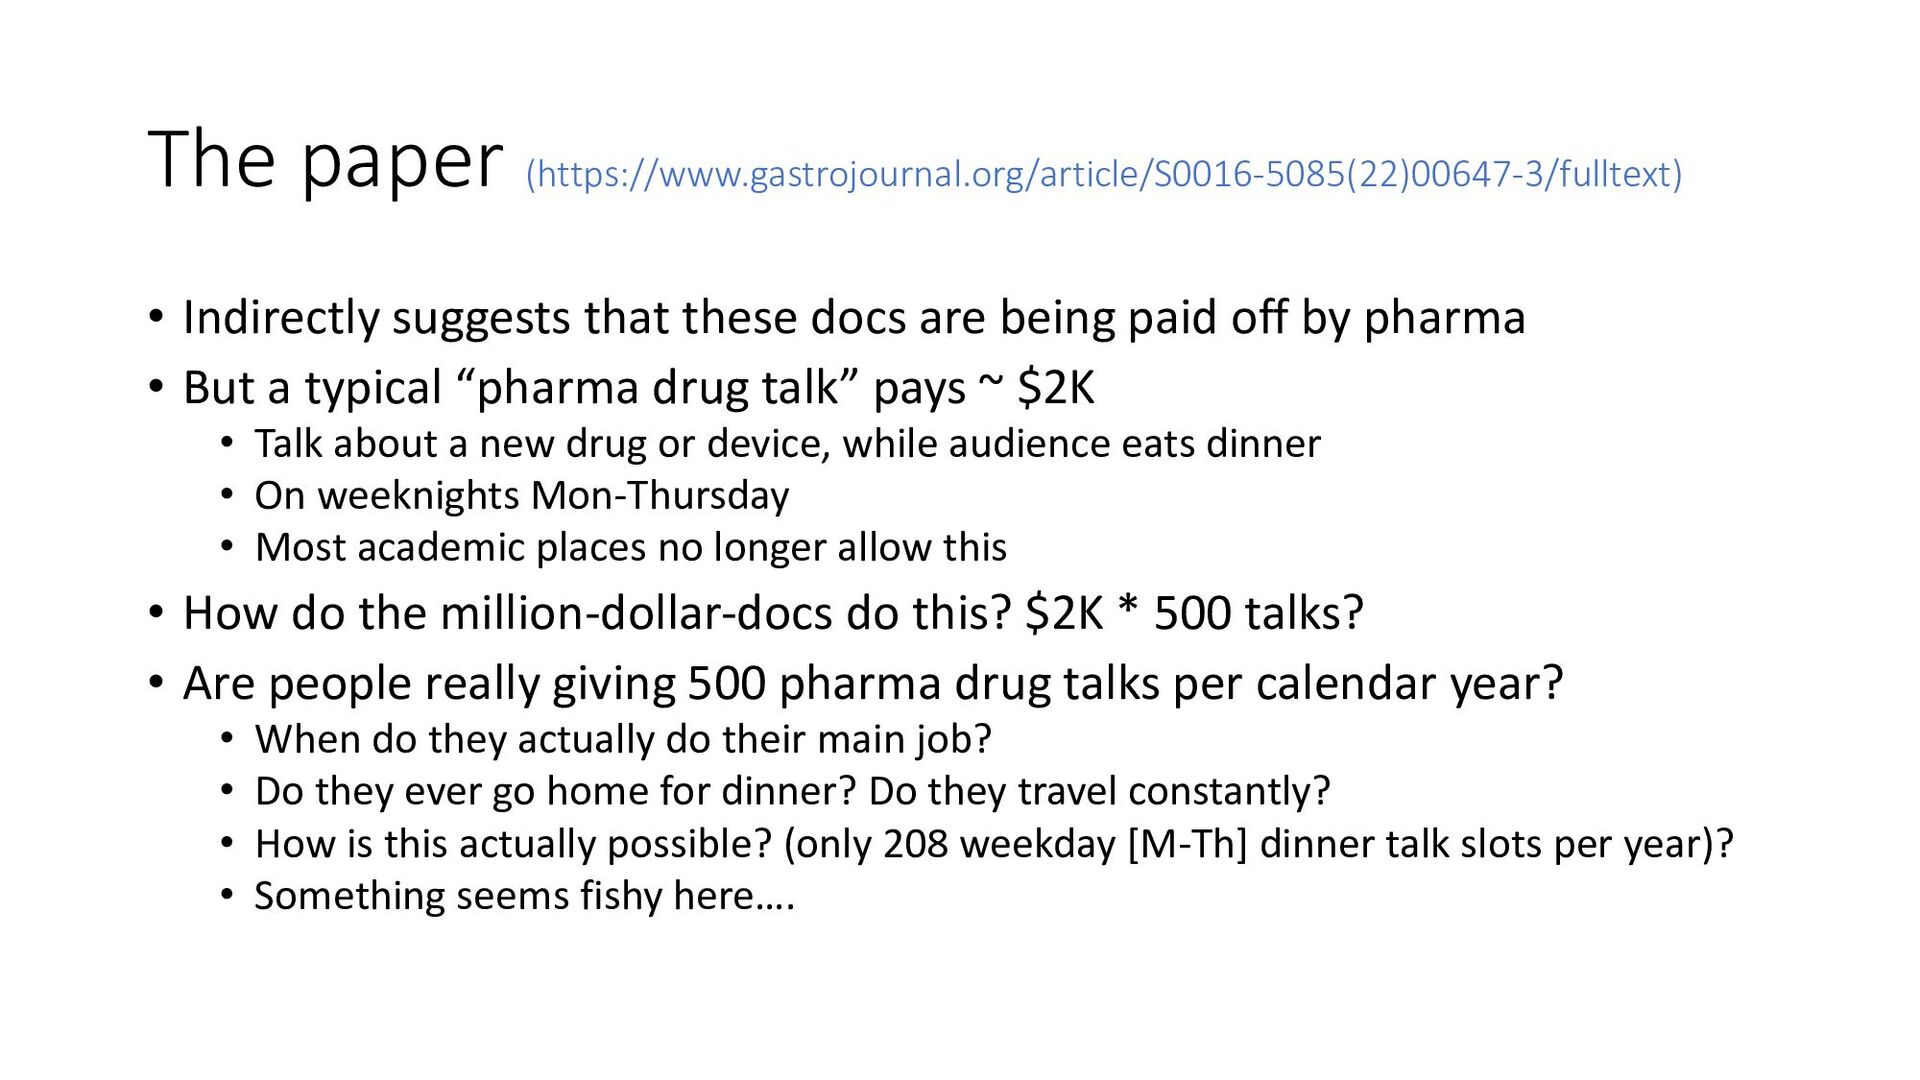
The paper (https://www.gastrojournal.org/article/S0016-5085(22)00647-3/fulltext) • Indirectly suggests that these docs are
being paid off by pharma • But a typical “pharma drug talk” pays ~ $2K • Talk about a new drug or device, while audience eats dinner • On weeknights Mon-Thursday • Most academic places no longer allow this • How do the million-dollar-docs do this? $2K * 500 talks? • Are people really giving 500 pharma drug talks per calendar year? • When do they actually do their main job? • Do they ever go home for dinner? Do they travel constantly? • How is this actually possible? (only 208 weekday [M-Th] dinner talk slots per year)? • Something seems fishy here…. -
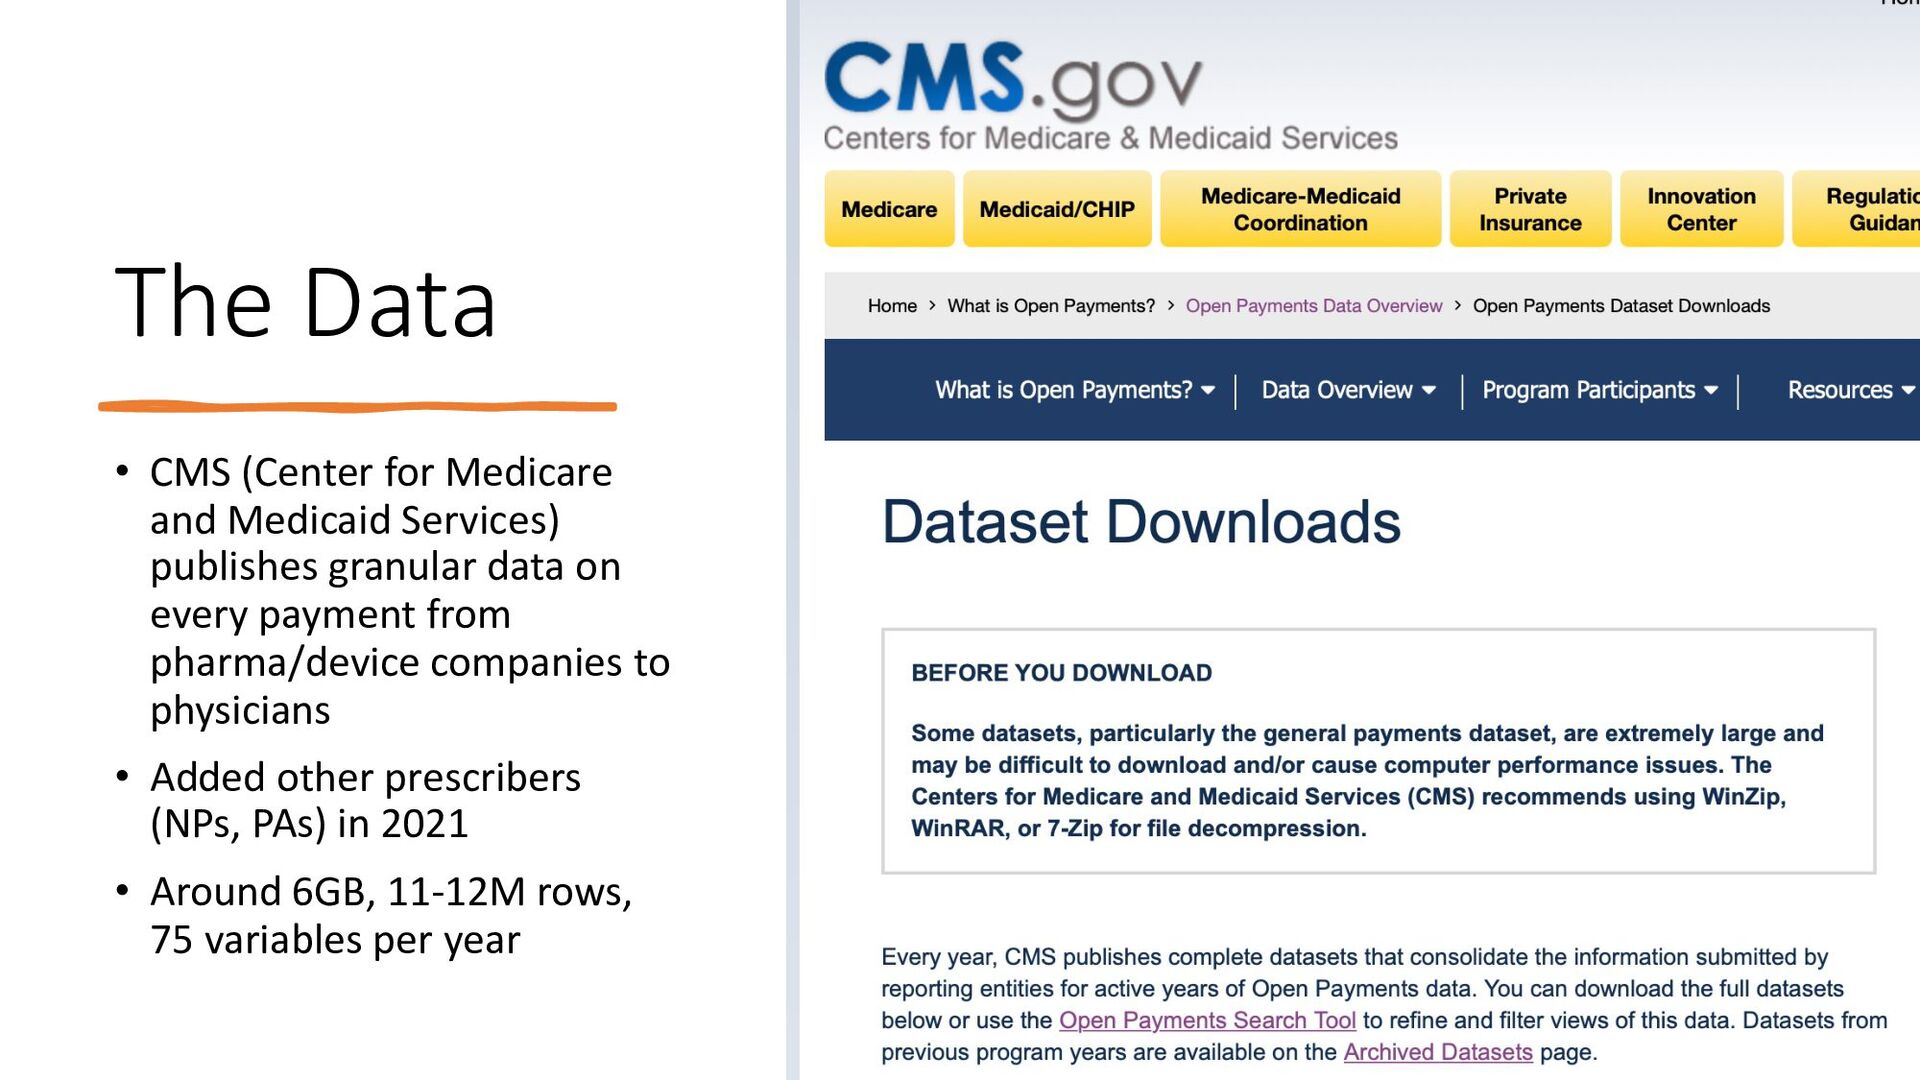
The Data • CMS (Center for Medicare and Medicaid Services)
publishes granular data on every payment from pharma/device companies to physicians • Added other prescribers (NPs, PAs) in 2021 • Around 6GB, 11-12M rows, 75 variables per year -
The Motivating Problem • My M1 Mac Mini has 16
GB of RAM • Total data on CMS website from 2013-2021 is 94 GB • Format, # of variables changed in 2016, so will ignore 2013-15 • R works on datasets in memory (RAM) -
Options • Work on 1 year at a time, extract
summary data, then pool across years • Slow, clunky • Find a better way -
First pilot attempts • Read in one year of data
(2016) • 11 million rows, 75 variables • Only 6.4 GB • Should work, might be a little slow… • readr::read_csv() is 2-3x faster than read.csv() – let’s use read_csv() • Using read_csv() – 2873.7 seconds ~ 49 minutes – not good • Now I have 2 problems • Speed • RAM capacity -
Speed-reading • Option 1 – the fread() function from {data.table}
• data.table::fread() on 2014 data – 93.3 seconds • MUCH better • 30x speed improvement! • Option 2 – the vroom() function from {vroom} • vroom::vroom() on 2014 data – 14.3 min • Better than read_csv() • 3.5x speed improvement – but slower than {data.table} • Works well with dplyr wrangling -
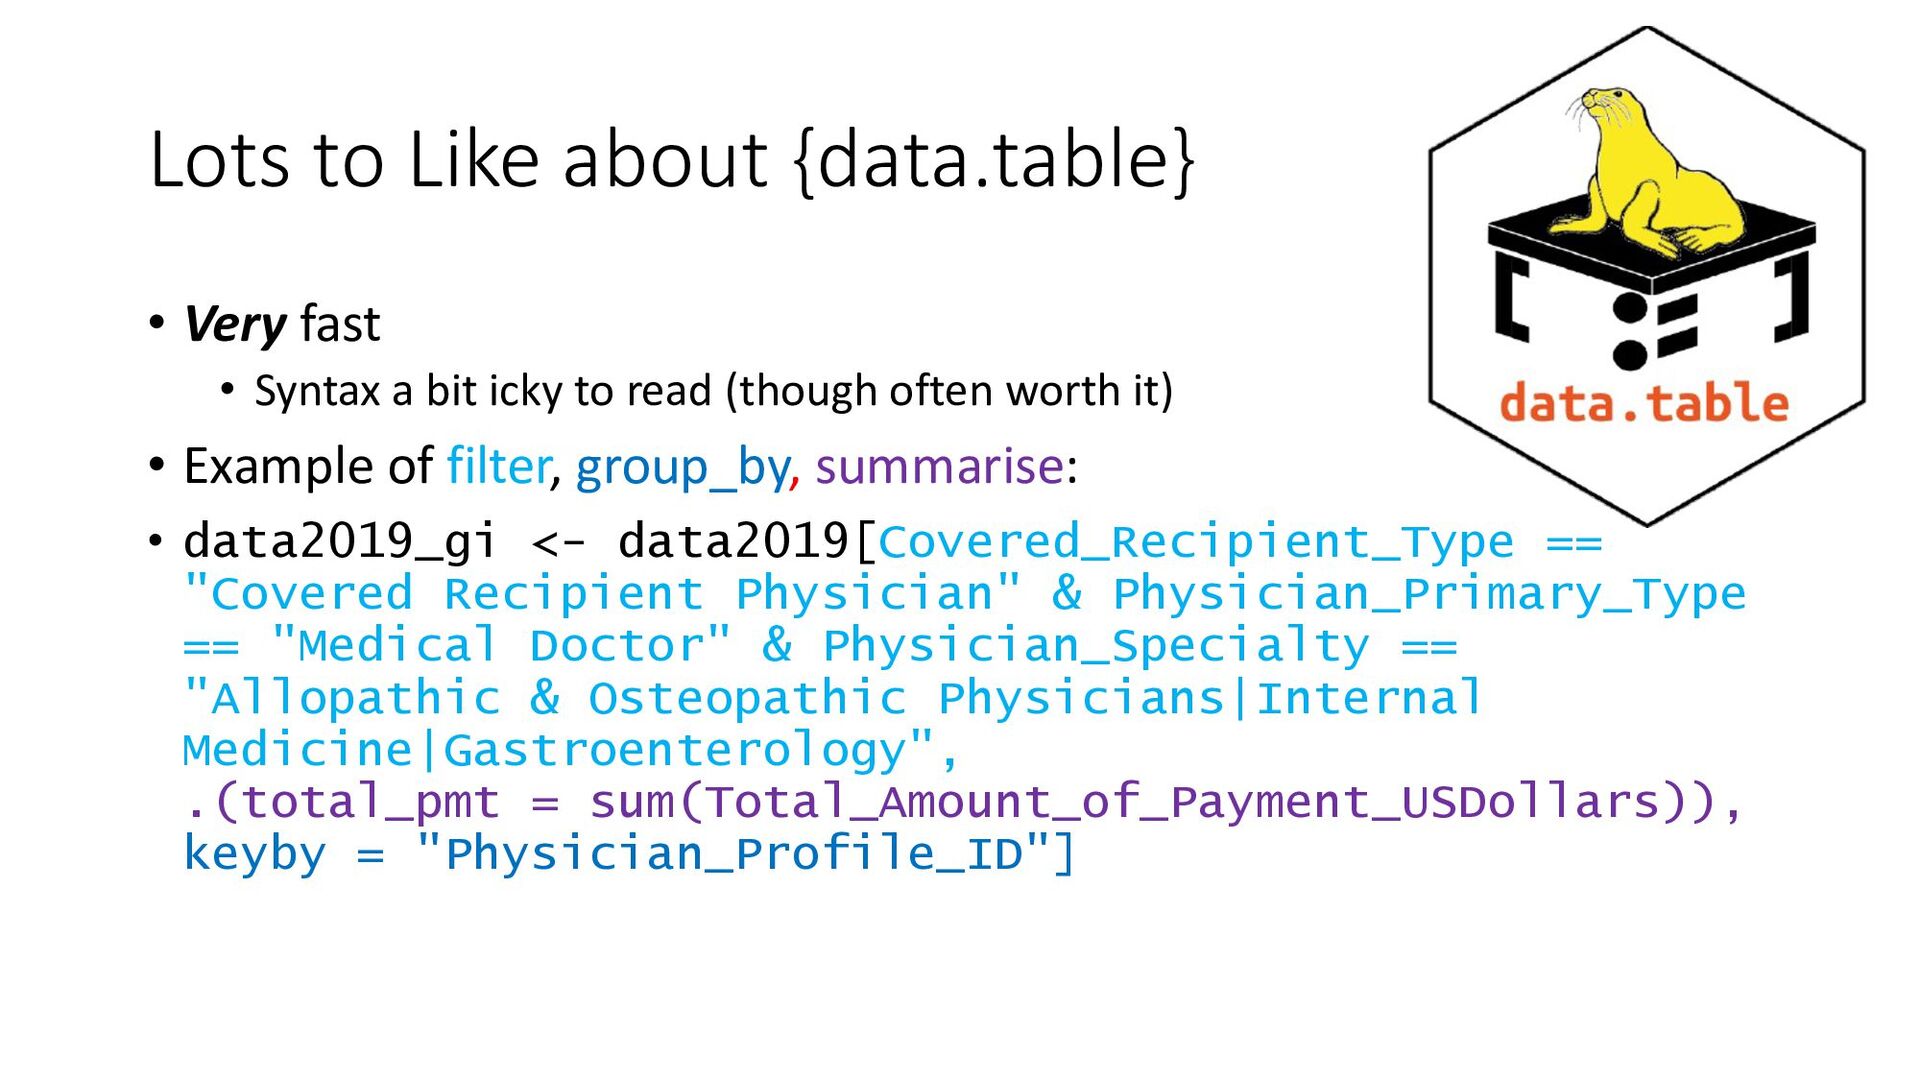
Lots to Like about {data.table} • Very fast • Syntax
a bit icky to read (though often worth it) • Example of filter, group_by, summarise: • data2019_gi <- data2019[Covered_Recipient_Type == "Covered Recipient Physician" & Physician_Primary_Type == "Medical Doctor" & Physician_Specialty == "Allopathic & Osteopathic Physicians|Internal Medicine|Gastroenterology", .(total_pmt = sum(Total_Amount_of_Payment_USDollars)), keyby = "Physician_Profile_ID"] -
Data.table package • For sheer speed, definitely worth using. •
Syntax takes some time to master • The {dtplyr} package is a good back-end work- around if you are familiar with dplyr verbs • But it does not address the bigger-than-RAM data problem (nor does {vroom}) -
Data on Disk vs. Data in RAM • Data on
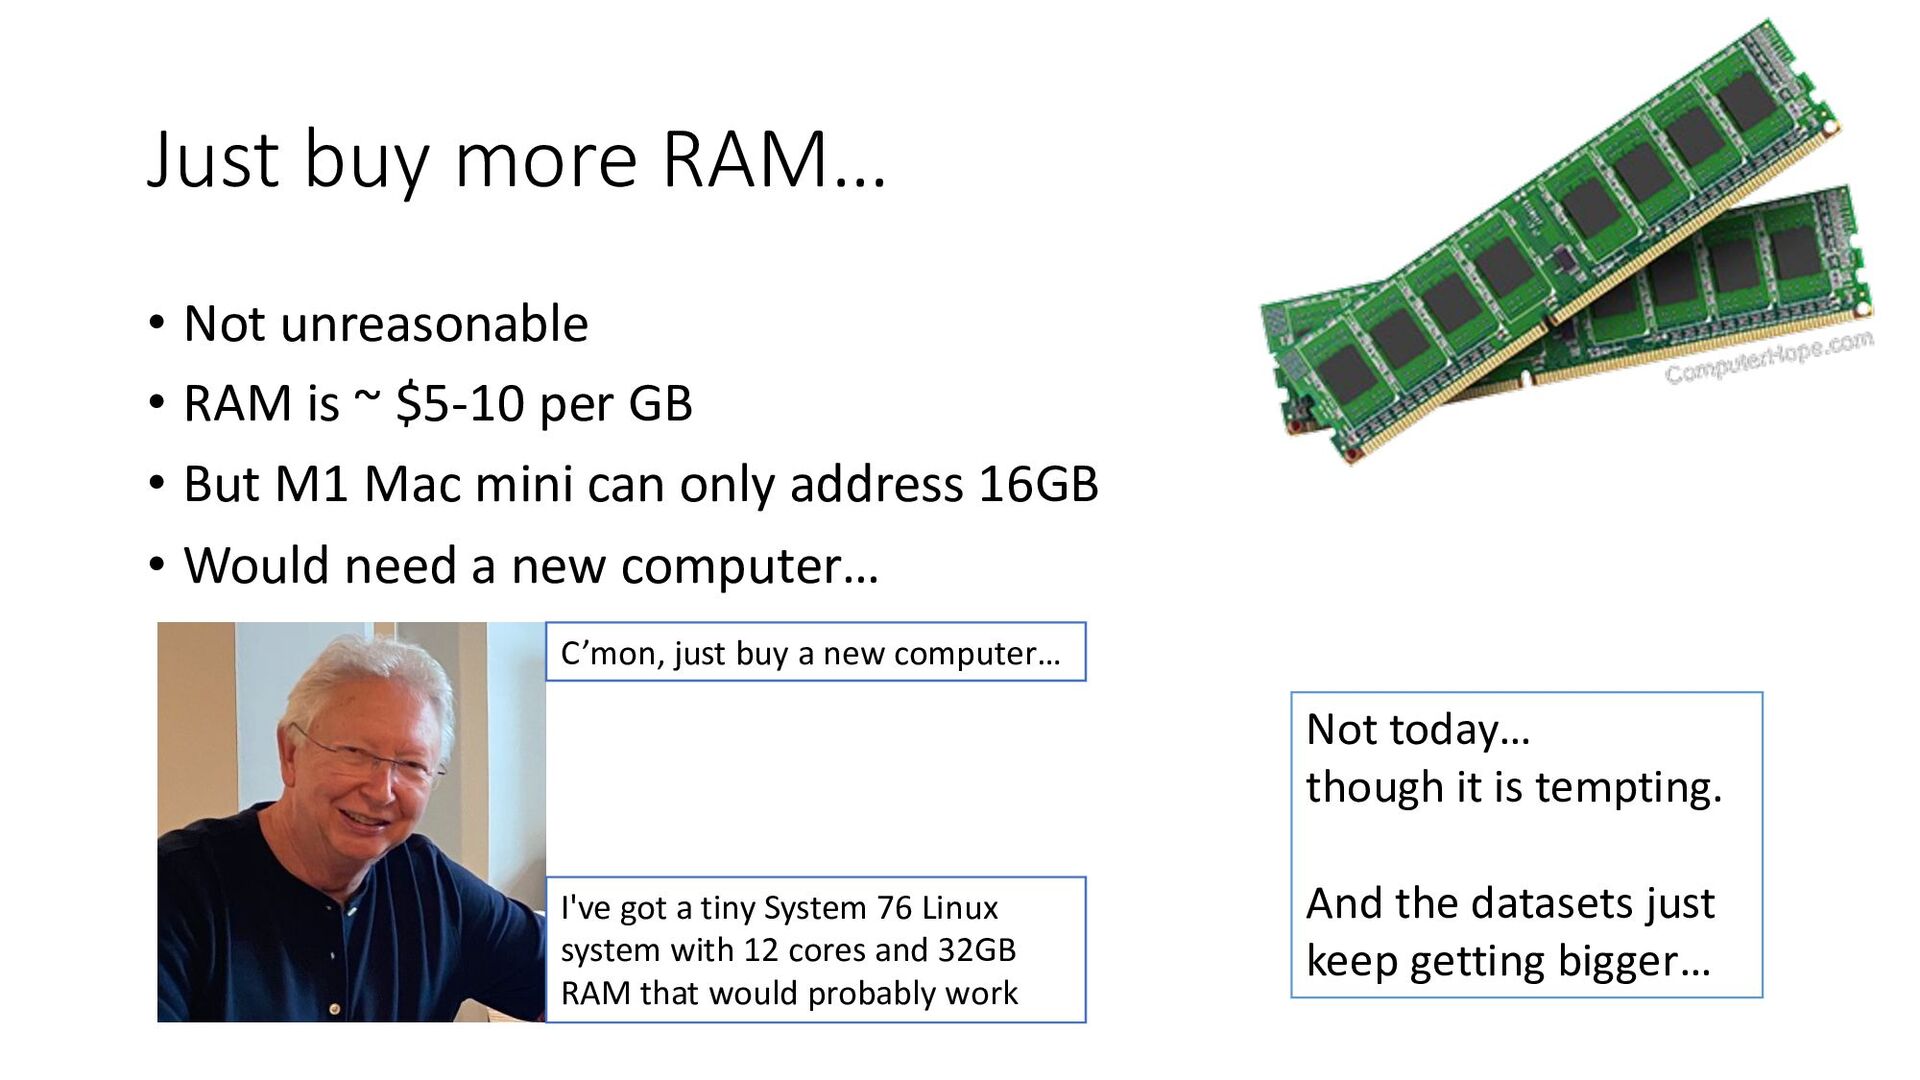
Disk • Easy to get a big disk – Terabytes now • Used to be slow (physical platters) – now SSD, much faster • Though 16TB SSD is still pretty pricey ~ $1800 • Need “scratch disk” space for writing intermediate data • Standard strategy of SAS • Data in RAM • Was much faster than disc – still faster, but not as dramatic with SSD drives • Limited to gigabytes, not terabytes • Standard vs biggest Mac configuration – 8 GB vs 128 GB • With big data, can often have insufficient RAM • Standard strategy of R -
Just buy more RAM… • Not unreasonable • RAM is
~ $5-10 per GB • But M1 Mac mini can only address 16GB • Would need a new computer… C’mon, just buy a new computer… I've got a tiny System 76 Linux system with 12 cores and 32GB RAM that would probably work Not today… though it is tempting. And the datasets just keep getting bigger… -
Twitter Suggests… • The {arrow} package • Uses a data
structure that works across languages (R, Py, Julia, etc.) • Very efficient • But can it read big data fast? -
Speed-reading • Option 3 – the read_csv_arrow() function from {arrow}
for single files • Arrow::read_csv_arrow() on 2014 data – 68.8 sec – very nice! • Encouraging on the speed front, slightly faster than {data.table}. -
What is Arrow? • The {arrow} R package is part
of the Apache Arrow project • Relies on the Arrow C++ library • Uses a standardized columnar memory format , organized for efficient analytic operations on modern hardware • Enables zero-copy data sharing between R and Python • A cross-language development platform for in-memory data • Available in C, C++, C#, Go, Java, JavaScript, Julia, MATLAB, Python, R, Ruby, and Rust. -
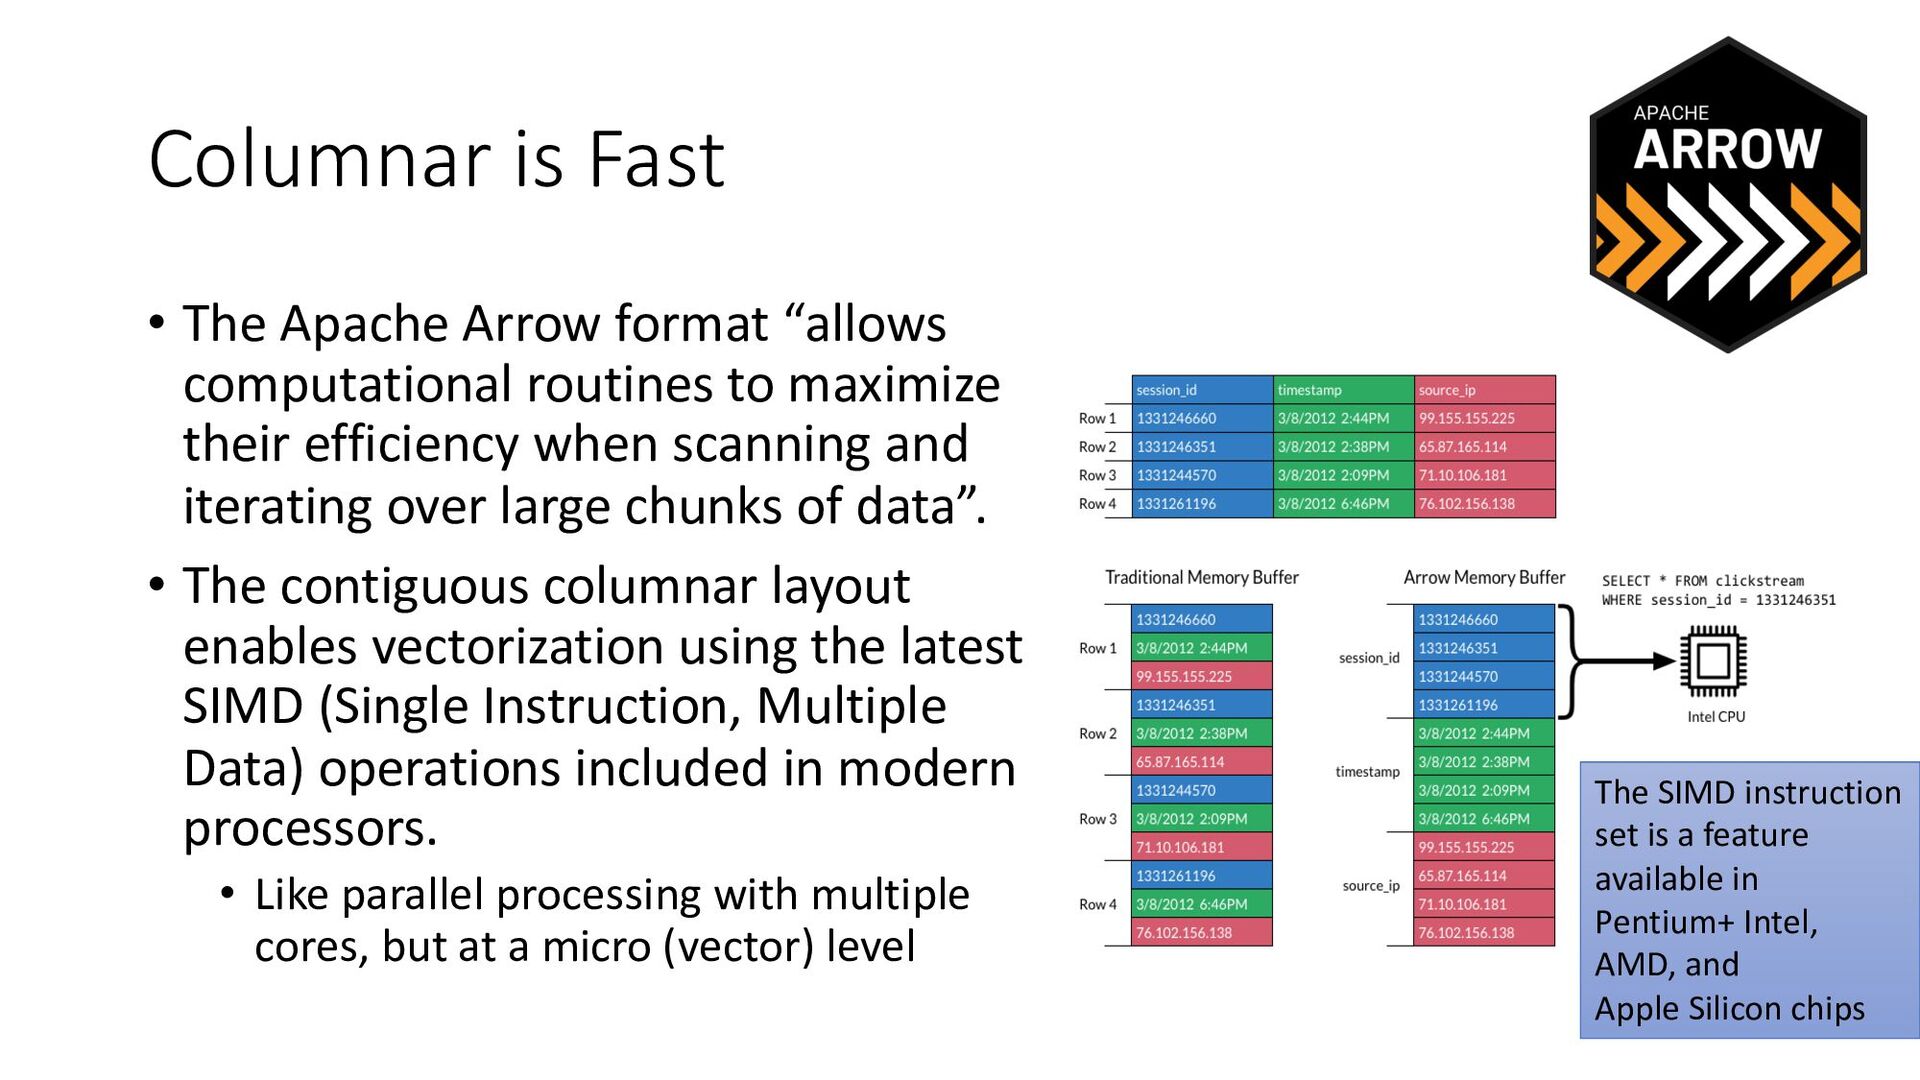
Columnar is Fast • The Apache Arrow format “allows computational
routines to maximize their efficiency when scanning and iterating over large chunks of data”. • The contiguous columnar layout enables vectorization using the latest SIMD (Single Instruction, Multiple Data) operations included in modern processors. • Like parallel processing with multiple cores, but at a micro (vector) level The SIMD instruction set is a feature available in Pentium+ Intel, AMD, and Apple Silicon chips -
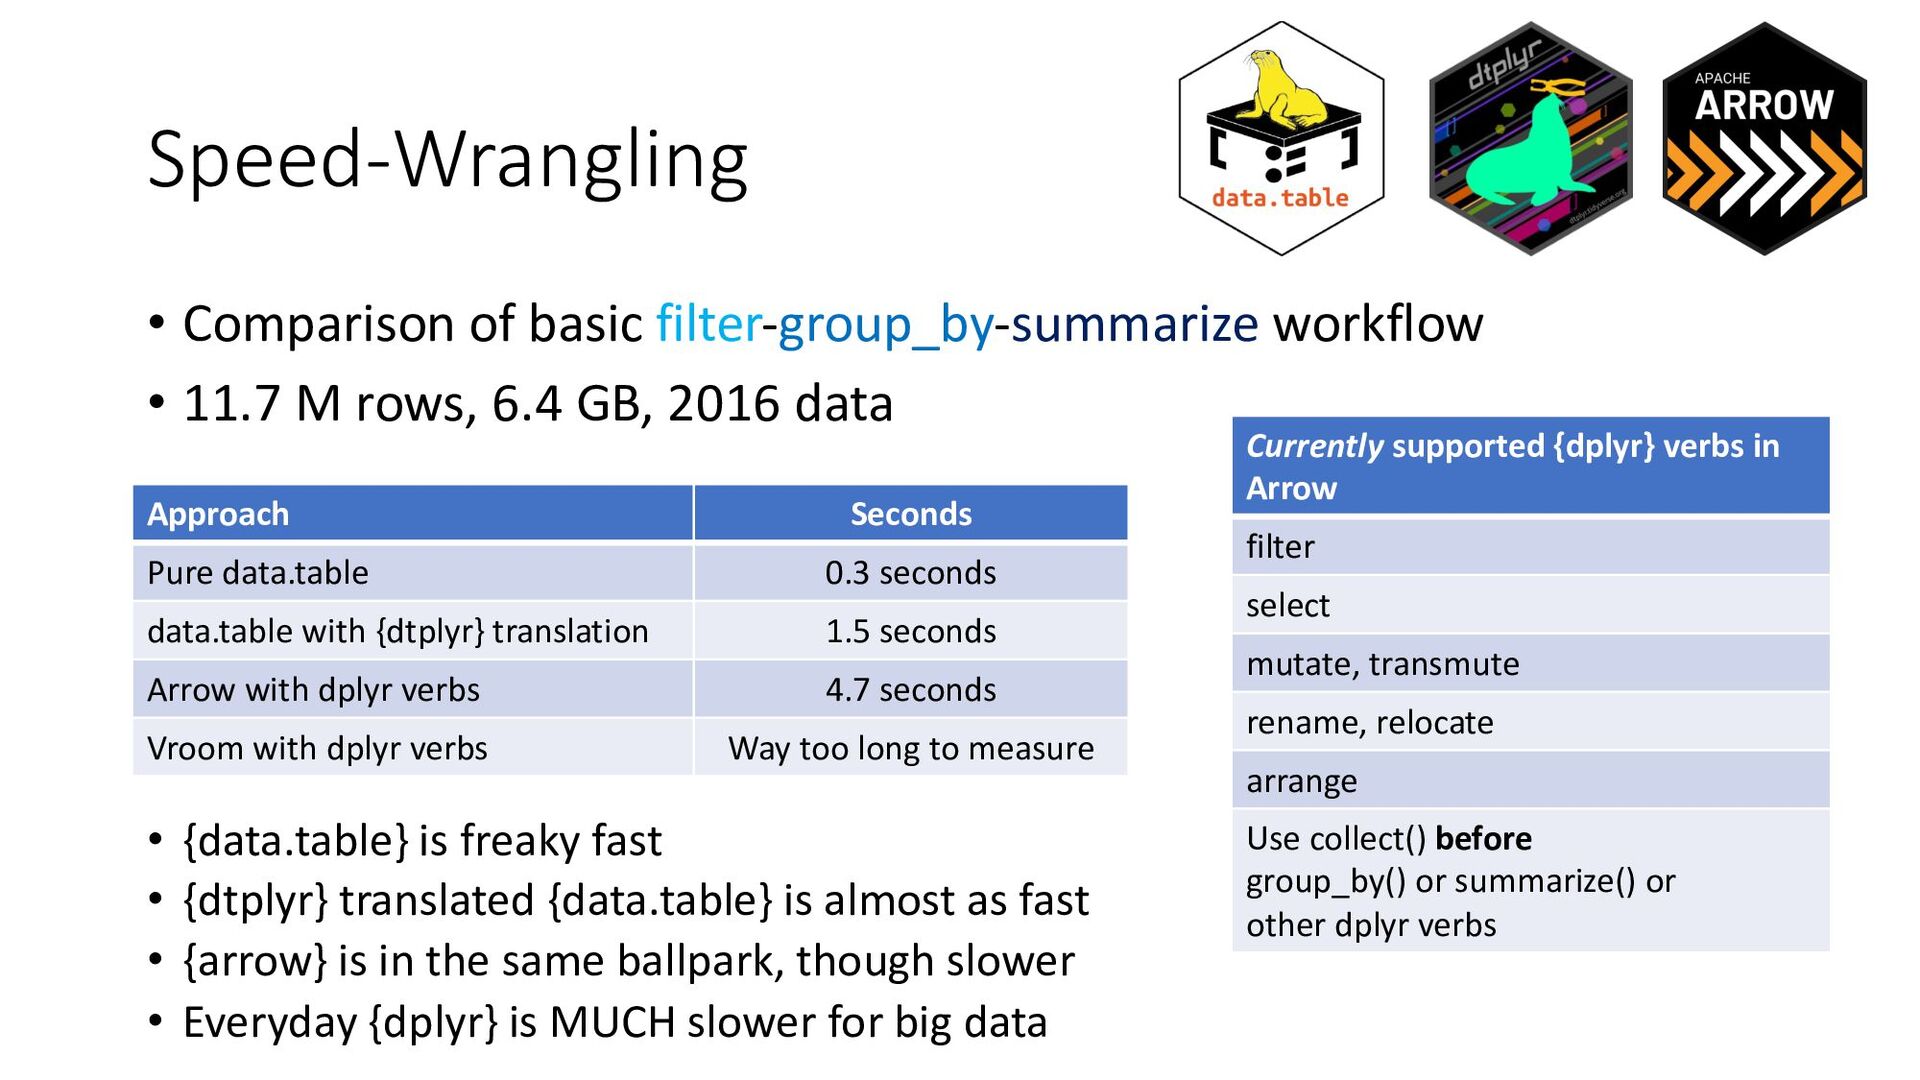
Speed-Wrangling • Comparison of basic filter-group_by-summarize workflow • 11.7 M
rows, 6.4 GB, 2016 data Approach Seconds Pure data.table 0.3 seconds data.table with {dtplyr} translation 1.5 seconds Arrow with dplyr verbs 4.7 seconds Vroom with dplyr verbs Way too long to measure Currently supported {dplyr} verbs in Arrow filter select mutate, transmute rename, relocate arrange Use collect() before group_by() or summarize() or other dplyr verbs • {data.table} is freaky fast • {dtplyr} translated {data.table} is almost as fast • {arrow} is in the same ballpark, though slower • Everyday {dplyr} is MUCH slower for big data -
Side Benefit of Multi-Lingual Arrow • Arrow-formatted data can be
used (unmodified) by many languages • Collaboration the old way – collaborator has a useful Python routine • Copy data from R to Python format • Run Python routine • Copy results back to R format • With {arrow} – multilingual with less friction • Insert a Python chunk into Rmd (or Qmd) • Run routine – Python can read R results in arrow format • R can read Python results in arrow format, no copying of data -
But what about the Bigger-Than-RAM problem? • Can {arrow} handle
this? • Arrow 6.0+ can analyze and process multi-file, larger-than-memory datasets • {disk.frame} soft-deprecated in favor of {arrow} • You can manipulate and analyze Arrow data with dplyr verbs • Not clear if you can {arrow} x {data.table} ?? • [TODO: test with dtplyr, is speed affected?] -
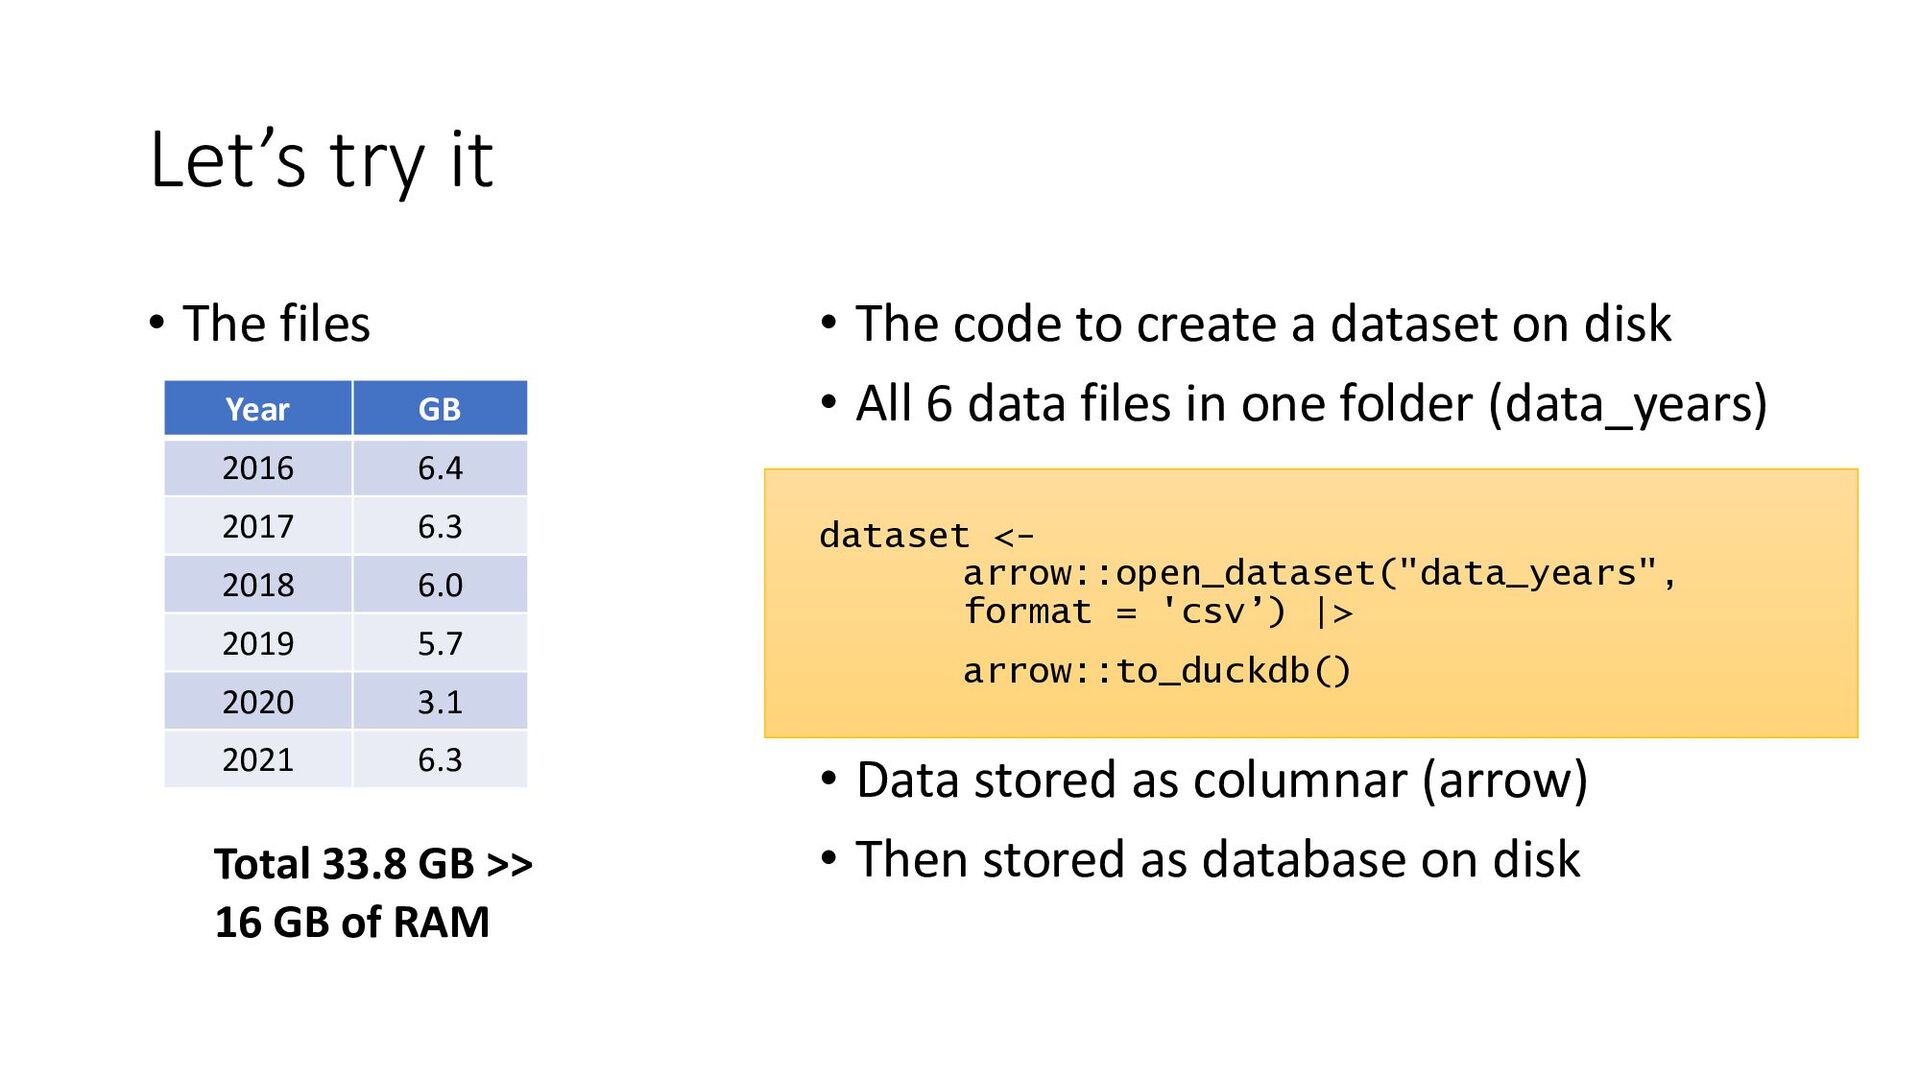
Let’s try it • The files • The code to
create a dataset on disk • All 6 data files in one folder (data_years) dataset <- arrow::open_dataset("data_years", format = 'csv’) |> arrow::to_duckdb() • Data stored as columnar (arrow) • Then stored as database on disk Year GB 2016 6.4 2017 6.3 2018 6.0 2019 5.7 2020 3.1 2021 6.3 Total 33.8 GB >> 16 GB of RAM -
What is duckDB? • Designed to be used as an
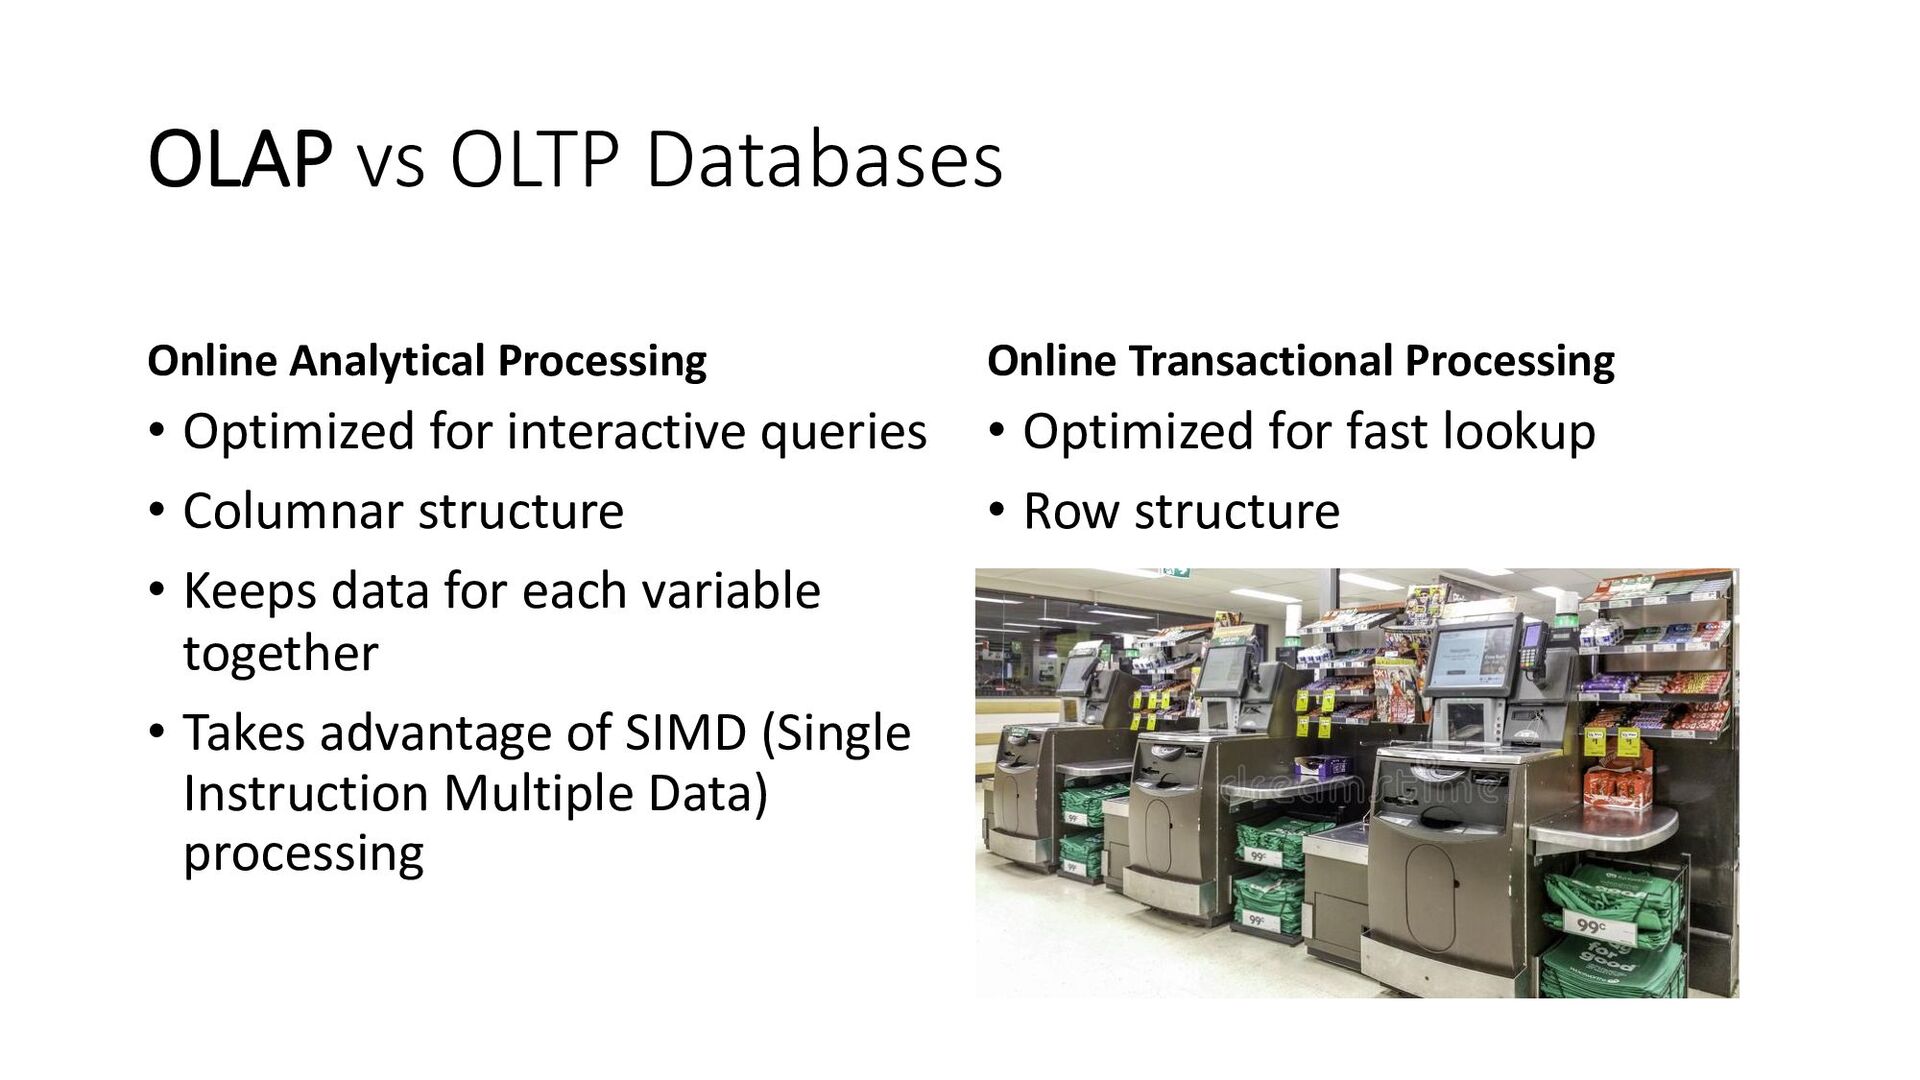
embeddable on-the-fly database (like SQLite) • No databasse setup required – just load the {duckdb} library and go • DuckDB is an OLAP database – Online Analytical Processing • Columnar structure, organized by field/variable • Designed to make complex queries fast >> making data lookup tables fast (OLTP) • Takes advantage of SIMD (single instruction, multiple data) instruction set to achieve speed-up with modern CPUs -
OLAP vs OLTP Databases Online Analytical Processing • Optimized for
interactive queries • Columnar structure • Keeps data for each variable together • Takes advantage of SIMD (Single Instruction Multiple Data) processing Online Transactional Processing • Optimized for fast lookup • Row structure -
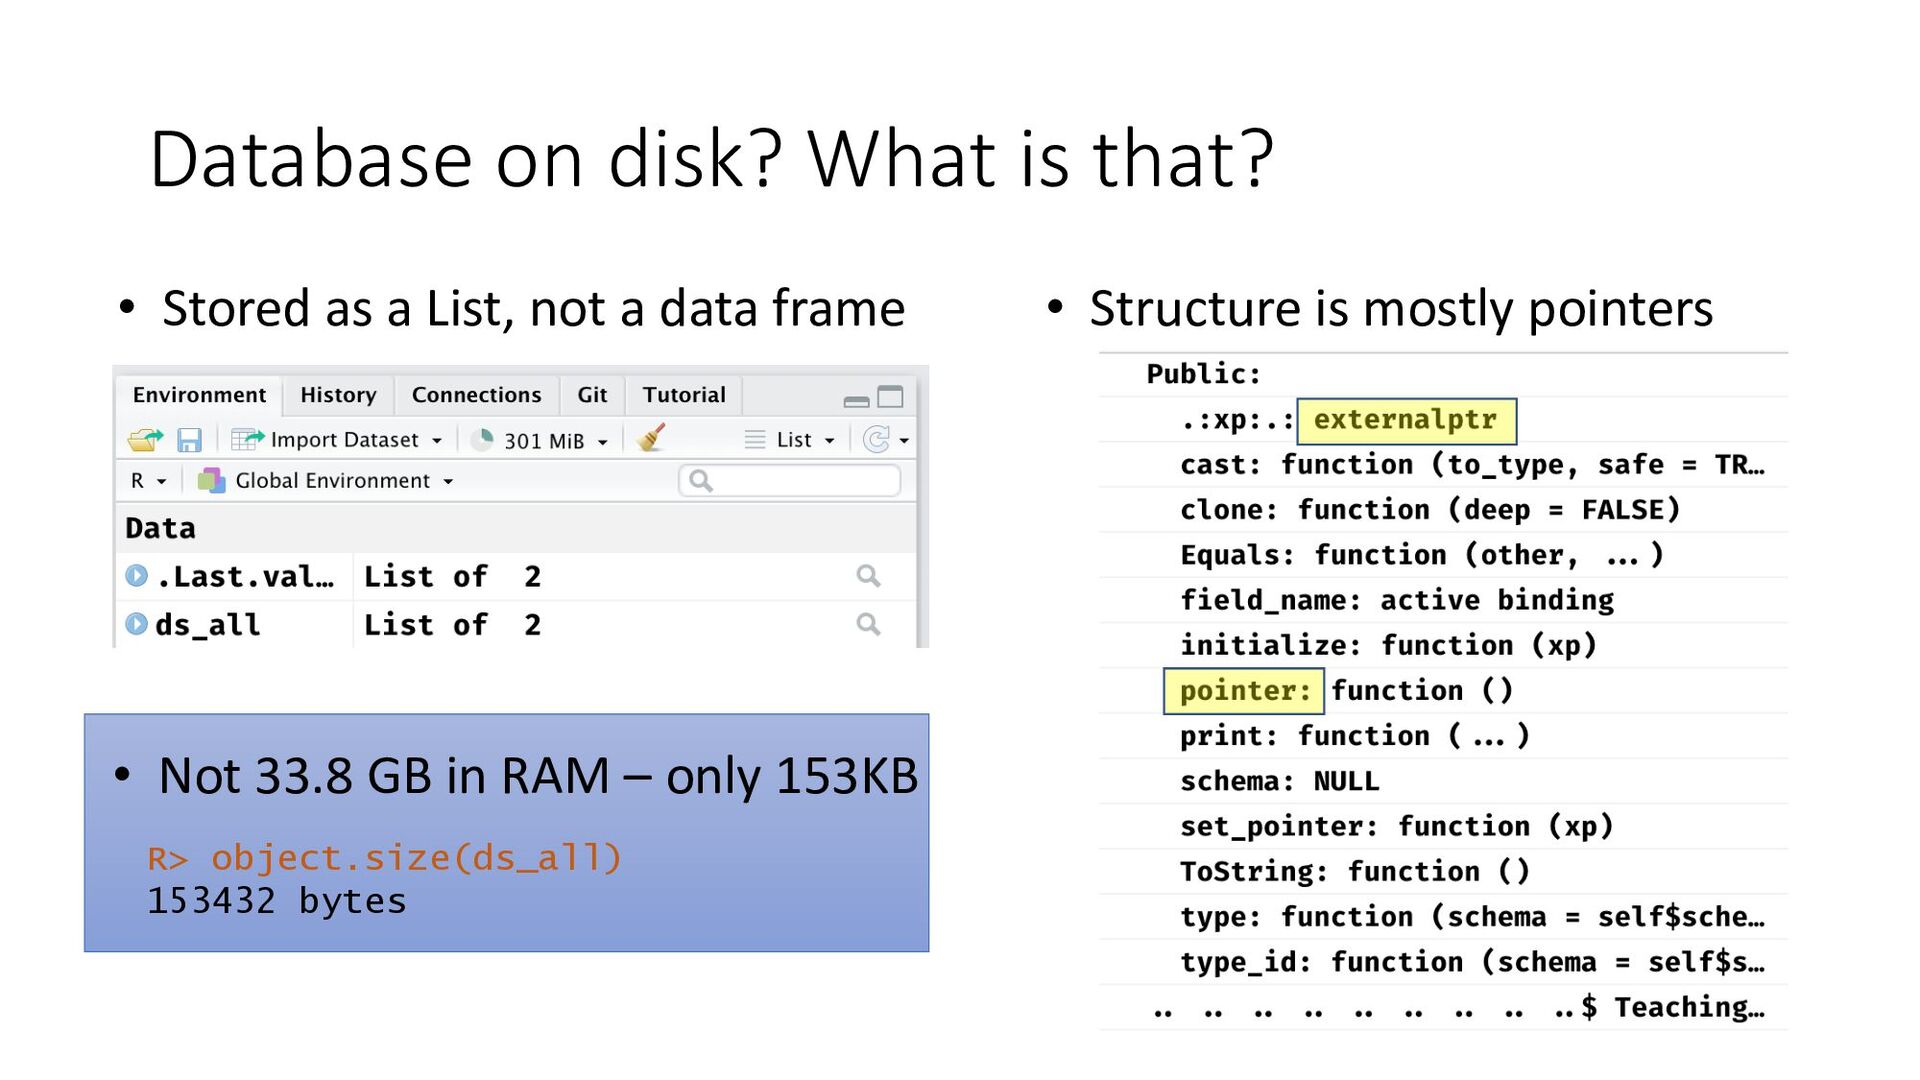
Database on disk? What is that? • Stored as a
List, not a data frame • Structure is mostly pointers R> object.size(ds_all) 153432 bytes • Not 33.8 GB in RAM – only 153KB -
Now you can wrangle with {dplyr} • {arrow} has a
{dplyr} back-end • Can write code with many (not all) dplyr verbs • Translated into arrow with duckDB • Partitions data into RAM-sized chunks • Runs calculations on each partition • Can wrangle – here for a descriptive data summary • This produces no result (yet) ds_all %>% filter(Physician_Specialty == "Gastroenterology") |> group_by(Physician_First_Name, Physician_Last_Name) |> summarize(total_usd = sum(Total_Amount_of_Payment_US Dollars)) -
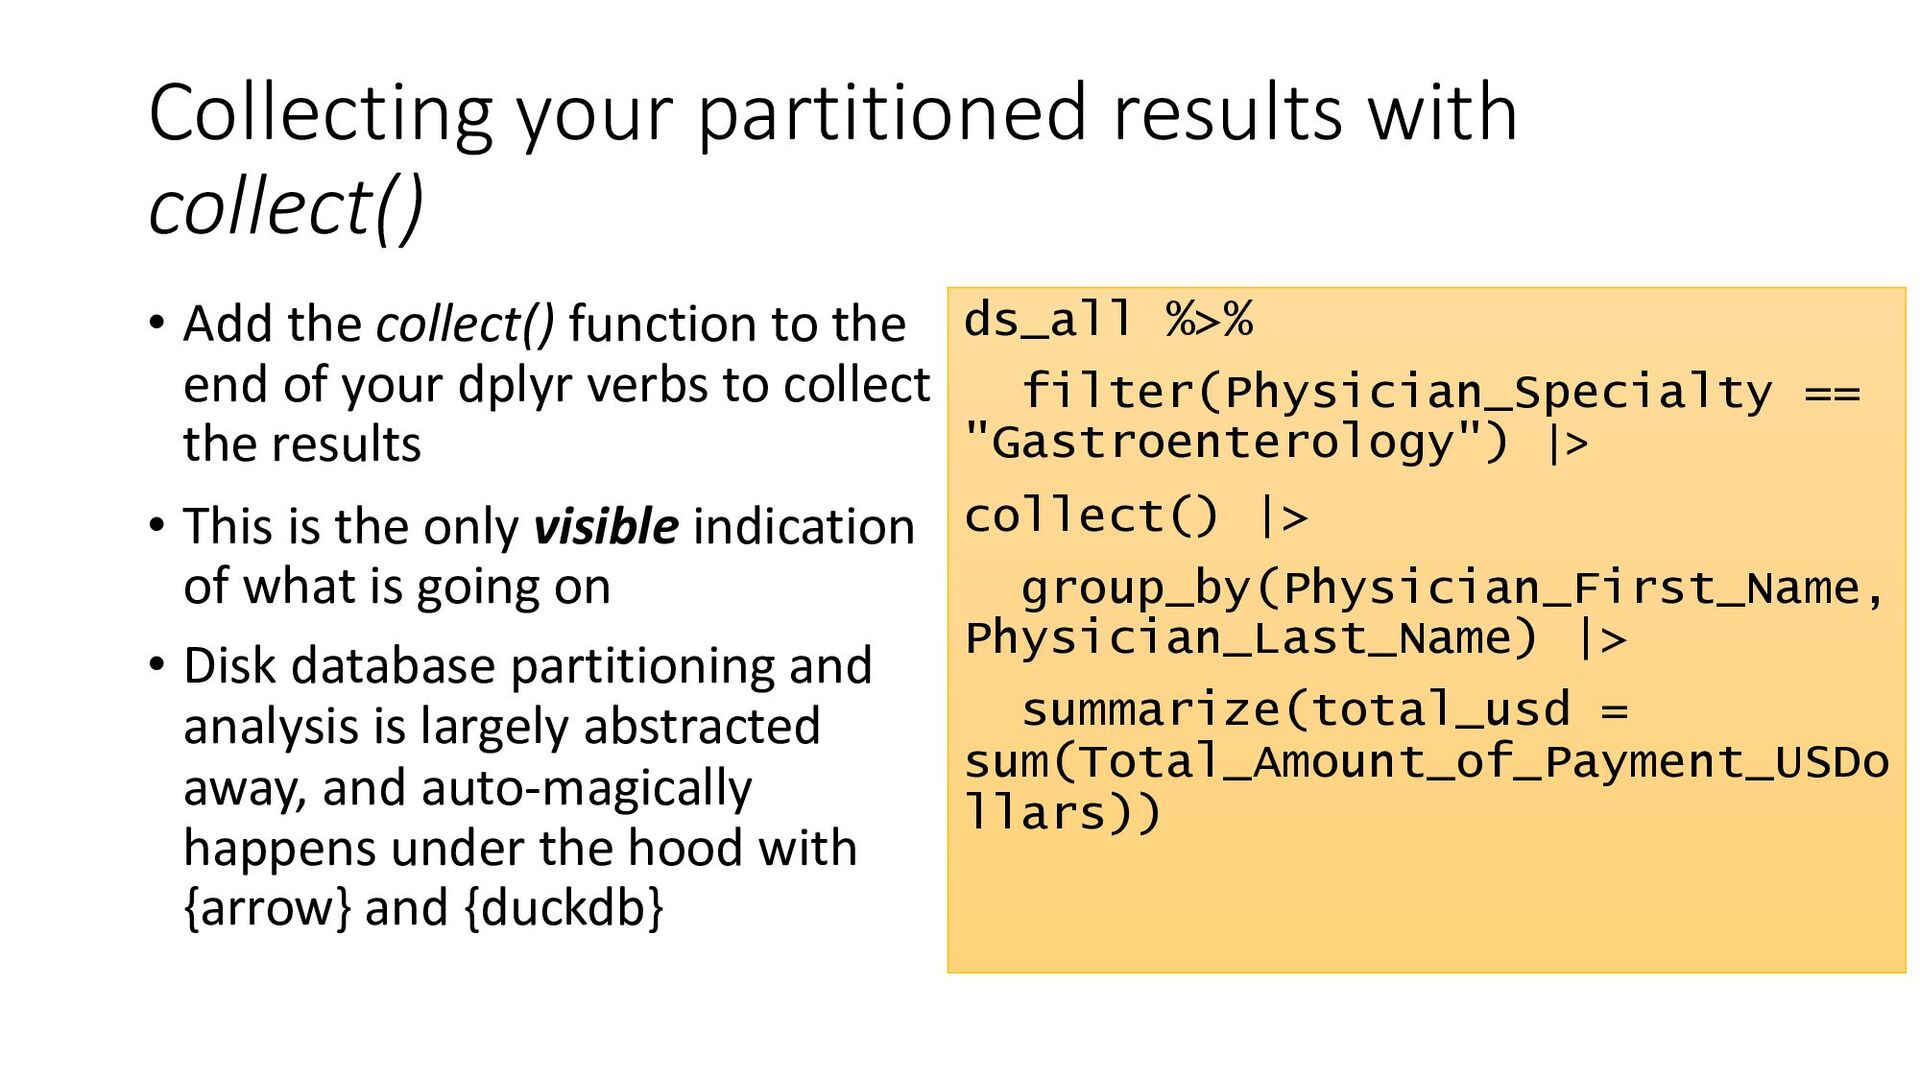
Collecting your partitioned results with collect() ds_all %>% filter(Physician_Specialty ==
"Gastroenterology") |> collect() |> group_by(Physician_First_Name, Physician_Last_Name) |> summarize(total_usd = sum(Total_Amount_of_Payment_USDo llars)) • Add the collect() function to the end of your dplyr verbs to collect the results • This is the only visible indication of what is going on • Disk database partitioning and analysis is largely abstracted away, and auto-magically happens under the hood with {arrow} and {duckdb} -
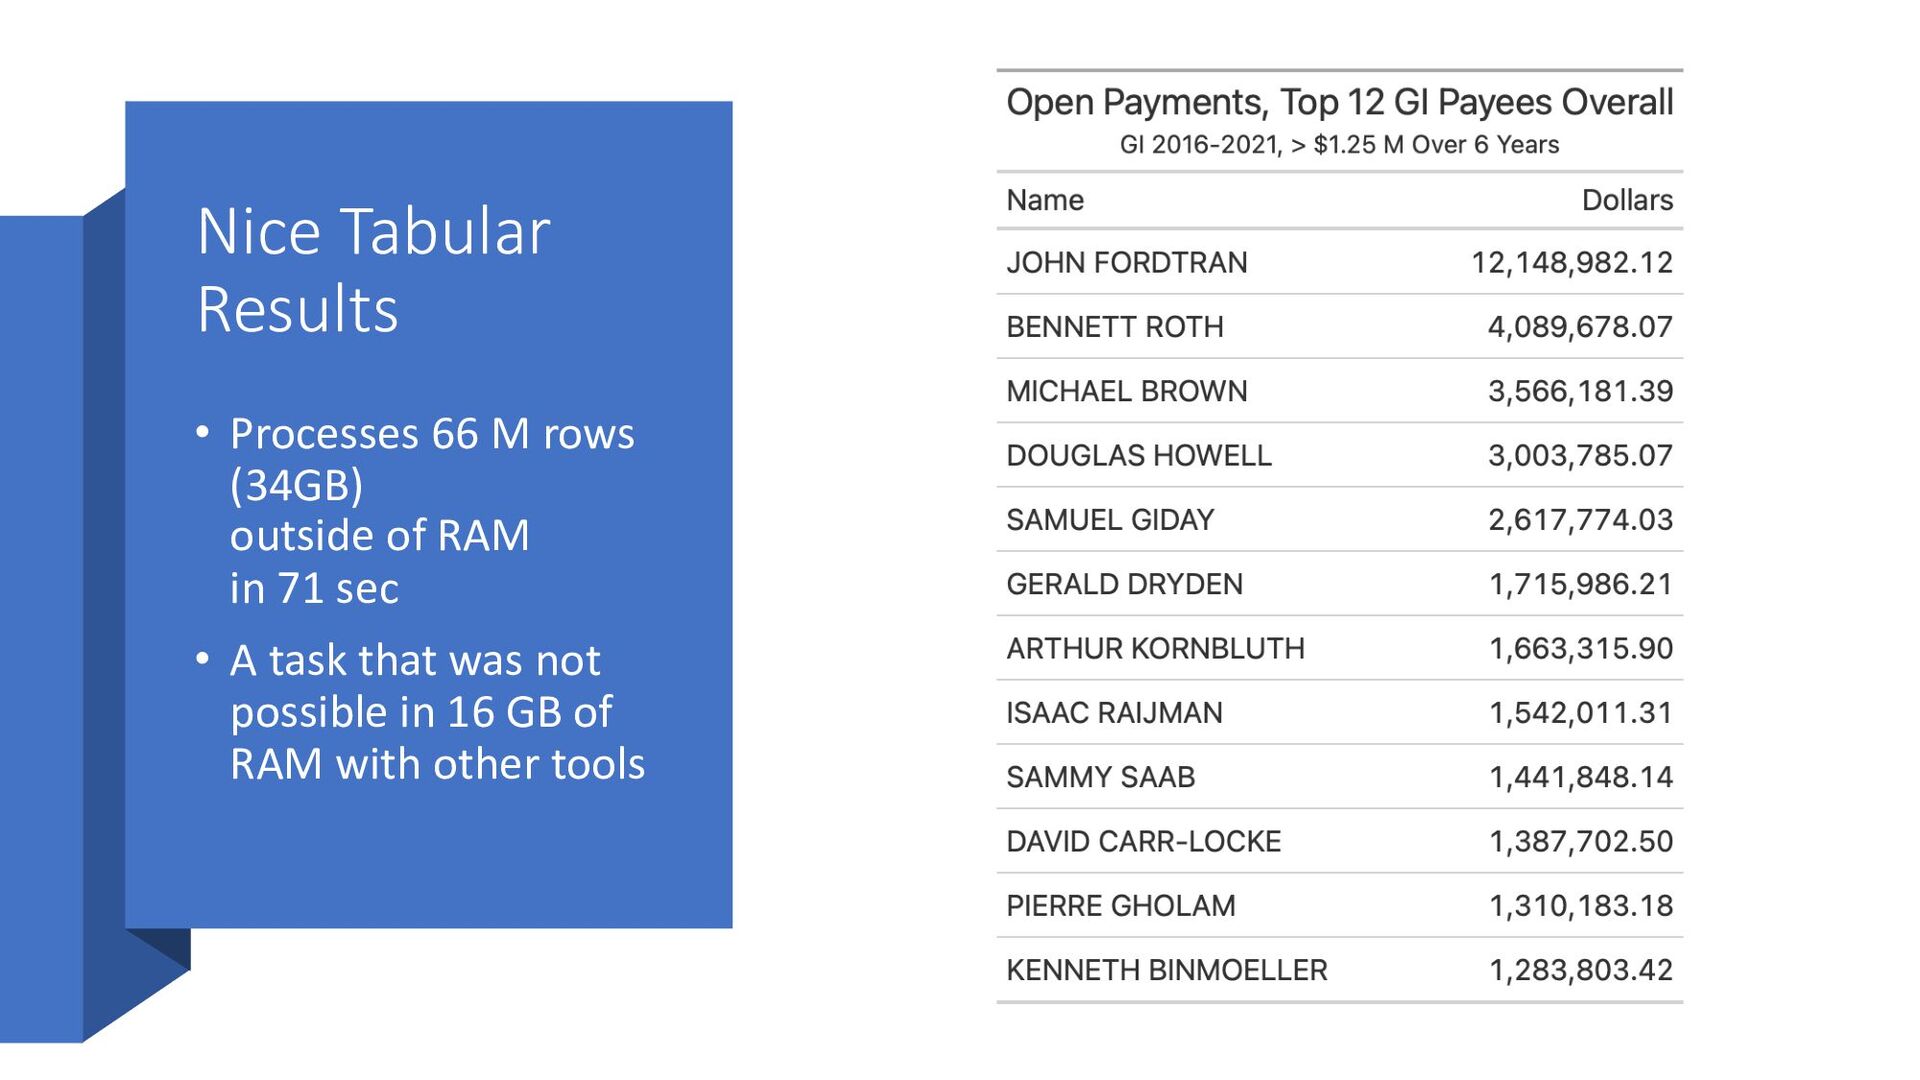
Nice Tabular Results • Processes 66 M rows (34GB) outside
of RAM in 71 sec • A task that was not possible in 16 GB of RAM with other tools -
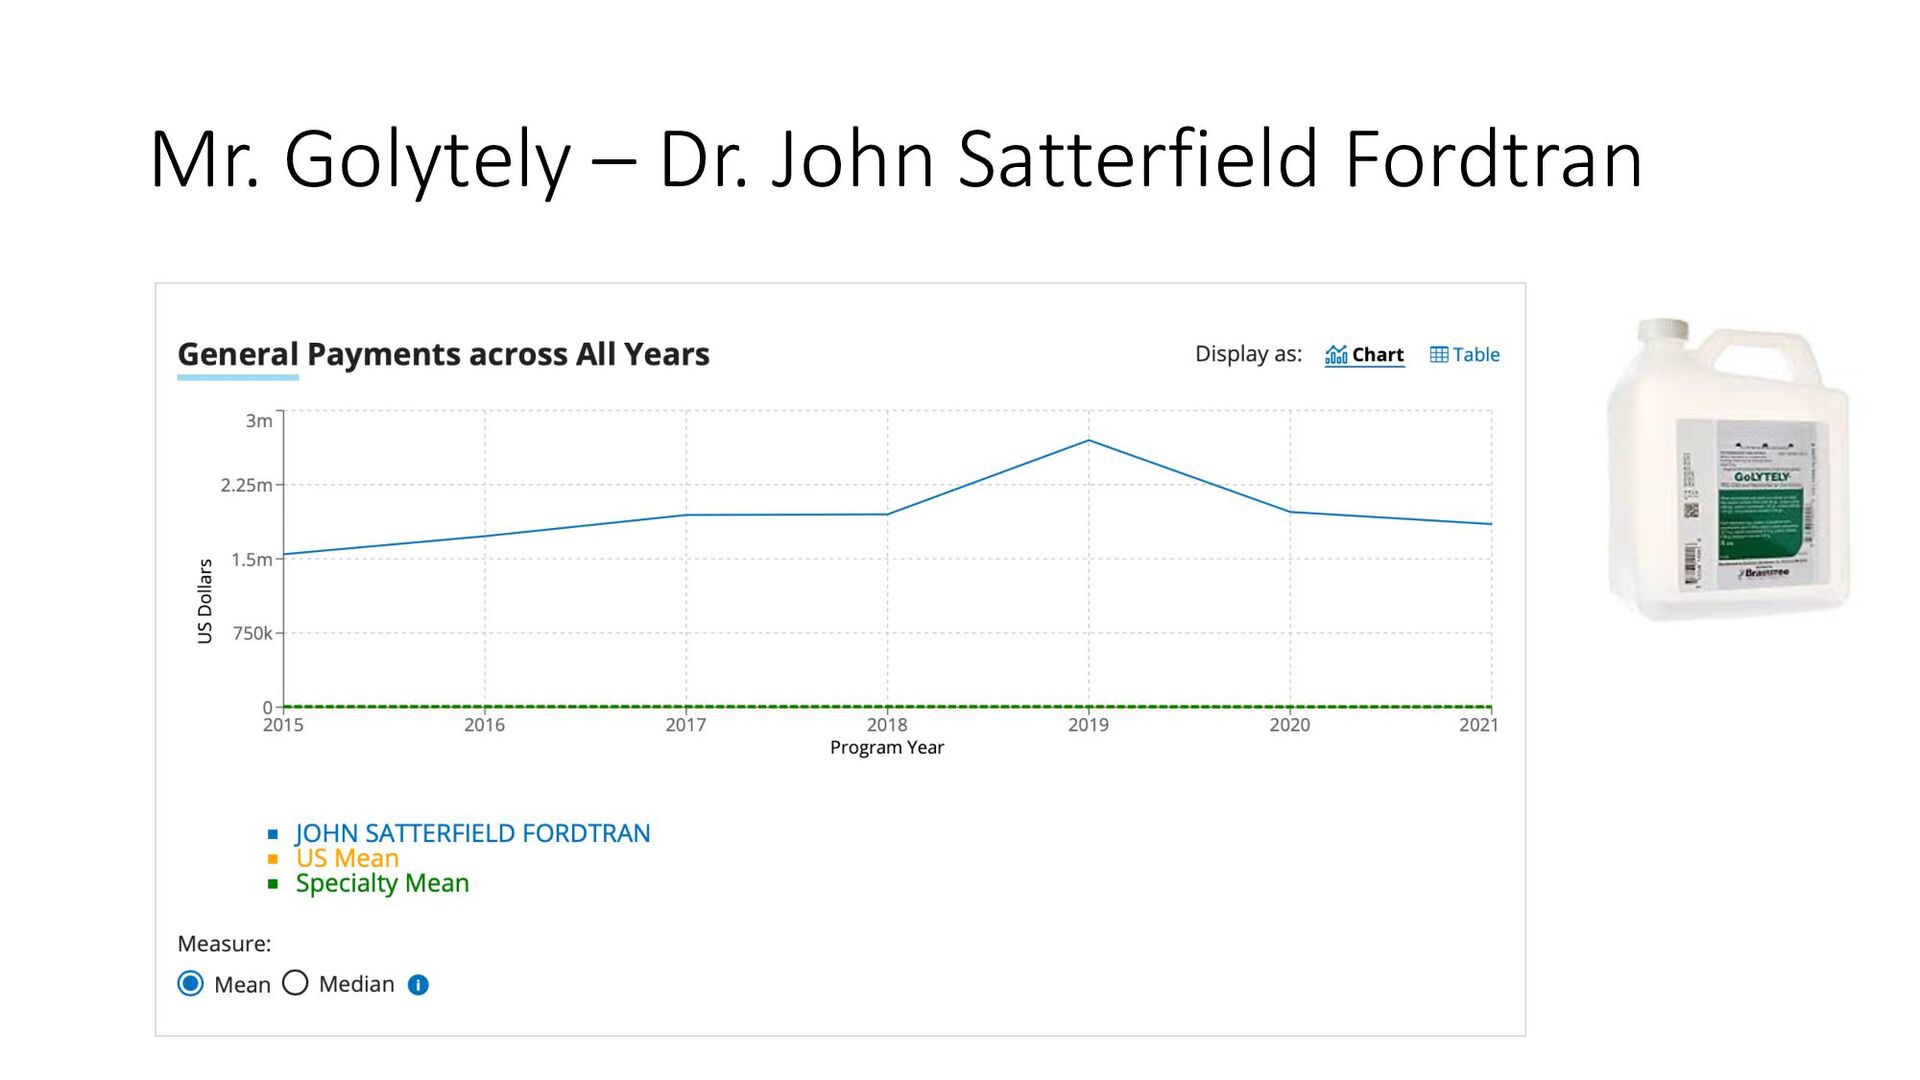
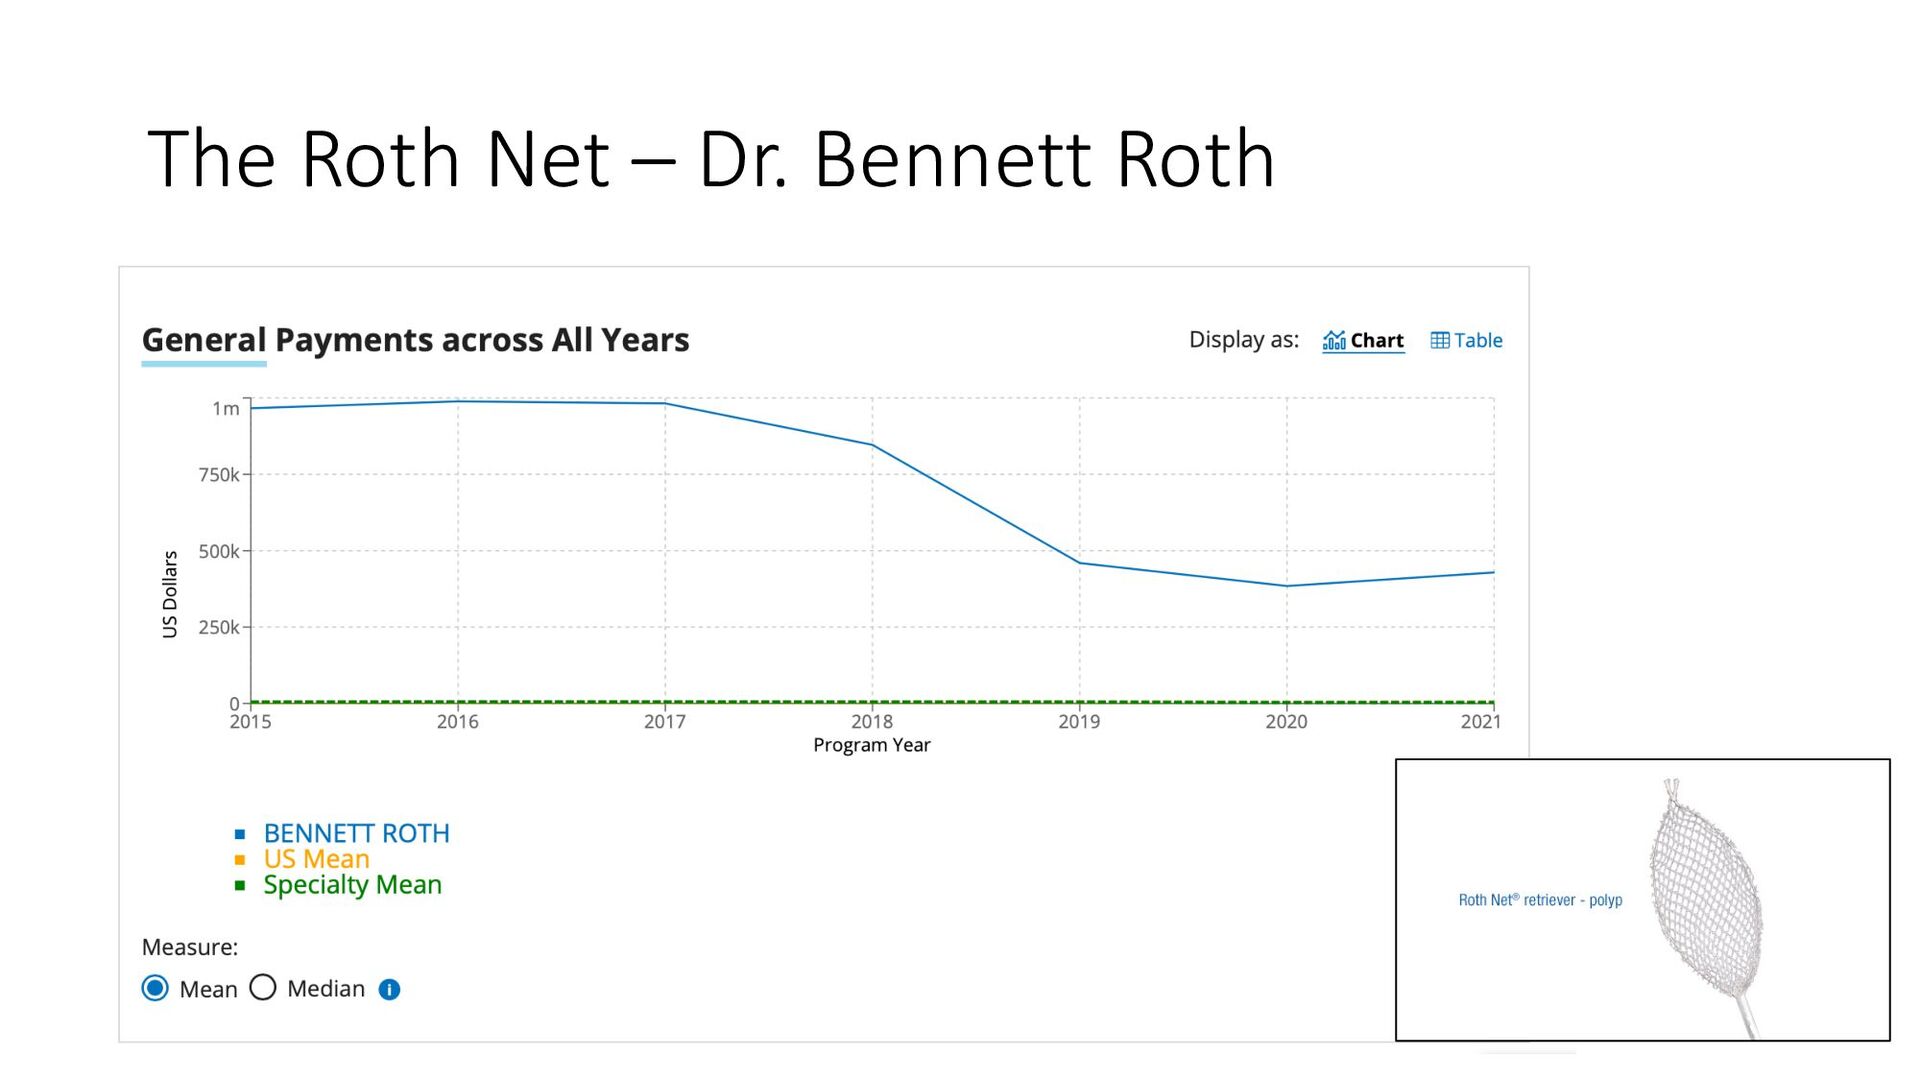
• Did 50 people actually give 250 drug talks per
year? • No, nearly all of the top 50 in payments were from royalties from patents • #1 Greater than $1M per year in royalties for John Fordtran • #2 – royalties for Bennett Roth $500K - $1M per year Back to the Question -
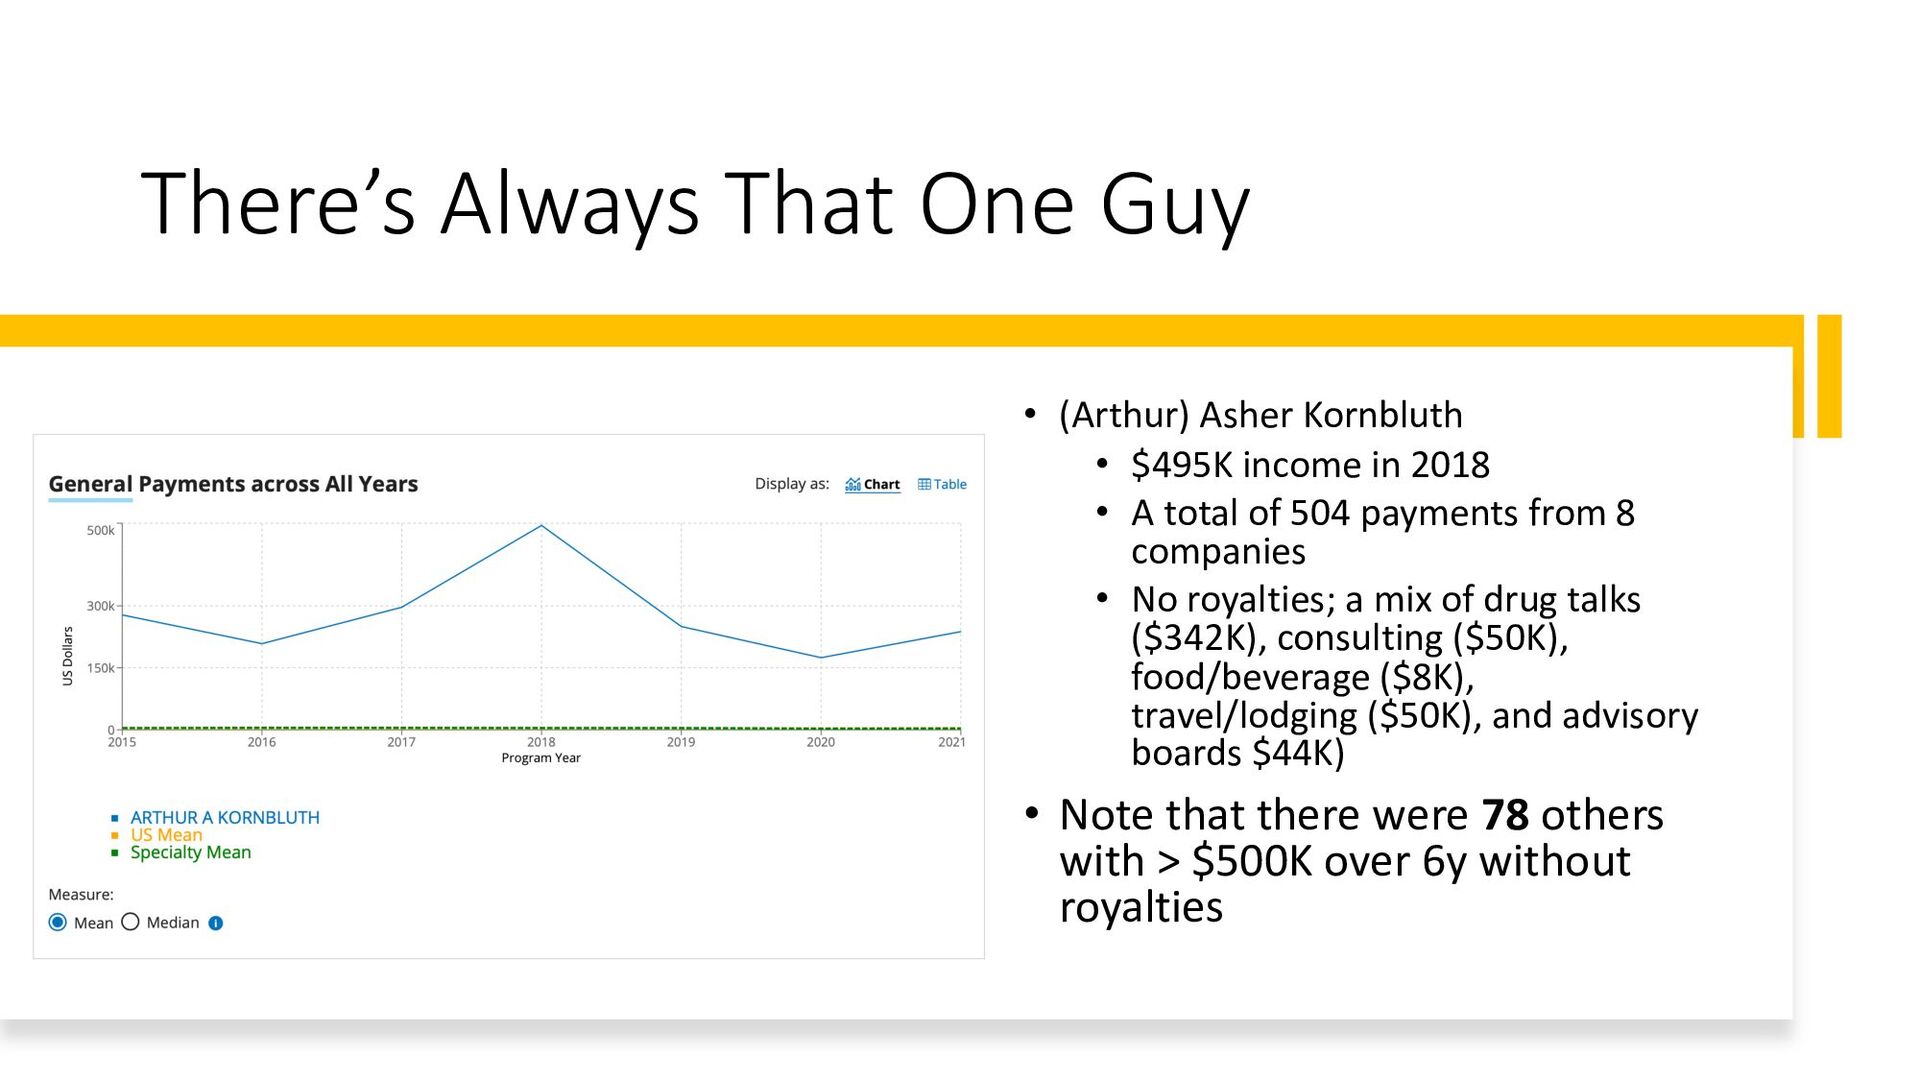
There’s Always That One Guy • (Arthur) Asher Kornbluth •
$495K income in 2018 • A total of 504 payments from 8 companies • No royalties; a mix of drug talks ($342K), consulting ($50K), food/beverage ($8K), travel/lodging ($50K), and advisory boards $44K) • Note that there were 78 others with > $500K over 6y without royalties -
Alternatives to Bigger-Than-RAM Wrangling • Buy more RAM • Though
you seem to always end up trying to keep up with bigger and bigger data • Rent some RAM (short-term) in the Cloud • If you have access to a local (often University) cluster • Or an Amazon Web Services S3, Google, or Azure instance • Walk through of RStudio in AWS in this video playlist • https://www.youtube.com/playlist?list=PL0hSJrxggIQoer5TwgW6qWHnVJfqzcX3l • Key videos for RStudio – 12 and 13 in the playlist -
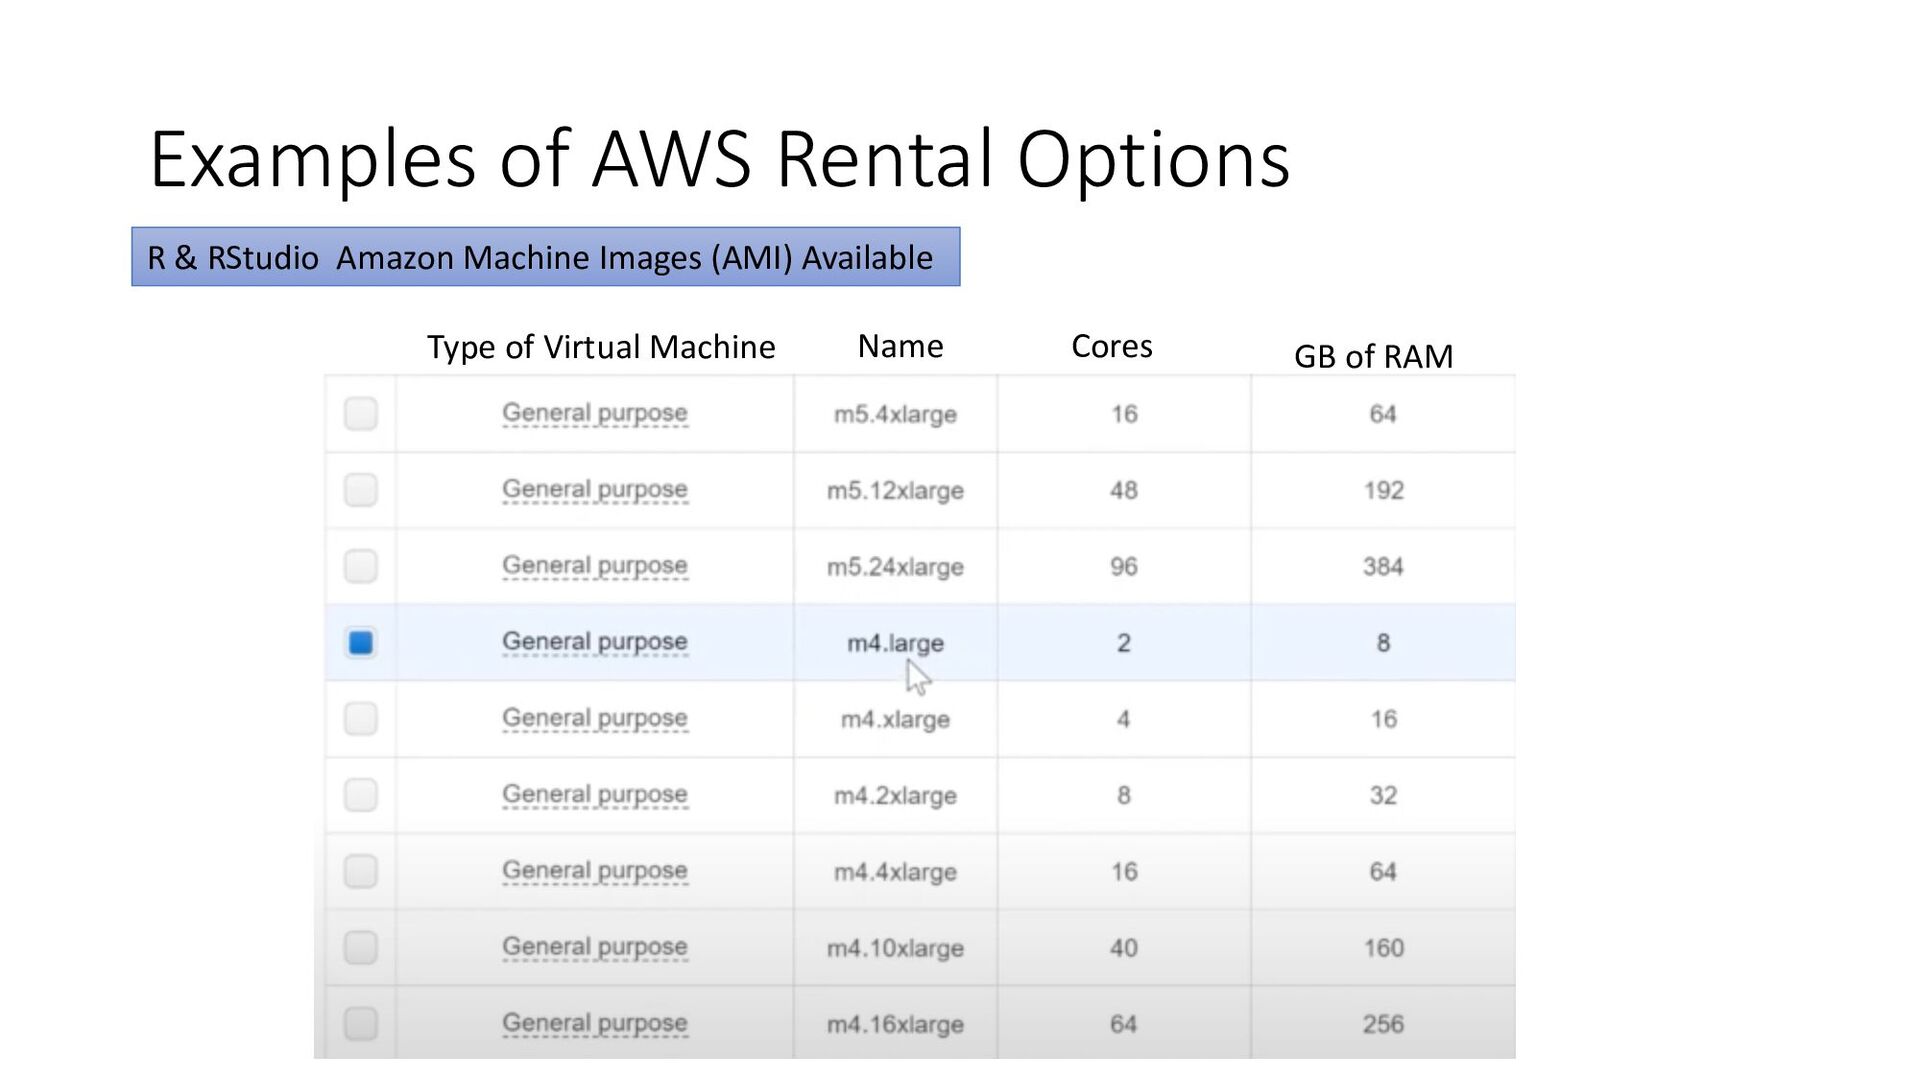
Examples of AWS Rental Options Name Cores GB of RAM
Type of Virtual Machine R & RStudio Amazon Machine Images (AMI) Available -
Take Home Points - Speed • {dplyr} read_csv() is 2-3x
faster than the base read.csv() • But it gets slooow with 10M+ rows of data • Faster options for reading in big data • {vroom} vroom() • {data.table} fread() • {arrow} read_csv_arrow() • Faster options for wrangling big data • {data.table} • {dtplyr} (front-end for data.table} • {arrow} with dplyr back-end (only for arrow data structures) -
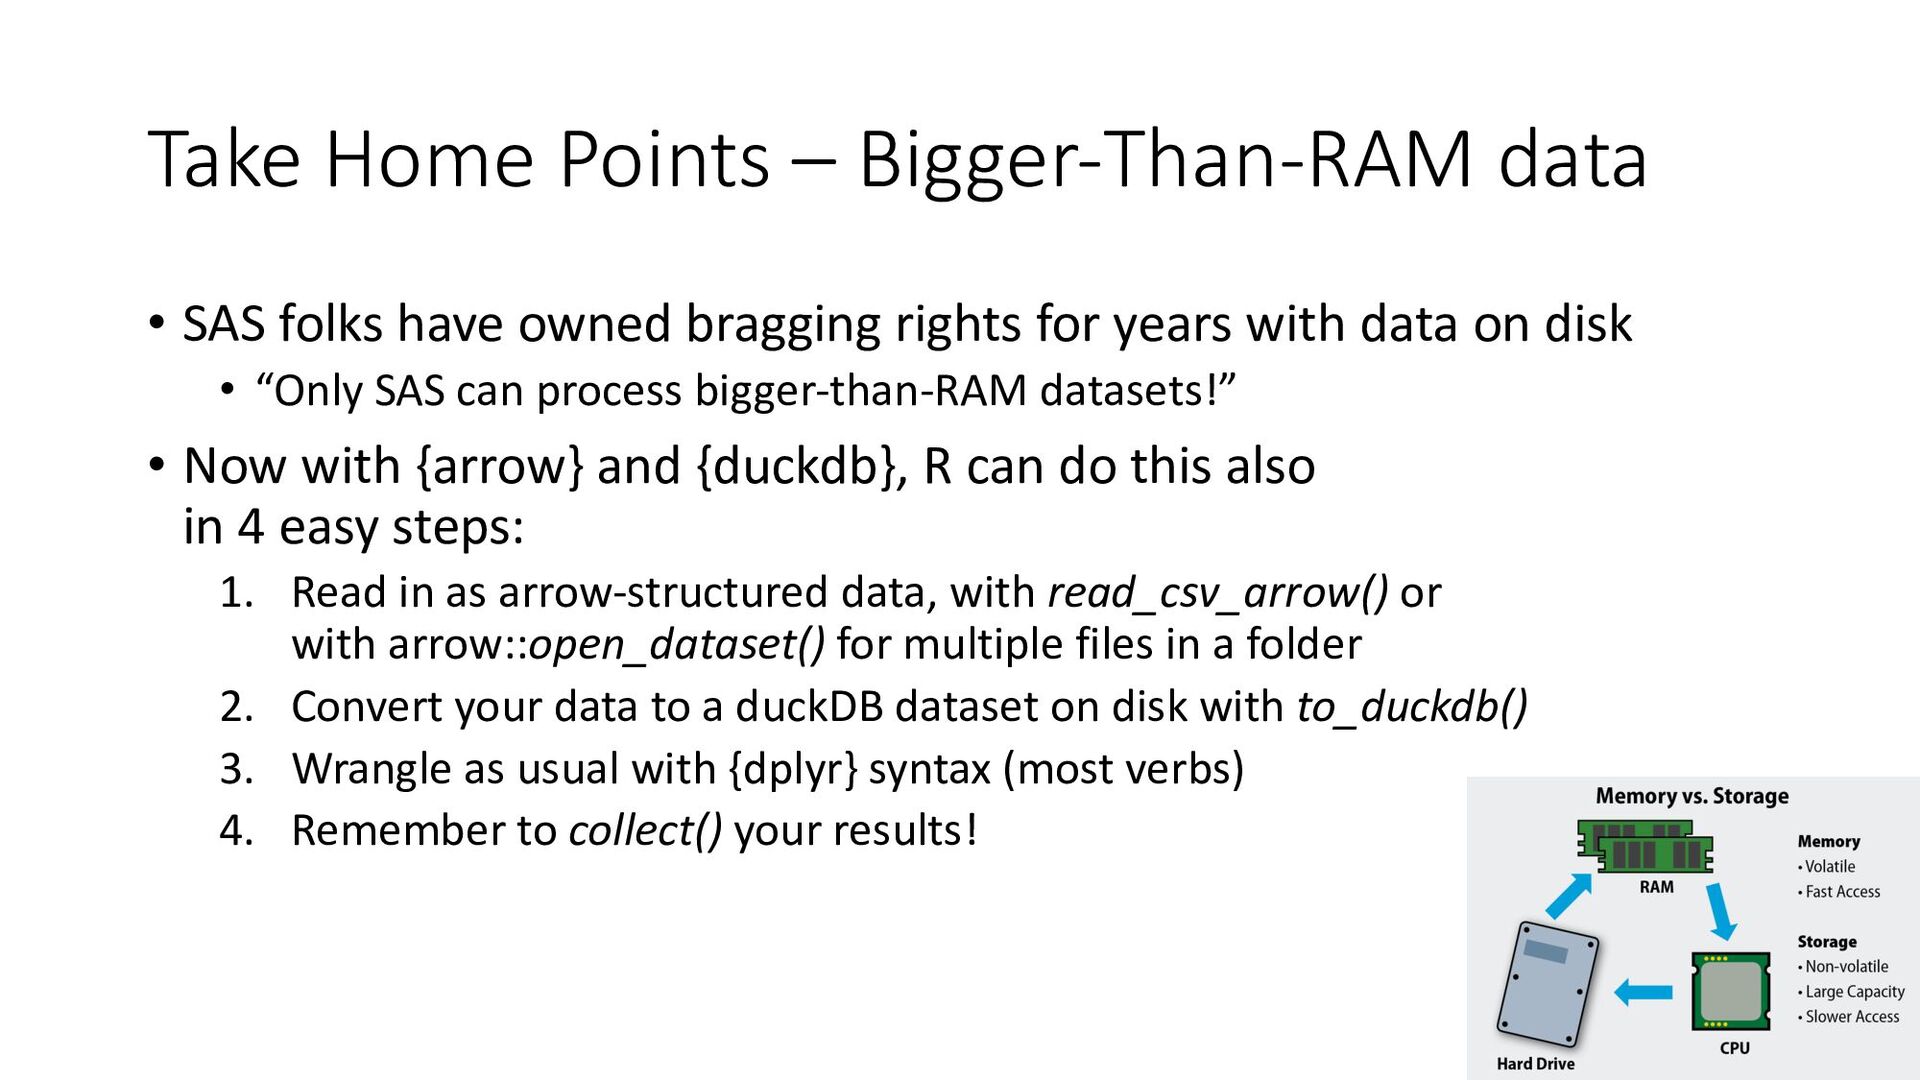
Take Home Points – Bigger-Than-RAM data • SAS folks have
owned bragging rights for years with data on disk • “Only SAS can process bigger-than-RAM datasets!” • Now with {arrow} and {duckdb}, R can do this also in 4 easy steps: 1. Read in as arrow-structured data, with read_csv_arrow() or with arrow::open_dataset() for multiple files in a folder 2. Convert your data to a duckDB dataset on disk with to_duckdb() 3. Wrangle as usual with {dplyr} syntax (most verbs) 4. Remember to collect() your results!