Share
Distributed computing and hyper-parameter tuning with Ray
Come for a while and learn how to execute your Python computations in parallel, to seamlessly scale the training of your machine learning models from a single machine to a cluster, find the right hyper-parameters, or accelerate your Pandas pipelines with large dataframes.
In this talk, we will cover Ray in action with plenty of examples. Ray is a flexible, high-performance distributed execution framework. Ray is well suited to deep learning workflows but its utility goes far beyond that.
Ray has several interesting and unique components, such as actors, or Plasma - an in-memory object store with zero-copy reads (particularly useful for working on large objects), and includes powerful hyper-parameter tuning tools.
We will compare Ray with its alternatives such as Dask or Celery, and see when it is more convenient or where it might even completely replace them.
Jan Margeta
Transcript
50 slides
-
Distributed computing and hyper-parameter tuning with Ray Jan Margeta |
| November 17, 2018 [email protected] @jmargeta -
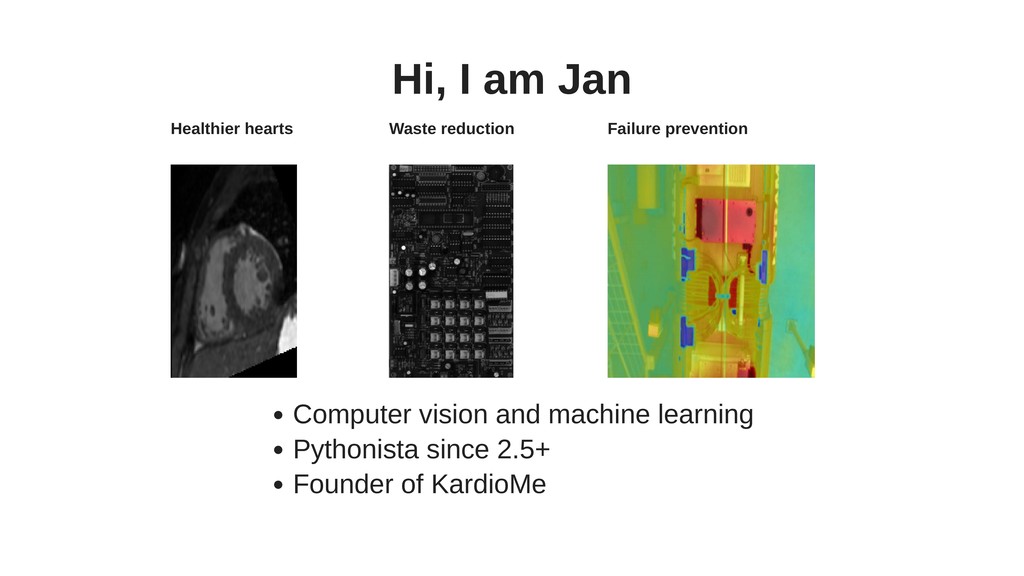
Healthier hearts Waste reduction Failure prevention Hi, I am Jan
Computer vision and machine learning Pythonista since 2.5+ Founder of KardioMe -
Martin Fowler's First rule of distributed objects computing Don't Massive
complexity booster See also Common fallacies of distributed computing -
AND ALSO Resilience cannot be achieved with a single machine
Machine learning workflows often need heterogeneous HW and intensive computations Need to scale up and down on demand ImageNet in 224 seconds -
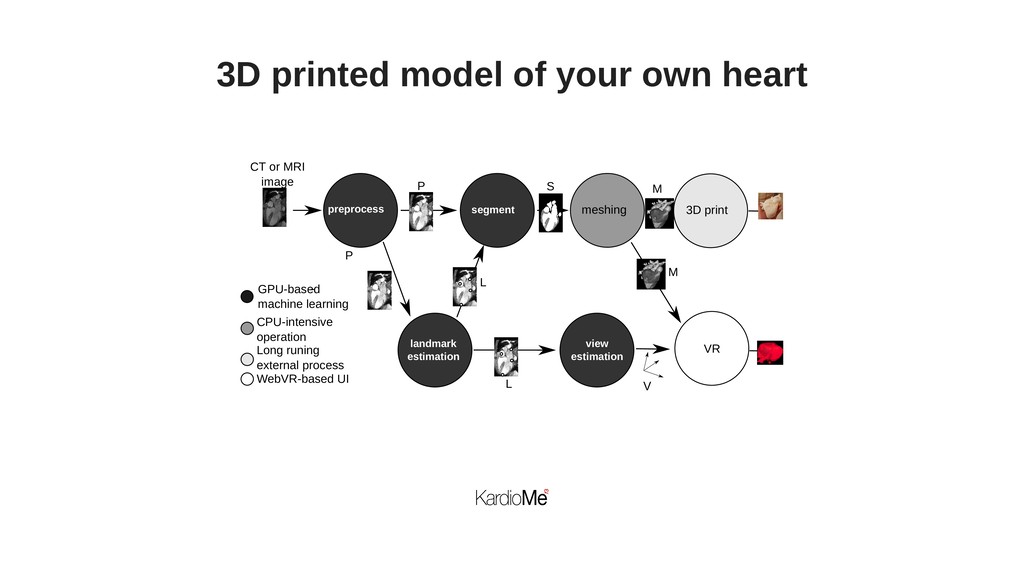
3D printed model of your own heart CT or MRI
image segment preprocess landmark estimation meshing view estimation VR L L P P S M V 3D print M GPU-based machine learning CPU-intensive operation WebVR-based UI - Long runing external process -
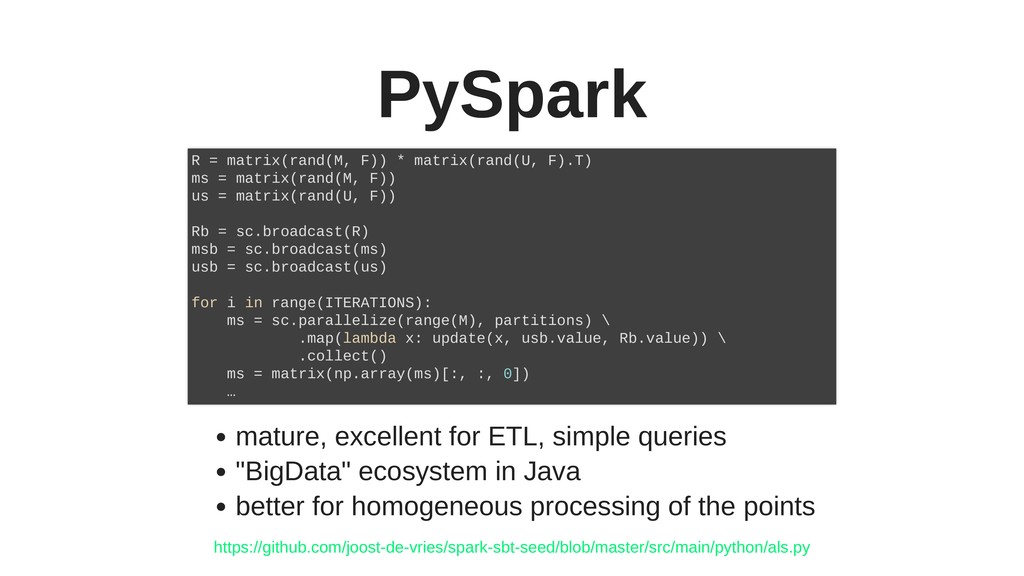
PySpark mature, excellent for ETL, simple queries "BigData" ecosystem in
Java better for homogeneous processing of the points R = matrix(rand(M, F)) * matrix(rand(U, F).T) ms = matrix(rand(M, F)) us = matrix(rand(U, F)) Rb = sc.broadcast(R) msb = sc.broadcast(ms) usb = sc.broadcast(us) for i in range(ITERATIONS): ms = sc.parallelize(range(M), partitions) \ .map(lambda x: update(x, usb.value, Rb.value)) \ .collect() ms = matrix(np.array(ms)[:, :, 0]) … https://github.com/joost-de-vries/spark-sbt-seed/blob/master/src/main/python/als.py -
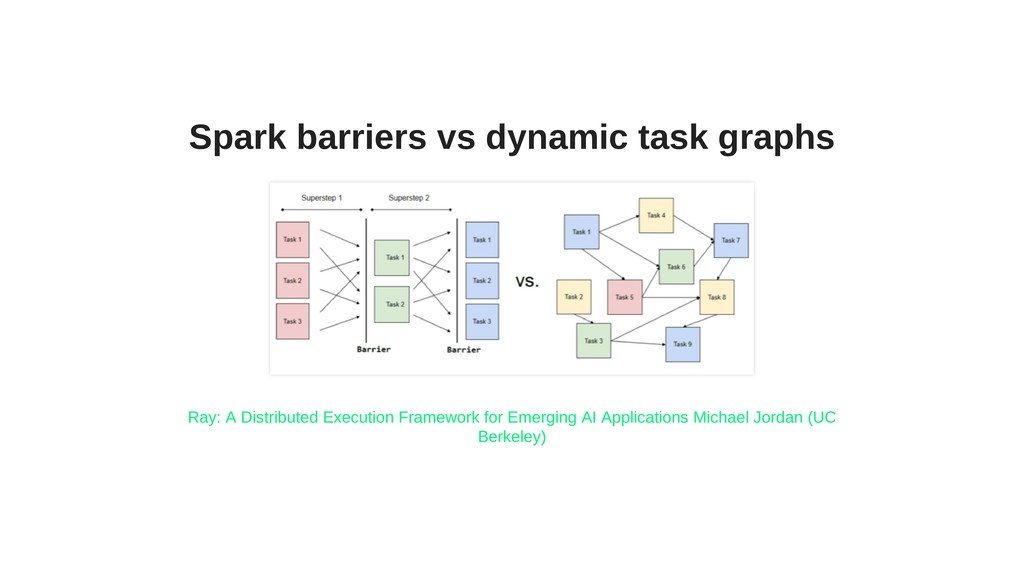
Spark barriers vs dynamic task graphs Ray: A Distributed Execution
Framework for Emerging AI Applications Michael Jordan (UC Berkeley) -
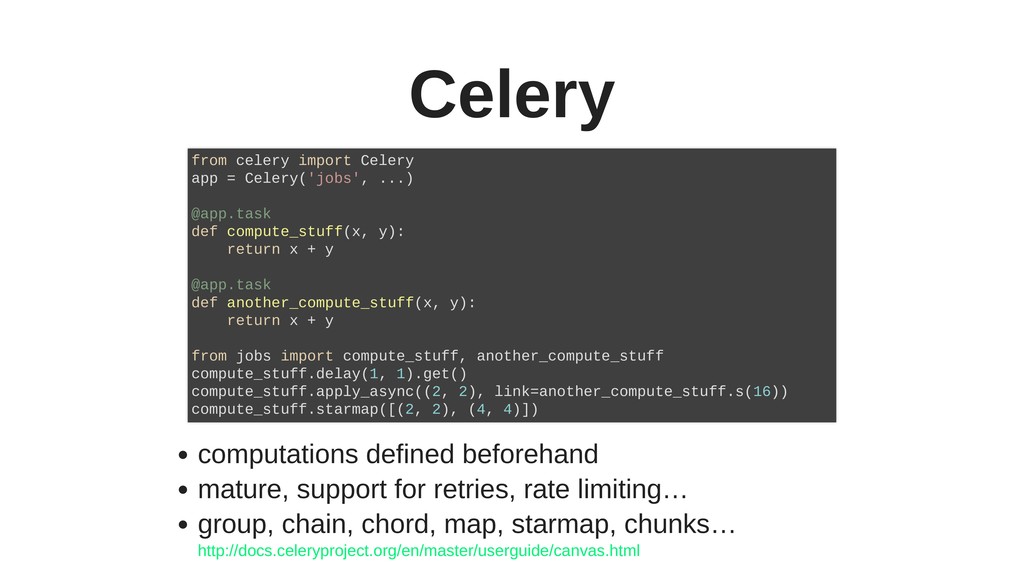
Celery computations defined beforehand mature, support for retries, rate limiting…
group, chain, chord, map, starmap, chunks… from celery import Celery app = Celery('jobs', ...) @app.task def compute_stuff(x, y): return x + y @app.task def another_compute_stuff(x, y): return x + y from jobs import compute_stuff, another_compute_stuff compute_stuff.delay(1, 1).get() compute_stuff.apply_async((2, 2), link=another_compute_stuff.s(16)) compute_stuff.starmap([(2, 2), (4, 4)]) http://docs.celeryproject.org/en/master/userguide/canvas.html -
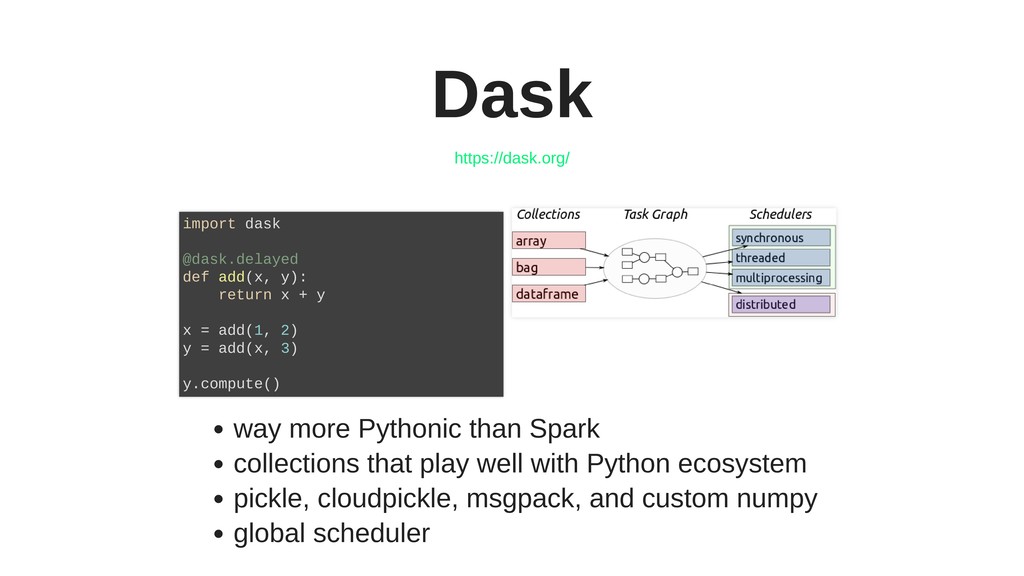
Dask way more Pythonic than Spark collections that play well
with Python ecosystem pickle, cloudpickle, msgpack, and custom numpy global scheduler https://dask.org/ import dask @dask.delayed def add(x, y): return x + y x = add(1, 2) y = add(x, 3) y.compute() -
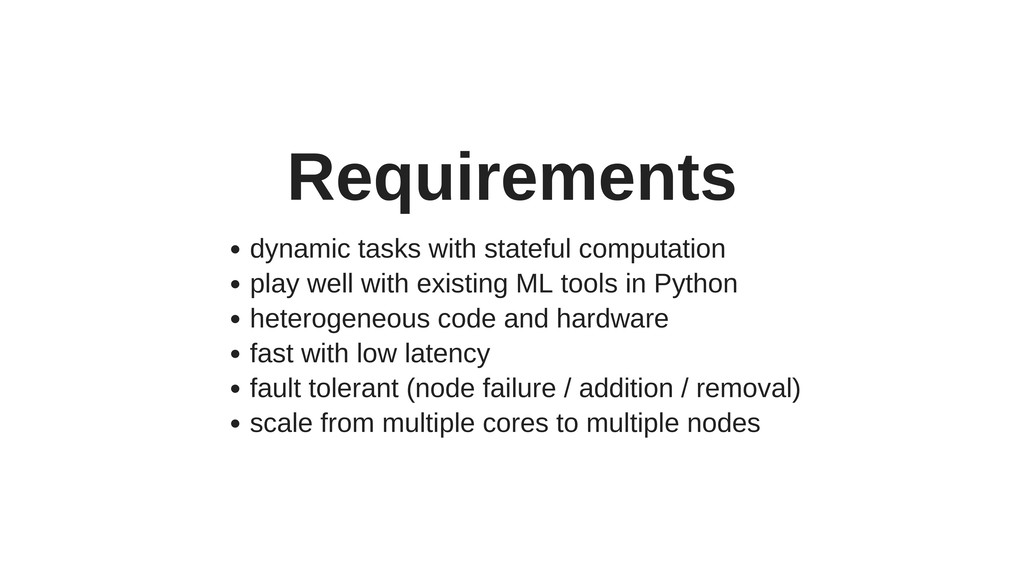
Requirements dynamic tasks with stateful computation play well with existing
ML tools in Python heterogeneous code and hardware fast with low latency fault tolerant (node failure / addition / removal) scale from multiple cores to multiple nodes -
Ray Ray is a general purpose framework for doing parallel
and distributed Python along with a collection of libraries targeting machine data processing workflows. Developed at UC Berkeley as an attempt to replace Spark https://github.com/ray-project/ray -
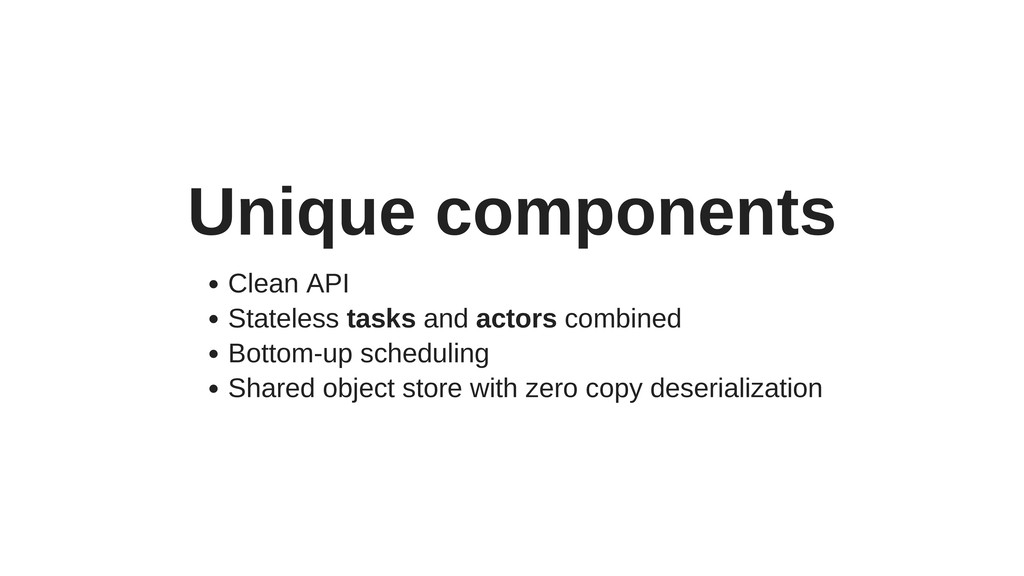
Unique components Clean API Stateless tasks and actors combined Bottom-up
scheduling Shared object store with zero copy deserialization -
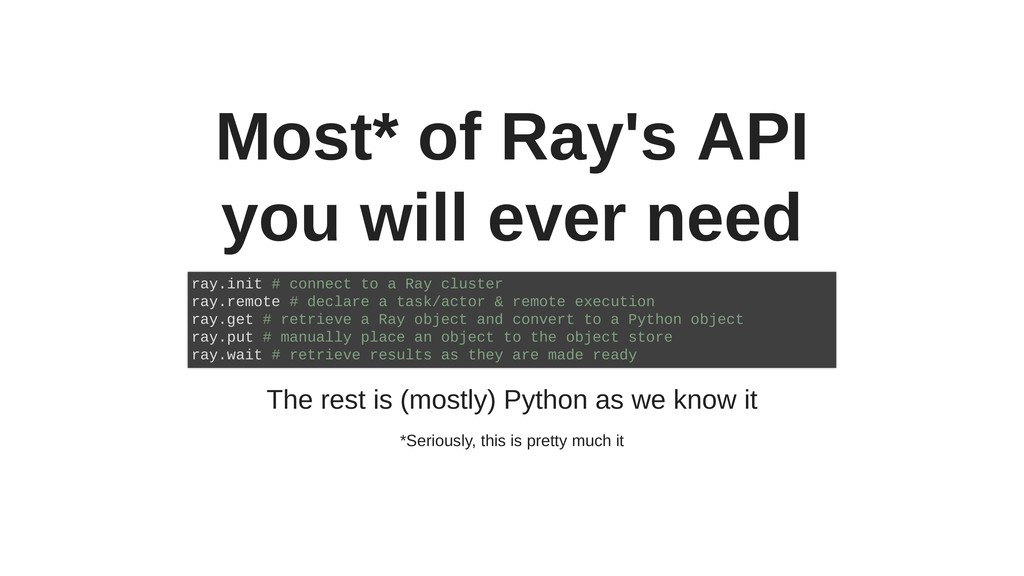
Most* of Ray's API you will ever need The rest
is (mostly) Python as we know it *Seriously, this is pretty much it ray.init # connect to a Ray cluster ray.remote # declare a task/actor & remote execution ray.get # retrieve a Ray object and convert to a Python object ray.put # manually place an object to the object store ray.wait # retrieve results as they are made ready -
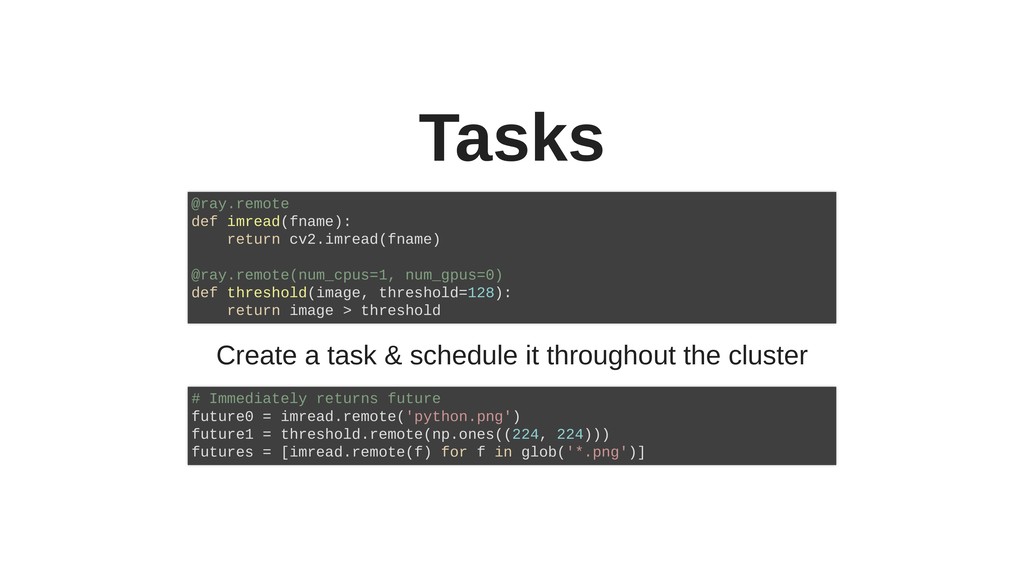
Tasks Create a task & schedule it throughout the cluster
@ray.remote def imread(fname): return cv2.imread(fname) @ray.remote(num_cpus=1, num_gpus=0) def threshold(image, threshold=128): return image > threshold # Immediately returns future future0 = imread.remote('python.png') future1 = threshold.remote(np.ones((224, 224))) futures = [imread.remote(f) for f in glob('*.png')] -
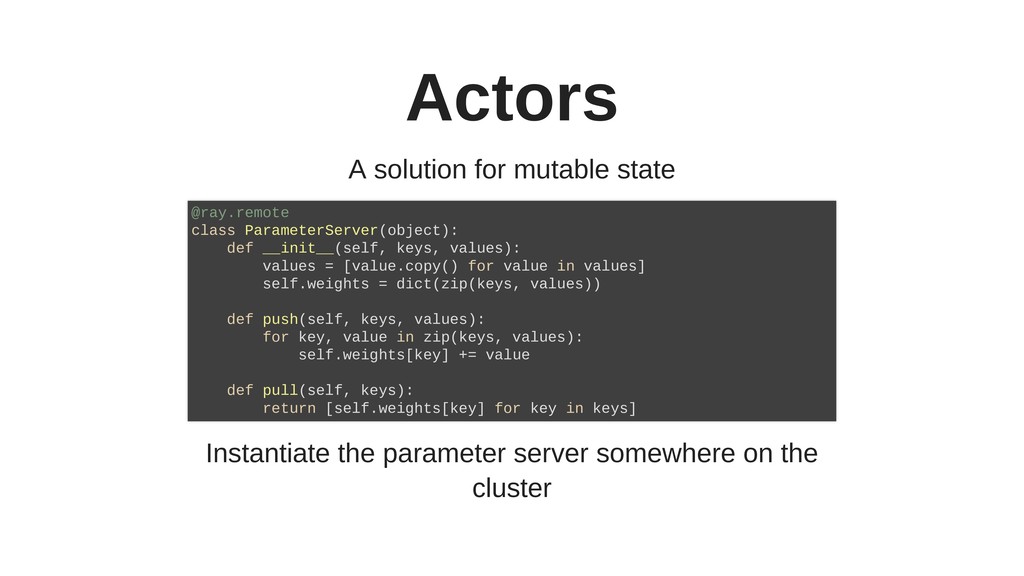
Actors A solution for mutable state Instantiate the parameter server
somewhere on the cluster @ray.remote class ParameterServer(object): def __init__(self, keys, values): values = [value.copy() for value in values] self.weights = dict(zip(keys, values)) def push(self, keys, values): for key, value in zip(keys, values): self.weights[key] += value def pull(self, keys): return [self.weights[key] for key in keys] -
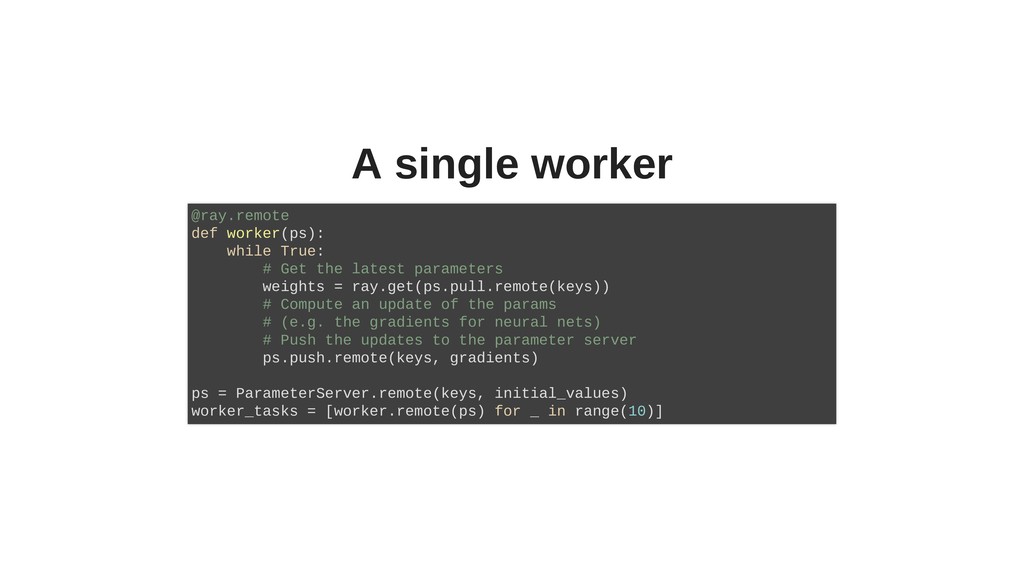
A single worker @ray.remote def worker(ps): while True: # Get
the latest parameters weights = ray.get(ps.pull.remote(keys)) # Compute an update of the params # (e.g. the gradients for neural nets) # Push the updates to the parameter server ps.push.remote(keys, gradients) ps = ParameterServer.remote(keys, initial_values) worker_tasks = [worker.remote(ps) for _ in range(10)] -
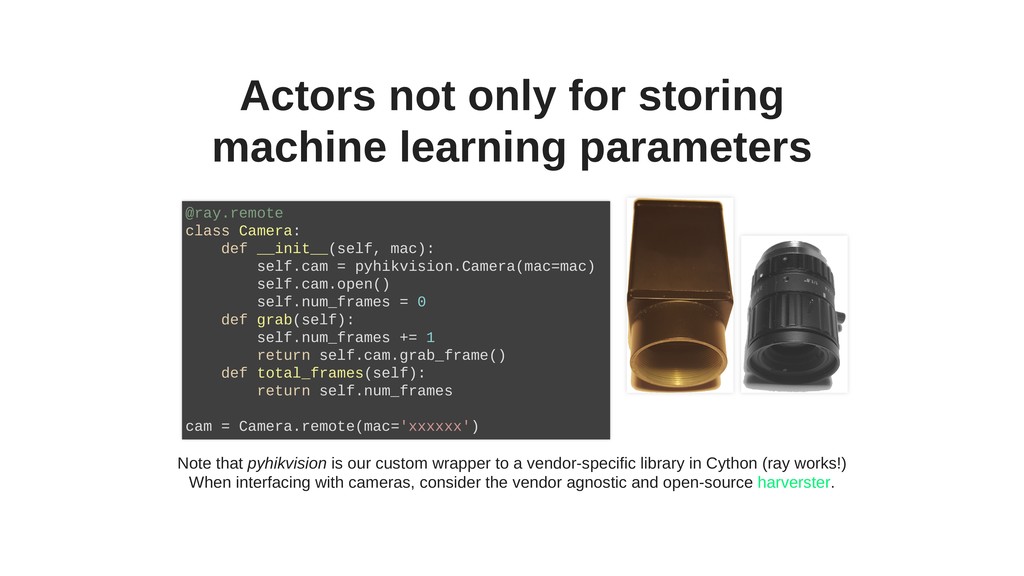
Actors not only for storing machine learning parameters Note that
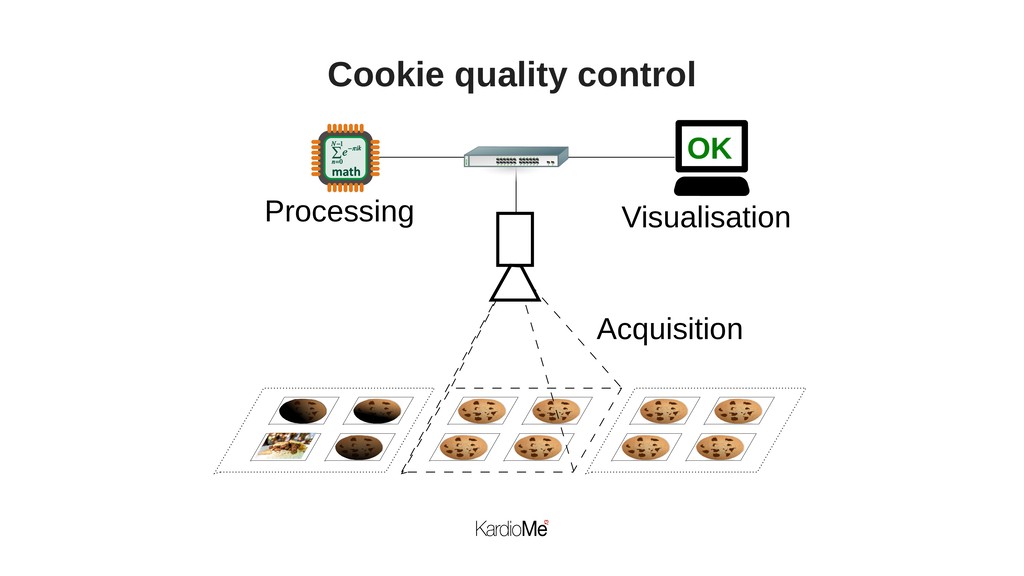
pyhikvision is our custom wrapper to a vendor-specific library in Cython (ray works!) When interfacing with cameras, consider the vendor agnostic and open-source . @ray.remote class Camera: def __init__(self, mac): self.cam = pyhikvision.Camera(mac=mac) self.cam.open() self.num_frames = 0 def grab(self): self.num_frames += 1 return self.cam.grab_frame() def total_frames(self): return self.num_frames cam = Camera.remote(mac='xxxxxx') harverster -
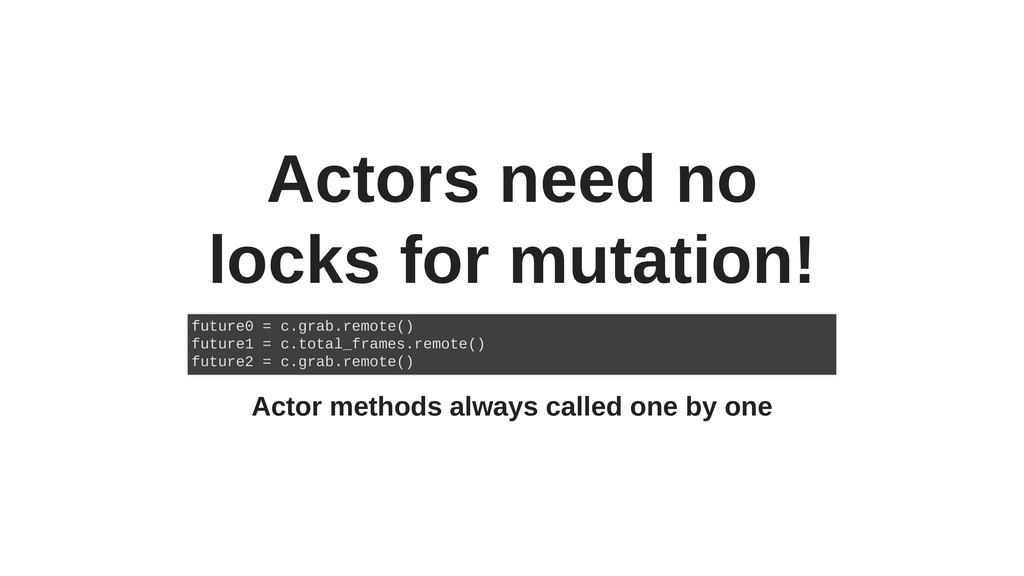
Actors need no locks for mutation! Actor methods always called
one by one future0 = c.grab.remote() future1 = c.total_frames.remote() future2 = c.grab.remote() -
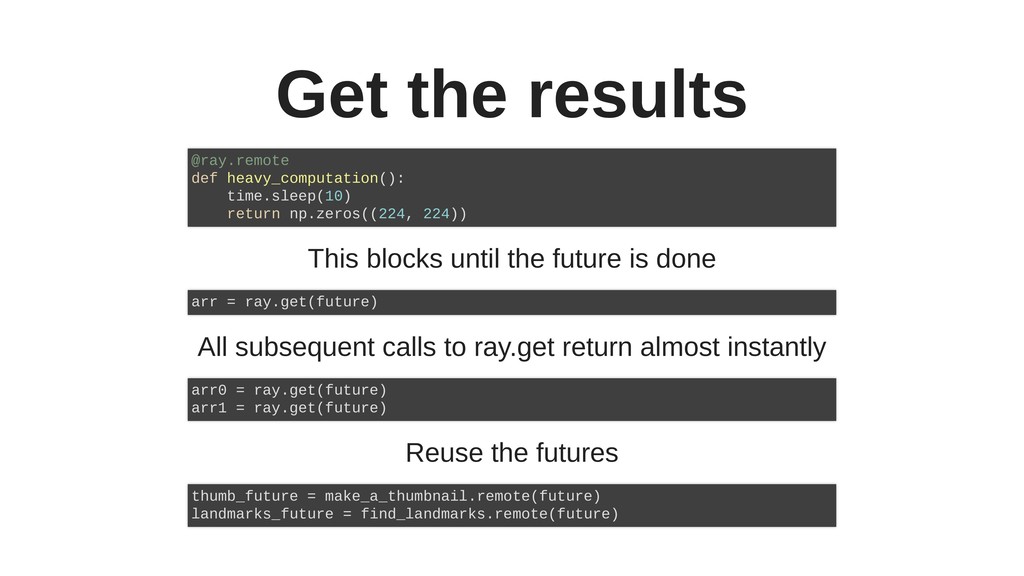
Get the results This blocks until the future is done
All subsequent calls to ray.get return almost instantly Reuse the futures @ray.remote def heavy_computation(): time.sleep(10) return np.zeros((224, 224)) arr = ray.get(future) arr0 = ray.get(future) arr1 = ray.get(future) thumb_future = make_a_thumbnail.remote(future) landmarks_future = find_landmarks.remote(future) -
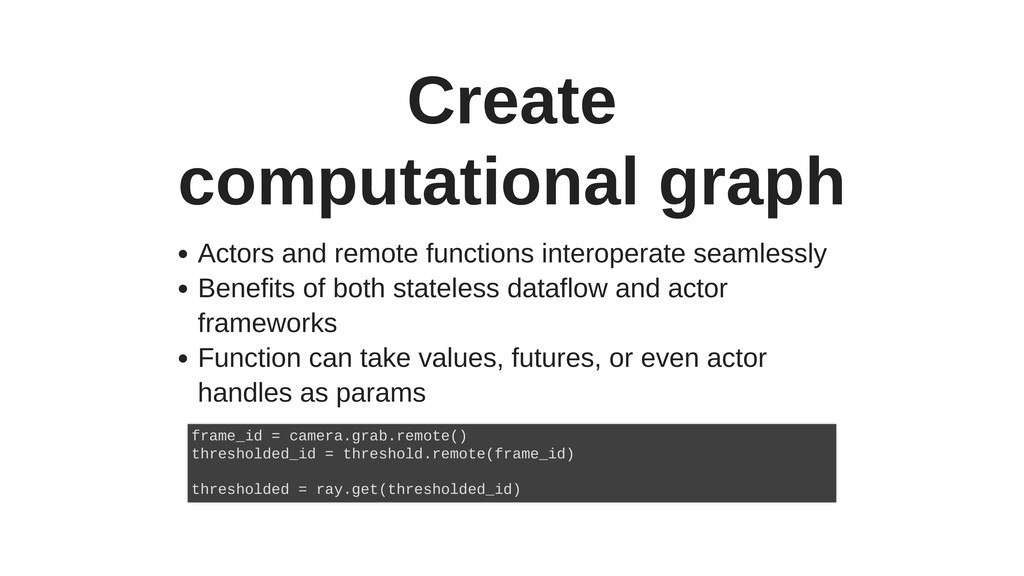
Create computational graph Actors and remote functions interoperate seamlessly Benefits
of both stateless dataflow and actor frameworks Function can take values, futures, or even actor handles as params frame_id = camera.grab.remote() thresholded_id = threshold.remote(frame_id) thresholded = ray.get(thresholded_id) -
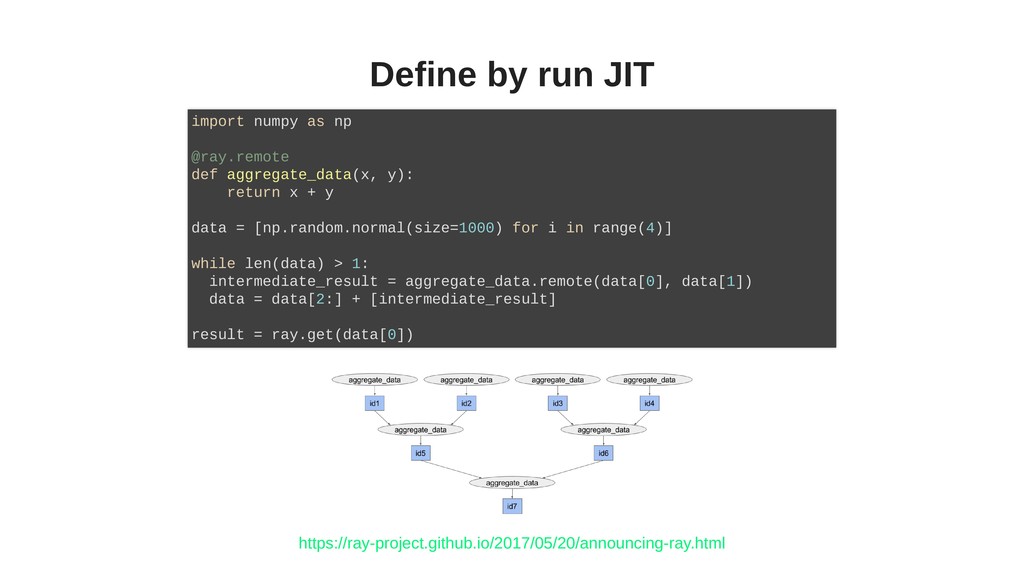
Define by run JIT import numpy as np @ray.remote def
aggregate_data(x, y): return x + y data = [np.random.normal(size=1000) for i in range(4)] while len(data) > 1: intermediate_result = aggregate_data.remote(data[0], data[1]) data = data[2:] + [intermediate_result] result = ray.get(data[0]) https://ray-project.github.io/2017/05/20/announcing-ray.html -
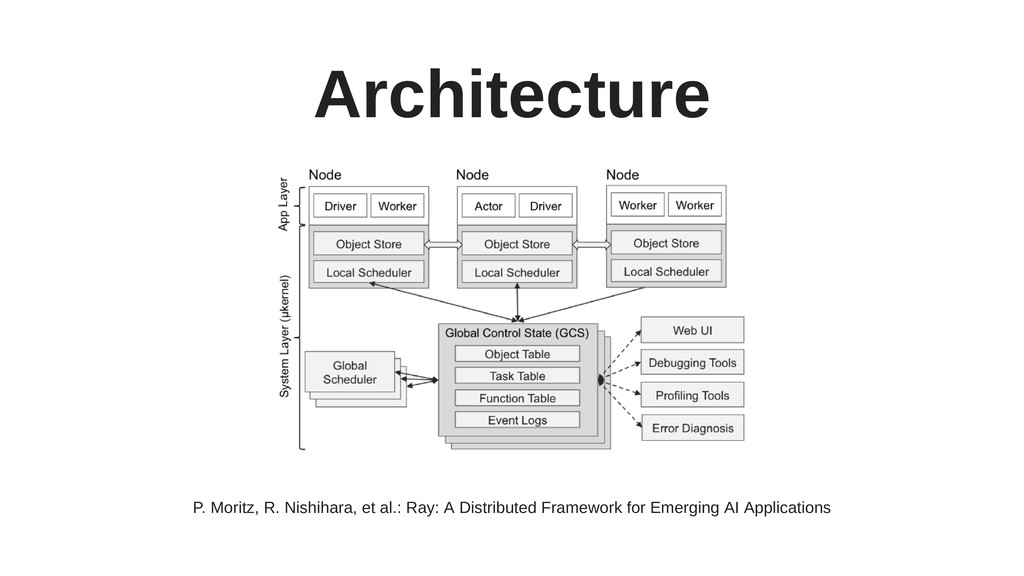
Architecture P. Moritz, R. Nishihara, et al.: Ray: A Distributed
Framework for Emerging AI Applications -
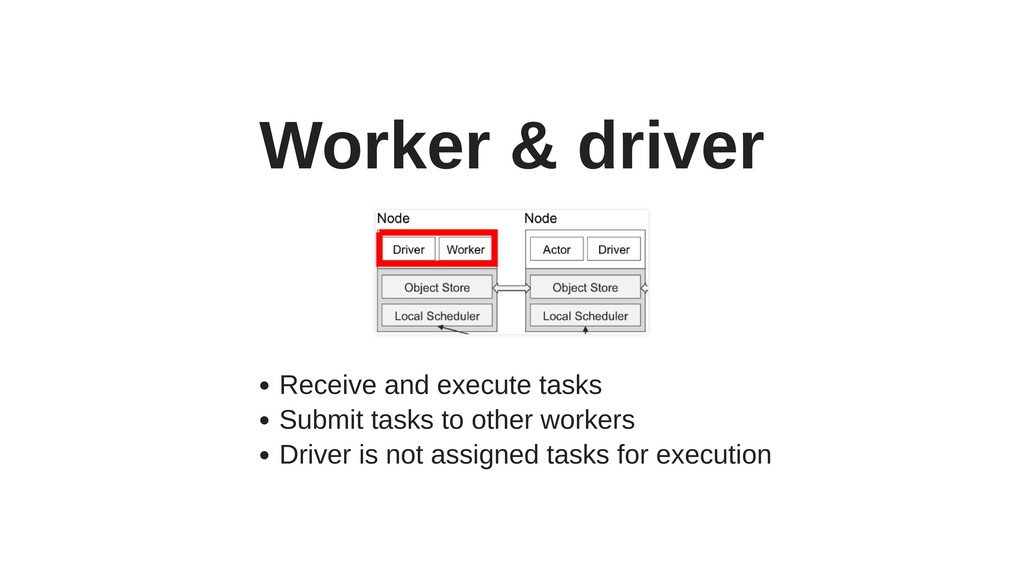
Worker & driver Receive and execute tasks Submit tasks to
other workers Driver is not assigned tasks for execution -
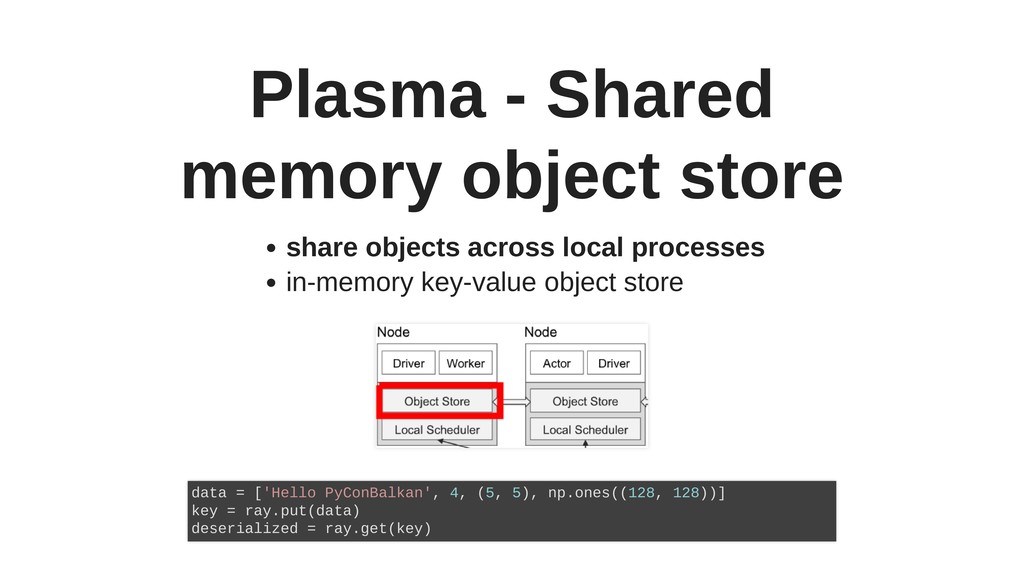
Plasma - Shared memory object store share objects across local
processes in-memory key-value object store data = ['Hello PyConBalkan', 4, (5, 5), np.ones((128, 128))] key = ray.put(data) deserialized = ray.get(key) -
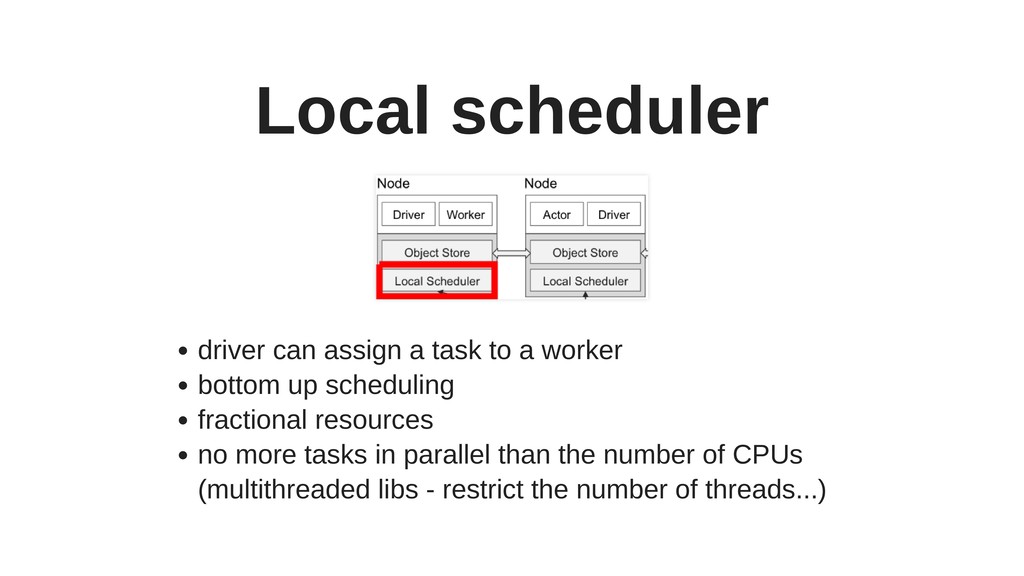
Local scheduler driver can assign a task to a worker
bottom up scheduling fractional resources no more tasks in parallel than the number of CPUs (multithreaded libs - restrict the number of threads...) -
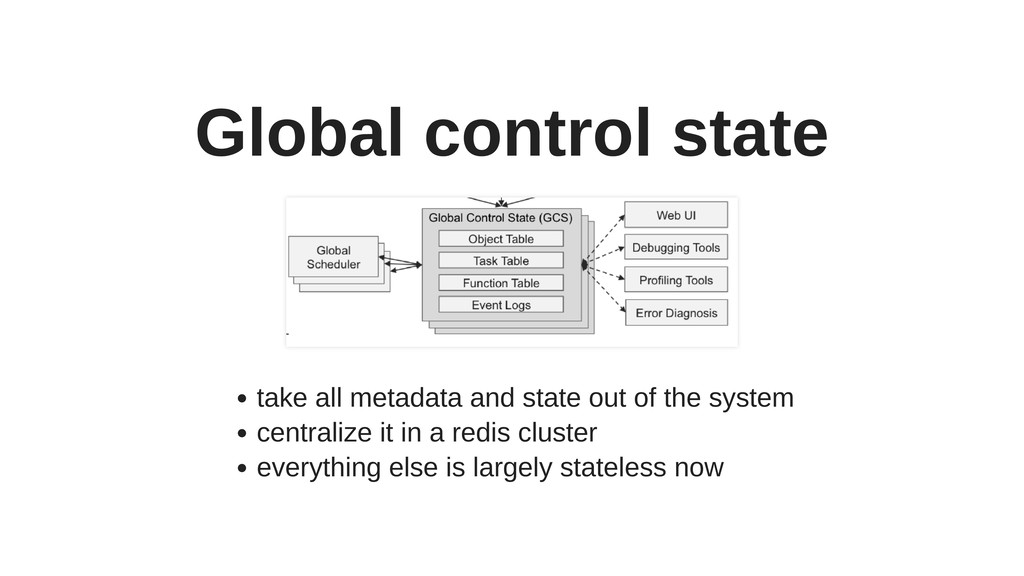
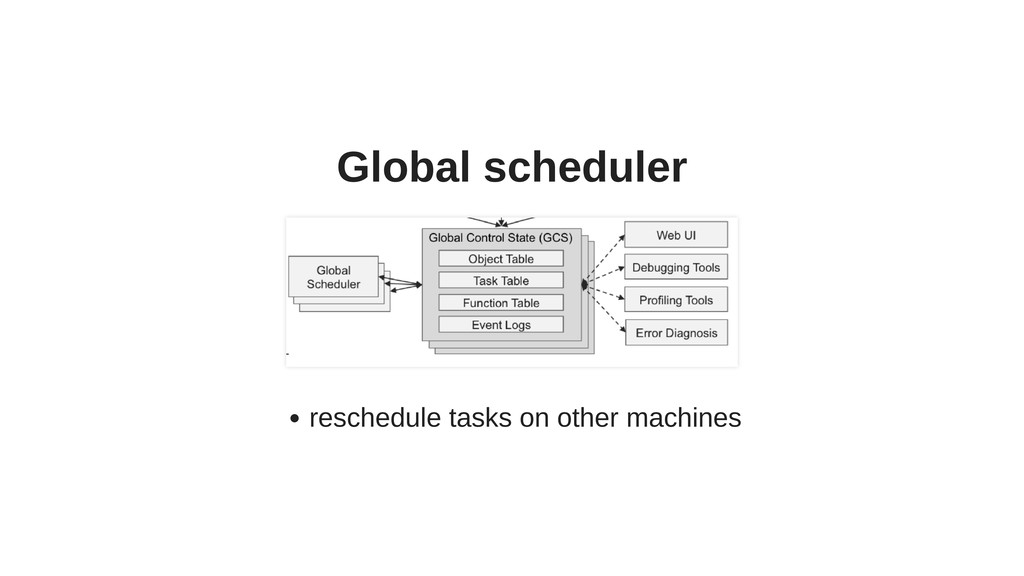
Global control state take all metadata and state out of
the system centralize it in a redis cluster everything else is largely stateless now -
Fault-tolerance Failover to other nodes based on the global control
state non actors lineage base - rerun the tasks to reconstruct actors (in the future) recreate actor from the beginning -
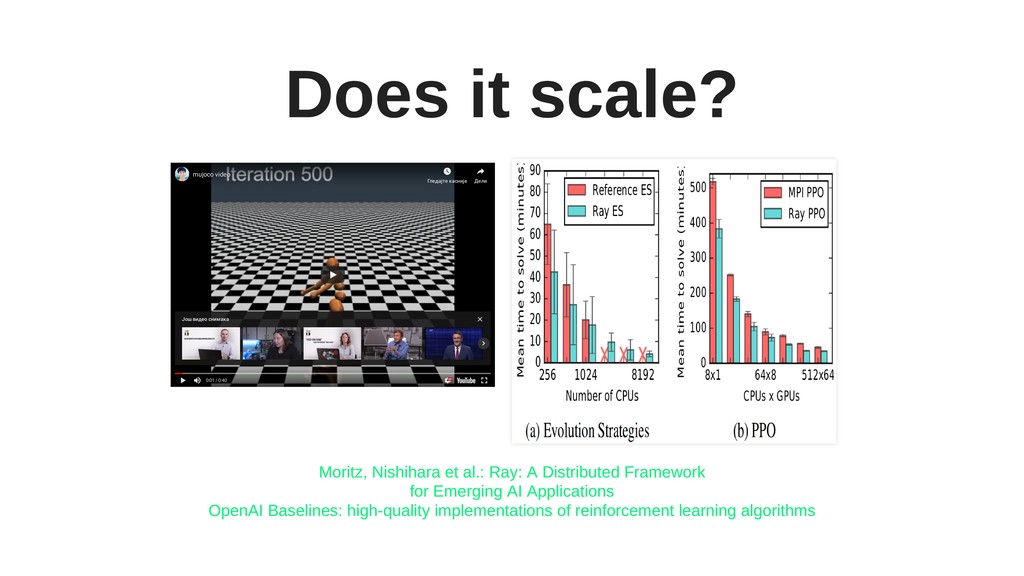
Does it scale? Још видео снимака mujoco video Гледајте касније
Дели 0:01 / 0:40 Moritz, Nishihara et al.: Ray: A Distributed Framework for Emerging AI Applications OpenAI Baselines: high-quality implementations of reinforcement learning algorithms -
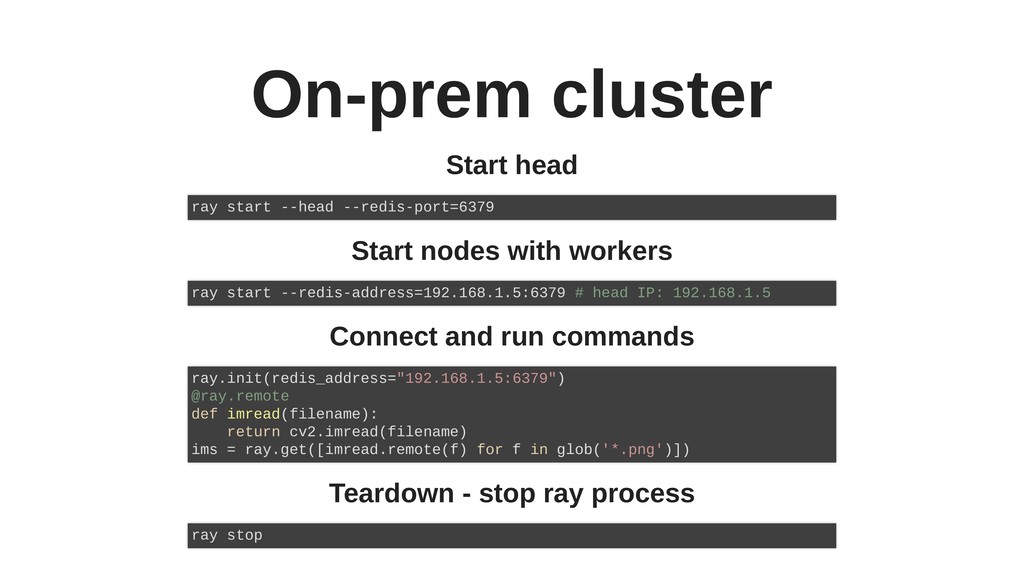
On-prem cluster Start head Start nodes with workers Connect and
run commands Teardown - stop ray process ray start --head --redis-port=6379 ray start --redis-address=192.168.1.5:6379 # head IP: 192.168.1.5 ray.init(redis_address="192.168.1.5:6379") @ray.remote def imread(filename): return cv2.imread(filename) ims = ray.get([imread.remote(f) for f in glob('*.png')]) ray stop -
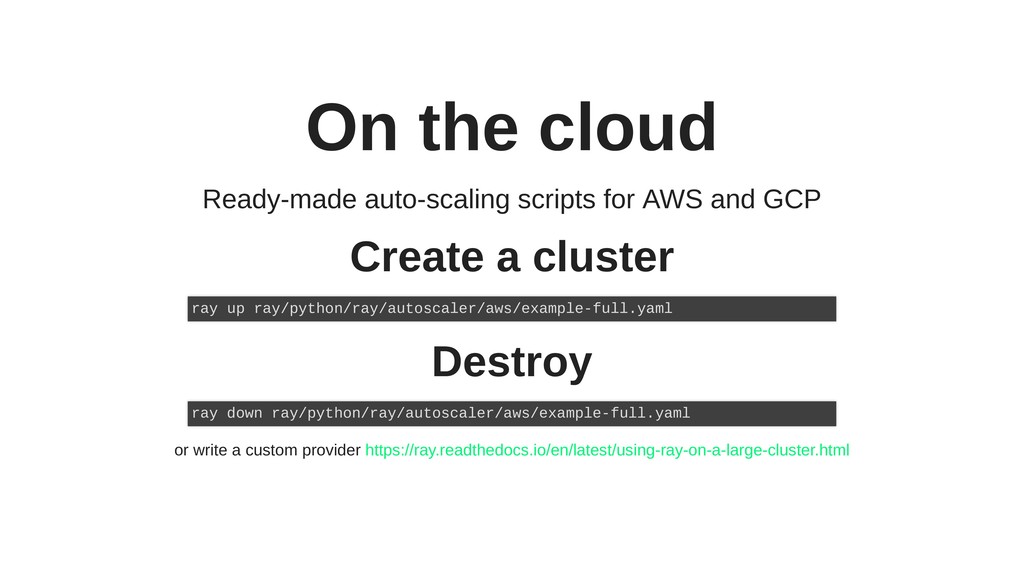
On the cloud Ready-made auto-scaling scripts for AWS and GCP
Create a cluster Destroy or write a custom provider ray up ray/python/ray/autoscaler/aws/example-full.yaml ray down ray/python/ray/autoscaler/aws/example-full.yaml https://ray.readthedocs.io/en/latest/using-ray-on-a-large-cluster.html -
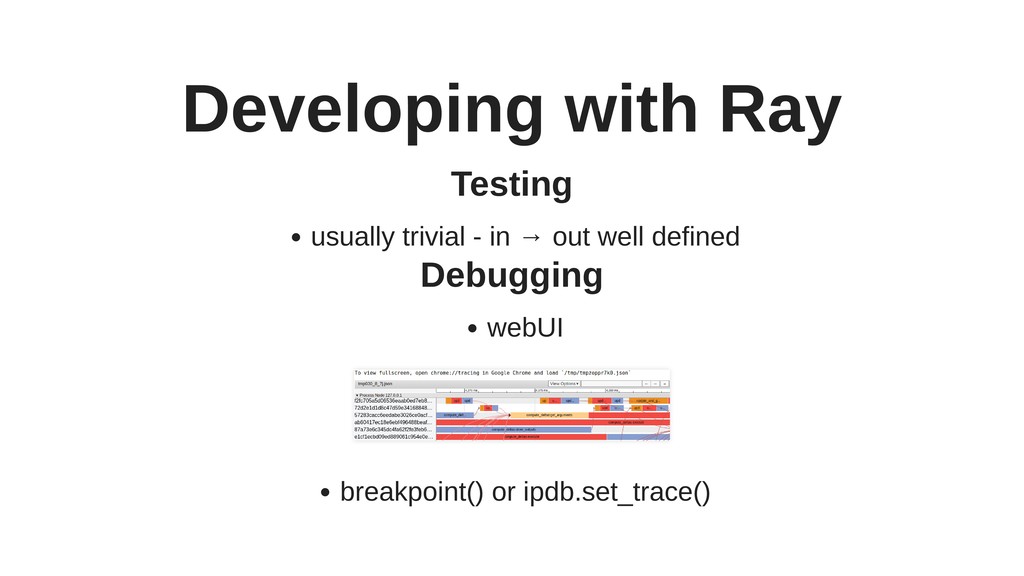
Developing with Ray Testing usually trivial - in → out
well defined Debugging webUI breakpoint() or ipdb.set_trace() -
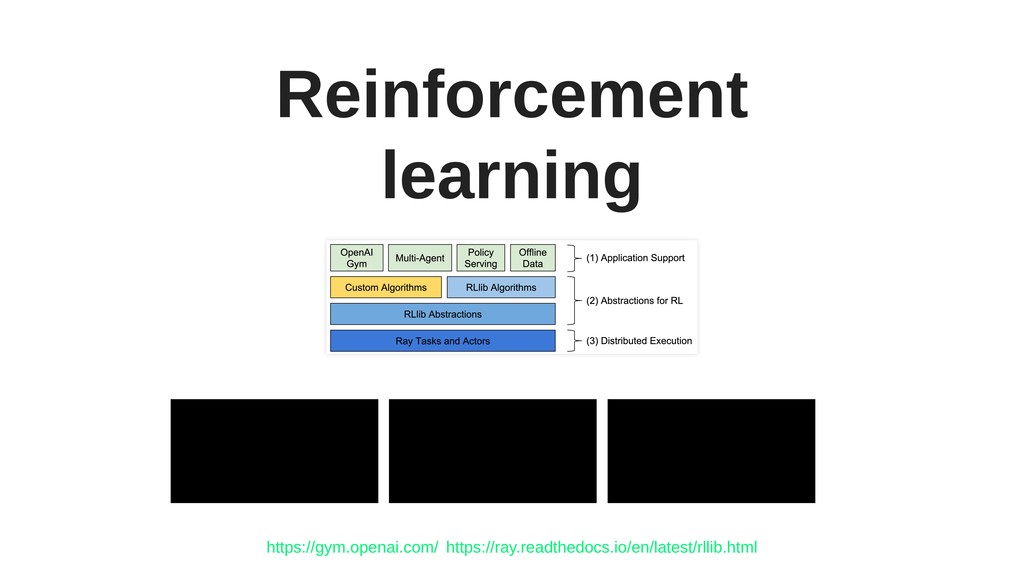
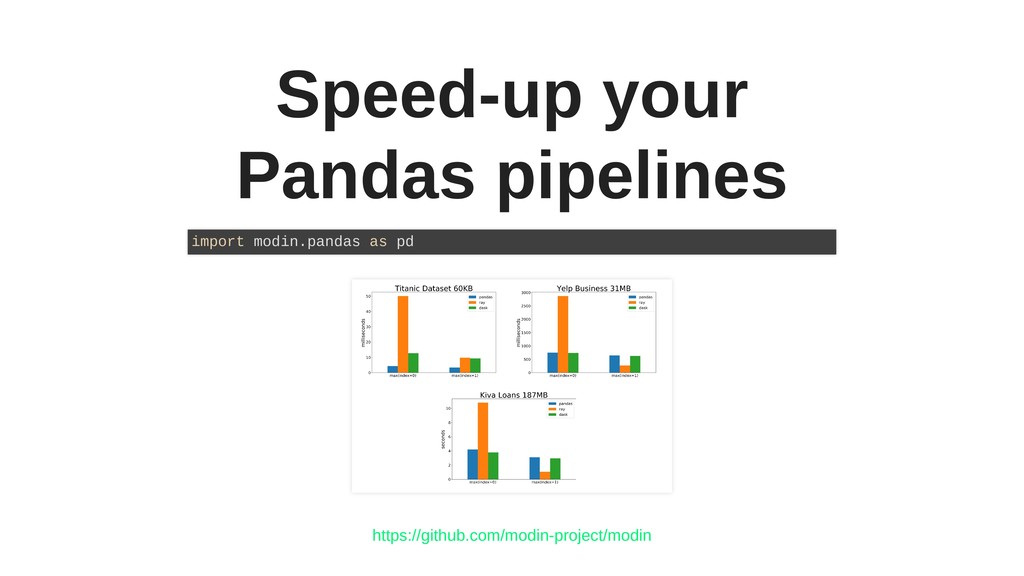
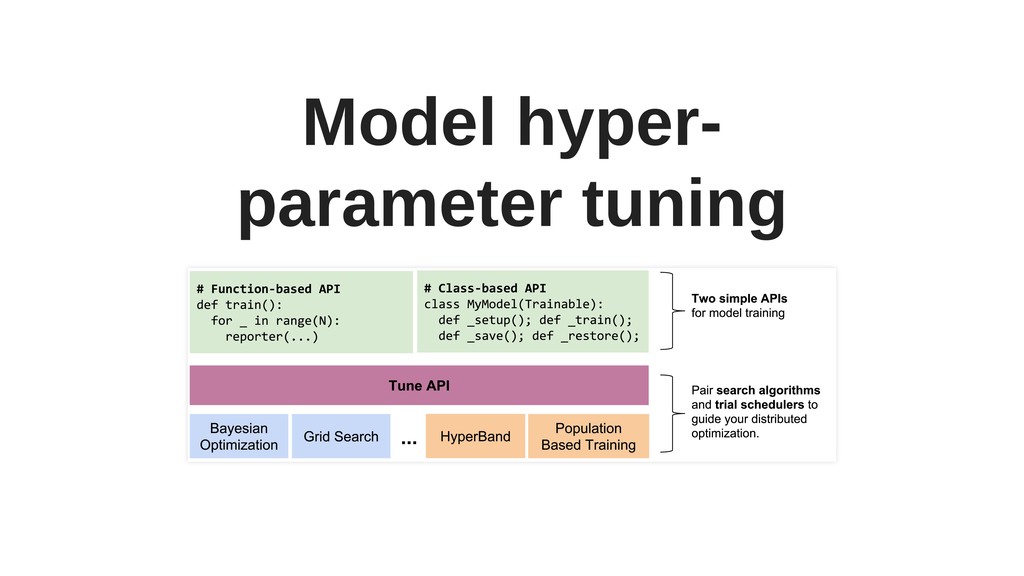
Higher level libs built on top of Ray Tune rllib
modin distributed linear algebra … -
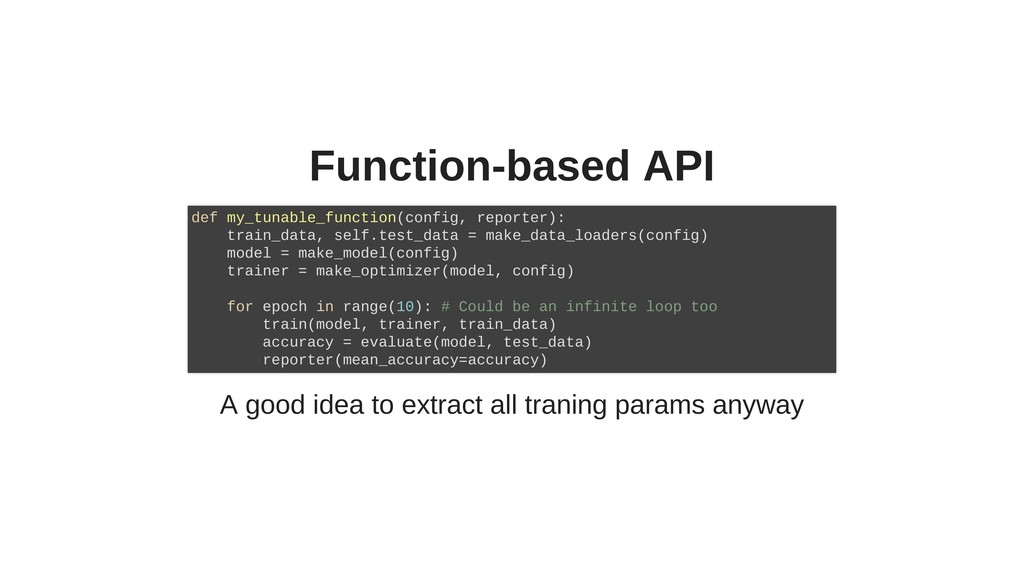
Function-based API A good idea to extract all traning params
anyway def my_tunable_function(config, reporter): train_data, self.test_data = make_data_loaders(config) model = make_model(config) trainer = make_optimizer(model, config) for epoch in range(10): # Could be an infinite loop too train(model, trainer, train_data) accuracy = evaluate(model, test_data) reporter(mean_accuracy=accuracy) -
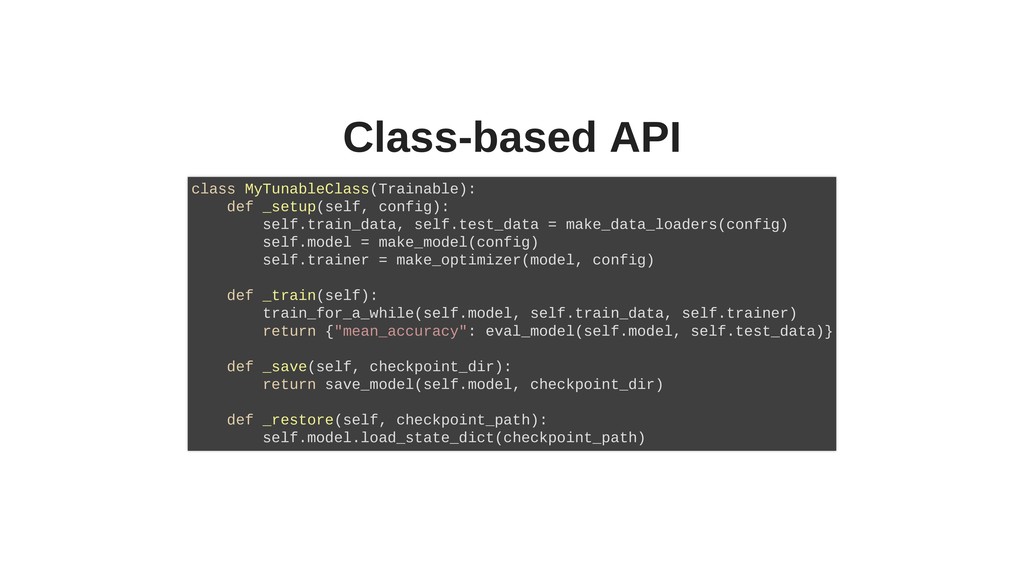
Class-based API class MyTunableClass(Trainable): def _setup(self, config): self.train_data, self.test_data =
make_data_loaders(config) self.model = make_model(config) self.trainer = make_optimizer(model, config) def _train(self): train_for_a_while(self.model, self.train_data, self.trainer) return {"mean_accuracy": eval_model(self.model, self.test_data)} def _save(self, checkpoint_dir): return save_model(self.model, checkpoint_dir) def _restore(self, checkpoint_path): self.model.load_state_dict(checkpoint_path) -
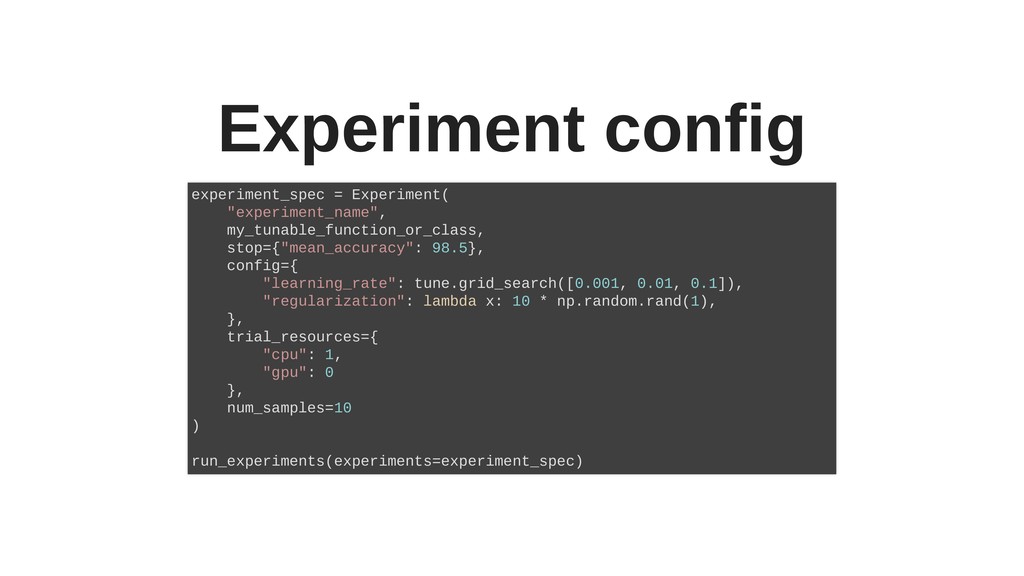
Experiment config experiment_spec = Experiment( "experiment_name", my_tunable_function_or_class, stop={"mean_accuracy": 98.5}, config={
"learning_rate": tune.grid_search([0.001, 0.01, 0.1]), "regularization": lambda x: 10 * np.random.rand(1), }, trial_resources={ "cpu": 1, "gpu": 0 }, num_samples=10 ) run_experiments(experiments=experiment_spec) -
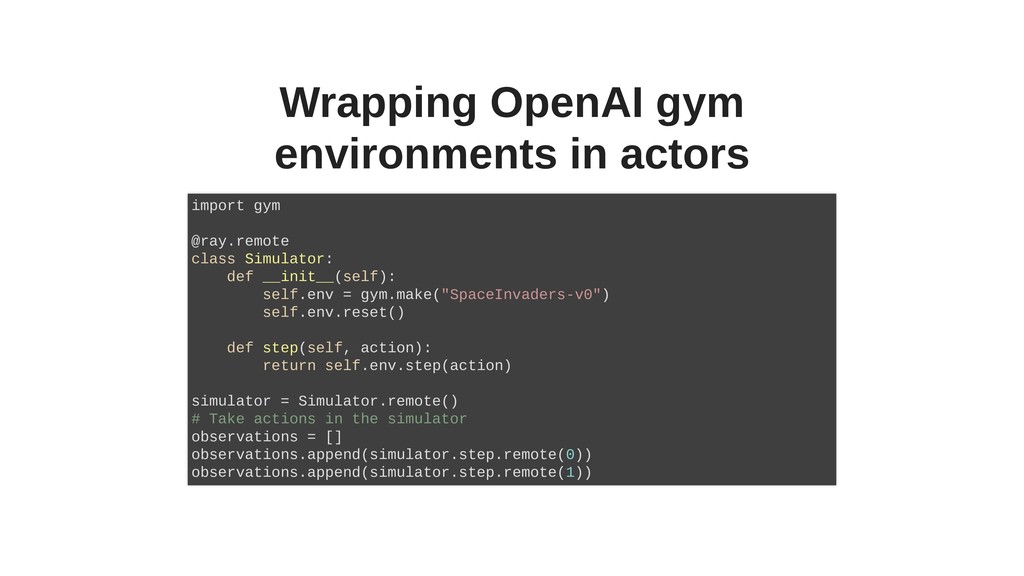
Wrapping OpenAI gym environments in actors import gym @ray.remote class
Simulator: def __init__(self): self.env = gym.make("SpaceInvaders-v0") self.env.reset() def step(self, action): return self.env.step(action) simulator = Simulator.remote() # Take actions in the simulator observations = [] observations.append(simulator.step.remote(0)) observations.append(simulator.step.remote(1)) -
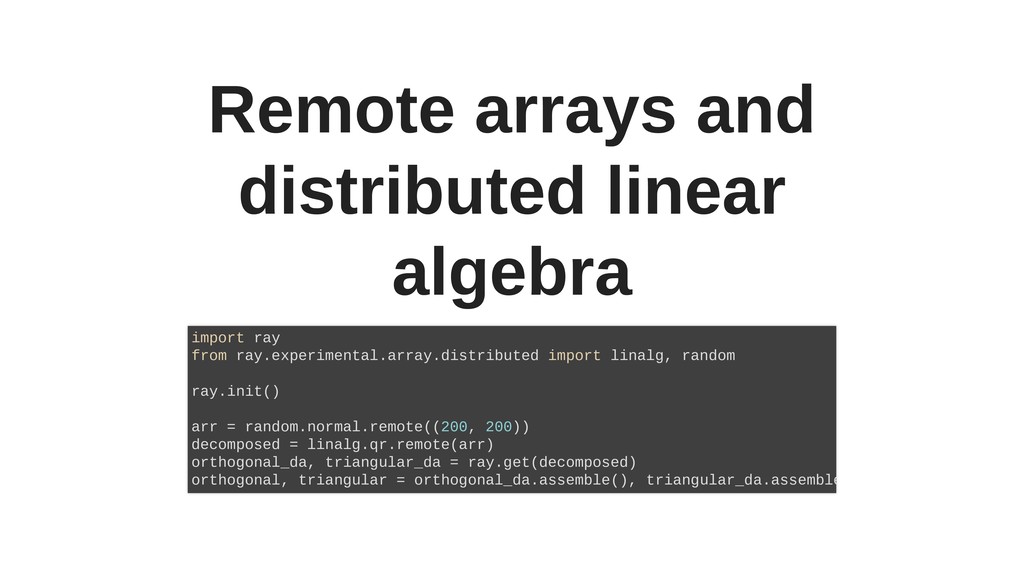
Remote arrays and distributed linear algebra import ray from ray.experimental.array.distributed
import linalg, random ray.init() arr = random.normal.remote((200, 200)) decomposed = linalg.qr.remote(arr) orthogonal_da, triangular_da = ray.get(decomposed) orthogonal, triangular = orthogonal_da.assemble(), triangular_da.assemble -
Conclusion A little teaser of Ray Build and scale your
ML and other tools Systems that adapt, learn online Even locally as an alternative to threads and processes Check out Ray's fantatic tutorials pip install ray -
Thanks! Distributed computing and hyper-parameter tuning with Ray Jan Margeta
| | November 17, 2018 [email protected] @jmargeta -
Read more Butcher - Seven concurrency models in seven weeks
A note on distributed computing - Waldo J. et al. Herb sutter - Free lunch is over Fallacies of distrib. computing explained - Rotem-Gal- Oz Fallacies of distrib. computing - P. Deutsch Ray docs Ray tutorial Plasma store Plasma store and Arrow Scaling Python modules witih ray framework -
Read more Ray - a cluster computing engine for reinforcement
learning applictions https://ray-project.github.io/2018/07/15/parameter- server-in-fifteen-lines.html Robert Nishihara - Ray: A Distributed Execution Framework for AI | SciPy 2018 M. Rocklin - Dask and Celery Dask comparison to Spark Ray: A Distributed System for AI Resources