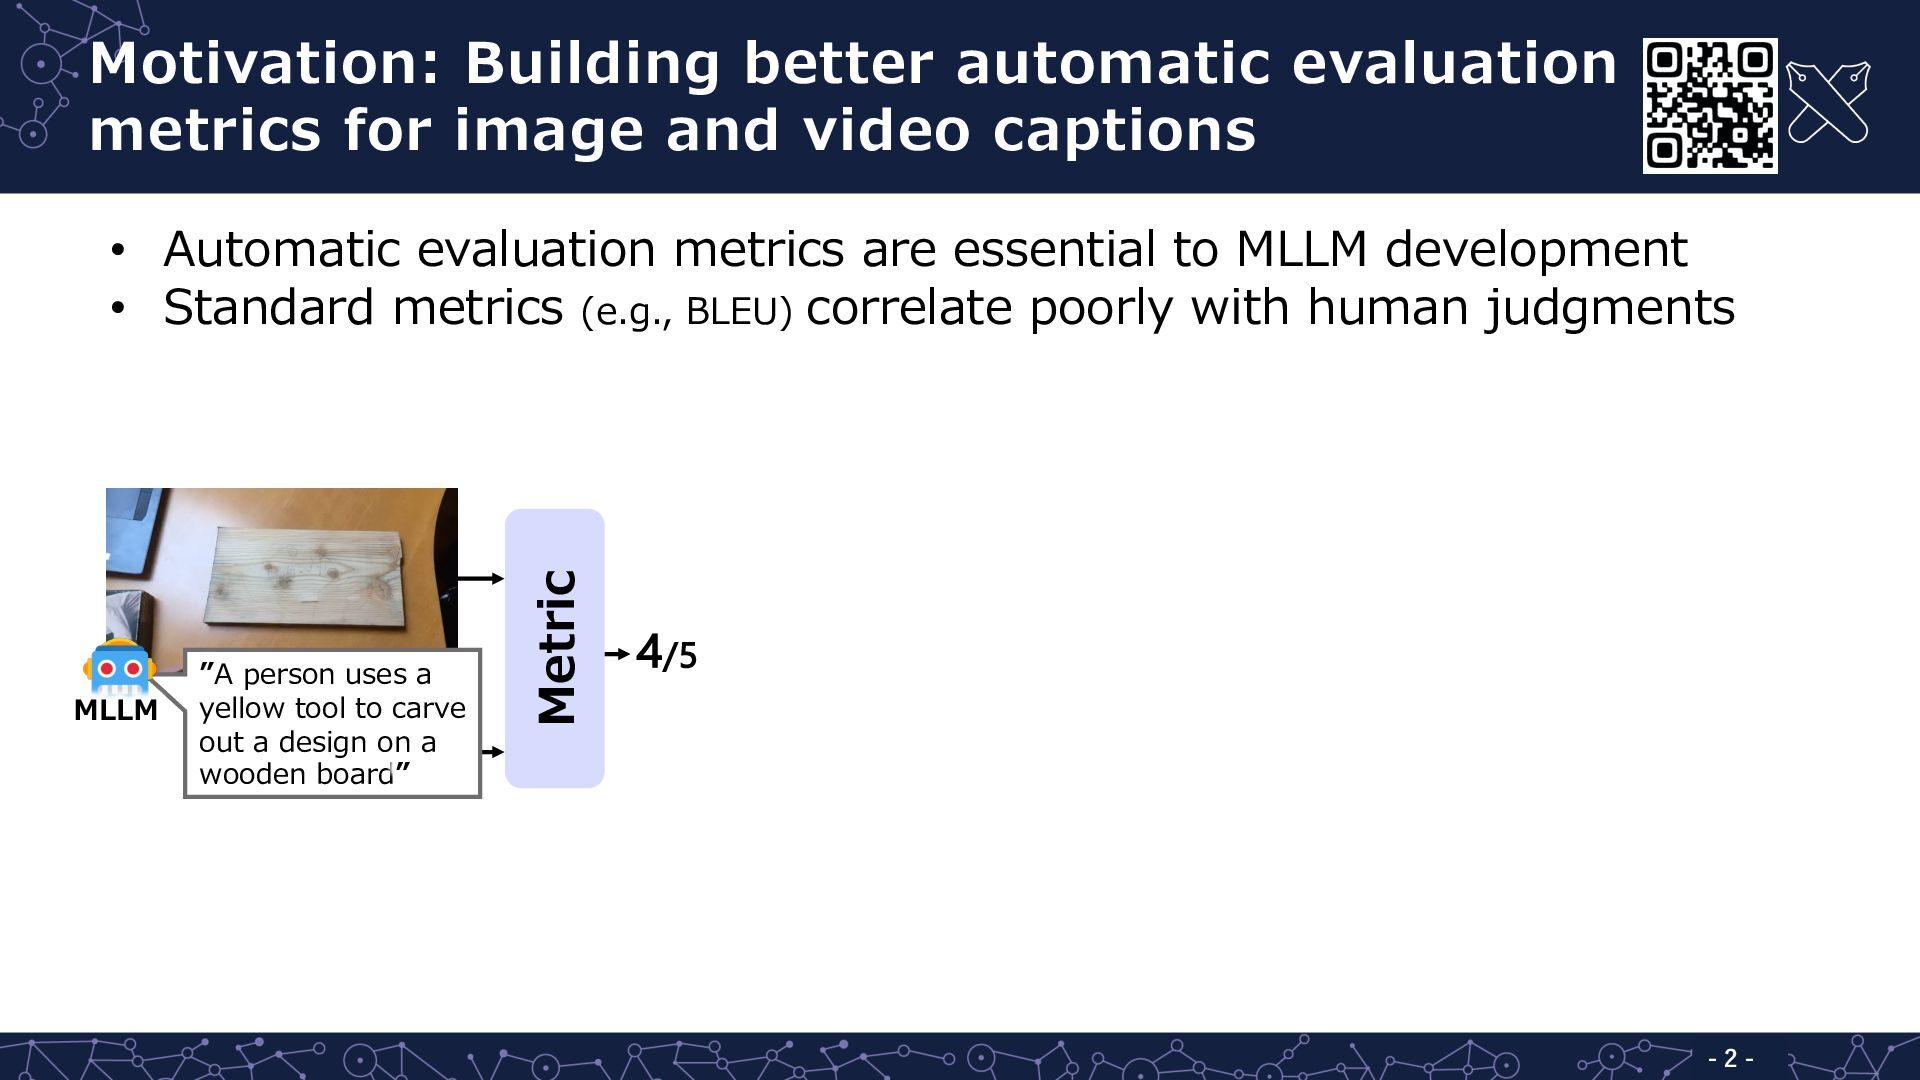
captions MLLM ”A person uses a yellow tool to carve out a design on a wooden board” Metric • Automatic evaluation metrics are essential to MLLM development • Standard metrics (e.g., BLEU) correlate poorly with human judgments 4/5 -2-
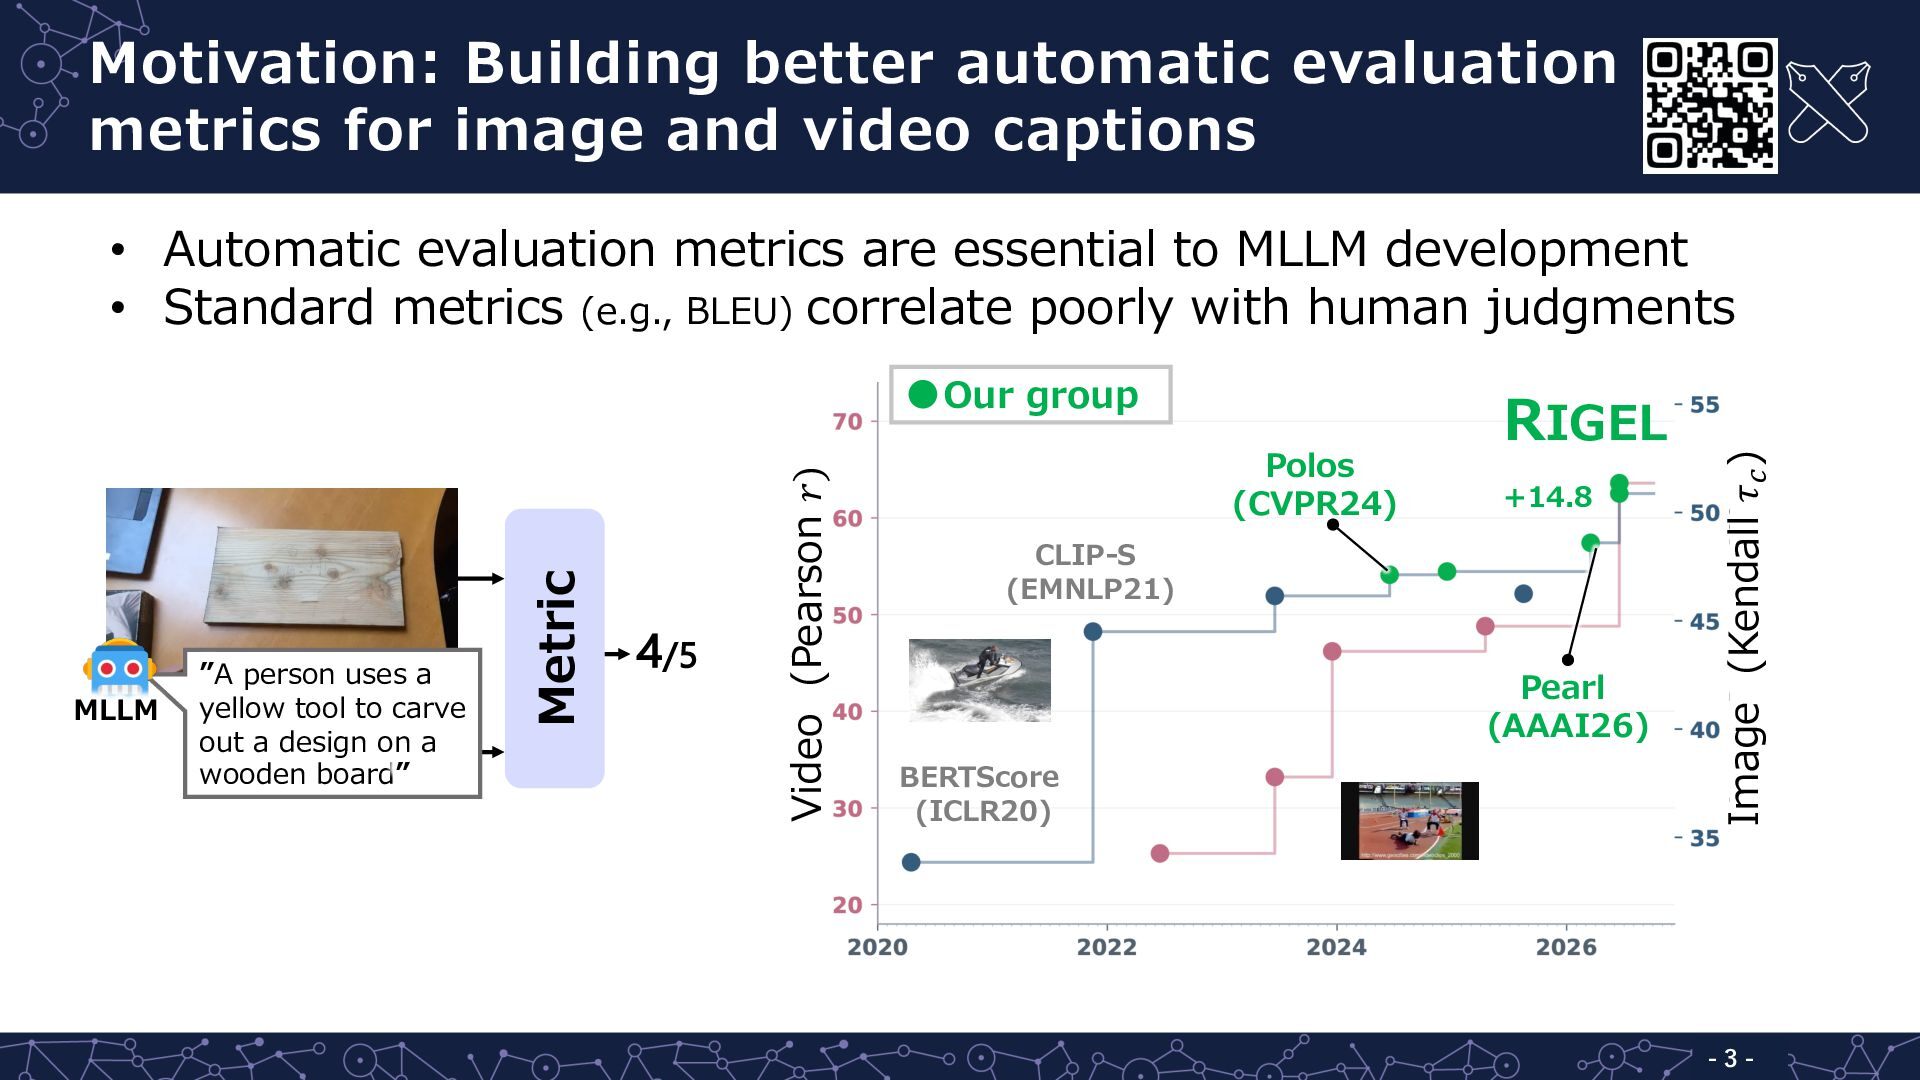
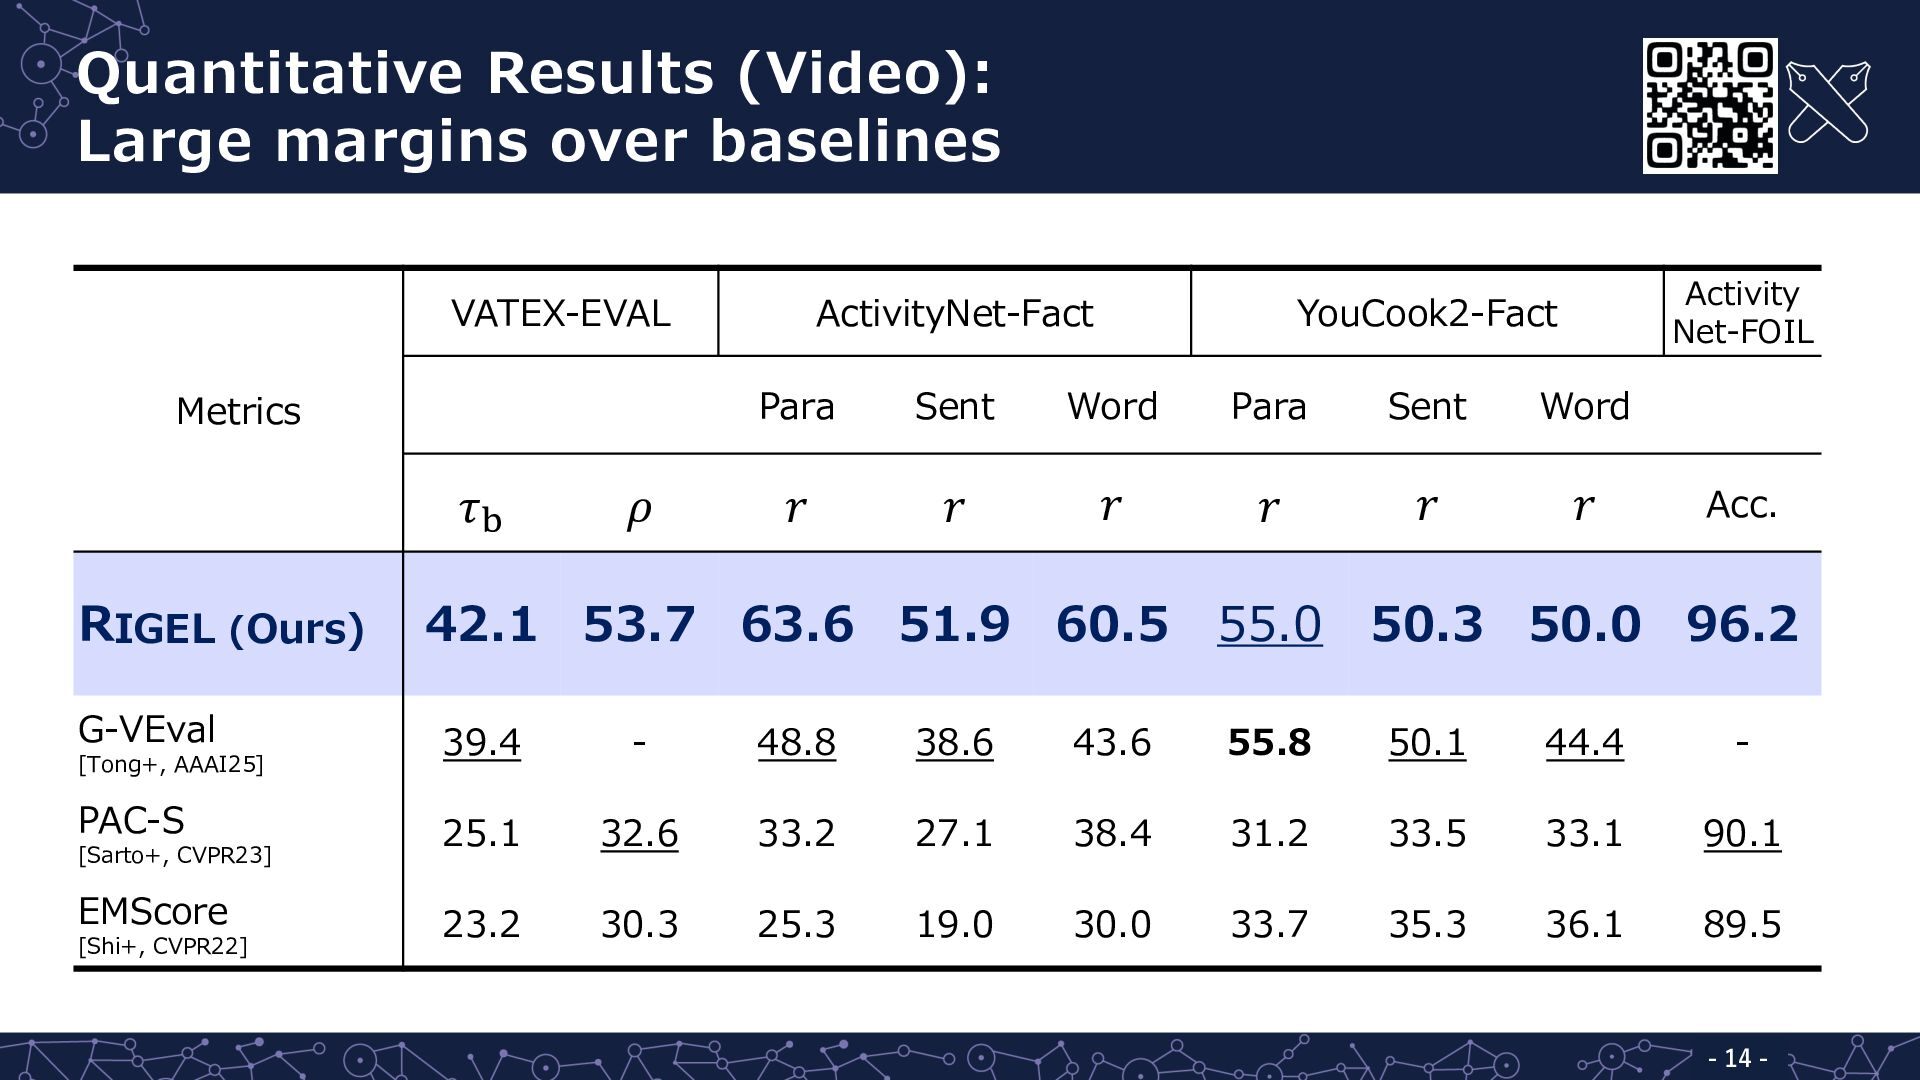
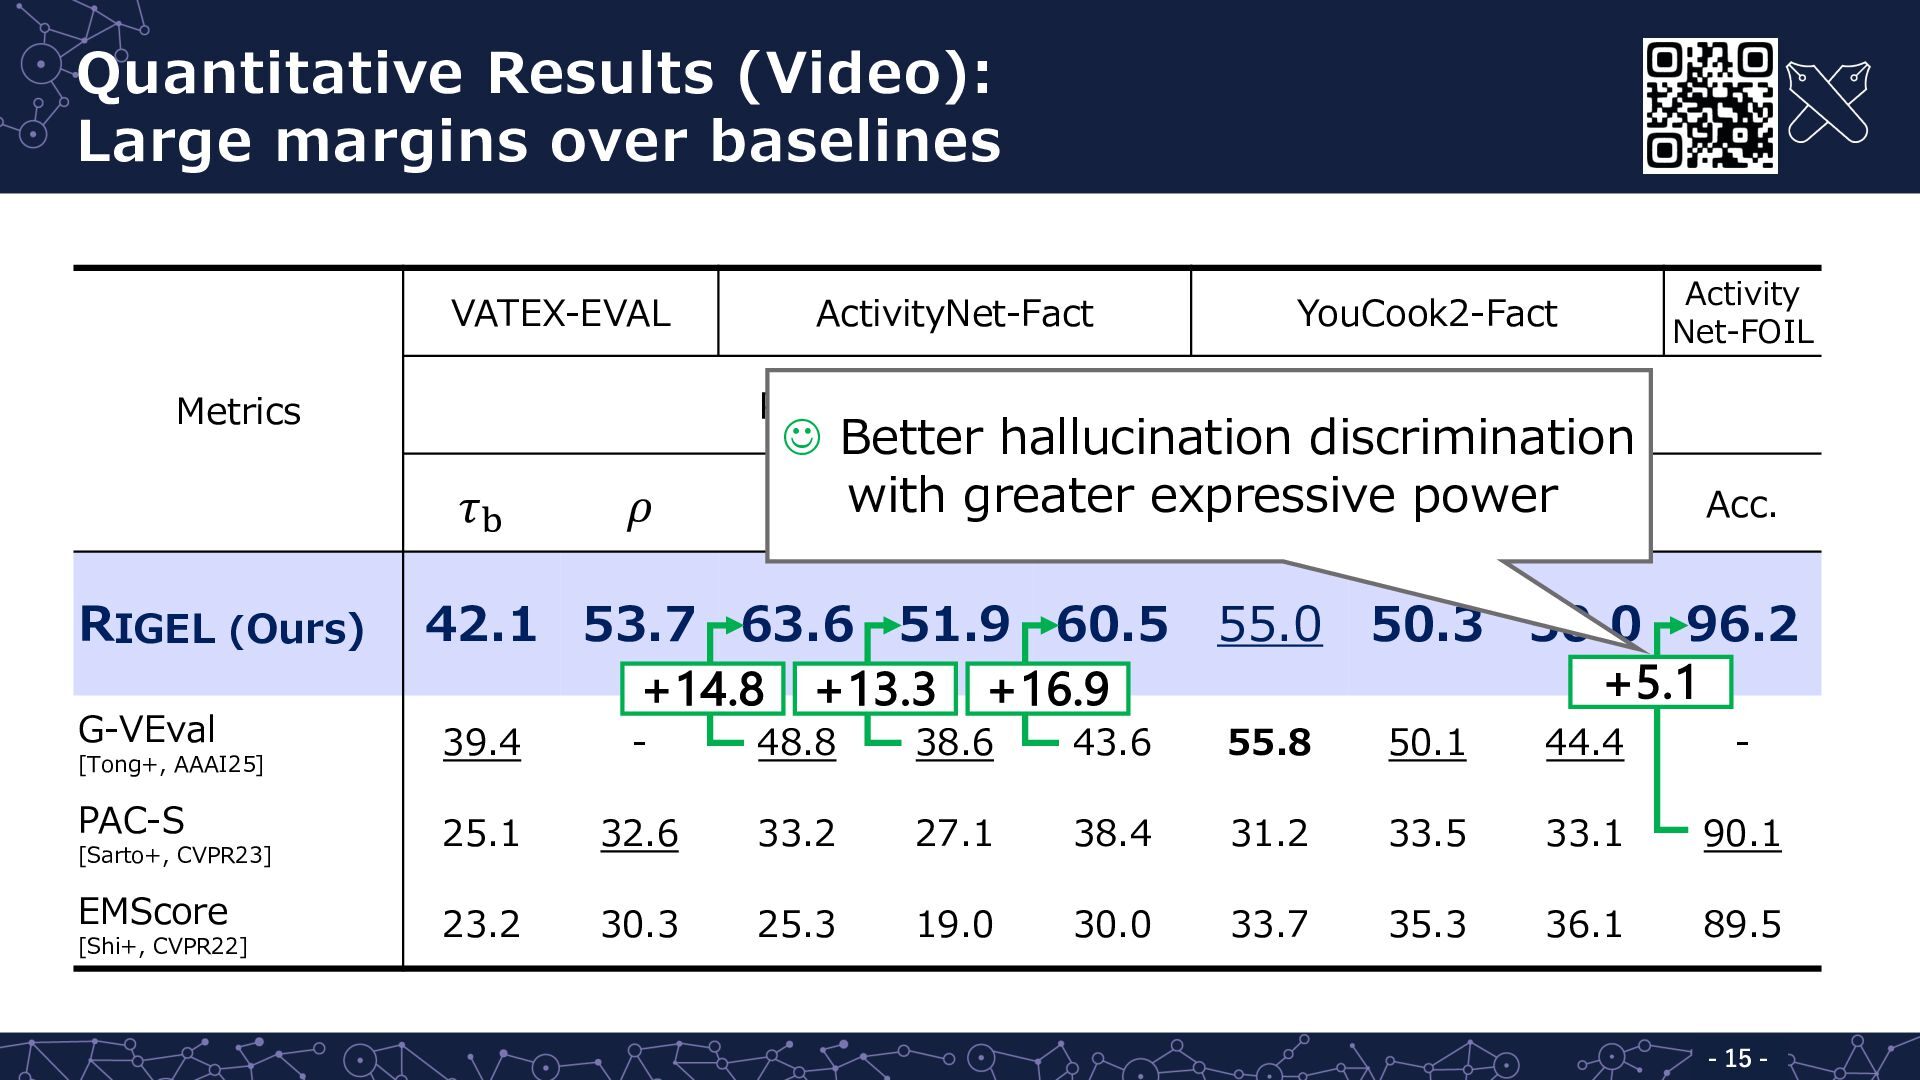
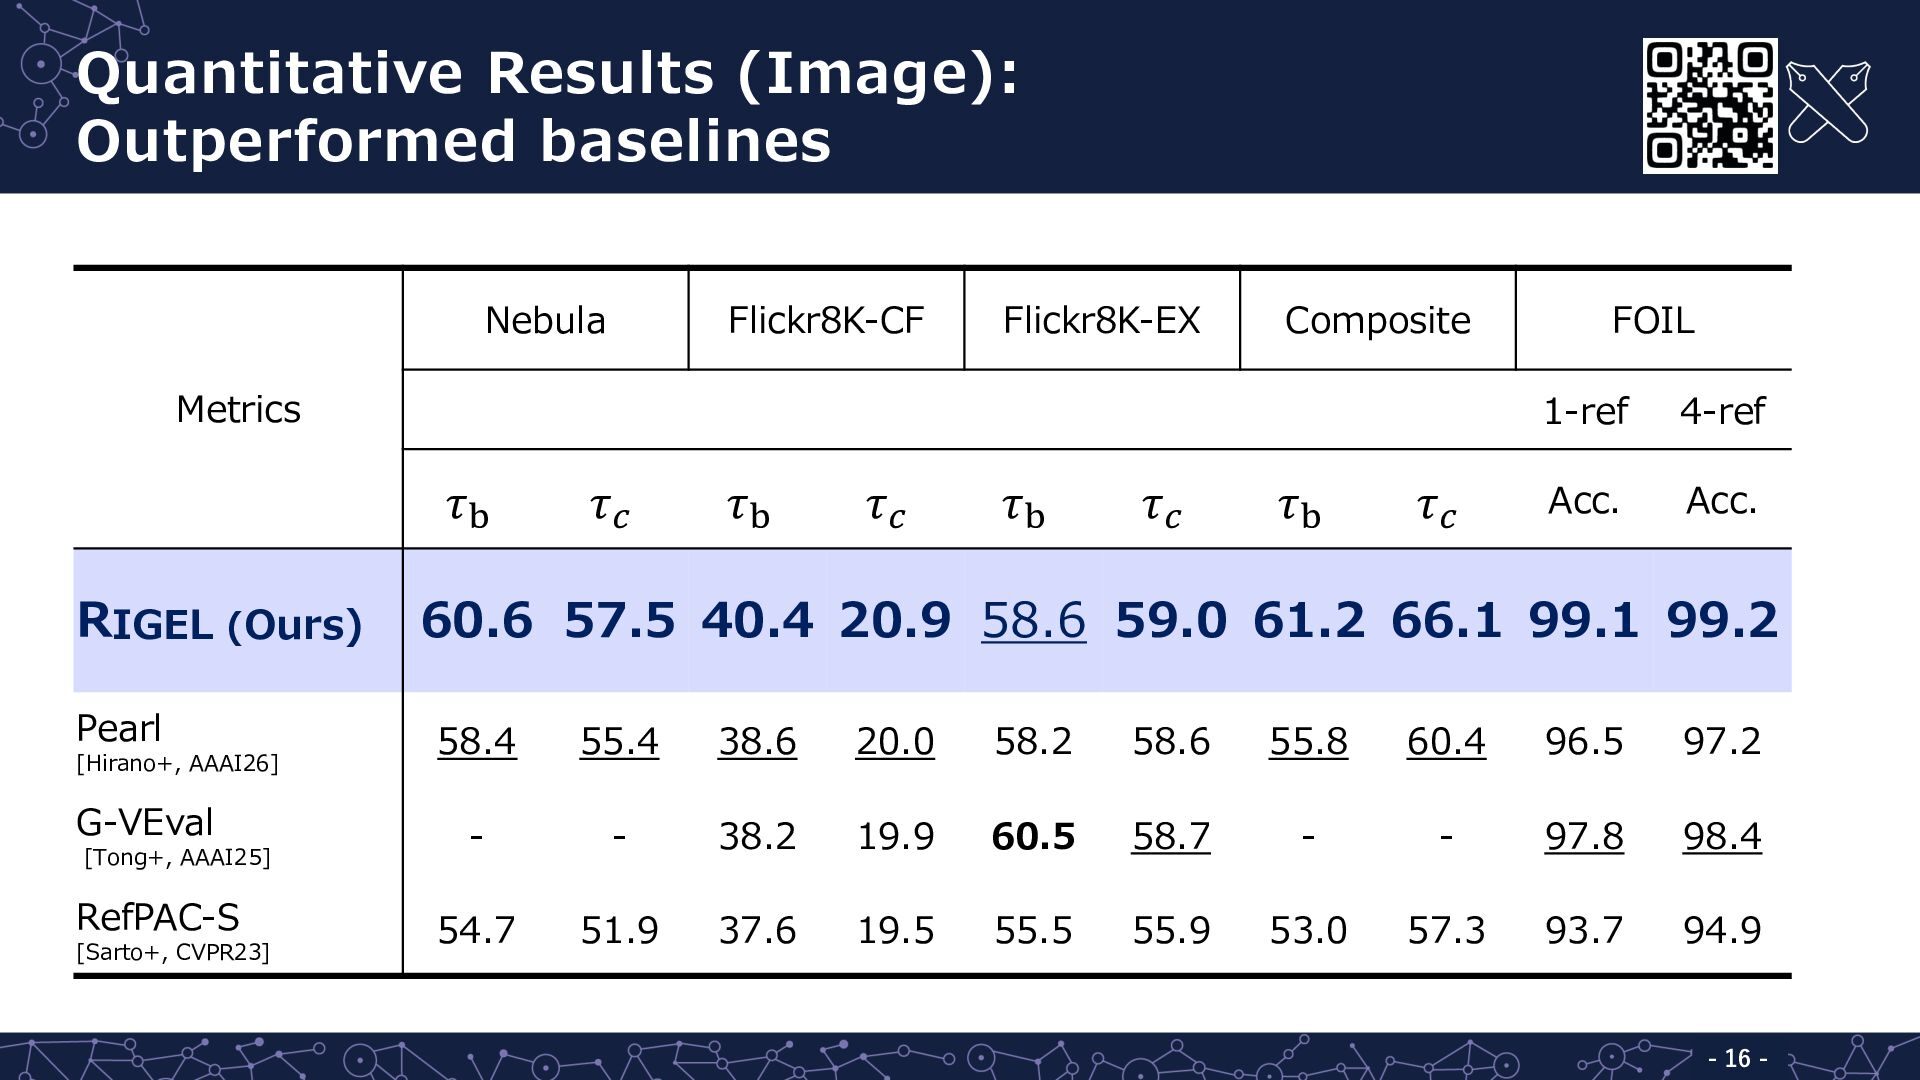
captions 4/5 Video (Pearson 𝑟) MLLM ”A person uses a yellow tool to carve out a design on a wooden board” Metric Our group Polos (CVPR24) RIGEL +14.8 CLIP-S (EMNLP21) Pearl (AAAI26) BERTScore (ICLR20) Image (Kendall 𝜏! ) • Automatic evaluation metrics are essential to MLLM development • Standard metrics (e.g., BLEU) correlate poorly with human judgments -3-
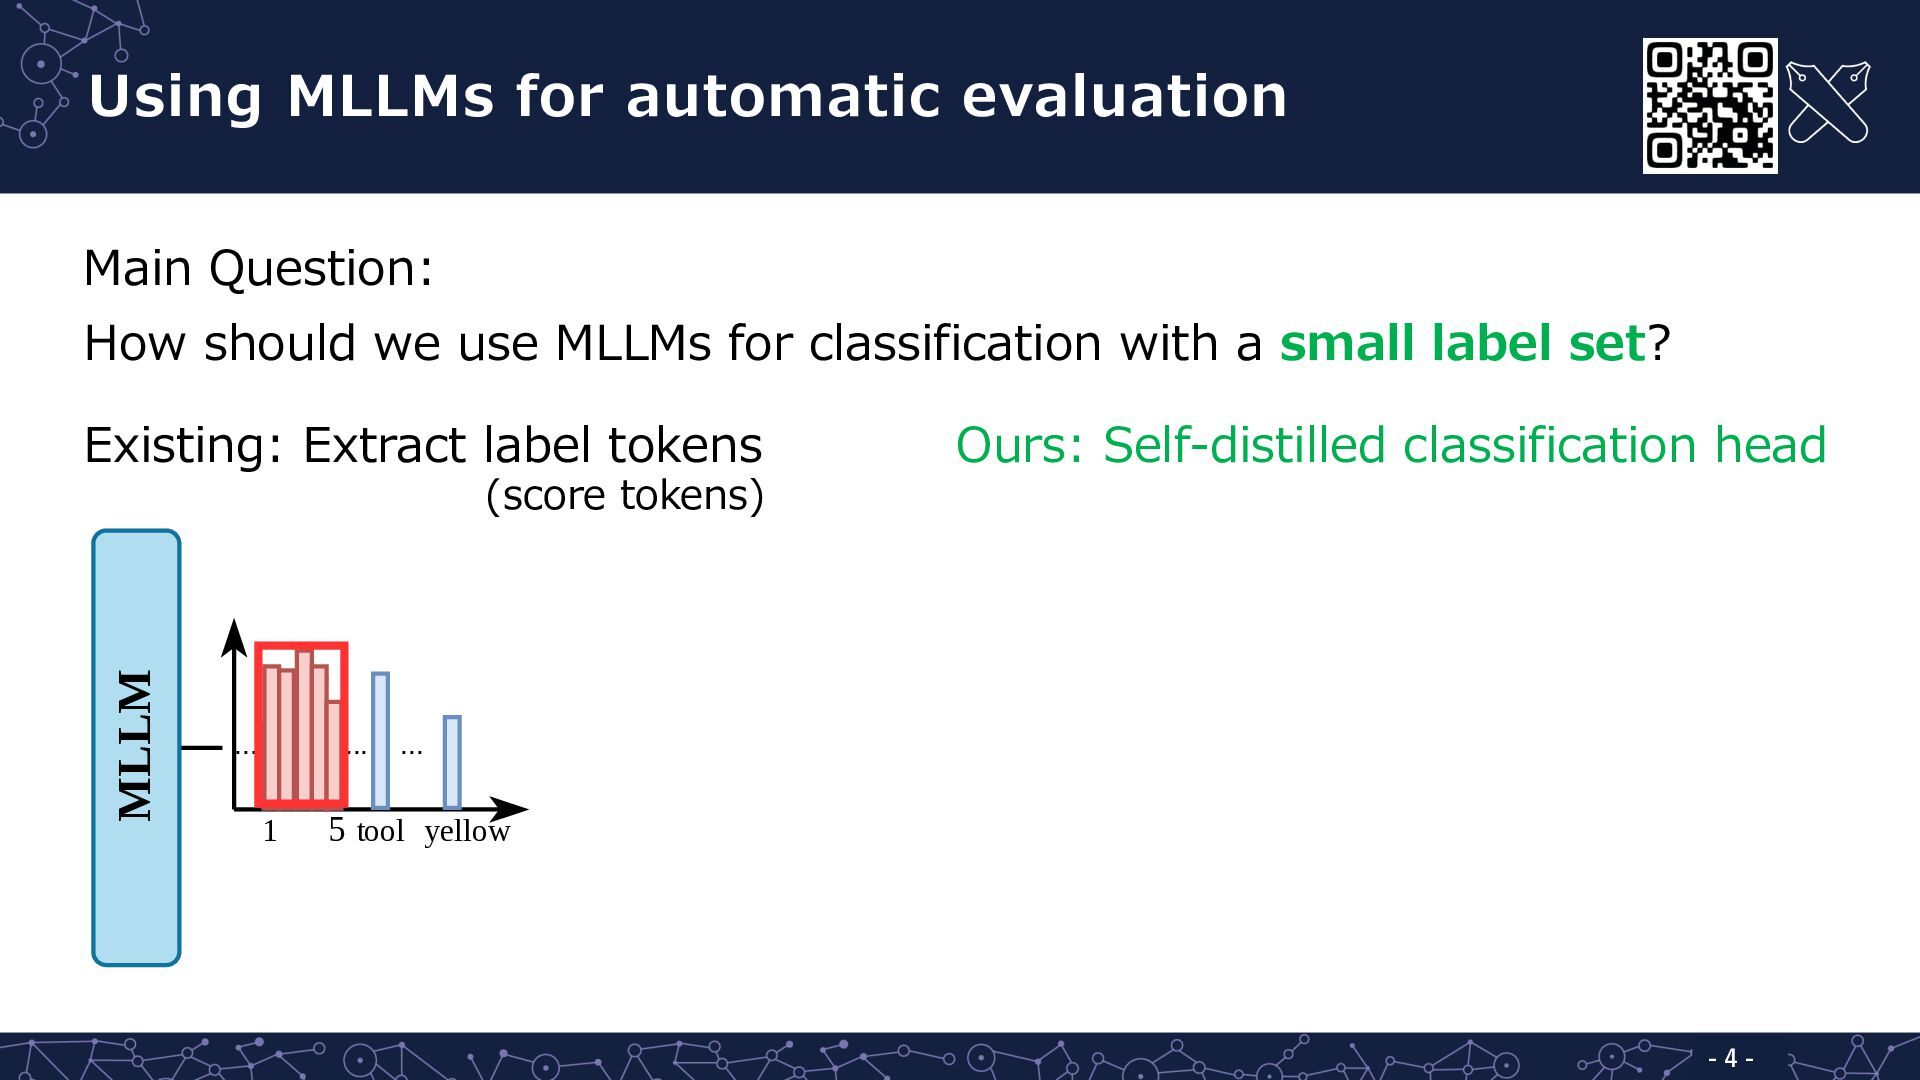
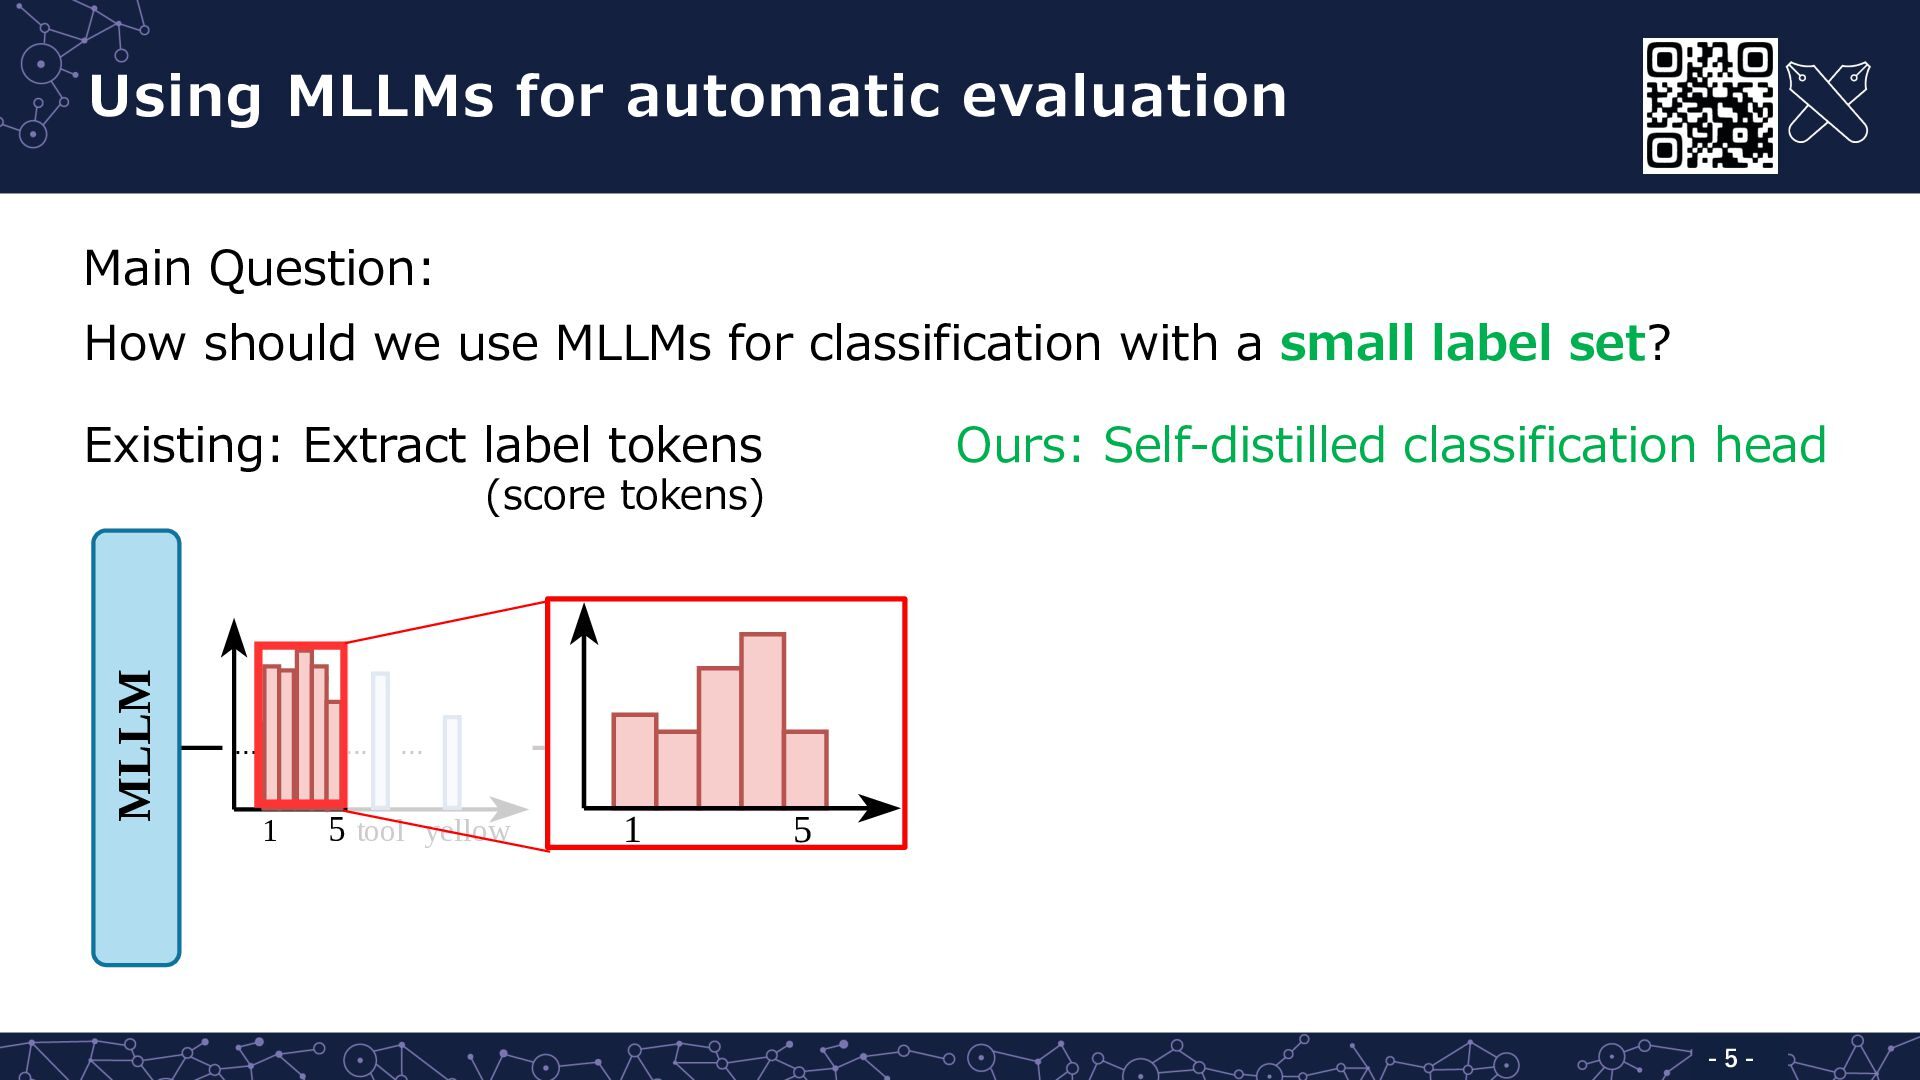
use MLLMs for classification with a small label set? Existing: Extract label tokens MLLM (score tokens) ... ... 1 Ours: Self-distilled classification head ... 5 tool yellow -4-
use MLLMs for classification with a small label set? Existing: Extract label tokens Ours: Self-distilled classification head MLLM (score tokens) ... ... 1 ... 5 tool yellow 1 5 -5-
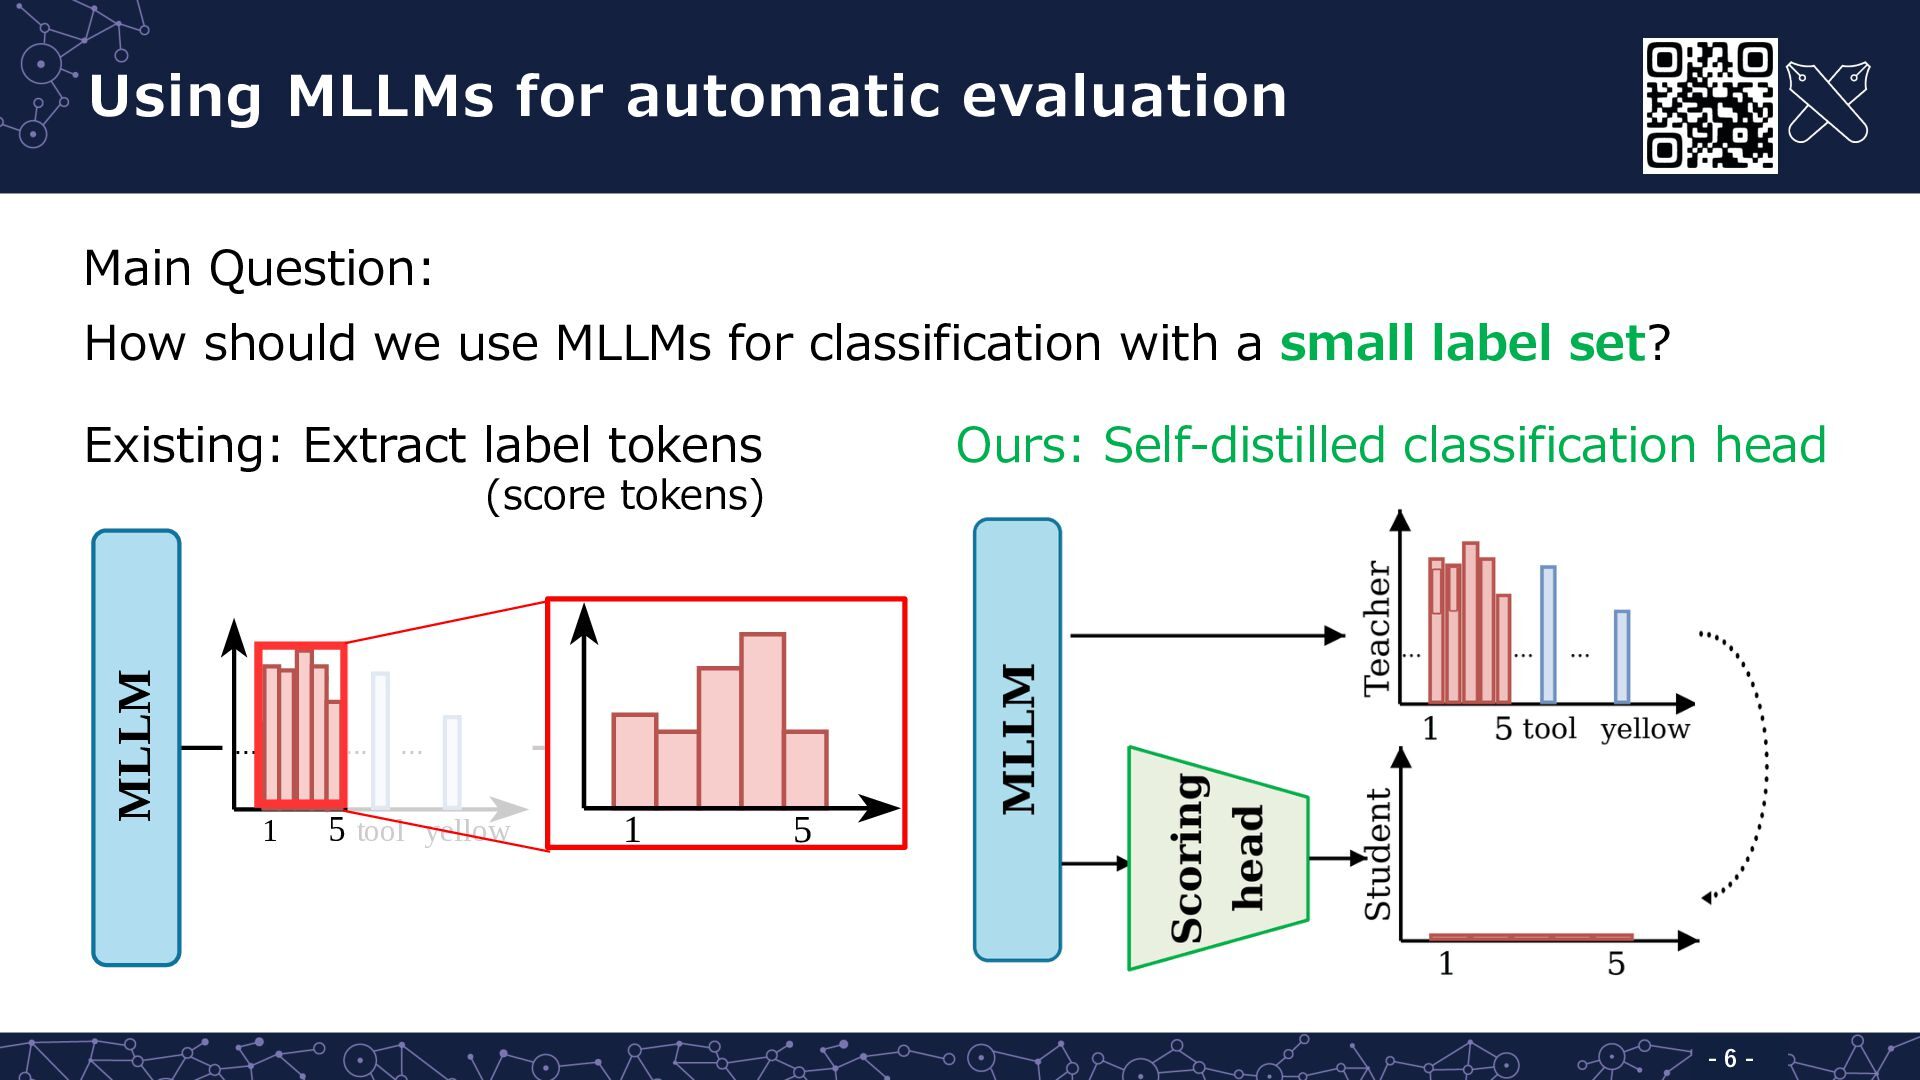
use MLLMs for classification with a small label set? Existing: Extract label tokens Ours: Self-distilled classification head MLLM (score tokens) ... ... 1 ... 5 tool yellow 1 5 -6-
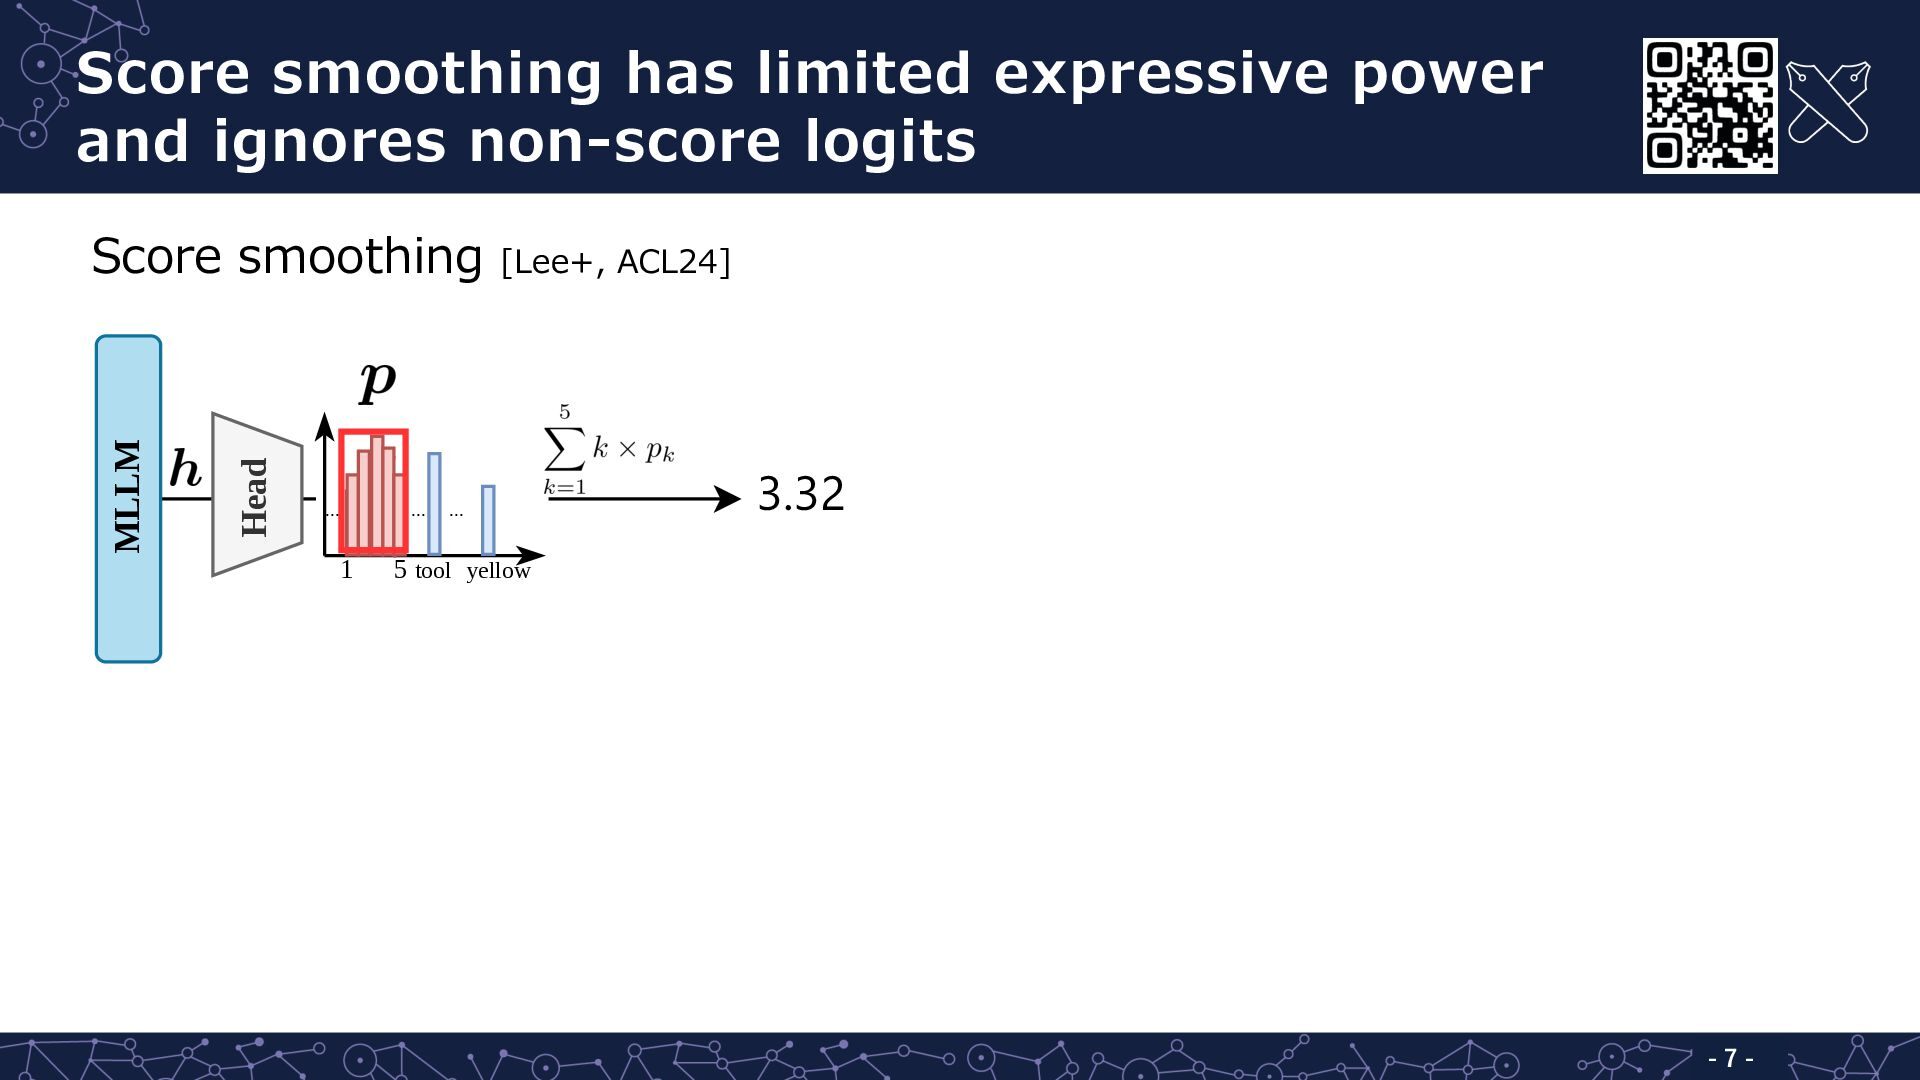
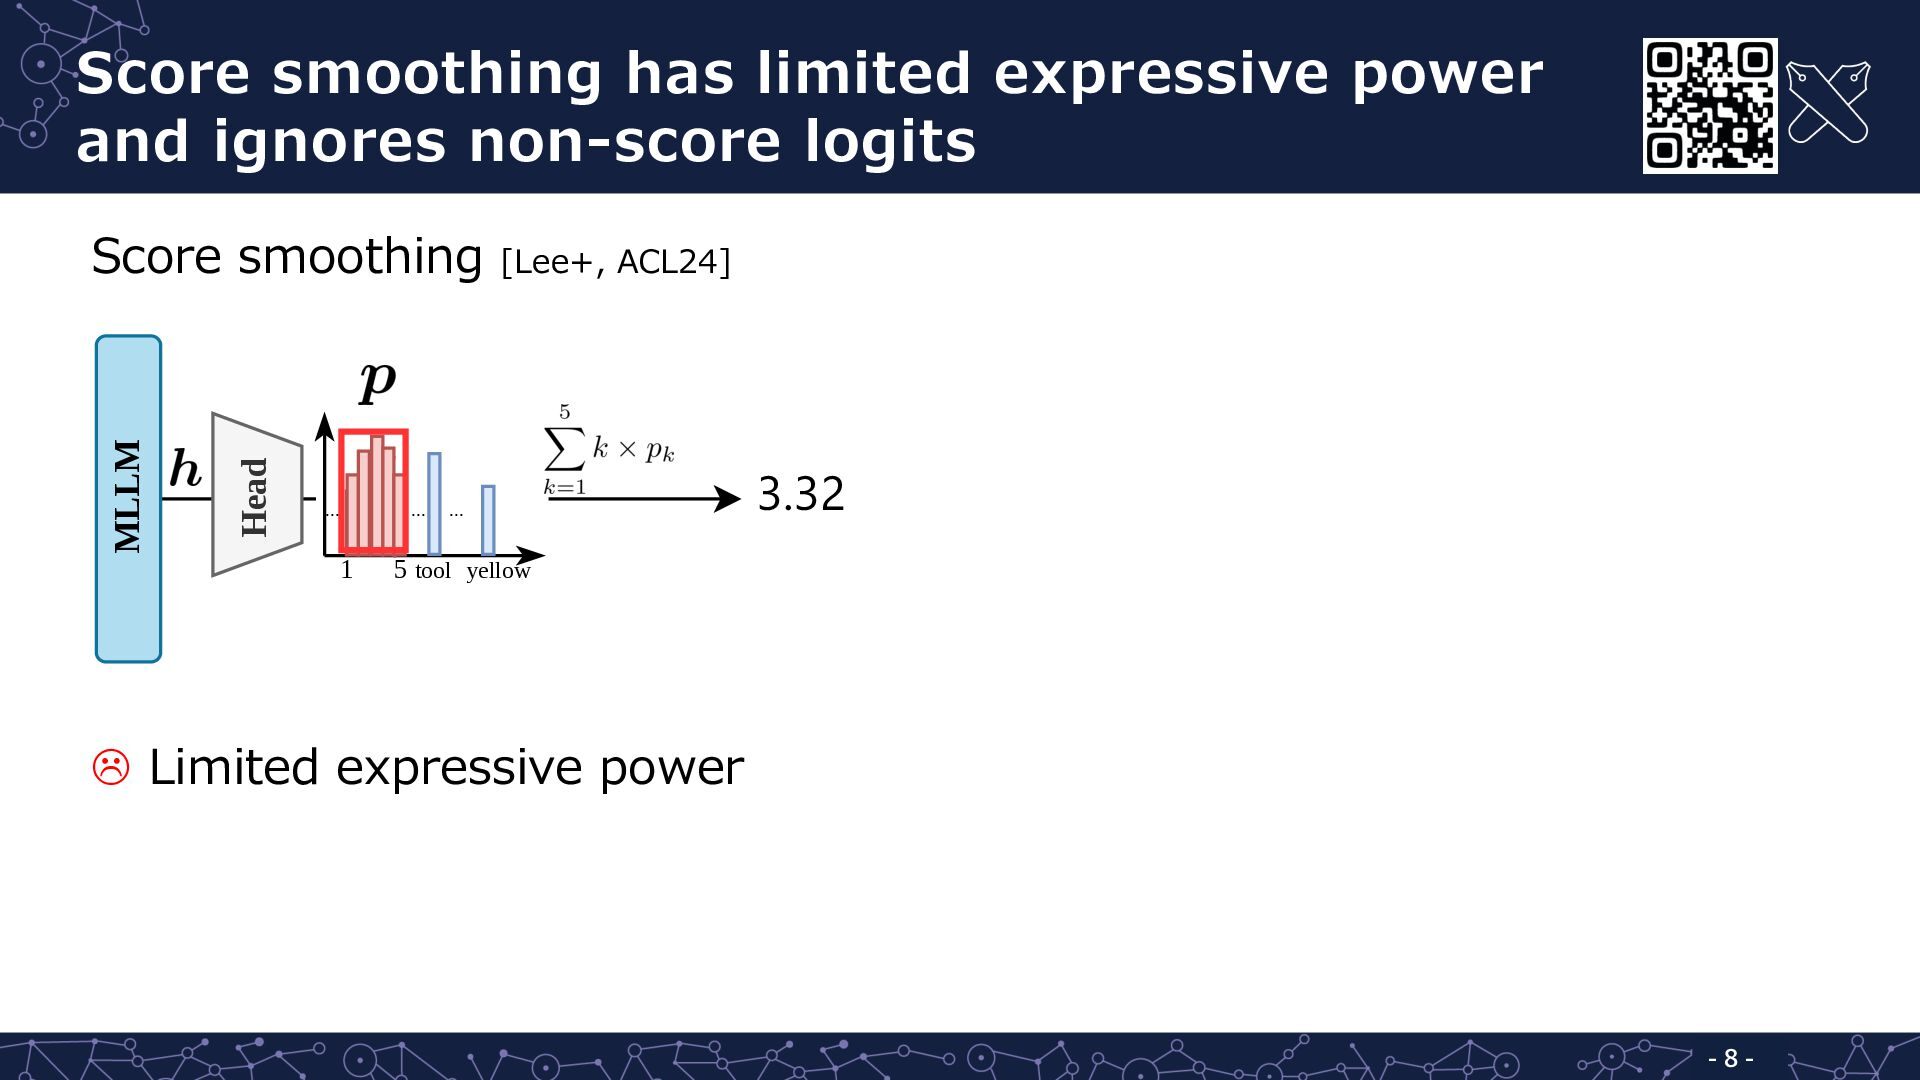
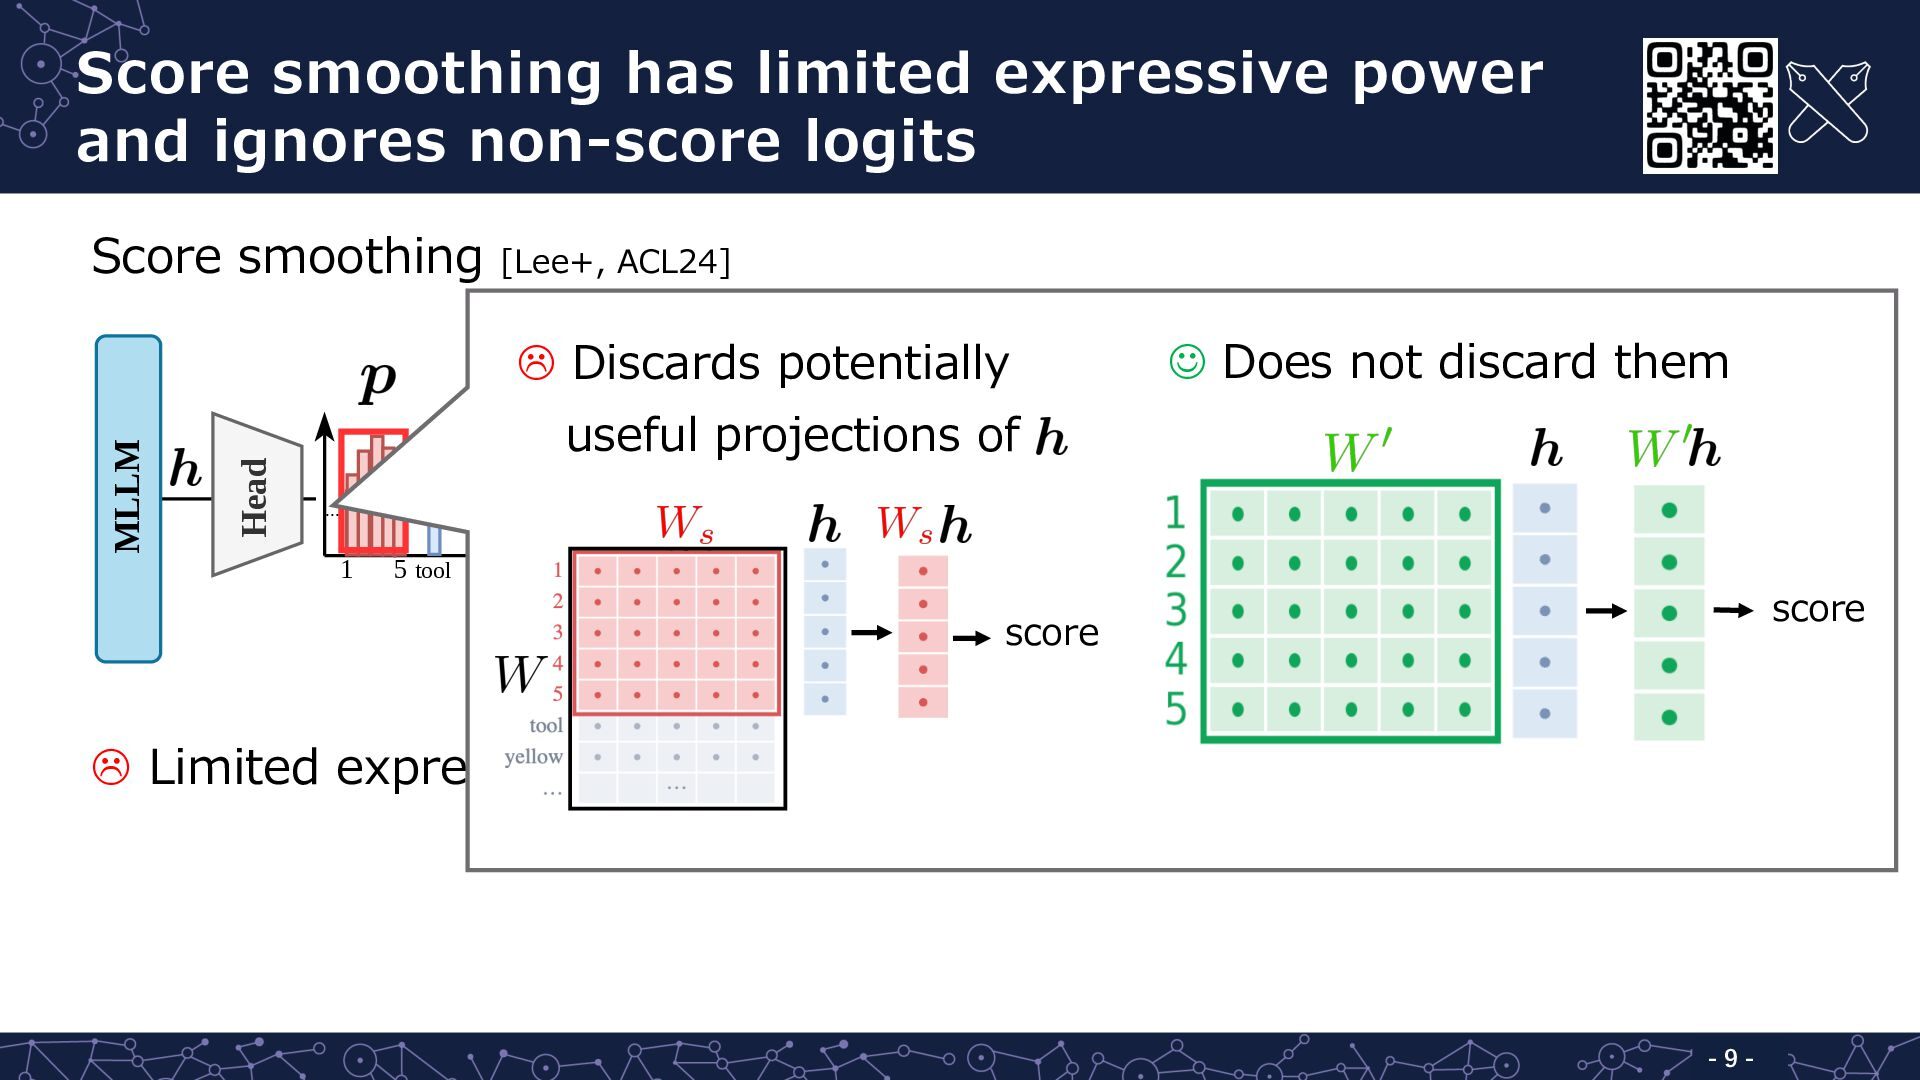
Score smoothing [Lee+, ACL24] Head MLLM L Discards potentially ... ... 1 ... J Does not discard them useful projections of 3.323.32 5 tool yellow score score L Limited expressive power -9-
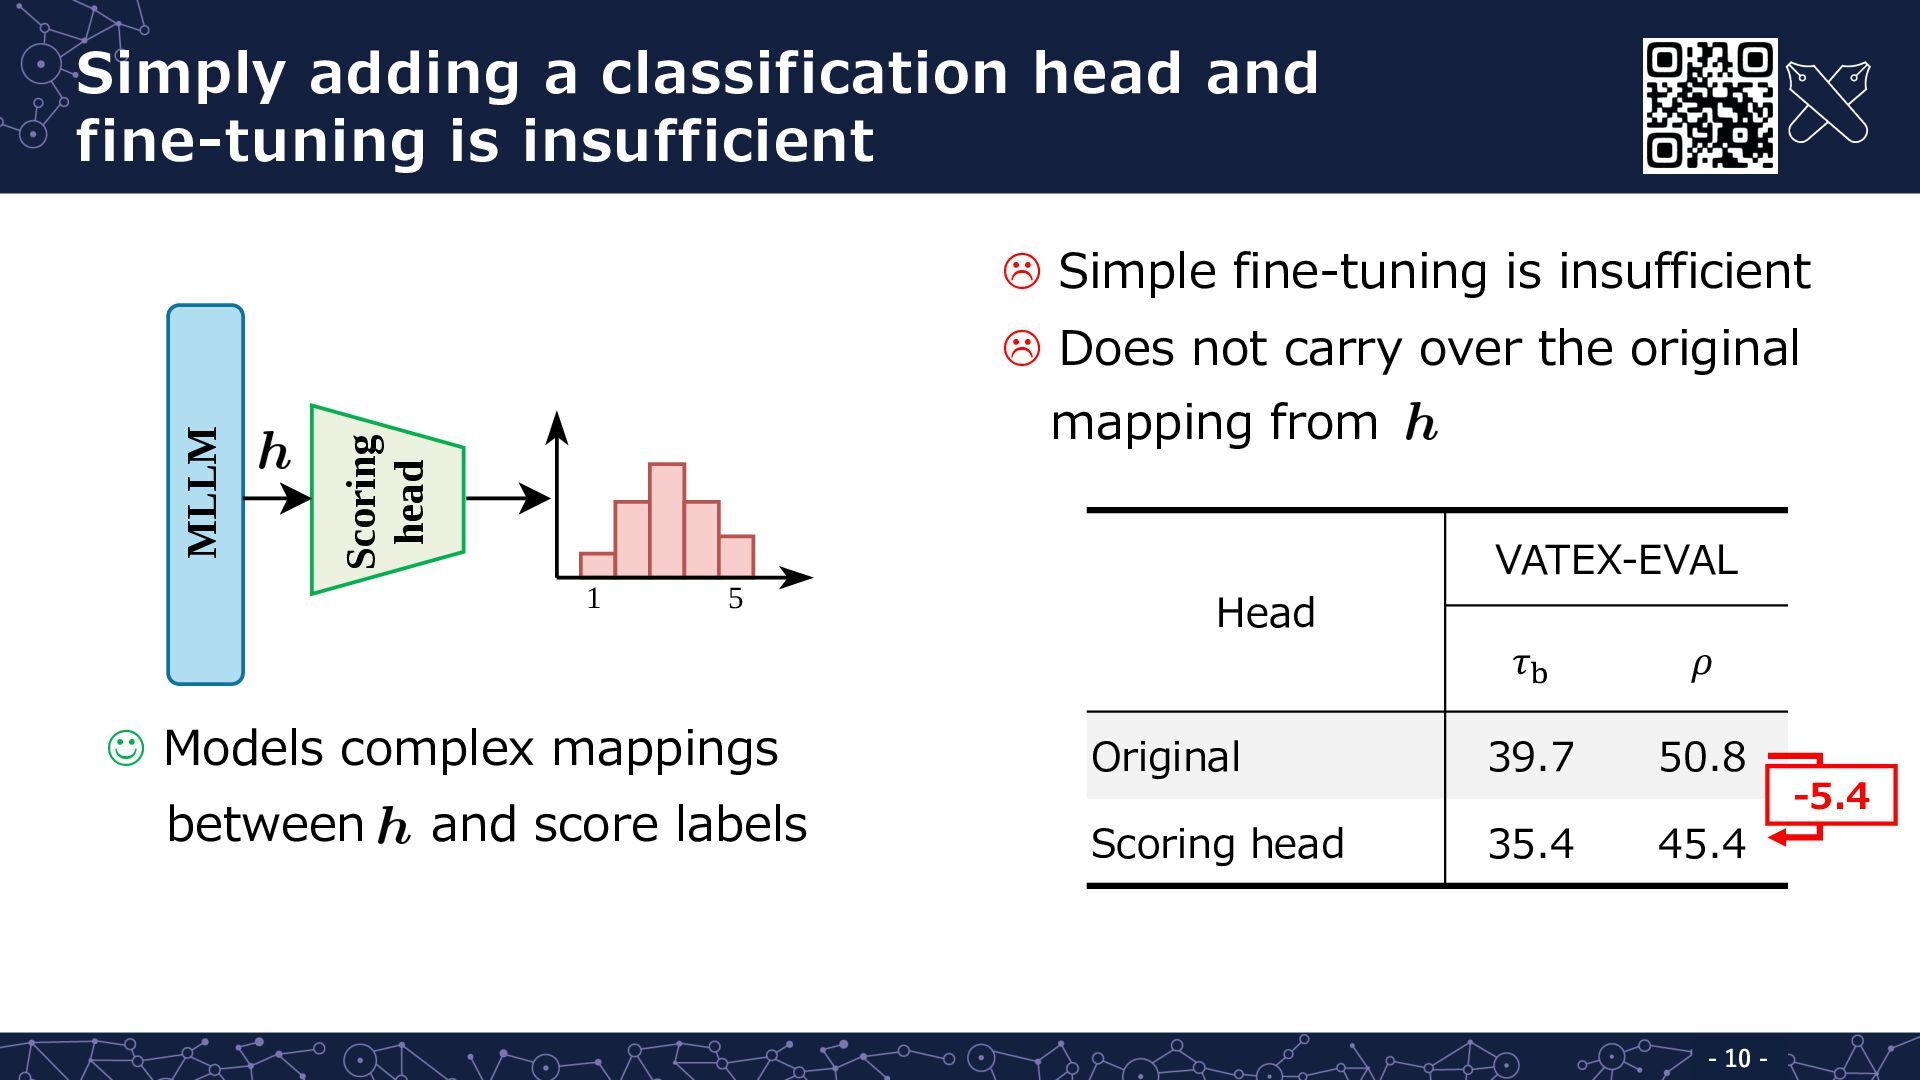
Simple fine-tuning is insufficient mapping from Scoring head MLLM L Does not carry over the original 1 5 J Models complex mappings between and score labels VATEX-EVAL Head 𝜏" 𝜌 Original 39.7 50.8 Scoring head 35.4 45.4 - 10 - -5.4
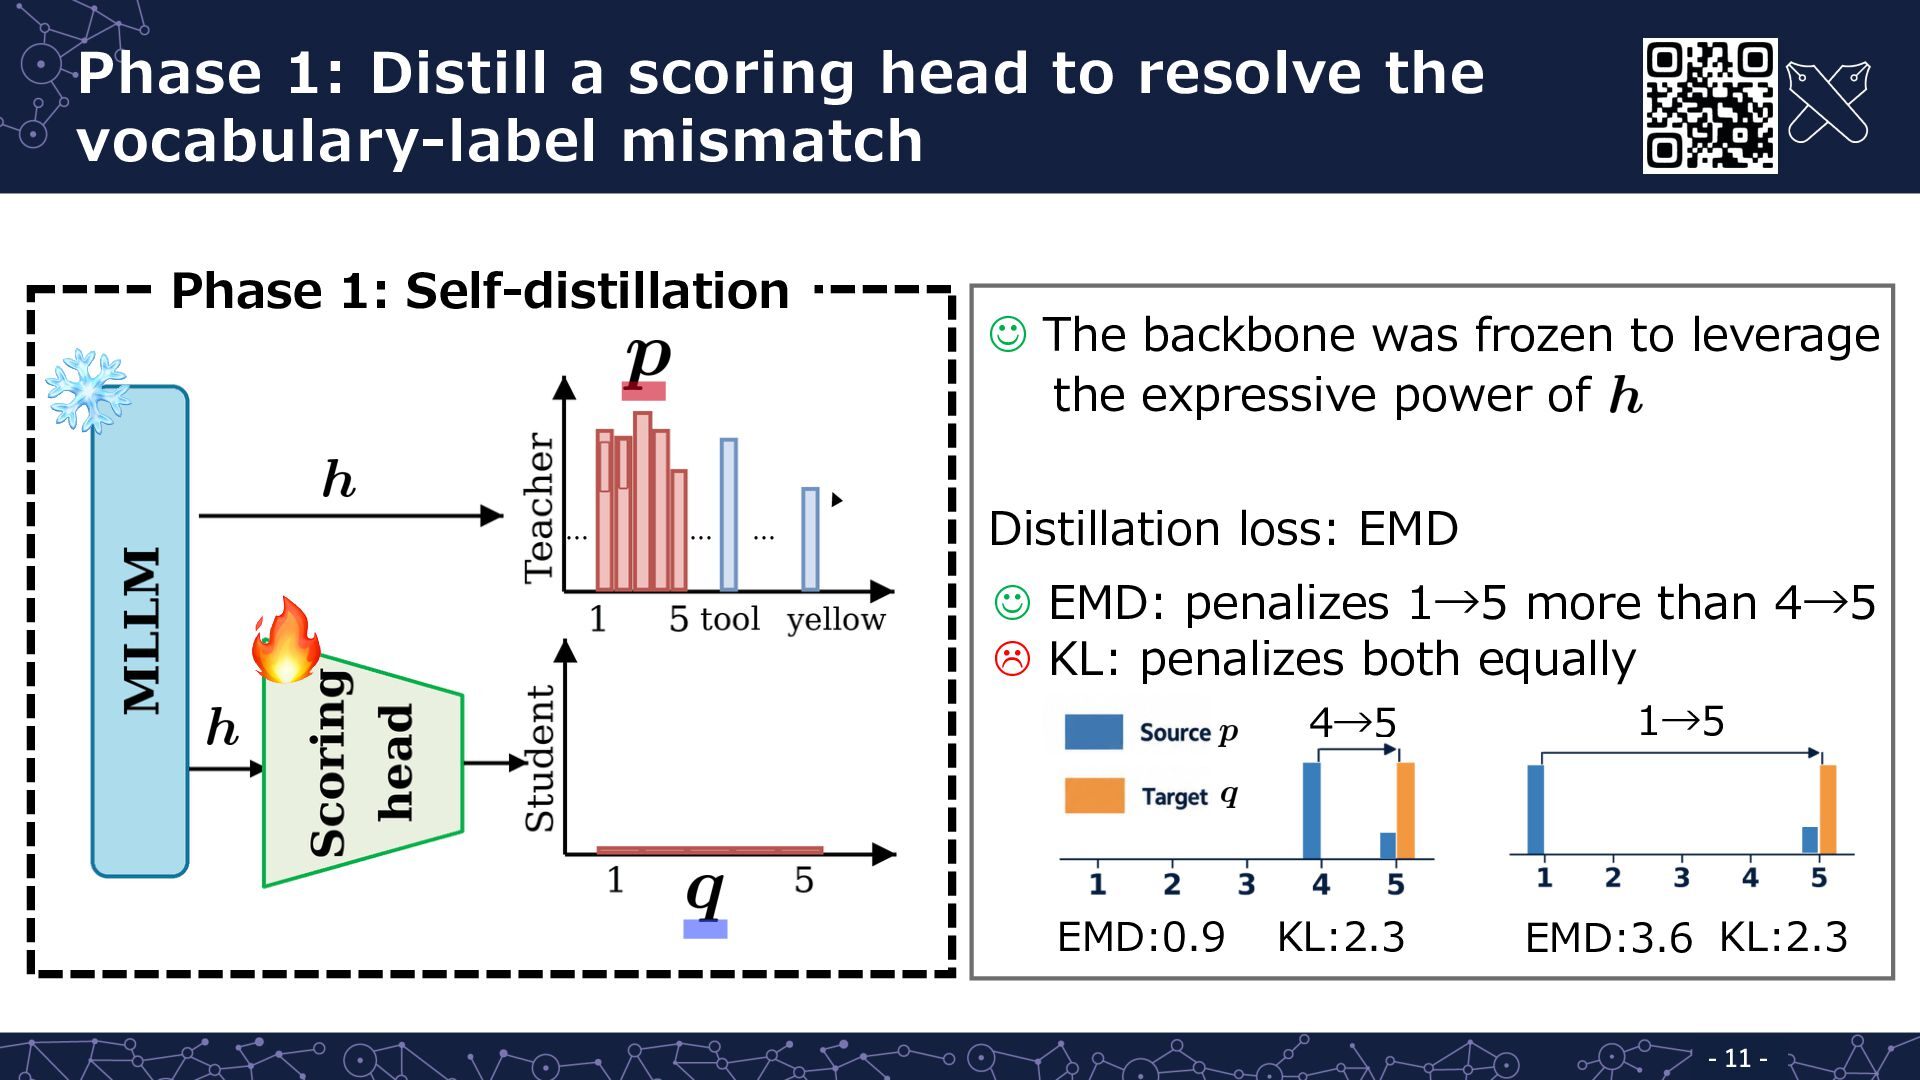
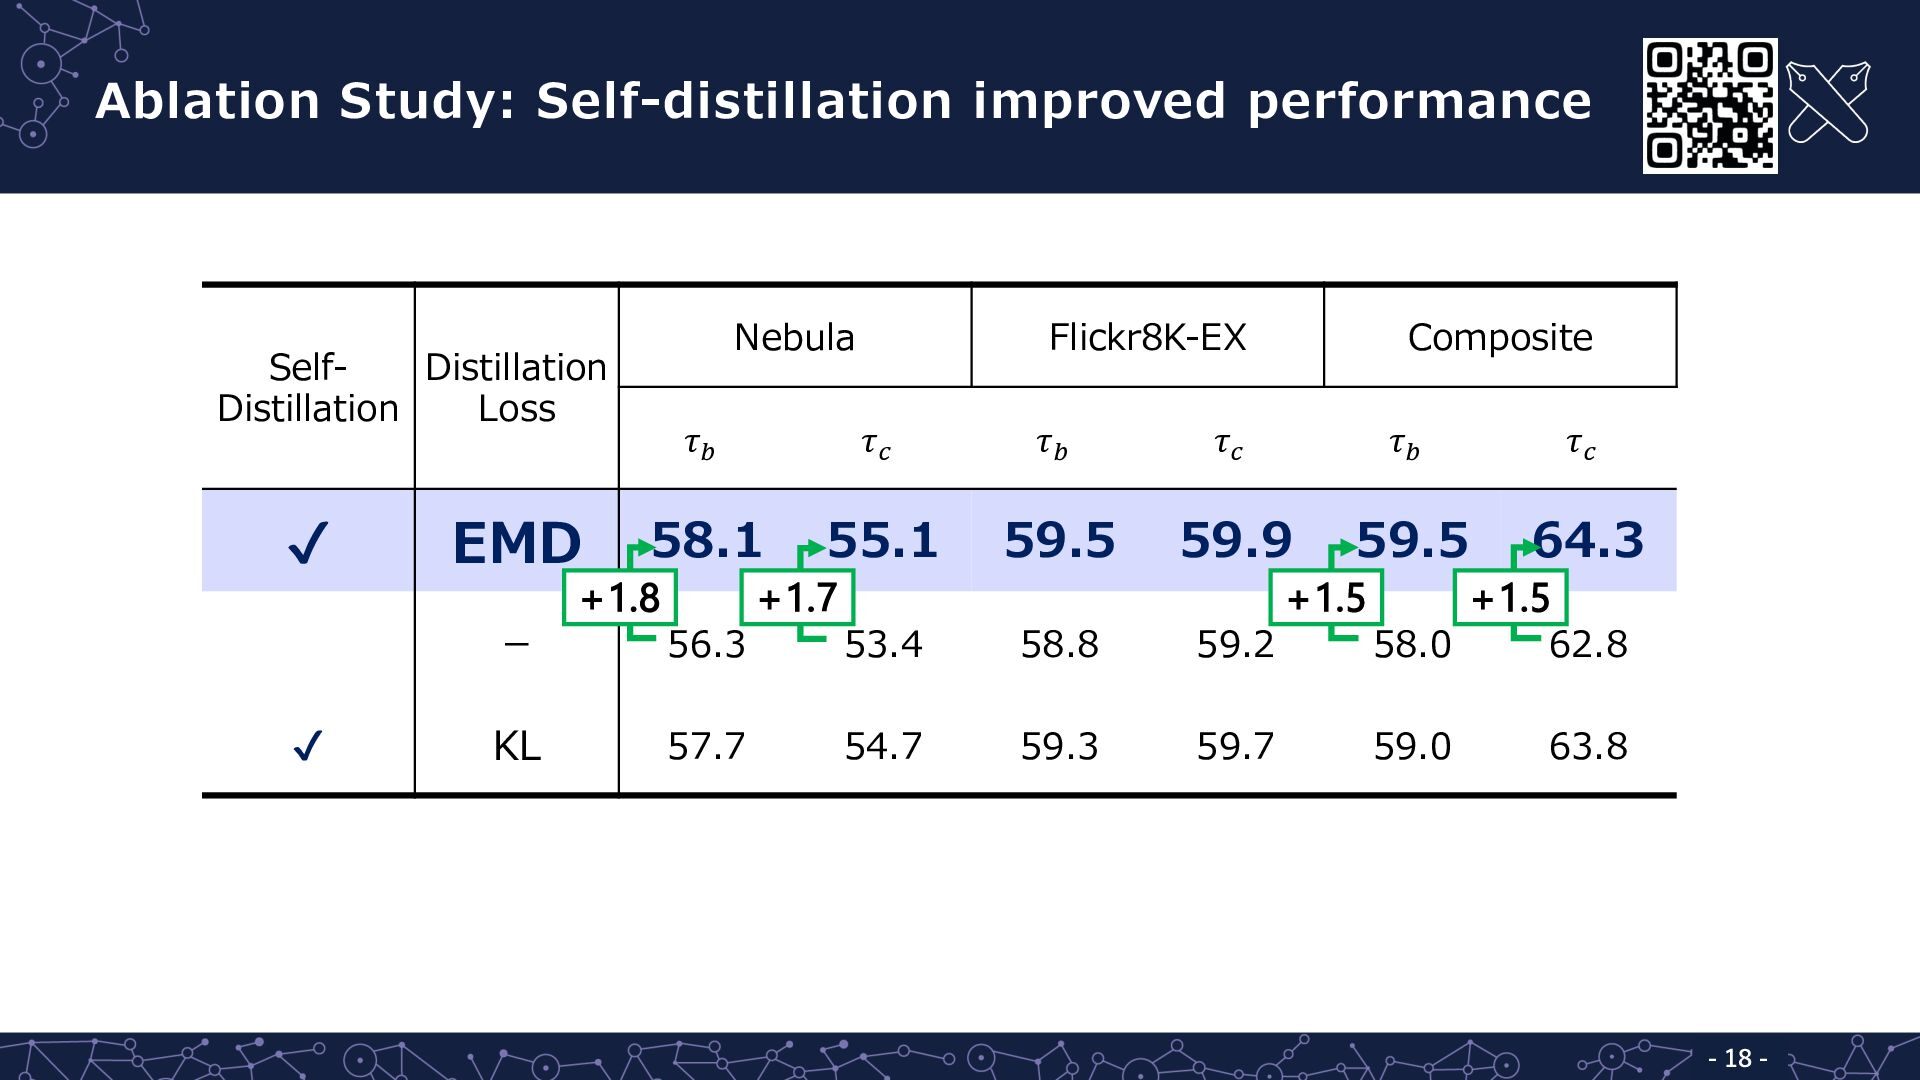
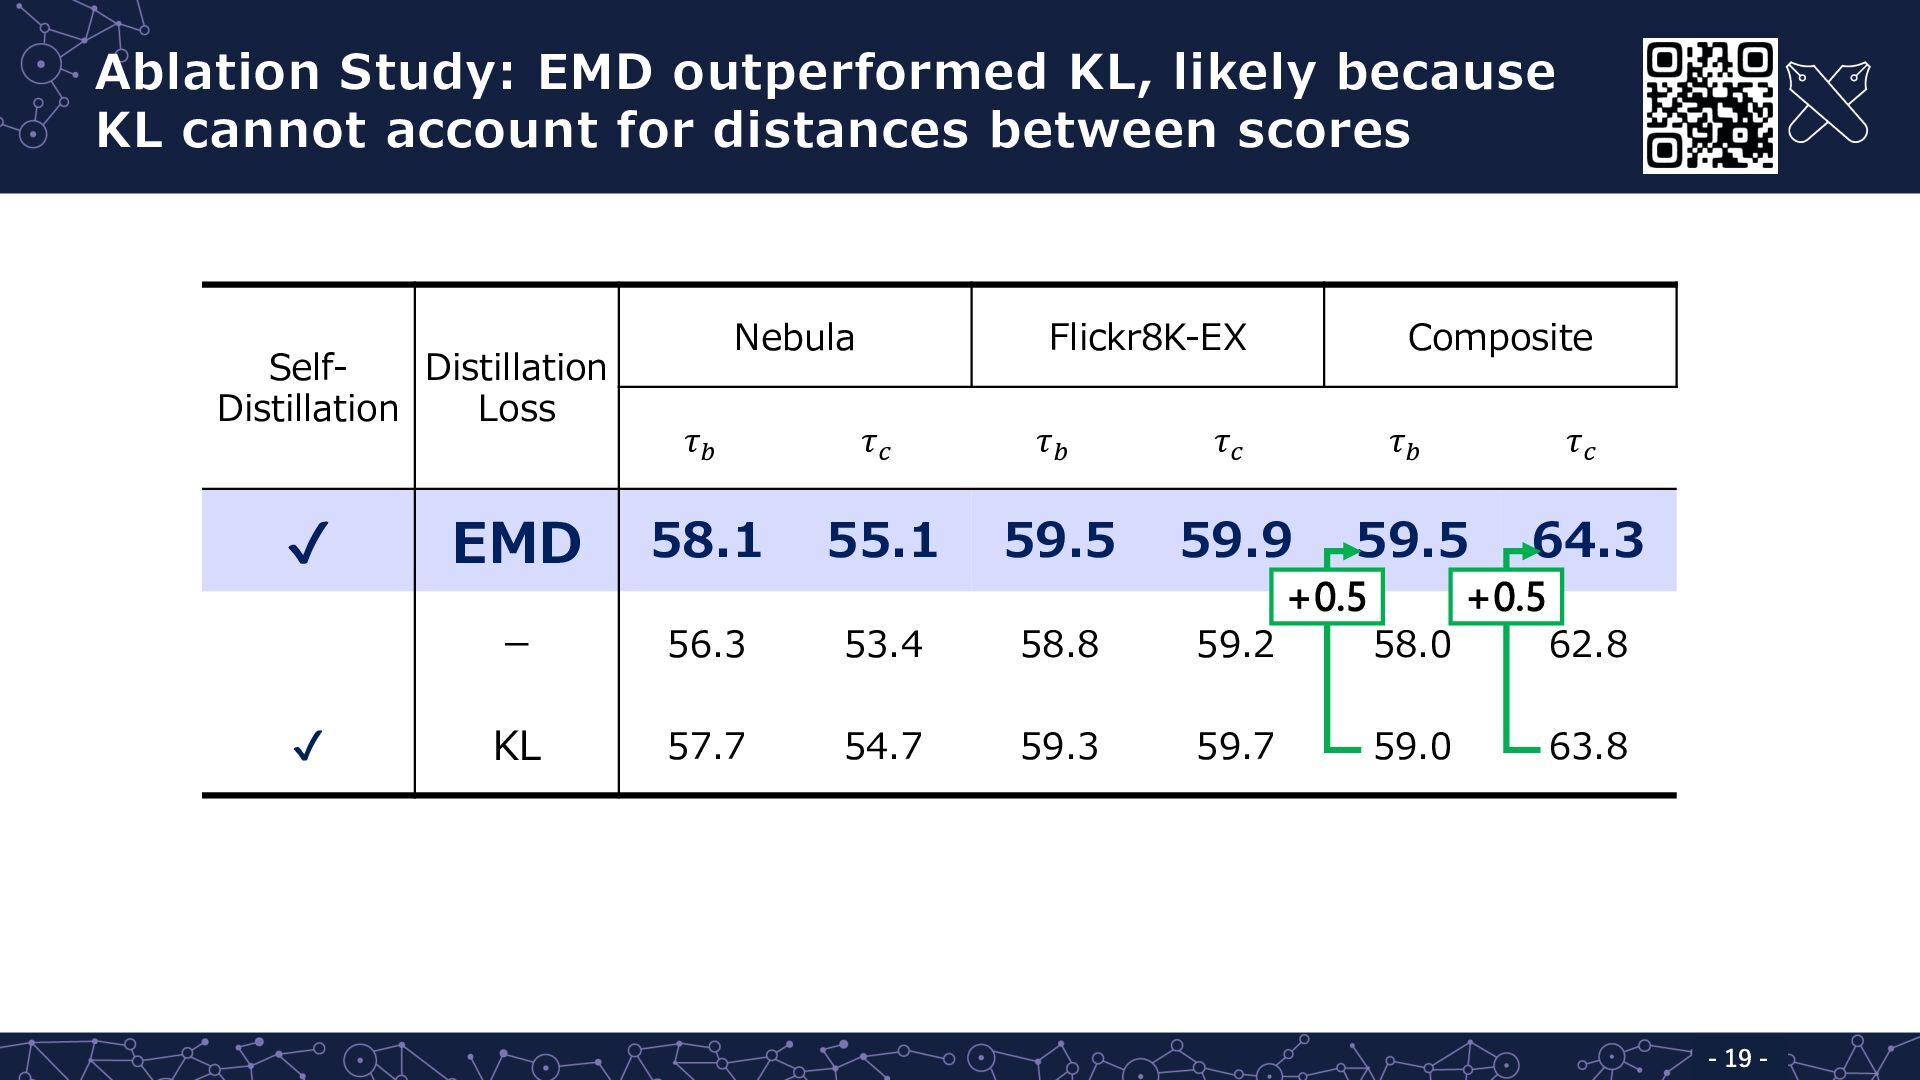
mismatch 1 Phase 1: Self-distillation ❄ J The backbone was frozen to leverage the expressive power of Distillation loss: EMD 🔥 1 J EMD: penalizes 1→5 more than 4→5 L KL: penalizes both equally EMD:0.9 4→5 1→5 KL:2.3 EMD:3.6 KL:2.3 - 11 -
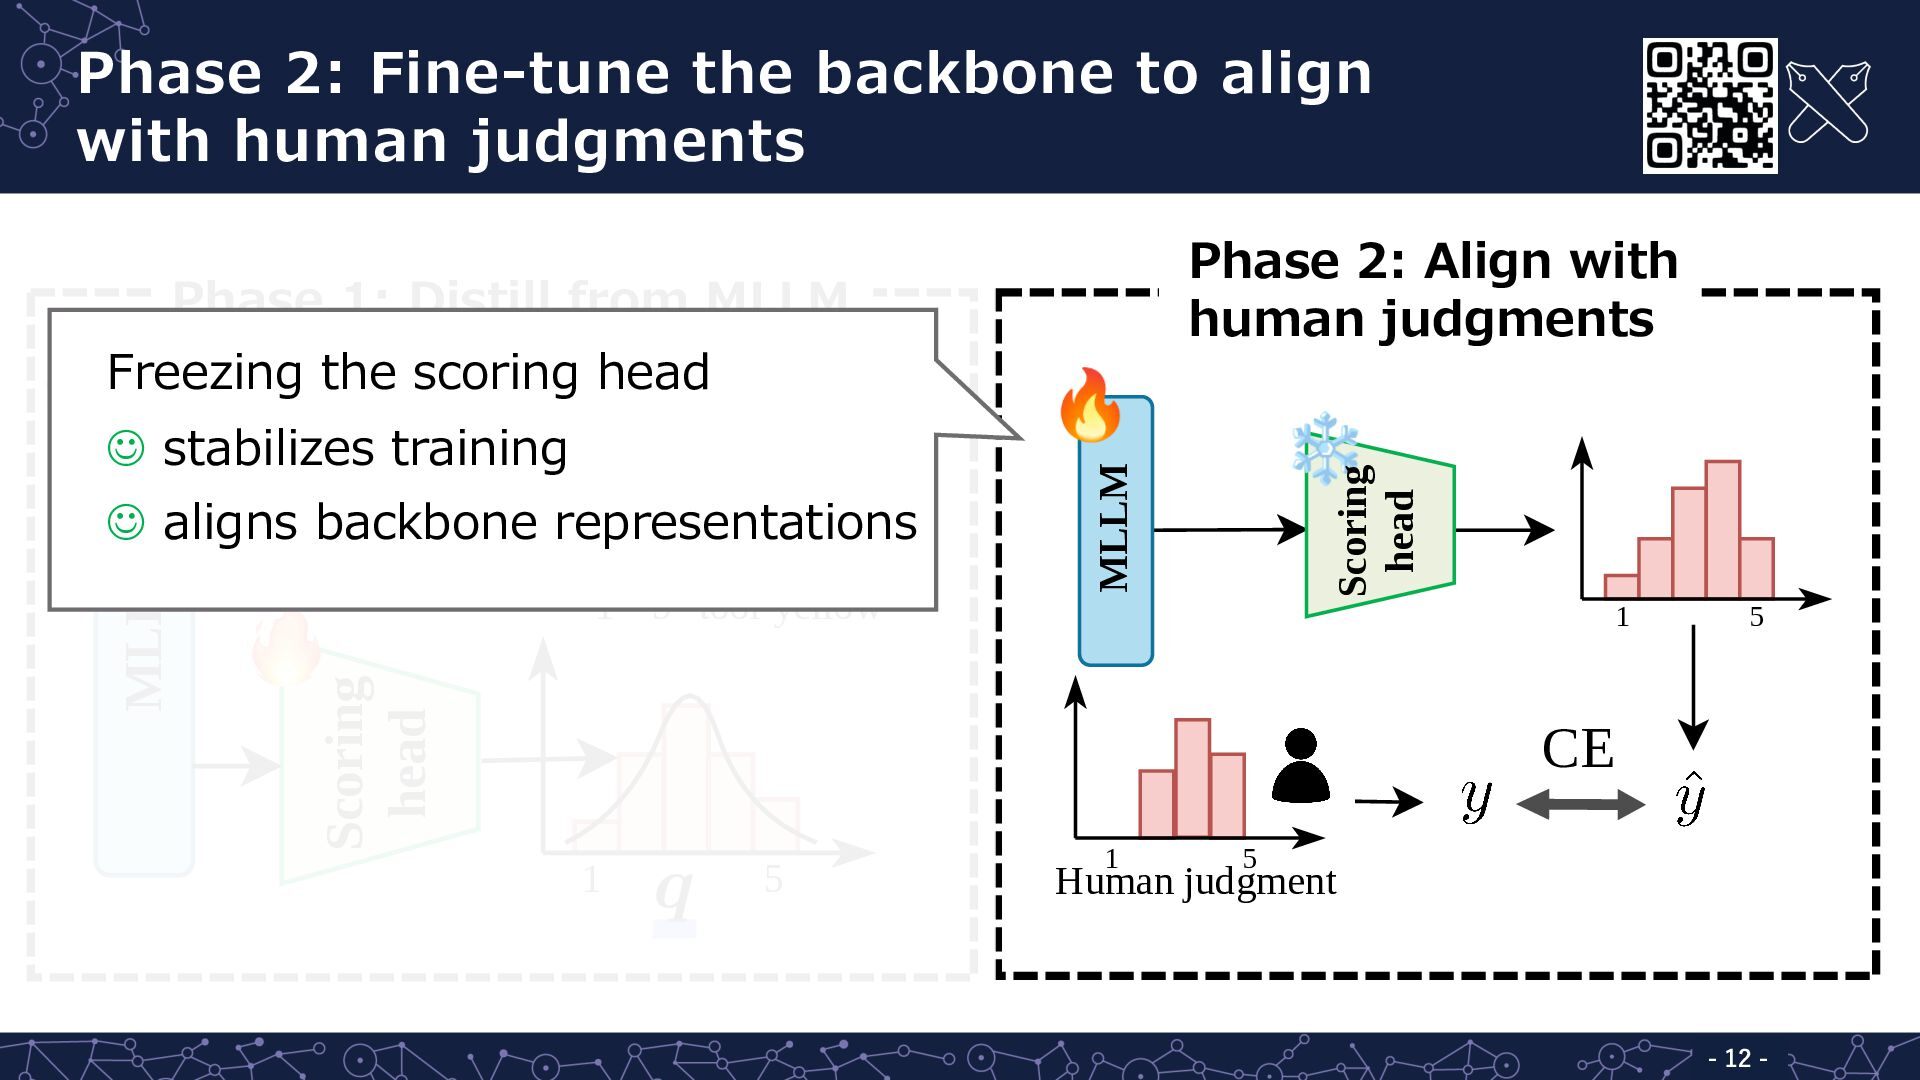
Phase 2: Align with 1 human judgments 1 from MLLM Phase 1: Distill 🔥 1 1 5 tool yellow Scoring head MLLM J aligns backbone representations Scoring head ❄J stabilizes training MLLM Freezing the scoring head 1 5 CE 1 5 1 5 Human judgment - 12 -
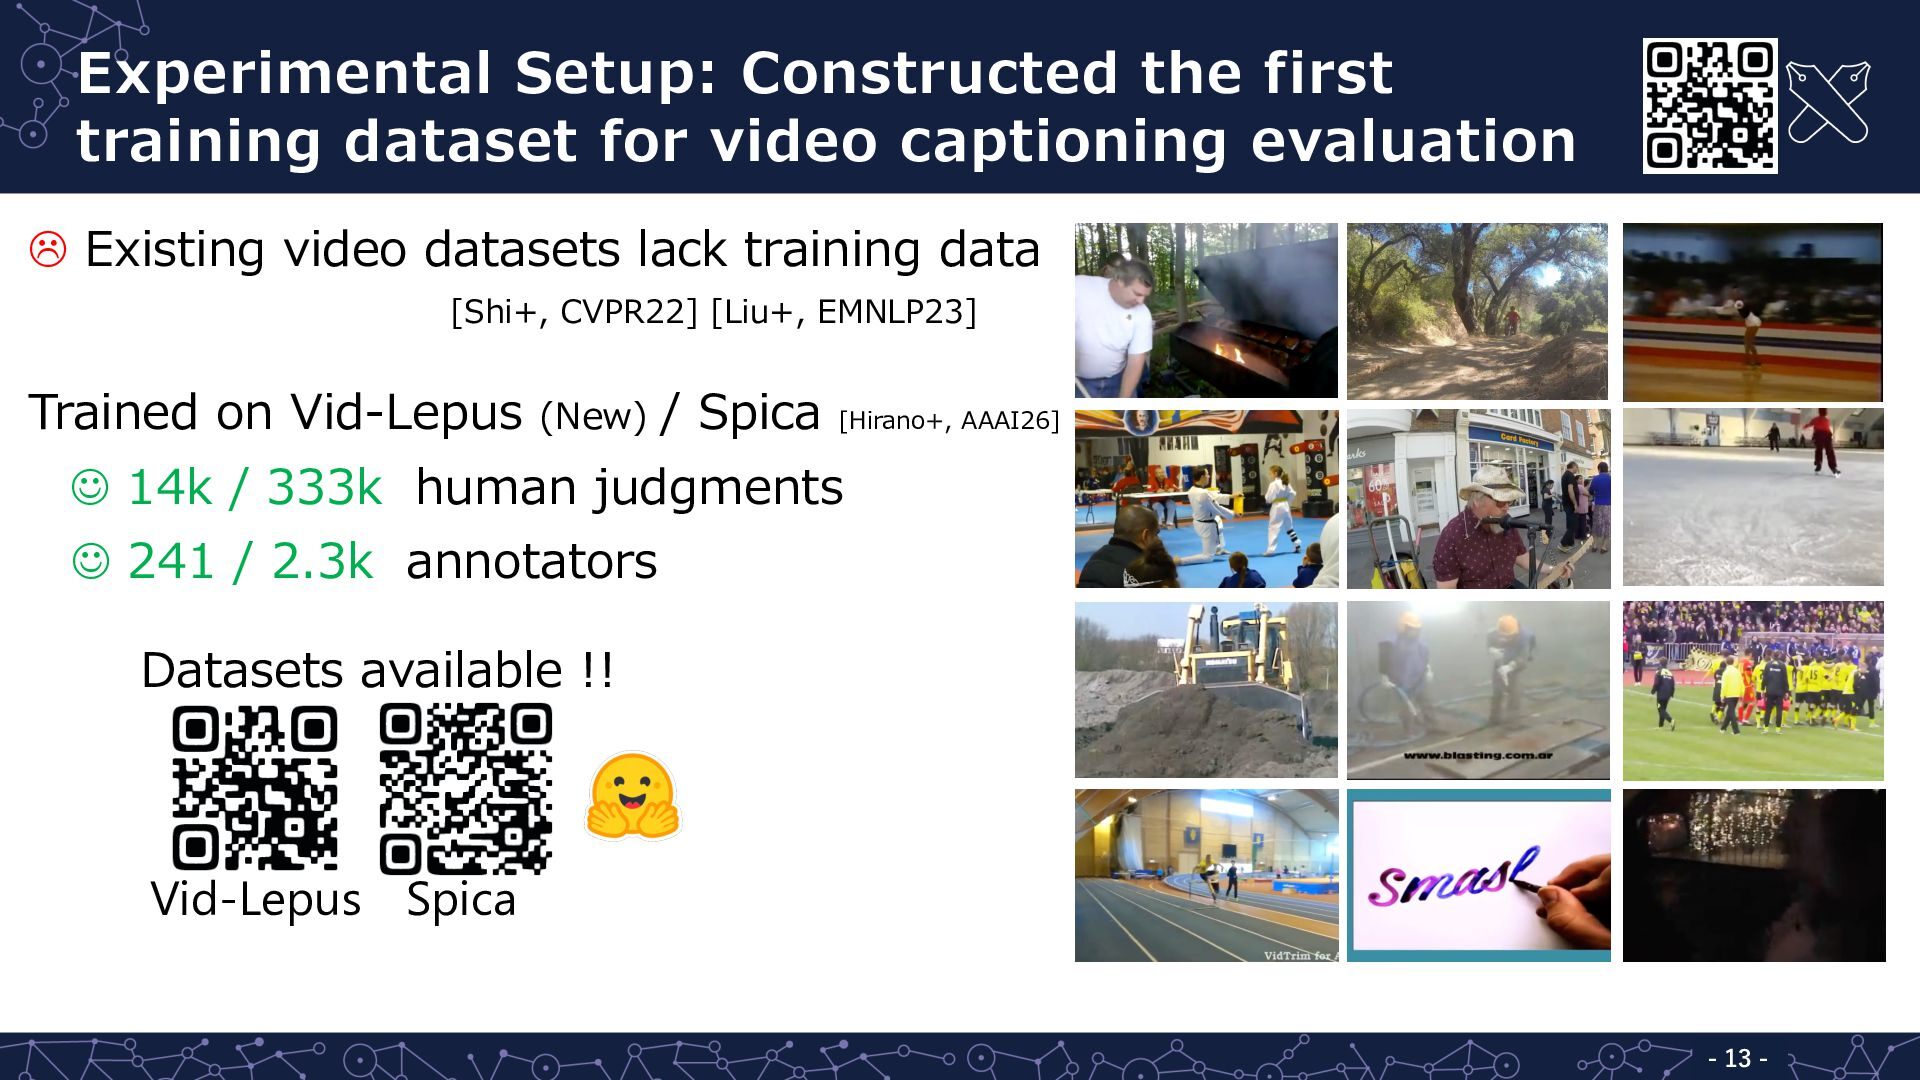
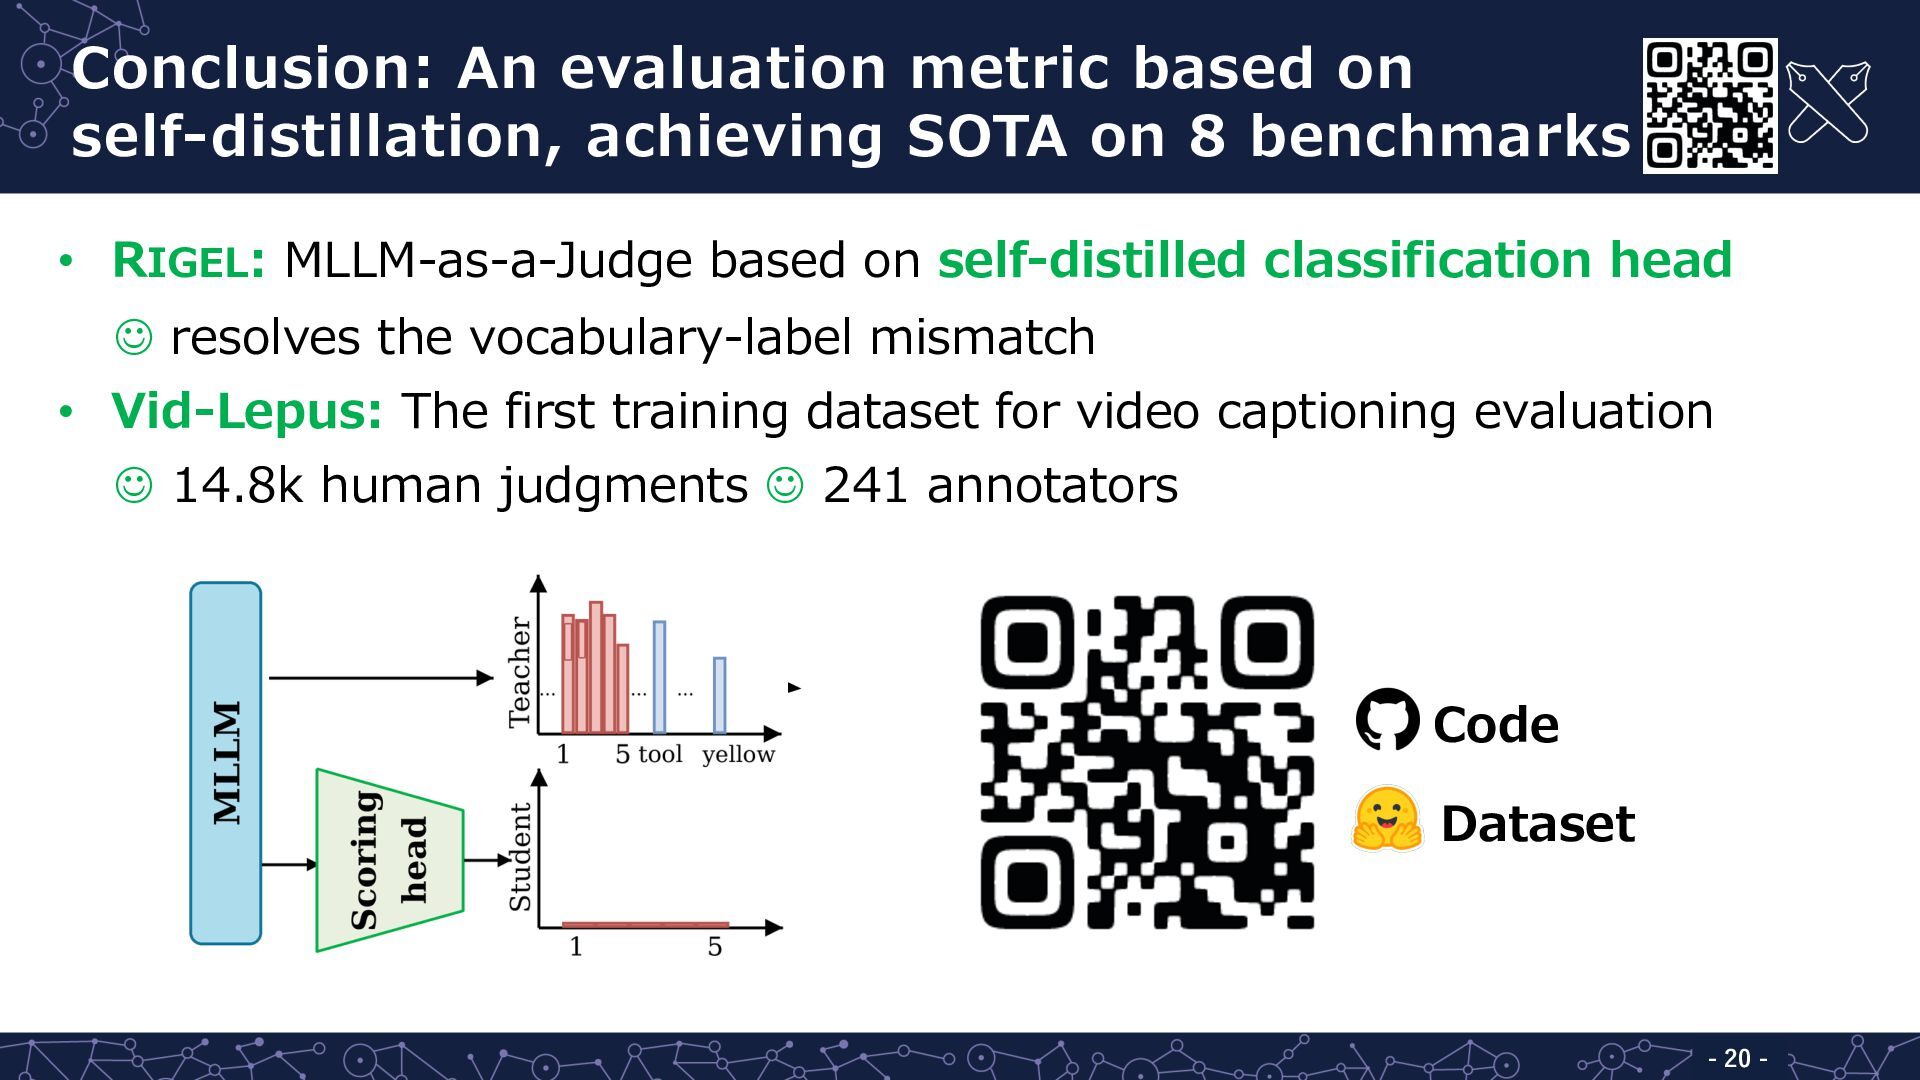
8 benchmarks • RIGEL: MLLM-as-a-Judge based on self-distilled classification head J resolves the vocabulary-label mismatch • Vid-Lepus: The first training dataset for video captioning evaluation J 14.8k human judgments J 241 annotators Code Dataset - 20 -


 keio_smilab
 takahashim
 puhitaku
 yahonda
 y0hgi
 yamanoku
 endonanana
 takanorip
 livesense
 mkdev10
 raspython3
 yazm
 jyouryuusui
 vanstee
 akademiya2063
 aemeredith
 kevinliebholz
 quramy
 sarafernandez
 livdayseo
 jonoalderson
 keathley
 moore
 ks91
 jnunemaker