Share
Embed
Gemma for Your Device - IO Extended Inchoen 2025
Google이 공개한 오픈웨이트 모델 Gemma 2B를 소형 디바이스에 탑재하기 위한 최소화 작업을 진행하고, DeepMind의 Token 기반 Chain-of-Thought 최적화 방법을 구현한 과정을 공유합니다.
Sungmin Han
August 02, 2025
Transcript
41 slides
-
Google I/O Extended 25 Proprietary & Confidential • Edge AI
Index • Gemma 3 • Demonstration • Conclusion -
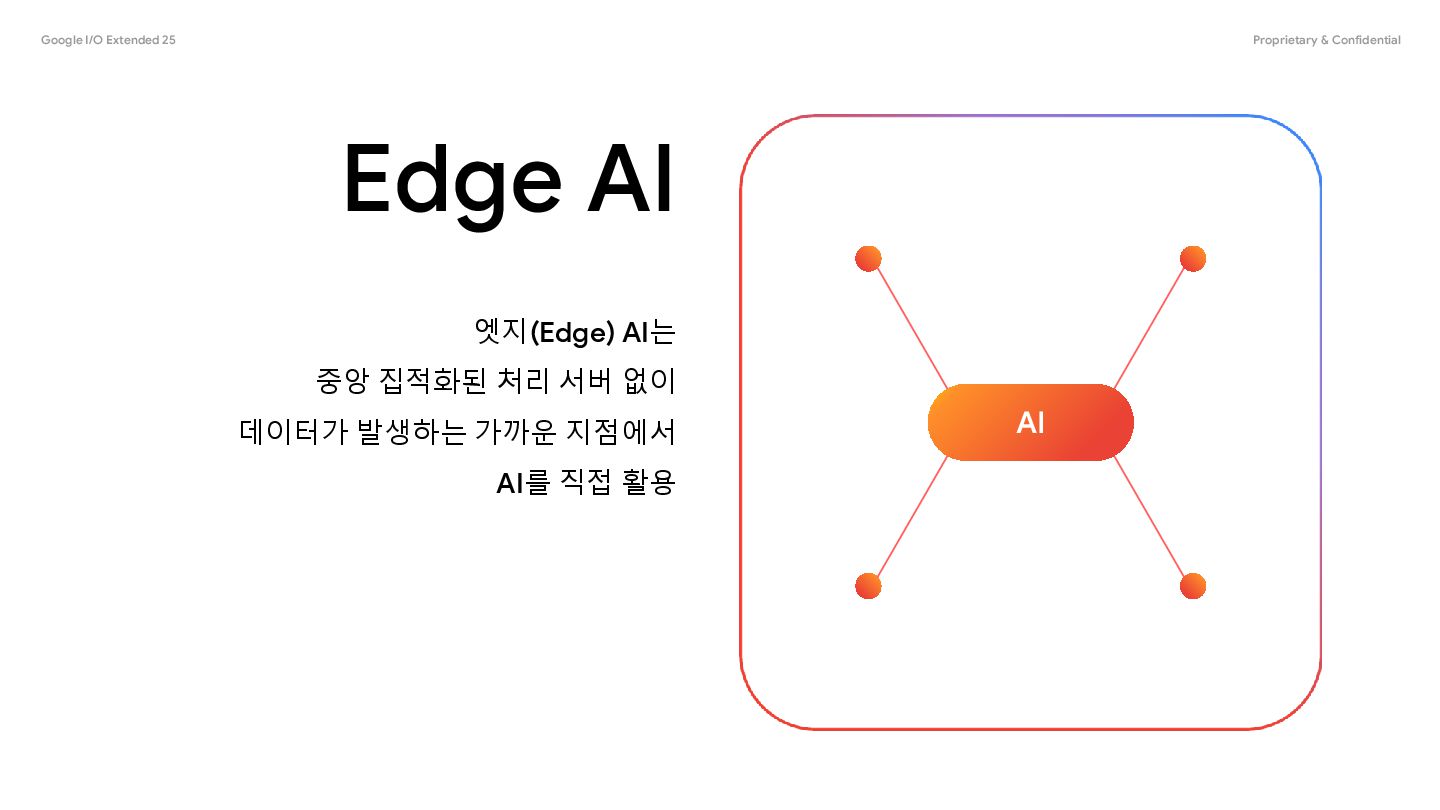
Google I/O Extended 25 Proprietary & Confidential Edge AI 엣지(Edge)
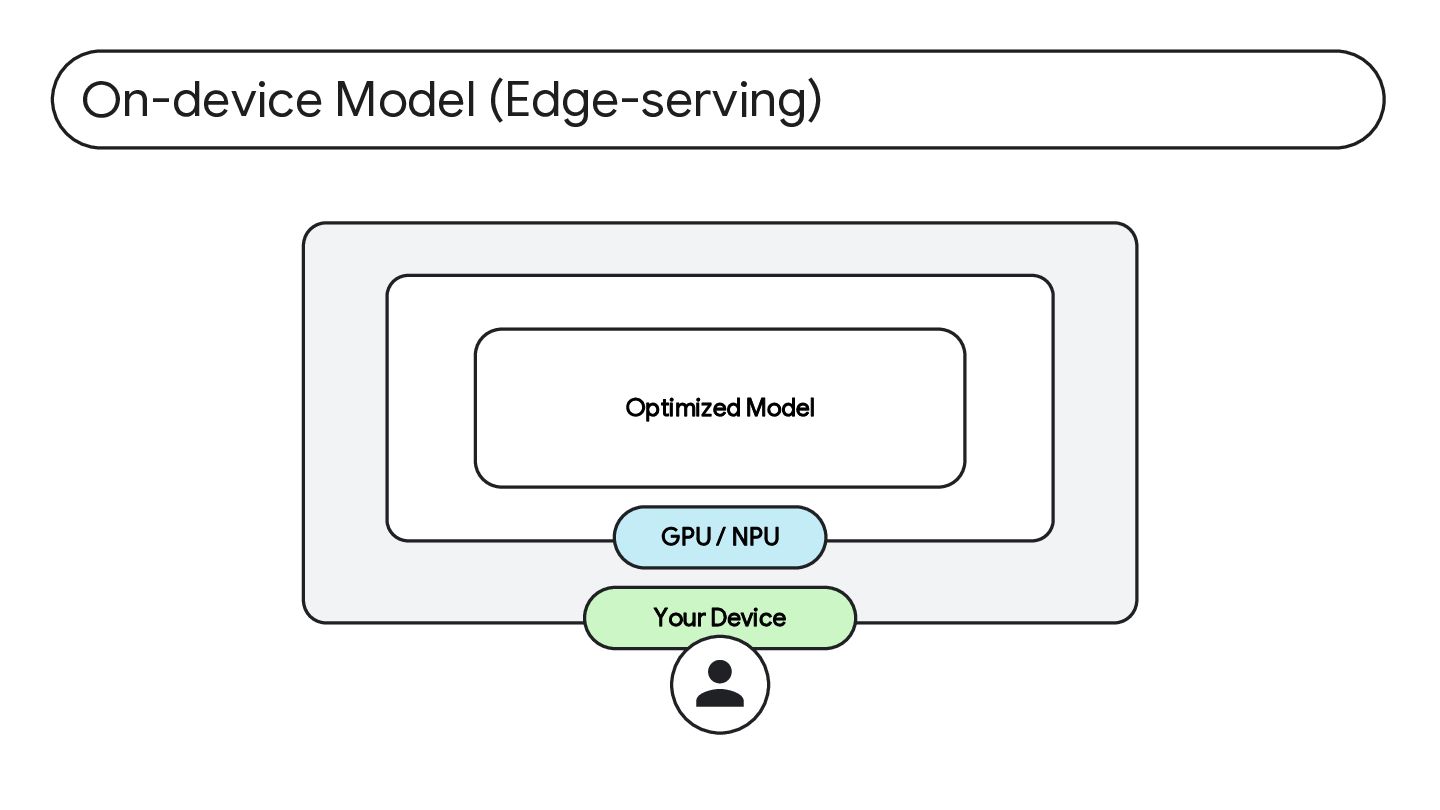
AI는 중앙 집적화된 처리 서버 없이 데이터가 발생하는 가까운 지점에서 AI를 직접 활용 AI -
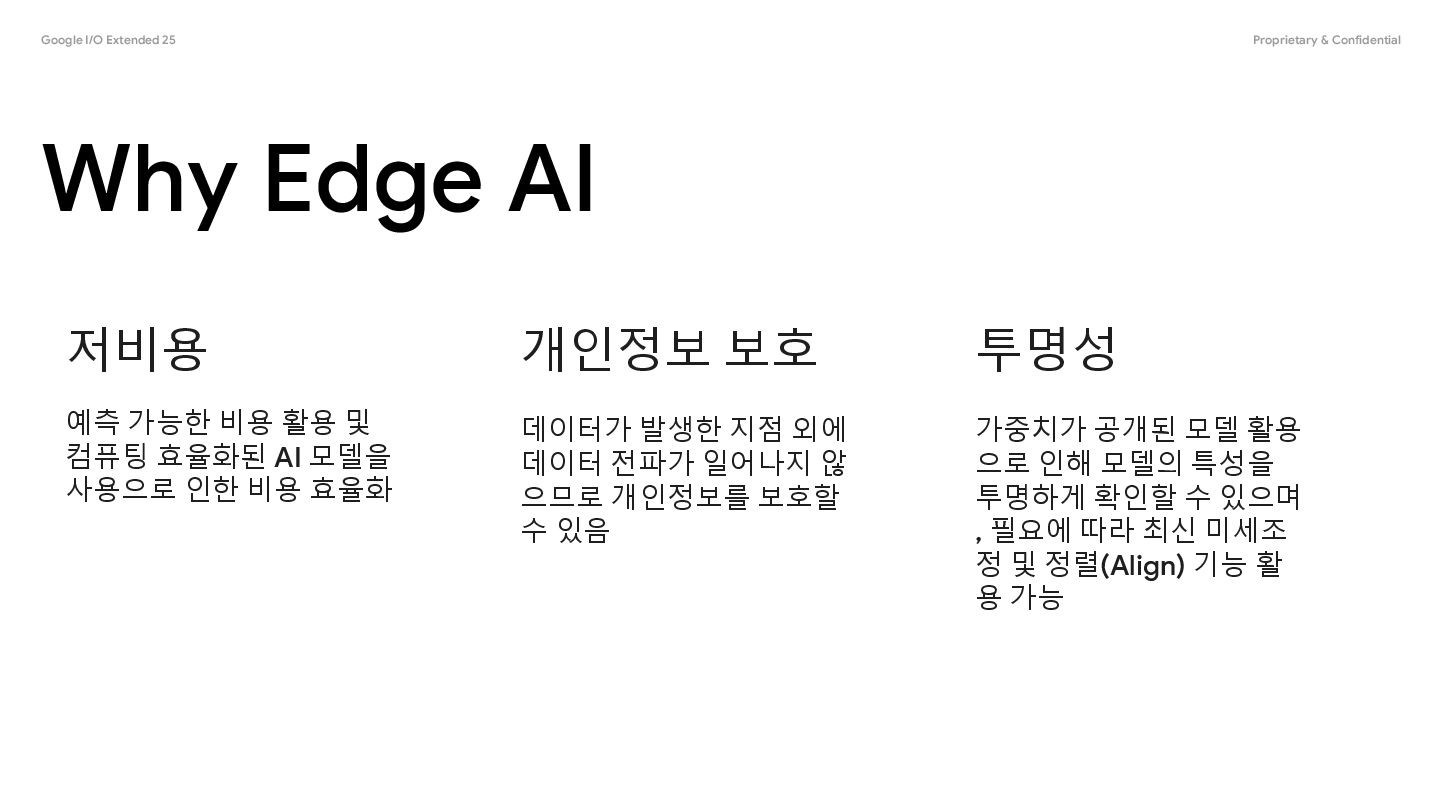
Google I/O Extended 25 Proprietary & Confidential Why Edge AI
저비용 예측 가능한 비용 활용 및 컴퓨팅 효율화된 AI 모델을 사용으로 인한 비용 효율화 개인정보 보호 데이터가 발생한 지점 외에 데이터 전파가 일어나지 않 으므로 개인정보를 보호할 수 있음 투명성 가중치가 공개된 모델 활용 으로 인해 모델의 특성을 투명하게 확인할 수 있으며 , 필요에 따라 최신 미세조 정 및 정렬(Align) 기능 활 용 가능 -
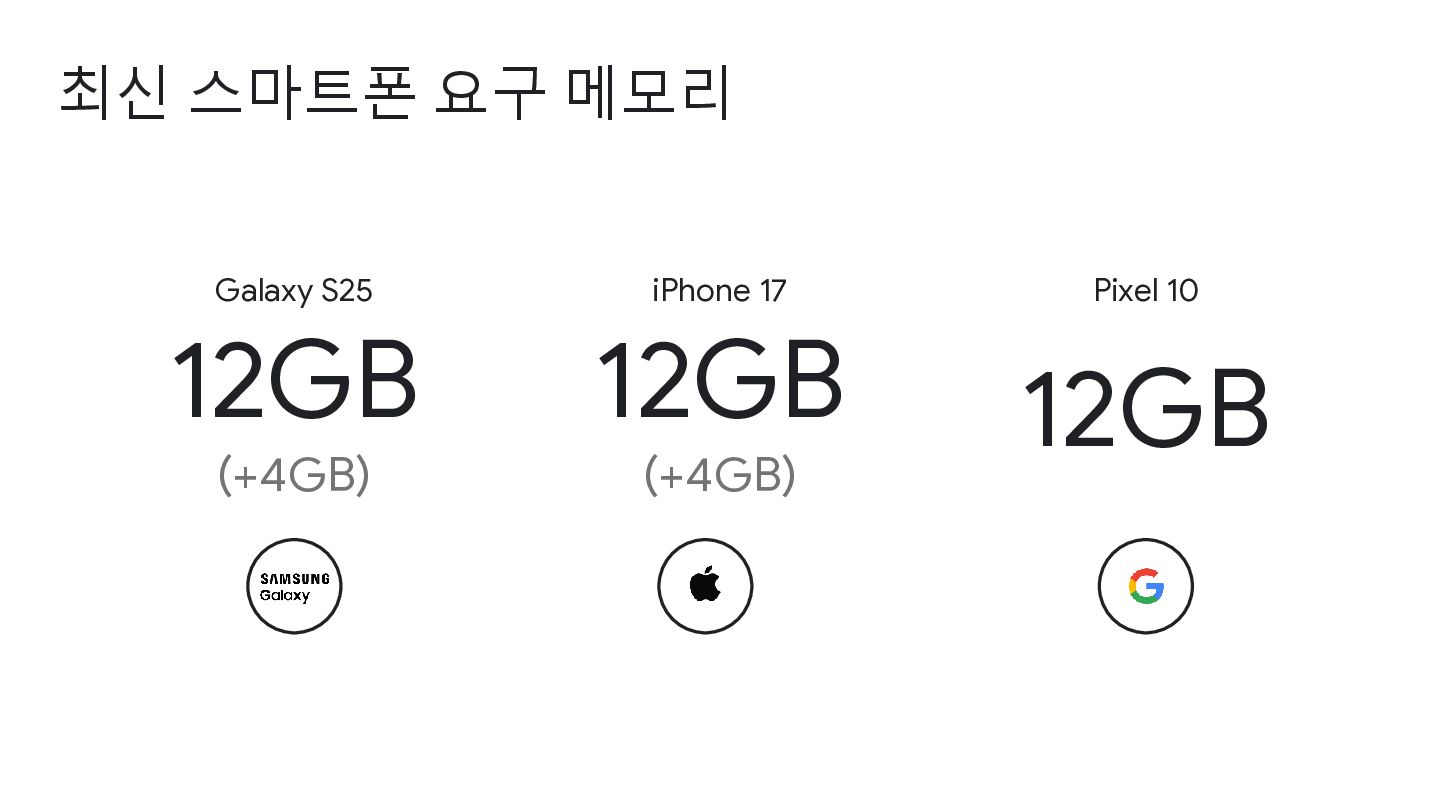
최신 스마트폰 요구 메모리 12GB (+4GB) 12GB (+4GB) 12GB Galaxy
S25 iPhone 17 Pixel 10 -
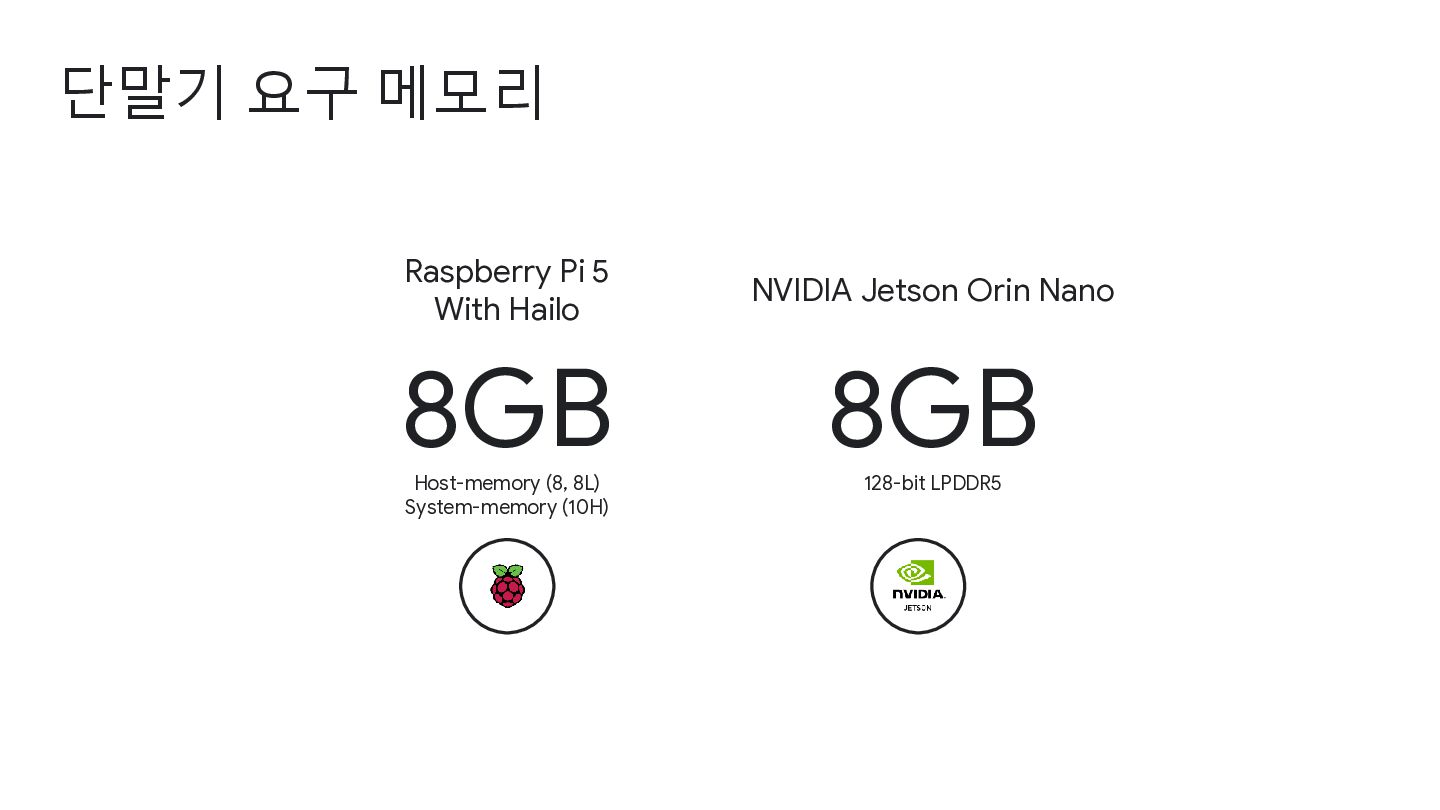
단말기 요구 메모리 8GB 8GB Raspberry Pi 5 With Hailo
NVIDIA Jetson Orin Nano Host-memory (8, 8L) System-memory (10H) 128-bit LPDDR5 -
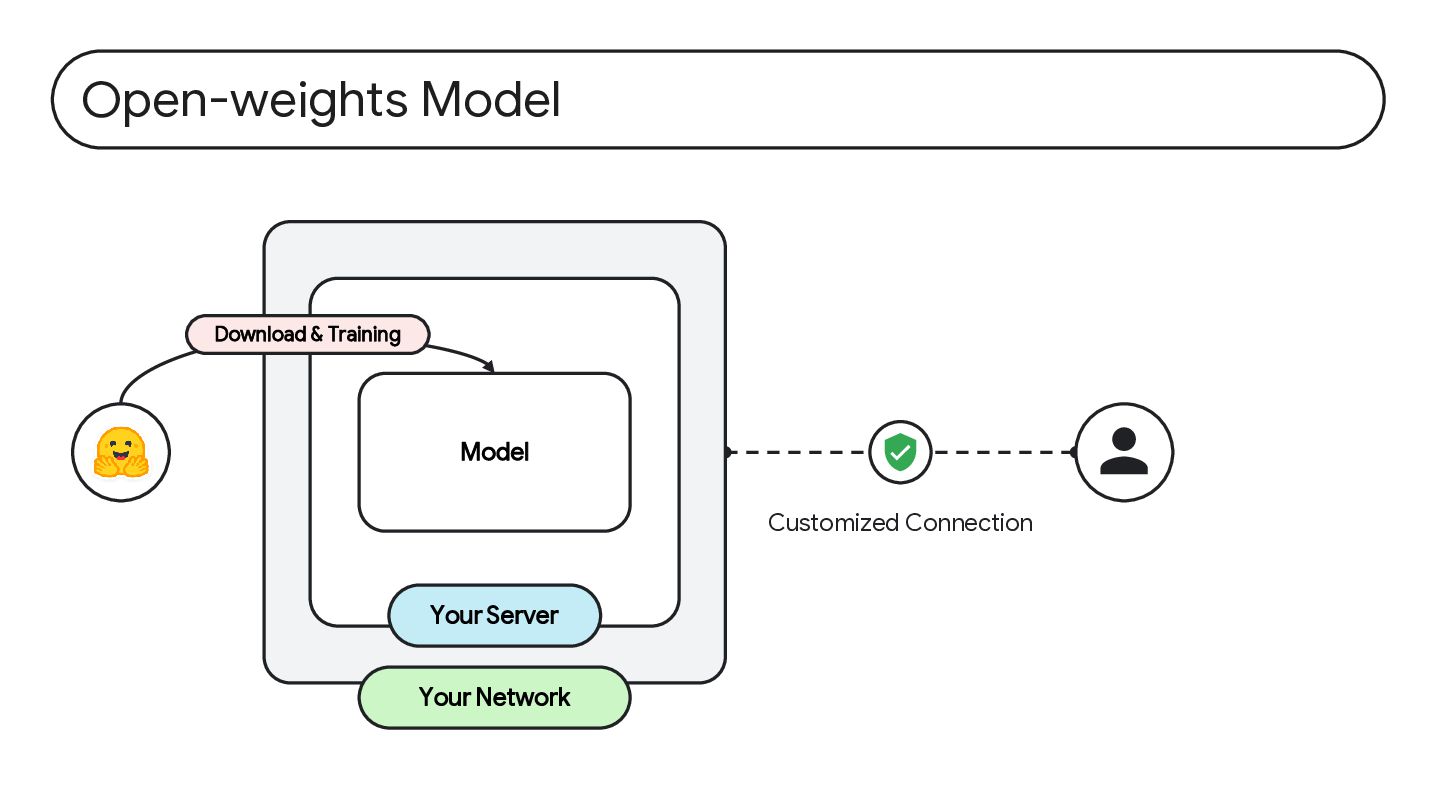
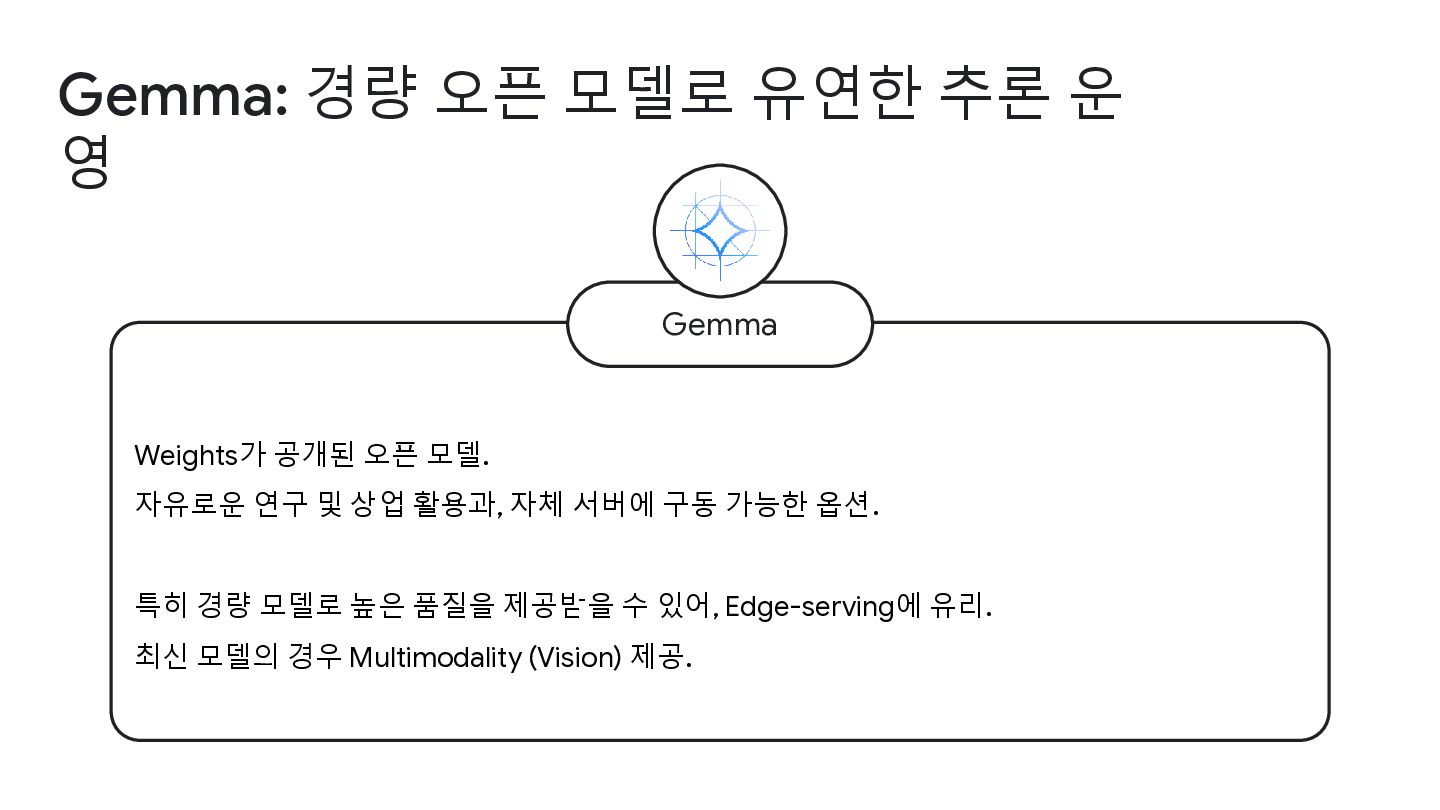
Weights가 공개된 오픈 모델. 자유로운 연구 및 상업 활용과, 자체
서버에 구동 가능한 옵션. 특히 경량 모델로 높은 품질을 제공받을 수 있어, Edge-serving에 유리. 최신 모델의 경우 Multimodality (Vision) 제공. Gemma Gemma: 경량 오픈 모델로 유연한 추론 운 영 -
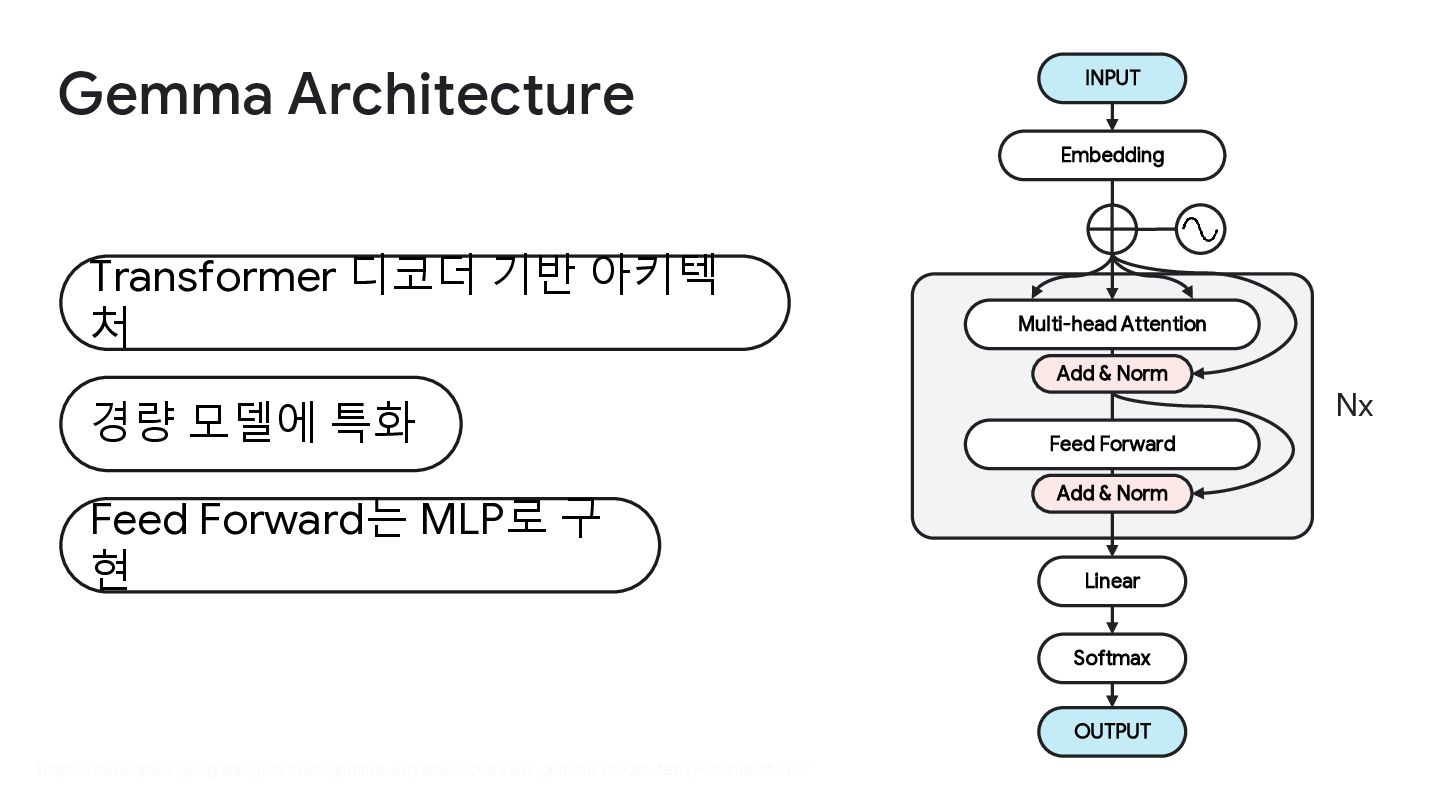
Gemma Architecture https://developers.googleblog.com/en/gemma-explained-overview-gemma-model-family-architectures/ INPUT Embedding Linear Softmax OUTPUT Multi-head Attention
Add & Norm Feed Forward Add & Norm Transformer 디코더 기반 아키텍 처 경량 모델에 특화 Feed Forward는 MLP로 구 현 Nx -
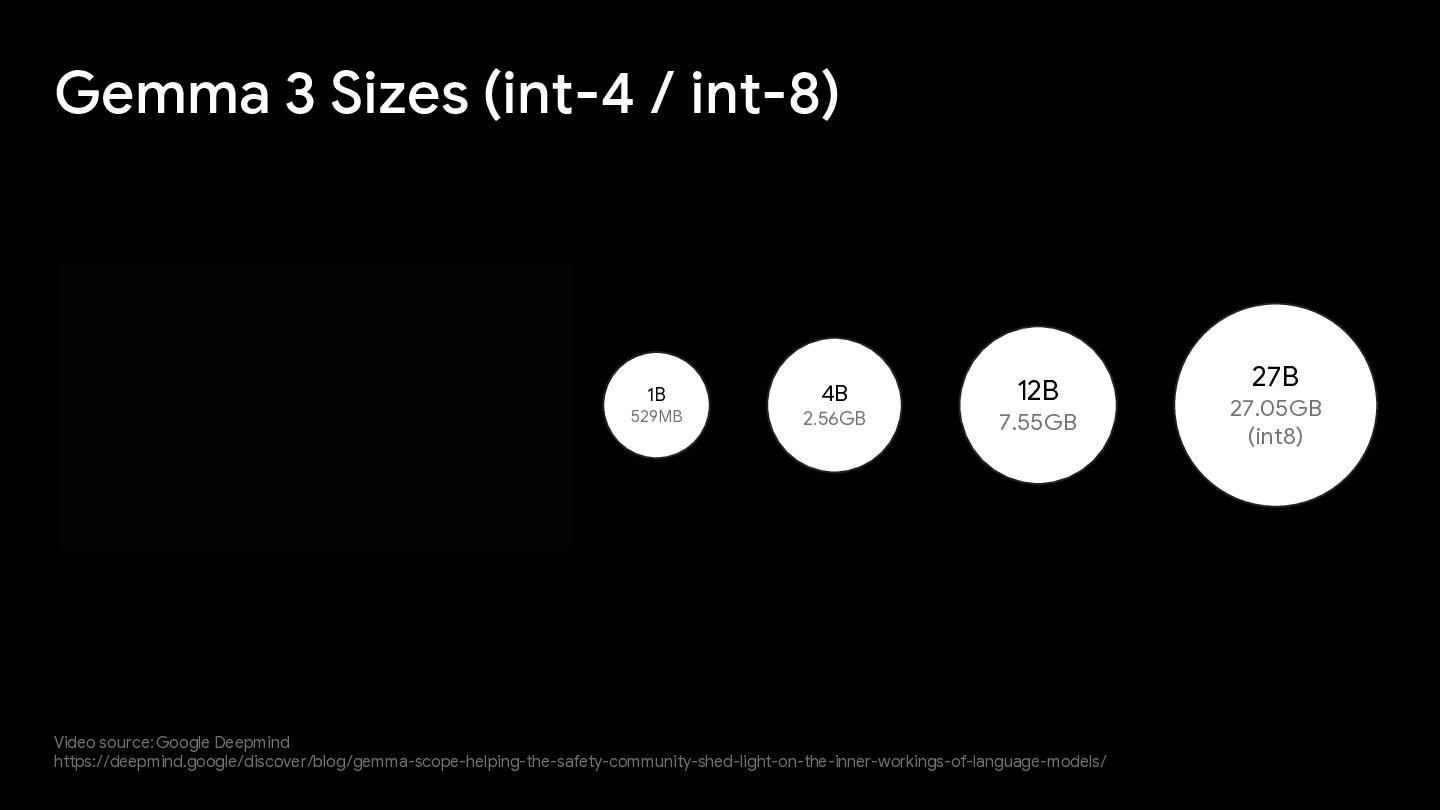
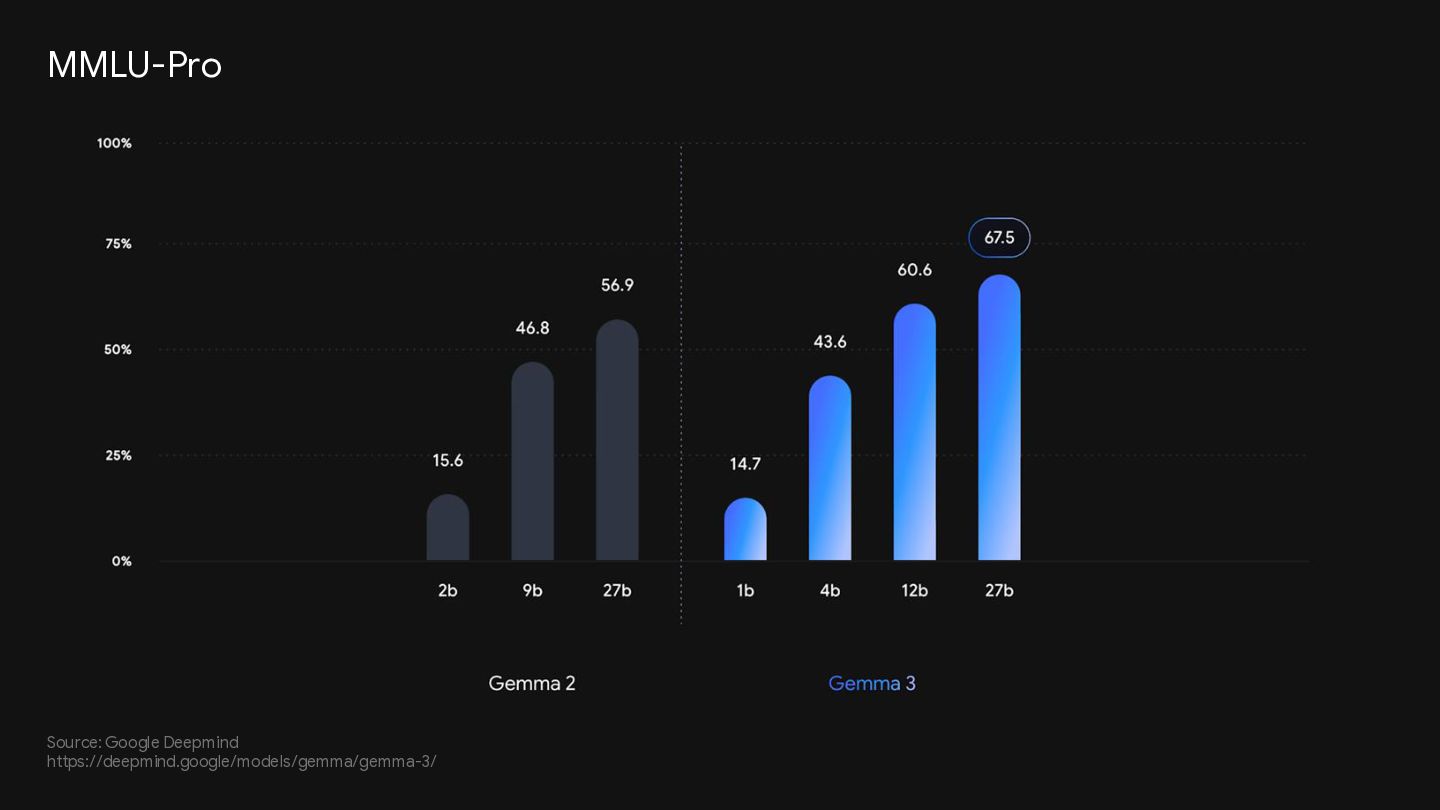
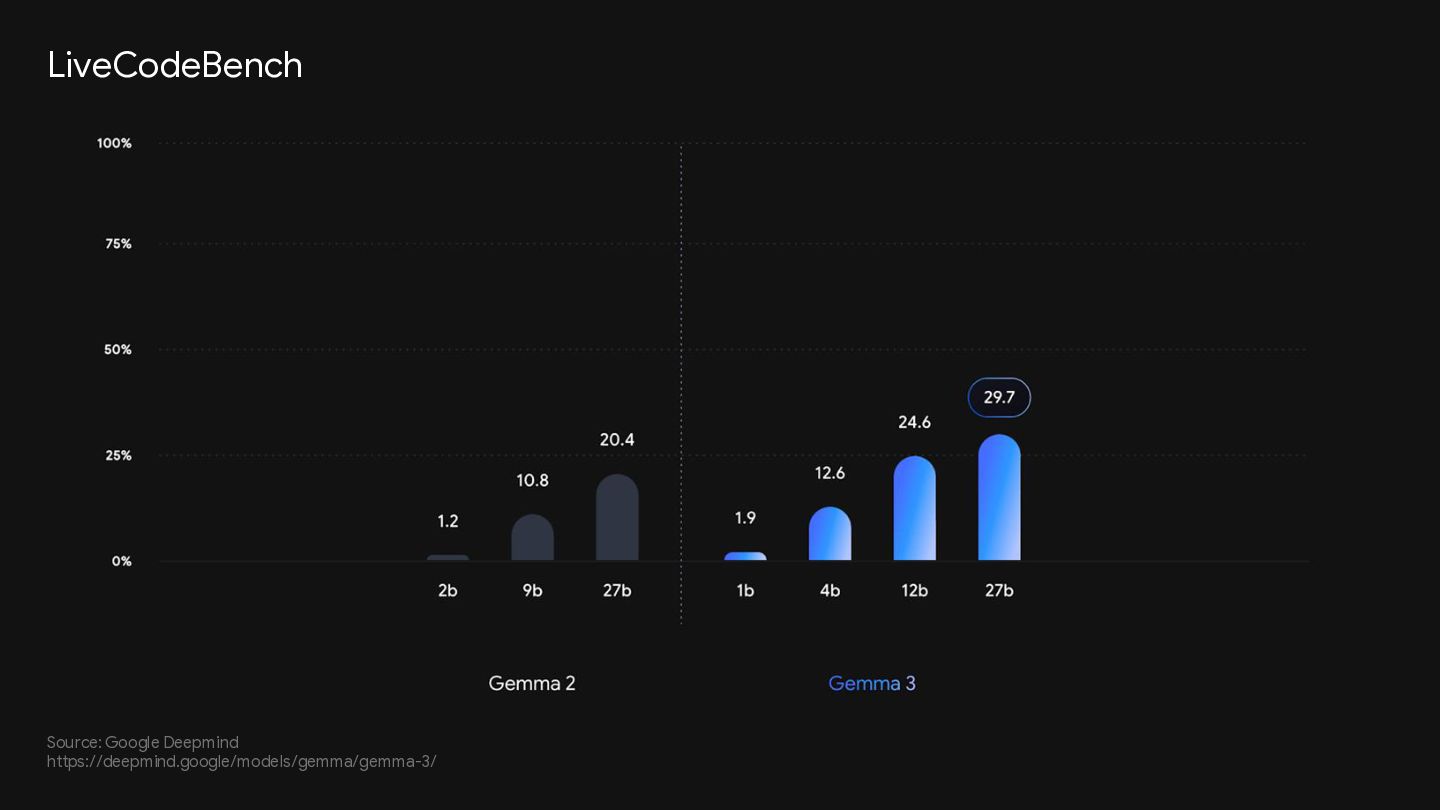
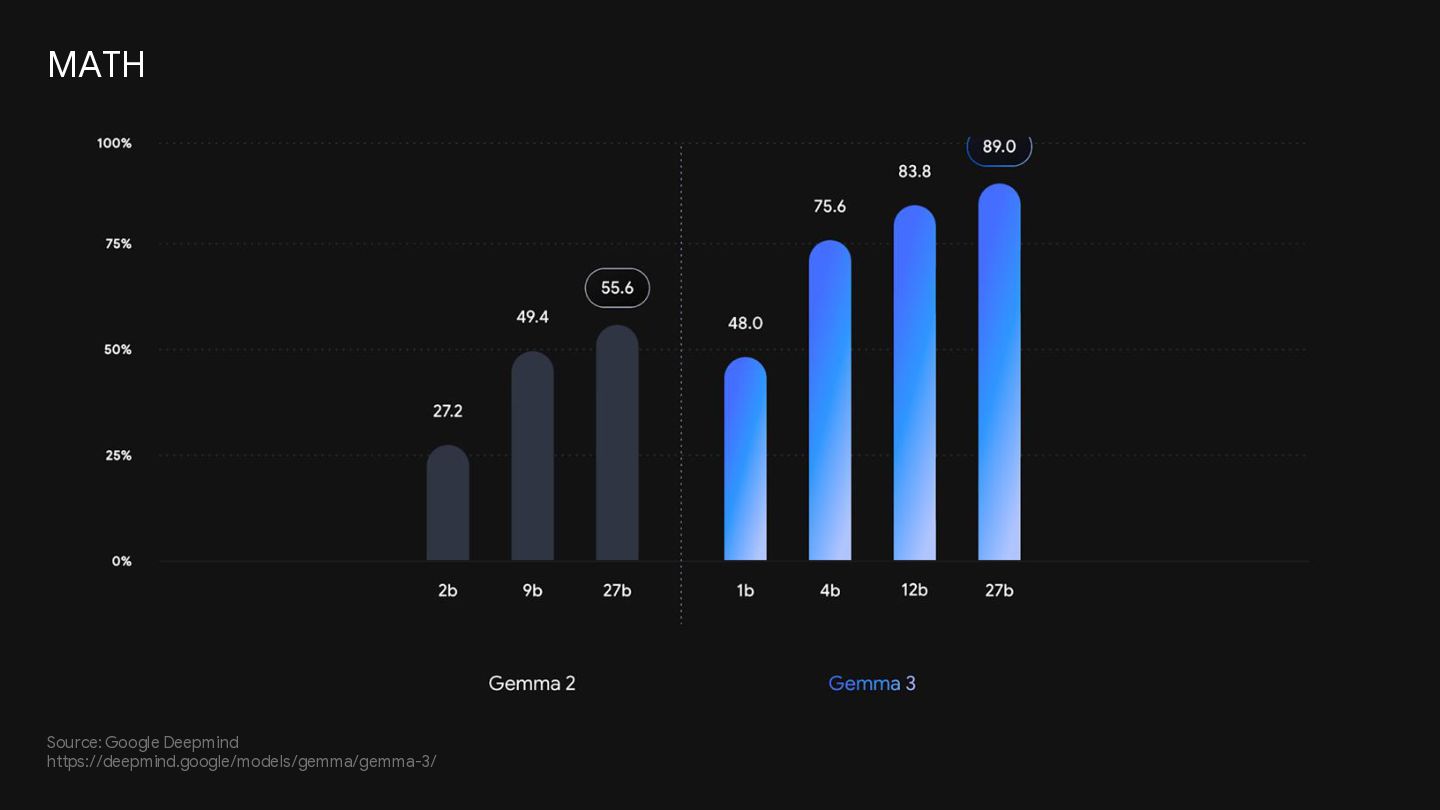
Gemma 3 Sizes (int-4 / int-8) 1B 529MB 4B 2.56GB
12B 7.55GB Video source: Google Deepmind https://deepmind.google/discover/blog/gemma-scope-helping-the-safety-community-shed-light-on-the-inner-workings-of-language-models/ 27B 27.05GB (int8) -
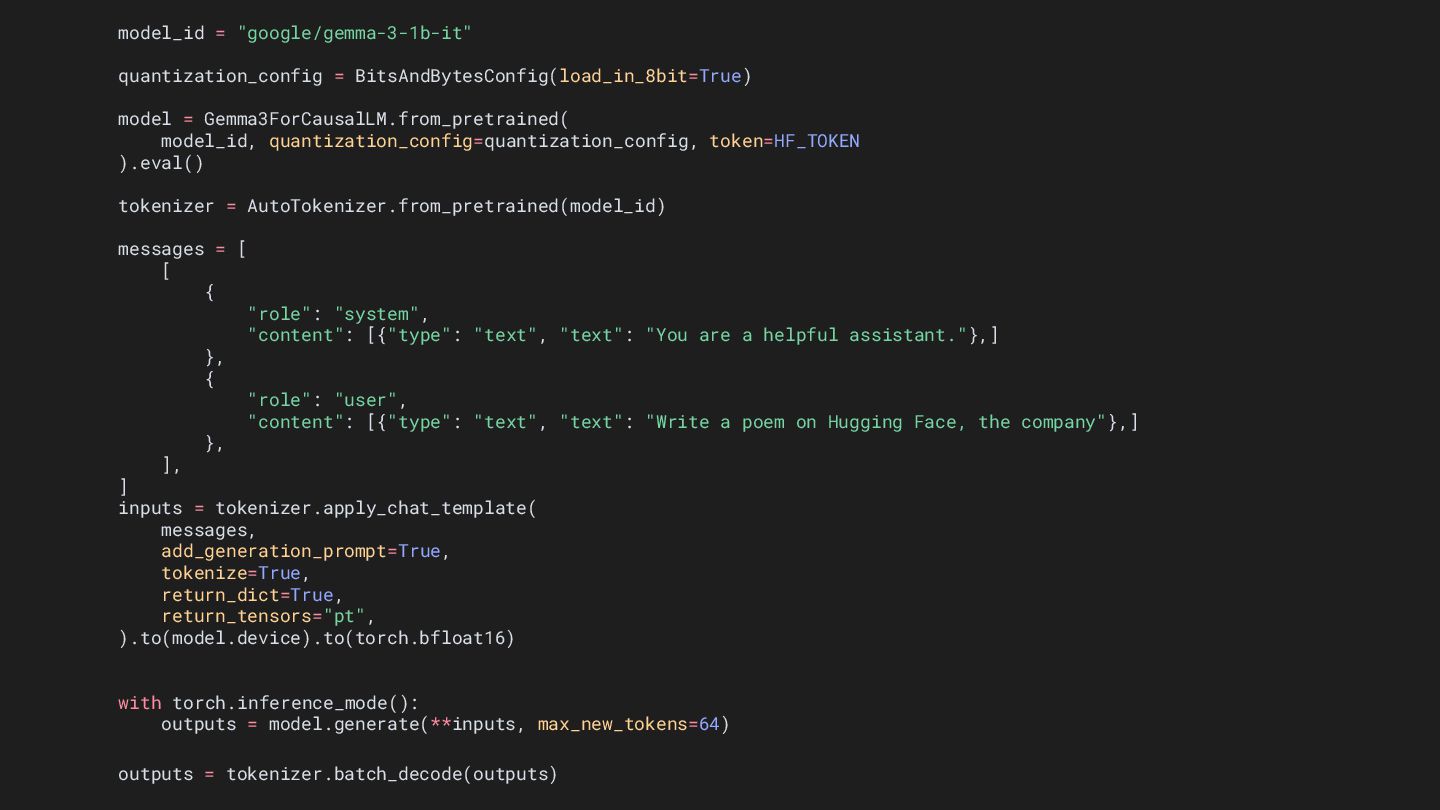
model_id = "google/gemma-3-1b-it" quantization_config = BitsAndBytesConfig(load_in_8bit=True) model = Gemma3ForCausalLM.from_pretrained( model_id,
quantization_config=quantization_config, token=HF_TOKEN ).eval() tokenizer = AutoTokenizer.from_pretrained(model_id) messages = [ [ { "role": "system", "content": [{"type": "text", "text": "You are a helpful assistant."},] }, { "role": "user", "content": [{"type": "text", "text": "Write a poem on Hugging Face, the company"},] }, ], ] inputs = tokenizer.apply_chat_template( messages, add_generation_prompt=True, tokenize=True, return_dict=True, return_tensors="pt", ).to(model.device).to(torch.bfloat16) with torch.inference_mode(): outputs = model.generate(**inputs, max_new_tokens=64) outputs = tokenizer.batch_decode(outputs) -
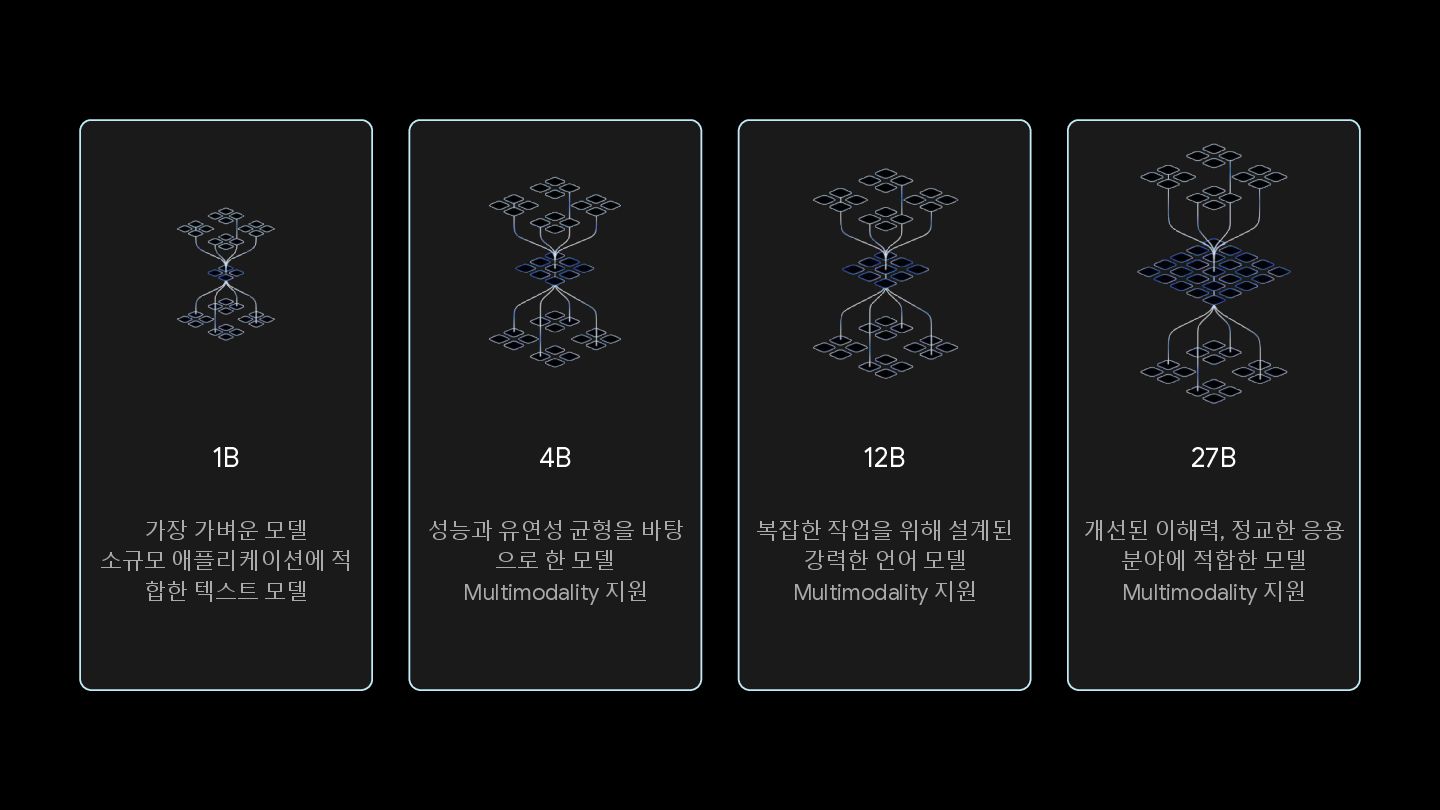
1B 가장 가벼운 모델 소규모 애플리케이션에 적 합한 텍스트 모델
4B 성능과 유연성 균형을 바탕 으로 한 모델 Multimodality 지원 12B 복잡한 작업을 위해 설계된 강력한 언어 모델 Multimodality 지원 27B 개선된 이해력, 정교한 응용 분야에 적합한 모델 Multimodality 지원 -
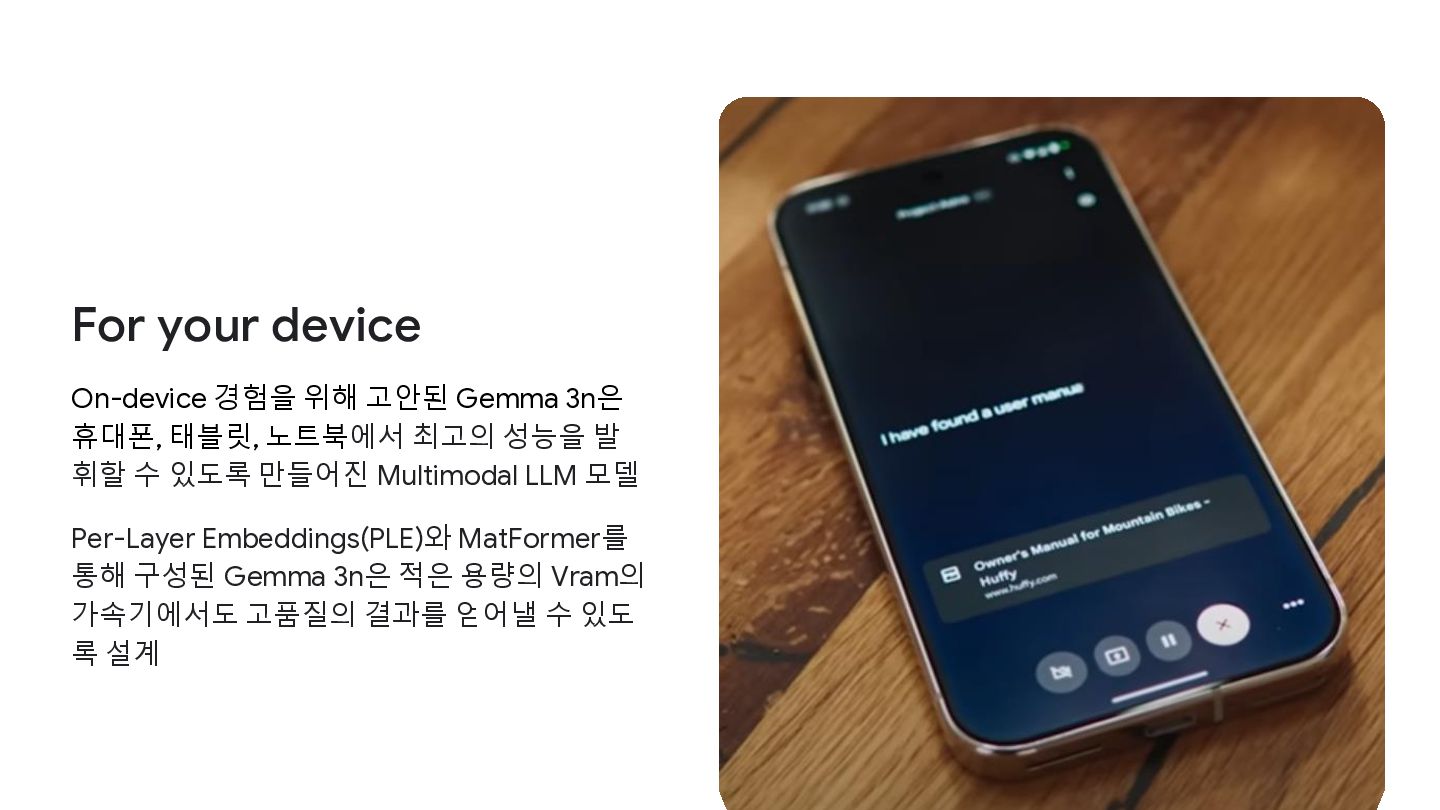
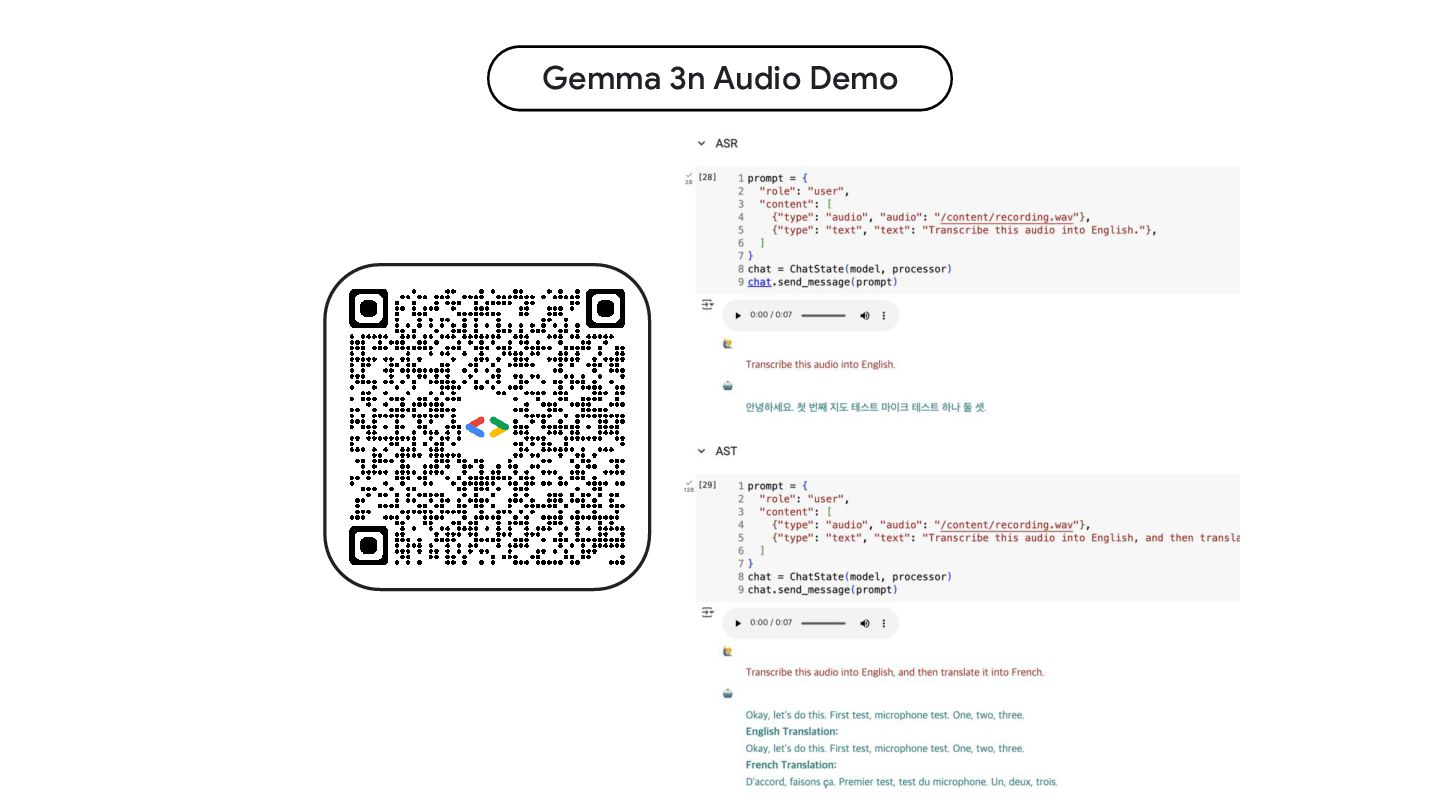
For your device On-device 경험을 위해 고안된 Gemma 3n은 휴대폰,
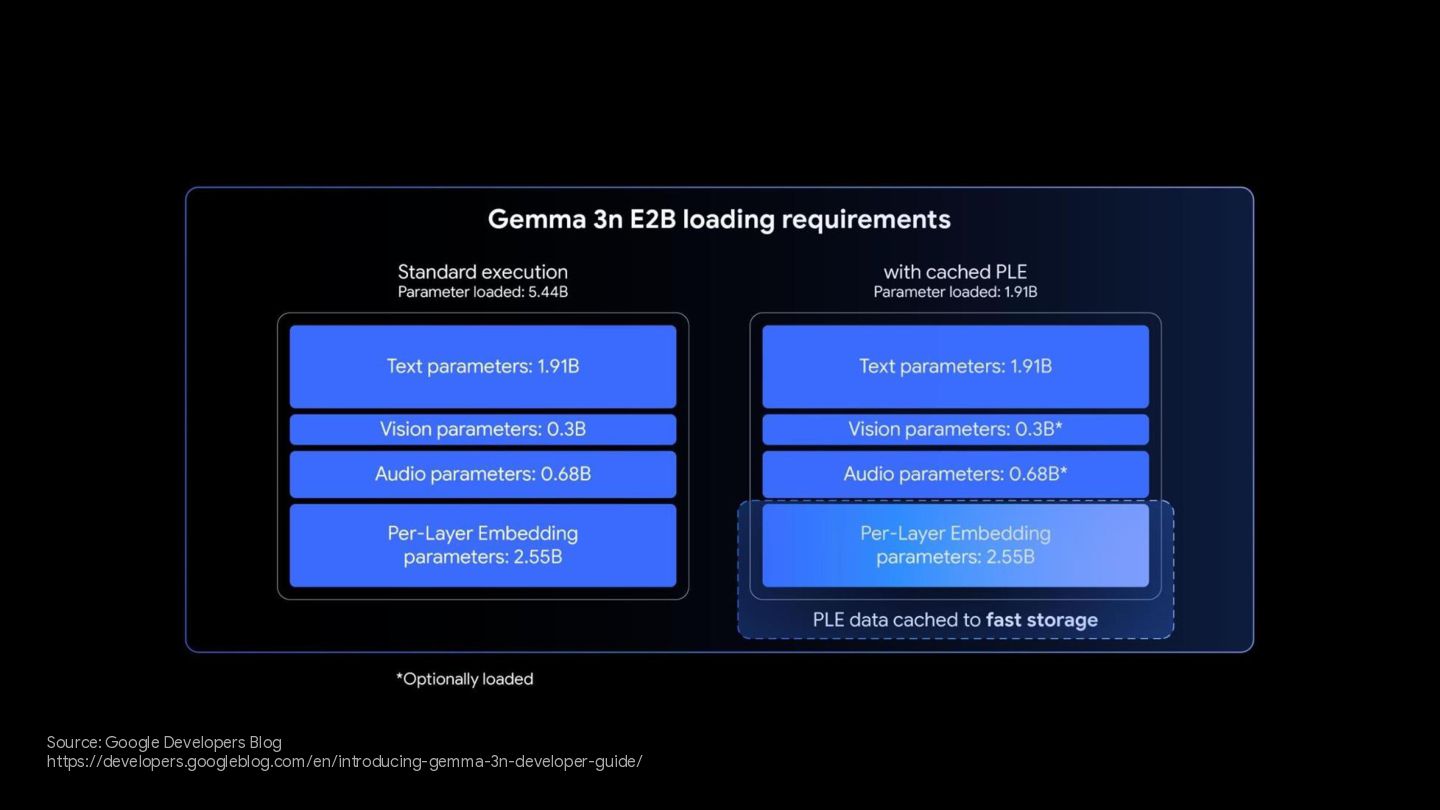
태블릿, 노트북에서 최고의 성능을 발 휘할 수 있도록 만들어진 Multimodal LLM 모델 Per-Layer Embeddings(PLE)와 MatFormer를 통해 구성된 Gemma 3n은 적은 용량의 Vram의 가속기에서도 고품질의 결과를 얻어낼 수 있도 록 설계 -
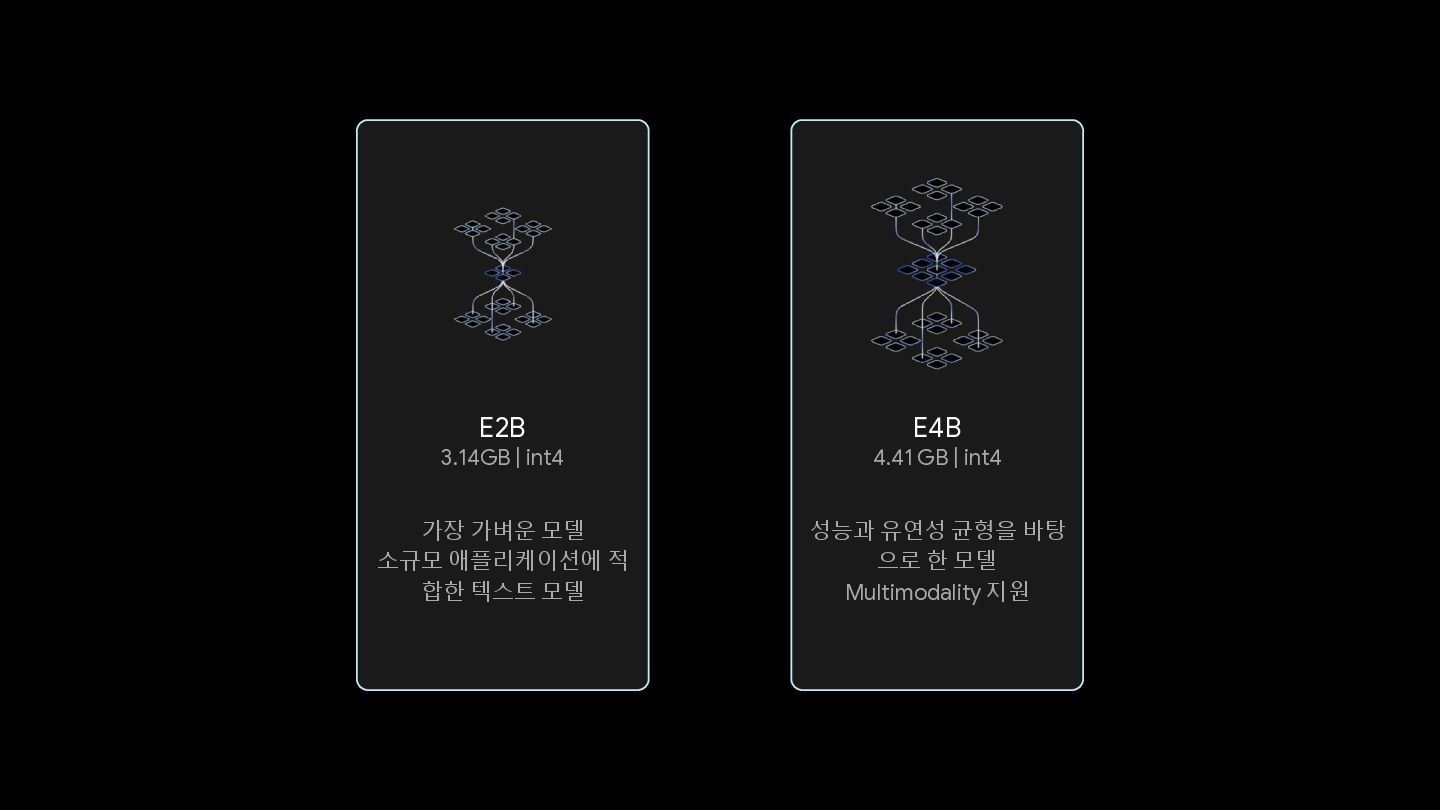
E2B 3.14GB | int4 가장 가벼운 모델 소규모 애플리케이션에 적
합한 텍스트 모델 E4B 4.41 GB | int4 성능과 유연성 균형을 바탕 으로 한 모델 Multimodality 지원 -
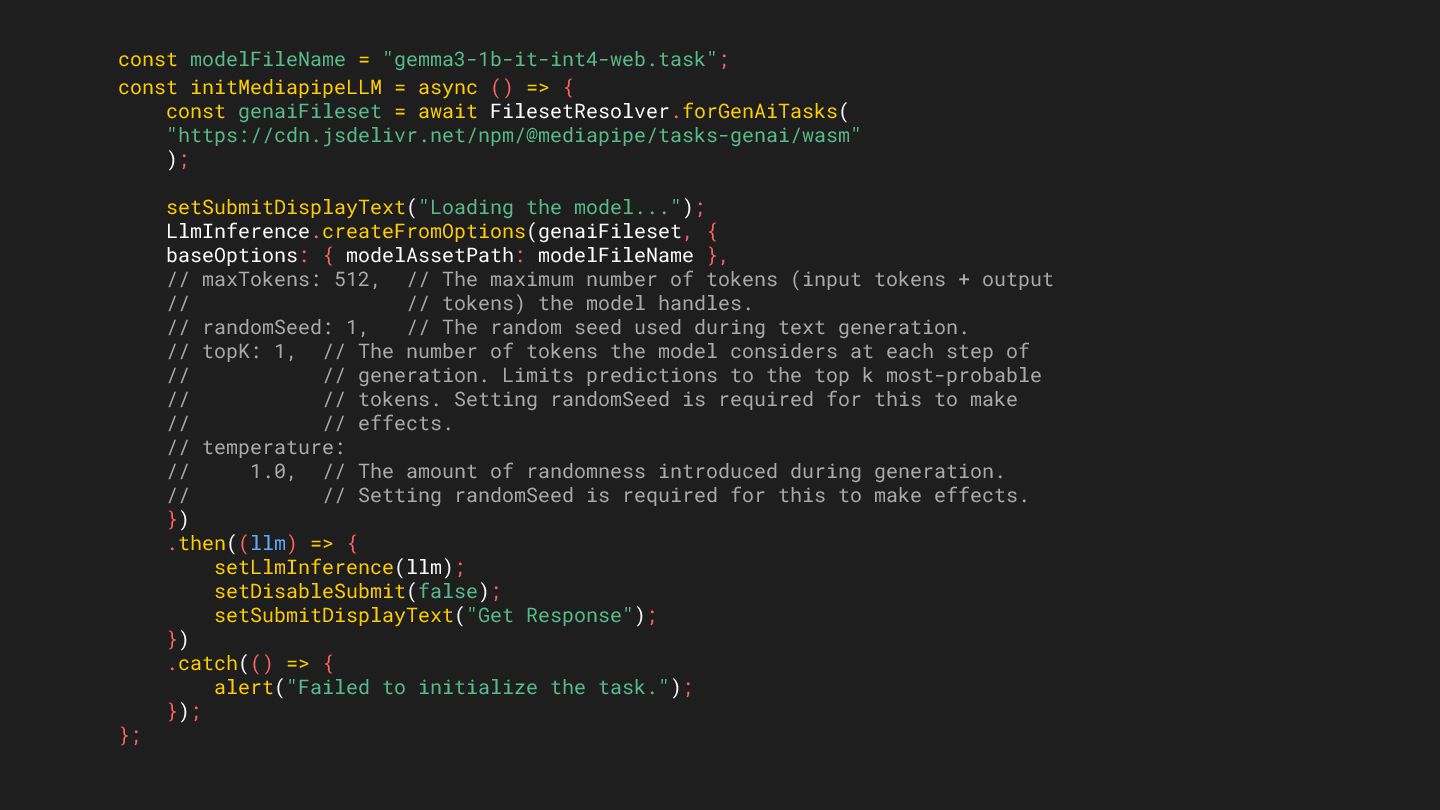
const modelFileName = "gemma3-1b-it-int4-web.task"; const initMediapipeLLM = async () =>
{ const genaiFileset = await FilesetResolver.forGenAiTasks( "https://cdn.jsdelivr.net/npm/@mediapipe/tasks-genai/wasm" ); setSubmitDisplayText("Loading the model..."); LlmInference.createFromOptions(genaiFileset, { baseOptions: { modelAssetPath: modelFileName }, // maxTokens: 512, // The maximum number of tokens (input tokens + output // // tokens) the model handles. // randomSeed: 1, // The random seed used during text generation. // topK: 1, // The number of tokens the model considers at each step of // // generation. Limits predictions to the top k most-probable // // tokens. Setting randomSeed is required for this to make // // effects. // temperature: // 1.0, // The amount of randomness introduced during generation. // // Setting randomSeed is required for this to make effects. }) .then((llm) => { setLlmInference(llm); setDisableSubmit(false); setSubmitDisplayText("Get Response"); }) .catch(() => { alert("Failed to initialize the task."); }); }; -
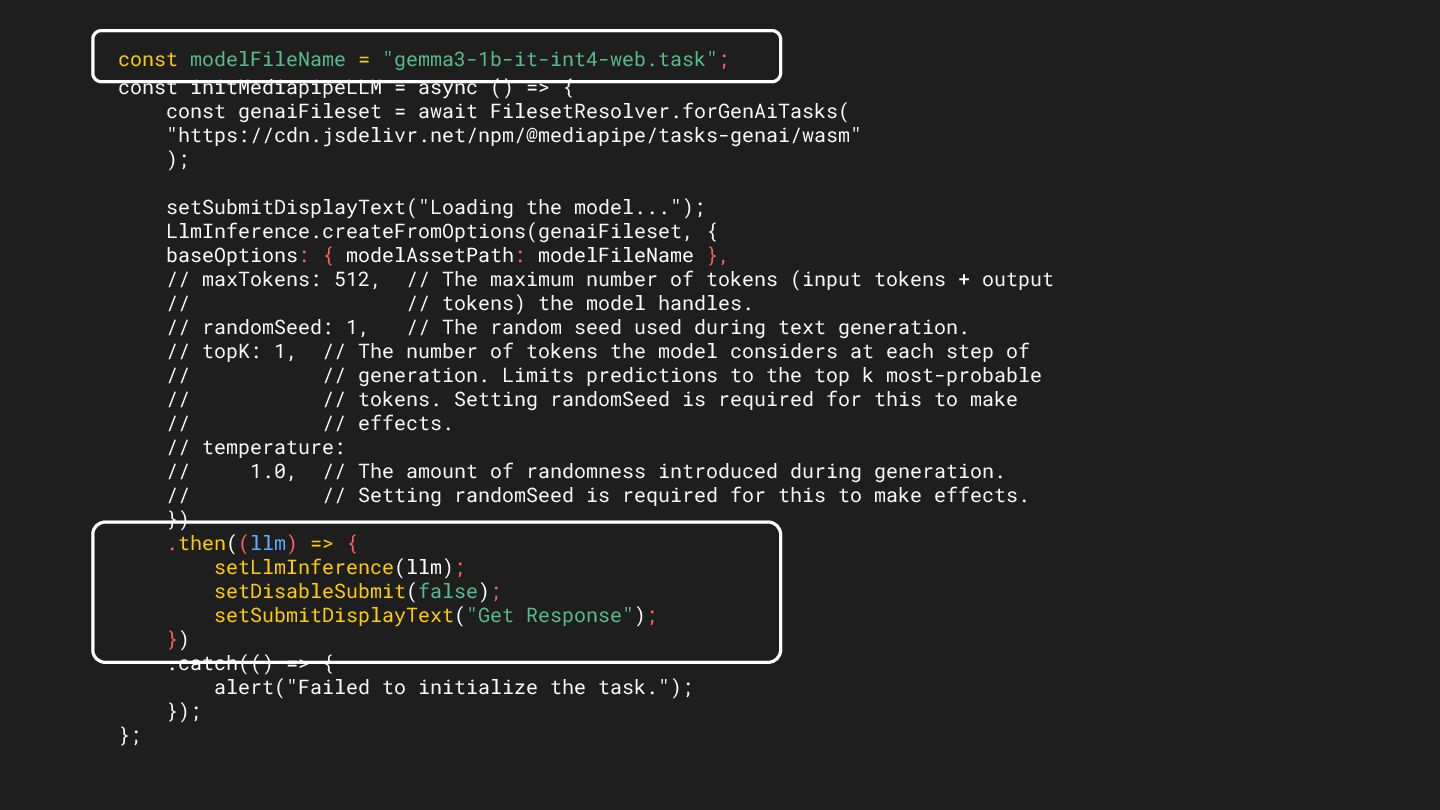
const modelFileName = "gemma3-1b-it-int4-web.task"; const initMediapipeLLM = async () =>
{ const genaiFileset = await FilesetResolver.forGenAiTasks( "https://cdn.jsdelivr.net/npm/@mediapipe/tasks-genai/wasm" ); setSubmitDisplayText("Loading the model..."); LlmInference.createFromOptions(genaiFileset, { baseOptions: { modelAssetPath: modelFileName }, // maxTokens: 512, // The maximum number of tokens (input tokens + output // // tokens) the model handles. // randomSeed: 1, // The random seed used during text generation. // topK: 1, // The number of tokens the model considers at each step of // // generation. Limits predictions to the top k most-probable // // tokens. Setting randomSeed is required for this to make // // effects. // temperature: // 1.0, // The amount of randomness introduced during generation. // // Setting randomSeed is required for this to make effects. }) .then((llm) => { setLlmInference(llm); setDisableSubmit(false); setSubmitDisplayText("Get Response"); }) .catch(() => { alert("Failed to initialize the task."); }); }; -
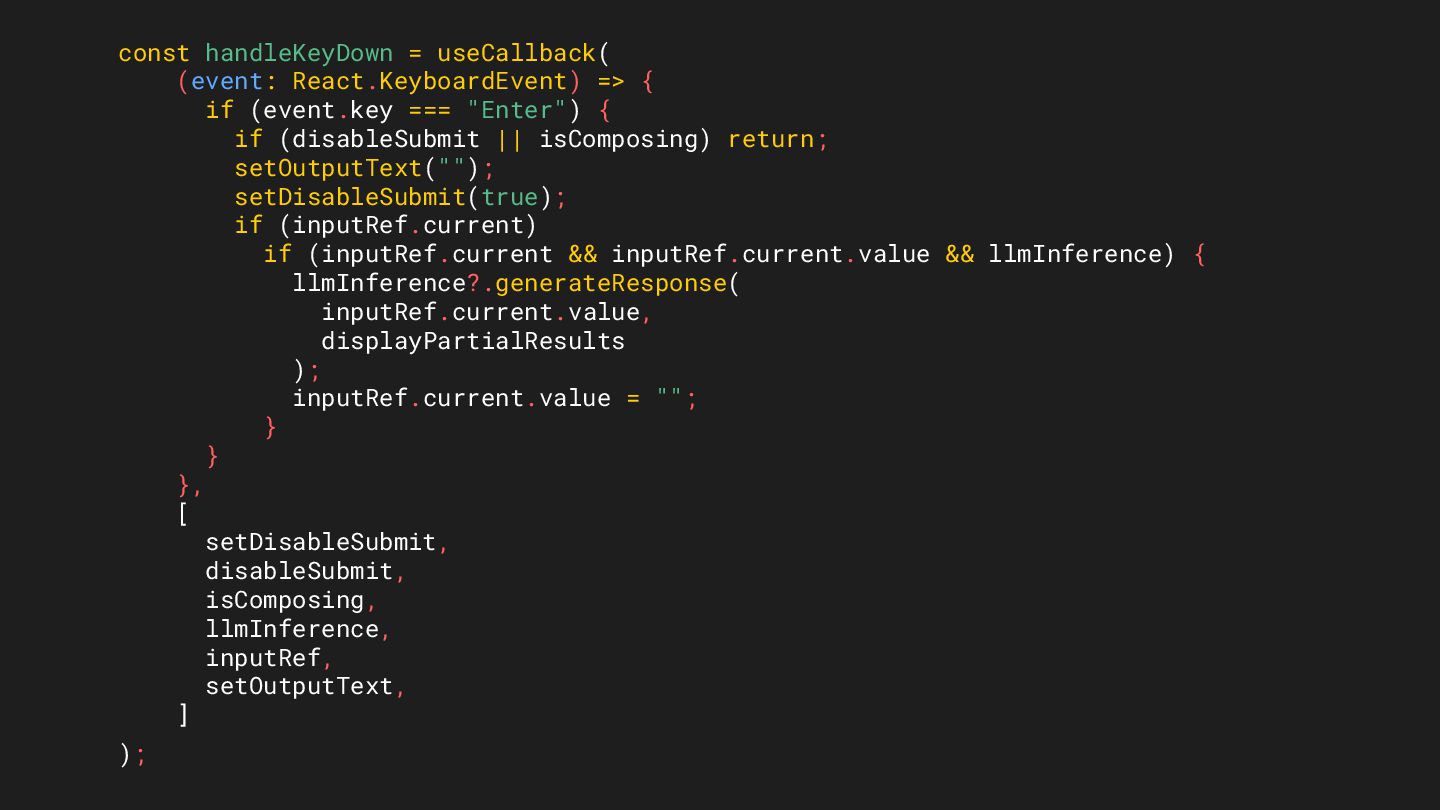
const handleKeyDown = useCallback( (event: React.KeyboardEvent) => { if (event.key
=== "Enter") { if (disableSubmit || isComposing) return; setOutputText(""); setDisableSubmit(true); if (inputRef.current) if (inputRef.current && inputRef.current.value && llmInference) { llmInference?.generateResponse( inputRef.current.value, displayPartialResults ); inputRef.current.value = ""; } } }, [ setDisableSubmit, disableSubmit, isComposing, llmInference, inputRef, setOutputText, ] ); -
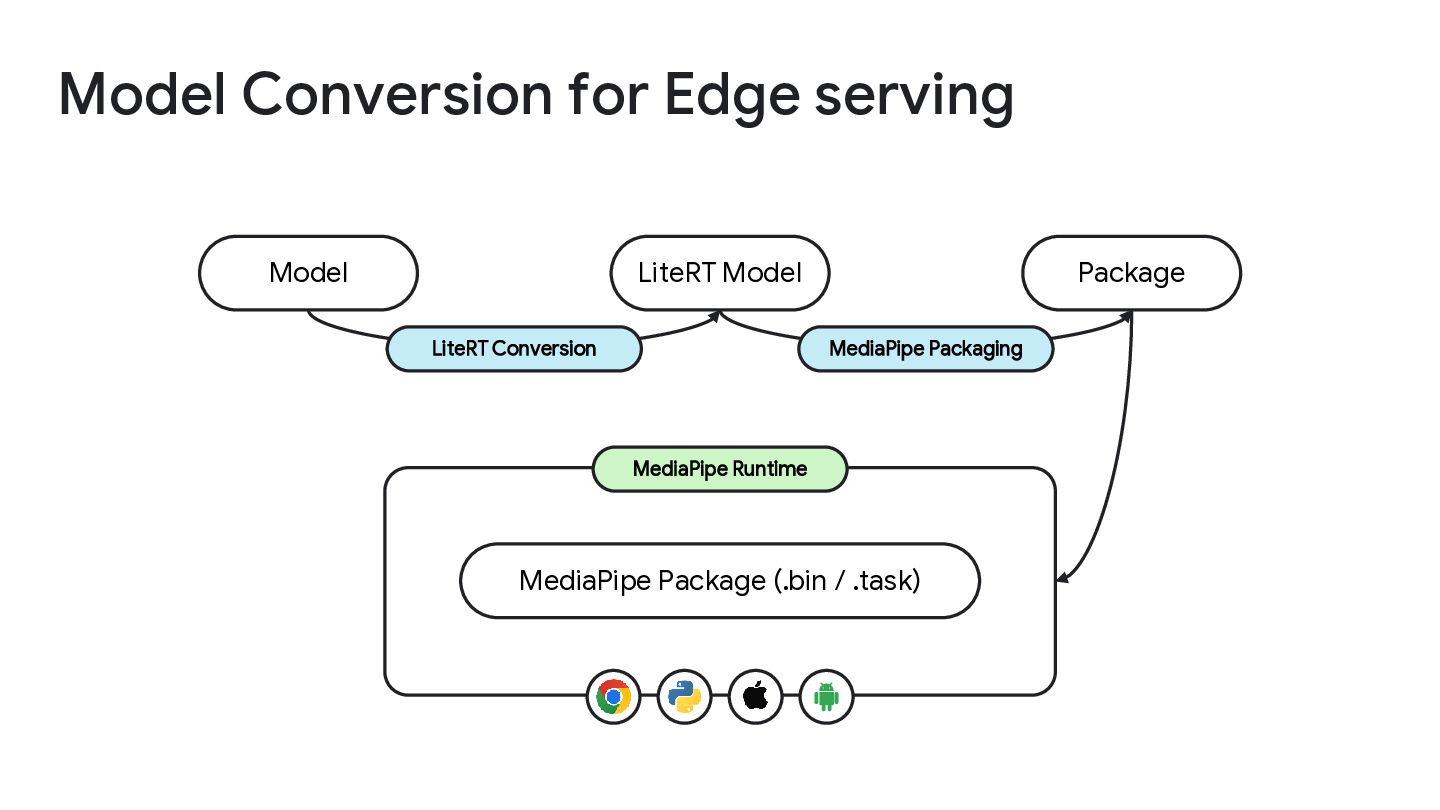
Model Conversion for Edge serving Model LiteRT Model Package LiteRT
Conversion MediaPipe Packaging MediaPipe Runtime MediaPipe Package (.bin / .task) -
Google I/O Extended 25 Proprietary & Confidential Conclusion 저비용, 고효율,
안전한 Edge AI 경량 모델에서 프론티어급 모델 활 용 Hybrid 모델 활용 고려 필요 비동기 UX 고민 필 요 -
Thank you! Proprietary & Confidential Google Events + Experiences Proprietary
& Confidential [email protected] linked.in/sungmin.han