Share
Embed
Transcript
43 slides
-
Speaker 한성민 (Sungmin Han) AIOps Senior backend-engineer at Riiid Former
Research engineer at Naver Clova Former Software engineer at IGAWorks Former Software engineer at 심심이 https://www.facebook.com/han.sungmin/ https://github.com/KennethanCeyer https://www.linkedin.com/in/sungmin-han-768419133/ [email protected] -
Table of Contents Introduction - Python in Business Multi-core Programming
- Thread in Python - GIL (Global Interpreter Lock) - IO Bound - Async IO Bindings - C-bindings - Lib bindings - Cross-compile bindings Hardware-accelerations - SIMD (Single Input Multiple Data) - GPGPU - Introduce libraries Data processing - Memory access mechanism - Zero-copy - Columnar Data Format - Clustered computing -
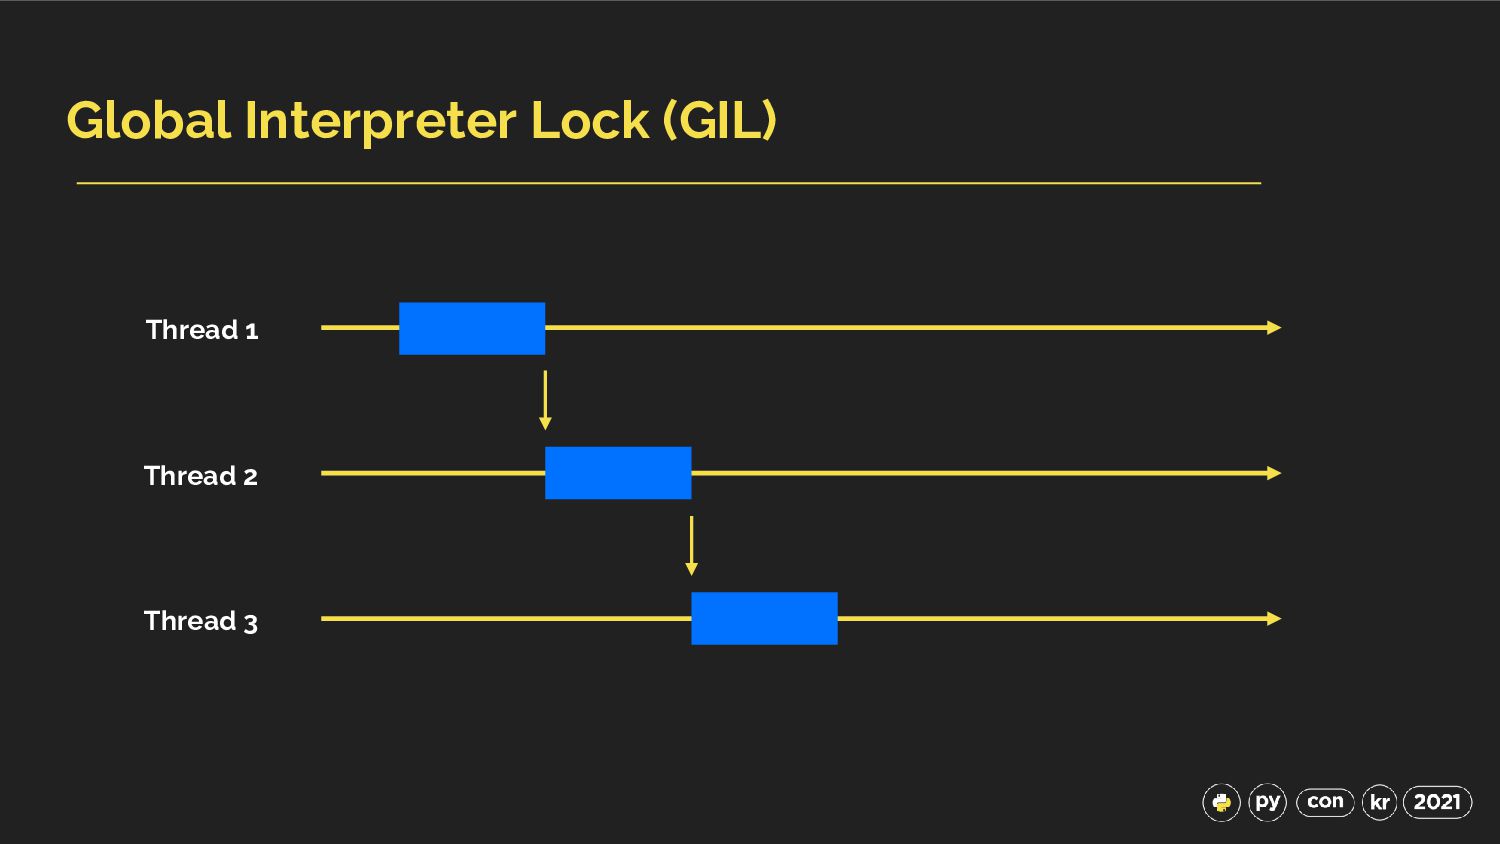
Thread in Python def calc(x: int) -> int: sum_value =
0 for _ in range(10000000): sum_value += x return sum_value if __name__ == "__main__": with ThreadPoolExecutor(max_workers=10) as executor: res = executor.map(calc, [1, 2, 3, 4, 5, 6, 7, 8, 9, 10]) print(list(res)) def calc(x: int) -> int: sum_value = 0 for _ in range(10000000): sum_value += x return sum_value if __name__ == "__main__": res = map(calc, [1, 2, 3]) print(list(res)) Thread: 4,116ms Single core: 1,208ms -
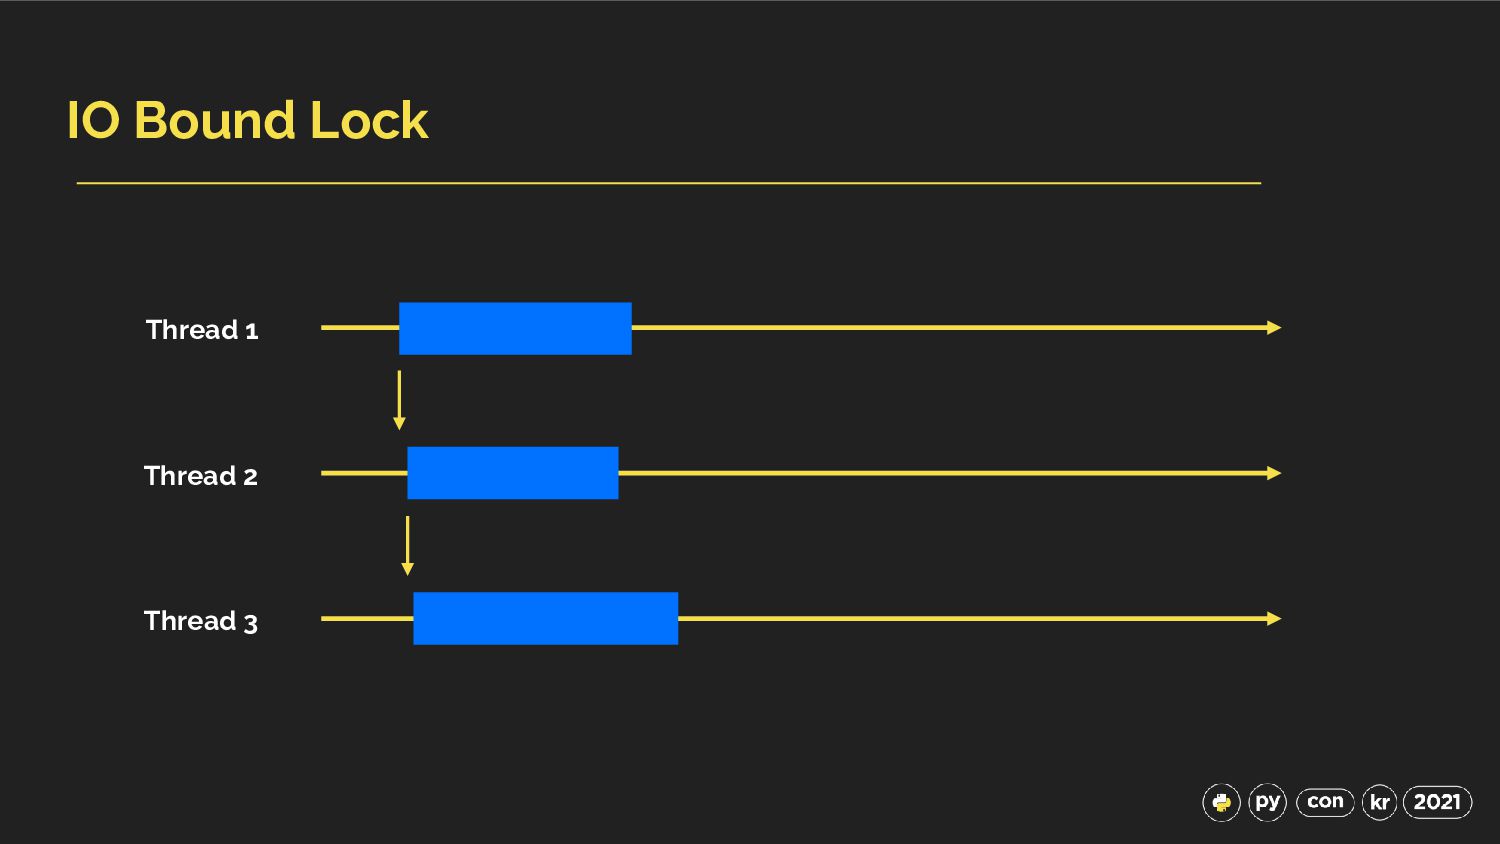
Thread in Python with IO Bound Requests URLS: List[str] =
[ "https://naver.com", "https://daum.net", "https://kakao.com", "https://google.com", "https://stackoverflow.com", ] if __name__ == "__main__": with ThreadPoolExecutor(max_workers=5) as executor: res = executor.map(requests.get, [*(URLS * 10)]) print(list(res)) URLS: List[str] = [ "https://naver.com", "https://daum.net", "https://kakao.com", "https://google.com", "https://stackoverflow.com", ] if __name__ == "__main__": res = map(requests.get, [*(URLS * 10)]) print(list(res)) Thread: 4,316ms Single core: 12,358ms -
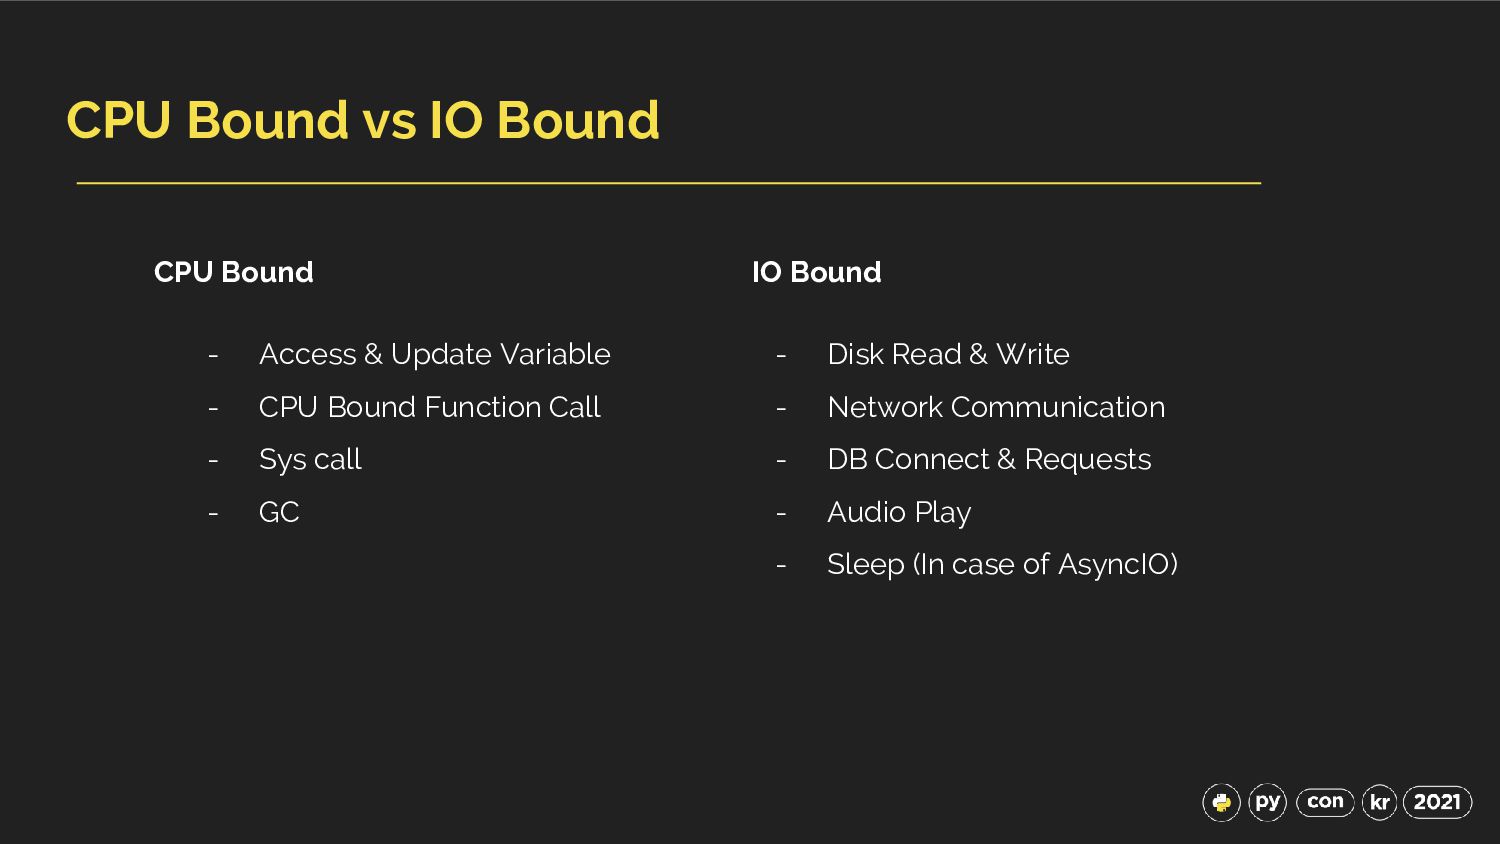
CPU Bound vs IO Bound CPU Bound IO Bound -
Access & Update Variable - CPU Bound Function Call - Sys call - GC - Disk Read & Write - Network Communication - DB Connect & Requests - Audio Play - Sleep (In case of AsyncIO) -
Native Python STD def mean(nums: List[float]) -> float: return sum(nums)
/ len(nums) def var(nums: List[float]) -> float: mean_ = mean(nums) vsum = 0 for n in nums: vsum += (n - mean_) ** 2 return vsum / len(nums) def std(nums: List[float]) -> float: return sqrt(var(nums)) data = list(range(5000)) timeit(lambda:std(data), number=100000) 94,582ms -
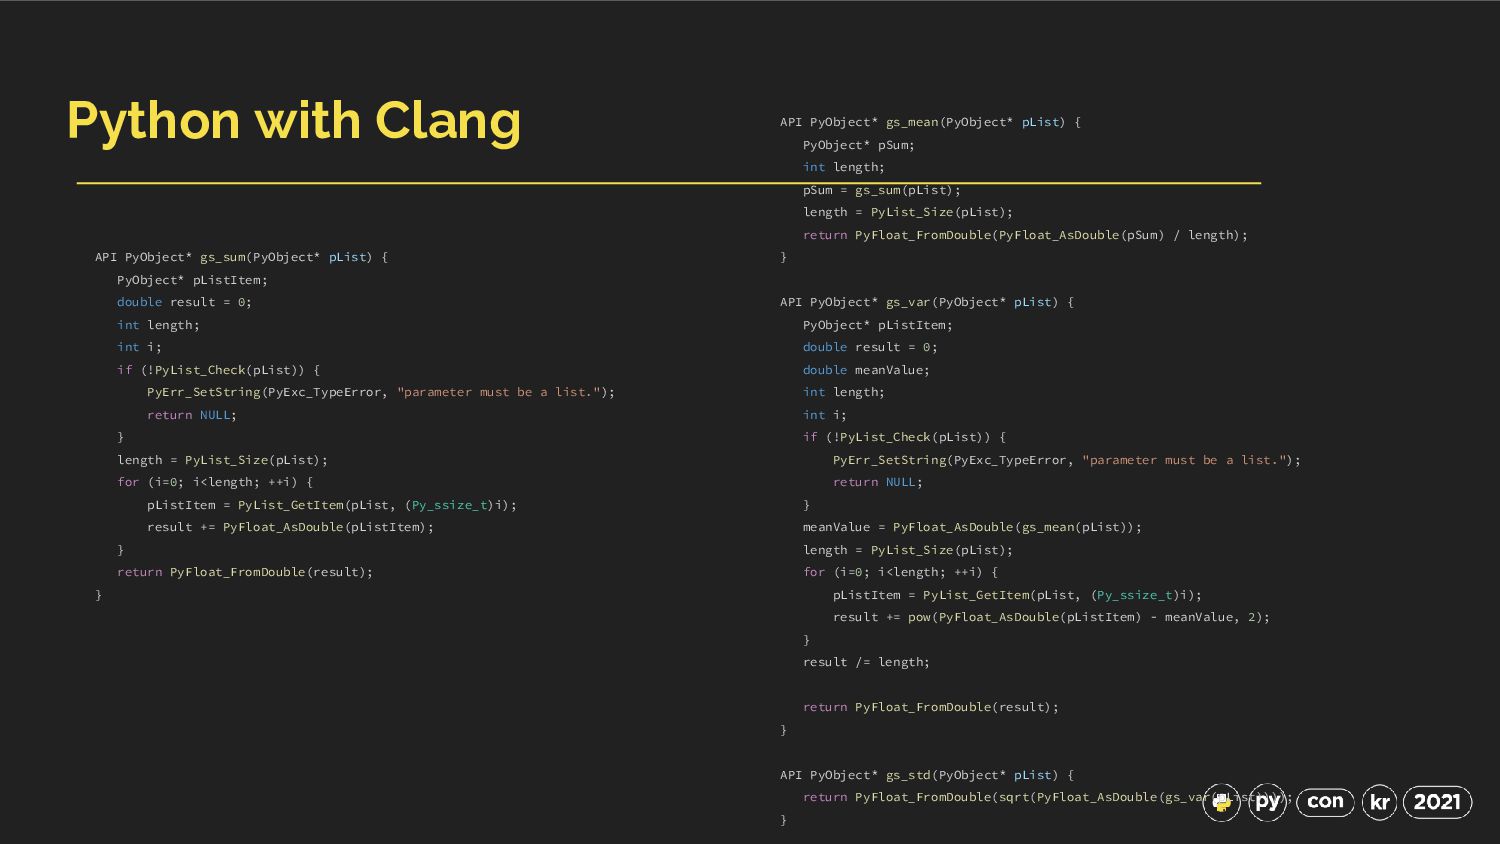
Python with Clang API PyObject* gs_sum(PyObject* pList) { PyObject* pListItem;
double result = 0; int length; int i; if (!PyList_Check(pList)) { PyErr_SetString(PyExc_TypeError, "parameter must be a list."); return NULL; } length = PyList_Size(pList); for (i=0; i<length; ++i) { pListItem = PyList_GetItem(pList, (Py_ssize_t)i); result += PyFloat_AsDouble(pListItem); } return PyFloat_FromDouble(result); } API PyObject* gs_mean(PyObject* pList) { PyObject* pSum; int length; pSum = gs_sum(pList); length = PyList_Size(pList); return PyFloat_FromDouble(PyFloat_AsDouble(pSum) / length); } API PyObject* gs_var(PyObject* pList) { PyObject* pListItem; double result = 0; double meanValue; int length; int i; if (!PyList_Check(pList)) { PyErr_SetString(PyExc_TypeError, "parameter must be a list."); return NULL; } meanValue = PyFloat_AsDouble(gs_mean(pList)); length = PyList_Size(pList); for (i=0; i<length; ++i) { pListItem = PyList_GetItem(pList, (Py_ssize_t)i); result += pow(PyFloat_AsDouble(pListItem) - meanValue, 2); } result /= length; return PyFloat_FromDouble(result); } API PyObject* gs_std(PyObject* pList) { return PyFloat_FromDouble(sqrt(PyFloat_AsDouble(gs_var(pList)))); } -
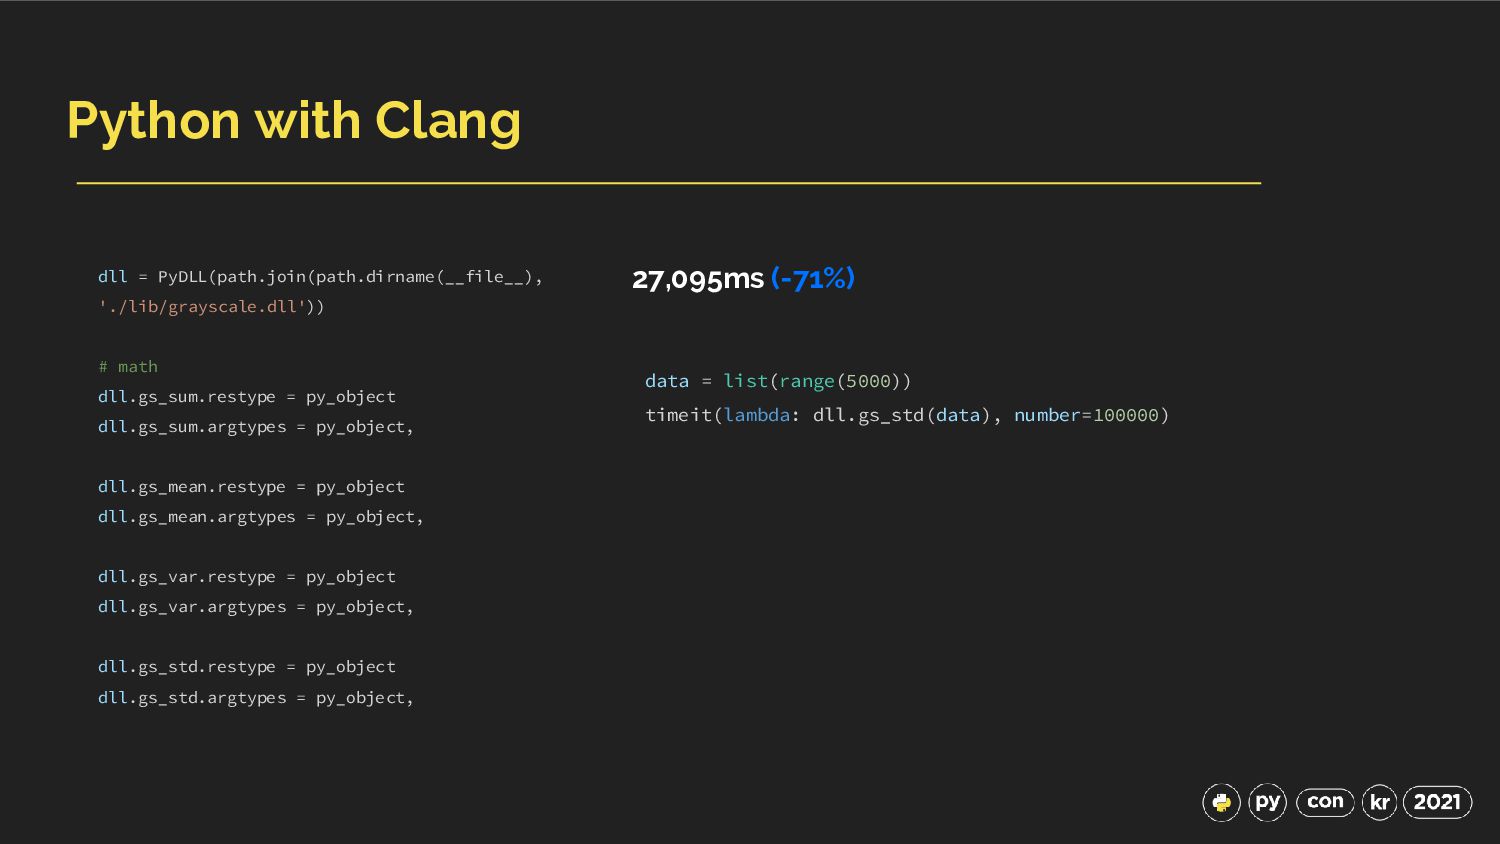
Python with Clang dll = PyDLL(path.join(path.dirname(__file__), './lib/grayscale.dll')) # math dll.gs_sum.restype
= py_object dll.gs_sum.argtypes = py_object, dll.gs_mean.restype = py_object dll.gs_mean.argtypes = py_object, dll.gs_var.restype = py_object dll.gs_var.argtypes = py_object, dll.gs_std.restype = py_object dll.gs_std.argtypes = py_object, data = list(range(5000)) timeit(lambda: dll.gs_std(data), number=100000) 27,095ms (-71%) -
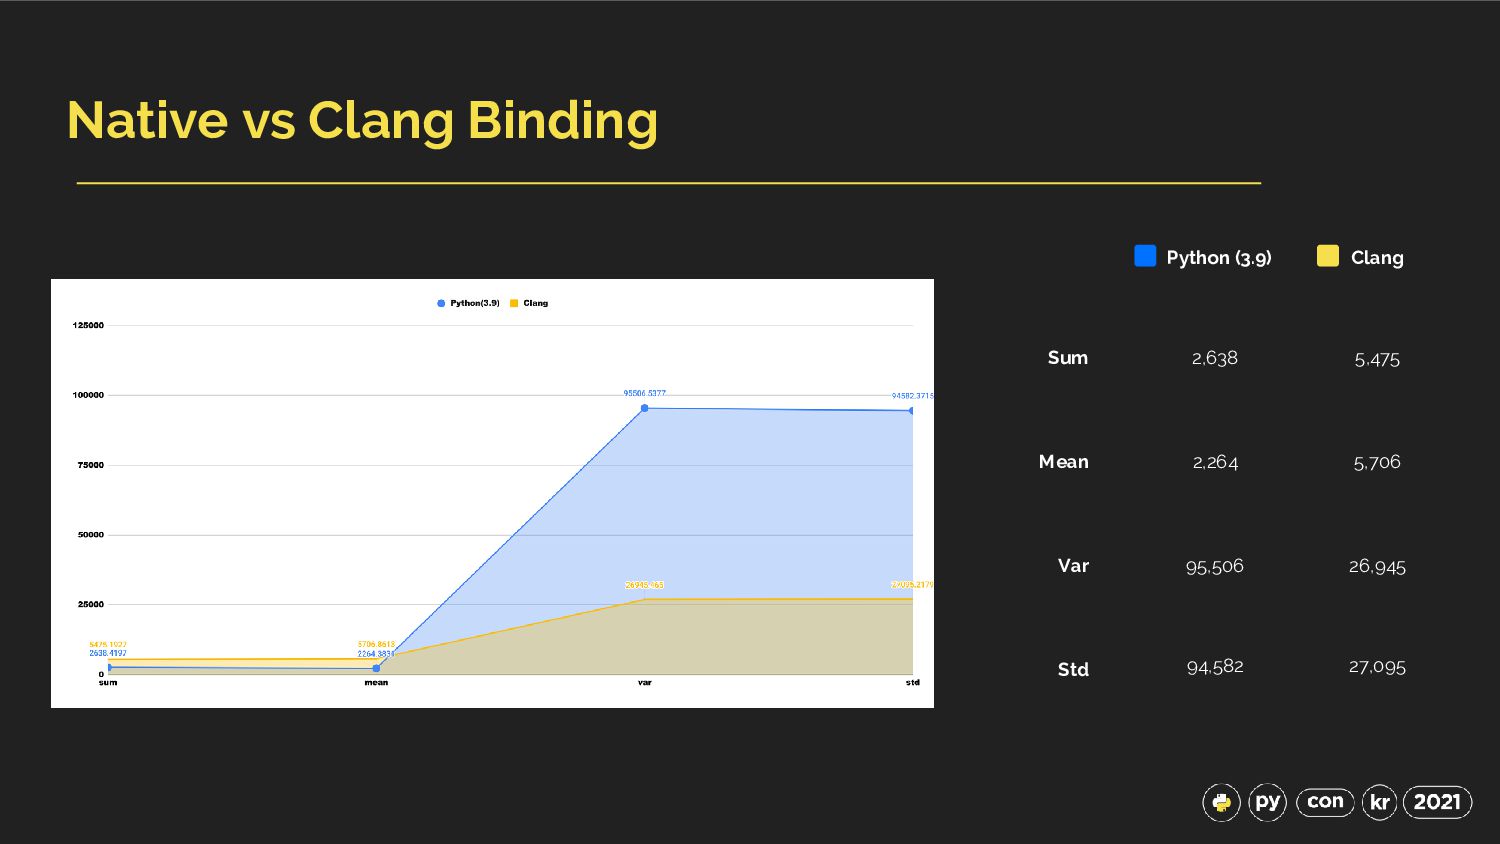
Native vs Clang Binding Python (3.9) Clang Sum Mean Var
Std 2,638 5,475 2,264 5,706 95,506 26,945 94,582 27,095 -
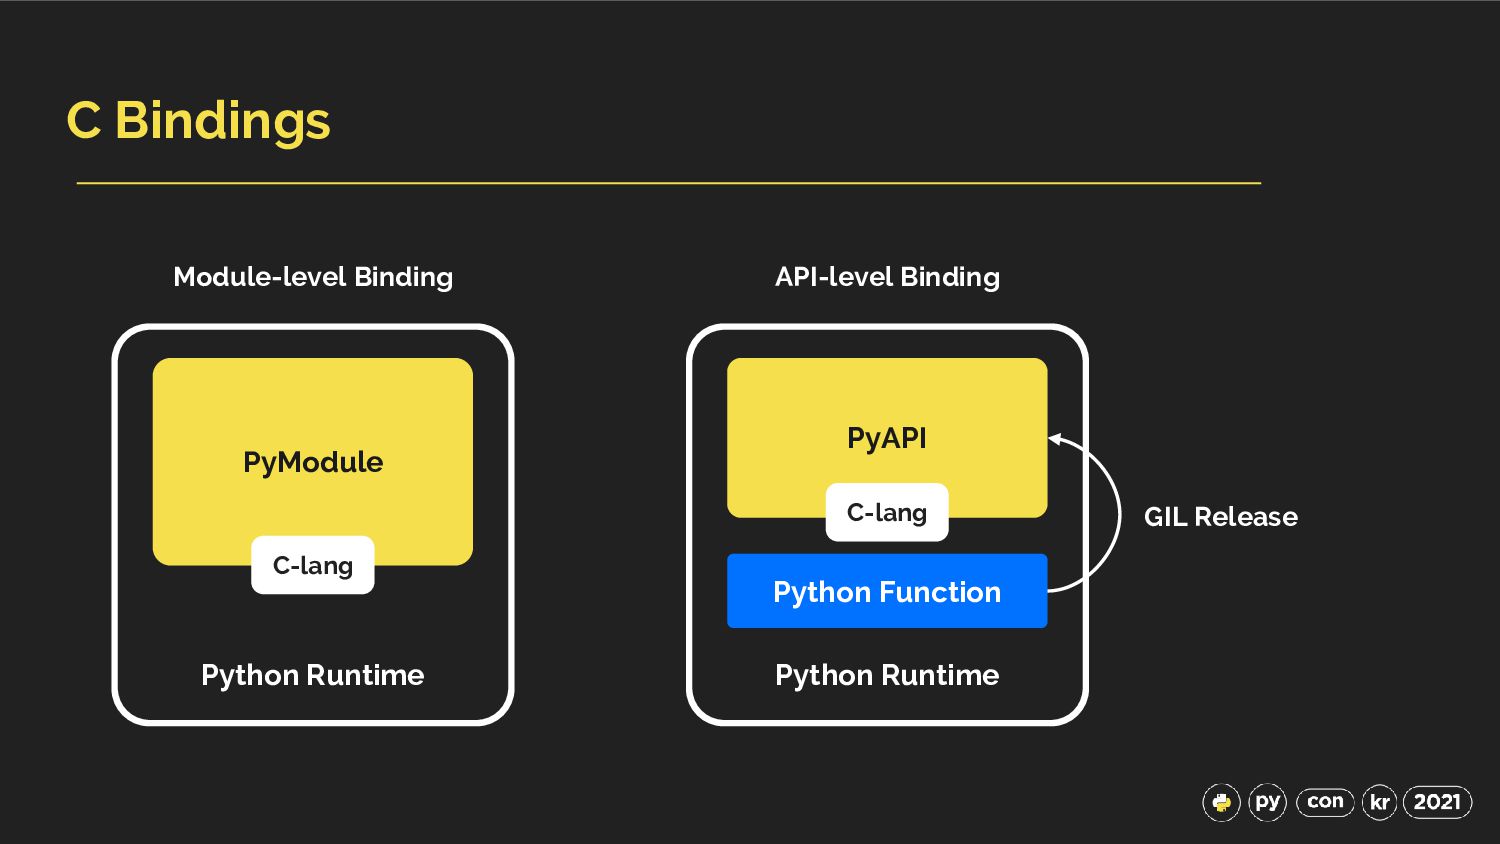
C Bindings Python Runtime PyModule C-lang Python Runtime PyAPI C-lang
Python Function Module-level Binding API-level Binding GIL Release -
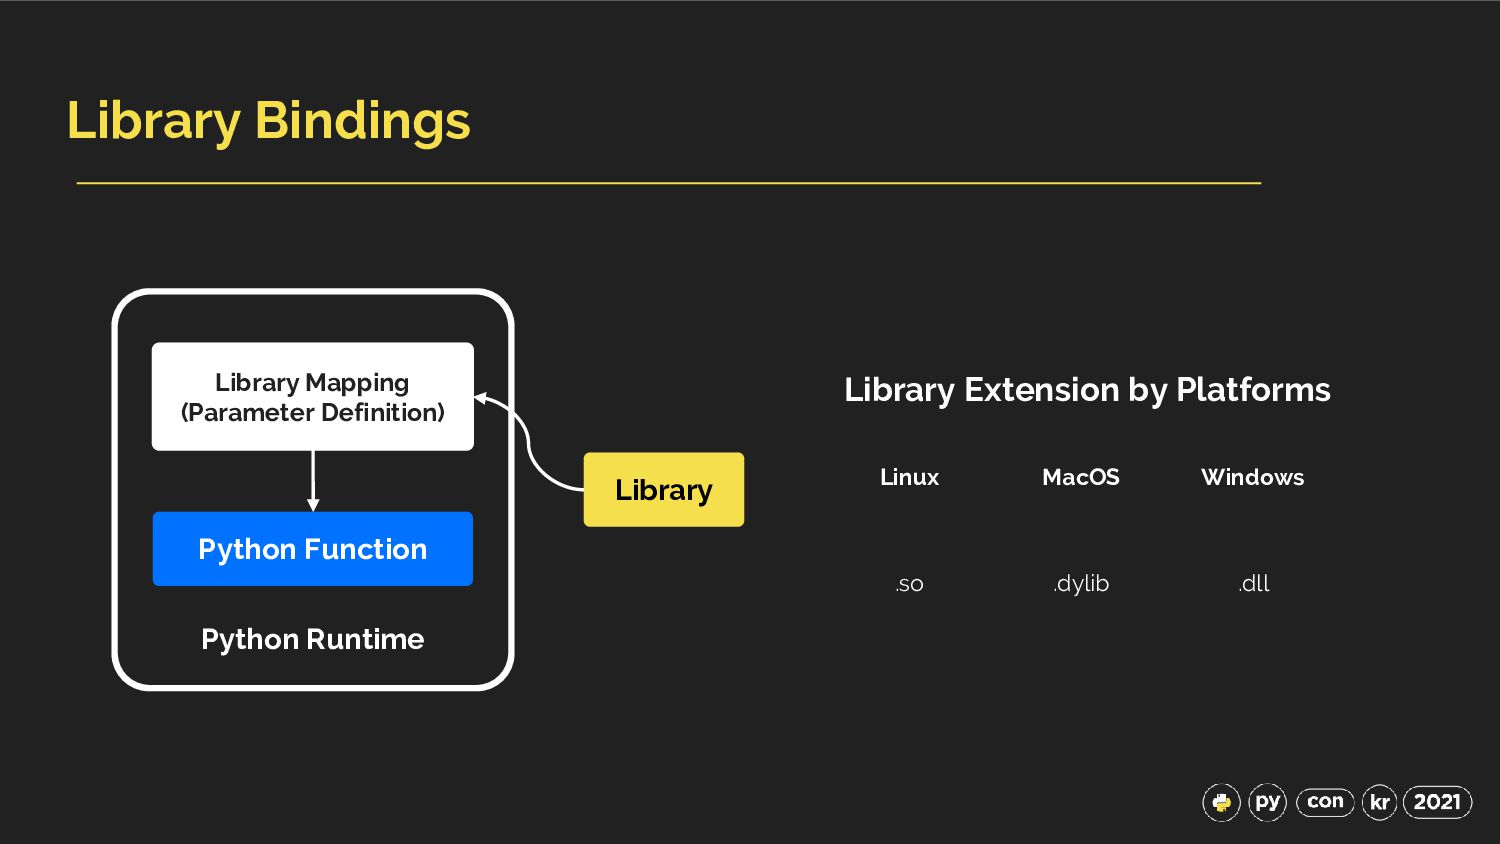
Library Bindings Linux .so MacOS .dylib Windows .dll Library Python
Runtime Library Mapping (Parameter Definition) Python Function Library Extension by Platforms -
Binding with Various languages Library Python Runtime * Due to
the structural nature of the library, only the native compile form is compatible, and the language constituting the VM runtime is not compatible. -
Rust: PyO3 https://github.com/PyO3/pyo3 [package] name = "string-sum" version = "0.1.0"
edition = "2018" [lib] name = "string_sum" # "cdylib" is necessary to produce a shared library for Python to import from. # # Downstream Rust code (including code in `bin/`, `examples/`, and `tests/`) will not be able # to `use string_sum;` unless the "rlib" or "lib" crate type is also included, e.g.: # crate-type = ["cdylib", "rlib"] crate-type = ["cdylib"] [dependencies.pyo3] version = "0.14.1" features = ["extension-module"] Cargo.toml -
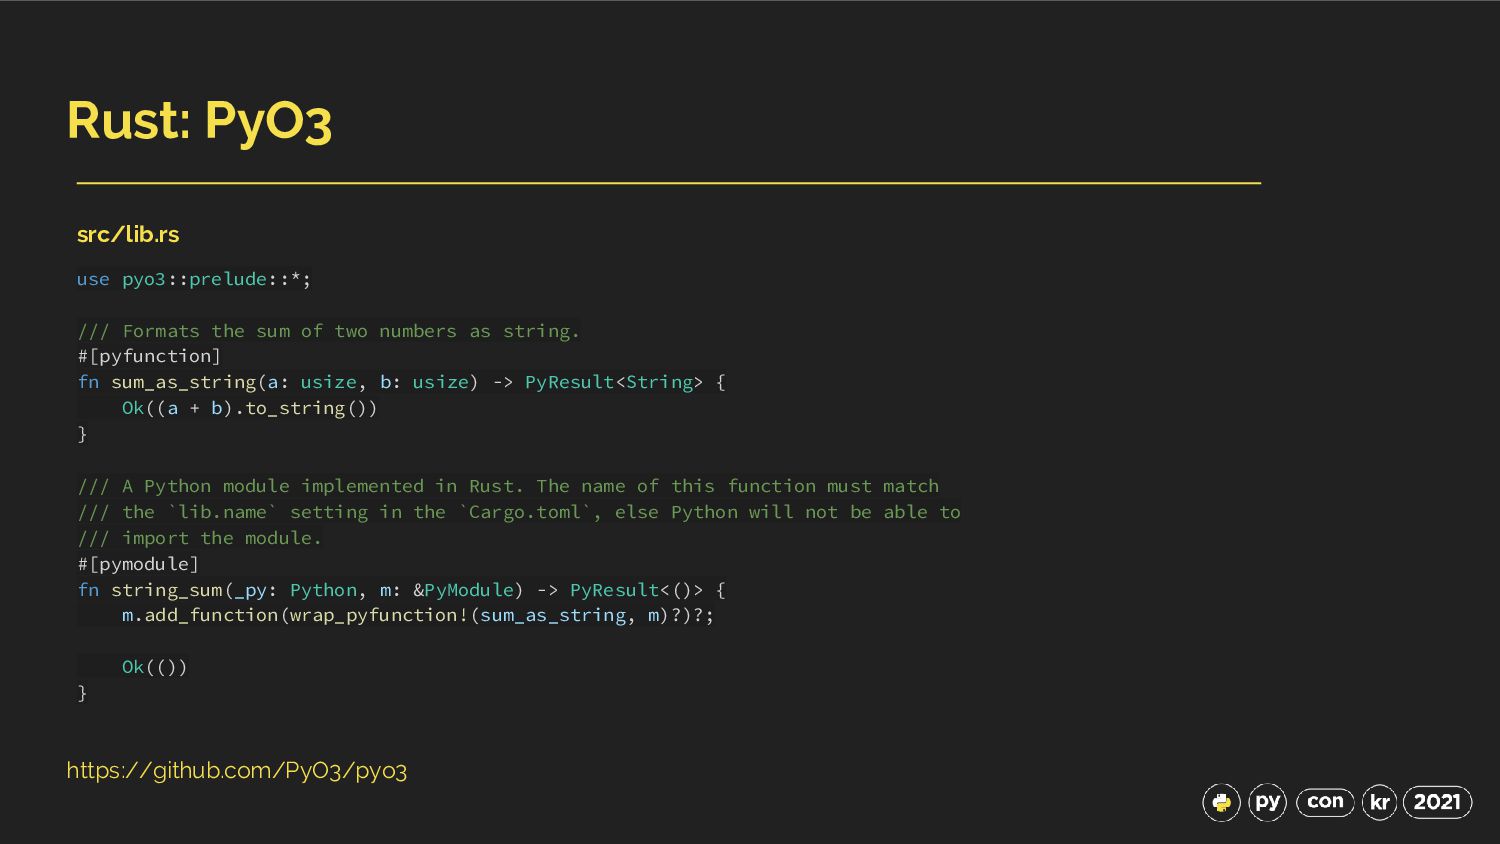
Rust: PyO3 https://github.com/PyO3/pyo3 use pyo3::prelude::*; /// Formats the sum of
two numbers as string. #[pyfunction] fn sum_as_string(a: usize, b: usize) -> PyResult<String> { Ok((a + b).to_string()) } /// A Python module implemented in Rust. The name of this function must match /// the `lib.name` setting in the `Cargo.toml`, else Python will not be able to /// import the module. #[pymodule] fn string_sum(_py: Python, m: &PyModule) -> PyResult<()> { m.add_function(wrap_pyfunction!(sum_as_string, m)?)?; Ok(()) } src/lib.rs -
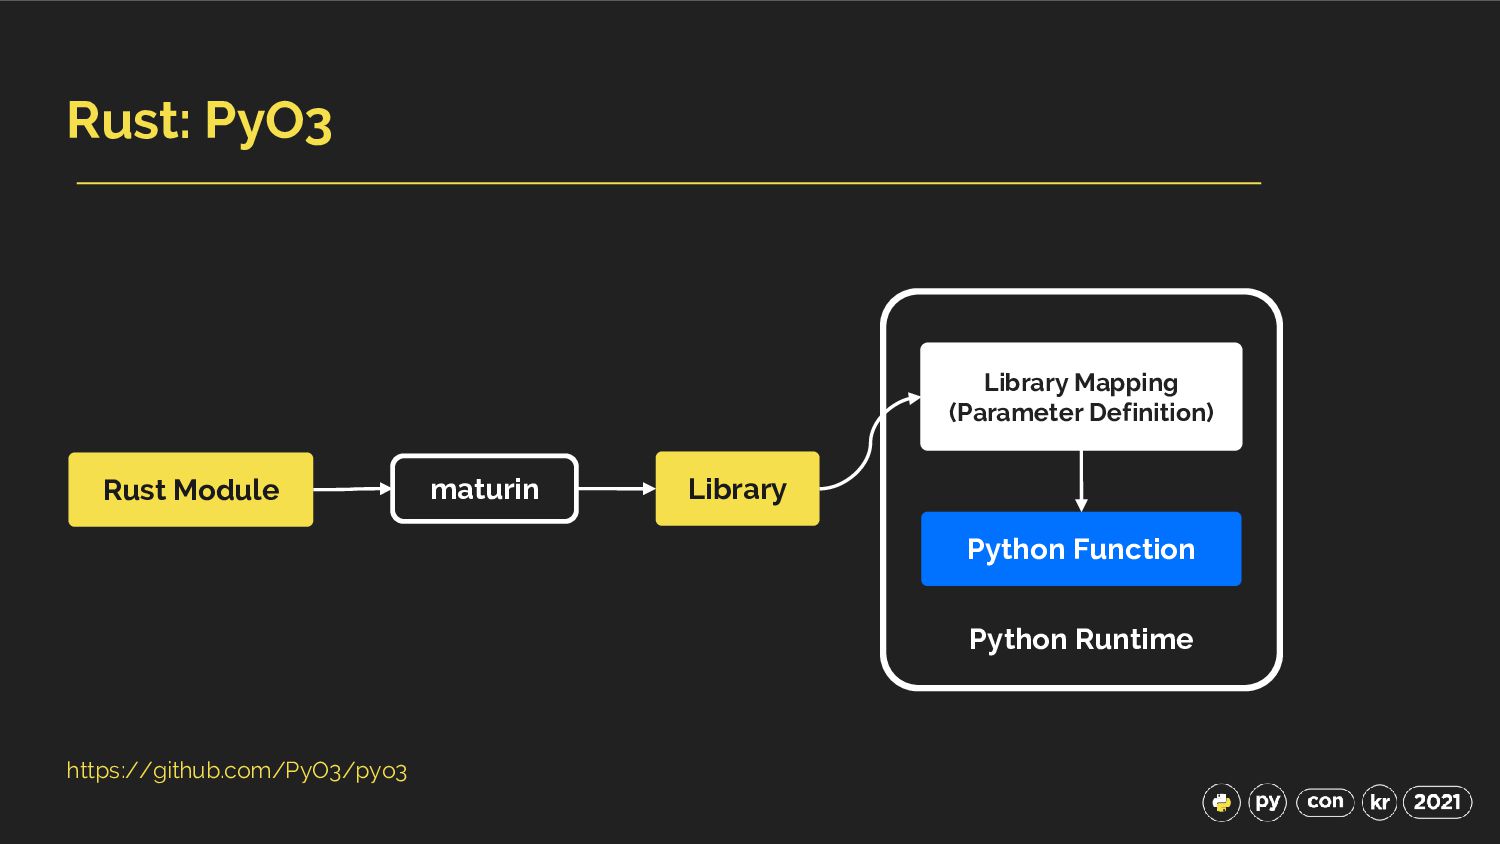
Rust: PyO3 https://github.com/PyO3/pyo3 Python Runtime Library Mapping (Parameter Definition) Python
Function Rust Module maturin Library -
Other projects Golang binding - gopy: https://github.com/go-python/gopy Kotlin binding -
kotlin-native python binding: https://github.com/JetBrains/kotlin/blob/master/kotlin- native/samples/python_extension -
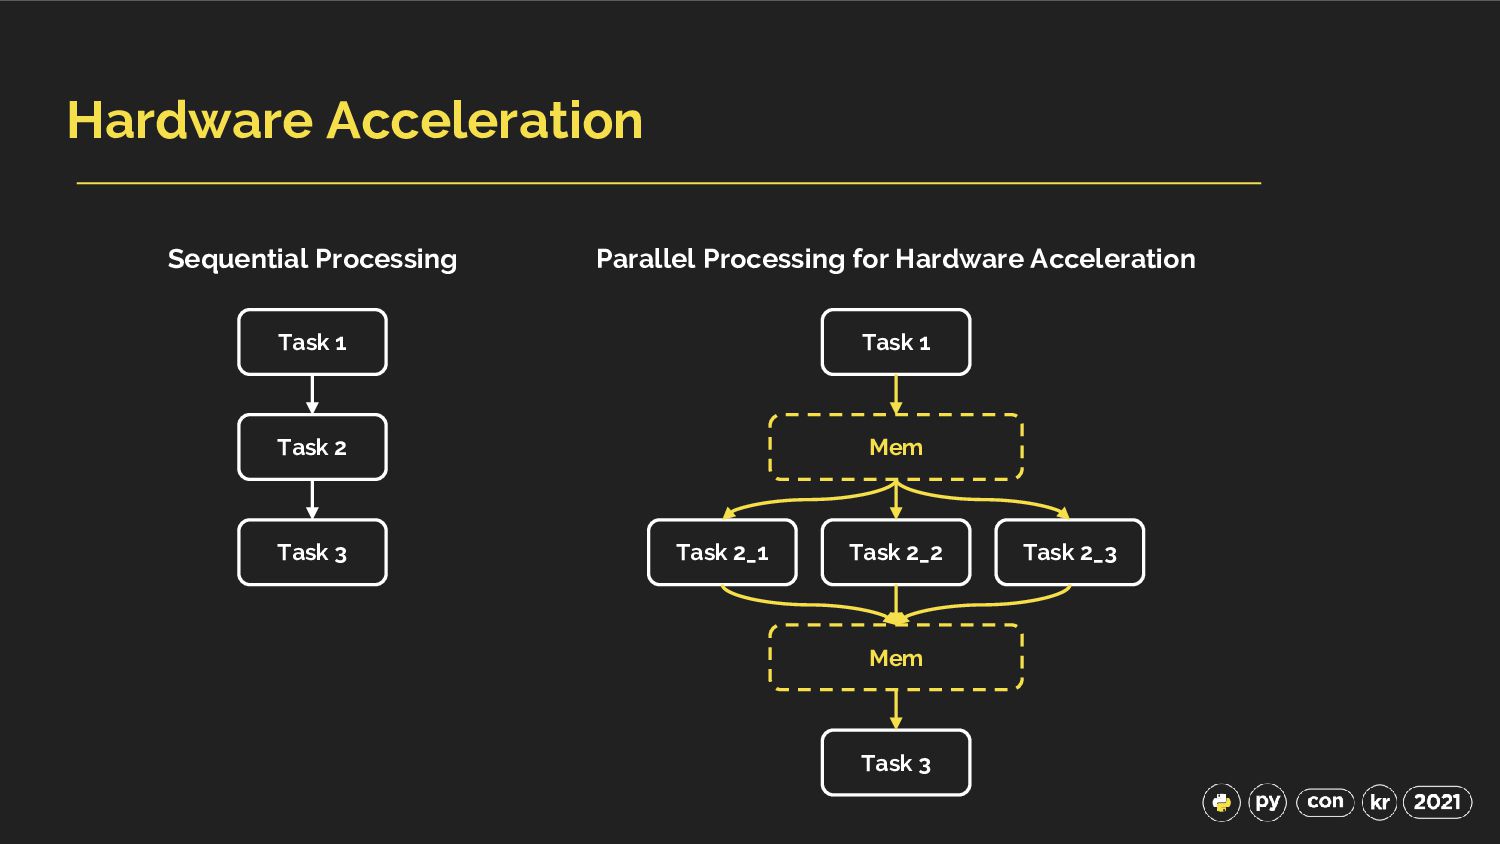
Hardware Acceleration Task 1 Task 2 Task 3 Task 1
Task 2_1 Task 3 Task 2_2 Task 2_3 Mem Mem Sequential Processing Parallel Processing for Hardware Acceleration -
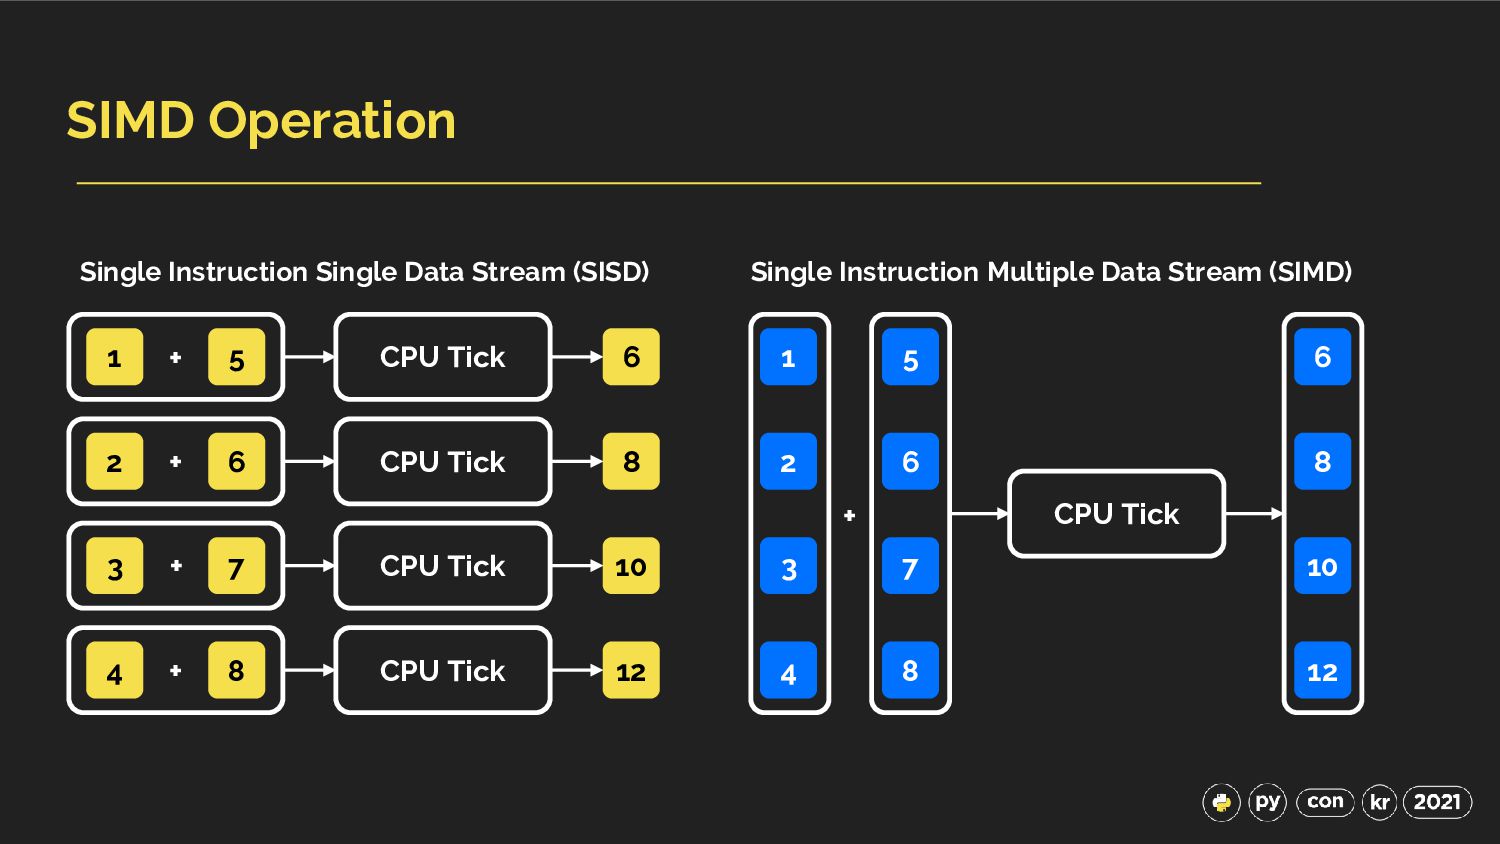
SIMD Operation 1 5 + 2 6 + 3 7
+ 4 8 + CPU Tick CPU Tick CPU Tick CPU Tick 6 8 10 12 Single Instruction Single Data Stream (SISD) 1 5 3 7 4 8 2 6 CPU Tick Single Instruction Multiple Data Stream (SIMD) + 6 8 10 12 -
SSE3 in Cython cdef void sample(): cdef double[4] operand1 cdef
double[4] operand2 cdef __m128d mdata, mtmp cdef double[4] out operand1[:] = [1.0, 2.0, 3.0, 4.0] operand2[:] = [5.0, 6.0, 7.0, 8.0] with nogil: moperand1 = _mm_loadu_pd(operand1) moperand2 = _mm_loadu_pd(operand2) # tmp = A + B # [1.0, 2.0, 3.0, 4.0] + [5.0, 6.0, 7.0, 8.0] mtmp = _mm_add_pd(moperand1, moperand2) _mm_store_pd(out, mtmp) -
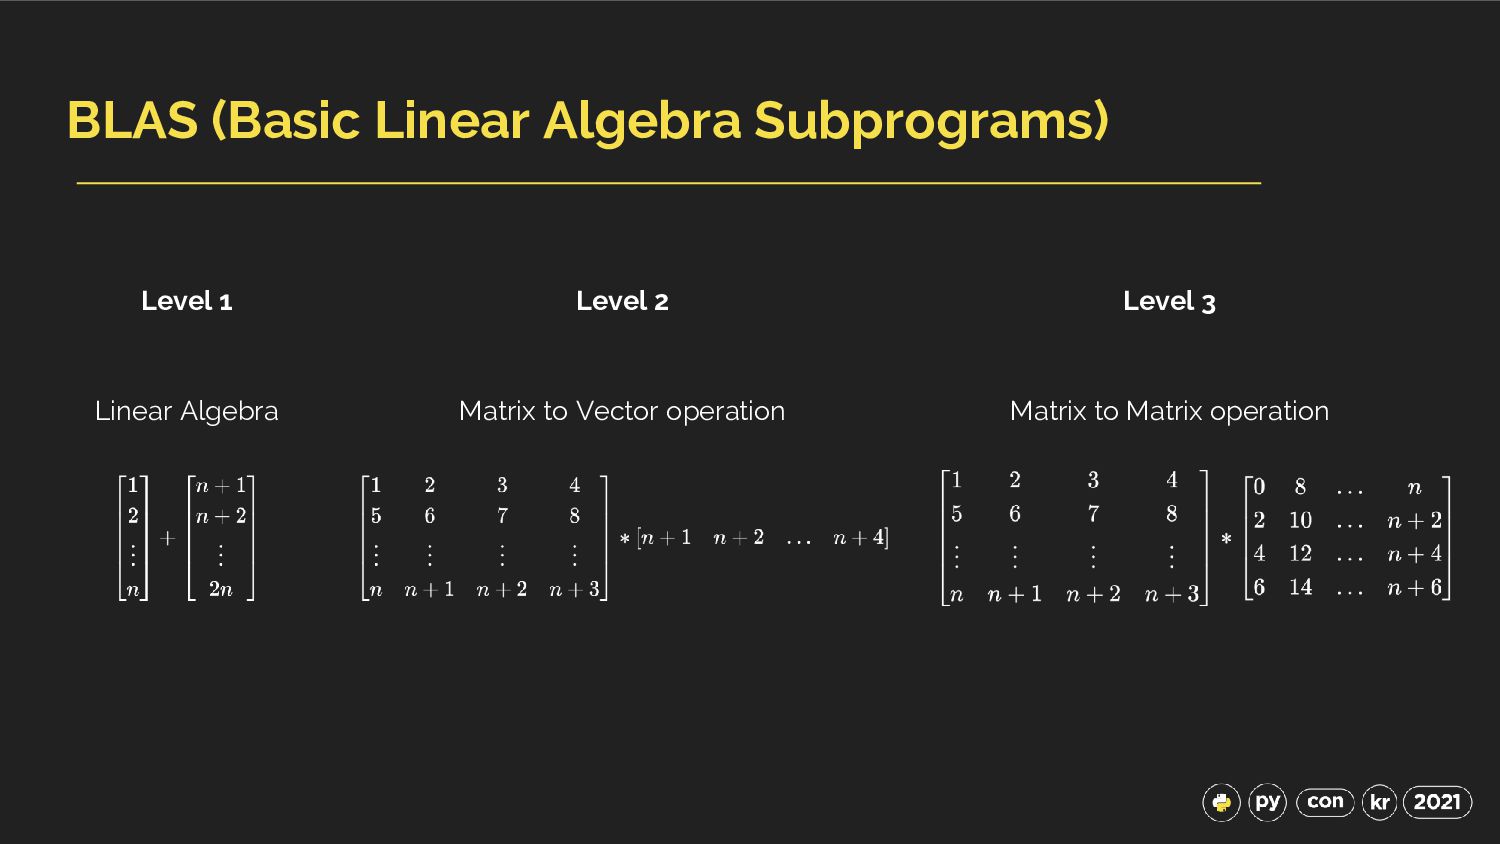
BLAS (Basic Linear Algebra Subprograms) Level 1 Level 2 Level
3 Linear Algebra Matrix to Vector operation Matrix to Matrix operation -
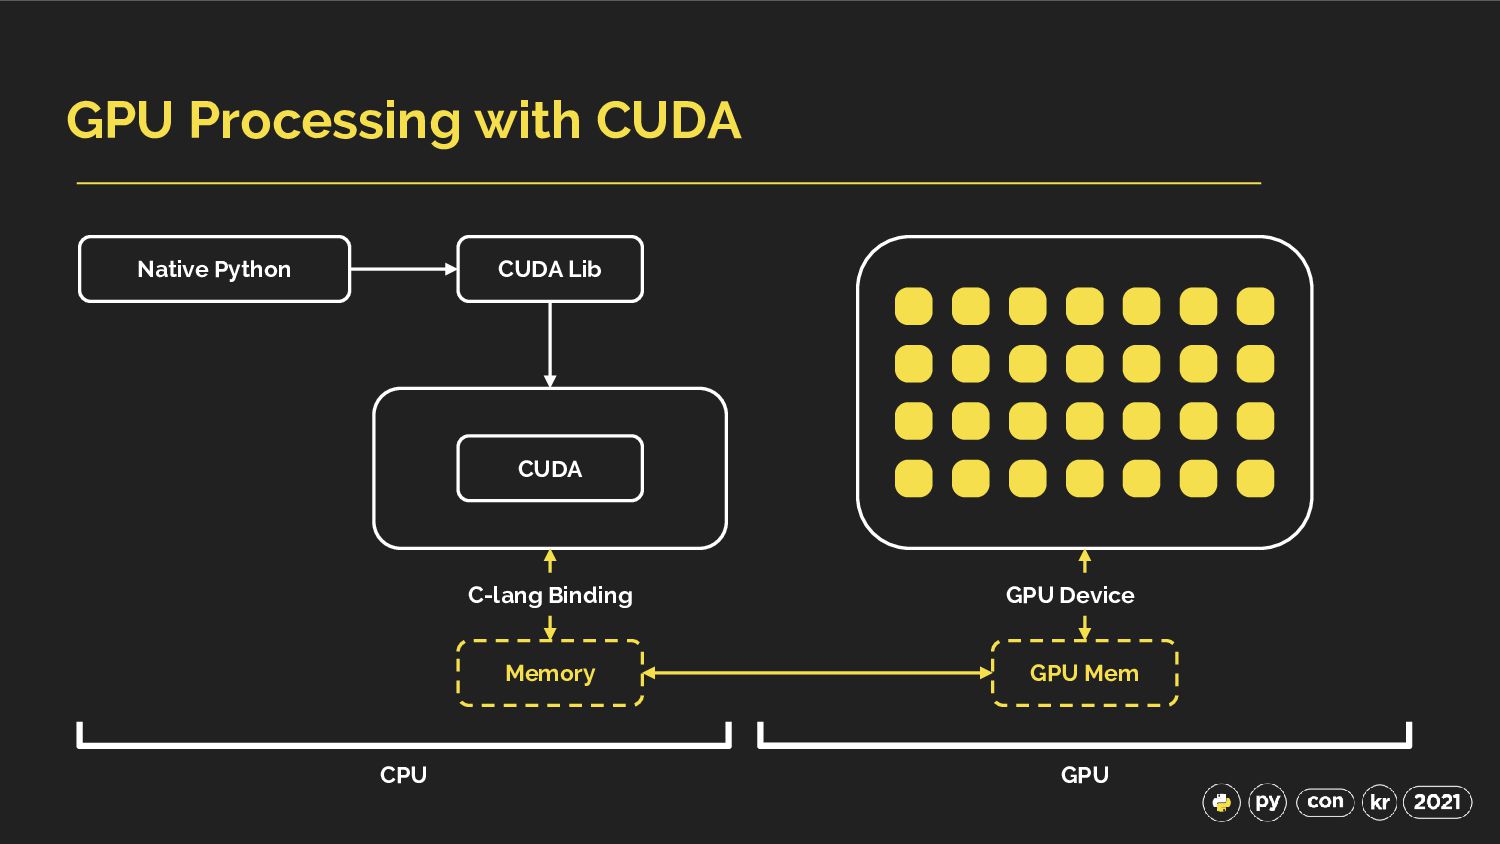
GPU Processing with CUDA Native Python CUDA Lib CUDA Memory
GPU Mem CPU GPU C-lang Binding GPU Device -
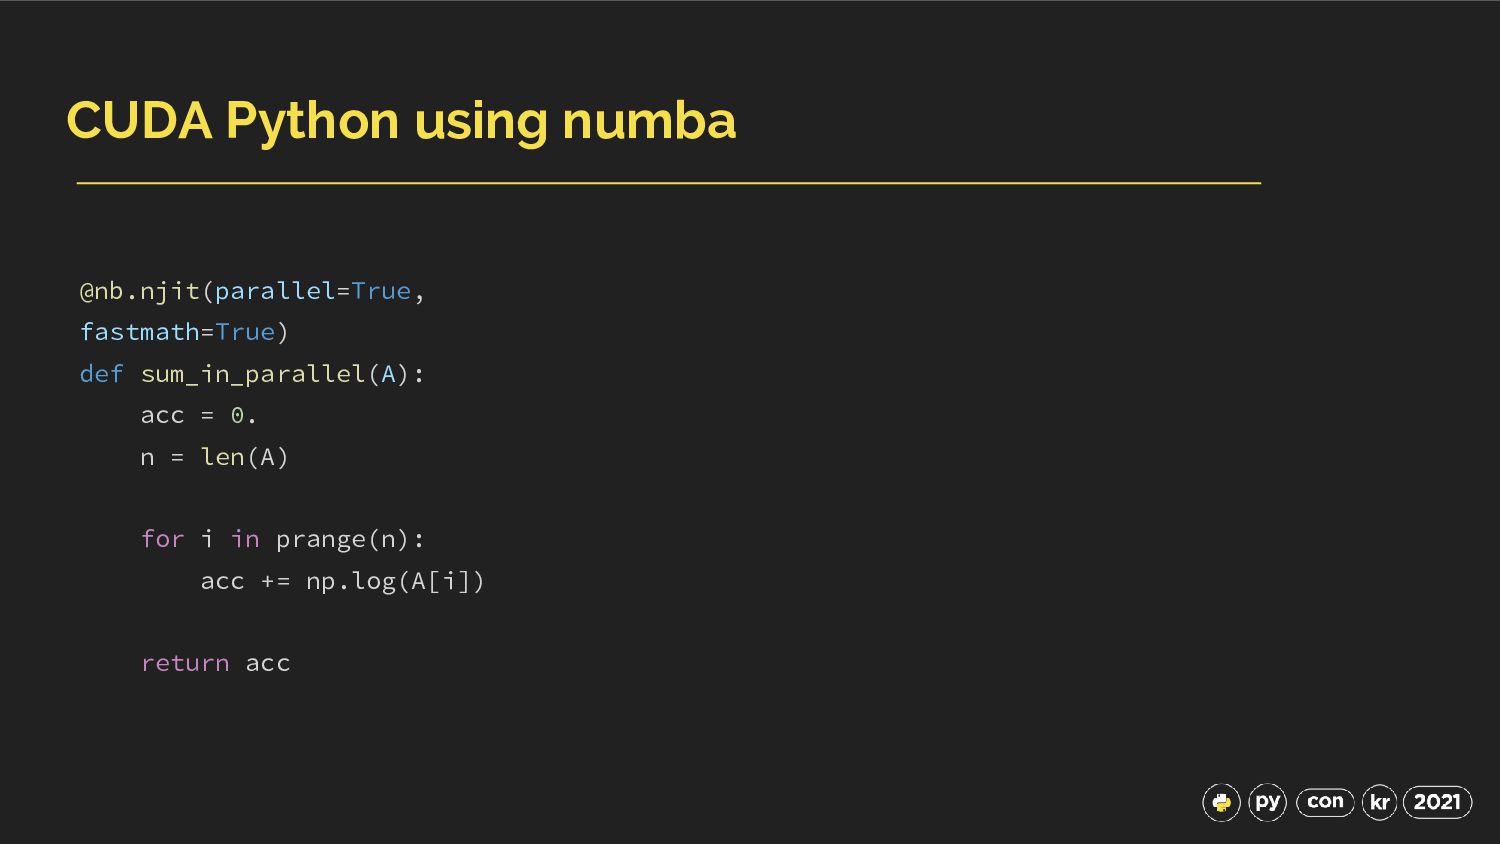
CUDA Python using numba @nb.njit(parallel=True, fastmath=True) def sum_in_parallel(A): acc =
0. n = len(A) for i in prange(n): acc += np.log(A[i]) return acc -
Numba package This slide explains the content below. - Introduce
Numba project - Inside of Numpy Impls - Main difference between Numba and Numpy https://developer.nvidia.com/how-to-cuda-python -
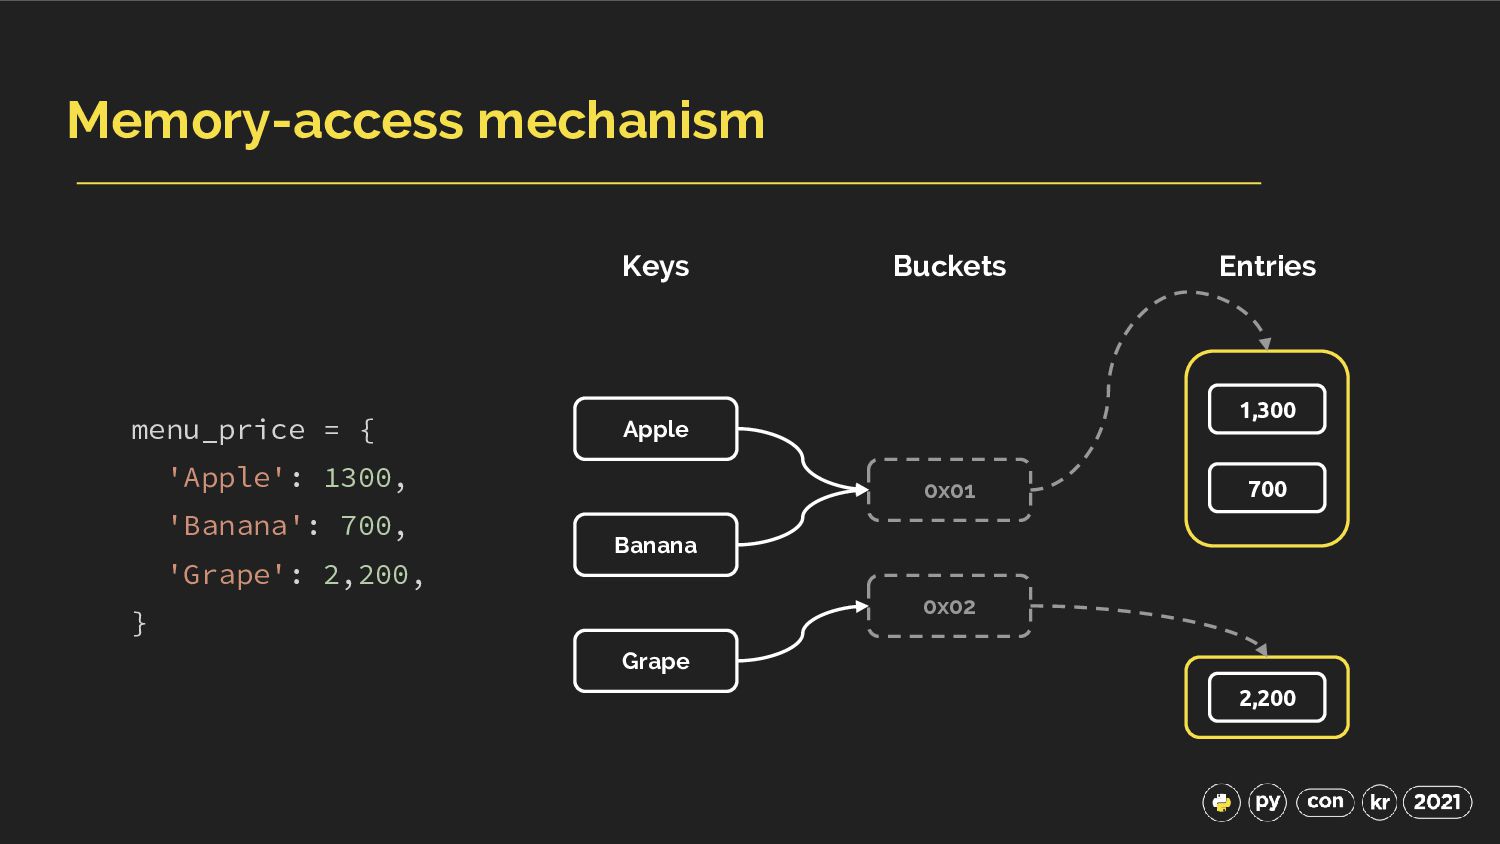
Memory-access mechanism Apple Banana Grape 0x02 1,300 0x01 700 2,200
menu_price = { 'Apple': 1300, 'Banana': 700, 'Grape': 2,200, } Keys Buckets Entries -
Hash mechanisms >>> hash(10) 10 >>> hash('a') 2879375576708175707 >>> hash((1,
2, 3)) 2528502973977326415 >>> from dataclasses import dataclass >>> @dataclass(frozen=True) ... class HelloWorld: ... hello: str ... >>> hello_world = HelloWorld('world') >>> hash(hello_world) 9136121803269620124 Hashable PyObject __hash__() hash() -
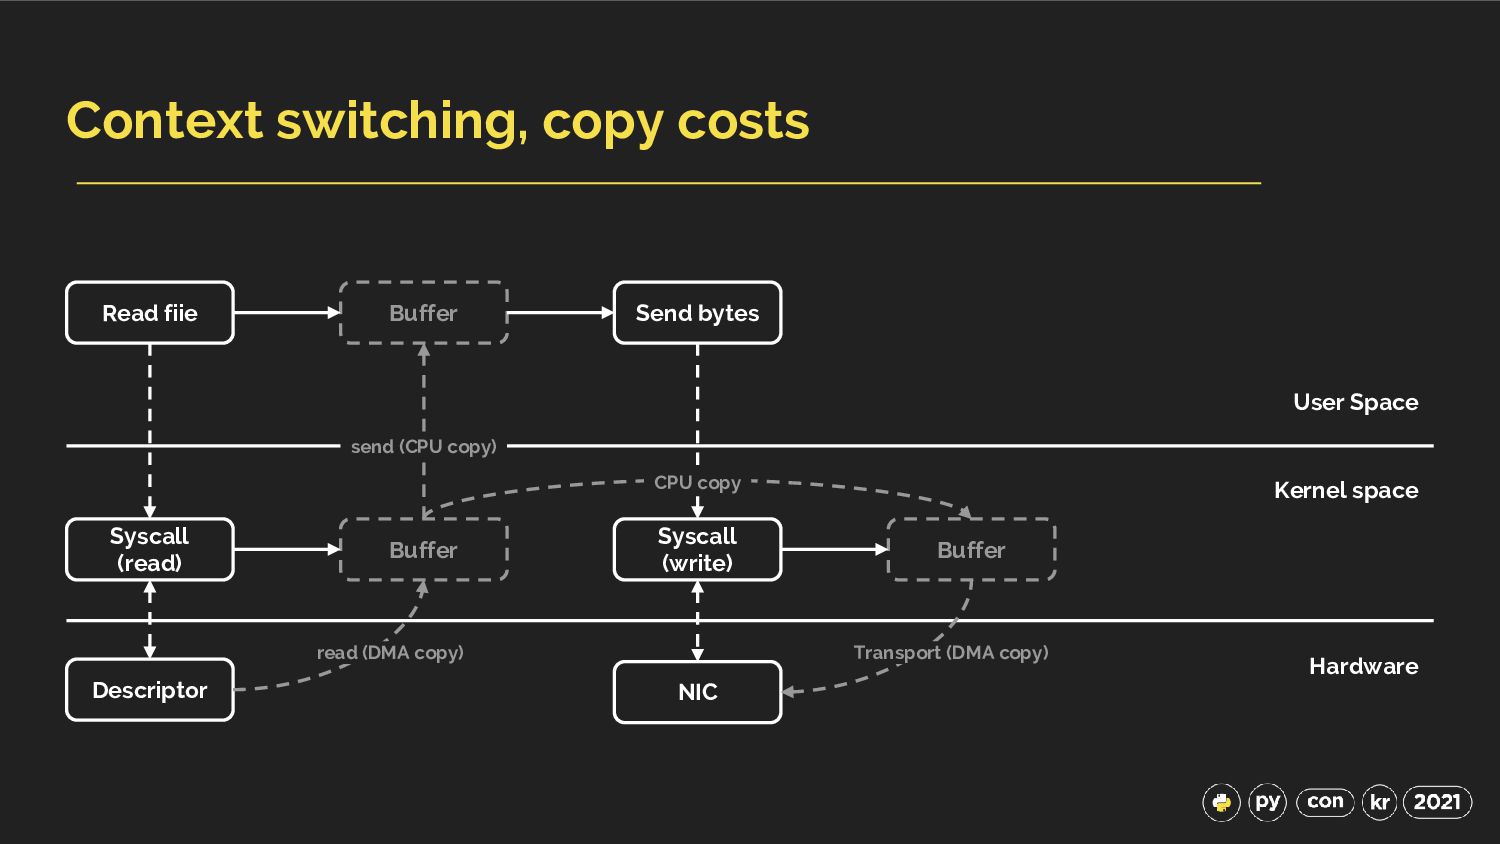
Context switching, copy costs User Space Kernel space Read fiie
Buffer Buffer send (CPU copy) Syscall (read) Descriptor Hardware read (DMA copy) Send bytes NIC Syscall (write) Buffer Transport (DMA copy) CPU copy -
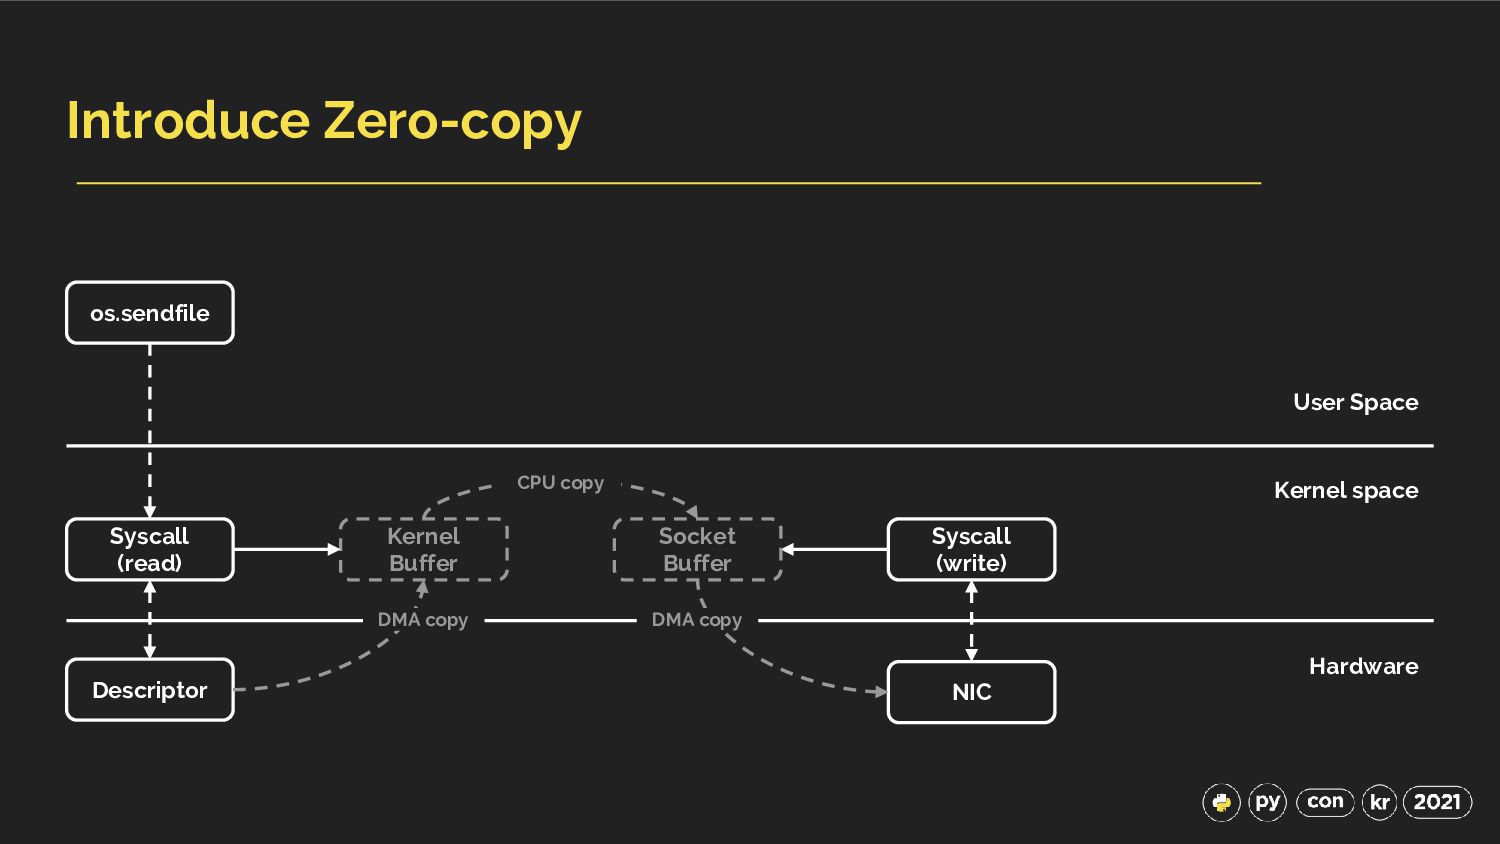
Introduce Zero-copy User Space Kernel space os.sendfile Kernel Buffer Syscall
(read) Descriptor Hardware DMA copy NIC Syscall (write) Socket Buffer DMA copy CPU copy -
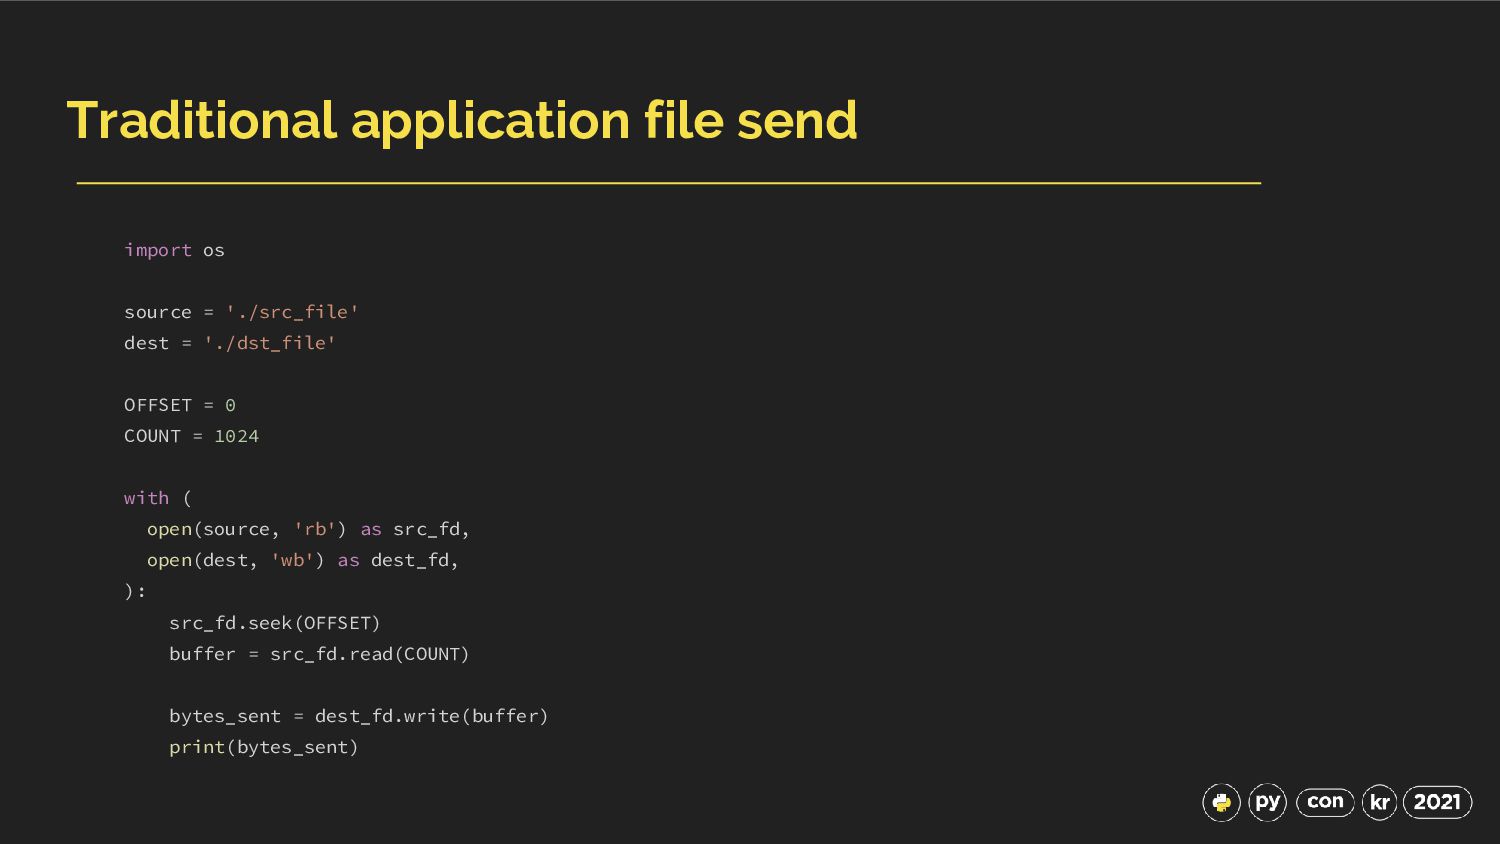
import os source = './src_file' dest = './dst_file' OFFSET =
0 COUNT = 1024 with ( open(source, 'rb') as src_fd, open(dest, 'wb') as dest_fd, ): src_fd.seek(OFFSET) buffer = src_fd.read(COUNT) bytes_sent = dest_fd.write(buffer) print(bytes_sent) Traditional application file send -
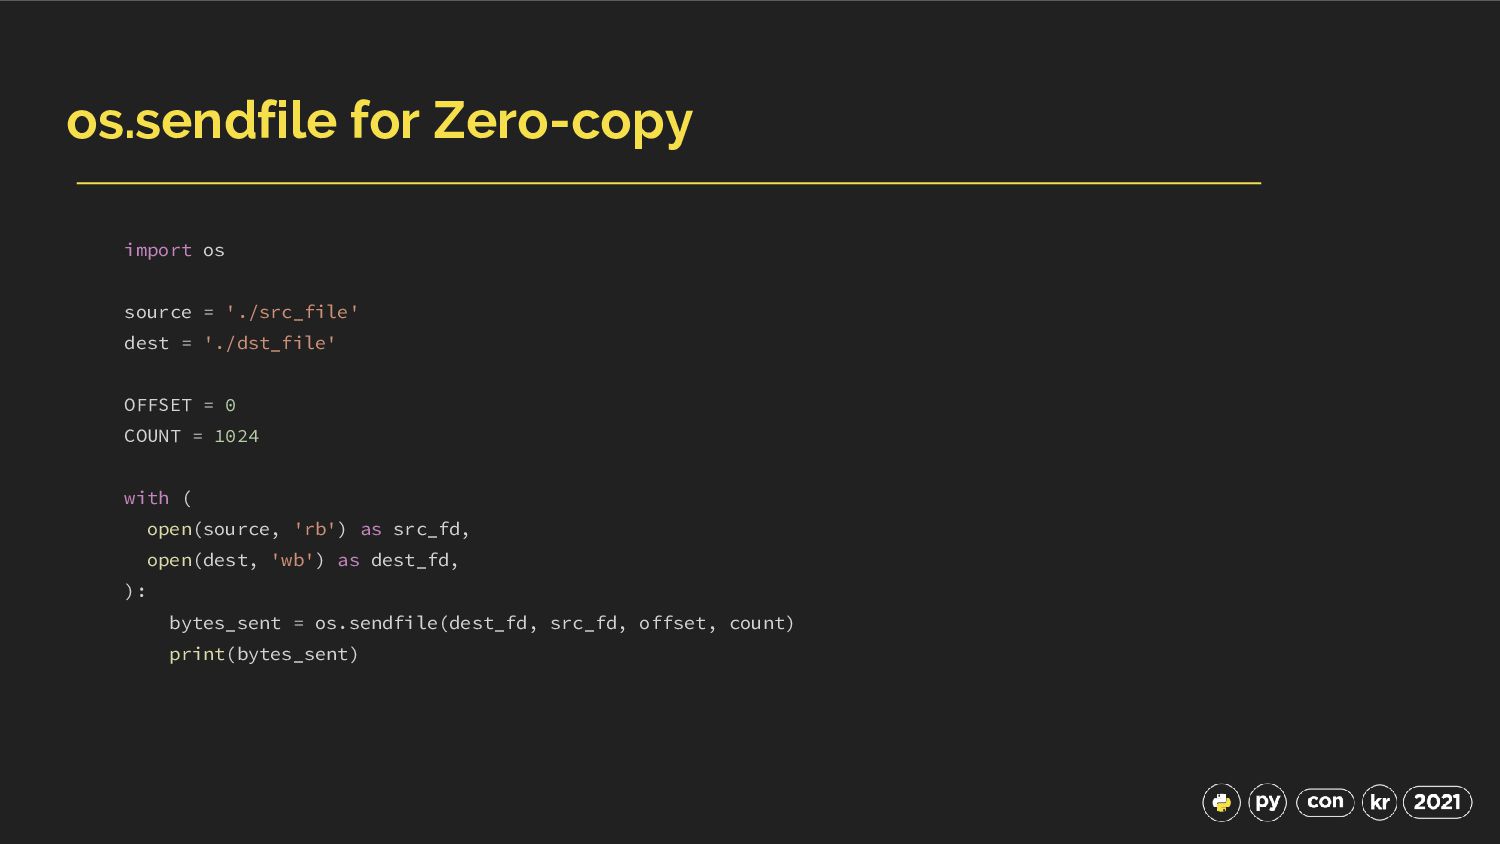
os.sendfile for Zero-copy import os source = './src_file' dest =
'./dst_file' OFFSET = 0 COUNT = 1024 with ( open(source, 'rb') as src_fd, open(dest, 'wb') as dest_fd, ): bytes_sent = os.sendfile(dest_fd, src_fd, offset, count) print(bytes_sent) -
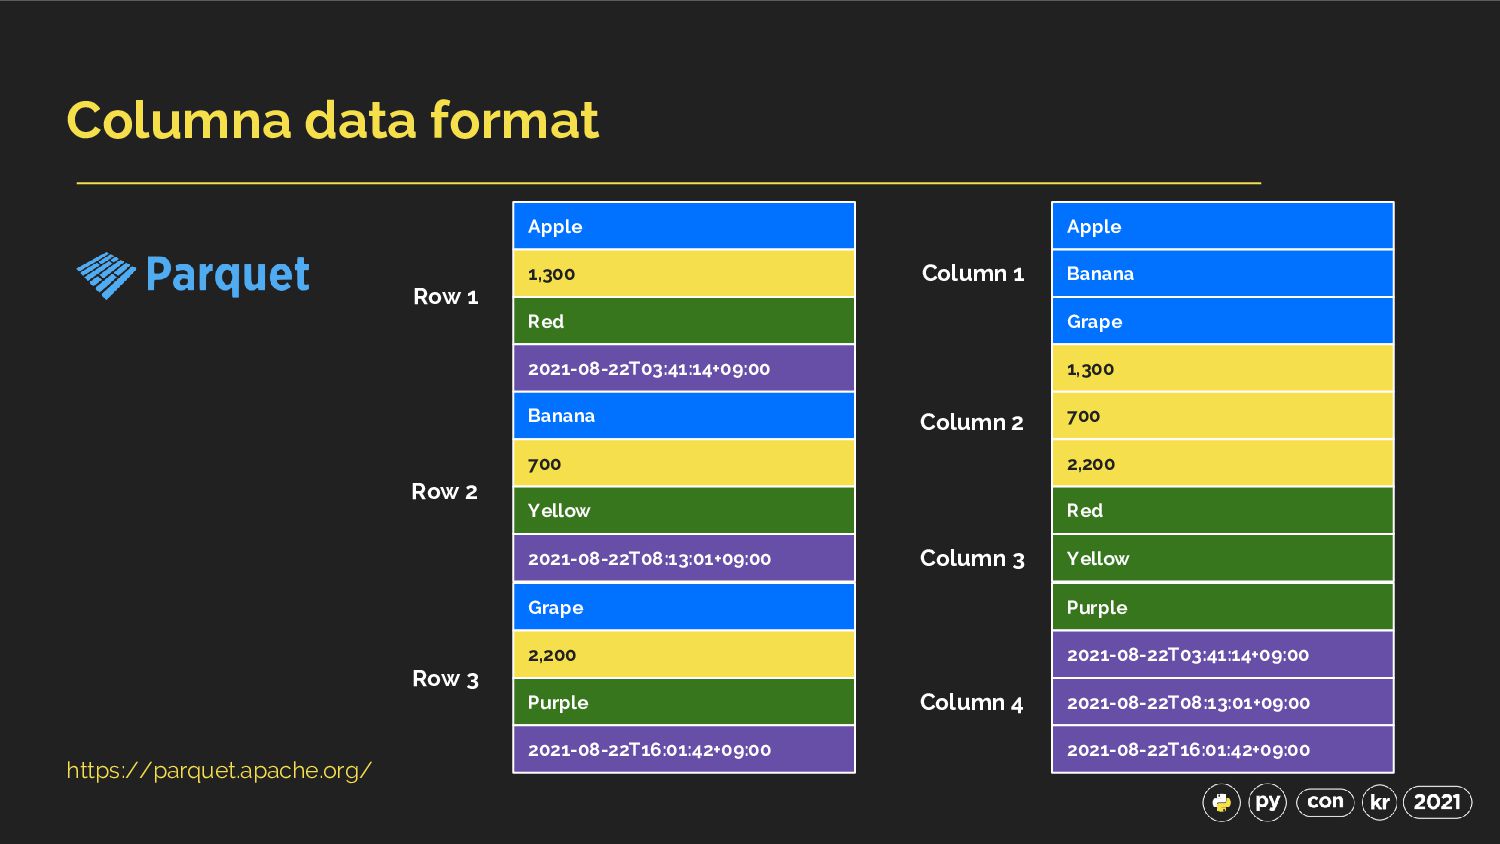
Columna data format https://parquet.apache.org/ Apple 1,300 Red 2021-08-22T03:41:14+09:00 Banana 700
Yellow 2021-08-22T08:13:01+09:00 Grape 2,200 Purple 2021-08-22T16:01:42+09:00 Row 1 Row 2 Row 3 Apple Banana Grape 1,300 700 2,200 Red Yellow Purple 2021-08-22T03:41:14+09:00 2021-08-22T08:13:01+09:00 2021-08-22T16:01:42+09:00 Column 1 Column 2 Column 3 Column 4 -
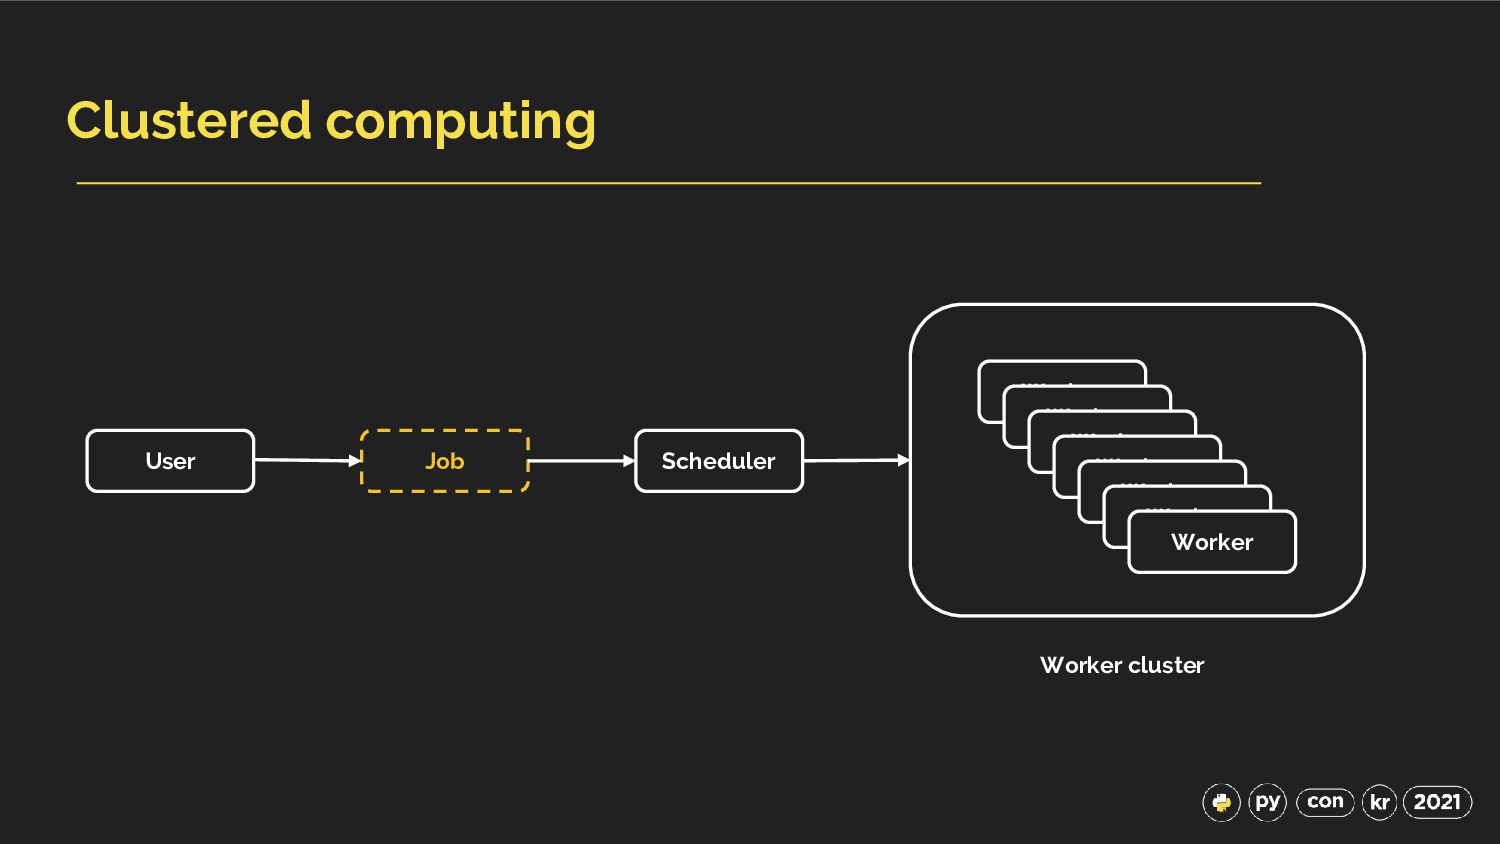
Clustered computing Job Scheduler Worker cluster User Worker Worker Worker
Worker Worker Worker Worker