Using Information Bottleneck principle for summarization • Outcomes • Better result on automatic / human evaluation • Better result on domain where sentence-summary is not available 2
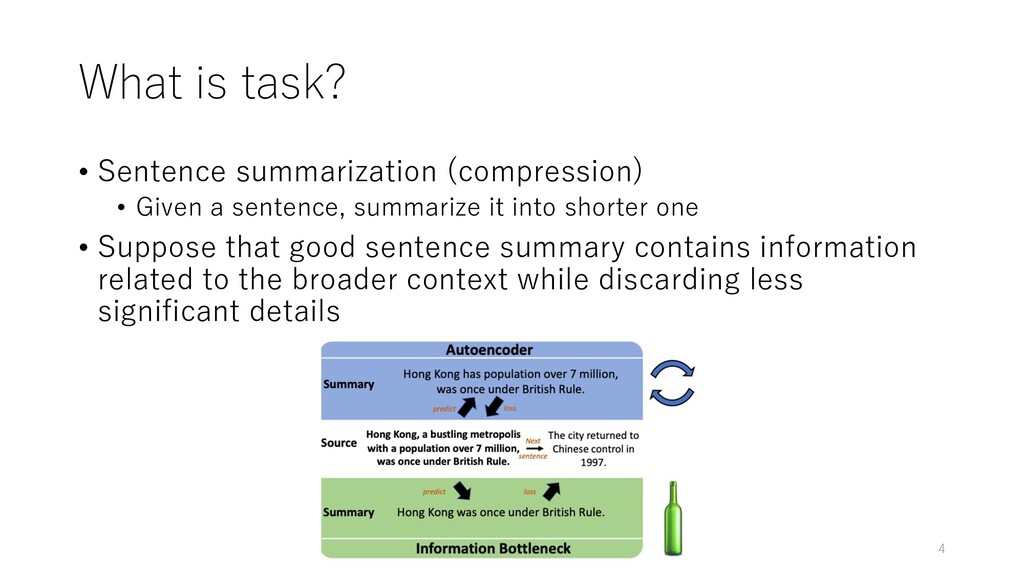
sentence, summarize it into shorter one • Suppose that good sentence summary contains information related to the broader context while discarding less significant details 4
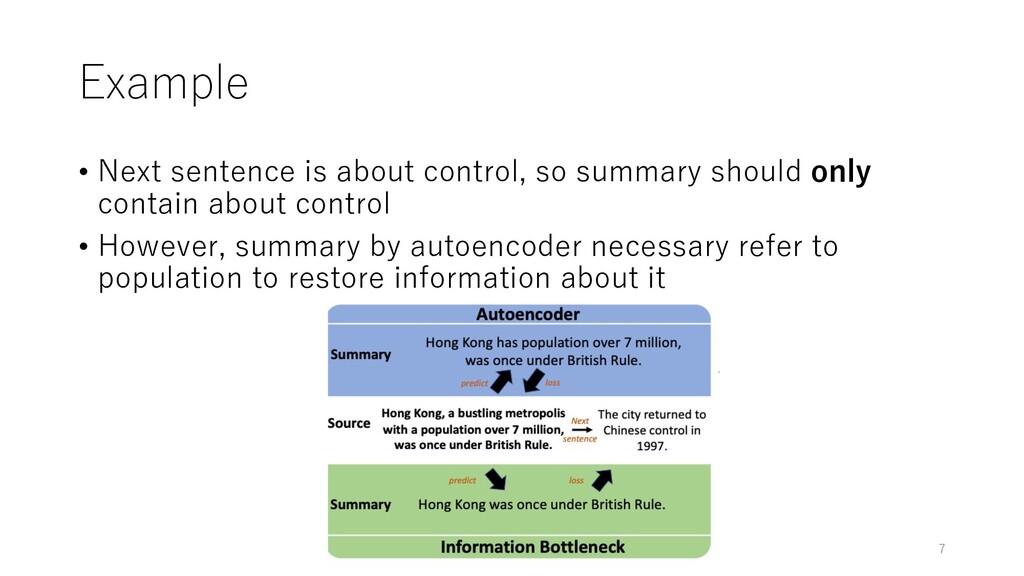
• Sentence-summarize pair is not always available • Current unsupervised methods use autoencoder(AE) as core of methods • The source sentence should be accurately predicted from summary • This goes against the fundamental goal of summarization • Crucially needs to forget all but the “relevant” information • Therefore, use Information Bottleneck(IB) to discard irrelevant information 6
the Information Bottleneck(IB) • 𝐵𝑜𝑡𝑡𝑙𝑒𝑆𝑢𝑚!" • Extractive unsupervised method • No need to train • Take consecutive two sentences as input • 𝐵𝑜𝑡𝑡𝑙𝑒𝑆𝑢𝑚#$%& • Abstractive self-supervised method • Use the result of 𝐵𝑜𝑡𝑡𝑙𝑒𝑆𝑢𝑚!" as training data • Take a sentence as input 8
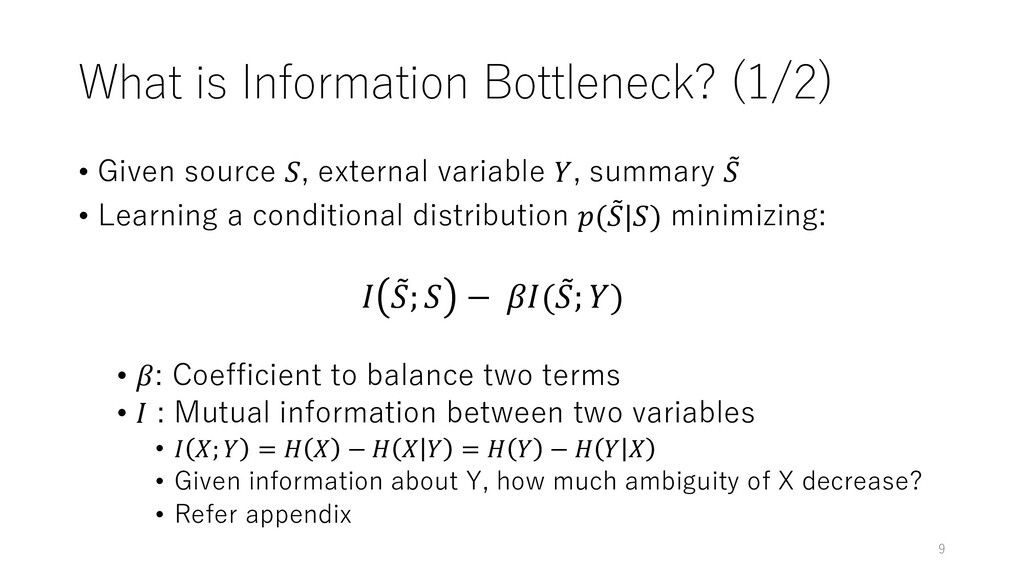
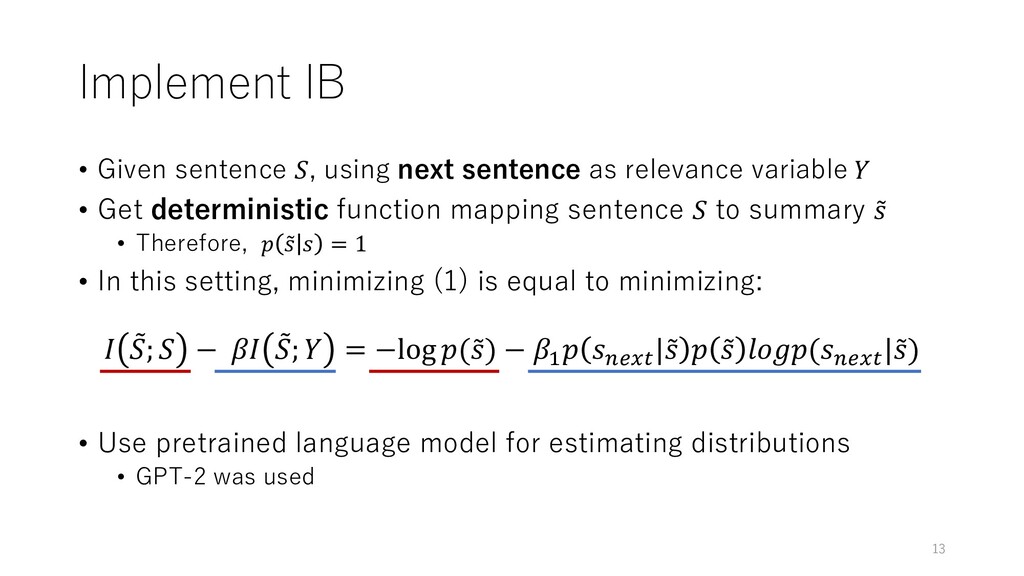
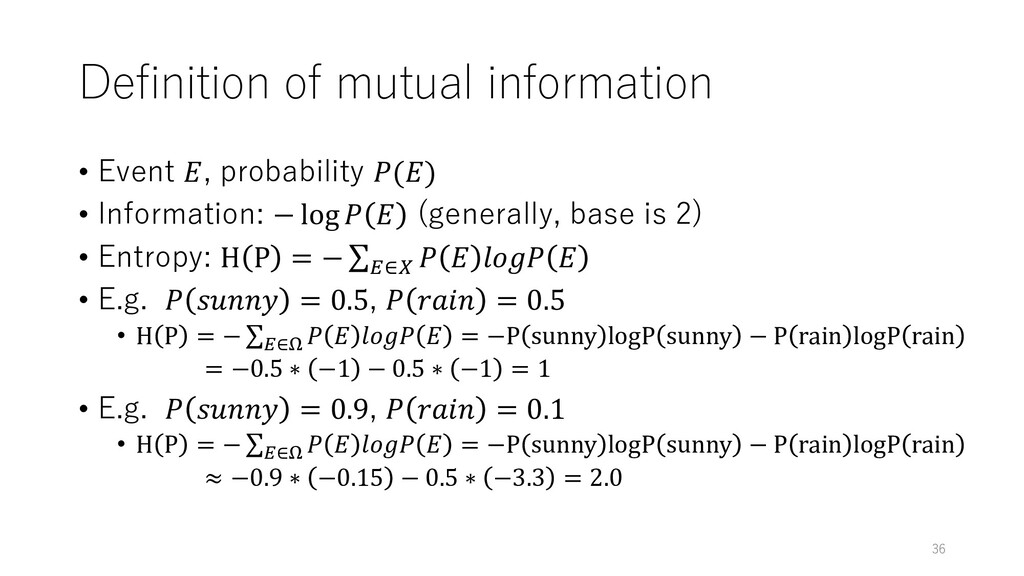
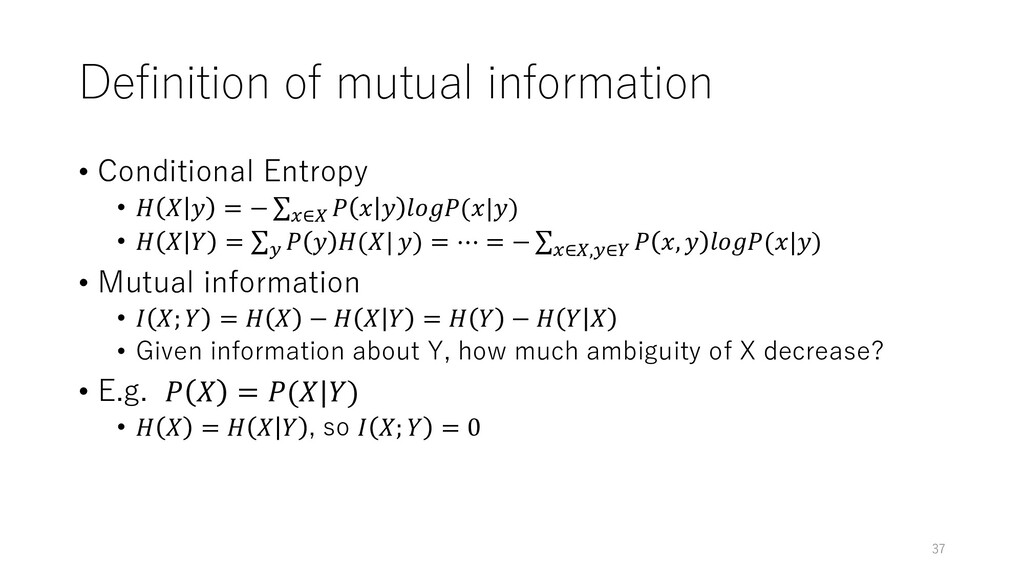
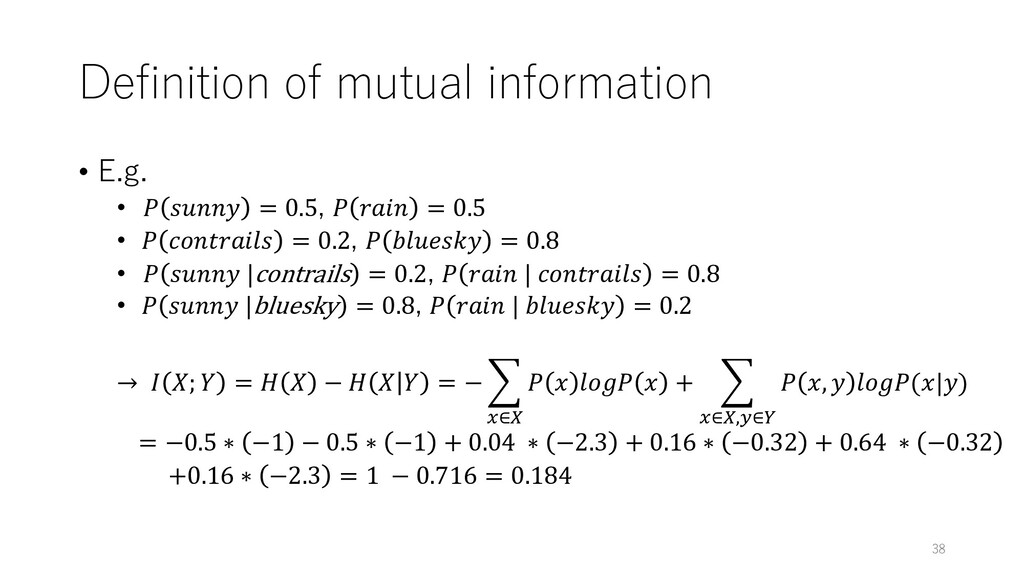
variable 𝑌, summary * 𝑆 • Learning a conditional distribution 𝑝( * 𝑆|𝑆) minimizing: 𝐼 " 𝑆; 𝑆 − 𝛽𝐼( " 𝑆; 𝑌) • 𝛽: Coefficient to balance two terms • 𝐼 : Mutual information between two variables • 𝐼 𝑋; 𝑌 = 𝐻 𝑋 − 𝐻 𝑋 𝑌 = 𝐻 𝑌 − 𝐻 𝑌 𝑋 • Given information about Y, how much ambiguity of X decrease? • Refer appendix 9
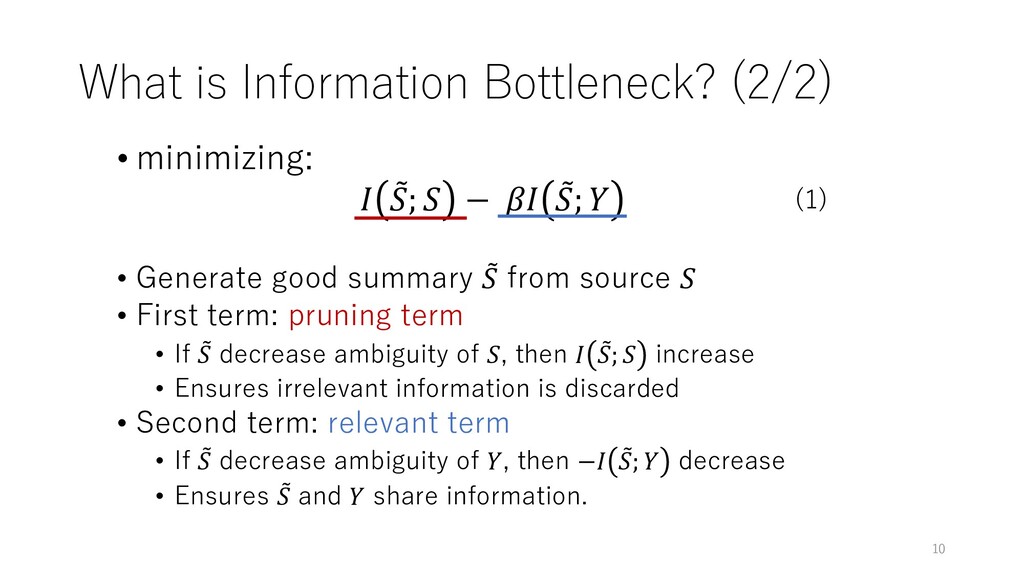
𝑆 − 𝛽𝐼 " 𝑆; 𝑌 • Generate good summary * 𝑆 from source 𝑆 • First term: pruning term • If 0 𝑆 decrease ambiguity of 𝑆, then 𝐼 0 𝑆; 𝑆 increase • Ensures irrelevant information is discarded • Second term: relevant term • If 0 𝑆 decrease ambiguity of 𝑌, then −𝐼 0 𝑆; 𝑌 decrease • Ensures 0 𝑆 and 𝑌 share information. (1) 10
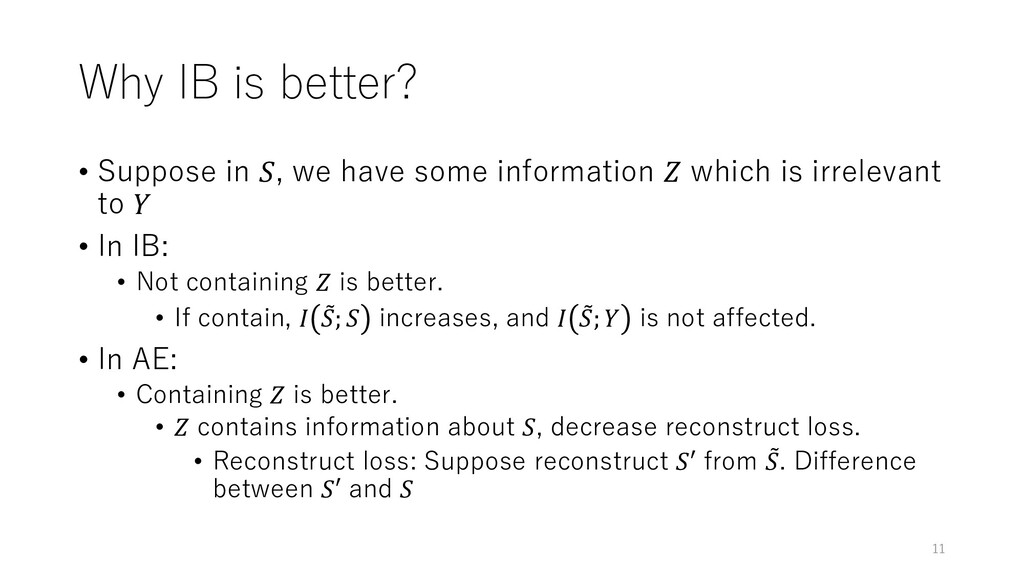
some information 𝑍 which is irrelevant to 𝑌 • In IB: • Not containing 𝑍 is better. • If contain, 𝐼 0 𝑆; 𝑆 increases, and 𝐼 0 𝑆; 𝑌 is not affected. • In AE: • Containing 𝑍 is better. • 𝑍 contains information about 𝑆, decrease reconstruct loss. • Reconstruct loss: Suppose reconstruct 𝑆′ from 0 𝑆. Difference between 𝑆′ and 𝑆 11
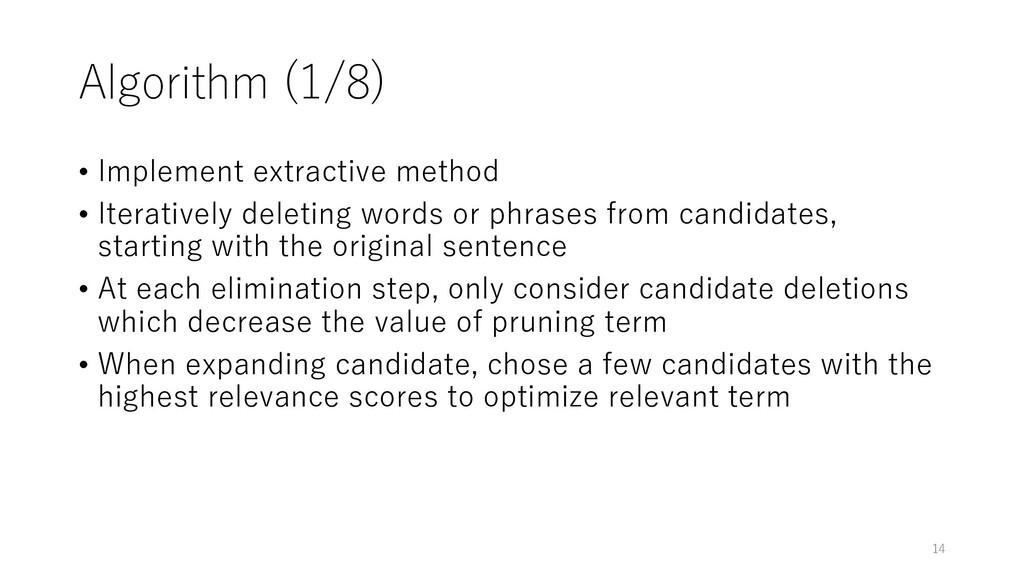
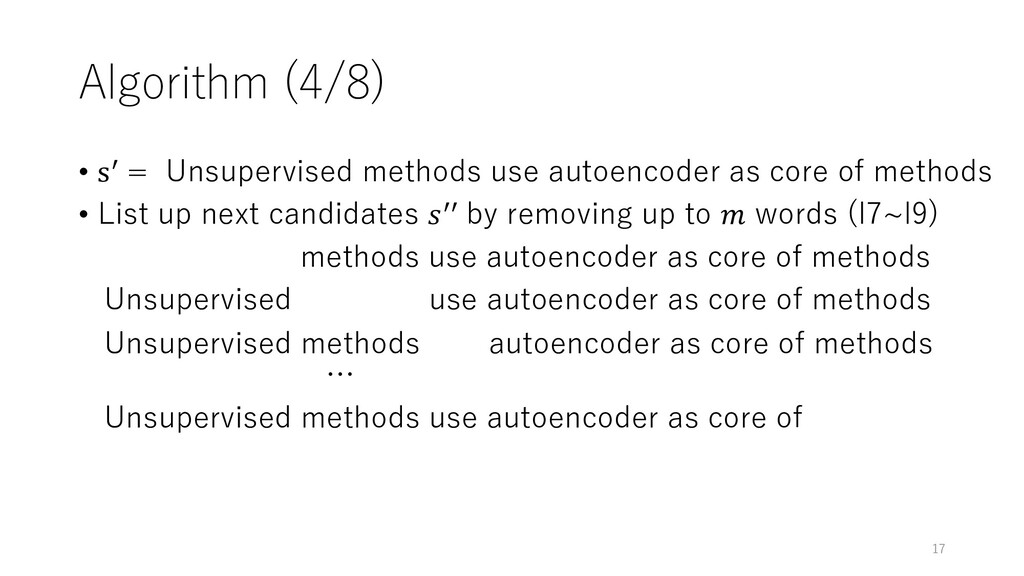
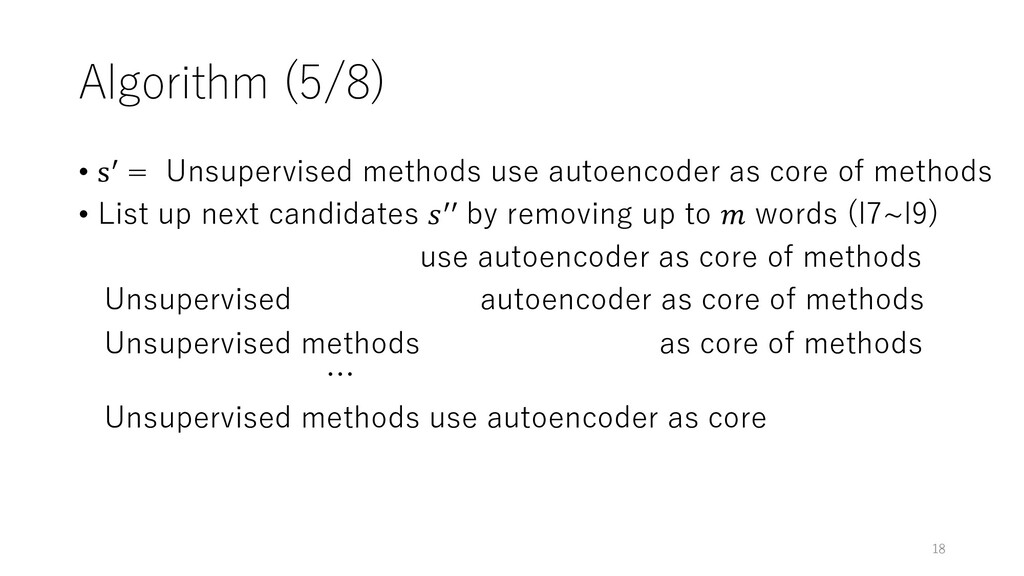
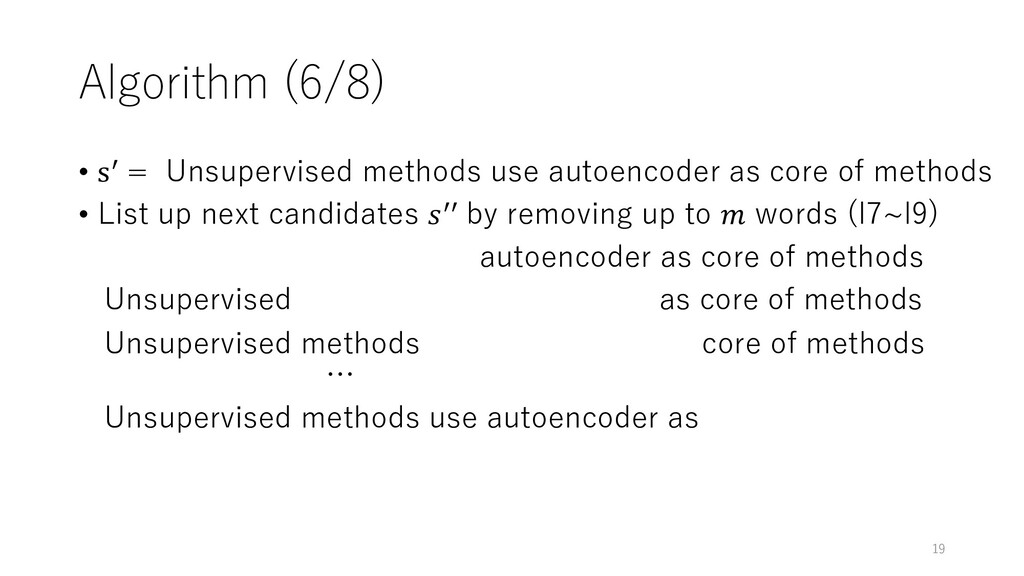
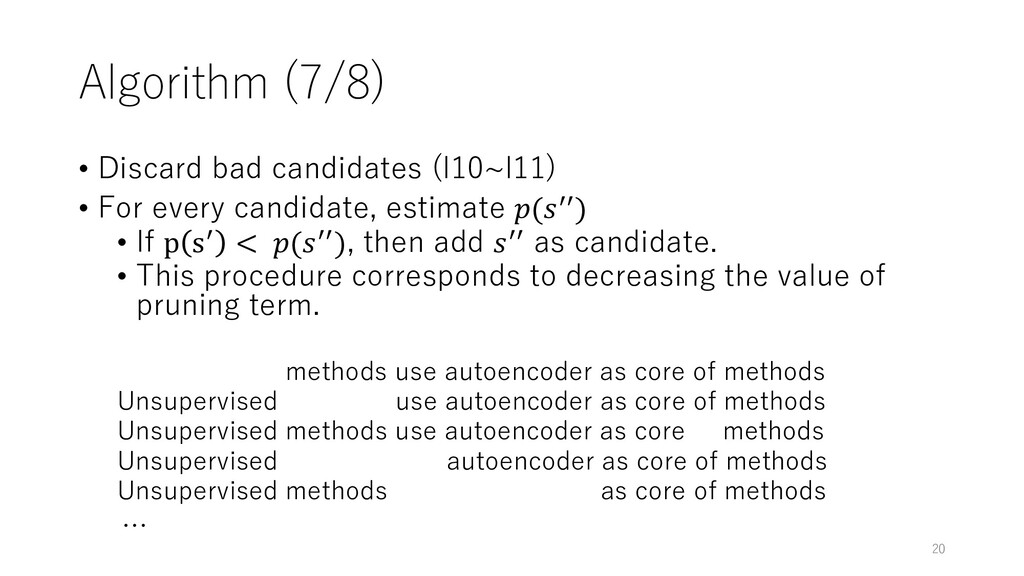
or phrases from candidates, starting with the original sentence • At each elimination step, only consider candidate deletions which decrease the value of pruning term • When expanding candidate, chose a few candidates with the highest relevance scores to optimize relevant term 14
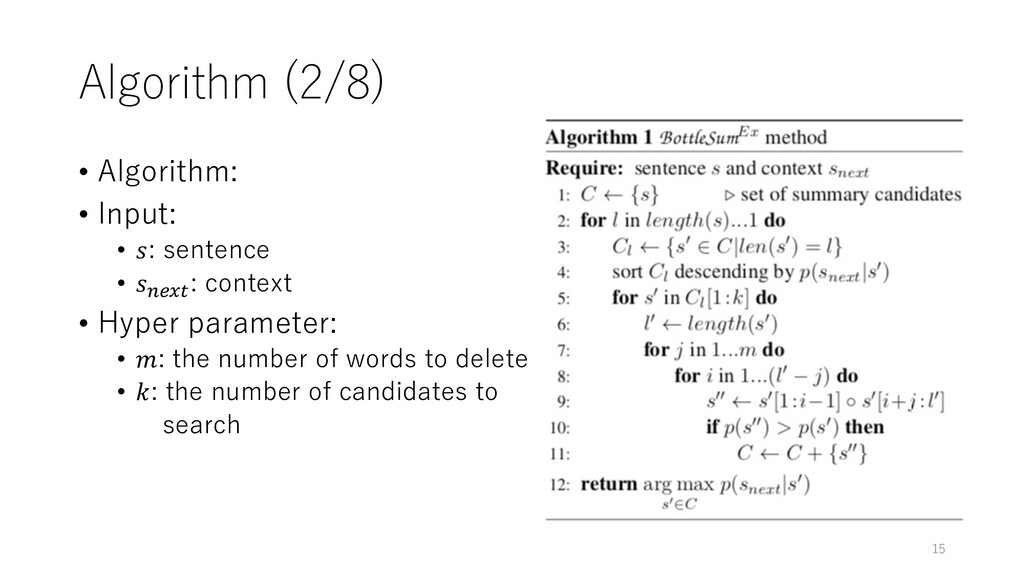
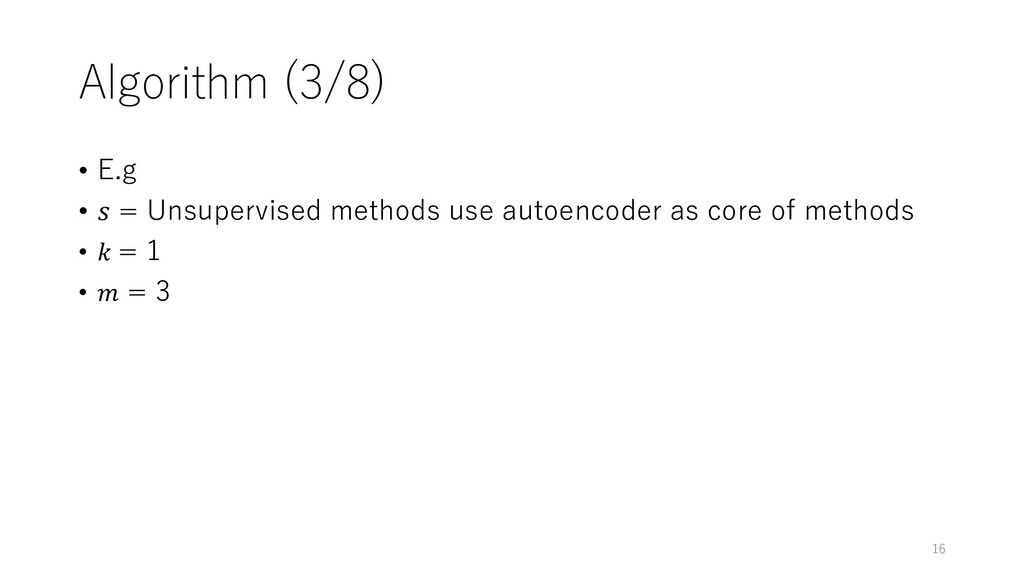
core of methods • List up next candidates 𝑠** by removing up to 𝑚 words (l7~l9) methods use autoencoder as core of methods Unsupervised use autoencoder as core of methods Unsupervised methods autoencoder as core of methods … Unsupervised methods use autoencoder as core of 17
core of methods • List up next candidates 𝑠** by removing up to 𝑚 words (l7~l9) use autoencoder as core of methods Unsupervised autoencoder as core of methods Unsupervised methods as core of methods … Unsupervised methods use autoencoder as core 18
core of methods • List up next candidates 𝑠** by removing up to 𝑚 words (l7~l9) autoencoder as core of methods Unsupervised as core of methods Unsupervised methods core of methods … Unsupervised methods use autoencoder as 19
candidate, estimate 𝑝(𝑠**) • If p s* < 𝑝(𝑠**), then add 𝑠** as candidate. • This procedure corresponds to decreasing the value of pruning term. methods use autoencoder as core of methods Unsupervised use autoencoder as core of methods Unsupervised methods use autoencoder as core methods Unsupervised autoencoder as core of methods Unsupervised methods as core of methods … 20
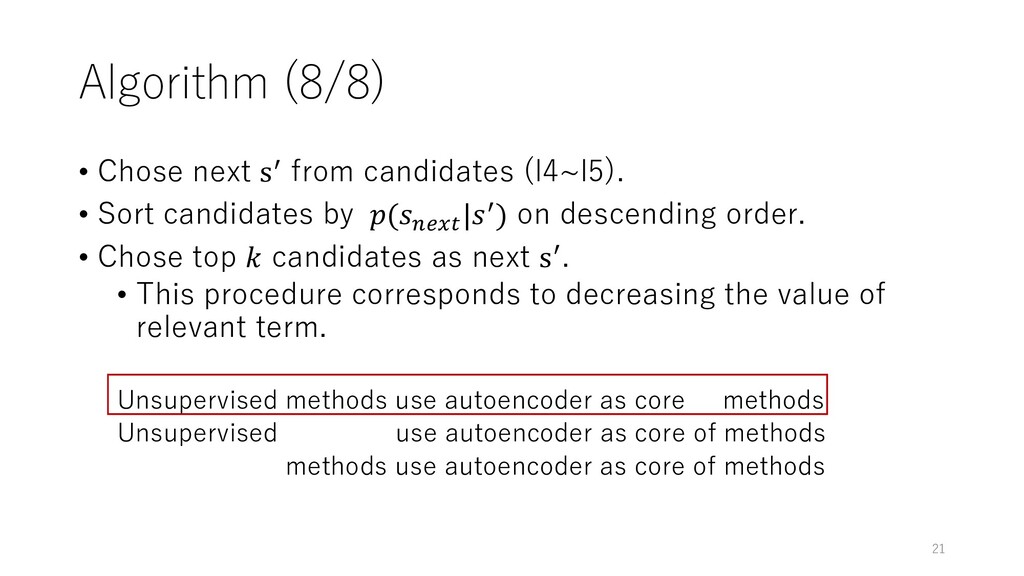
Sort candidates by 𝑝(𝑠($") |𝑠*) on descending order. • Chose top 𝑘 candidates as next s*. • This procedure corresponds to decreasing the value of relevant term. Unsupervised methods use autoencoder as core methods Unsupervised use autoencoder as core of methods methods use autoencoder as core of methods 21
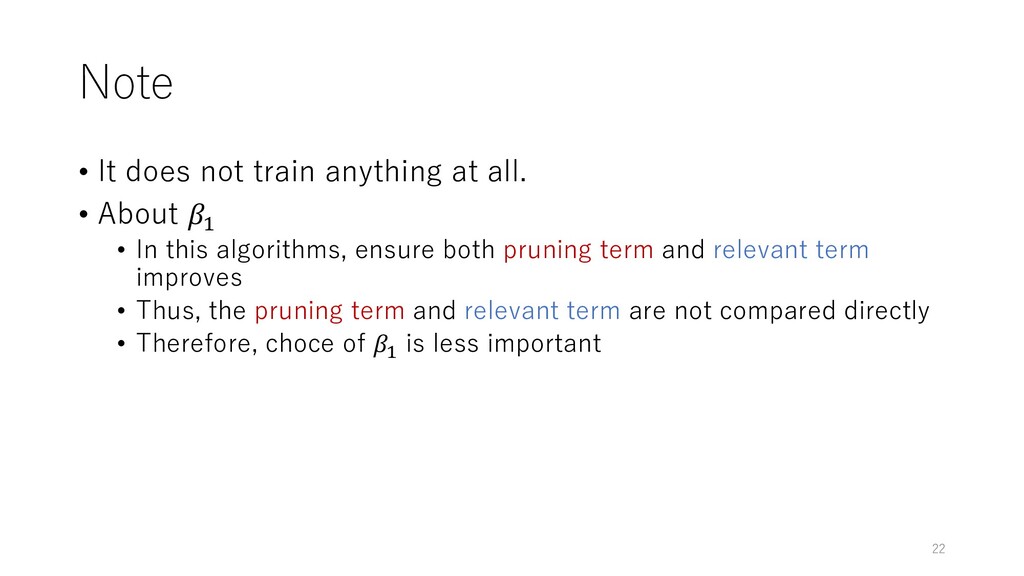
About 𝛽' • In this algorithms, ensure both pruning term and relevant term improves • Thus, the pruning term and relevant term are not compared directly • Therefore, choce of 𝛽& is less important 22
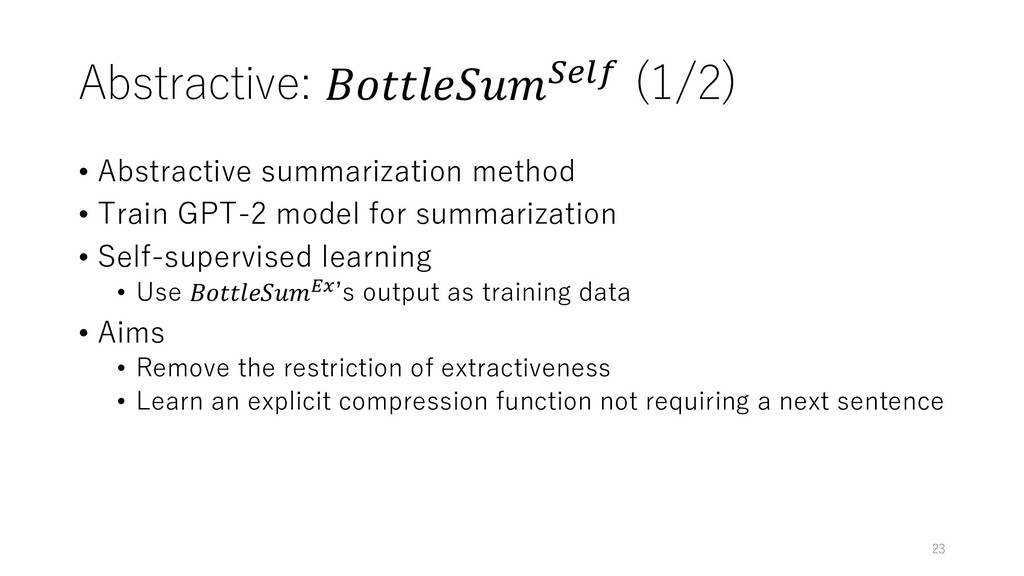
model for summarization • Self-supervised learning • Use 𝐵𝑜𝑡𝑡𝑙𝑒𝑆𝑢𝑚!"ʼs output as training data • Aims • Remove the restriction of extractiveness • Learn an explicit compression function not requiring a next sentence 23
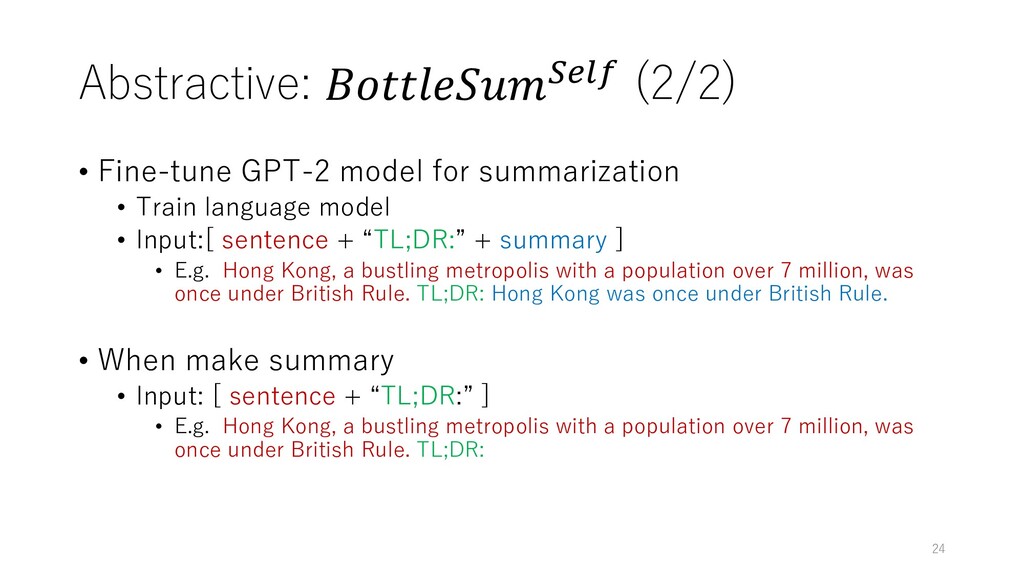
Train language model • Input:[ sentence + “TL;DR:” + summary ] • E.g. Hong Kong, a bustling metropolis with a population over 7 million, was once under British Rule. TL;DR: Hong Kong was once under British Rule. • When make summary • Input: [ sentence + “TL;DR:” ] • E.g. Hong Kong, a bustling metropolis with a population over 7 million, was once under British Rule. TL;DR: 24
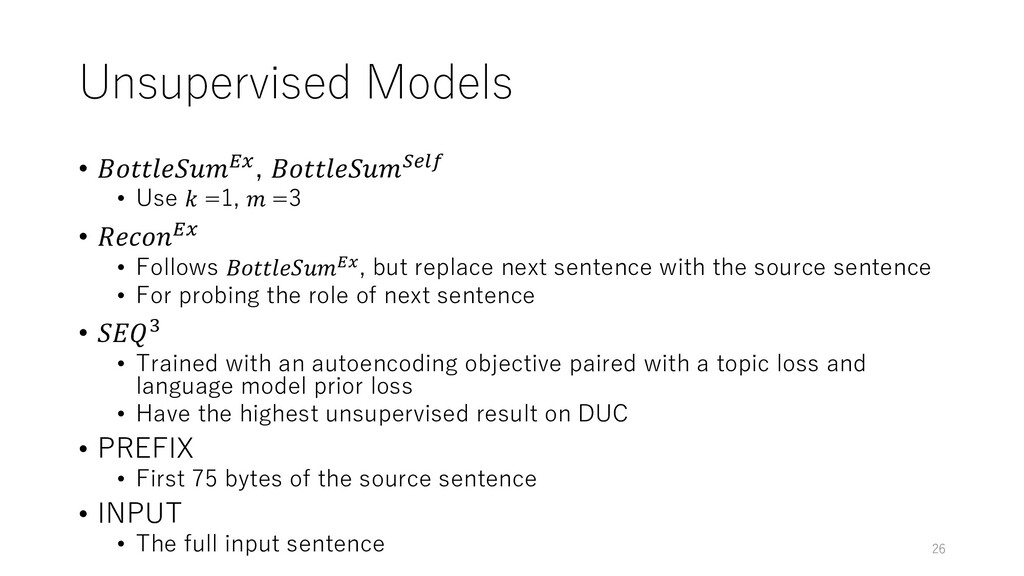
=3 • 𝑅𝑒𝑐𝑜𝑛!" • Follows 𝐵𝑜𝑡𝑡𝑙𝑒𝑆𝑢𝑚!", but replace next sentence with the source sentence • For probing the role of next sentence • 𝑆𝐸𝑄' • Trained with an autoencoding objective paired with a topic loss and language model prior loss • Have the highest unsupervised result on DUC • PREFIX • First 75 bytes of the source sentence • INPUT • The full input sentence 26
• DUC-2003, DUC-2004 datasets • Automatic ROUGE metrics • Sentence-summary pairs • CNN corpus • Summary is not available • Human evaluation • Compare two summary from different models over 3 attributes • coherence, conciseness, and agreement with the input 28
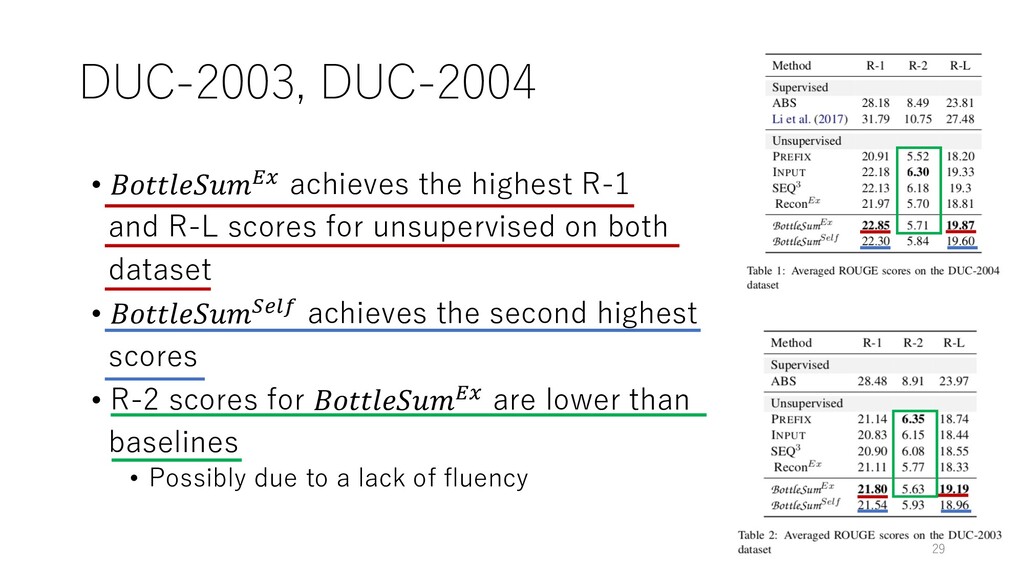
scores for unsupervised on both dataset • 𝐵𝑜𝑡𝑡𝑙𝑒𝑆𝑢𝑚#$%& achieves the second highest scores • R-2 scores for 𝐵𝑜𝑡𝑡𝑙𝑒𝑆𝑢𝑚!" are lower than baselines • Possibly due to a lack of fluency 29
available • 𝑆𝐸𝑄+ is trained on CNN corpus • ABS is not trained • Use the model as originally trained on the Gigaword sentence dataset • Attribute scores are average of three peopleʼs score • Attribute scores are averaged over a scale of 1 (better), 0 (equal) and -1 (worse) 30
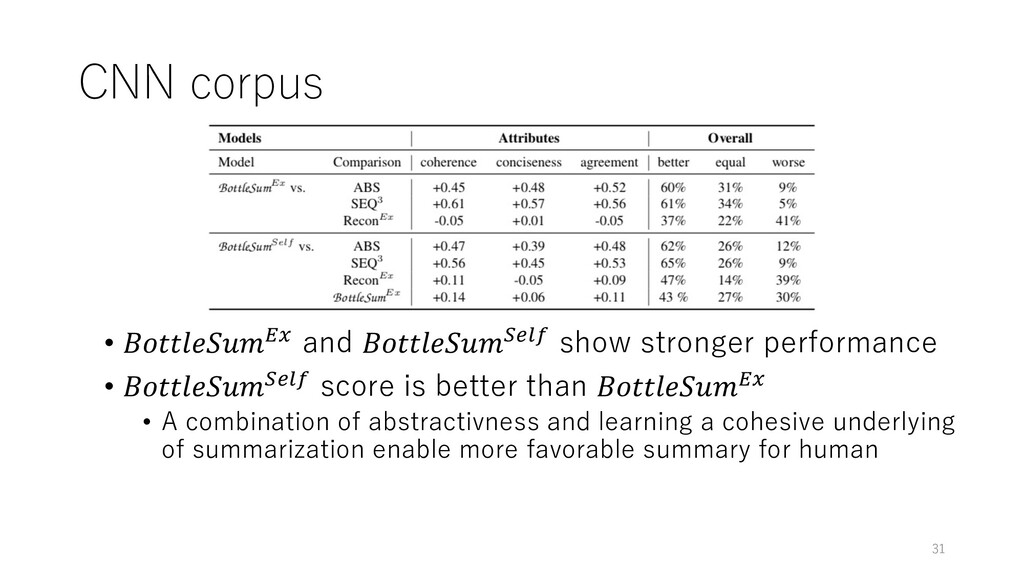
𝐵𝑜𝑡𝑡𝑙𝑒𝑆𝑢𝑚#$%& score is better than 𝐵𝑜𝑡𝑡𝑙𝑒𝑆𝑢𝑚!" • A combination of abstractivness and learning a cohesive underlying of summarization enable more favorable summary for human 31
training set • Poor out-of-domain performance • 𝑆𝐸𝑄+ is unsupervised, but still needs extensive training on a large corpus of in-domain text • 𝐵𝑜𝑡𝑡𝑙𝑒𝑆𝑢𝑚!" requires neither of them 32
Using Information Bottleneck principle for summarization • Outcomes • Better result on automatic / human evaluation • Better result on domain where sentence-summary is not available 34


 kevin3314
 s_shimotori
 neuecc
 curekoshimizu
 yosuke_furukawa
 oga5
 ivargrimstad
 chigichan24
 kentaroutakeda
 yuukiw00w
 soyuka
 ioki
 headius
 marktimemedia
 sabderemane
 retrage
 eileencodes
 nmsamuel
 marcelosomers
 konakalab
 aleyda
 quramy
 bryan
 smashingmag
 chrisshort