Share
Embed
Real-time Estimation on Billion ows of events using Apache Druid
LINE Developers Thailand
September 14, 2022
Transcript
31 slides
-
Real-time Estimation on Billion rows of events using Apache Druid
How OAPlus manages to do real-time segment aggregation -
Phisit Jorphochaudom Technical Project Manager, Solution Engineer LINE Thailand Real-time
Estimation on Billion rows of events using Apache Druid -
• Problem Statement • Introduction to Apache Druid • Theta
Sketch estimation • How Druid solve data pipeline problems • Real-time events Agenda -
• Lots of user event data • Survey responses •
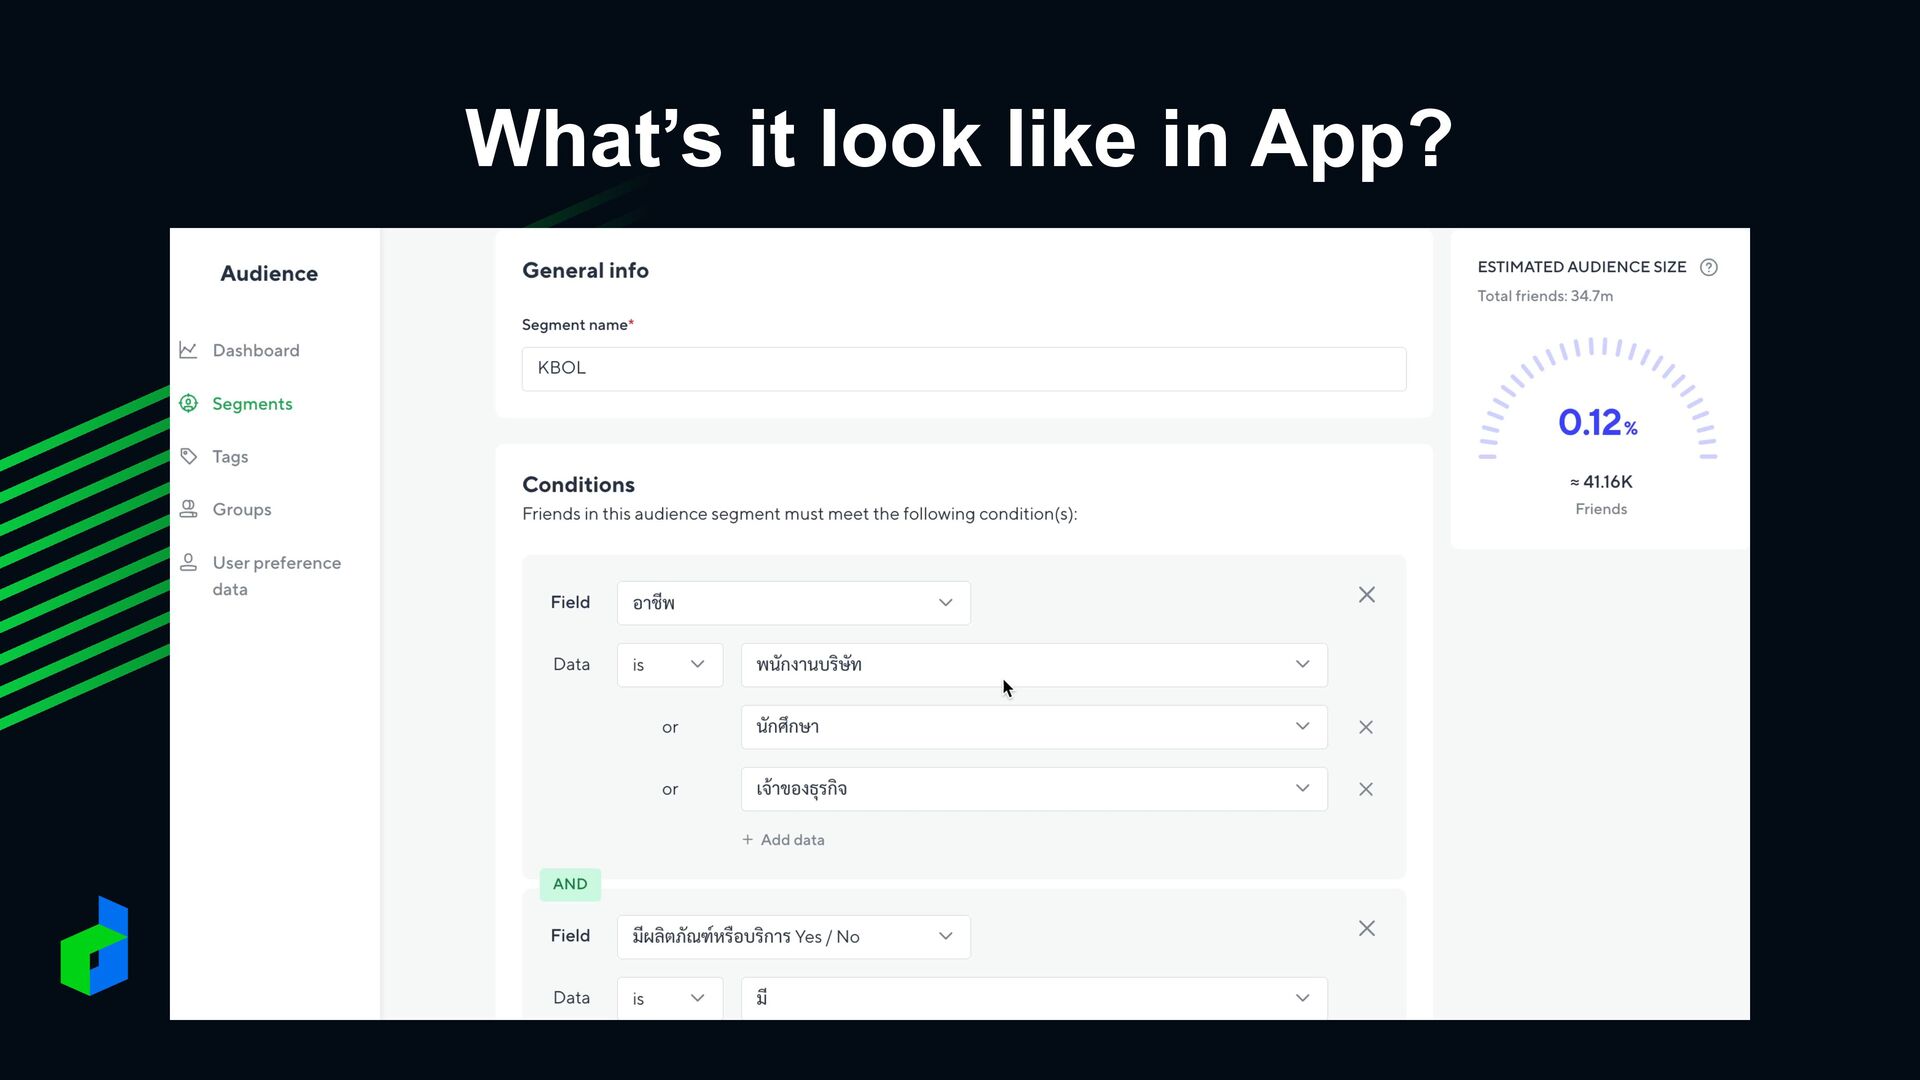
Chat messages • Tags, Groups • Data size (Billion+ rows) • Aggregate in real-time • i.e. How many users are in this tag and answer this survey? Problem Statement -
• SQL database does not work (Data is too large)
• LINE has a big Hadoop cluster (but not suitable for real-time usage) • Aggregation in Mongo is really slow Problem Statement -
• Apache Druid allows us to store very large data
• Deep storage stores data on HDFS • Can ingest data directly from HDFS • Suitable for real-time workload • Can do sketch estimation! Answer -
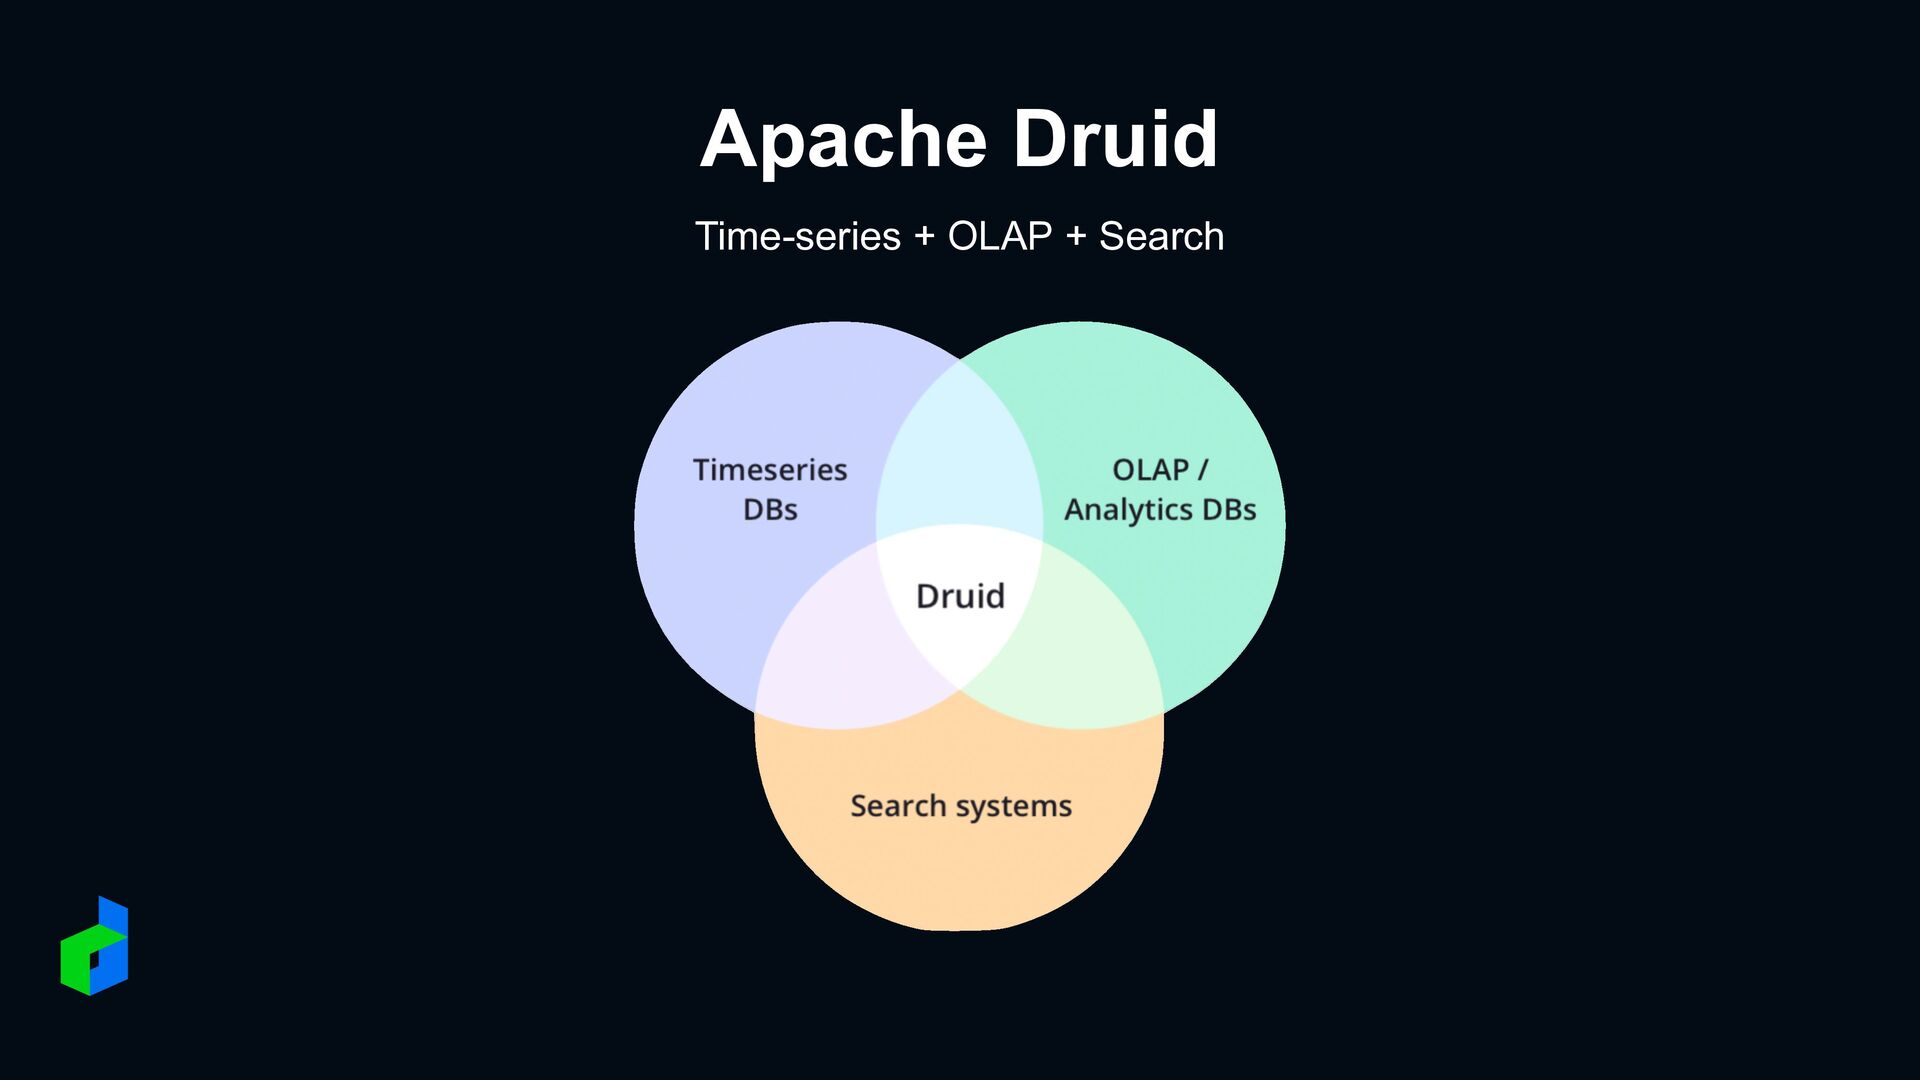
What is • Apache Druid is a real-time analytics database
designed for fast slice-and-dice analytics on large data sets • Druid is most used where real-time ingest, fast query performance, and high uptime are important • Druid is commonly used for powering GUIs of analytical applications, or as a backend for highly- concurrent APIs that need fast aggregations. Druid works best with event-oriented data. -
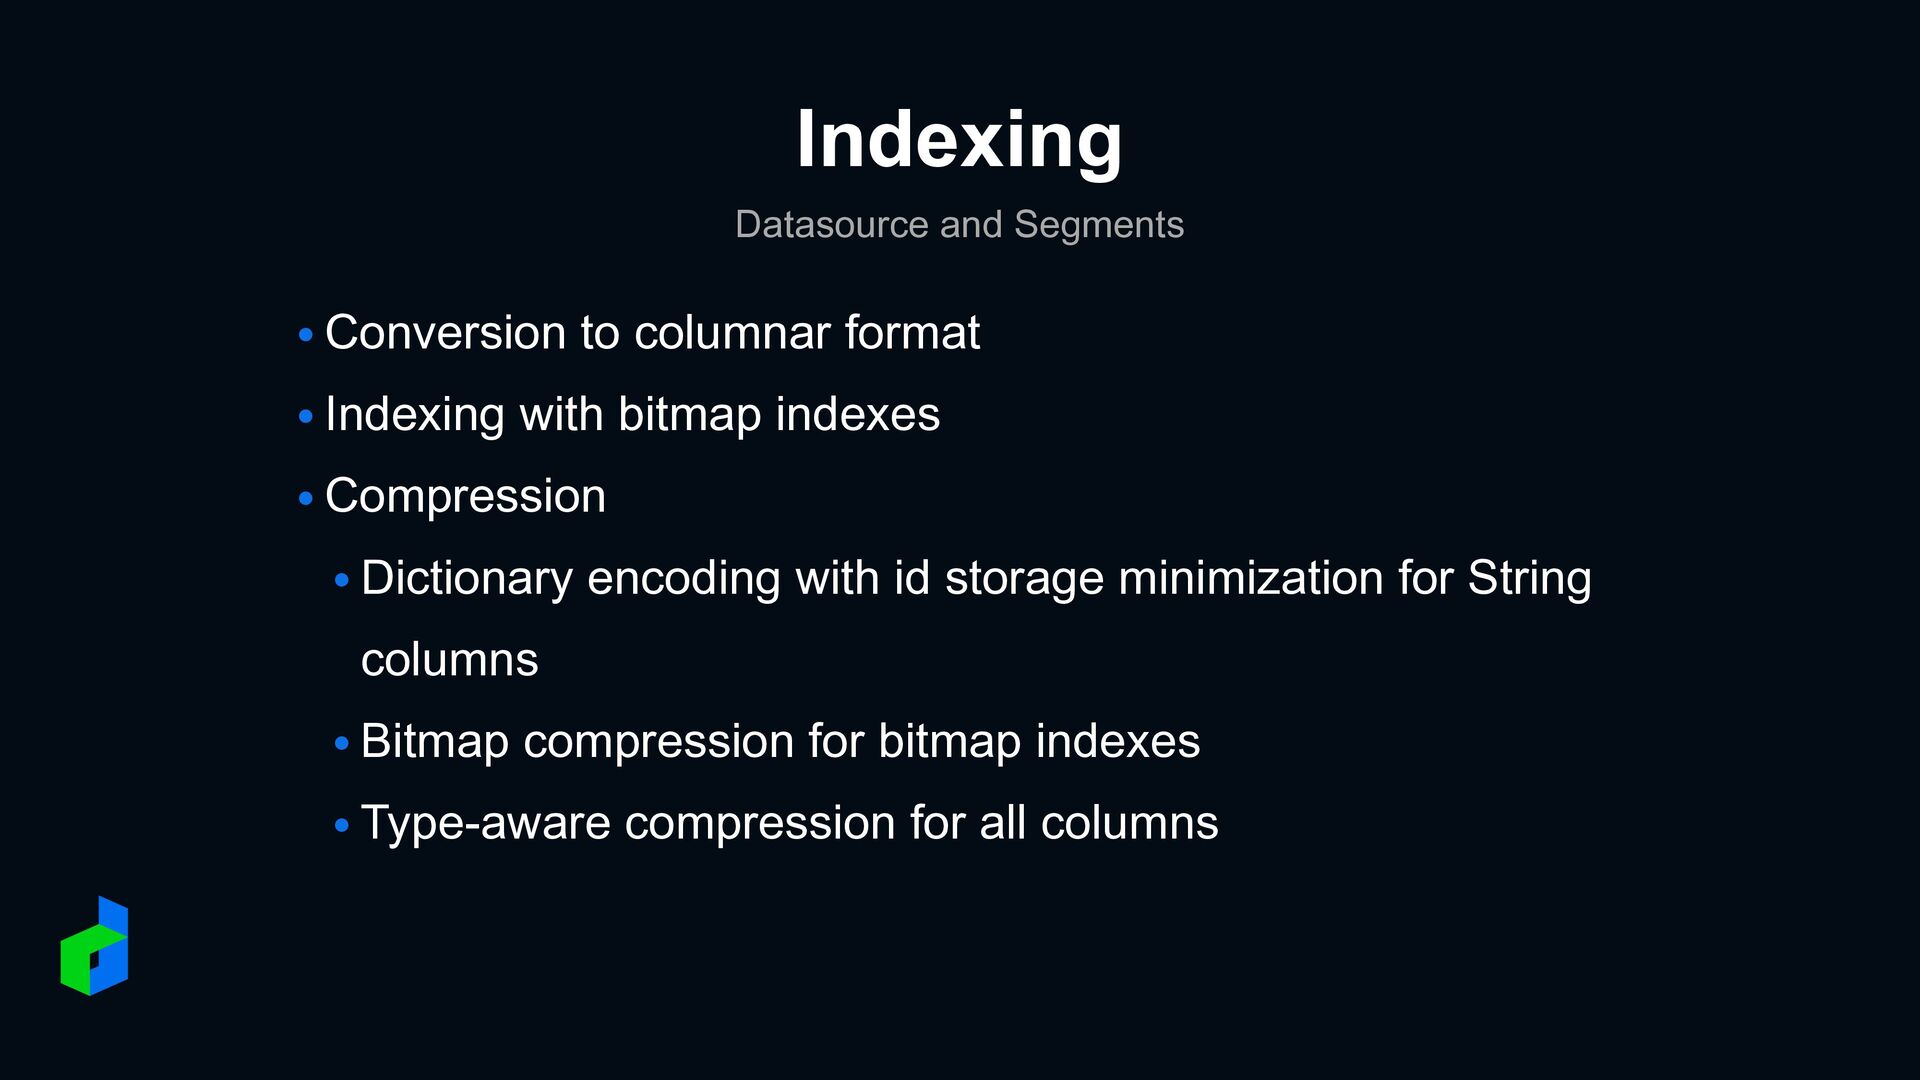
Indexing Datasource and Segments • Conversion to columnar format •
Indexing with bitmap indexes • Compression • Dictionary encoding with id storage minimization for String columns • Bitmap compression for bitmap indexes • Type-aware compression for all columns -
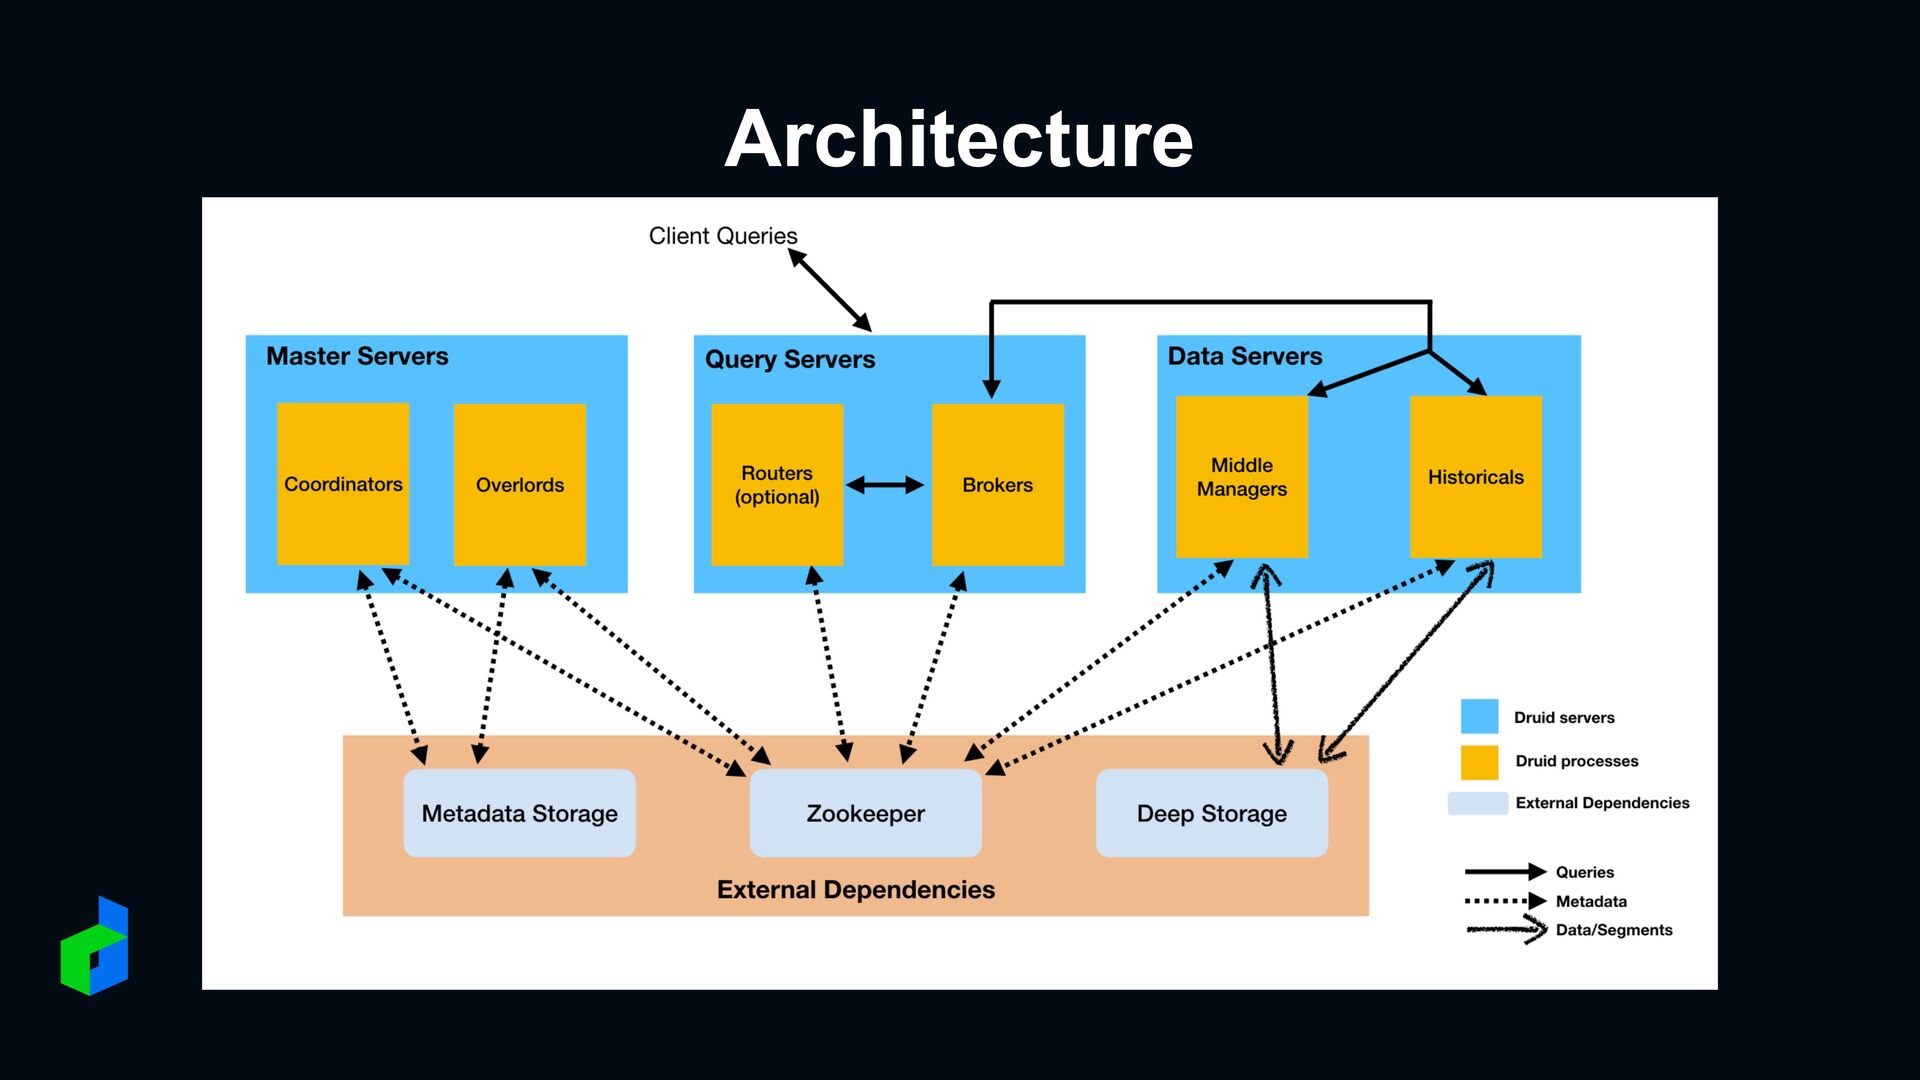
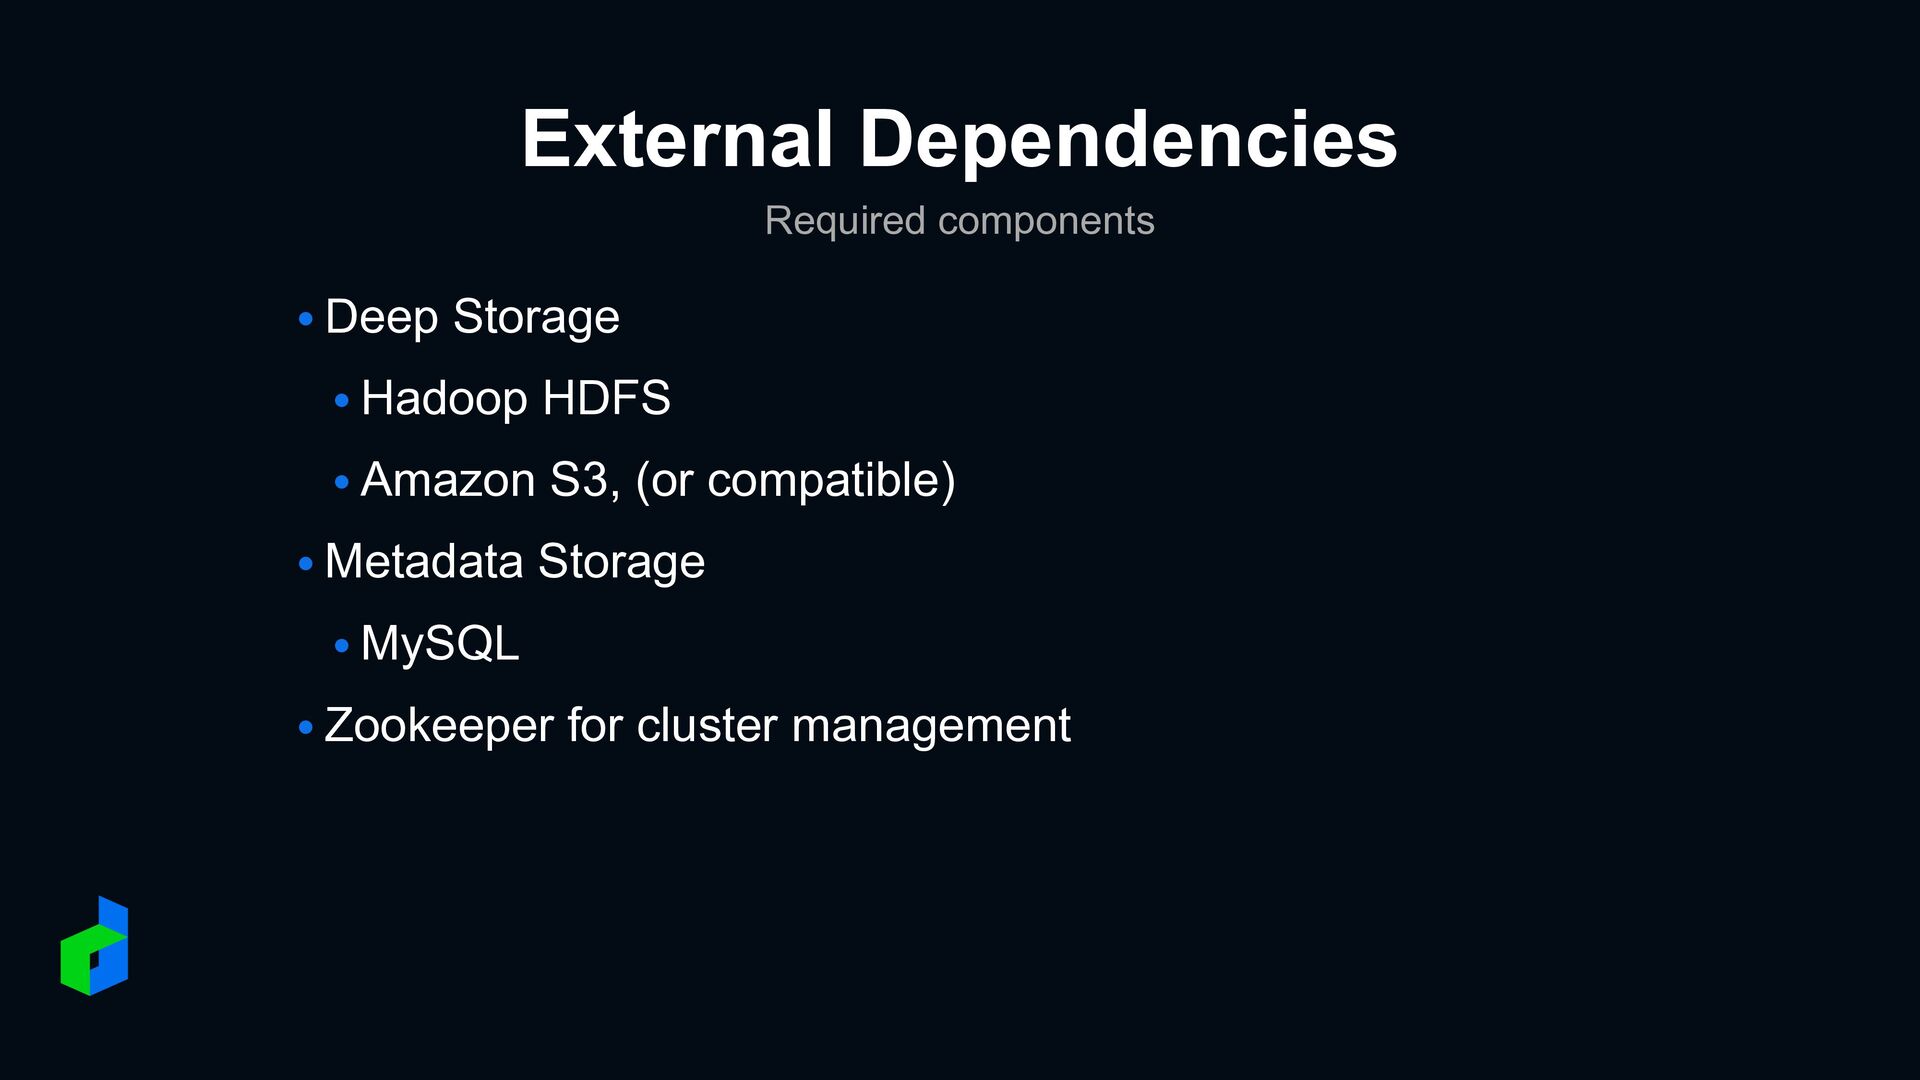
External Dependencies Required components • Deep Storage • Hadoop HDFS
• Amazon S3, (or compatible) • Metadata Storage • MySQL • Zookeeper for cluster management -
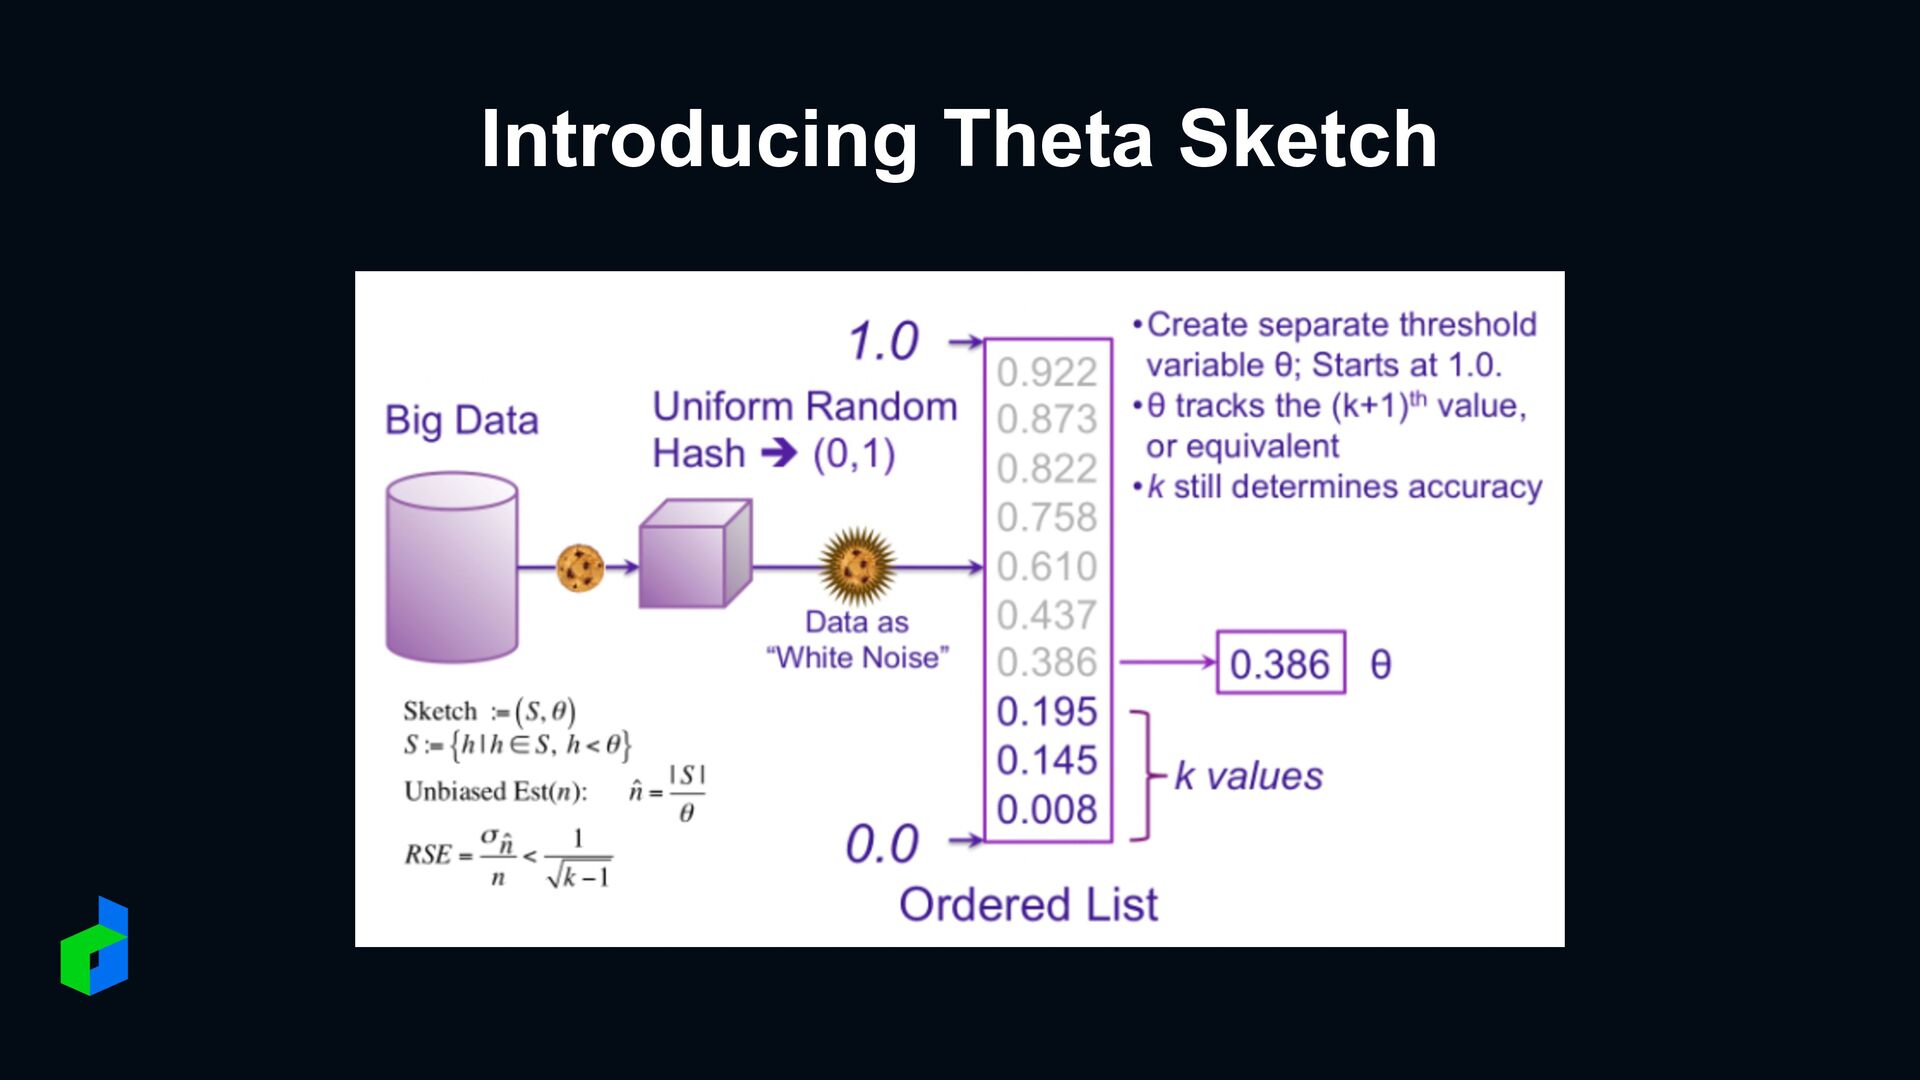
Introducing Theta Sketch • The Challenge: Fast, Approximate Analysis of
Big Data • Unique User (or Count Distinct) Queries • Set Operation (and, or, not) • If An Approximate Answer is Acceptable • +/- 1~4% accuracy -
What is our data pipeline looks like? From application to
Druid App DB App DB LINE Hadoop Cluster Druid ET ET Inges App (for estimation) -
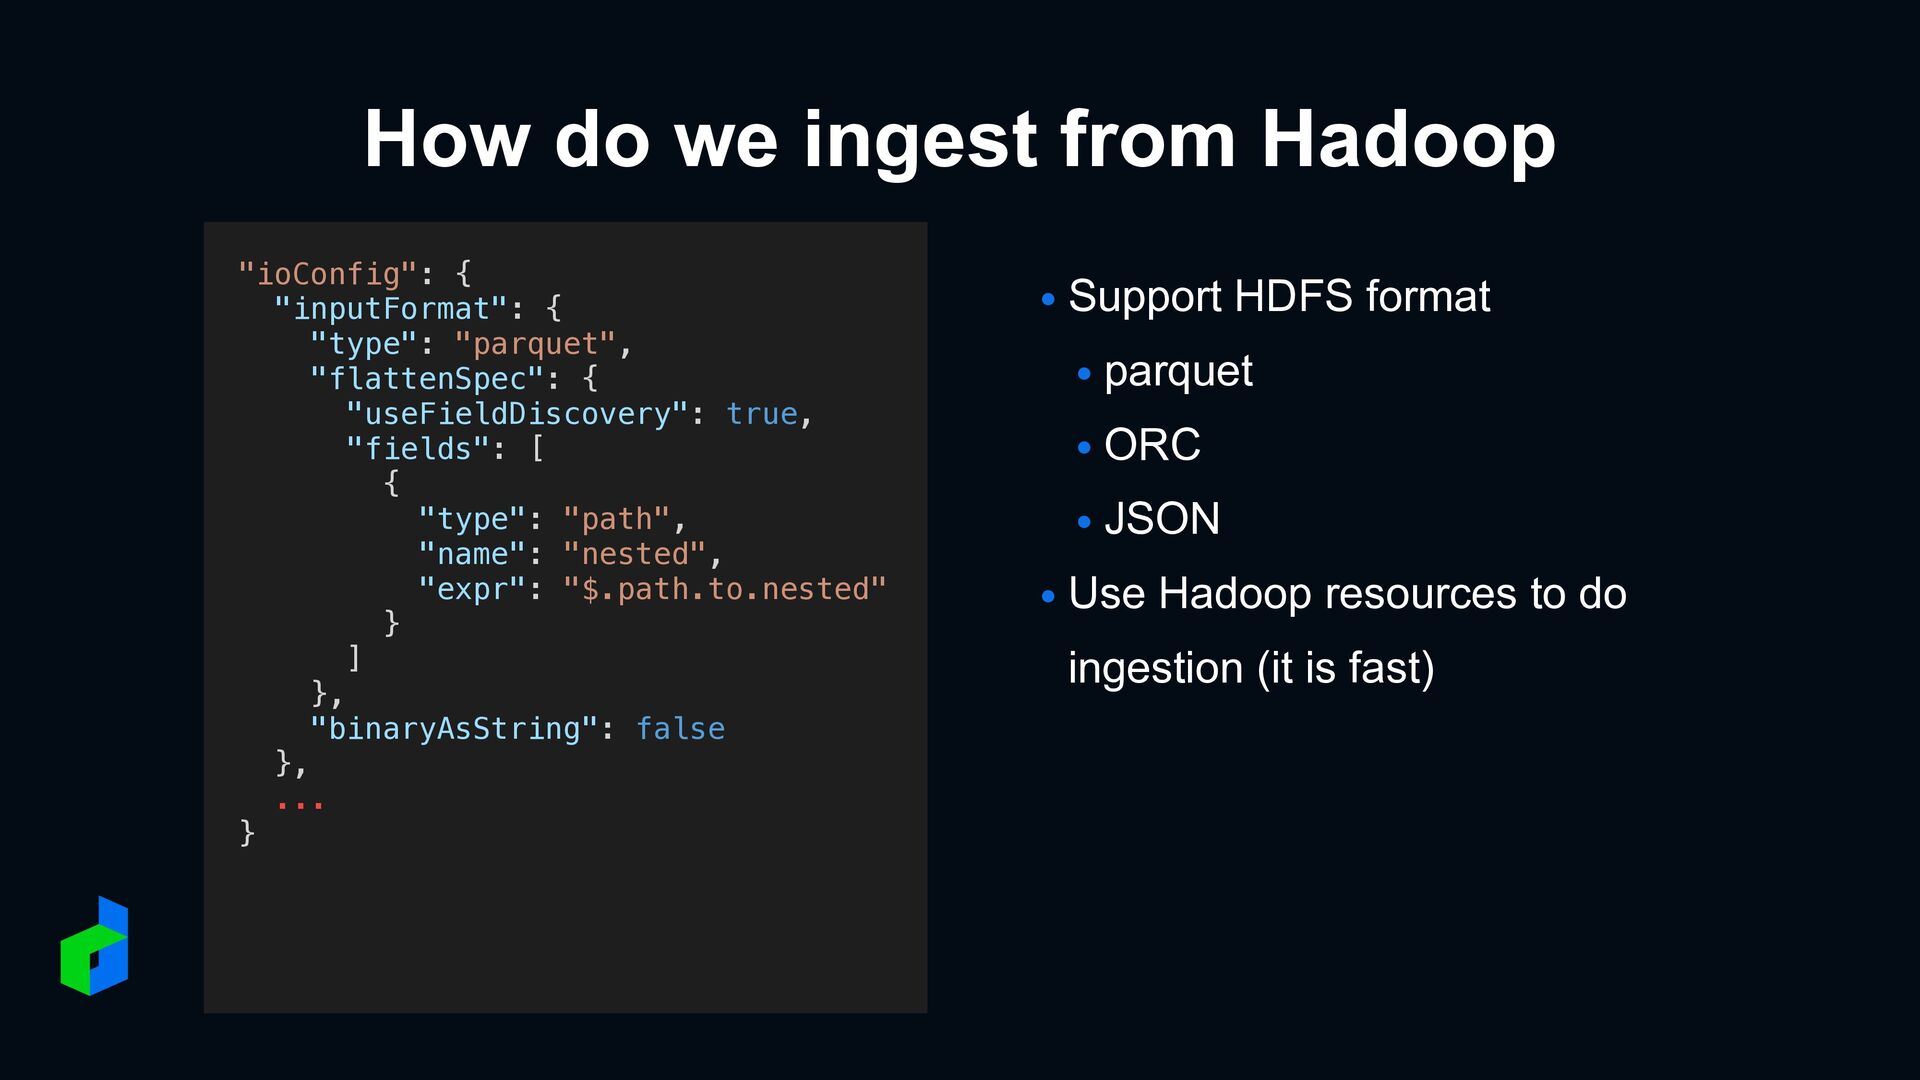
How do we ingest from Hadoop "ioConfig": { "inputFormat": {
"type": "parquet", "flattenSpec": { "useFieldDiscovery": true, "fields": [ { "type": "path", "name": "nested", "expr": "$.path.to.nested" } ] }, "binaryAsString": false }, ... } • Support HDFS format • parquet • ORC • JSON • Use Hadoop resources to do ingestion (it is fast) -
Our Use Cases Group A Group B Group A &
Group B • Simple Case • What if it goes on and on • A & B & C & … • Mongo DB aggregation can take up to 5 minutes on just about million users. -
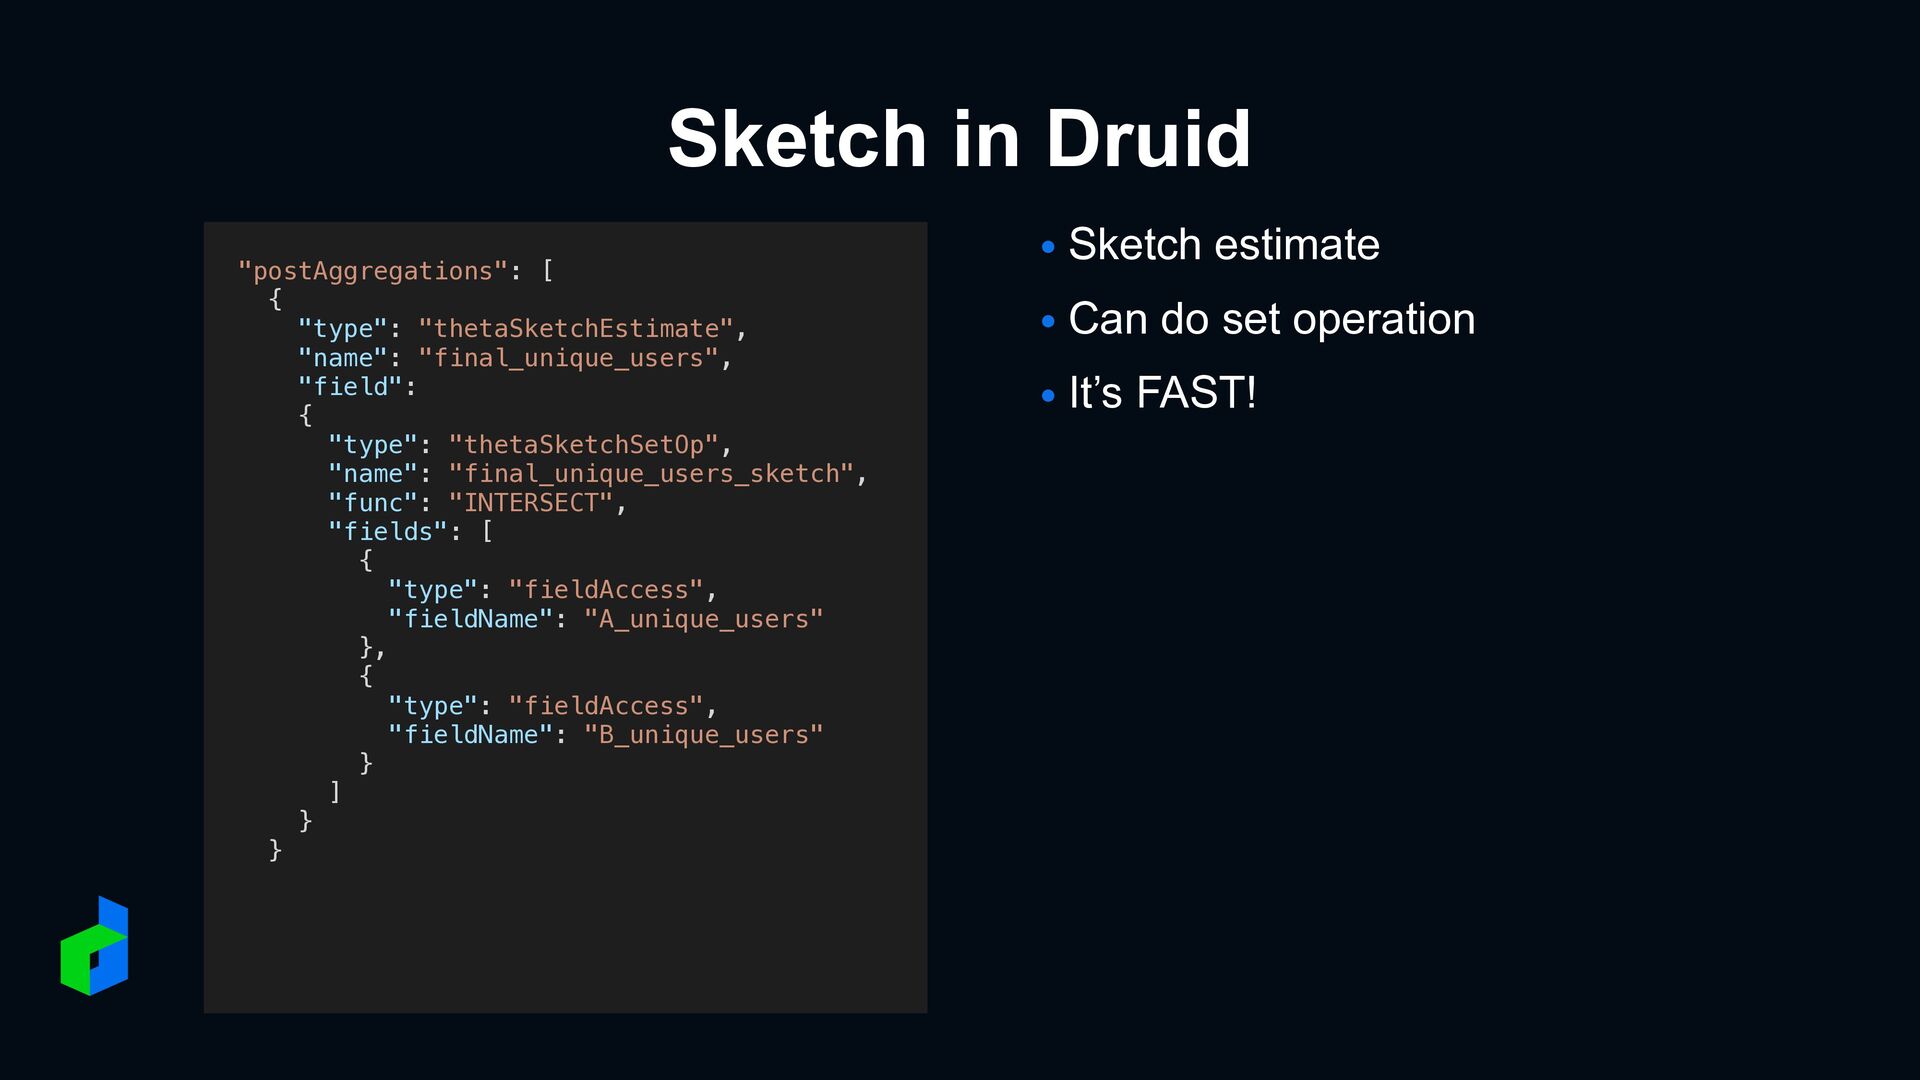
Sketch in Druid "postAggregations": [ { "type": "thetaSketchEstimate", "name": "final_unique_users",
"field": { "type": "thetaSketchSetOp", "name": "final_unique_users_sketch", "func": "INTERSECT", "fields": [ { "type": "fieldAccess", "fieldName": "A_unique_users" }, { "type": "fieldAccess", "fieldName": "B_unique_users" } ] } } • Sketch estimate • Can do set operation • It’s FAST! -
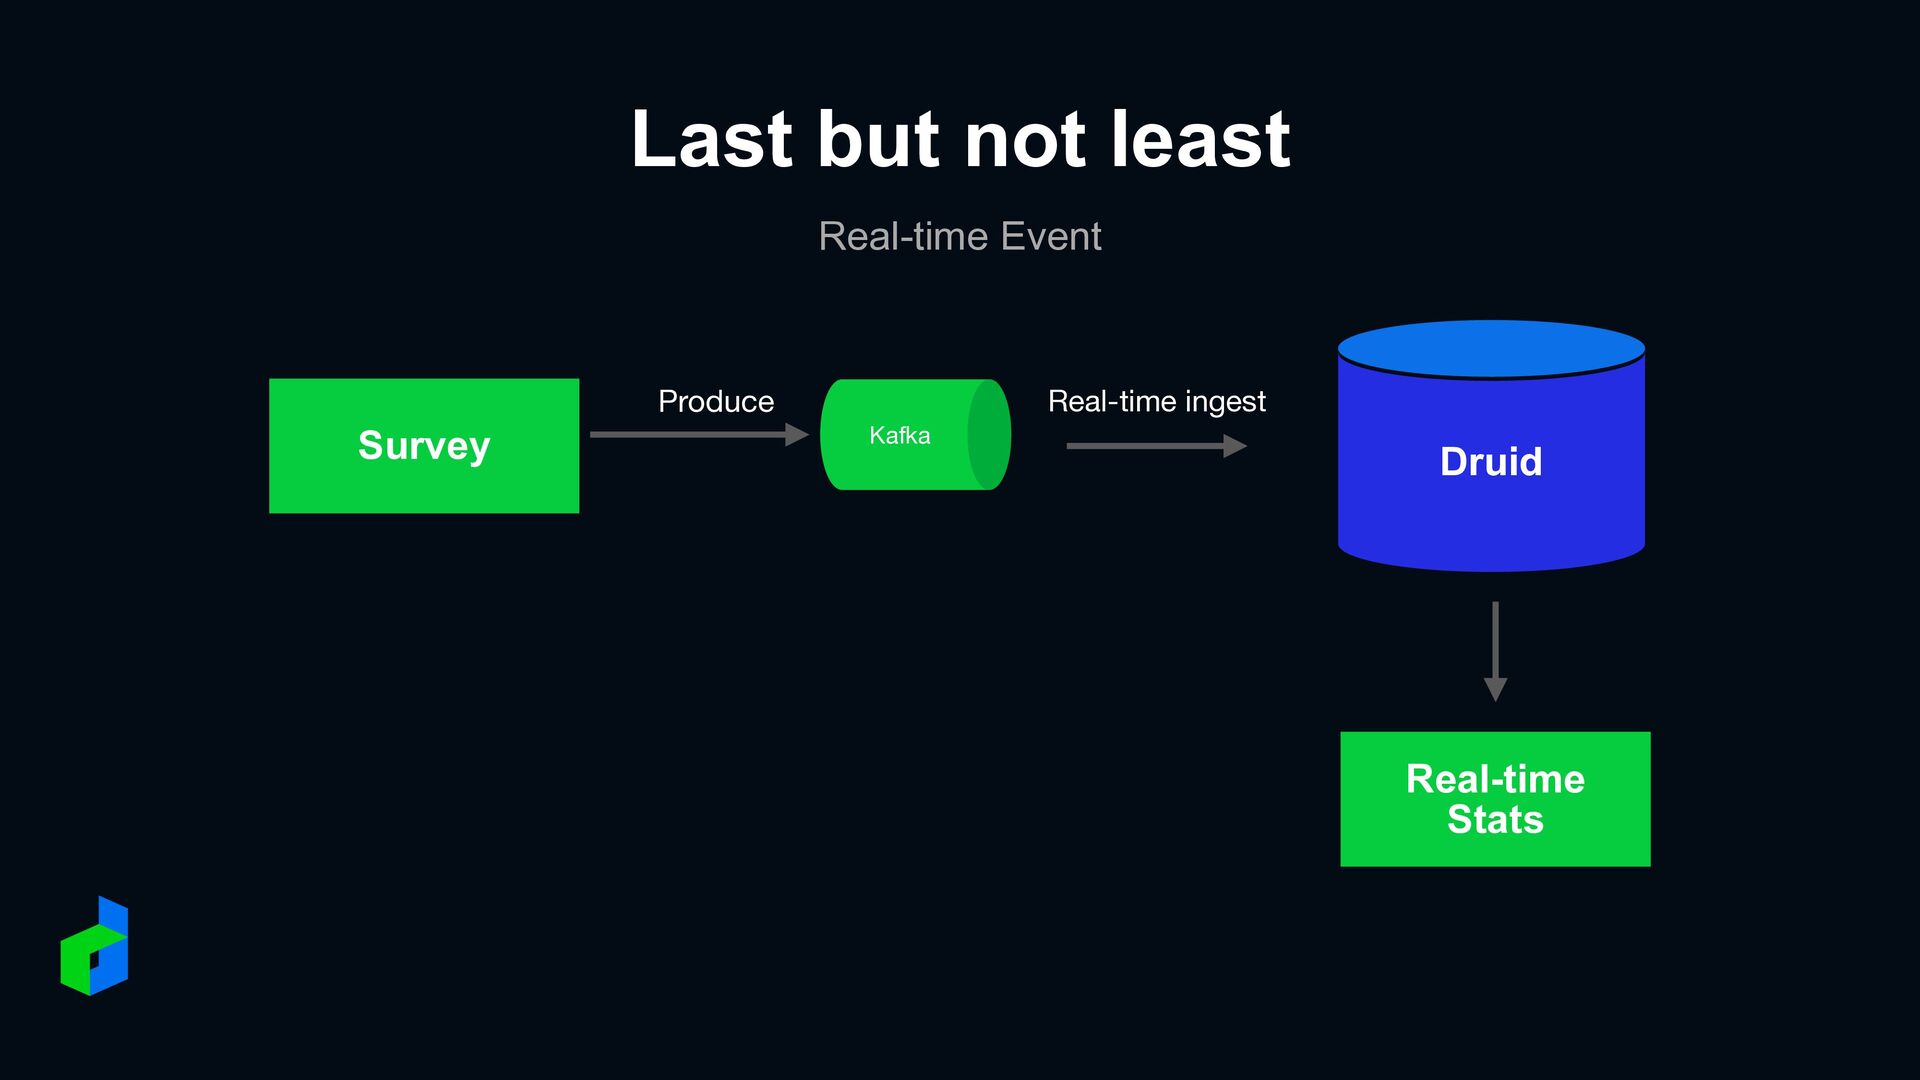
Last but not least Real-time Event Druid Produce Real-time ingest
Survey Kafka Real-time Stats -
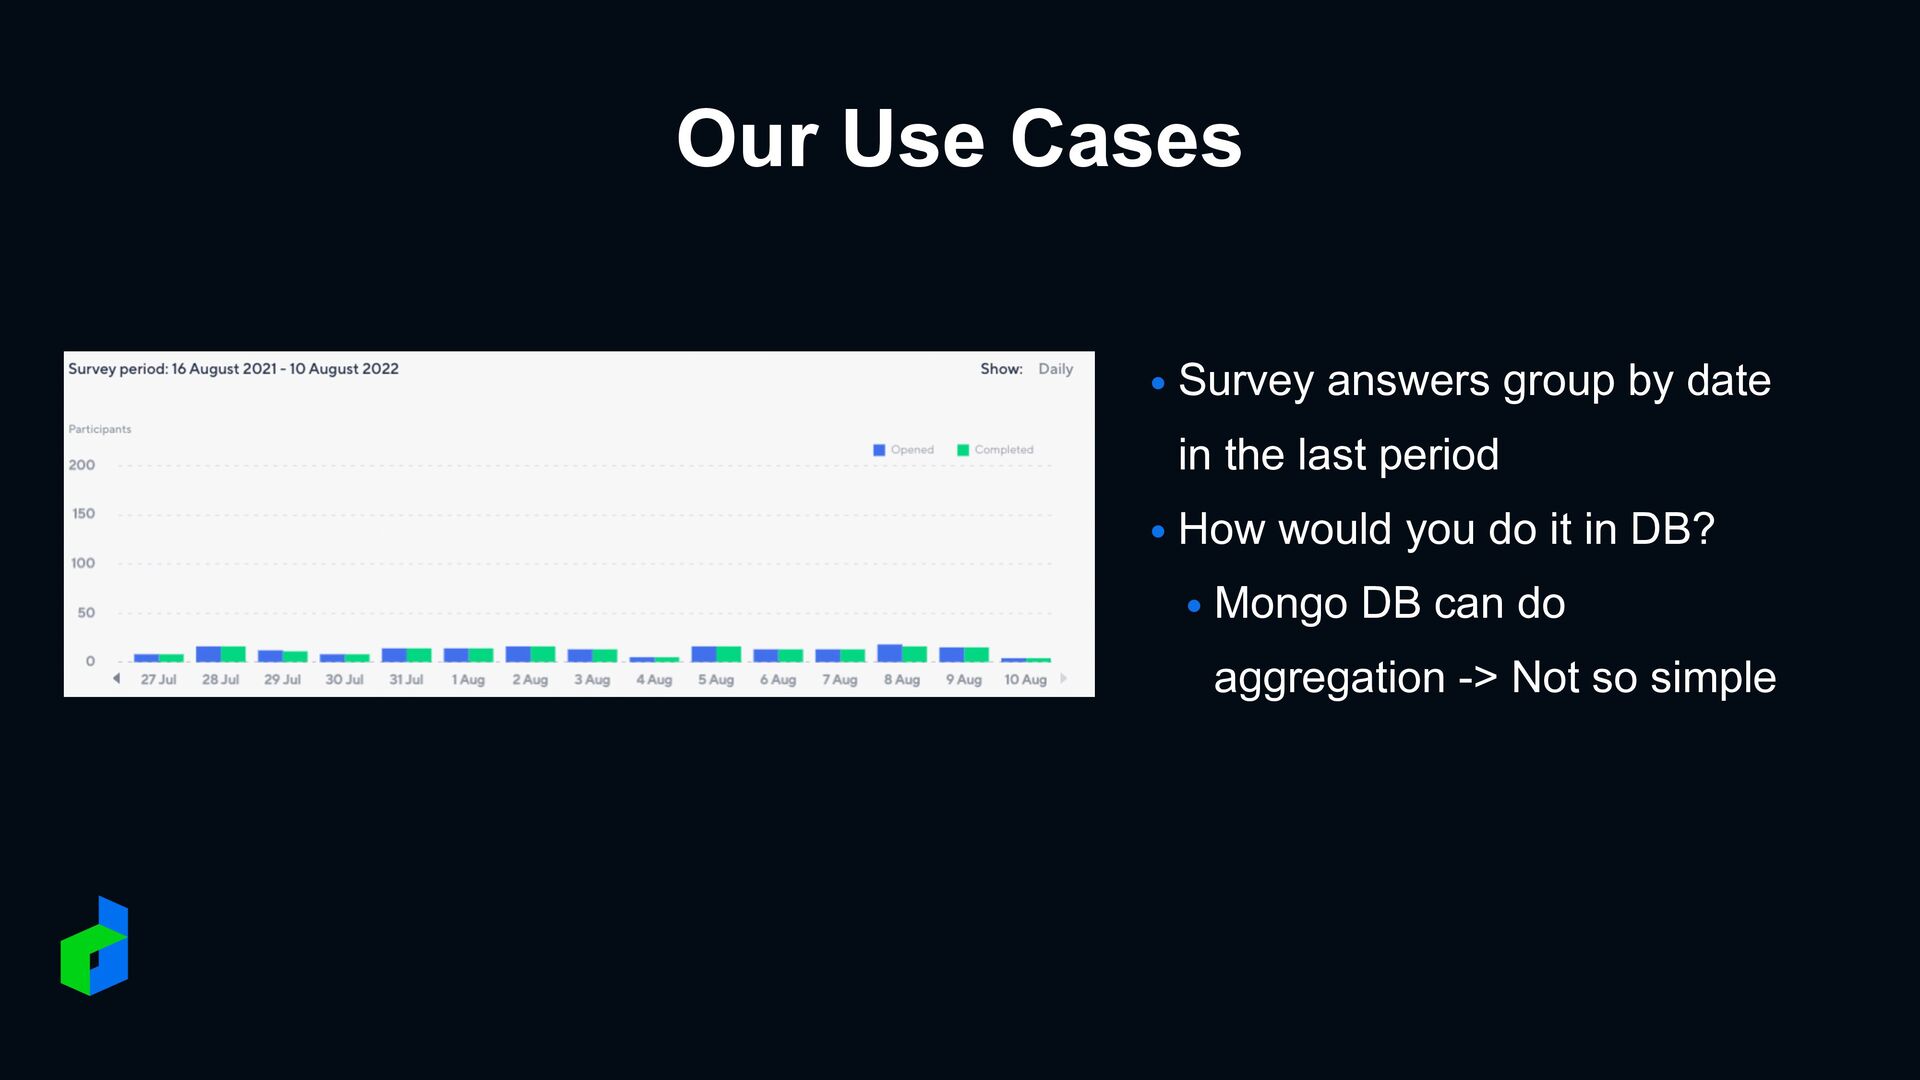
Our Use Cases • Survey answers group by date in
the last period • How would you do it in DB? • Mongo DB can do aggregation -> Not so simple -
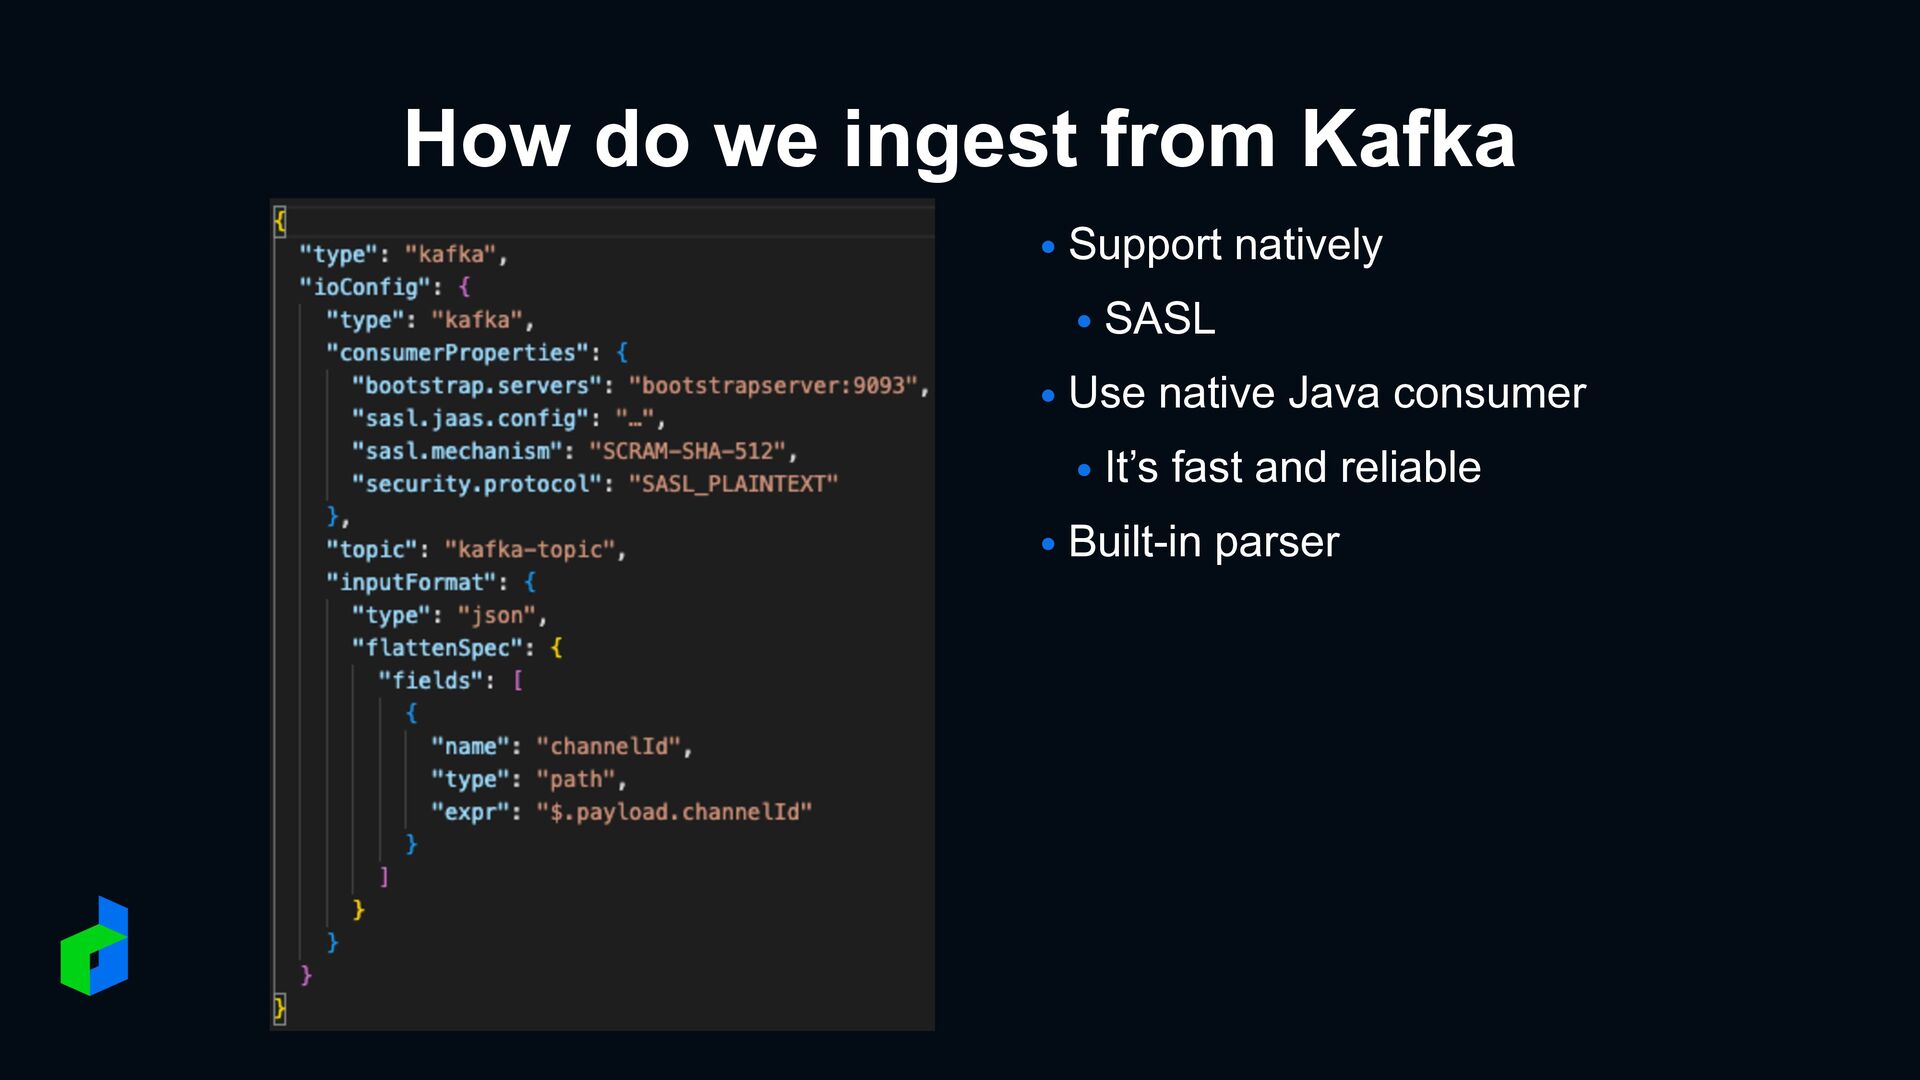
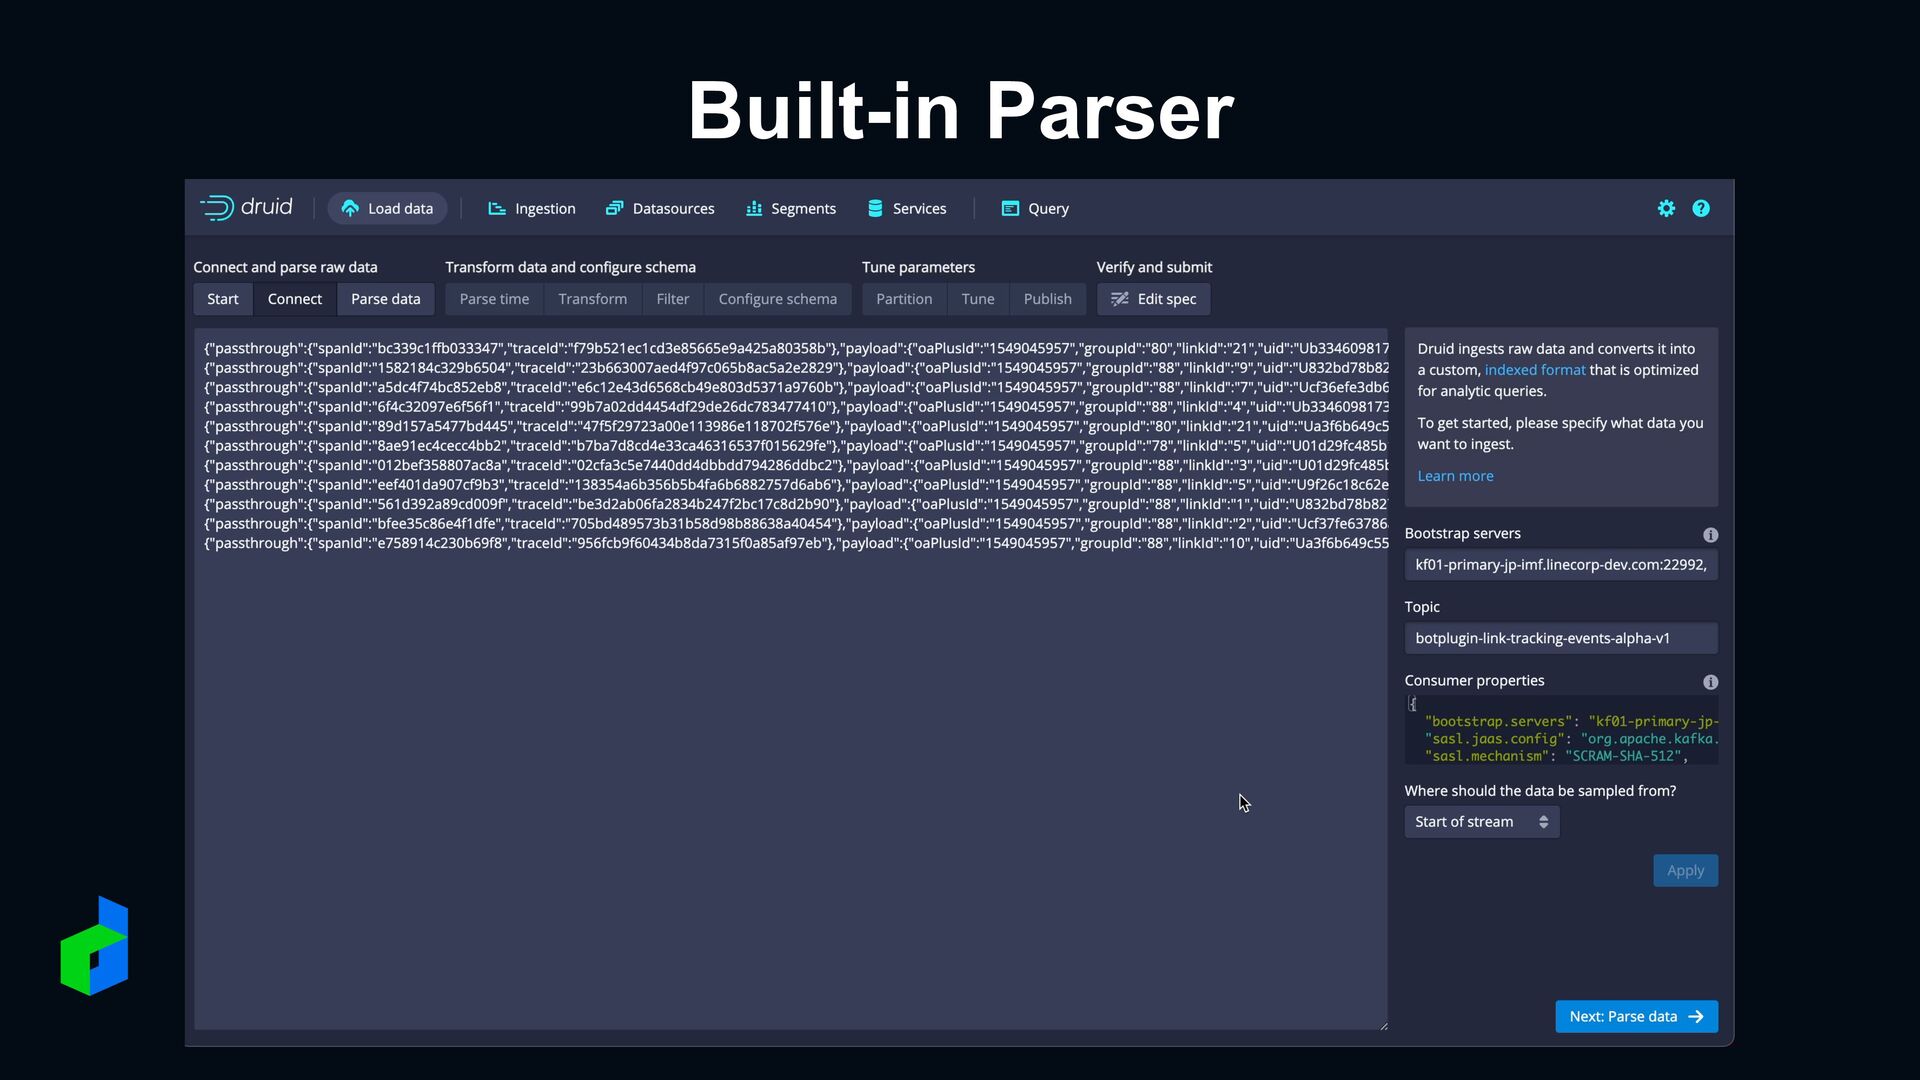
How do we ingest from Kafka • Support natively •
SASL • Use native Java consumer • It’s fast and reliable • Built-in parser -
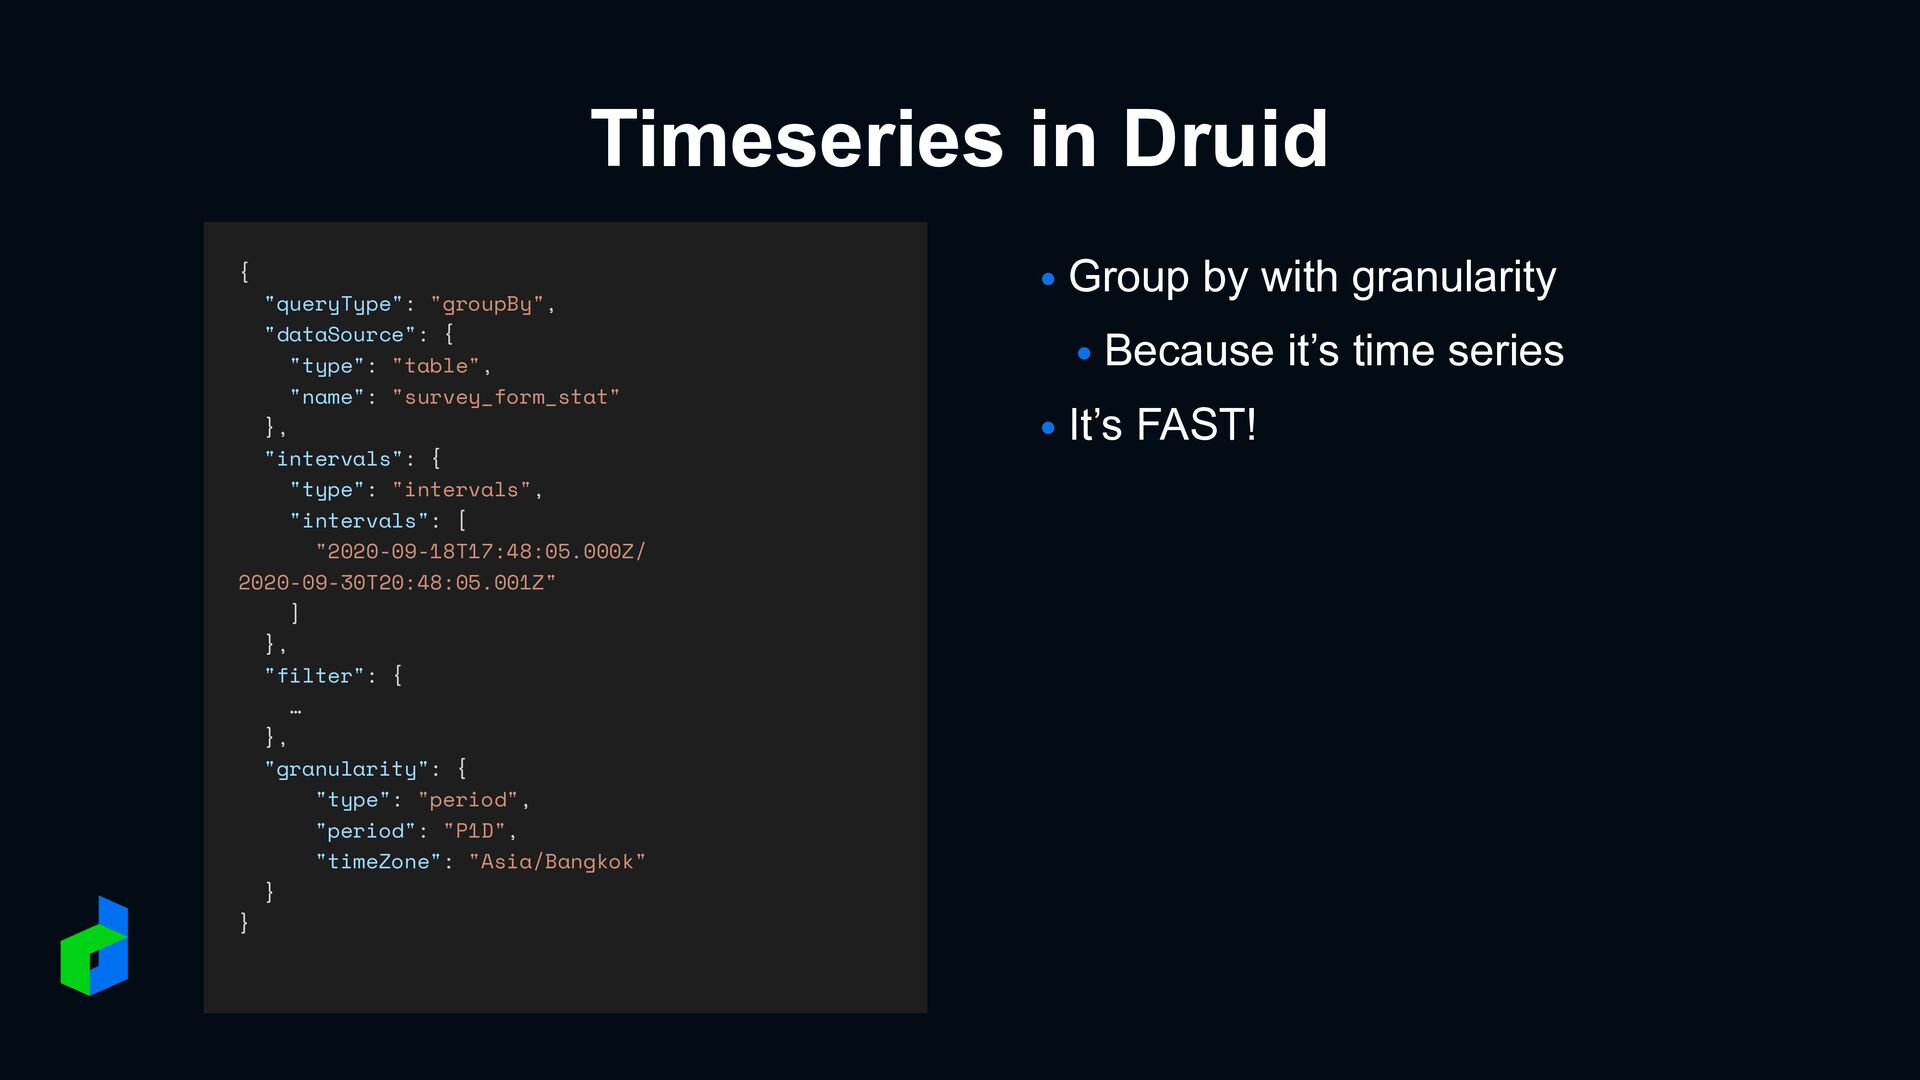
Timeseries in Druid { "queryType": "groupBy", "dataSource": { "type": "table",
"name": "survey_form_stat" }, "intervals": { "type": "intervals", "intervals": [ "2020-09-18T17:48:05.000Z/ 2020-09-30T20:48:05.001Z" ] }, "filter": { … }, "granularity": { "type": "period", "period": "P1D", "timeZone": "Asia/Bangkok" } } • Group by with granularity • Because it’s time series • It’s FAST! -
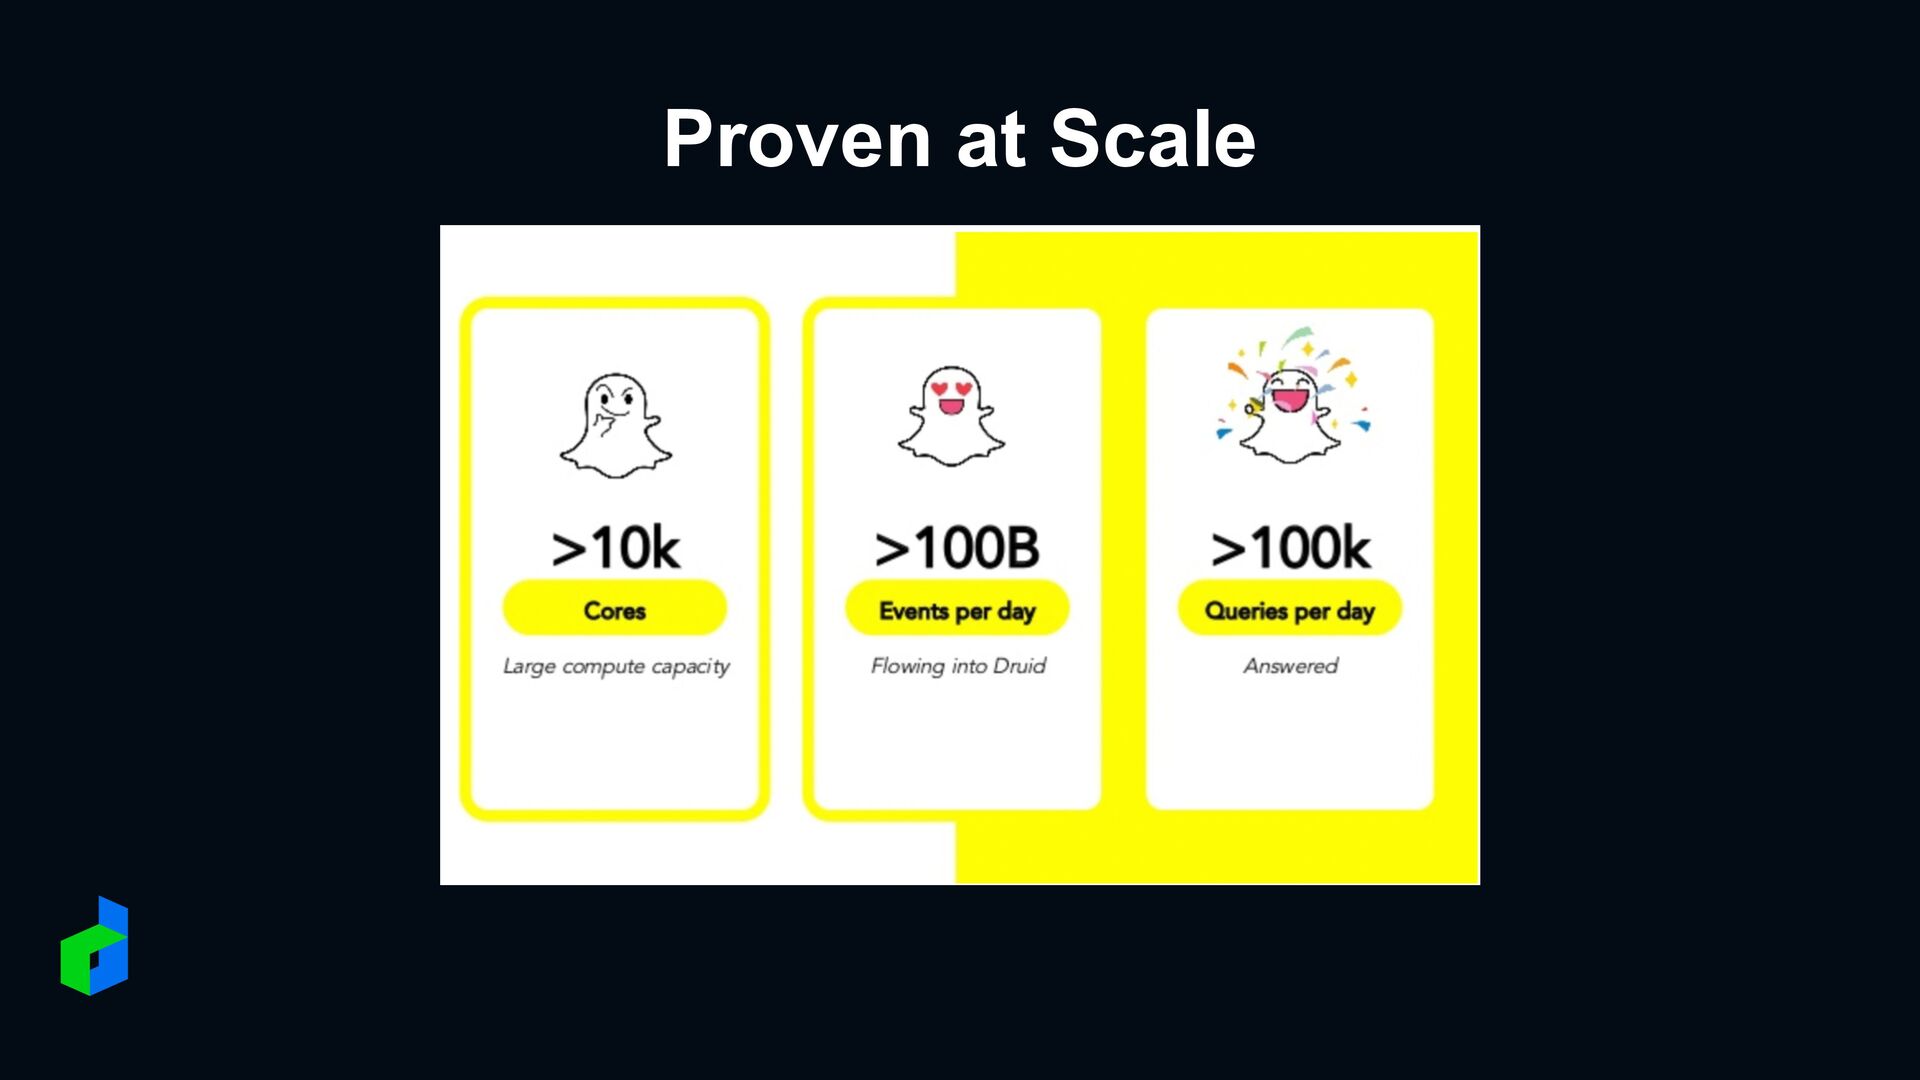
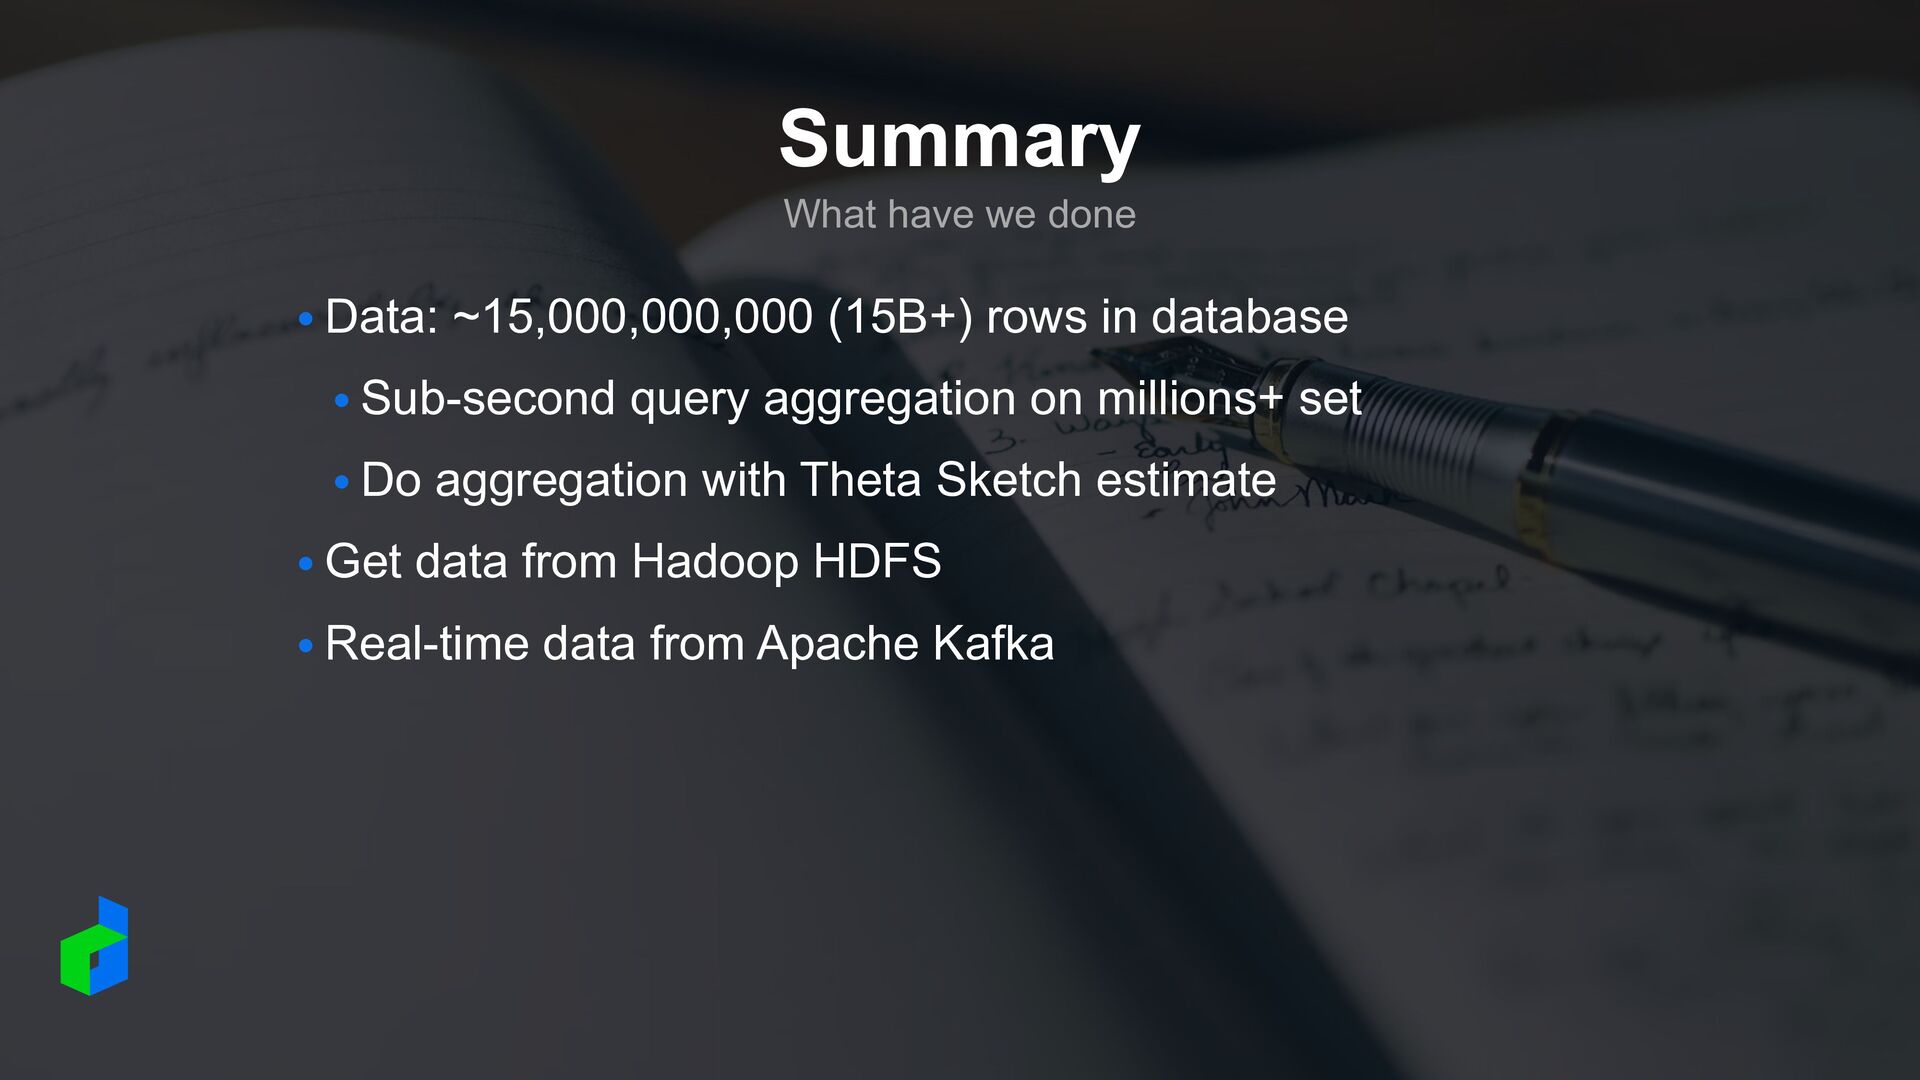
Summary What have we done • Data: ~15,000,000,000 (15B+) rows
in database • Sub-second query aggregation on millions+ set • Do aggregation with Theta Sketch estimate • Get data from Hadoop HDFS • Real-time data from Apache Kafka