STUDIES IN MECHATRONICS Predictive Maintenance and Condition Monitoring Dr. Madhuri Mahawar Department of Mechatonics Engineering Sanjivani College of Engineering, Kopargaon
and analytical models to estimate whether equipment is developing a problem and when maintenance may be required. • Instead of maintaining equipment only according to a fixed schedule, the maintenance decision uses evidence about the machine's condition. • Example: A motor's vibration level gradually increases. An ML model identifies the abnormal trend and alerts the maintenance team before a breakdown occur
cause: • Production downtime • Equipment damage • Product quality problems • High repair costs • Safety risks • Unplanned production scheduling • Predictive maintenance aims to detect developing problems early enough for maintenance to be planned.
a fault or failure occurs. • Example: Replacing a motor after it stops working. • Preventive Maintenance • Perform maintenance at fixed intervals or after a specified amount of operating time. • Example: Replacing a bearing every 2,000 operating hours. • Predictive Maintenance • Use machine-condition data and predictions to determine when maintenance may be necessary. • Example: Scheduling bearing replacement because vibration trends indicate degradation.
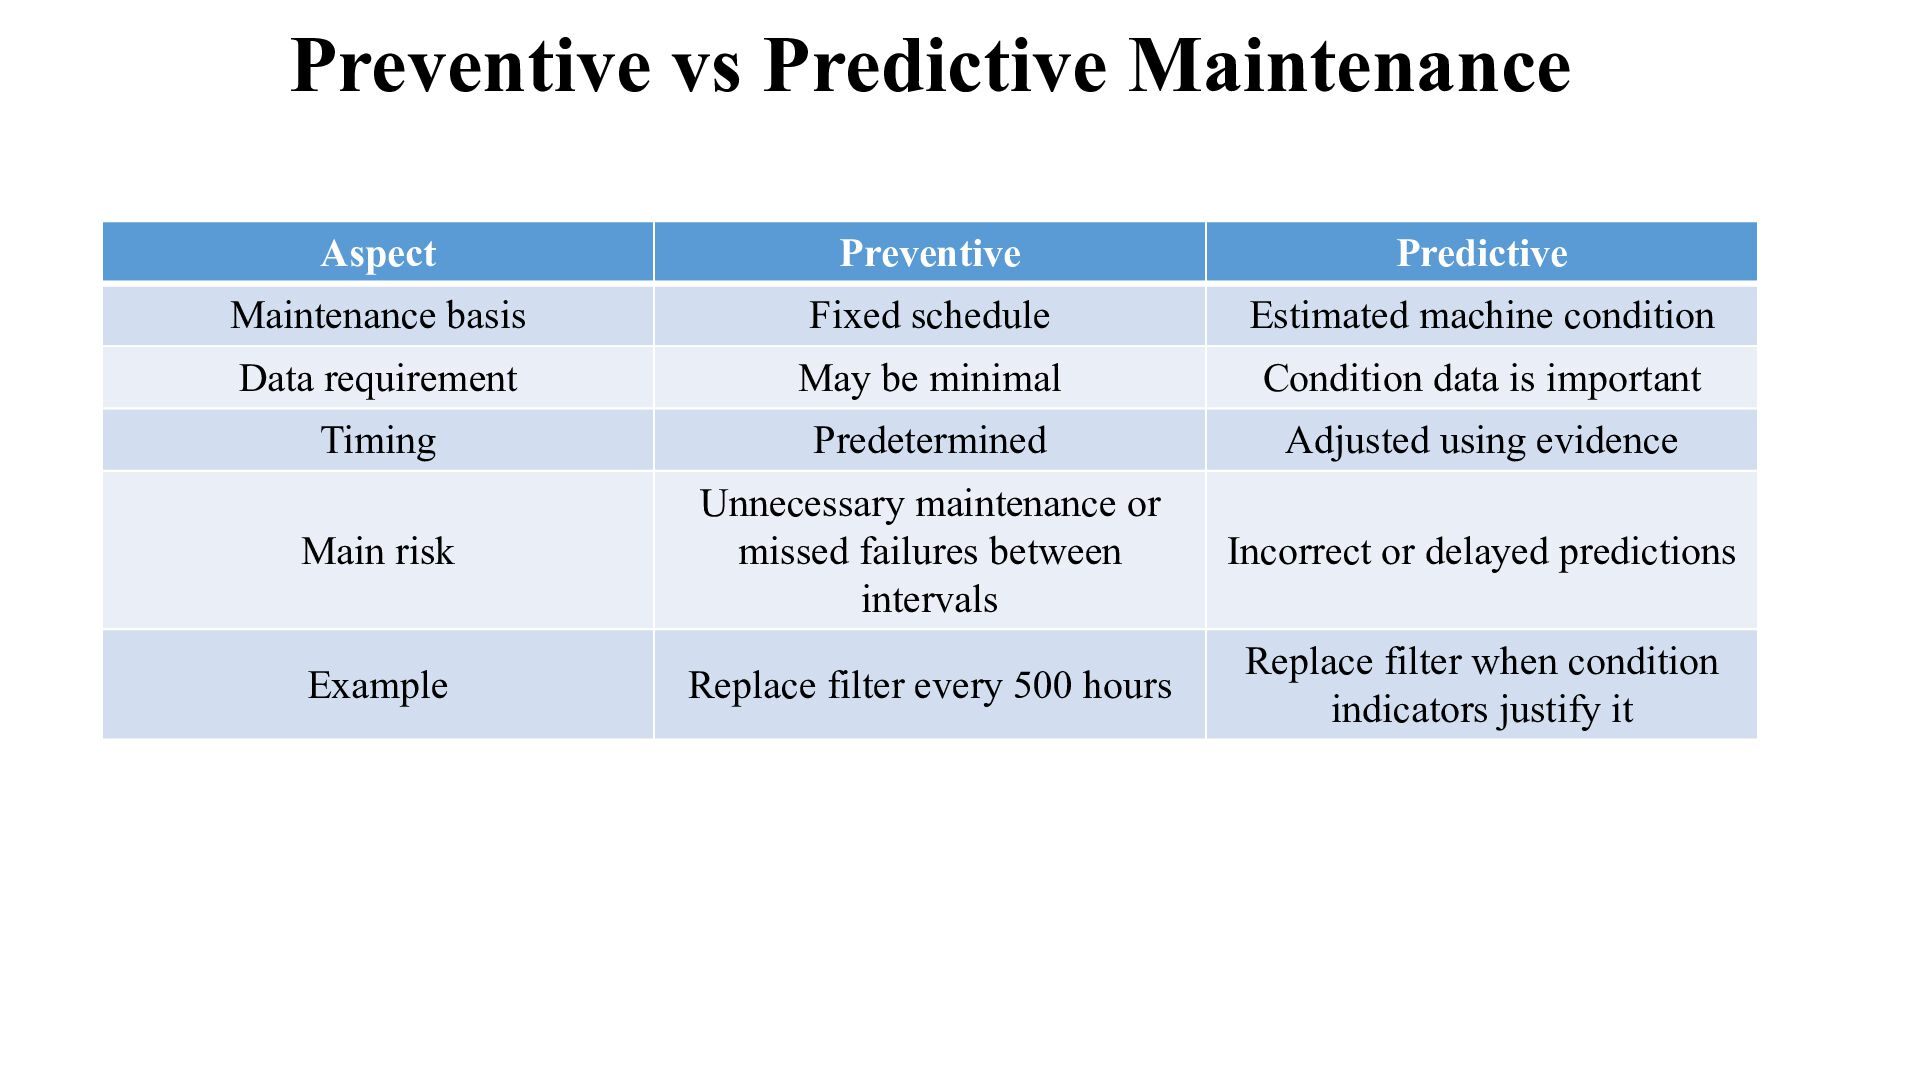
schedule Estimated machine condition Data requirement May be minimal Condition data is important Timing Predetermined Adjusted using evidence Main risk Unnecessary maintenance or missed failures between intervals Incorrect or delayed predictions Example Replace filter every 500 hours Replace filter when condition indicators justify it
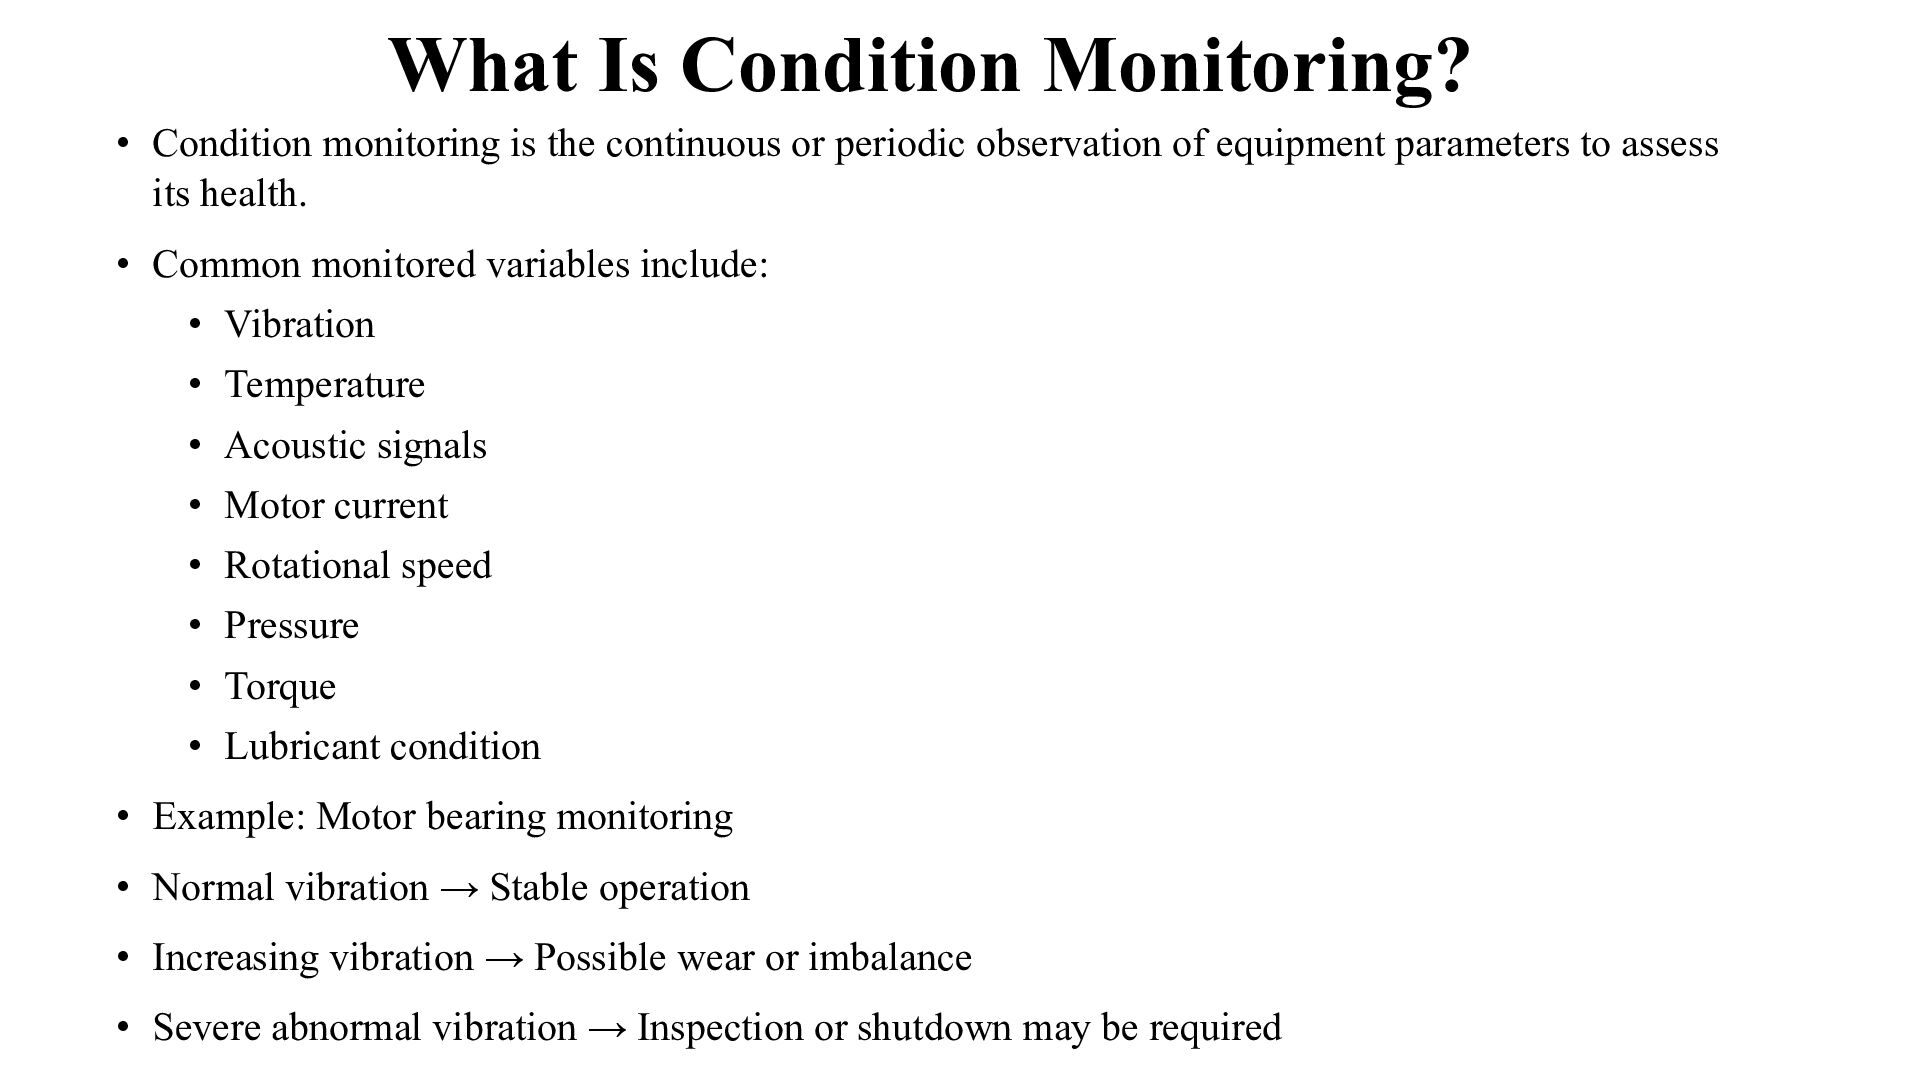
or periodic observation of equipment parameters to assess its health. • Common monitored variables include: • Vibration • Temperature • Acoustic signals • Motor current • Rotational speed • Pressure • Torque • Lubricant condition • Example: Motor bearing monitoring • Normal vibration → Stable operation • Increasing vibration → Possible wear or imbalance • Severe abnormal vibration → Inspection or shutdown may be required
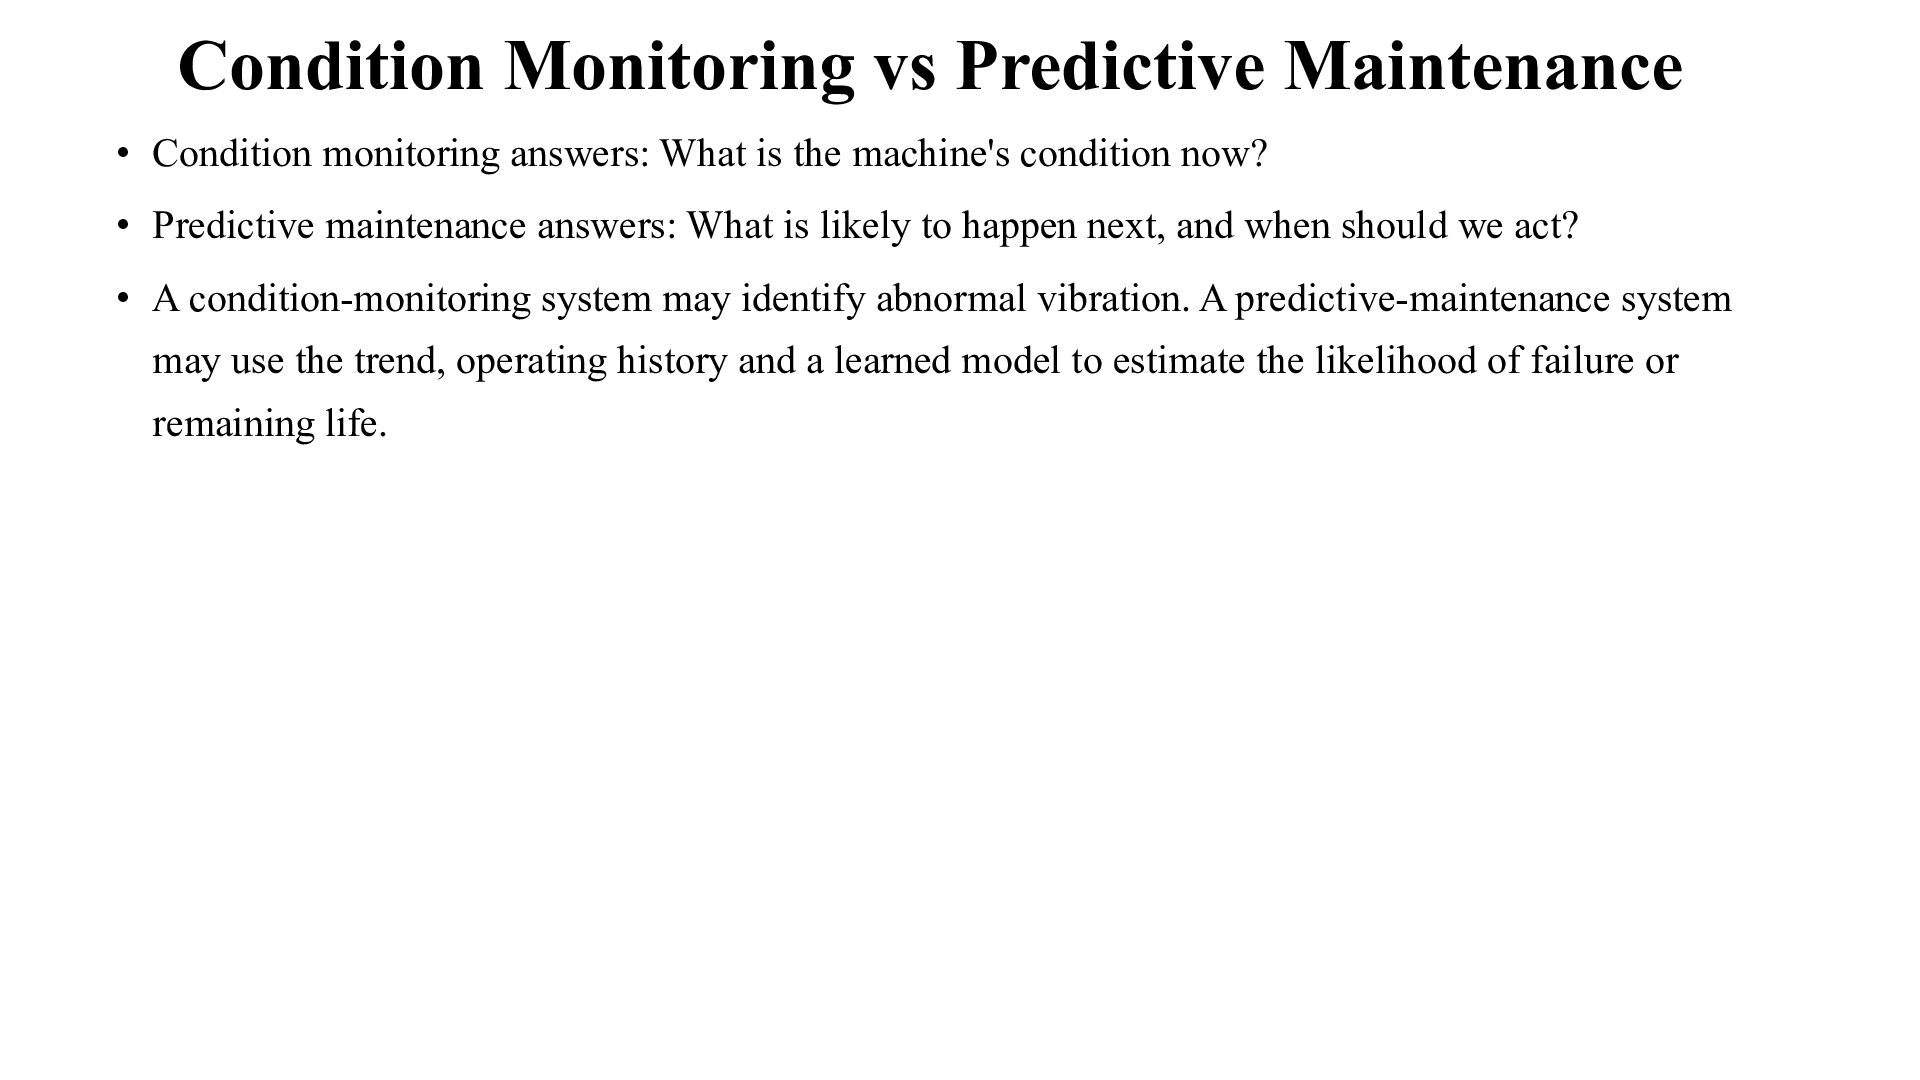
is the machine's condition now? • Predictive maintenance answers: What is likely to happen next, and when should we act? • A condition-monitoring system may identify abnormal vibration. A predictive-maintenance system may use the trend, operating history and a learned model to estimate the likelihood of failure or remaining life.
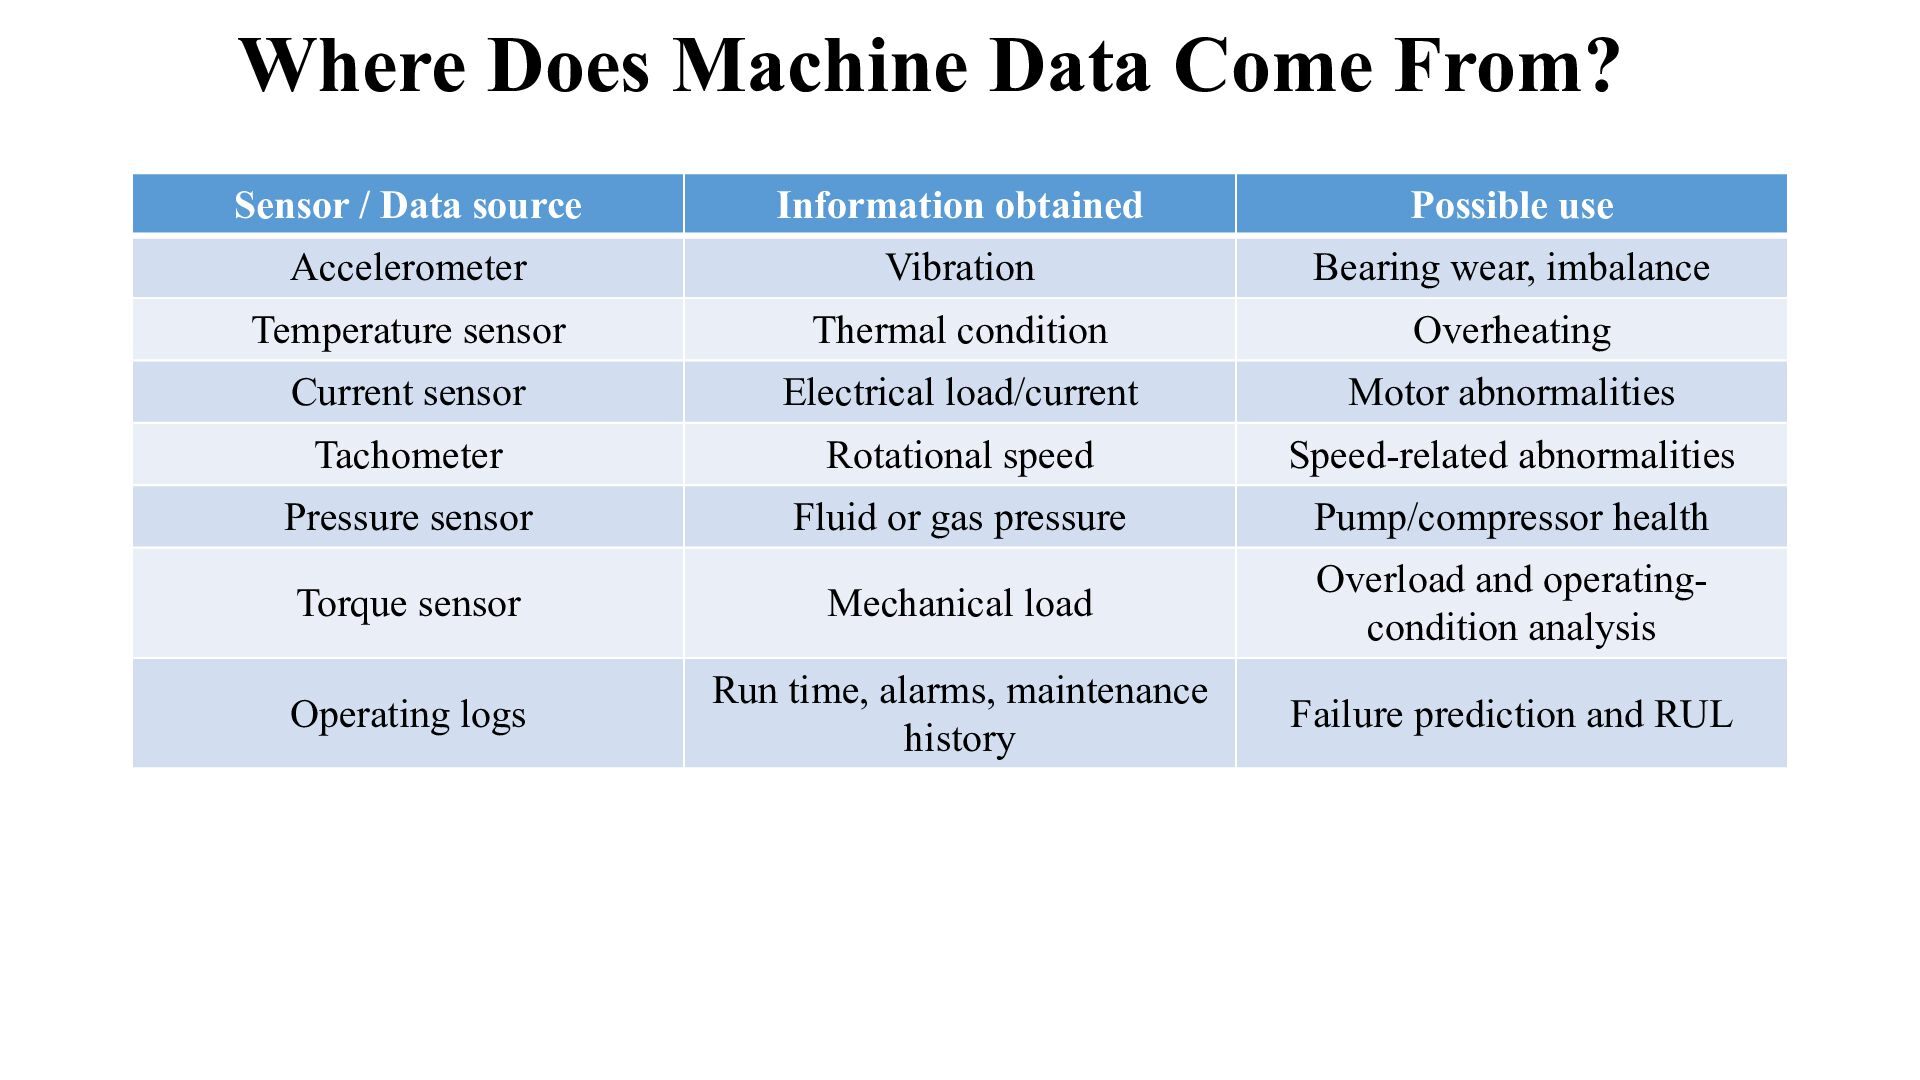
Information obtained Possible use Accelerometer Vibration Bearing wear, imbalance Temperature sensor Thermal condition Overheating Current sensor Electrical load/current Motor abnormalities Tachometer Rotational speed Speed-related abnormalities Pressure sensor Fluid or gas pressure Pump/compressor health Torque sensor Mechanical load Overload and operatingcondition analysis Operating logs Run time, alarms, maintenance history Failure prediction and RUL
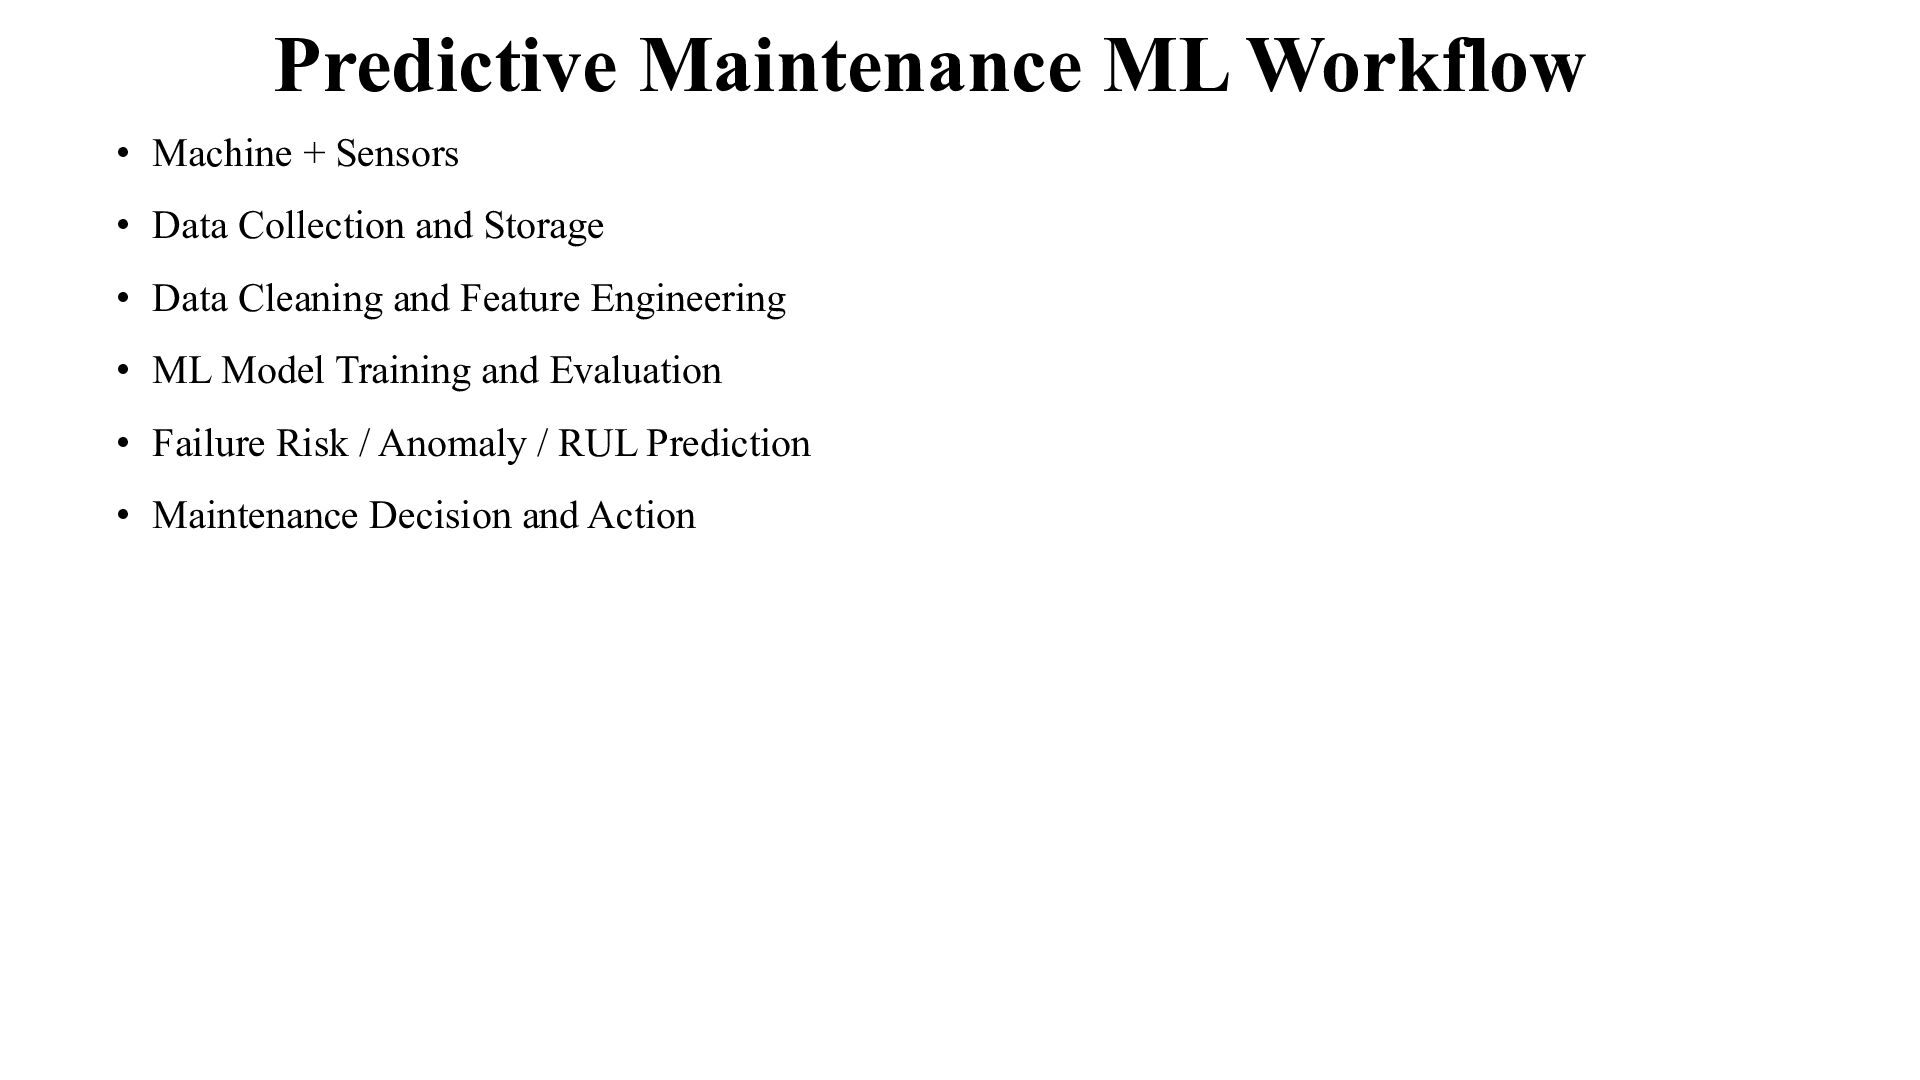
Collection and Storage • Data Cleaning and Feature Engineering • ML Model Training and Evaluation • Failure Risk / Anomaly / RUL Prediction • Maintenance Decision and Action
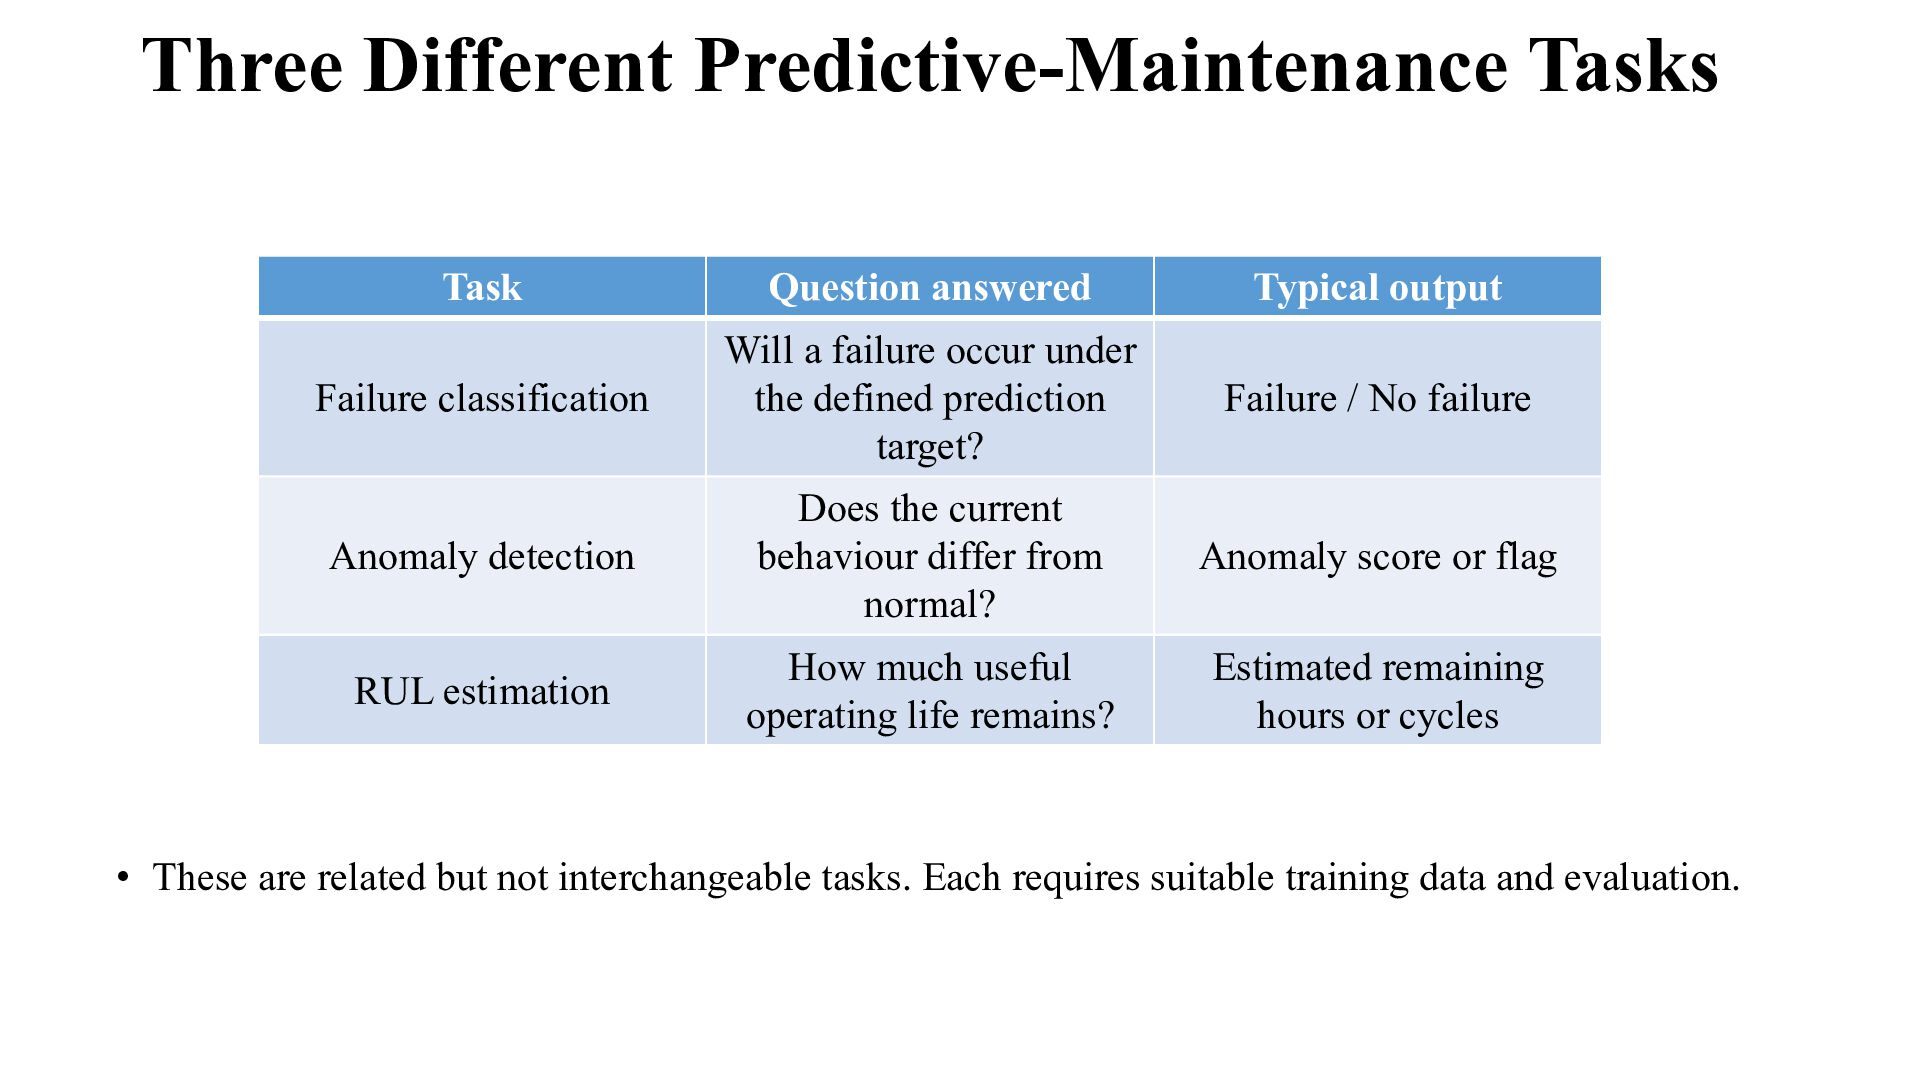
classification Will a failure occur under the defined prediction target? Failure / No failure Anomaly detection Does the current behaviour differ from normal? Anomaly score or flag RUL estimation How much useful operating life remains? Estimated remaining hours or cycles • These are related but not interchangeable tasks. Each requires suitable training data and evaluation.
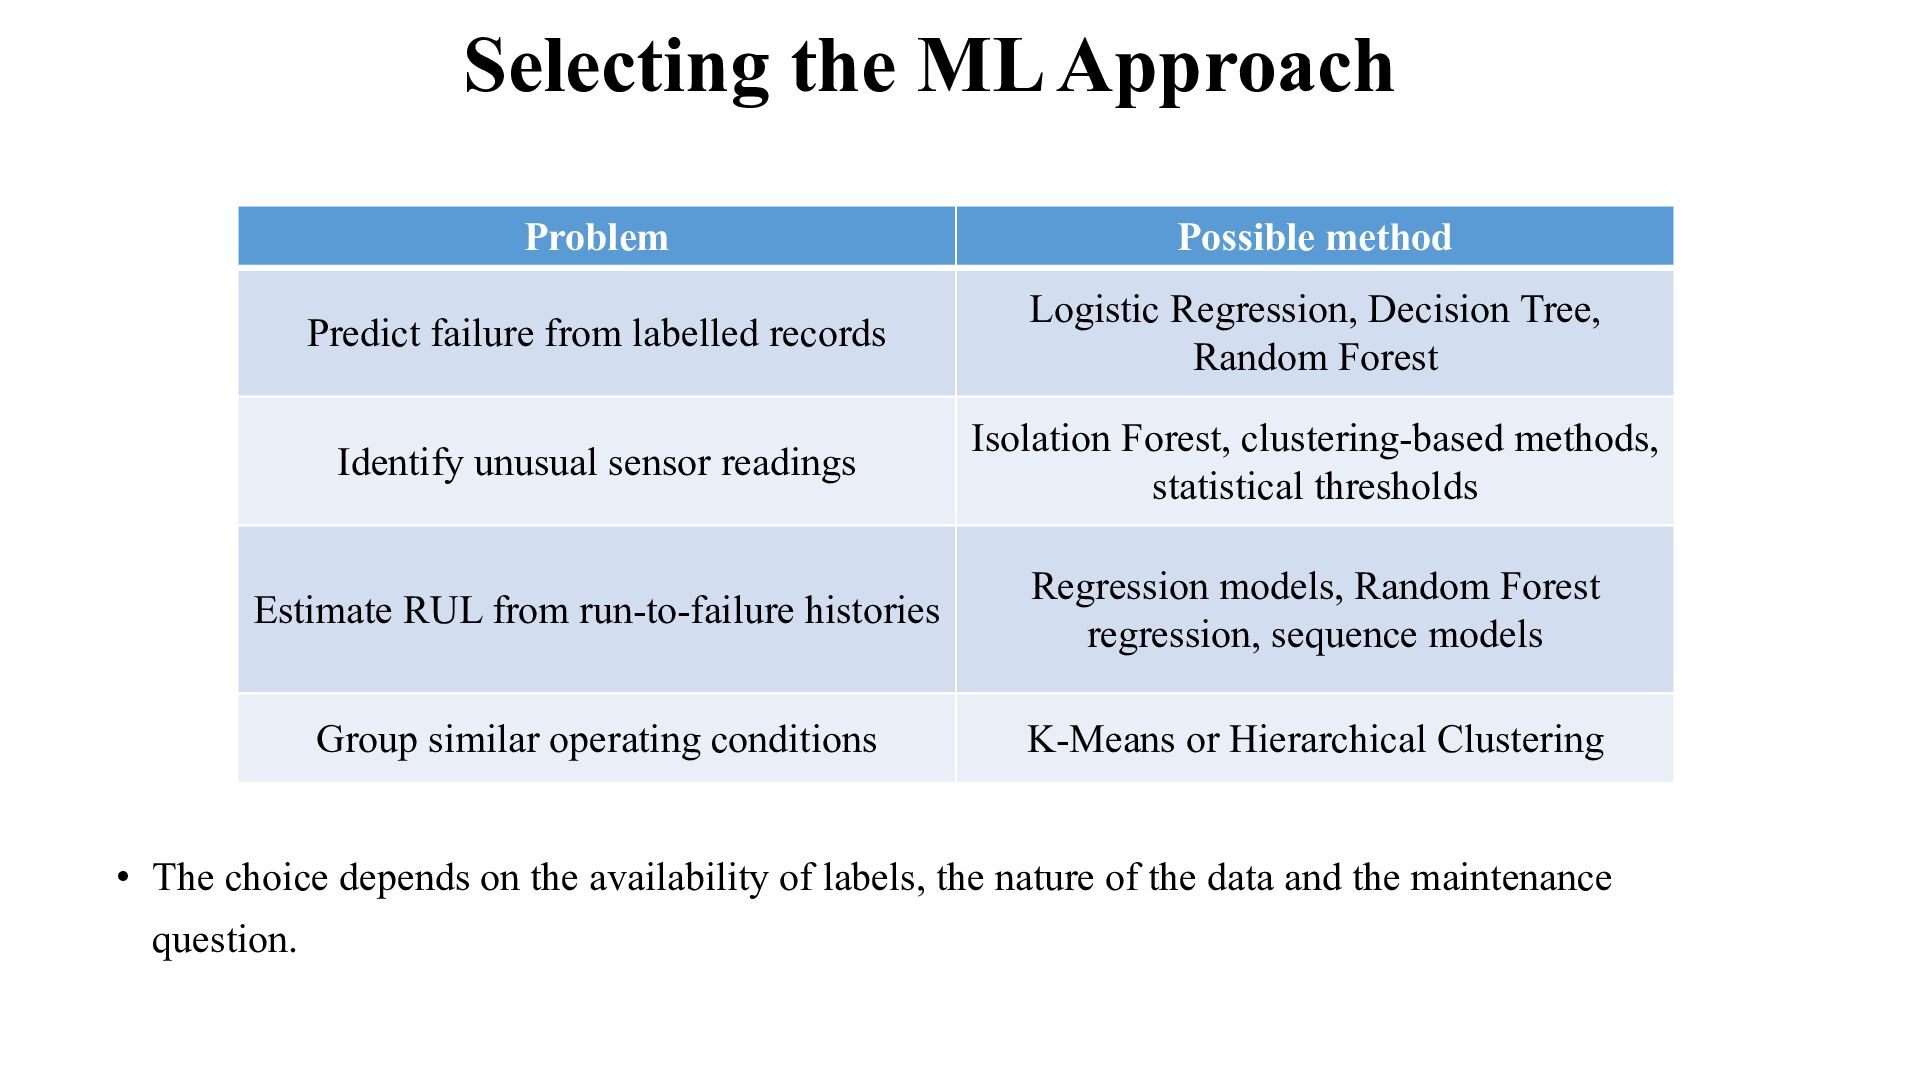
labelled records Logistic Regression, Decision Tree, Random Forest Identify unusual sensor readings Isolation Forest, clustering-based methods, statistical thresholds Estimate RUL from run-to-failure histories Regression models, Random Forest regression, sequence models Group similar operating conditions K-Means or Hierarchical Clustering • The choice depends on the availability of labels, the nature of the data and the maintenance question.
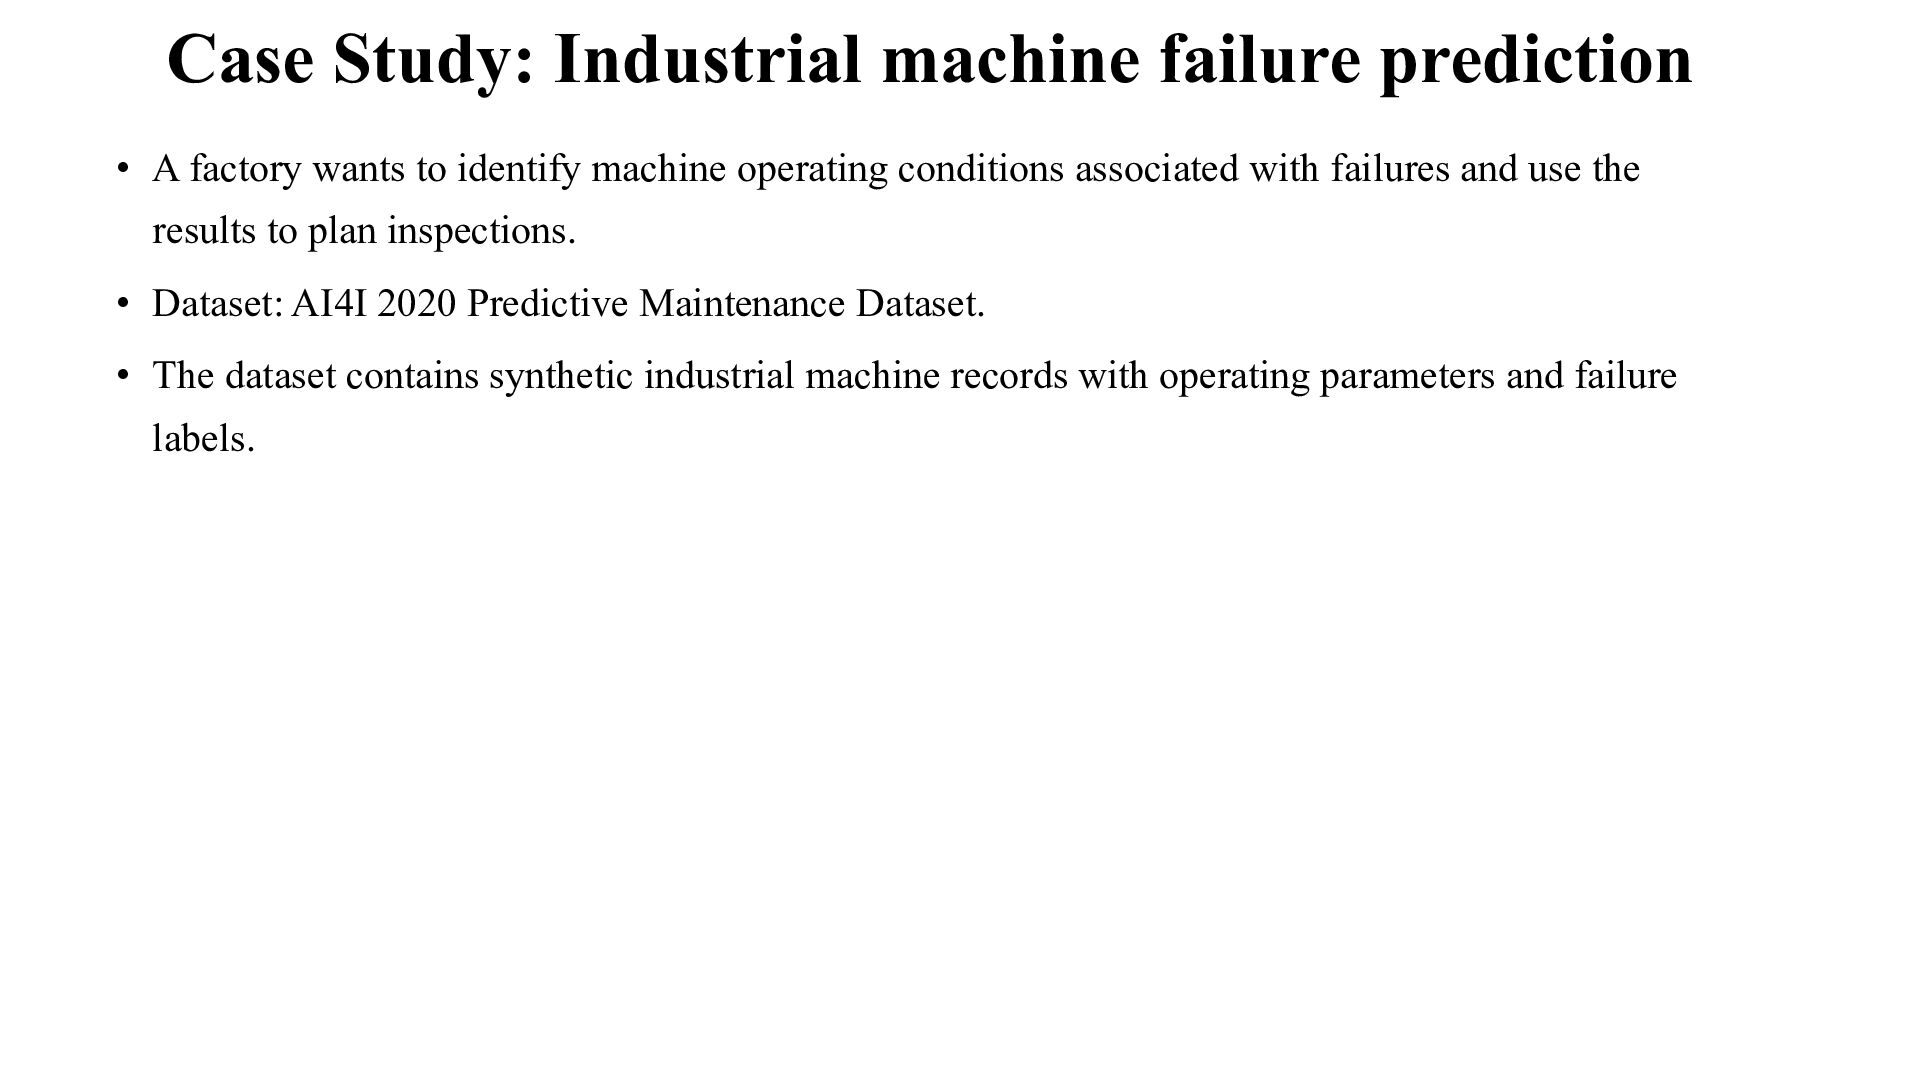
to identify machine operating conditions associated with failures and use the results to plan inspections. • Dataset: AI4I 2020 Predictive Maintenance Dataset. • The dataset contains synthetic industrial machine records with operating parameters and failure labels.
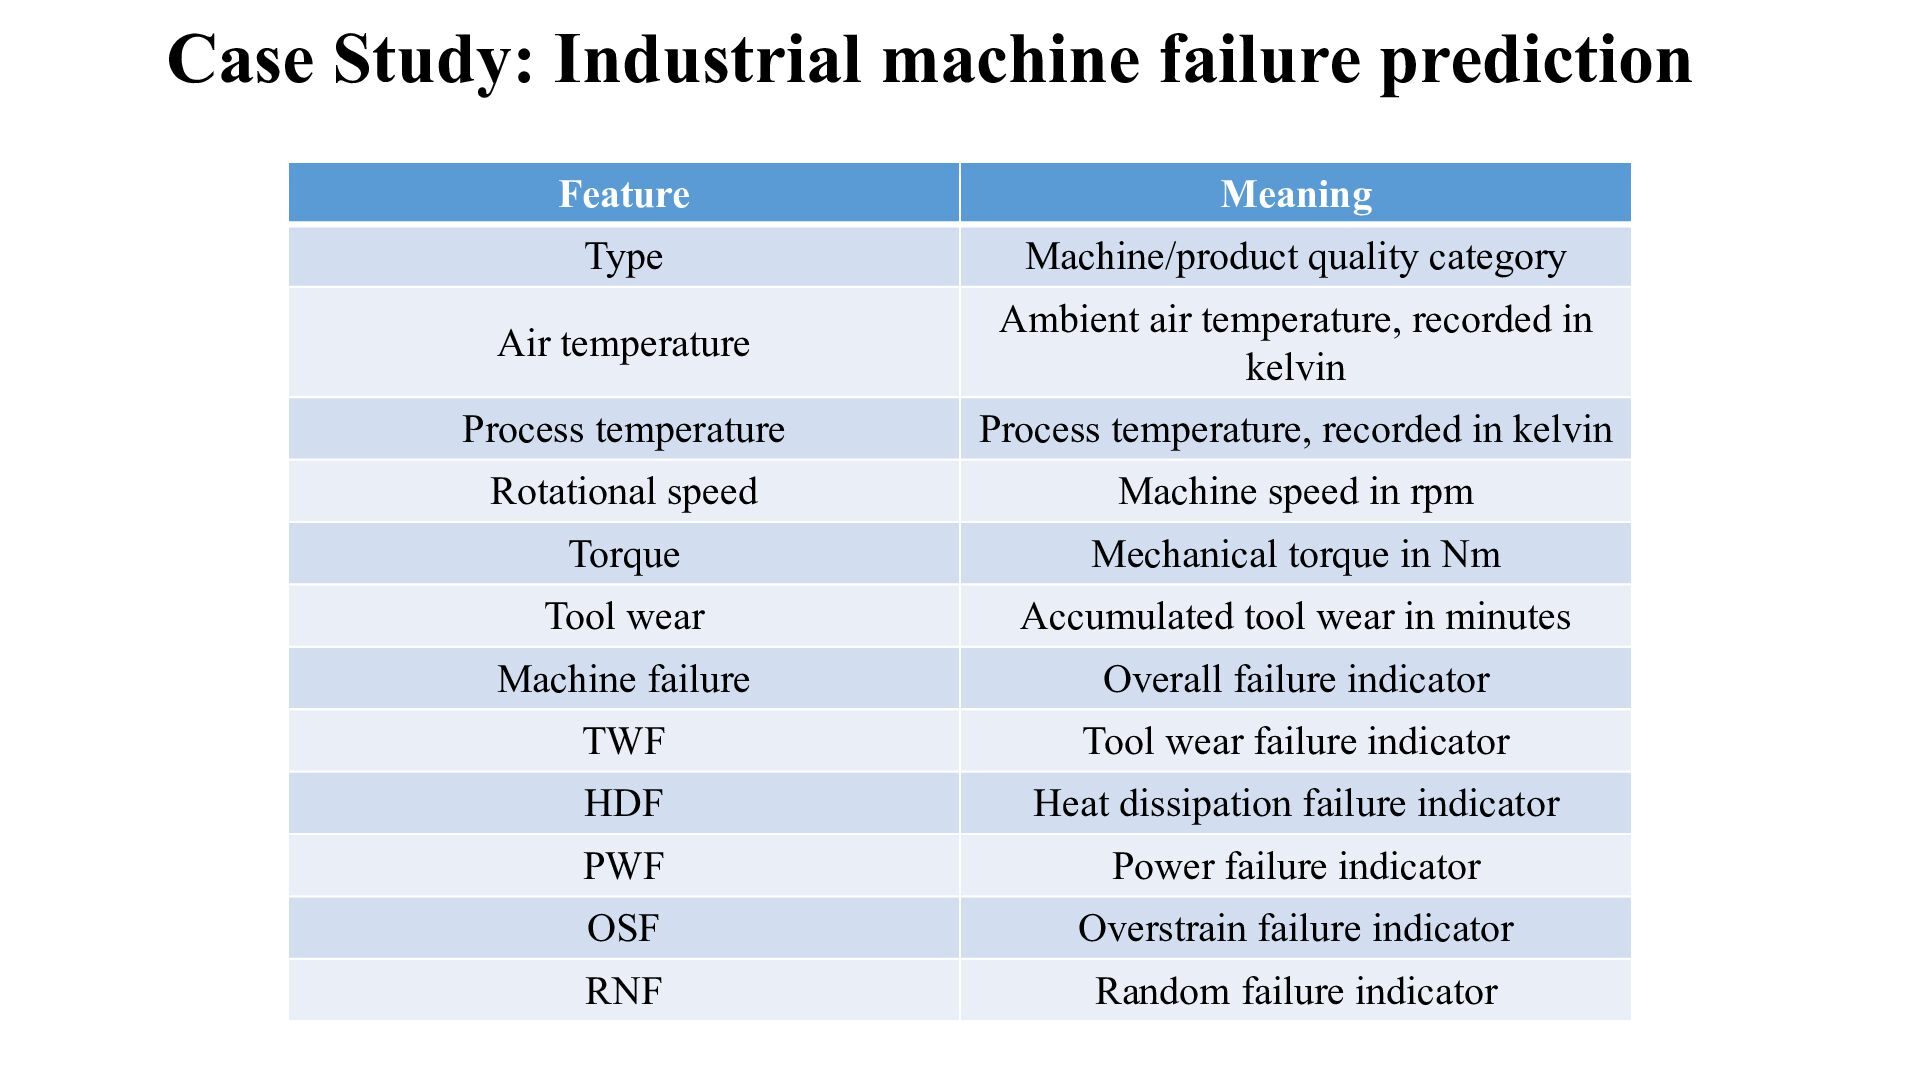
quality category Air temperature Ambient air temperature, recorded in kelvin Process temperature Process temperature, recorded in kelvin Rotational speed Machine speed in rpm Torque Mechanical torque in Nm Tool wear Accumulated tool wear in minutes Machine failure Overall failure indicator TWF Tool wear failure indicator HDF Heat dissipation failure indicator PWF Power failure indicator OSF Overstrain failure indicator RNF Random failure indicator
records associated with machine failure so that maintenance teams can investigate risky conditions. • ML formulation • Input: • Target: • Task: • Output: • Question: Can the model identify patterns associated with failure before a breakdown occurs?
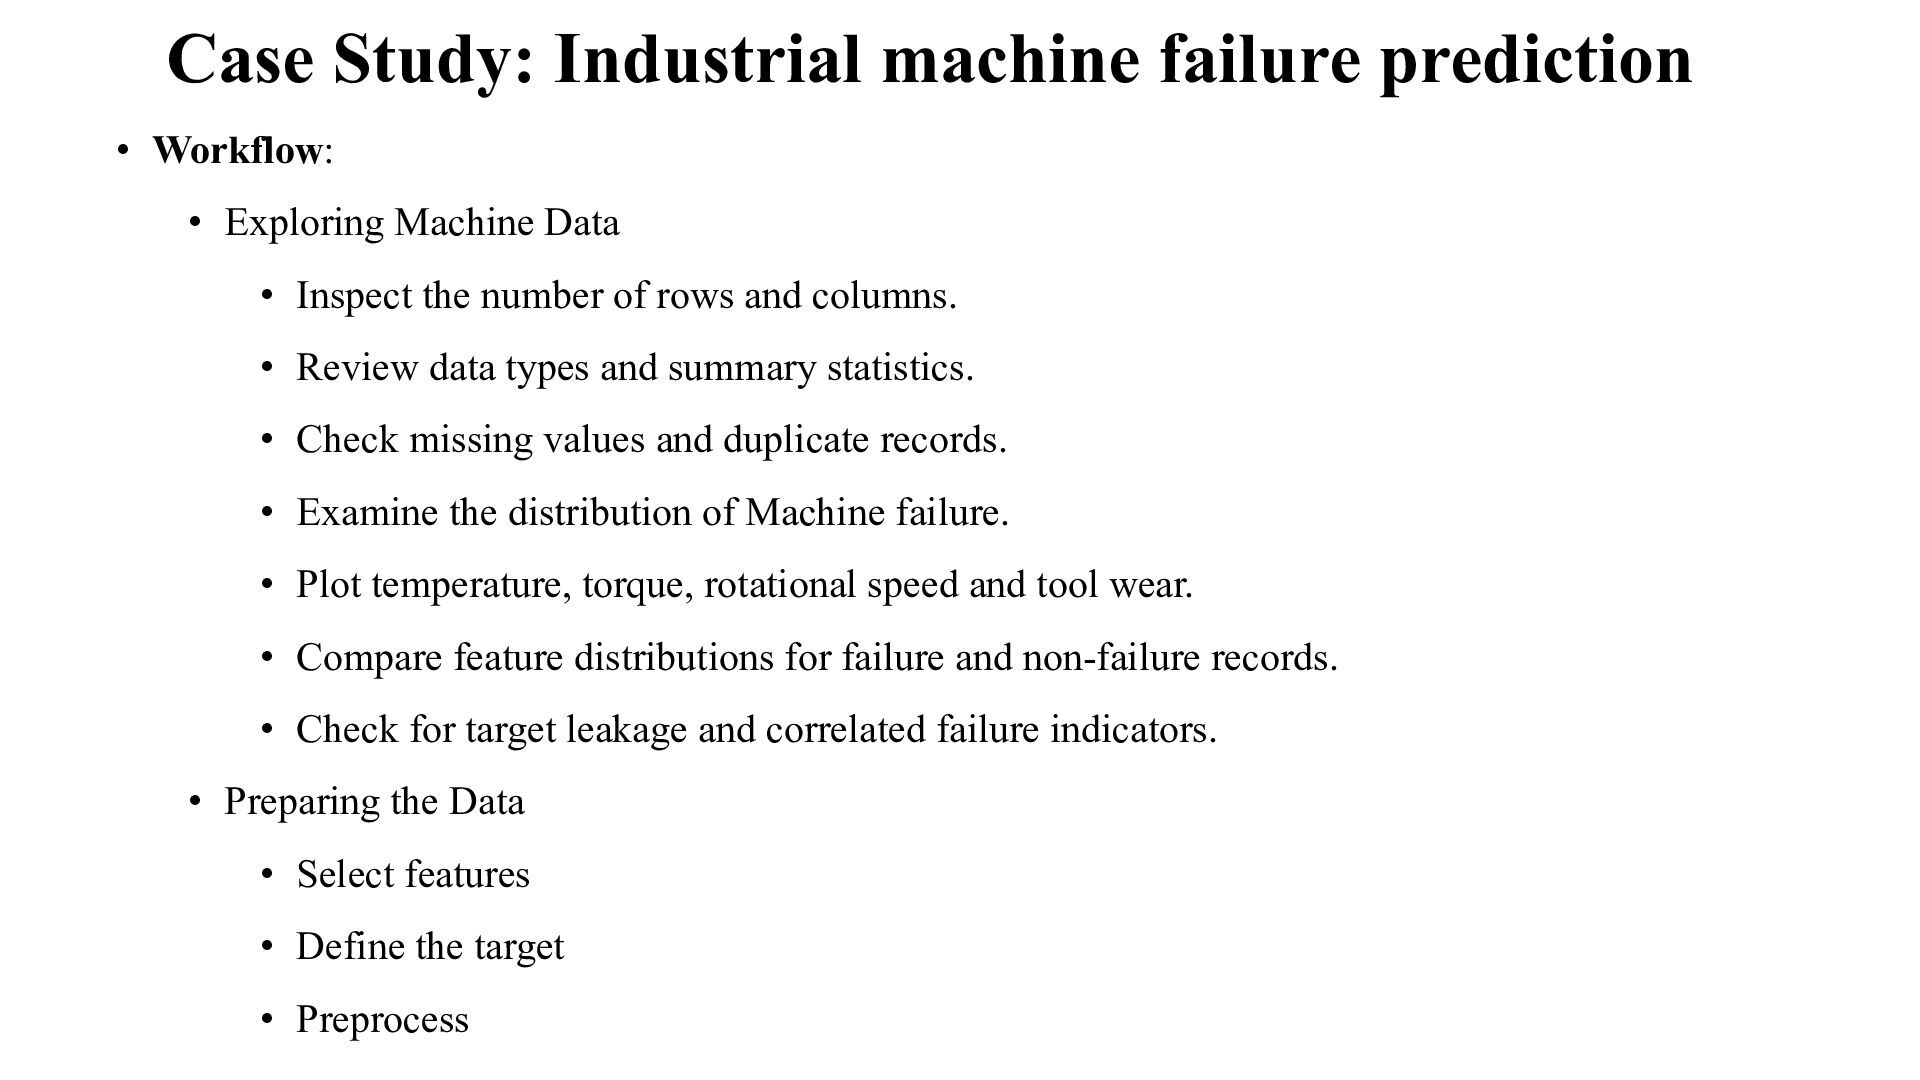
Machine Data • Inspect the number of rows and columns. • Review data types and summary statistics. • Check missing values and duplicate records. • Examine the distribution of Machine failure. • Plot temperature, torque, rotational speed and tool wear. • Compare feature distributions for failure and non-failure records. • Check for target leakage and correlated failure indicators. • Preparing the Data • Select features • Define the target • Preprocess
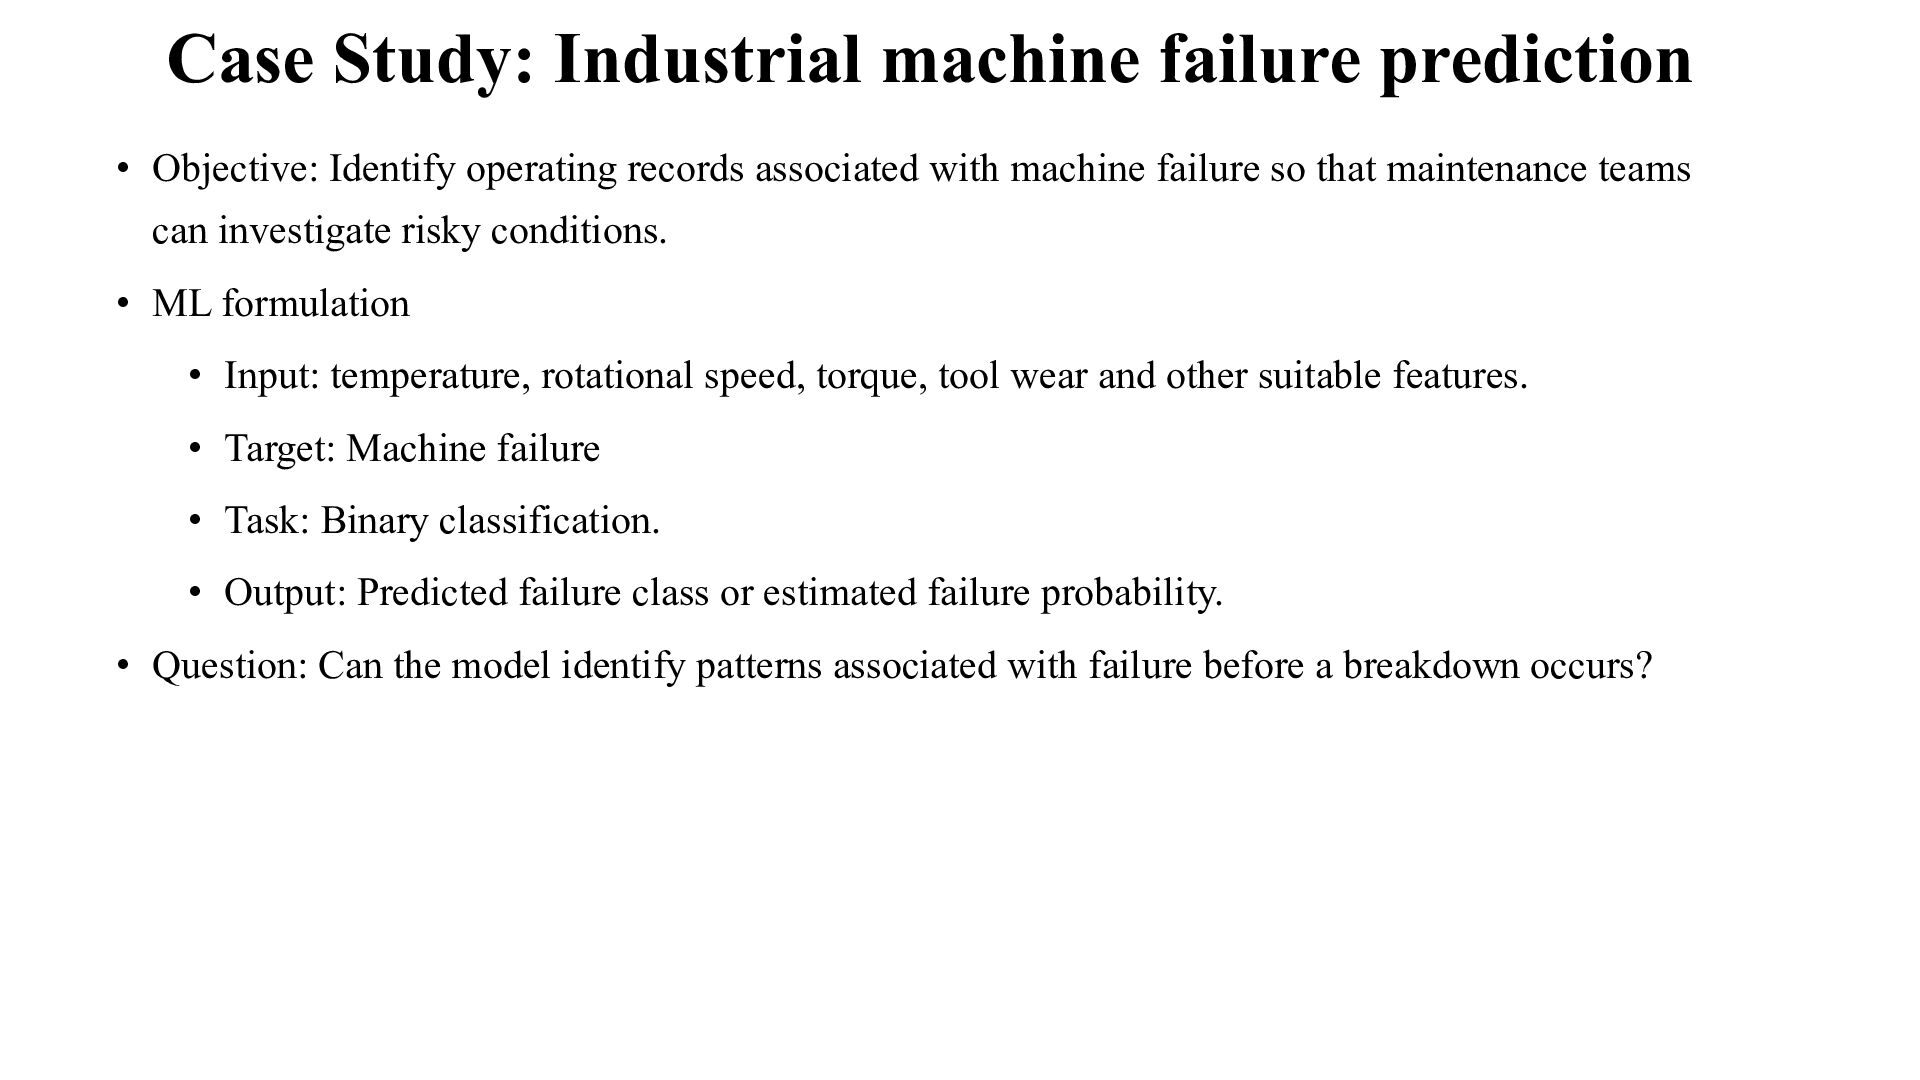
records associated with machine failure so that maintenance teams can investigate risky conditions. • ML formulation • Input: temperature, rotational speed, torque, tool wear and other suitable features. • Target: Machine failure • Task: Binary classification. • Output: Predicted failure class or estimated failure probability. • Question: Can the model identify patterns associated with failure before a breakdown occurs?
the ML model • Use a baseline model before trying more complex methods. • Evaluate: • Precision • Recall • F1-score • Confusion matrix • Precision-recall curve, where appropriate
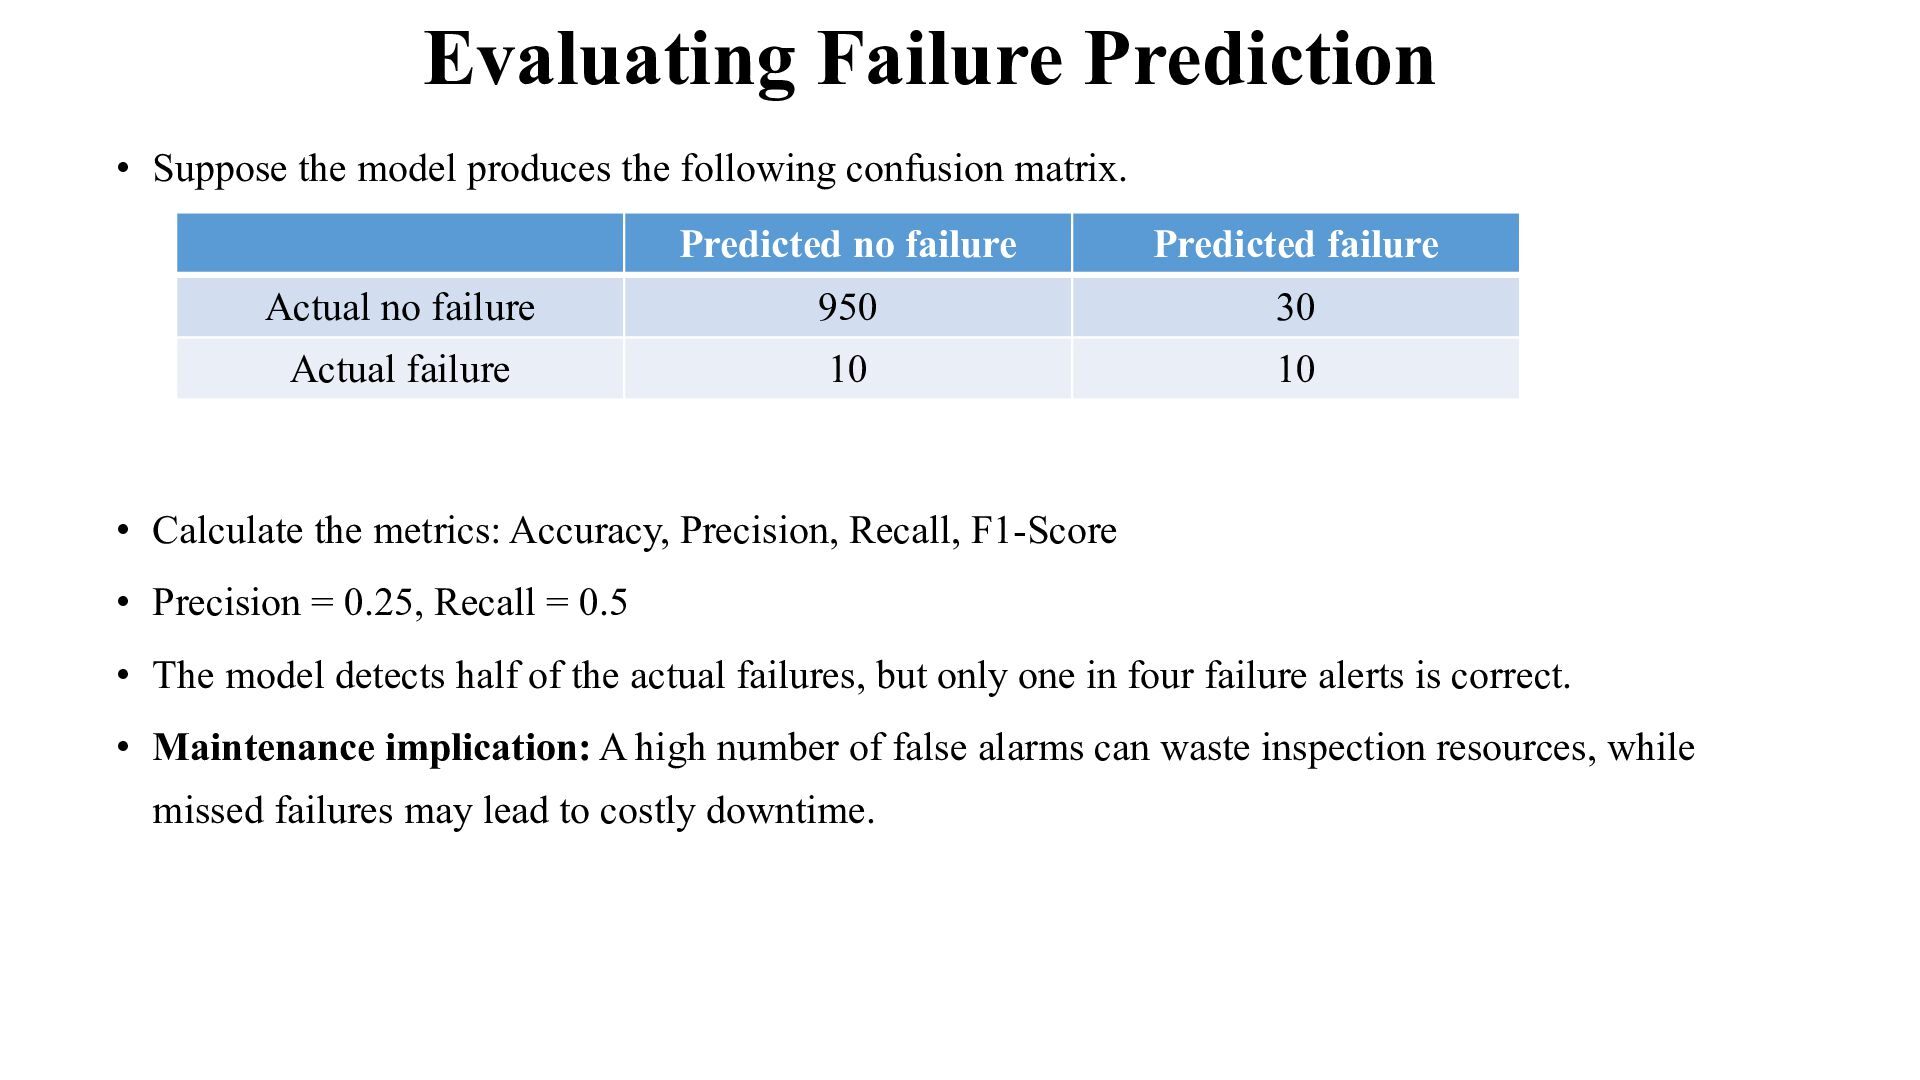
confusion matrix. Predicted no failure Predicted failure Actual no failure 950 30 Actual failure 10 10 • Calculate the metrics: Accuracy, Precision, Recall, F1-Score • Precision = 0.25, Recall = 0.5 • The model detects half of the actual failures, but only one in four failure alerts is correct. • Maintenance implication: A high number of false alarms can waste inspection resources, while missed failures may lead to costly downtime.
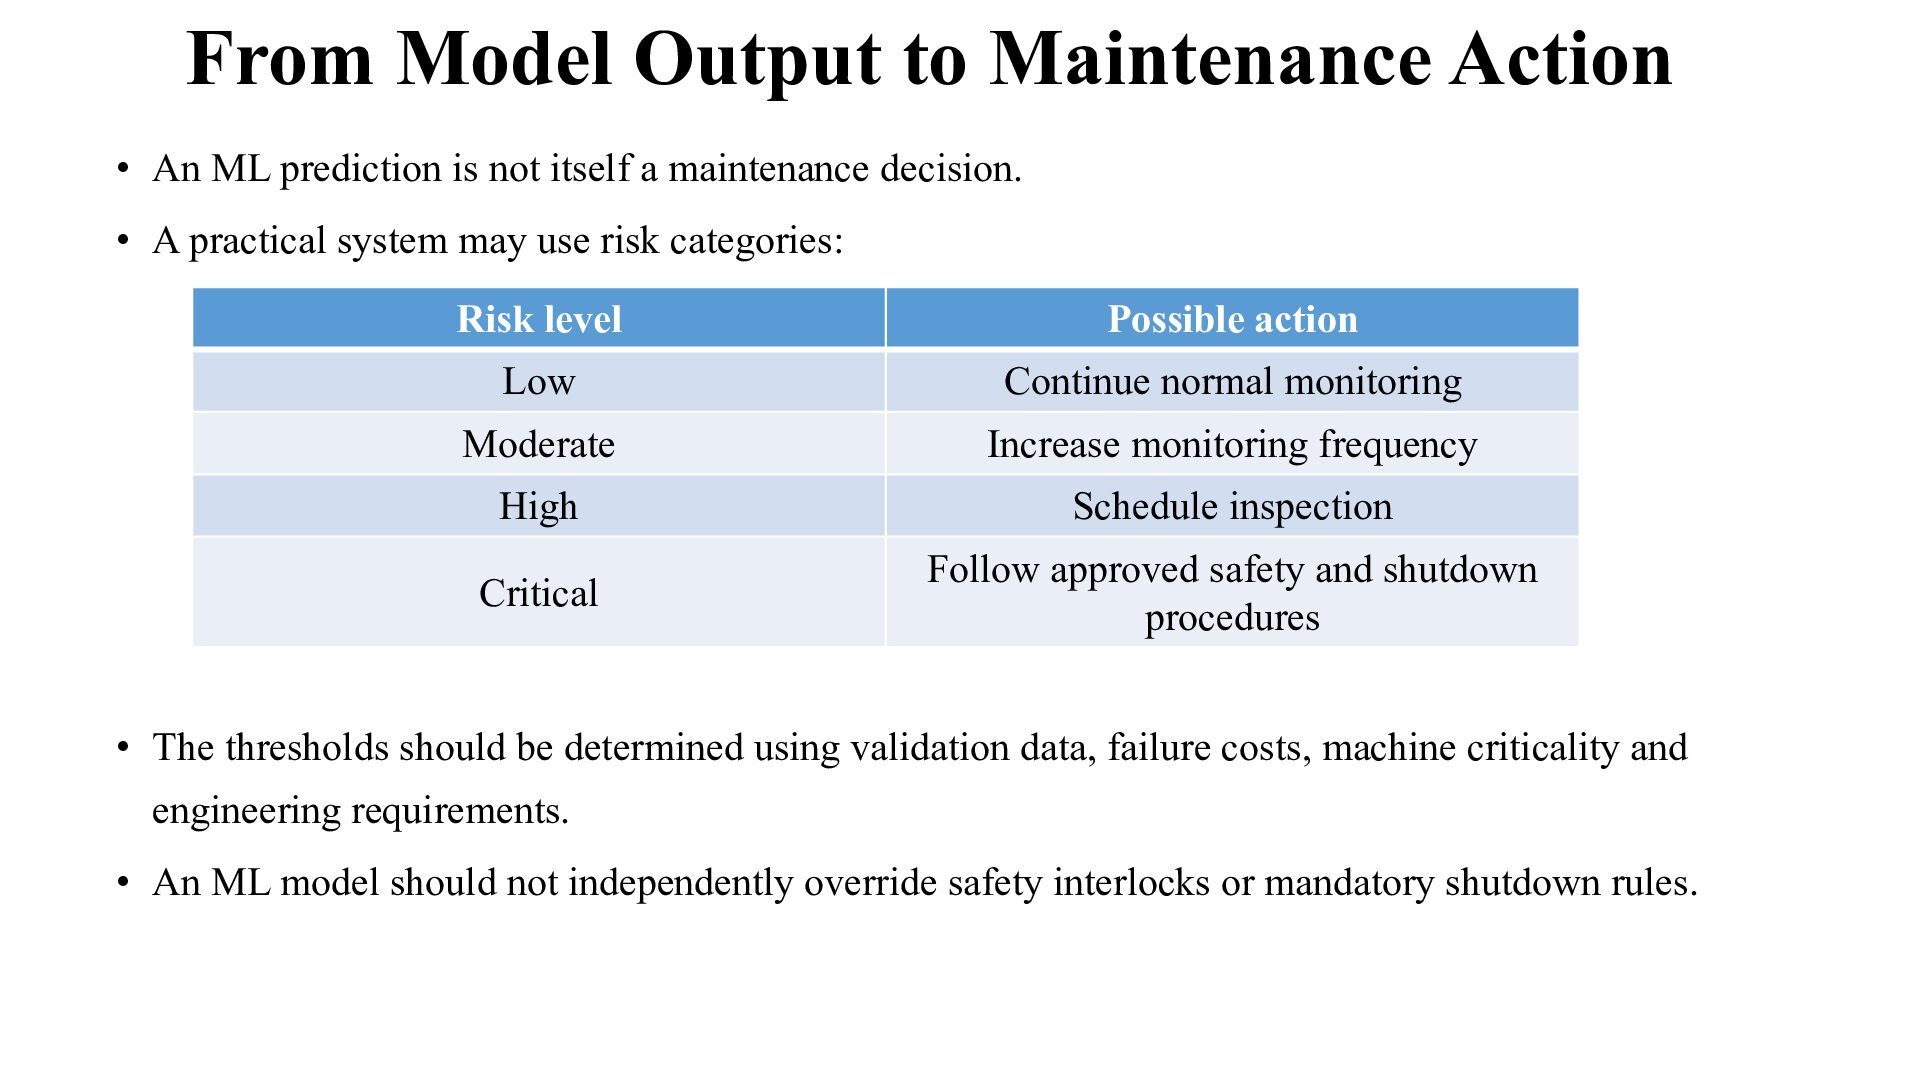
is not itself a maintenance decision. • A practical system may use risk categories: Risk level Possible action Low Continue normal monitoring Moderate Increase monitoring frequency High Schedule inspection Critical Follow approved safety and shutdown procedures • The thresholds should be determined using validation data, failure costs, machine criticality and engineering requirements. • An ML model should not independently override safety interlocks or mandatory shutdown rules.
Machine data can be used to develop a failure-classification model. • Data exploration helps reveal operating patterns and class imbalance. • Feature selection and data splitting influence evaluation quality. • Recall and precision have practical maintenance consequences. • Feature importance can help guide further engineering investigation. • A failure classifier does not automatically estimate when a failure will occur. • What if we do not know all possible failure types, or the failure labels are incomplete? This is where anomaly detection becomes useful.
operates at a stable speed and load. Over several days, its vibration pattern changes. • Approach: • Collect sensor data during known normal operation. • Calculate vibration and operating-condition features. • Train an anomaly detector. • Score new measurements. • Flag sustained or severe anomalies. • Inspect the machine and confirm the physical cause. • Update the maintenance record and monitoring strategy. • Expected benefit: Earlier investigation of unusual behaviour, potentially before a failure is observed.
always trigger a maintenance intervention. • Practical strategies include: • Use rolling averages or signal windows. • Consider machine operating mode. • Require repeated abnormal readings where appropriate. • Combine multiple sensor indicators. • Use persistence rules and severity levels. • Confirm alerts through engineering inspection. • Safety note: Filtering must not delay responses to critical alarms or override safety systems.
• A CNC spindle is expensive to repair and can stop production unexpectedly. • Potential indicators: • Vibration increases • Bearing temperature rises • Current changes • Operating speed and load vary • Objective • Develop a monitoring system that detects abnormal behaviour, supports failure-risk assessment and estimates remaining life when suitable degradation histories are available.
1. Data Collection: Collect data with timestamps and operating-mode information. 2. Data Processing • Synchronize timestamps. • Handle missing or invalid readings. • Segment high-frequency signals into windows. • Calculate statistical and frequency-domain features. • Associate observations with operating conditions. • Preserve machine and component identifiers. • Link maintenance events and failure records where available.
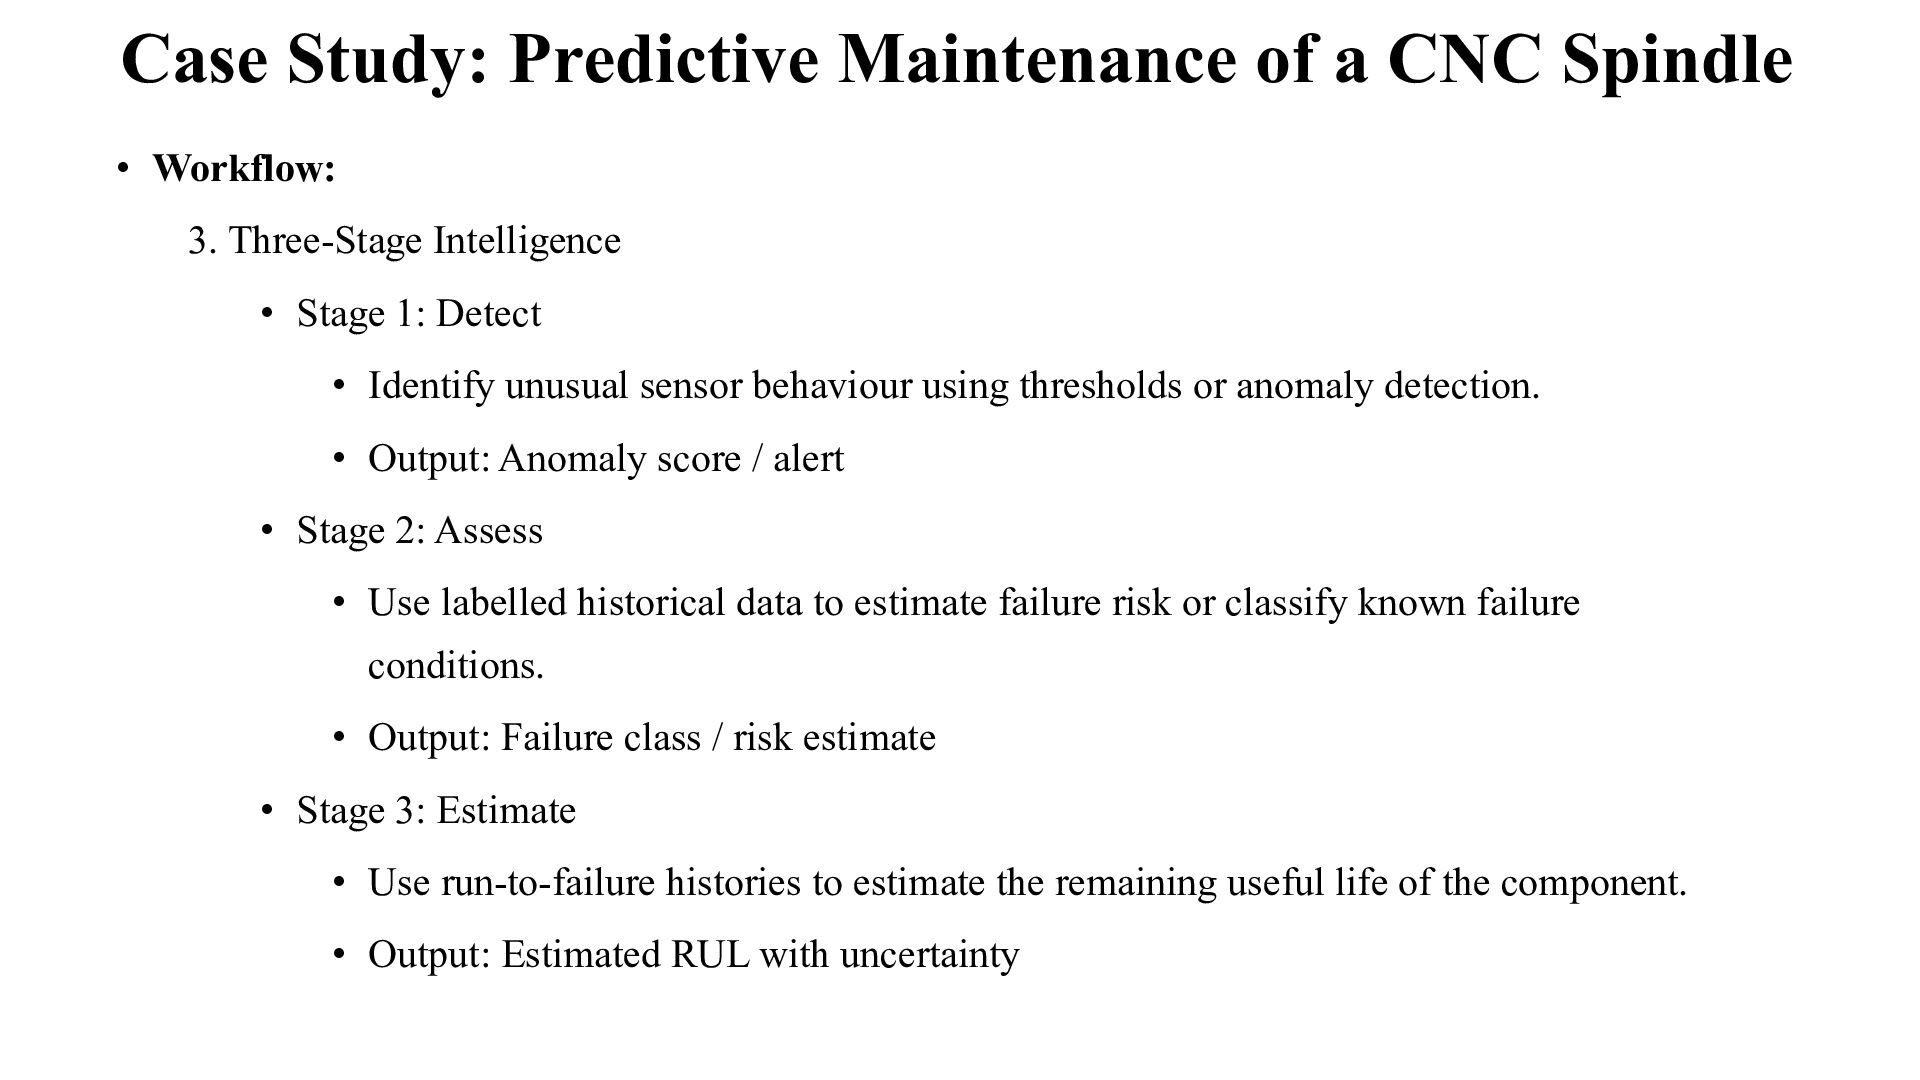
3. Three-Stage Intelligence • Stage 1: Detect • Identify unusual sensor behaviour using thresholds or anomaly detection. • Output: Anomaly score / alert • Stage 2: Assess • Use labelled historical data to estimate failure risk or classify known failure conditions. • Output: Failure class / risk estimate • Stage 3: Estimate • Use run-to-failure histories to estimate the remaining useful life of the component. • Output: Estimated RUL with uncertainty
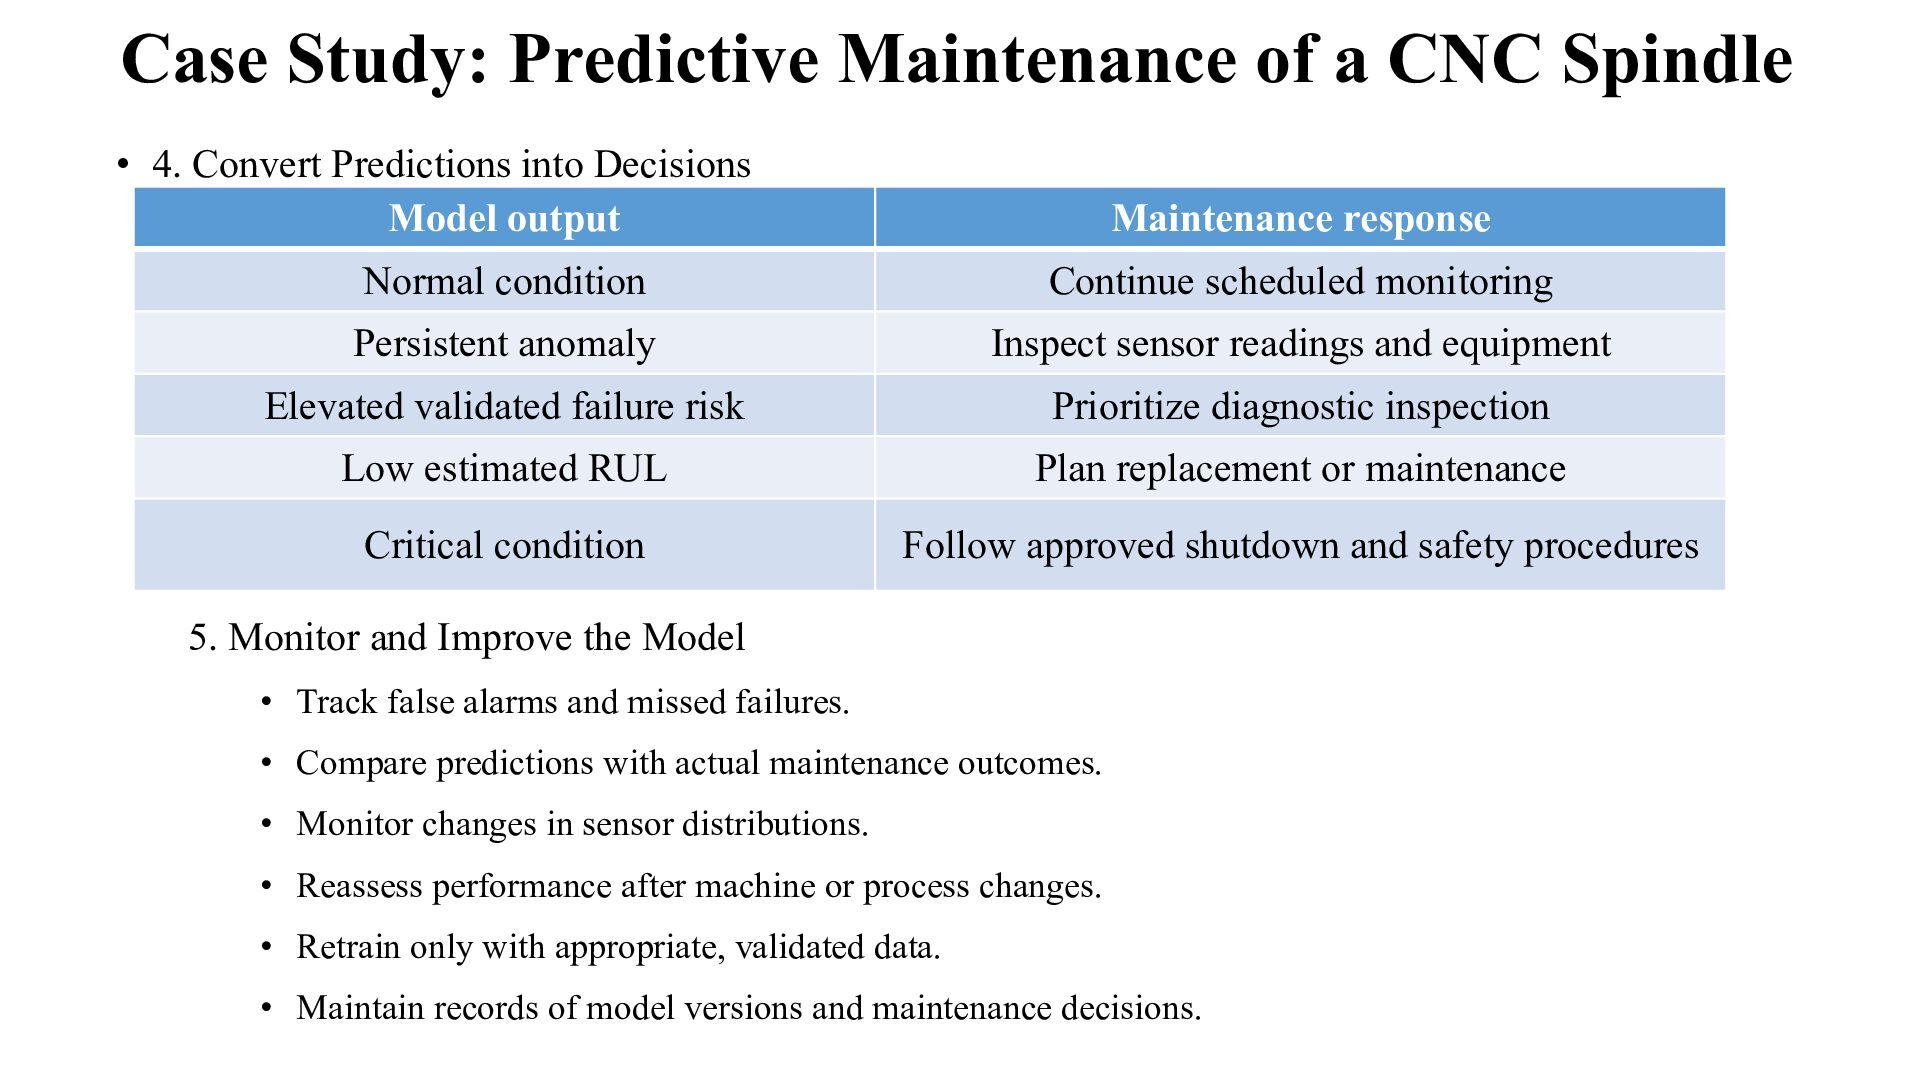
Convert Predictions into Decisions Model output Maintenance response Normal condition Continue scheduled monitoring Persistent anomaly Inspect sensor readings and equipment Elevated validated failure risk Prioritize diagnostic inspection Low estimated RUL Plan replacement or maintenance Critical condition Follow approved shutdown and safety procedures 5. Monitor and Improve the Model • Track false alarms and missed failures. • Compare predictions with actual maintenance outcomes. • Monitor changes in sensor distributions. • Reassess performance after machine or process changes. • Retrain only with appropriate, validated data. • Maintain records of model versions and maintenance decisions.


 madhuri28
 uchi8977
 hiola
 yoshimura_datam
 ishii_mit
 coderdojojapan
 cbtlibrary
 bvr7352
 mariooc
 pawan_pharm
 signer
 terasawat
 soudai
 panda_program
 katiecoart
 lfama
 carmenintech
 minecr
 rkendrick25
 cassininazir
 denniskardys
 skipperchong
 thekraken
 techseoconnect
 vanstee