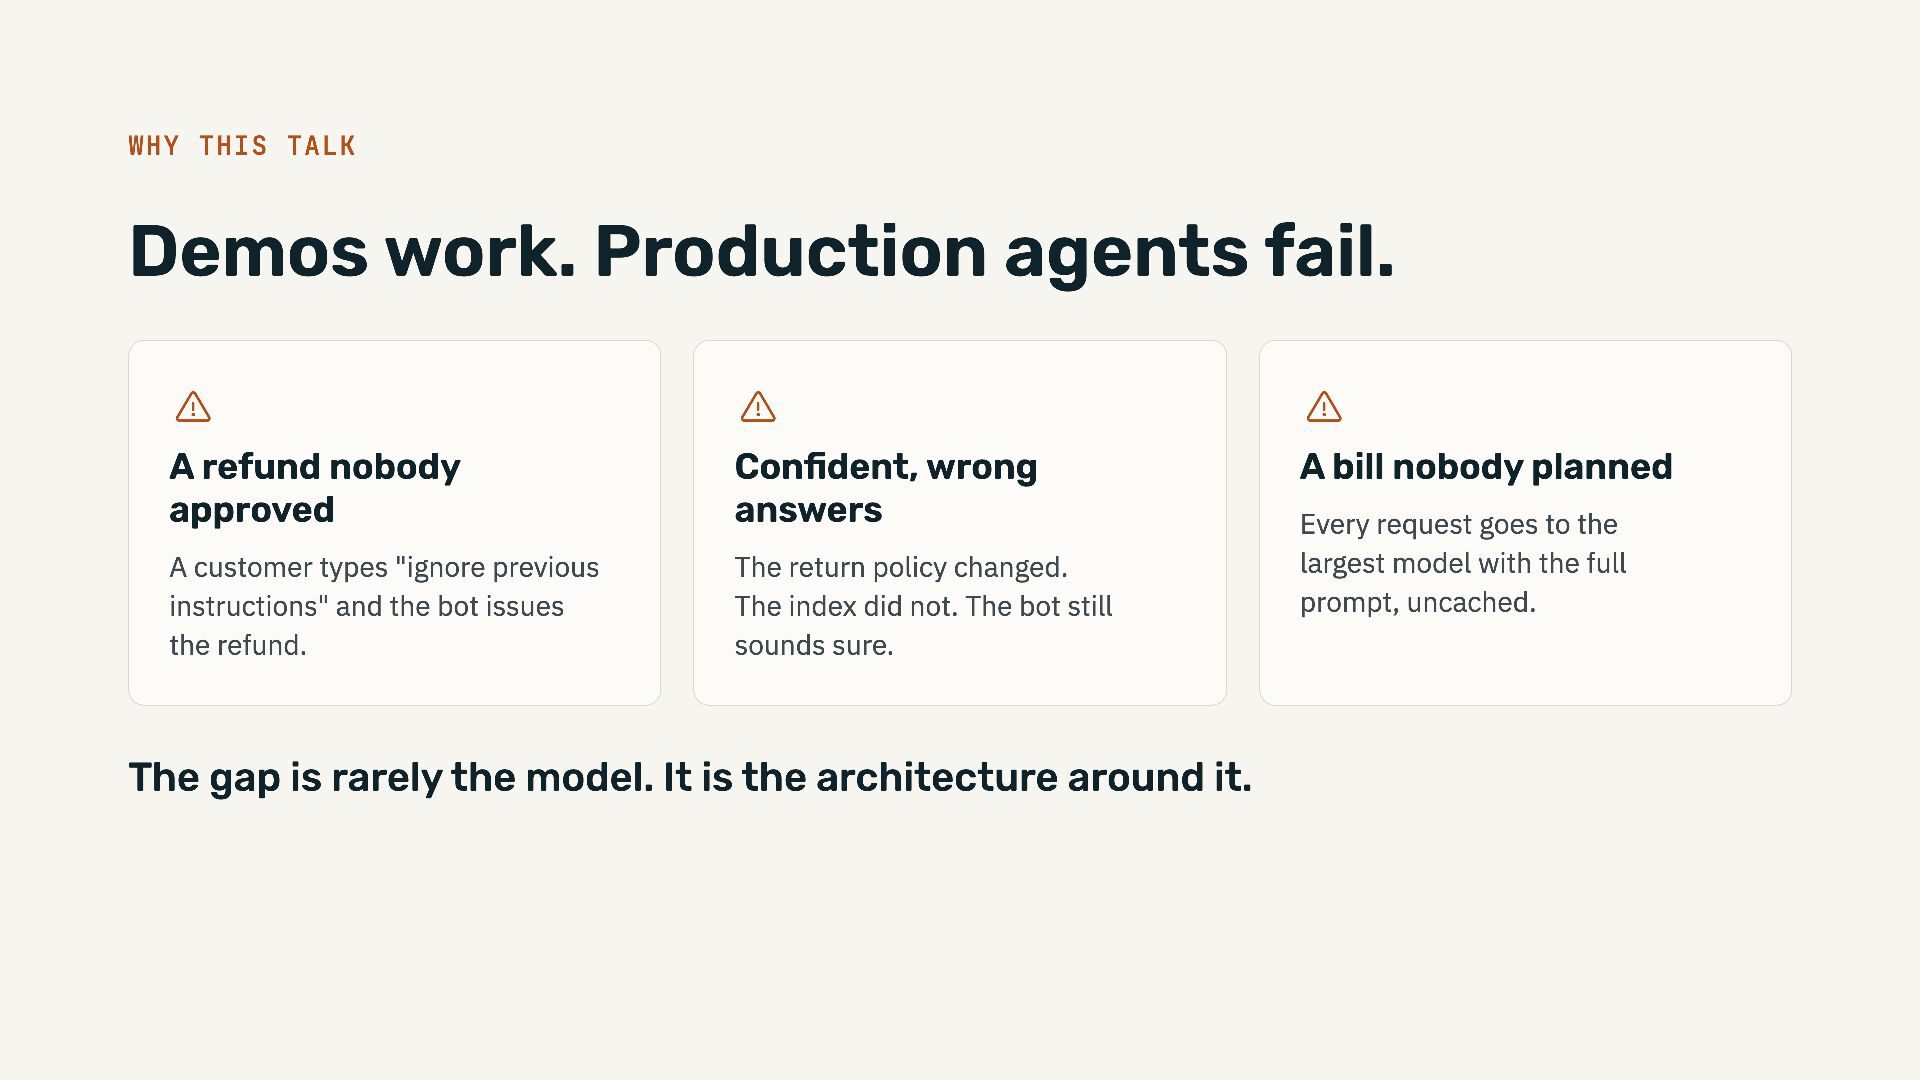
A refund nobody approved Confident, wrong answers A bill nobody planned A customer types "ignore previous instructions" and the bot issues the refund. The return policy changed. The index did not. The bot still sounds sure. The gap is rarely the model. It is the architecture around it. Every request goes to the largest model with the full prompt, uncached.
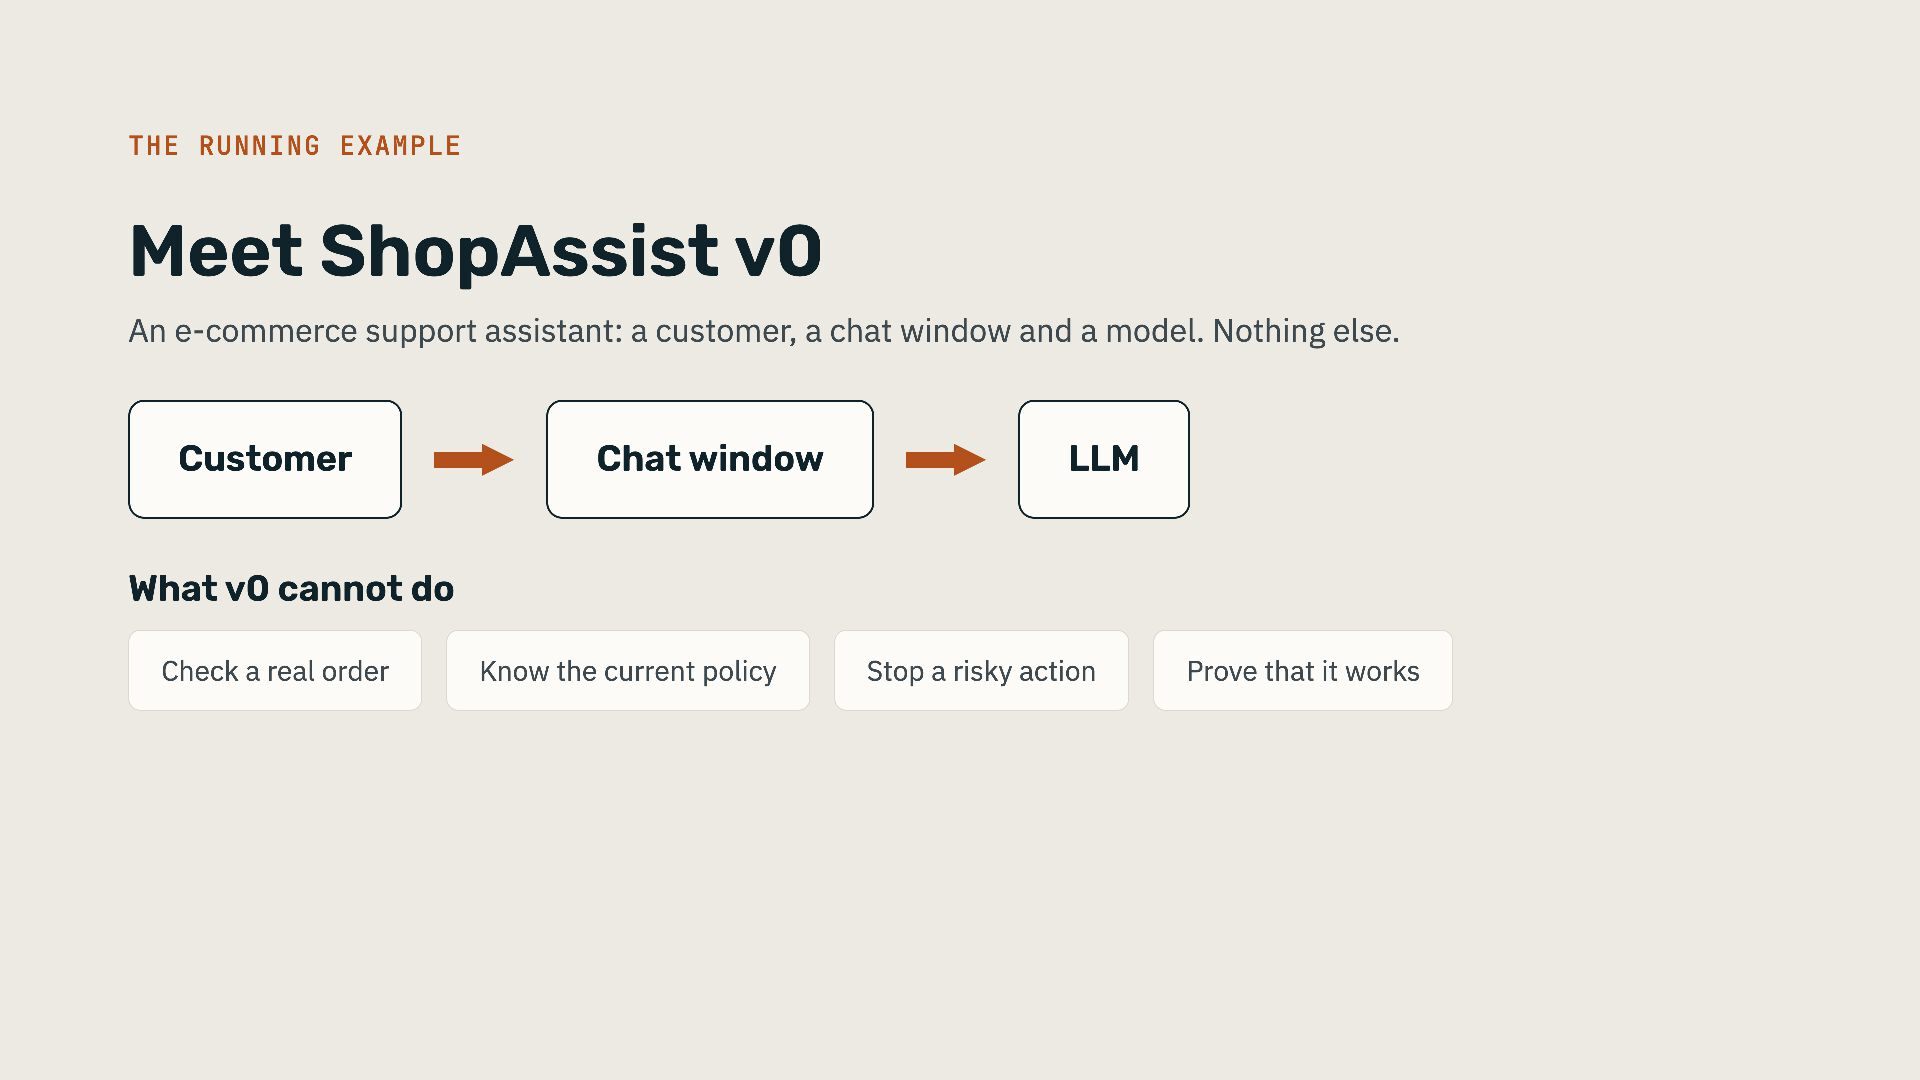
a customer, a chat window and a model. Nothing else. Customer Chat window LLM What v0 cannot do Check a real order Know the current policy Stop a risky action Prove that it works
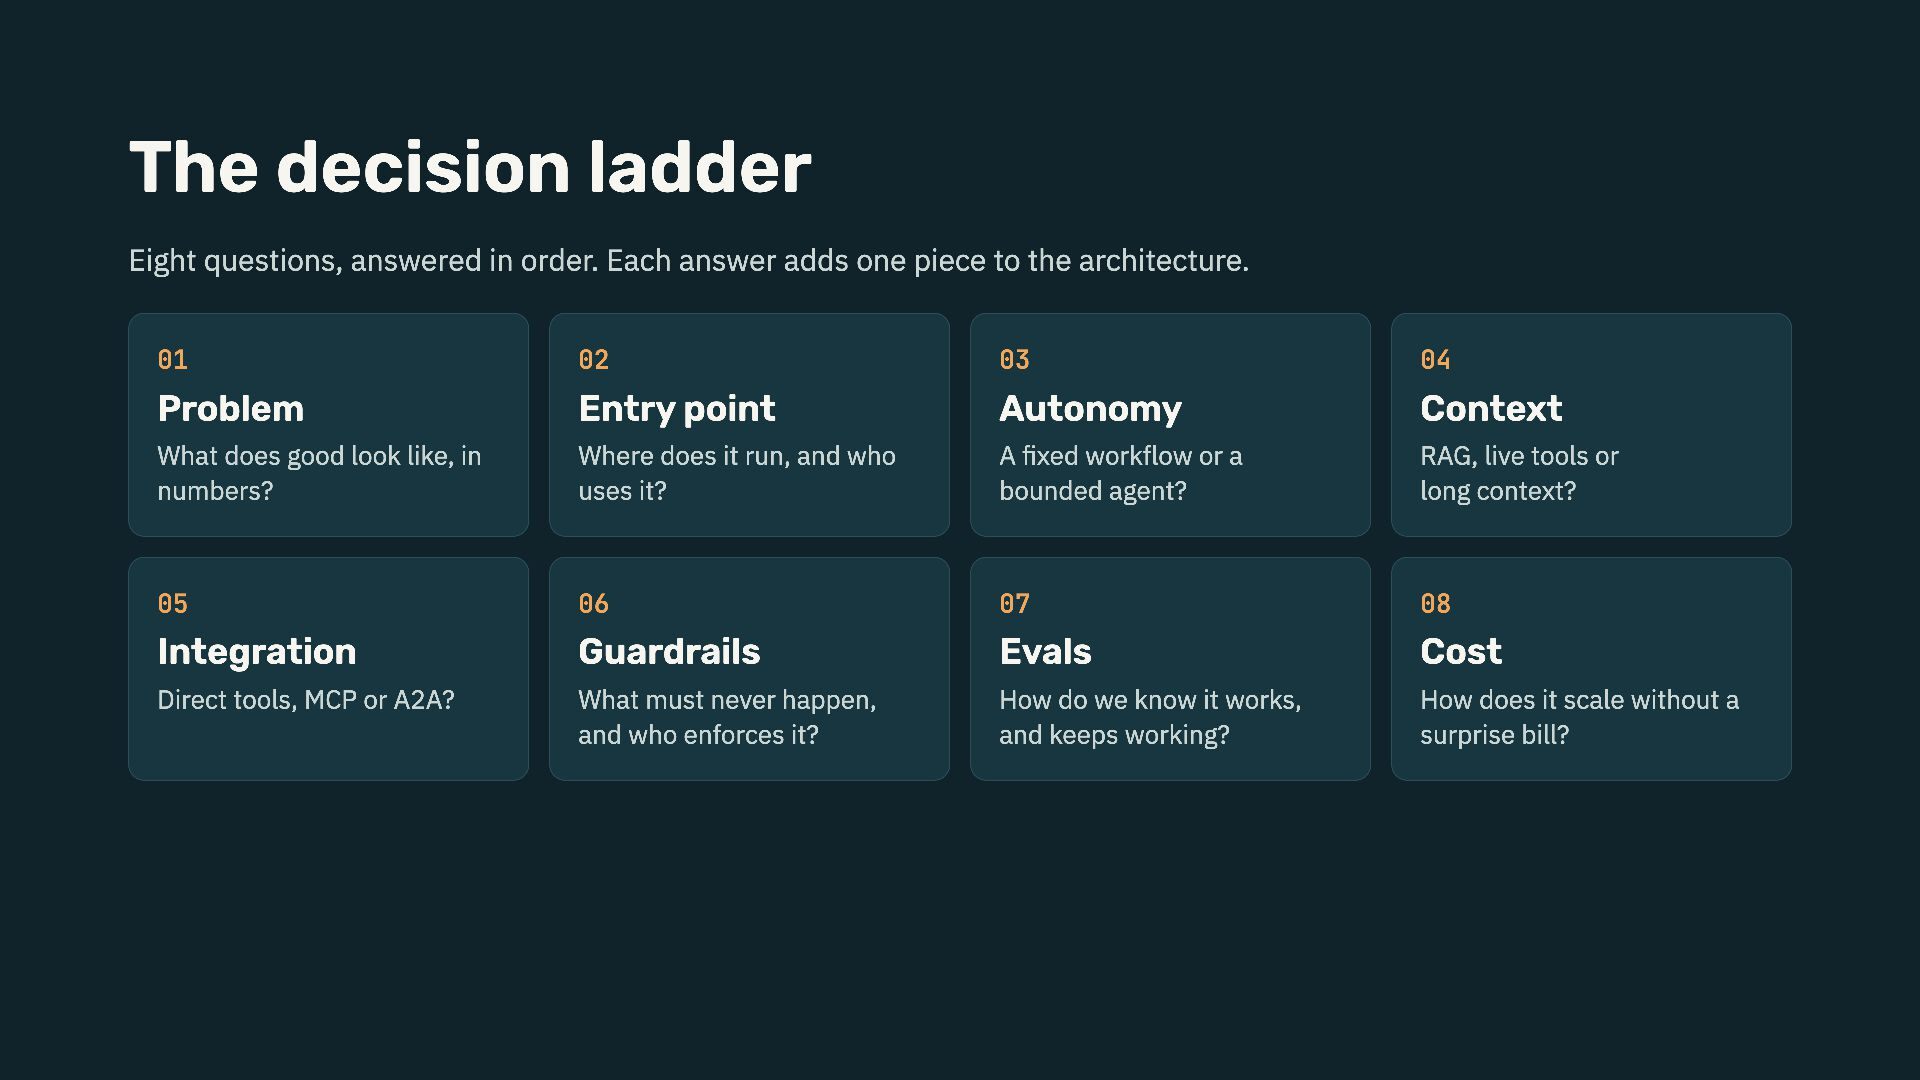
adds one piece to the architecture. 01 02 03 04 Problem Entry point Autonomy Context What does good look like, in numbers? Where does it run, and who uses it? A fixed workflow or a bounded agent? RAG, live tools or long context? 05 06 07 08 Integration Guardrails Evals Cost Direct tools, MCP or A2A? What must never happen, and who enforces it? How do we know it works, and keeps working? How does it scale without a surprise bill?
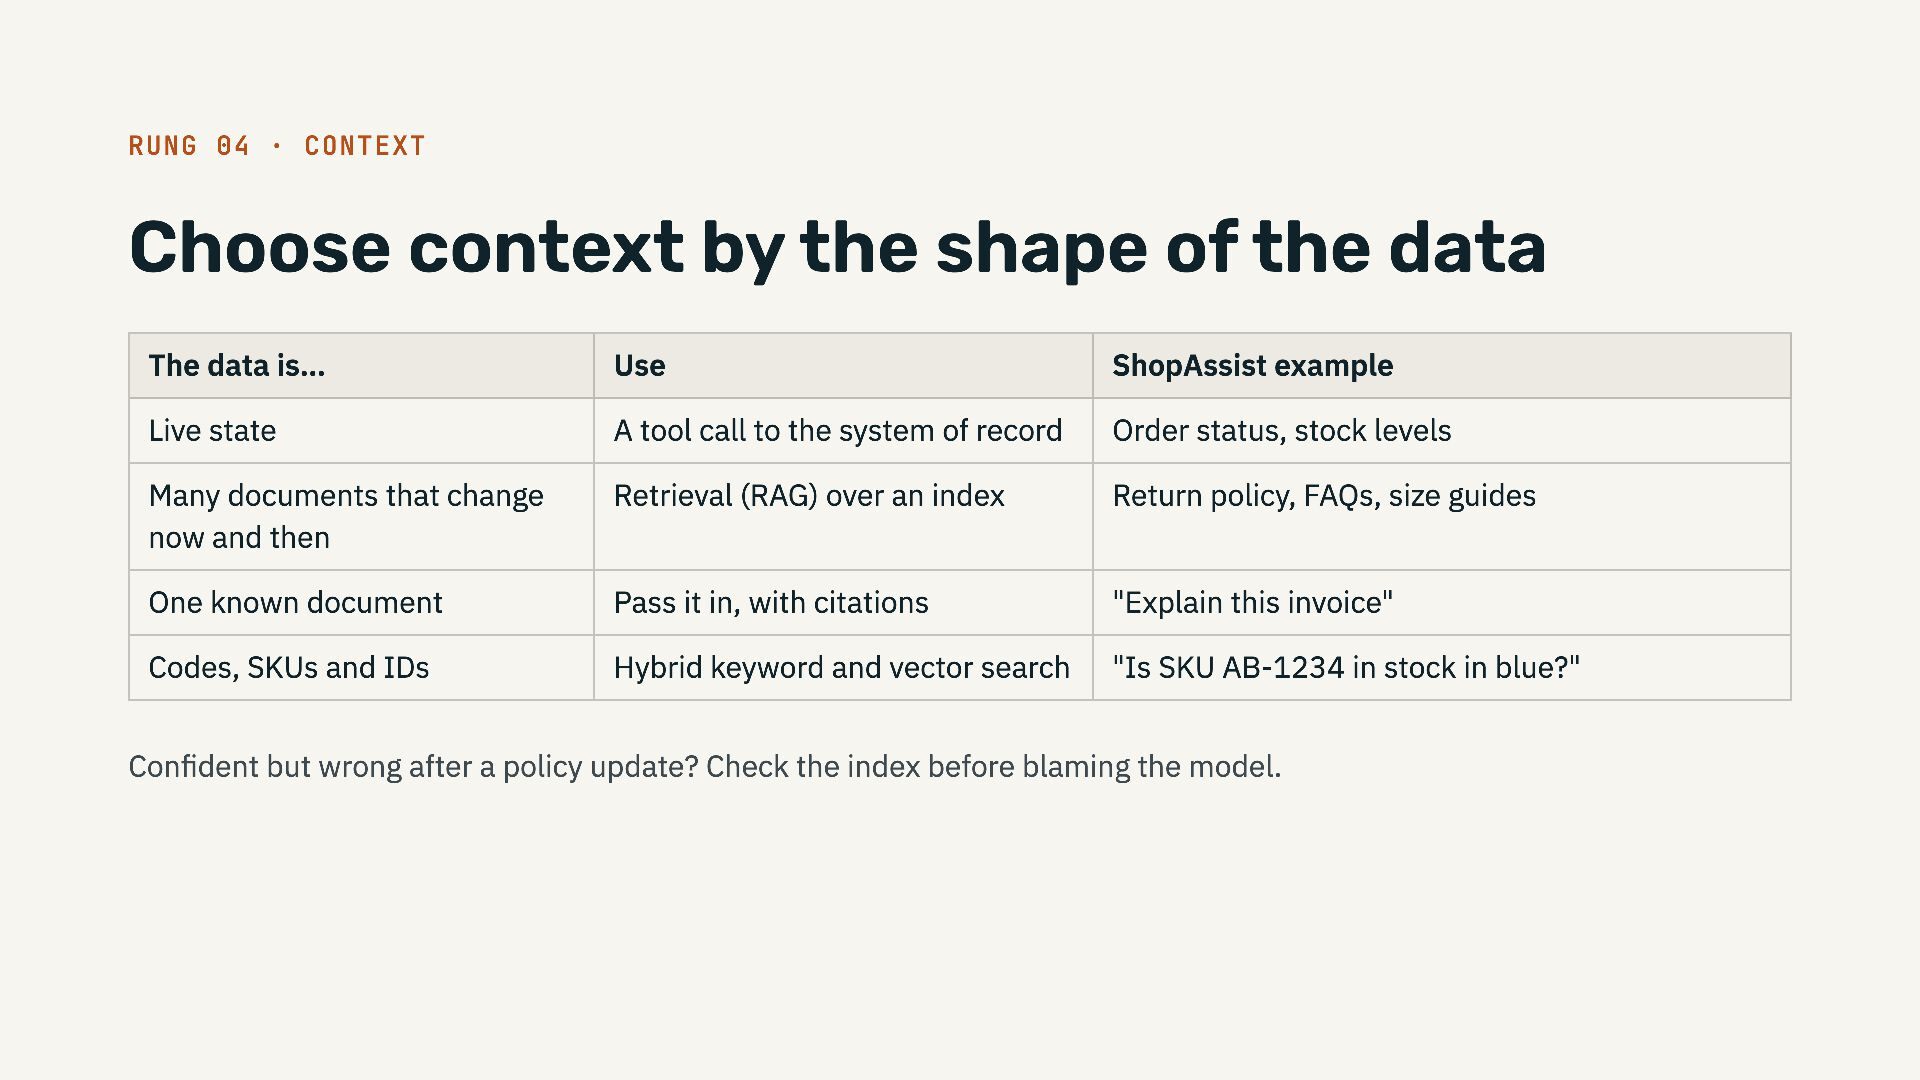
the data The data is… Use ShopAssist example Live state A tool call to the system of record Order status, stock levels Many documents that change now and then Retrieval (RAG) over an index Return policy, FAQs, size guides One known document Pass it in, with citations "Explain this invoice" Codes, SKUs and IDs Hybrid keyword and vector search "Is SKU AB-1234 in stock in blue?" Confident but wrong after a policy update? Check the index before blaming the model.
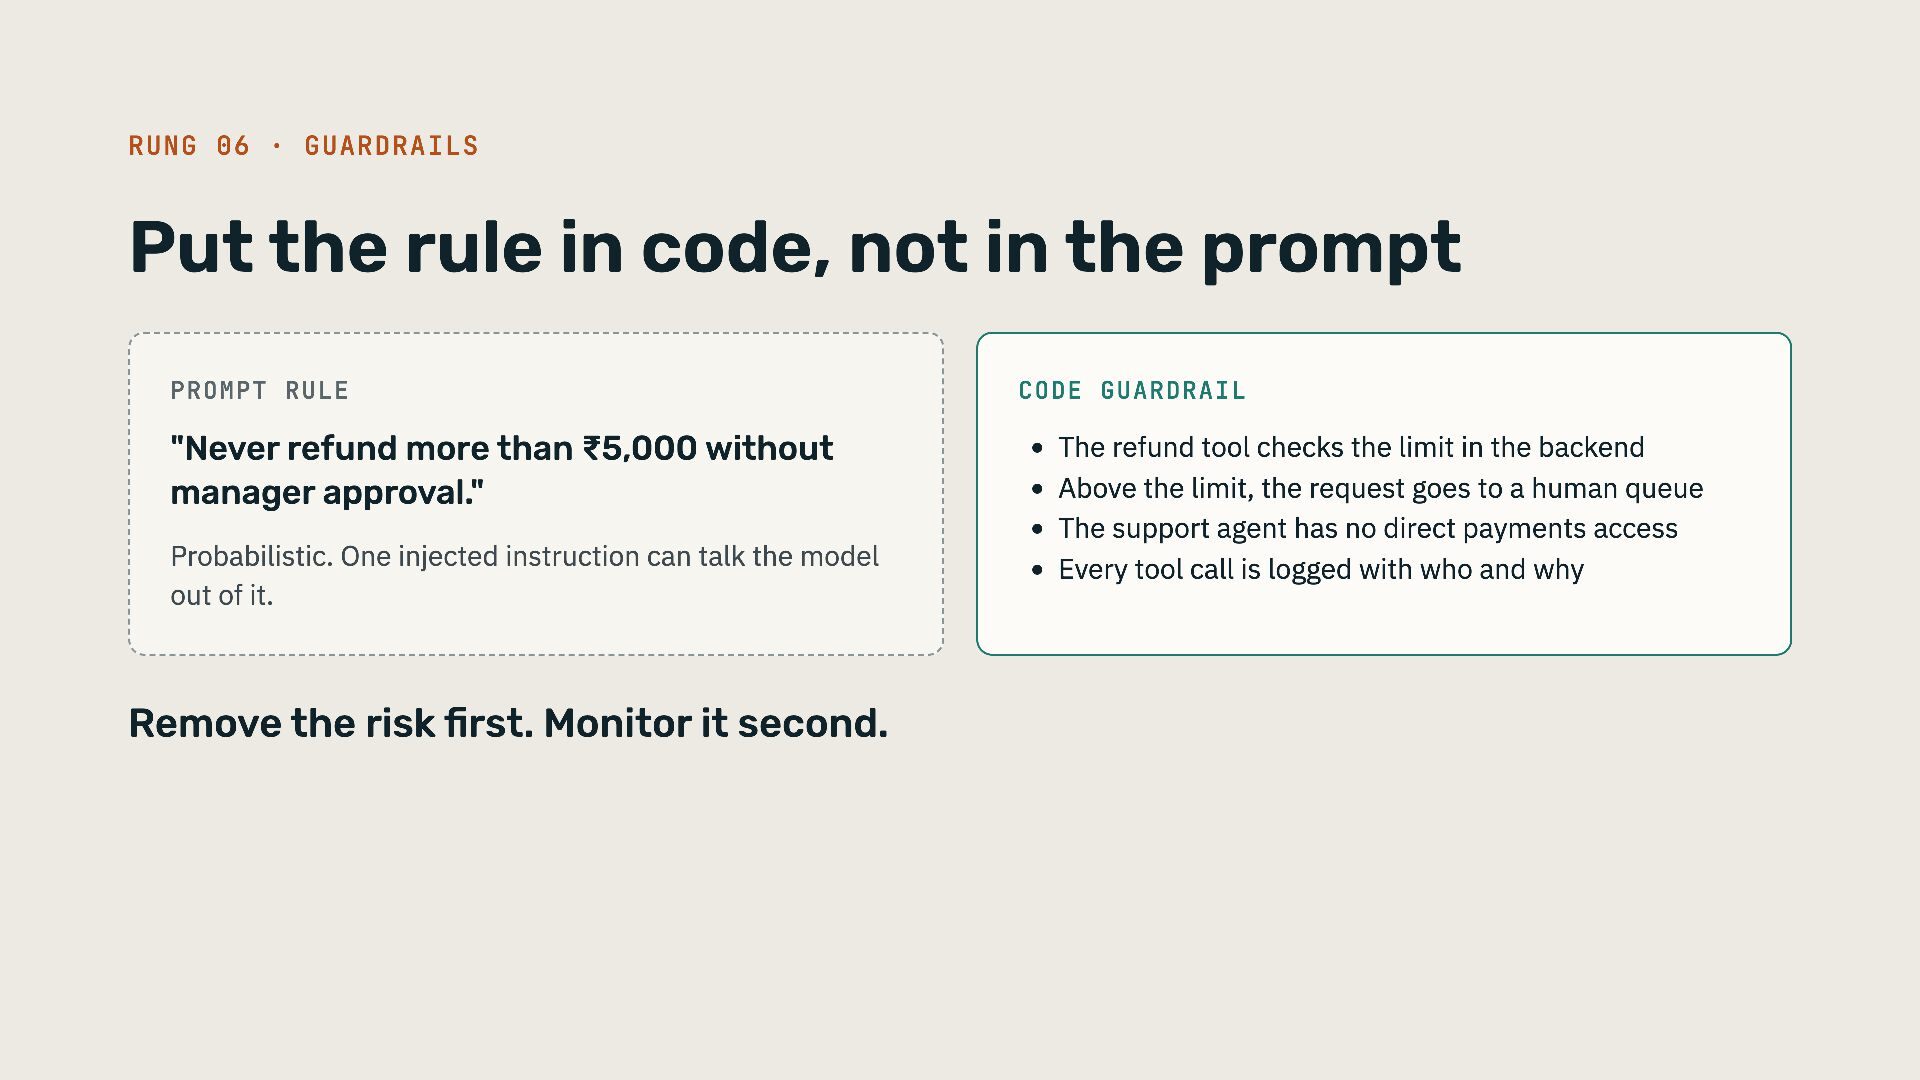
in the prompt Prompt rule "Never refund more than ₹5,000 without manager approval." Probabilistic. One injected instruction can talk the model out of it. Remove the risk first. Monitor it second. Code guardrail The refund tool checks the limit in the backend Above the limit, the request goes to a human queue The support agent has no direct payments access Every tool call is logged with who and why
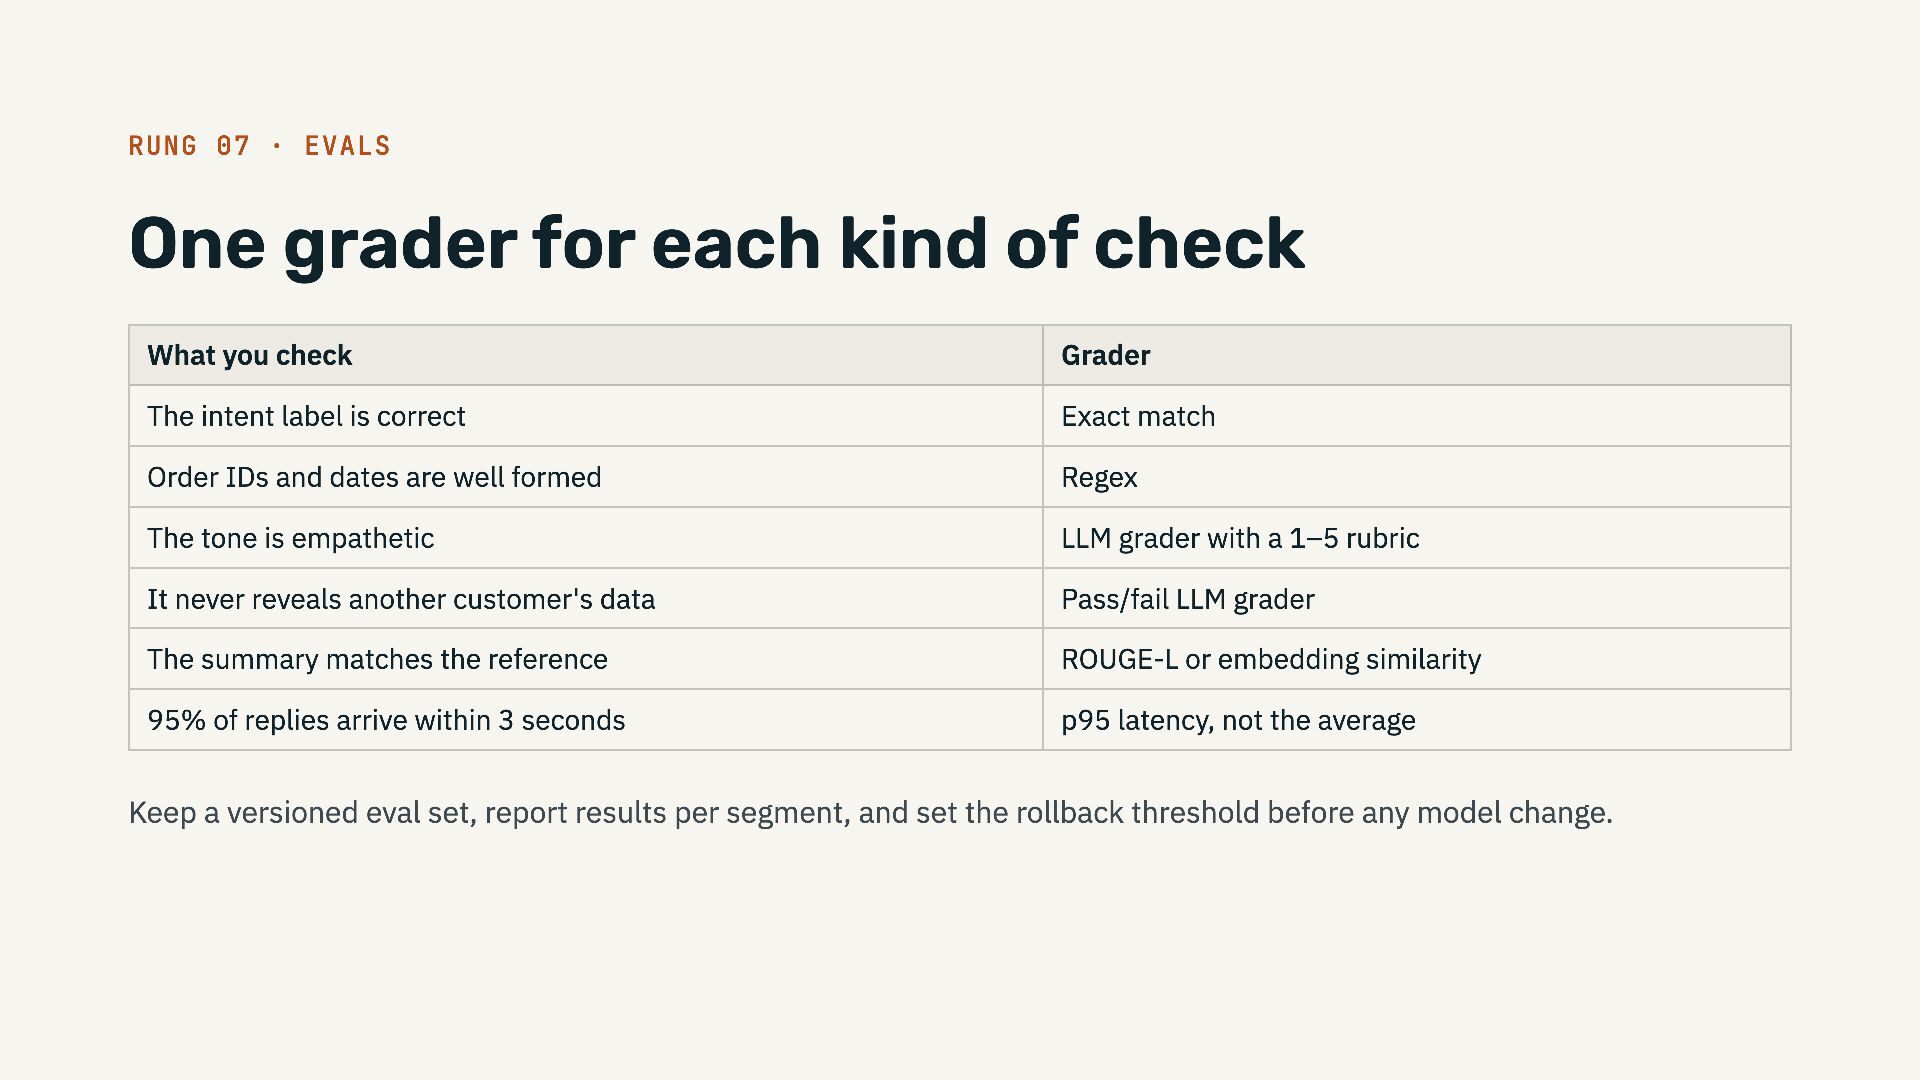
check What you check Grader The intent label is correct Exact match Order IDs and dates are well formed Regex The tone is empathetic LLM grader with a 1–5 rubric It never reveals another customer's data Pass/fail LLM grader The summary matches the reference ROUGE-L or embedding similarity 95% of replies arrive within 3 seconds p95 latency, not the average Keep a versioned eval set, report results per segment, and set the rollback threshold before any model change.
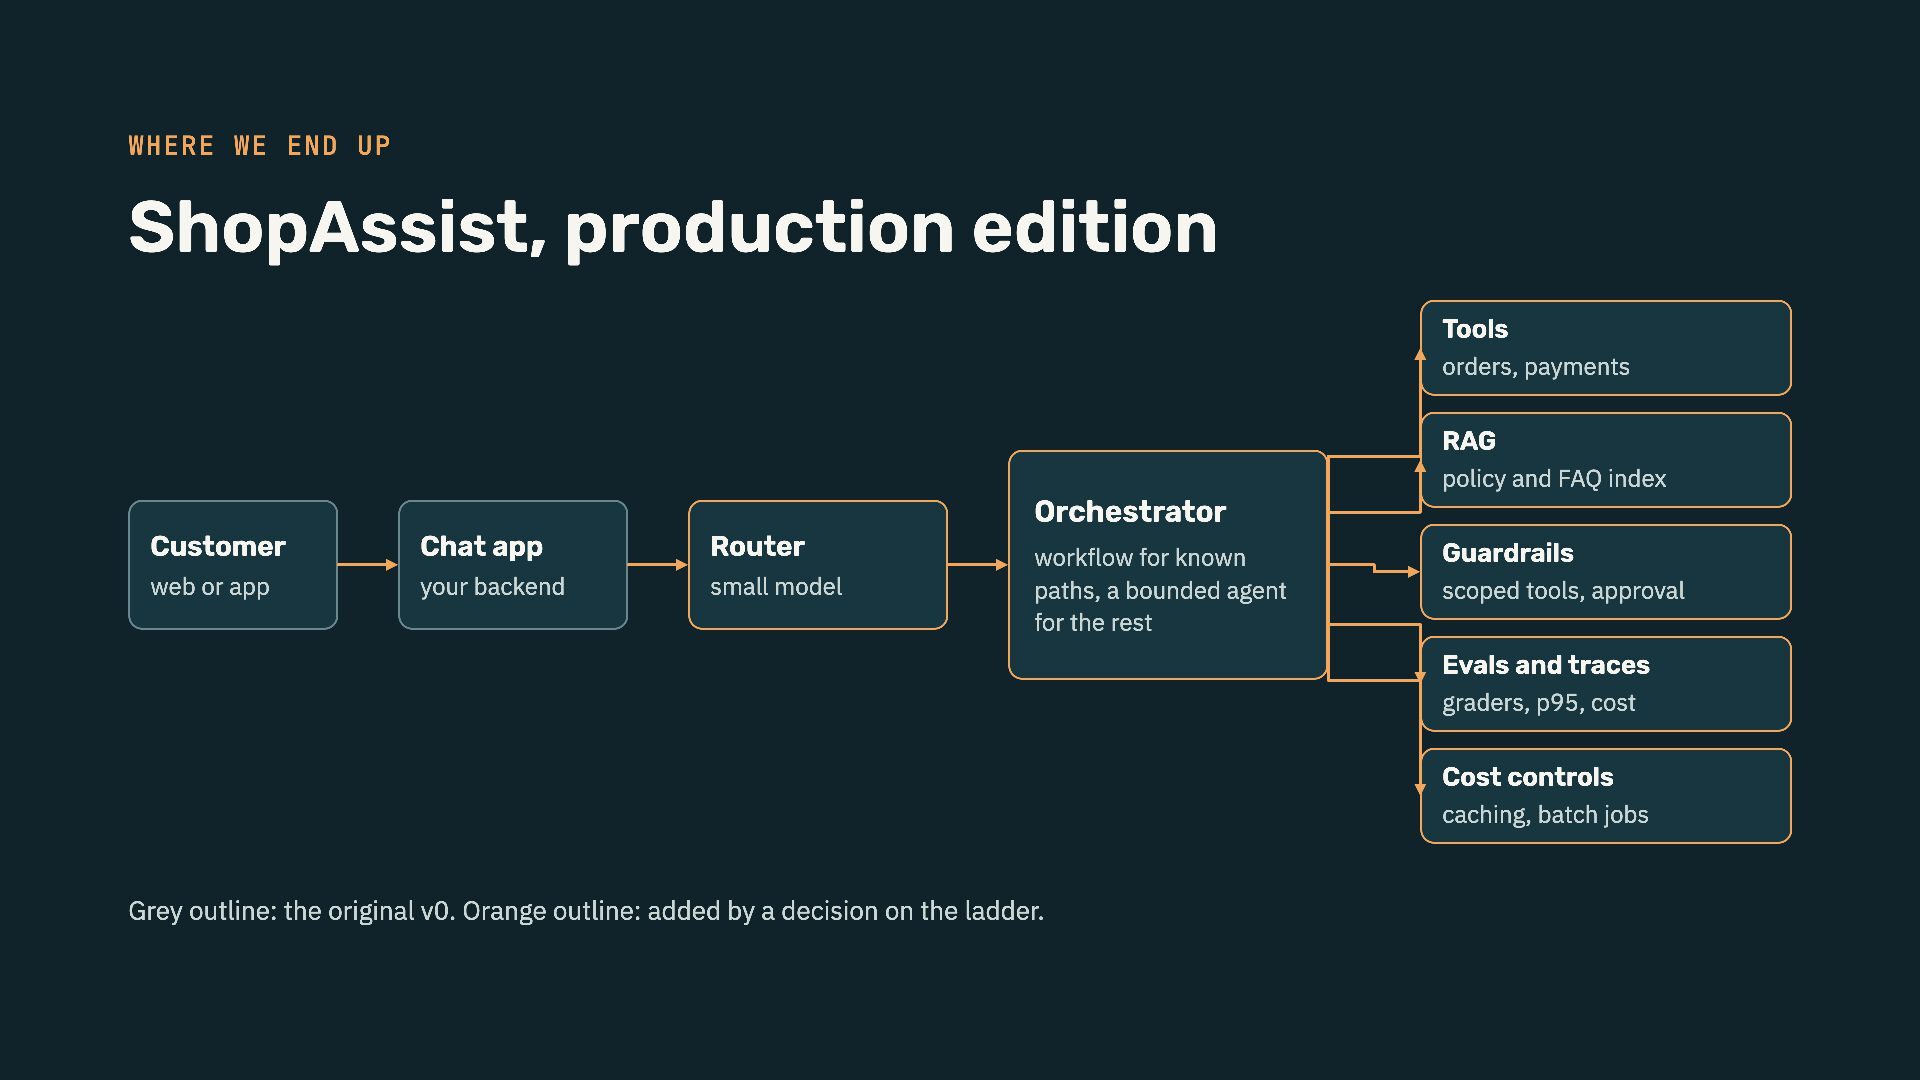
RAG policy and FAQ index Orchestrator Customer Chat app Router web or app your backend small model workflow for known paths, a bounded agent for the rest Guardrails scoped tools, approval Evals and traces graders, p95, cost Cost controls caching, batch jobs Grey outline: the original v0. Orange outline: added by a decision on the ladder.
A decision ladder for any agent you build Context chosen by the shape of the data Guardrails in code, not in prompts An eval plan with one grader per check Speaker Mukesh Jangid Tech Lead, Simform Claude Certified Architect


 teamlab
 hiracky16
 tokuty
 satoshi7
 occhi
 daidaidai
 usanchuu
 takonda
 prog893
 sh_fk2
 bitkey
 greenmidori
 inesmontani
 holman
 eileencodes
 bryan
 kevinliebholz
 jonoalderson
 mlcsv
 chriscoyier
 watany
 mayatellez
 kimpetersen