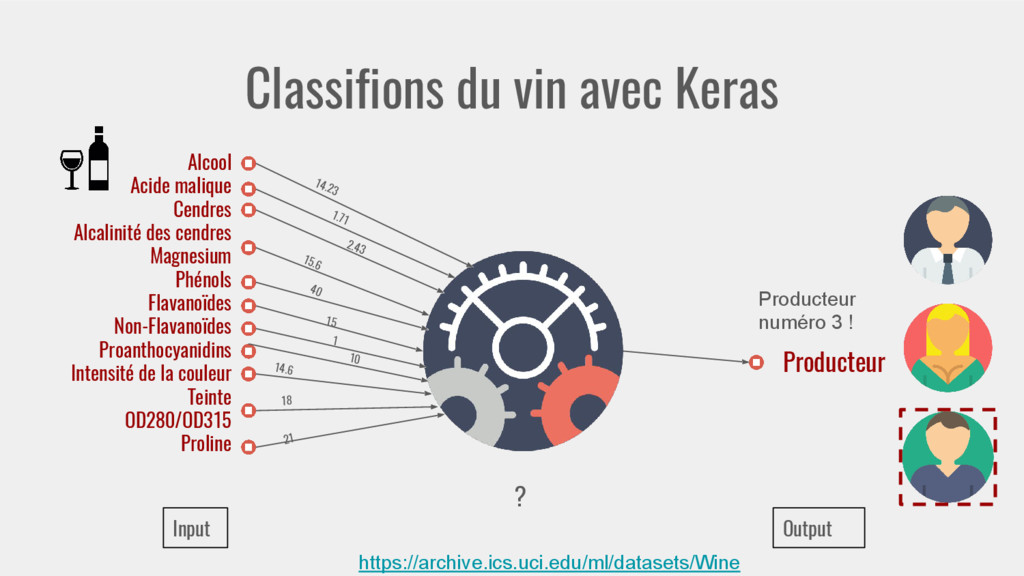
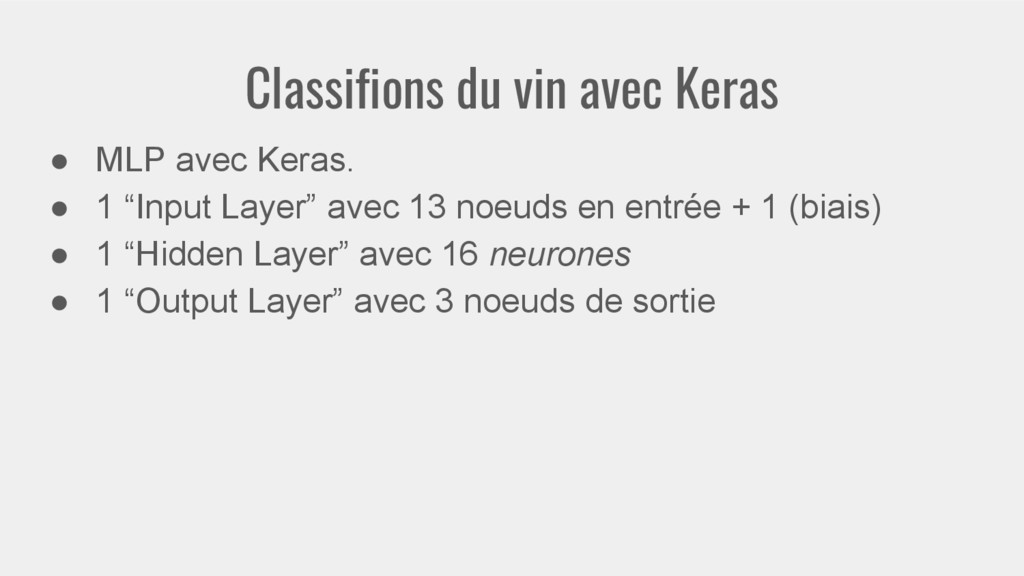
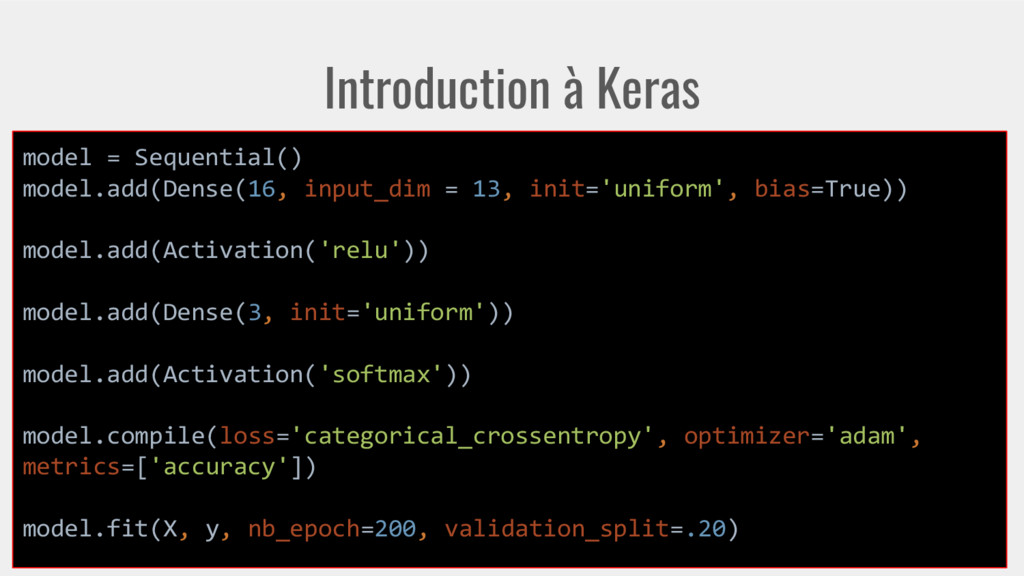
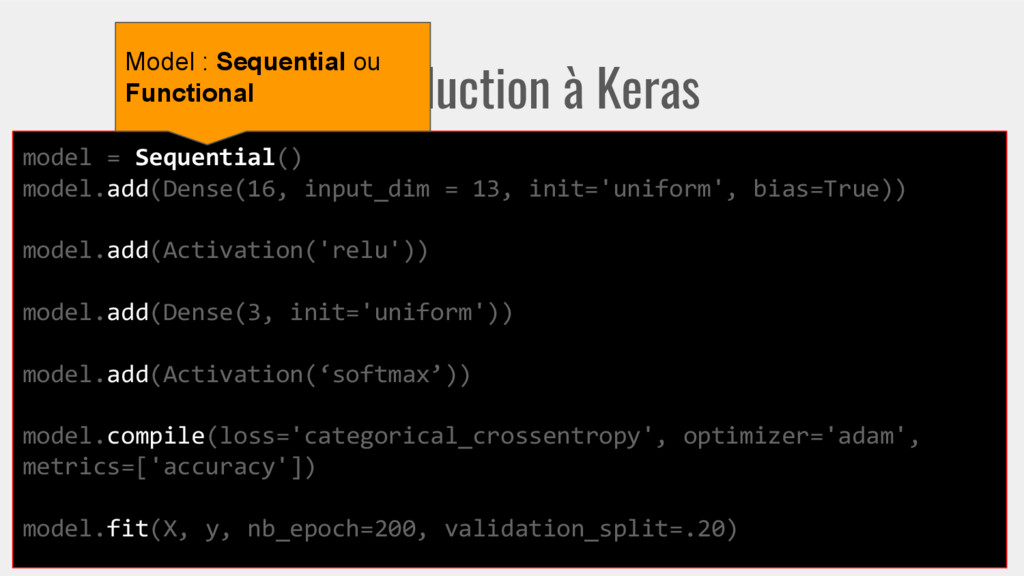
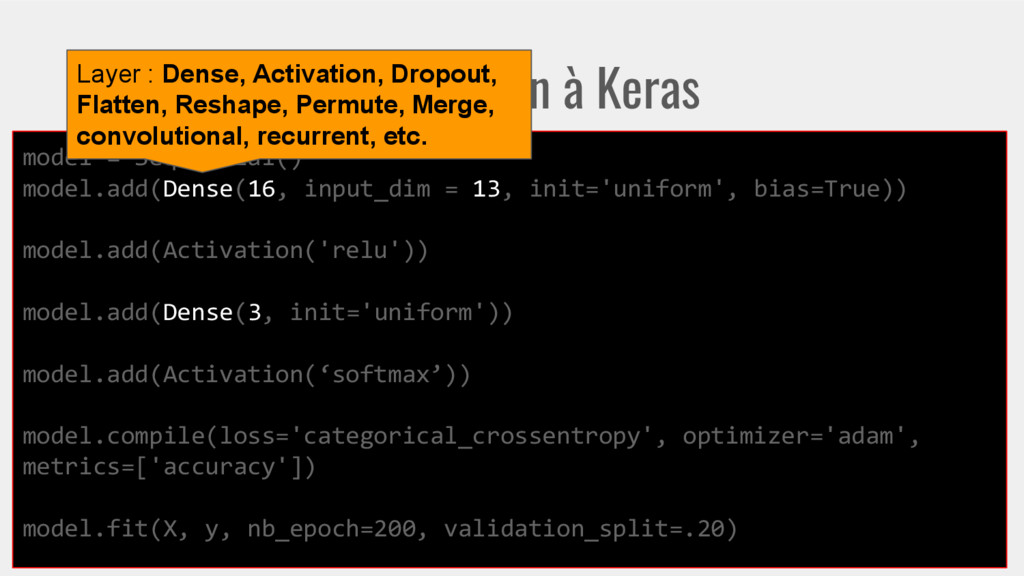
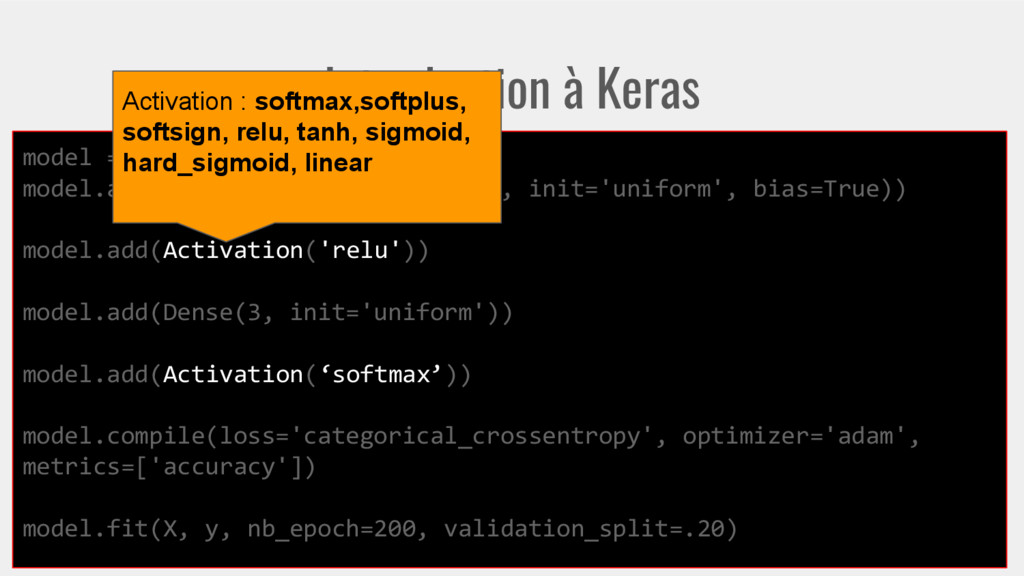
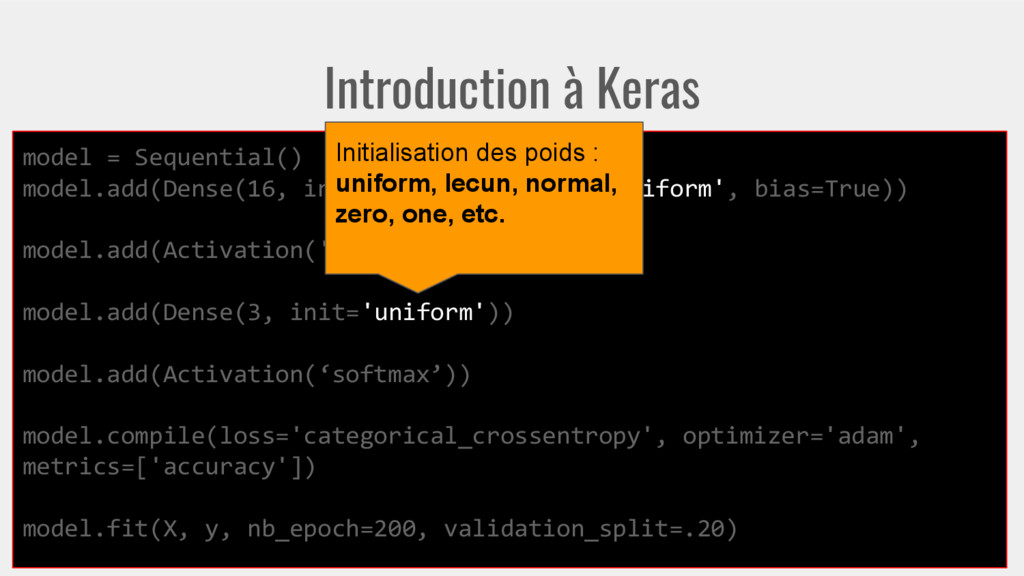
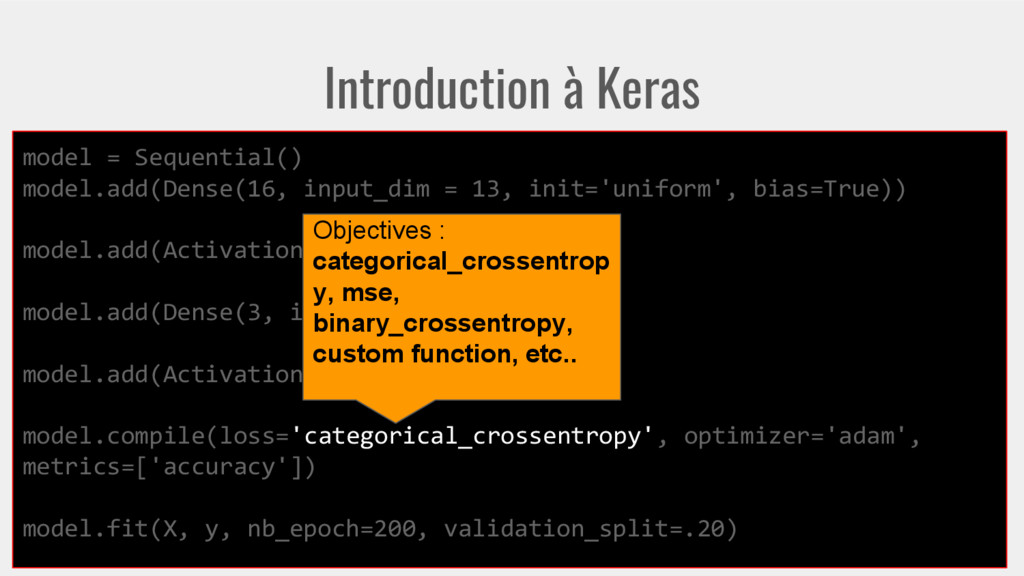
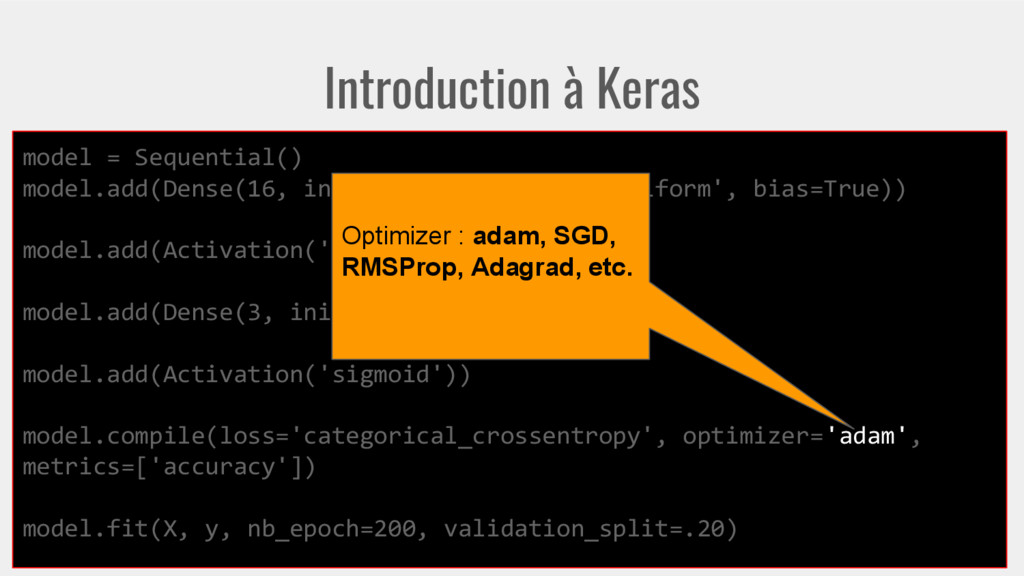
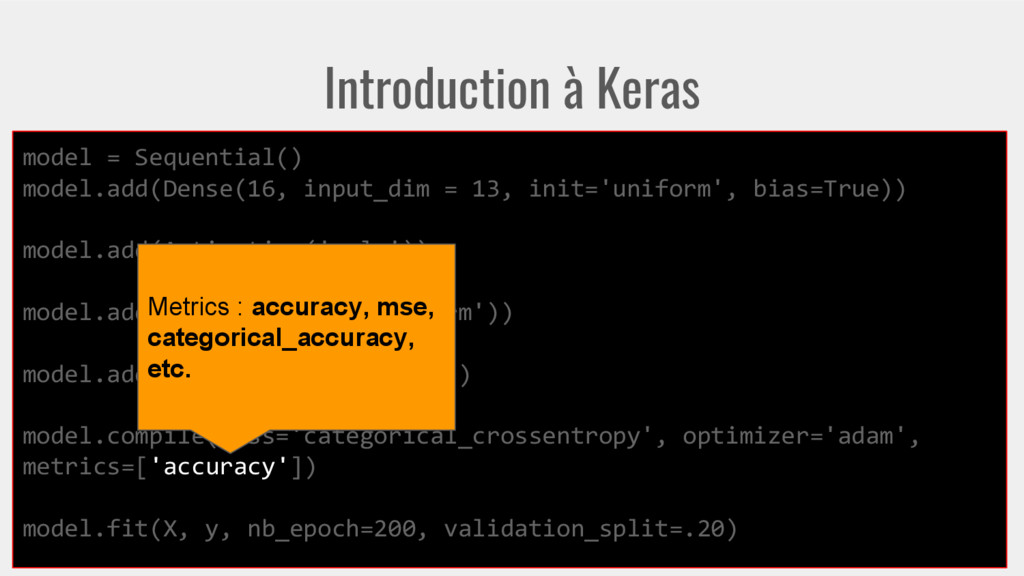
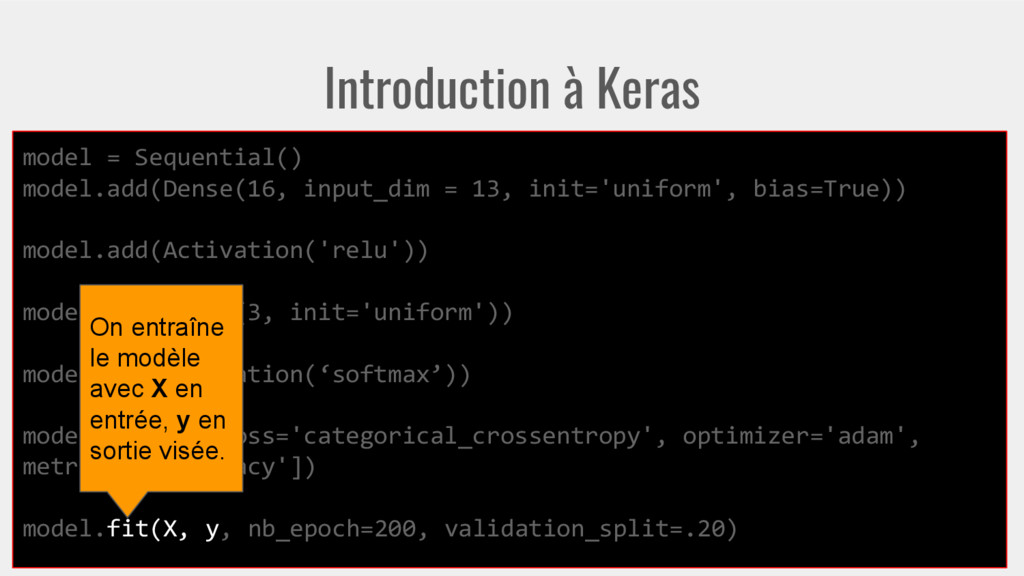
init='uniform', bias=True)) model.add(Activation('relu')) model.add(Dense(3, init='uniform')) model.add(Activation(‘softmax’)) model.compile(loss='categorical_crossentropy', optimizer='adam', metrics=['accuracy']) model.fit(X, y, nb_epoch=200, validation_split=.20) On entraîne le modèle avec X en entrée, y en sortie visée.
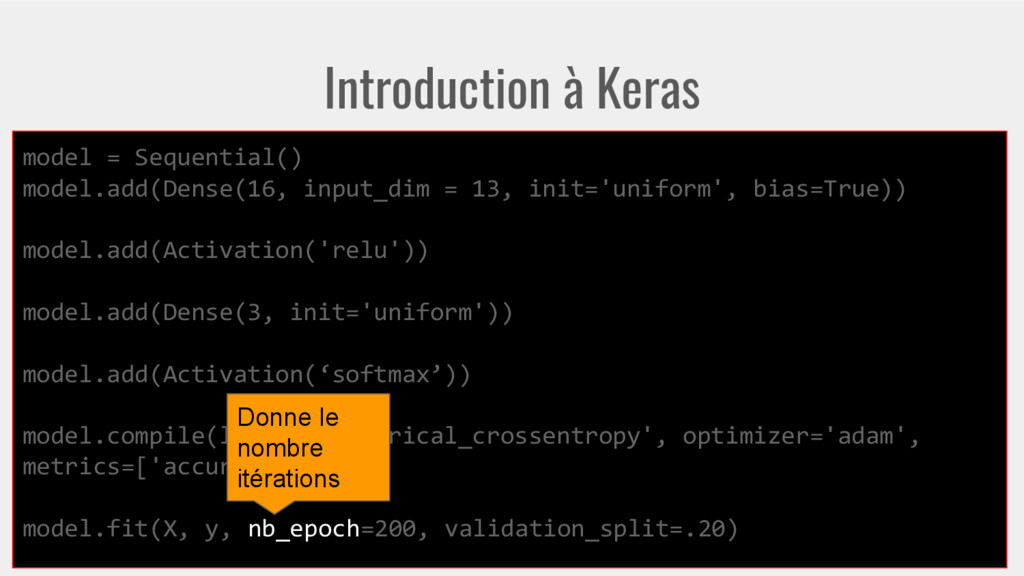
init='uniform', bias=True)) model.add(Activation('relu')) model.add(Dense(3, init='uniform')) model.add(Activation(‘softmax’)) model.compile(loss='categorical_crossentropy', optimizer='adam', metrics=['accuracy']) model.fit(X, y, nb_epoch=200, validation_split=.20) Donne le nombre itérations
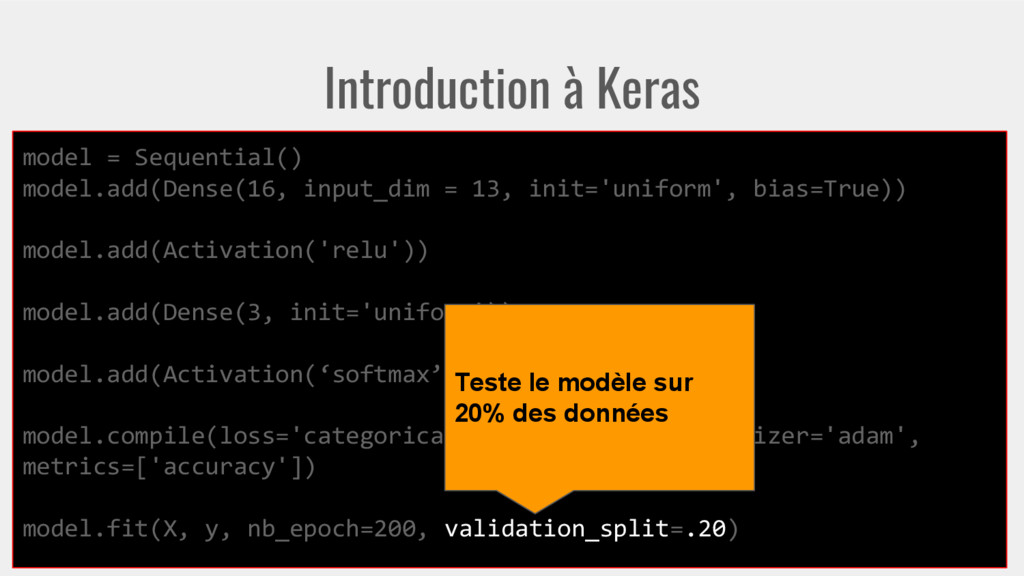
init='uniform', bias=True)) model.add(Activation('relu')) model.add(Dense(3, init='uniform')) model.add(Activation(‘softmax’)) model.compile(loss='categorical_crossentropy', optimizer='adam', metrics=['accuracy']) model.fit(X, y, nb_epoch=200, validation_split=.20) Teste le modèle sur 20% des données
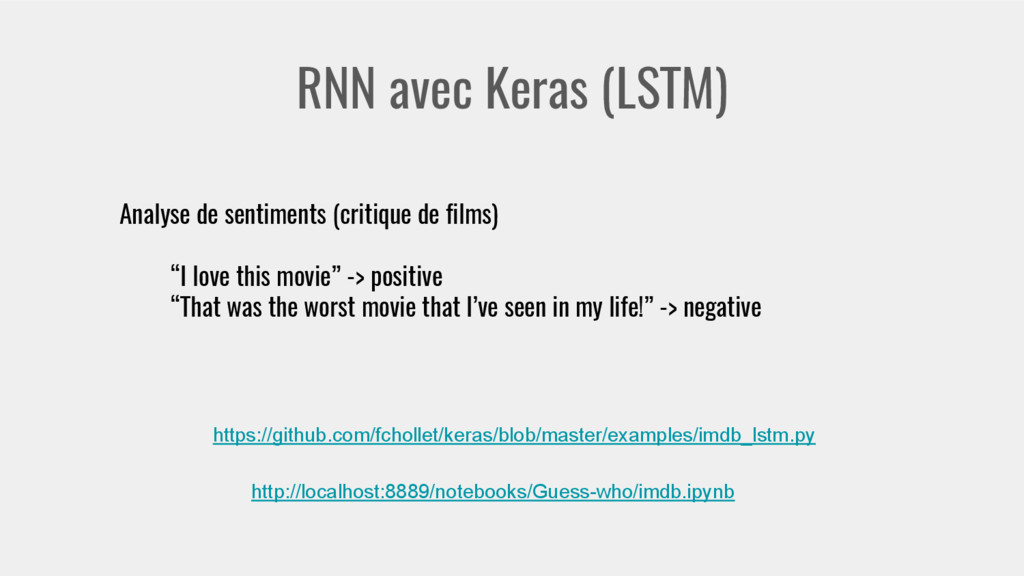
“I love this movie” -> positive “That was the worst movie that I’ve seen in my life!” -> negative http://localhost:8889/notebooks/Guess-who/imdb.ipynb https://github.com/fchollet/keras/blob/master/examples/imdb_lstm.py
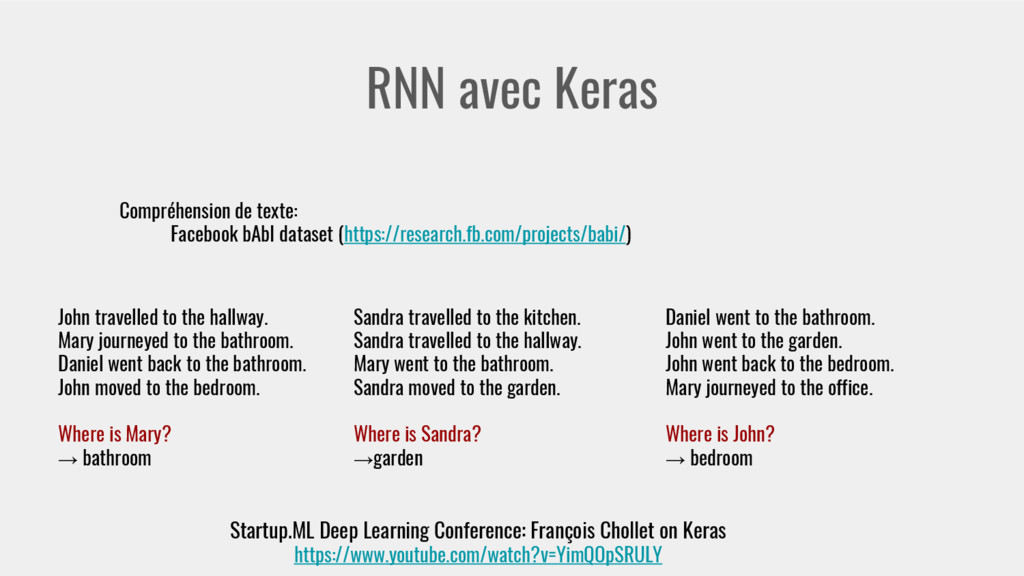
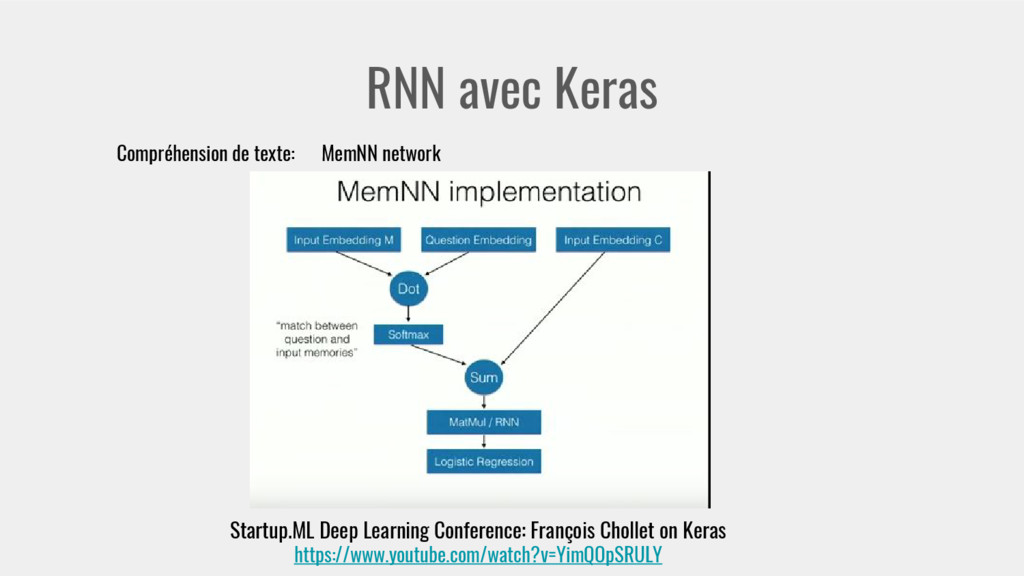
John travelled to the hallway. Mary journeyed to the bathroom. Daniel went back to the bathroom. John moved to the bedroom. Where is Mary? → bathroom Sandra travelled to the kitchen. Sandra travelled to the hallway. Mary went to the bathroom. Sandra moved to the garden. Where is Sandra? →garden Daniel went to the bathroom. John went to the garden. John went back to the bedroom. Mary journeyed to the office. Where is John? → bedroom Startup.ML Deep Learning Conference: François Chollet on Keras https://www.youtube.com/watch?v=YimQOpSRULY
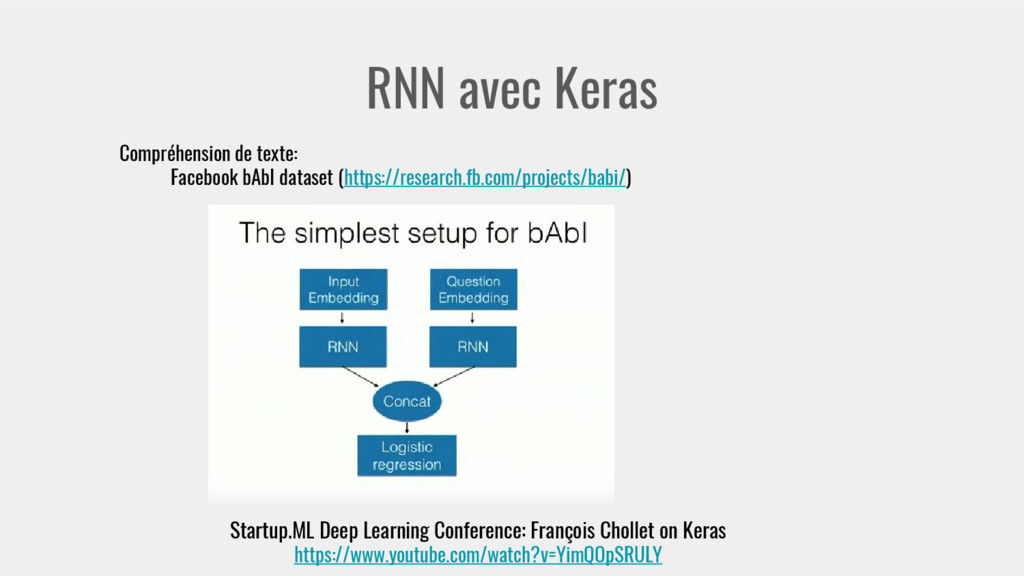
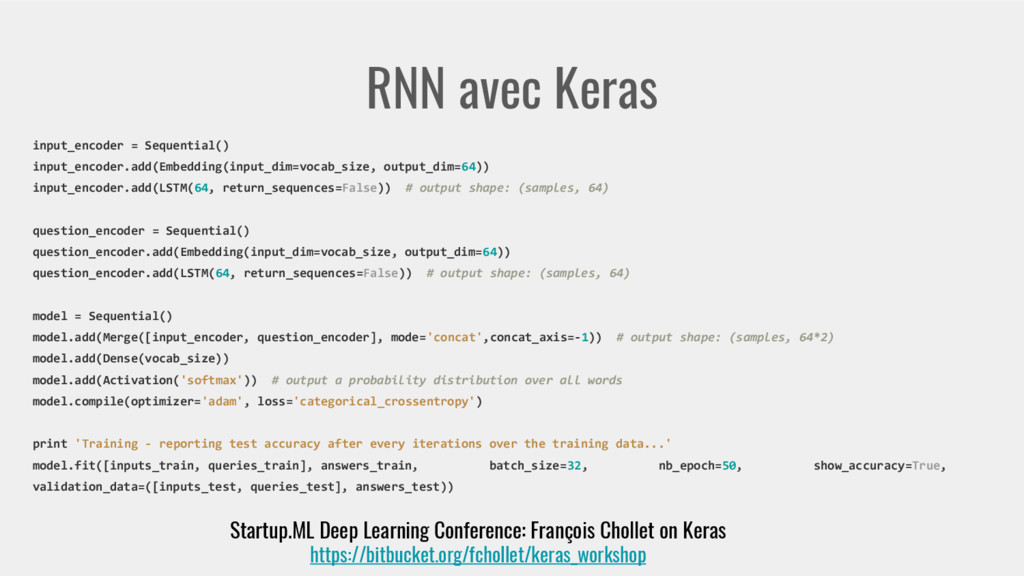
# output shape: (samples, 64) question_encoder = Sequential() question_encoder.add(Embedding(input_dim=vocab_size, output_dim=64)) question_encoder.add(LSTM(64, return_sequences=False)) # output shape: (samples, 64) model = Sequential() model.add(Merge([input_encoder, question_encoder], mode='concat',concat_axis=-1)) # output shape: (samples, 64*2) model.add(Dense(vocab_size)) model.add(Activation('softmax')) # output a probability distribution over all words model.compile(optimizer='adam', loss='categorical_crossentropy') print 'Training - reporting test accuracy after every iterations over the training data...' model.fit([inputs_train, queries_train], answers_train, batch_size=32, nb_epoch=50, show_accuracy=True, validation_data=([inputs_test, queries_test], answers_test)) Startup.ML Deep Learning Conference: François Chollet on Keras https://bitbucket.org/fchollet/keras_workshop
(avec ou sans poids) au format HDF5 • Import des modèles Keras vers Deeplearning4j • Distribution ◦ GPU / Instances avec Tensorflow ◦ Spark ( https://github.com/maxpumperla/elephas )


 mverriez
 hinakko
 shimastripe
 ponponmikankan
 lycorptech_jp
 genda
 simosako
 ts020
 nikkei_engineer_recruiting
 kazzpapa3
 kgnkhkr
 7nohe
 22mi
 livdayseo
 davidcarrasco
 greggifford
 chrislema
 aemeredith
 philnash
 lara
 eitanlees
 wayneb77
 techseoconnect
 caitiem20
 lcolladotor