Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
PostgreSQL オプティマイザ統計の秘密
Search
Noriyoshi Shinoda
November 04, 2026
Technology
110
0
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
PostgreSQL オプティマイザ統計の秘密
PostgreSQL optimizer statistic summary
Noriyoshi Shinoda
November 04, 2026
More Decks by Noriyoshi Shinoda
See All by Noriyoshi Shinoda
PostgreSQL 19 新機能概要 OSC Hokkaido 2026
nori_shinoda
0
480
SEQUENCE object comparison - db tech showcase 2025 LT2
nori_shinoda
1
930
JPOUG Tech Talk #12 UNDO Tablespace Reintroduction
nori_shinoda
3
710
PostgreSQL Unconference #52 pg_tde
nori_shinoda
1
770
PostgreSQL Conference Japan 2024 A4 Comparison of column-oriented access methods
nori_shinoda
0
460
Implementation Dependencies in the Commonly Used SQL
nori_shinoda
4
630
関西DB勉強会 #14 PostgreSQL の進化と最新バージョン情報
nori_shinoda
0
770
JPOUG#7 Oracle Database 23c New Features
nori_shinoda
1
3.4k
Other Decks in Technology
See All in Technology
Autonomous AI Lakehouse - Live AI Hubから始めるセキュアなAIデータ活用 -
oracle4engineer
PRO
2
190
クラウドエージェントの先駆け Devin。今も最先端を走る、他との違い
kinopeee
2
550
今から始めるAWS環境の暗号移行 - ポスト量子時代に備える
sato4mi
0
150
IoTとは〜? 数字で見るSORACOM UG【SORACOM UG Explorer 2026】
soracom
PRO
0
100
なぜAI時代に技術記事を書くのか?どう書くのか? 〜bunの場合〜
kworkdev
PRO
0
4.6k
(swiftc) NonCopyableとライフタイム修飾子
teamhimeh
0
170
キヨさん、67歳。AIコーディングエージェントに挑む
happysamurai294
0
140
Jev の中身は50行で再現できる。でも本物との差はどこにあるのか
hisuzuya
0
280
Deep Data Security 機能解説
oracle4engineer
PRO
3
1k
AI時代のエンジニアの情報発信〜個人の発信を組織の力に変える〜
ryo_kawamata
0
6.9k
増え続けるプロダクトの品質をどう担保するか。ProductSpecとTypeScriptによる取り組み
joere
3
340
Copilot Coworkで「みのるん式」やってみた
minorun365
PRO
1
1.1k
Featured
See All Featured
Designing for Performance
lara
612
70k
HDC tutorial
michielstock
2
990
The SEO identity crisis: Don't let AI make you average
varn
0
620
The Organizational Zoo: Understanding Human Behavior Agility Through Metaphoric Constructive Conversations (based on the works of Arthur Shelley, Ph.D)
kimpetersen
PRO
0
520
How to audit for AI Accessibility on your Front & Back End
davetheseo
0
620
How to optimise 3,500 product descriptions for ecommerce in one day using ChatGPT
katarinadahlin
PRO
3
3.9k
Imperfection Machines: The Place of Print at Facebook
scottboms
270
14k
Side Projects
sachag
456
43k
SEO in 2025: How to Prepare for the Future of Search
ipullrank
3
3.9k
Music & Morning Musume
bryan
48
7.5k
Dealing with People You Can't Stand - Big Design 2015
cassininazir
367
27k
Test your architecture with Archunit
thirion
2
2.5k
Transcript
CM2 12:35~13:00 PostgreSQL オプティマイザ統計の秘密 Noriyoshi Shinoda November 5, 2026
SPEAKER ✓篠田 典良(しのだ のりよし) ✓所属 ✓ 日本ヒューレット・パッカード合同会社 ✓現在の業務など ✓ PostgreSQL
をはじめ Oracle Database, Microsoft SQL Server, Vertica 等 RDBMS 全般に関するシステムの設計、移行、チューニング、コンサルティング ✓ Oracle ACE Pro (2009~) ✓ PostgreSQL 開発 (PostgreSQL 10~19) ✓ 「篠田の虎の巻」作成 ✓関連する URL ✓ Oracle ACE Profile https://ace.oracle.com/apex/ace/profile/nshino483 ✓ 「PostgreSQL 虎の巻」シリーズ https://github.com/nori-shinoda/documents/blob/main/README.md ✓ Redgate 100 in 2022 (Most influential in the database community 2022) https://www.red-gate.com/hub/redgate-100/ © 2026 Hewlett Packard Enterprise Development LP 2
PostgreSQL の最新情報 バージョン ✓PostgreSQL とは? ✓ 公式: https://www.postgresql.org/ ✓ 日本
PostgreSQL ユーザ会(日本語マニュアル): https://www.postgresql.jp/ ✓バージョンアップ ✓ メジャー・バージョンは毎年一回公開(=新機能の追加) ✓ マイナー・バージョンは3か月に一回公開される(=バグフィックス版/脆弱性への対応) ✓最新バージョン ✓ PostgreSQL 18 (18.6) が最新 ✓ PostgreSQL 19 Release Candidate 1 (RC1) が公開中、2026/11/12 RC2 公開予定 ✓ PostgreSQL 19 (19.0) GA は 2026/11/19 公開予定 ✓ PostgreSQL 20 (20.0) dev は開発中 © 2026 Hewlett Packard Enterprise Development LP 3
オプティマイザ統計とは? オプティマイザ統計とは? ✓オプティマイザが実行計画のコストを計算する際に参照する以下のような情報 ✓ レコード数 ✓ ブロック数 ✓ 列値の平均サイズ ✓
列値の分散 ✓ 最頻値 ✓ Etc ✓ひとことで言えばテーブルに格納されたデータのメタ情報 ✓具体的には後述 © 2026 Hewlett Packard Enterprise Development LP 4
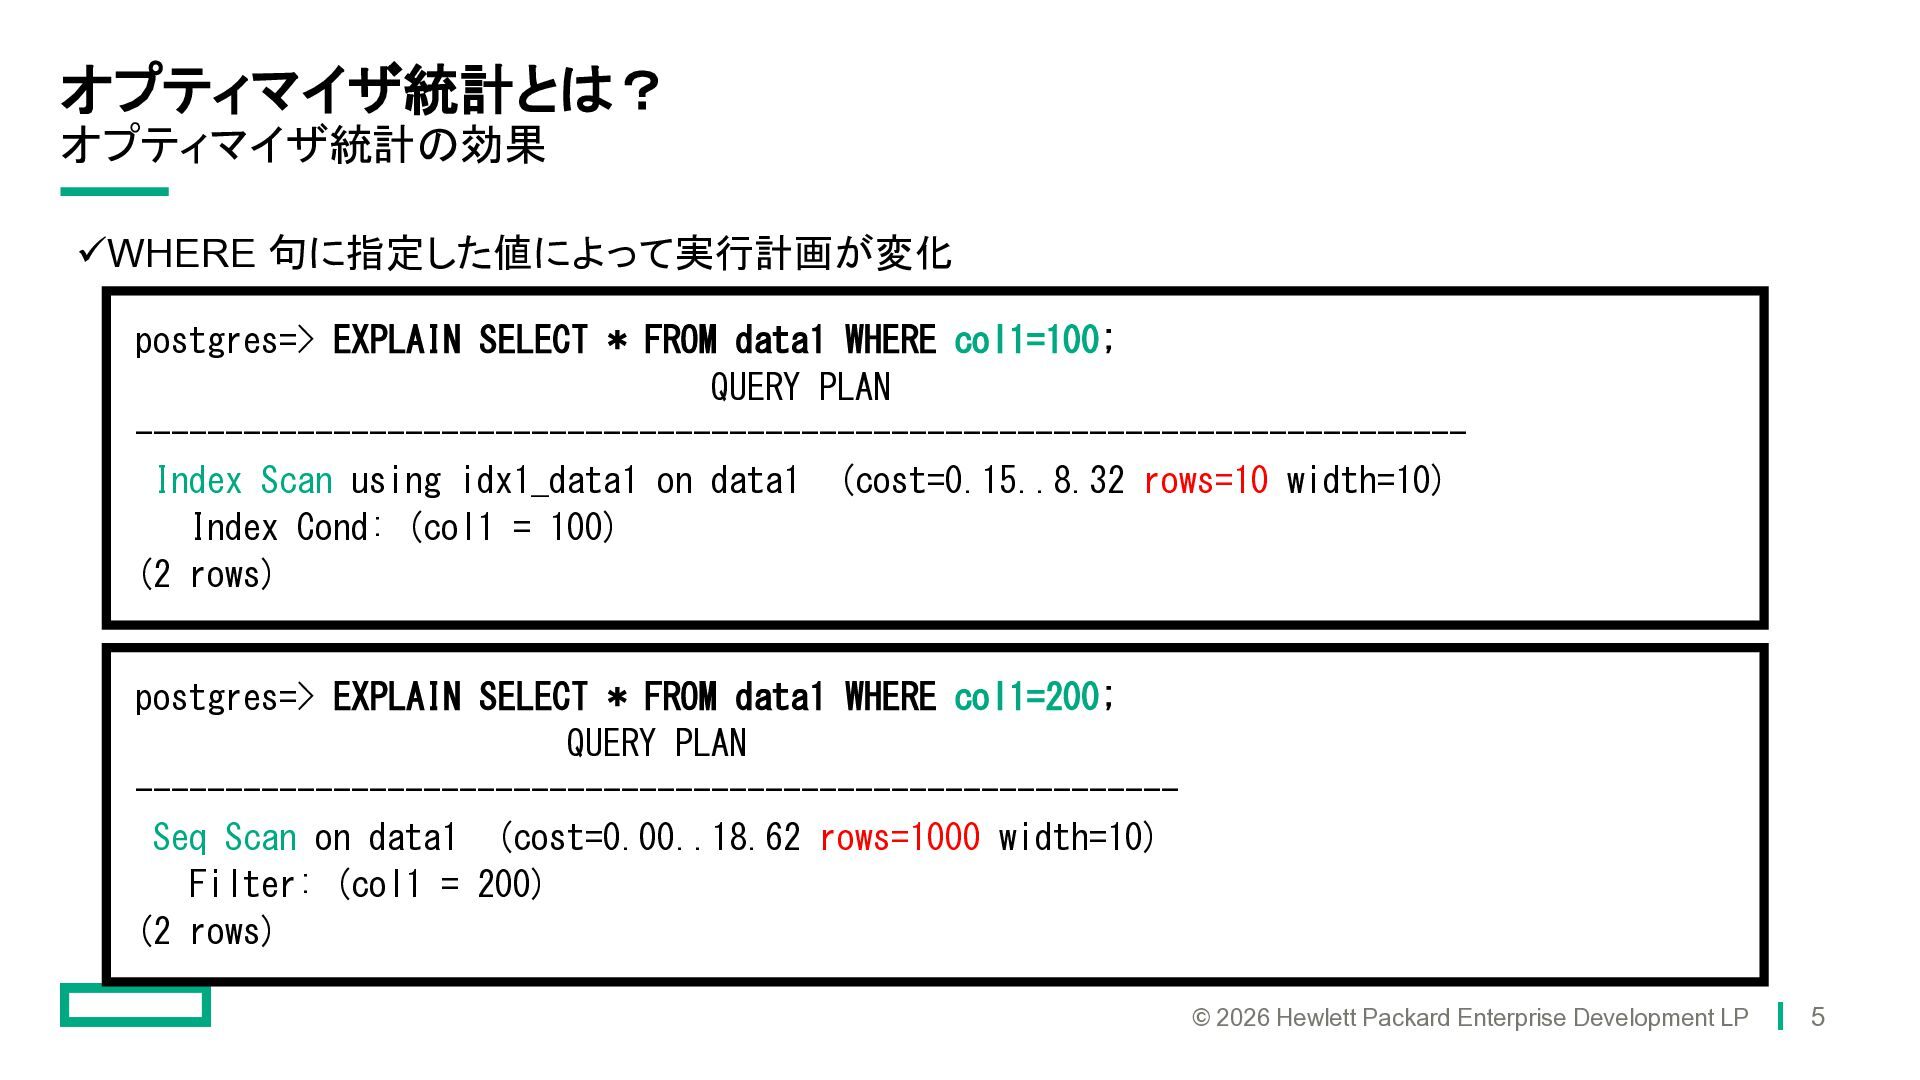
オプティマイザ統計とは? オプティマイザ統計の効果 ✓WHERE 句に指定した値によって実行計画が変化 postgres=> EXPLAIN SELECT * FROM data1
WHERE col1=100; QUERY PLAN -------------------------------------------------------------------------Index Scan using idx1_data1 on data1 (cost=0.15..8.32 rows=10 width=10) Index Cond: (col1 = 100) (2 rows) postgres=> EXPLAIN SELECT * FROM data1 WHERE col1=200; QUERY PLAN ---------------------------------------------------------Seq Scan on data1 (cost=0.00..18.62 rows=1000 width=10) Filter: (col1 = 200) (2 rows) © 2026 Hewlett Packard Enterprise Development LP 5
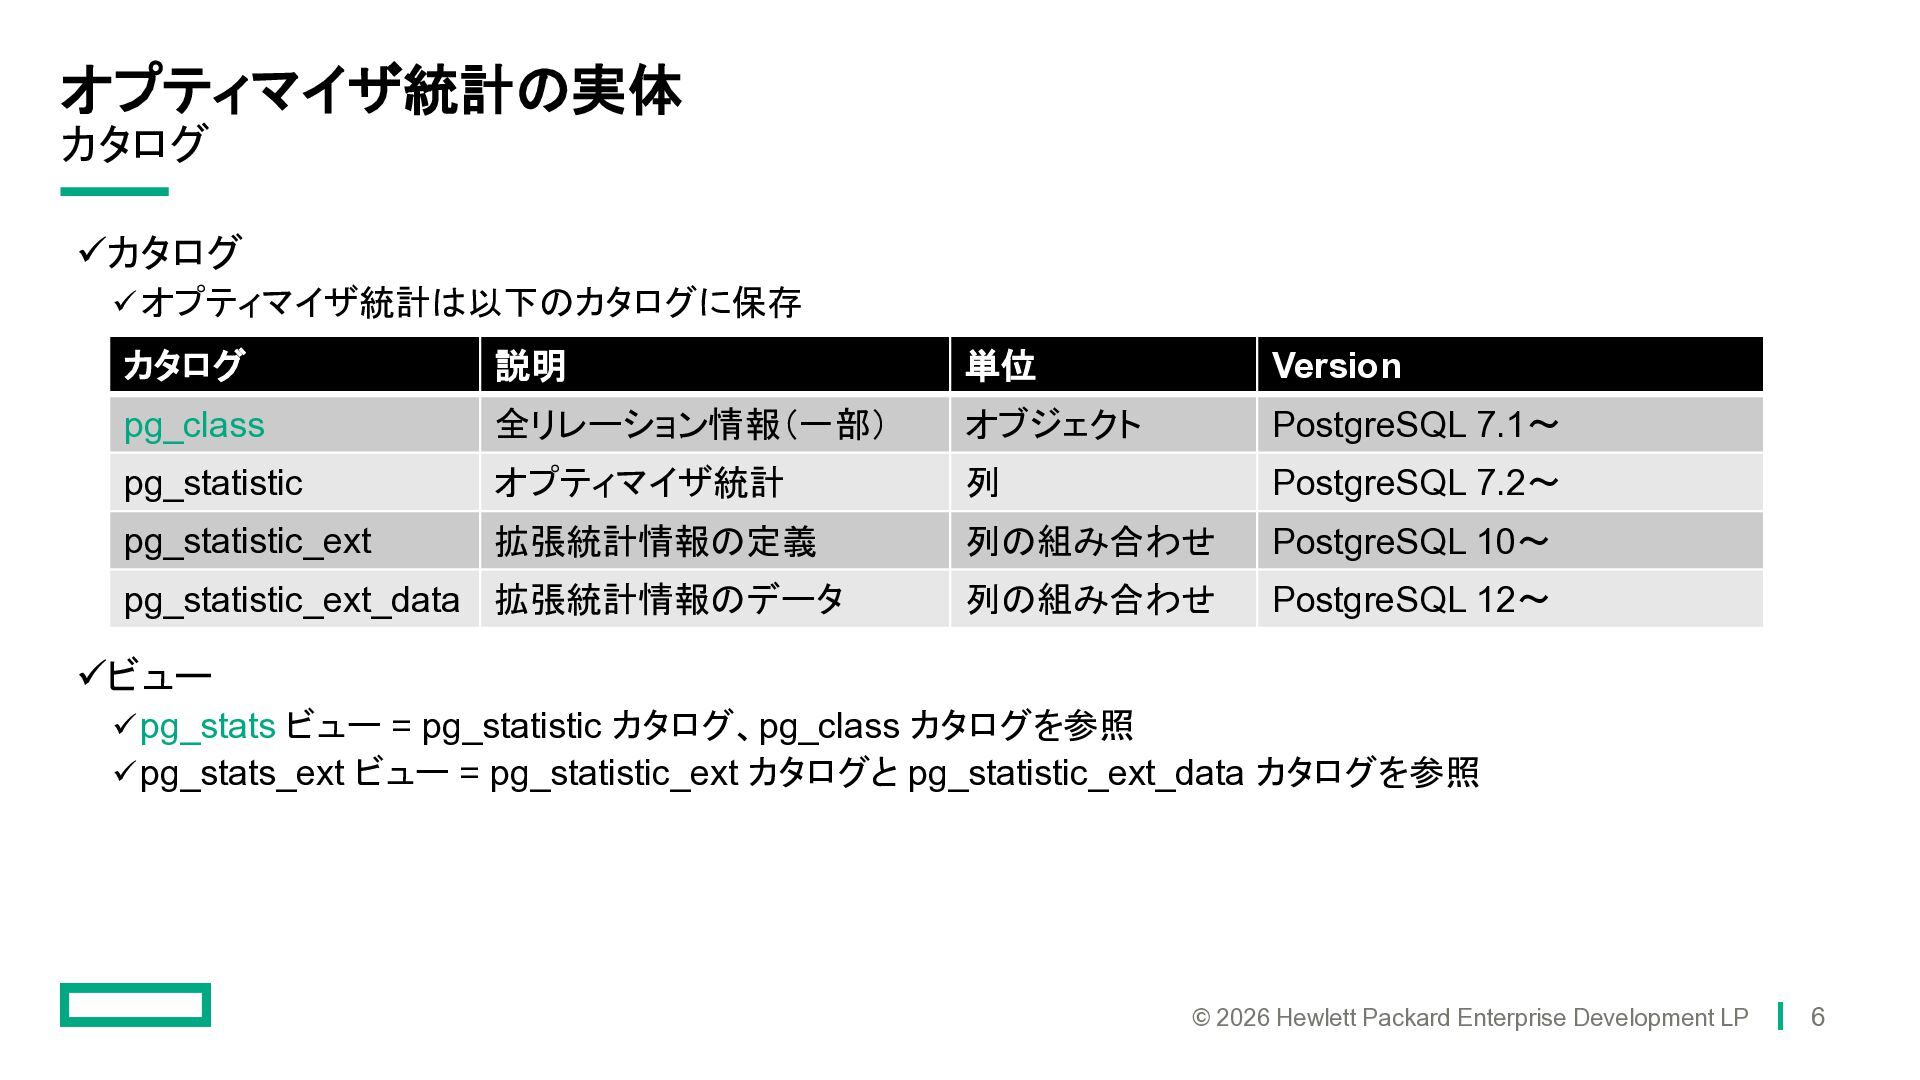
オプティマイザ統計の実体 カタログ ✓カタログ ✓ オプティマイザ統計は以下のカタログに保存 カタログ 説明 単位 Version pg_class
全リレーション情報(一部) オブジェクト PostgreSQL 7.1~ pg_statistic オプティマイザ統計 列 PostgreSQL 7.2~ pg_statistic_ext 拡張統計情報の定義 列の組み合わせ PostgreSQL 10~ pg_statistic_ext_data 拡張統計情報のデータ 列の組み合わせ PostgreSQL 12~ ✓ビュー ✓ pg_stats ビュー = pg_statistic カタログ、pg_class カタログを参照 ✓ pg_stats_ext ビュー = pg_statistic_ext カタログと pg_statistic_ext_data カタログを参照 © 2026 Hewlett Packard Enterprise Development LP 6
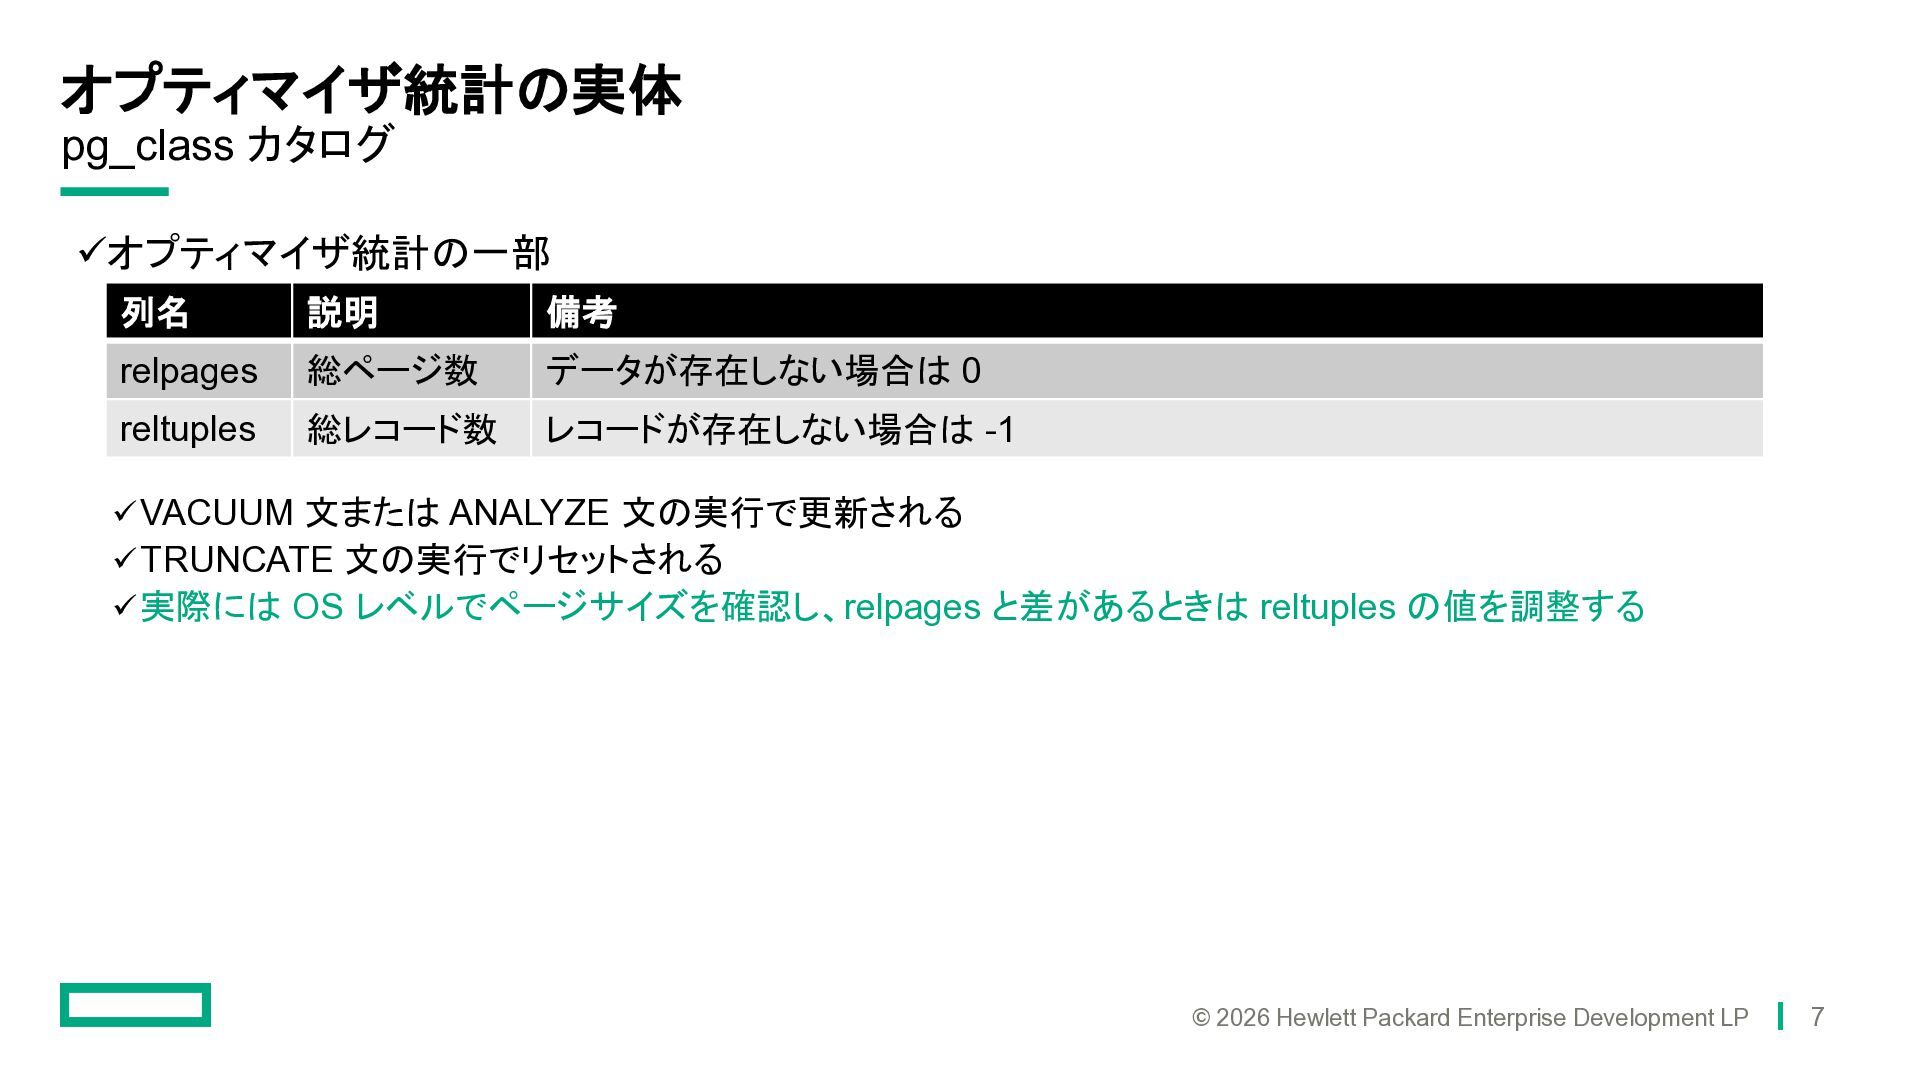
オプティマイザ統計の実体 pg_class カタログ ✓オプティマイザ統計の一部 列名 説明 備考 relpages 総ページ数 データが存在しない場合は
0 reltuples 総レコード数 レコードが存在しない場合は -1 ✓ VACUUM 文または ANALYZE 文の実行で更新される ✓ TRUNCATE 文の実行でリセットされる ✓ 実際には OS レベルでページサイズを確認し、relpages と差があるときは reltuples の値を調整する © 2026 Hewlett Packard Enterprise Development LP 7
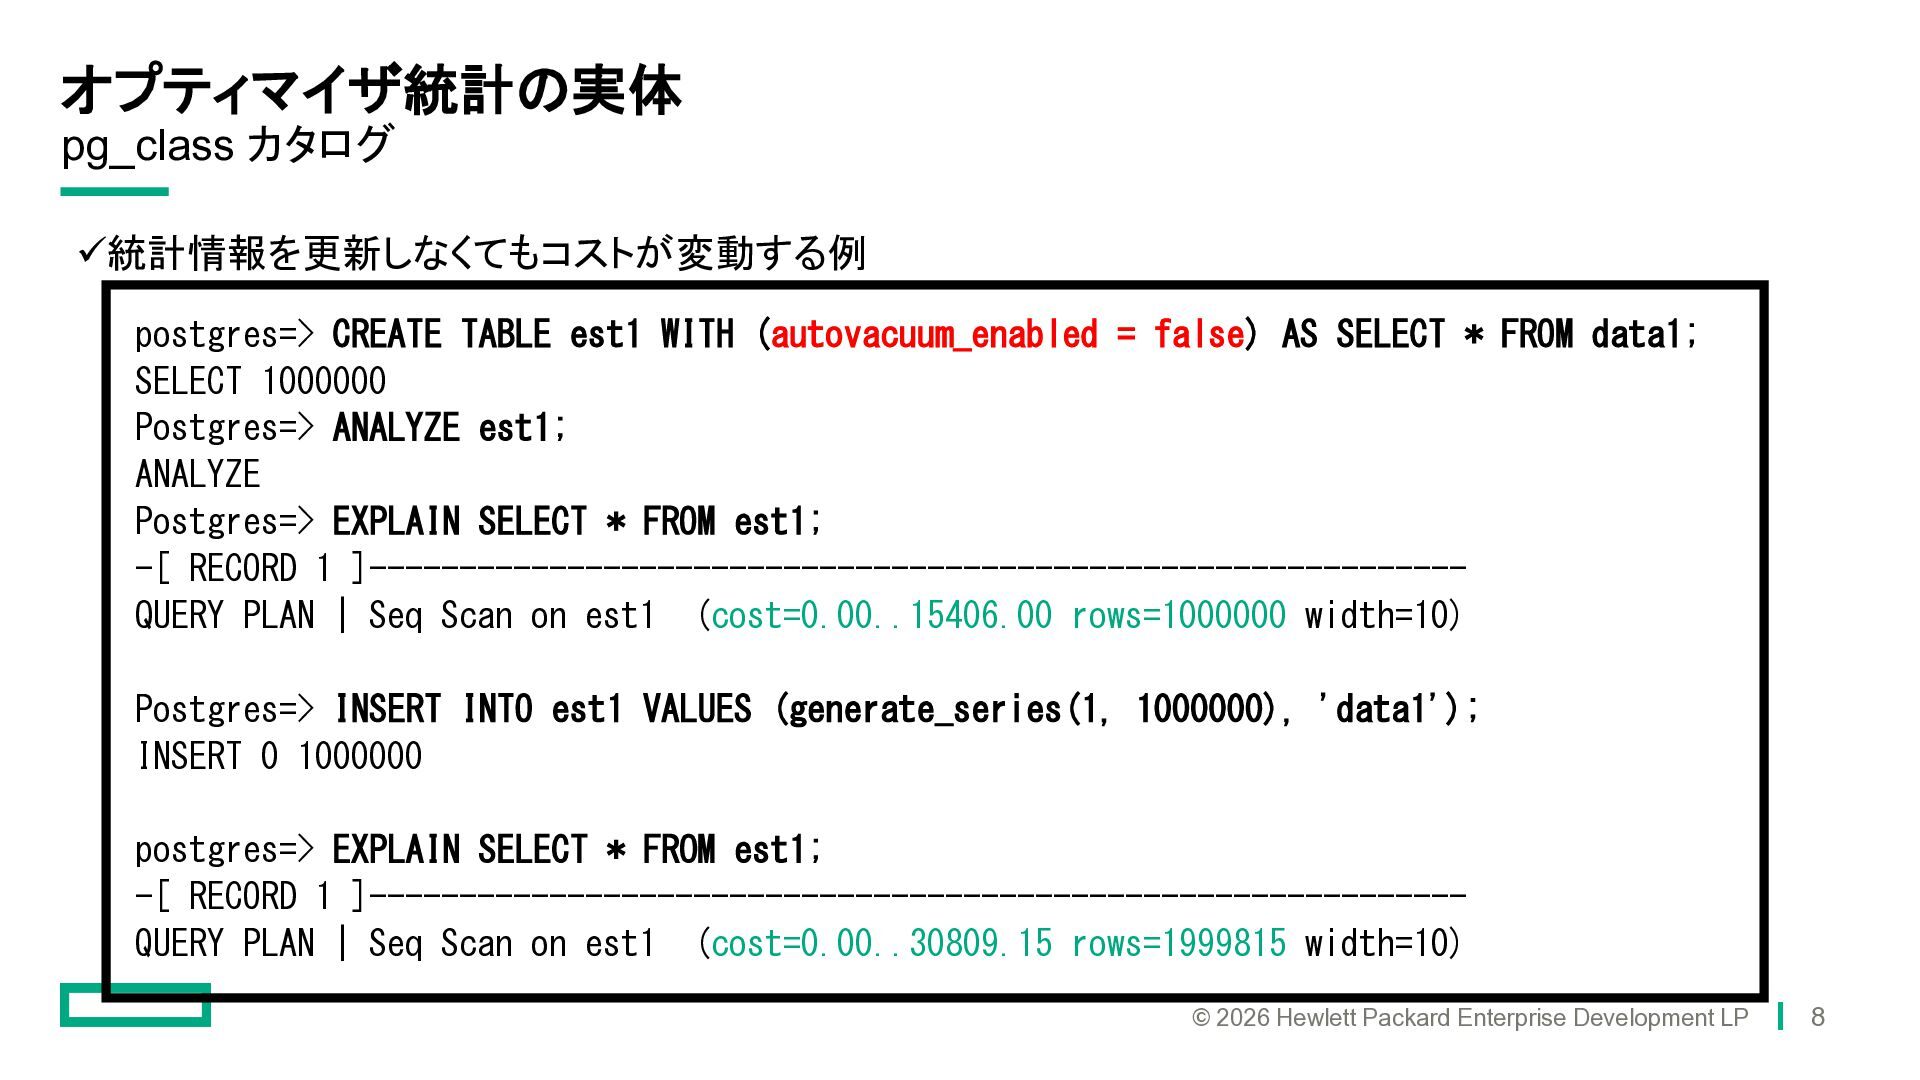
オプティマイザ統計の実体 pg_class カタログ ✓統計情報を更新しなくてもコストが変動する例 postgres=> CREATE TABLE est1 WITH (autovacuum_enabled
= false) AS SELECT * FROM data1; SELECT 1000000 Postgres=> ANALYZE est1; ANALYZE Postgres=> EXPLAIN SELECT * FROM est1; -[ RECORD 1 ]------------------------------------------------------------QUERY PLAN | Seq Scan on est1 (cost=0.00..15406.00 rows=1000000 width=10) Postgres=> INSERT INTO est1 VALUES (generate_series(1, 1000000), 'data1'); INSERT 0 1000000 postgres=> EXPLAIN SELECT * FROM est1; -[ RECORD 1 ]------------------------------------------------------------QUERY PLAN | Seq Scan on est1 (cost=0.00..30809.15 rows=1999815 width=10) © 2026 Hewlett Packard Enterprise Development LP 8
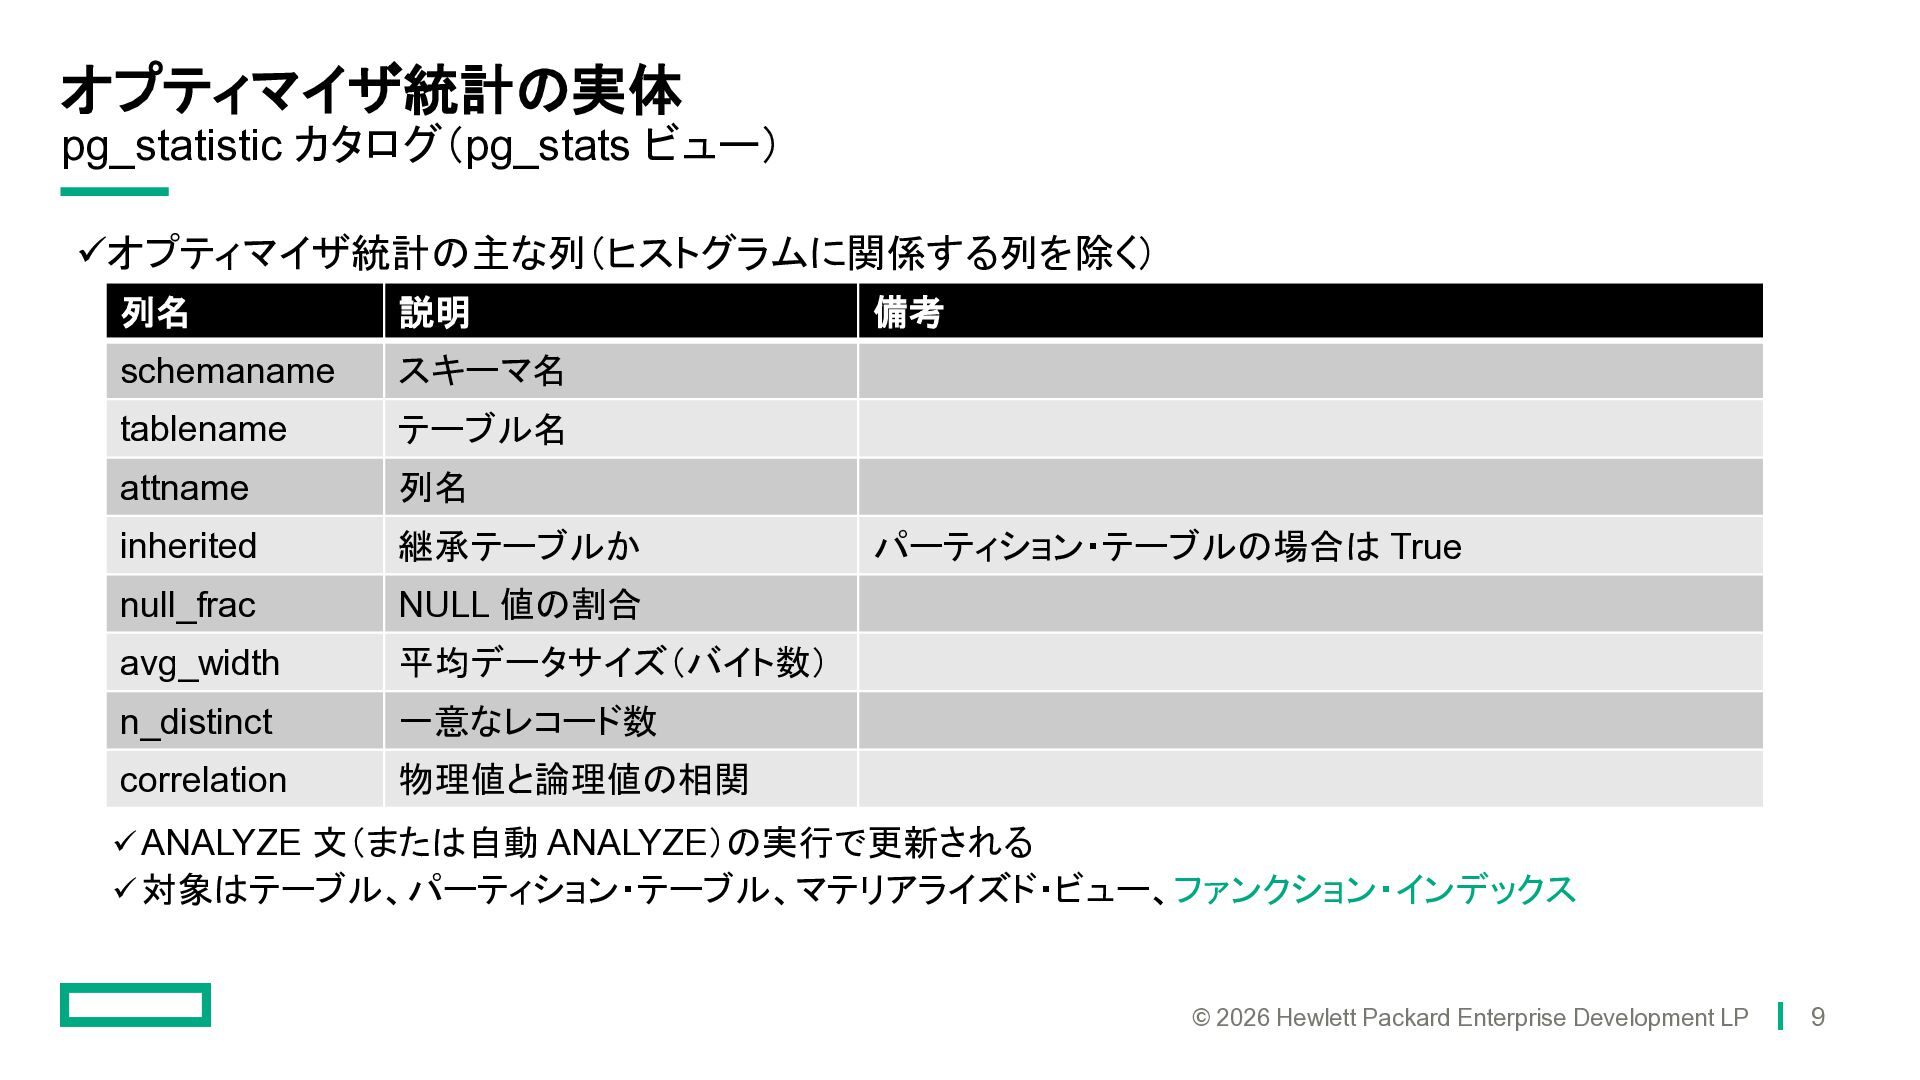
オプティマイザ統計の実体 pg_statistic カタログ(pg_stats ビュー) ✓オプティマイザ統計の主な列(ヒストグラムに関係する列を除く) 列名 説明 schemaname スキーマ名 tablename
テーブル名 attname 列名 inherited 継承テーブルか null_frac NULL 値の割合 avg_width 平均データサイズ(バイト数) n_distinct 一意なレコード数 correlation 物理値と論理値の相関 備考 パーティション・テーブルの場合は True ✓ ANALYZE 文(または自動 ANALYZE)の実行で更新される ✓ 対象はテーブル、パーティション・テーブル、マテリアライズド・ビュー、ファンクション・インデックス © 2026 Hewlett Packard Enterprise Development LP 9
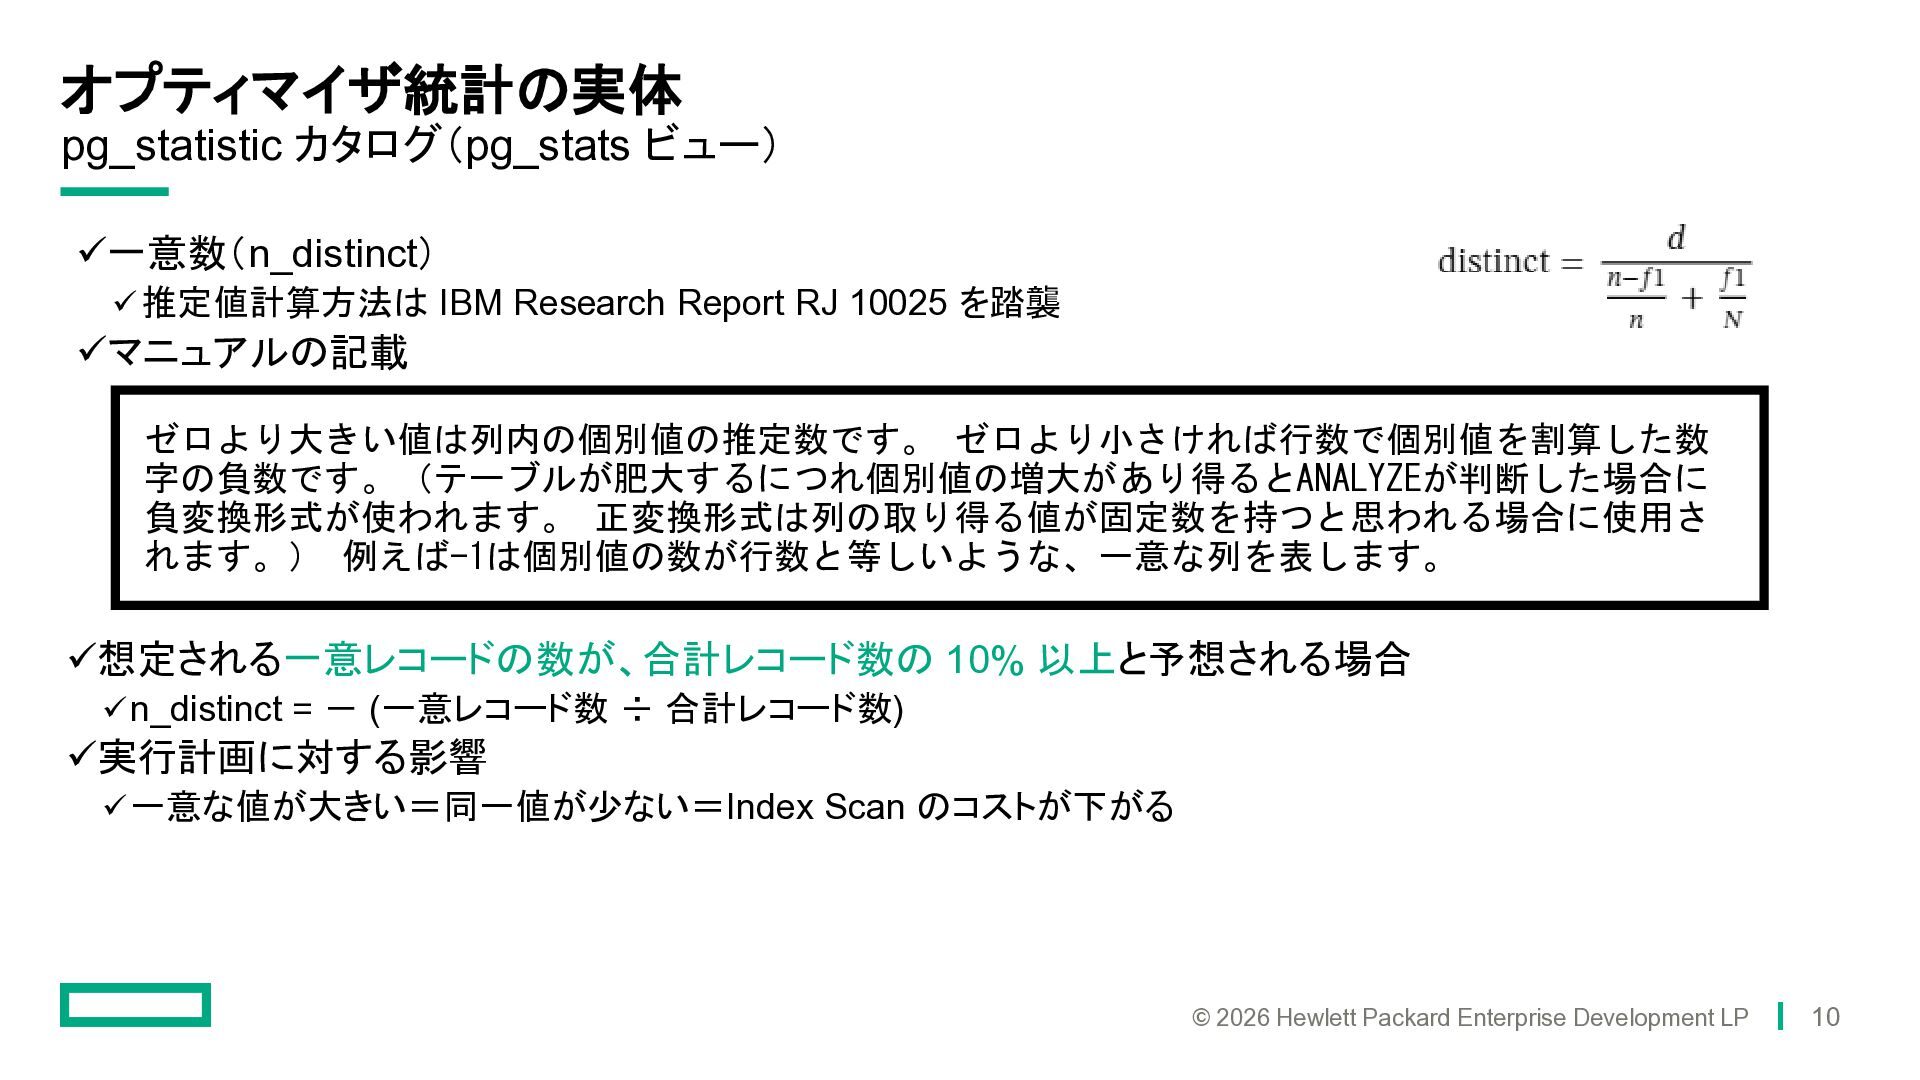
オプティマイザ統計の実体 pg_statistic カタログ(pg_stats ビュー) ✓一意数(n_distinct) ✓ 推定値計算方法は IBM Research Report
RJ 10025 を踏襲 ✓マニュアルの記載 ゼロより大きい値は列内の個別値の推定数です。 ゼロより小さければ行数で個別値を割算した数 字の負数です。(テーブルが肥大するにつれ個別値の増大があり得るとANALYZEが判断した場合に 負変換形式が使われます。 正変換形式は列の取り得る値が固定数を持つと思われる場合に使用さ れます。) 例えば-1は個別値の数が行数と等しいような、一意な列を表します。 ✓想定される一意レコードの数が、合計レコード数の 10% 以上と予想される場合 ✓ n_distinct = - (一意レコード数 ÷ 合計レコード数) ✓実行計画に対する影響 ✓ 一意な値が大きい=同一値が少ない=Index Scan のコストが下がる © 2026 Hewlett Packard Enterprise Development LP 10
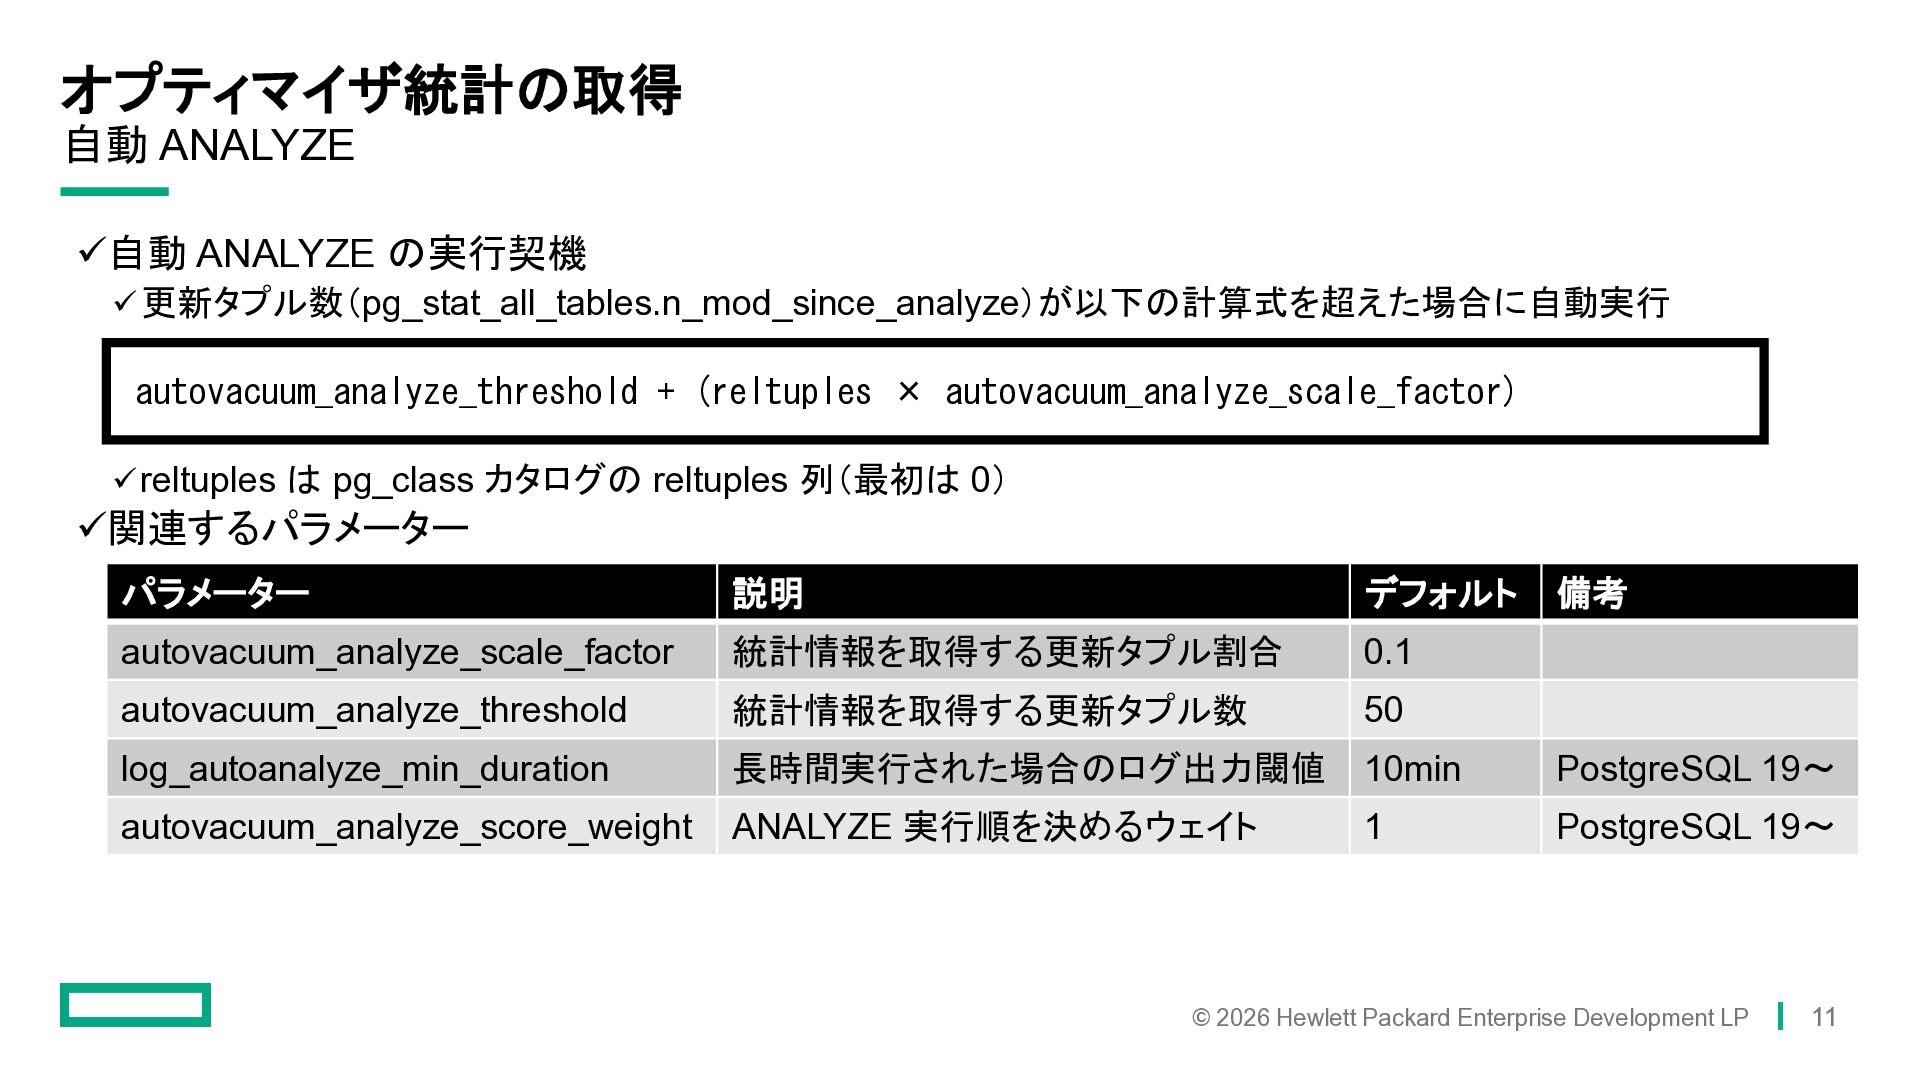
オプティマイザ統計の取得 自動 ANALYZE ✓自動 ANALYZE の実行契機 ✓ 更新タプル数(pg_stat_all_tables.n_mod_since_analyze)が以下の計算式を超えた場合に自動実行 autovacuum_analyze_threshold +
(reltuples × autovacuum_analyze_scale_factor) ✓ reltuples は pg_class カタログの reltuples 列(最初は 0) ✓関連するパラメーター パラメーター 説明 デフォルト 備考 autovacuum_analyze_scale_factor 統計情報を取得する更新タプル割合 0.1 autovacuum_analyze_threshold 統計情報を取得する更新タプル数 50 log_autoanalyze_min_duration 長時間実行された場合のログ出力閾値 10min PostgreSQL 19~ autovacuum_analyze_score_weight ANALYZE 実行順を決めるウェイト 1 PostgreSQL 19~ © 2026 Hewlett Packard Enterprise Development LP 11
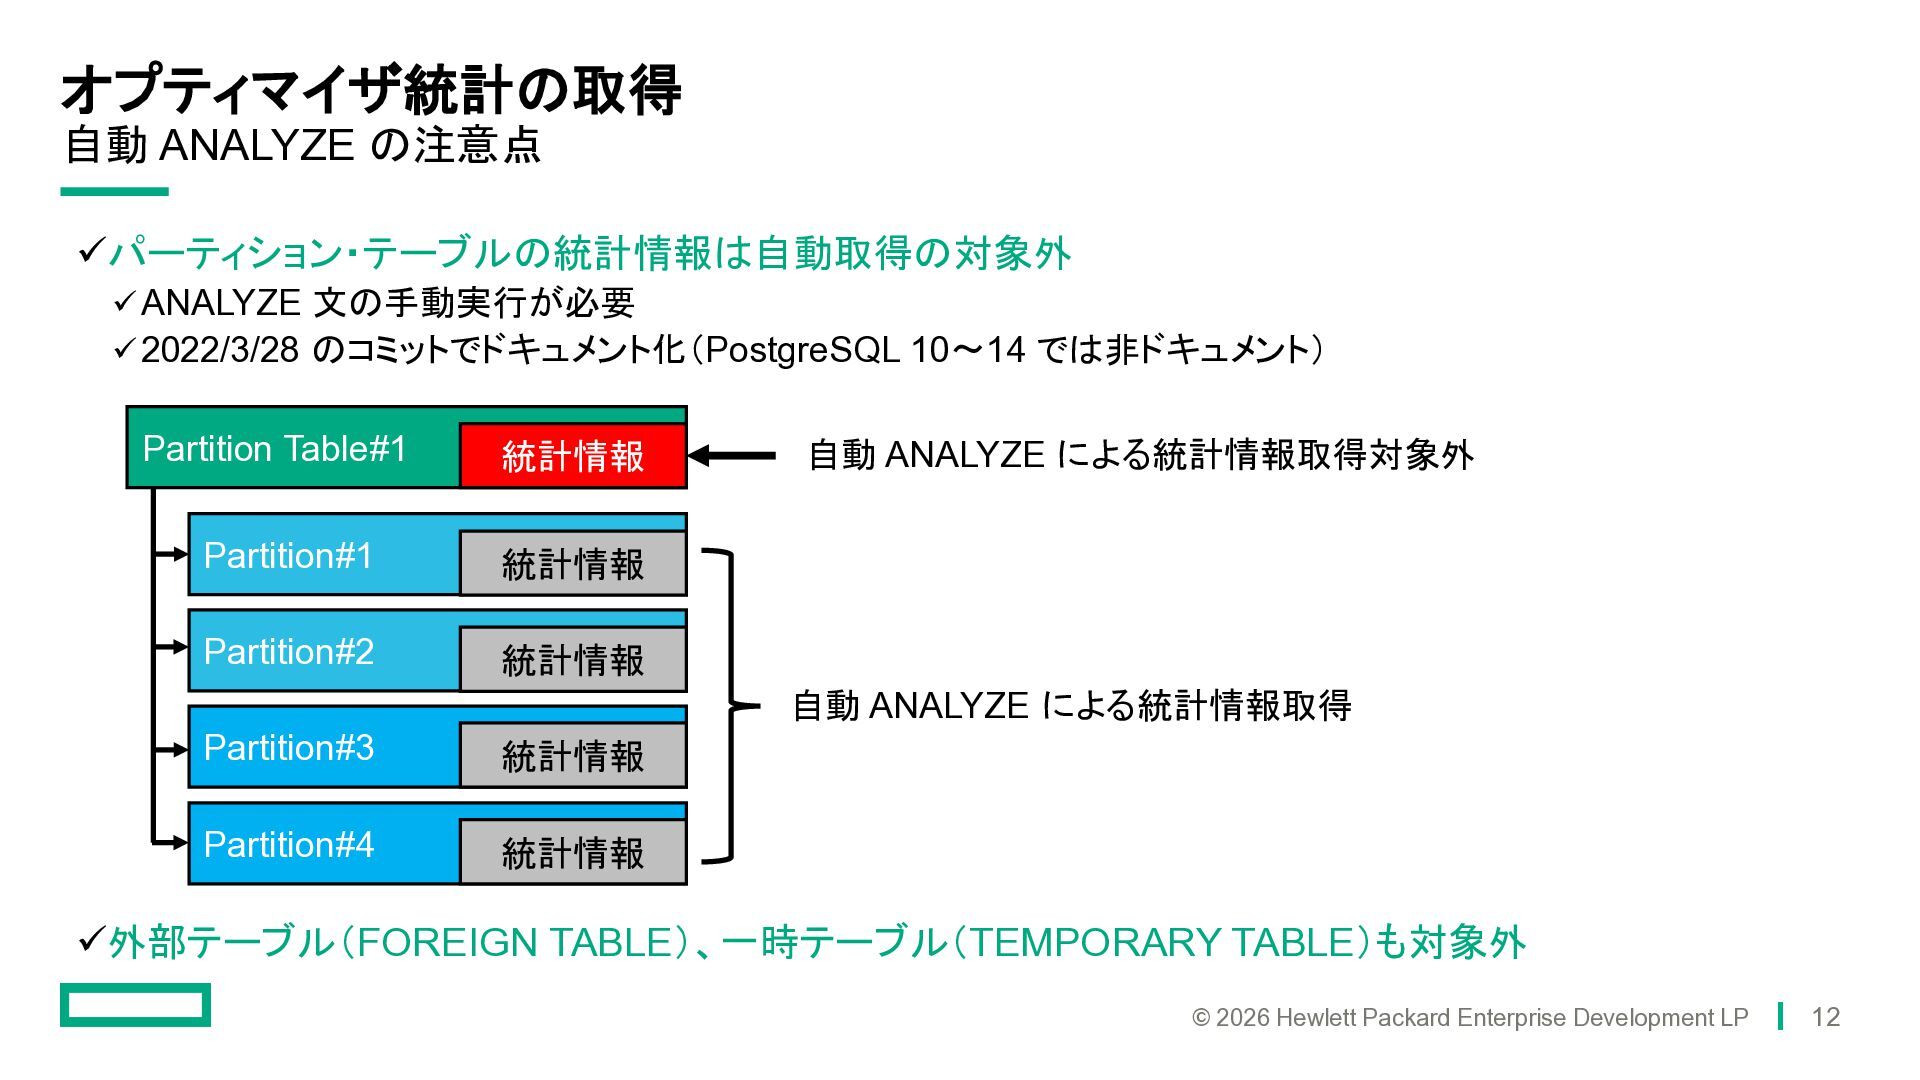
オプティマイザ統計の取得 自動 ANALYZE の注意点 ✓パーティション・テーブルの統計情報は自動取得の対象外 ✓ ANALYZE 文の手動実行が必要 ✓ 2022/3/28
のコミットでドキュメント化(PostgreSQL 10~14 では非ドキュメント) Partition Table#1 統計情報 Partition#1 統計情報 Partition#2 統計情報 自動 ANALYZE による統計情報取得対象外 自動 ANALYZE による統計情報取得 Partition#3 統計情報 Partition#4 統計情報 ✓外部テーブル(FOREIGN TABLE)、一時テーブル(TEMPORARY TABLE)も対象外 © 2026 Hewlett Packard Enterprise Development LP 12
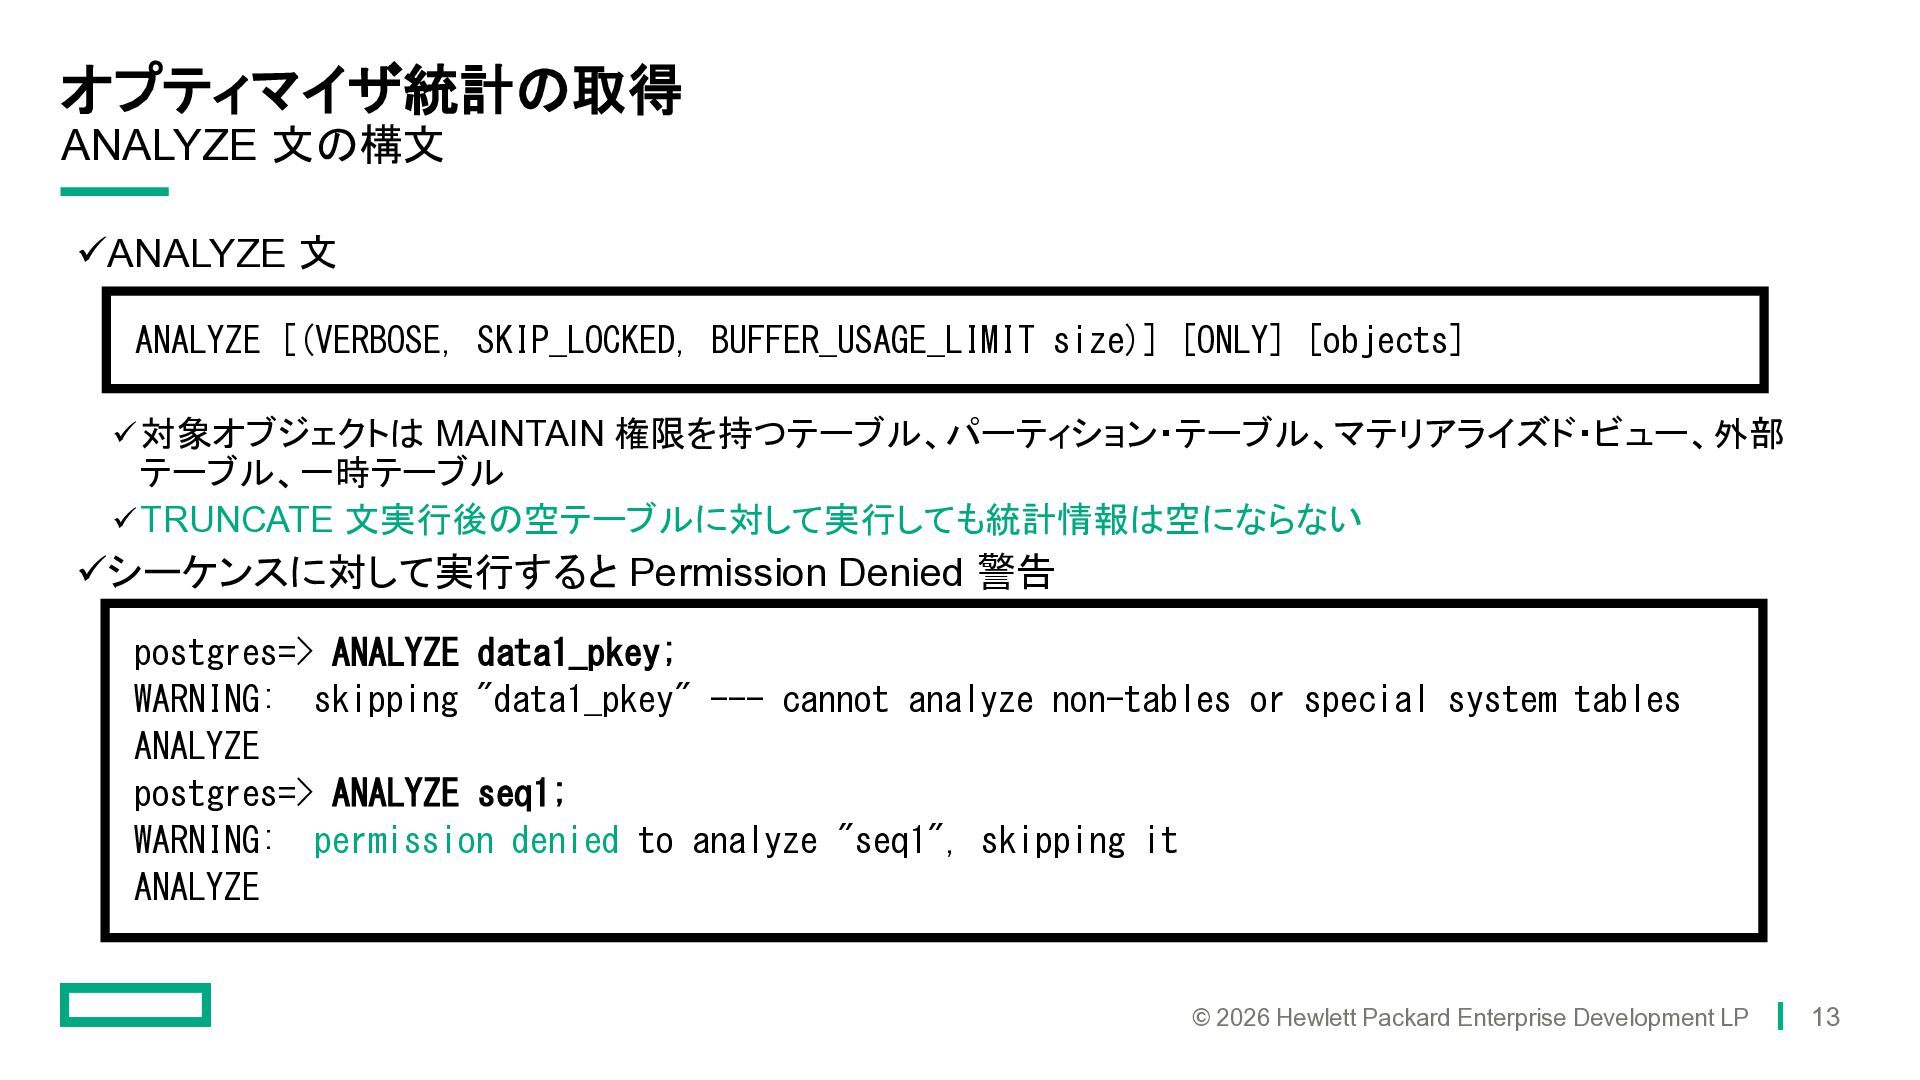
オプティマイザ統計の取得 ANALYZE 文の構文 ✓ANALYZE 文 ANALYZE [(VERBOSE, SKIP_LOCKED, BUFFER_USAGE_LIMIT size)]
[ONLY] [objects] ✓ 対象オブジェクトは MAINTAIN 権限を持つテーブル、パーティション・テーブル、マテリアライズド・ビュー、外部 テーブル、一時テーブル ✓ TRUNCATE 文実行後の空テーブルに対して実行しても統計情報は空にならない ✓シーケンスに対して実行すると Permission Denied 警告 postgres=> ANALYZE data1_pkey; WARNING: skipping "data1_pkey" --- cannot analyze non-tables or special system tables ANALYZE postgres=> ANALYZE seq1; WARNING: permission denied to analyze "seq1", skipping it ANALYZE © 2026 Hewlett Packard Enterprise Development LP 13
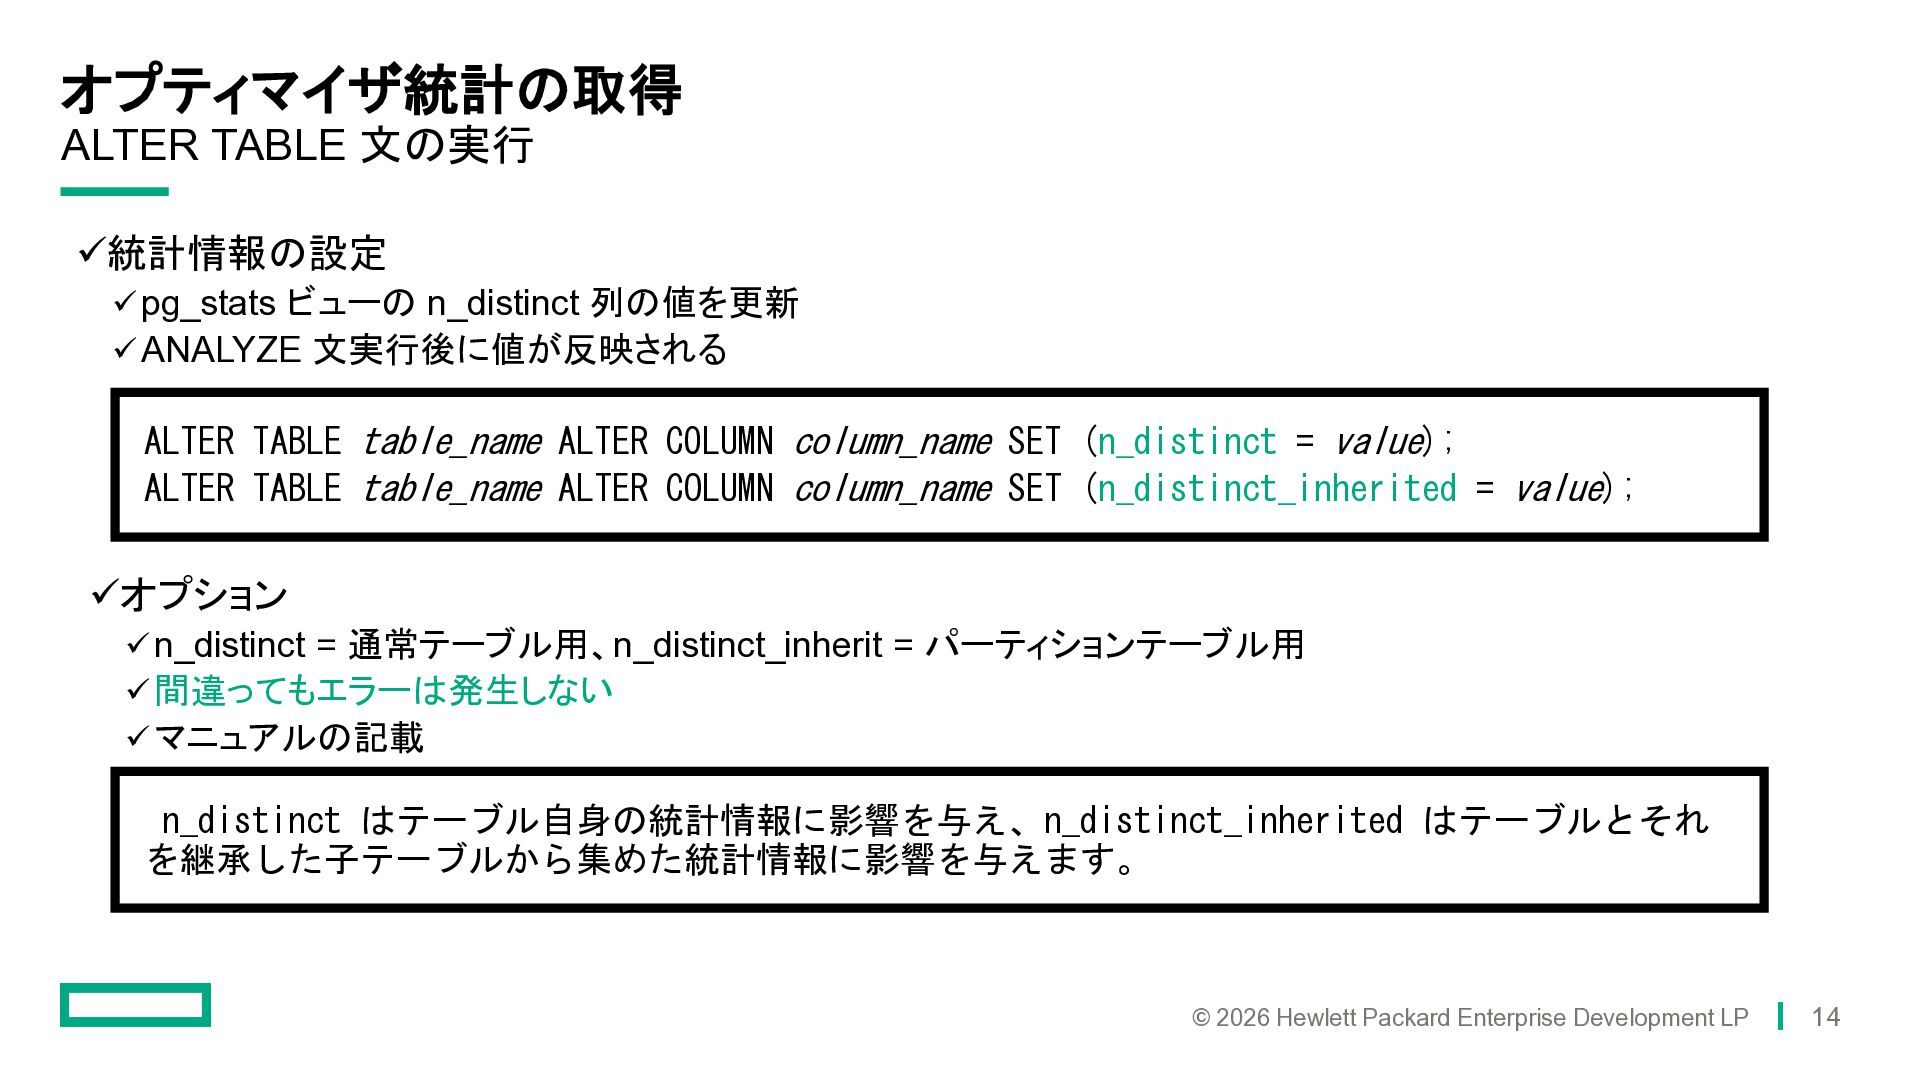
オプティマイザ統計の取得 ALTER TABLE 文の実行 ✓統計情報の設定 ✓ pg_stats ビューの n_distinct 列の値を更新
✓ ANALYZE 文実行後に値が反映される ALTER TABLE table_name ALTER COLUMN column_name SET (n_distinct = value); ALTER TABLE table_name ALTER COLUMN column_name SET (n_distinct_inherited = value); ✓オプション ✓ n_distinct = 通常テーブル用、n_distinct_inherit = パーティションテーブル用 ✓ 間違ってもエラーは発生しない ✓ マニュアルの記載 n_distinct はテーブル自身の統計情報に影響を与え、n_distinct_inherited はテーブルとそれ を継承した子テーブルから集めた統計情報に影響を与えます。 © 2026 Hewlett Packard Enterprise Development LP 14
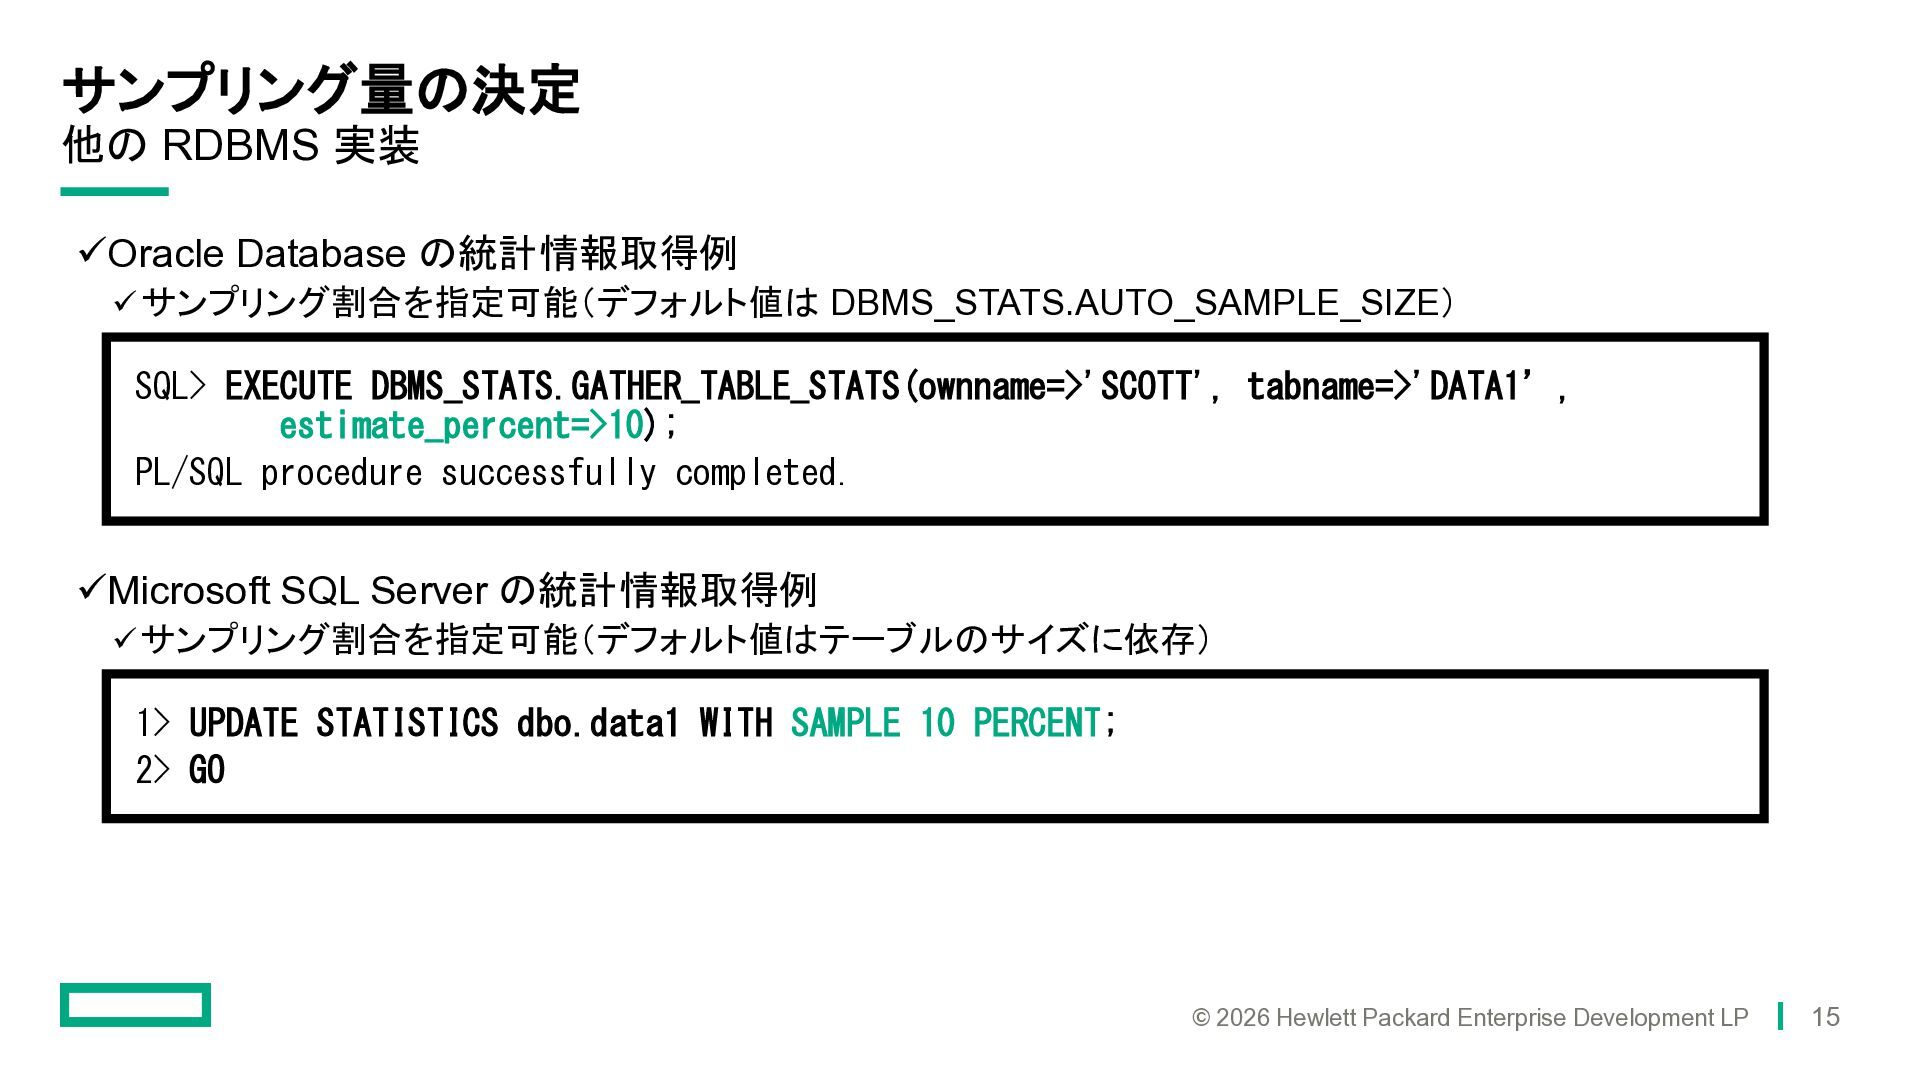
サンプリング量の決定 他の RDBMS 実装 ✓Oracle Database の統計情報取得例 ✓ サンプリング割合を指定可能(デフォルト値は DBMS_STATS.AUTO_SAMPLE_SIZE)
SQL> EXECUTE DBMS_STATS.GATHER_TABLE_STATS(ownname=>'SCOTT', tabname=>'DATA1’, estimate_percent=>10); PL/SQL procedure successfully completed. ✓Microsoft SQL Server の統計情報取得例 ✓ サンプリング割合を指定可能(デフォルト値はテーブルのサイズに依存) 1> UPDATE STATISTICS dbo.data1 WITH SAMPLE 10 PERCENT; 2> GO © 2026 Hewlett Packard Enterprise Development LP 15
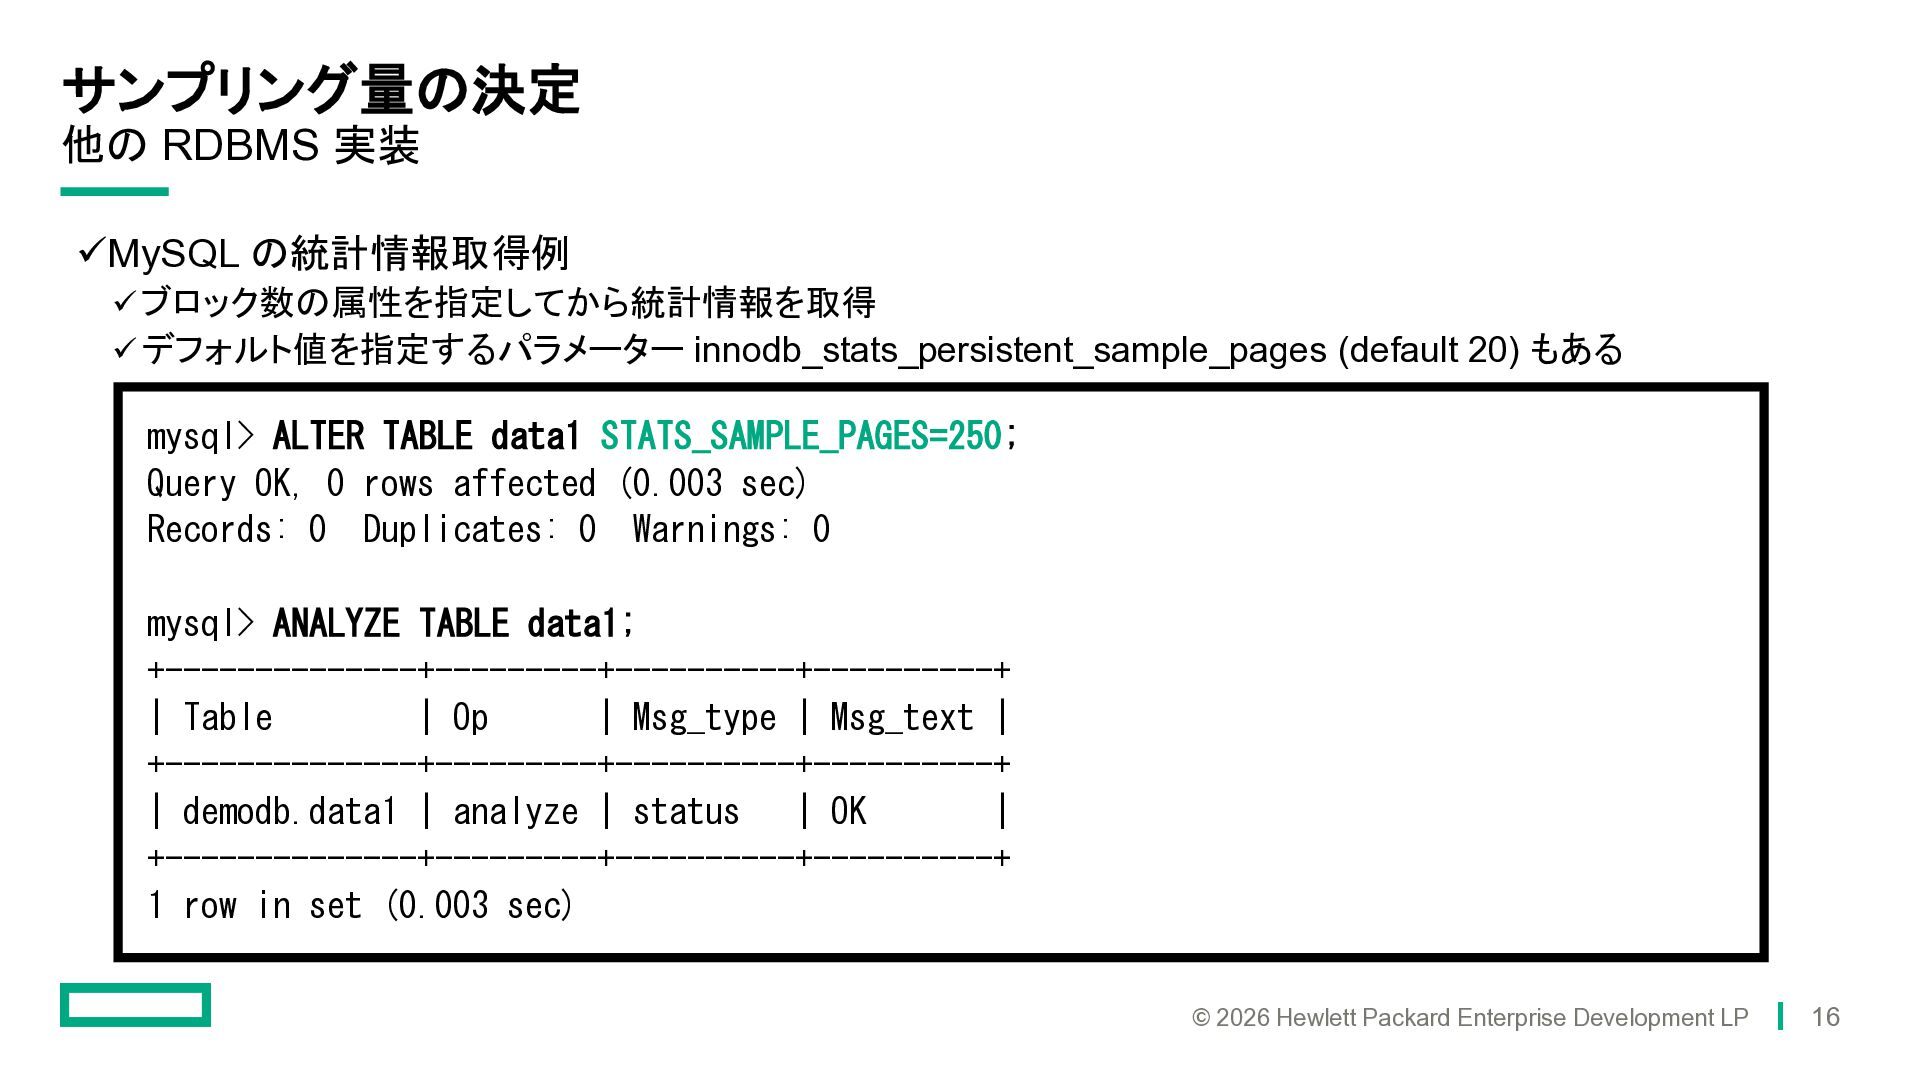
サンプリング量の決定 他の RDBMS 実装 ✓MySQL の統計情報取得例 ✓ ブロック数の属性を指定してから統計情報を取得 ✓ デフォルト値を指定するパラメーター
innodb_stats_persistent_sample_pages (default 20) もある mysql> ALTER TABLE data1 STATS_SAMPLE_PAGES=250; Query OK, 0 rows affected (0.003 sec) Records: 0 Duplicates: 0 Warnings: 0 mysql> ANALYZE TABLE data1; +--------------+---------+----------+----------+ | Table | Op | Msg_type | Msg_text | +--------------+---------+----------+----------+ | demodb.data1 | analyze | status | OK | +--------------+---------+----------+----------+ 1 row in set (0.003 sec) © 2026 Hewlett Packard Enterprise Development LP 16
サンプリング量の決定 他の RDBMS 実装 ✓PostgreSQL は? ✓ 自動的にサンプリング量を調整する方法は無い ✓ サンプリング量の決定は
DBA の仕事 © 2026 Hewlett Packard Enterprise Development LP 17
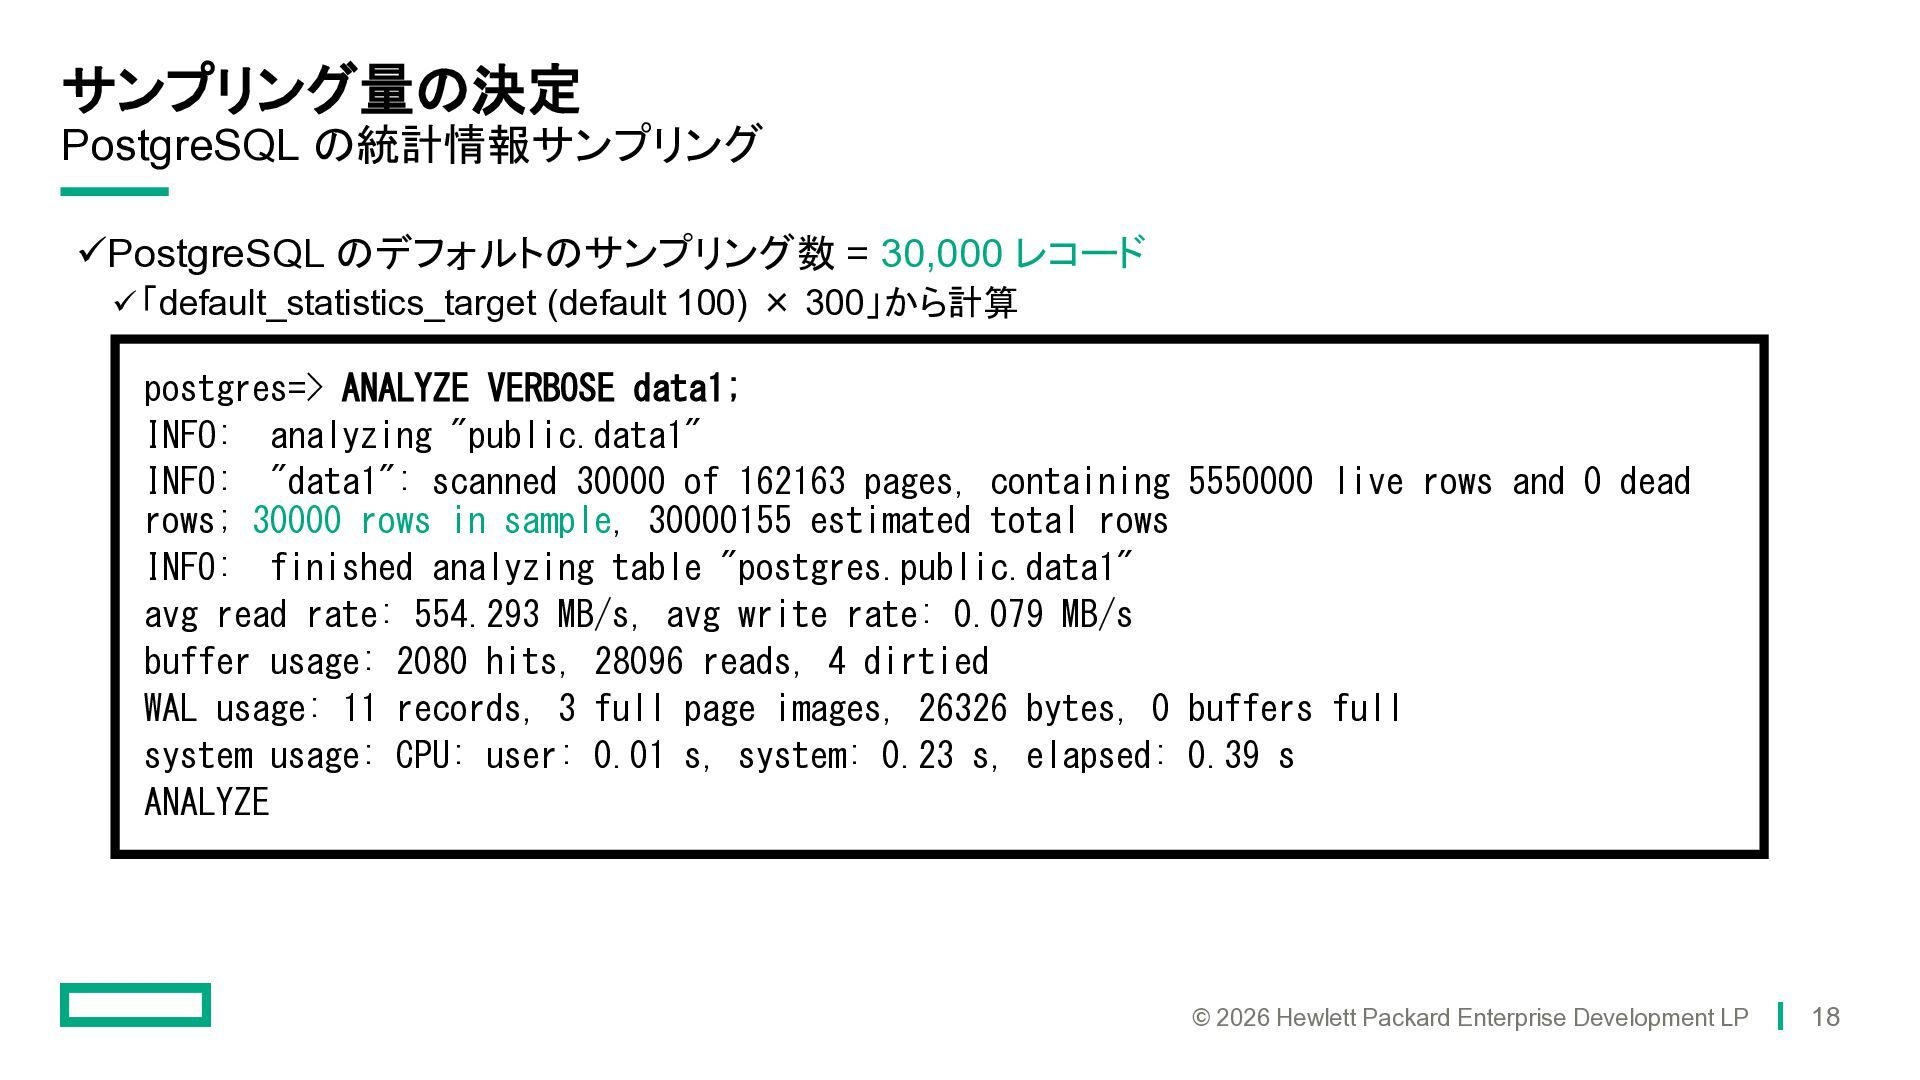
サンプリング量の決定 PostgreSQL の統計情報サンプリング ✓PostgreSQL のデフォルトのサンプリング数 = 30,000 レコード ✓ 「default_statistics_target
(default 100) × 300」から計算 postgres=> ANALYZE VERBOSE data1; INFO: analyzing "public.data1" INFO: "data1": scanned 30000 of 162163 pages, containing 5550000 live rows and 0 dead rows; 30000 rows in sample, 30000155 estimated total rows INFO: finished analyzing table "postgres.public.data1" avg read rate: 554.293 MB/s, avg write rate: 0.079 MB/s buffer usage: 2080 hits, 28096 reads, 4 dirtied WAL usage: 11 records, 3 full page images, 26326 bytes, 0 buffers full system usage: CPU: user: 0.01 s, system: 0.23 s, elapsed: 0.39 s ANALYZE © 2026 Hewlett Packard Enterprise Development LP 18
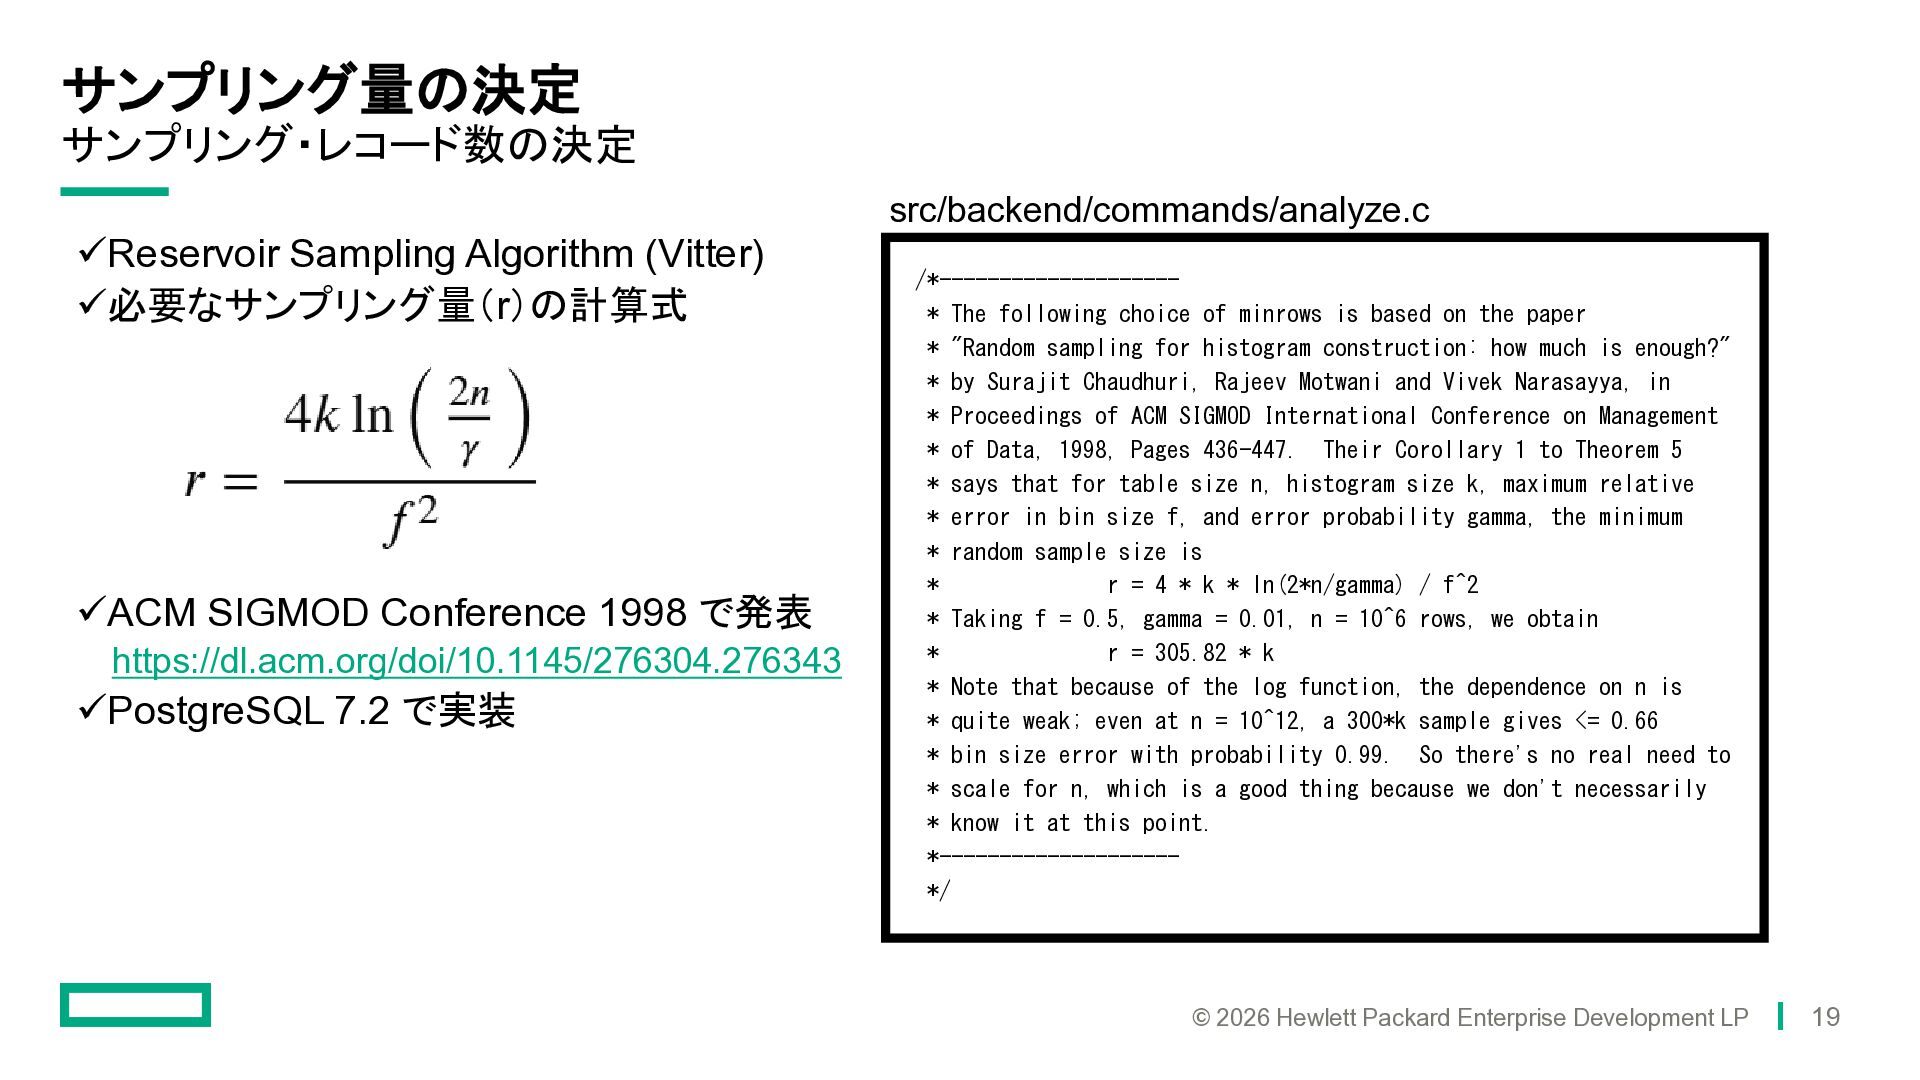
サンプリング量の決定 サンプリング・レコード数の決定 src/backend/commands/analyze.c ✓Reservoir Sampling Algorithm (Vitter) ✓必要なサンプリング量(r)の計算式 ✓ACM SIGMOD
Conference 1998 で発表 https://dl.acm.org/doi/10.1145/276304.276343 ✓PostgreSQL 7.2 で実装 /*-------------------* The following choice of minrows is based on the paper * "Random sampling for histogram construction: how much is enough?" * by Surajit Chaudhuri, Rajeev Motwani and Vivek Narasayya, in * Proceedings of ACM SIGMOD International Conference on Management * of Data, 1998, Pages 436-447. Their Corollary 1 to Theorem 5 * says that for table size n, histogram size k, maximum relative * error in bin size f, and error probability gamma, the minimum * random sample size is * r = 4 * k * ln(2*n/gamma) / f^2 * Taking f = 0.5, gamma = 0.01, n = 10^6 rows, we obtain * r = 305.82 * k * Note that because of the log function, the dependence on n is * quite weak; even at n = 10^12, a 300*k sample gives <= 0.66 * bin size error with probability 0.99. So there's no real need to * scale for n, which is a good thing because we don't necessarily * know it at this point. *-------------------*/ © 2026 Hewlett Packard Enterprise Development LP 19
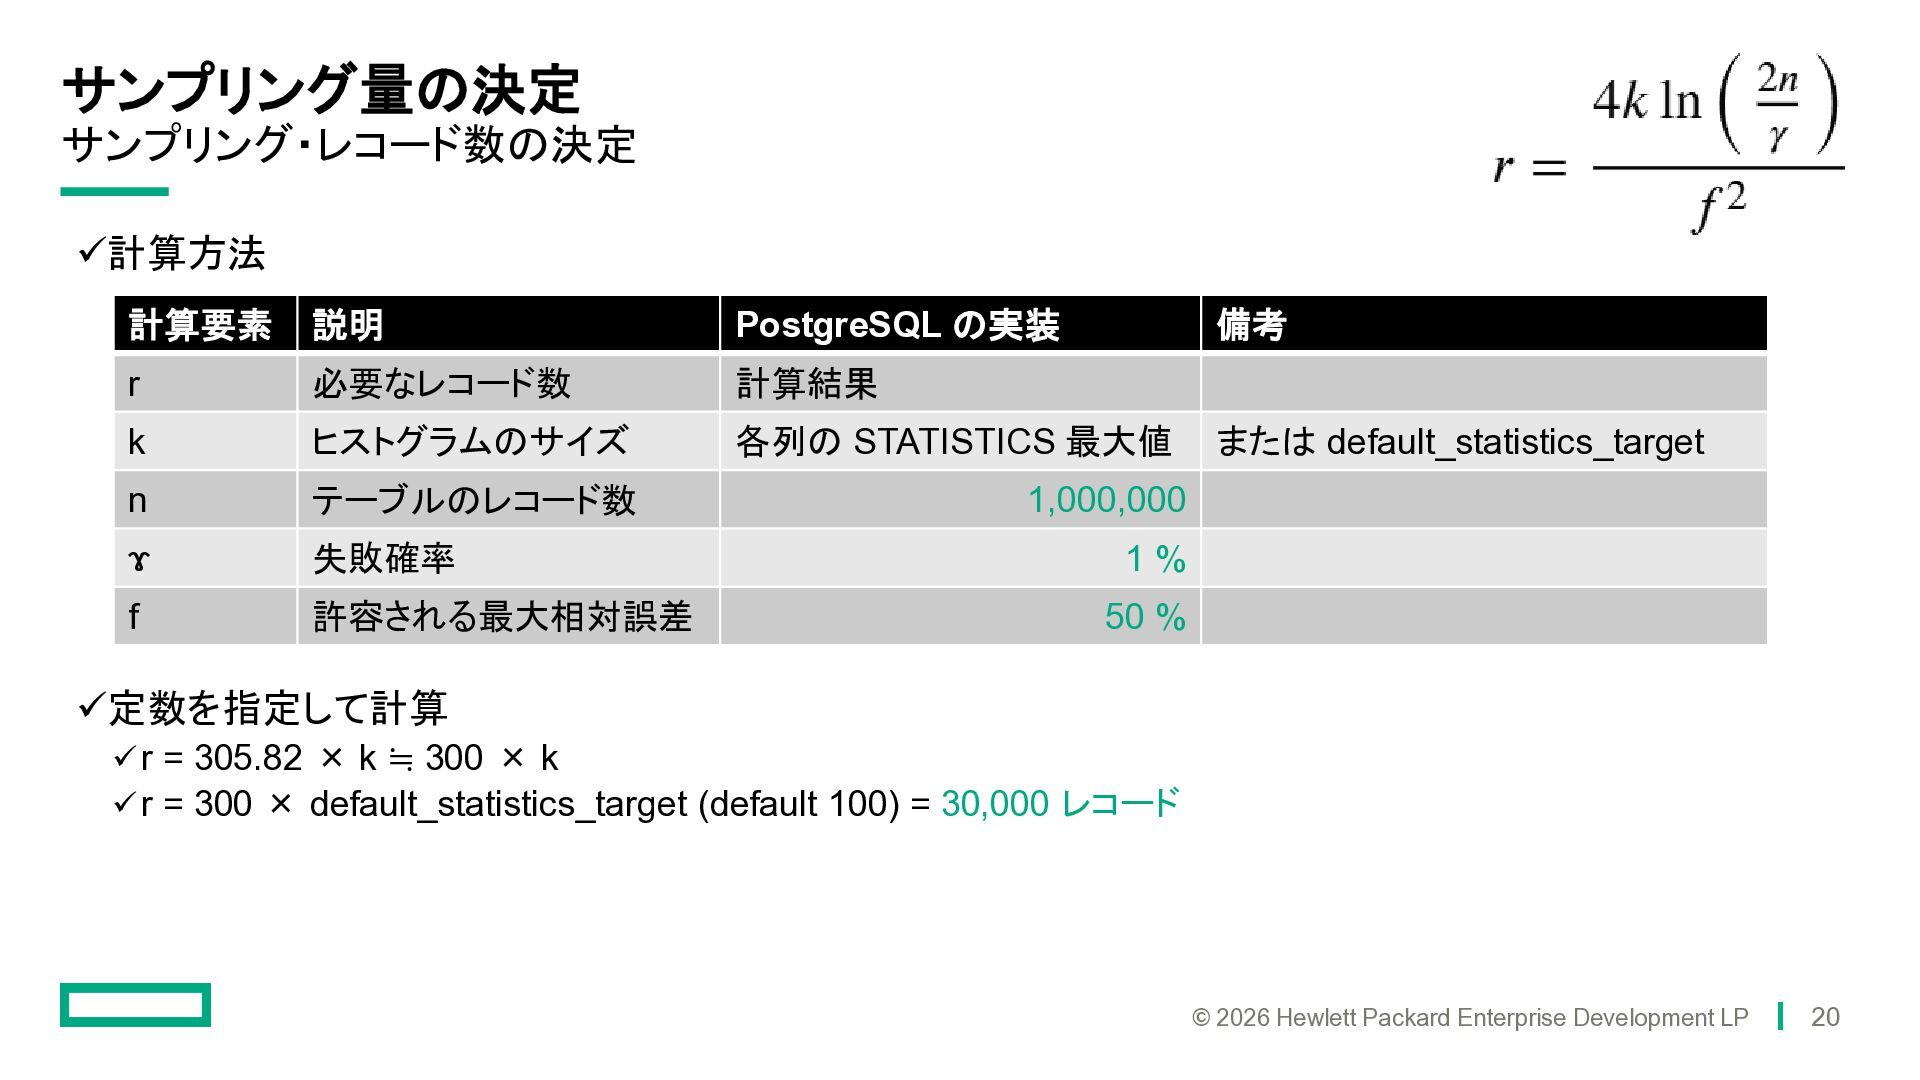
サンプリング量の決定 サンプリング・レコード数の決定 ✓計算方法 計算要素 説明 PostgreSQL の実装 r 必要なレコード数 計算結果
k ヒストグラムのサイズ 各列の STATISTICS 最大値 n テーブルのレコード数 1,000,000 ɤ 失敗確率 1% f 許容される最大相対誤差 50 % 備考 または default_statistics_target ✓定数を指定して計算 ✓ r = 305.82 × k ≒ 300 × k ✓ r = 300 × default_statistics_target (default 100) = 30,000 レコード © 2026 Hewlett Packard Enterprise Development LP 20
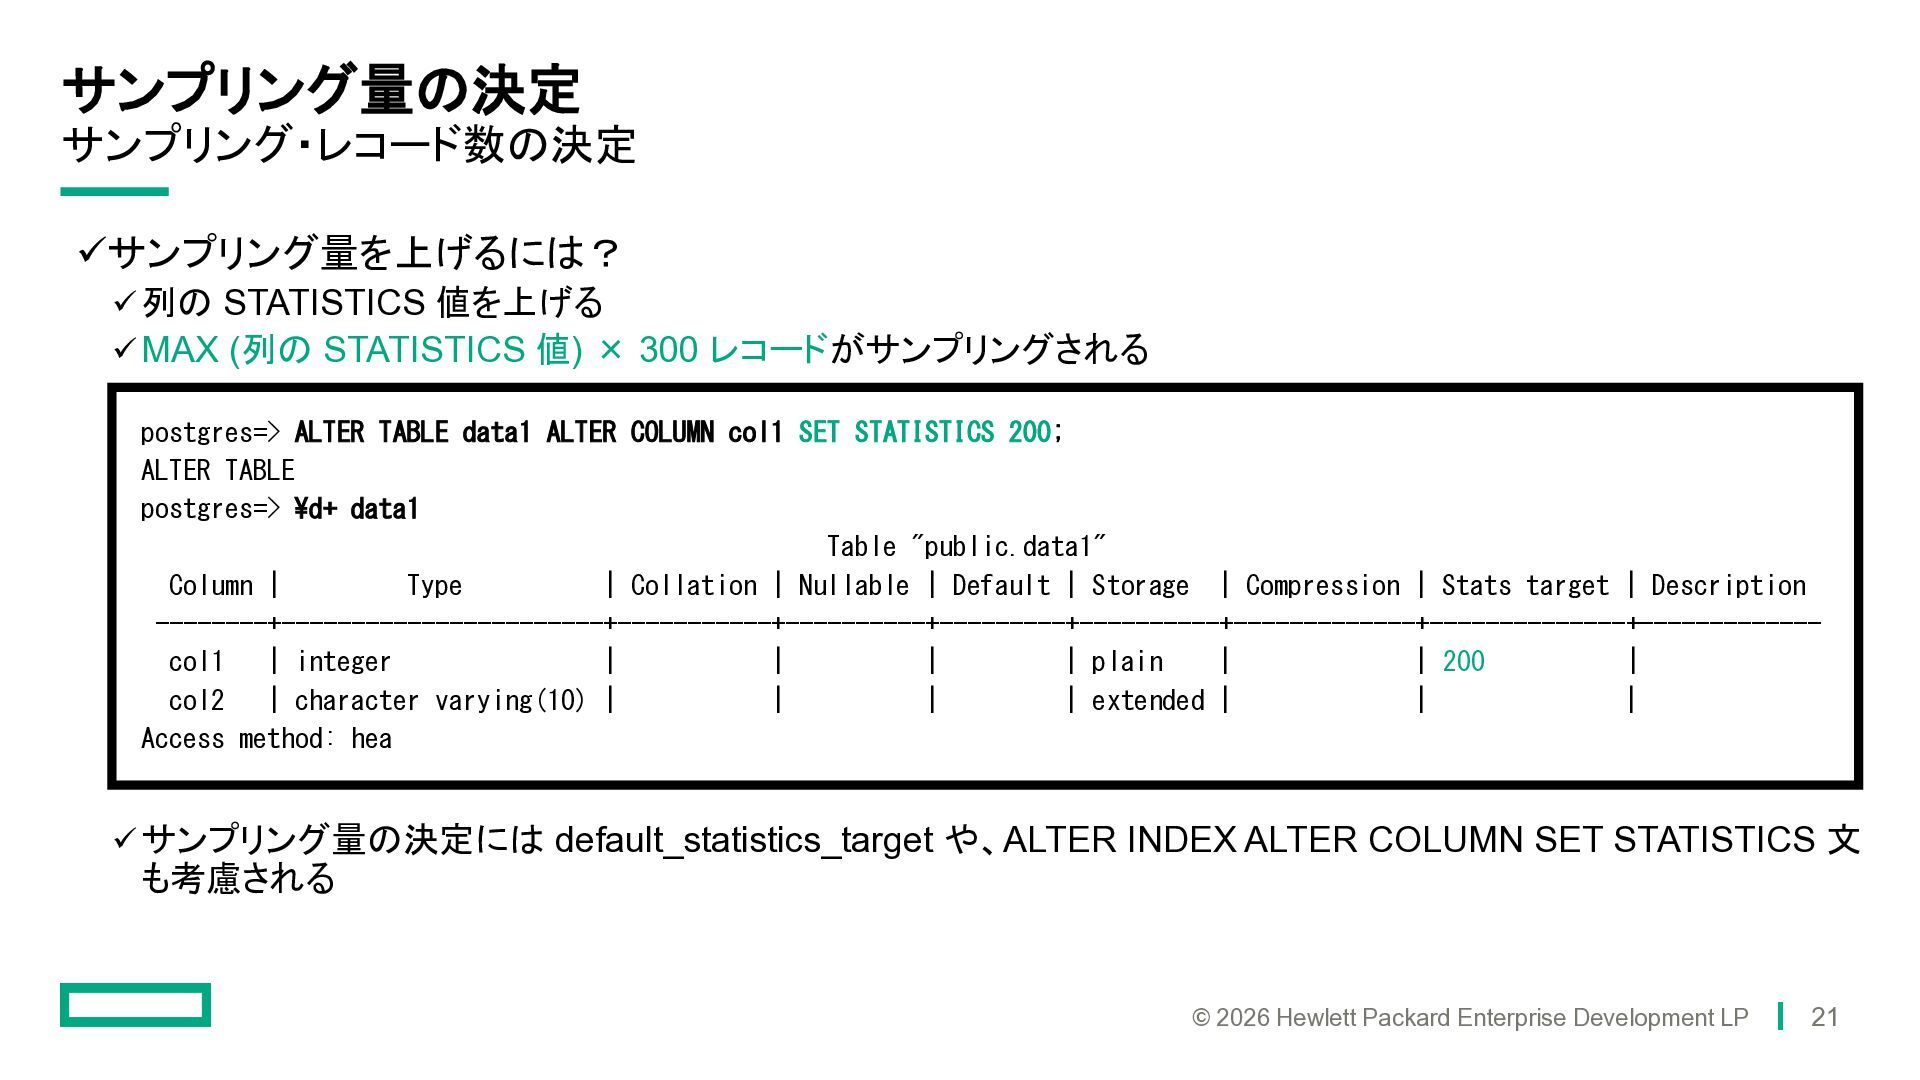
サンプリング量の決定 サンプリング・レコード数の決定 ✓サンプリング量を上げるには? ✓ 列の STATISTICS 値を上げる ✓ MAX (列の
STATISTICS 値) × 300 レコードがサンプリングされる postgres=> ALTER TABLE data1 ALTER COLUMN col1 SET STATISTICS 200; ALTER TABLE postgres=> ¥d+ data1 Table "public.data1" Column | Type | Collation | Nullable | Default | Storage | Compression | Stats target | Description --------+-----------------------+-----------+----------+---------+----------+-------------+--------------+------------col1 | integer | | | | plain | | 200 | col2 | character varying(10) | | | | extended | | | Access method: hea ✓ サンプリング量の決定には default_statistics_target や、ALTER INDEX ALTER COLUMN SET STATISTICS 文 も考慮される © 2026 Hewlett Packard Enterprise Development LP 21
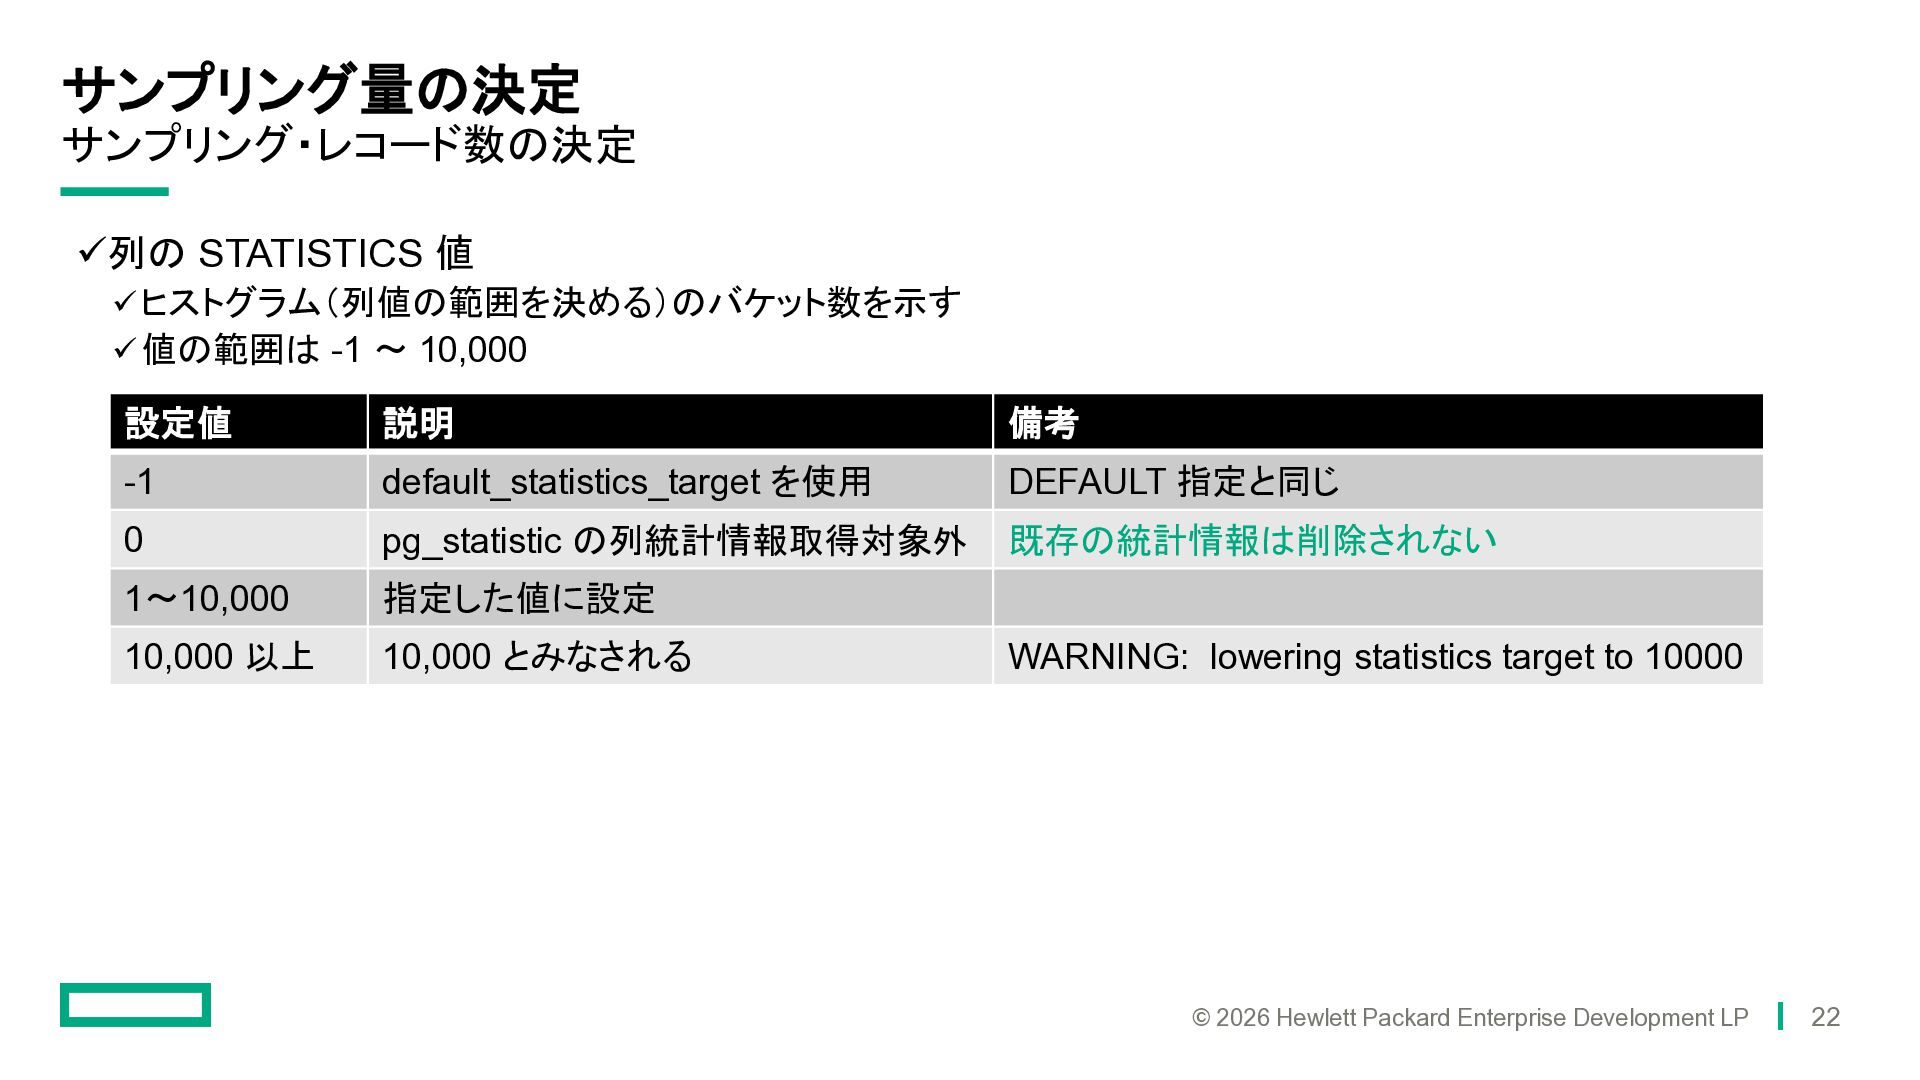
サンプリング量の決定 サンプリング・レコード数の決定 ✓列の STATISTICS 値 ✓ ヒストグラム(列値の範囲を決める)のバケット数を示す ✓ 値の範囲は -1
~ 10,000 設定値 説明 備考 -1 default_statistics_target を使用 DEFAULT 指定と同じ 0 pg_statistic の列統計情報取得対象外 既存の統計情報は削除されない 1~10,000 指定した値に設定 10,000 以上 10,000 とみなされる WARNING: lowering statistics target to 10000 © 2026 Hewlett Packard Enterprise Development LP 22
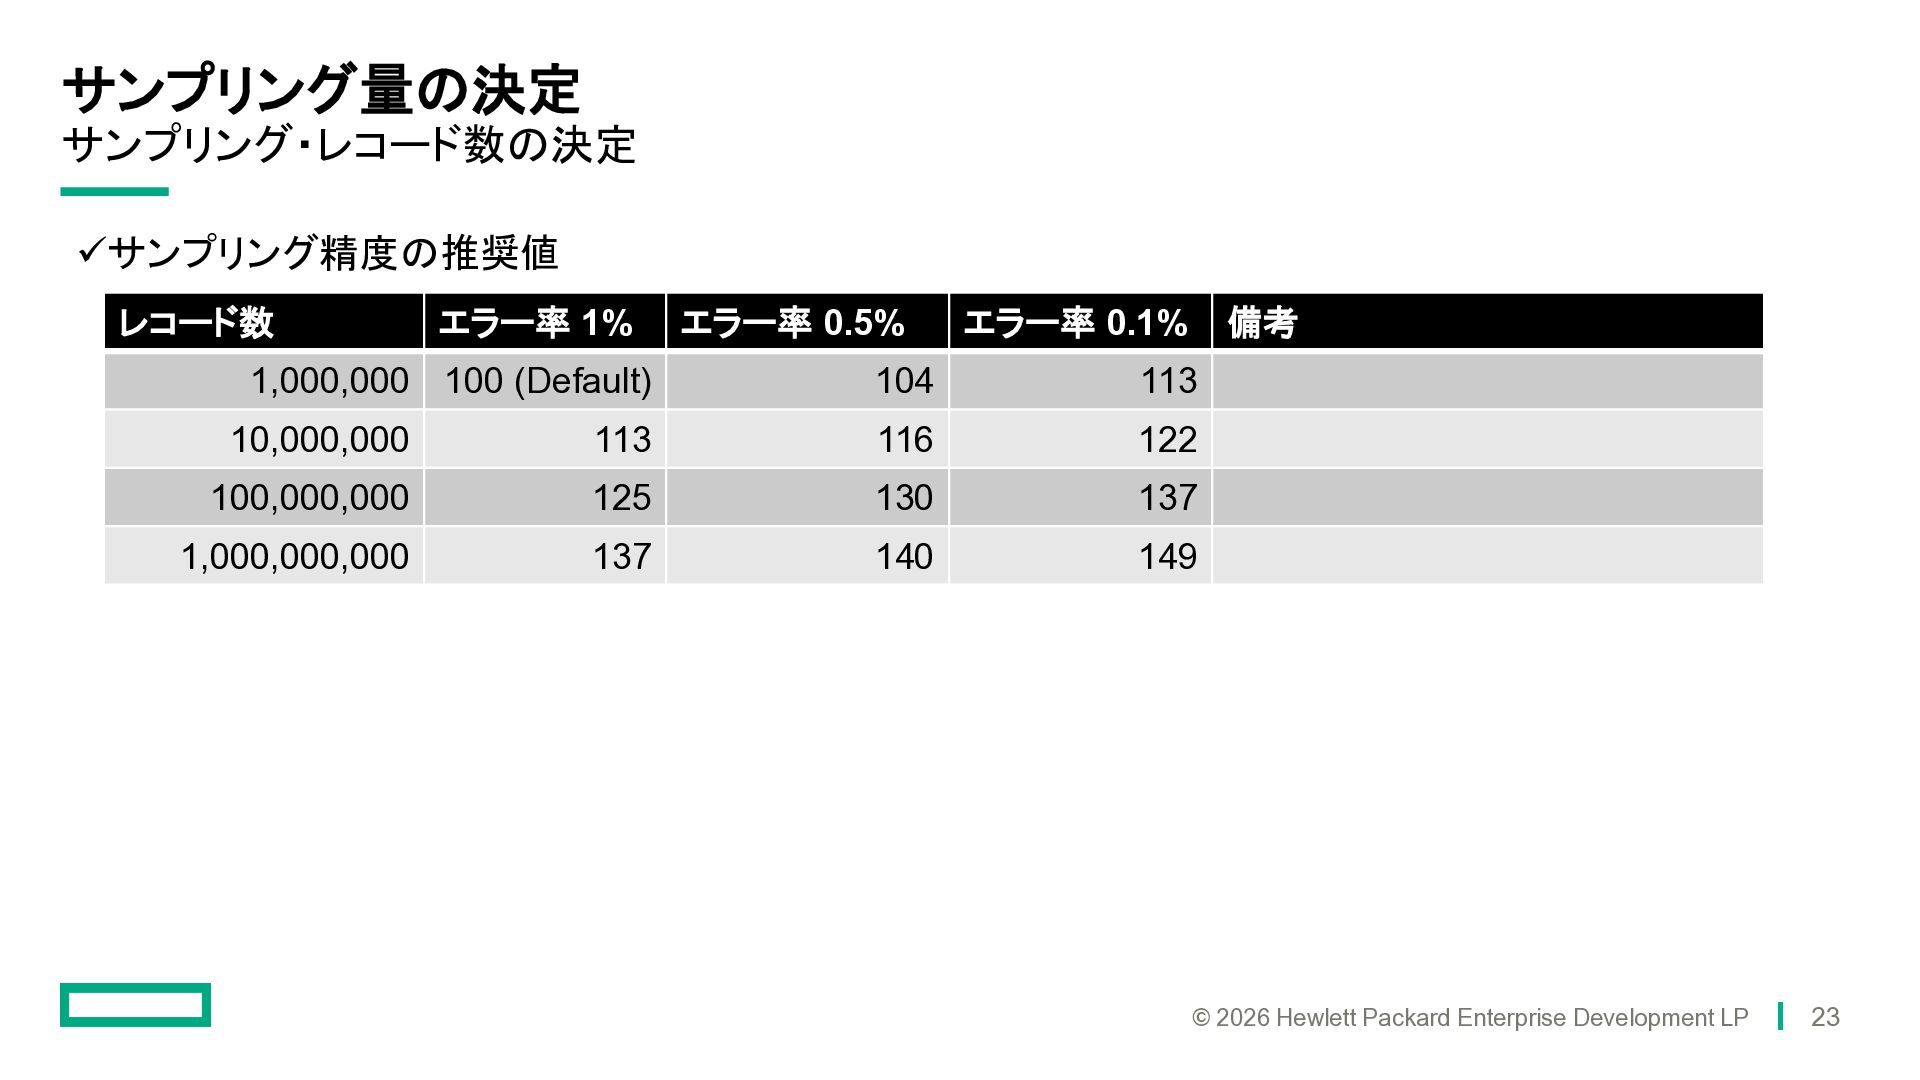
サンプリング量の決定 サンプリング・レコード数の決定 ✓サンプリング精度の推奨値 レコード数 エラー率 1% エラー率 0.5% エラー率 0.1%
備考 1,000,000 100 (Default) 104 113 10,000,000 113 116 122 100,000,000 125 130 137 1,000,000,000 137 140 149 © 2026 Hewlett Packard Enterprise Development LP 23
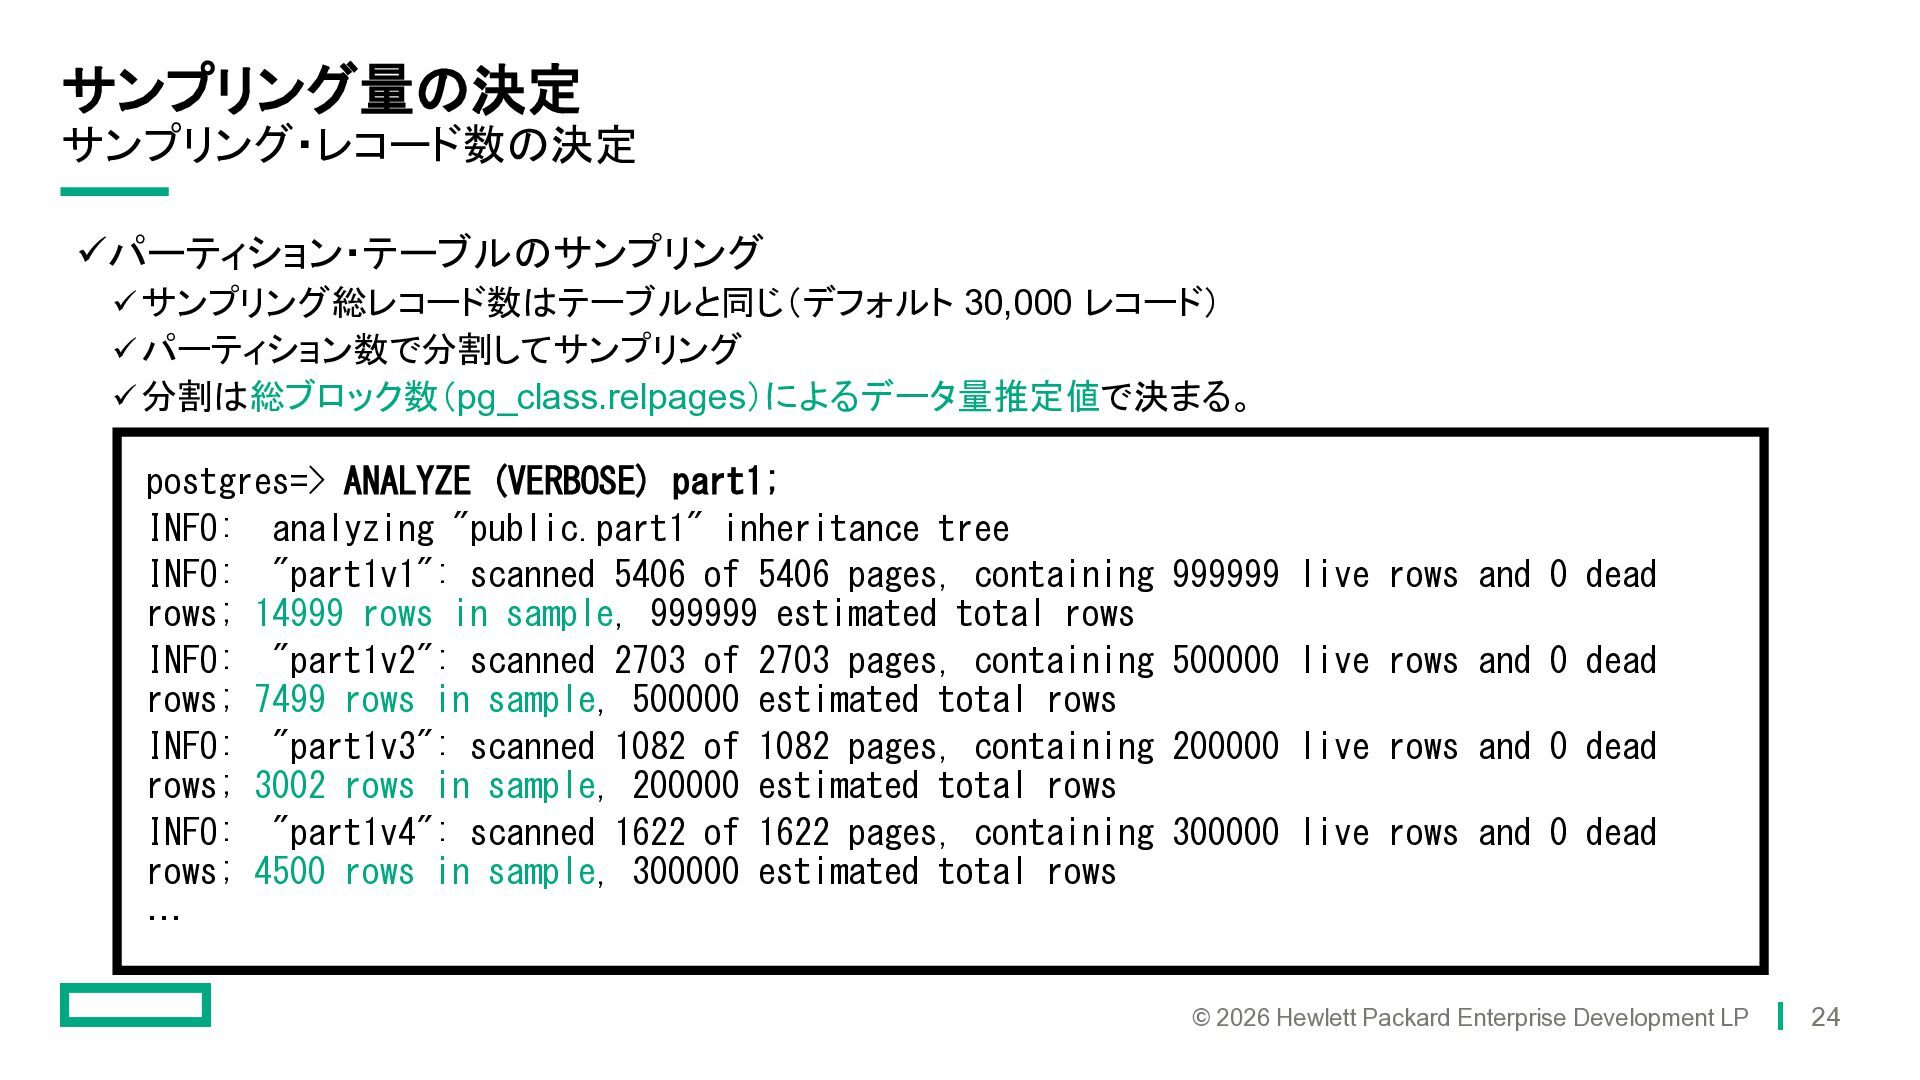
サンプリング量の決定 サンプリング・レコード数の決定 ✓パーティション・テーブルのサンプリング ✓ サンプリング総レコード数はテーブルと同じ(デフォルト 30,000 レコード) ✓ パーティション数で分割してサンプリング ✓
分割は総ブロック数(pg_class.relpages)によるデータ量推定値で決まる。 postgres=> ANALYZE (VERBOSE) part1; INFO: analyzing "public.part1" inheritance tree INFO: "part1v1": scanned 5406 of 5406 pages, containing 999999 live rows and 0 dead rows; 14999 rows in sample, 999999 estimated total rows INFO: "part1v2": scanned 2703 of 2703 pages, containing 500000 live rows and 0 dead rows; 7499 rows in sample, 500000 estimated total rows INFO: "part1v3": scanned 1082 of 1082 pages, containing 200000 live rows and 0 dead rows; 3002 rows in sample, 200000 estimated total rows INFO: "part1v4": scanned 1622 of 1622 pages, containing 300000 live rows and 0 dead rows; 4500 rows in sample, 300000 estimated total rows … © 2026 Hewlett Packard Enterprise Development LP 24
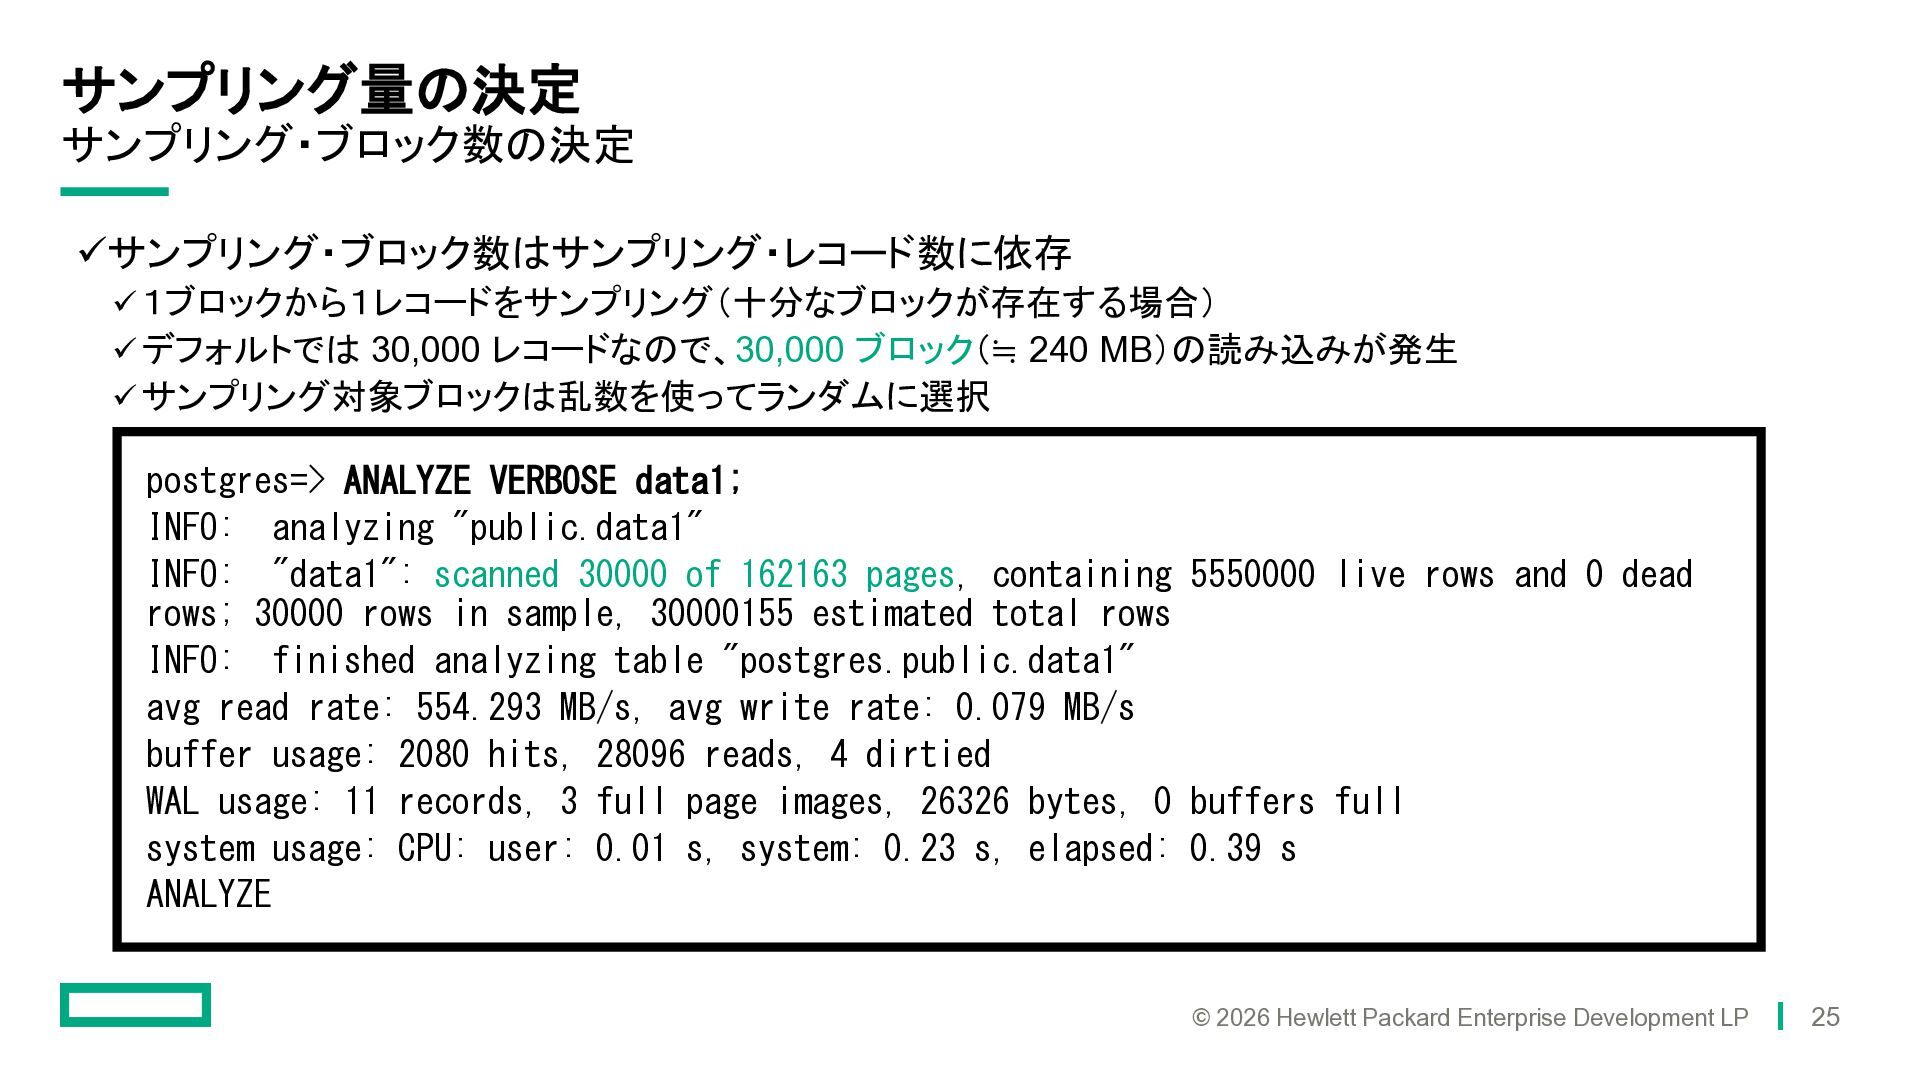
サンプリング量の決定 サンプリング・ブロック数の決定 ✓サンプリング・ブロック数はサンプリング・レコード数に依存 ✓ 1ブロックから1レコードをサンプリング(十分なブロックが存在する場合) ✓ デフォルトでは 30,000 レコードなので、30,000 ブロック(≒
240 MB)の読み込みが発生 ✓ サンプリング対象ブロックは乱数を使ってランダムに選択 postgres=> ANALYZE VERBOSE data1; INFO: analyzing "public.data1" INFO: "data1": scanned 30000 of 162163 pages, containing 5550000 live rows and 0 dead rows; 30000 rows in sample, 30000155 estimated total rows INFO: finished analyzing table "postgres.public.data1" avg read rate: 554.293 MB/s, avg write rate: 0.079 MB/s buffer usage: 2080 hits, 28096 reads, 4 dirtied WAL usage: 11 records, 3 full page images, 26326 bytes, 0 buffers full system usage: CPU: user: 0.01 s, system: 0.23 s, elapsed: 0.39 s ANALYZE © 2026 Hewlett Packard Enterprise Development LP 25
参考 参考にした資料 ✓A Deep Dive into Statistics https://www.postgresql.eu/events/pgconfeu2024/sessions/session/5747/slides/559/postgres_statistics_prese ntation.pdf ✓The
effect of frequent values on histogram_bounds in PostgreSQL https://dev.to/msdousti/understanding-histogram-bounds-in-postgresql-54d1 ✓Estimating number of distinct values. https://www.postgresql.org/message-id/4338f834-dee9-2eb8-0577-10abe9d39e2d%40postgrespro.ru ✓Estimating Unseen Deduplication from Theory To Practice https://www.usenix.org/system/files/conference/fast16/fast16-papers-harnik.pdf ✓書籍「PostgreSQL 実践入門」 第7章 クエリ処理 https://gihyo.jp/book/2026/978-4-297-14861-4 ✓書籍「内部構造から学ぶPostgreSQL」 第15章 実行計画の取得/解析 https://gihyo.jp/book/2022/978-4-297-13206-4 © 2026 Hewlett Packard Enterprise Development LP 26
THANK YOU Mail :
[email protected]
X(Twitter) : @nori_shinoda Qiita :
@plusultra © 2026 Hewlett Packard Enterprise Development LP 27


 nori_shinoda
 oracle4engineer
 kinopeee
 sato4mi
 soracom
 kworkdev
 teamhimeh
 happysamurai294
 hisuzuya
 ryo_kawamata
 joere
 minorun365
 lara
 michielstock
 varn
 kimpetersen
 davetheseo
 katarinadahlin
 scottboms
 sachag
 ipullrank
 bryan
 cassininazir
 thirion