Upgrade to Pro — share decks privately, control downloads, hide ads and more …

ICAITD 2026 Oral Presentation

Sponsored · Your Podcast. Everywhere. Effortlessly. Share. Educate. Inspire. Entertain. You do you. We'll handle the rest. →
Avatar for Rikka Botan Rikka Botan
October 13, 2026

ICAITD 2026 Oral Presentation

SSE: A Parameter-Efficient Training Recipe
for Static Retrieval Embeddings

Avatar for Rikka Botan

Rikka Botan

October 13, 2026

More Decks by Rikka Botan

Other Decks in Research

Transcript

  1. SSE: A Parameter-Efficient Training Recipe for Static Retrieval Embeddings ICAITD

    2026 @Tokyo Rikka Botan Independent Researcher, Japan
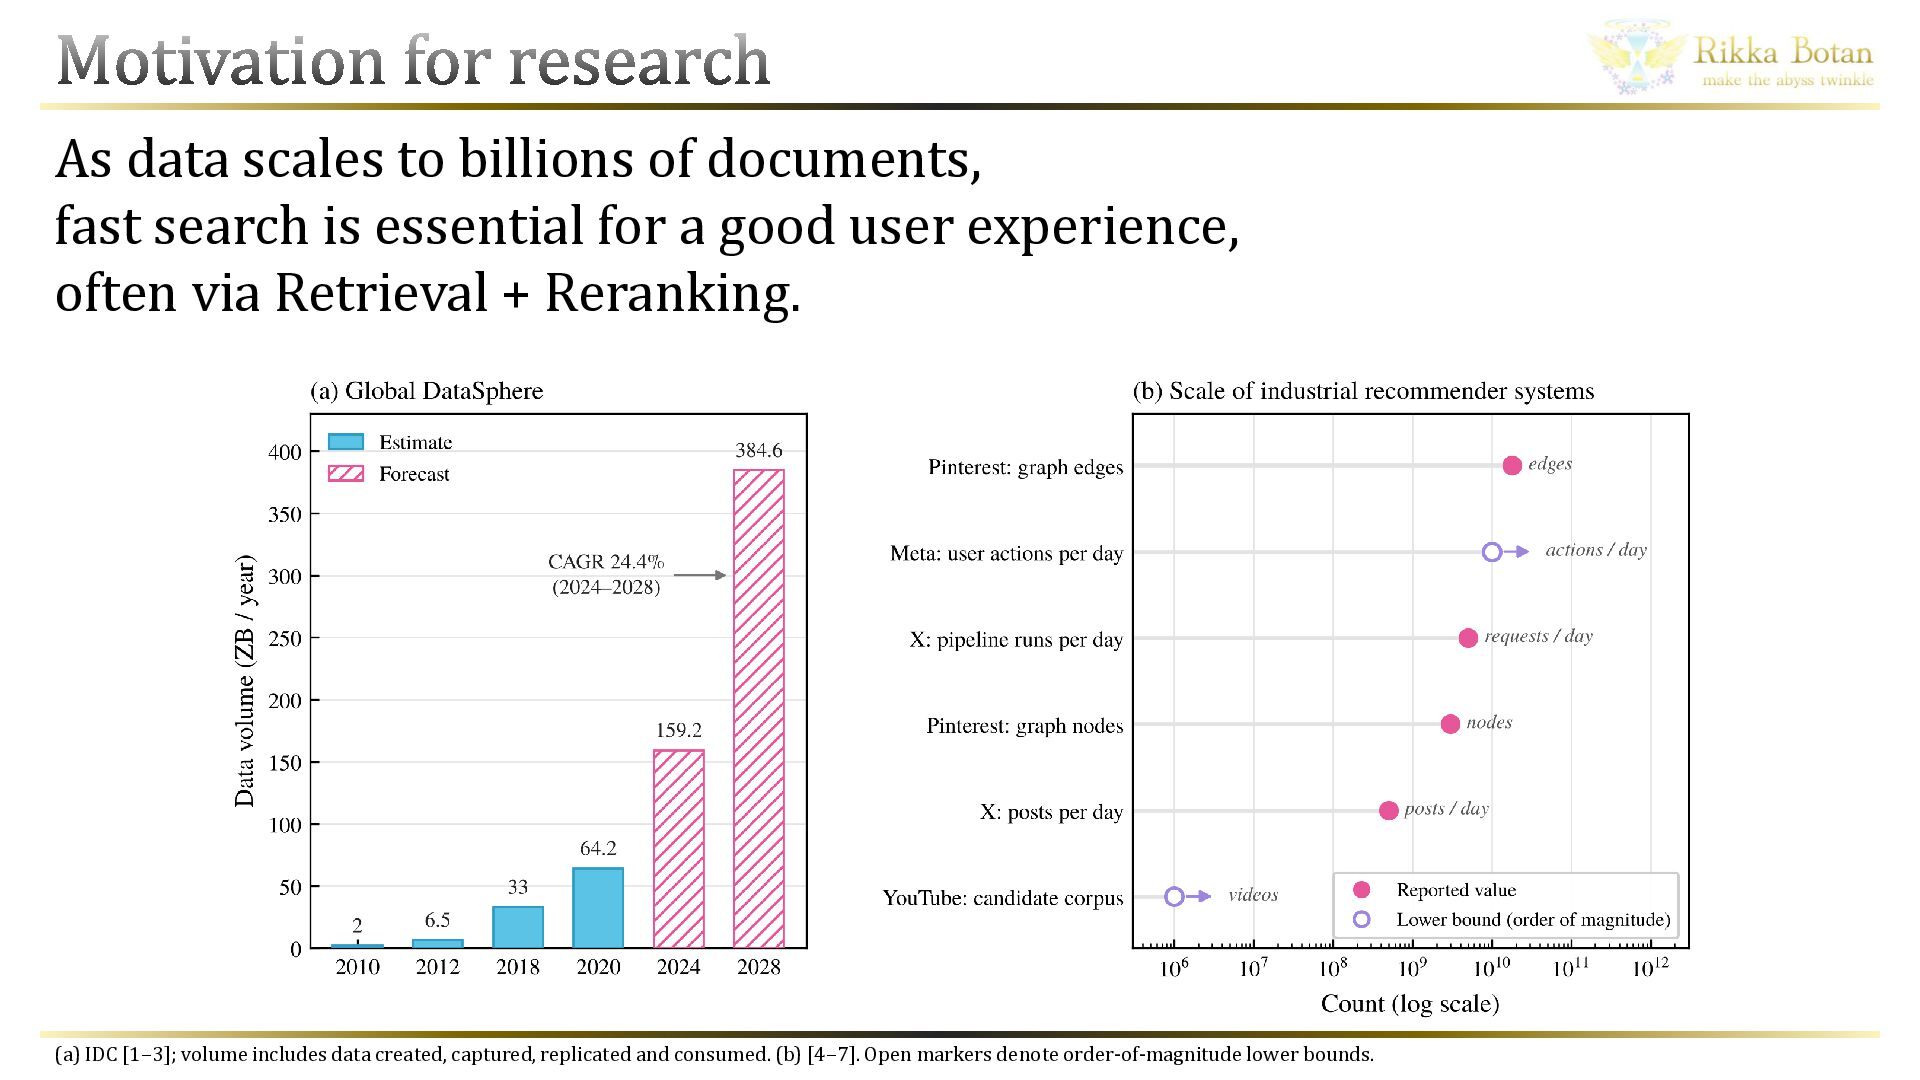
  2. Motivation for research As data scales to billions of documents,

    fast search is essential for a good user experience, often via Retrieval + Reranking. (a) IDC [1–3]; volume includes data created, captured, replicated and consumed. (b) [4–7]. Open markers denote order-of-magnitude lower bounds.
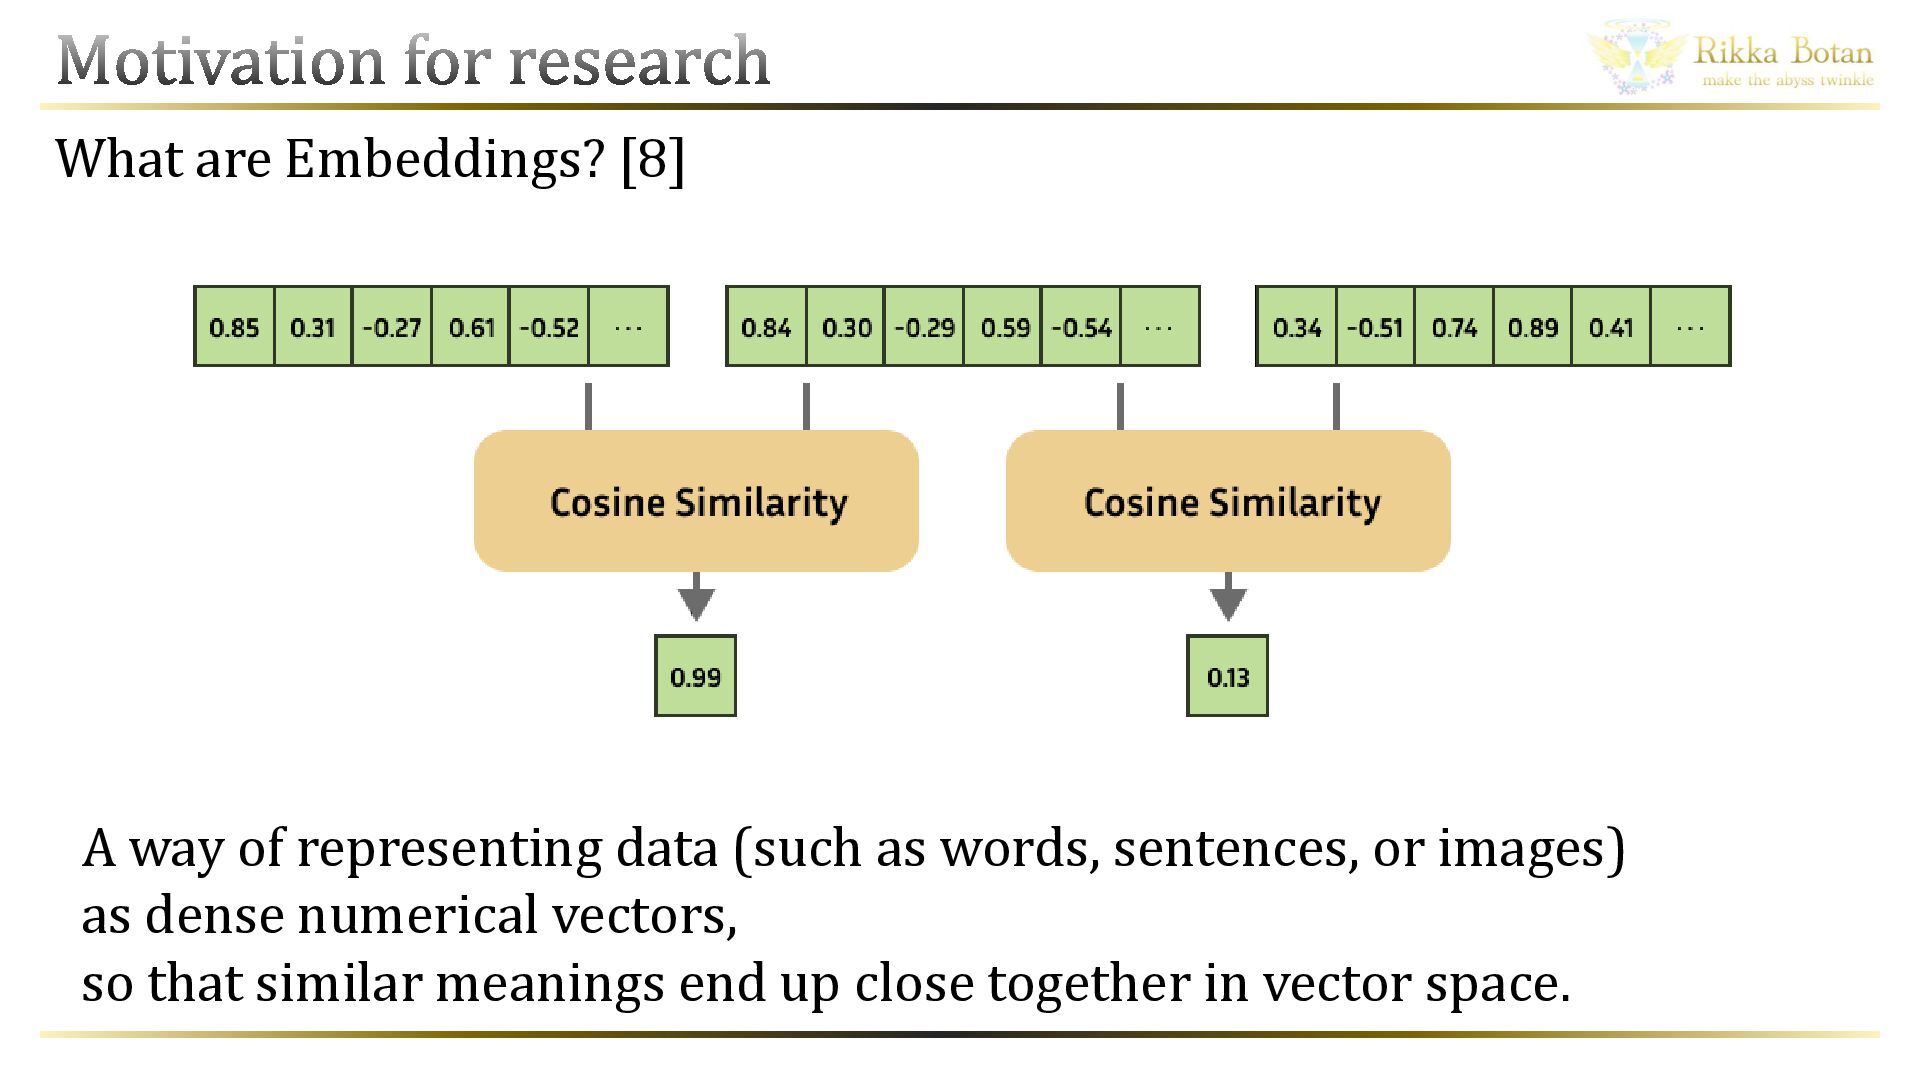
  3. Motivation for research What are Embeddings? [8] A way of

    representing data (such as words, sentences, or images) as dense numerical vectors, so that similar meanings end up close together in vector space.
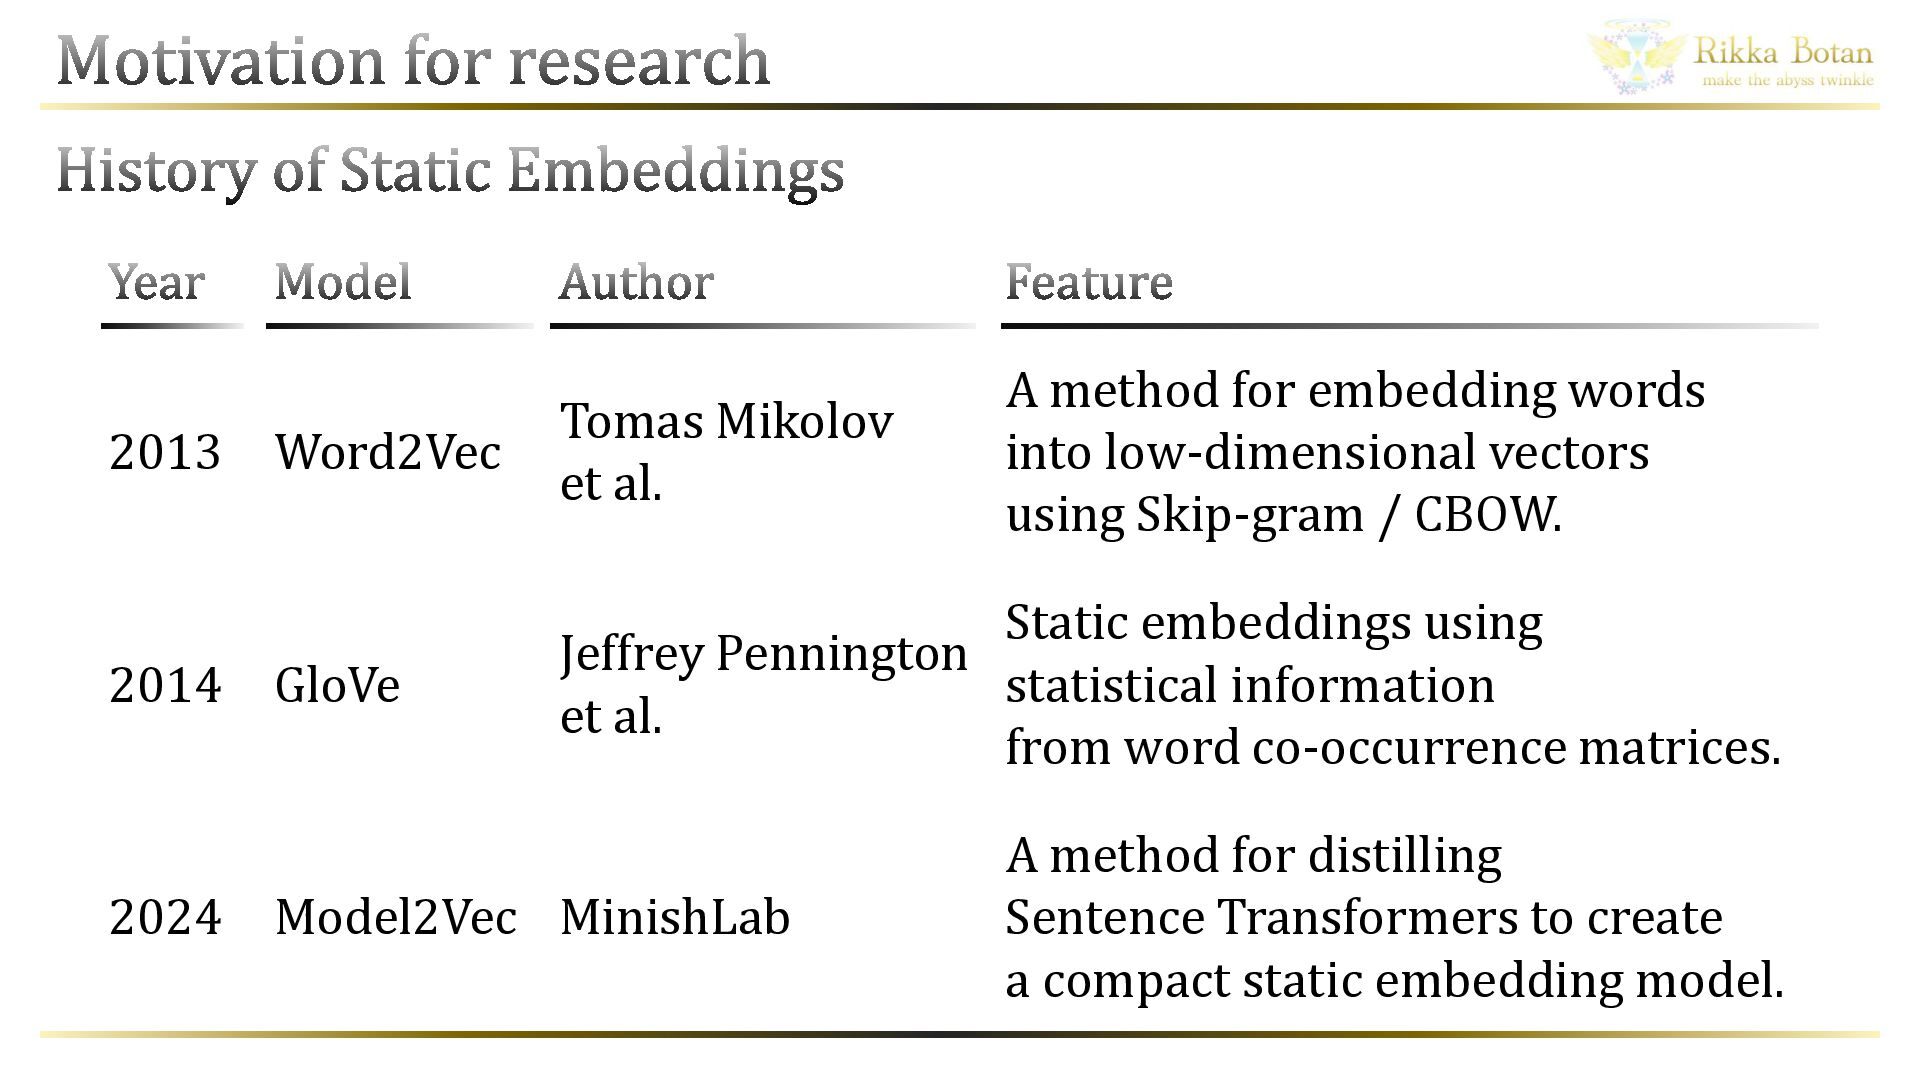
  4. Motivation for research History of Static Embeddings Year Model Author

    Feature 2013 Word2Vec Tomas Mikolov et al. A method for embedding words into low-dimensional vectors using Skip-gram / CBOW. 2014 GloVe Static embeddings using Jeffrey Pennington statistical information et al. from word co-occurrence matrices. 2024 Model2Vec MinishLab A method for distilling Sentence Transformers to create a compact static embedding model.
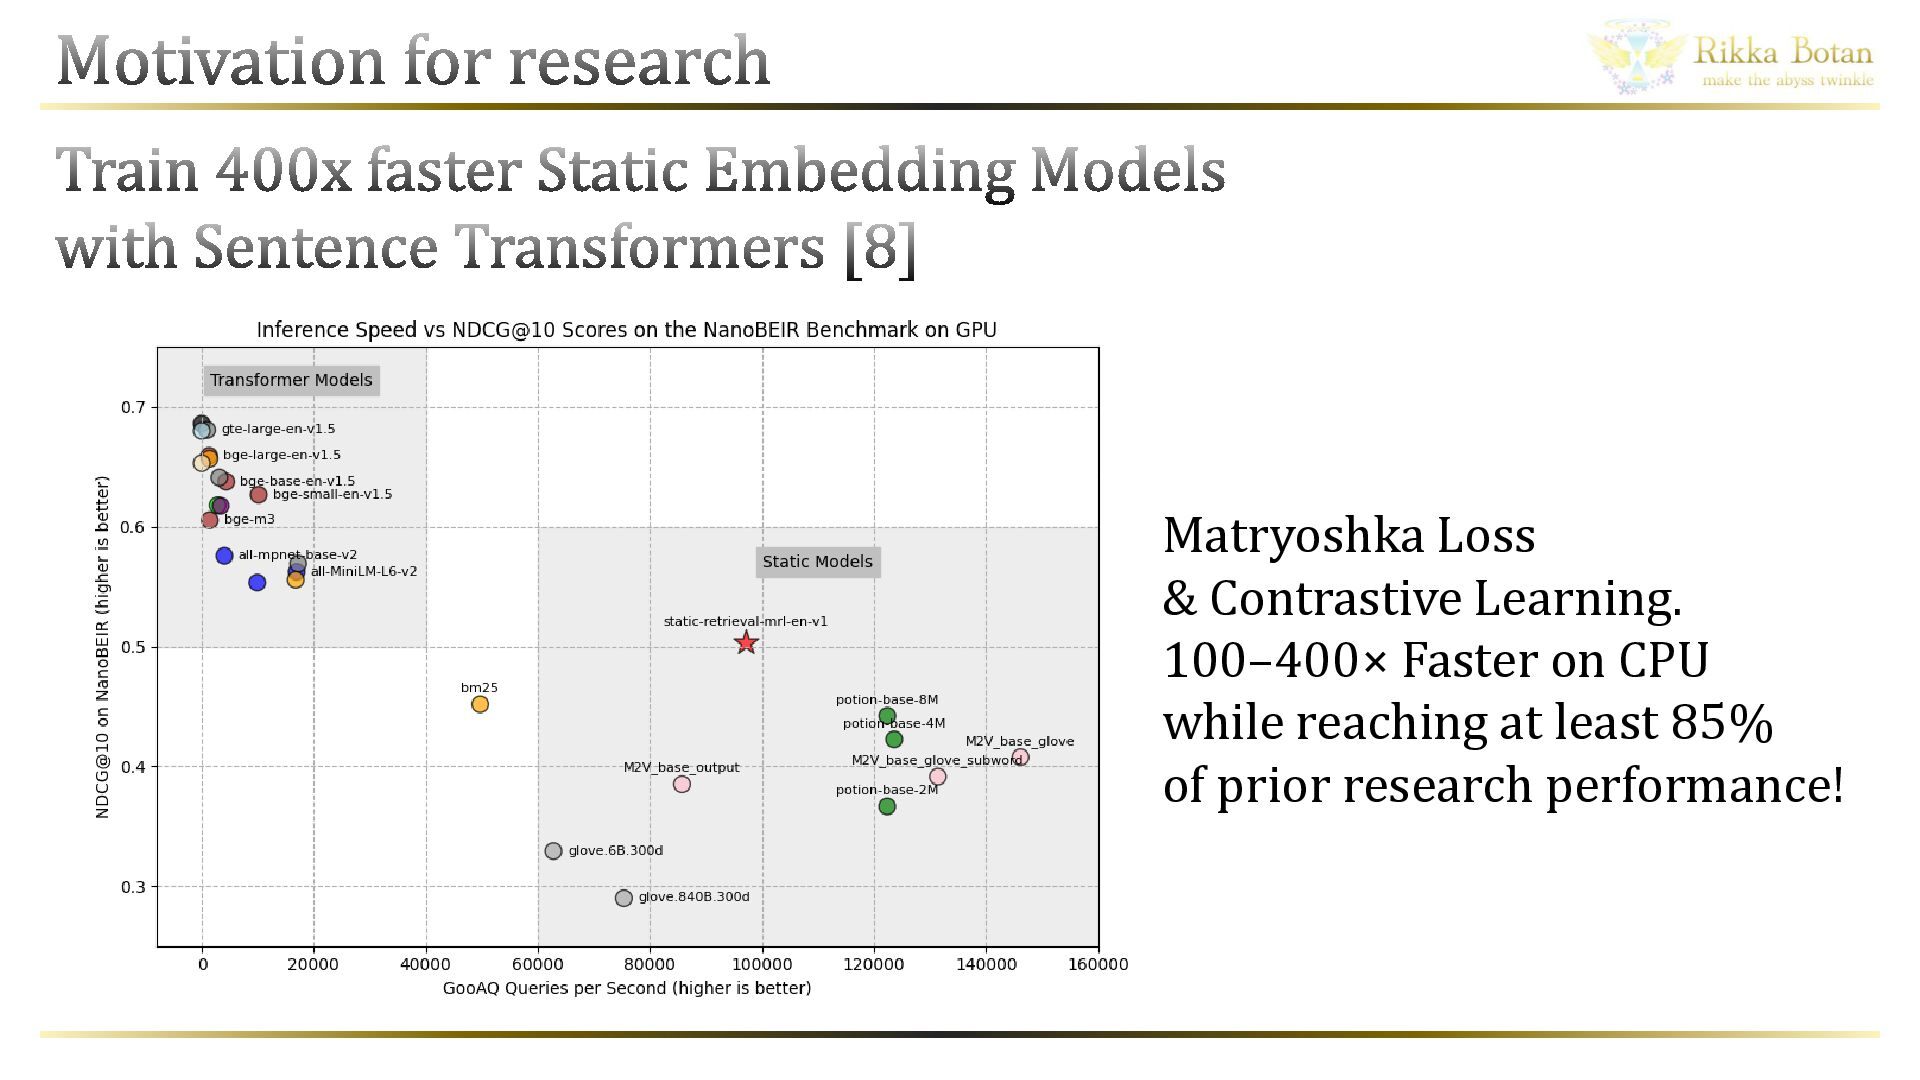
  5. Motivation for research Train 400x faster Static Embedding Models with

    Sentence Transformers [8] Matryoshka Loss & Contrastive Learning. 100–400× Faster on CPU while reaching at least 85% of prior research performance!
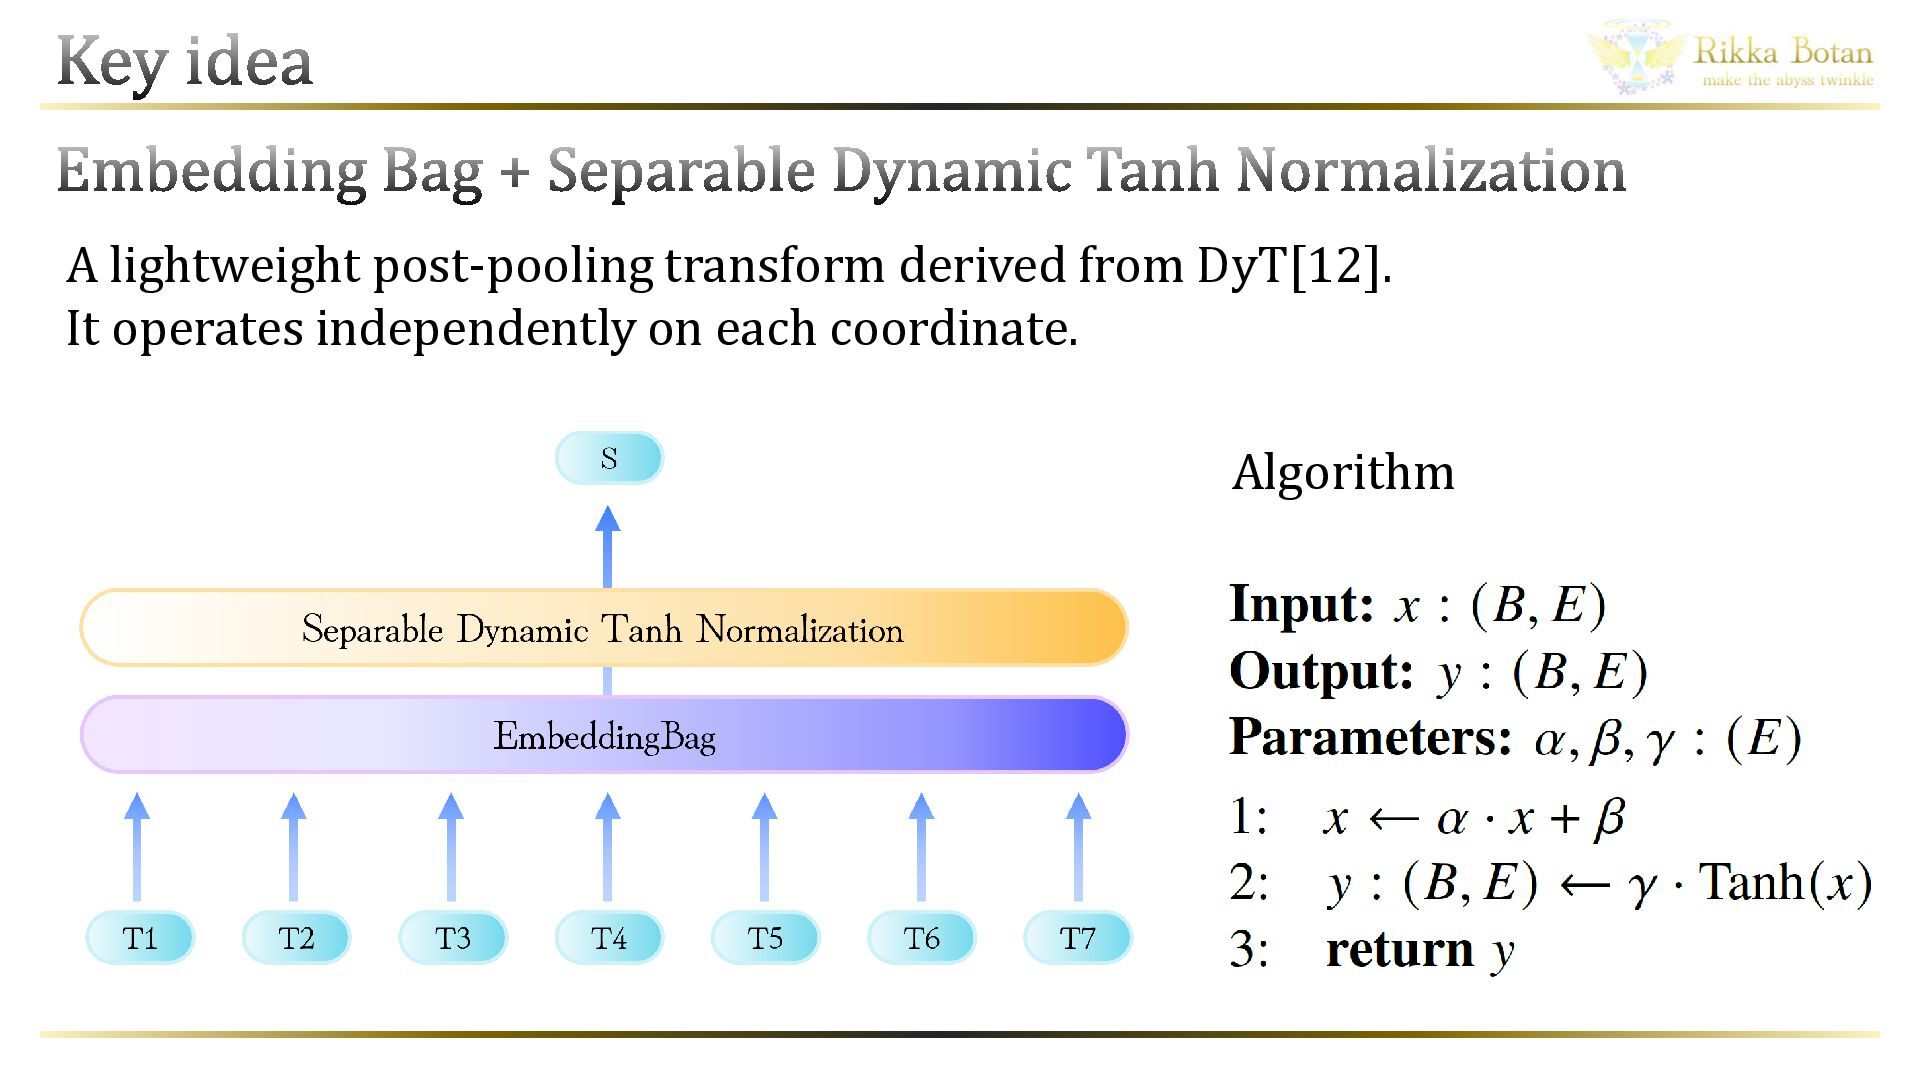
  6. Key idea Embedding Bag + Separable Dynamic Tanh Normalization A

    lightweight post-pooling transform derived from DyT[12]. It operates independently on each coordinate. Algorithm
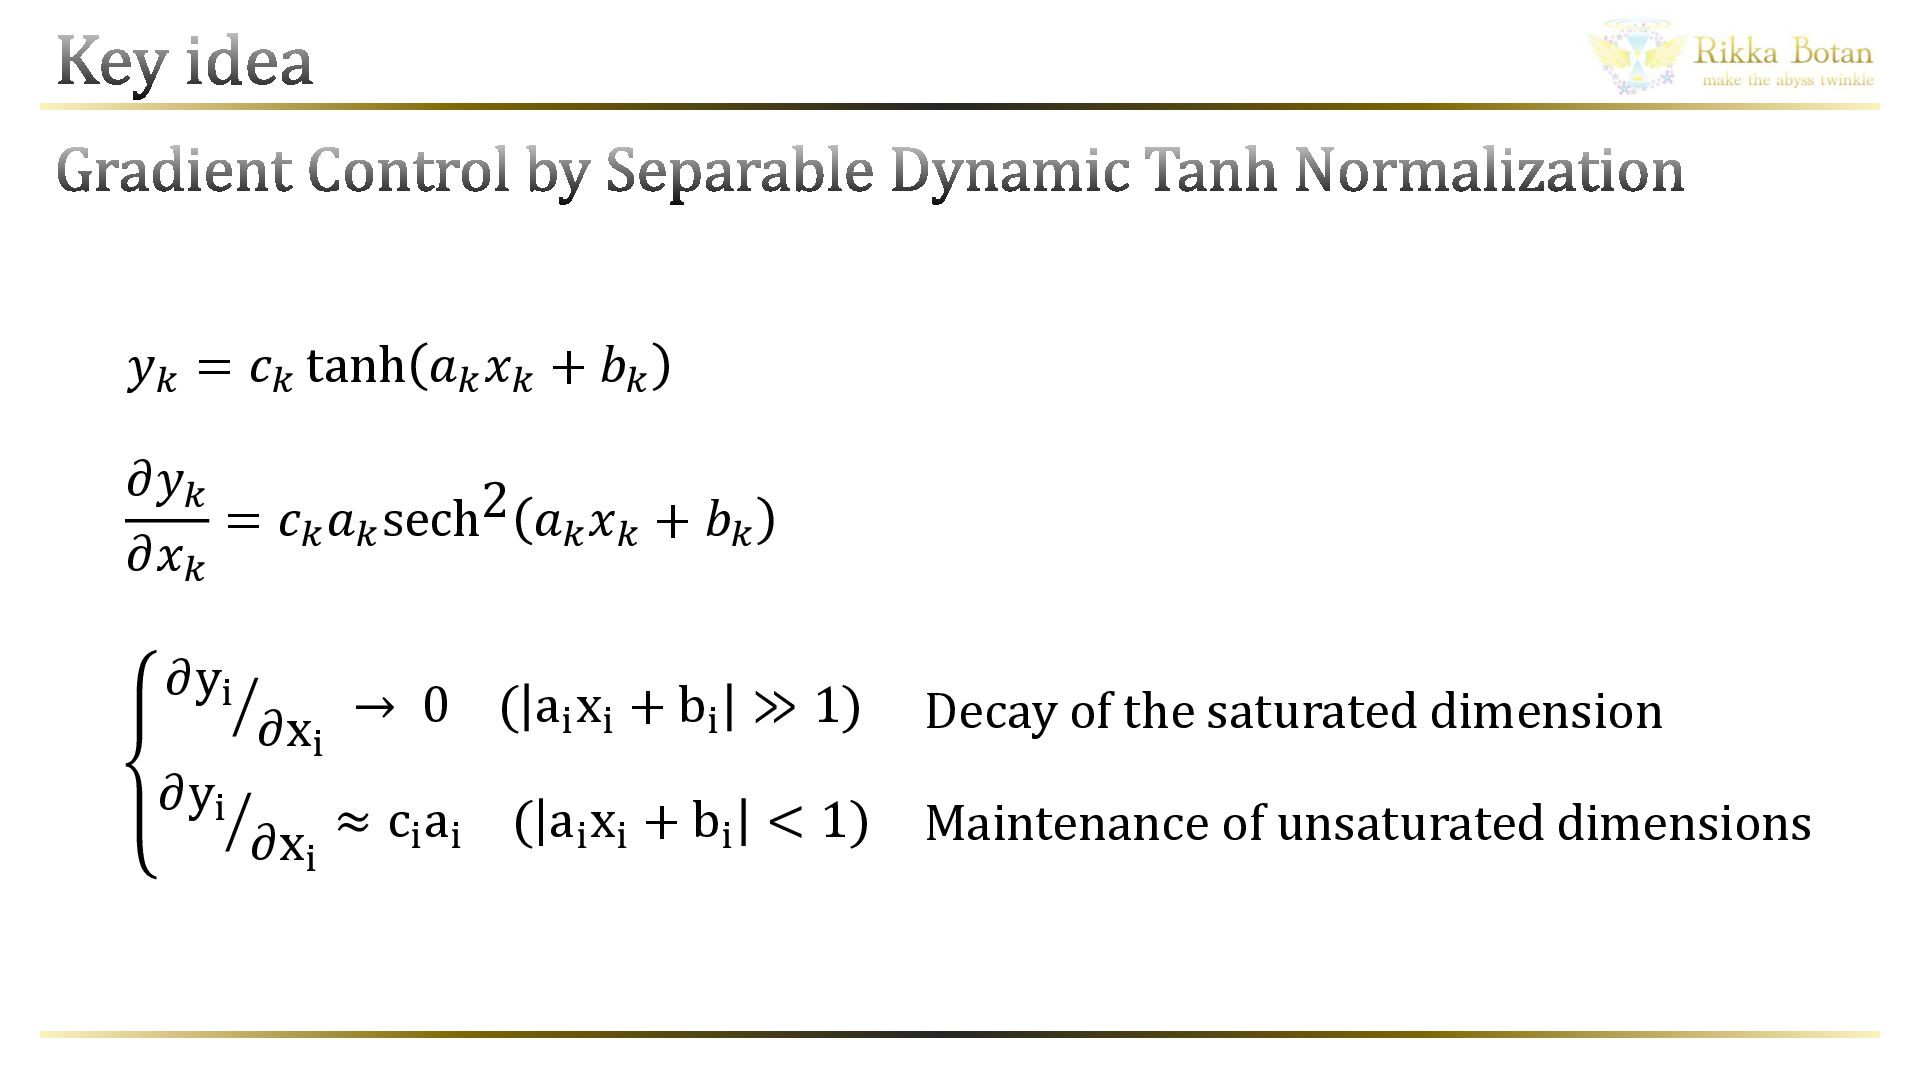
  7. Key idea Gradient Control by Separable Dynamic Tanh Normalization 𝑦𝑘

    = 𝑐𝑘 tanh 𝑎𝑘 𝑥𝑘 + 𝑏𝑘 𝜕𝑦𝑘 = 𝑐𝑘 𝑎𝑘 sech2 𝑎𝑘 𝑥𝑘 + 𝑏𝑘 𝜕𝑥𝑘 𝜕yi ൗ𝜕x → 0 ( ai xi + bi ≫ 1) i 𝜕yi ൗ𝜕x ≈ ci ai ( ai xi + bi < 1) i Decay of the saturated dimension Maintenance of unsaturated dimensions
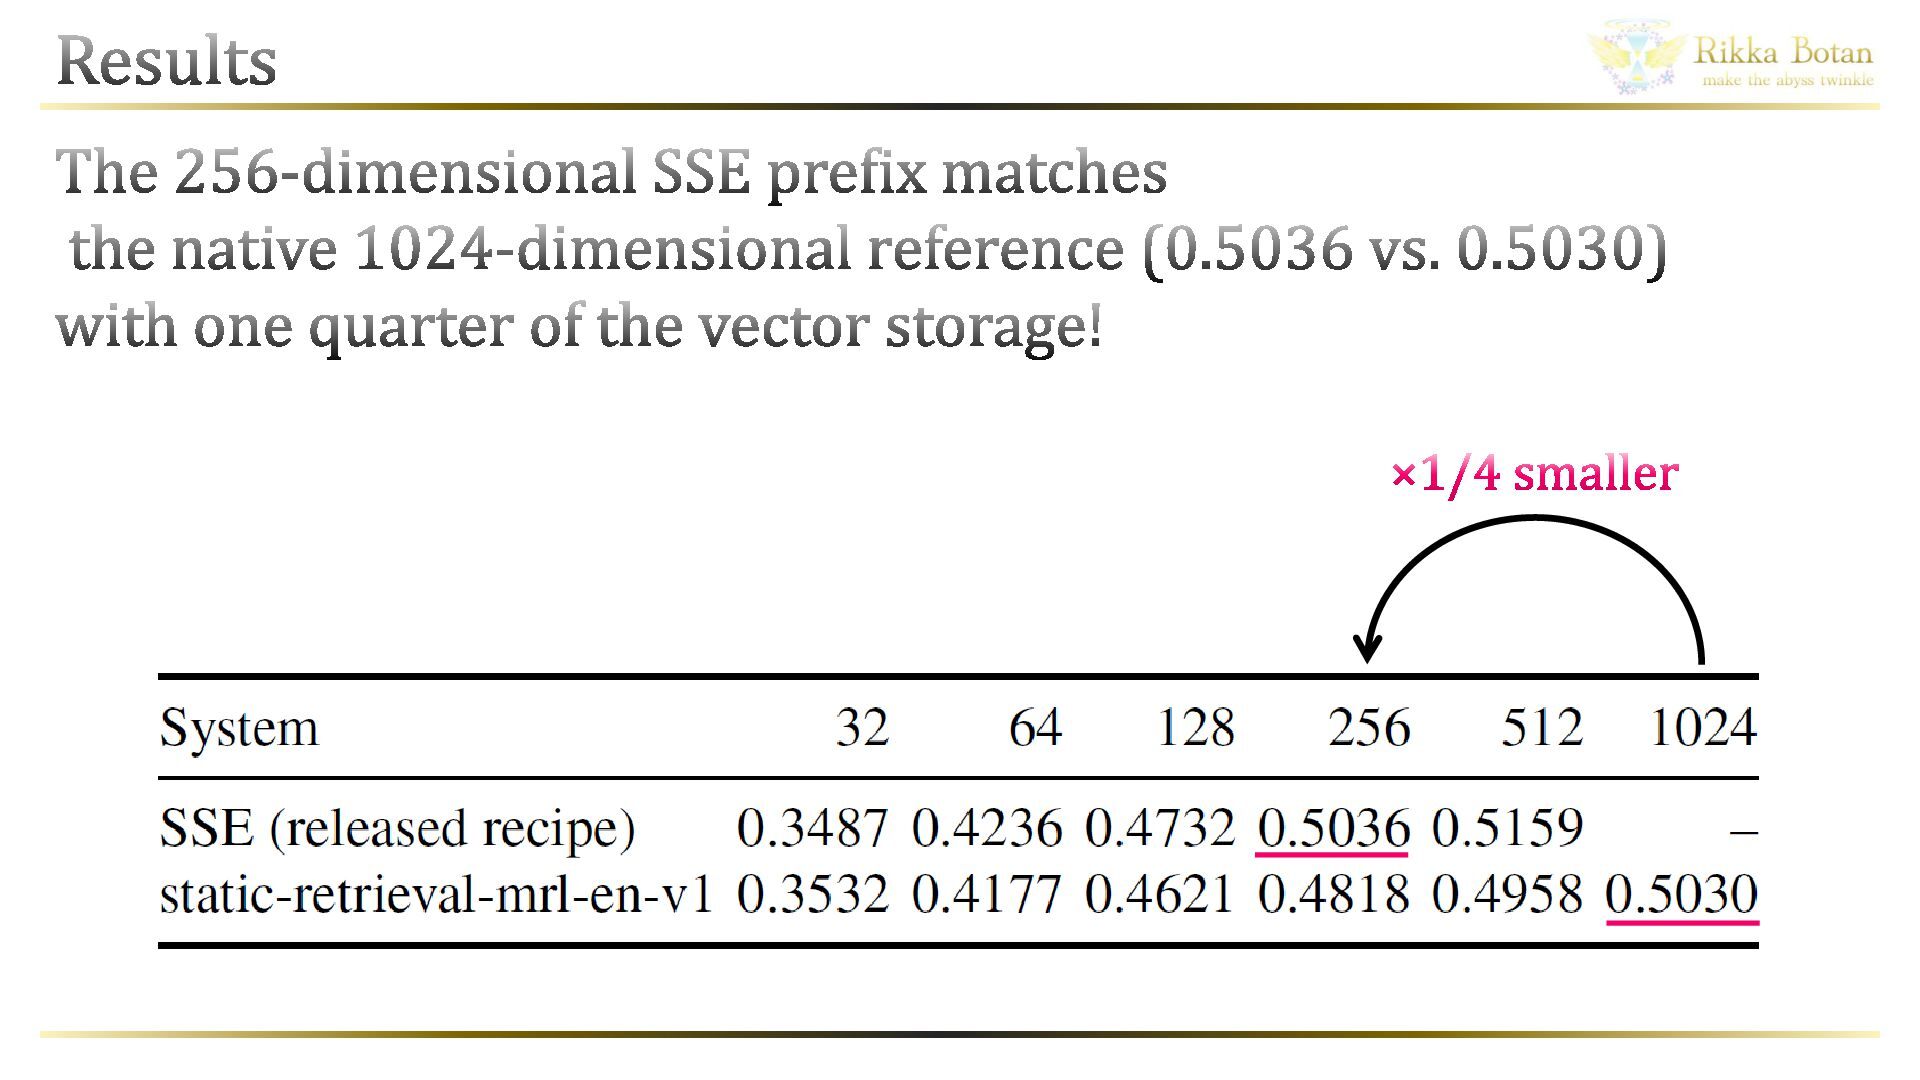
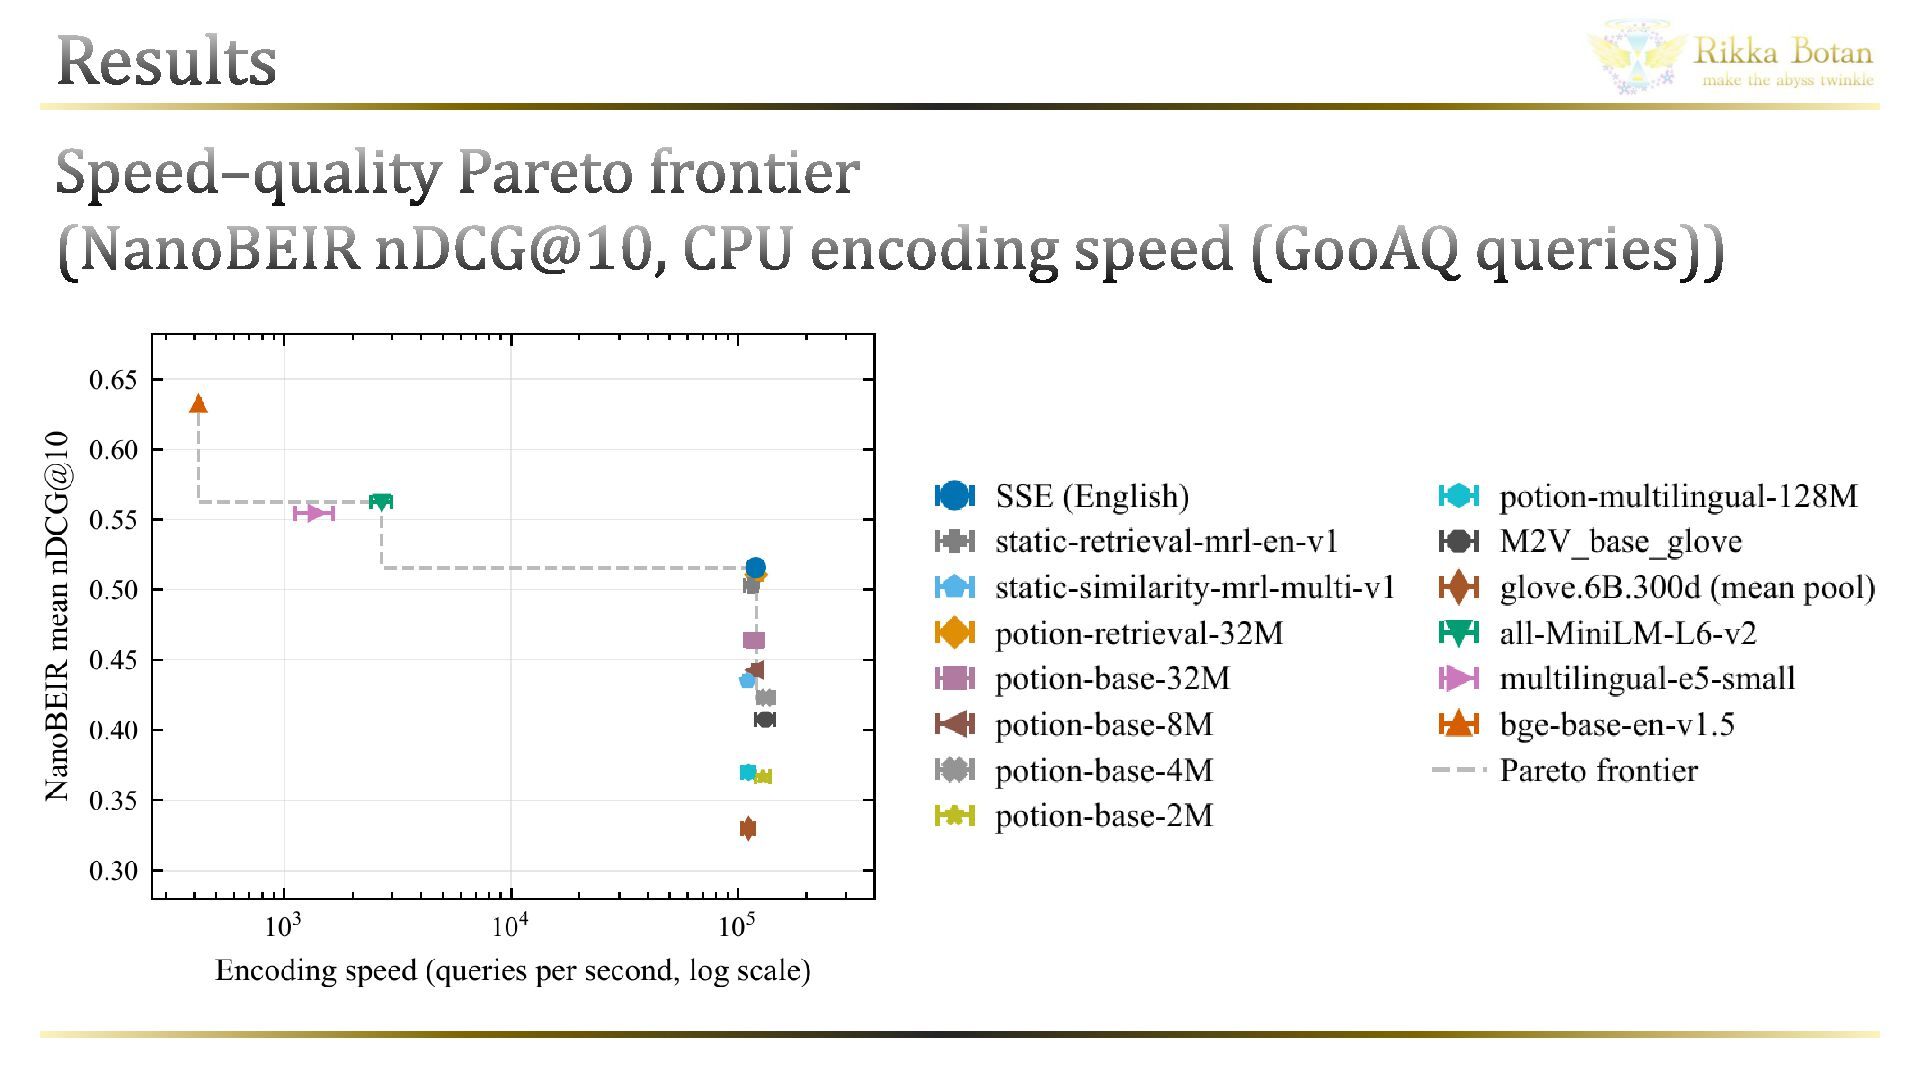
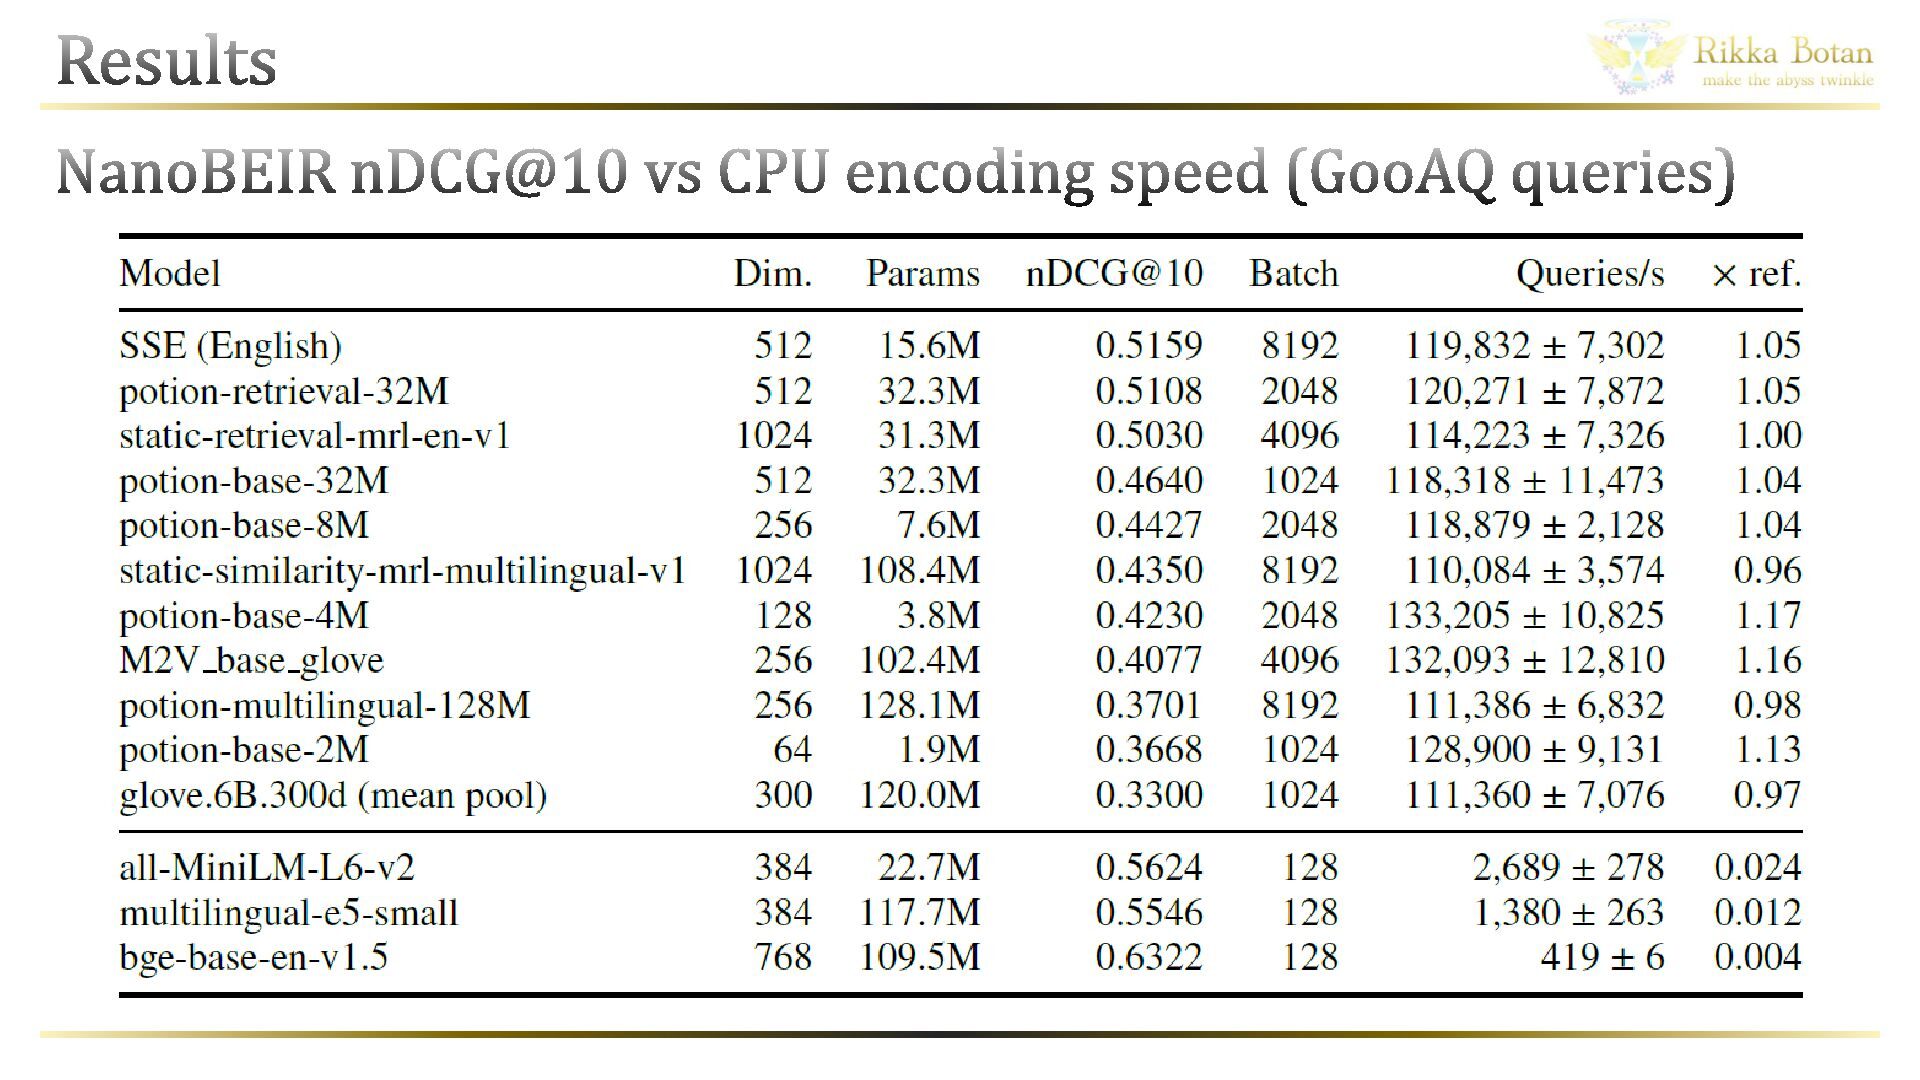
  8. Results The 256-dimensional SSE prefix matches the native 1024-dimensional reference

    (0.5036 vs. 0.5030) with one quarter of the vector storage! ×1/4 smaller
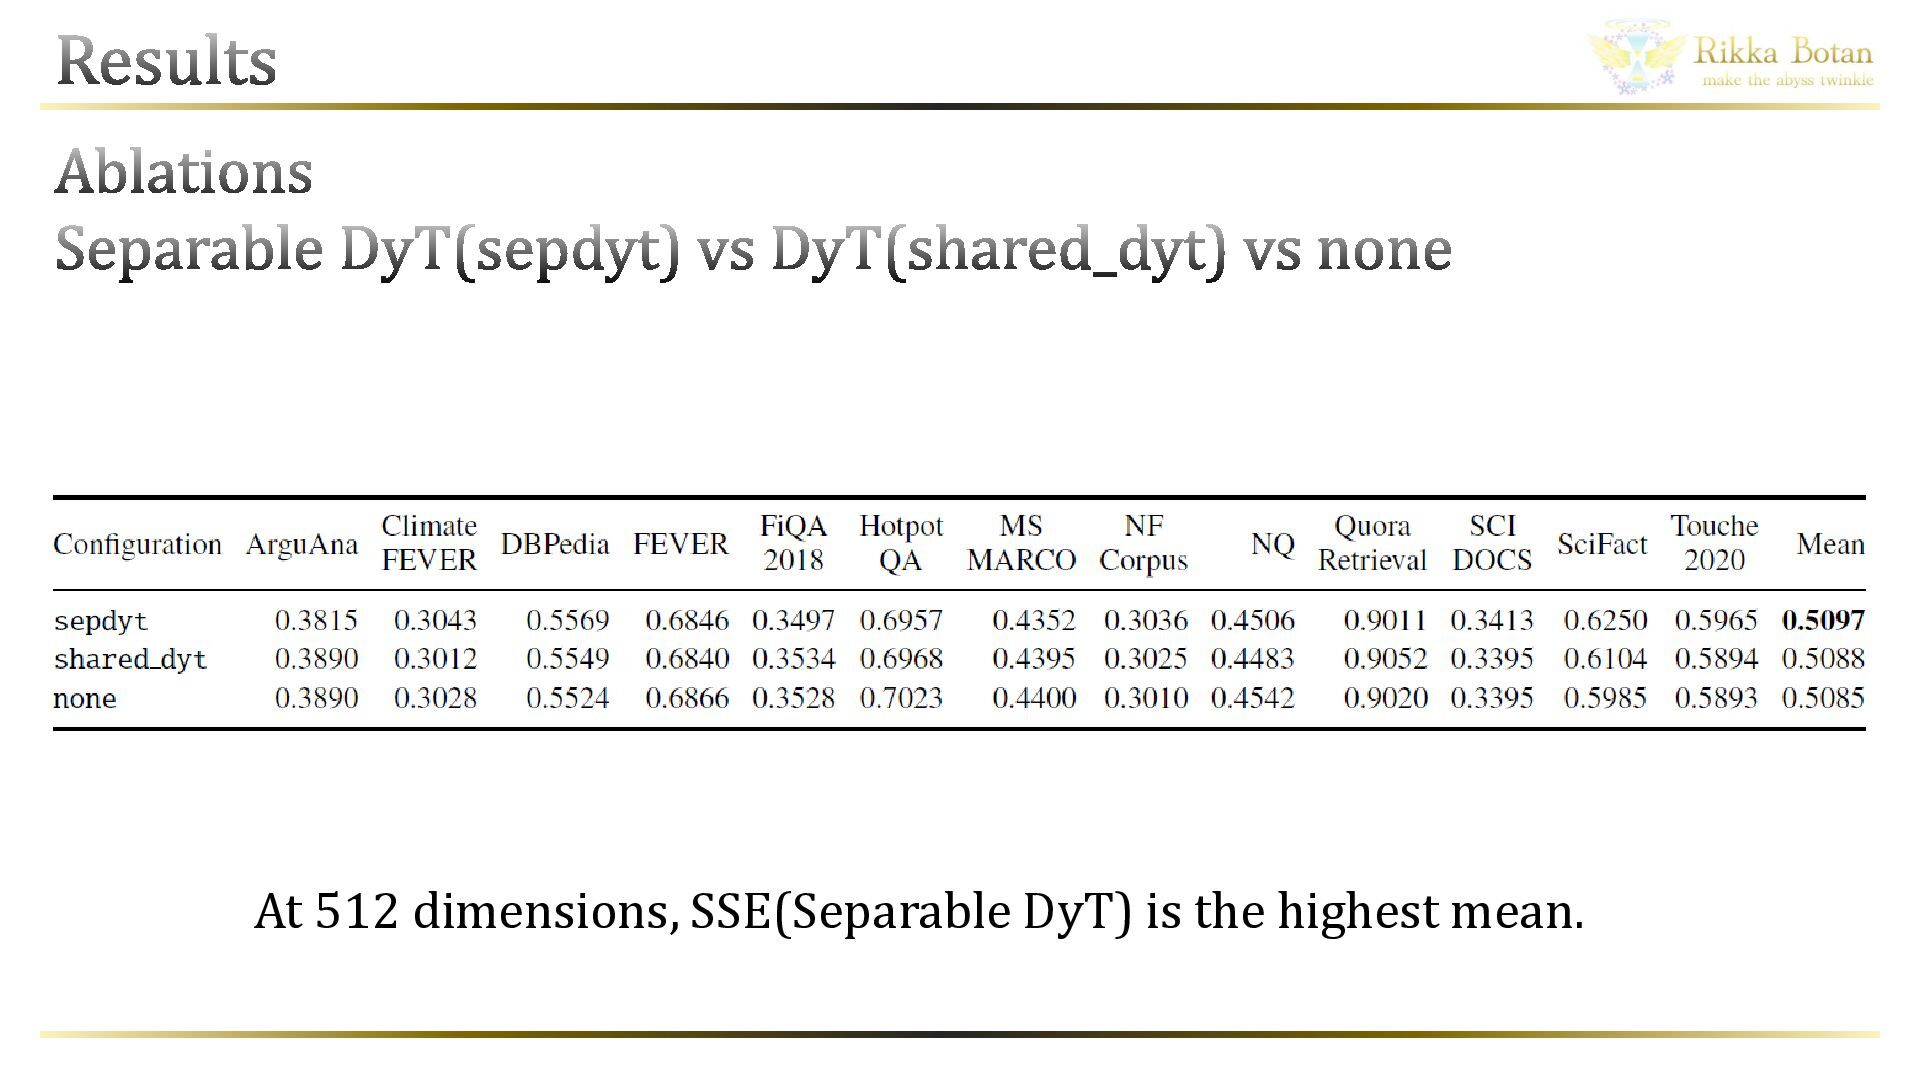
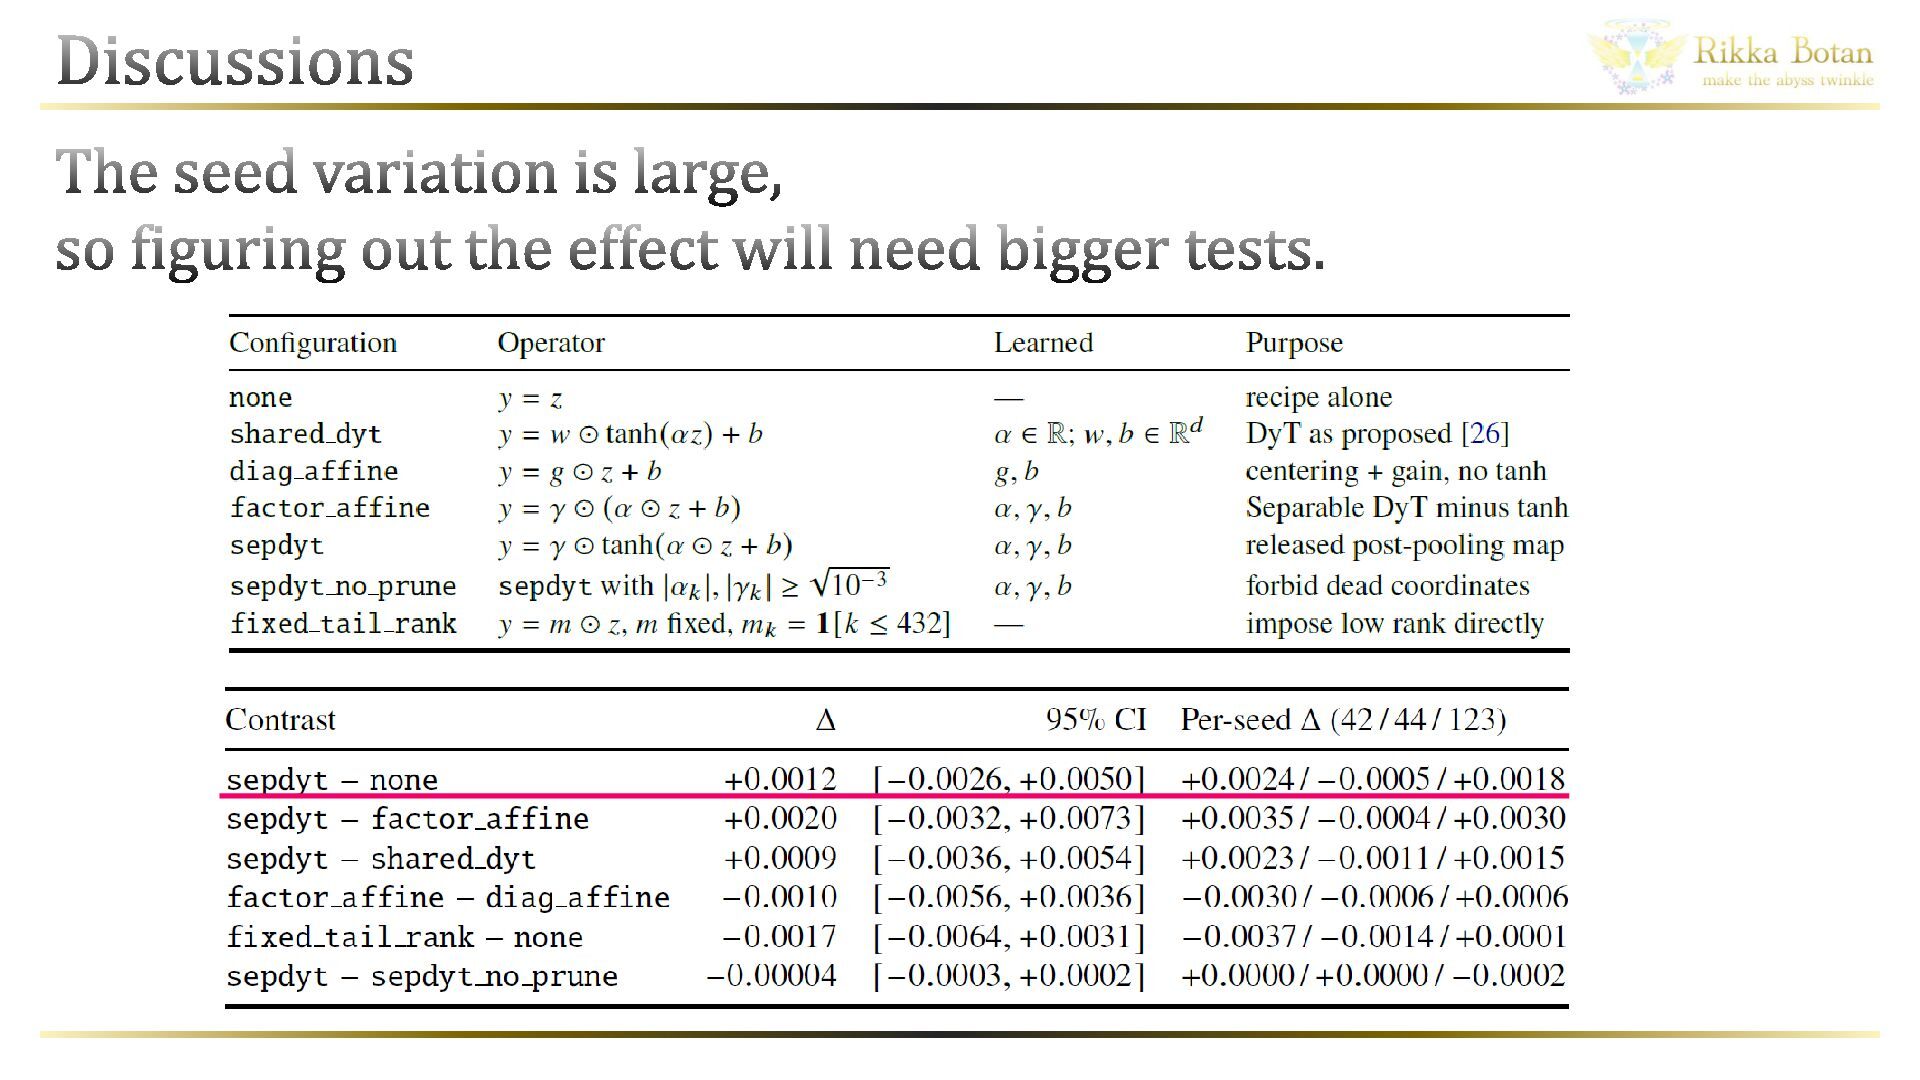
  9. Results Ablations Separable DyT(sepdyt) vs DyT(shared_dyt) vs none At 512

    dimensions, SSE(Separable DyT) is the highest mean.
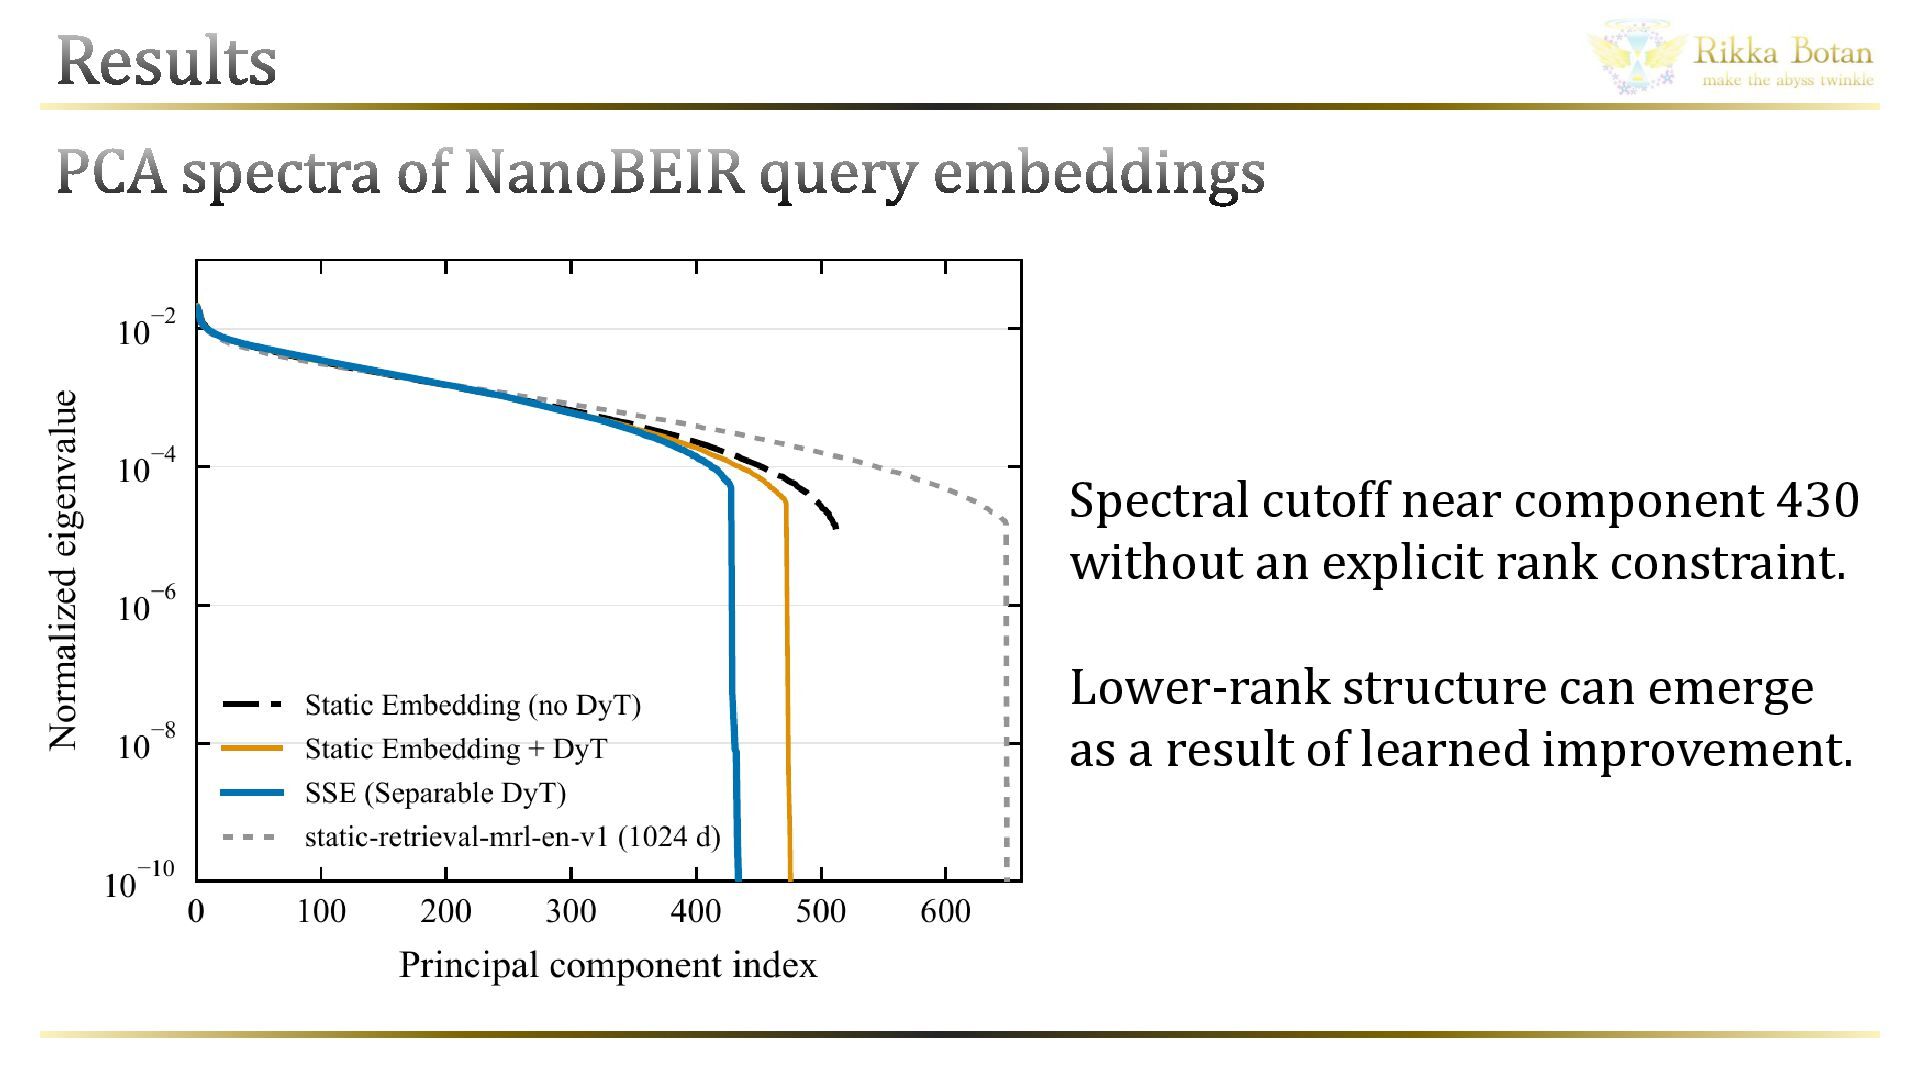
  10. Results PCA spectra of NanoBEIR query embeddings Spectral cutoff near

    component 430 without an explicit rank constraint. Lower-rank structure can emerge as a result of learned improvement.
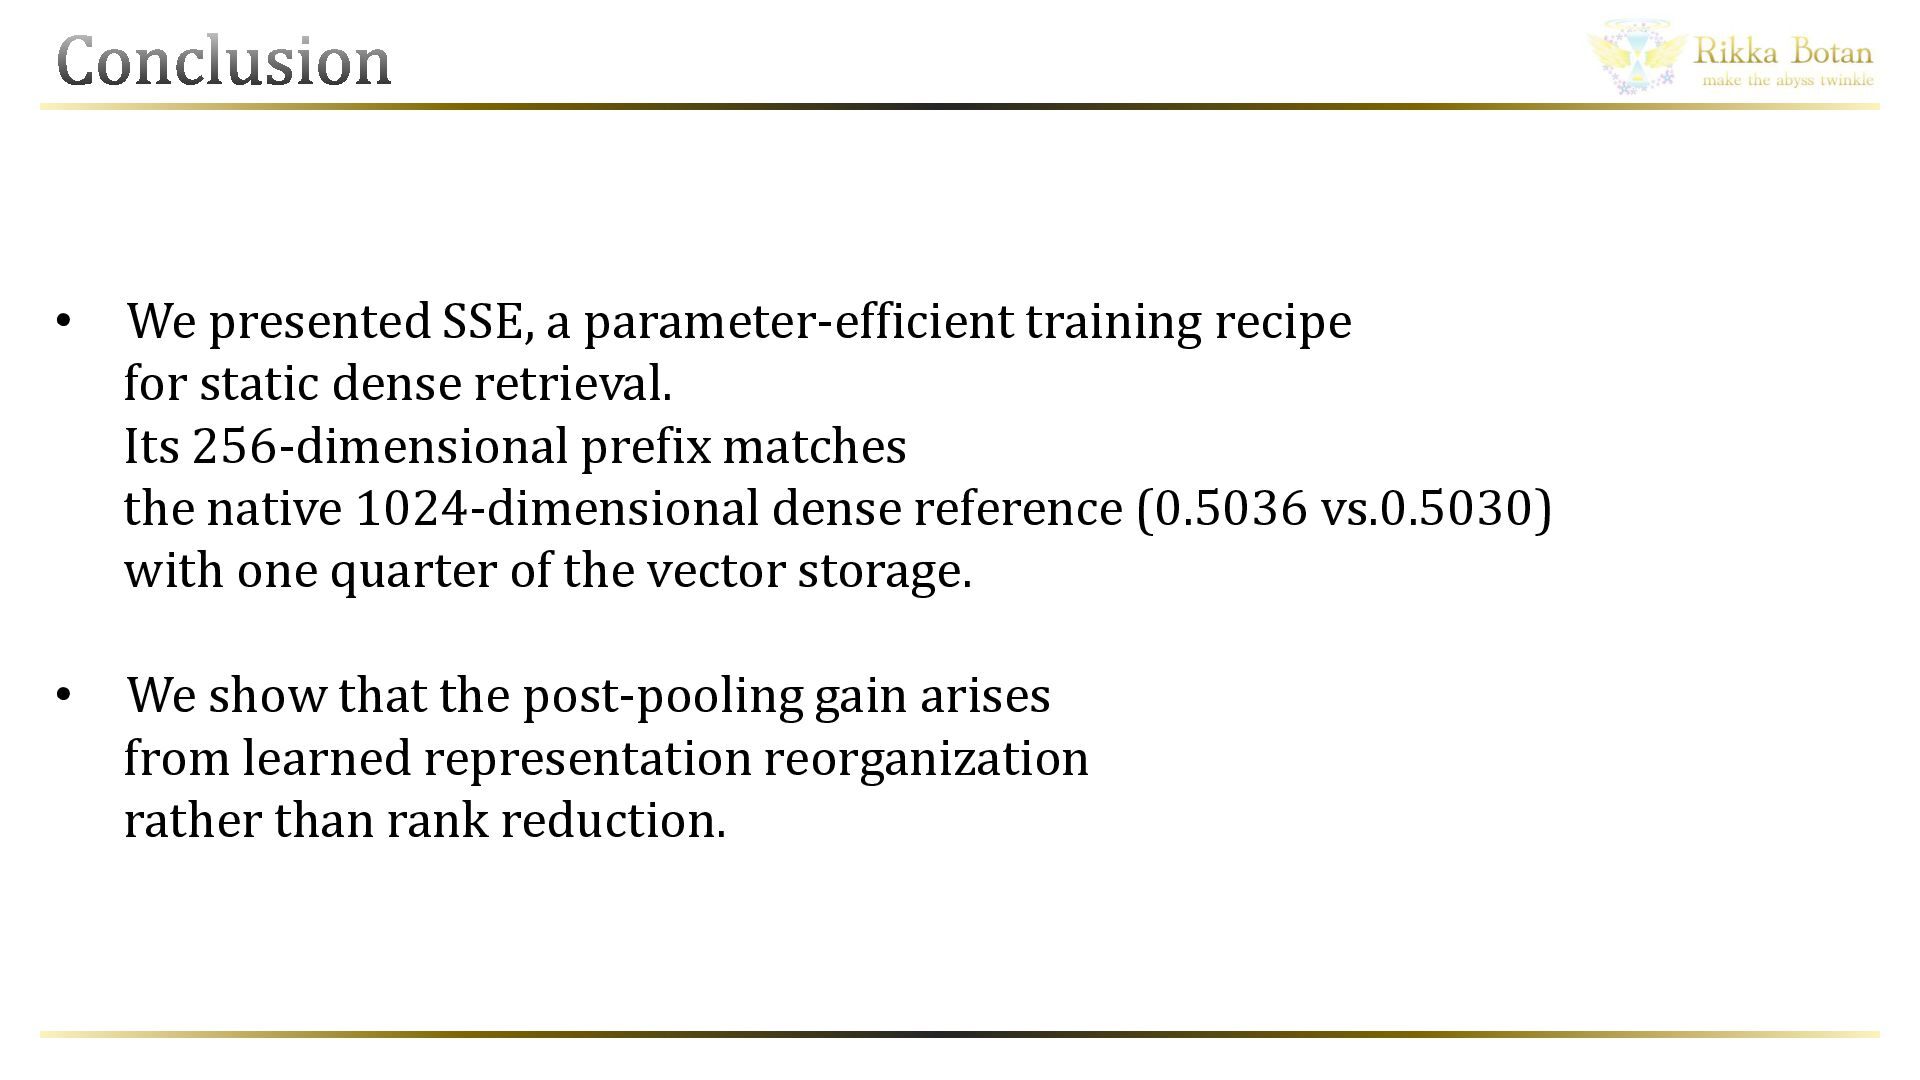
  11. Conclusion • We presented SSE, a parameter-efficient training recipe for

    static dense retrieval. Its 256-dimensional prefix matches the native 1024-dimensional dense reference (0.5036 vs.0.5030) with one quarter of the vector storage. • We show that the post-pooling gain arises from learned representation reorganization rather than rank reduction.
  12. References [1] D. Reinsel et al., "The Digitization of the

    World," IDC #US44413318, 2018. [2] IDC, "Worldwide Global DataSphere Forecast, 2021–2025," #US46410421, 2021. [3] IDC, "Worldwide IDC Global DataSphere Forecast, 2024–2028," 2024. [4] P. Covington et al., "Deep Neural Networks for YouTube Recommendations," RecSys, 2016. [5] R. Ying et al., "Graph Convolutional Neural Networks for Web-Scale Recommender Systems," KDD, 2018. [6] Twitter Engineering, "Twitter's Recommendation Algorithm," blog, Mar. 2023. [7] J. Zhai et al., "Actions Speak Louder than Words," ICML, 2024. [8] Tom Aarsen, “Train 400x faster Static Embedding Models with Sentence Transformers”, HuggingFace blog, 2025. [9] Tomas Mikolov et al., “Efficient Estimation of Word Representations in Vector Space”, arXiv:1301.3781, 2013. [10] Jeffrey Pennington et al., “GloVe: Global Vectors for Word Representation”, Association for Computational Linguistics:D14-1162, 2014. [11] Thomas van Dongen, Stéphan Tulkens, “Model2Vec: Distill a Small Fast Model from any Sentence Transformer”, HuggingFace blog, 2024. [12] Jiachen Zhu, Xinlei Chen, Kaiming He, Yann LeCun and Zhuang Liu. Transformers without Normalization. arXiv:2503.10622, 2025.