Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
【HackSick vol.10 LT会】複数軸から見るSelf Attention改善手法の...
Search
Rikka Botan
October 31, 2026
Research
16
0
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
【HackSick vol.10 LT会】複数軸から見るSelf Attention改善手法の体系的整理
近年、性能改善と事前学習安定化、スーパーウェイトの発生抑制を目的としてさまざまな手法が提案されています。
Self Attentionの改善手法を複数軸で体系的に解説します。
Rikka Botan
October 31, 2026
More Decks by Rikka Botan
See All by Rikka Botan
ICAITD 2026 Oral Presentation
rikkabotan7
0
120
生成AIなんでも展示会vol6 LT登壇資料 NexteraBERT
rikkabotan7
0
210
HackSick vol.7 LT資料【LLMアーキテクチャ入門・事前学習時の躓き所解説】 スパースなAttention・状態空間モデル
rikkabotan7
0
230
SSE: Stable Static Embedding
rikkabotan7
0
54
【ローカルAI LT大会】SSE: Stable Static Embedding ー速度低下を伴わず 静的埋め込みモデルの潜在能力を引き出す Dynamic Tanh手法の提案
rikkabotan7
0
120
Other Decks in Research
See All in Research
SPACE 2026 - Femmes en Elevage – Regards croisés desdifférentes filières
institutdelelevage
PRO
0
110
SPACE 2026 - Renforcer l’attractivité des métiers des productions animales dans les établissements d'enseignement agricole
institutdelelevage
PRO
0
110
ふとした出会いで生まれたSkillが、 社内利用1位になるまで
mikimhk
22
25k
実例から見るLLMのマンガ理解:実務VQAタスクによる長期的文脈と視覚情報の定性評価
kzmssk
0
200
超効率化への挑戦:1bit LLMの現状と展望
yumaichikawa
0
940
Bilan travail en élevage : première restitution des enquêtes 2025-2026
institutdelelevage
PRO
0
130
[CV勉強会@関東 CVPR2026] PSDesigner: Automated Graphic Design with a Human-Like Creative Workflow / kantocv 67th CVPR 2026
shunk031
0
390
Vector Map as Language: Toward Unified Remote Sensing Vector Mapping
satai
3
330
山中市政が招いた組織崩壊:よこはま安心ボックスを例に
sishi
0
360
モデル評価を効率的にする方法
ftakahashi
0
230
横浜市長(山中氏)の言動にかかる第三者による調査報告書
sishi2026
0
670
【令和7年度版】内航船 VS 外航船 早見表
anikisencyo
0
150
Featured
See All Featured
Done Done
chrislema
187
17k
The Director’s Chair: Orchestrating AI for Truly Effective Learning
tmiket
1
340
Conquering PDFs: document understanding beyond plain text
inesmontani
PRO
4
3.2k
Making the Leap to Tech Lead
cromwellryan
135
10k
The untapped power of vector embeddings
frankvandijk
2
2k
A Tale of Four Properties
chriscoyier
163
24k
A better future with KSS
kneath
240
18k
Odyssey Design
rkendrick25
PRO
2
900
Stop Working from a Prison Cell
hatefulcrawdad
274
21k
Are puppies a ranking factor?
jonoalderson
2
4.1k
DBのスキルで生き残る技術 - AI時代におけるテーブル設計の勘所
soudai
PRO
68
59k
Java REST API Framework Comparison - PWX 2021
mraible
34
9.8k
Transcript
複数軸から見るSelf Attention改善手法の体系的整理 GSXA: Gated Scalable Exclusive Self Attentionの提案
Vol.10
自己紹介 / About us り っ か ぼ た ん
六花 牡丹 Rikka Botan 独立研究者(機械学習 / 代数学 / 数理論理学) Independent researcher (machine learning / algebra / mathematical logic) ◆趣味 お菓子作り・紅茶・クラシック鑑賞・お洋服 ◆最近の活動 Silver Award: Liquid AI Hackathon Series | Tokyo 記事執筆(Mamba, LFM2 (LTCs) 関連) SSE Model / NexteraBERT Modelシリーズの公開 X(Twitter) Portfolio
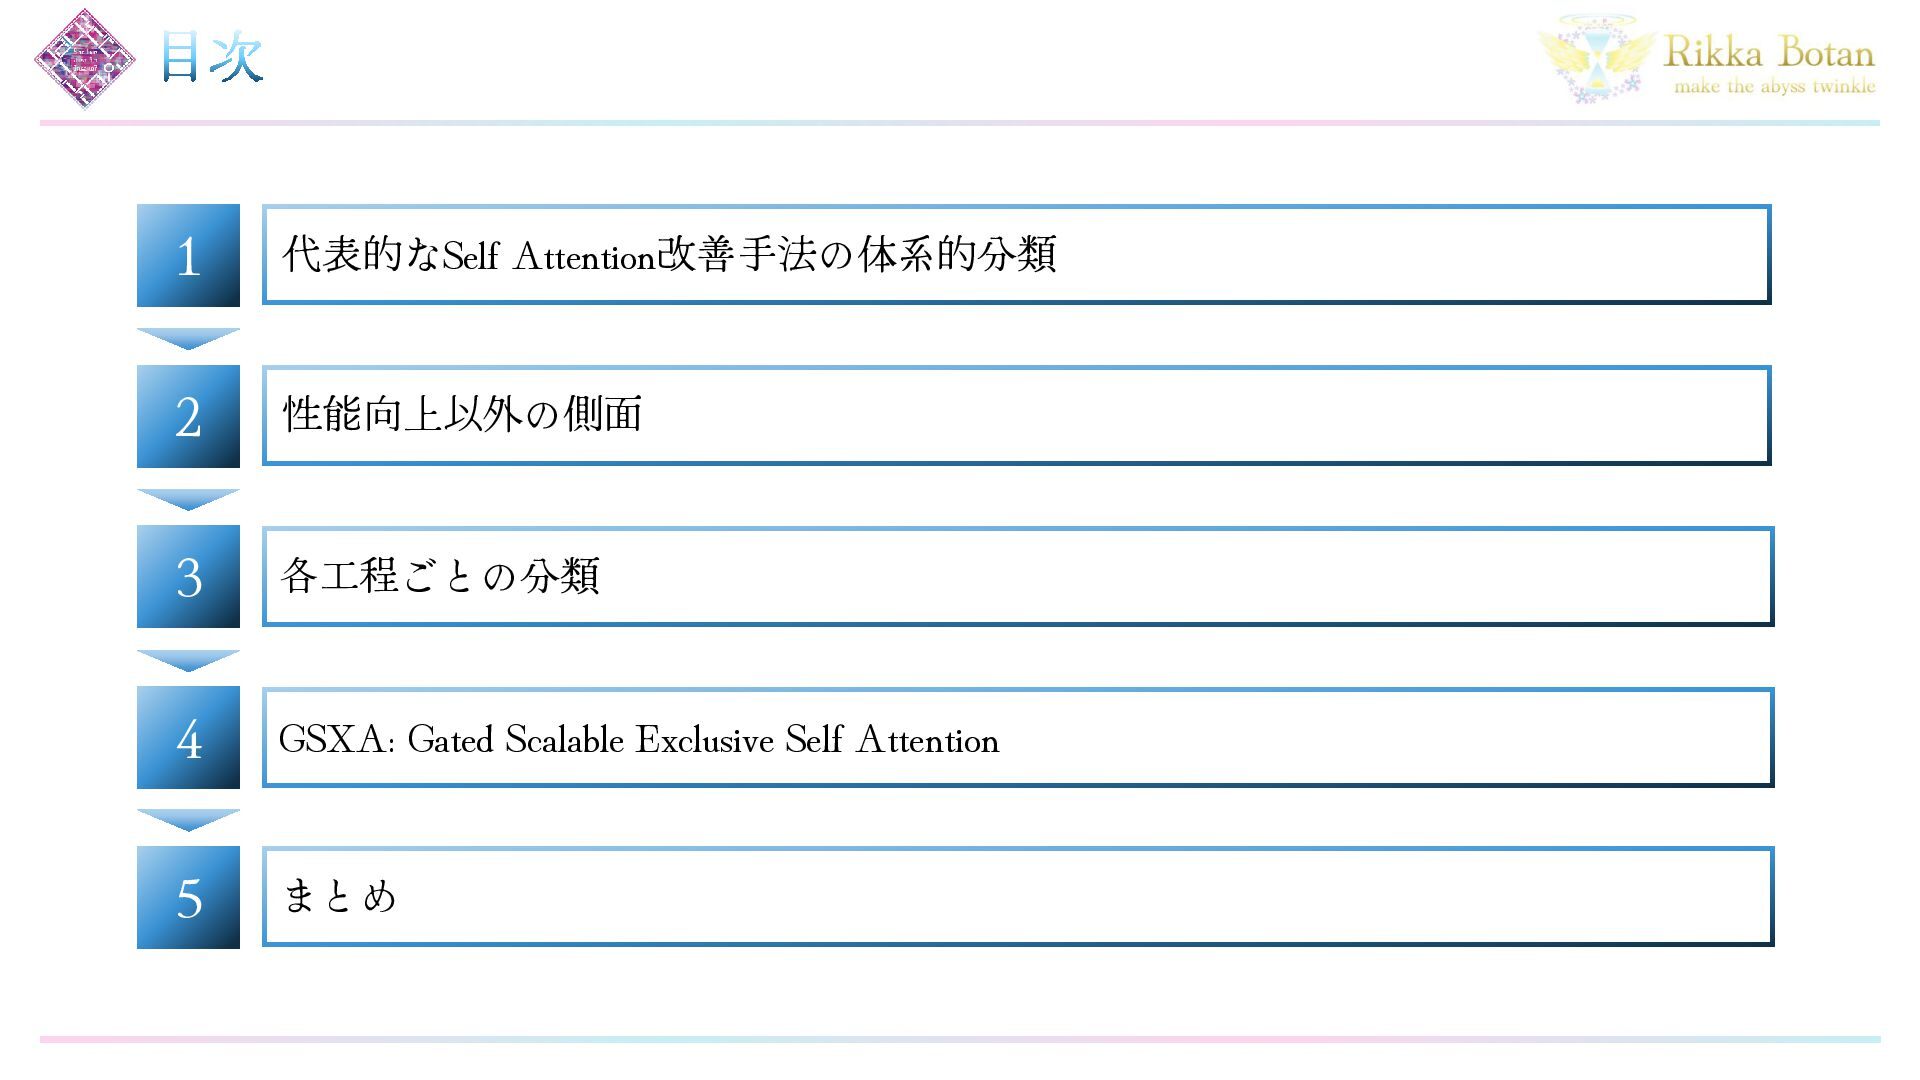
目次 1 代表的なSelf Attention改善手法の体系的分類 2 性能向上以外の側面 3 各工程ごとの分類 4 GSXA:
Gated Scalable Exclusive Self Attention 5 まとめ
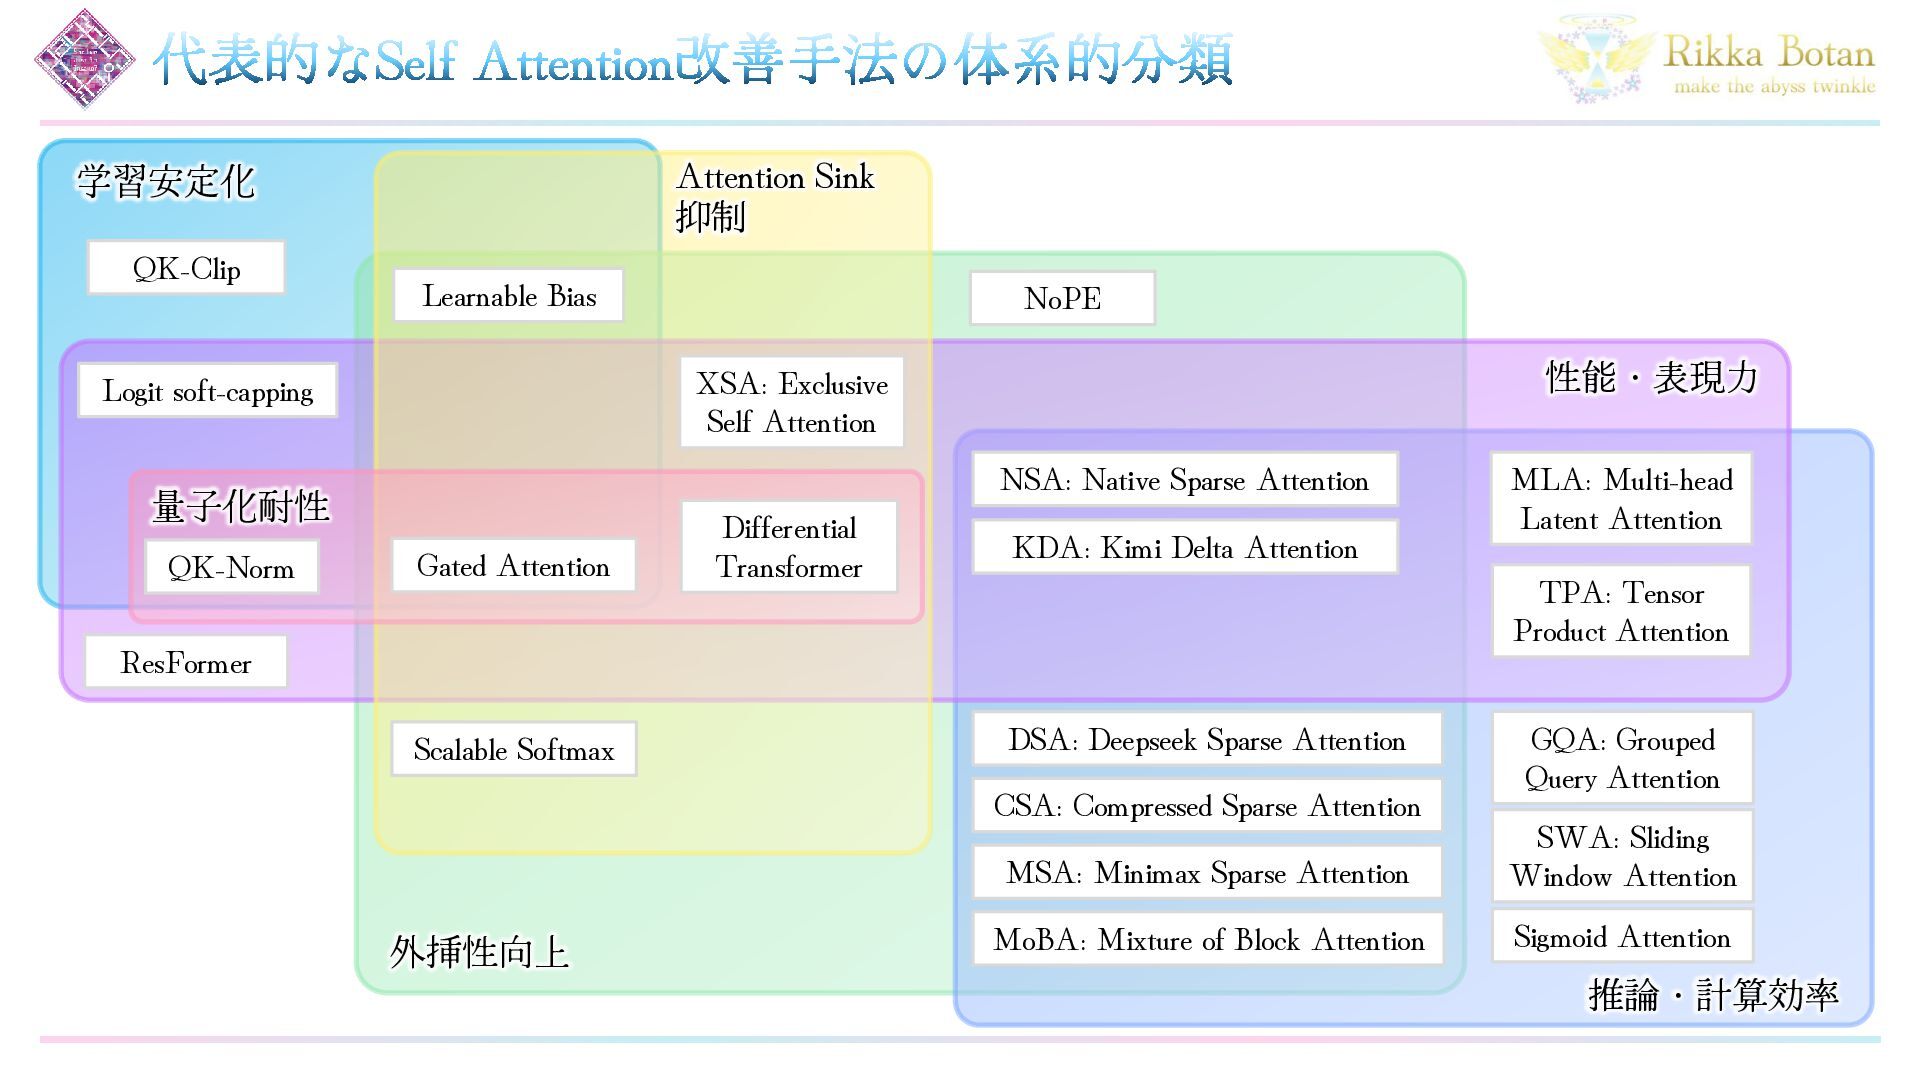
代表的なSelf Attention改善手法の体系的分類 Attention Sink 抑制 学習安定化 QK-Clip Learnable Bias 性能・表現力
XSA: Exclusive Self Attention Logit soft-capping NSA: Native Sparse Attention 量子化耐性 QK-Norm NoPE Gated Attention Differential Transformer KDA: Kimi Delta Attention TPA: Tensor Product Attention ResFormer Scalable Softmax DSA: Deepseek Sparse Attention CSA: Compressed Sparse Attention 外挿性向上 MLA: Multi-head Latent Attention GQA: Grouped Query Attention MSA: Minimax Sparse Attention SWA: Sliding Window Attention MoBA: Mixture of Block Attention Sigmoid Attention 推論・計算効率
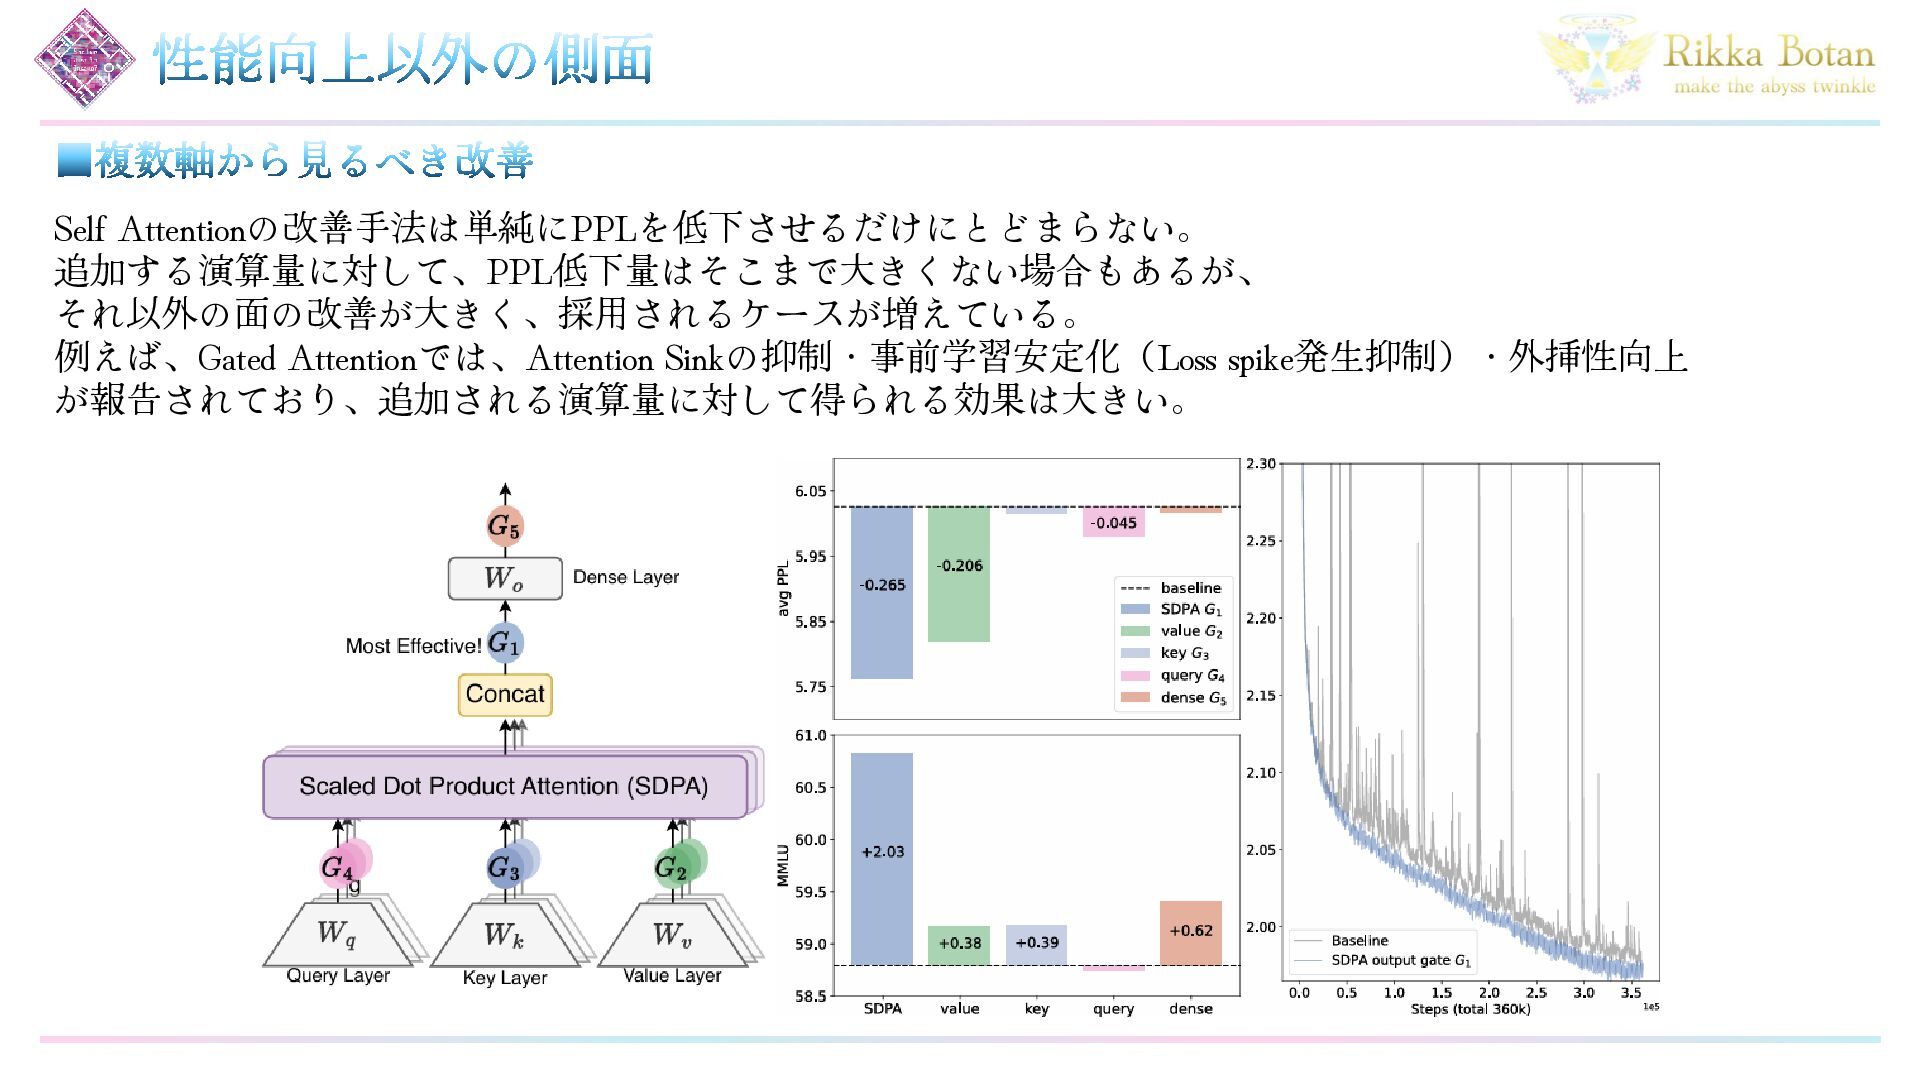
性能向上以外の側面 ▪複数軸から見るべき改善 Self Attentionの改善手法は単純にPPLを低下させるだけにとどまらない。 追加する演算量に対して、PPL低下量はそこまで大きくない場合もあるが、 それ以外の面の改善が大きく、採用されるケースが増えている。 例えば、Gated Attentionでは、Attention Sinkの抑制・事前学習安定化(Loss spike発生抑制)・外挿性向上
が報告されており、追加される演算量に対して得られる効果は大きい。
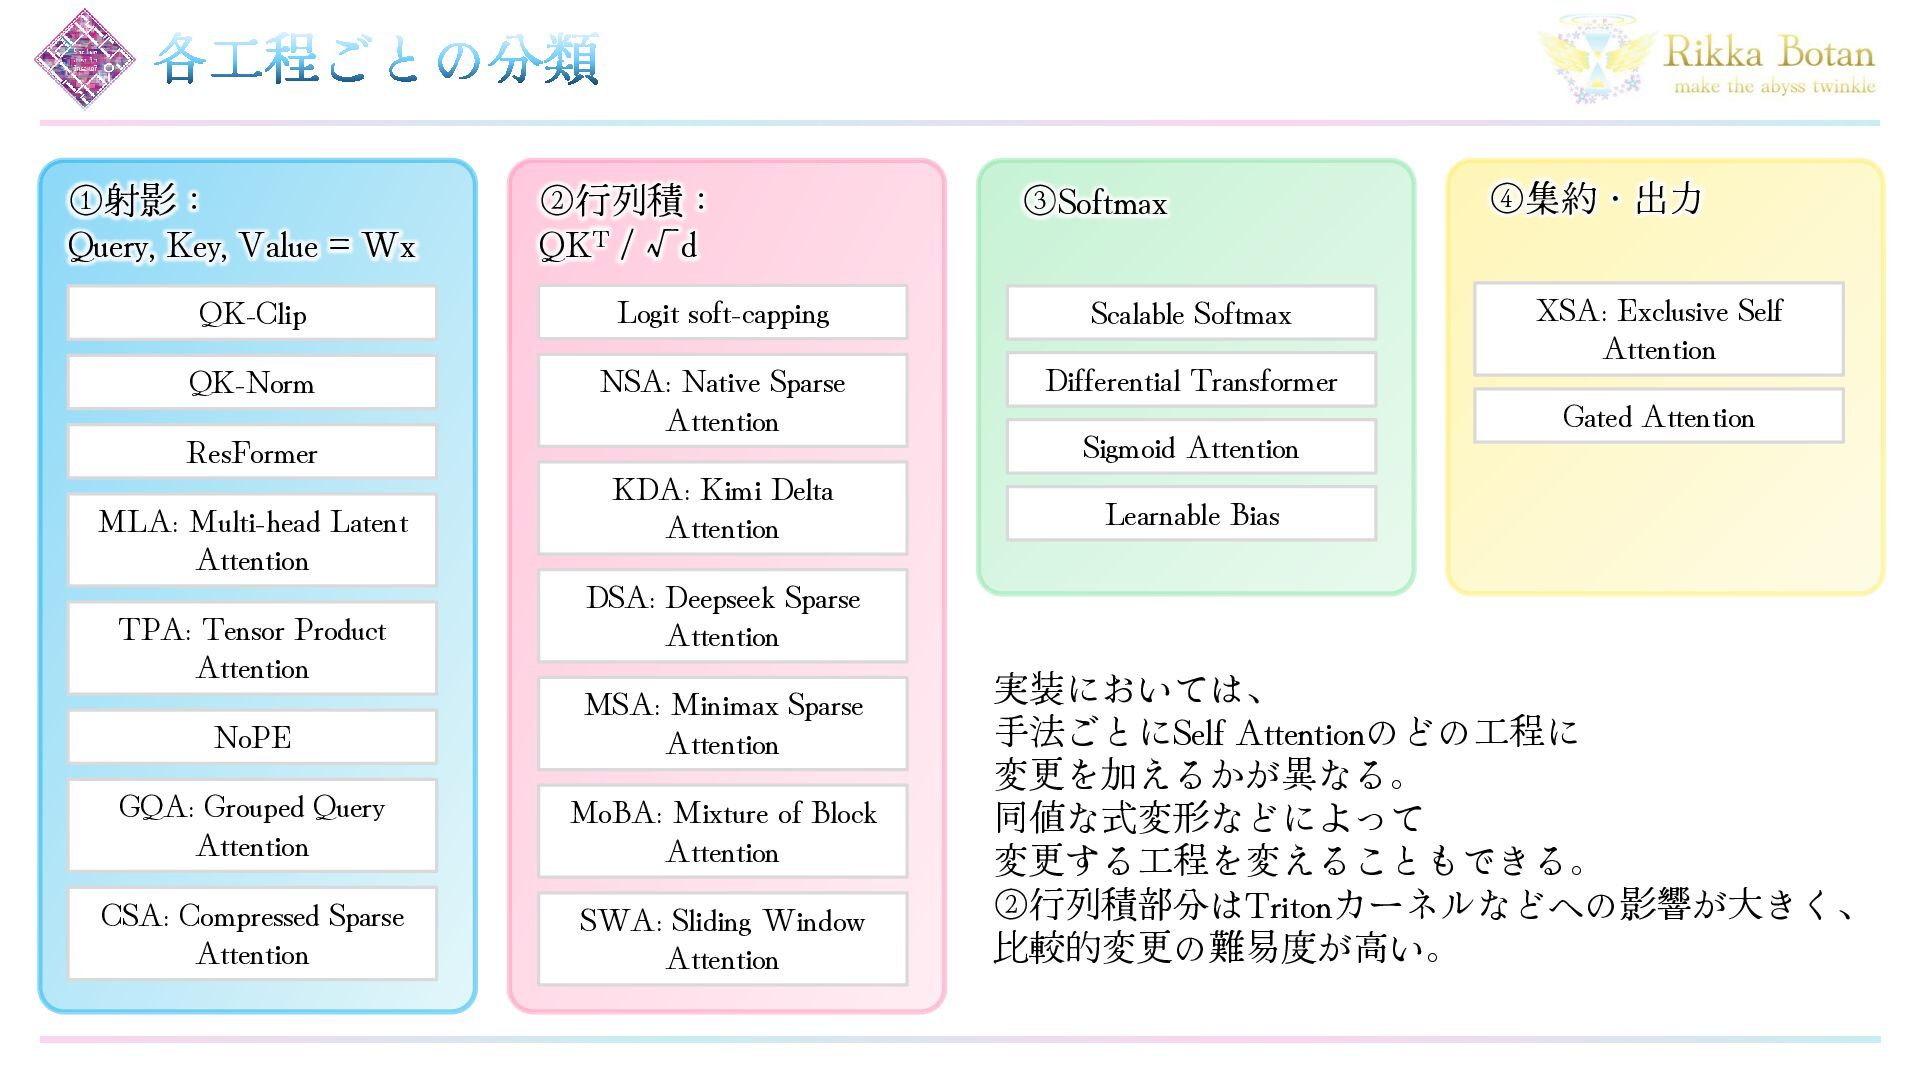
各工程ごとの分類 ①射影: Query, Key, Value = Wx ②行列積: QKT /
√d ③Softmax QK-Clip Logit soft-capping Scalable Softmax QK-Norm NSA: Native Sparse Attention Differential Transformer ResFormer MLA: Multi-head Latent Attention TPA: Tensor Product Attention KDA: Kimi Delta Attention Sigmoid Attention ④集約・出力 XSA: Exclusive Self Attention Gated Attention Learnable Bias DSA: Deepseek Sparse Attention NoPE MSA: Minimax Sparse Attention GQA: Grouped Query Attention MoBA: Mixture of Block Attention CSA: Compressed Sparse Attention SWA: Sliding Window Attention 実装においては、 手法ごとにSelf Attentionのどの工程に 変更を加えるかが異なる。 同値な式変形などによって 変更する工程を変えることもできる。 ②行列積部分はTritonカーネルなどへの影響が大きく、 比較的変更の難易度が高い。
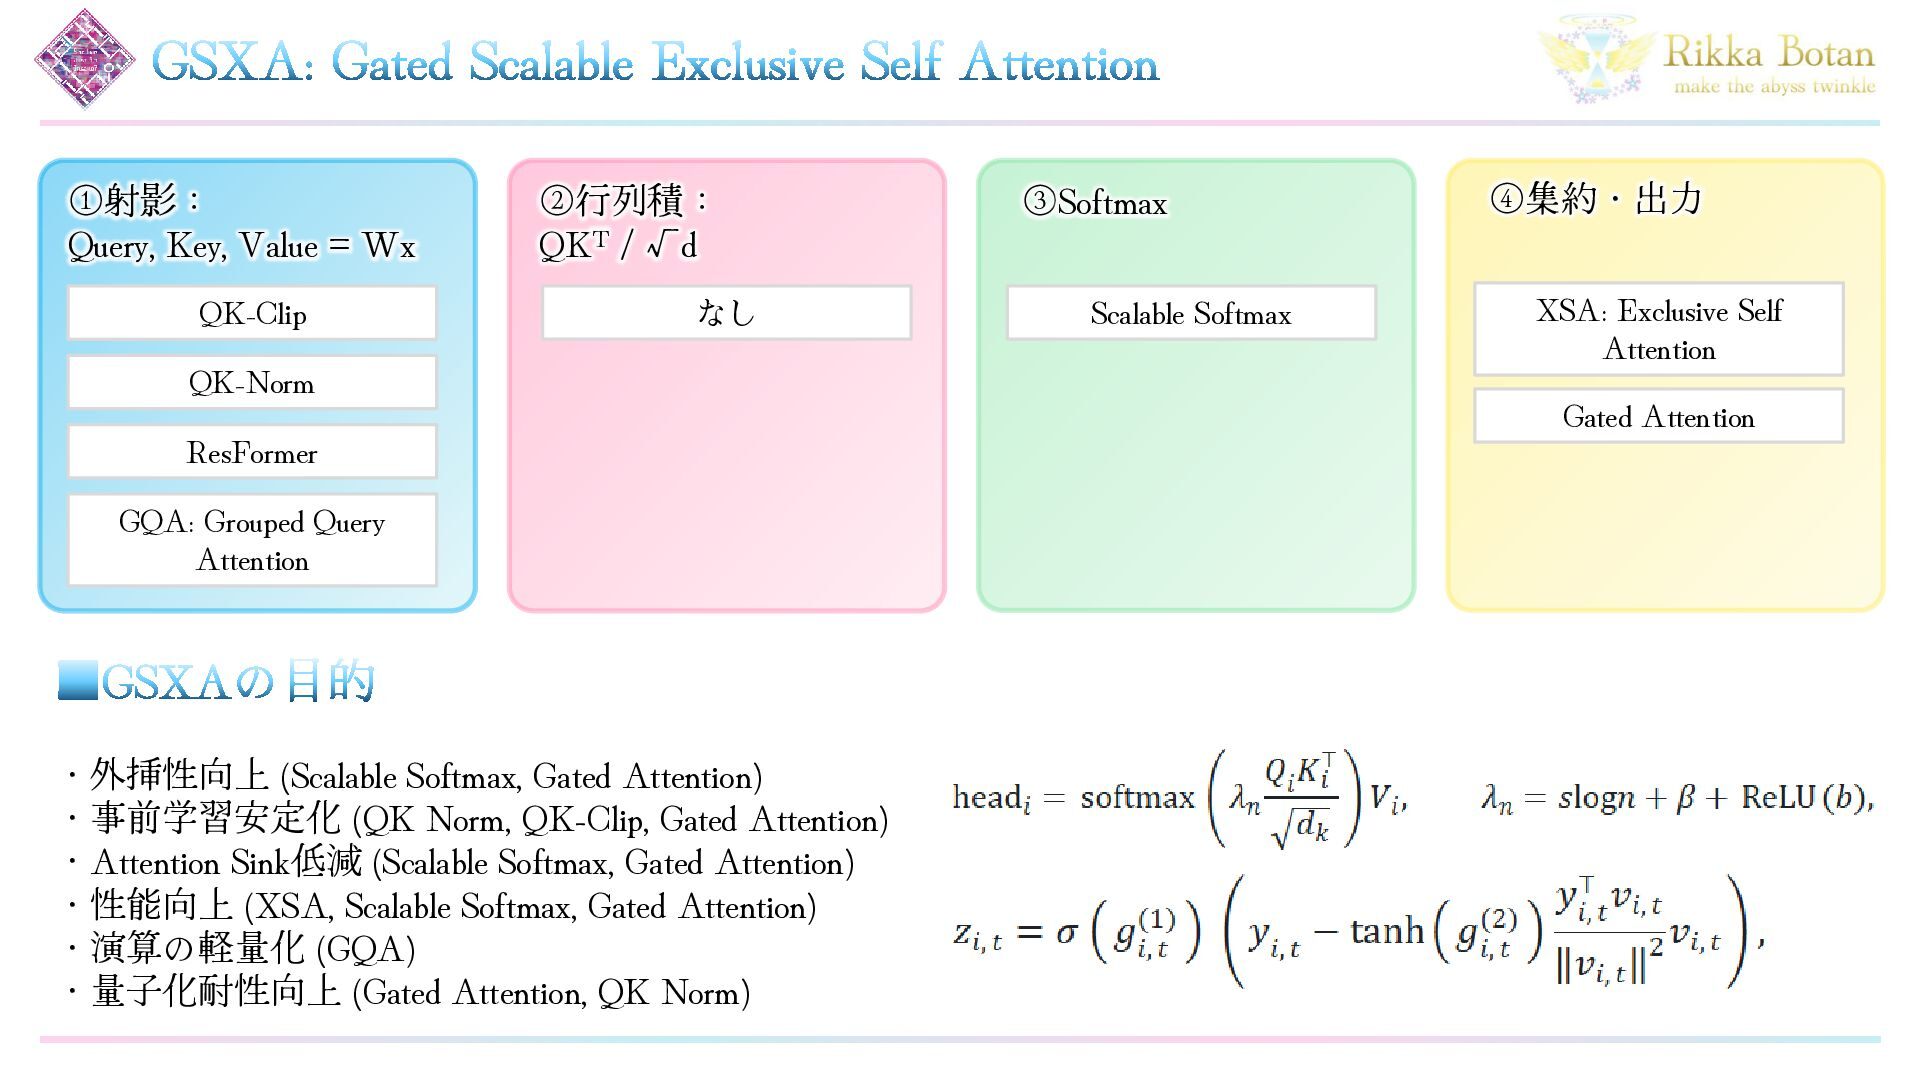
GSXA: Gated Scalable Exclusive Self Attention ①射影: Query, Key, Value
= Wx QK-Clip ②行列積: QKT / √d なし QK-Norm ResFormer GQA: Grouped Query Attention ▪GSXAの目的 ・外挿性向上 (Scalable Softmax, Gated Attention) ・事前学習安定化 (QK Norm, QK-Clip, Gated Attention) ・Attention Sink低減 (Scalable Softmax, Gated Attention) ・性能向上 (XSA, Scalable Softmax, Gated Attention) ・演算の軽量化 (GQA) ・量子化耐性向上 (Gated Attention, QK Norm) ③Softmax Scalable Softmax ④集約・出力 XSA: Exclusive Self Attention Gated Attention
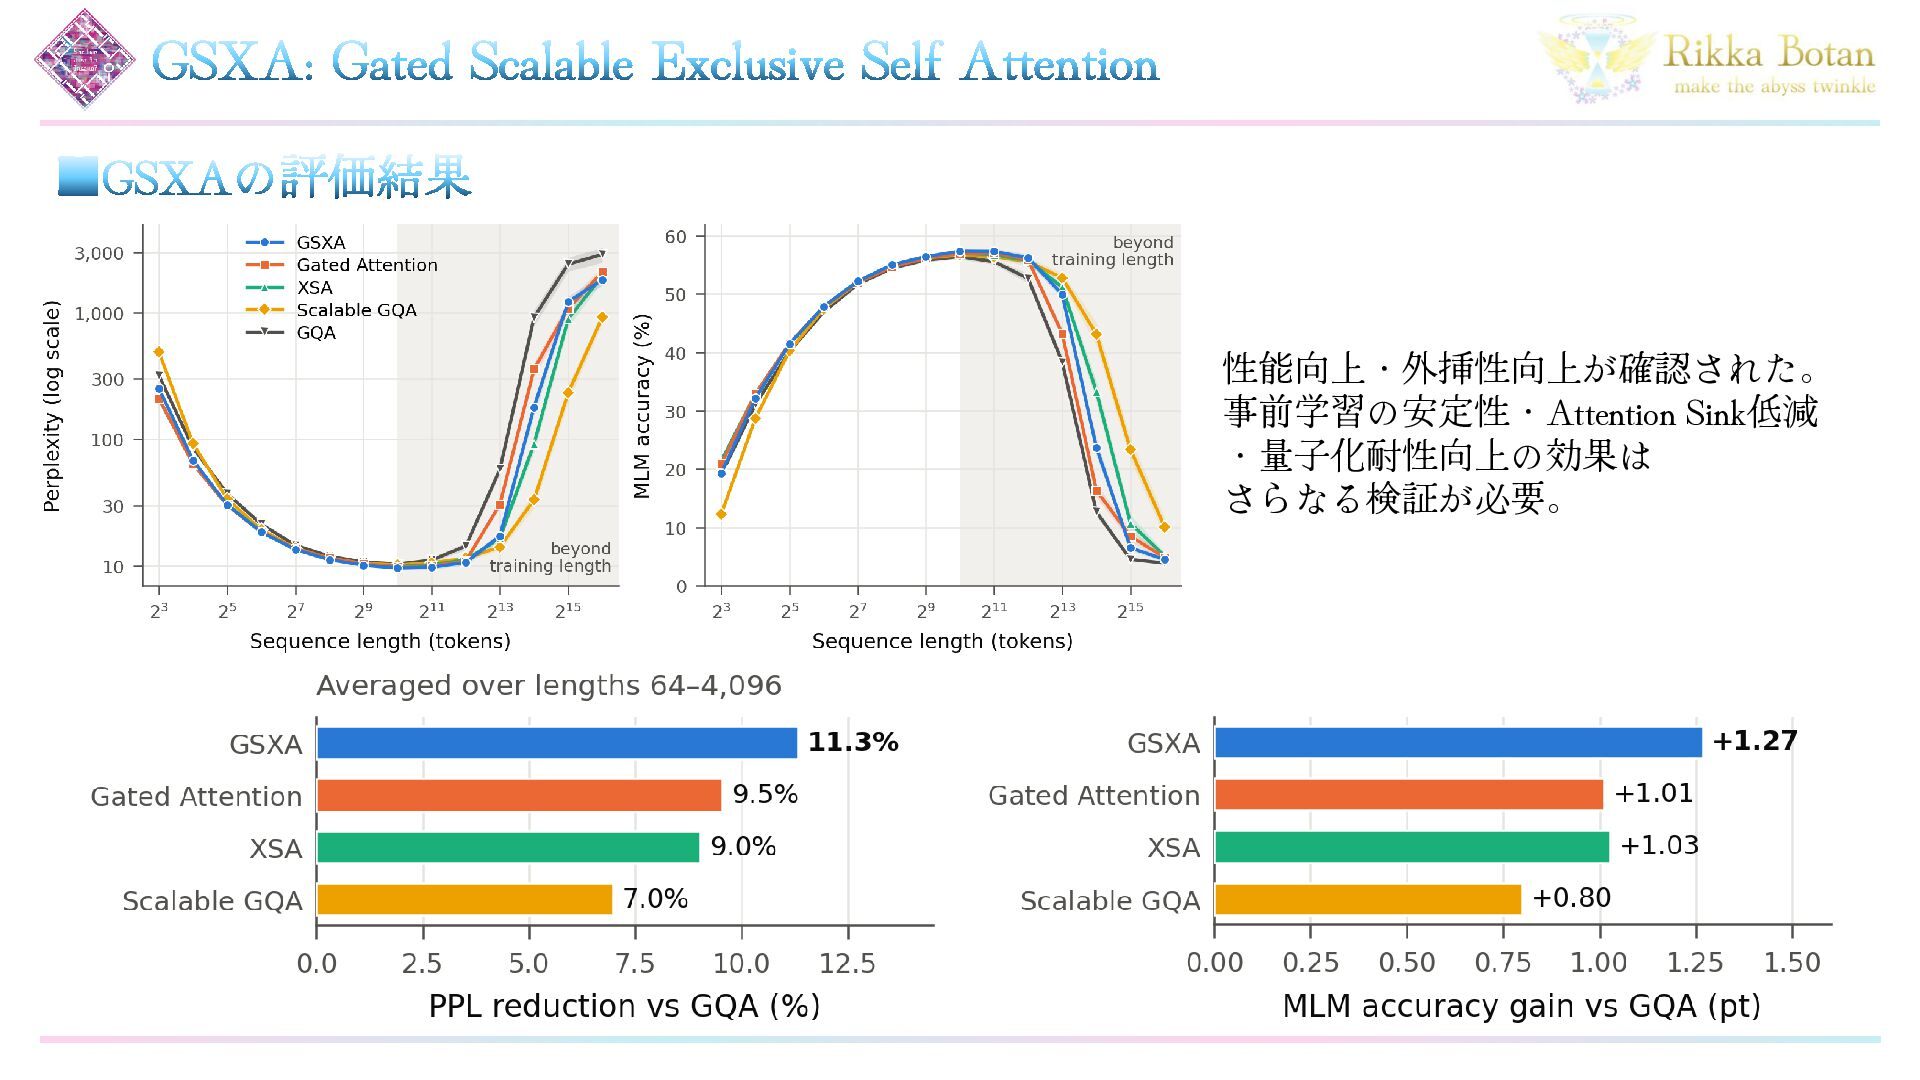
GSXA: Gated Scalable Exclusive Self Attention ▪GSXAの評価結果 性能向上・外挿性向上が確認された。 事前学習の安定性・Attention Sink低減
・量子化耐性向上の効果は さらなる検証が必要。
まとめ Self Attentionの改善手法はPPL低下だけが目的ではありません。 そのモデルにおいて、 何を改善したいのか、 そのタスクでどの性質が必要となるのか、 使用条件で何がボトルネックとなるのか を見極め、俯瞰的な視点で採用を決める必要があります。
11


 rikkabotan7
 institutdelelevage
 mikimhk
 kzmssk
 yumaichikawa
 shunk031
 satai
 sishi
 ftakahashi
 sishi2026
 anikisencyo
 chrislema
 tmiket
 inesmontani
 cromwellryan
 frankvandijk
 chriscoyier
 kneath
 rkendrick25
 hatefulcrawdad
 jonoalderson
 soudai
 mraible