Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
Beating State-of-the-art By -10000% @ CIDR Gong...
Search
Reynold Xin
January 07, 2013
Research
170
1
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
Beating State-of-the-art By -10000% @ CIDR Gong Show
I gave a 5-min Gong Show talk at CIDR on my experience with Spark, Shark, and GraphX.
Reynold Xin
January 07, 2013
More Decks by Reynold Xin
See All by Reynold Xin
(Berkeley CS186 guest lecture) Big Data Analytics Systems: What Goes Around Comes Around
rxin
12
2k
Interface Design for Spark Community
rxin
12
1.4k
Spark Committer Night meetup @ NYC
rxin
1
150
Apache Spark: Unified Platform for Big Data
rxin
1
260
Advanced Spark @ Spark Summit 2014
rxin
4
370
Apache Spark: Easier and Faster Big Data
rxin
2
330
GraphX at Spark User Meetup
rxin
0
190
Shark SIGMOD research deck
rxin
2
590
The Spark Ecosystem: Fast and Expressive Big Data Analytics in Scala @ Scala Days 2013
rxin
3
740
Other Decks in Research
See All in Research
20261101GISA-FOSS4G
tosseto
1
120
A new deal for disabled people
resolutionfoundation
0
360
The Conductor Pattern -Multi-Granularity Feedback for Creative Agents-
shibuiwilliam
2
120
Byzantine Eventual Consistency for Reliable Local-First Software
ept
0
370
進化?迷走?CasualConc ファミリーアプリの現在地 @ 英語コーパス学会 2026
casualconc
0
150
AI対話に何を挟むか ― 高回転対話・デジタル摘録・手書き記録による創造体験の違い|日本創造学会2026
ishiirikie
0
200
Work in progress: How have changes in the labour market over the past decade affected attitudes to work?
resolutionfoundation
0
230
XDPerf: A High-Performance Traffic Generator Built with WASM and eBPF
takehaya
1
370
[IEICE-Soceity-Conf2026] セマンティック通信を見据えたマルチスケールセンシングと 学習の融合によるデジタルツイン基盤 / Digital Twin Infrastructure via the Fusion of Multi-Scale Sensing and Learning toward Semantic Communications
pman0214
0
140
Kunai: Toward a Verifier-Safe Layered DSL for Nested Encapsulation Packet Filtering on eBPF
takehaya
1
190
Santé et fertilité des sols : ce que nous disent les pratiques dans les systèmes de polyculture-élevage
institutdelelevage
PRO
0
150
Easy to Guess, Hard to Verify: Lessons from AIMO 3 for Olympiad-Level AI Mathematics
corochann
0
150
Featured
See All Featured
Dominate Local Search Results - an insider guide to GBP, reviews, and Local SEO
greggifford
PRO
0
400
技術選定の審美眼(2025年版) / Understanding the Spiral of Technologies 2025 edition
twada
PRO
121
120k
Introduction to Domain-Driven Design and Collaborative software design
baasie
1
1.1k
Test your architecture with Archunit
thirion
2
2.5k
How to Align SEO within the Product Triangle To Get Buy-In & Support - #RIMC
aleyda
2
1.9k
Marketing to machines
jonoalderson
1
6k
Color Theory Basics | Prateek | Gurzu
gurzu
1
510
[Rails World 2026] Durable orchestration on Rails: from continuation to workflow
palkan
3
1.2k
What does AI have to do with Human Rights?
axbom
PRO
1
2.5k
CoffeeScript is Beautiful & I Never Want to Write Plain JavaScript Again
sstephenson
162
16k
Writing Fast Ruby
sferik
630
63k
Being A Developer After 40
akosma
PRO
92
590k
Transcript
Beating State-of-the-art By -10000% Reynold Xin, AMPLab, UC Berkeley with
help from Joseph Gonzalez, Josh Rosen, Matei Zaharia, Michael Franklin, Scott Shenker, Ion Stoica
Beating State-of-the-art By -10000% NOT A TYPO Reynold Xin, AMPLab,
UC Berkeley with help from Joseph Gonzalez, Josh Rosen, Matei Zaharia, Michael Franklin, Scott Shenker, Ion Stoica
MapReduce deterministic, idempotent tasks fault-tolerance elasticity resource sharing
“The bar for open source software is at historical low.”
“The bar for open source software is at historical low.”
i.e. “This is the right time to do grad school.”
iterative machine learning OLAP strong temporal locality
Does in-memory computation help in petabyte-scale warehouses?
Does in-memory computation help in petabyte-scale warehouses? YES
Spark How to do in-memory computation efficiently in a fault-tolerant
way?
Shark How to do SQL query processing efficiently in “MapReduce”
style SQL on top of Spark Hive compatible (UDF, Type, InputFormat, Metadata)
“You need to beat Hadoop by at least 100X to
publish a paper in 2013.”
“You need to beat Hadoop by at least 100X to
publish a paper in 2013.” i.e. “You should’ve come to grad school 2 years earlier.”
Shark in-memory columnar store dynamic query re-optimization and a lot
of engineering...
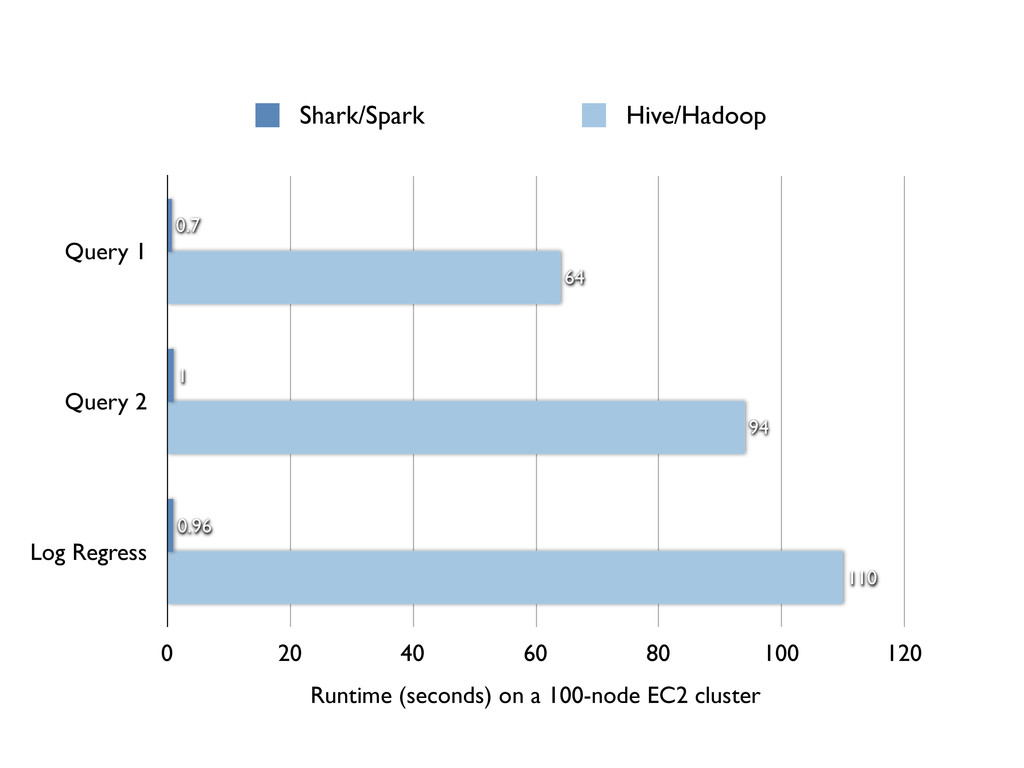
Query 1 Query 2 Log Regress 0 20 40 60
80 100 120 110 94 64 0.96 1 0.7 Runtime (seconds) on a 100-node EC2 cluster Shark/Spark Hive/Hadoop
iterative machine learning SQL query processing
iterative machine learning SQL query processing graph computation
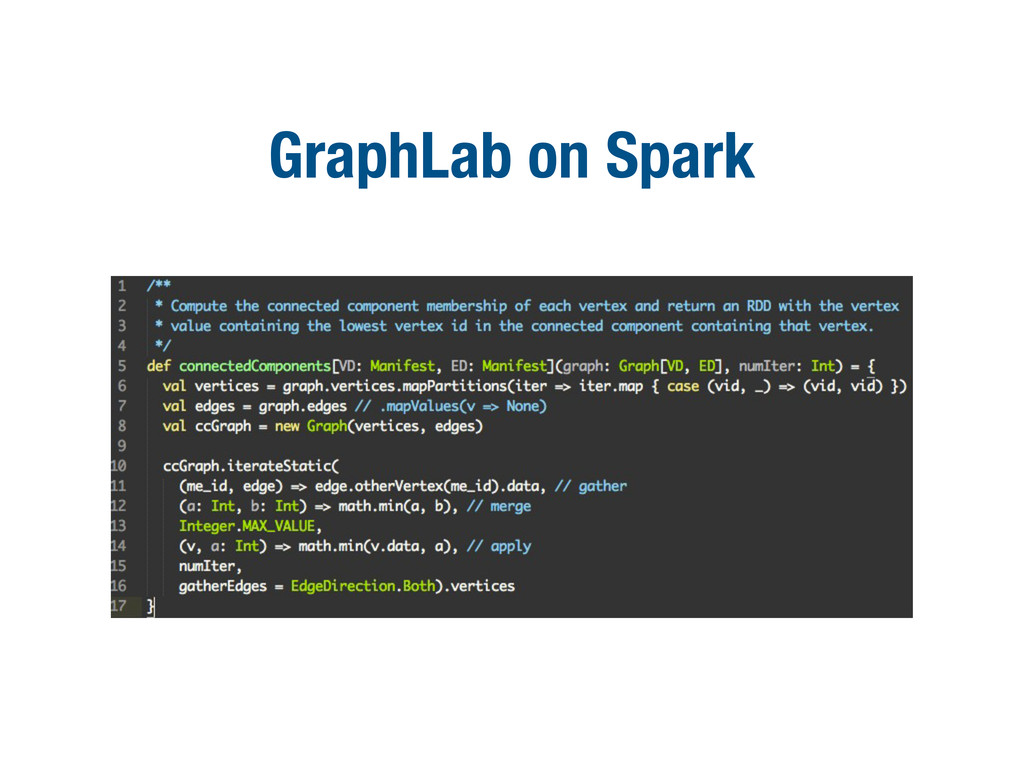
GraphLab on Spark
I spent a day pair-programming with Joey Gonzalez and improved
performance by 10X. Not bad for a day of work!
I spent a day pair-programming with Joey Gonzalez and improved
performance by 10X. but I later found out that it is still 10X slower than the latest version of GraphLab :(
A lot of open questions for fault- tolerant, distributed graph
computation. “MapReduce”? Data partitioning? Fault-tolerance? Asynchrony?
iterative machine learning www.spark-project.org SQL query processing shark.cs.berkeley.edu graph computation
www.wait-another-year.com


 rxin
 tosseto
 resolutionfoundation
 shibuiwilliam
 ept
 casualconc
 ishiirikie
 takehaya
 pman0214
 institutdelelevage
 corochann
 greggifford
 twada
 baasie
 thirion
 aleyda
 jonoalderson
 gurzu
 palkan
 axbom
 sstephenson
 sferik
 akosma