Share
Research and development of advanced information processing technologies and intelligent systems for supporting geosciences innovations
Since October 2016, Rosa Filgueira has been working at the British Geological Survey (BGS) as a Senior Data Scientist. She is involved in a variety of national and international research projects where she applies different technologies from Data Science and High Performance Computing to extract data-driven insights from different domain areas. During her visit at ISI, she has mainly worked in two complementary subjects. The first consists in building a new data-streaming infrastructure to collect and perform data analytics in real-time. The proposed infrastructure can be used for analysing real-time workflows performance and/or for monitoring real-time sensor/instrument data (e.g. geo-energy data). The second topic consists to create a new semantic catalog for describing geosciences resources.
SciTech
Transcript
39 slides
-
Development of advanced information processing technologies and intelligent systems
for supporting geosciences innovation Rosa Filgueira Vicente 12,06,2017 British Geological Survey -
2 Background: • PhD Computer Science - HPC research
– Madrid/Carlos III • 5 years as a Postdoc – University of Edinburgh Currently: • Data sciences activities across Geoscience domains: - Data gathering, cleaning, filtering, analysis - Parallelization/optimization of applications - Promoting scientific workflows, data-frameworks, containers and reproducibility tools, etc. - Distributed systems and open source tools - Research activities Senior Data Scientist British Geological Survey (BGS) -
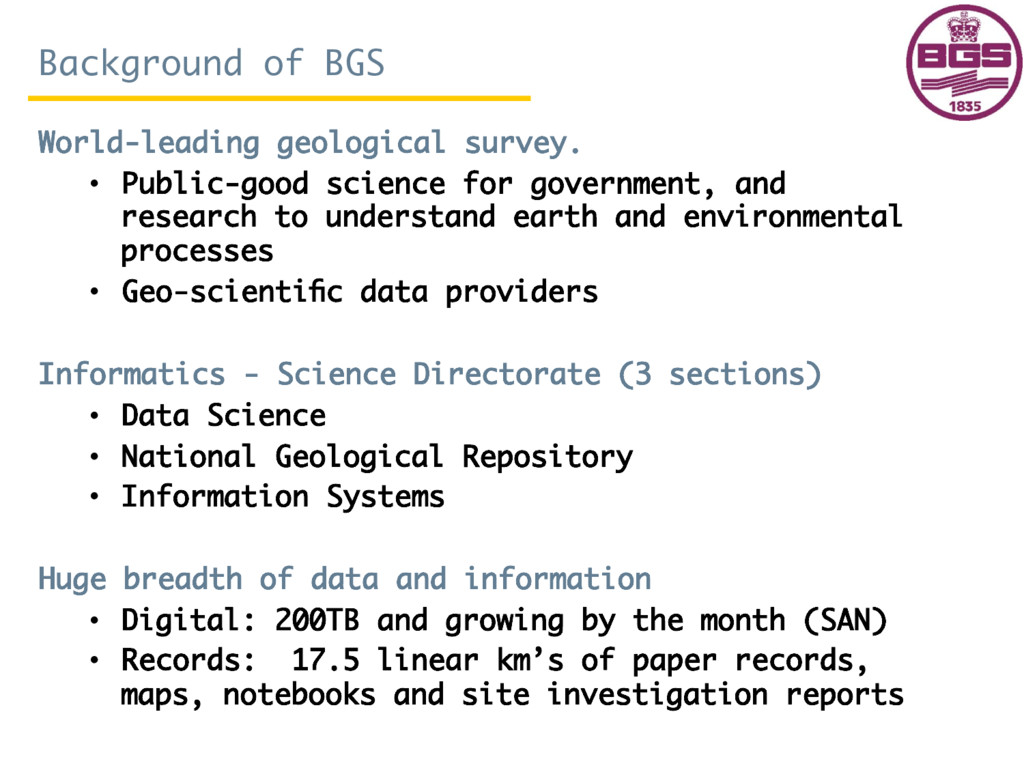
World-leading geological survey. • Public-good science for government, and research
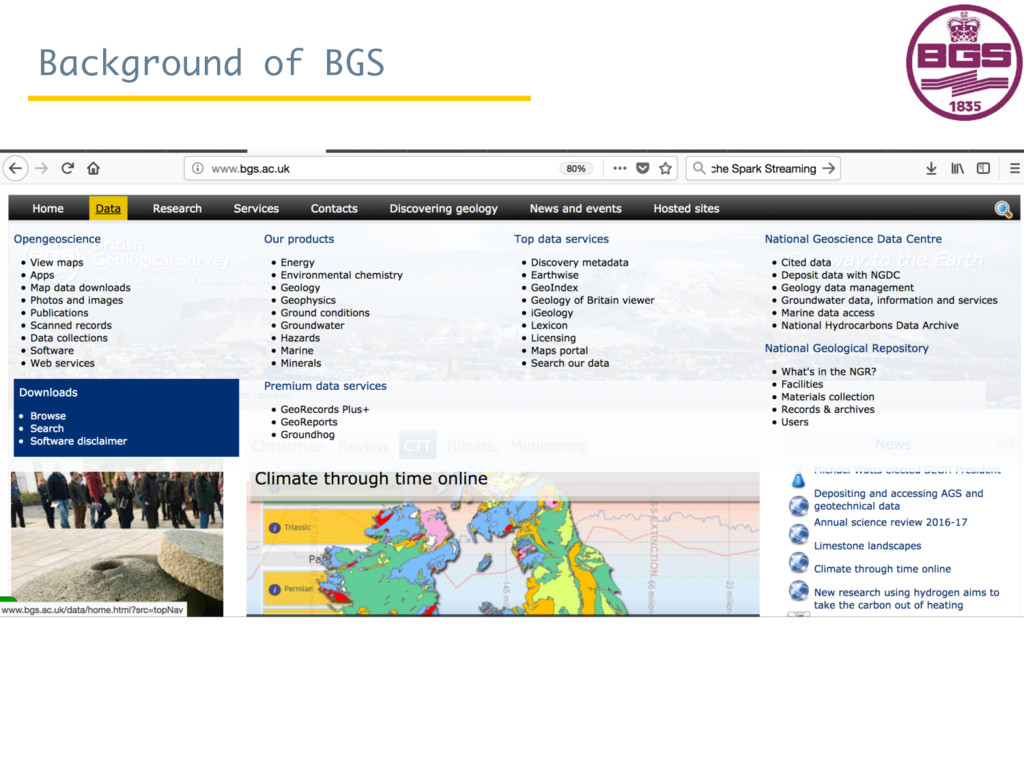
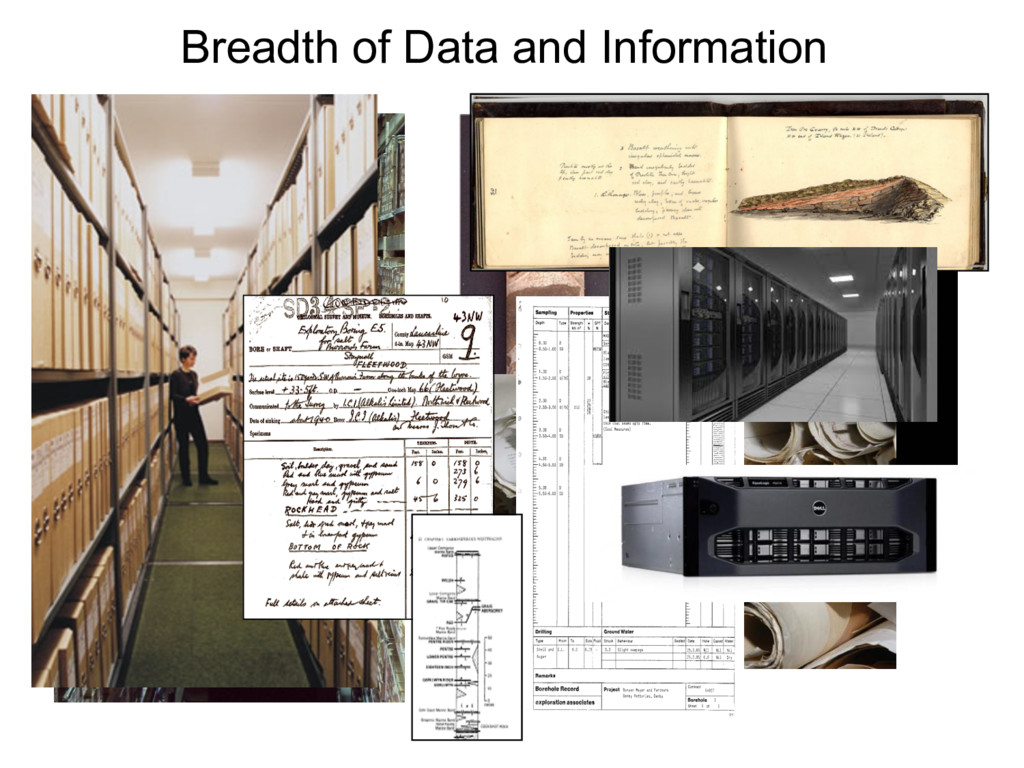
to understand earth and environmental processes • Geo-scientific data providers Informatics - Science Directorate (3 sections) • Data Science • National Geological Repository • Information Systems Huge breadth of data and information • Digital: 200TB and growing by the month (SAN) • Records: 17.5 linear km’s of paper records, maps, notebooks and site investigation reports Background of BGS -
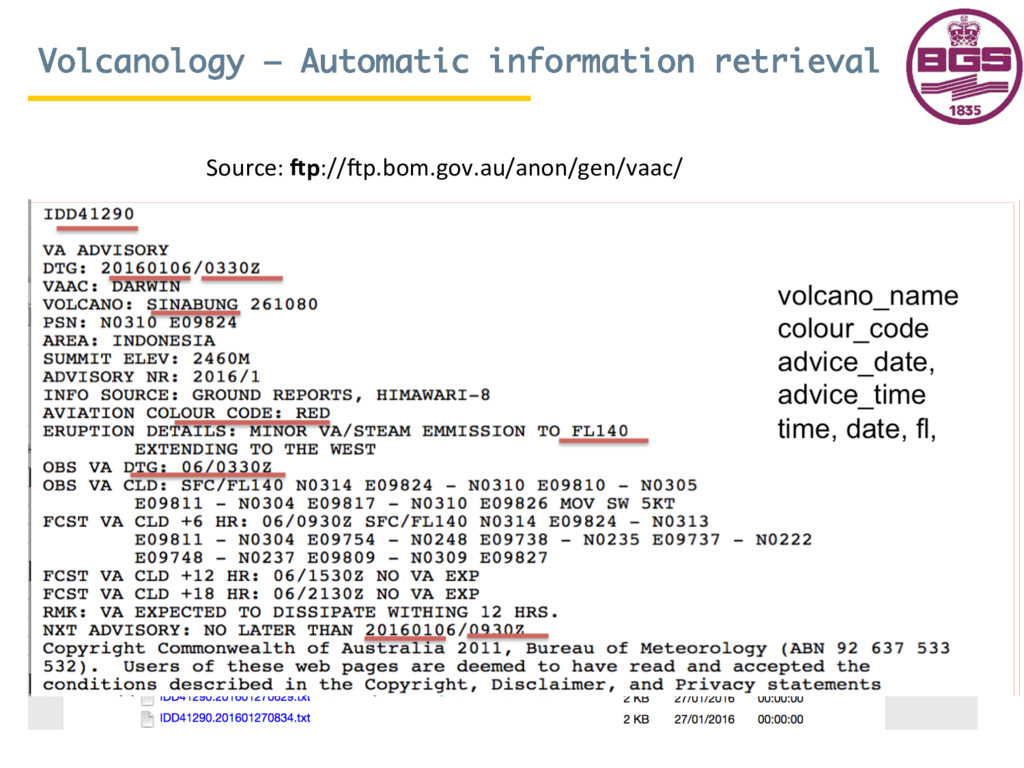
Volcanology – Automatic information retrieval Sensor data – Real-time analysis/monitoring
Hydrology models – Code parallelization BGS projects - Examples -
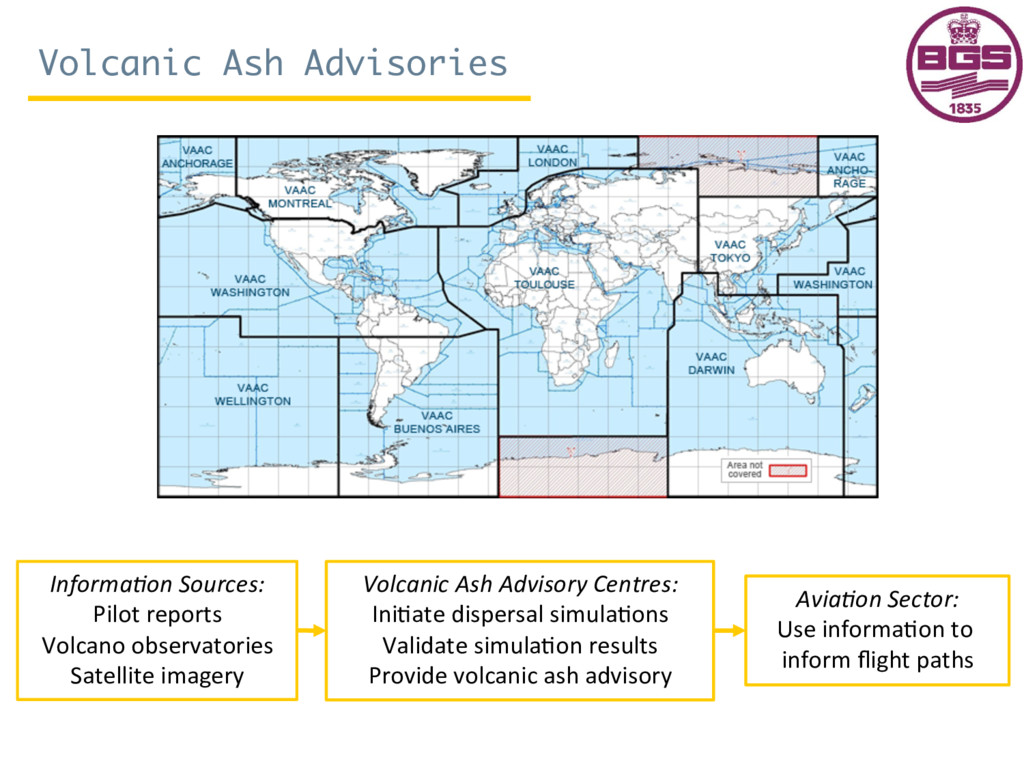
Informa(on Sources: Pilot reports Volcano observatories Satellite
imagery Volcanic Ash Advisory Centres: Ini7ate dispersal simula7ons Validate simula7on results Provide volcanic ash advisory Avia(on Sector: Use informa7on to inform flight paths Volcanic Ash Advisories -
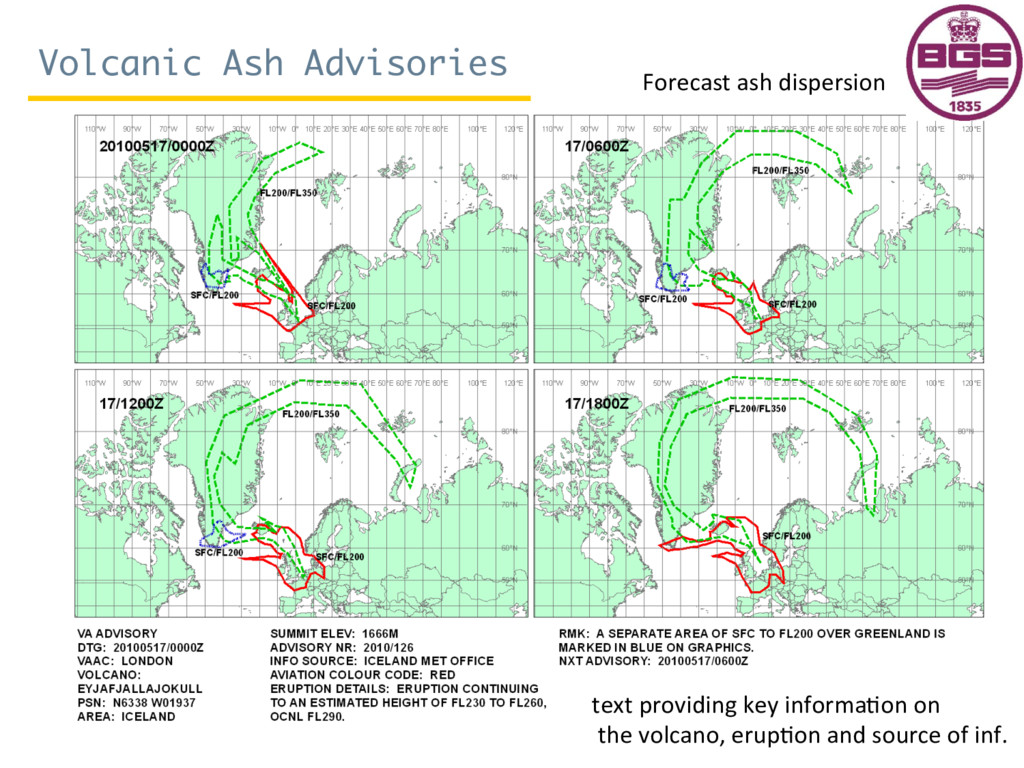
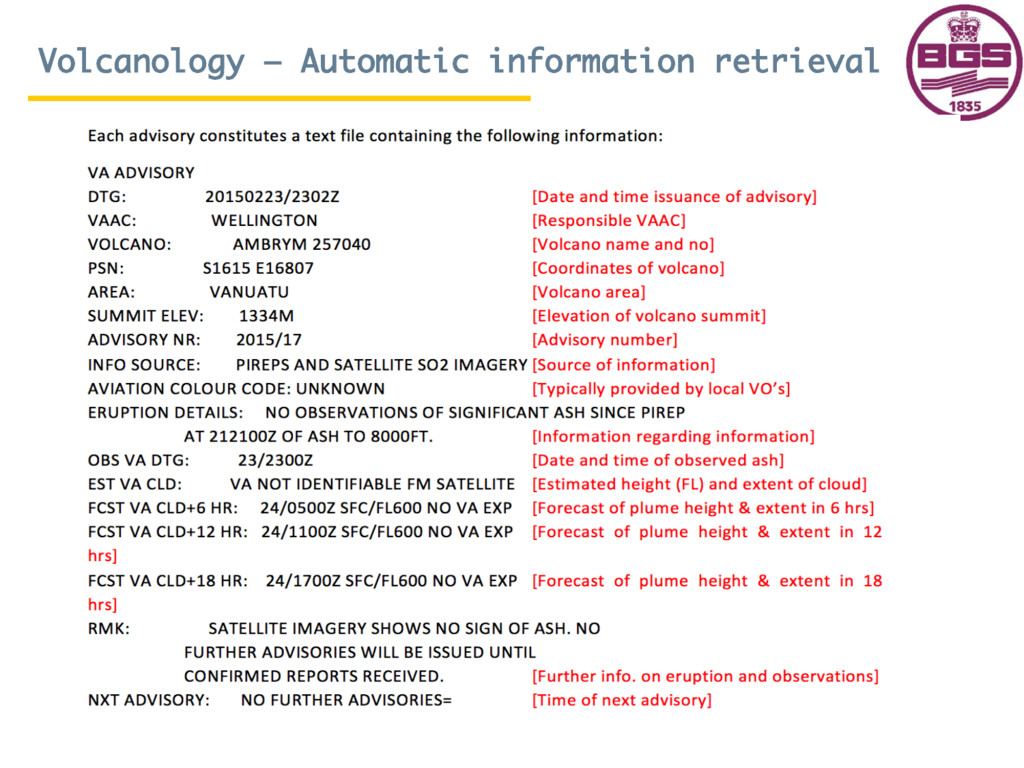
Volcanic Ash Advisories Forecast ash dispersion text providing key
informa7on on the volcano, erup7on and source of inf. -
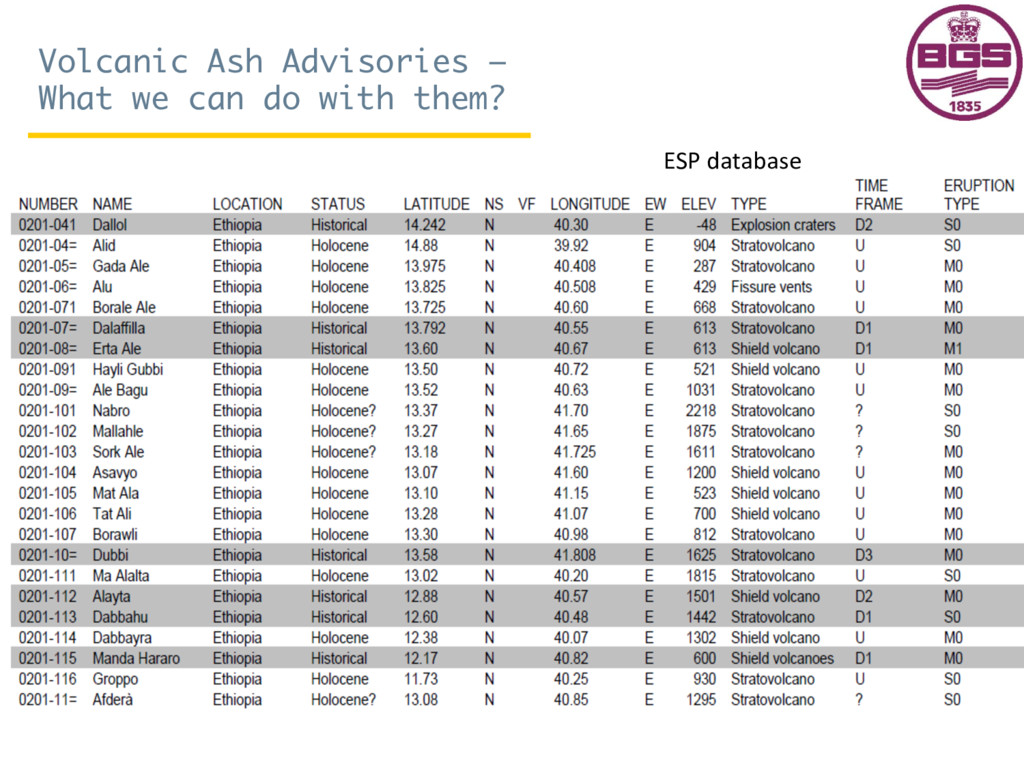
Forecasting ash dispersal based on numerical models The accuracy of
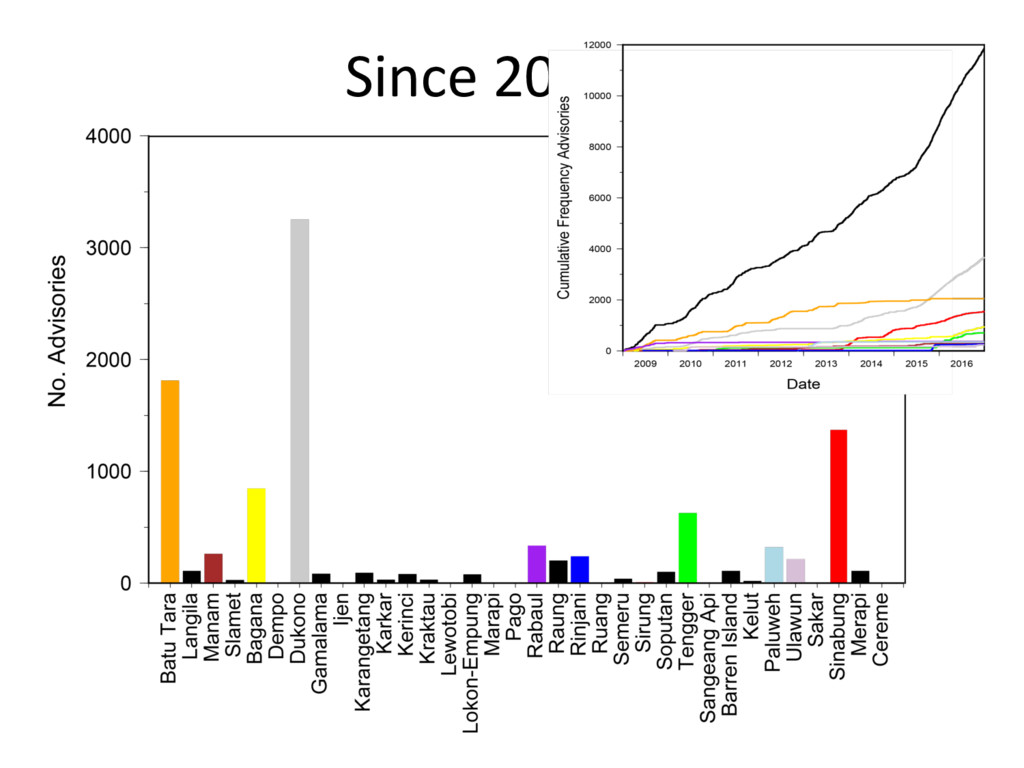
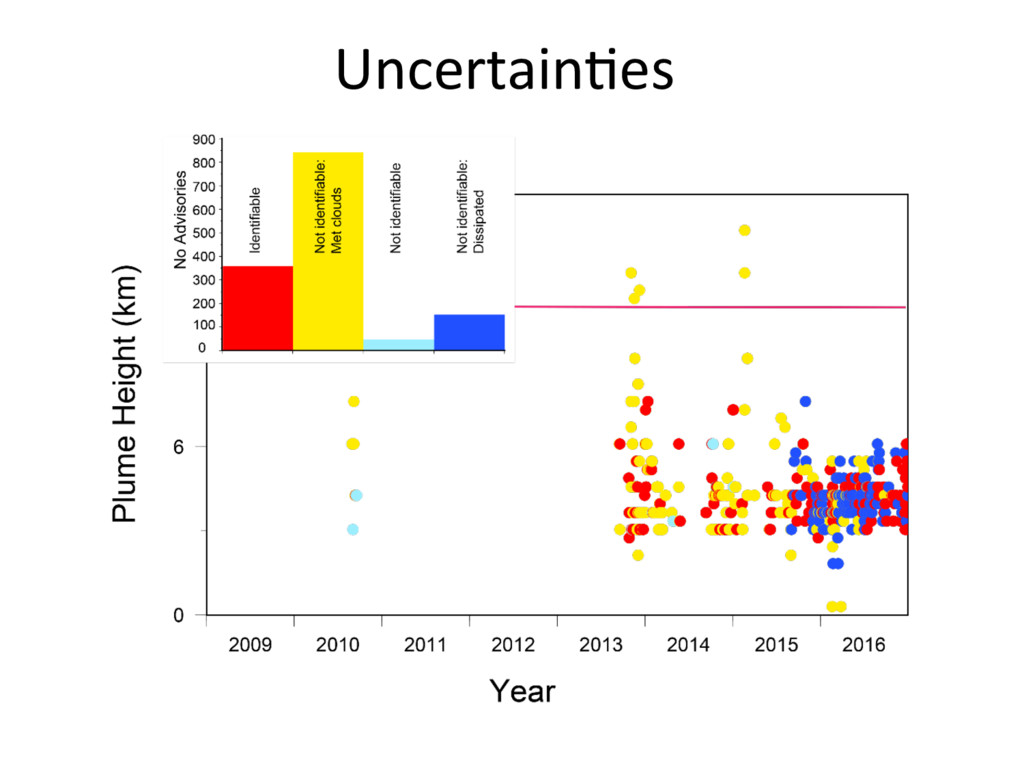
model outputs is dependent on the accuracy of the input parameters (e.g. eruption source parameter). Idea VAAs reports constitute one of the most frequent sources of information describing eruptive activity à Use it to test assumptions regarding eruptive activity, for example in the ESP database. Volcanic Ash Advisories – What we can do with them? Those reports have never been used for research before!! ESP database -
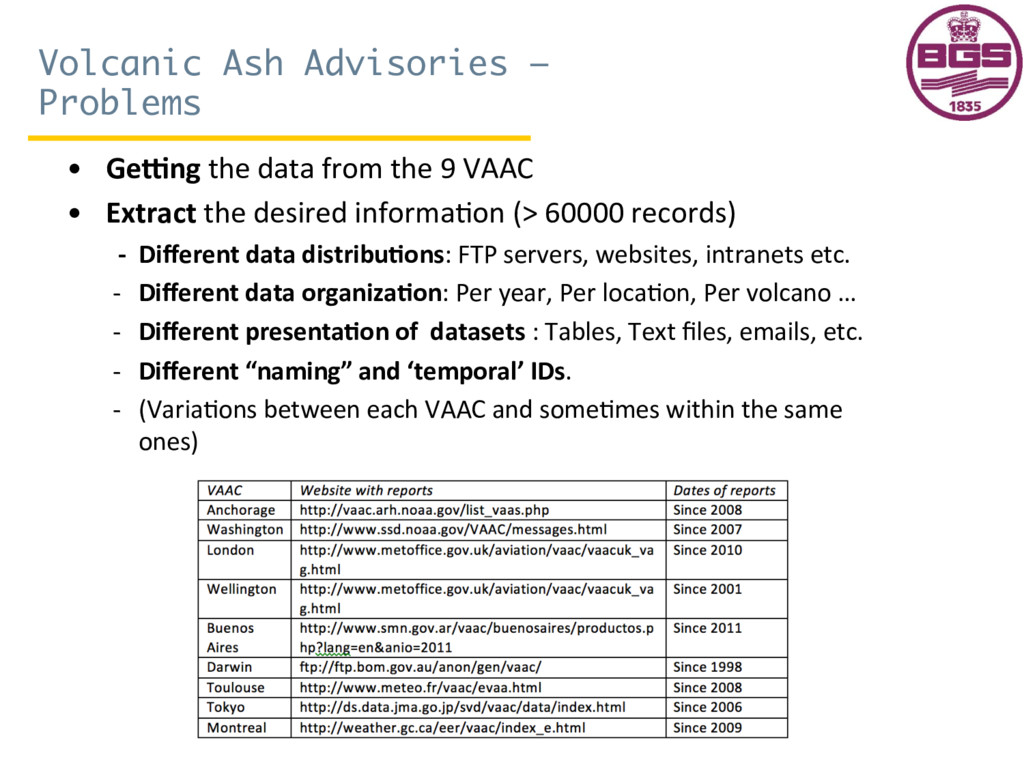
• Ge#ng the data from the 9 VAAC
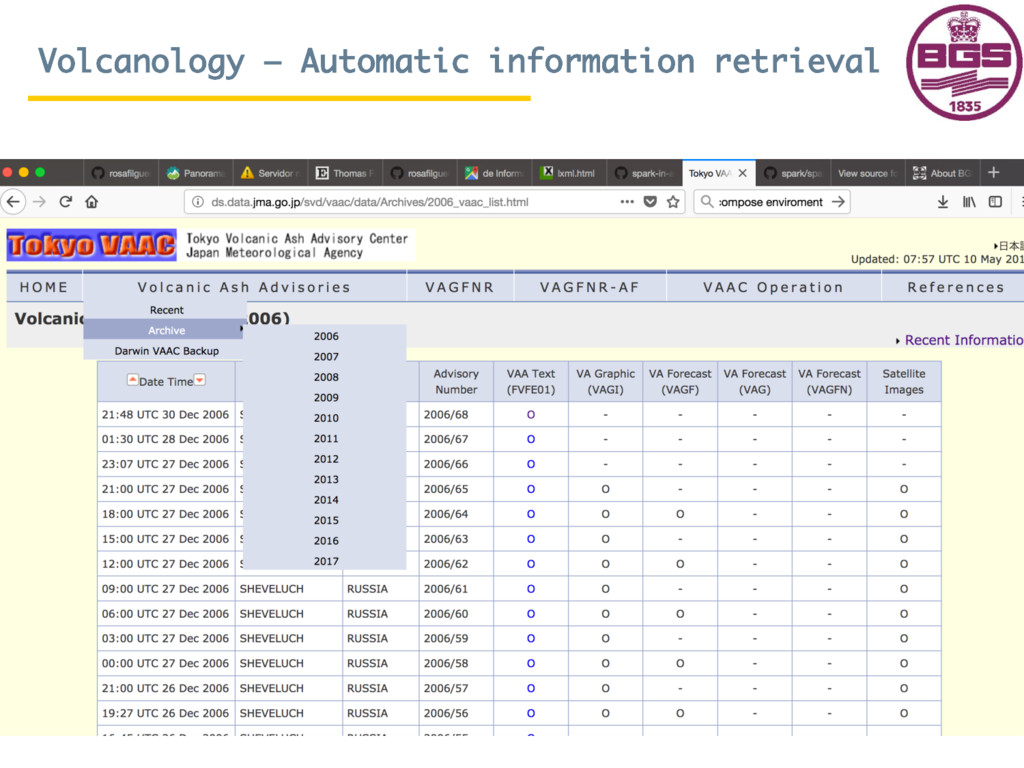
• Extract the desired informa7on (> 60000 records) -‐ Different data distribu5ons: FTP servers, websites, intranets etc. -‐ Different data organiza5on: Per year, Per loca7on, Per volcano … -‐ Different presenta5on of datasets : Tables, Text files, emails, etc. -‐ Different “naming” and ‘temporal’ IDs. -‐ (Varia7ons between each VAAC and some7mes within the same ones) Volcanic Ash Advisories – Problems -
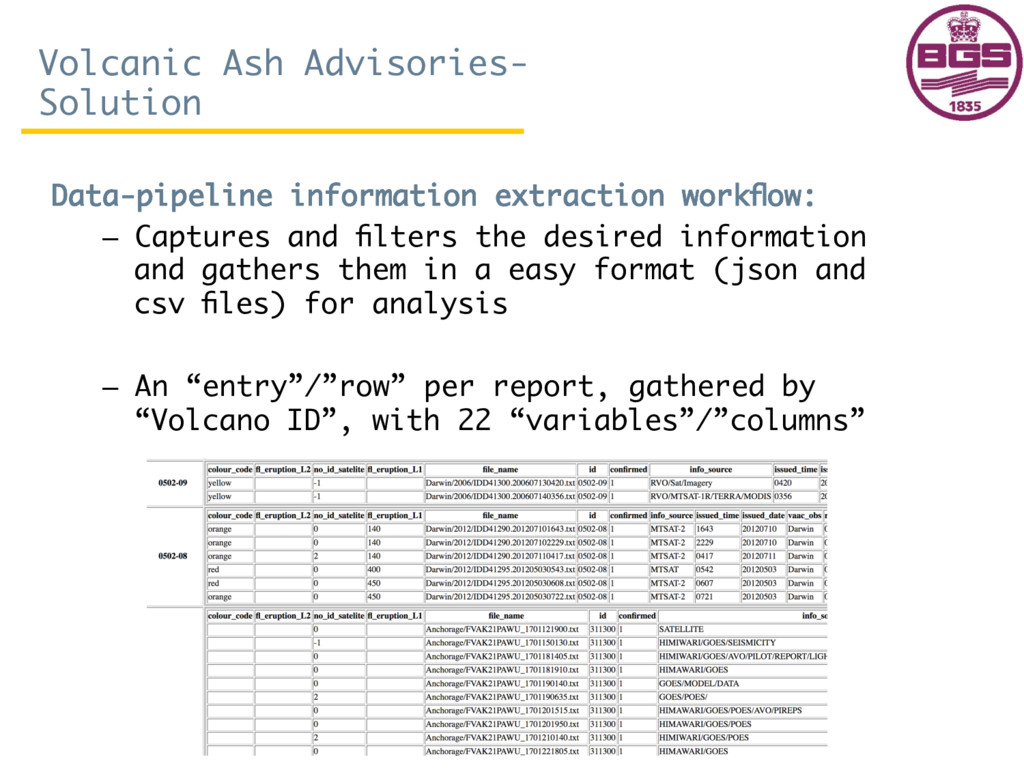
Data-pipeline information extraction workflow: – Captures and filters the desired
information and gathers them in a easy format (json and csv files) for analysis – An “entry”/”row” per report, gathered by “Volcano ID”, with 22 “variables”/”columns” Volcanic Ash Advisories- Solution -
Sensor data – UK Geoenergy Observatories (UKGO) Objective: • Establish
new centres for world-leading research into the subsurface environment • Initially 2 places will start streaming data in 2018 with many different type of sensors (seismic sensors, groundwater sensors, etc …) but more places during the future … • The BGS is delivering the research infrastructure and will operate the facilities over their 15-year lifetime Initial idea: • Data architecture from “BGS sensor data” • http://www.bgs.ac.uk/Sensors/ -
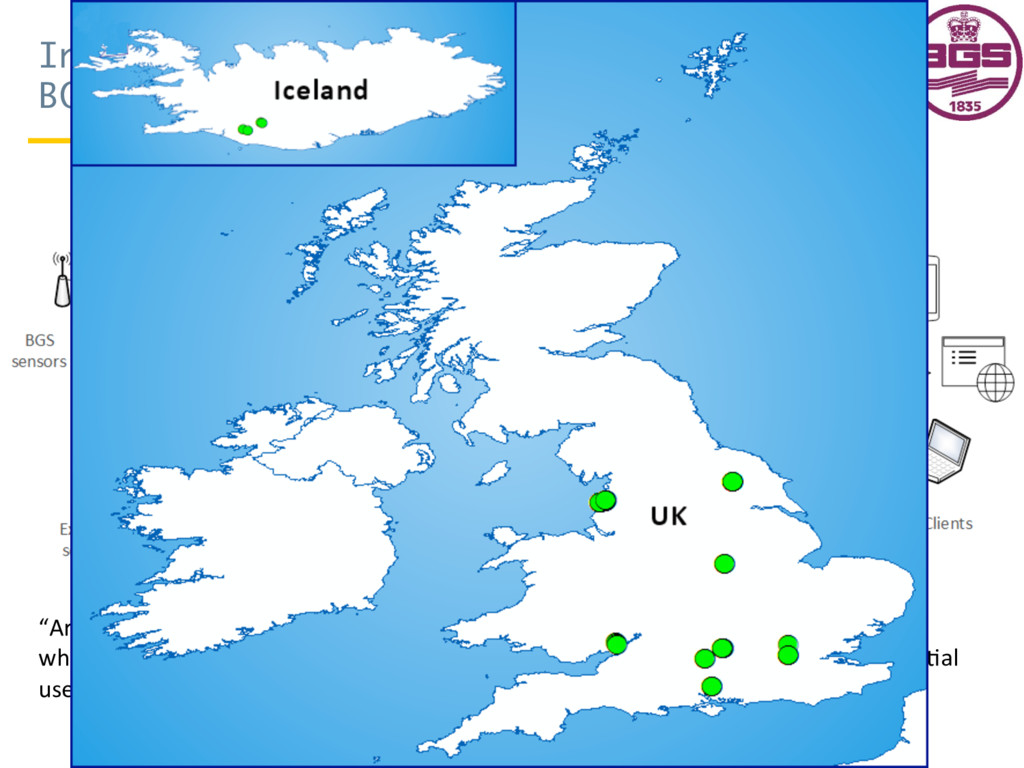
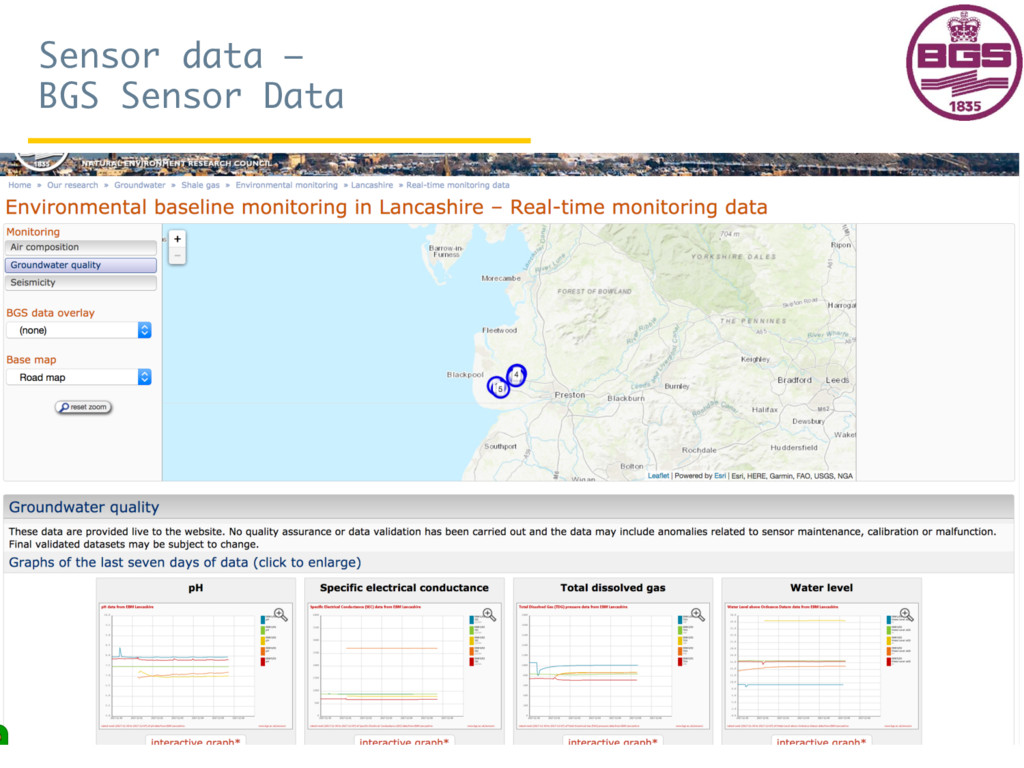
Instrument data – BGS Sensor Data “Architecture for streaming sensor
telemetry data into a central data store where it can be standardised, cleaned up and generally prepared for the many poten7al users that want to access that data”. -
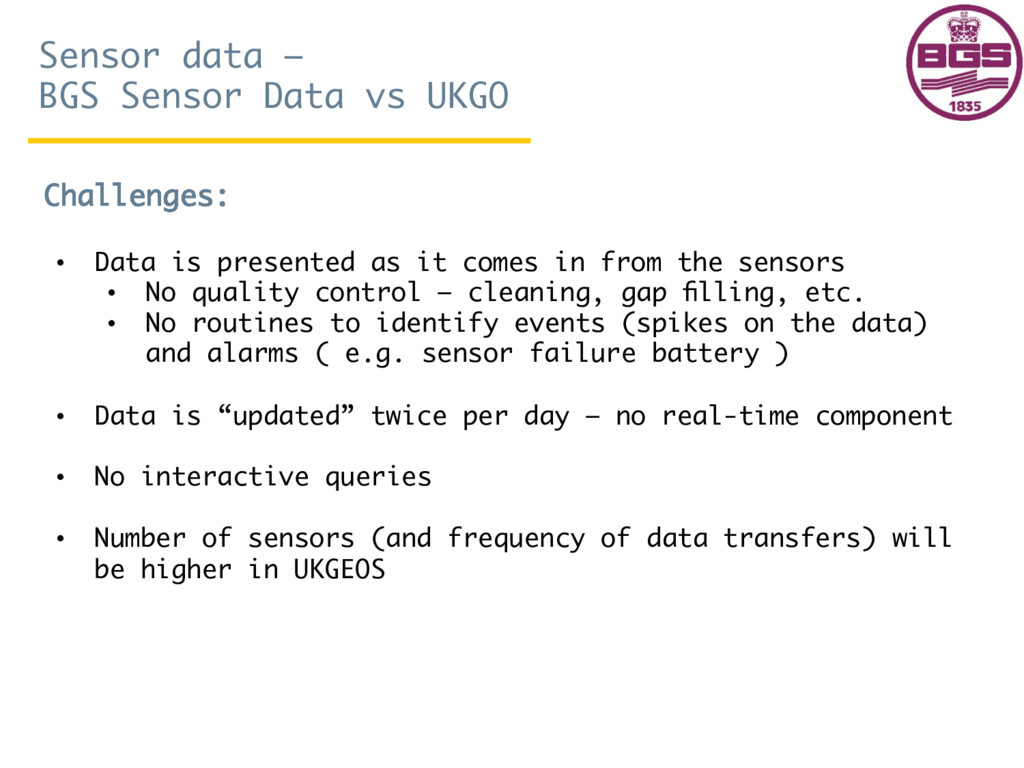
Sensor data – BGS Sensor Data vs UKGO Challenges: •
Data is presented as it comes in from the sensors • No quality control – cleaning, gap filling, etc. • No routines to identify events (spikes on the data) and alarms ( e.g. sensor failure battery ) • Data is “updated” twice per day – no real-time component • No interactive queries • Number of sensors (and frequency of data transfers) will be higher in UKGEOS -
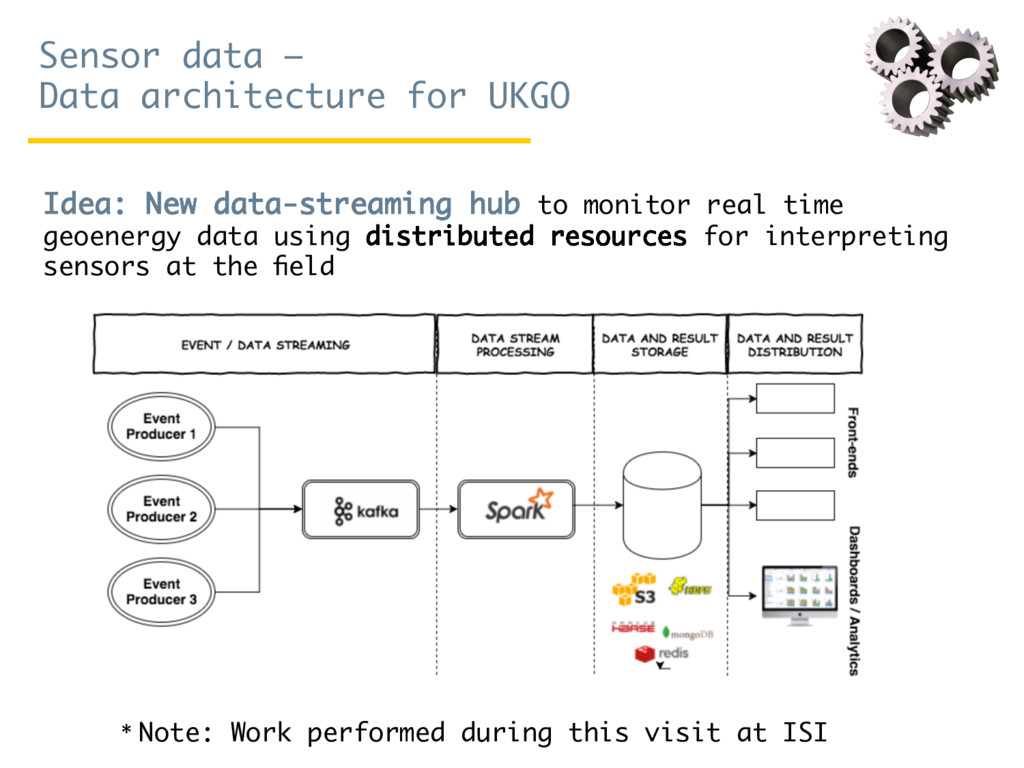
Sensor data – Data architecture for UKGO Idea: New data-streaming
hub to monitor real time geoenergy data using distributed resources for interpreting sensors at the field * Note: Work performed during this visit at ISI -
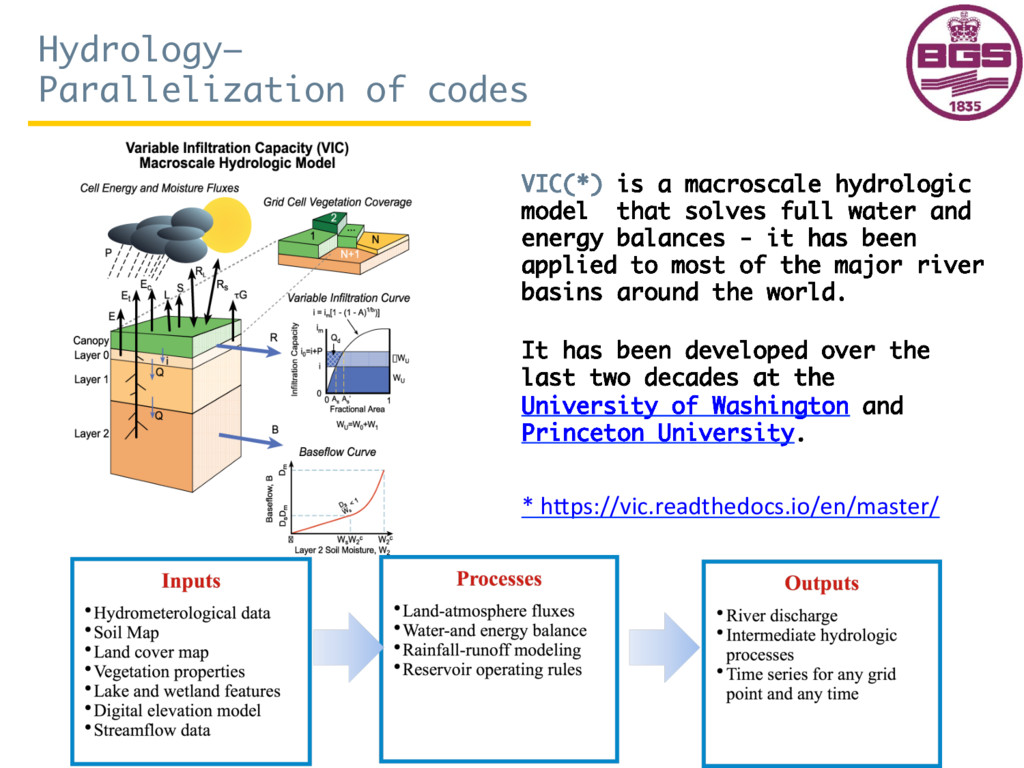
Hydrology– Parallelization of codes VIC(*) is a macroscale hydrologic model
that solves full water and energy balances - it has been applied to most of the major river basins around the world. It has been developed over the last two decades at the University of Washington and Princeton University. * hXps://vic.readthedocs.io/en/master/ -
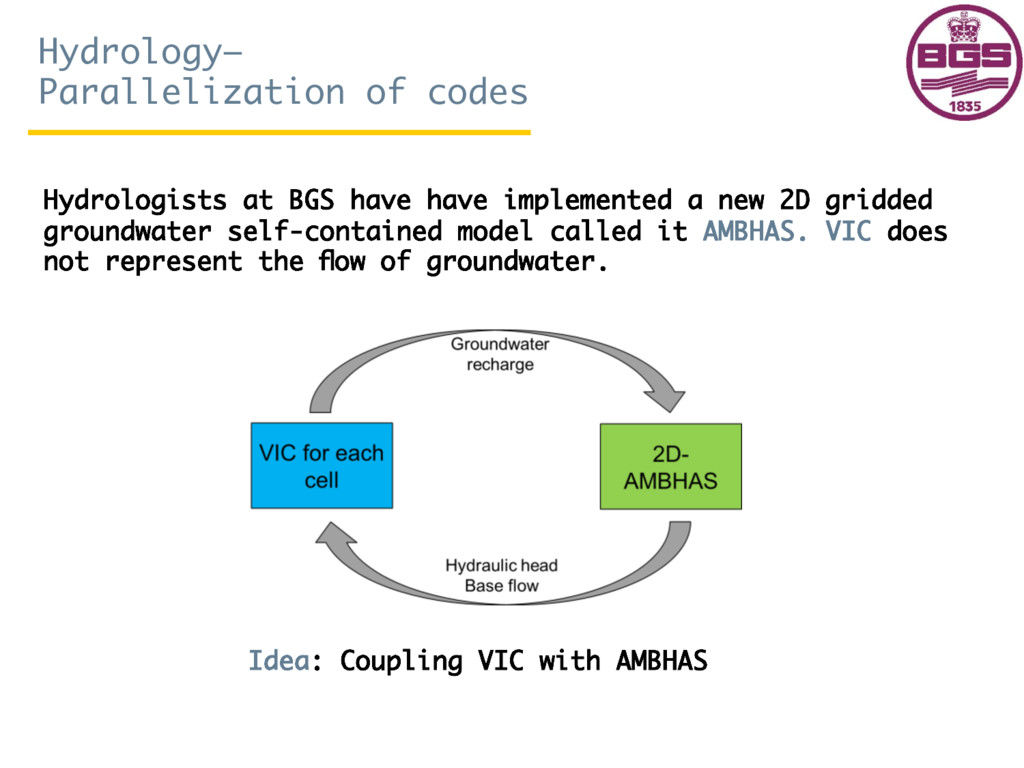
Hydrology– Parallelization of codes Hydrologists at BGS have have implemented
a new 2D gridded groundwater self-contained model called it AMBHAS. VIC does not represent the flow of groundwater. Idea: Coupling VIC with AMBHAS -
Hydrology– Parallelization of codes Problem: VIC is implemented in MPI
(parallel code) and AMBHAS in sequential. Role: Modify the parallel code of VIC to integrate AMBHAS. And run the new version of VIC-AMBHAS (parallel code) into the BGS cluster. * Modifications on data structures/routines/headers of both modules. Relevant to PANORAMA and MINT projects -
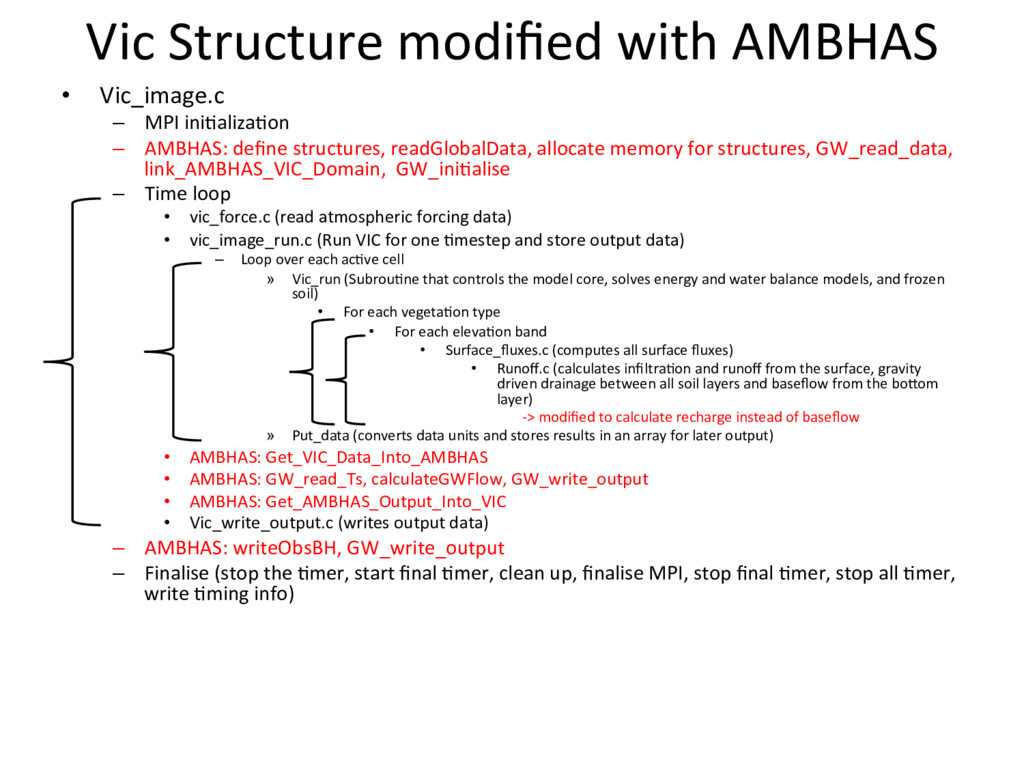
Vic Structure modified with AMBHAS • Vic_image.c –
MPI ini7aliza7on – AMBHAS: define structures, readGlobalData, allocate memory for structures, GW_read_data, link_AMBHAS_VIC_Domain, GW_ini7alise – Time loop • vic_force.c (read atmospheric forcing data) • vic_image_run.c (Run VIC for one 7mestep and store output data) – Loop over each ac7ve cell » Vic_run (Subrou7ne that controls the model core, solves energy and water balance models, and frozen soil) • For each vegeta7on type • For each eleva7on band • Surface_fluxes.c (computes all surface fluxes) • Runoff.c (calculates infiltra7on and runoff from the surface, gravity driven drainage between all soil layers and baseflow from the boXom layer) -‐> modified to calculate recharge instead of baseflow » Put_data (converts data units and stores results in an array for later output) • AMBHAS: Get_VIC_Data_Into_AMBHAS • AMBHAS: GW_read_Ts, calculateGWFlow, GW_write_output • AMBHAS: Get_AMBHAS_Output_Into_VIC • Vic_write_output.c (writes output data) – AMBHAS: writeObsBH, GW_write_output – Finalise (stop the 7mer, start final 7mer, clean up, finalise MPI, stop final 7mer, stop all 7mer, write 7ming info) -
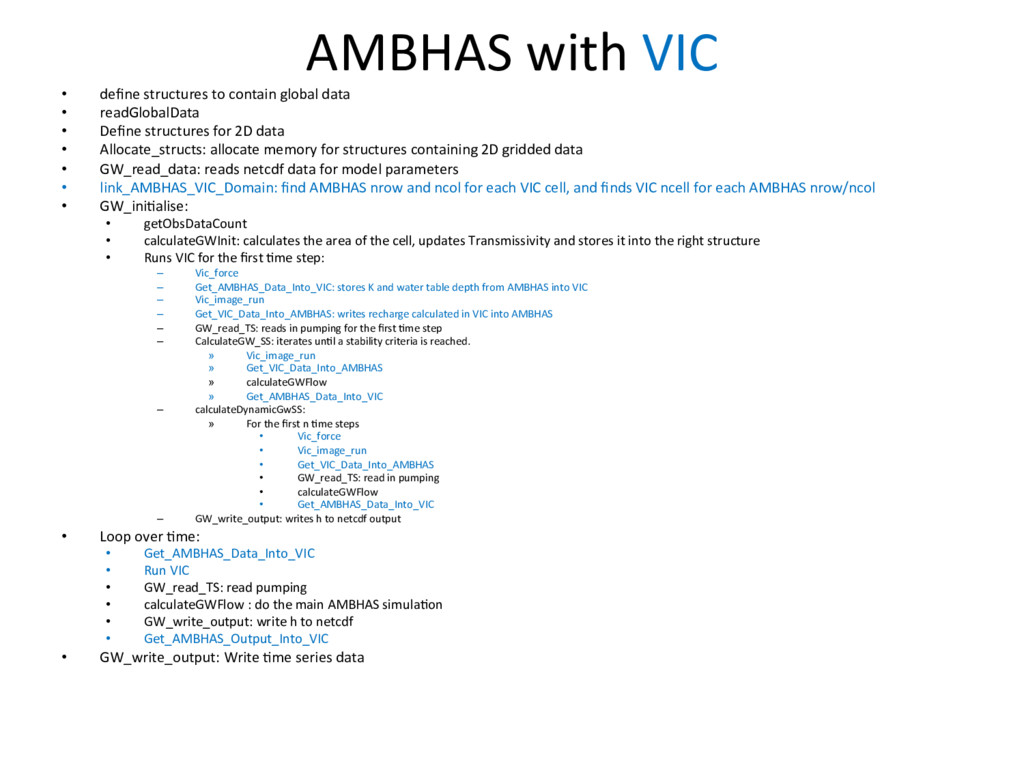
AMBHAS with VIC • define structures to contain global
data • readGlobalData • Define structures for 2D data • Allocate_structs: allocate memory for structures containing 2D gridded data • GW_read_data: reads netcdf data for model parameters • link_AMBHAS_VIC_Domain: find AMBHAS nrow and ncol for each VIC cell, and finds VIC ncell for each AMBHAS nrow/ncol • GW_ini7alise: • getObsDataCount • calculateGWInit: calculates the area of the cell, updates Transmissivity and stores it into the right structure • Runs VIC for the first 7me step: – Vic_force – Get_AMBHAS_Data_Into_VIC: stores K and water table depth from AMBHAS into VIC – Vic_image_run – Get_VIC_Data_Into_AMBHAS: writes recharge calculated in VIC into AMBHAS – GW_read_TS: reads in pumping for the first 7me step – CalculateGW_SS: iterates un7l a stability criteria is reached. » Vic_image_run » Get_VIC_Data_Into_AMBHAS » calculateGWFlow » Get_AMBHAS_Data_Into_VIC – calculateDynamicGwSS: » For the first n 7me steps • Vic_force • Vic_image_run • Get_VIC_Data_Into_AMBHAS • GW_read_TS: read in pumping • calculateGWFlow • Get_AMBHAS_Data_Into_VIC – GW_write_output: writes h to netcdf output • Loop over 7me: • Get_AMBHAS_Data_Into_VIC • Run VIC • GW_read_TS: read pumping • calculateGWFlow : do the main AMBHAS simula7on • GW_write_output: write h to netcdf • Get_AMBHAS_Output_Into_VIC • GW_write_output: Write 7me series data -
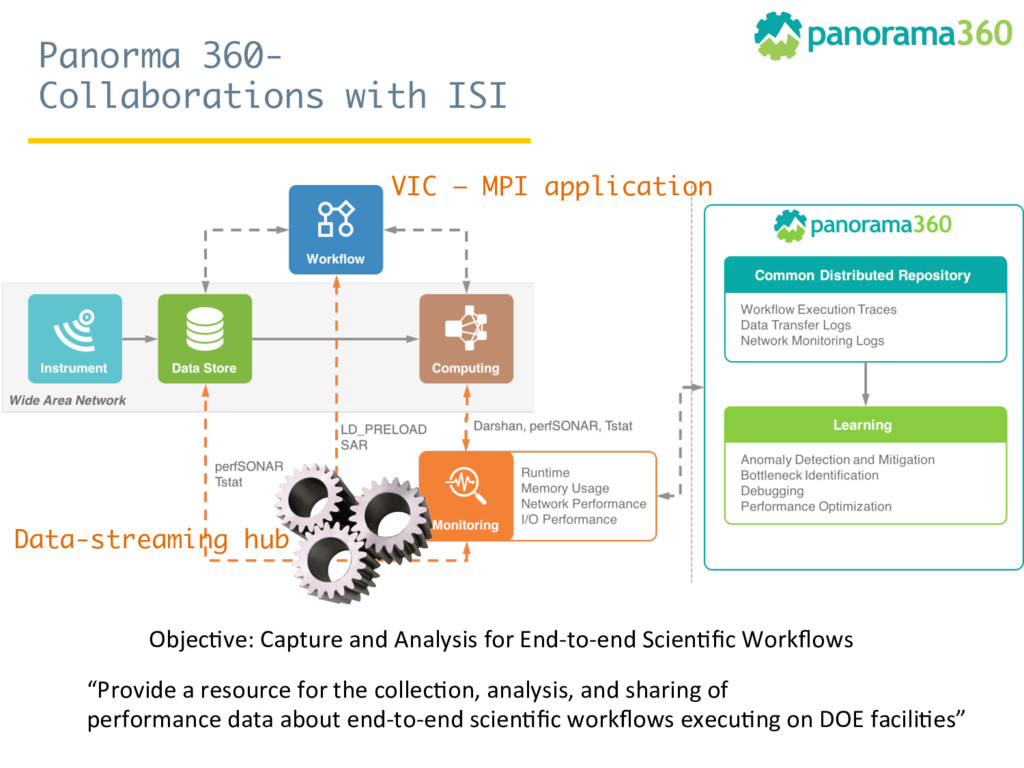
Panorma 360- Collaborations with ISI “Provide a resource for the
collec7on, analysis, and sharing of performance data about end-‐to-‐end scien7fic workflows execu7ng on DOE facili7es” Objec7ve: Capture and Analysis for End-‐to-‐end Scien7fic Workflows Data-streaming hub VIC – MPI application -
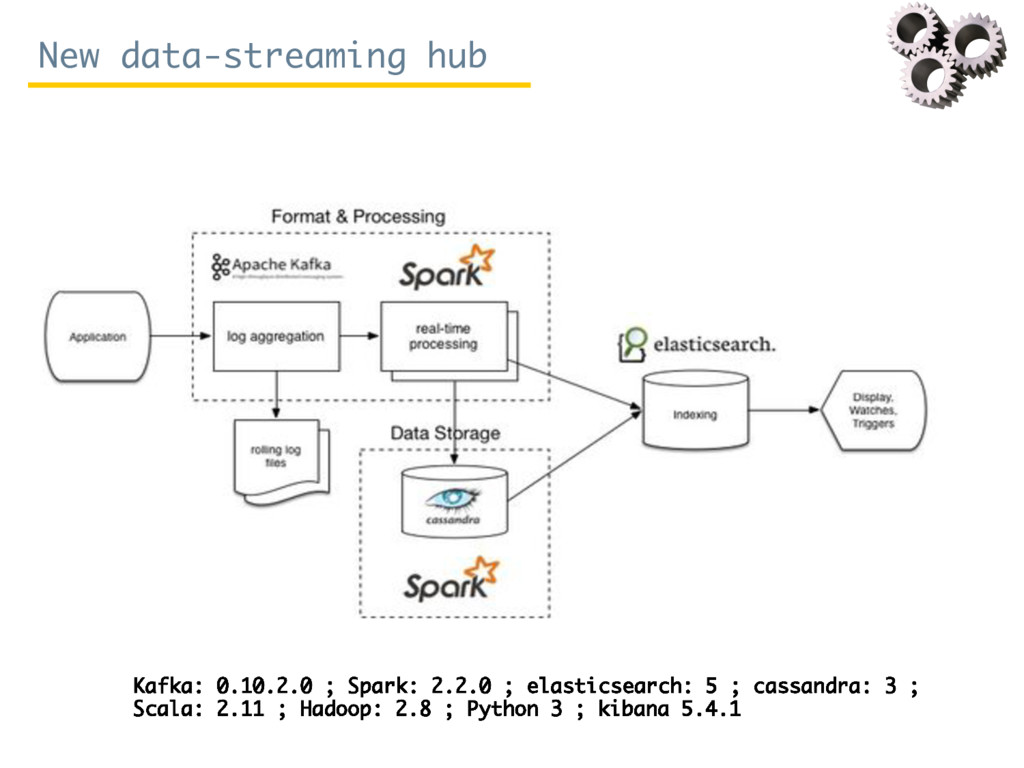
New data-streaming hub Kafka: 0.10.2.0 ; Spark: 2.2.0 ; elasticsearch:
5 ; cassandra: 3 ; Scala: 2.11 ; Hadoop: 2.8 ; Python 3 ; kibana 5.4.1 -
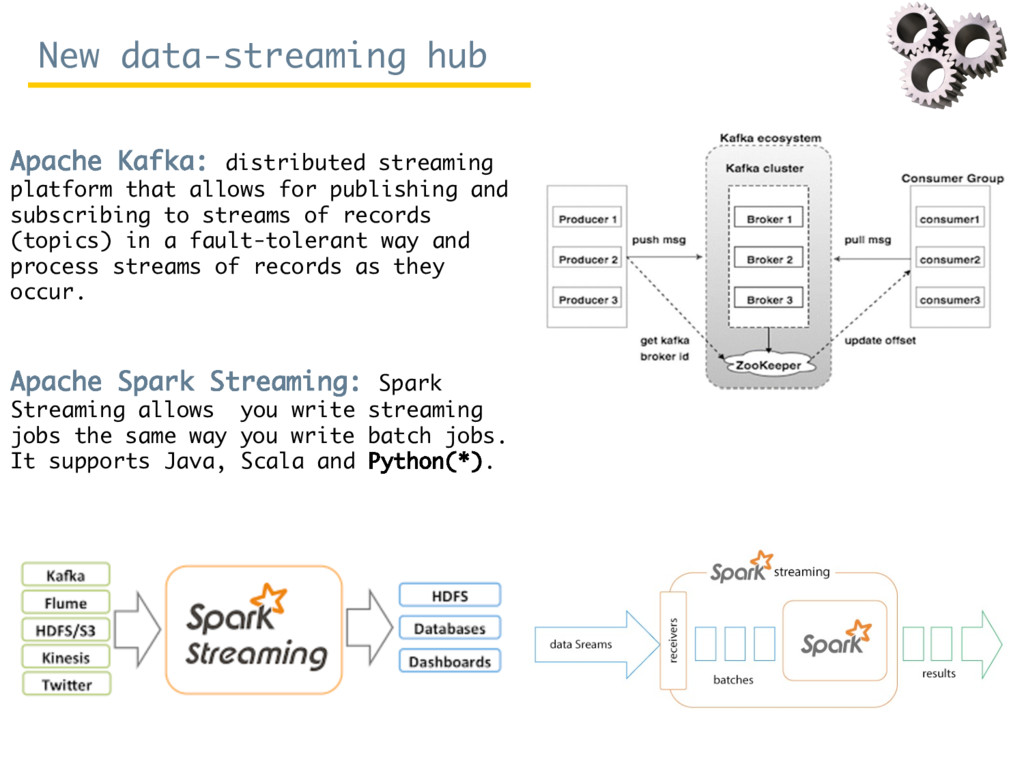
New data-streaming hub Apache Kafka: distributed streaming platform that allows
for publishing and subscribing to streams of records (topics) in a fault-tolerant way and process streams of records as they occur. Apache Spark Streaming: Spark Streaming allows you write streaming jobs the same way you write batch jobs. It supports Java, Scala and Python(*). -
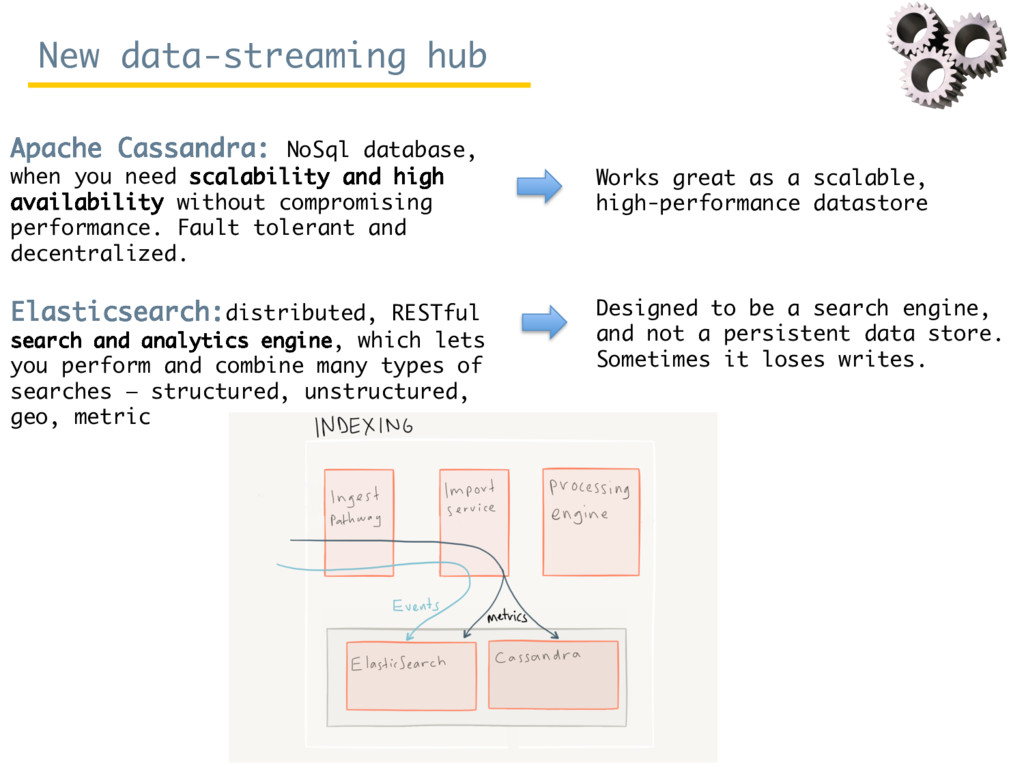
New data-streaming hub Apache Cassandra: NoSql database, when you need
scalability and high availability without compromising performance. Fault tolerant and decentralized. Elasticsearch:distributed, RESTful search and analytics engine, which lets you perform and combine many types of searches — structured, unstructured, geo, metric Designed to be a search engine, and not a persistent data store. Sometimes it loses writes. Works great as a scalable, high-performance datastore -
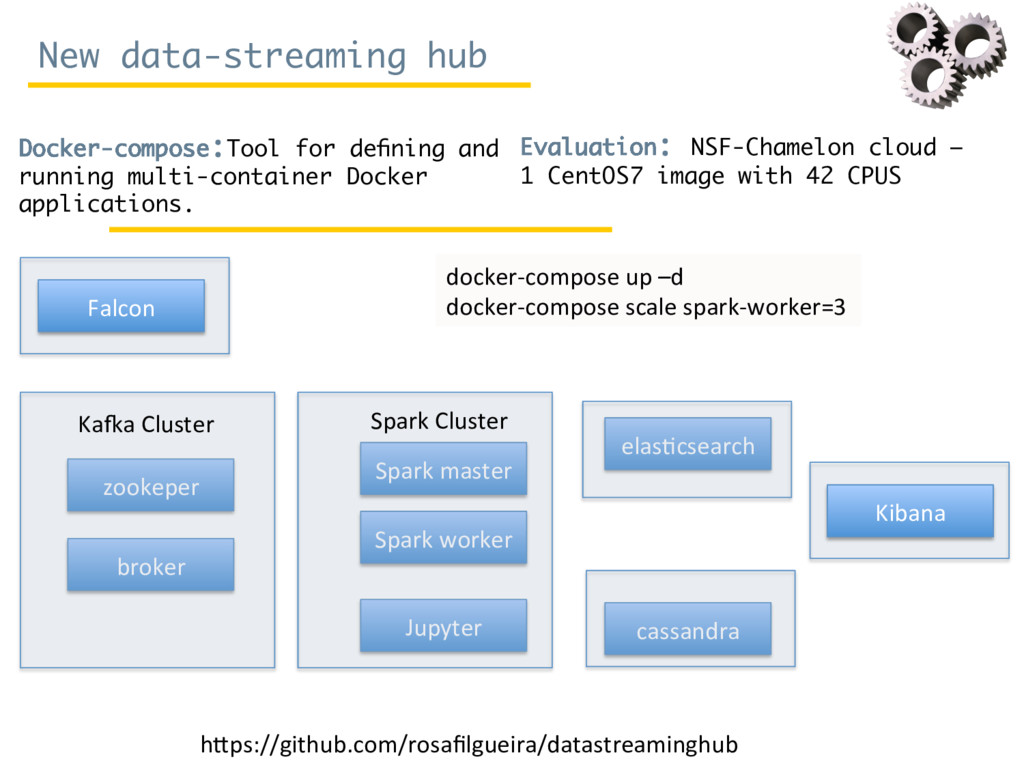
New data-streaming hub Docker-compose:Tool for defining and running multi-container Docker
applications. hXps://github.com/rosafilgueira/datastreaminghub Evaluation: NSF-Chamelon cloud – 1 CentOS7 image with 42 CPUS -
New data-streaming hub Docker-compose:Tool for defining and running multi-container Docker
applications. zookeper broker Spark master Spark worker Jupyter elas7csearch cassandra Kaha Cluster Spark Cluster Kibana Falcon hXps://github.com/rosafilgueira/datastreaminghub Evaluation: NSF-Chamelon cloud – 1 CentOS7 image with 42 CPUS docker-‐compose up –d docker-‐compose scale spark-‐worker=3 -
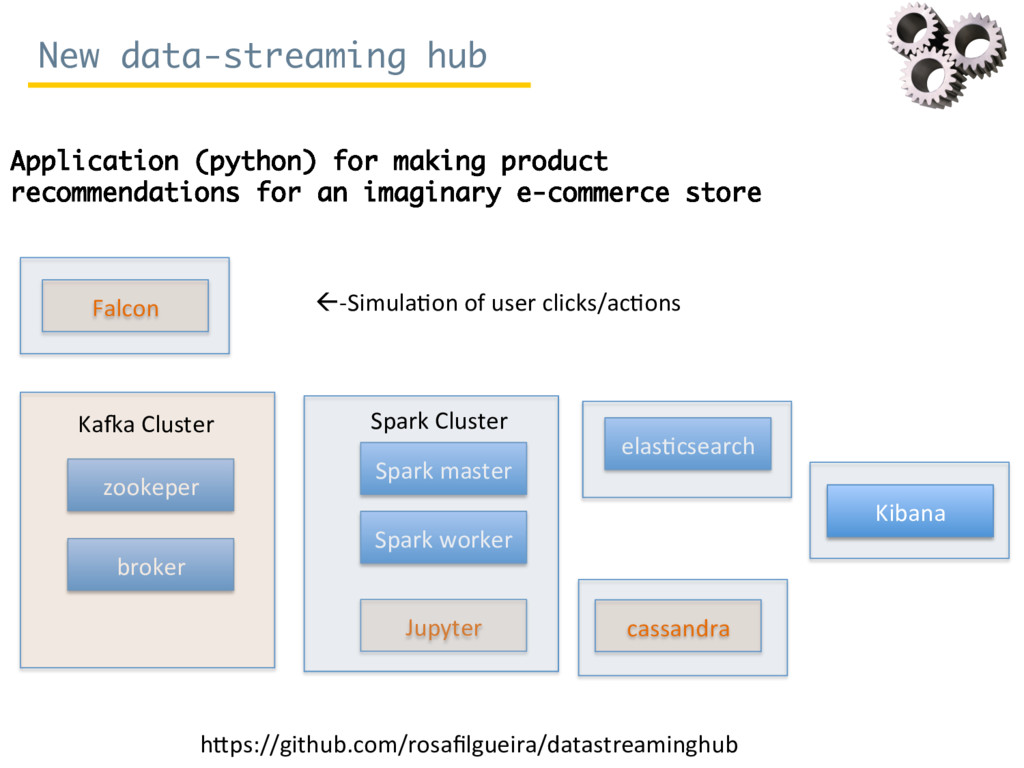
New data-streaming hub Application (python) for making product recommendations for
an imaginary e-commerce store zookeper broker Spark master Spark worker Jupyter elas7csearch Kaha Cluster Spark Cluster Kibana cassandra Falcon hXps://github.com/rosafilgueira/datastreaminghub ß-‐Simula7on of user clicks/ac7ons -
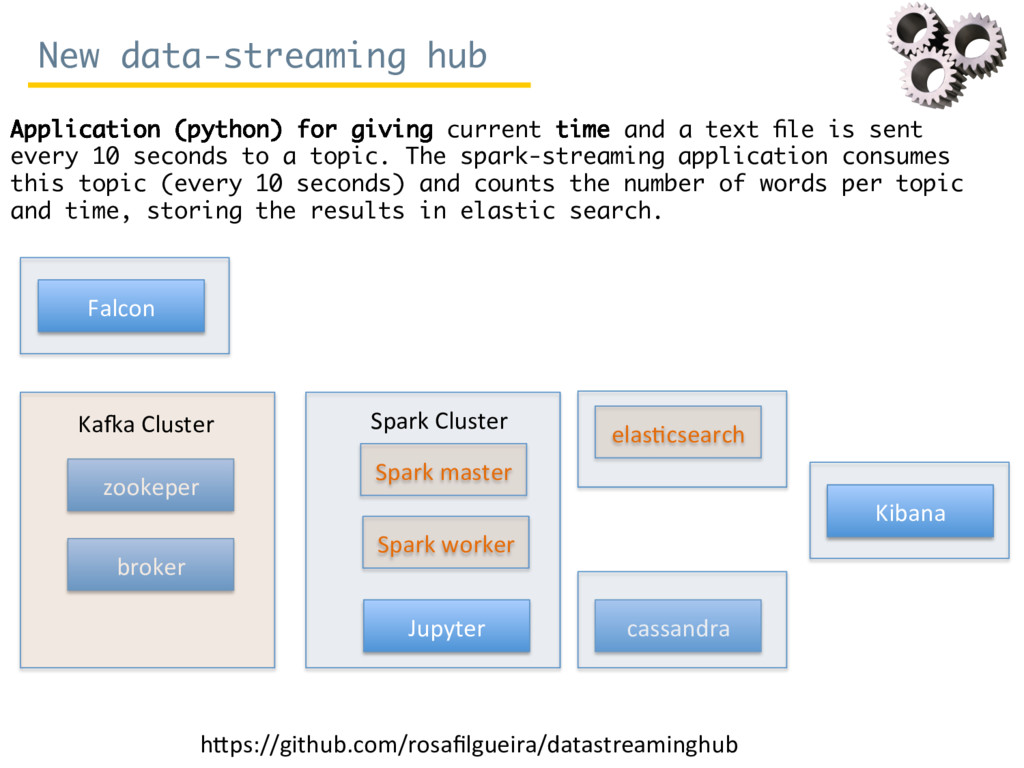
New data-streaming hub Application (python) for giving current time and
a text file is sent every 10 seconds to a topic. The spark-streaming application consumes this topic (every 10 seconds) and counts the number of words per topic and time, storing the results in elastic search. zookeper broker cassandra Kaha Cluster Spark Cluster Kibana hXps://github.com/rosafilgueira/datastreaminghub Falcon Jupyter Spark master Spark worker elas7csearch -
New data-streaming hub hXps://github.com/rosafilgueira/datastreaminghub Next steps: Create (draft) applications
for panorama and UKGEOS projects. Future changes in the current architecture: • Develop applications in Scala instead of Python • Integrate a resource manager in the Spark Cluster (Apache Mesos or Hadoop Yarn) • Swarm mode (or Kubernetes): Group of machines that are running Docker and joined into a cluster – instead of having a single VM with many CPU cores. -
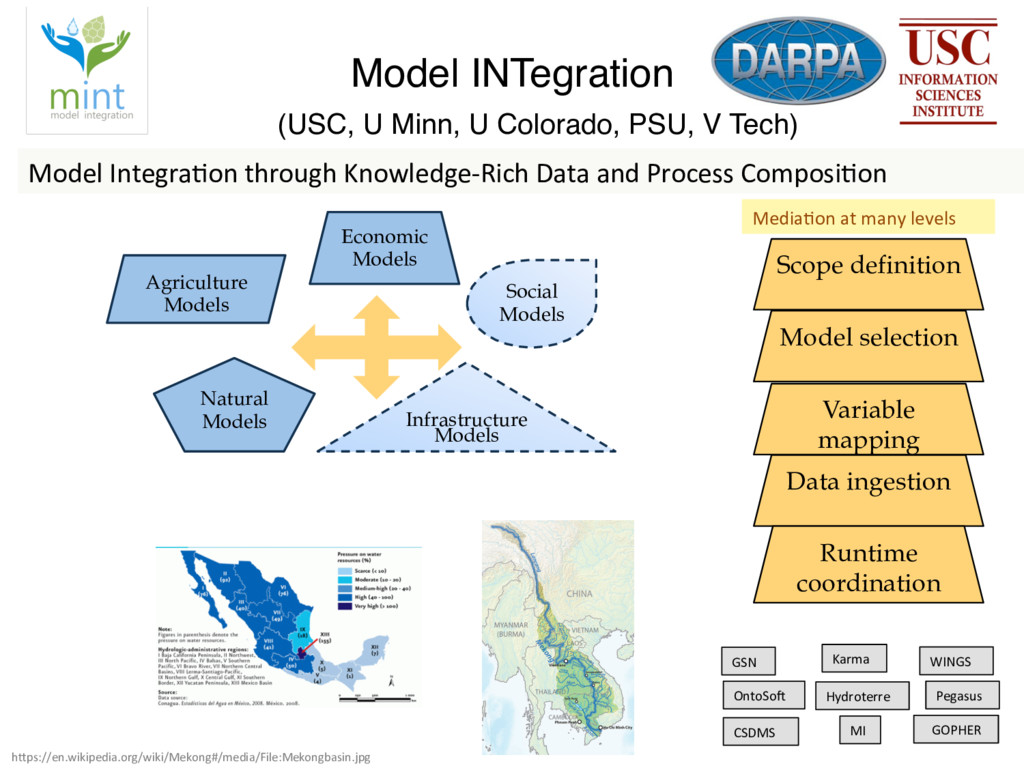
Model INTegration (USC, U Minn, U Colorado, PSU, V Tech)
Economic Models Natural Models Social Models Infrastructure Models hXps://en.wikipedia.org/wiki/Mekong#/media/File:Mekongbasin.jpg Agriculture Models Model selection Variable mapping Data ingestion Runtime coordination Scope definition Media7on at many levels WINGS GSN OntoSoT MI CSDMS Pegasus Karma Hydroterre GOPHER Model Integra7on through Knowledge-‐Rich Data and Process Composi7on -
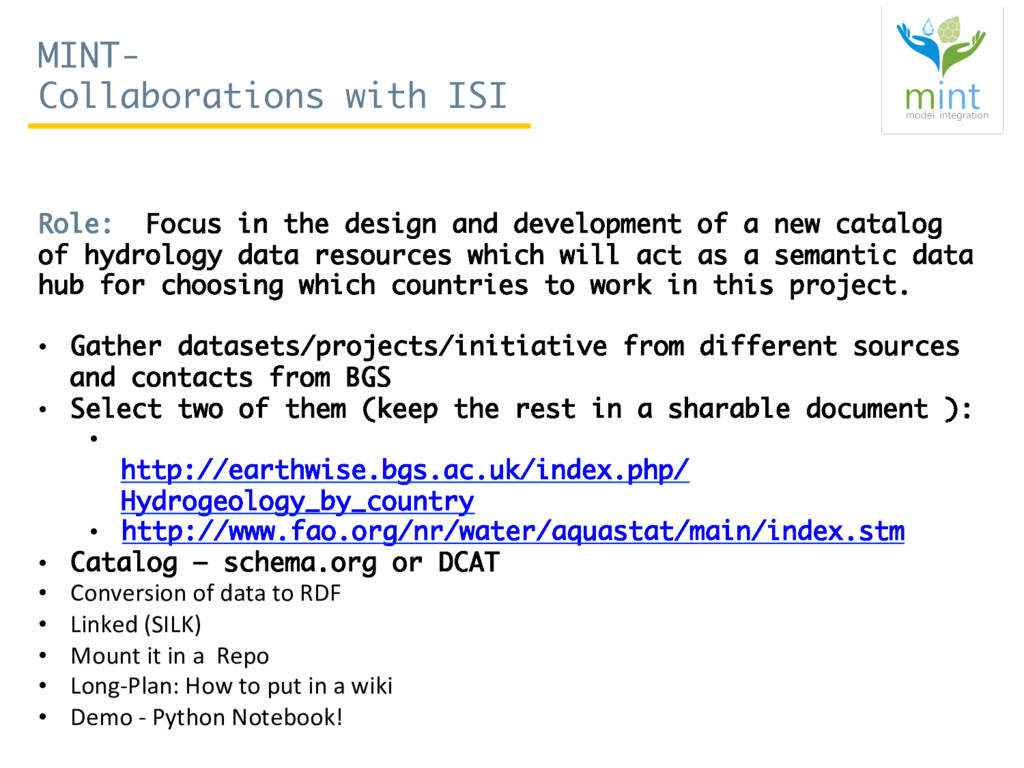
MINT- Collaborations with ISI Role: Focus in the design and
development of a new catalog of hydrology data resources which will act as a semantic data hub for choosing which countries to work in this project. • Gather datasets/projects/initiative from different sources and contacts from BGS • Select two of them (keep the rest in a sharable document ): • http://earthwise.bgs.ac.uk/index.php/ Hydrogeology_by_country • http://www.fao.org/nr/water/aquastat/main/index.stm • Catalog – schema.org or DCAT • Conversion of data to RDF • Linked (SILK) • Mount it in a Repo • Long-‐Plan: How to put in a wiki • Demo -‐ Python Notebook! -
Development of advanced information processing technologies and intelligent systems
for supporting geosciences innovation THANKS!