Introduction to Amazon DynamoDB
Presentation given at Percona 2013 conference in Santa Clara, California. Speaker is Simone Brunozzi.
You can follow him on Twitter: @simon

Simone Brunozzi
April 23, 2013
Presentation given at Percona 2013 conference in Santa Clara, California. Speaker is Simone Brunozzi.
You can follow him on Twitter: @simon
 simonebrunozzi
 atalie2m
 shotashiratori
 shadowhat
 daishukojima
 oidfj
 jackojacko_
 minorun365
 hatahata021
 yuutosi
 kamadamakoto
 yosukeyoshida
 cassininazir
 addyosmani
 jnunemaker
 brettharned
 tammielis
 tamaranovitovic
 twada
 chriscoyier
 garrettdimon
 kimpetersen
 akademiya2063
![Who invented “NoSQL” ? ] [ 3](https://files.speakerdeck.com/presentations/9060aa208e950130f883123138195151/slide_2.jpg)
![Who invented “NoSQL” ? ] [ 3 “NoSQL” conceived in](https://files.speakerdeck.com/presentations/9060aa208e950130f883123138195151/slide_3.jpg)
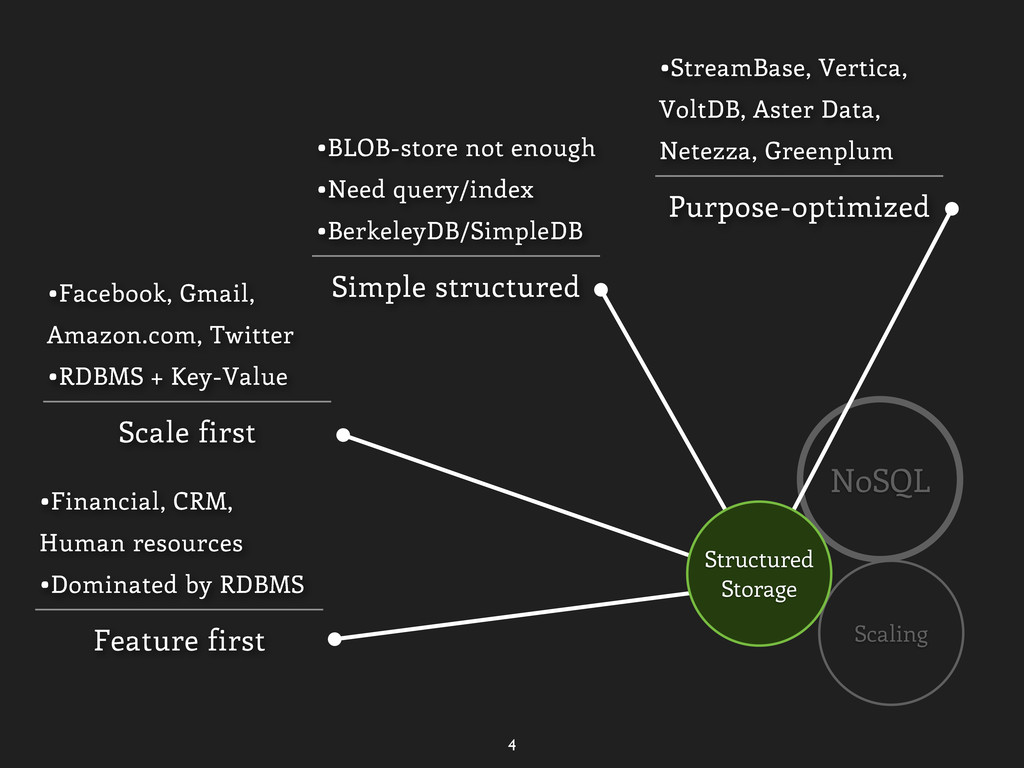
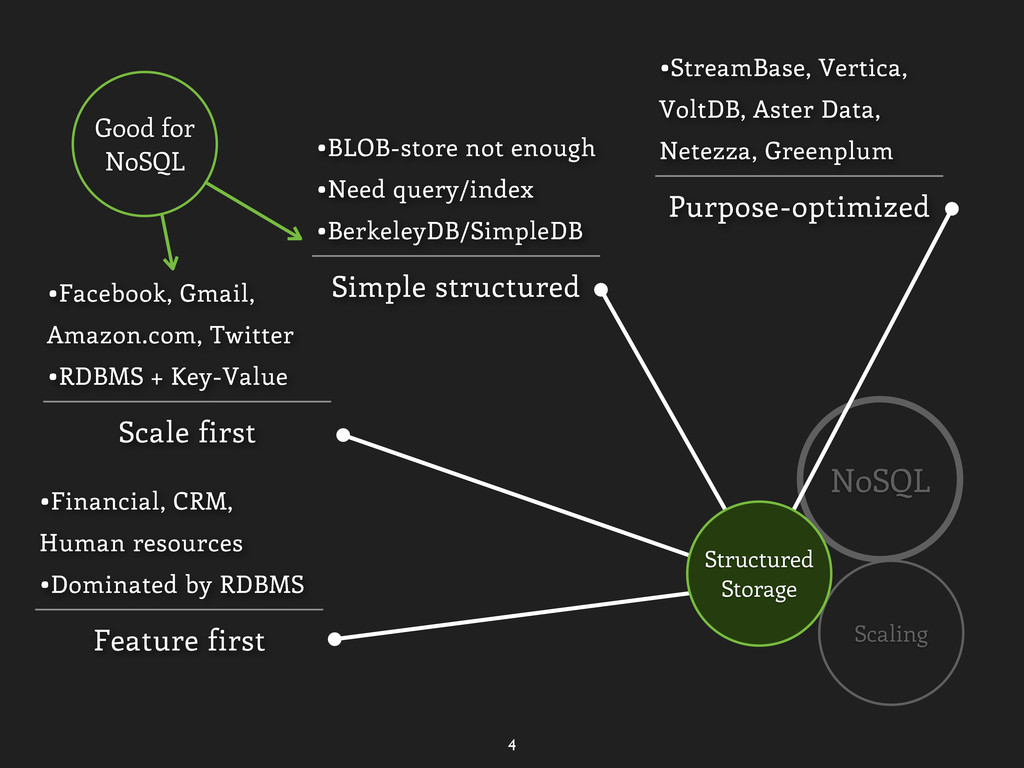
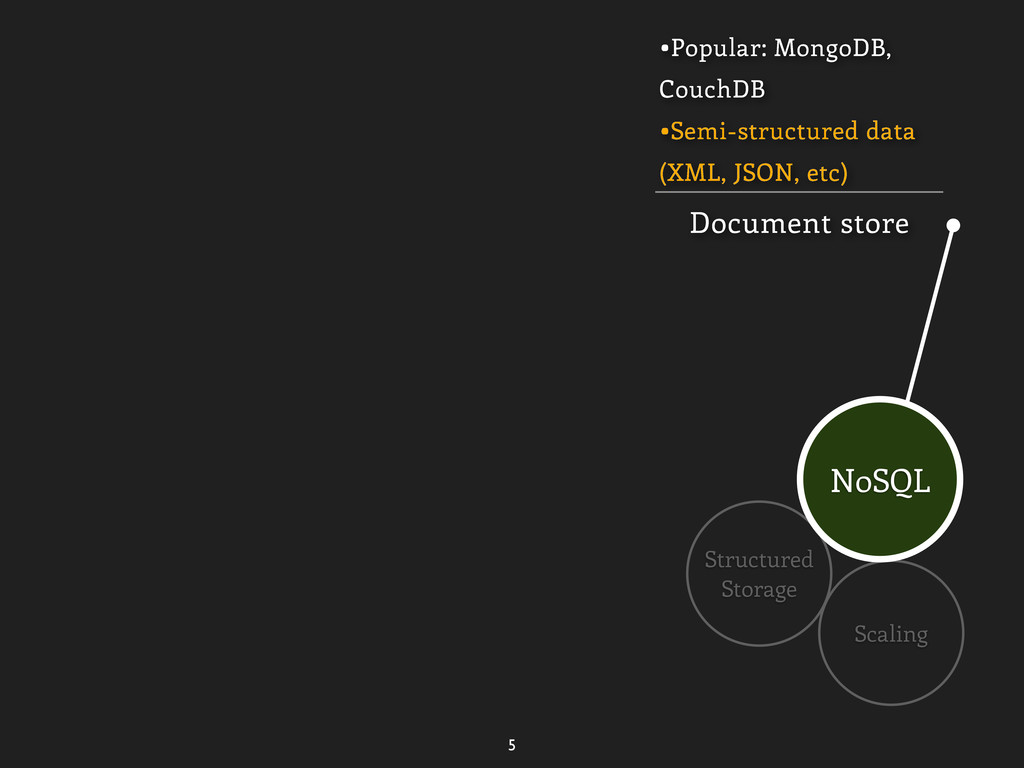
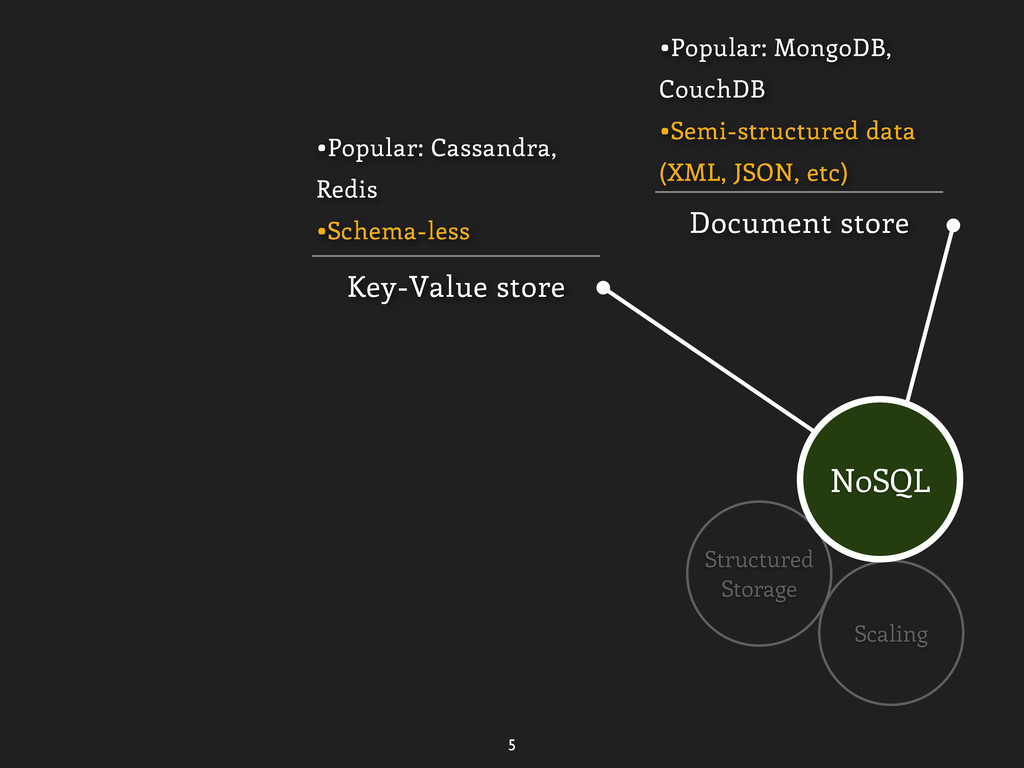
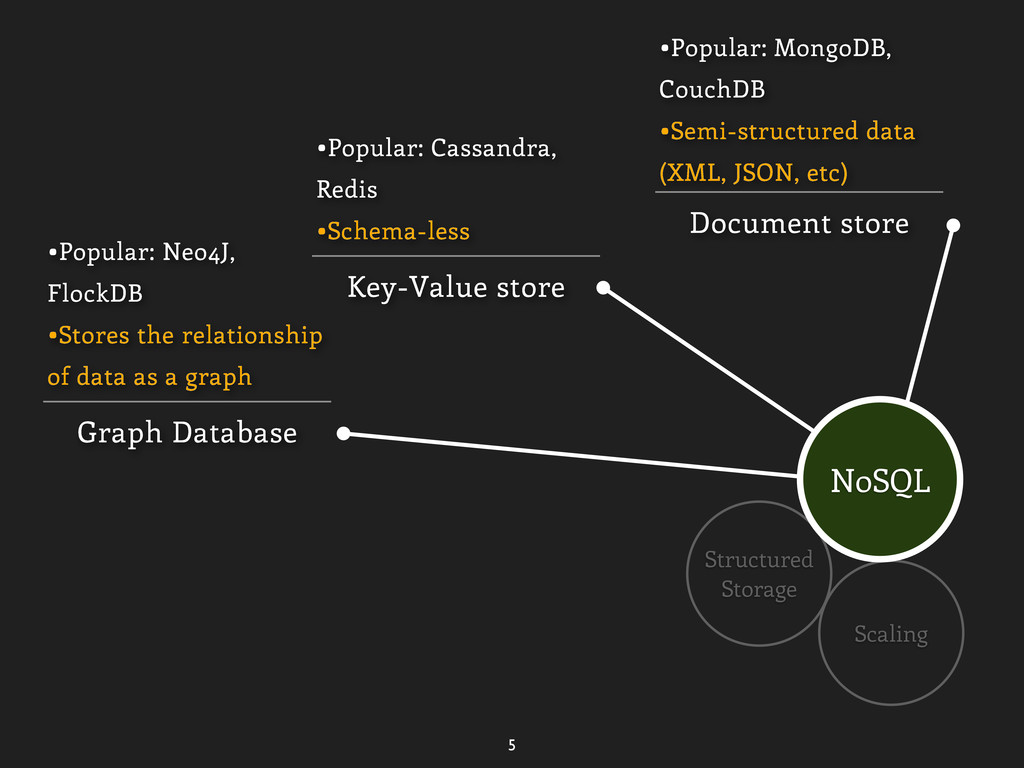
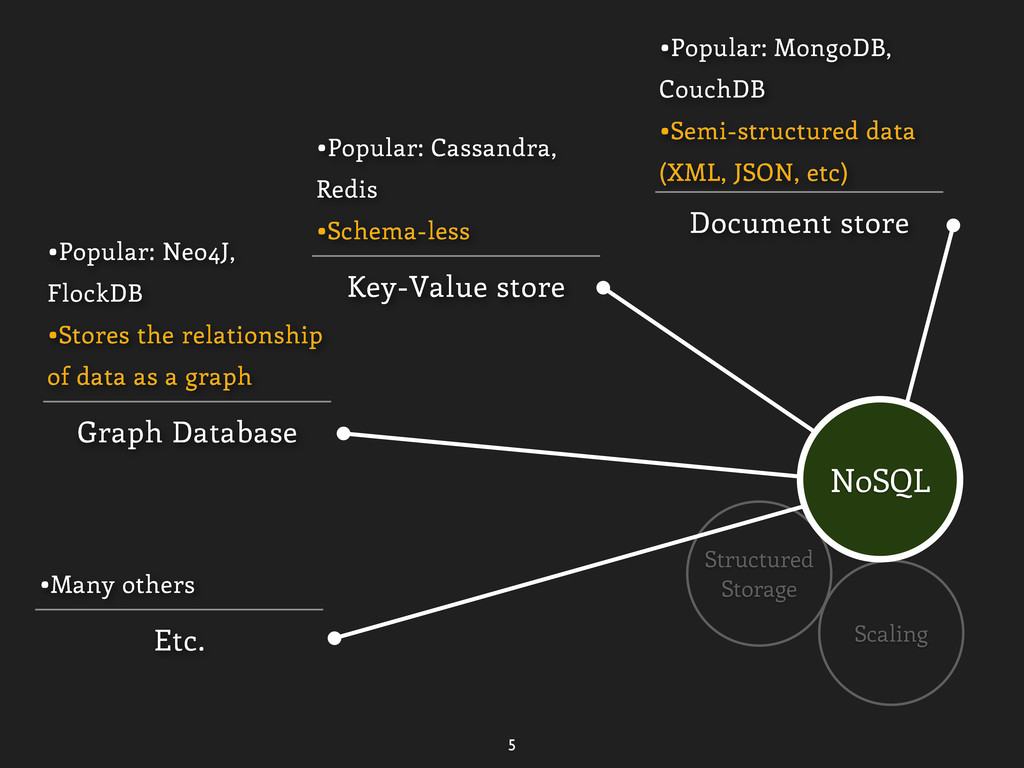
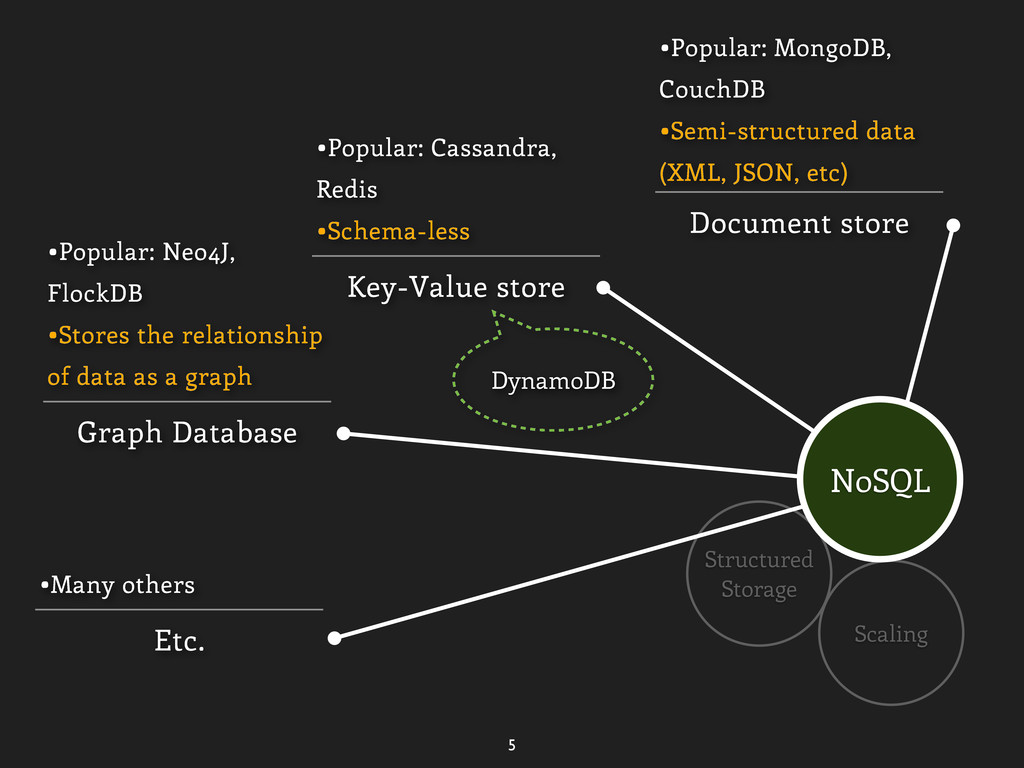
![Why scalability is important ] [ 7 traditional IT capacity](https://files.speakerdeck.com/presentations/9060aa208e950130f883123138195151/slide_20.jpg)
![8 Usage patterns: traditional IT ] [](https://files.speakerdeck.com/presentations/9060aa208e950130f883123138195151/slide_21.jpg)
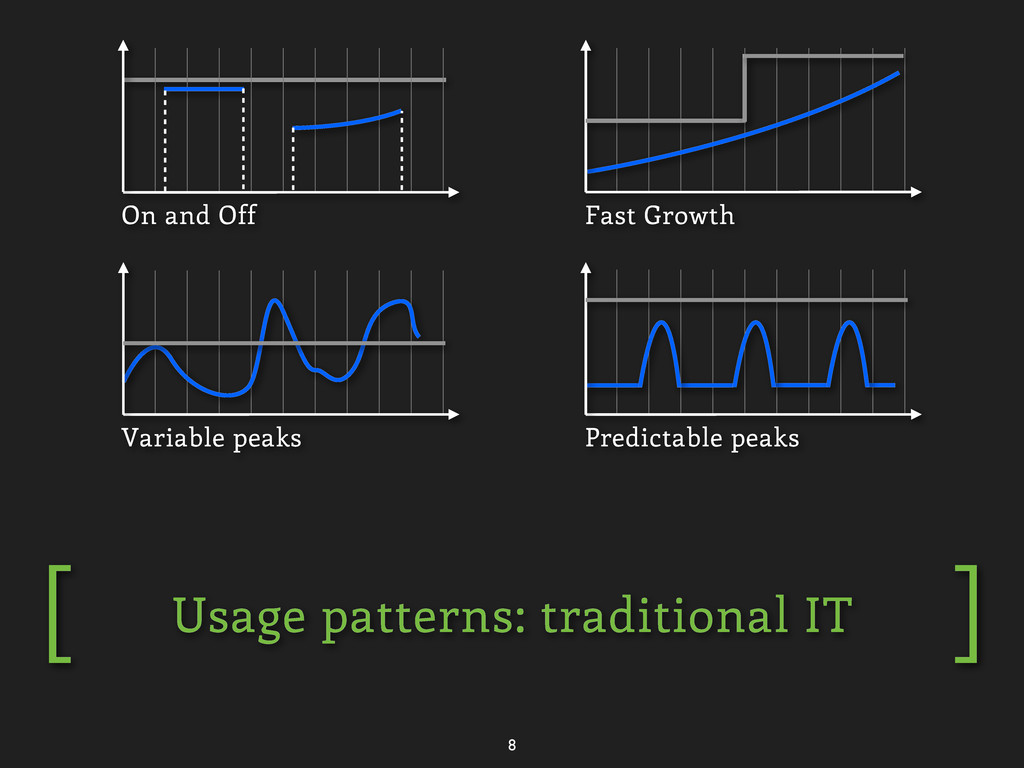
![9 Usage patterns: traditional IT ] [ Variable peaks Fast](https://files.speakerdeck.com/presentations/9060aa208e950130f883123138195151/slide_23.jpg)
![9 Poor Service WASTE Usage patterns: traditional IT ] [](https://files.speakerdeck.com/presentations/9060aa208e950130f883123138195151/slide_24.jpg)
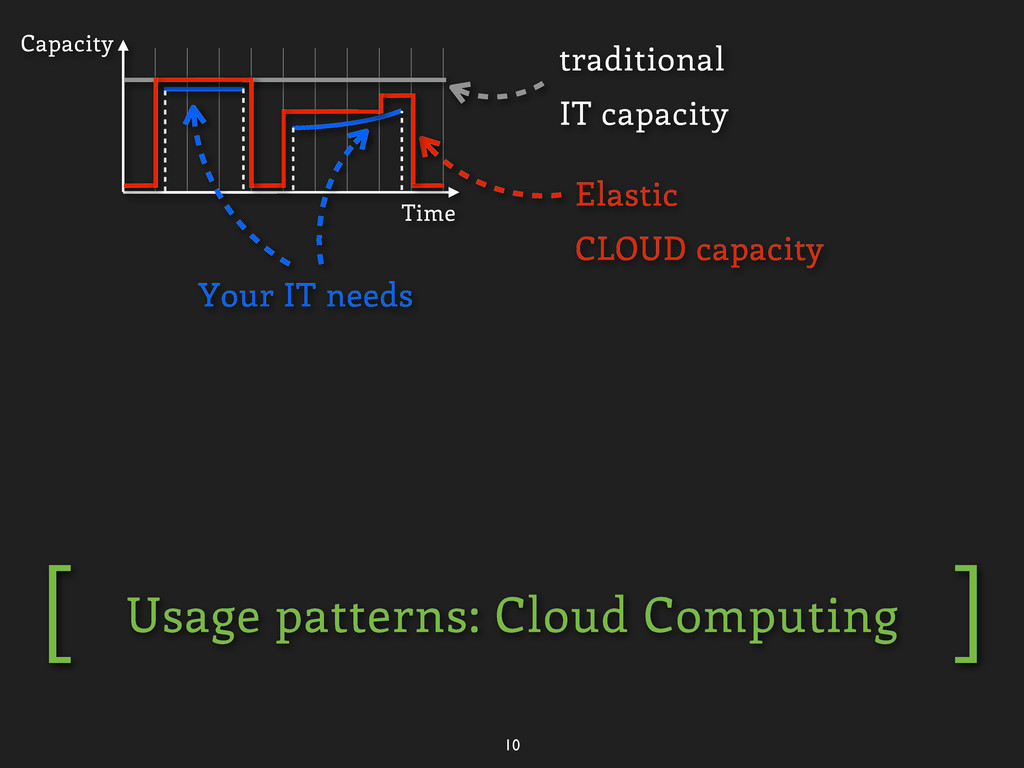
![11 Usage patterns: Cloud Computing ] [ Variable peaks Fast](https://files.speakerdeck.com/presentations/9060aa208e950130f883123138195151/slide_26.jpg)
![11 Usage patterns: Cloud Computing ] [ Variable peaks Fast](https://files.speakerdeck.com/presentations/9060aa208e950130f883123138195151/slide_27.jpg)
![13 DynamoDB: Speeeed ] [ (image)](https://files.speakerdeck.com/presentations/9060aa208e950130f883123138195151/slide_29.jpg)
![13 DynamoDB: Speeeed ] [ Scale to 100,000+ Writes/second (image)](https://files.speakerdeck.com/presentations/9060aa208e950130f883123138195151/slide_30.jpg)
![DynamoDB ] [ 15 DynamoDB](https://files.speakerdeck.com/presentations/9060aa208e950130f883123138195151/slide_32.jpg)
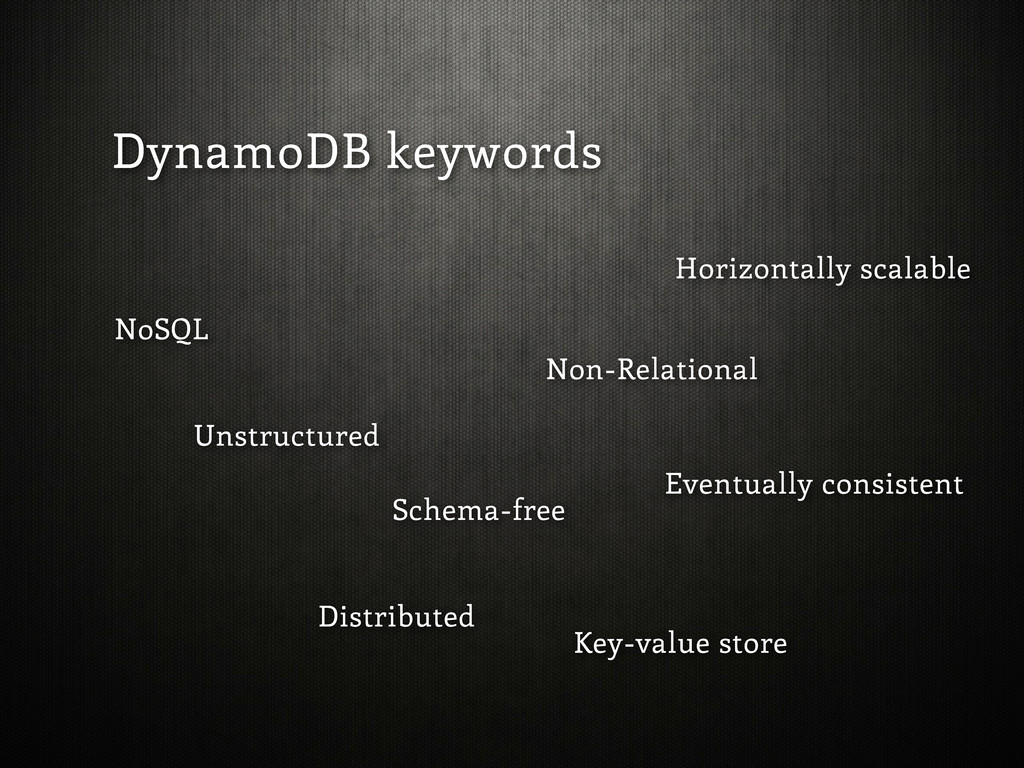
![DynamoDB ] [ 15 NoSQL • No schema (only Key)](https://files.speakerdeck.com/presentations/9060aa208e950130f883123138195151/slide_33.jpg)
![DynamoDB ] [ 15 NoSQL • No schema (only Key)](https://files.speakerdeck.com/presentations/9060aa208e950130f883123138195151/slide_34.jpg)
![DynamoDB ] [ 15 NoSQL • No schema (only Key)](https://files.speakerdeck.com/presentations/9060aa208e950130f883123138195151/slide_35.jpg)
![Creating a table with the Java low-level API ] [](https://files.speakerdeck.com/presentations/9060aa208e950130f883123138195151/slide_37.jpg)
![Creating a table with the Java low-level API ] [](https://files.speakerdeck.com/presentations/9060aa208e950130f883123138195151/slide_38.jpg)
![Creating a table with BOTO library (Python) ] [ 18](https://files.speakerdeck.com/presentations/9060aa208e950130f883123138195151/slide_39.jpg)
![Creating a table with BOTO library (Python) ] [ 18](https://files.speakerdeck.com/presentations/9060aa208e950130f883123138195151/slide_40.jpg)
![Deleting a table? Careful... ] [ 19 >>> conn.delete_table(table)](https://files.speakerdeck.com/presentations/9060aa208e950130f883123138195151/slide_41.jpg)
![Deleting a table? Careful... ] [ 19 >>> conn.delete_table(table) Permanently](https://files.speakerdeck.com/presentations/9060aa208e950130f883123138195151/slide_42.jpg)
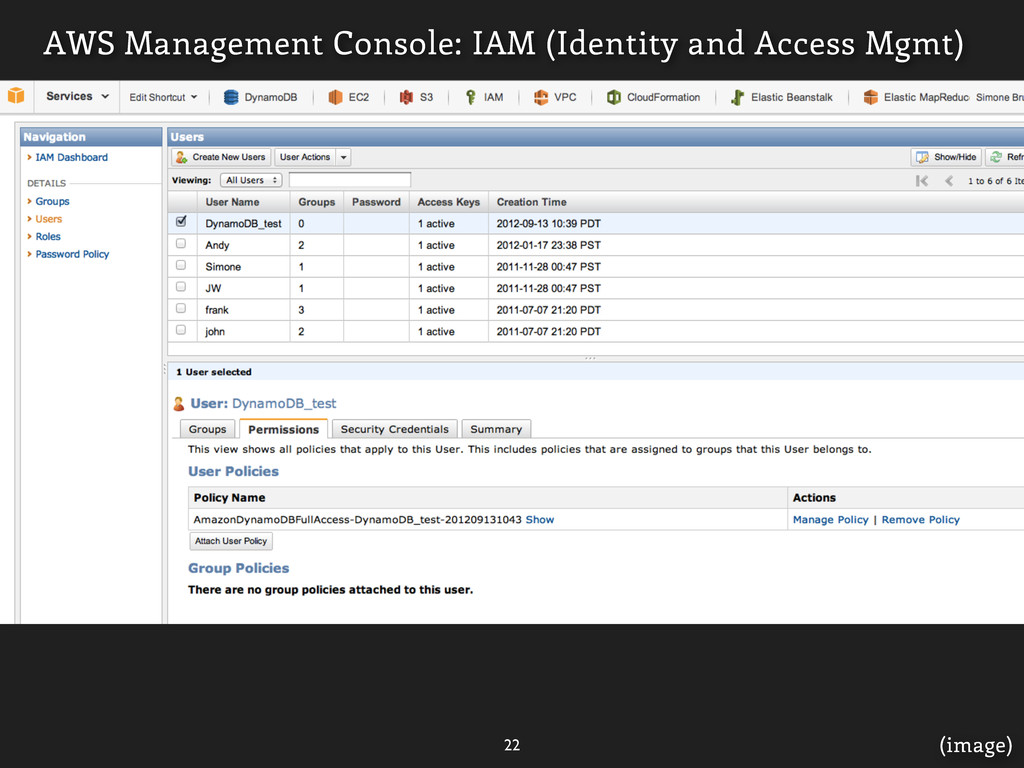
![Managing DynamoDB permissions with IAM ] [ 20 { "Statement":](https://files.speakerdeck.com/presentations/9060aa208e950130f883123138195151/slide_43.jpg)
![Managing DynamoDB permissions with IAM ] [ 20 { "Statement":](https://files.speakerdeck.com/presentations/9060aa208e950130f883123138195151/slide_44.jpg)
![Managing DynamoDB permissions with IAM ] [ 21 { "Statement":](https://files.speakerdeck.com/presentations/9060aa208e950130f883123138195151/slide_45.jpg)
![Managing DynamoDB permissions with IAM ] [ 21 { "Statement":](https://files.speakerdeck.com/presentations/9060aa208e950130f883123138195151/slide_46.jpg)
![DynamoDB Data Model ] [](https://files.speakerdeck.com/presentations/9060aa208e950130f883123138195151/slide_49.jpg)
![DynamoDB Data Model ] [ Table(s) Item(s) Attribute(s)](https://files.speakerdeck.com/presentations/9060aa208e950130f883123138195151/slide_50.jpg)
![Example: Table, Items, Attributes ] [](https://files.speakerdeck.com/presentations/9060aa208e950130f883123138195151/slide_51.jpg)
![Products Example: Table, Items, Attributes ] [ Table You must](https://files.speakerdeck.com/presentations/9060aa208e950130f883123138195151/slide_52.jpg)
![Products Example: Table, Items, Attributes ] [](https://files.speakerdeck.com/presentations/9060aa208e950130f883123138195151/slide_53.jpg)
![Products Example: Table, Items, Attributes ] [ Item Item Item](https://files.speakerdeck.com/presentations/9060aa208e950130f883123138195151/slide_54.jpg)
![Products Example: Table, Items, Attributes ] [](https://files.speakerdeck.com/presentations/9060aa208e950130f883123138195151/slide_55.jpg)
![Products Example: Table, Items, Attributes ] [ id=”301” id=”201” Author=”Simone”,](https://files.speakerdeck.com/presentations/9060aa208e950130f883123138195151/slide_56.jpg)
![Products Example: Table, Items, Attributes ] [ id=”301” id=”201” Author=”Simone”,](https://files.speakerdeck.com/presentations/9060aa208e950130f883123138195151/slide_57.jpg)
![Products Example: Table, Items, Attributes ] [ id=”301” id=”201” Author=”Simone”,](https://files.speakerdeck.com/presentations/9060aa208e950130f883123138195151/slide_58.jpg)
![DynamoDB Data Types ] [](https://files.speakerdeck.com/presentations/9060aa208e950130f883123138195151/slide_59.jpg)
![DynamoDB Data Types ] [ Scalar Number (+/-, 38 digits)](https://files.speakerdeck.com/presentations/9060aa208e950130f883123138195151/slide_60.jpg)
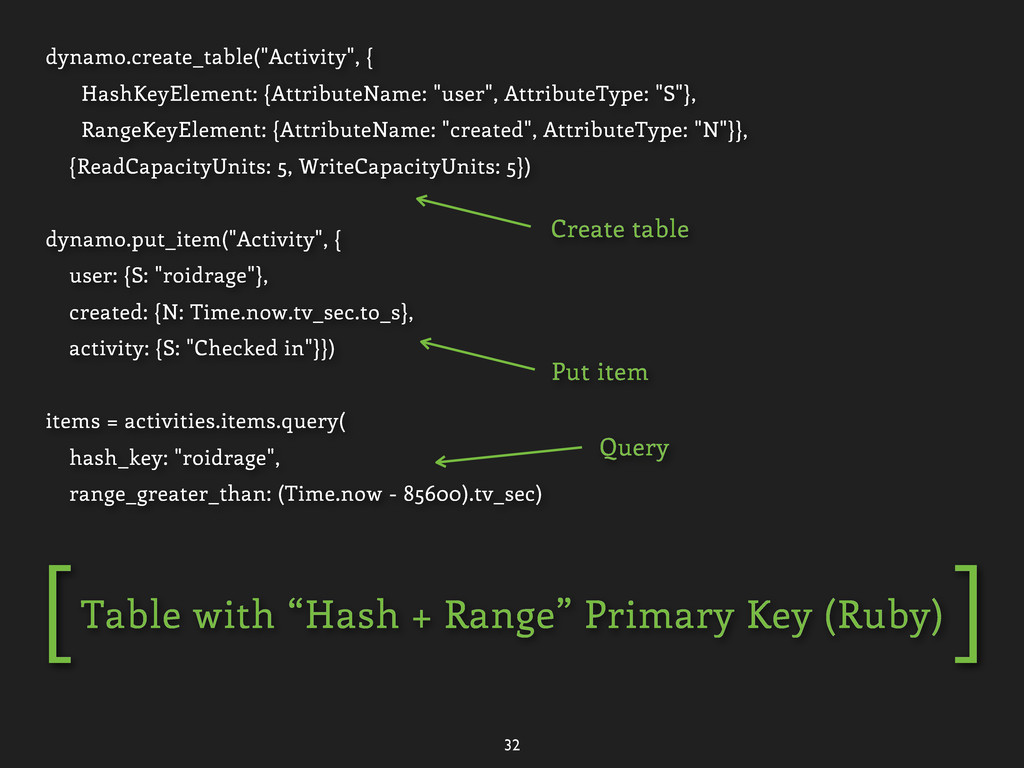
![Primary Key: Hash / Hash + Range ] [ 30](https://files.speakerdeck.com/presentations/9060aa208e950130f883123138195151/slide_61.jpg)
![Primary Key: Hash / Hash + Range ] [ 30](https://files.speakerdeck.com/presentations/9060aa208e950130f883123138195151/slide_62.jpg)
![Primary Key: Hash / Hash + Range ] [ 30](https://files.speakerdeck.com/presentations/9060aa208e950130f883123138195151/slide_63.jpg)
![Primary Key: Hash / Hash + Range ] [ 31](https://files.speakerdeck.com/presentations/9060aa208e950130f883123138195151/slide_64.jpg)
![Primary Key: Hash / Hash + Range ] [ 31](https://files.speakerdeck.com/presentations/9060aa208e950130f883123138195151/slide_65.jpg)
![Primary Key: Hash / Hash + Range ] [ 31](https://files.speakerdeck.com/presentations/9060aa208e950130f883123138195151/slide_66.jpg)
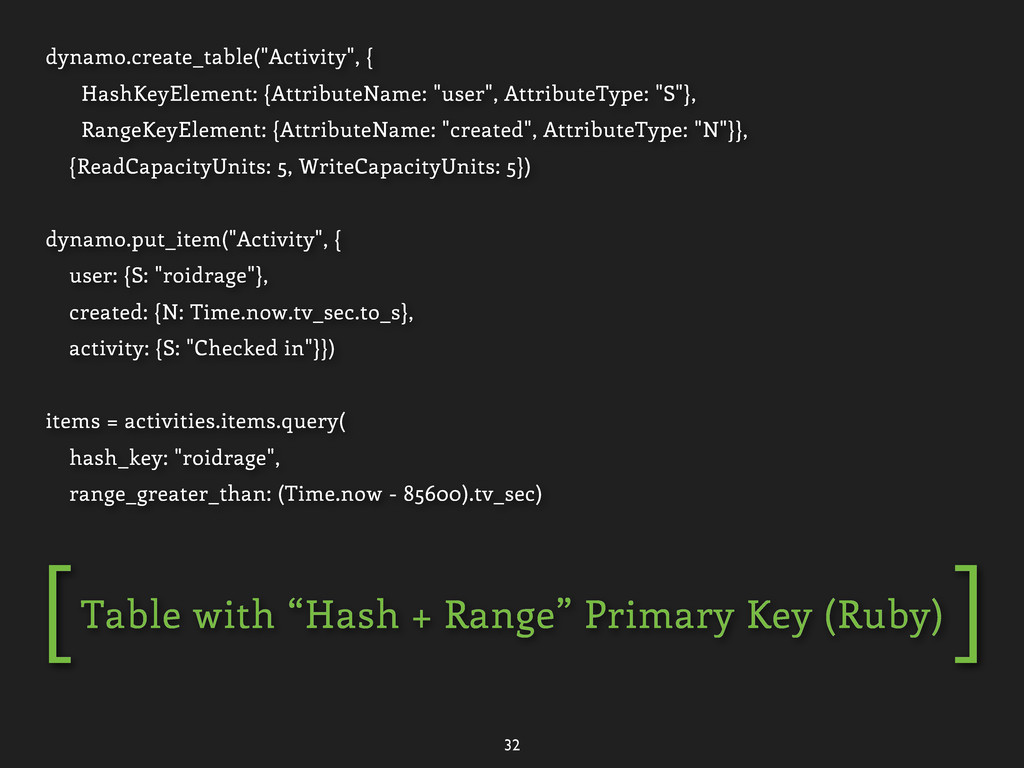
![Query / Scan ] [ 36 http://docs.amazonwebservices.com/amazondynamodb/latest/developerguide/QueryAndScan.html](https://files.speakerdeck.com/presentations/9060aa208e950130f883123138195151/slide_72.jpg)
![Query / Scan ] [ 36 Query • Search only](https://files.speakerdeck.com/presentations/9060aa208e950130f883123138195151/slide_73.jpg)
![Query / Scan ] [ 36 Scan • Scans the](https://files.speakerdeck.com/presentations/9060aa208e950130f883123138195151/slide_74.jpg)
![Writing to DynamoDB ] [ 41 http://docs.amazonwebservices.com/amazondynamodb/latest/developerguide/QueryAndScan.html](https://files.speakerdeck.com/presentations/9060aa208e950130f883123138195151/slide_79.jpg)
![Writing to DynamoDB ] [ 41 http://docs.amazonwebservices.com/amazondynamodb/latest/developerguide/QueryAndScan.html How to solve](https://files.speakerdeck.com/presentations/9060aa208e950130f883123138195151/slide_80.jpg)
![Writing to DynamoDB ] [ 41 http://docs.amazonwebservices.com/amazondynamodb/latest/developerguide/QueryAndScan.html How to solve](https://files.speakerdeck.com/presentations/9060aa208e950130f883123138195151/slide_81.jpg)
![DynamoDB The “Lost update” concurrency issue ] [ Client 1](https://files.speakerdeck.com/presentations/9060aa208e950130f883123138195151/slide_82.jpg)
![DynamoDB The “Lost update” concurrency issue ] [ Client 1](https://files.speakerdeck.com/presentations/9060aa208e950130f883123138195151/slide_83.jpg)
![DynamoDB The “Lost update” concurrency issue ] [ Client 1](https://files.speakerdeck.com/presentations/9060aa208e950130f883123138195151/slide_84.jpg)
![DynamoDB How to fix it with Conditional Writes ] [](https://files.speakerdeck.com/presentations/9060aa208e950130f883123138195151/slide_85.jpg)
![DynamoDB How to fix it with Conditional Writes ] [](https://files.speakerdeck.com/presentations/9060aa208e950130f883123138195151/slide_86.jpg)
![DynamoDB How to fix it with Conditional Writes ] [](https://files.speakerdeck.com/presentations/9060aa208e950130f883123138195151/slide_87.jpg)
![Conditional Writes or Atomic Counters? ] [](https://files.speakerdeck.com/presentations/9060aa208e950130f883123138195151/slide_88.jpg)
![Conditional Writes or Atomic Counters? ] [ Conditional Writes •Idempotent](https://files.speakerdeck.com/presentations/9060aa208e950130f883123138195151/slide_89.jpg)
![Conditional Writes or Atomic Counters? ] [ Conditional Writes •Idempotent](https://files.speakerdeck.com/presentations/9060aa208e950130f883123138195151/slide_90.jpg)
![(Eventually) Consistent Reads ] [](https://files.speakerdeck.com/presentations/9060aa208e950130f883123138195151/slide_92.jpg)
![(Eventually) Consistent Reads ] [ Consistent Read •Consumes more “read](https://files.speakerdeck.com/presentations/9060aa208e950130f883123138195151/slide_93.jpg)
![(Eventually) Consistent Reads ] [ Consistent Read •Consumes more “read](https://files.speakerdeck.com/presentations/9060aa208e950130f883123138195151/slide_94.jpg)
![(Eventually) Consistent Reads ] [ Consistent Read •Consumes more “read](https://files.speakerdeck.com/presentations/9060aa208e950130f883123138195151/slide_95.jpg)
![(Eventually) Consistent Reads ] [ Consistent Read •Consumes more “read](https://files.speakerdeck.com/presentations/9060aa208e950130f883123138195151/slide_96.jpg)
![DynamoDB Durability in DynamoDB ] [ Client Time](https://files.speakerdeck.com/presentations/9060aa208e950130f883123138195151/slide_97.jpg)
![DynamoDB Durability in DynamoDB ] [ Client Id=1 Price=10 Id=1](https://files.speakerdeck.com/presentations/9060aa208e950130f883123138195151/slide_98.jpg)
![Example: Consistent Read (HTTP request) ] [ 49 // This](https://files.speakerdeck.com/presentations/9060aa208e950130f883123138195151/slide_99.jpg)
![Example: Consistent Read (HTTP request) ] [ 49 // This](https://files.speakerdeck.com/presentations/9060aa208e950130f883123138195151/slide_100.jpg)
![Consistency Availability Partition Tolerance CAP Theorem ] [](https://files.speakerdeck.com/presentations/9060aa208e950130f883123138195151/slide_101.jpg)
![DynamoDB APIs ] [](https://files.speakerdeck.com/presentations/9060aa208e950130f883123138195151/slide_103.jpg)
![DynamoDB APIs ] [ Table •CreateTable •UpdateTable •DeleteTable •DescribeTable •ListTables](https://files.speakerdeck.com/presentations/9060aa208e950130f883123138195151/slide_104.jpg)
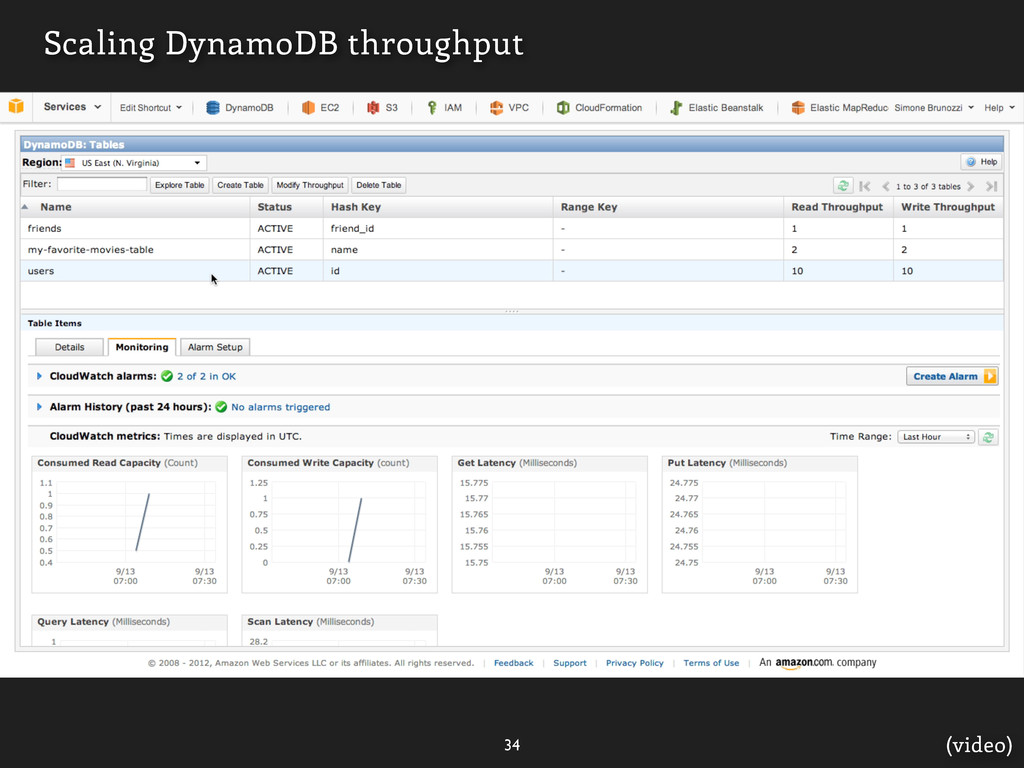
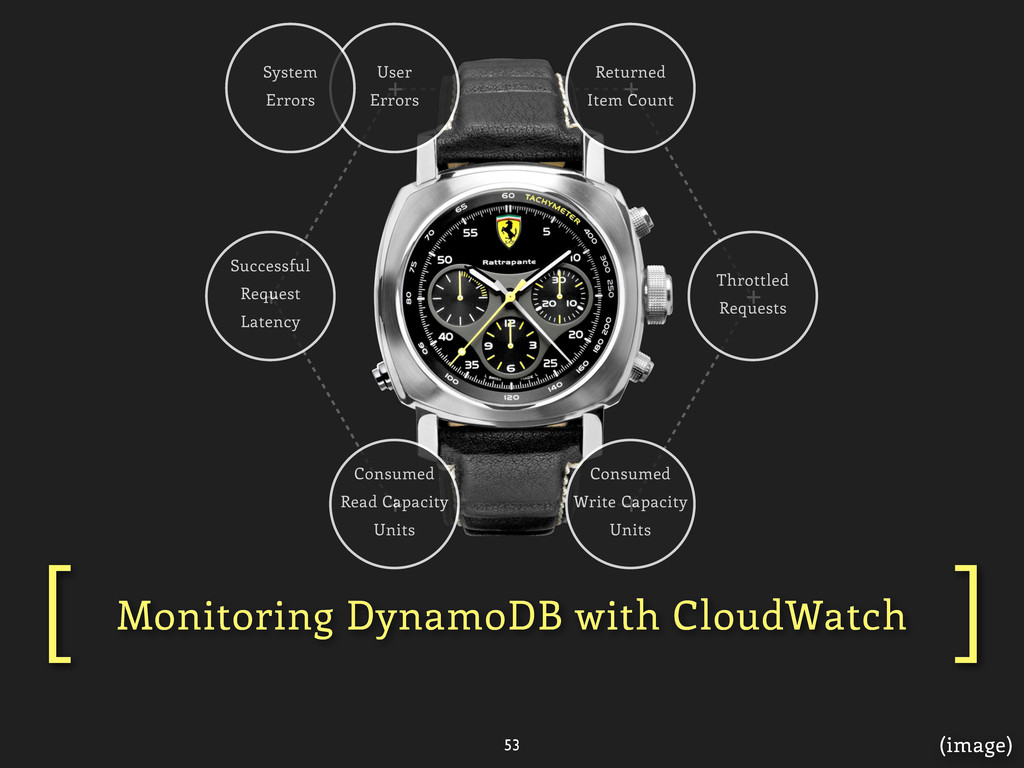
![53 (image) Monitoring DynamoDB with CloudWatch ] [](https://files.speakerdeck.com/presentations/9060aa208e950130f883123138195151/slide_105.jpg)
![A simple example ] [](https://files.speakerdeck.com/presentations/9060aa208e950130f883123138195151/slide_107.jpg)
![A simple example ] [ Let’s take a look. How](https://files.speakerdeck.com/presentations/9060aa208e950130f883123138195151/slide_108.jpg)
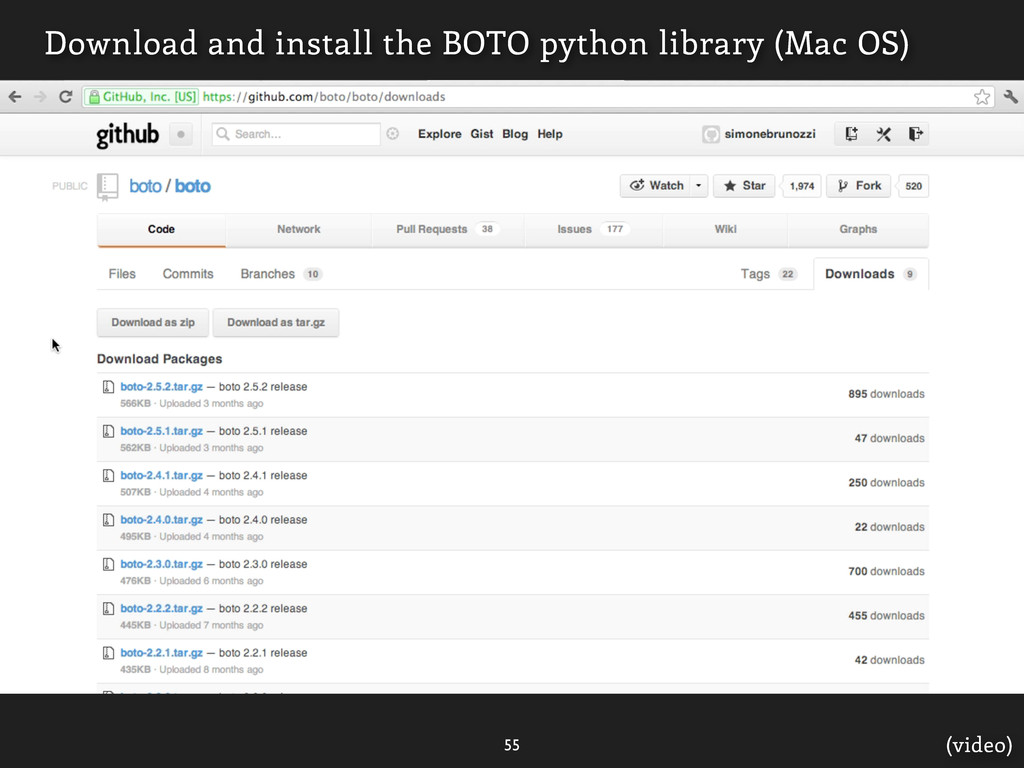
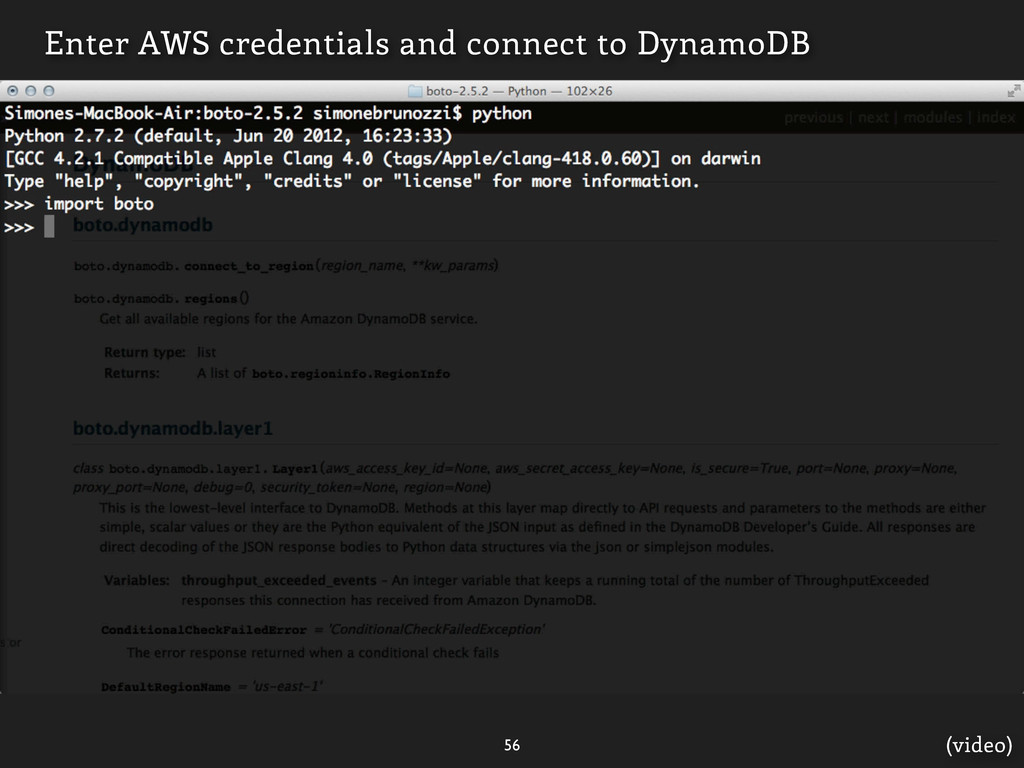
![Table We are going to use this schema... ] [](https://files.speakerdeck.com/presentations/9060aa208e950130f883123138195151/slide_111.jpg)
![Table We are going to use this schema... ] [](https://files.speakerdeck.com/presentations/9060aa208e950130f883123138195151/slide_112.jpg)
![Messages ... to create a table, and add items. ]](https://files.speakerdeck.com/presentations/9060aa208e950130f883123138195151/slide_113.jpg)
![Messages ... to create a table, and add items. ]](https://files.speakerdeck.com/presentations/9060aa208e950130f883123138195151/slide_114.jpg)
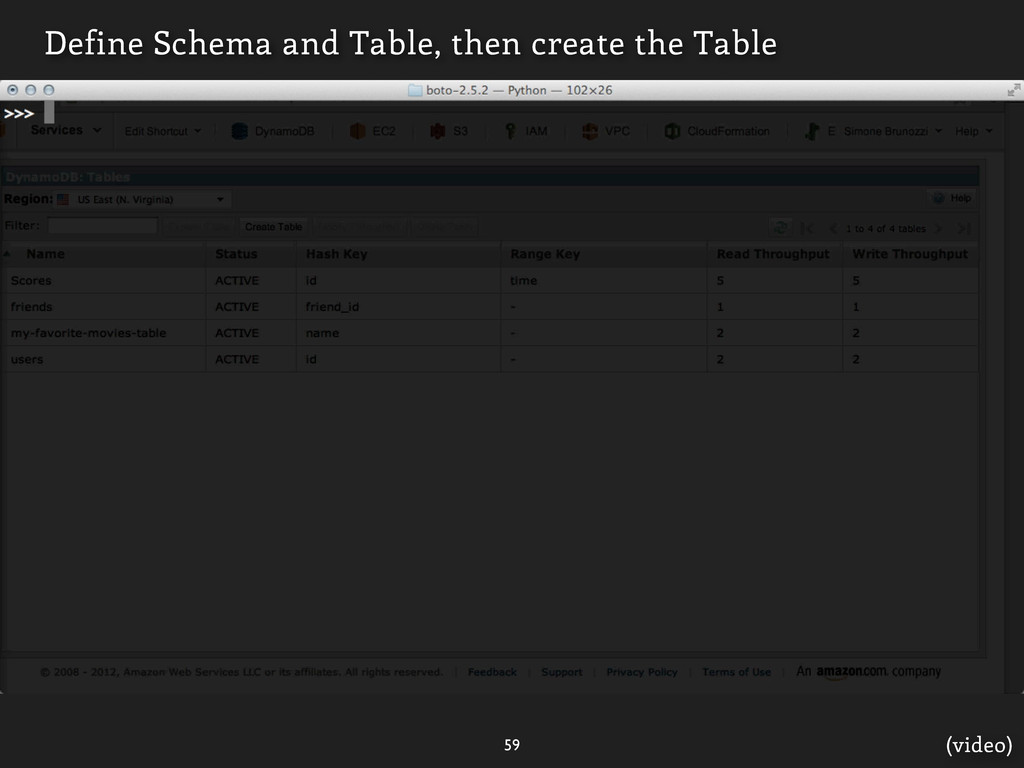
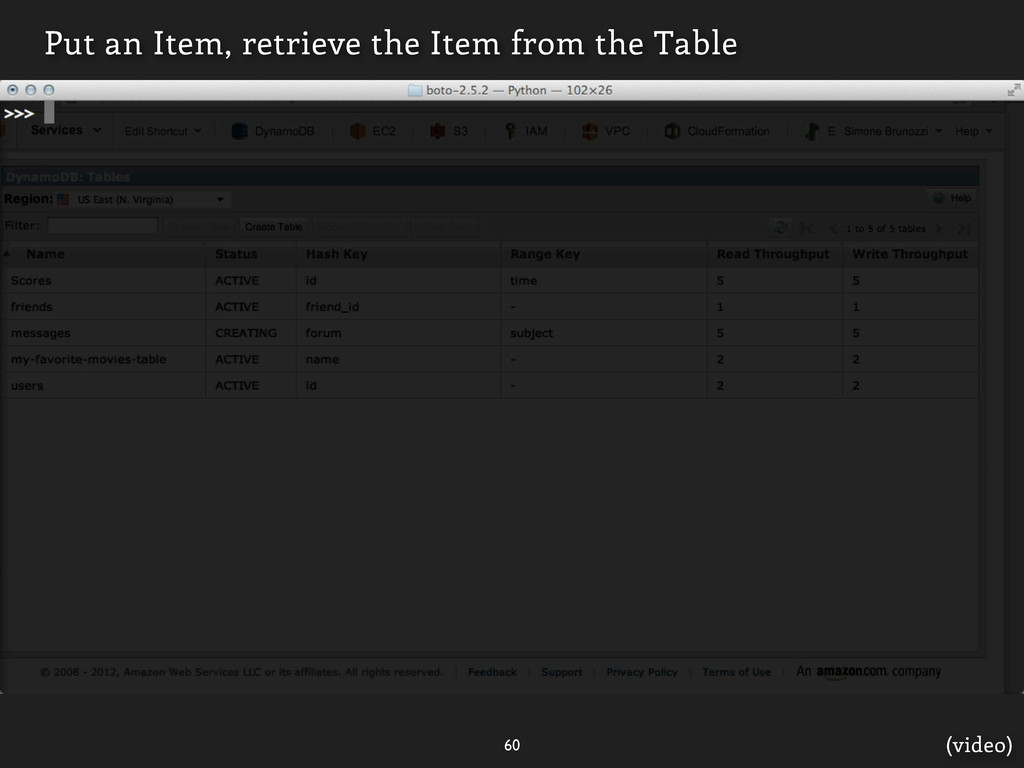
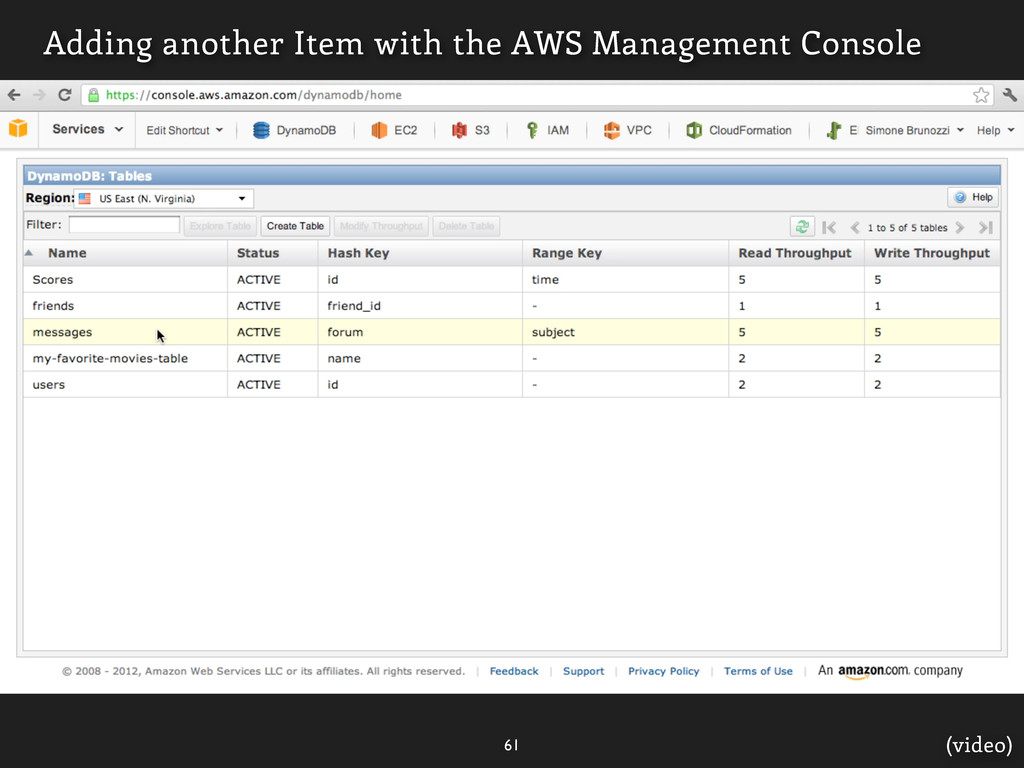
![Ok, I get BOTO. ] [](https://files.speakerdeck.com/presentations/9060aa208e950130f883123138195151/slide_118.jpg)
![Ok, I get BOTO. ] [ Do you want more](https://files.speakerdeck.com/presentations/9060aa208e950130f883123138195151/slide_119.jpg)
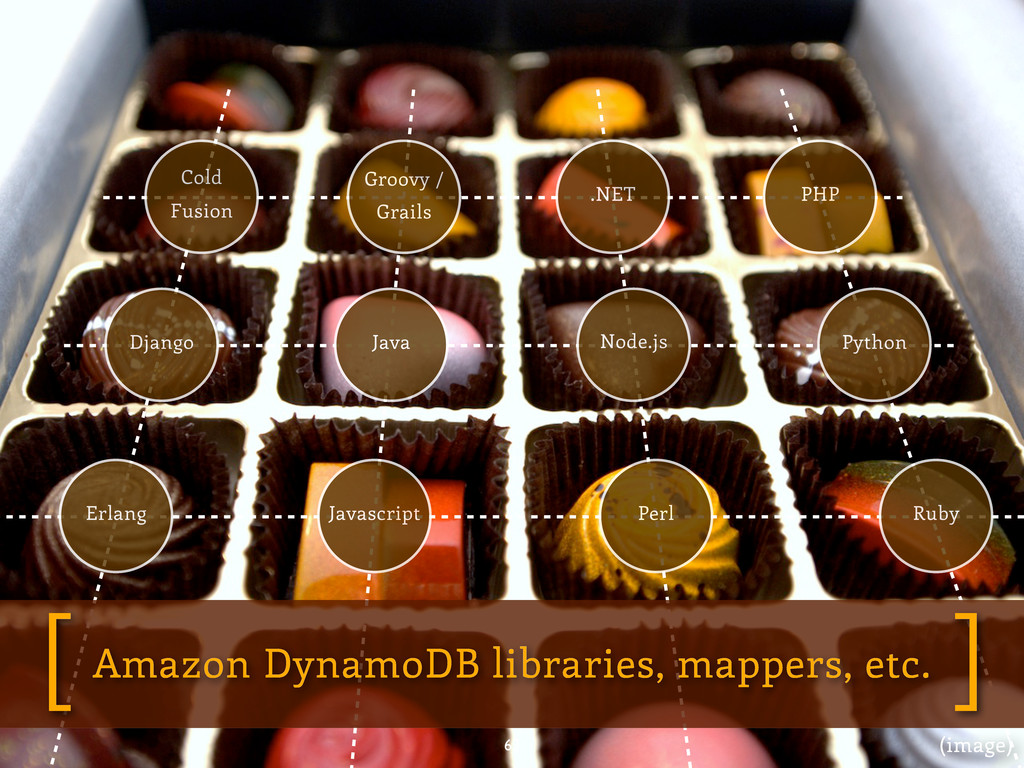
![63 (image) Amazon DynamoDB libraries, mappers, etc. ] [](https://files.speakerdeck.com/presentations/9060aa208e950130f883123138195151/slide_120.jpg)

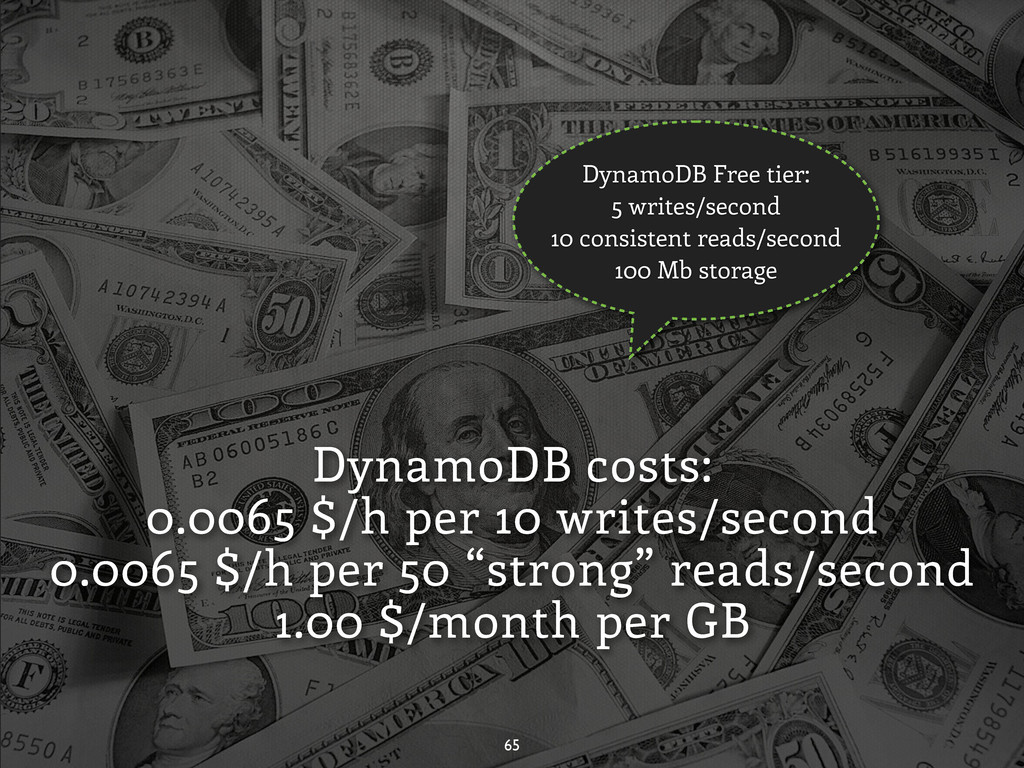
![73 (image) Live repartitioning, no downtime ] [](https://files.speakerdeck.com/presentations/9060aa208e950130f883123138195151/slide_134.jpg)
![Why DynamoDB ] [ • Sorted range keys • Conditional](https://files.speakerdeck.com/presentations/9060aa208e950130f883123138195151/slide_135.jpg)