Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
GSEA-InContext: identifying novel and common pa...
Search
Sponsored
·
Your Podcast. Everywhere. Effortlessly.
Share. Educate. Inspire. Entertain. You do you. We'll handle the rest.
→
Y-h. Taguchi
PRO
August 13, 2018
Science
310
1
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
GSEA-InContext: identifying novel and common patterns in expression experiments
ISMB2018読み会
https://atnd.org/events/98383
でのプレゼンです。
Y-h. Taguchi
PRO
August 13, 2018
More Decks by Y-h. Taguchi
See All by Y-h. Taguchi
Tensor decomposition-based unsupervised feature extraction applied to bioinformatics and affinity with AI-based methodology
tagtag
PRO
0
51
知能とはなにか -ヒトとAIのあいだ-
tagtag
PRO
0
230
サンプル対応のない複数遺伝子発現プロファイルに対するテンソル分解型統合解析の要約
tagtag
PRO
0
270
AI(人工知能)の過去・現在・未来 ~AIは人類を越えるのか~
tagtag
PRO
0
170
presen_司法書士学員会.pdf
tagtag
PRO
1
120
生成AIと司法書士の未来.pdf
tagtag
PRO
0
190
データ駆動型ゲノム解析で迫る睡眠研究
tagtag
PRO
0
130
適応テンソル分解と主成分分析に基づく教師なし特徴抽出は、従来手法よりも生物学的に妥当な発現量差のある遺伝子を選択する
tagtag
PRO
0
81
知能とはなにか -ヒトとAIのあいだ-
tagtag
PRO
0
120
Other Decks in Science
See All in Science
ゲームと人工知能
miyayou
0
260
[Webinaire presse] Sécheresse 2026 : quelles conséquences techniques en élevage de ruminants et quels leviers d'action ?
institutdelelevage
PRO
0
300
データベース09: 実体関連モデル上の一貫性制約
trycycle
PRO
0
1.9k
バランスって大事だね
akasan
1
160
[Relay webinaire eBIS actu n°16] Conclusion
institutdelelevage
PRO
0
210
機械学習 - K-means & 階層的クラスタリング
trycycle
PRO
0
2.3k
因果探索の発展と展望
sshimizu2006
2
1.2k
SAT ソルバーの仕組みと制約ソルバーへの応用
tsoh
3
680
Webinaire : Valorisez les résultats de vos projets européens avec EU-FarmBook
institutdelelevage
PRO
0
180
社内で活躍できるデータサイエンティストになるために
aikinohara
1
180
Kritische evaluatie van GenAI-output voor literatuuronderzoek
voginip
0
250
摂理と合理の肉体改造 — AI時代の減量を支える観測・制御・継続
kiyoshi
0
3.7k
Featured
See All Featured
How to make the Groovebox
asonas
2
2.5k
Product Roadmaps are Hard
iamctodd
55
13k
A Modern Web Designer's Workflow
chriscoyier
699
190k
Chasing Engaging Ingredients in Design
codingconduct
0
360
Visualizing Your Data: Incorporating Mongo into Loggly Infrastructure
mongodb
50
10k
Neural Spatial Audio Processing for Sound Field Analysis and Control
skoyamalab
0
570
The Power of CSS Pseudo Elements
geoffreycrofte
82
6.6k
Agile Actions for Facilitating Distributed Teams - ADO2019
mkilby
0
310
[RailsConf 2023] Rails as a piece of cake
palkan
59
7.1k
Save Time (by Creating Custom Rails Generators)
garrettdimon
PRO
33
5.2k
AI in Enterprises - Java and Open Source to the Rescue
ivargrimstad
0
1.5k
The agentic SEO stack - context over prompts
schlessera
0
970
Transcript
ISMB2018読み会 GSEA-InContext: identifying novel and common patterns in expression experiments
Rani K. Powers, Andrew Goodspeed, Harrison Pielke-Lombardo, Aik-Choon Tan and James C. Costello Bioinformatics, 34, 2018, i555–i564 doi: 10.1093/bioinformatics/bty271 報告者: 中央大学理工学部物理学科 田口善弘
論文の目的: 論文の目的: GSEA(Gene Set Enrichment Analysis)は「遺伝子を『何か(例: 発現差の大きさ)の順番』で並べた場合、順番には意味があ る。ある遺伝子セットAが有意に上位に並ぶなら、そのセットに は『何か』の大きさが有意に大きい遺伝子のセットであるとい えるだろう」
というものですが、その場合「有意に上位に並ぶ」の判定をす るときの比較対象(=帰無仮説)が「完全にランダムな並び」 になっている。しかし、遺伝子はお互いに相関しているんだか ら、『何か』と全く無関係じゃない限り、遺伝子セットAはどっち にしろグループで動く(上位に来る)だろう。そうなると「遺伝 子セットAに意味があるか?」という検証にはなっても「順位 付けした『何か』と関係している」と言えなくないか? この問題は解決するには比較対象を完全にランダムな並び じゃなく、いろいろな実験での並びの集合に置き換えないとい けないのでは?
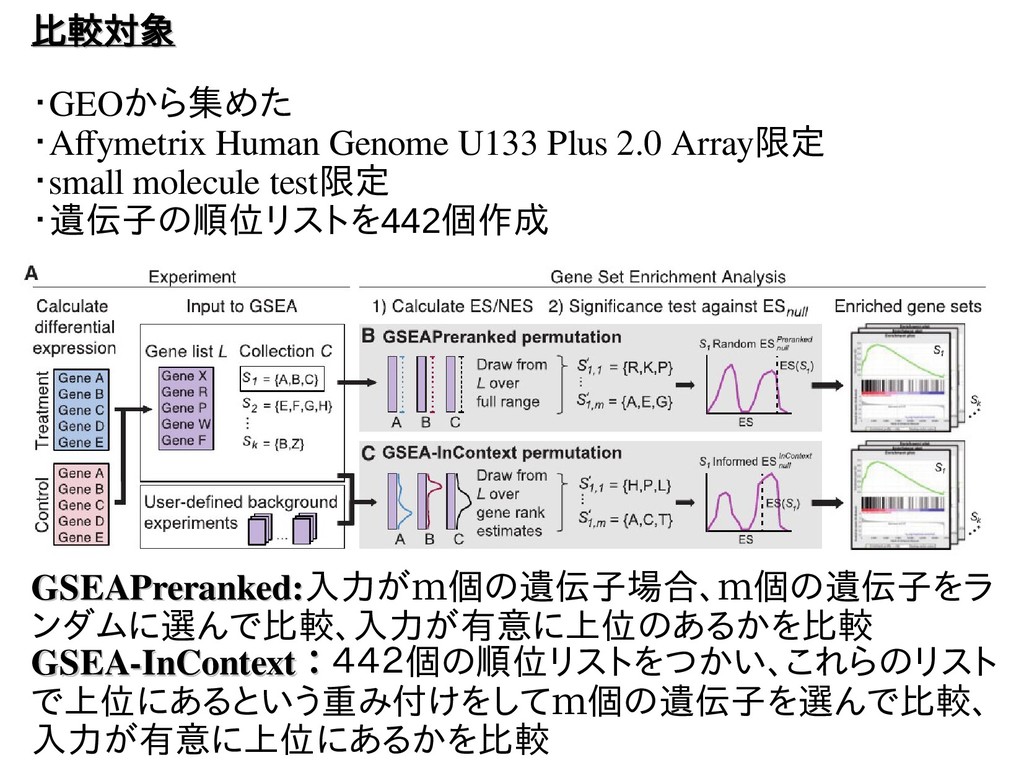
比較対象 比較対象 ・GEOから集めた ・Afymetrix Human Genome U133 Plus 2.0 Array限定
・small molecule test限定 ・遺伝子の順位リストを442個作成 GSEAPreranked: GSEAPreranked:入力がm個の遺伝子場合、m個の遺伝子をラ ンダムに選んで比較、入力が有意に上位のあるかを比較 GSEA-InContext GSEA-InContext: :442個の順位リストをつかい、これらのリスト で上位にあるという重み付けをしてm個の遺伝子を選んで比較、 入力が有意に上位にあるかを比較
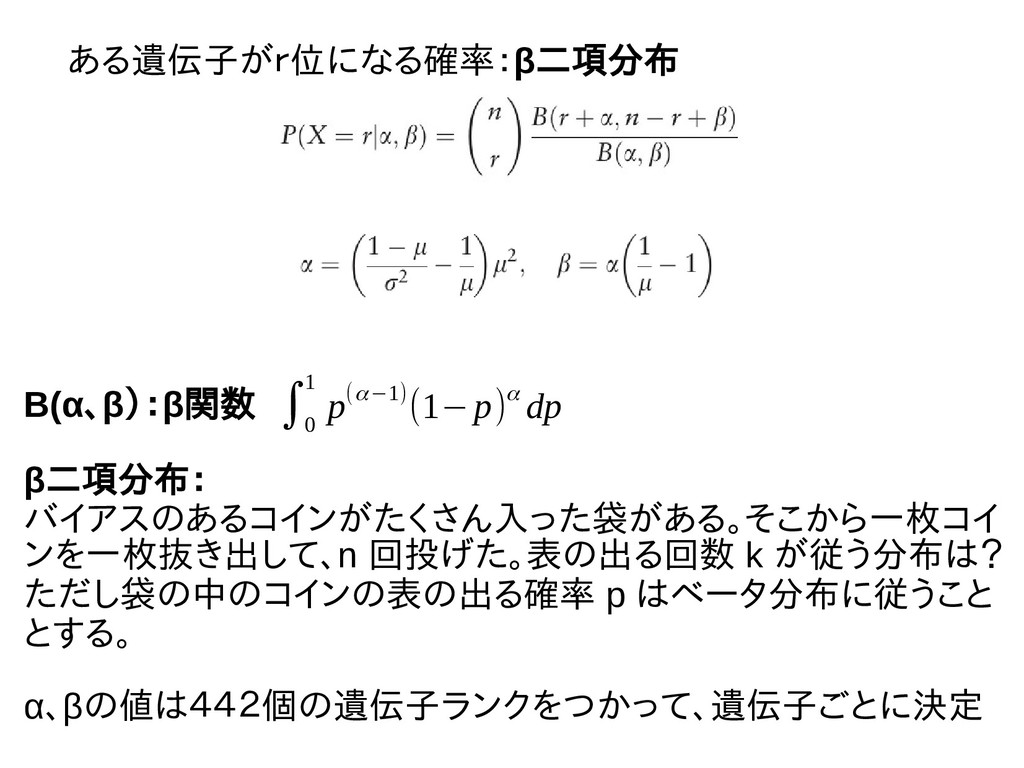
B(α、β):β関数 β二項分布: バイアスのあるコインがたくさん入った袋がある。そこから一枚コイ ンを一枚抜き出して、n 回投げた。表の出る回数 k が従う分布は? ただし袋の中のコインの表の出る確率 p はベータ分布に従うこと
とする。 α、βの値は442個の遺伝子ランクをつかって、遺伝子ごとに決定 ある遺伝子がr位になる確率:β二項分布 ∫0 1 p(α−1)(1−p)α dp
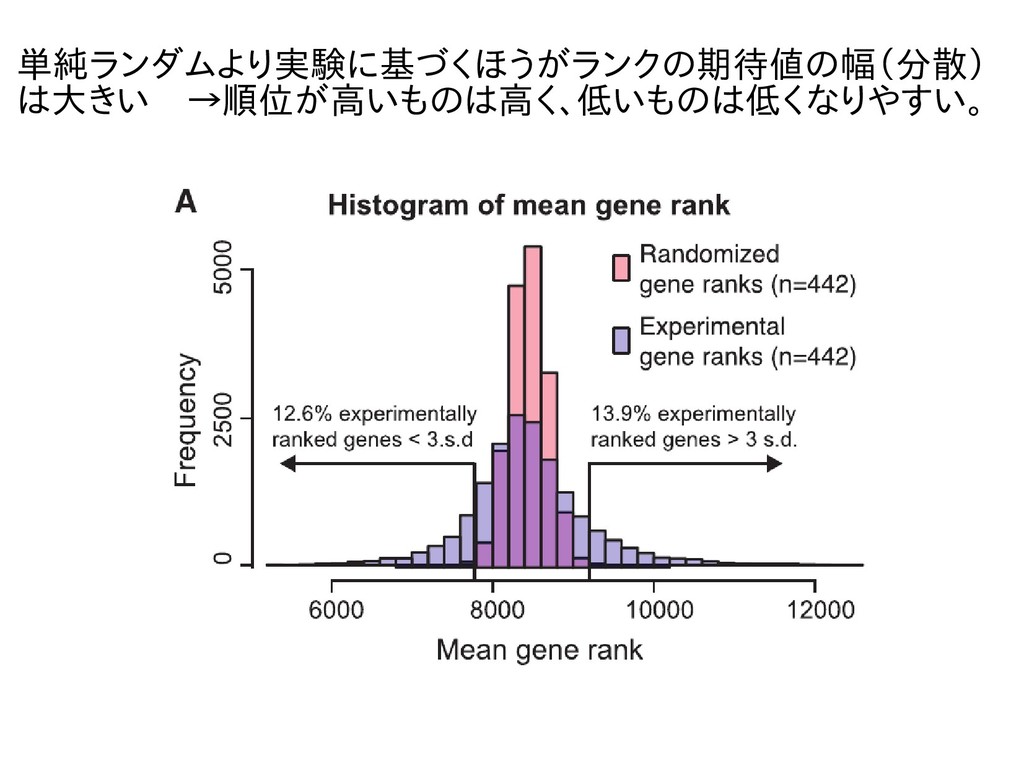
単純ランダムより実験に基づくほうがランクの期待値の幅(分散) は大きい →順位が高いものは高く、低いものは低くなりやすい。
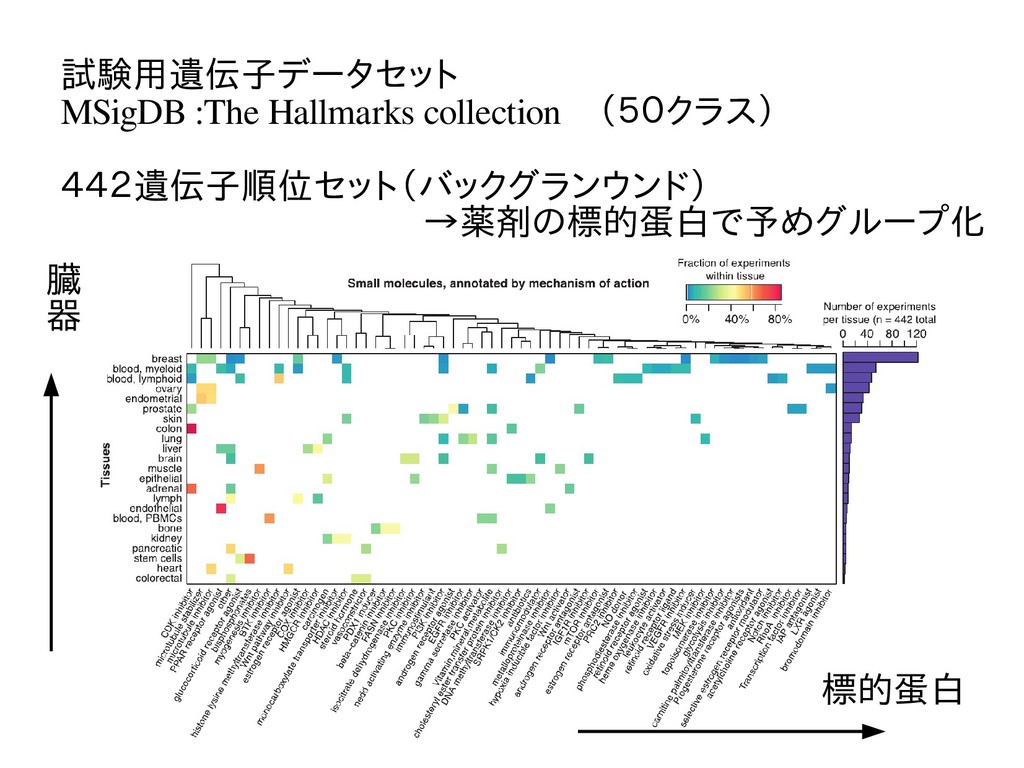
試験用遺伝子データセット MSigDB :The Hallmarks collection (50クラス) 442遺伝子順位セット(バックグランウンド) →薬剤の標的蛋白で予めグループ化 標的蛋白 臓 器
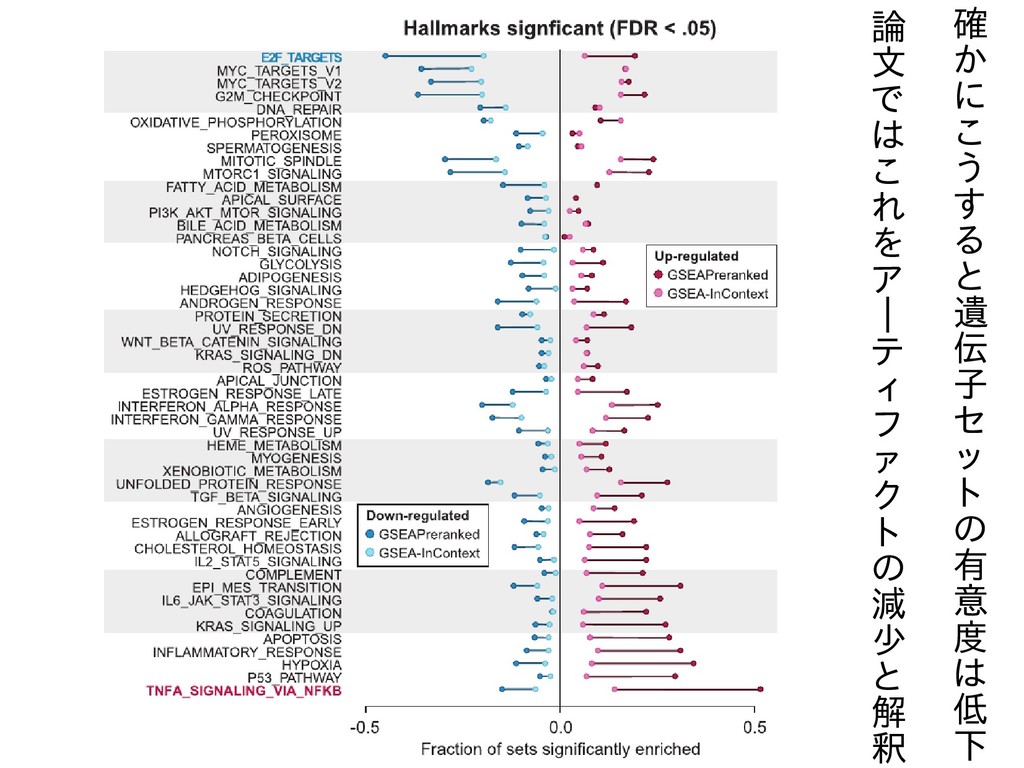
確 か に こ う す る と 遺 伝
子 セ ッ ト の 有 意 度 は 低 下 論 文 で は こ れ を ア | テ ィ フ ァ ク ト の 減 少 と 解 釈
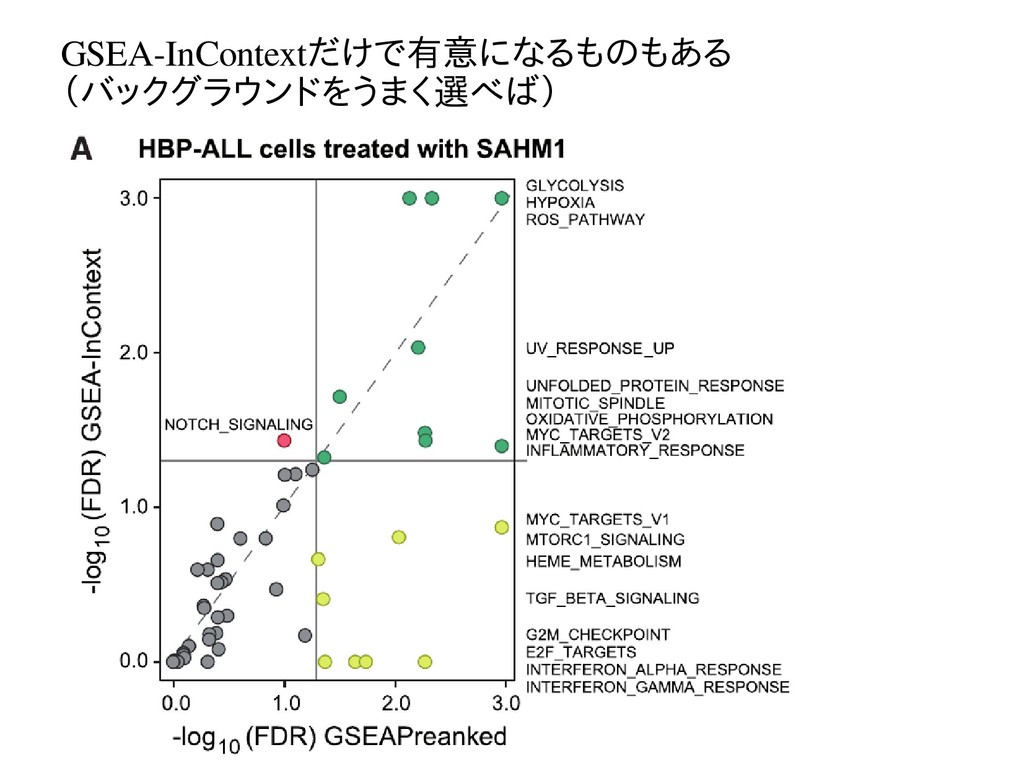
GSEA-InContextだけで有意になるものもある (バックグラウンドをうまく選べば)
なんで なんでISMB ISMB2018に採択されたの? 2018に採択されたの? 正直、何が面白いのか皆目わかりません。 コレポンはgoogle scholarの引用数が4000ある(2007年から論文 を書き始めた)。実験系の論文が多く、ファーストやコレポンは少な い。 多分、最初の論文から10年でgoogle
scholarの引用数を4000くら いにするのがISMBに論文通すコツなのでは? (僕にはもう実現できないハードルですが、過去のことなので)


 tagtag
 miyayou
 institutdelelevage
 trycycle
 akasan
 sshimizu2006
 tsoh
 aikinohara
 voginip
 kiyoshi
 asonas
 iamctodd
 chriscoyier
 codingconduct
 mongodb
 skoyamalab
 geoffreycrofte
 mkilby
 palkan
 garrettdimon
 ivargrimstad
 schlessera