Share
Embed
Container Scheduling Without the Hype: Why Bother?
Tyler L
June 06, 2018
Transcript
20 slides
-
Container Scheduling Without the Hype: Why Bother? DevOpsDays Boise 2018
Tyler Langlois Software Engineer, Elastic -
$ whois tylerjl • Infrastructure/software/devops-y things @ Elastic • Lots
of recent work on dynamic/containerized environments Come talk to me about Arm SBCs (or if you want to yell about the Elastic Puppet modules) ____________________ < angry at computers > -------------------- \ ^__^ \ (oo)\_______ (__)\ )\/\ ||----w | || || -
Who is This For? • Why care about container schedulers?
• What can they offer operations and development? • Real-world achievements made possible by these solutions (or, new ideas for current practitioners) -
Where We’ve Been ??? /var/log/? tcp:localhost:??? statsd? prometheus? graphite? ...
Dependent: • Libraries • Packages • Runtime • Distro • etc. -
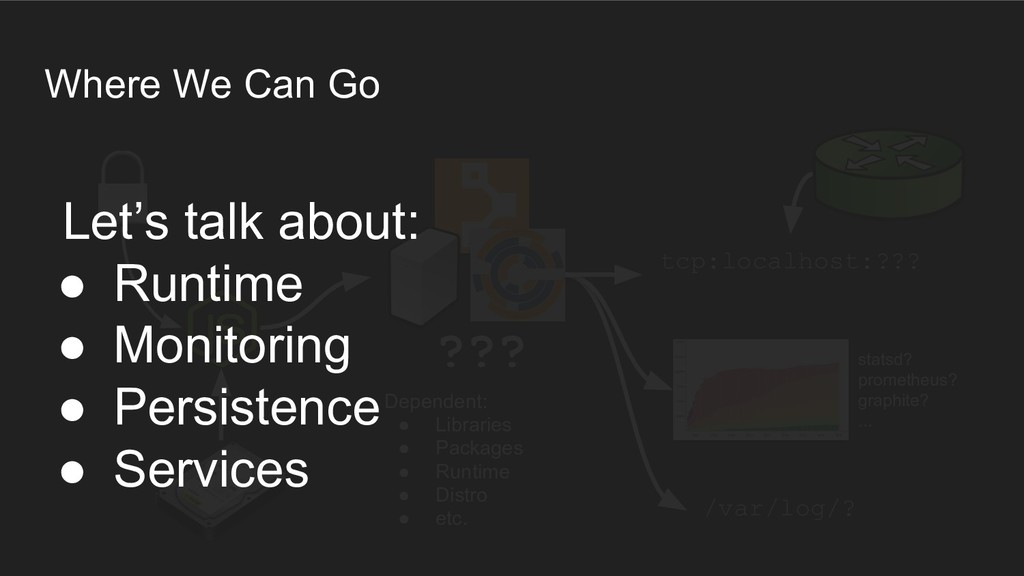
Where We Can Go ??? /var/log/? tcp:localhost:??? statsd? prometheus? graphite?
... Dependent: • Libraries • Packages • Runtime • Distro • etc. Let’s talk about: • Runtime • Monitoring • Persistence • Services -
Runtime (Traditional) • Without containers ◦ Don’t even - dependencies
are separate from code, messy • With just containers ◦ Where are you running them? Cloud instances? ◦ How are you scheduling and running them? -
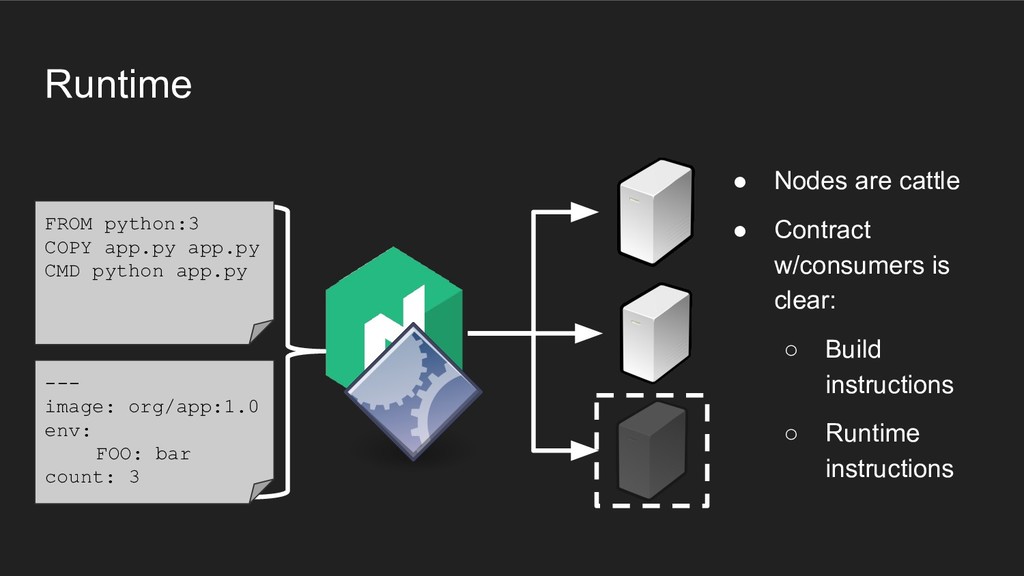
Runtime --- image: org/app:1.0 env: FOO: bar count: 3 •
Nodes are cattle • Contract w/consumers is clear: ◦ Build instructions ◦ Runtime instructions FROM python:3 COPY app.py app.py CMD python app.py -
Runtime --- image: org/app:1.0 env: FOO: bar count: 3 •
Nodes are cattle • Contract w/consumers is clear: ◦ Build instructions ◦ Runtime instructions FROM python:3 COPY app.py app.py CMD python app.py • Deployments are always the same bits - repeatability • Updates are hands-off for both dev and ops - rolling container upgrades • Application changes async from backend (container build instructions) -
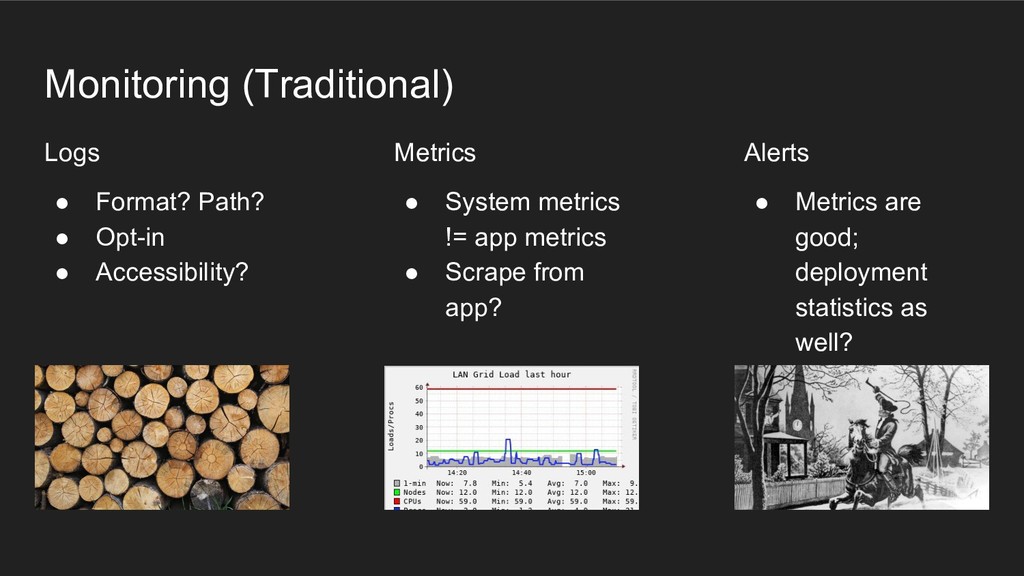
Monitoring (Traditional) Logs • Format? Path? • Opt-in • Accessibility?
Metrics • System metrics != app metrics • Scrape from app? Alerts • Metrics are good; deployment statistics as well? -
Monitoring stdout stderr • Zero-config for generic logs/metrics out of
the box • Easily build custom tools atop this data for out of the box alerting as well • Logs/metrics become self-service with appropriate visualization solutions -
Persistence (Traditional) • Shared mass storage (ceph, gluster) in traditional
setups • Dynamically attached storage in the case of cloud environments (EBS) • Works, but: ◦ What ties them together, provisions them, migrates them, backs up? big ol’ data ? -
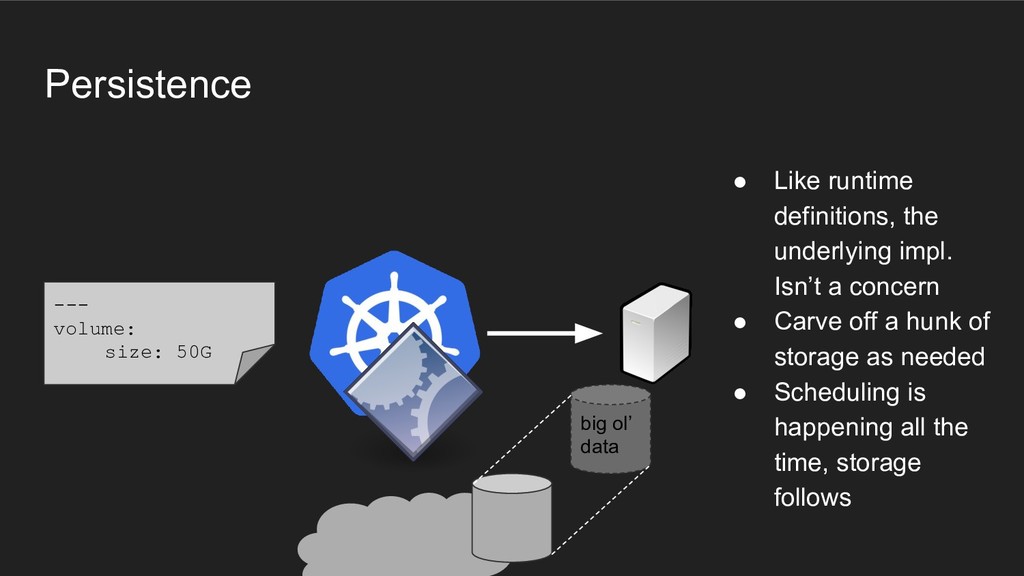
Persistence --- volume: size: 50G • Like runtime definitions, the
underlying impl. Isn’t a concern • Carve off a hunk of storage as needed • Scheduling is happening all the time, storage follows big ol’ data -
Persistence --- volume: size: 50G • Like runtime definitions, the
underlying impl. Isn’t a concern • Carve off a hunk of storage as needed • Scheduling is happening all the time, storage follows big ol’ data • Nobody cares where or what the persistence base is, we just have space now • Infra can develop tools to enhance storage for everyone (automated backups, snapshotting, etc.) • Backend-agnostic - GCP, AWS, Azure, etc. -
Services (Traditional) • Both internal and external: ◦ Spin up
an app, add it to a pool of servers ◦ Health checks sometimes ◦ Typically, the “expose this” process very loosely coupled with “provision this” -
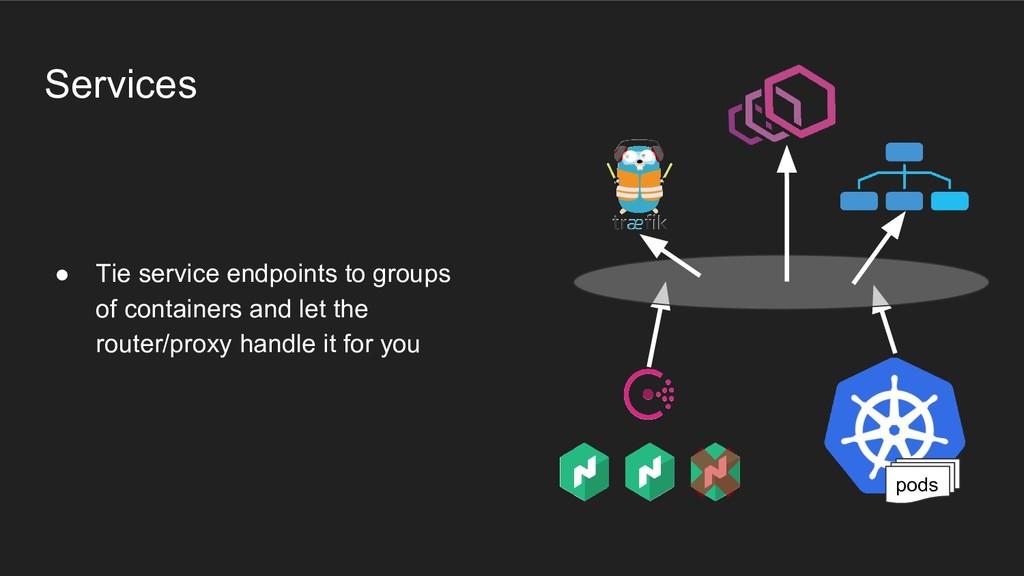
• Tie service endpoints to groups of containers and let
the router/proxy handle it for you Services pods -
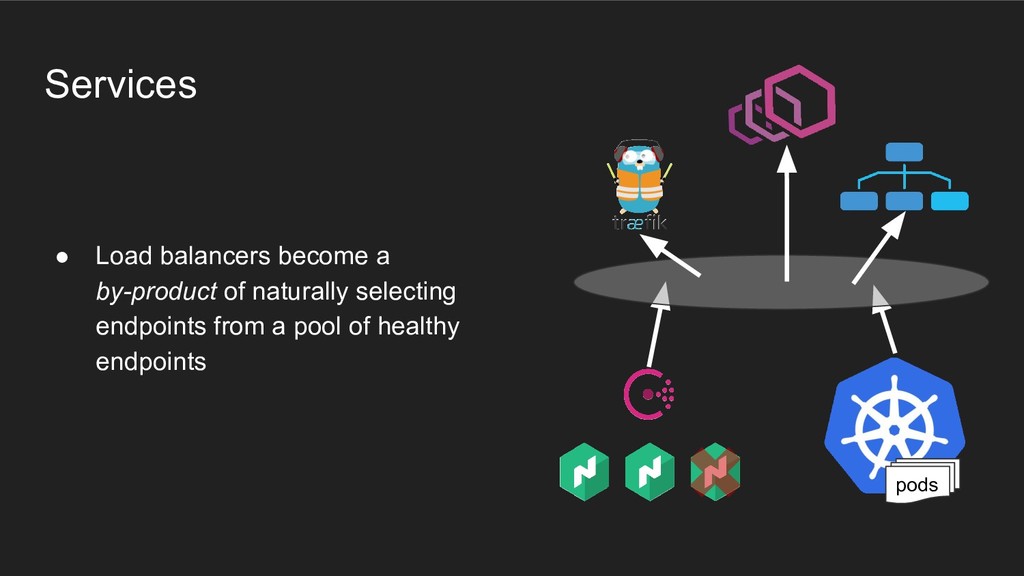
• Load balancers become a by-product of naturally selecting endpoints
from a pool of healthy endpoints Services pods -
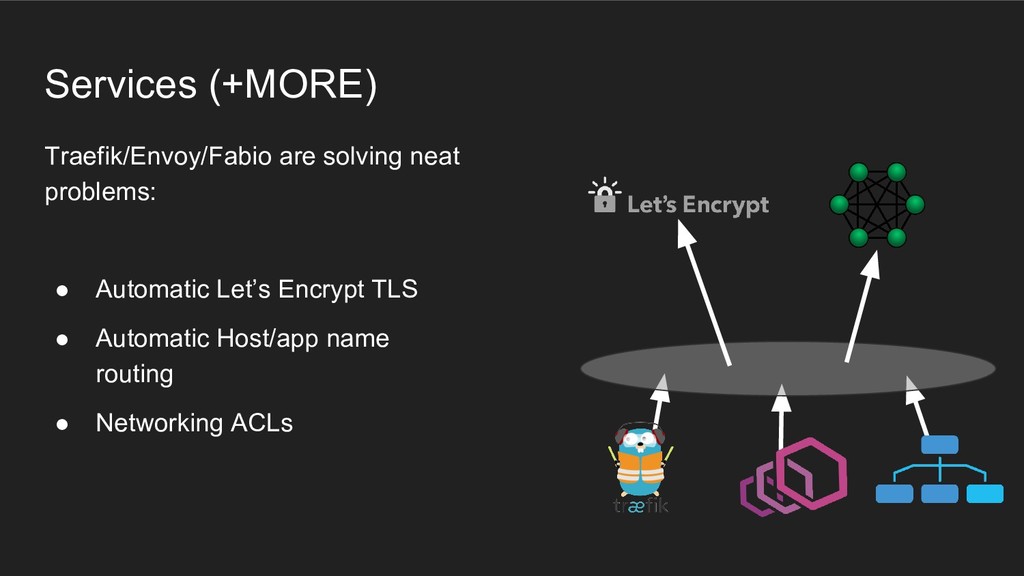
Services (+MORE) Traefik/Envoy/Fabio are solving neat problems: • Automatic Let’s
Encrypt TLS • Automatic Host/app name routing • Networking ACLs -
Better Processes Runtime Monitoring Persistence Services • Contracts are clear
- no one needs to learn another team’s tools if they don’t want to • Improvements and iteration are completely unblocked on either side • Infra tooling becomes immediately useful for everyone on the platform -
Thank you! github.com/tylerjl irc/twitter: leothrix tjll.net Additional Information: • Google
for: ◦ Kubernetes ◦ Nomad ◦ Mesos ◦ Traefik ◦ Envoy Let’s talk about monitoring/metrics at the Elastic booth