Share
Exactly-Once Semantics Revisited: Distributed Transactions across Flink and Kafka
Apache Flink’s Exactly-Once Semantics (EOS) integration for writing to Apache Kafka has several pitfalls, due mostly to the fact that the Kafka transaction protocol was not originally designed with distributed transactions in mind. The integration uses Java reflection hacks as a workaround, and the solution can still result in inconsistencies under certain scenarios. Can we do better?
In this session, you’ll see how the Flink and Kafka communities are uniting to tackle these long-standing technical debts. We’ll introduce the basics of how Flink achieves EOS with external systems and explore the common hurdles that are encountered when implementing distributed transactions. Then we’ll dive into the details of the proposed changes to both the Kafka transaction protocol and Flink transaction coordination that seek to provide a more robust integration.
By the end of the talk, you’ll know the unique challenges of EOS with Flink and Kafka and the improvements you can expect across both projects.
Tzu-Li (Gordon) Tai
Transcript
65 slides
-
Tzu-Li (Gordon) Tai Staff Software Engineer Confluent Exactly-Once Semantics Revisited:
Distributed Transactions across Flink and Kafka Alexander Sorokoumov Staff Software Engineer Confluent -
01 02 03 04 Primer: How Flink achieves EOS Flink’s
KafkaSink: Current state and issues Enter KIP-939: Kafka’s support for 2PC Putting things together with FLIP-319 Agenda 3 -
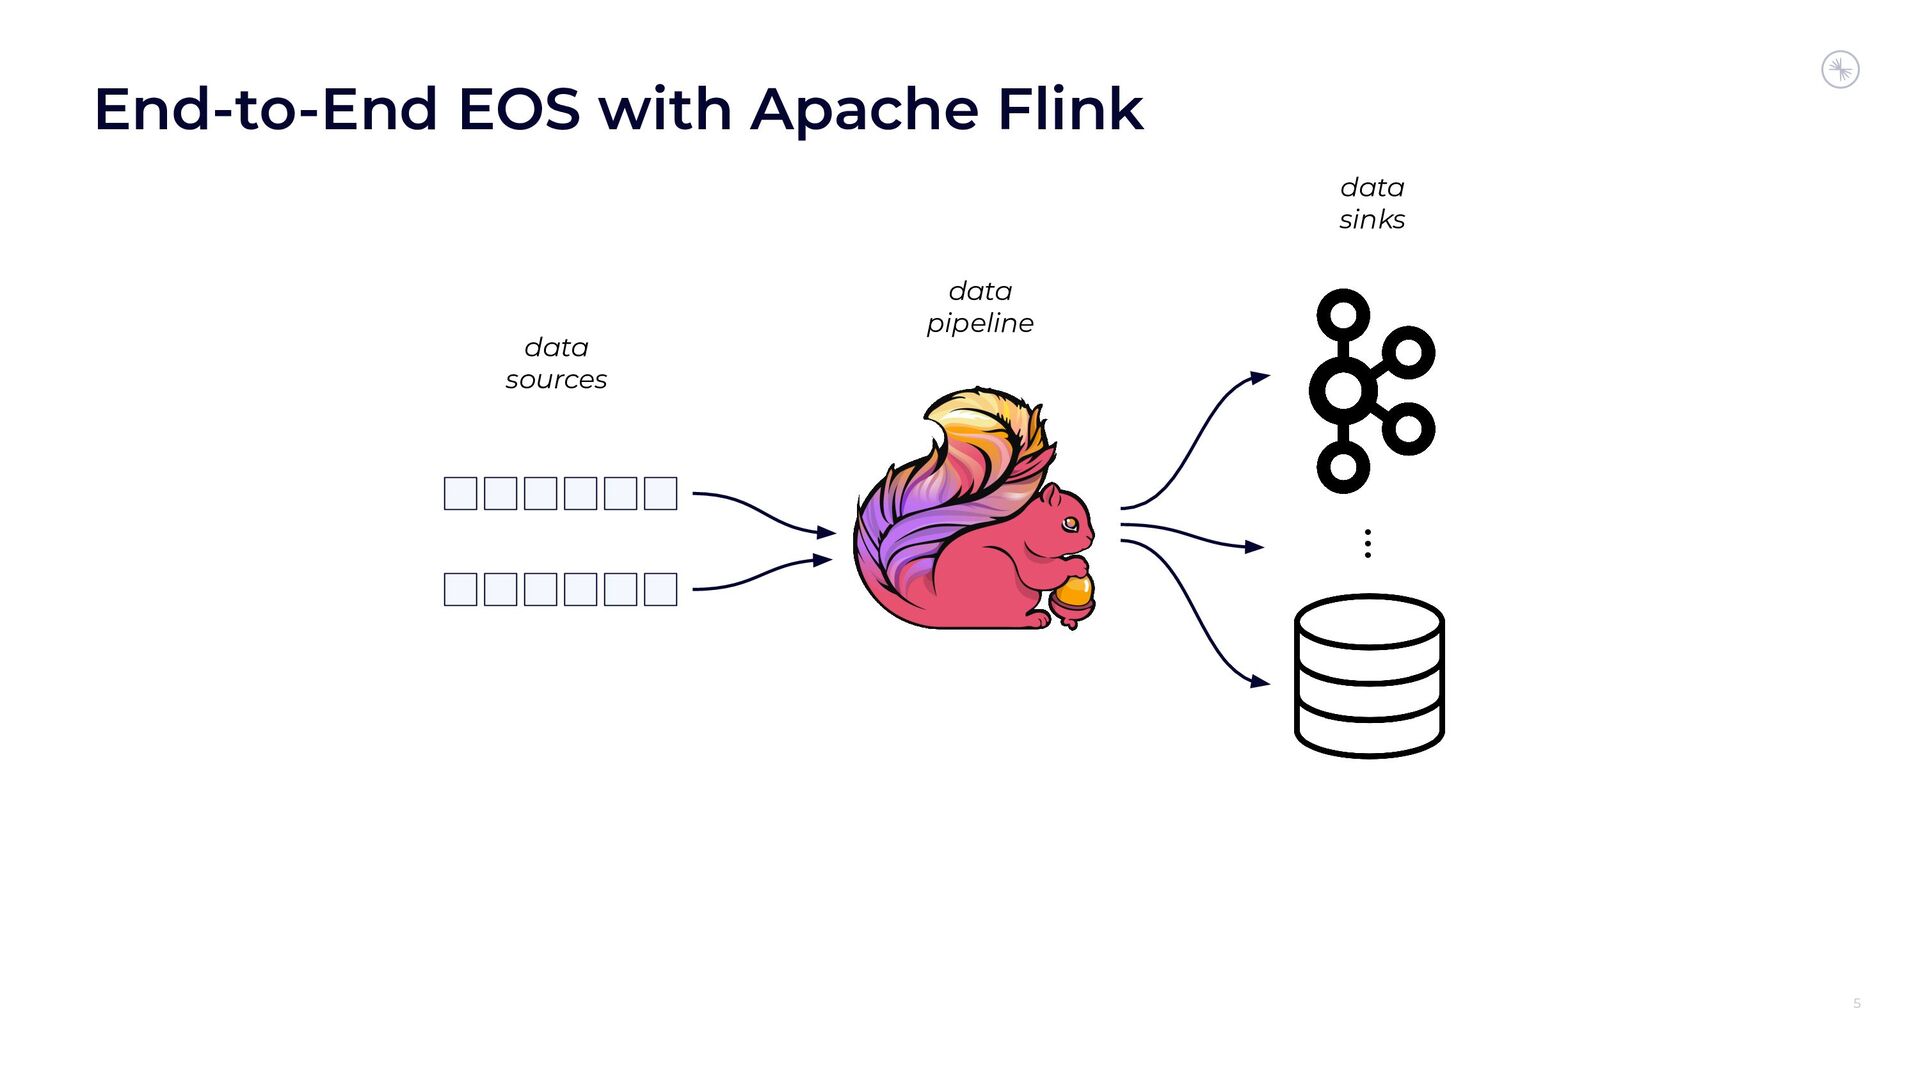
5 End-to-End EOS with Apache Flink … data sources data
pipeline data sinks -
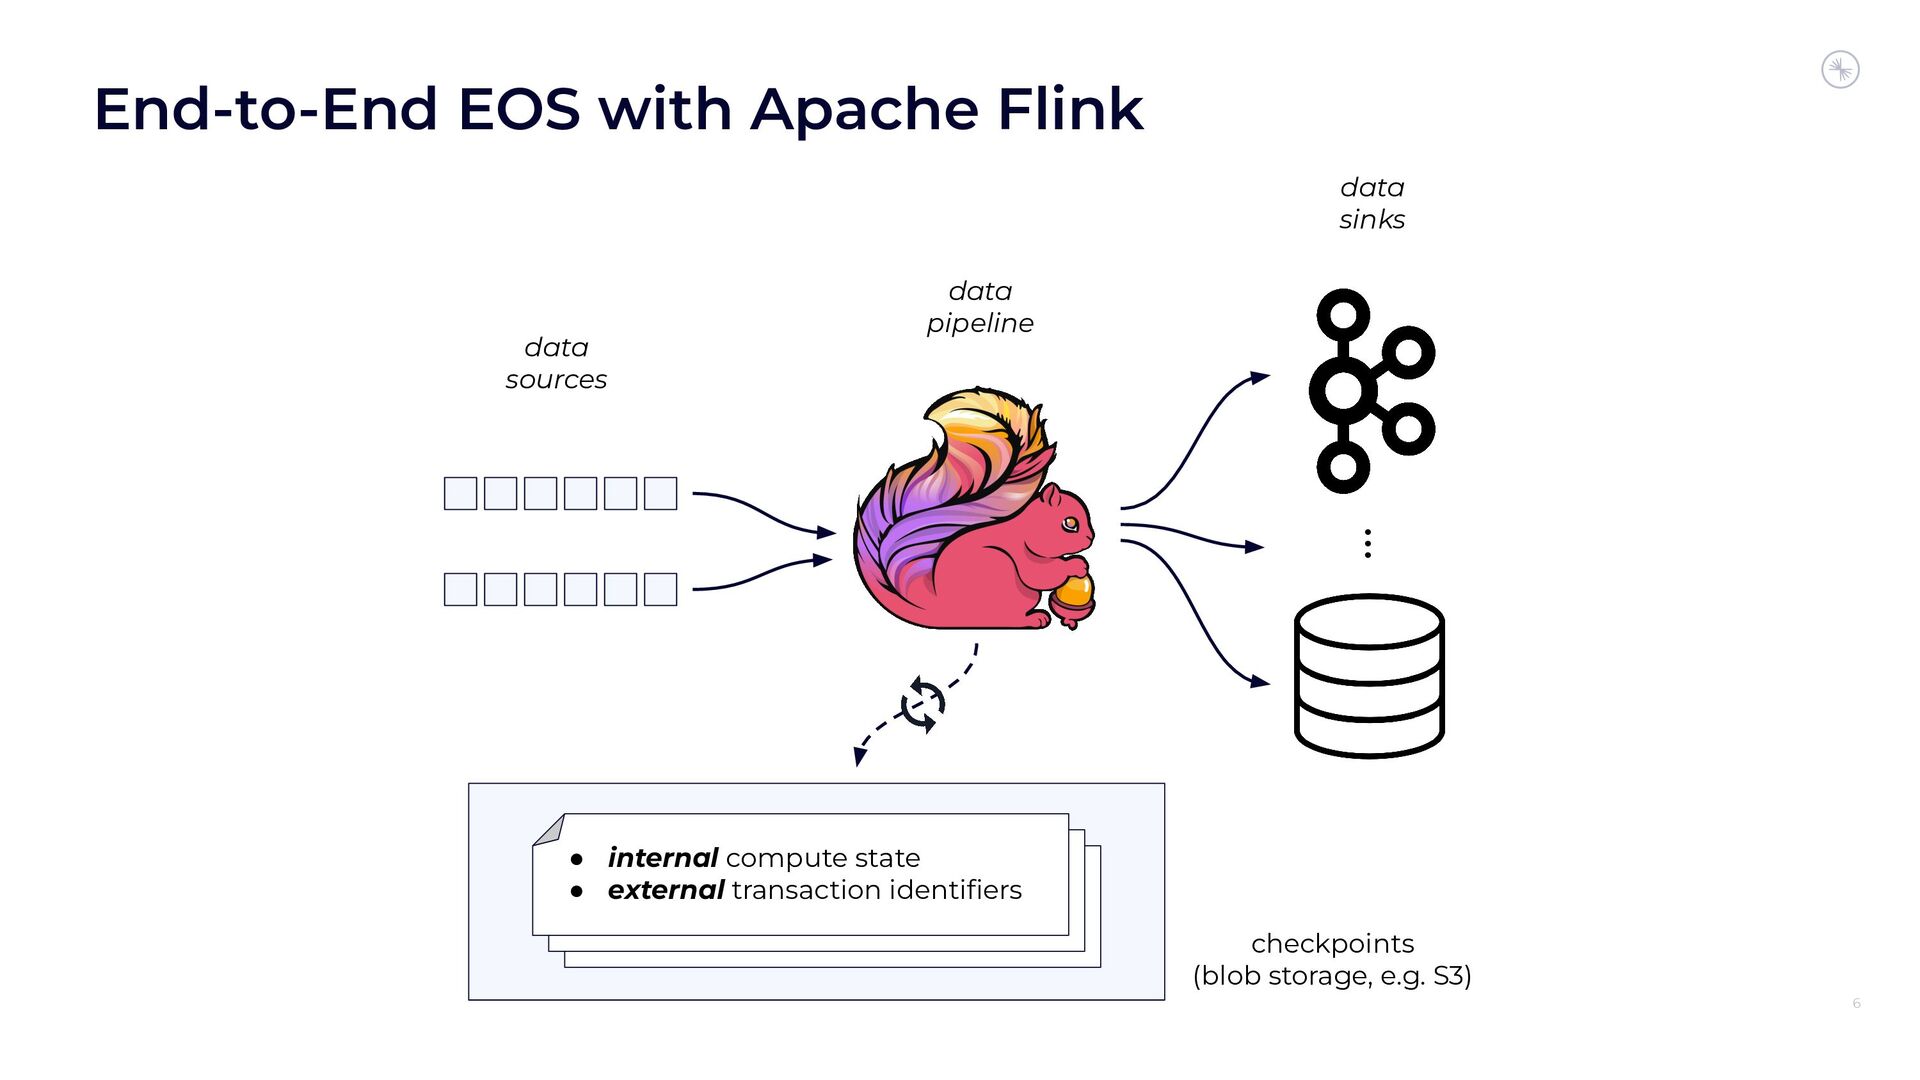
6 End-to-End EOS with Apache Flink … data sources data
pipeline data sinks checkpoints (blob storage, e.g. S3) • internal compute state • external transaction identifiers -
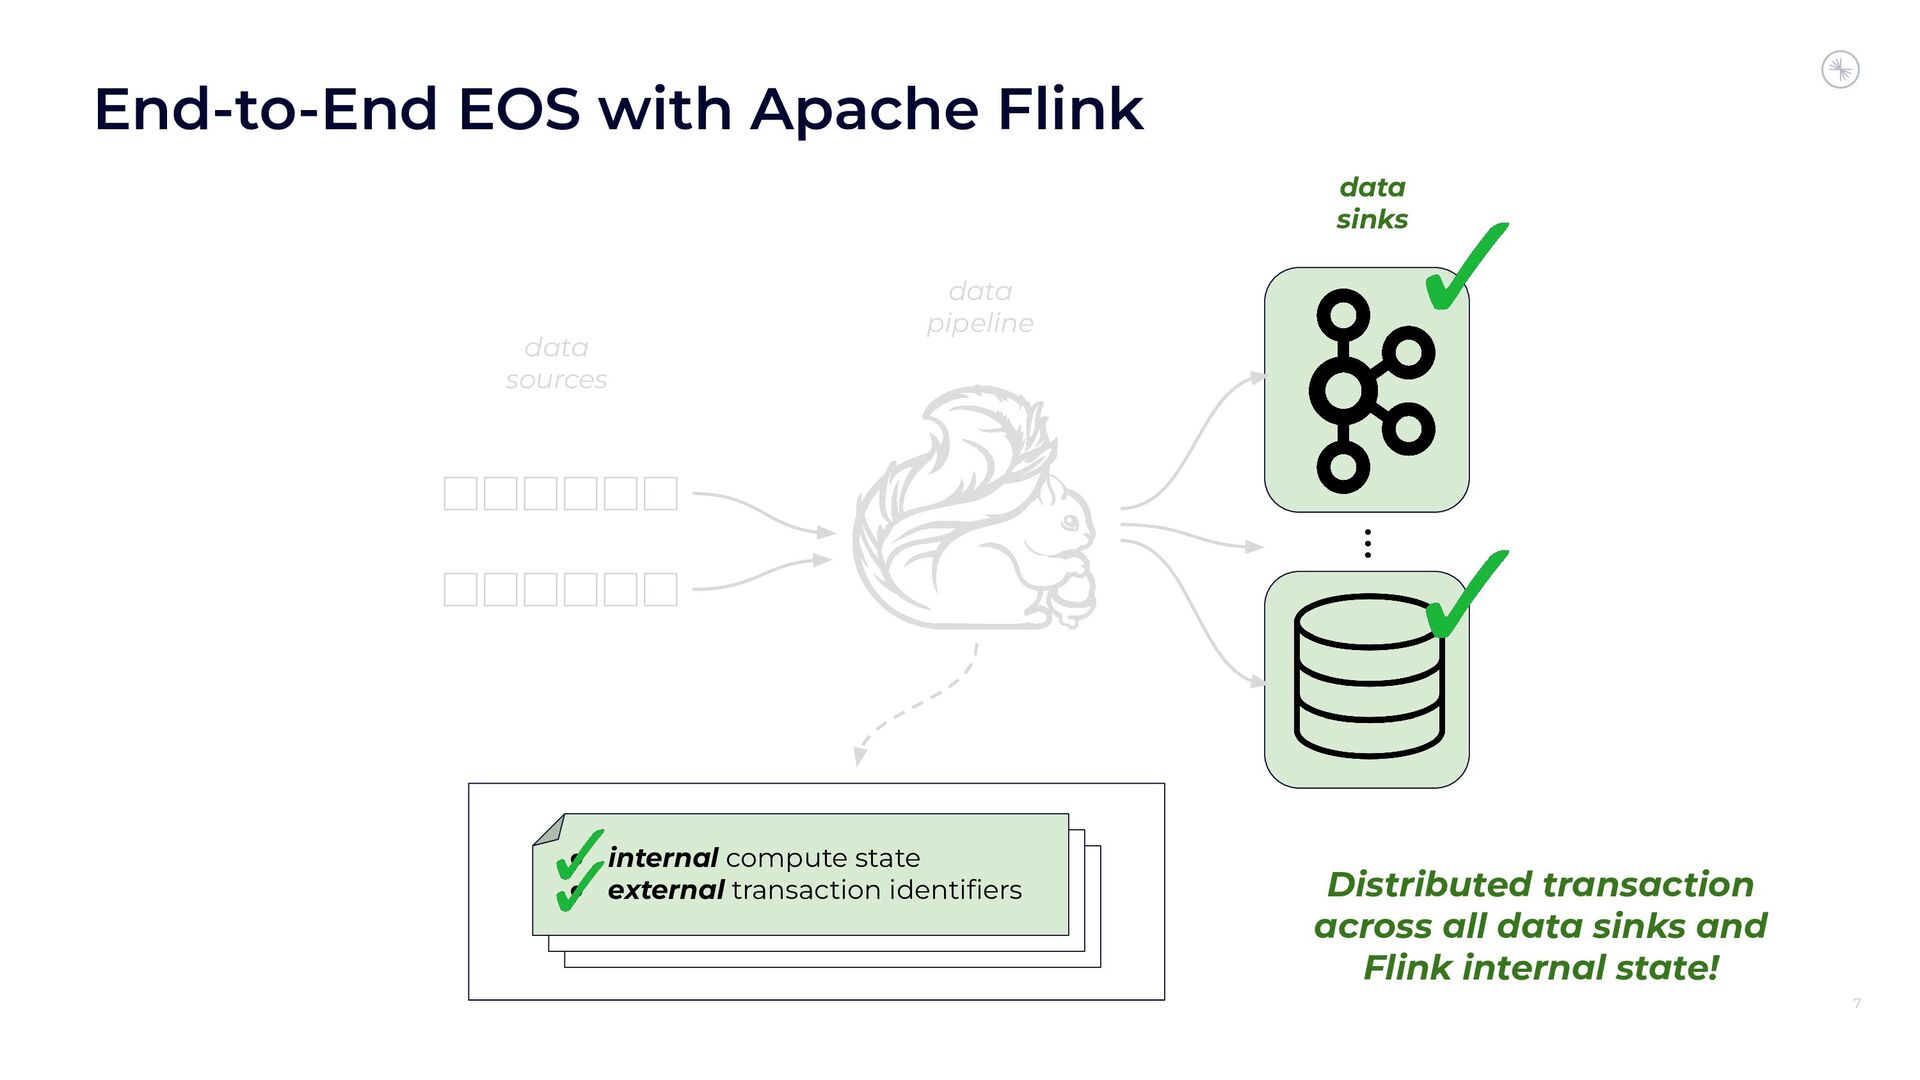
7 End-to-End EOS with Apache Flink … data sources data
pipeline data sinks • internal compute state • external transaction identifiers Distributed transaction across all data sinks and Flink internal state! -
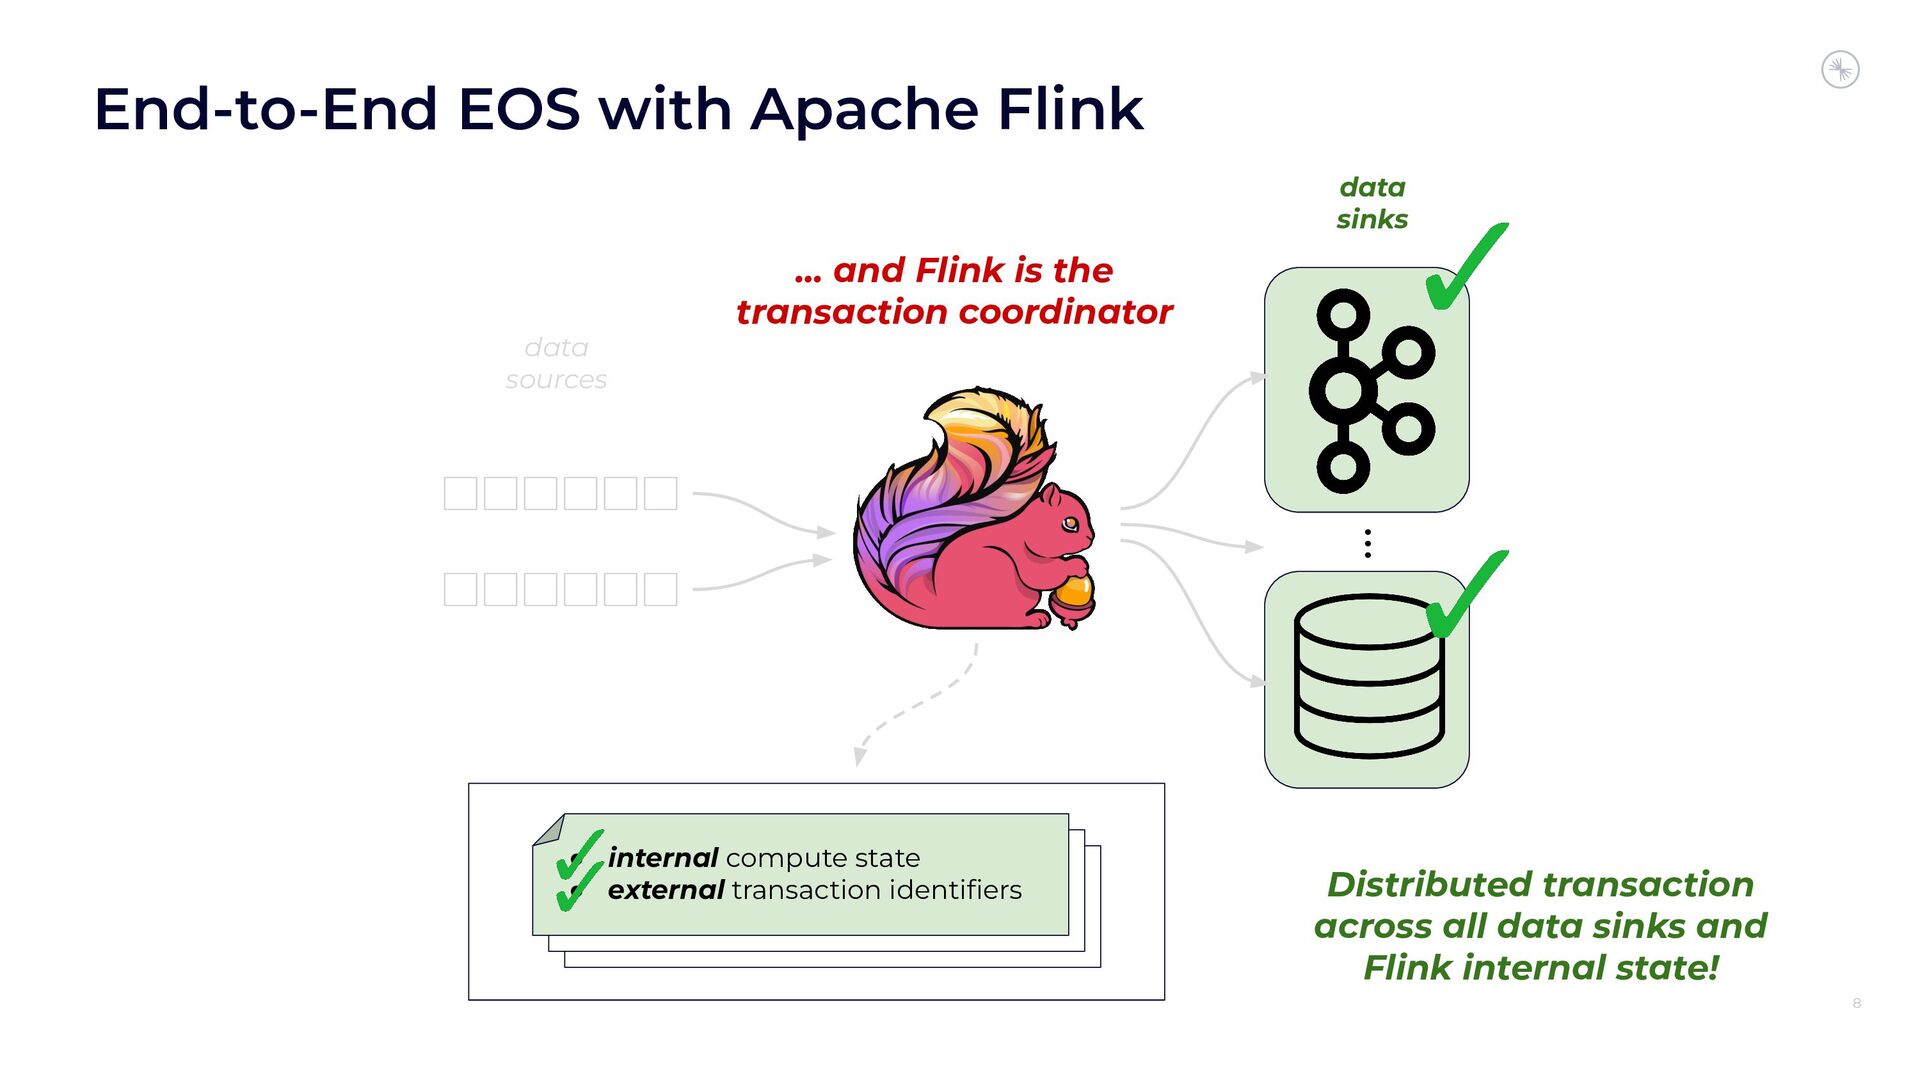
8 End-to-End EOS with Apache Flink … data sources data
sinks • internal compute state • external transaction identifiers Distributed transaction across all data sinks and Flink internal state! … and Flink is the transaction coordinator -
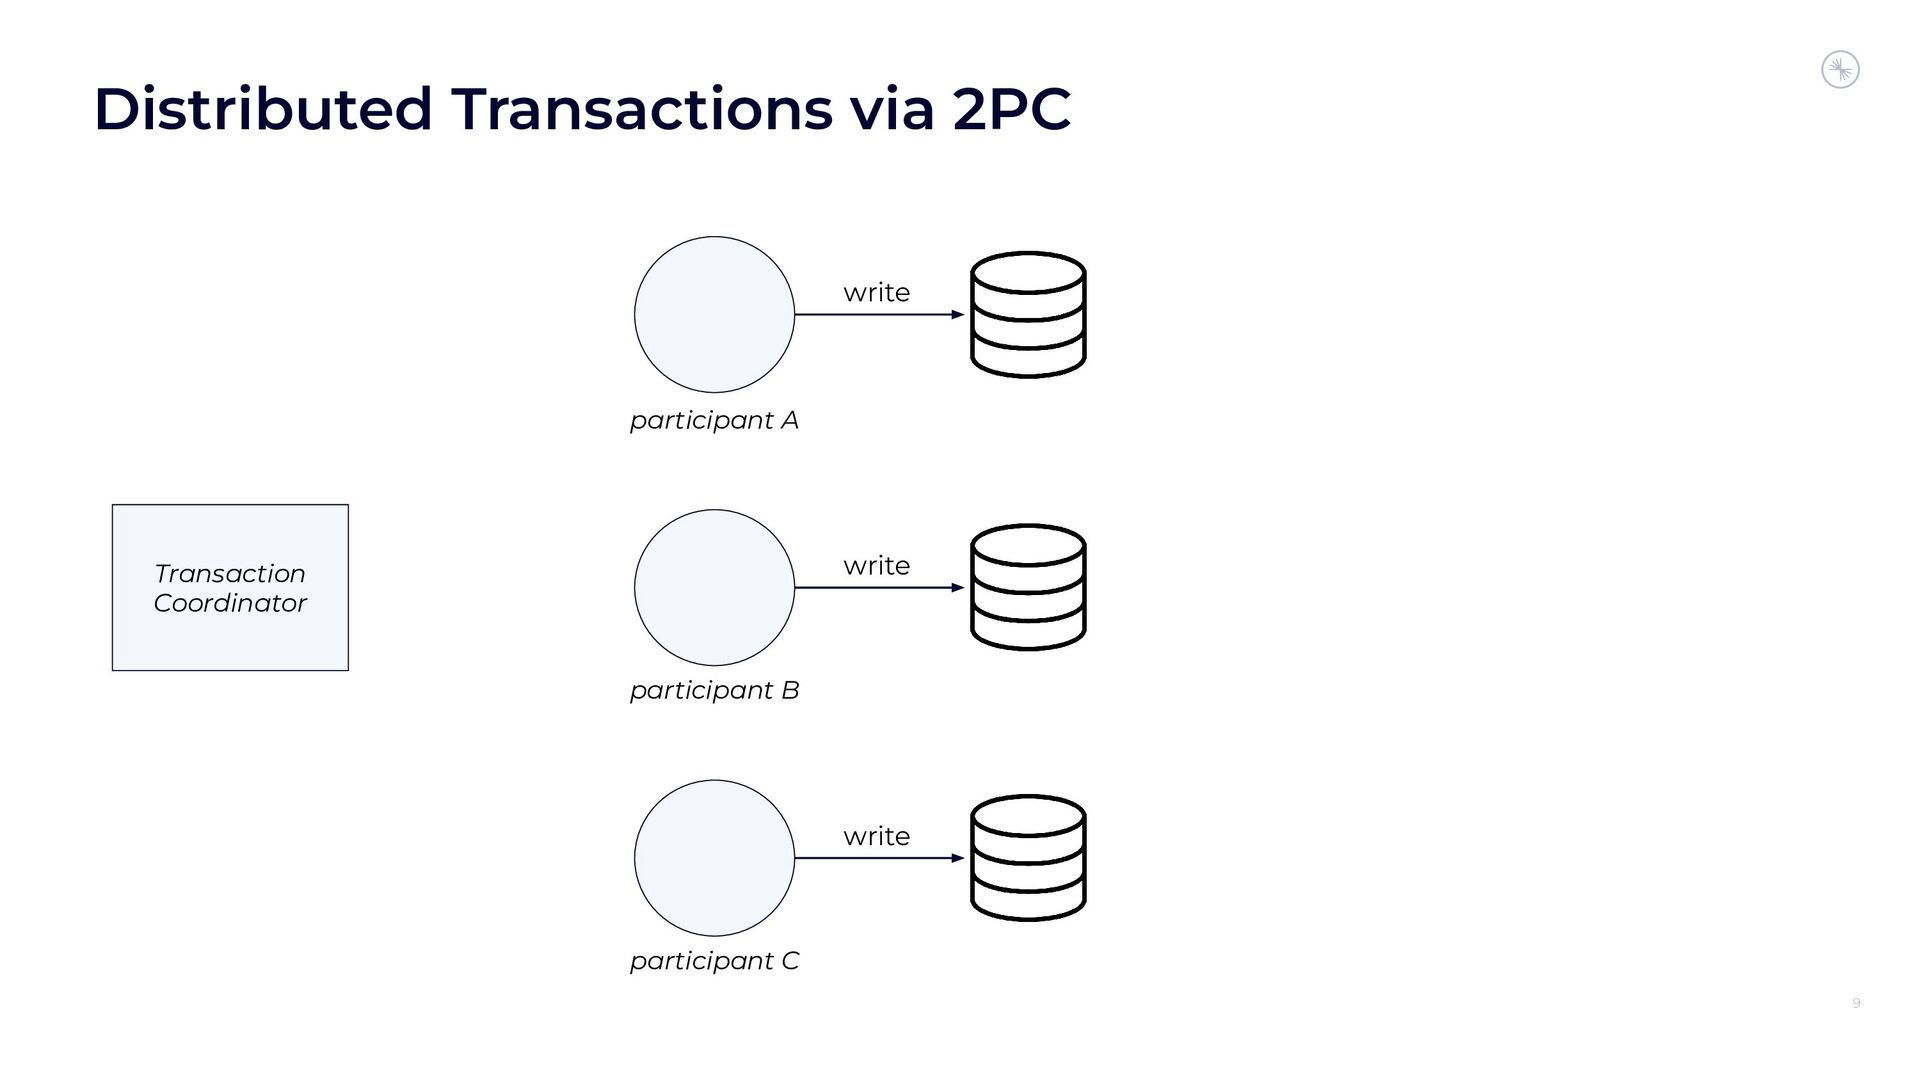
9 Distributed Transactions via 2PC Transaction Coordinator participant A participant
B write write participant C write -
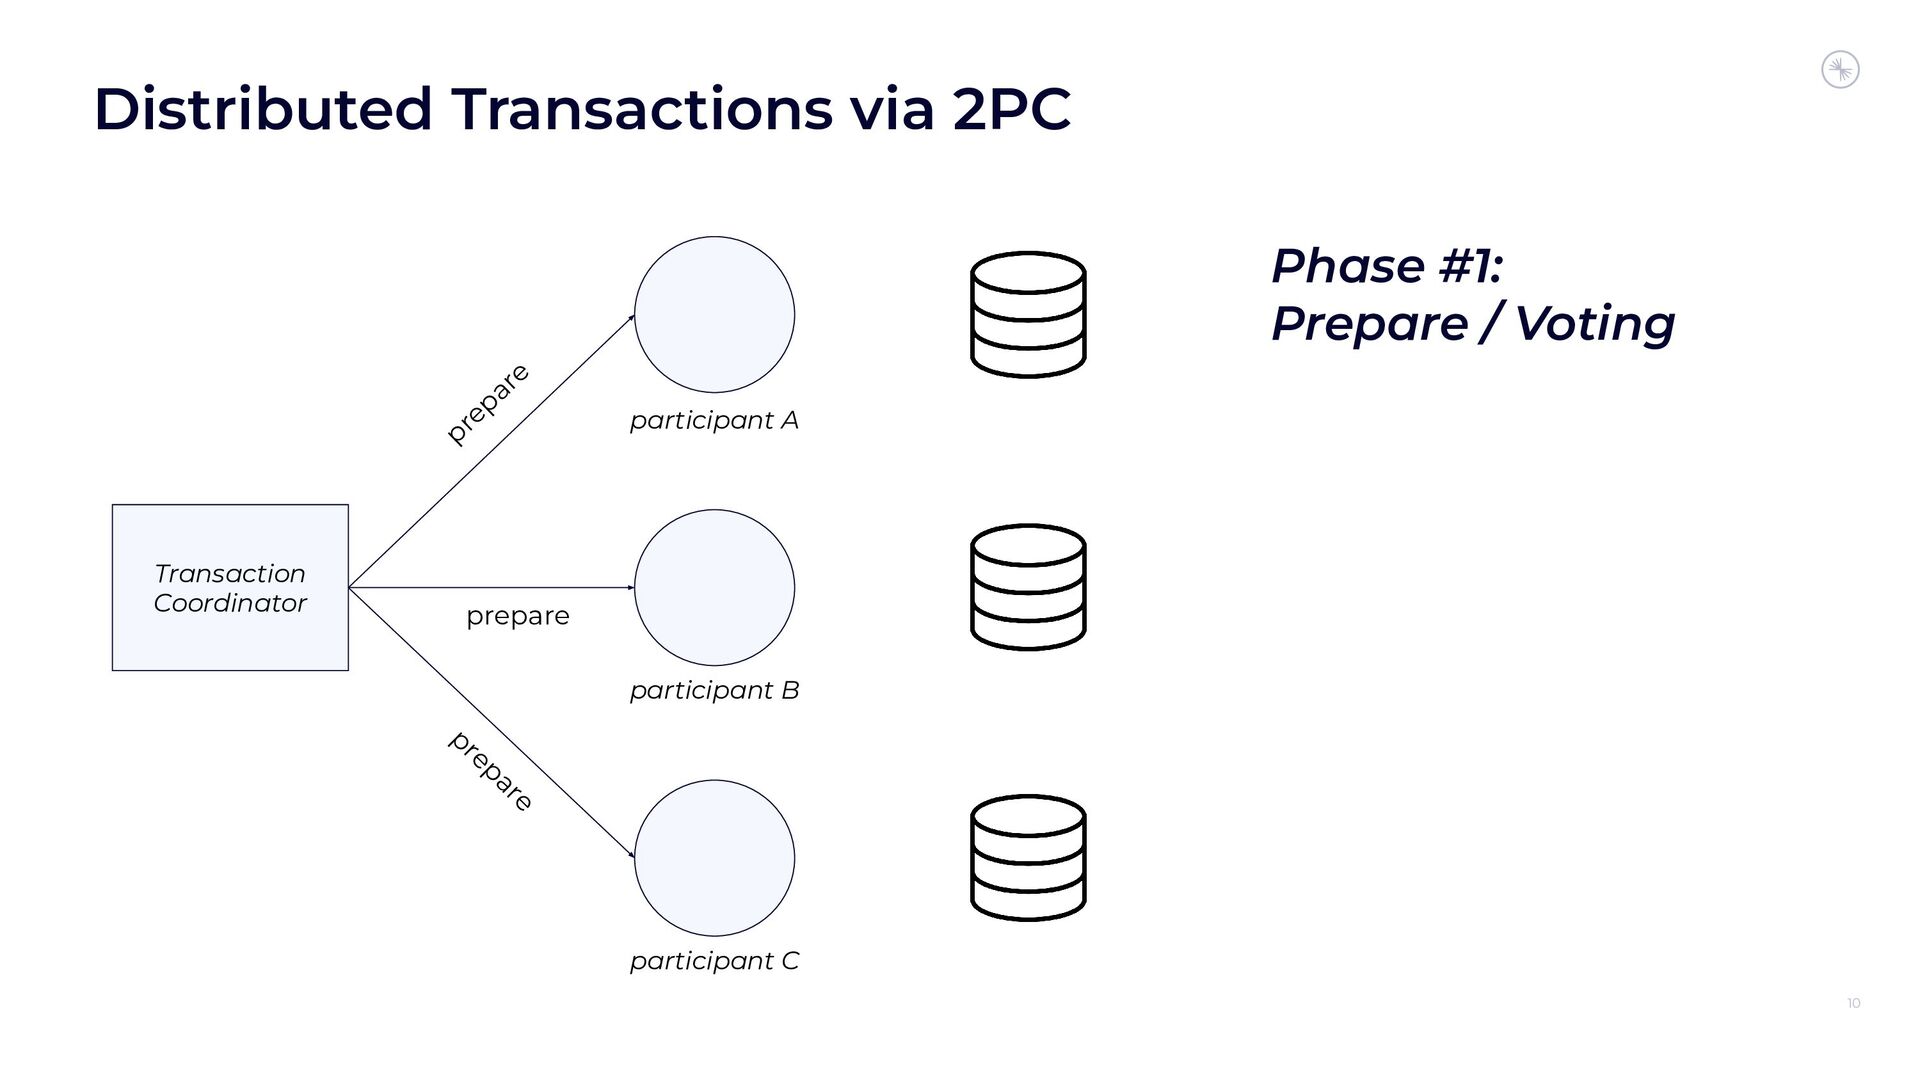
10 Distributed Transactions via 2PC Transaction Coordinator participant A participant
B participant C prepare prepare prepare Phase #1: Prepare / Voting -
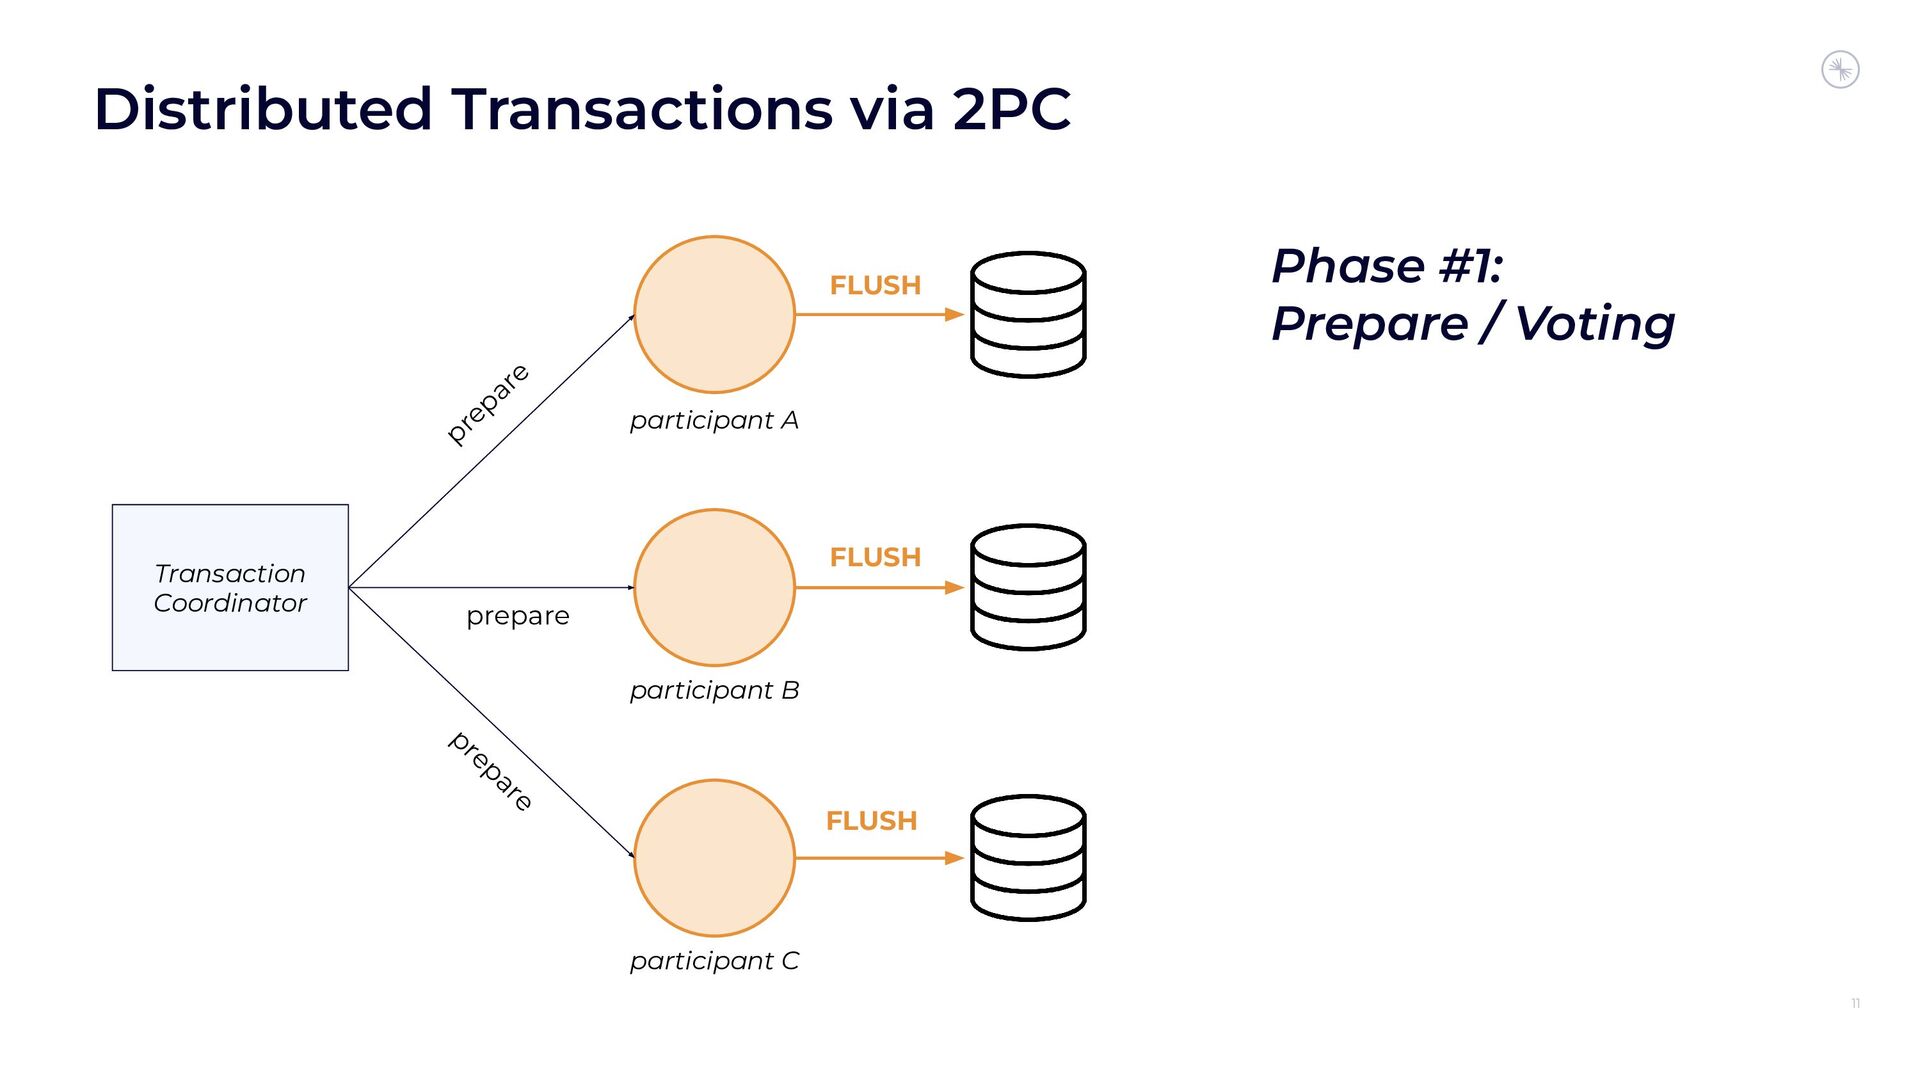
11 Distributed Transactions via 2PC Transaction Coordinator participant A participant
B participant C prepare prepare prepare FLUSH FLUSH FLUSH Phase #1: Prepare / Voting -
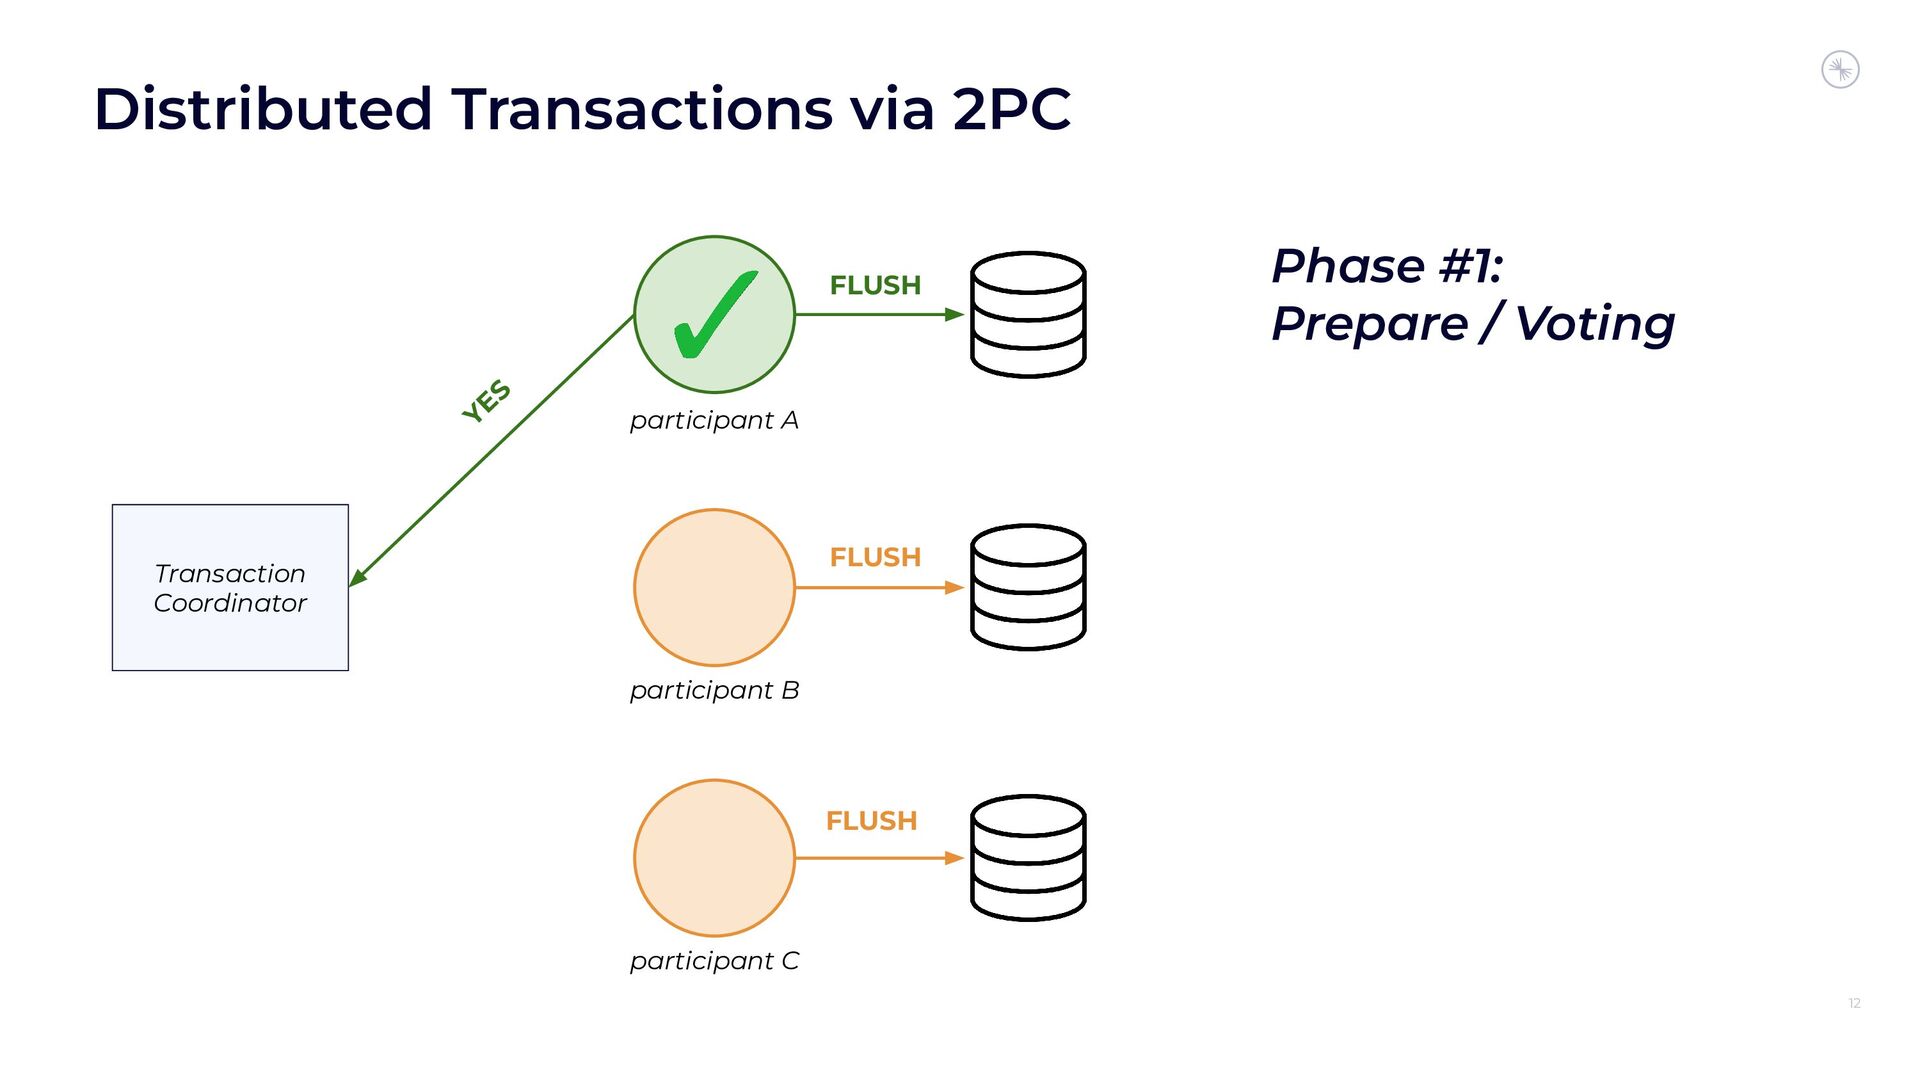
12 Distributed Transactions via 2PC Transaction Coordinator participant A participant
B participant C YES FLUSH FLUSH FLUSH Phase #1: Prepare / Voting -
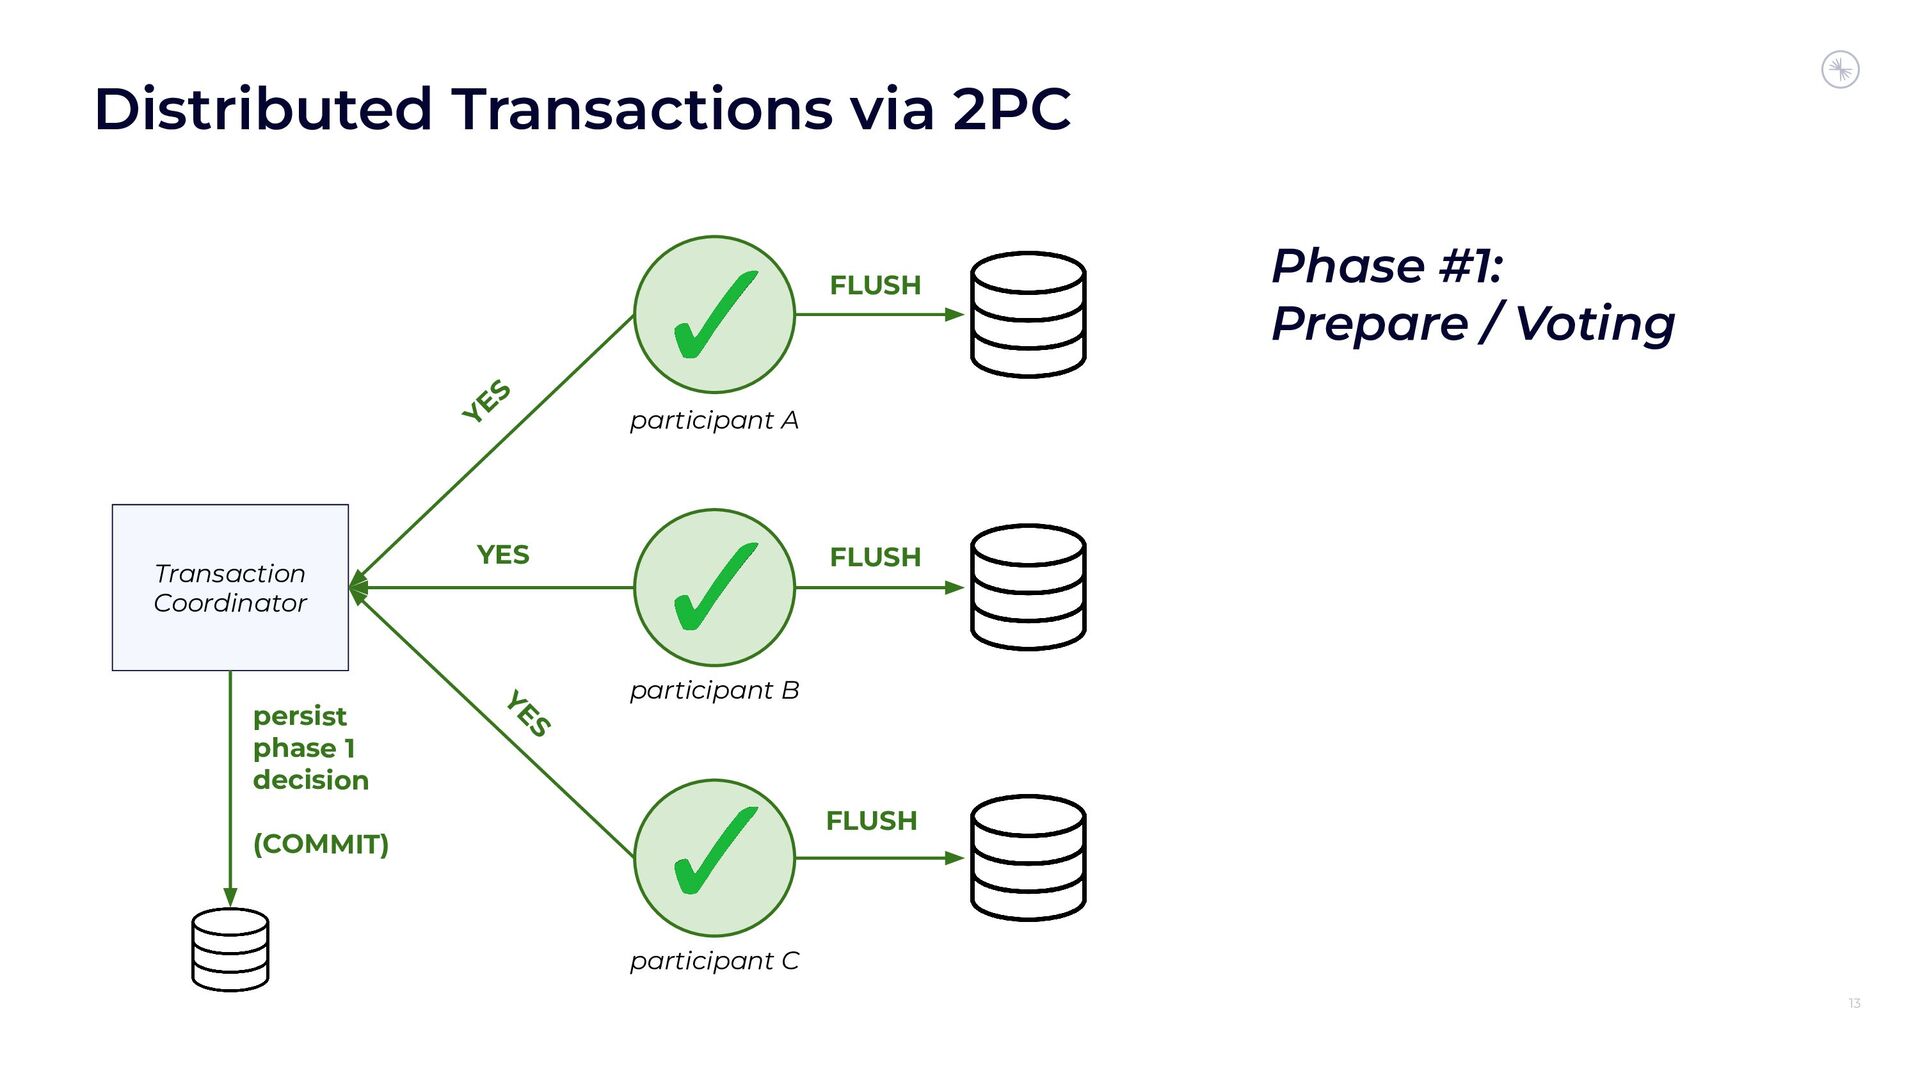
13 Distributed Transactions via 2PC Transaction Coordinator participant A participant
B participant C YES FLUSH FLUSH FLUSH YES YES persist phase 1 decision (COMMIT) Phase #1: Prepare / Voting -
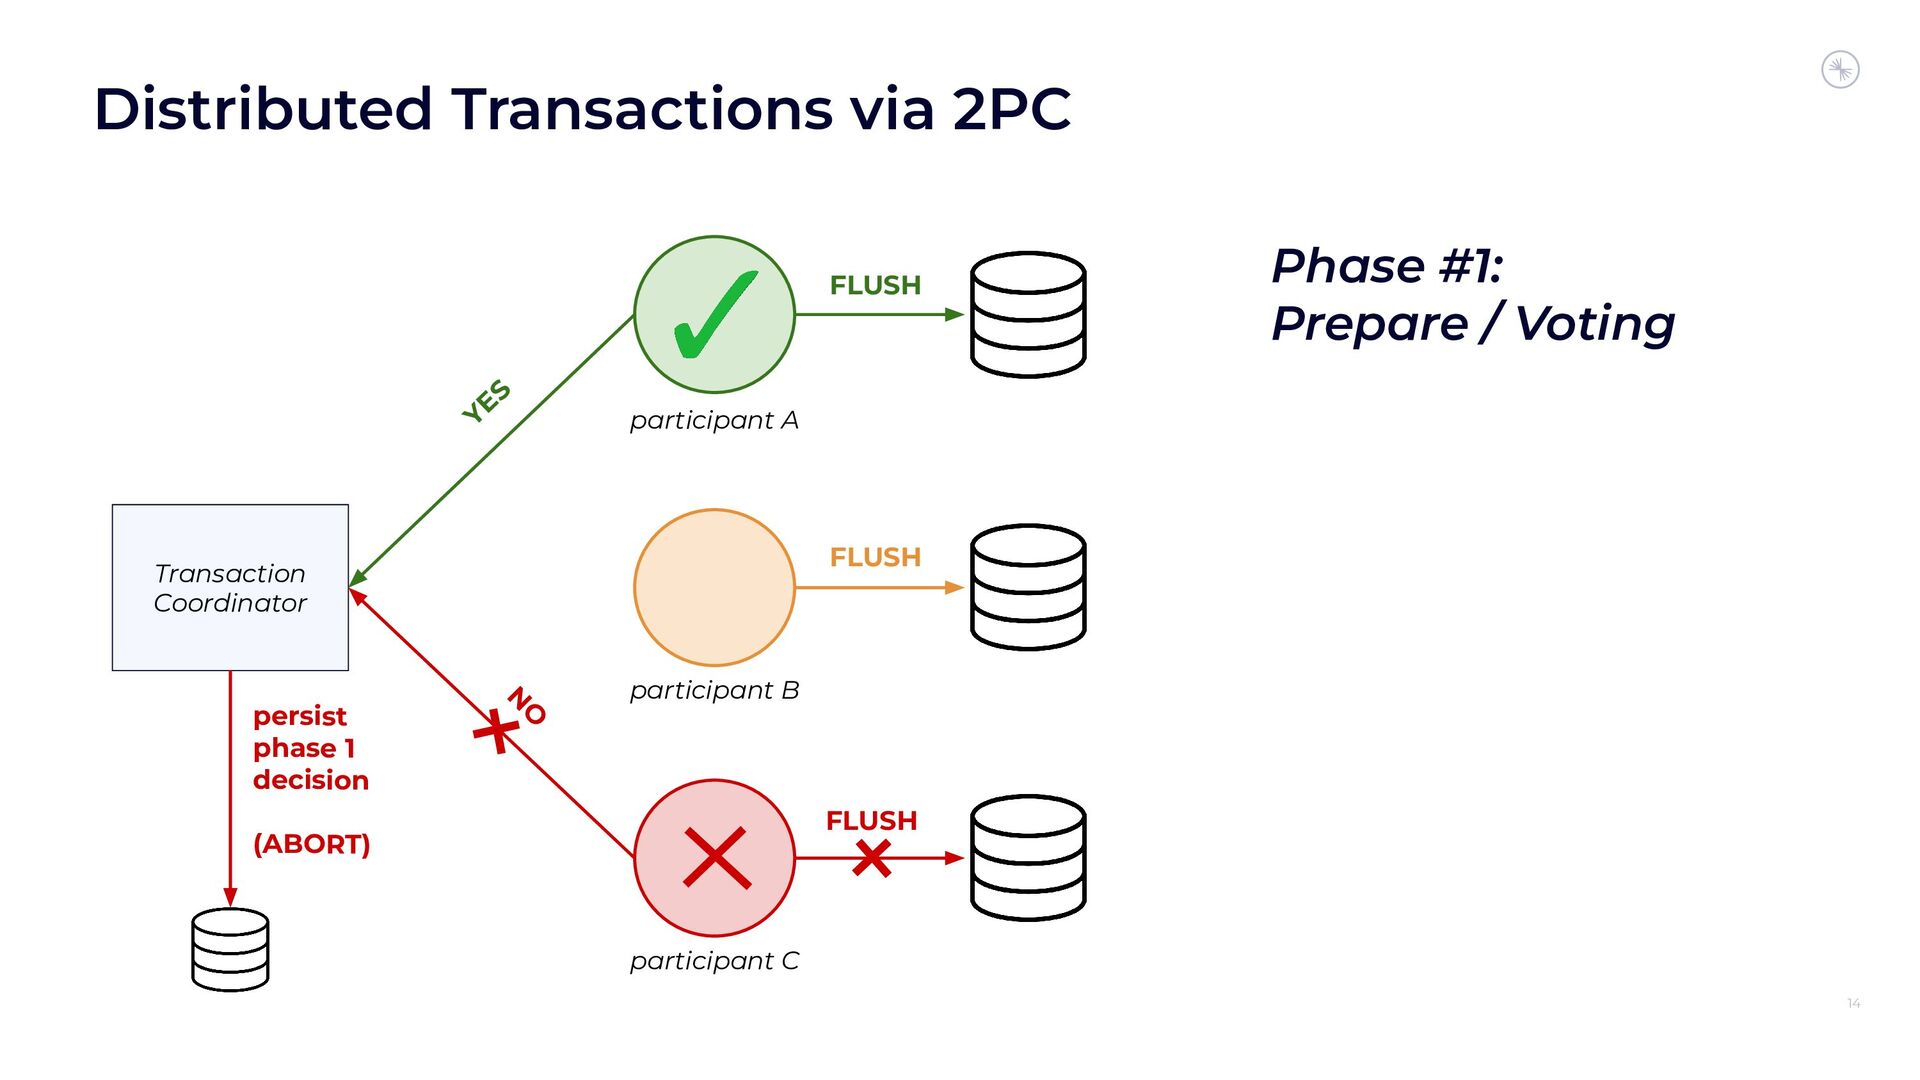
14 Distributed Transactions via 2PC Transaction Coordinator participant A participant
B participant C YES FLUSH FLUSH FLUSH N O persist phase 1 decision (ABORT) Phase #1: Prepare / Voting -
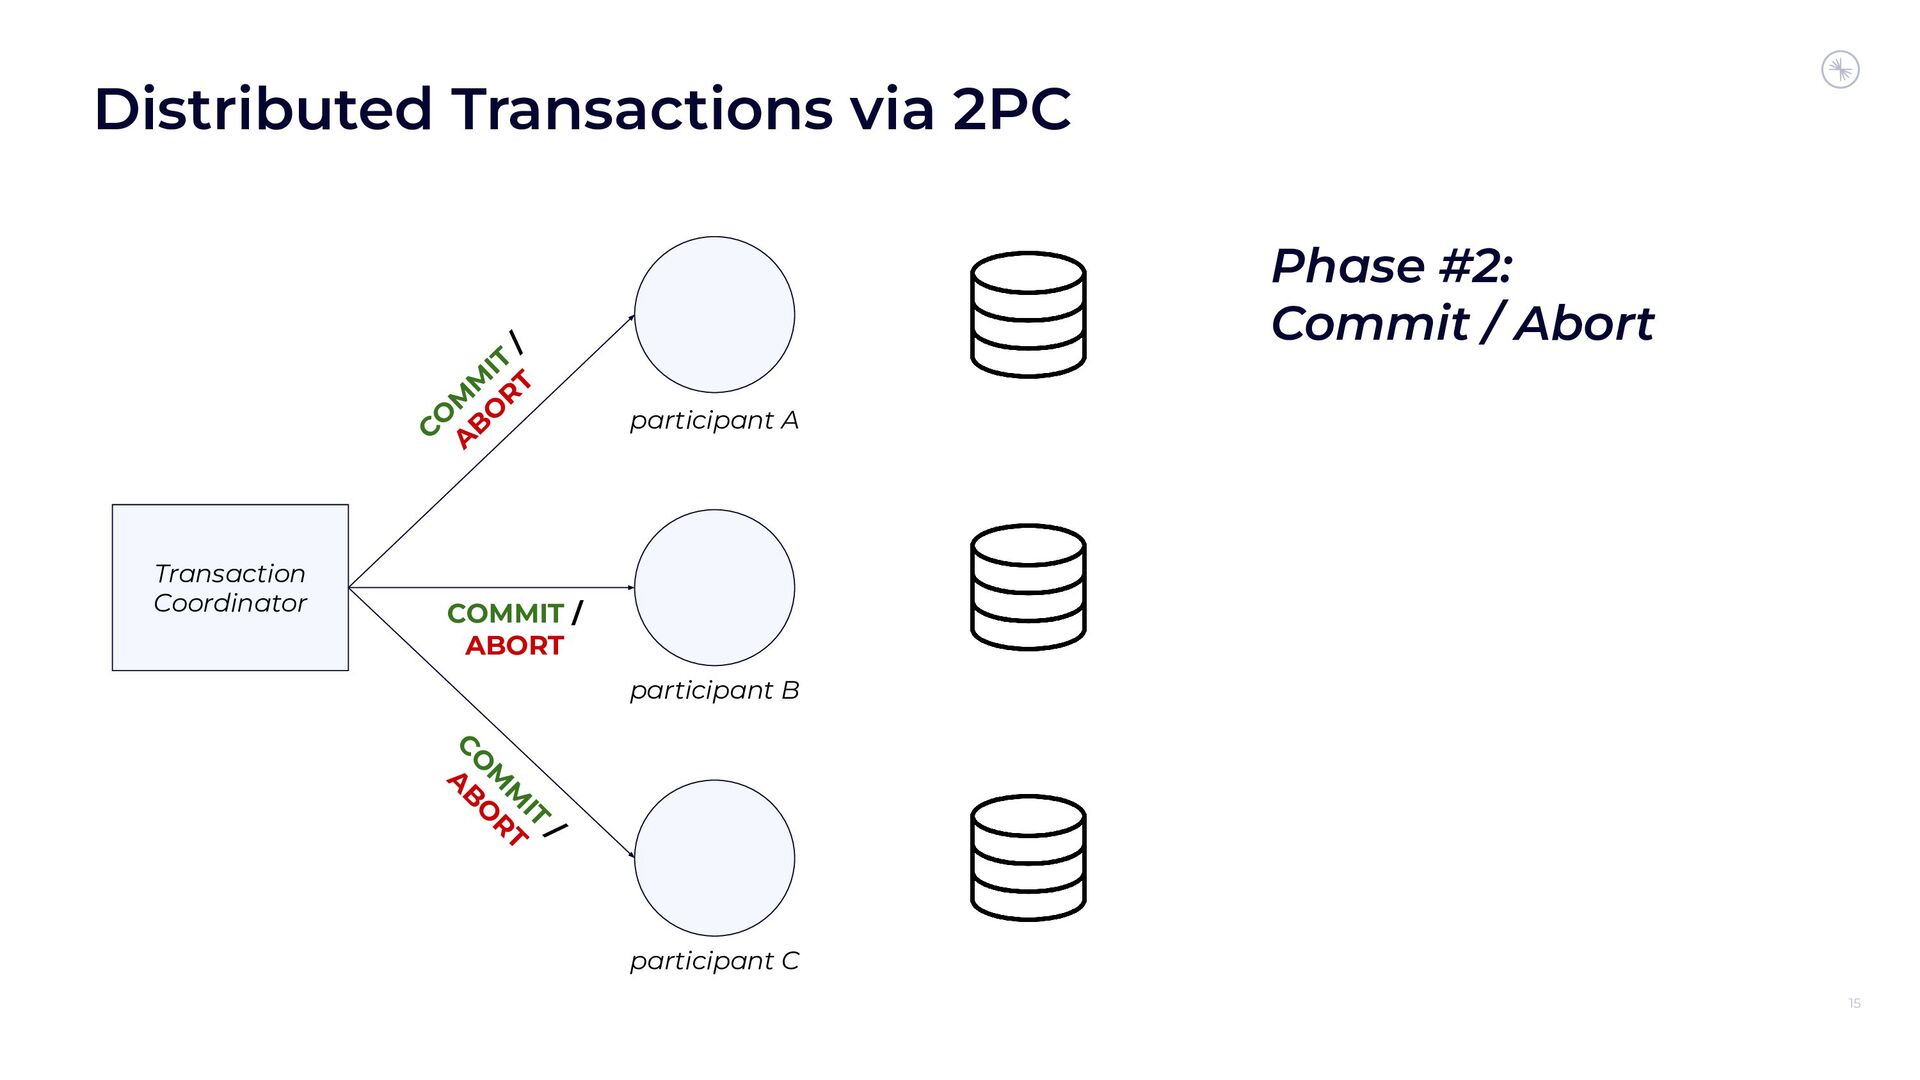
15 Distributed Transactions via 2PC Transaction Coordinator participant A participant
B participant C CO M M IT / A B O R T COMMIT / ABORT C O M M IT / A B O R T Phase #2: Commit / Abort -
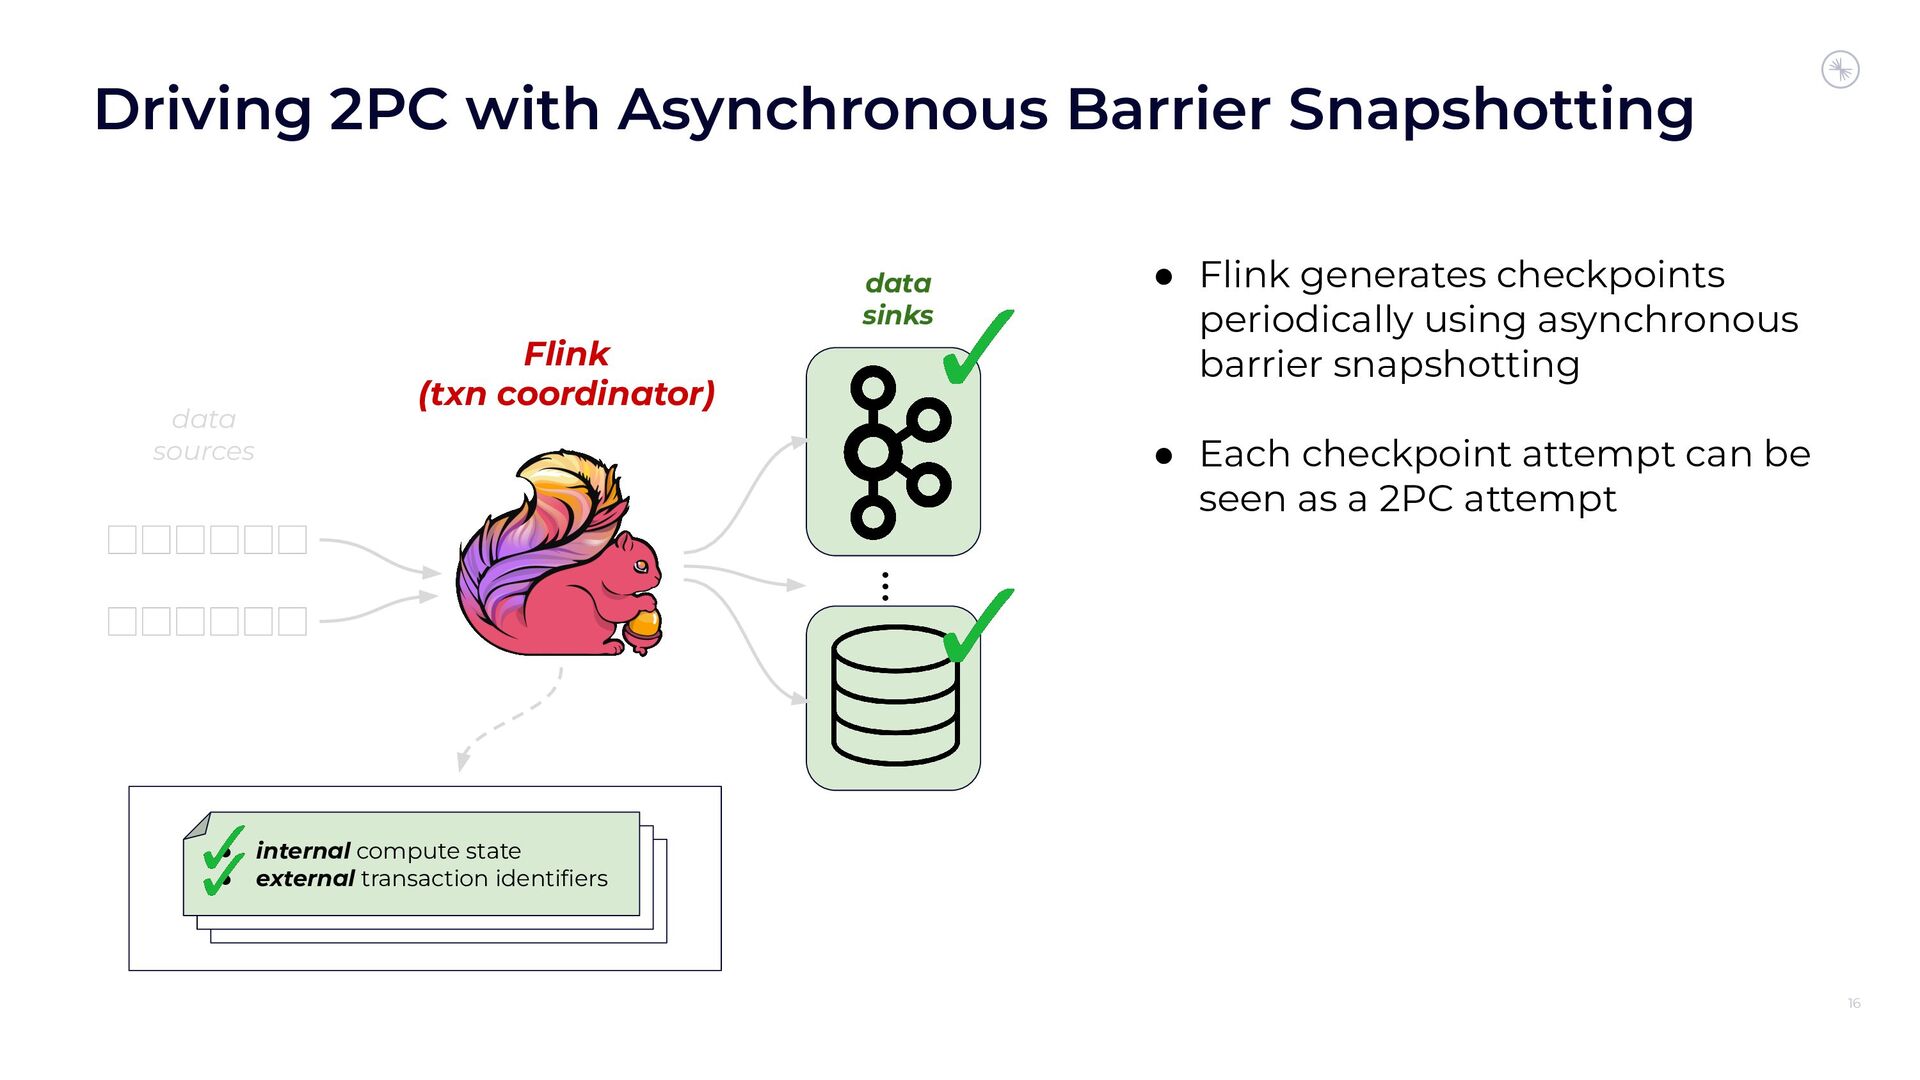
16 Driving 2PC with Asynchronous Barrier Snapshotting • Flink generates
checkpoints periodically using asynchronous barrier snapshotting • Each checkpoint attempt can be seen as a 2PC attempt … data sources data sinks • internal compute state • external transaction identifiers Flink (txn coordinator) -
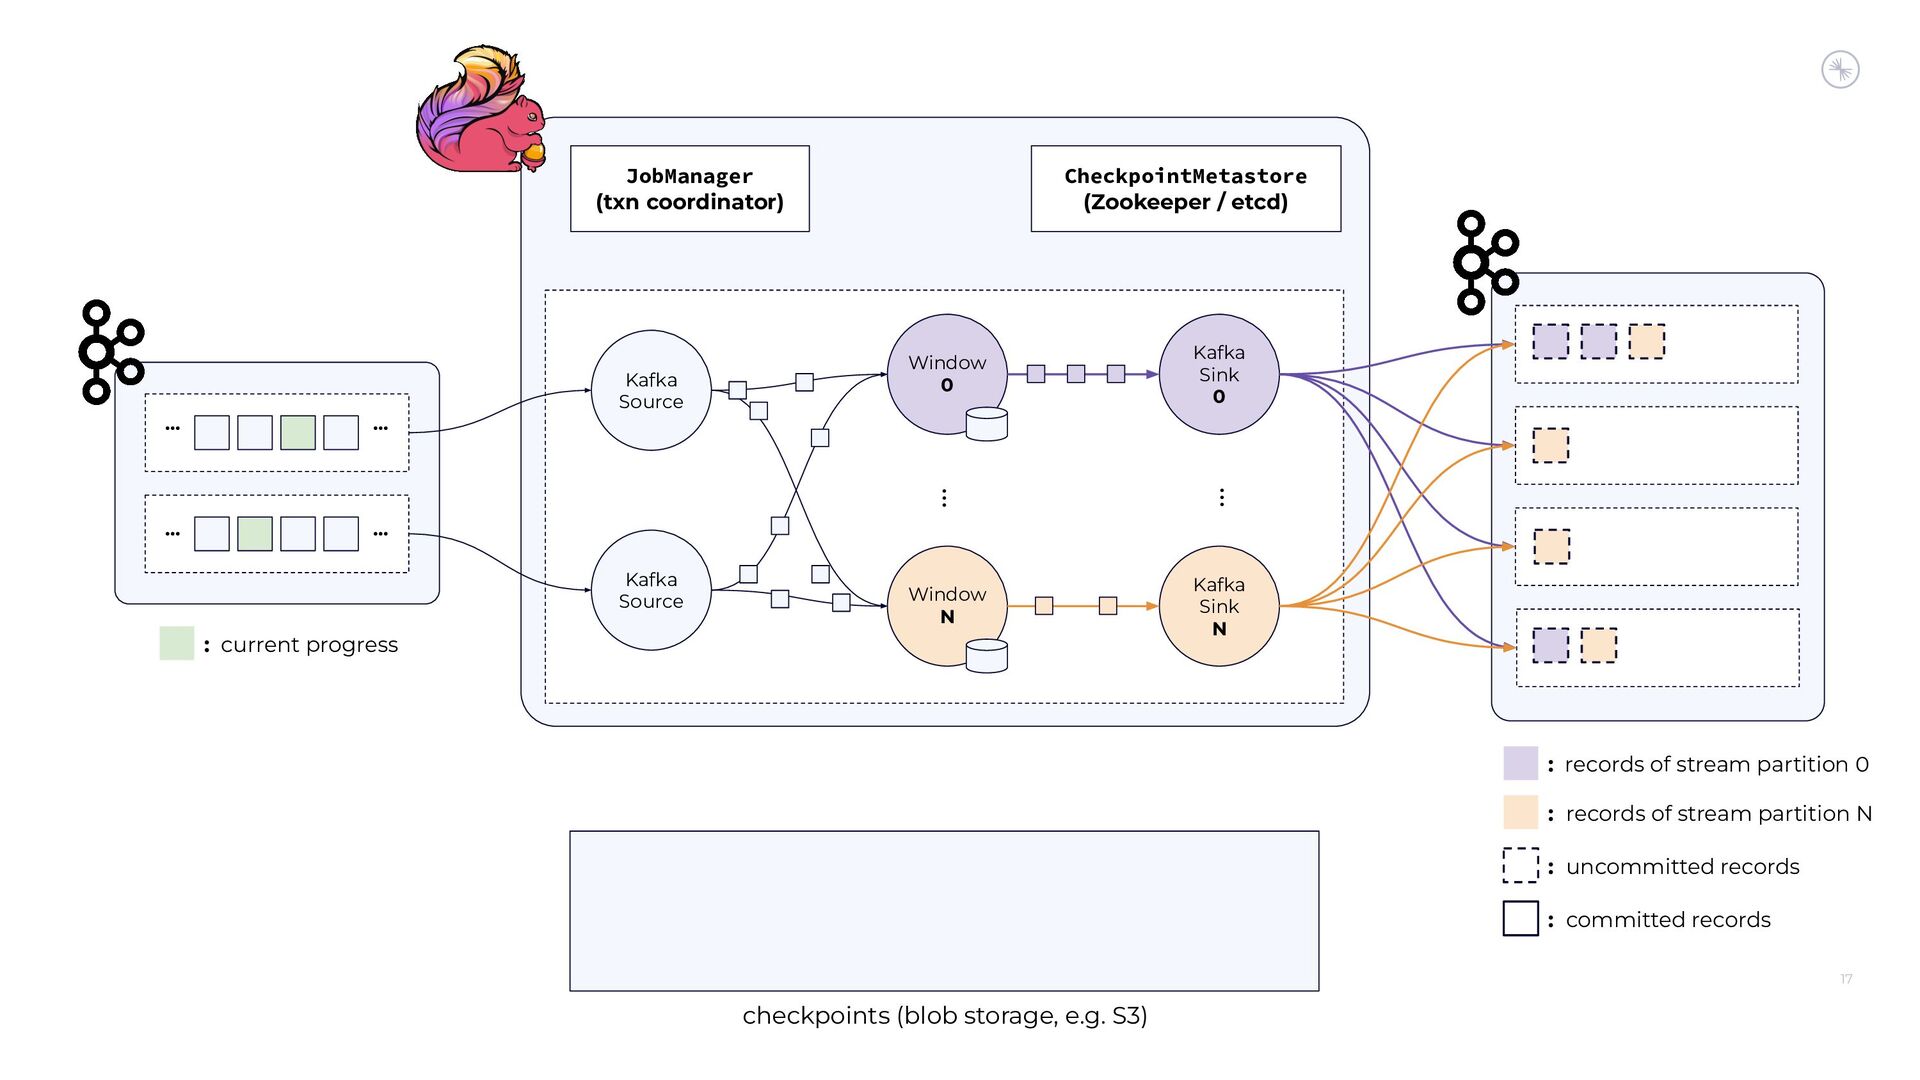
17 checkpoints (blob storage, e.g. S3) Kafka Source Kafka Source
JobManager (txn coordinator) CheckpointMetastore (Zookeeper / etcd) … Kafka Sink 0 Kafka Sink N … … … Window 0 Window N … … : records of stream partition 0 : records of stream partition N : uncommitted records : committed records : current progress -
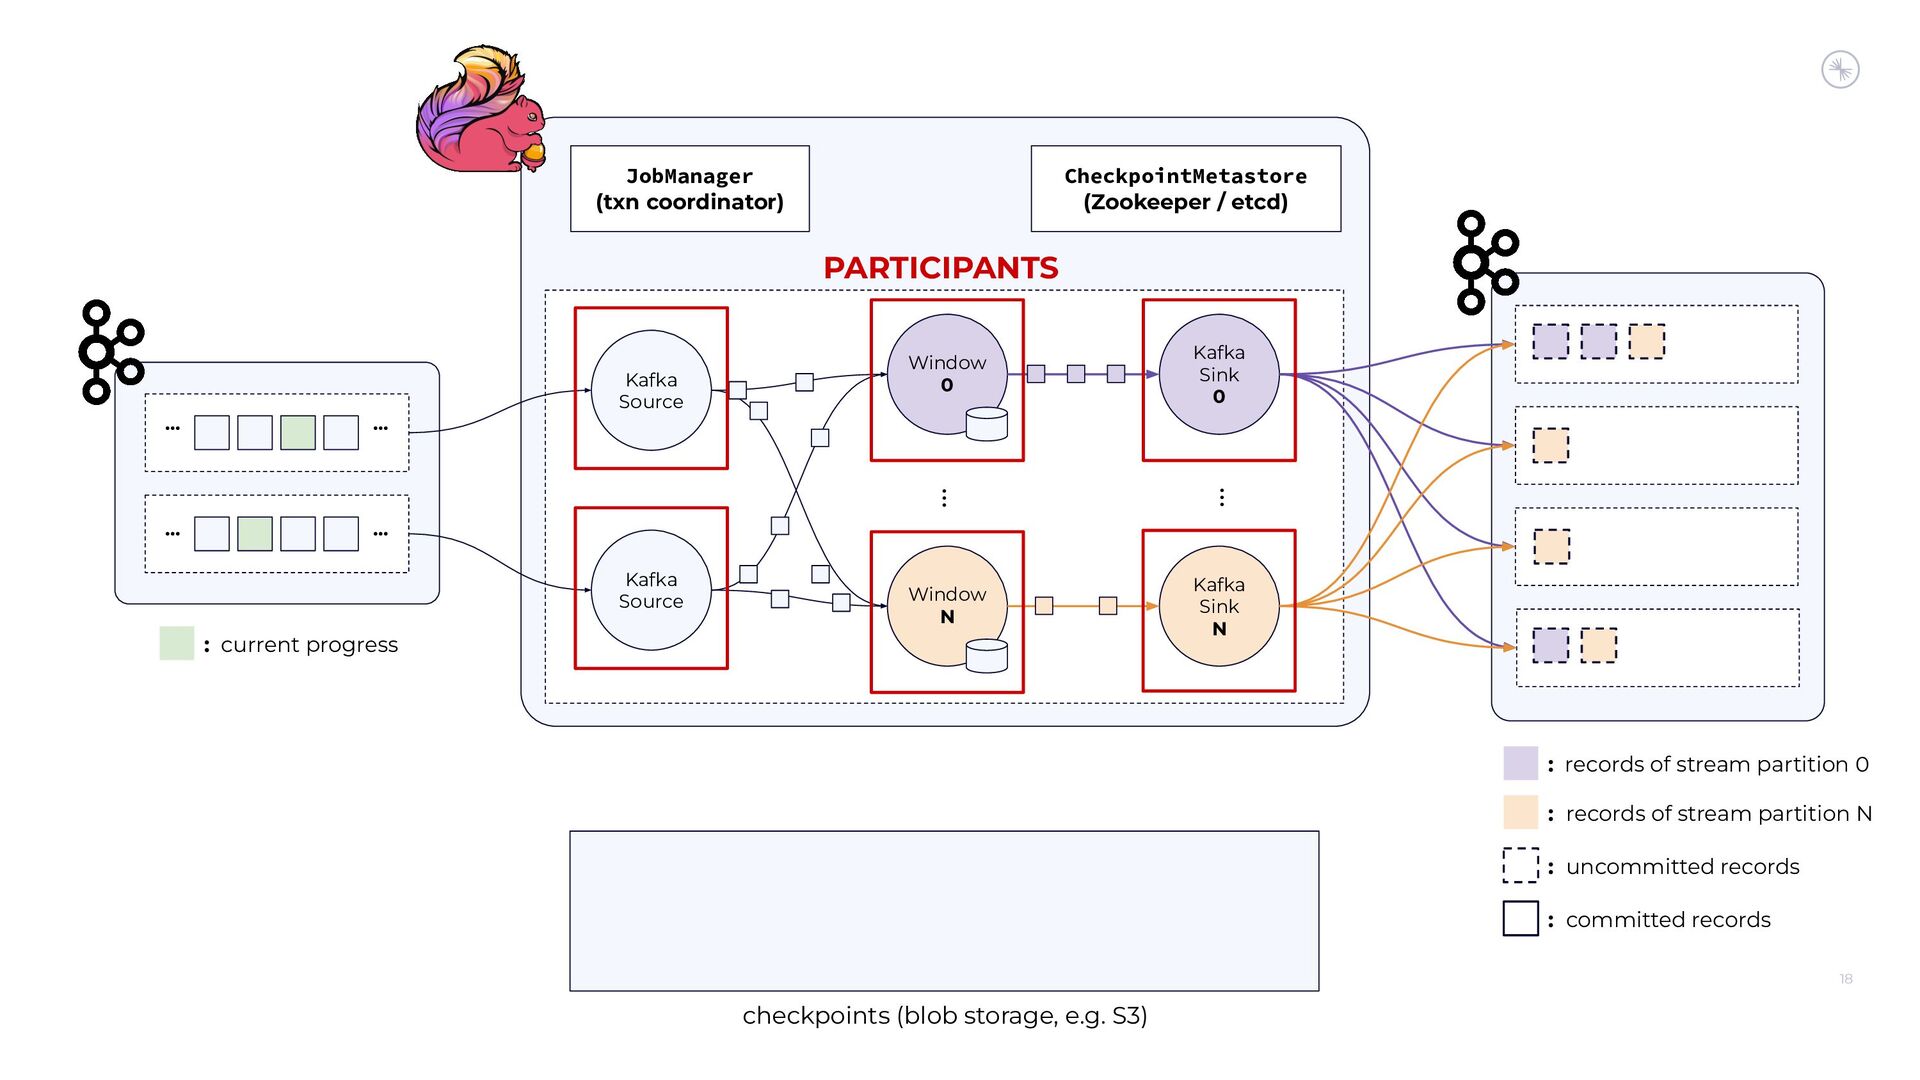
18 checkpoints (blob storage, e.g. S3) Kafka Source Kafka Source
JobManager (txn coordinator) CheckpointMetastore (Zookeeper / etcd) … Kafka Sink 0 Kafka Sink N … … … Window 0 Window N … … : records of stream partition 0 : records of stream partition N : uncommitted records : committed records : current progress PARTICIPANTS -
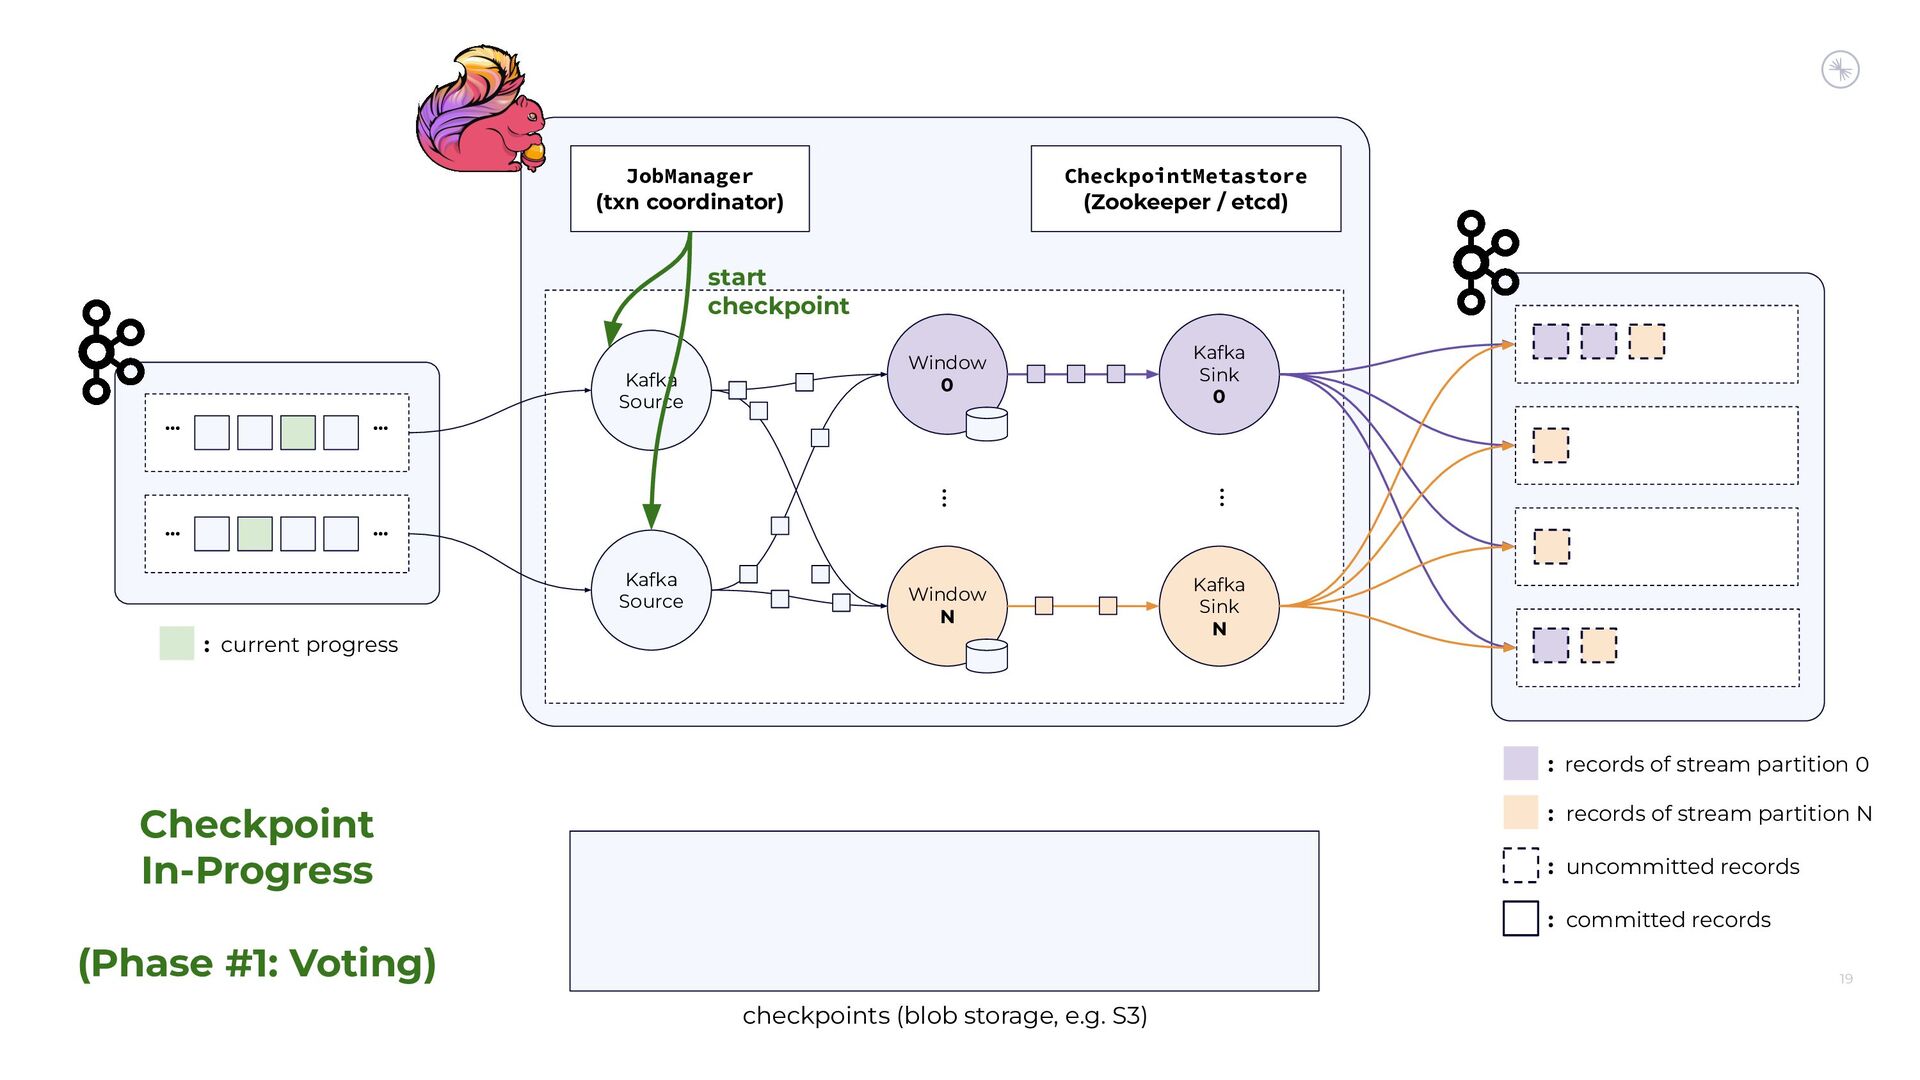
19 checkpoints (blob storage, e.g. S3) Kafka Source Kafka Source
JobManager (txn coordinator) CheckpointMetastore (Zookeeper / etcd) … Kafka Sink 0 Kafka Sink N … … … Window 0 Window N … … : records of stream partition 0 : records of stream partition N : uncommitted records : committed records : current progress start checkpoint Checkpoint In-Progress (Phase #1: Voting) -
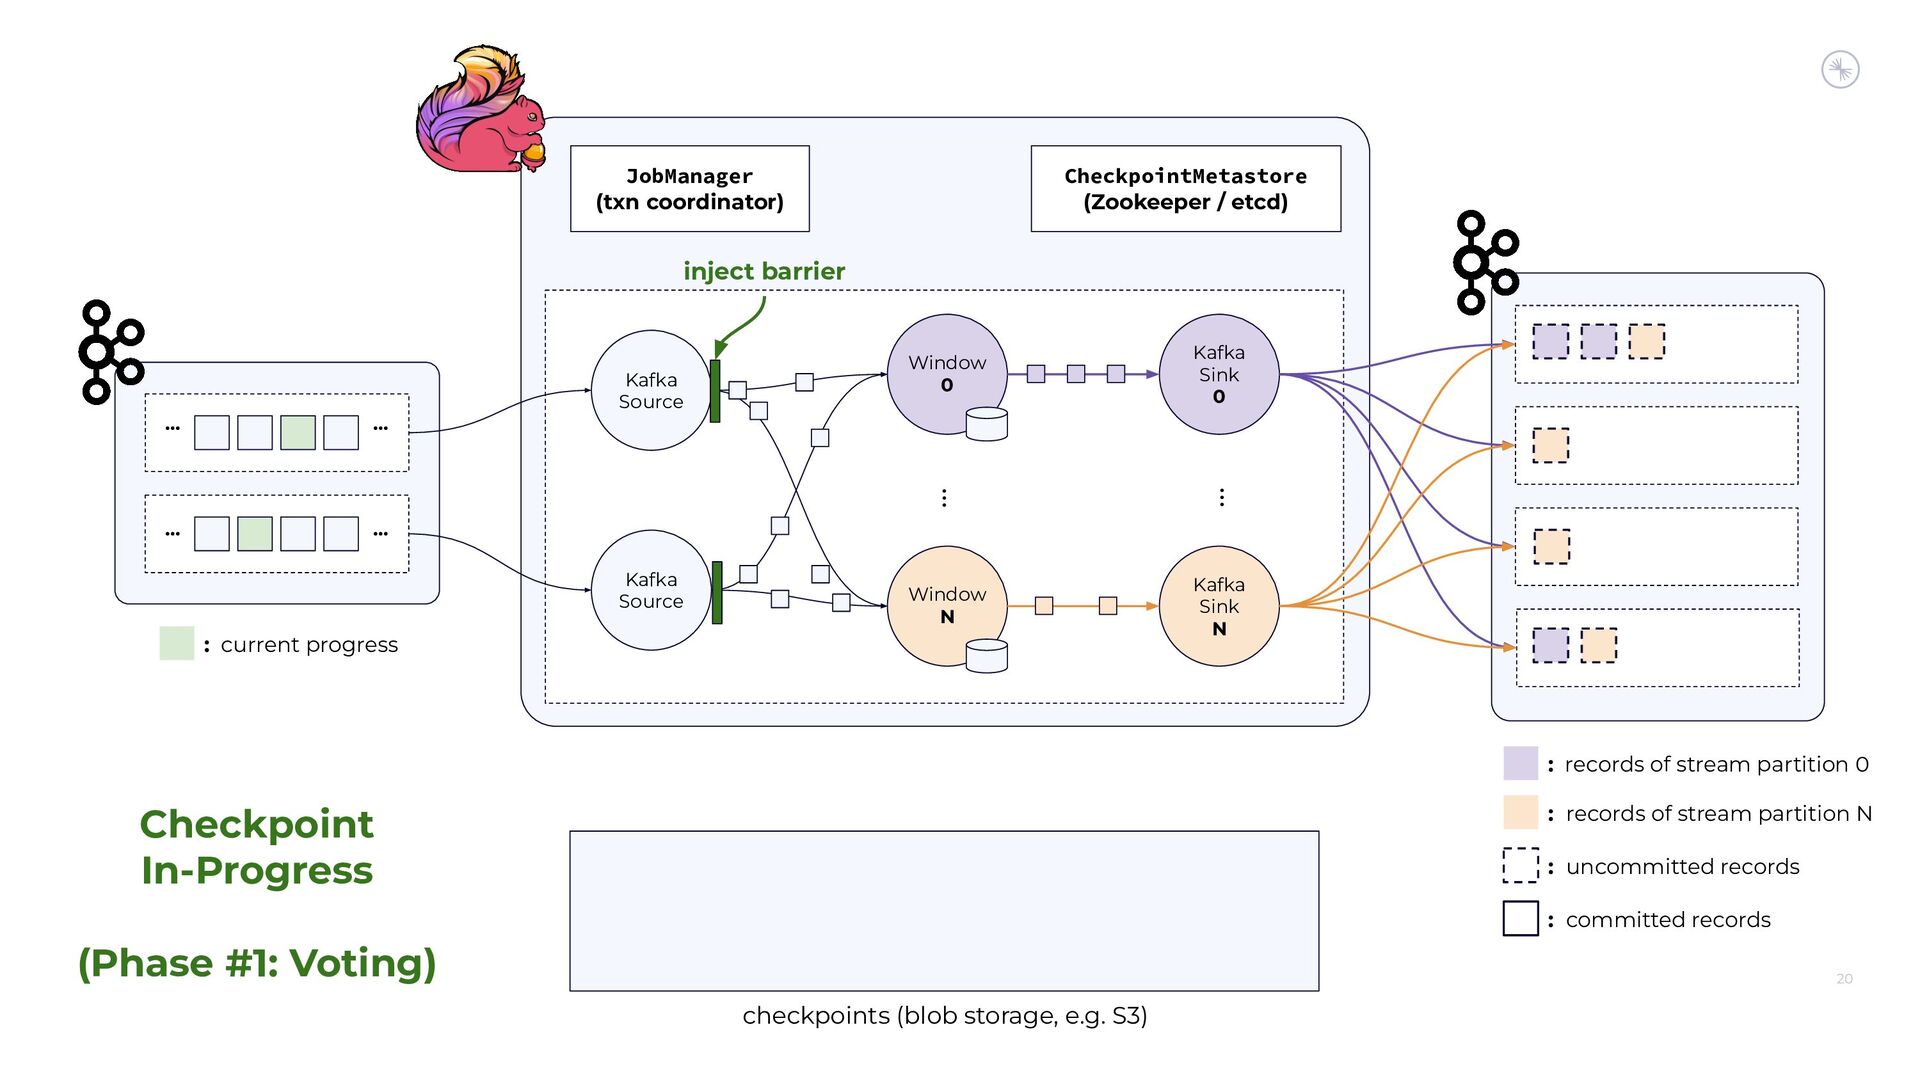
20 checkpoints (blob storage, e.g. S3) Kafka Source Kafka Source
JobManager (txn coordinator) CheckpointMetastore (Zookeeper / etcd) … Kafka Sink 0 Kafka Sink N … … … Window 0 Window N … … : records of stream partition 0 : records of stream partition N : uncommitted records : committed records : current progress inject barrier Checkpoint In-Progress (Phase #1: Voting) -
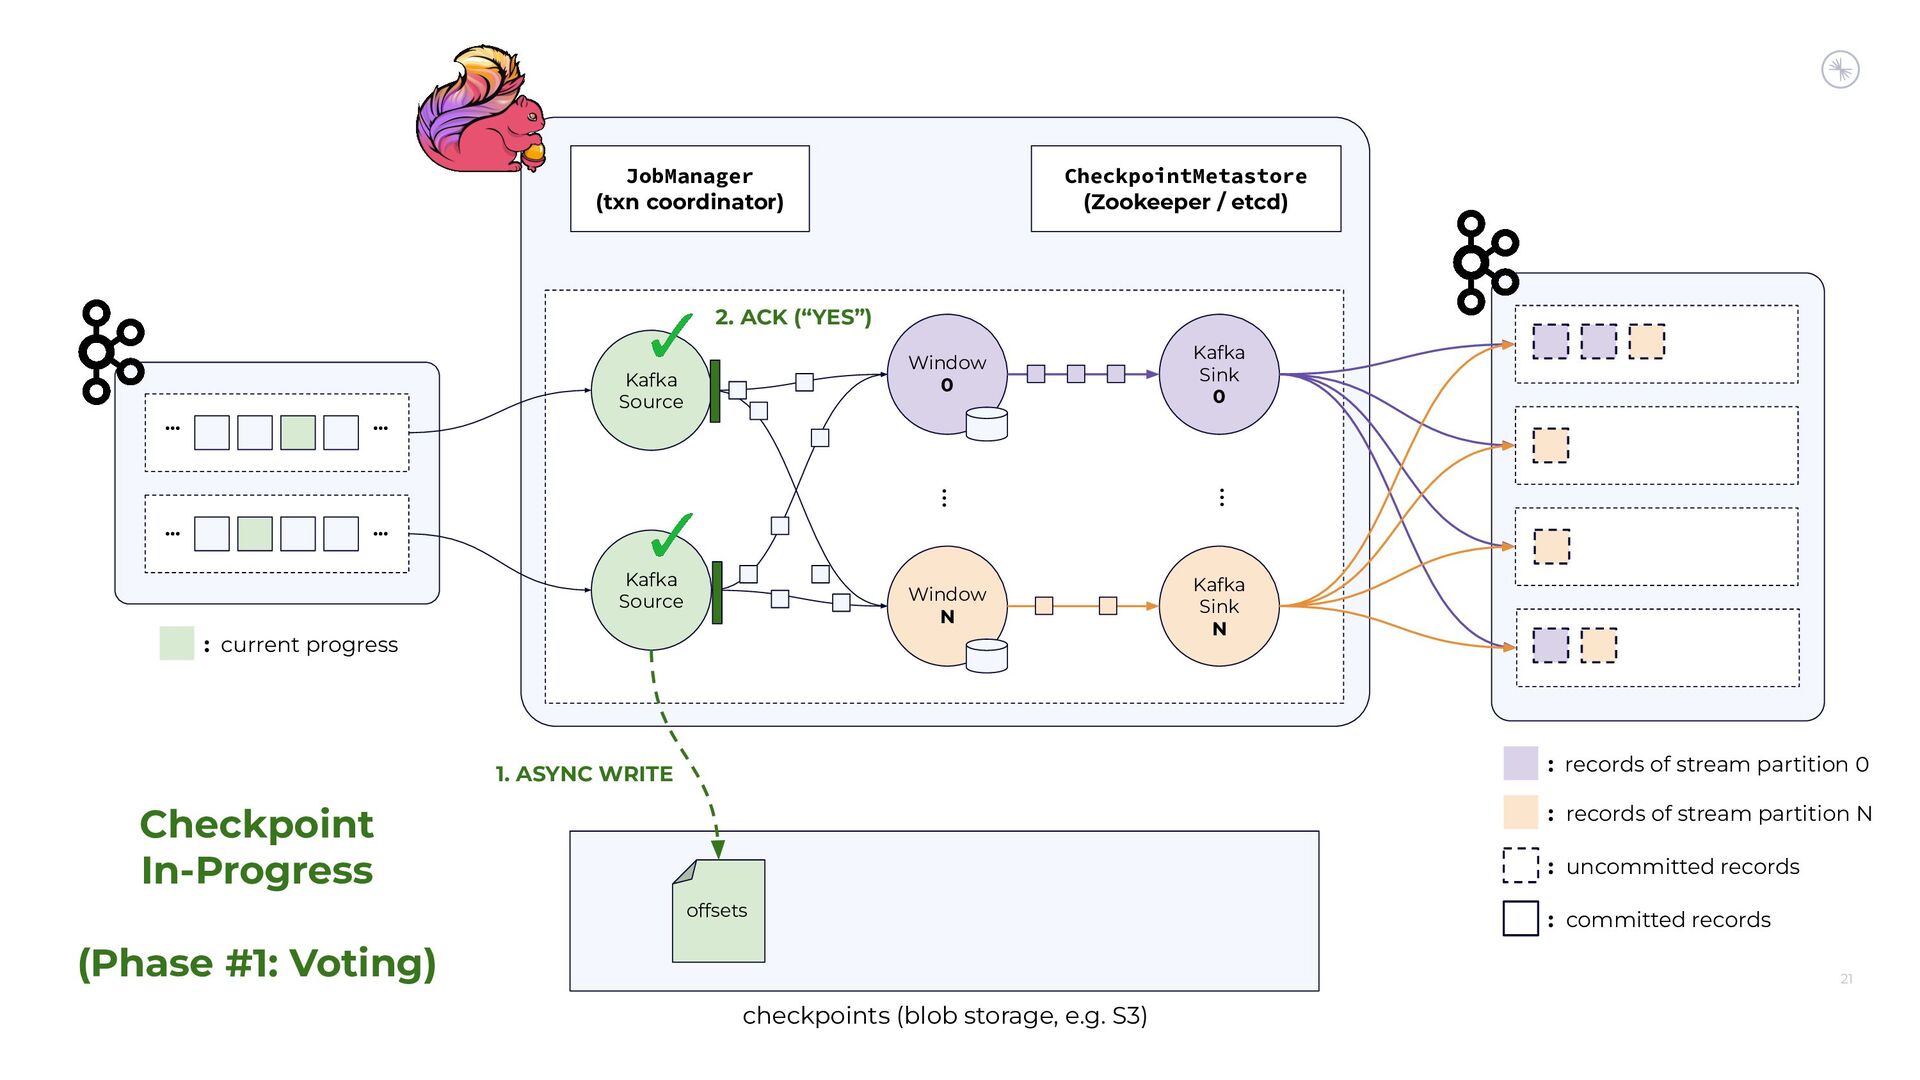
21 checkpoints (blob storage, e.g. S3) Kafka Source Kafka Source
JobManager (txn coordinator) CheckpointMetastore (Zookeeper / etcd) … Kafka Sink 0 Kafka Sink N … … … Window 0 Window N … … : records of stream partition 0 : records of stream partition N : uncommitted records : committed records : current progress offsets 1. ASYNC WRITE 2. ACK (“YES”) Checkpoint In-Progress (Phase #1: Voting) -
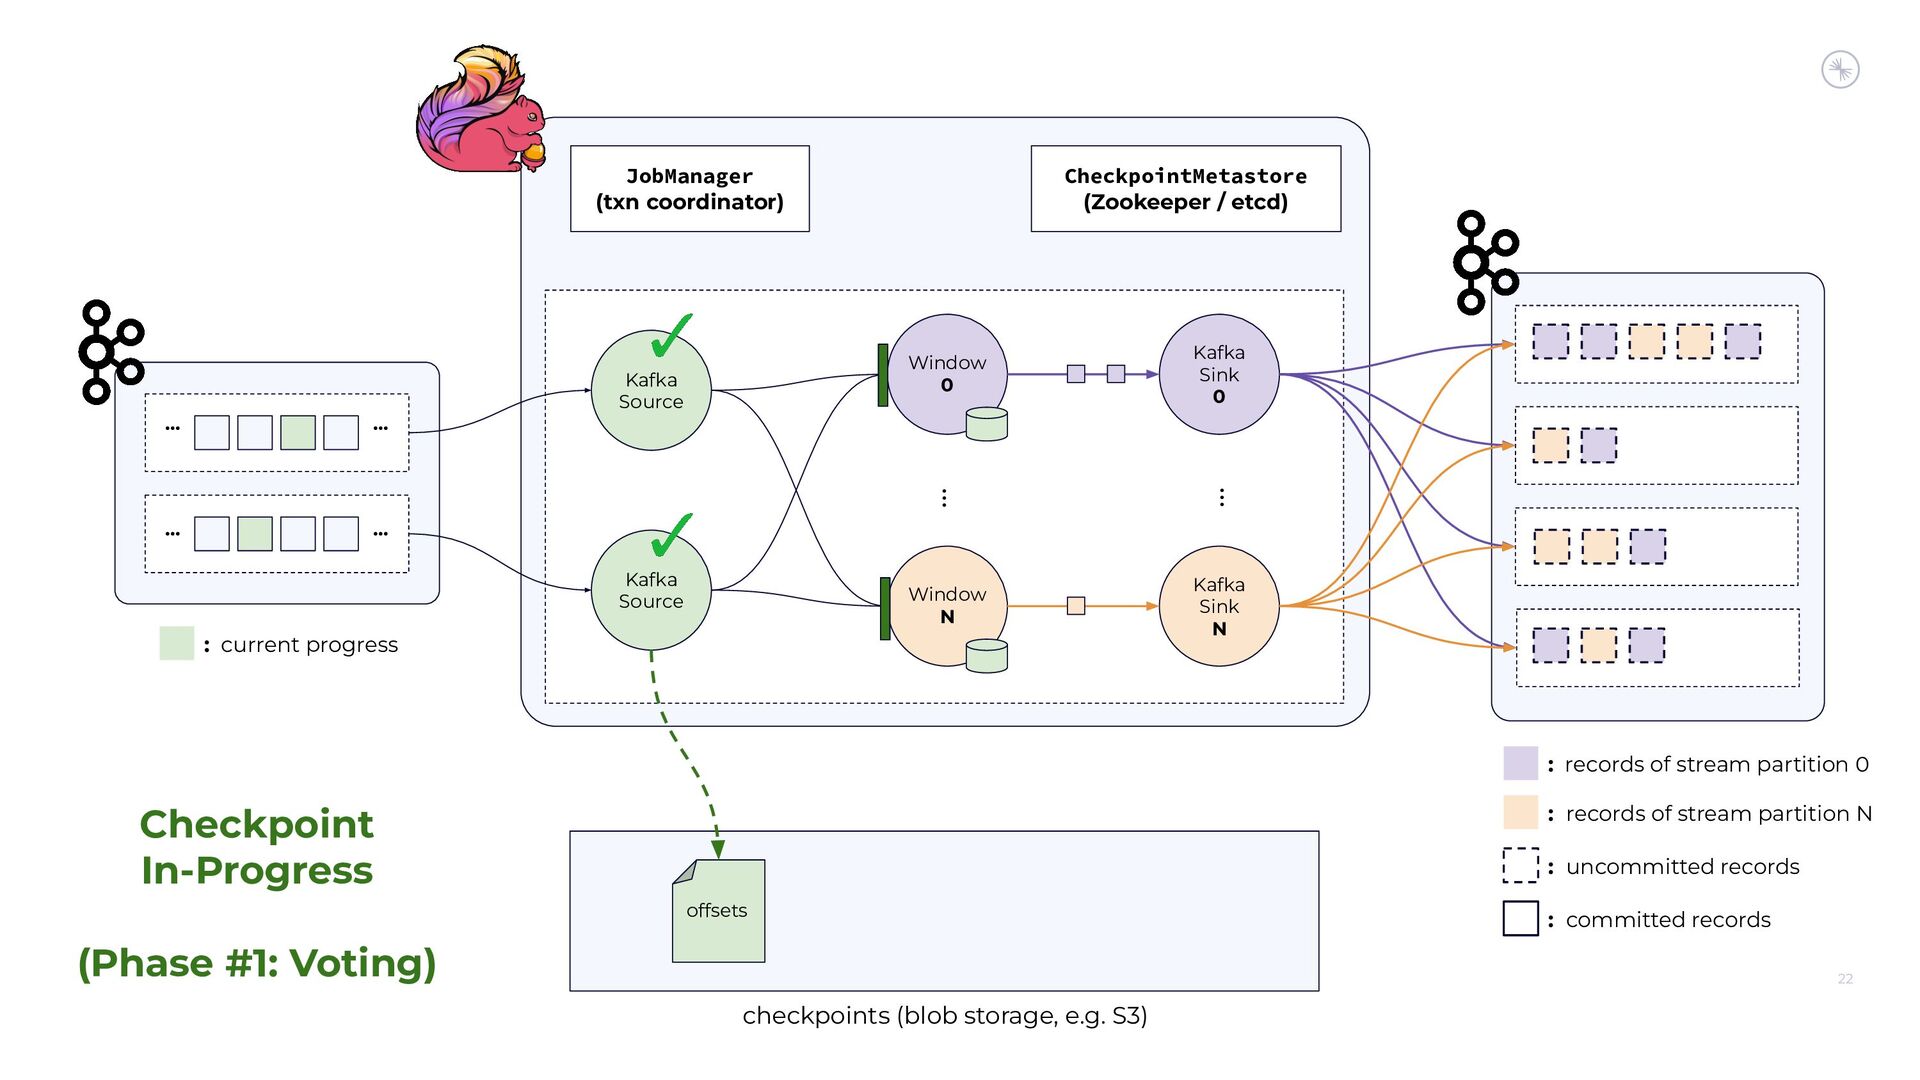
22 checkpoints (blob storage, e.g. S3) Kafka Source Kafka Source
JobManager (txn coordinator) CheckpointMetastore (Zookeeper / etcd) … Kafka Sink 0 Kafka Sink N … … … Window 0 Window N … … : records of stream partition 0 : records of stream partition N : uncommitted records : committed records : current progress offsets Checkpoint In-Progress (Phase #1: Voting) -
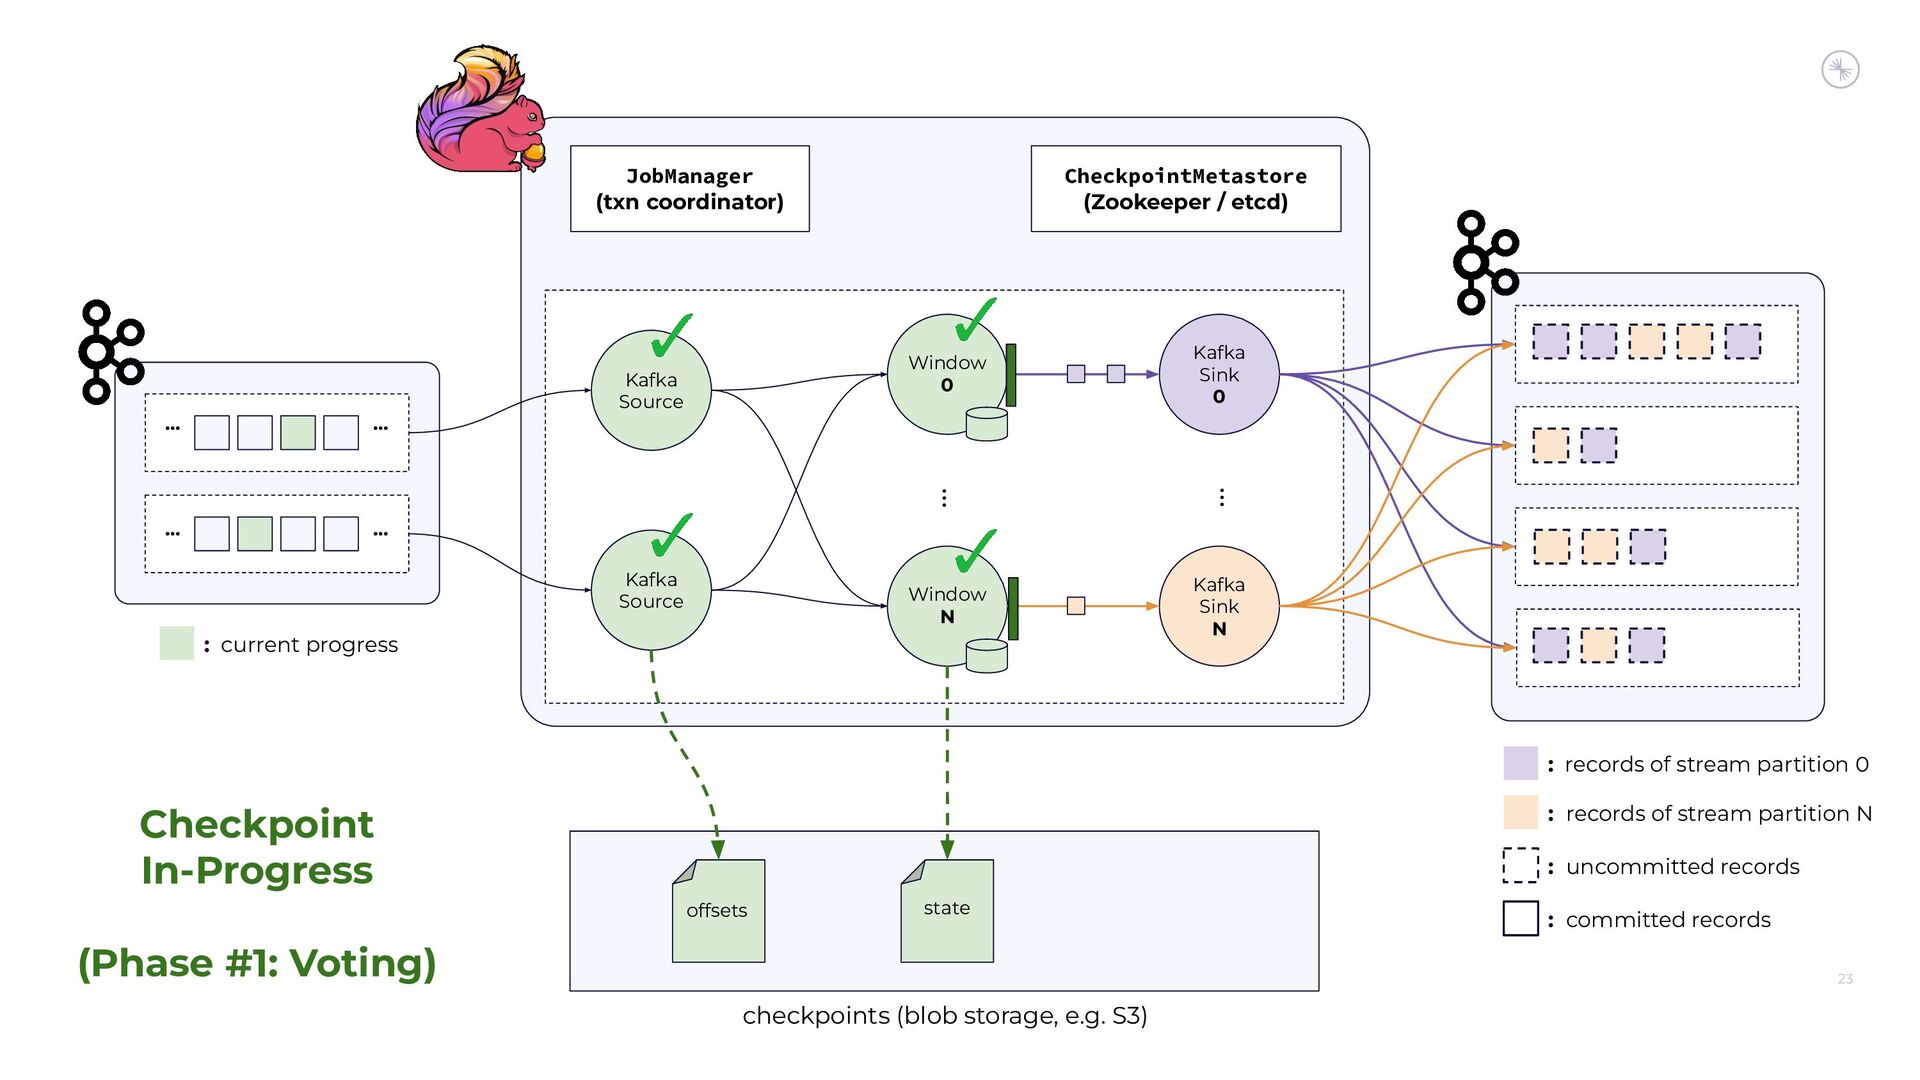
23 checkpoints (blob storage, e.g. S3) Kafka Source Kafka Source
JobManager (txn coordinator) CheckpointMetastore (Zookeeper / etcd) … Kafka Sink 0 Kafka Sink N … … … Window 0 Window N … … : records of stream partition 0 : records of stream partition N : uncommitted records : committed records : current progress offsets state Checkpoint In-Progress (Phase #1: Voting) -
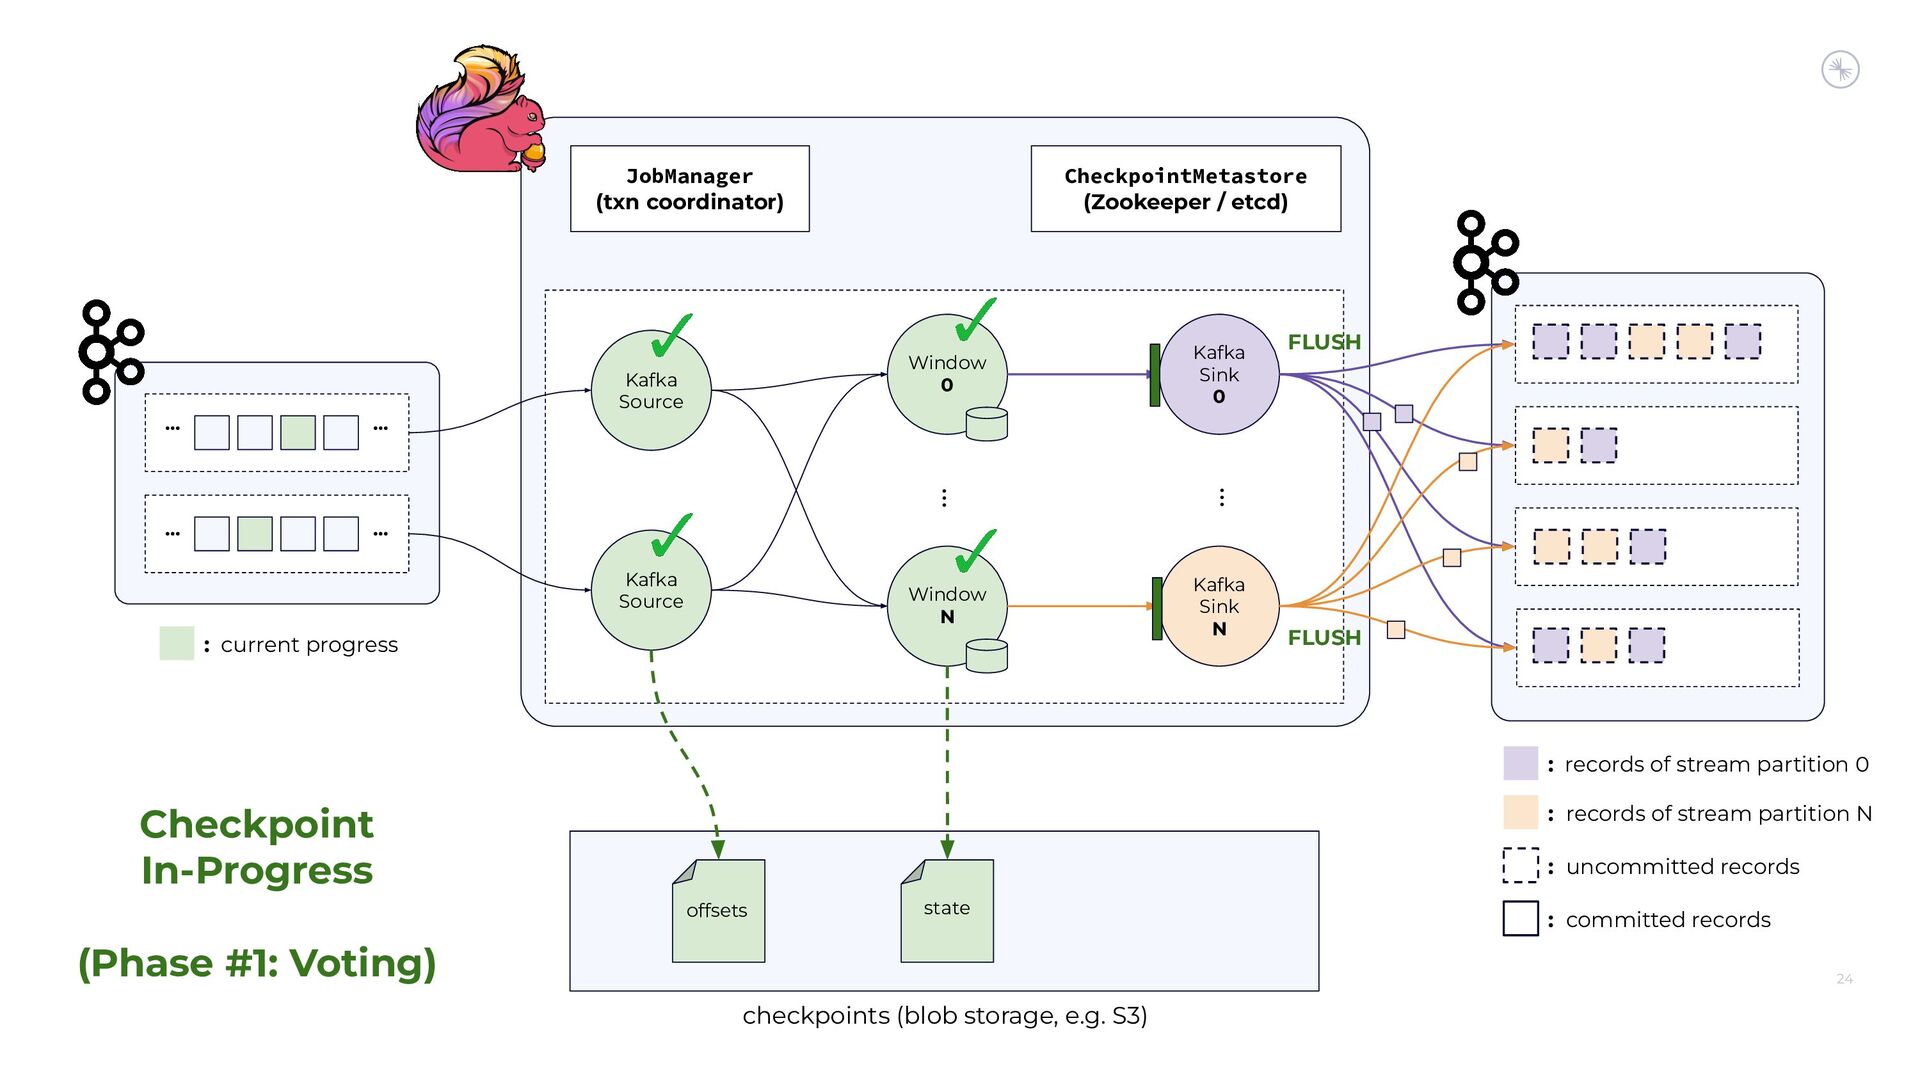
24 checkpoints (blob storage, e.g. S3) Kafka Source Kafka Source
JobManager (txn coordinator) CheckpointMetastore (Zookeeper / etcd) … Kafka Sink 0 Kafka Sink N … … … Window 0 Window N … … : records of stream partition 0 : records of stream partition N : uncommitted records : committed records : current progress offsets state FLUSH FLUSH Checkpoint In-Progress (Phase #1: Voting) -
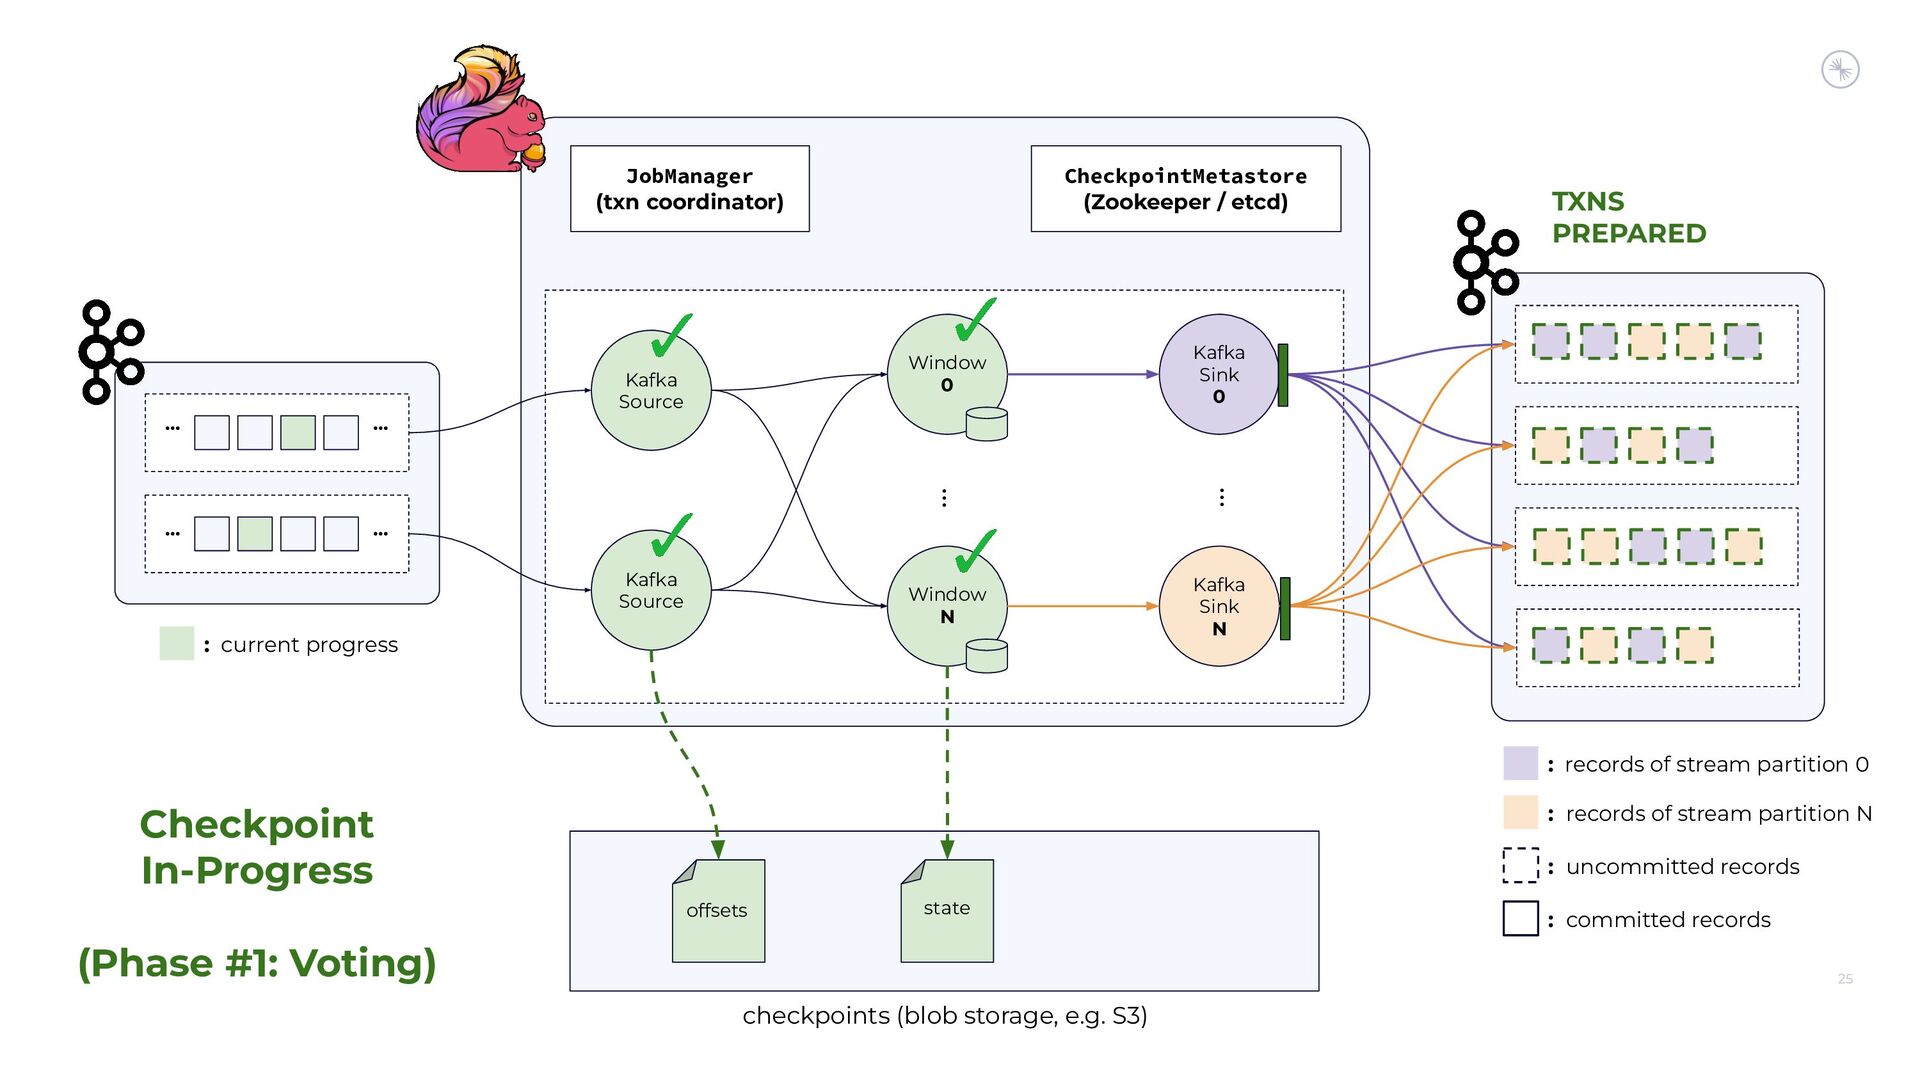
25 checkpoints (blob storage, e.g. S3) Kafka Source Kafka Source
JobManager (txn coordinator) CheckpointMetastore (Zookeeper / etcd) … Kafka Sink 0 Kafka Sink N … … … Window 0 Window N … … : records of stream partition 0 : records of stream partition N : uncommitted records : committed records : current progress offsets state TXNS PREPARED Checkpoint In-Progress (Phase #1: Voting) -
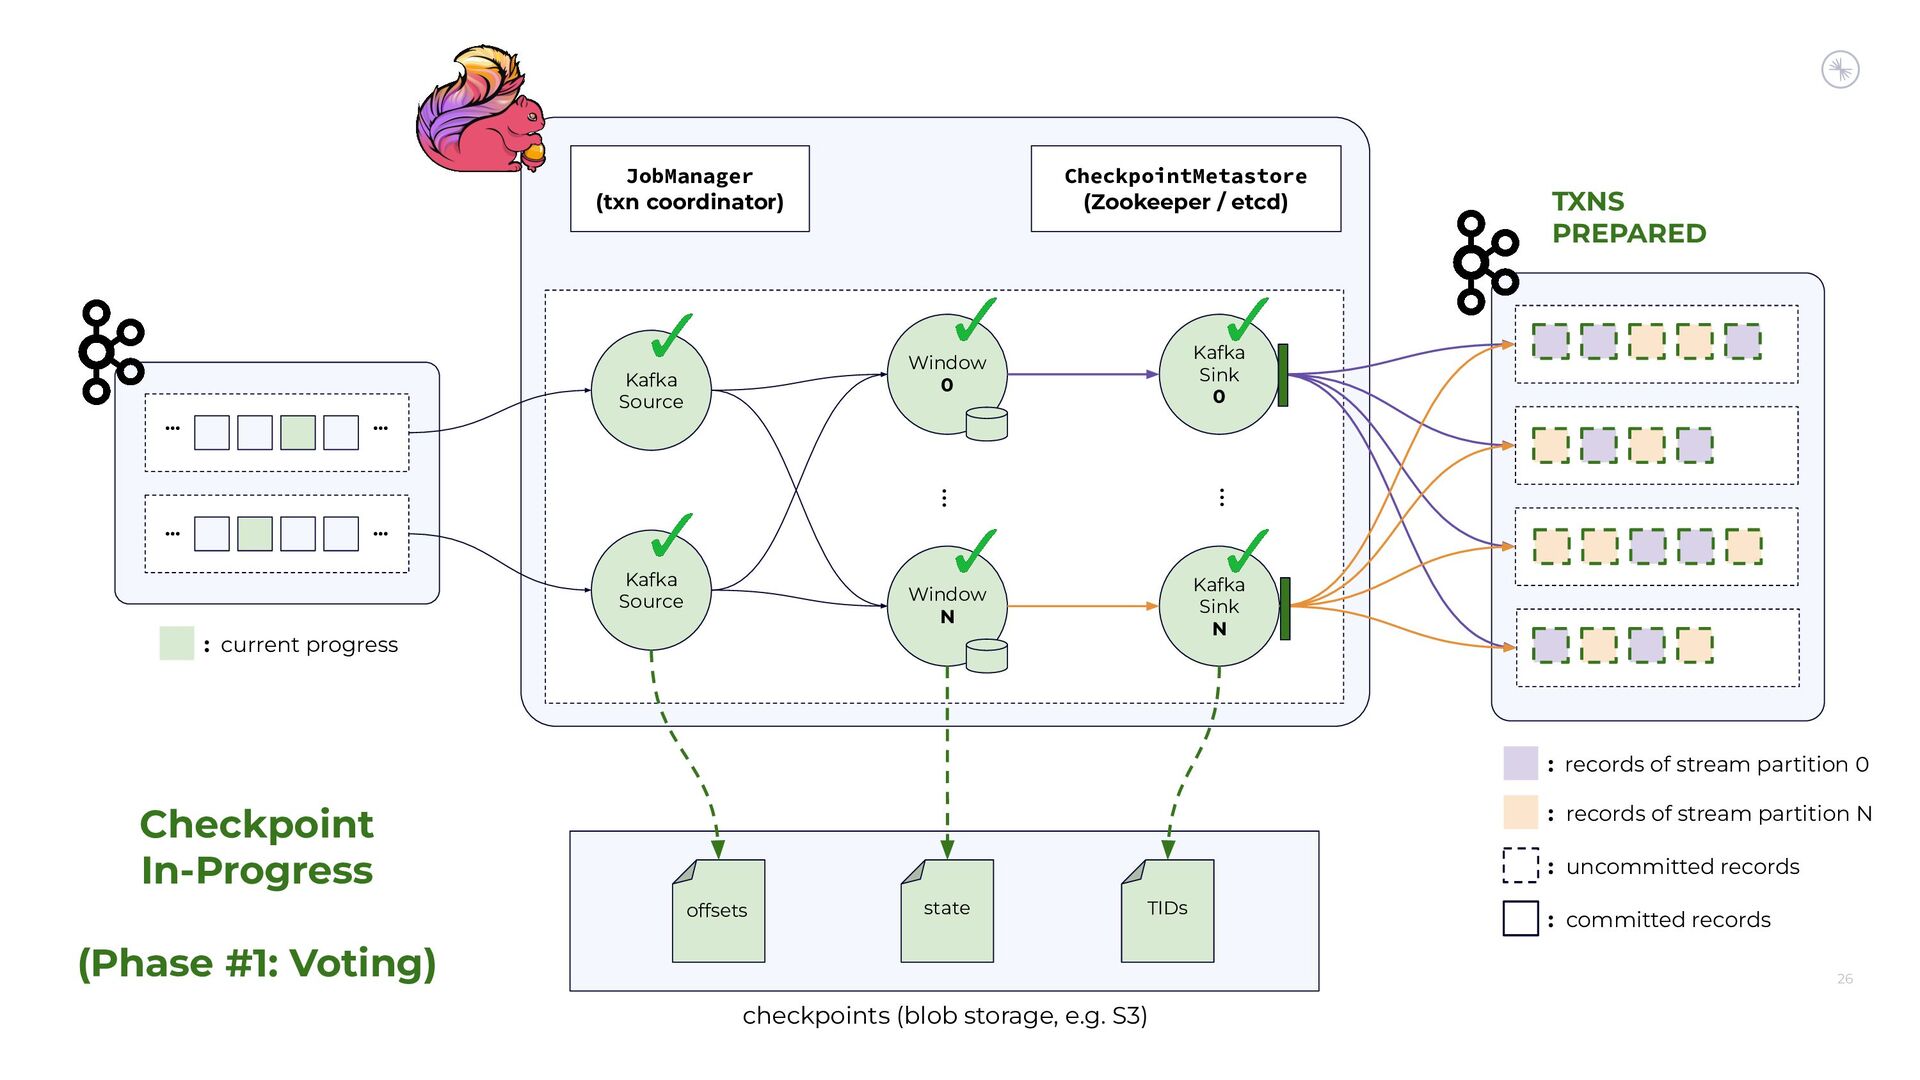
26 checkpoints (blob storage, e.g. S3) Kafka Source Kafka Source
JobManager (txn coordinator) CheckpointMetastore (Zookeeper / etcd) … Kafka Sink 0 Kafka Sink N … … … Window 0 Window N … … : records of stream partition 0 : records of stream partition N : uncommitted records : committed records : current progress offsets state TXNS PREPARED TIDs Checkpoint In-Progress (Phase #1: Voting) -
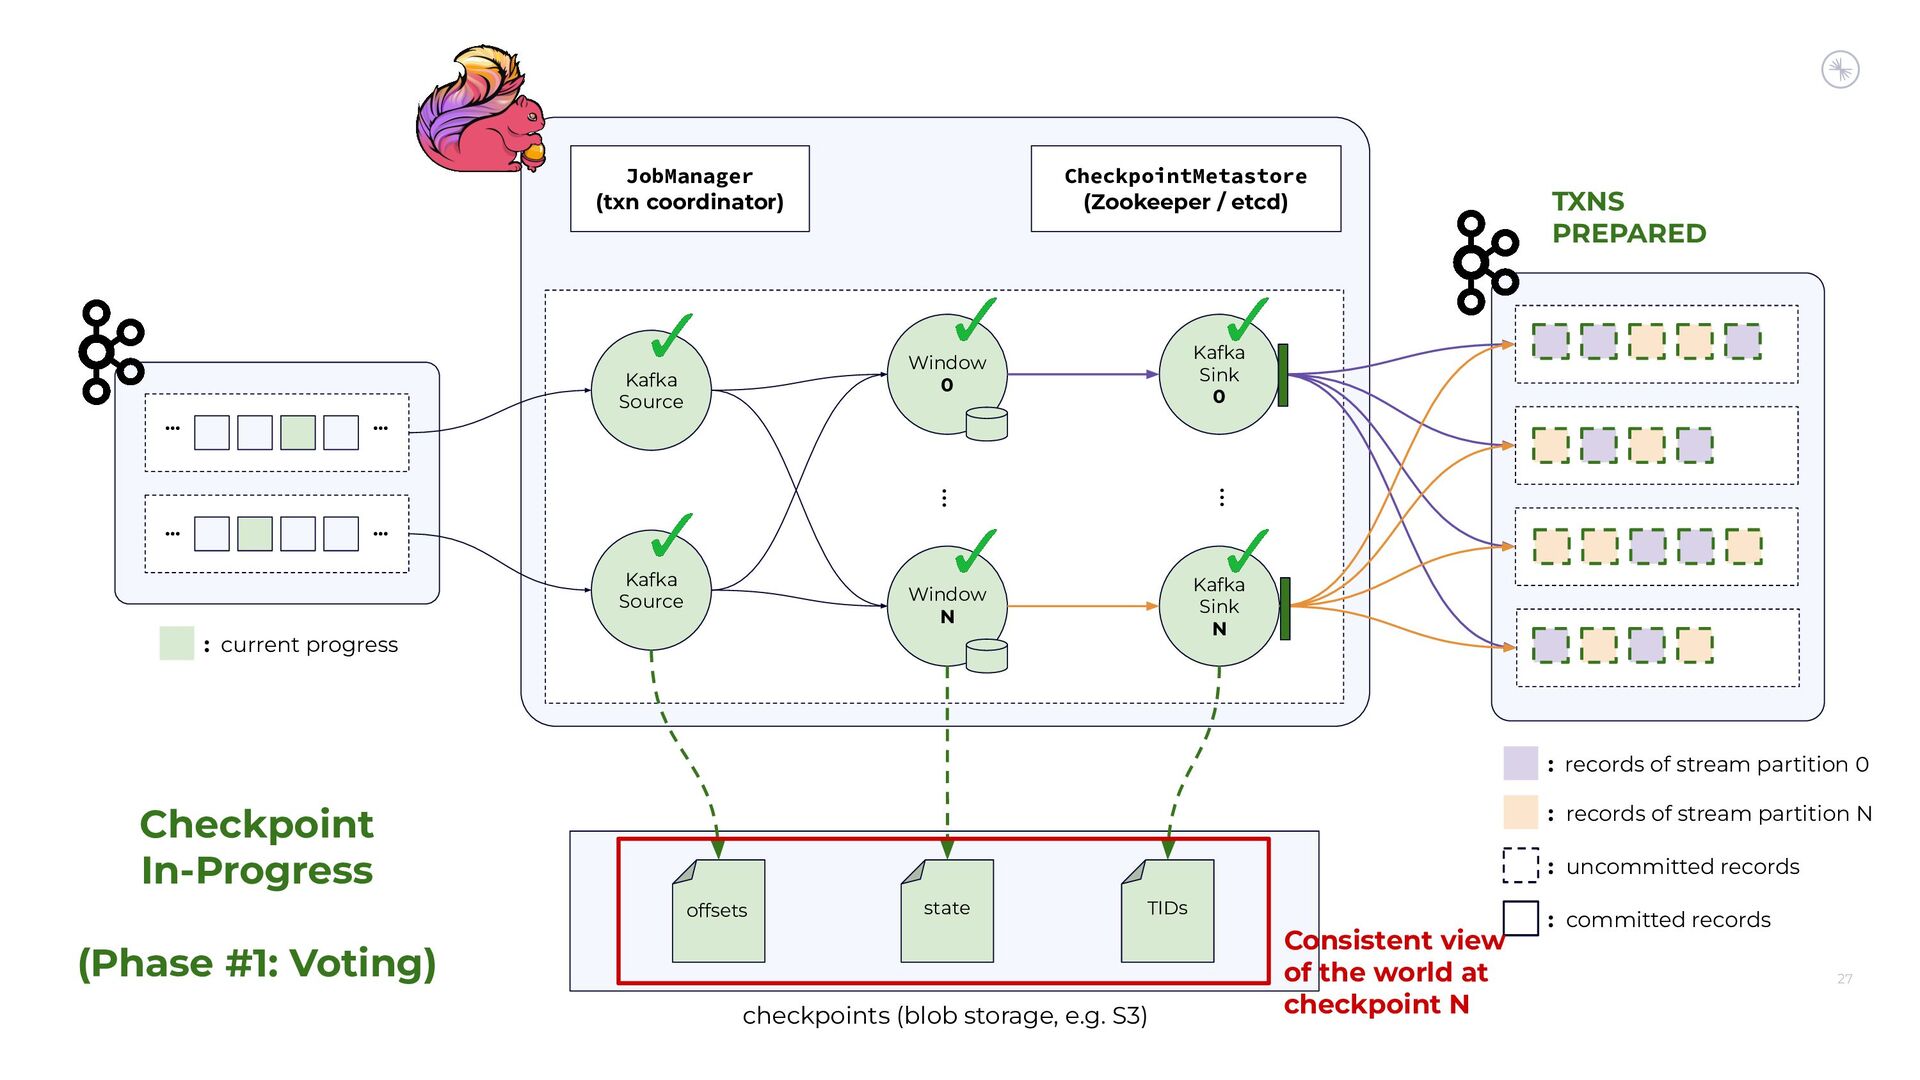
27 checkpoints (blob storage, e.g. S3) Kafka Source Kafka Source
JobManager (txn coordinator) CheckpointMetastore (Zookeeper / etcd) … Kafka Sink 0 Kafka Sink N … … … Window 0 Window N … … : records of stream partition 0 : records of stream partition N : uncommitted records : committed records : current progress offsets state TXNS PREPARED TIDs Checkpoint In-Progress (Phase #1: Voting) Consistent view of the world at checkpoint N -
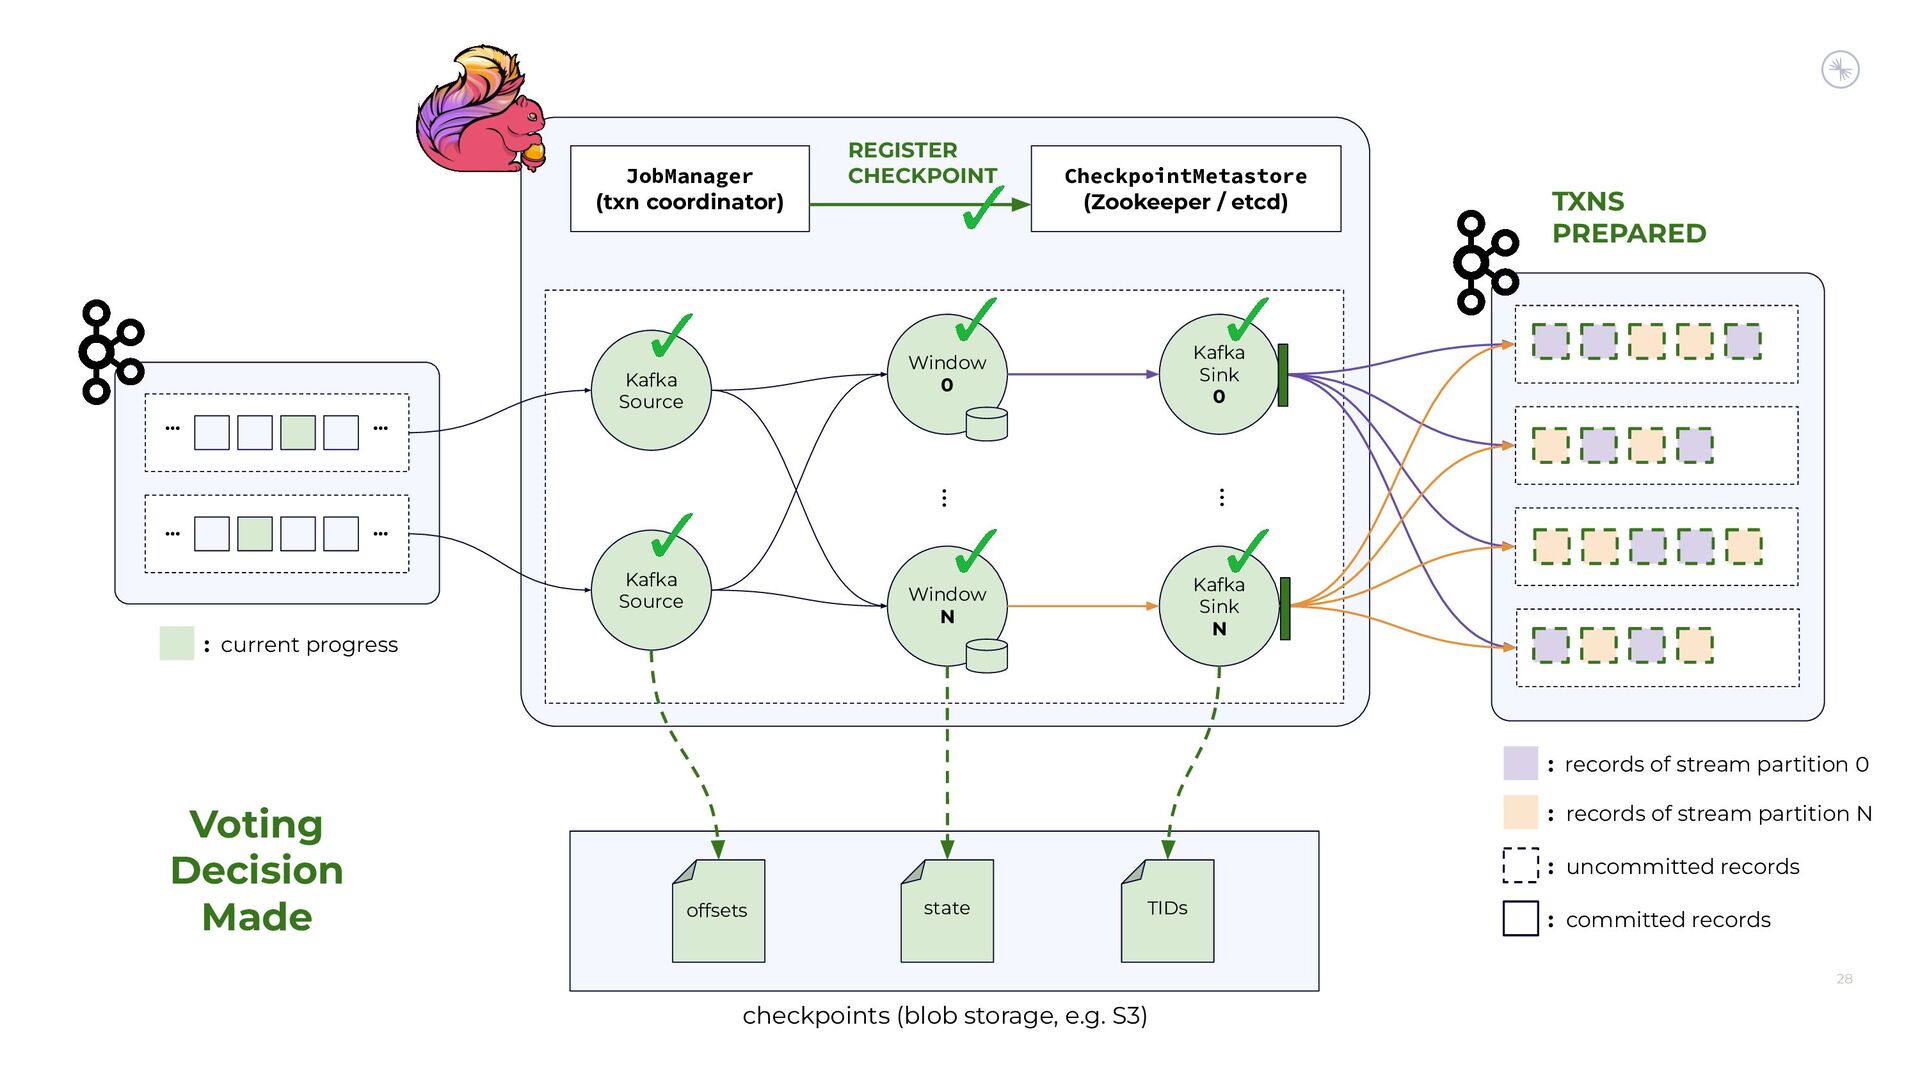
28 checkpoints (blob storage, e.g. S3) Kafka Source Kafka Source
JobManager (txn coordinator) CheckpointMetastore (Zookeeper / etcd) … Kafka Sink 0 Kafka Sink N … … … Window 0 Window N … … : records of stream partition 0 : records of stream partition N : uncommitted records : committed records : current progress offsets state TXNS PREPARED TIDs Voting Decision Made REGISTER CHECKPOINT -
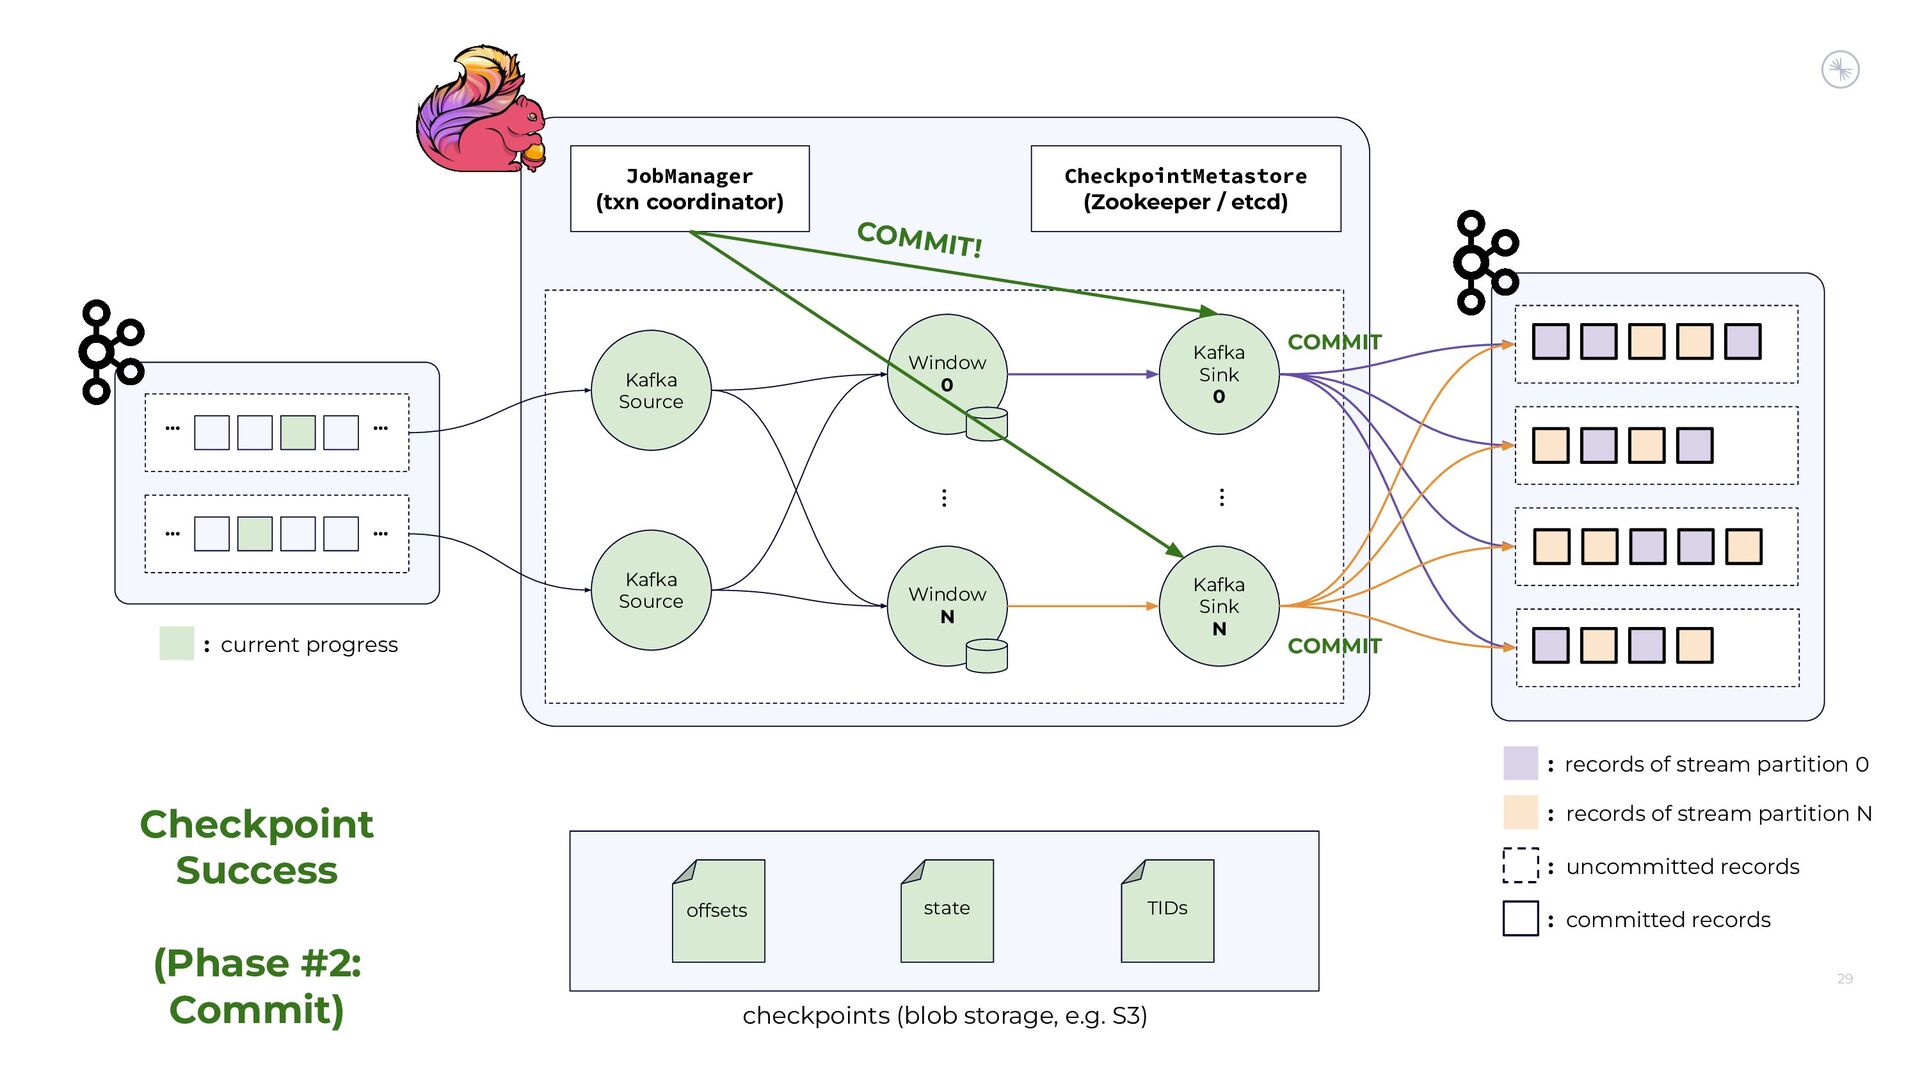
29 checkpoints (blob storage, e.g. S3) Kafka Source Kafka Source
JobManager (txn coordinator) CheckpointMetastore (Zookeeper / etcd) … Kafka Sink 0 Kafka Sink N … … … Window 0 Window N … … : records of stream partition 0 : records of stream partition N : uncommitted records : committed records : current progress offsets state TIDs Checkpoint Success (Phase #2: Commit) COMMIT! COMMIT COMMIT -
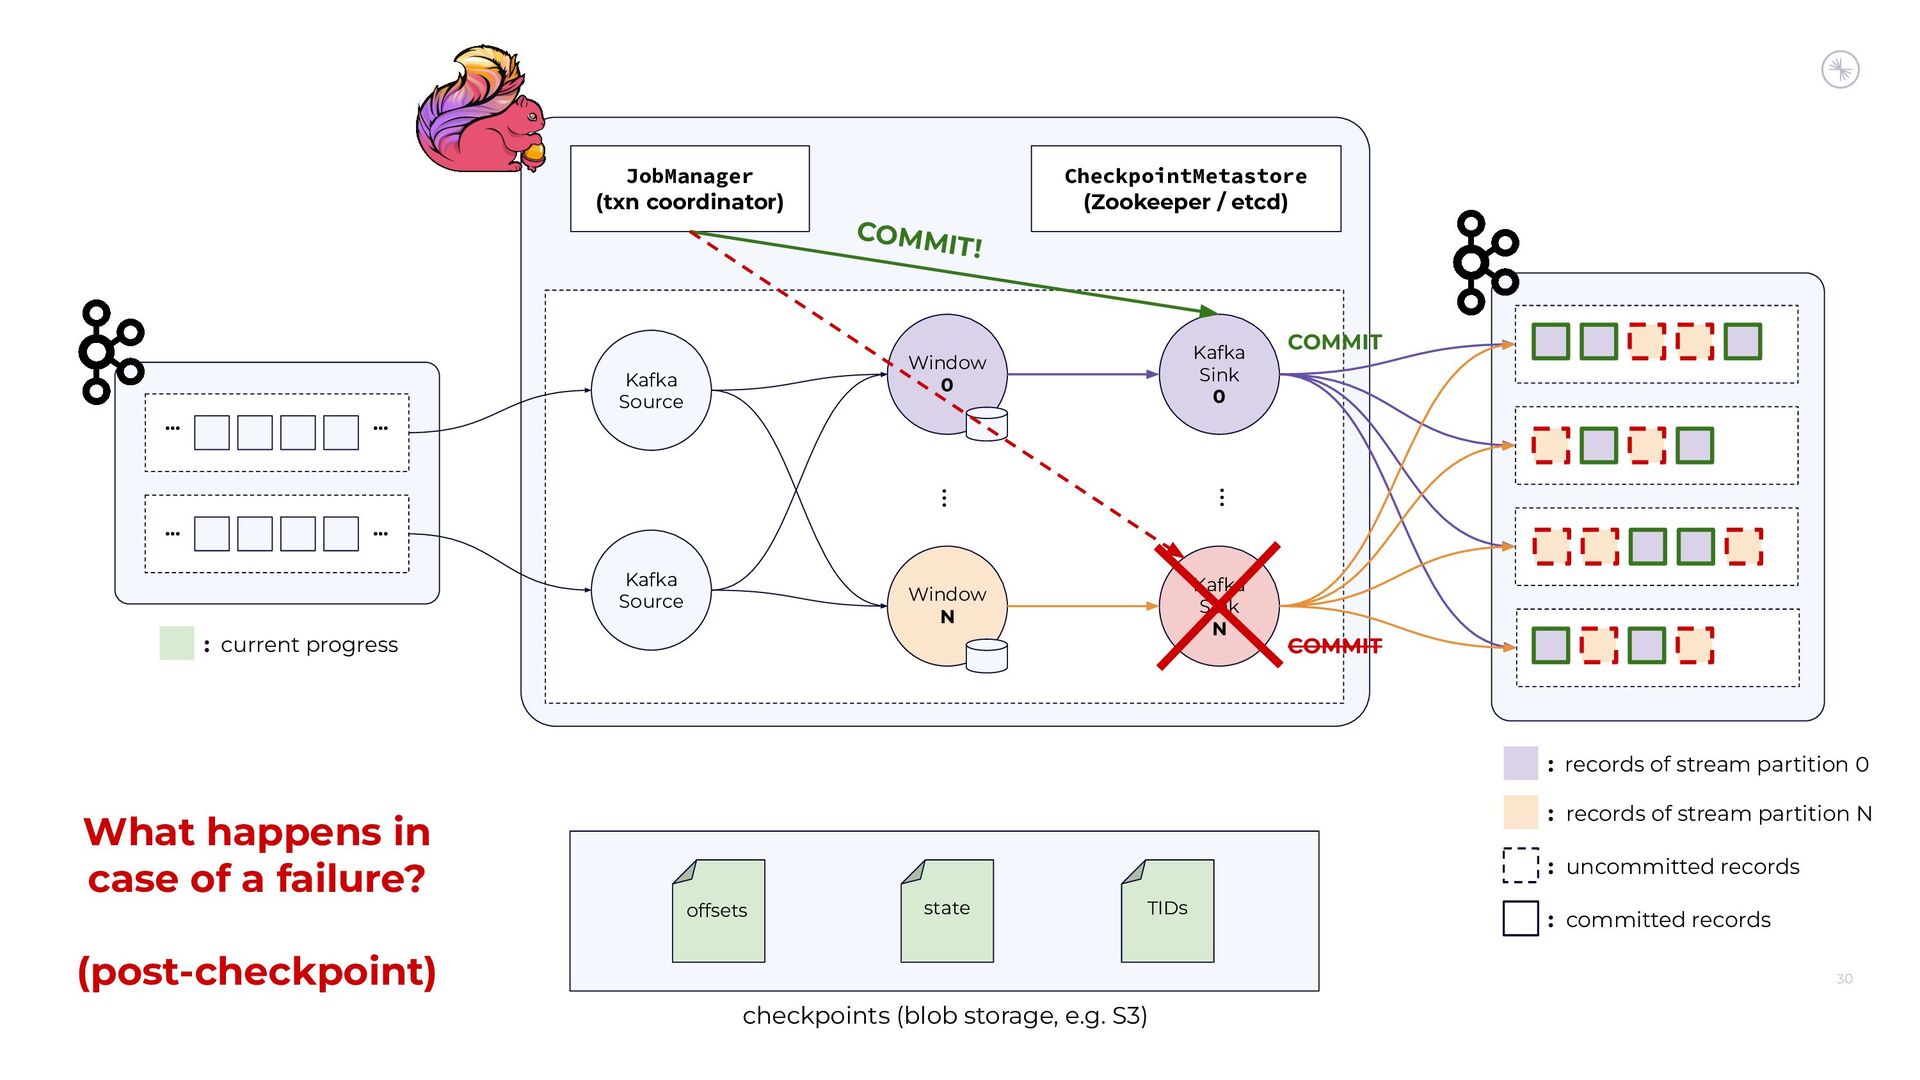
30 checkpoints (blob storage, e.g. S3) Kafka Source Kafka Source
JobManager (txn coordinator) CheckpointMetastore (Zookeeper / etcd) … Kafka Sink 0 Kafka Sink N … … … Window 0 Window N … … : records of stream partition 0 : records of stream partition N : uncommitted records : committed records : current progress offsets state TIDs What happens in case of a failure? (post-checkpoint) COMMIT! COMMIT COMMIT -
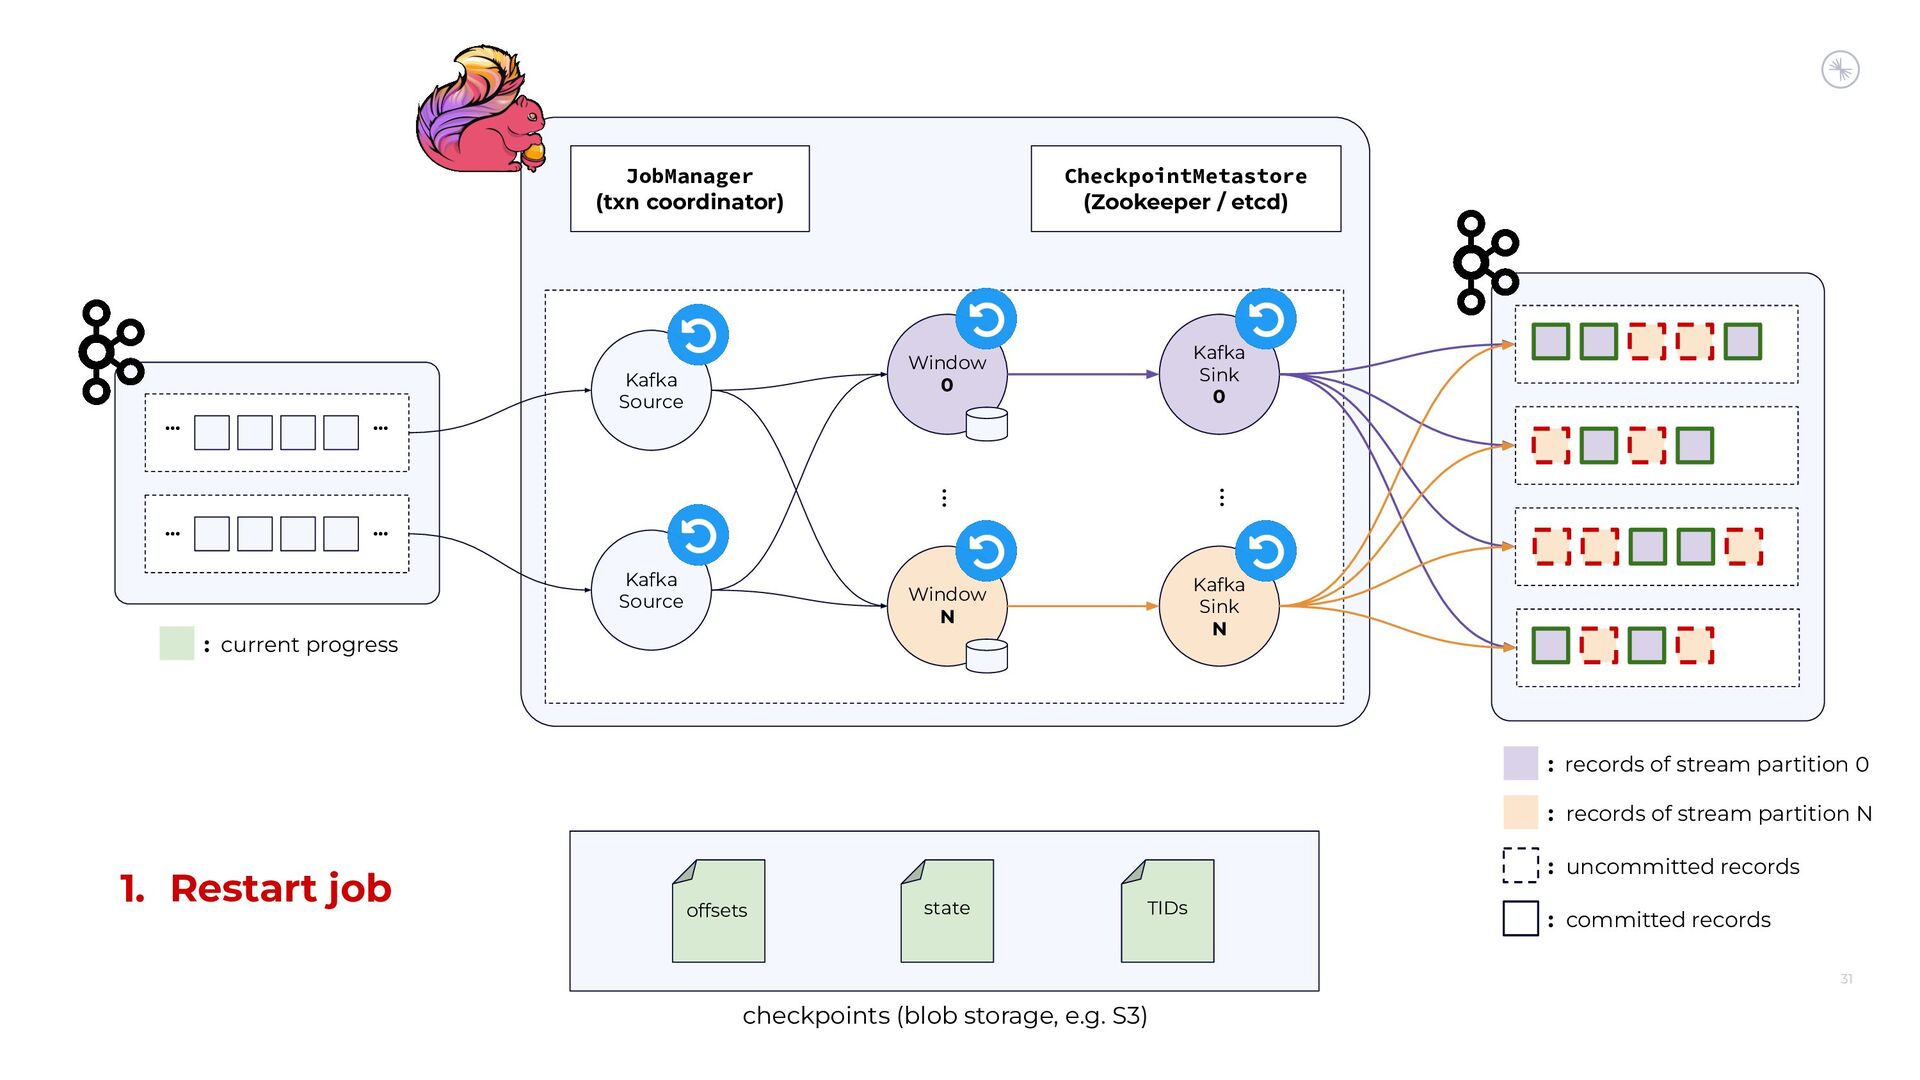
31 checkpoints (blob storage, e.g. S3) Kafka Source Kafka Source
JobManager (txn coordinator) CheckpointMetastore (Zookeeper / etcd) … Kafka Sink 0 Kafka Sink N … … … Window 0 Window N … … : records of stream partition 0 : records of stream partition N : uncommitted records : committed records : current progress offsets state TIDs 1. Restart job -
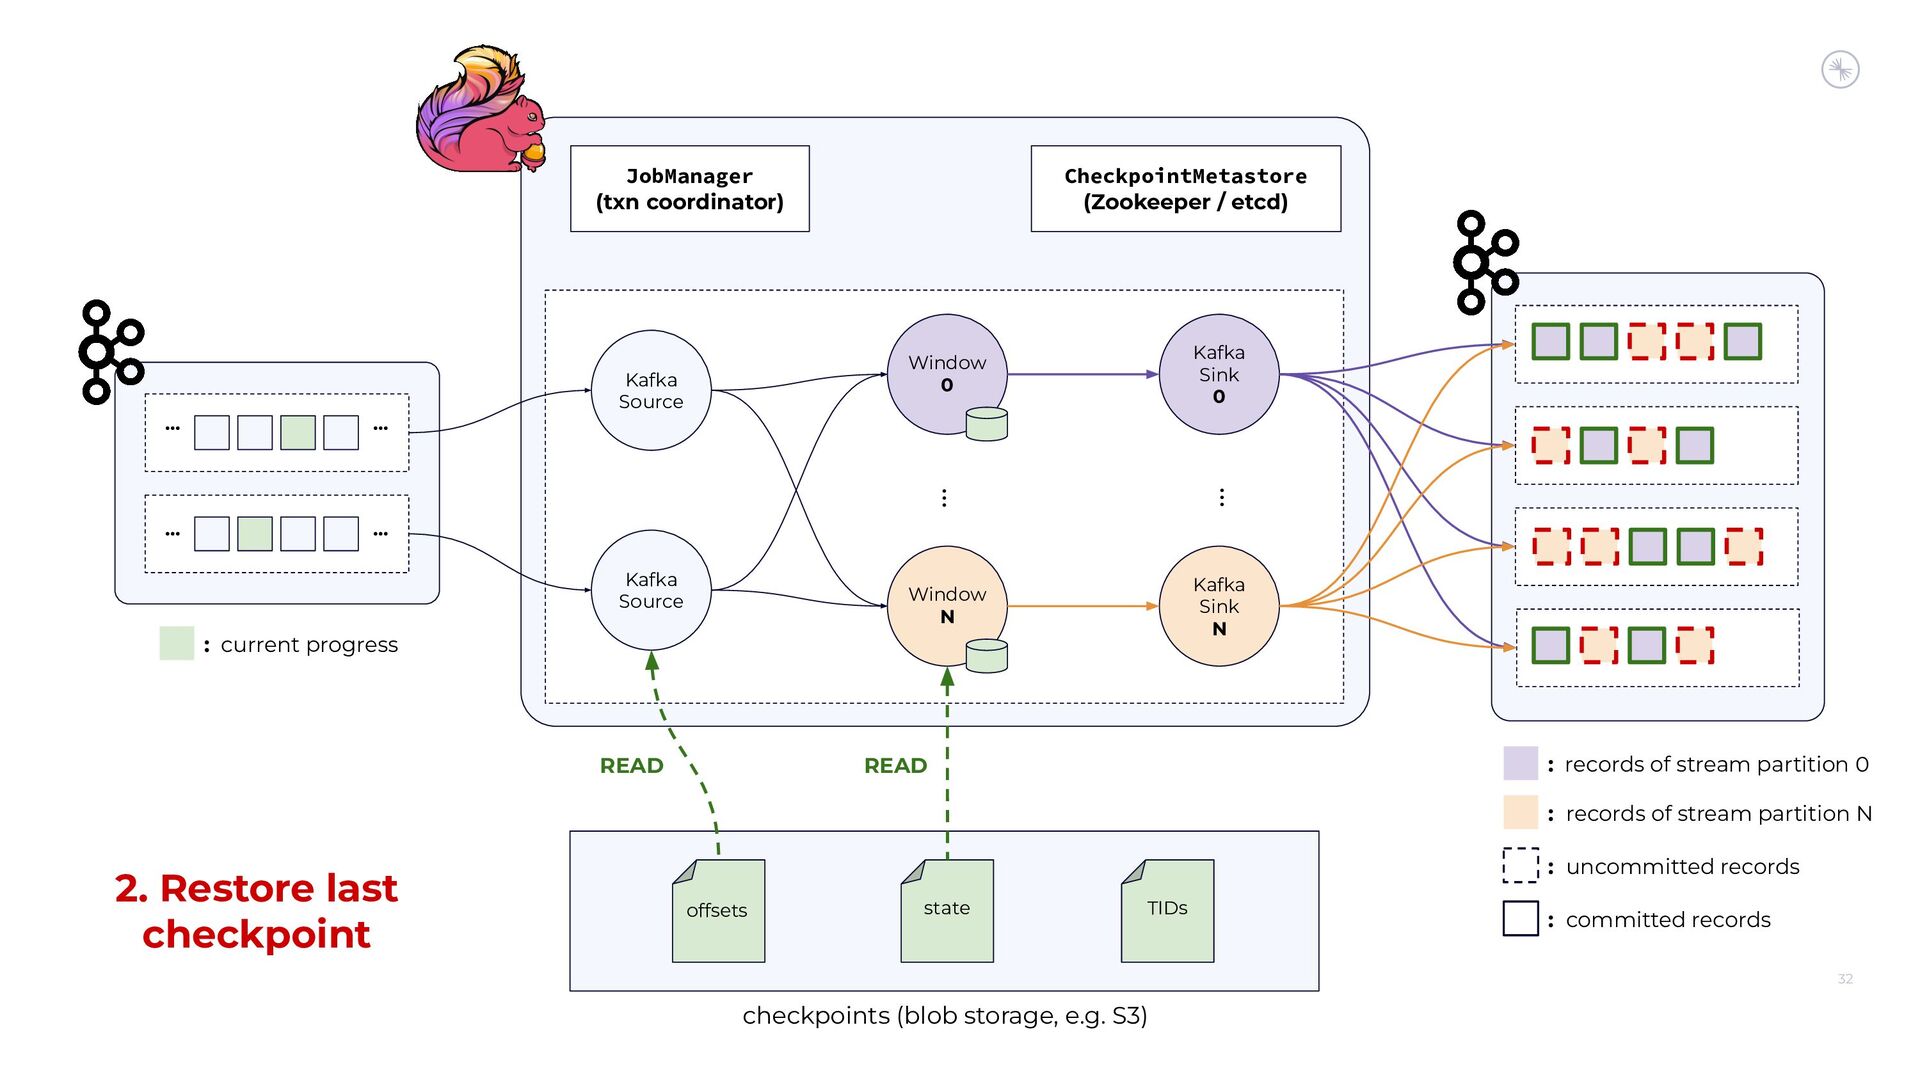
32 checkpoints (blob storage, e.g. S3) Kafka Source Kafka Source
JobManager (txn coordinator) CheckpointMetastore (Zookeeper / etcd) … Kafka Sink 0 Kafka Sink N … … … Window 0 Window N … … : records of stream partition 0 : records of stream partition N : uncommitted records : committed records : current progress offsets state TIDs 2. Restore last checkpoint READ READ -
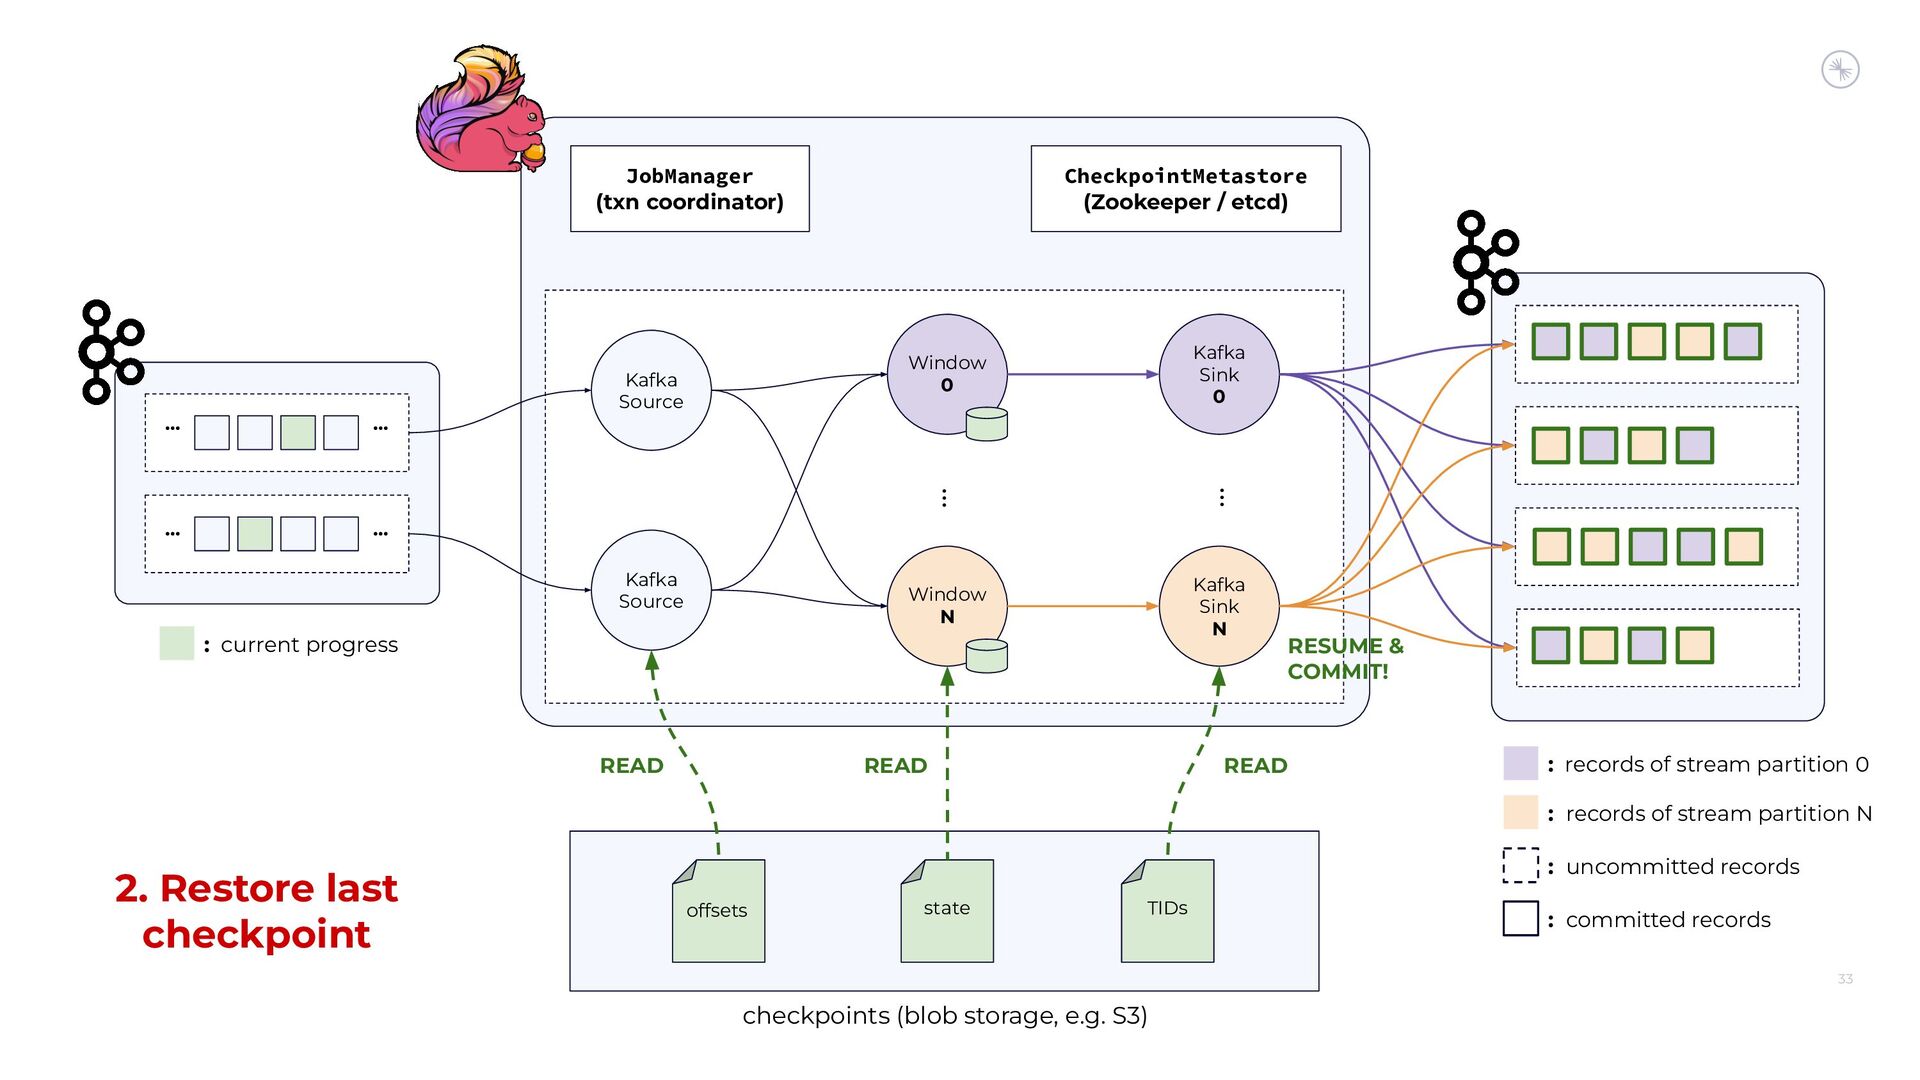
33 checkpoints (blob storage, e.g. S3) Kafka Source Kafka Source
JobManager (txn coordinator) CheckpointMetastore (Zookeeper / etcd) … Kafka Sink 0 Kafka Sink N … … … Window 0 Window N … … : records of stream partition 0 : records of stream partition N : uncommitted records : committed records : current progress offsets state TIDs 2. Restore last checkpoint READ READ READ RESUME & COMMIT! -
35 Problem #1: In-doubt transactions can be aborted by Kafka,
outside of Flink’s control -
36 transaction.timeout.ms Kafka config • Timeout period after the first
write to an open transaction, before it gets auto aborted • Default value: 15 minutes • Provides the means to prevent LSO getting stuck due to permanently failed producers -
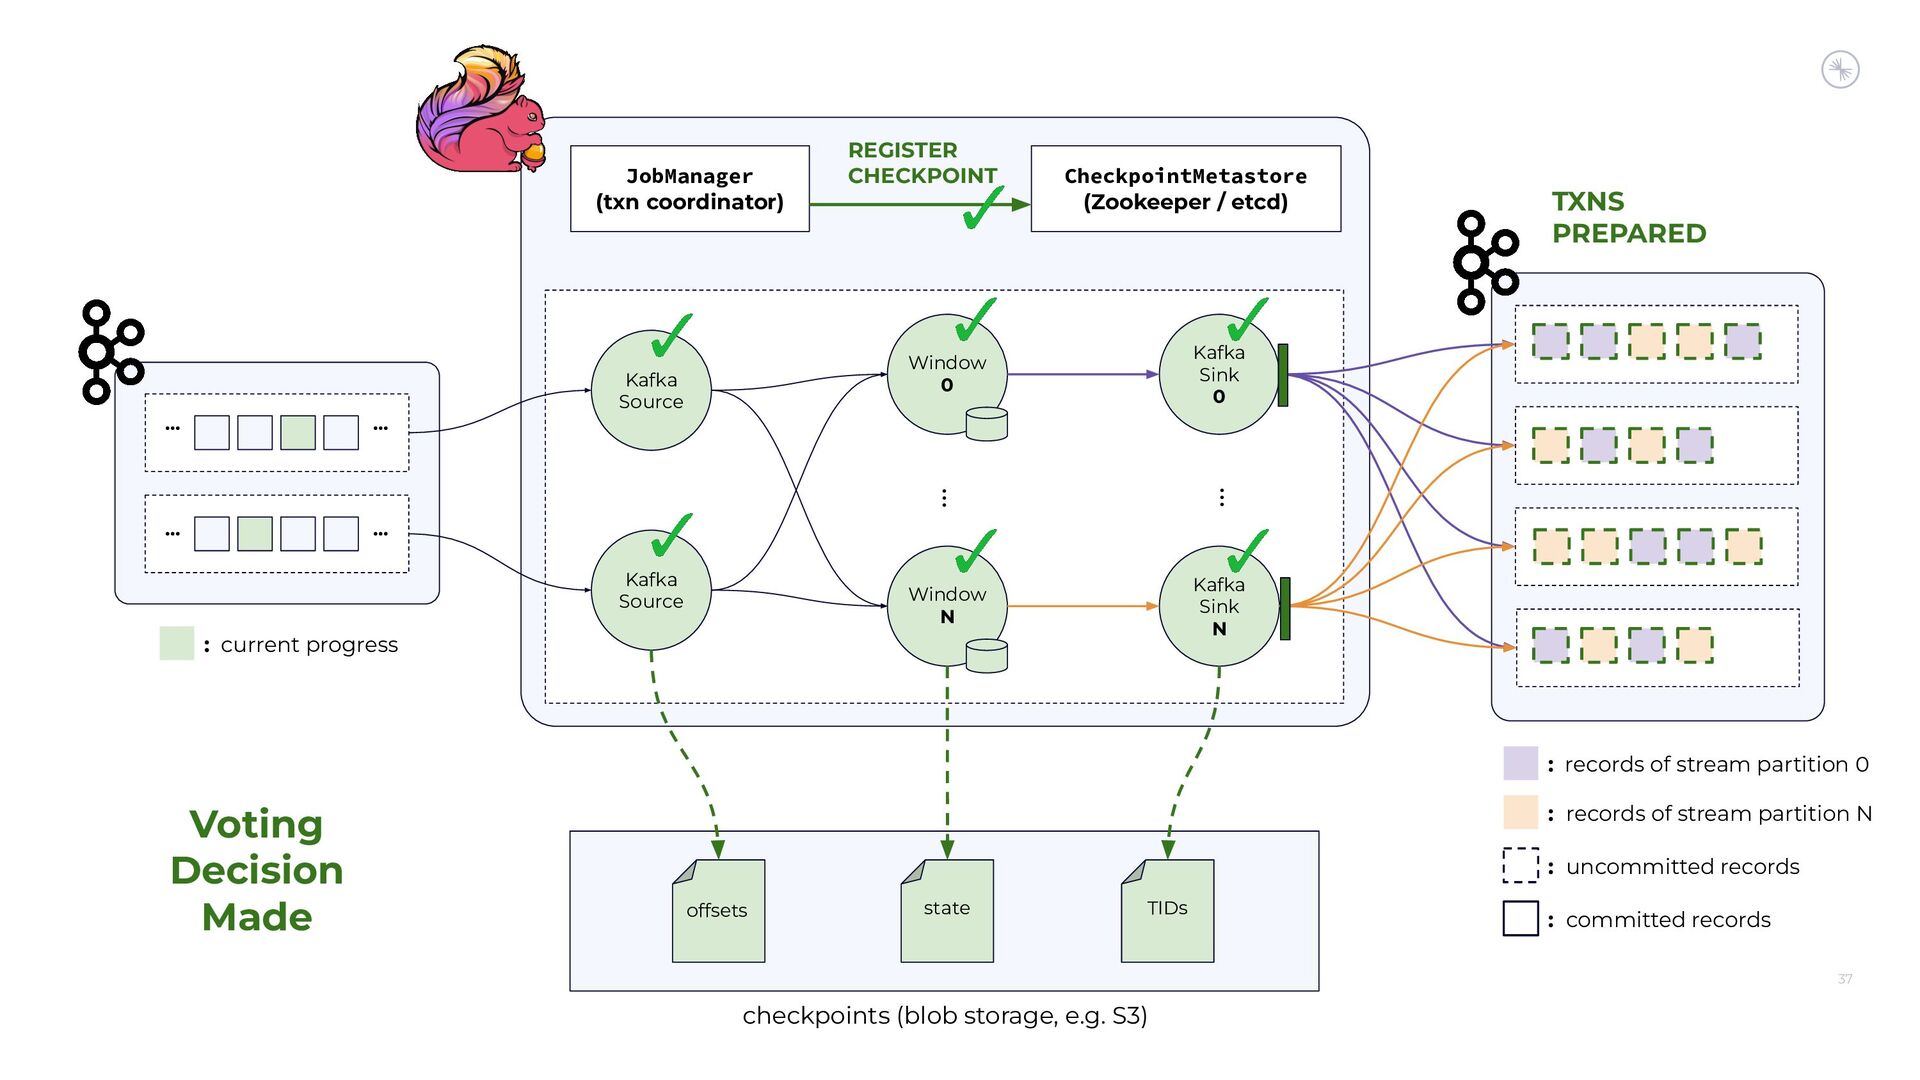
37 checkpoints (blob storage, e.g. S3) Kafka Source Kafka Source
JobManager (txn coordinator) CheckpointMetastore (Zookeeper / etcd) … Kafka Sink 0 Kafka Sink N … … … Window 0 Window N … … : records of stream partition 0 : records of stream partition N : uncommitted records : committed records : current progress offsets state TXNS PREPARED TIDs Voting Decision Made REGISTER CHECKPOINT -
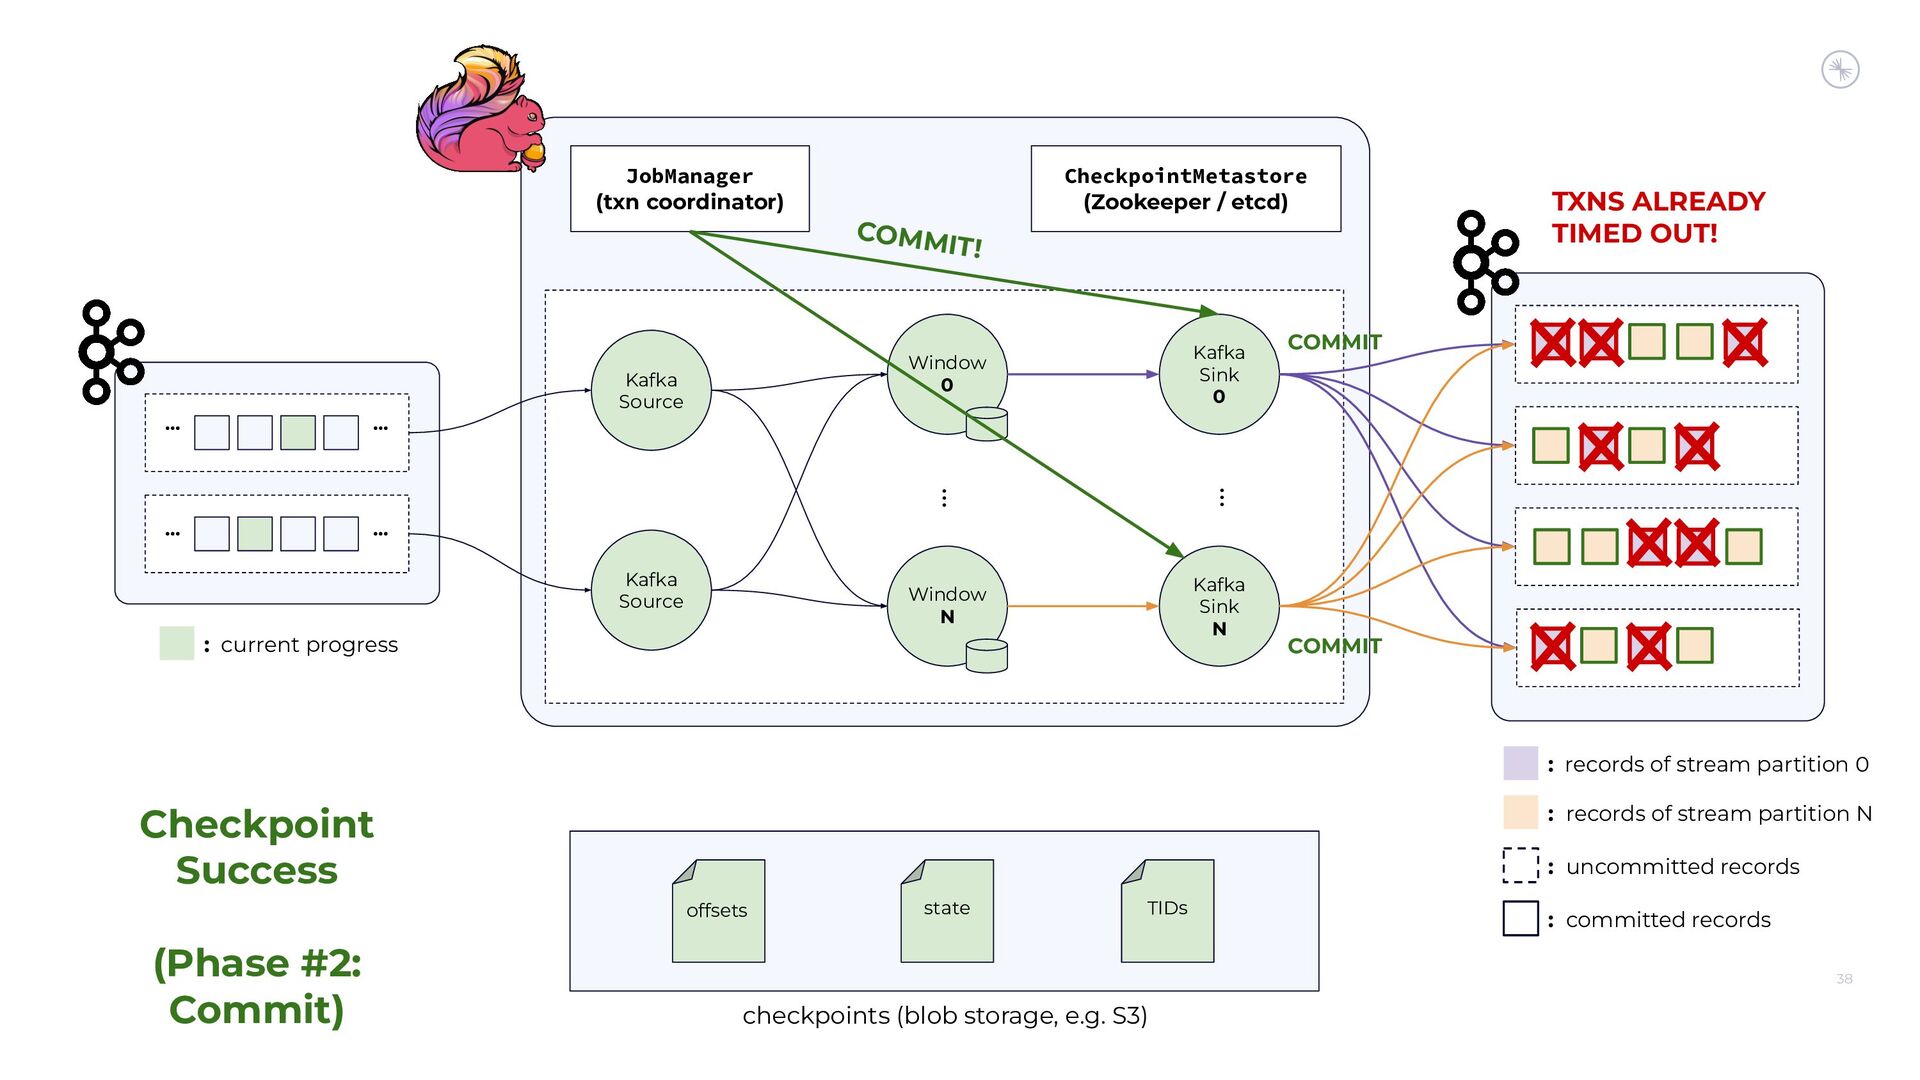
38 checkpoints (blob storage, e.g. S3) Kafka Source Kafka Source
JobManager (txn coordinator) CheckpointMetastore (Zookeeper / etcd) … Kafka Sink 0 Kafka Sink N … … … Window 0 Window N … … : records of stream partition 0 : records of stream partition N : uncommitted records : committed records : current progress offsets state TIDs Checkpoint Success (Phase #2: Commit) COMMIT! COMMIT COMMIT TXNS ALREADY TIMED OUT! -
39 Suggested mitigations (so far) • Set transaction.timeout.ms to be
as large as possible (capped by broker-side config) • No matter how large you set it, there’s always some possibility of inconsistency -
41 checkpoints (blob storage, e.g. S3) Kafka Source Kafka Source
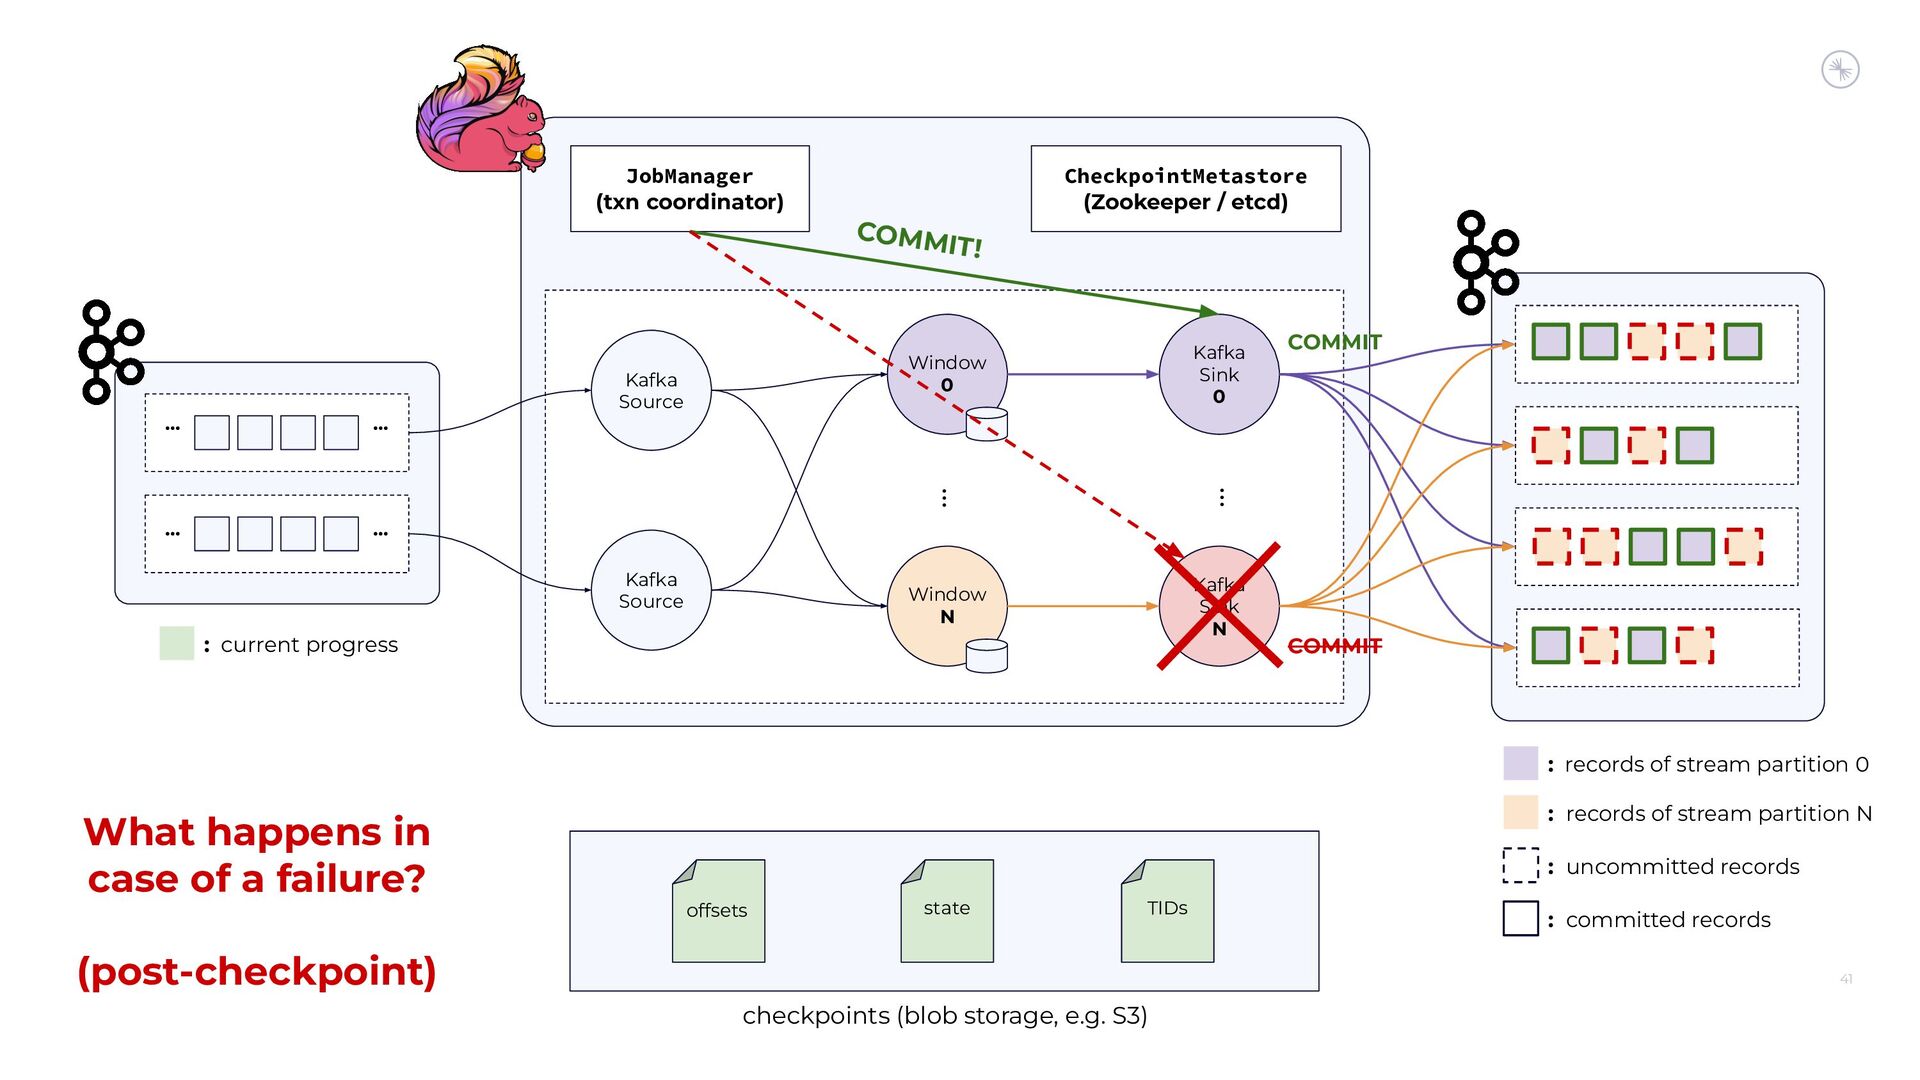
JobManager (txn coordinator) CheckpointMetastore (Zookeeper / etcd) … Kafka Sink 0 Kafka Sink N … … … Window 0 Window N … … : records of stream partition 0 : records of stream partition N : uncommitted records : committed records : current progress offsets state TIDs What happens in case of a failure? (post-checkpoint) COMMIT! COMMIT COMMIT -
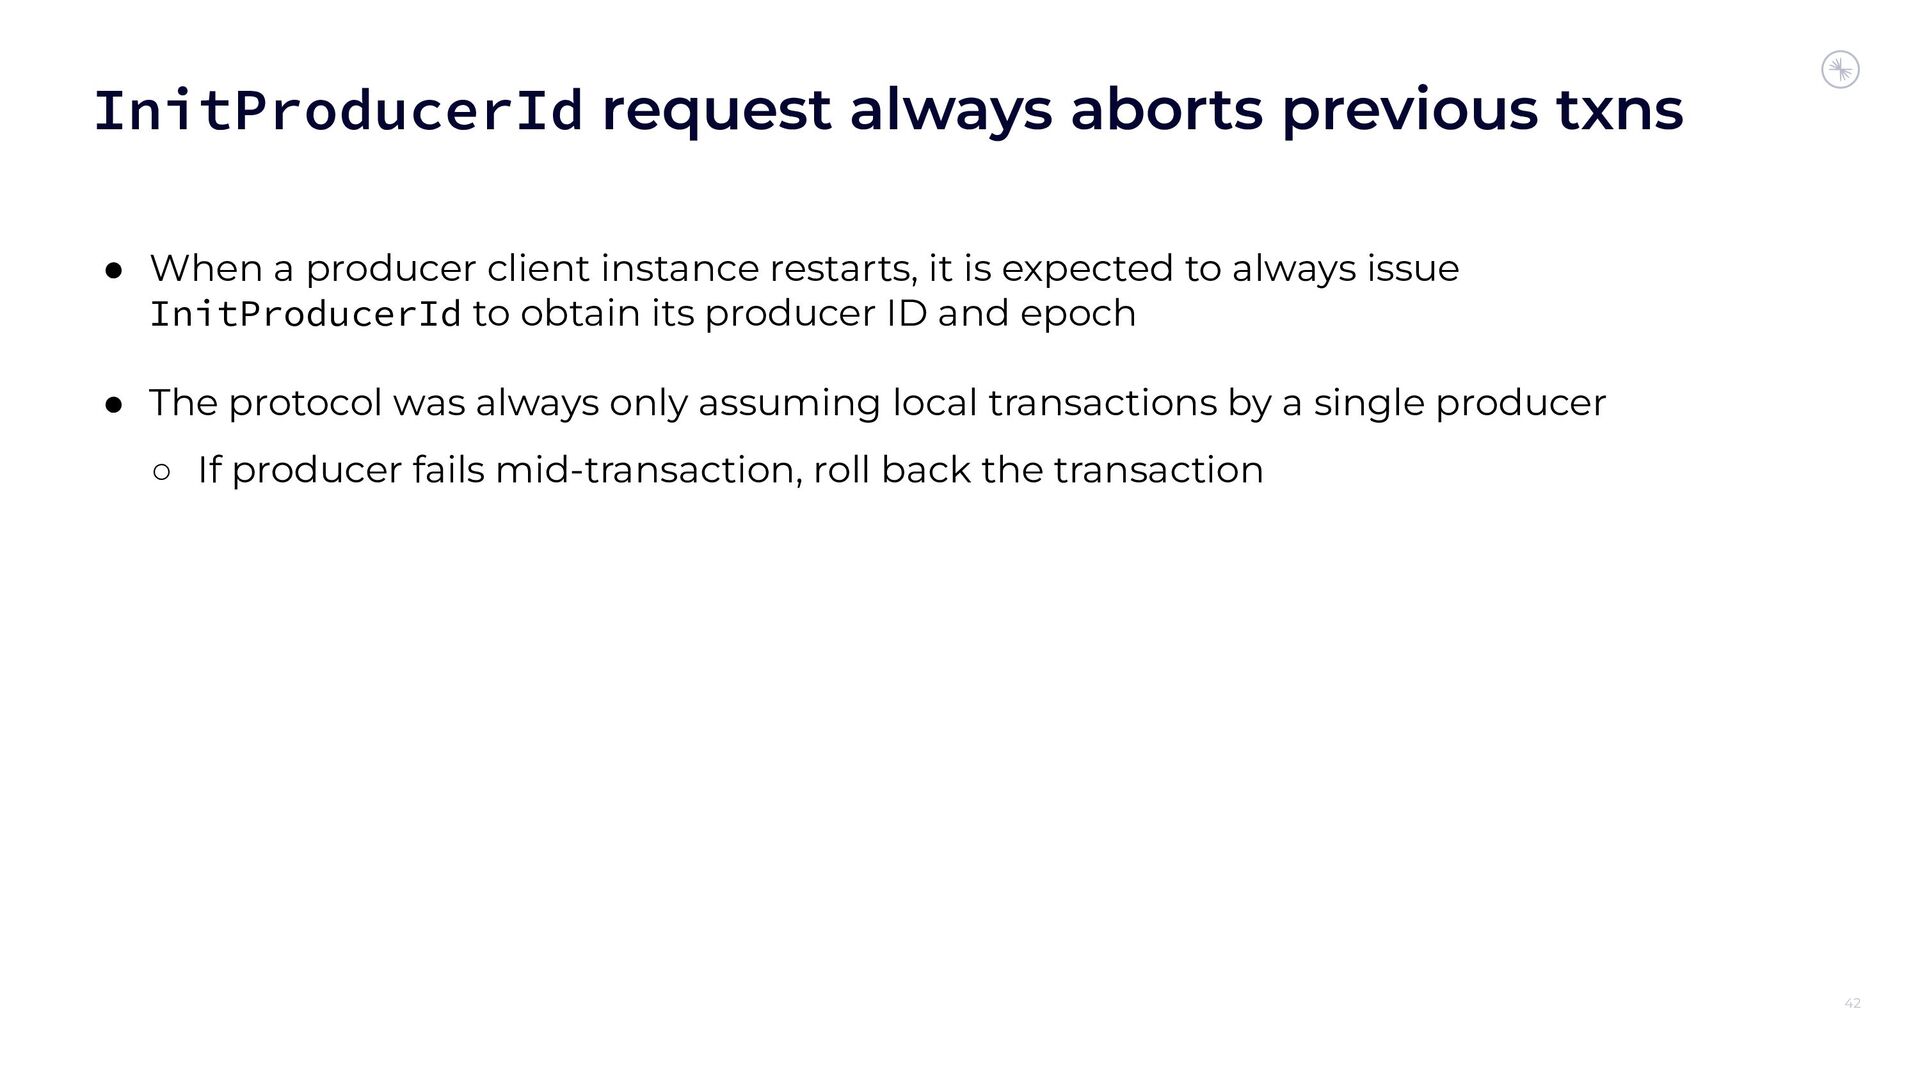
42 • When a producer client instance restarts, it is
expected to always issue InitProducerId to obtain its producer ID and epoch • The protocol was always only assuming local transactions by a single producer ◦ If producer fails mid-transaction, roll back the transaction InitProducerId request always aborts previous txns -
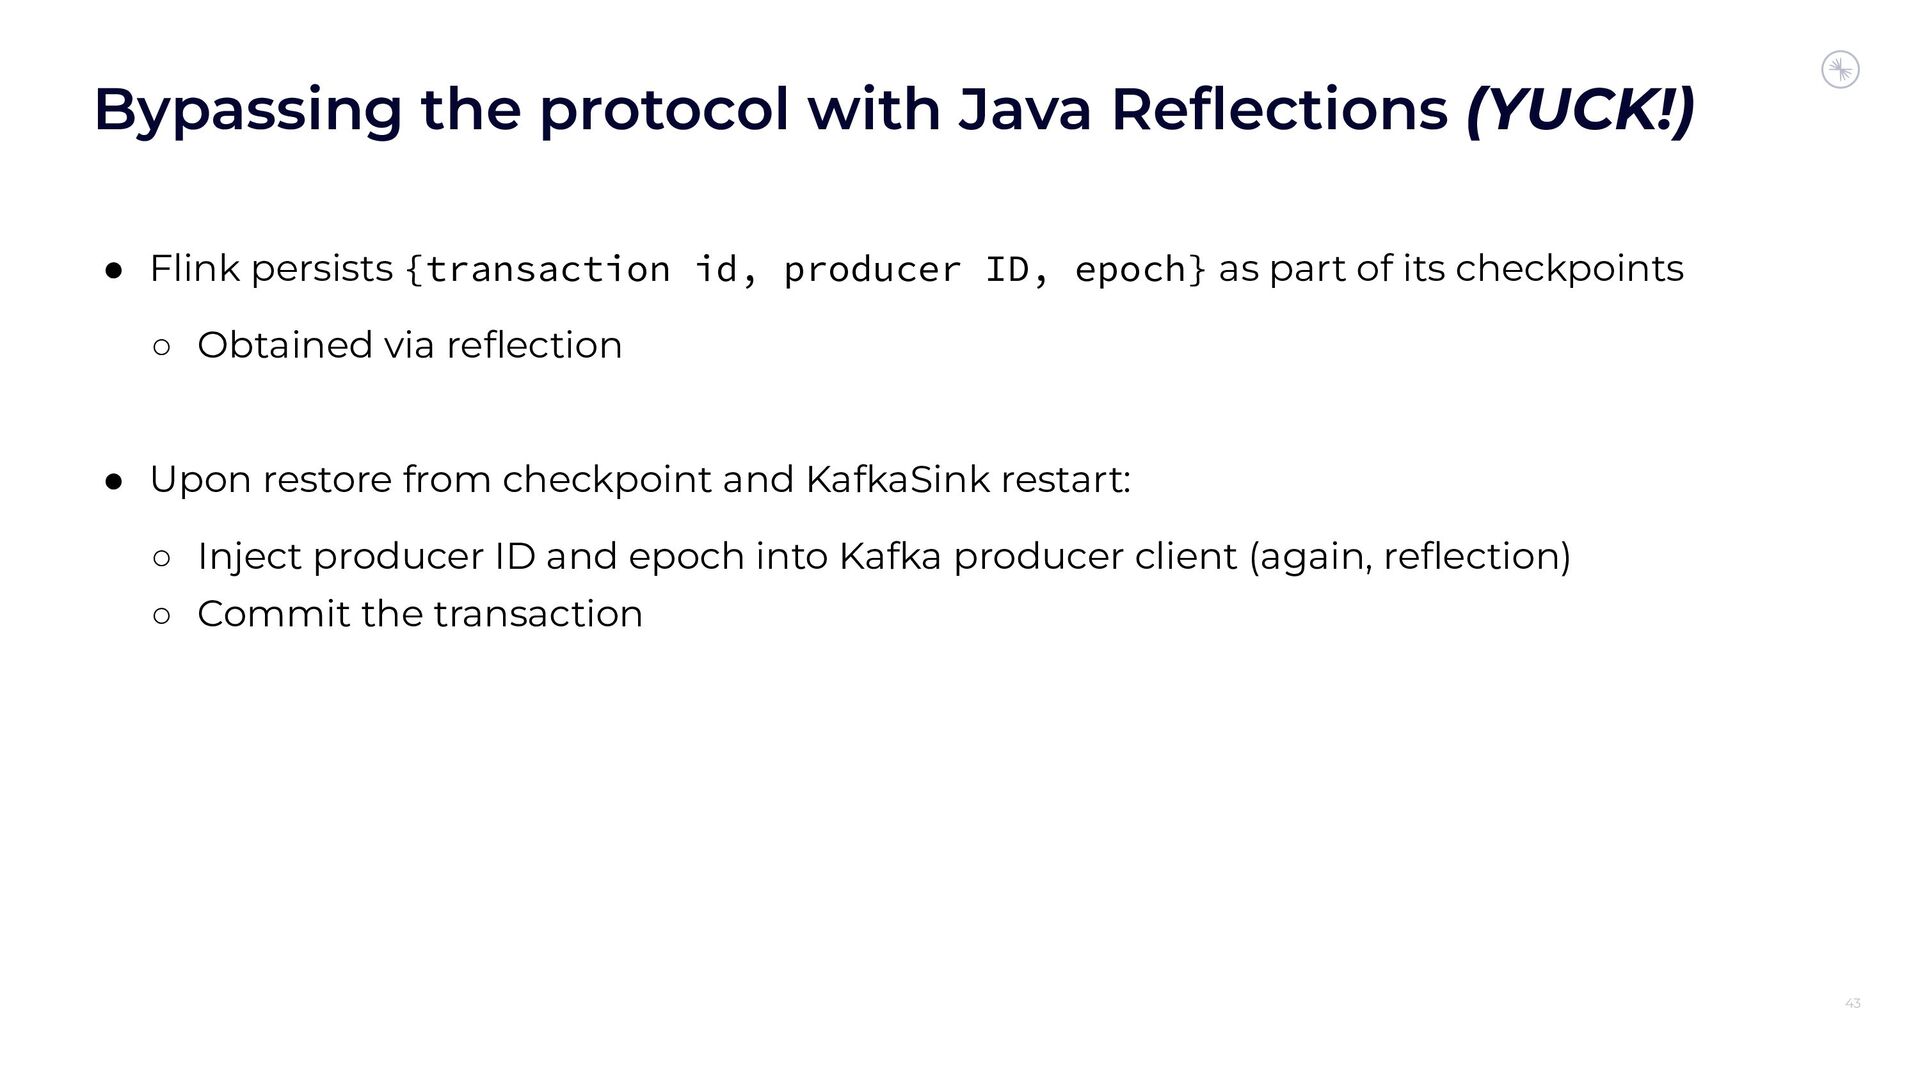
43 Bypassing the protocol with Java Reflections (YUCK!) • Flink
persists {transaction id, producer ID, epoch} as part of its checkpoints ◦ Obtained via reflection • Upon restore from checkpoint and KafkaSink restart: ◦ Inject producer ID and epoch into Kafka producer client (again, reflection) ◦ Commit the transaction -
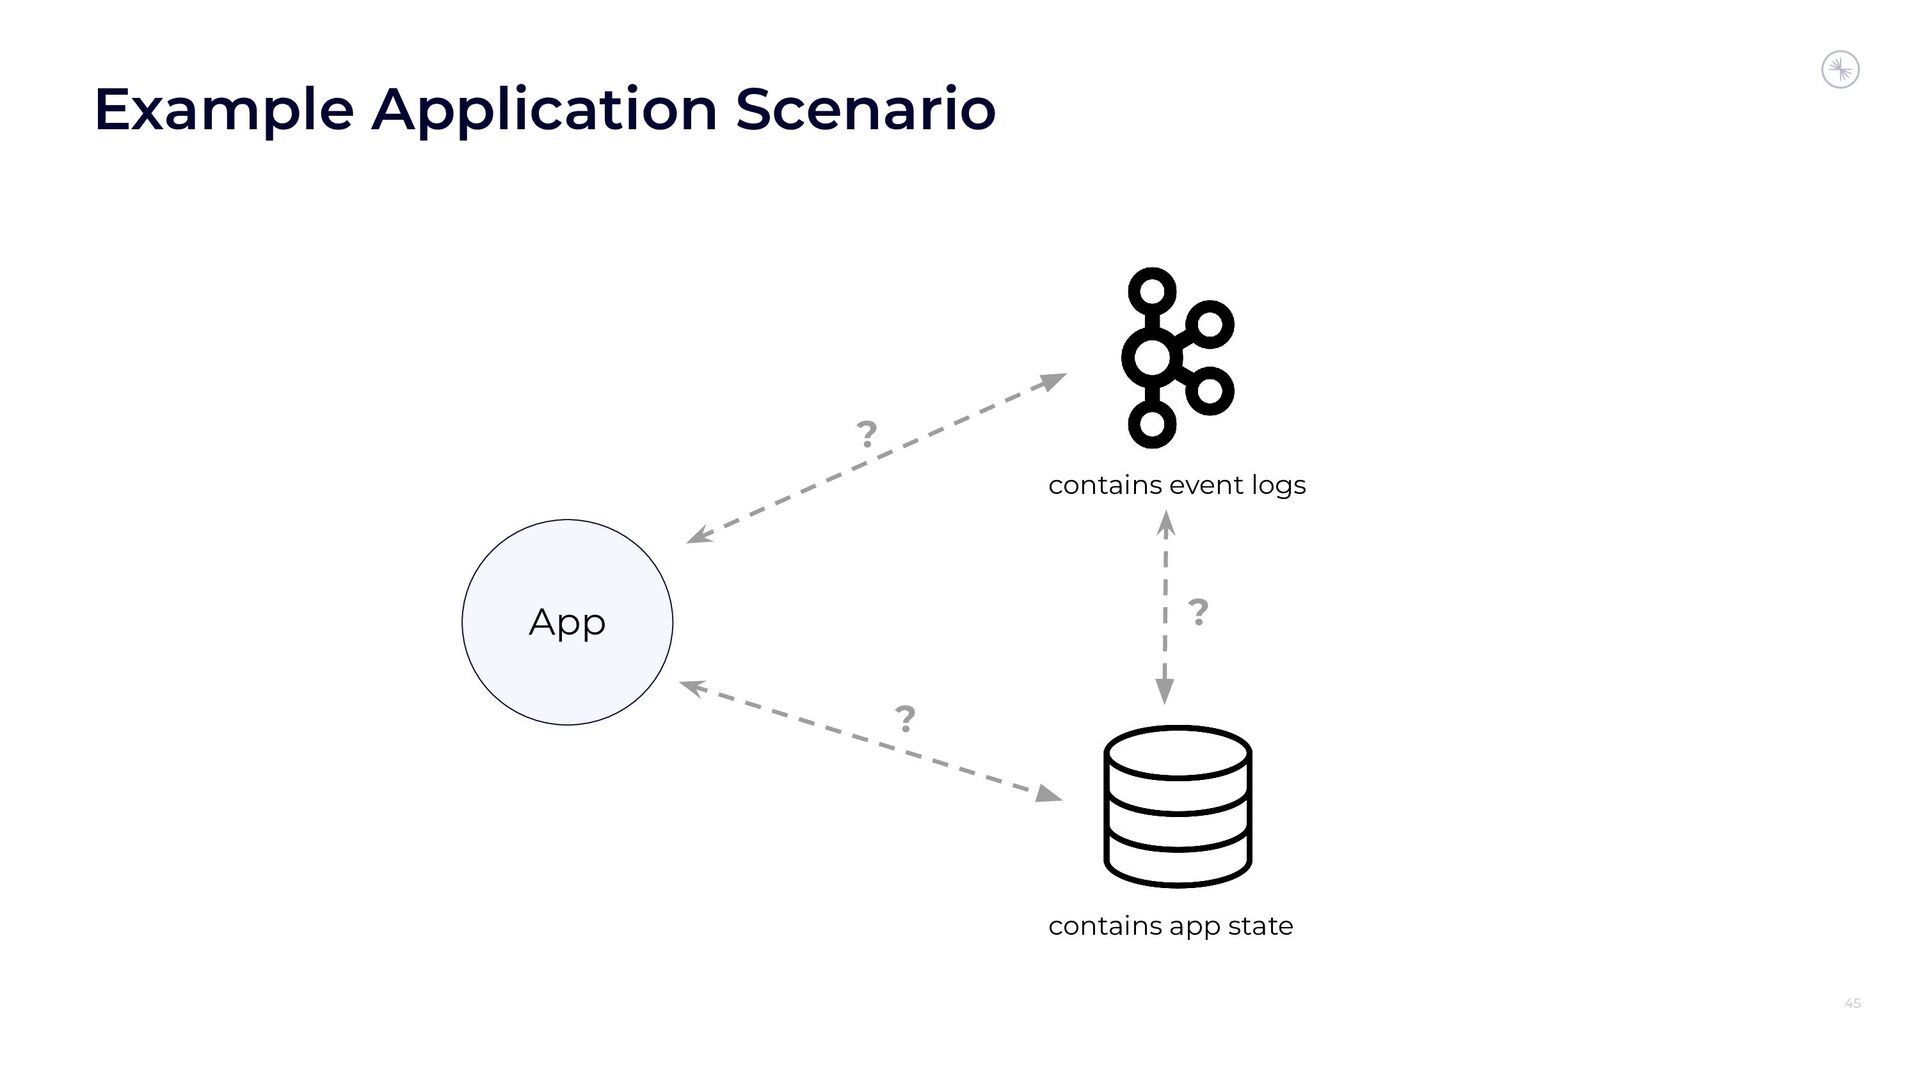
45 Example Application Scenario ? ? App contains event logs
contains app state ? -
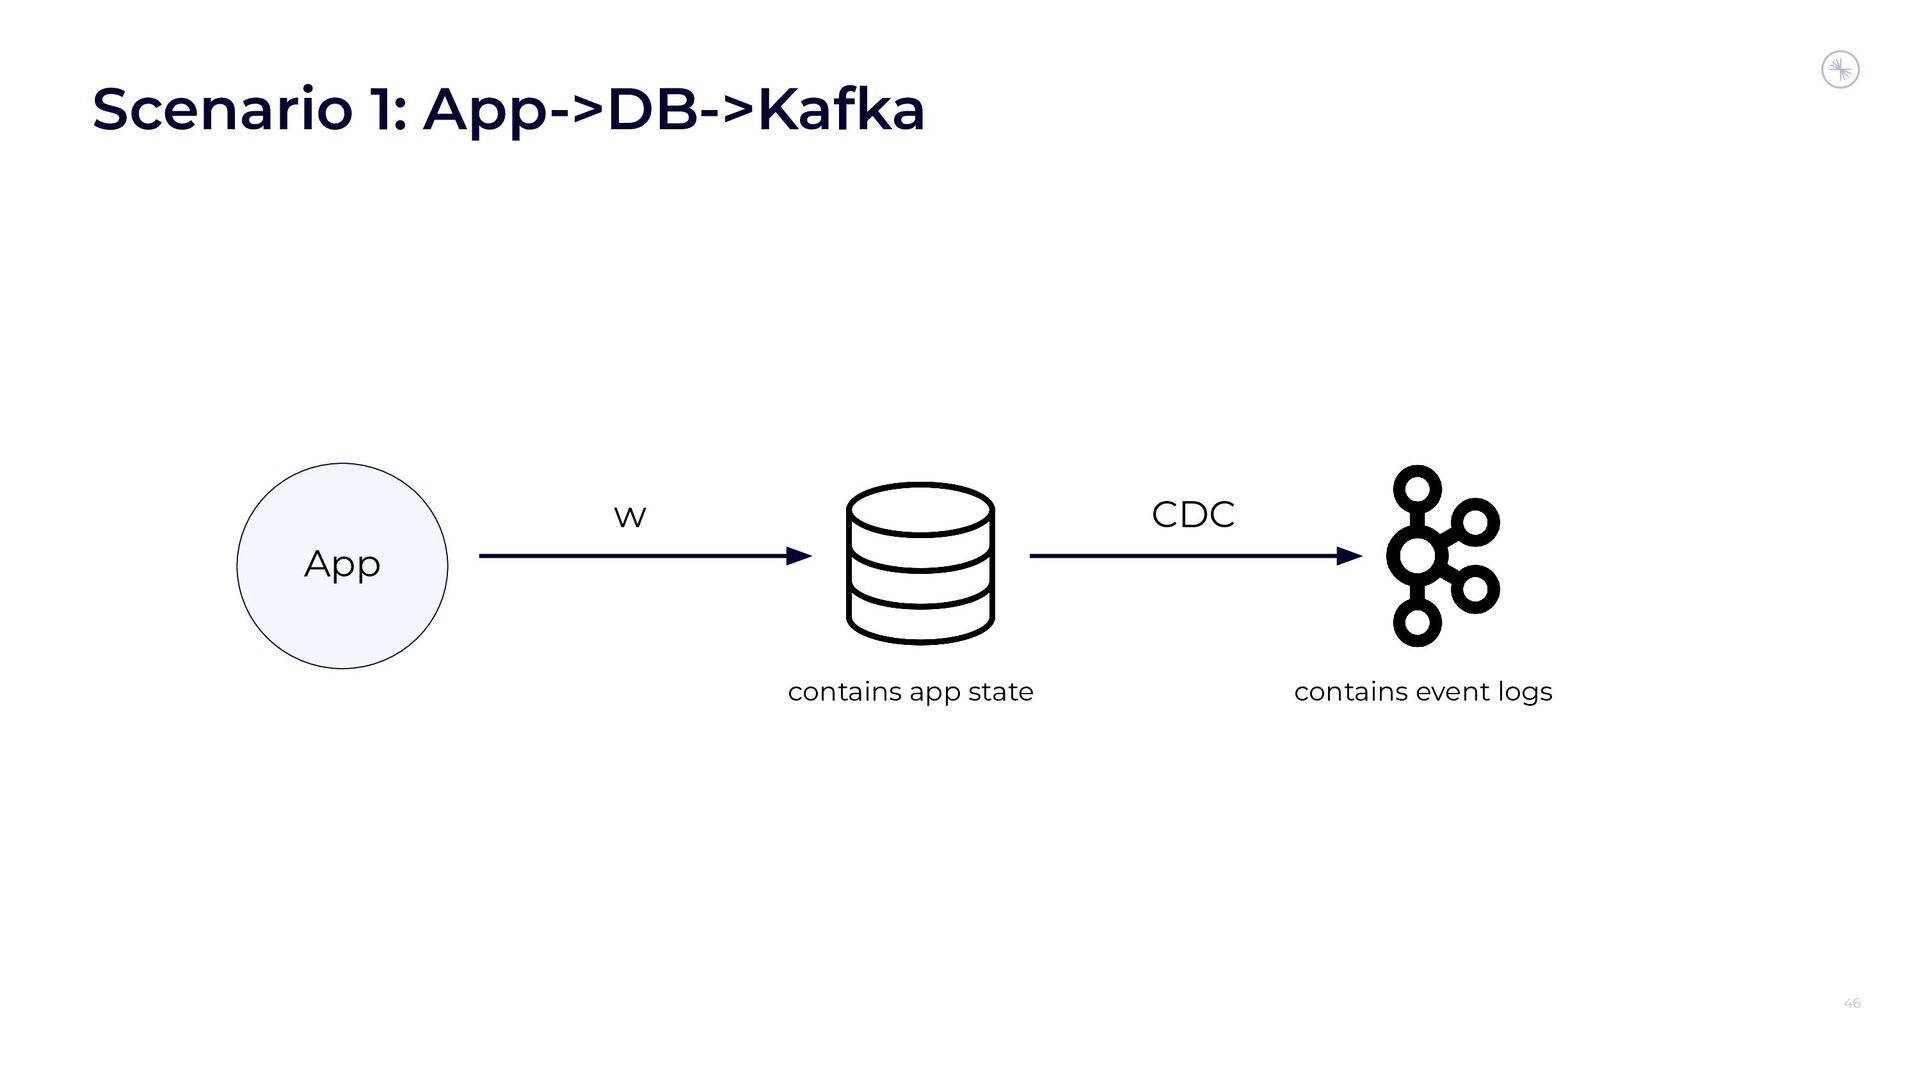
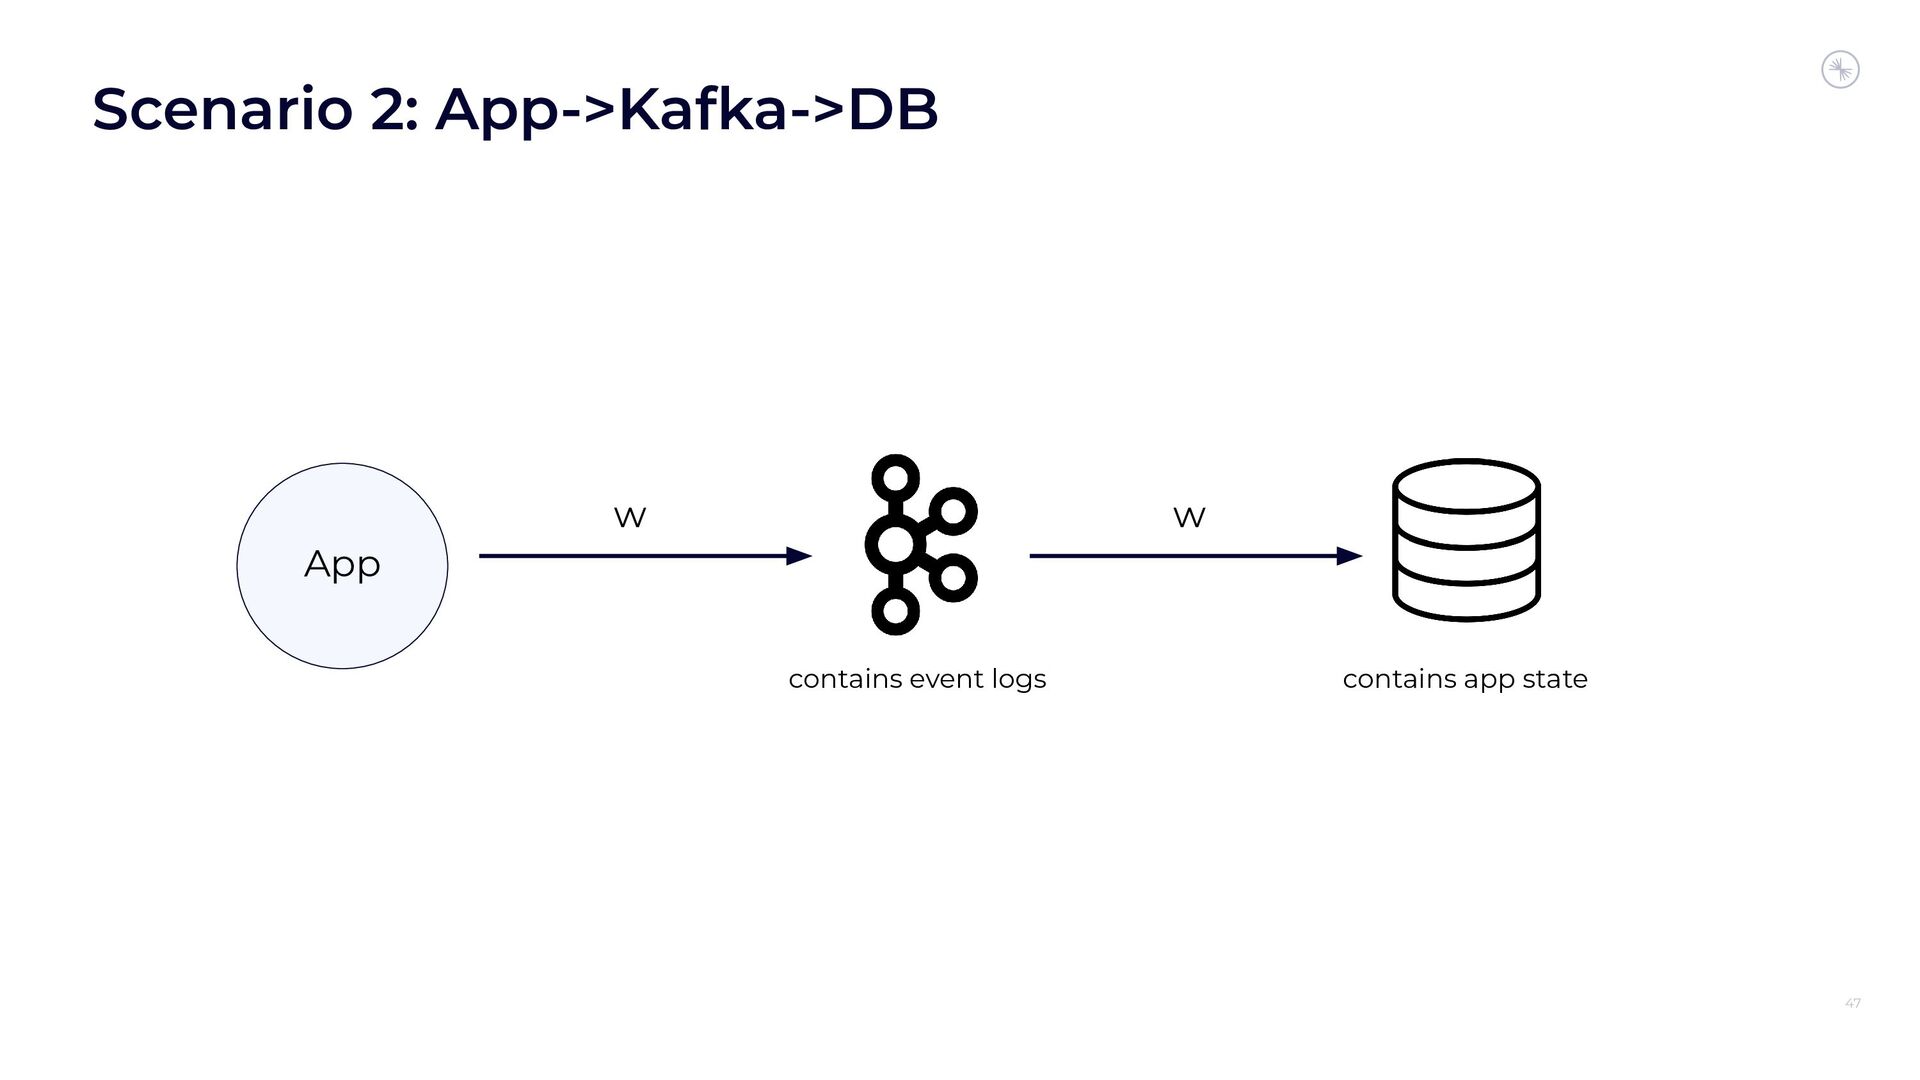
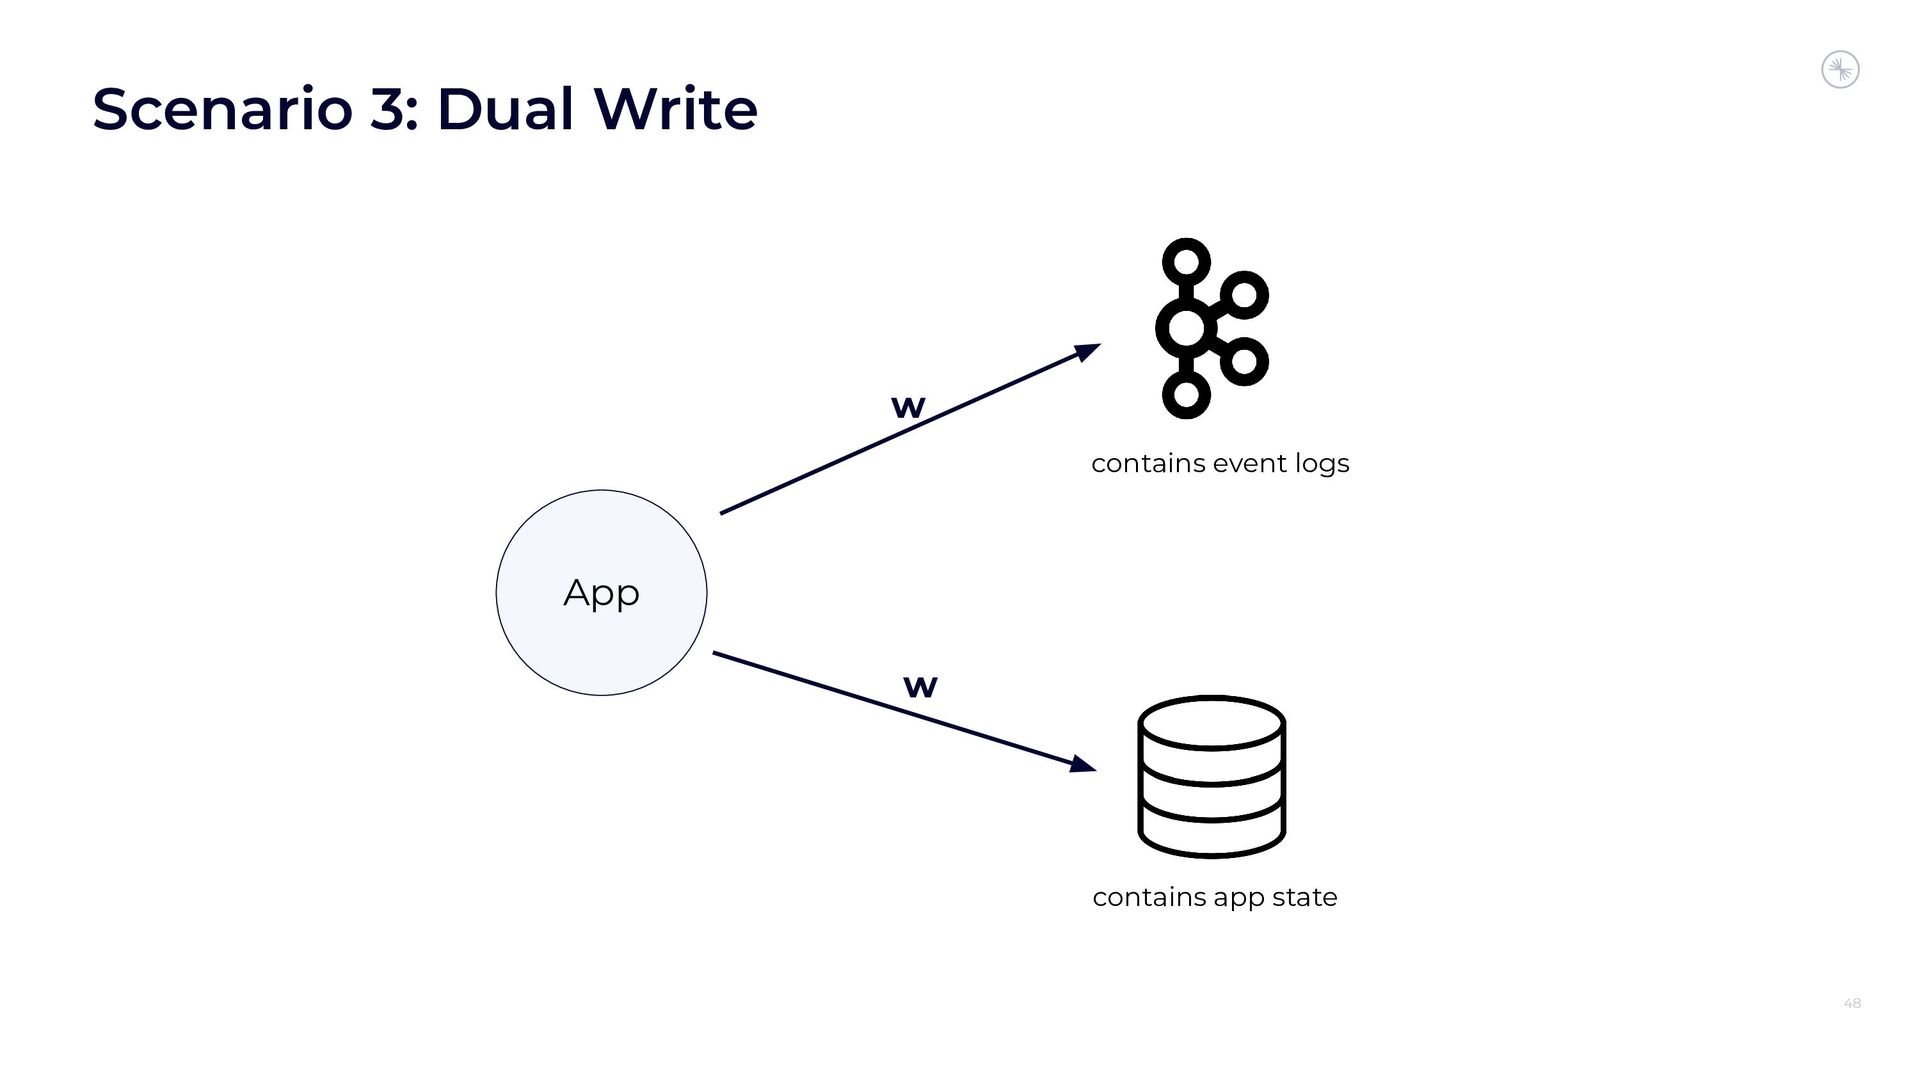
48 Scenario 3: Dual Write w w App contains event
logs contains app state -
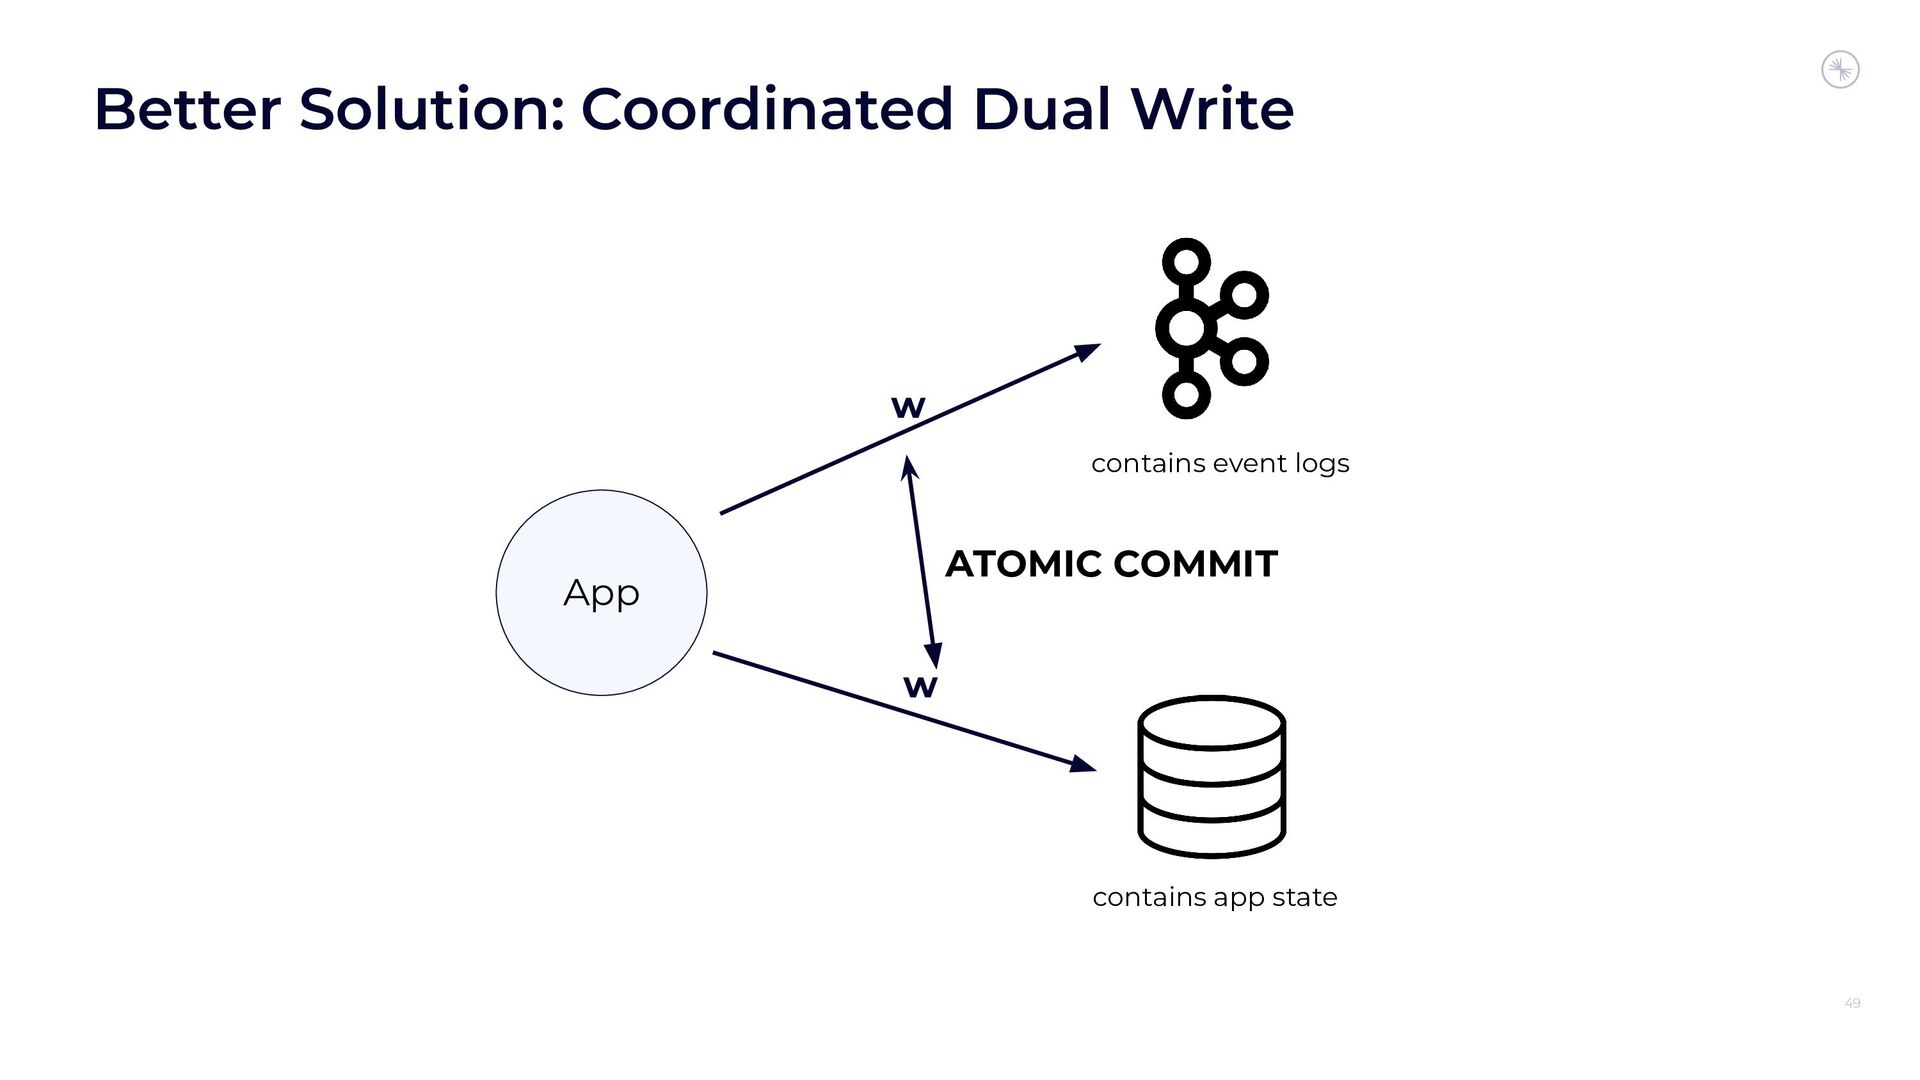
49 Better Solution: Coordinated Dual Write w w ATOMIC COMMIT
App contains event logs contains app state -
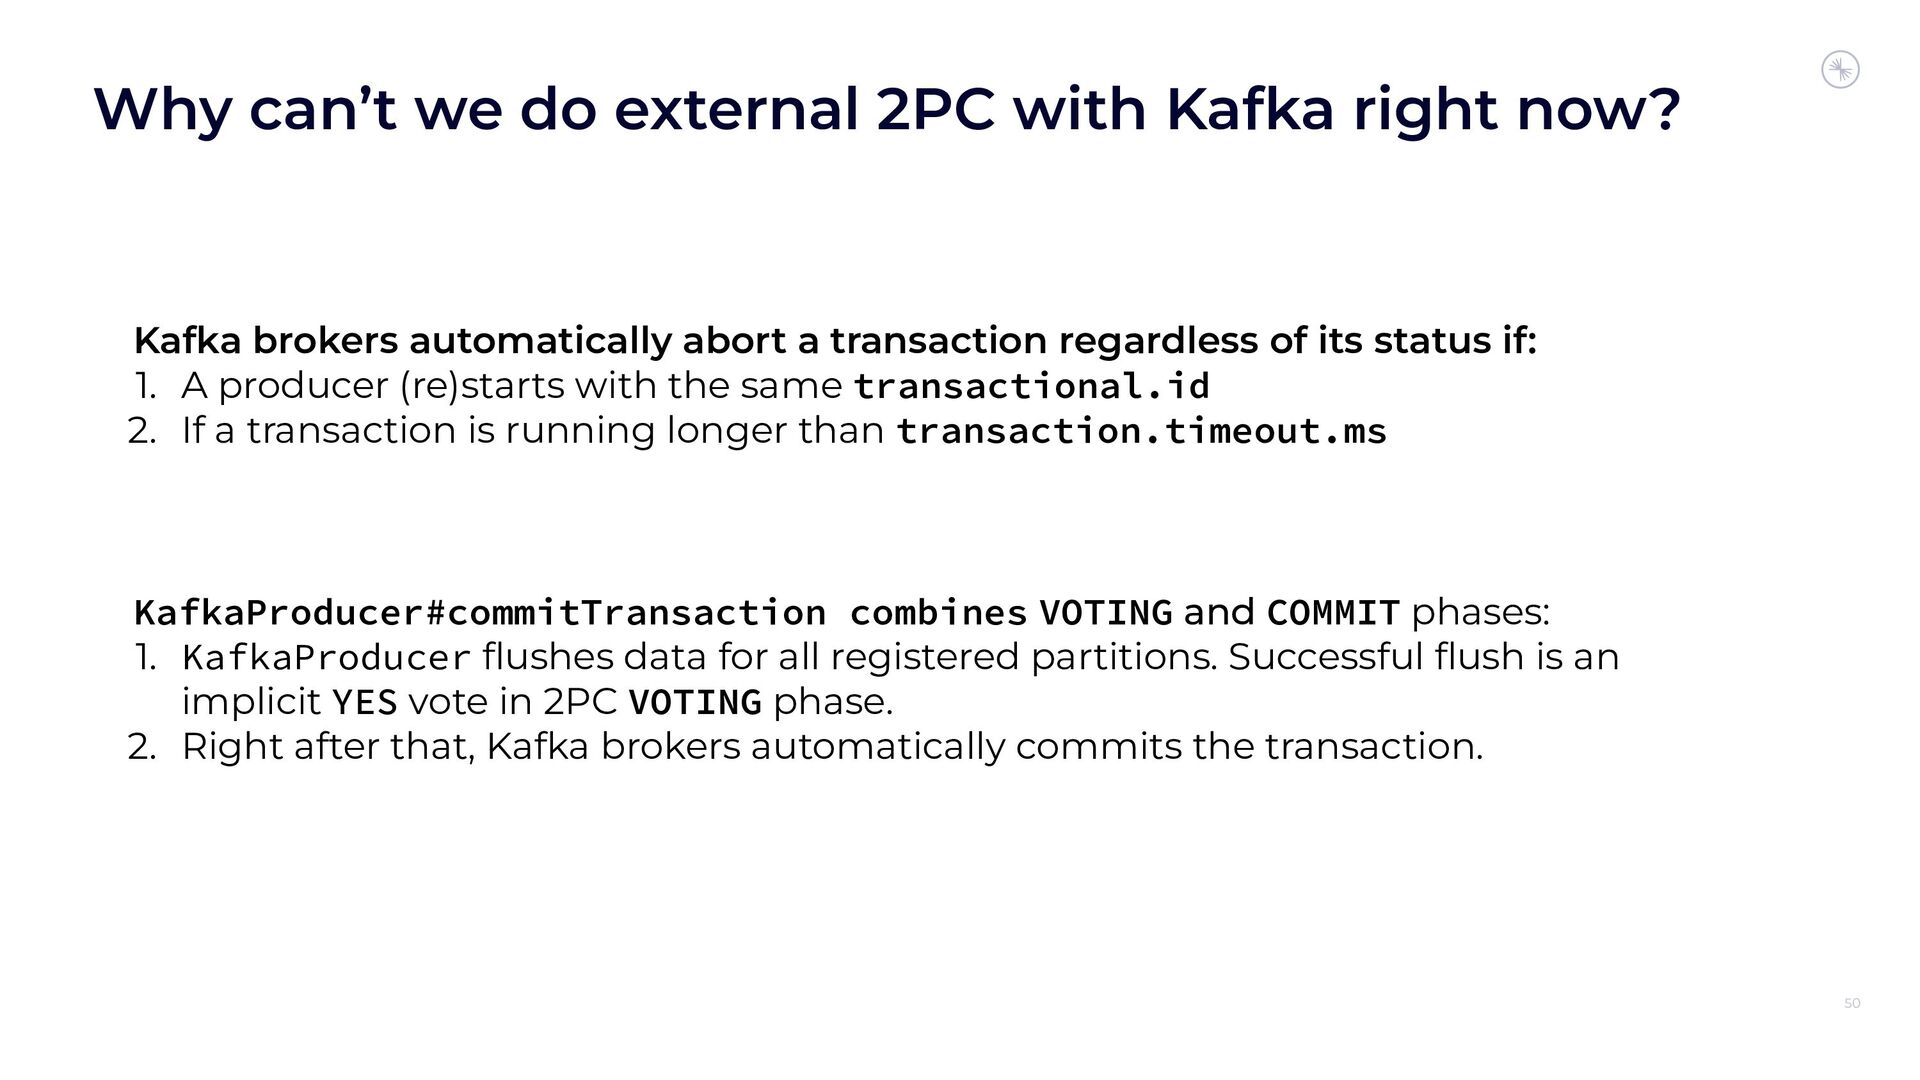
50 Why can’t we do external 2PC with Kafka right
now? Kafka brokers automatically abort a transaction regardless of its status if: 1. A producer (re)starts with the same transactional.id 2. If a transaction is running longer than transaction.timeout.ms KafkaProducer#commitTransaction combines VOTING and COMMIT phases: 1. KafkaProducer flushes data for all registered partitions. Successful flush is an implicit YES vote in 2PC VOTING phase. 2. Right after that, Kafka brokers automatically commits the transaction. -
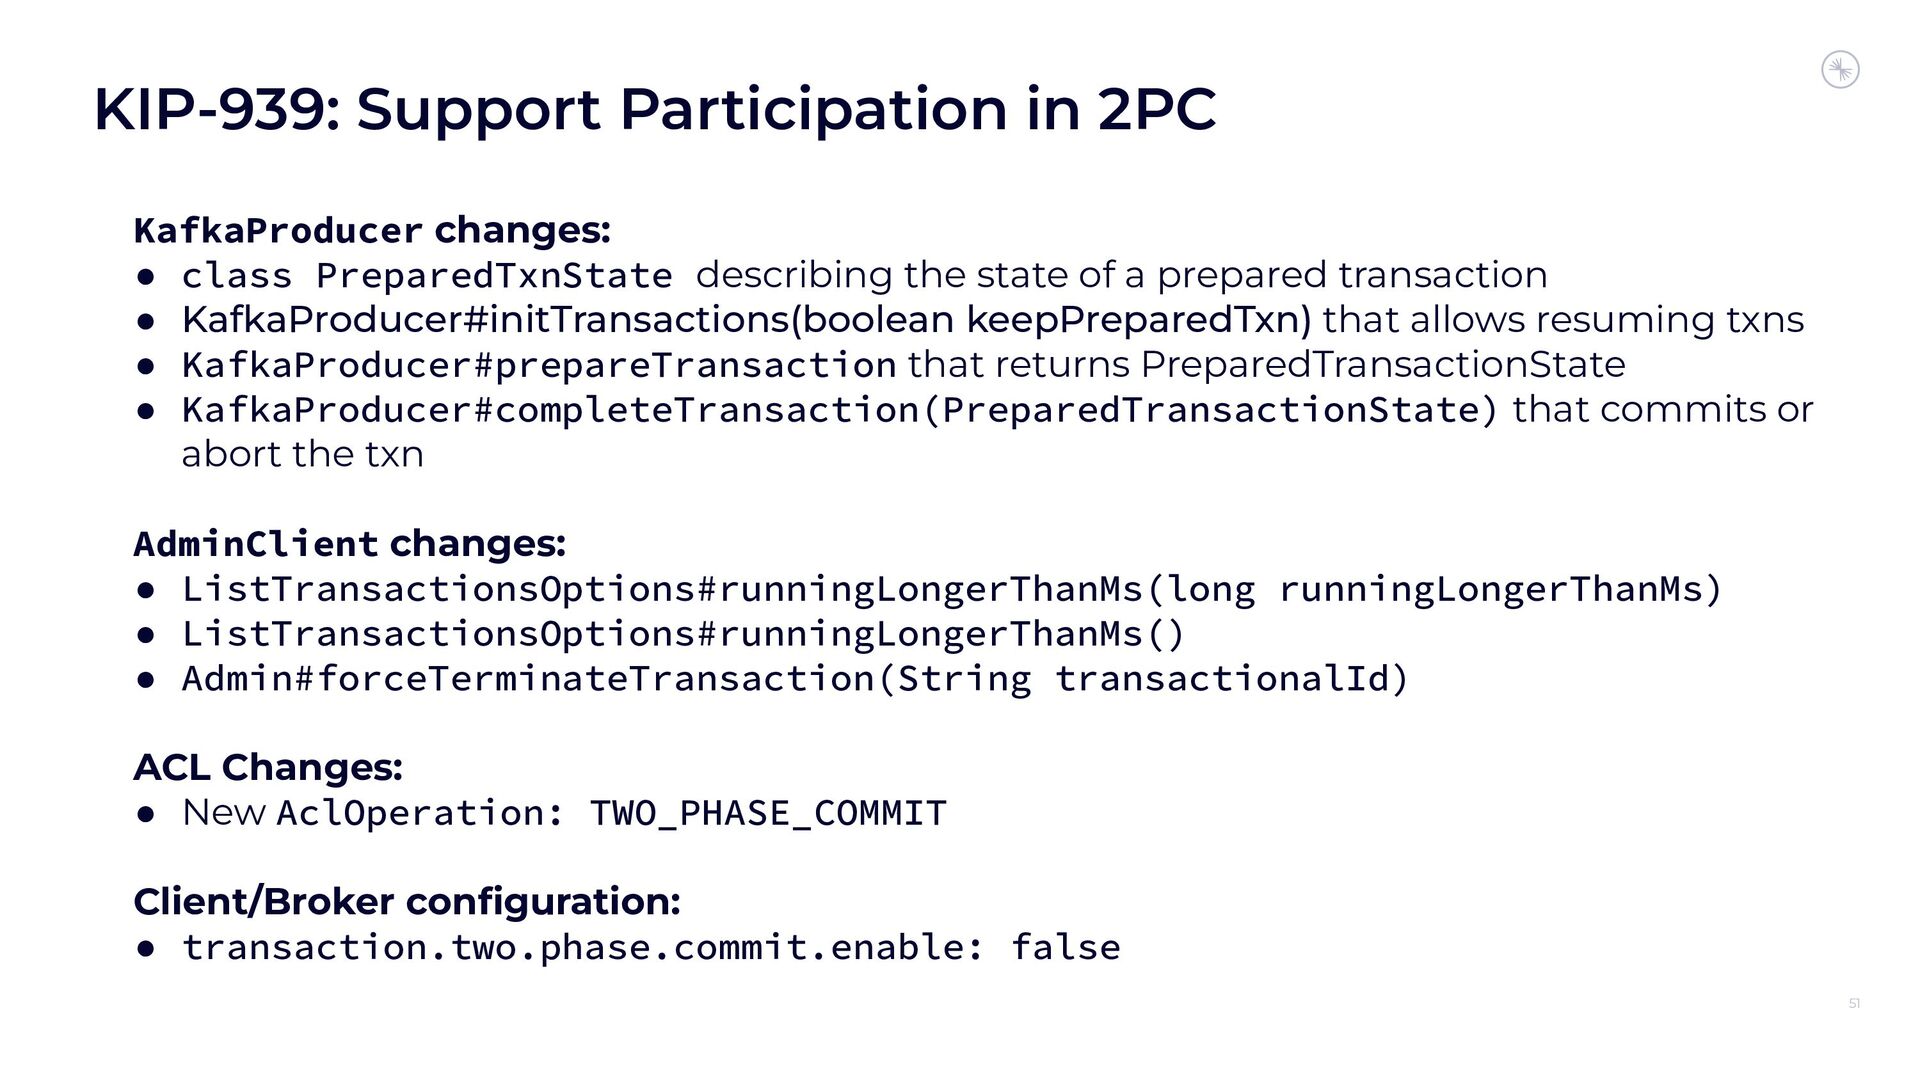
51 KIP-939: Support Participation in 2PC KafkaProducer changes: • class
PreparedTxnState describing the state of a prepared transaction • KafkaProducer#initTransactions(boolean keepPreparedTxn) that allows resuming txns • KafkaProducer#prepareTransaction that returns PreparedTransactionState • KafkaProducer#completeTransaction(PreparedTransactionState) that commits or abort the txn AdminClient changes: • ListTransactionsOptions#runningLongerThanMs(long runningLongerThanMs) • ListTransactionsOptions#runningLongerThanMs() • Admin#forceTerminateTransaction(String transactionalId) ACL Changes: • New AclOperation: TWO_PHASE_COMMIT Client/Broker configuration: • transaction.two.phase.commit.enable: false -
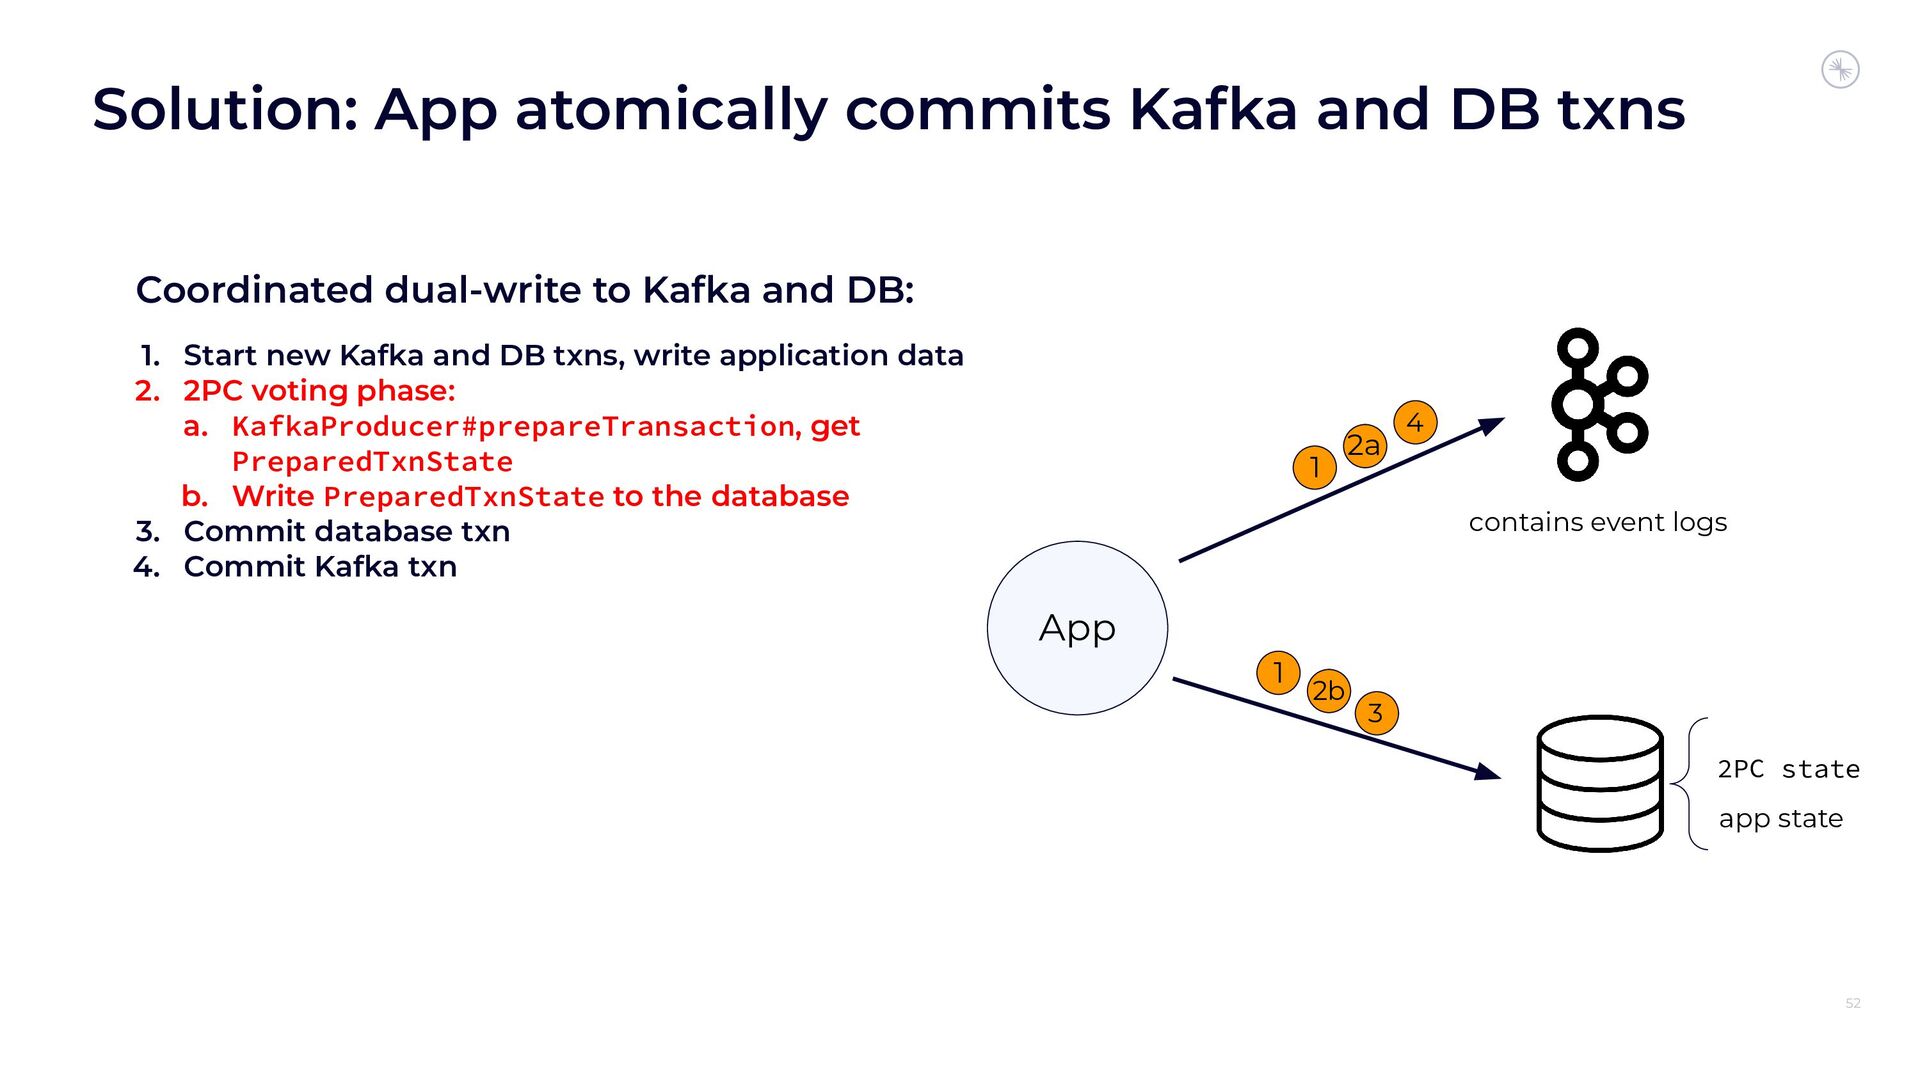
52 Solution: App atomically commits Kafka and DB txns Coordinated
dual-write to Kafka and DB: 1. Start new Kafka and DB txns, write application data 2. 2PC voting phase: a. KafkaProducer#prepareTransaction, get PreparedTxnState b. Write PreparedTxnState to the database 3. Commit database txn 4. Commit Kafka txn contains event logs 2PC state app state 2a 4 App 1 1 2b 3 -
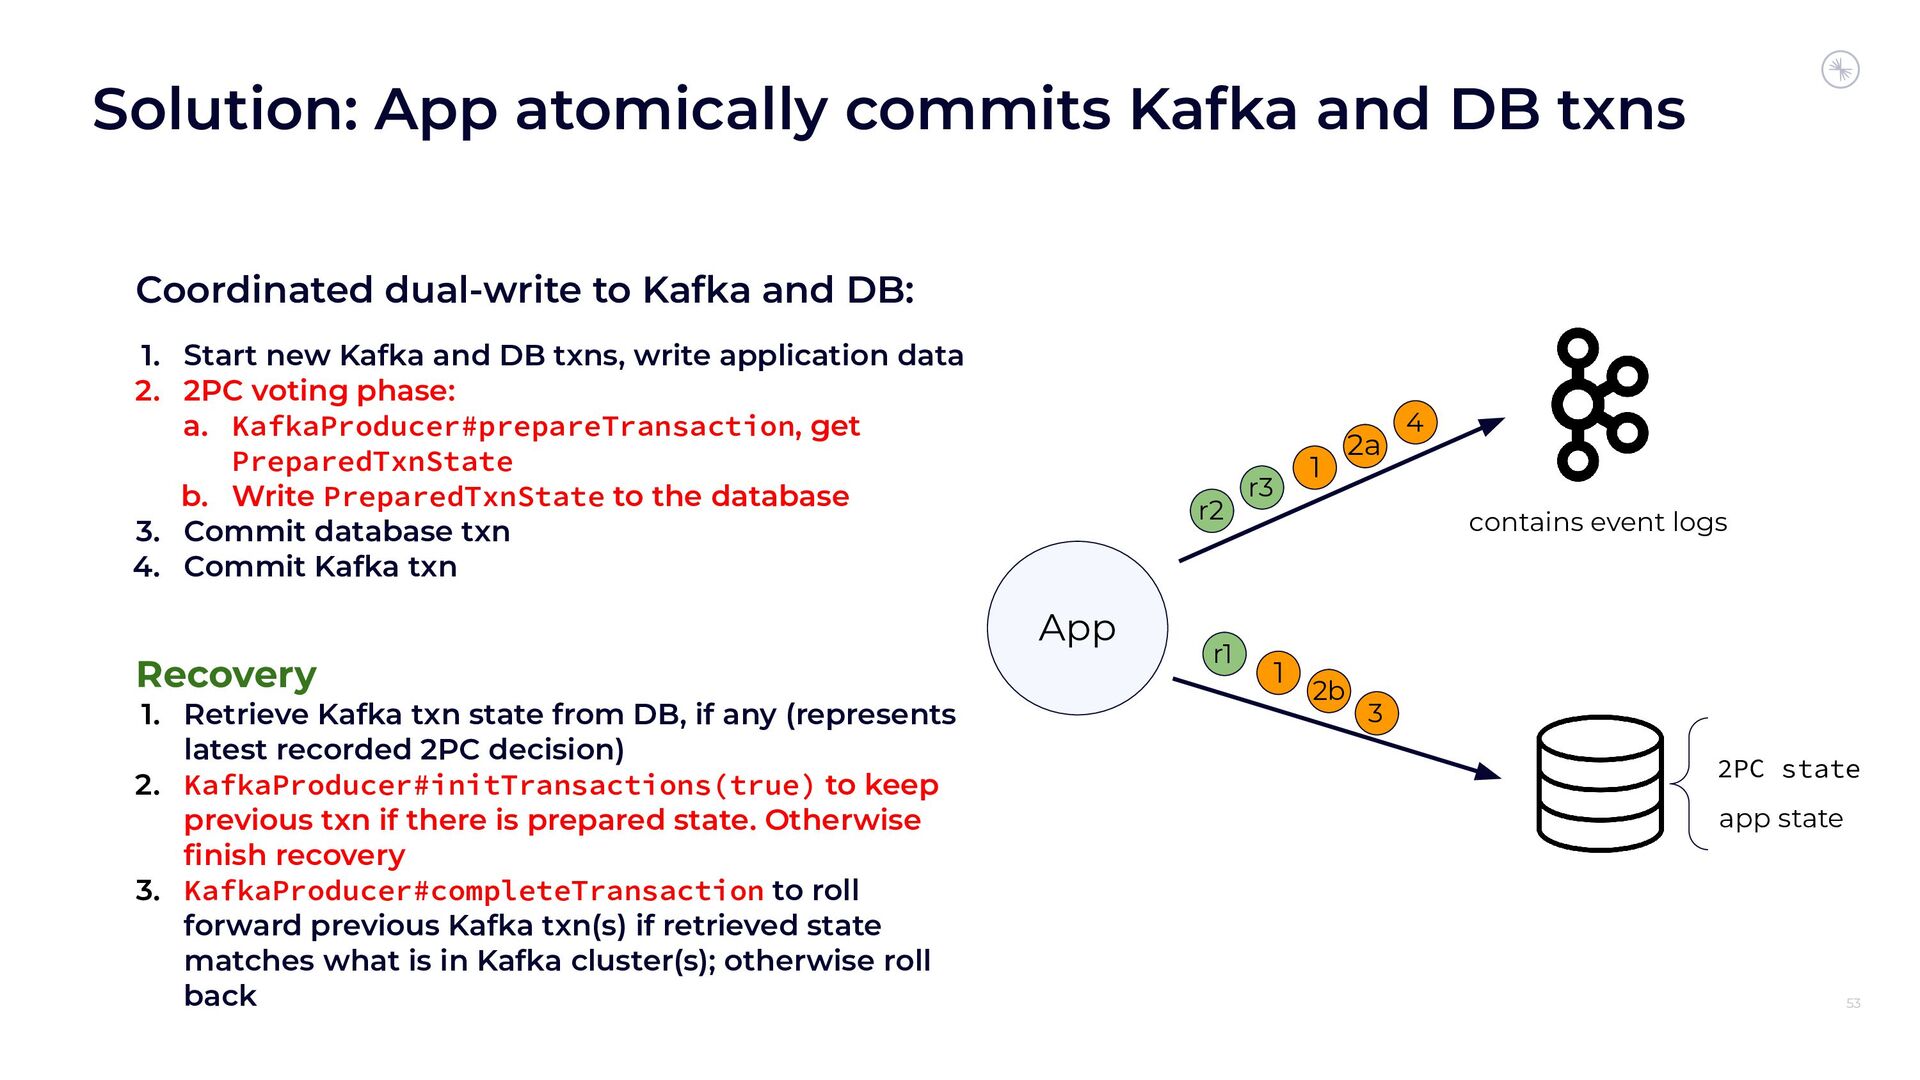
53 Solution: App atomically commits Kafka and DB txns r2
r1 r3 Recovery 1. Retrieve Kafka txn state from DB, if any (represents latest recorded 2PC decision) 2. KafkaProducer#initTransactions(true) to keep previous txn if there is prepared state. Otherwise finish recovery 3. KafkaProducer#completeTransaction to roll forward previous Kafka txn(s) if retrieved state matches what is in Kafka cluster(s); otherwise roll back Coordinated dual-write to Kafka and DB: 1. Start new Kafka and DB txns, write application data 2. 2PC voting phase: a. KafkaProducer#prepareTransaction, get PreparedTxnState b. Write PreparedTxnState to the database 3. Commit database txn 4. Commit Kafka txn 2a 4 1 1 2b 3 contains event logs 2PC state app state App -
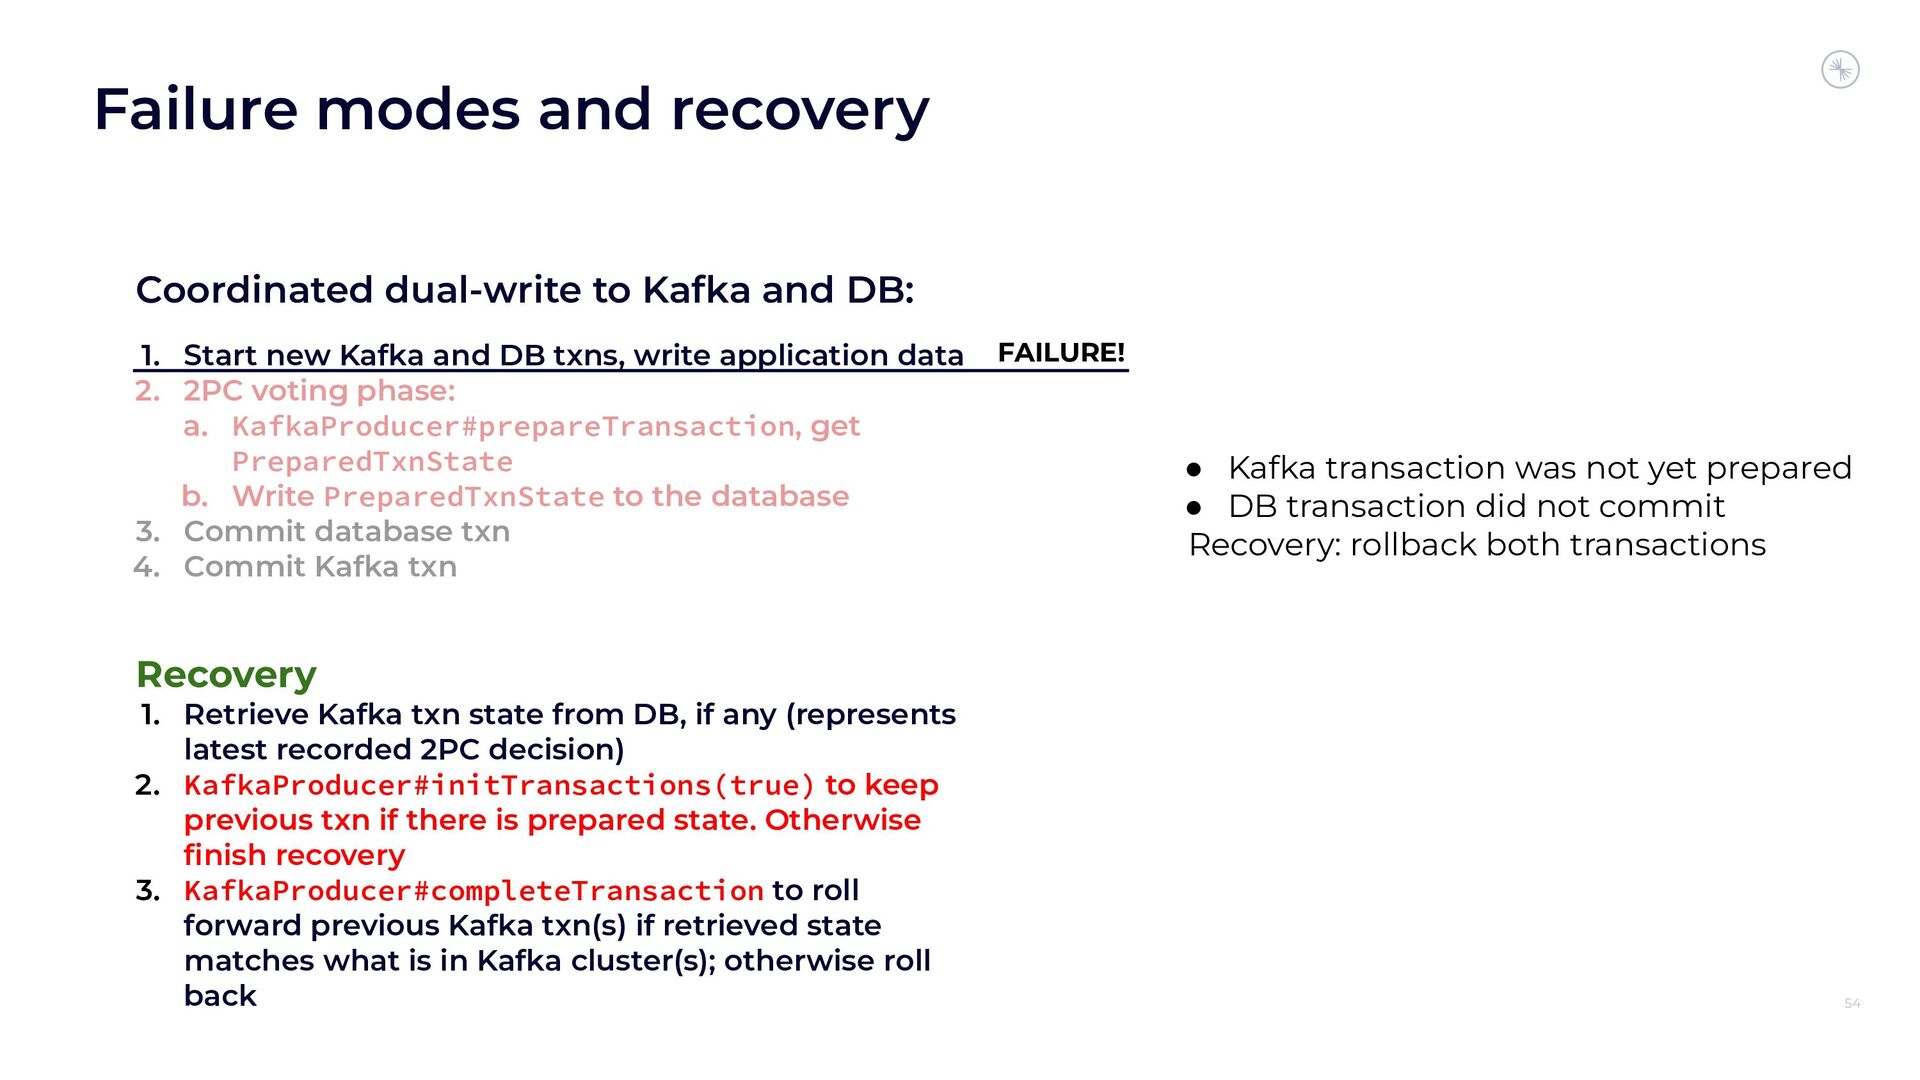
54 Failure modes and recovery Coordinated dual-write to Kafka and
DB: 1. Start new Kafka and DB txns, write application data 2. 2PC voting phase: a. KafkaProducer#prepareTransaction, get PreparedTxnState b. Write PreparedTxnState to the database 3. Commit database txn 4. Commit Kafka txn • Kafka transaction was not yet prepared • DB transaction did not commit Recovery: rollback both transactions FAILURE! Recovery 1. Retrieve Kafka txn state from DB, if any (represents latest recorded 2PC decision) 2. KafkaProducer#initTransactions(true) to keep previous txn if there is prepared state. Otherwise finish recovery 3. KafkaProducer#completeTransaction to roll forward previous Kafka txn(s) if retrieved state matches what is in Kafka cluster(s); otherwise roll back -
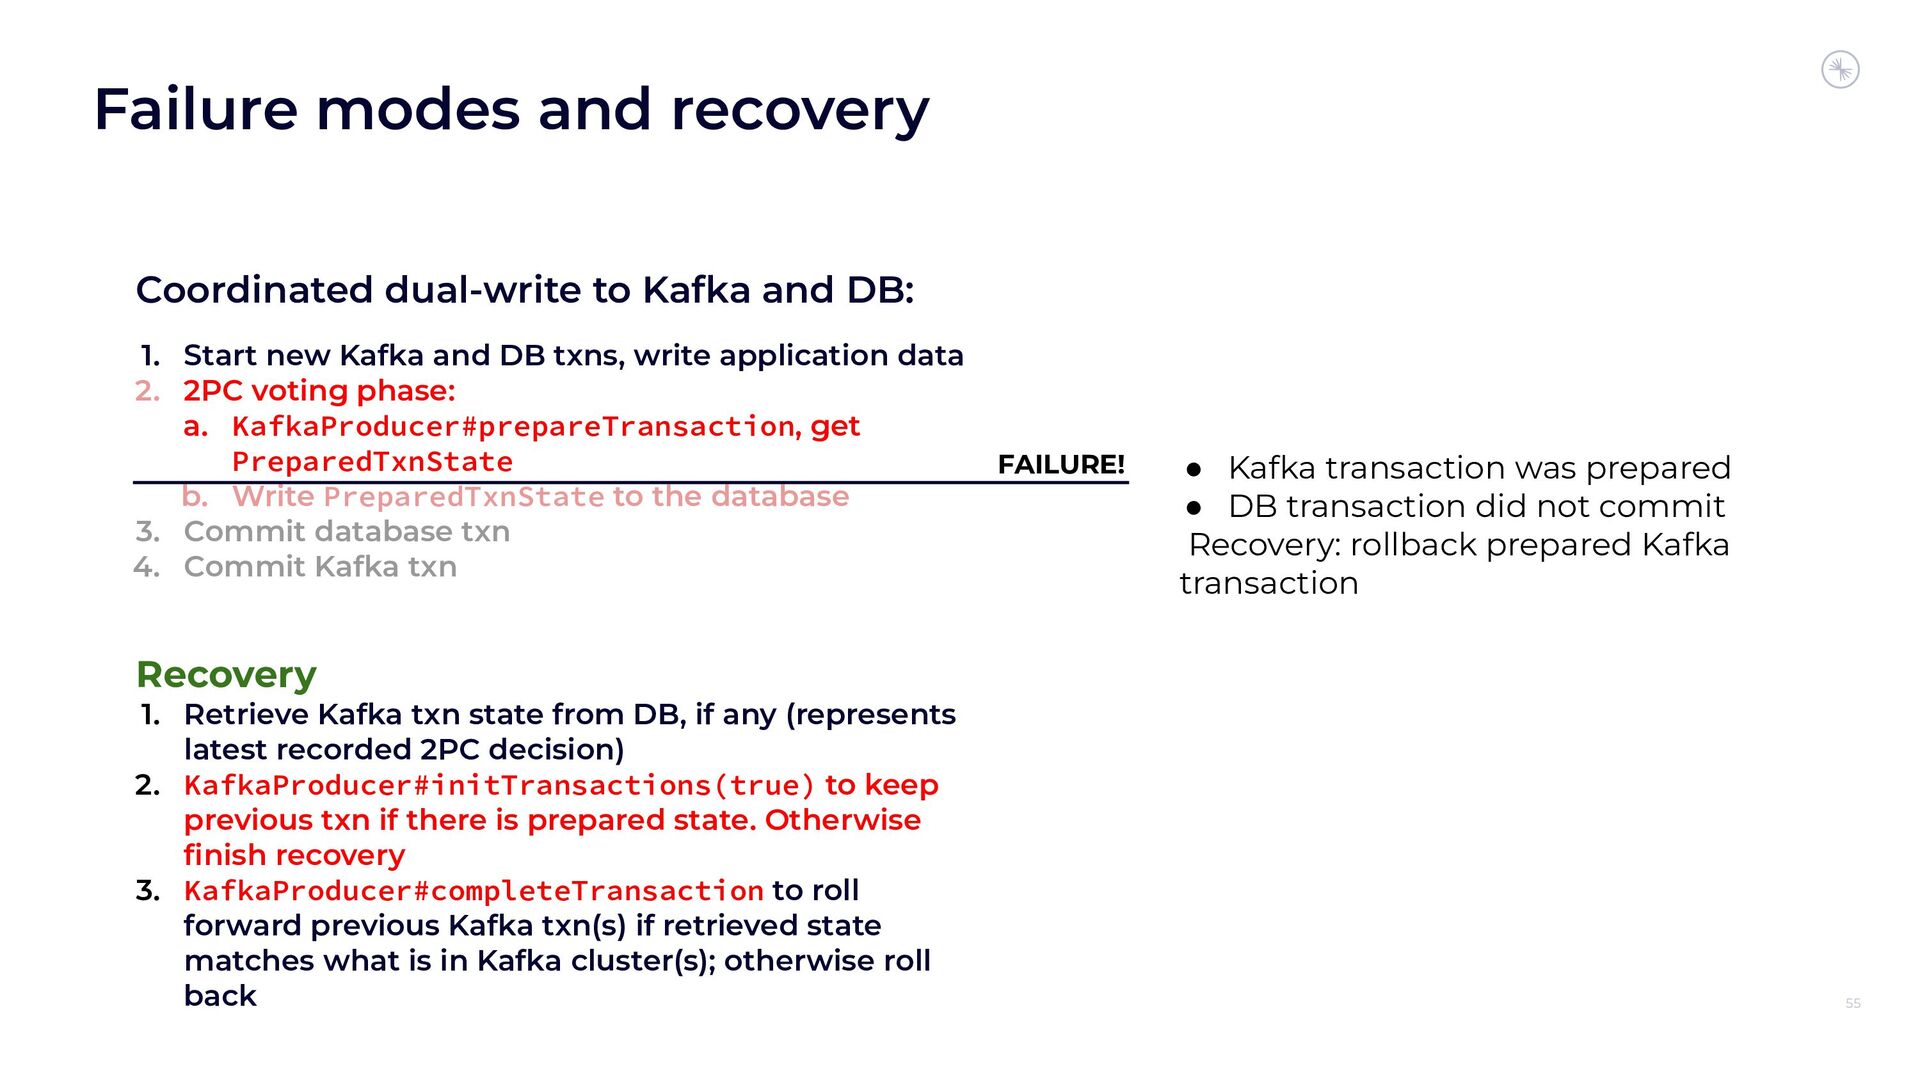
55 Failure modes and recovery Coordinated dual-write to Kafka and
DB: 1. Start new Kafka and DB txns, write application data 2. 2PC voting phase: a. KafkaProducer#prepareTransaction, get PreparedTxnState b. Write PreparedTxnState to the database 3. Commit database txn 4. Commit Kafka txn • Kafka transaction was prepared • DB transaction did not commit Recovery: rollback prepared Kafka transaction Recovery 1. Retrieve Kafka txn state from DB, if any (represents latest recorded 2PC decision) 2. KafkaProducer#initTransactions(true) to keep previous txn if there is prepared state. Otherwise finish recovery 3. KafkaProducer#completeTransaction to roll forward previous Kafka txn(s) if retrieved state matches what is in Kafka cluster(s); otherwise roll back FAILURE! -
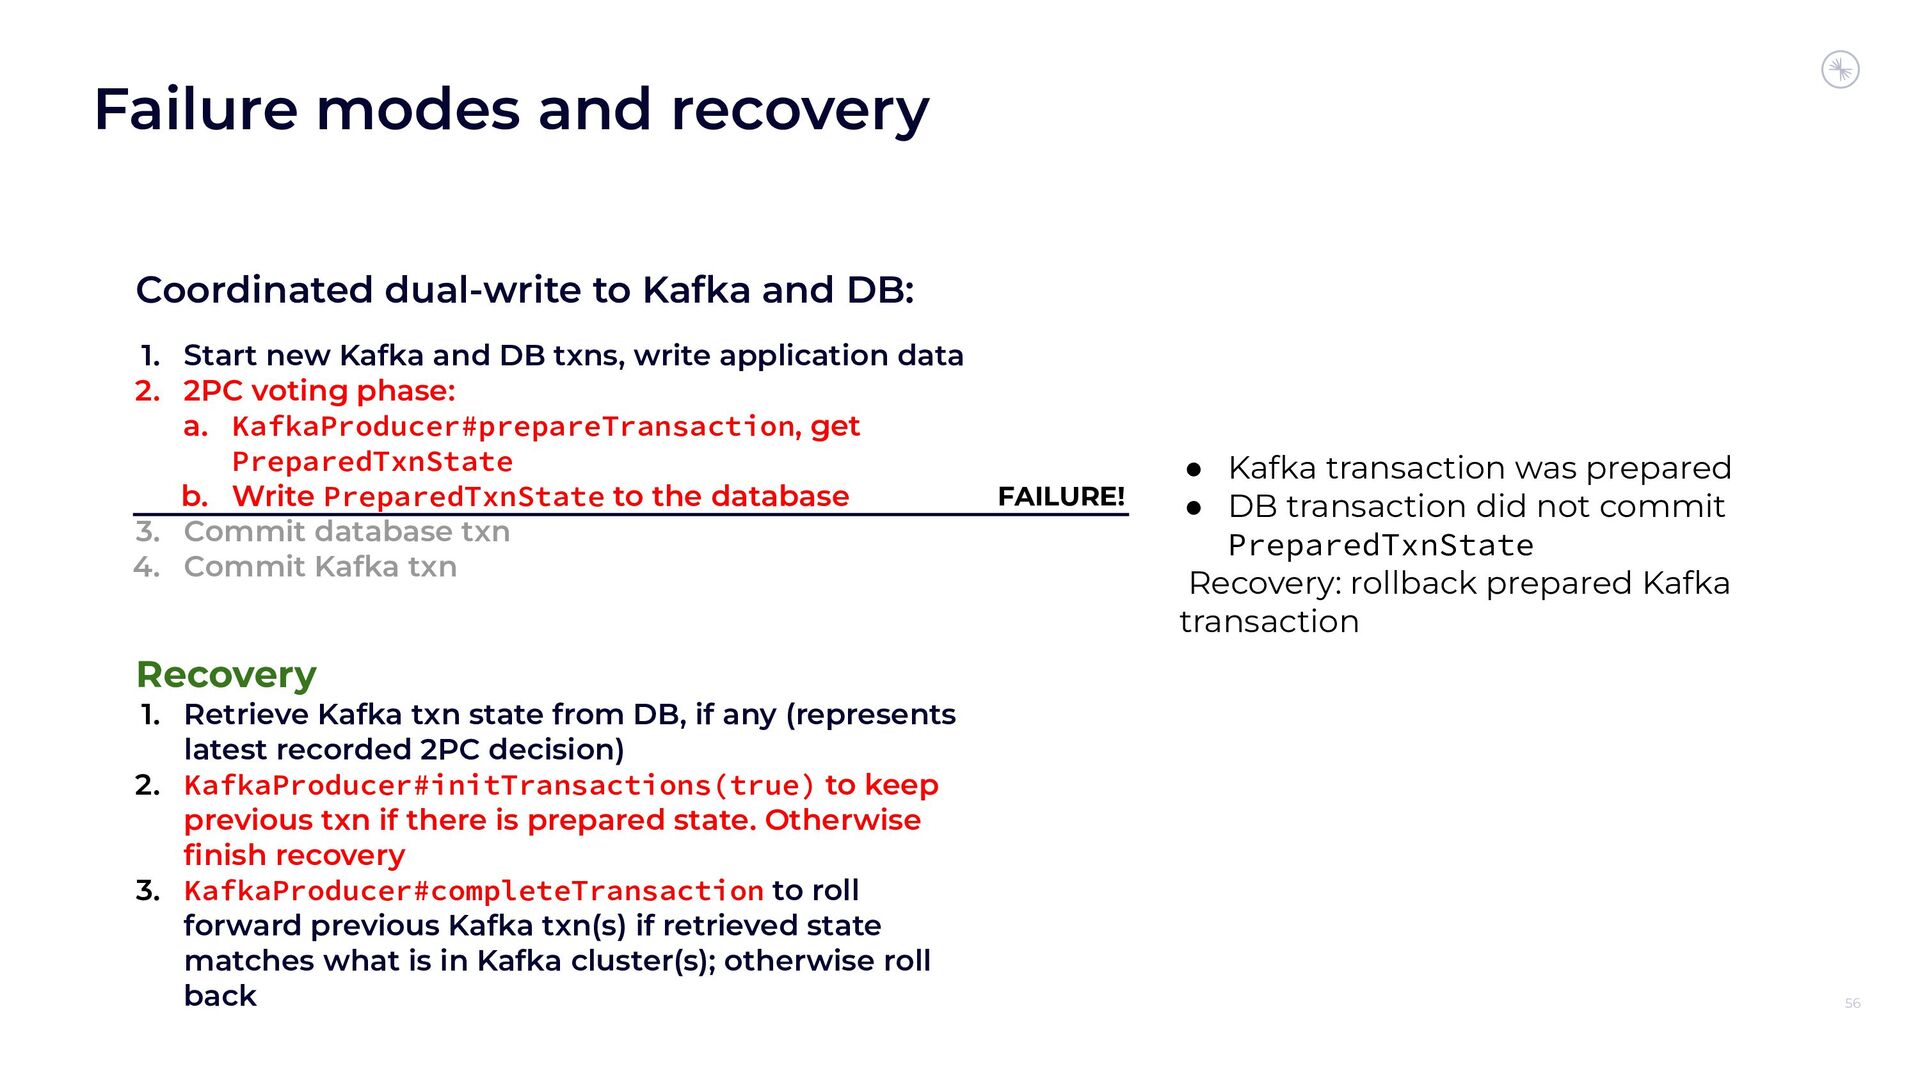
56 Failure modes and recovery Coordinated dual-write to Kafka and
DB: 1. Start new Kafka and DB txns, write application data 2. 2PC voting phase: a. KafkaProducer#prepareTransaction, get PreparedTxnState b. Write PreparedTxnState to the database 3. Commit database txn 4. Commit Kafka txn • Kafka transaction was prepared • DB transaction did not commit PreparedTxnState Recovery: rollback prepared Kafka transaction Recovery 1. Retrieve Kafka txn state from DB, if any (represents latest recorded 2PC decision) 2. KafkaProducer#initTransactions(true) to keep previous txn if there is prepared state. Otherwise finish recovery 3. KafkaProducer#completeTransaction to roll forward previous Kafka txn(s) if retrieved state matches what is in Kafka cluster(s); otherwise roll back FAILURE! -
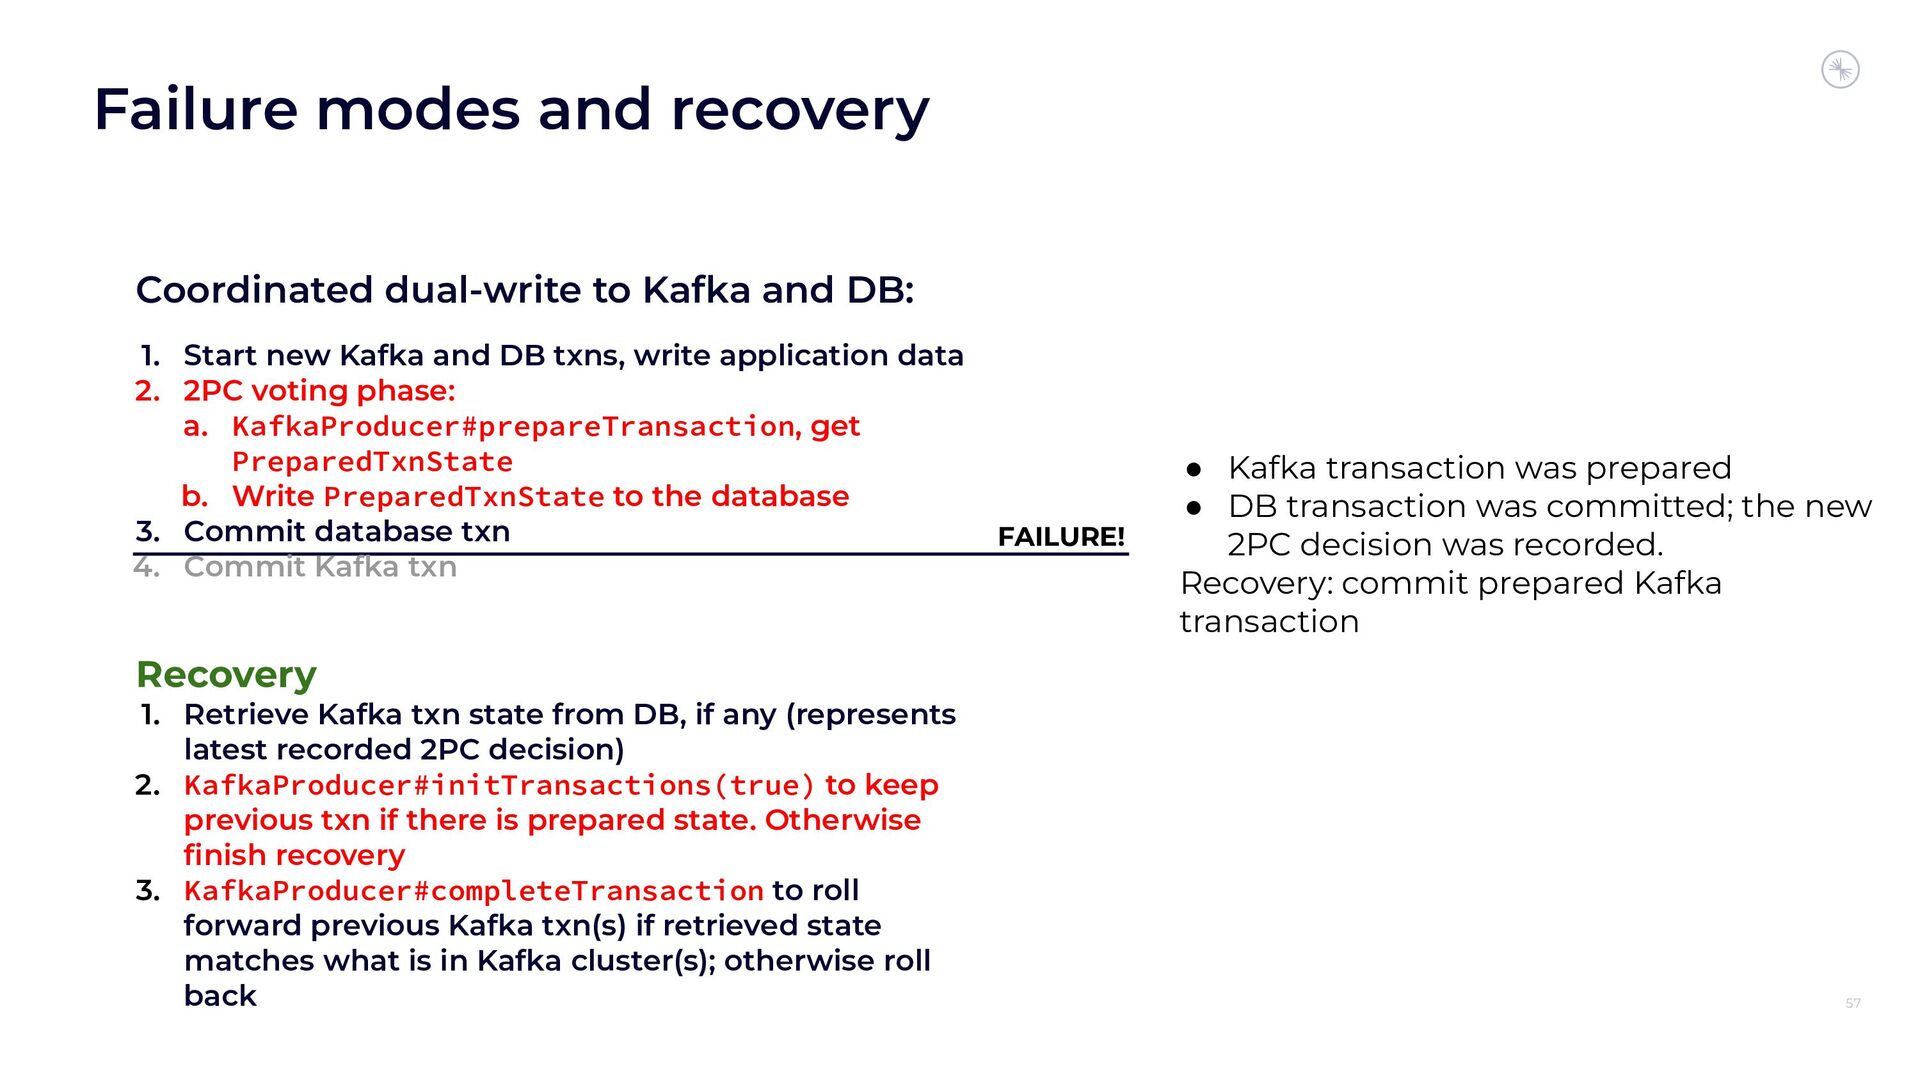
57 Failure modes and recovery • Kafka transaction was prepared
• DB transaction was committed; the new 2PC decision was recorded. Recovery: commit prepared Kafka transaction Recovery 1. Retrieve Kafka txn state from DB, if any (represents latest recorded 2PC decision) 2. KafkaProducer#initTransactions(true) to keep previous txn if there is prepared state. Otherwise finish recovery 3. KafkaProducer#completeTransaction to roll forward previous Kafka txn(s) if retrieved state matches what is in Kafka cluster(s); otherwise roll back Coordinated dual-write to Kafka and DB: 1. Start new Kafka and DB txns, write application data 2. 2PC voting phase: a. KafkaProducer#prepareTransaction, get PreparedTxnState b. Write PreparedTxnState to the database 3. Commit database txn 4. Commit Kafka txn FAILURE! -
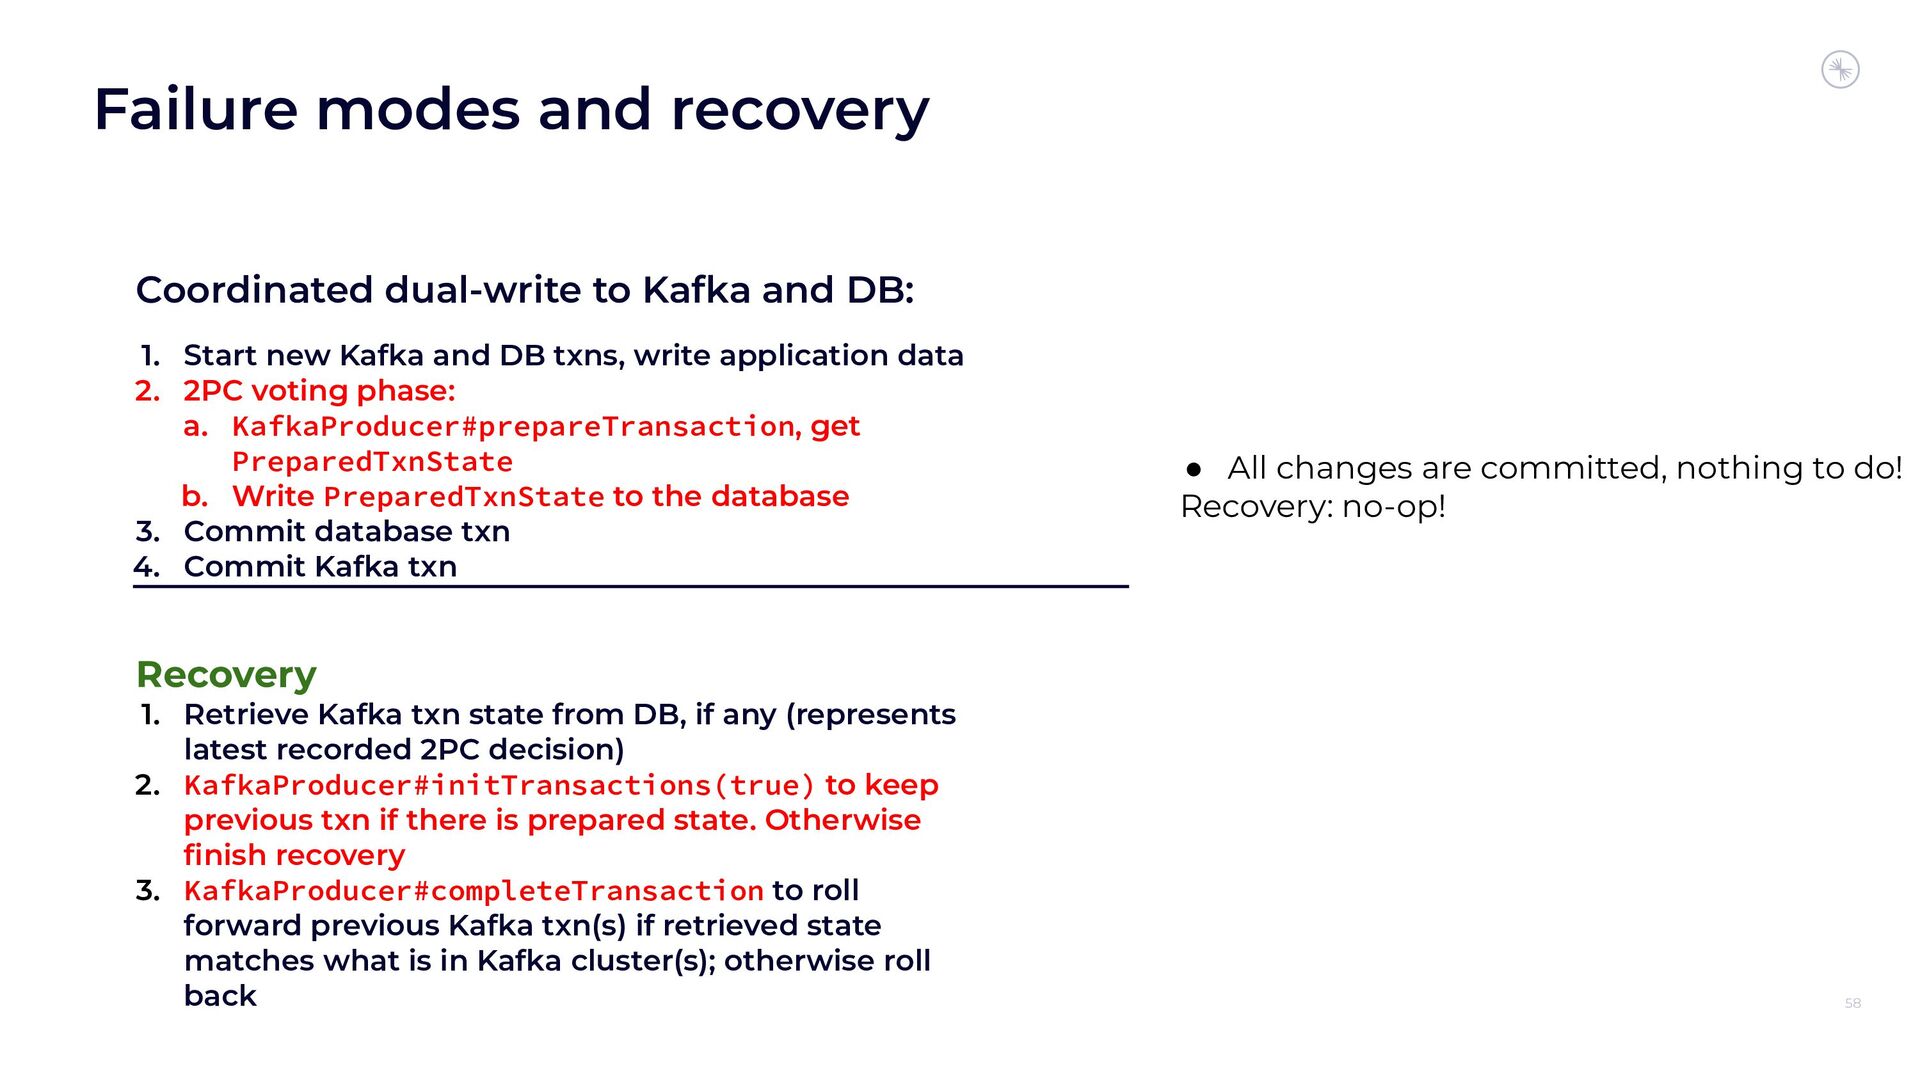
58 Failure modes and recovery • All changes are committed,
nothing to do! Recovery: no-op! Recovery 1. Retrieve Kafka txn state from DB, if any (represents latest recorded 2PC decision) 2. KafkaProducer#initTransactions(true) to keep previous txn if there is prepared state. Otherwise finish recovery 3. KafkaProducer#completeTransaction to roll forward previous Kafka txn(s) if retrieved state matches what is in Kafka cluster(s); otherwise roll back Coordinated dual-write to Kafka and DB: 1. Start new Kafka and DB txns, write application data 2. 2PC voting phase: a. KafkaProducer#prepareTransaction, get PreparedTxnState b. Write PreparedTxnState to the database 3. Commit database txn 4. Commit Kafka txn -
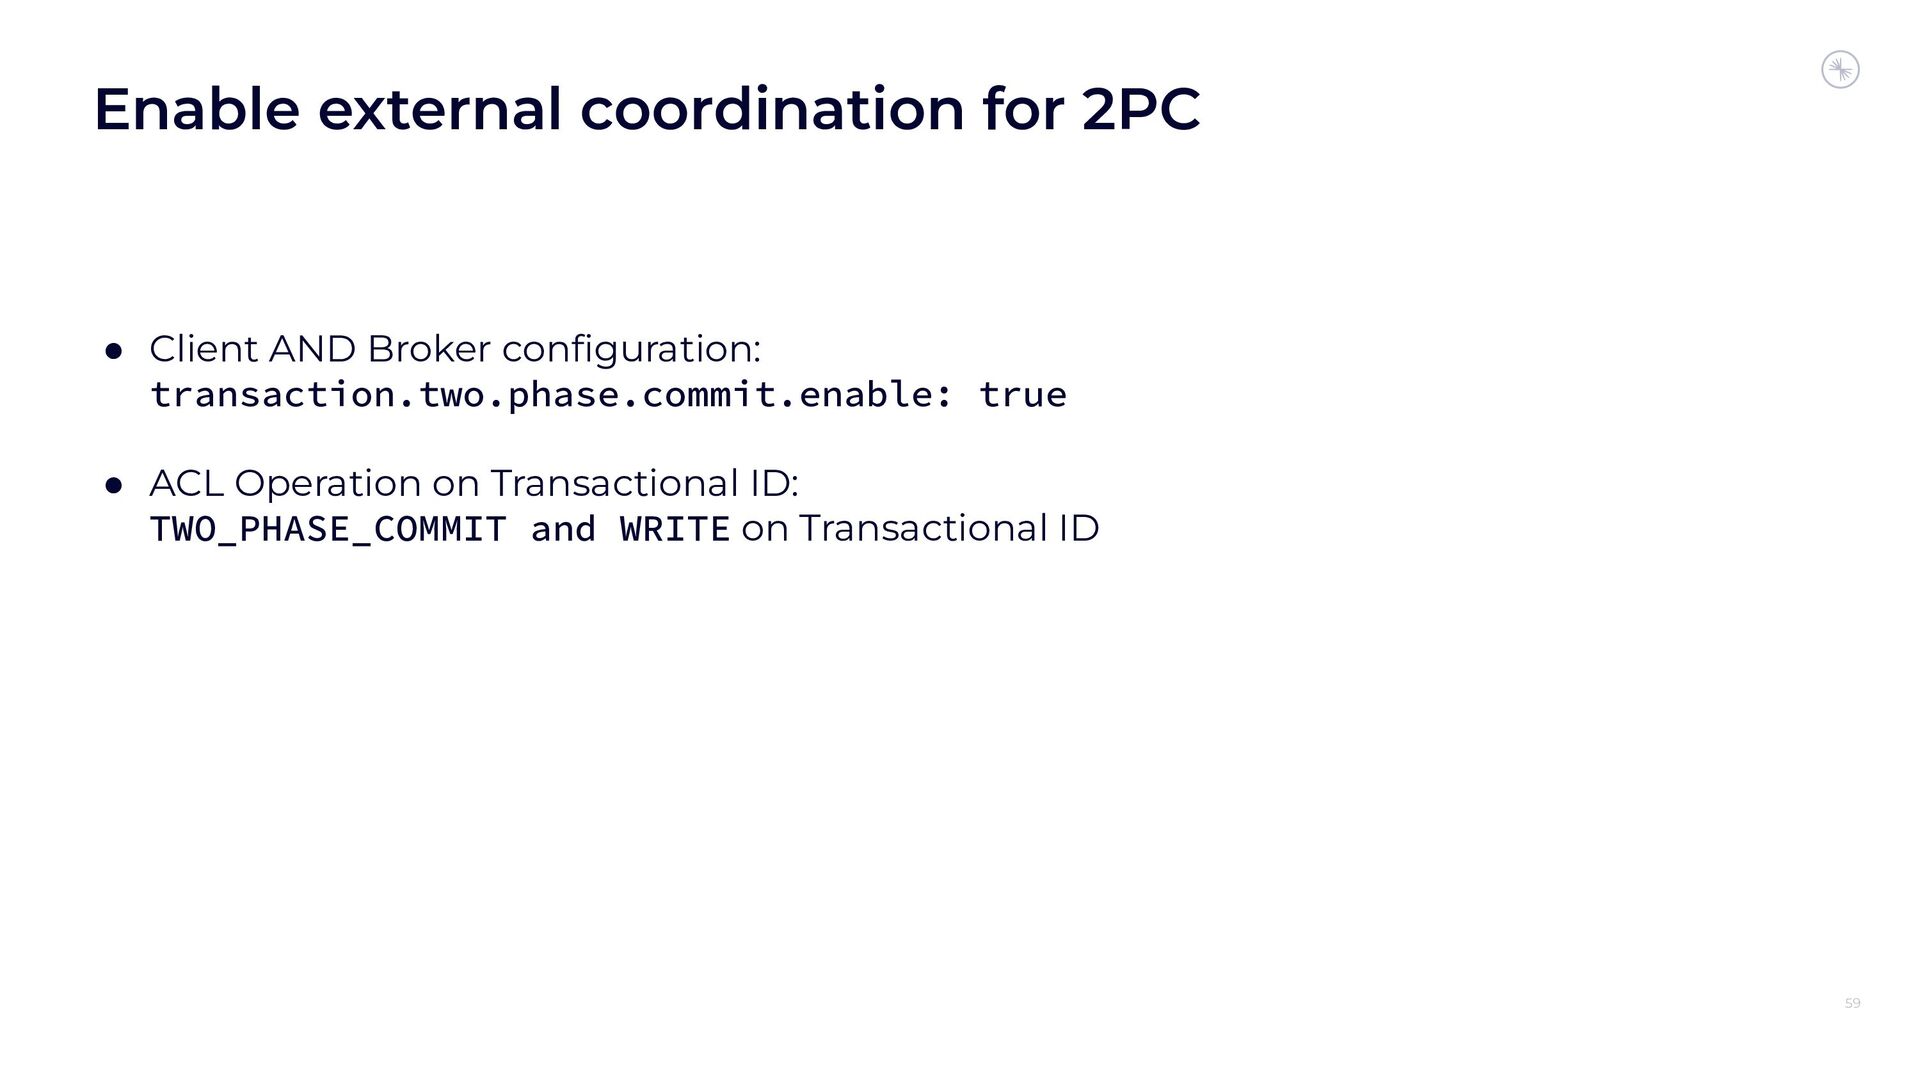
Enable external coordination for 2PC 59 • Client AND Broker
configuration: transaction.two.phase.commit.enable: true • ACL Operation on Transactional ID: TWO_PHASE_COMMIT and WRITE on Transactional ID -
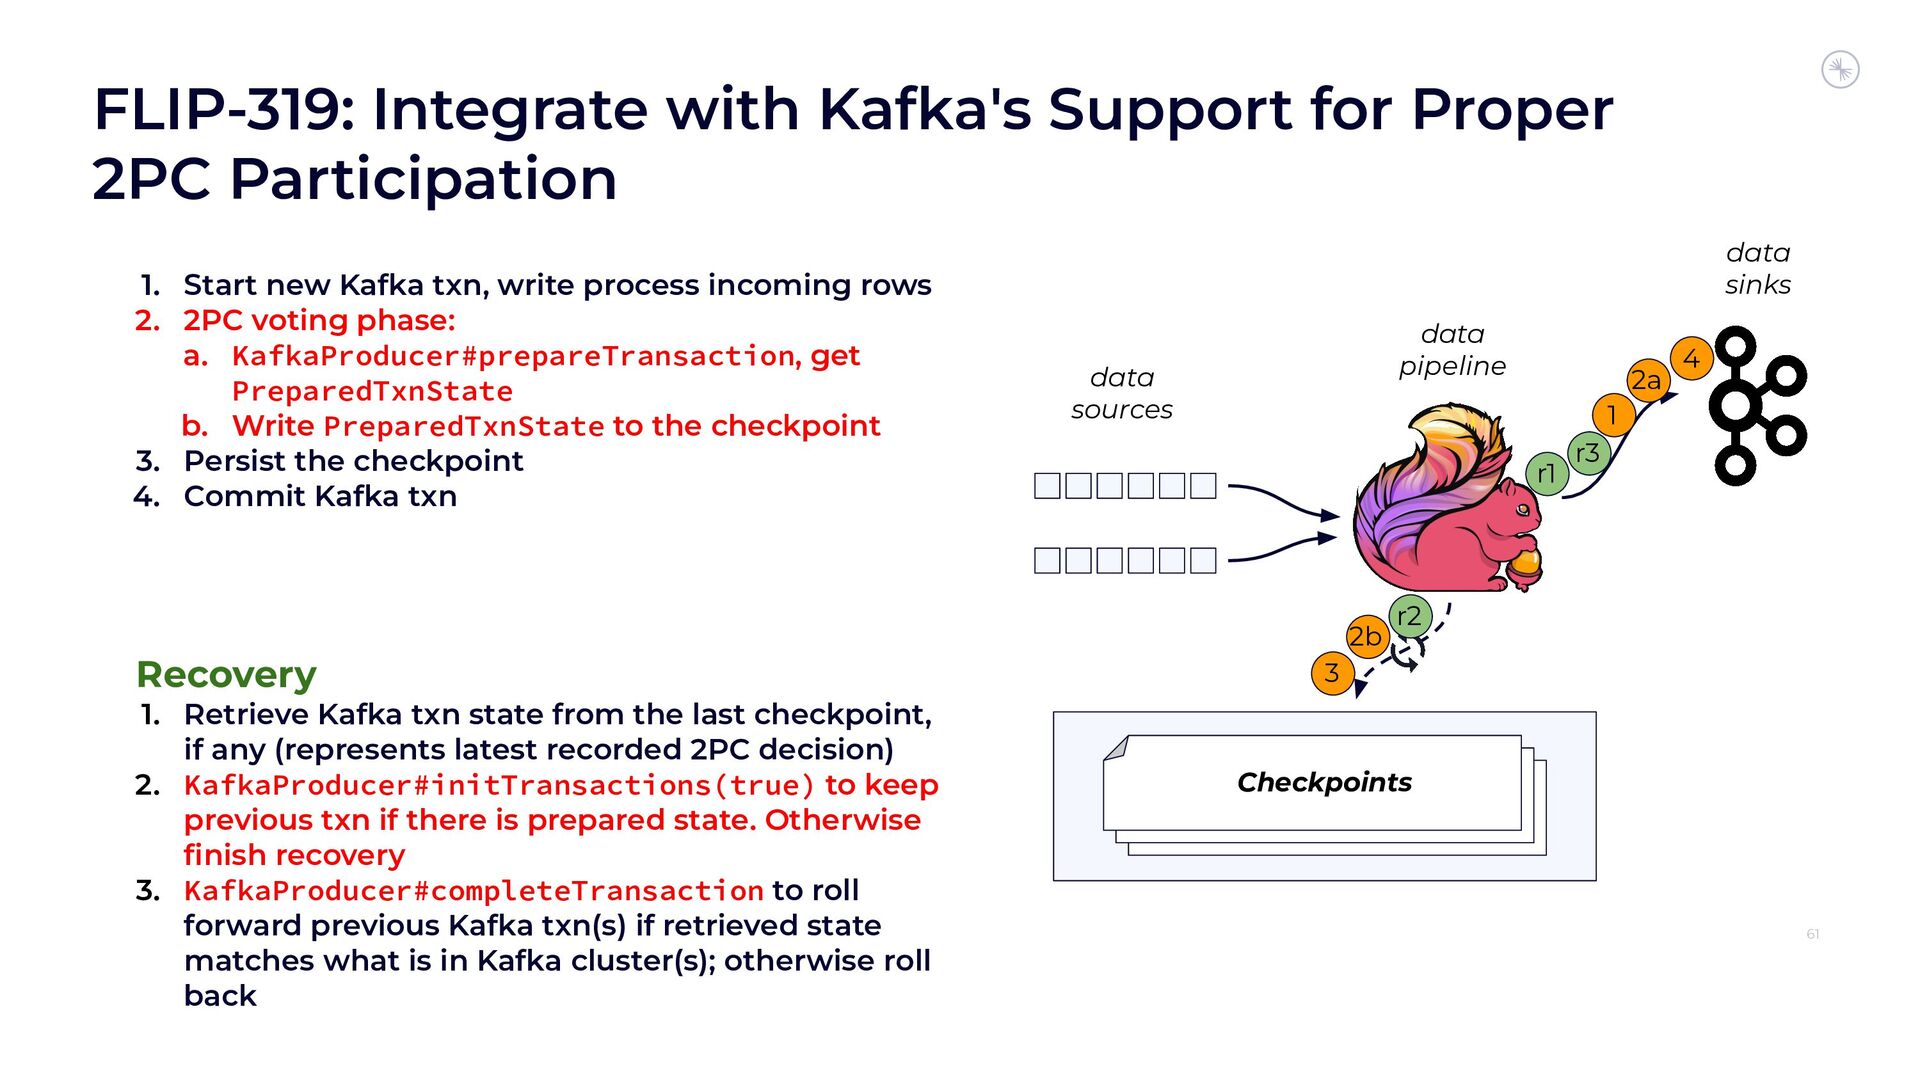
FLIP-319: Integrate with Kafka's Support for Proper 2PC Participation 61
data sources data pipeline data sinks Checkpoints r1 r2 r3 1 4 2a 2b 3 Recovery 1. Retrieve Kafka txn state from the last checkpoint, if any (represents latest recorded 2PC decision) 2. KafkaProducer#initTransactions(true) to keep previous txn if there is prepared state. Otherwise finish recovery 3. KafkaProducer#completeTransaction to roll forward previous Kafka txn(s) if retrieved state matches what is in Kafka cluster(s); otherwise roll back 1. Start new Kafka txn, write process incoming rows 2. 2PC voting phase: a. KafkaProducer#prepareTransaction, get PreparedTxnState b. Write PreparedTxnState to the checkpoint 3. Persist the checkpoint 4. Commit Kafka txn -
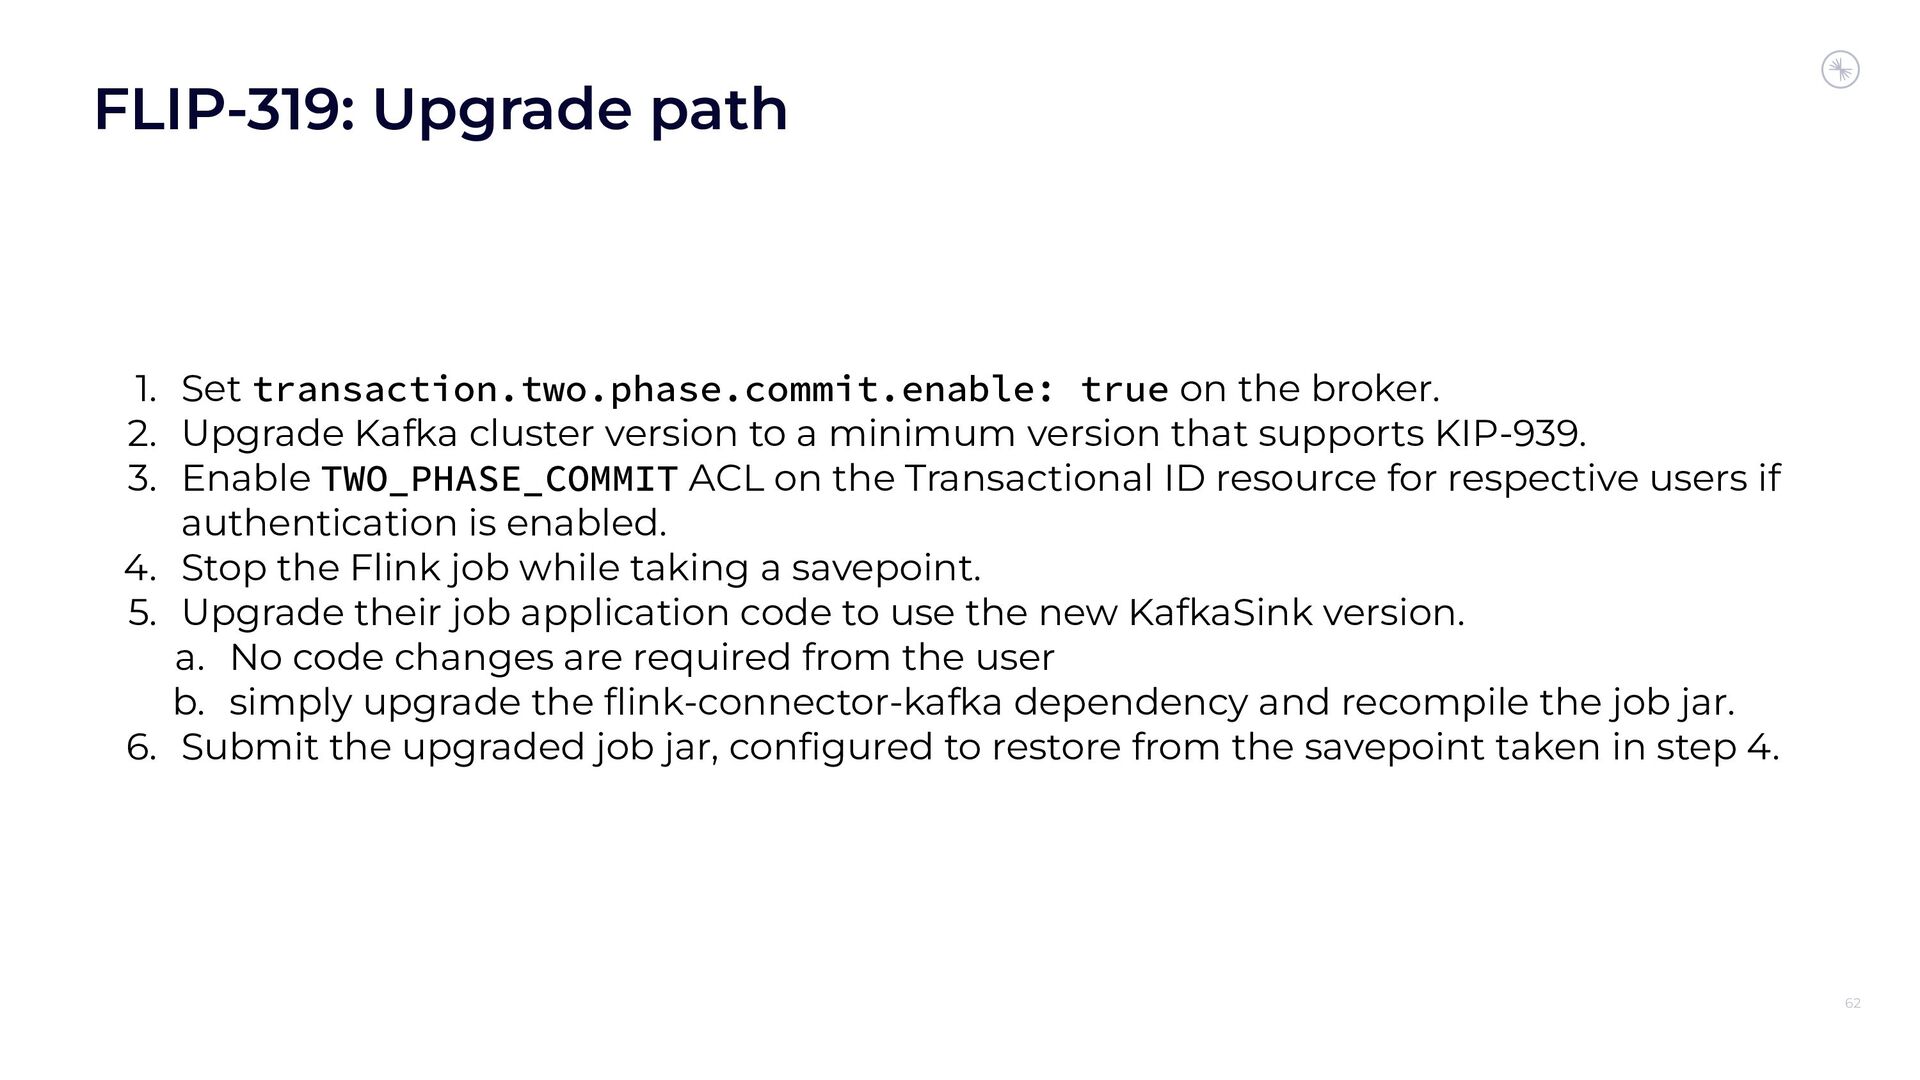
FLIP-319: Upgrade path 62 1. Set transaction.two.phase.commit.enable: true on the
broker. 2. Upgrade Kafka cluster version to a minimum version that supports KIP-939. 3. Enable TWO_PHASE_COMMIT ACL on the Transactional ID resource for respective users if authentication is enabled. 4. Stop the Flink job while taking a savepoint. 5. Upgrade their job application code to use the new KafkaSink version. a. No code changes are required from the user b. simply upgrade the flink-connector-kafka dependency and recompile the job jar. 6. Submit the upgraded job jar, configured to restore from the savepoint taken in step 4. -
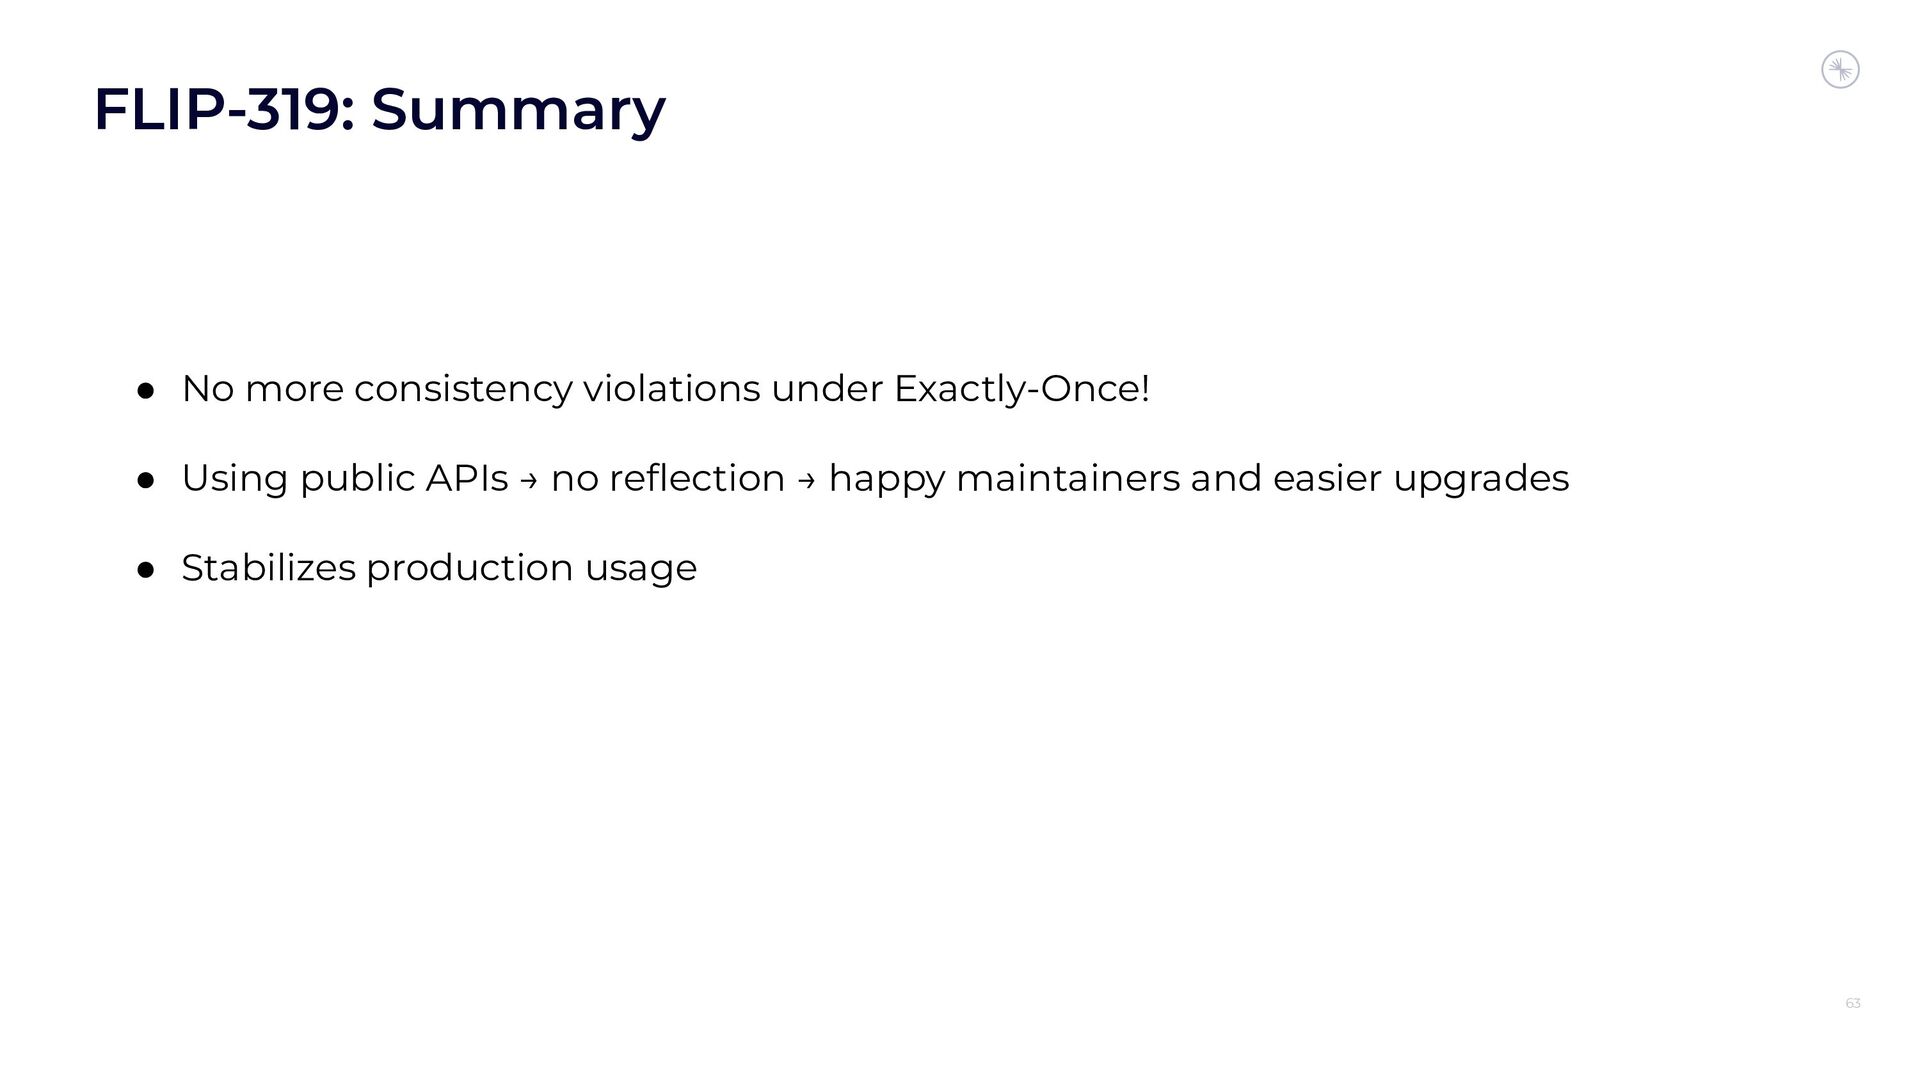
FLIP-319: Summary 63 • No more consistency violations under Exactly-Once!
• Using public APIs → no reflection → happy maintainers and easier upgrades • Stabilizes production usage -
Conclusion 65 • KIP-939 enables external 2PC transaction coordination. •
With FLIP-319, Apache Flink is the first application that makes use of that capability. • KIP-939 and FLIP-319 are in discussion on the corresponding mailing lists. KIP-939: • Proposal: https://cwiki.apache.org/confluence/display/KAFKA/KIP-939%3A+Support+Participation+i n+2PC • Discussion thread: https://lists.apache.org/thread/wbs9sqs3z1tdm7ptw5j4o9osmx9s41nf FLIP-319: • Proposal https://cwiki.apache.org/confluence/pages/viewpage.action?pageId=255071710 • Discussion thread: https://lists.apache.org/thread/p0z40w60qgyrmwjttbxx7qncjdohqtrc