Upgrade to Pro — share decks privately, control downloads, hide ads and more …

Convolutional Neural Network

Convolutional Neural Network

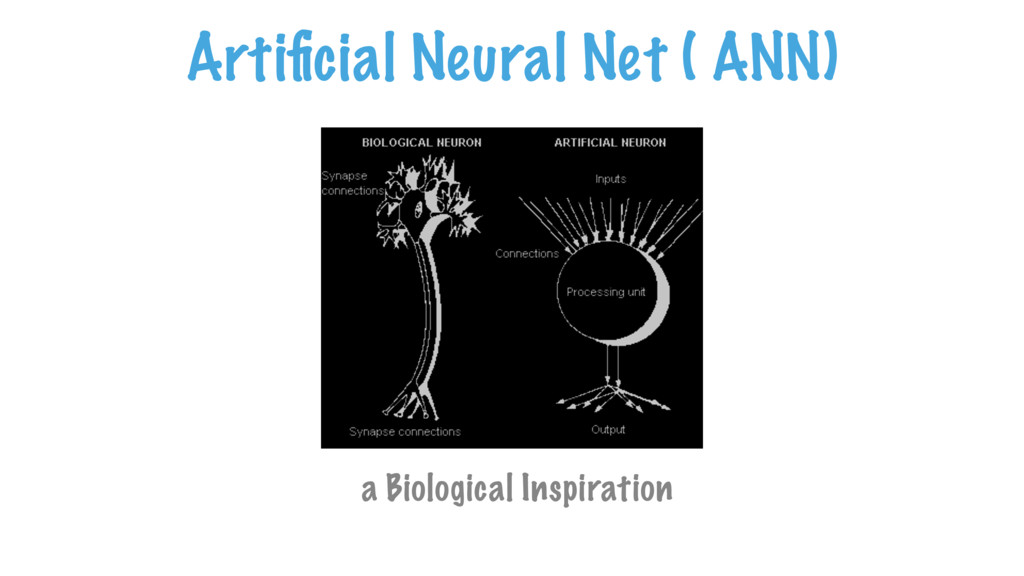
Talk covering basics of Neural Net to Convolutional Neural Net

Avatar for Amit Kushwaha

Amit Kushwaha

April 01, 2017

Other Decks in Research

Transcript

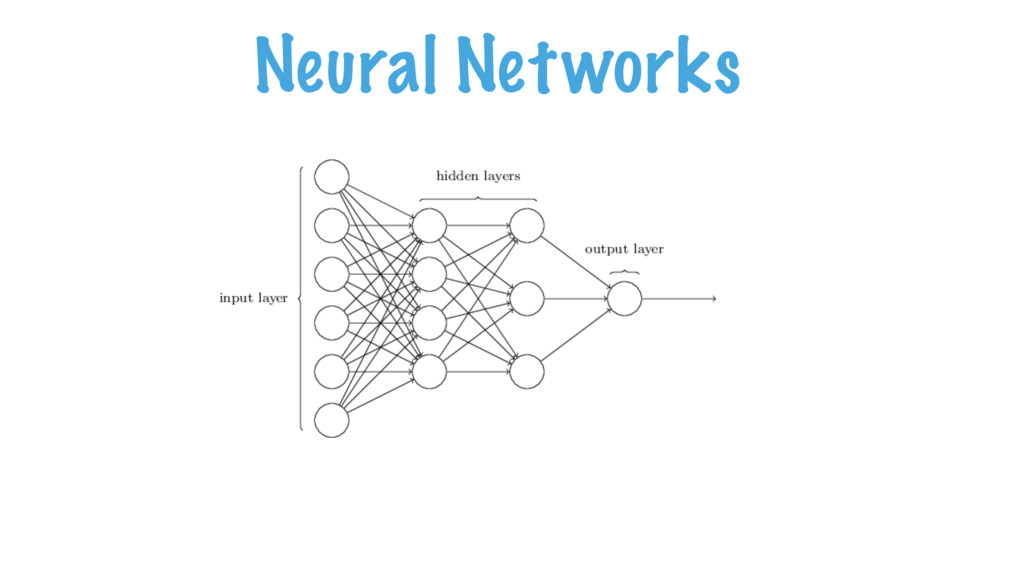
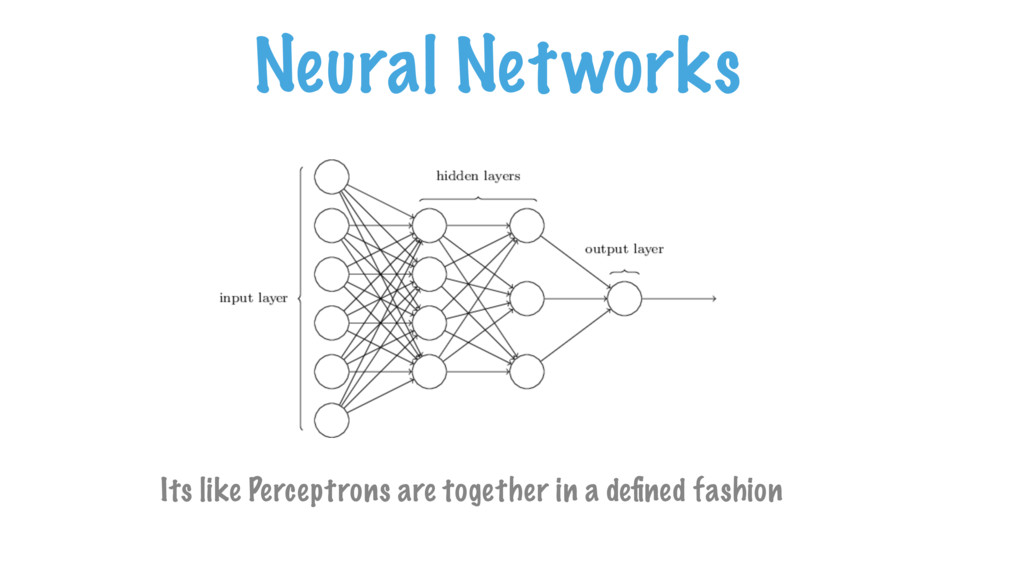
  1. The most basic form of neural network which can also

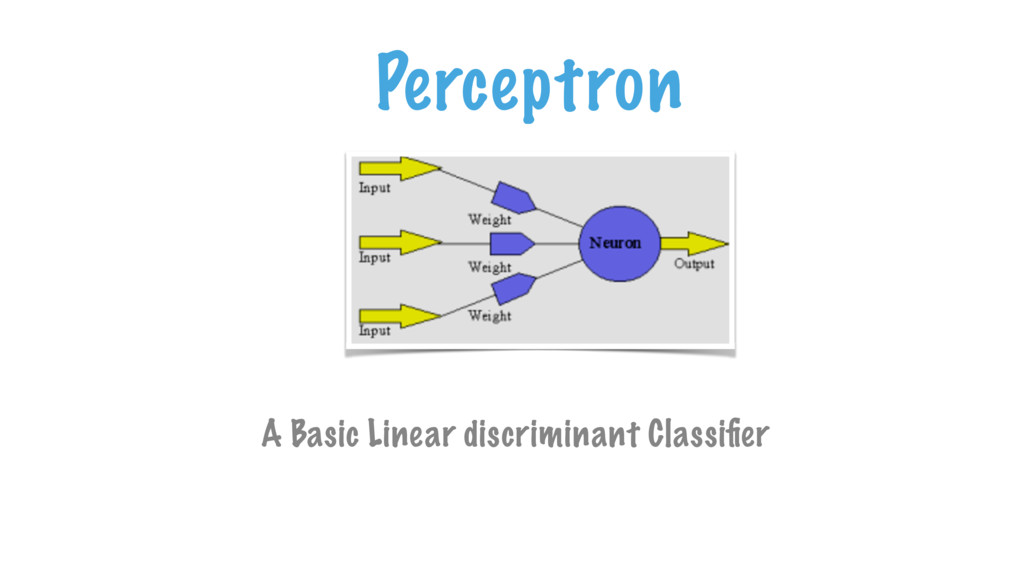
    learn Perceptron The elementary entity of a neural network.
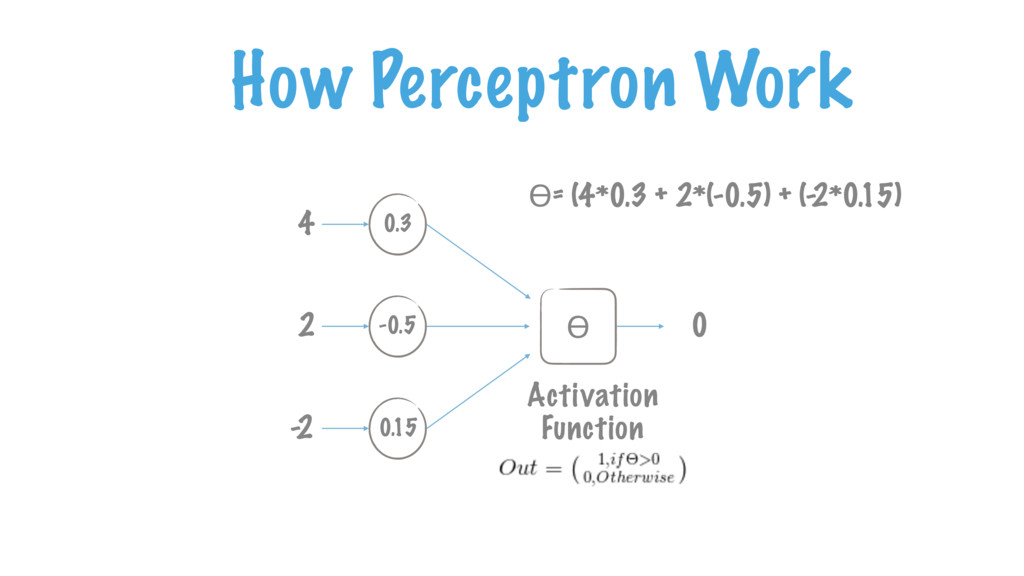
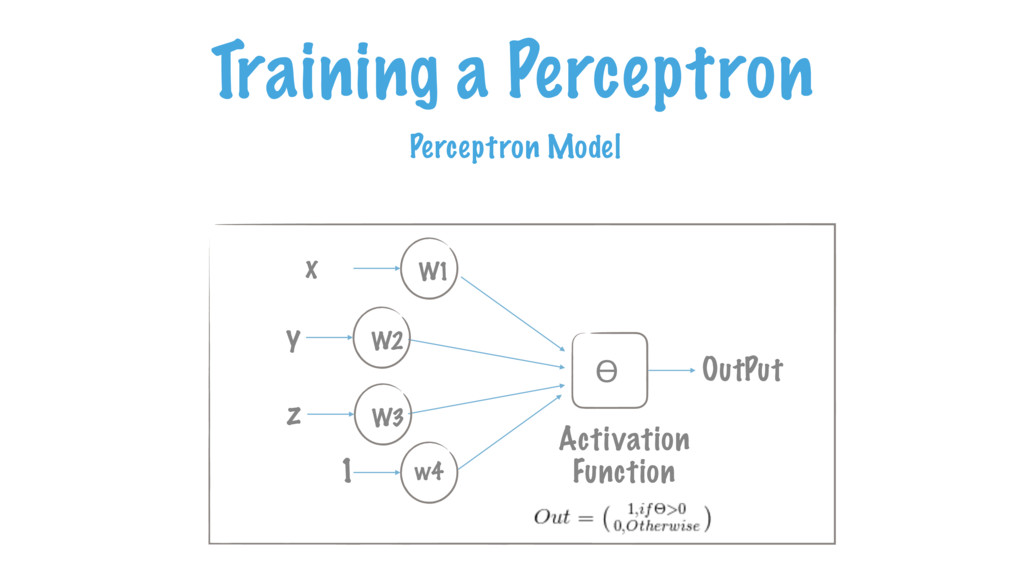
  2. How Perceptron Work 0.3 -0.5 0.15 Activation Function ϴ 4

    2 -2 0 ϴ= (4*0.3 + 2*(-0.5) + (-2*0.15)
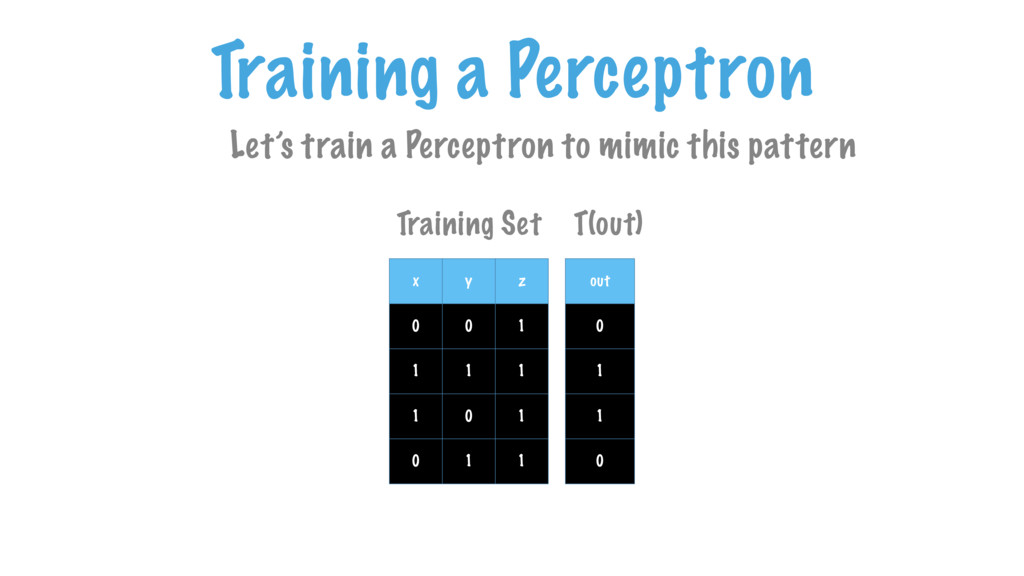
  3. Training a Perceptron Let’s train a Perceptron to mimic this

    pattern x y z 0 0 1 1 1 1 1 0 1 0 1 1 Training Set out 0 1 1 0 T(out)
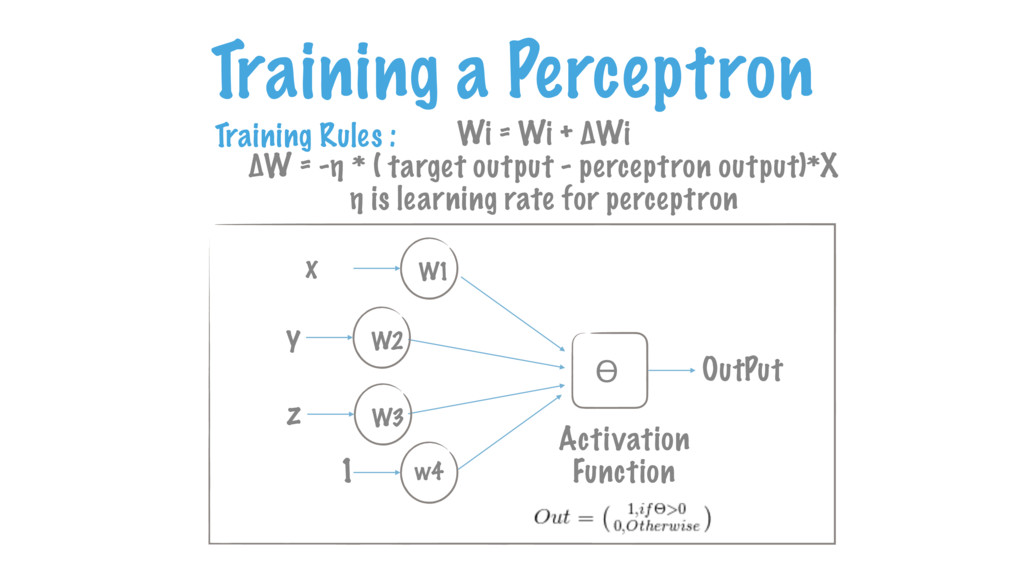
  4. Wi = Wi + ∆Wi ∆W = -η * (

    target output - perceptron output)*X η is learning rate for perceptron Training Rules : W1 w4 Activation Function ϴ OutPut W2 W3 x y z 1 Training a Perceptron
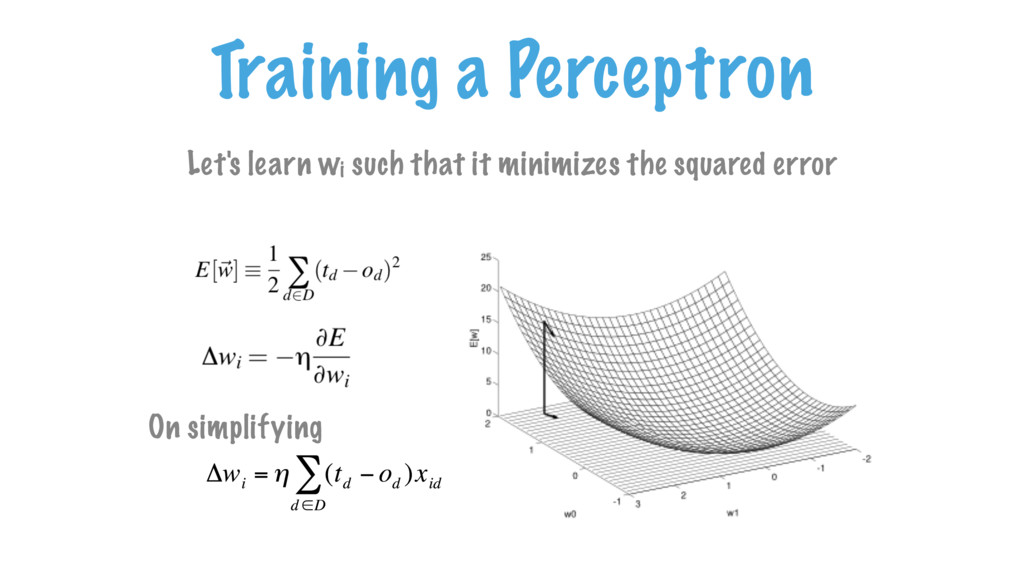
  5. Let's learn wi such that it minimizes the squared error

    On simplifying Training a Perceptron
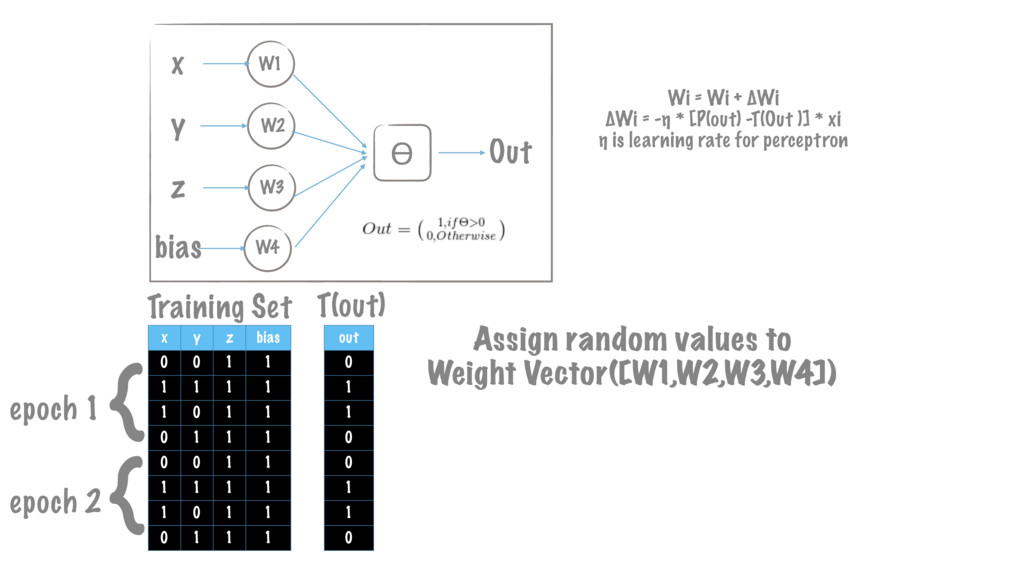
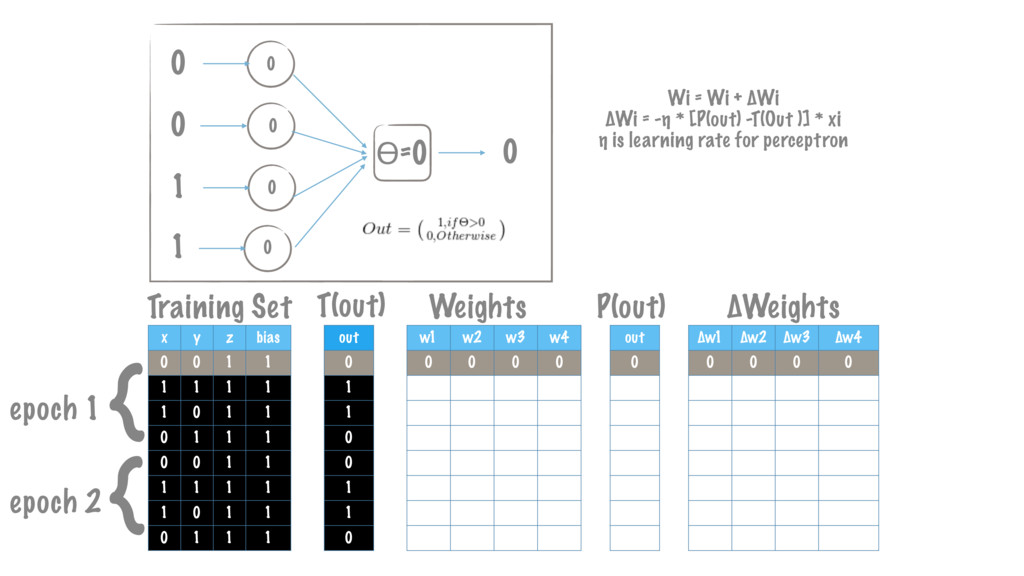
  6. W1 ϴ Out Assign random values to Weight Vector([W1,W2,W3,W4]) x

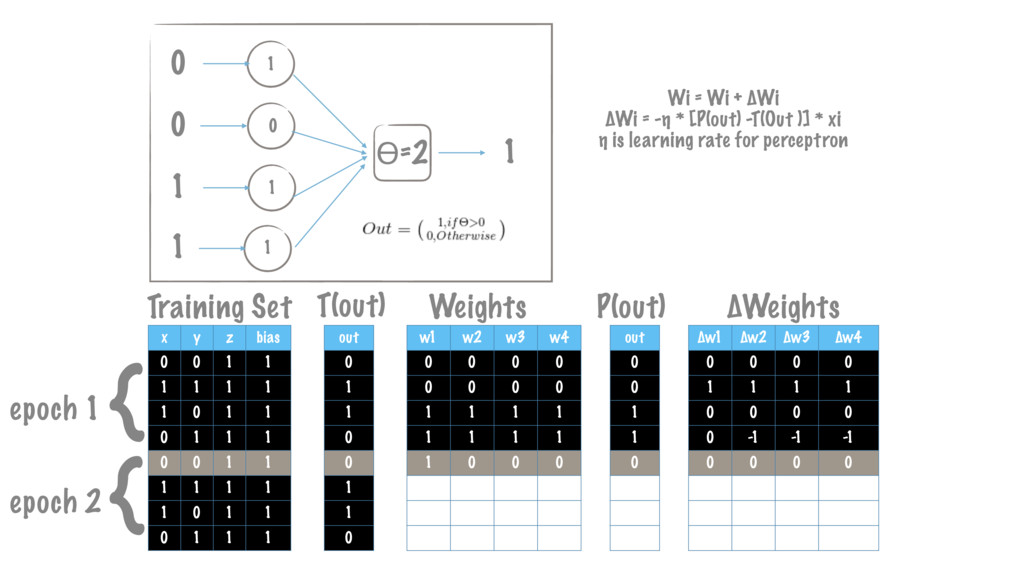
    y z bias 0 0 1 1 1 1 1 1 1 0 1 1 0 1 1 1 0 0 1 1 1 1 1 1 1 0 1 1 0 1 1 1 Training Set out 0 1 1 0 0 1 1 0 T(out) W2 W3 W4 x y z bias { { epoch 1 epoch 2 Wi = Wi + ∆Wi ∆Wi = -η * [P(out) -T(Out )] * xi η is learning rate for perceptron
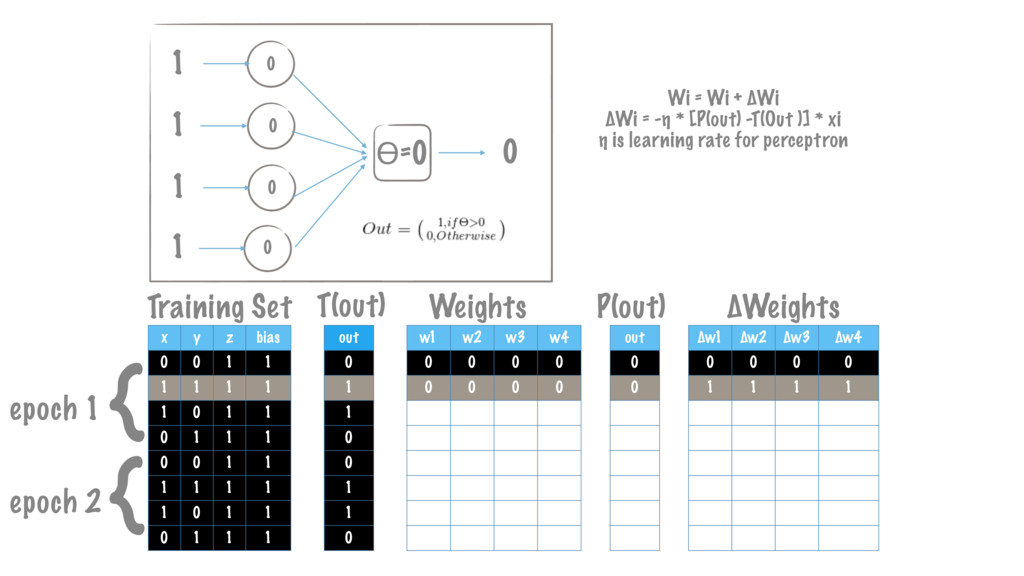
  7. x y z bias 0 0 1 1 1 1

    1 1 1 0 1 1 0 1 1 1 0 0 1 1 1 1 1 1 1 0 1 1 0 1 1 1 ∆w1 ∆w2 ∆w3 ∆w4 0 0 0 0 1 1 1 1 0 0 0 0 0 -1 -1 -1 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 w1 w2 w3 w4 0 0 0 0 0 0 0 0 1 1 1 1 1 1 1 1 1 0 0 0 1 0 0 0 1 0 0 0 1 0 0 0 out 0 0 1 1 0 1 1 0 Training Set Weights P(out) ∆Weights out 0 0 1 1 0 1 1 0 T(out) 0 ϴ=0 0 0 0 0 0 0 1 1 { { epoch 1 epoch 2 Wi = Wi + ∆Wi ∆Wi = -η * [P(out) -T(Out )] * xi η is learning rate for perceptron out 0 1 1 0 0 1 1 0
  8. x y z bias 0 0 1 1 1 1

    1 1 1 0 1 1 0 1 1 1 0 0 1 1 1 1 1 1 1 0 1 1 0 1 1 1 ∆w1 ∆w2 ∆w3 ∆w4 0 0 0 0 1 1 1 1 0 0 0 0 0 -1 -1 -1 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 w1 w2 w3 w4 0 0 0 0 0 0 0 0 1 1 1 1 1 1 1 1 1 0 0 0 1 0 0 0 1 0 0 0 1 0 0 0 out 0 0 1 1 0 1 1 0 Training Set Weights P(out) ∆Weights out 0 0 1 1 0 1 1 0 T(out) { { epoch 1 epoch 2 0 ϴ=0 0 0 0 0 1 1 1 1 Wi = Wi + ∆Wi ∆Wi = -η * [P(out) -T(Out )] * xi η is learning rate for perceptron out 0 1 1 0 0 1 1 0
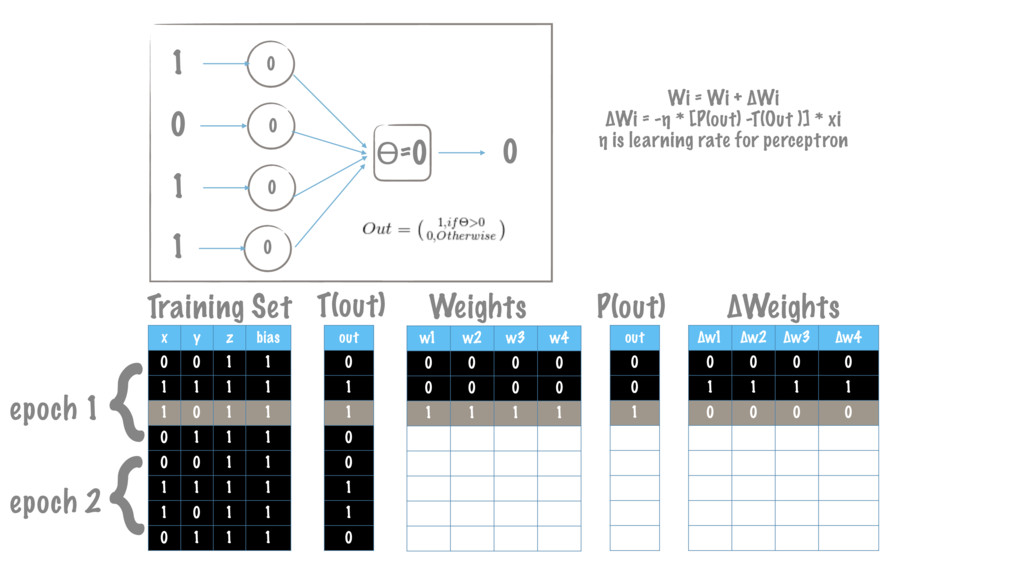
  9. x y z bias 0 0 1 1 1 1

    1 1 1 0 1 1 0 1 1 1 0 0 1 1 1 1 1 1 1 0 1 1 0 1 1 1 ∆w1 ∆w2 ∆w3 ∆w4 0 0 0 0 1 1 1 1 0 0 0 0 0 -1 -1 -1 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 w1 w2 w3 w4 0 0 0 0 0 0 0 0 1 1 1 1 1 1 1 1 1 0 0 0 1 0 0 0 1 0 0 0 1 0 0 0 out 0 0 1 1 0 1 1 0 Training Set Weights P(out) ∆Weights T(out) { { epoch 1 epoch 2 0 ϴ=0 0 0 0 0 1 0 1 1 Wi = Wi + ∆Wi ∆Wi = -η * [P(out) -T(Out )] * xi η is learning rate for perceptron out 0 1 1 0 0 1 1 0
  10. x y z bias 0 0 1 1 1 1

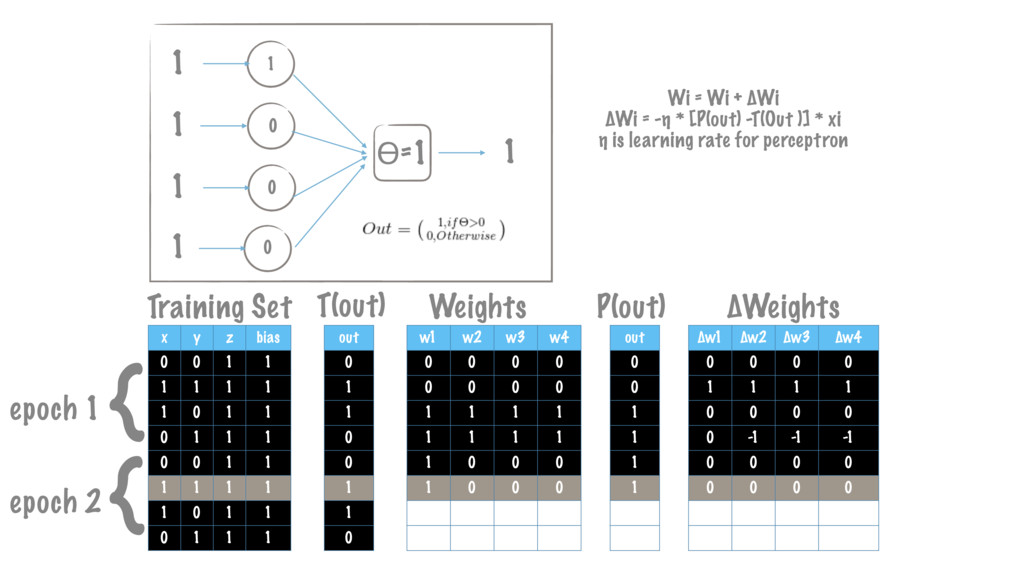
    1 1 1 0 1 1 0 1 1 1 0 0 1 1 1 1 1 1 1 0 1 1 0 1 1 1 ∆w1 ∆w2 ∆w3 ∆w4 0 0 0 0 1 1 1 1 0 0 0 0 0 -1 -1 -1 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 w1 w2 w3 w4 0 0 0 0 0 0 0 0 1 1 1 1 1 1 1 1 1 0 0 0 1 0 0 0 1 0 0 0 1 0 0 0 out 0 0 1 1 0 1 1 0 Training Set Weights P(out) ∆Weights out 0 1 1 0 0 1 1 0 T(out) { { epoch 1 epoch 2 1 ϴ=1 1 0 1 1 0 1 1 1 Wi = Wi + ∆Wi ∆Wi = -η * [P(out) -T(Out )] * xi η is learning rate for perceptron
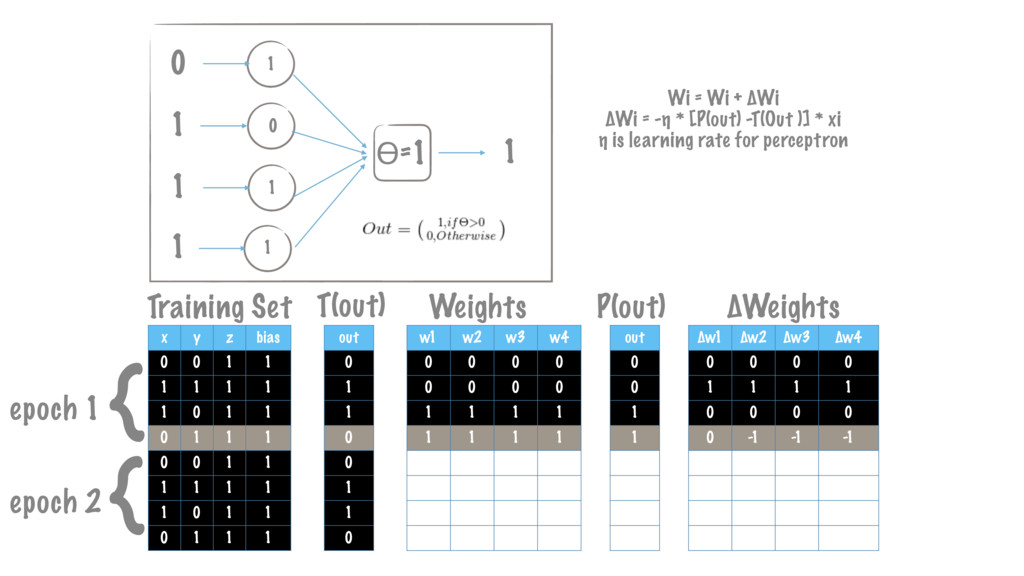
  11. x y z bias 0 0 1 1 1 1

    1 1 1 0 1 1 0 1 1 1 0 0 1 1 1 1 1 1 1 0 1 1 0 1 1 1 ∆w1 ∆w2 ∆w3 ∆w4 0 0 0 0 1 1 1 1 0 0 0 0 0 -1 -1 -1 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 w1 w2 w3 w4 0 0 0 0 0 0 0 0 1 1 1 1 1 1 1 1 1 0 0 0 1 0 0 0 1 0 0 0 1 0 0 0 out 0 0 1 1 0 1 1 0 Training Set Weights P(out) ∆Weights out 0 1 1 0 0 1 1 0 T(out) 1 ϴ=2 1 0 1 1 0 0 1 1 Wi = Wi + ∆Wi ∆Wi = -η * [P(out) -T(Out )] * xi η is learning rate for perceptron { { epoch 1 epoch 2 Wi = Wi + ∆Wi ∆Wi = -η * [P(out) -T(Out )] * xi η is learning rate for perceptron
  12. x y z bias 0 0 1 1 1 1

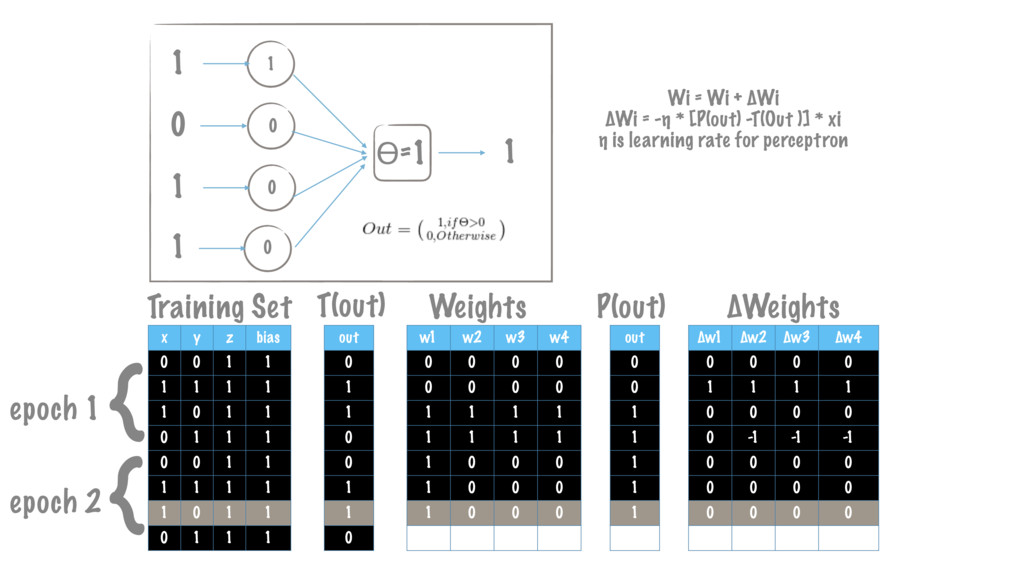
    1 1 1 0 1 1 0 1 1 1 0 0 1 1 1 1 1 1 1 0 1 1 0 1 1 1 ∆w1 ∆w2 ∆w3 ∆w4 0 0 0 0 1 1 1 1 0 0 0 0 0 -1 -1 -1 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 w1 w2 w3 w4 0 0 0 0 0 0 0 0 1 1 1 1 1 1 1 1 1 0 0 0 1 0 0 0 1 0 0 0 1 0 0 0 out 0 0 1 1 1 1 1 0 Training Set Weights P(out) ∆Weights out 0 1 1 0 0 1 1 0 T(out) 1 ϴ=1 1 0 0 0 1 1 1 1 Wi = Wi + ∆Wi ∆Wi = -η * [P(out) -T(Out )] * xi η is learning rate for perceptron { { epoch 1 epoch 2 Wi = Wi + ∆Wi ∆Wi = -η * [P(out) -T(Out )] * xi η is learning rate for perceptron
  13. x y z bias 0 0 1 1 1 1

    1 1 1 0 1 1 0 1 1 1 0 0 1 1 1 1 1 1 1 0 1 1 0 1 1 1 ∆w1 ∆w2 ∆w3 ∆w4 0 0 0 0 1 1 1 1 0 0 0 0 0 -1 -1 -1 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 w1 w2 w3 w4 0 0 0 0 0 0 0 0 1 1 1 1 1 1 1 1 1 0 0 0 1 0 0 0 1 0 0 0 1 0 0 0 out 0 0 1 1 1 1 1 0 Training Set Weights P(out) ∆Weights out 0 1 1 0 0 1 1 0 T(out) 1 ϴ=1 1 0 0 0 1 0 1 1 Wi = Wi + ∆Wi ∆Wi = -η * [P(out) -T(Out )] * xi η is learning rate for perceptron { { epoch 1 epoch 2 Wi = Wi + ∆Wi ∆Wi = -η * [P(out) -T(Out )] * xi η is learning rate for perceptron
  14. x y z bias 0 0 1 1 1 1

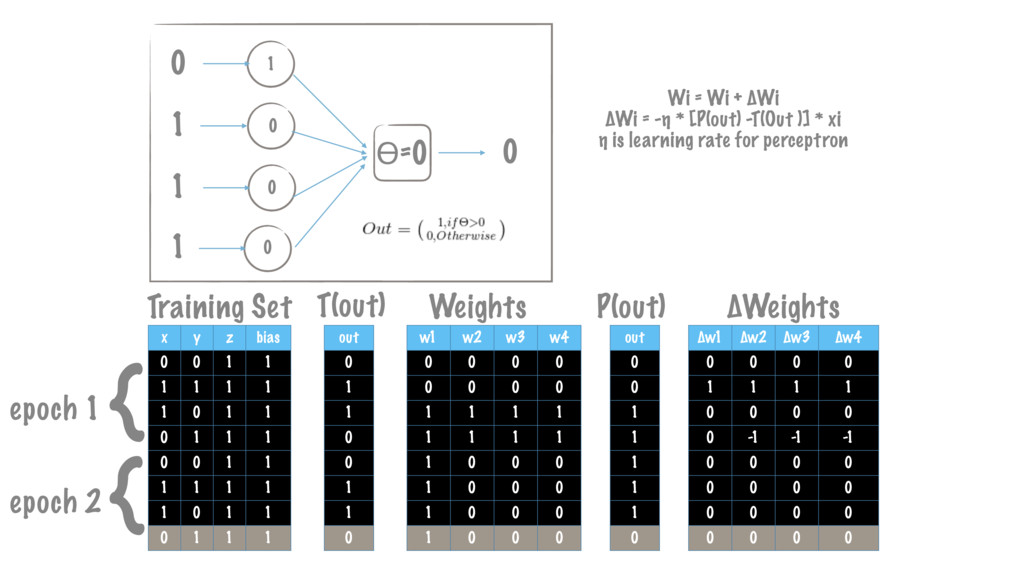
    1 1 1 0 1 1 0 1 1 1 0 0 1 1 1 1 1 1 1 0 1 1 0 1 1 1 ∆w1 ∆w2 ∆w3 ∆w4 0 0 0 0 1 1 1 1 0 0 0 0 0 -1 -1 -1 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 w1 w2 w3 w4 0 0 0 0 0 0 0 0 1 1 1 1 1 1 1 1 1 0 0 0 1 0 0 0 1 0 0 0 1 0 0 0 out 0 0 1 1 1 1 1 0 Training Set Weights P(out) ∆Weights out 0 1 1 0 0 1 1 0 T(out) 1 ϴ=0 0 0 0 0 0 1 1 1 Wi = Wi + ∆Wi ∆Wi = -η * [P(out) -T(Out )] * xi η is learning rate for perceptron { { epoch 1 epoch 2 Wi = Wi + ∆Wi ∆Wi = -η * [P(out) -T(Out )] * xi η is learning rate for perceptron
  15. x y z bias 0 0 1 1 1 1

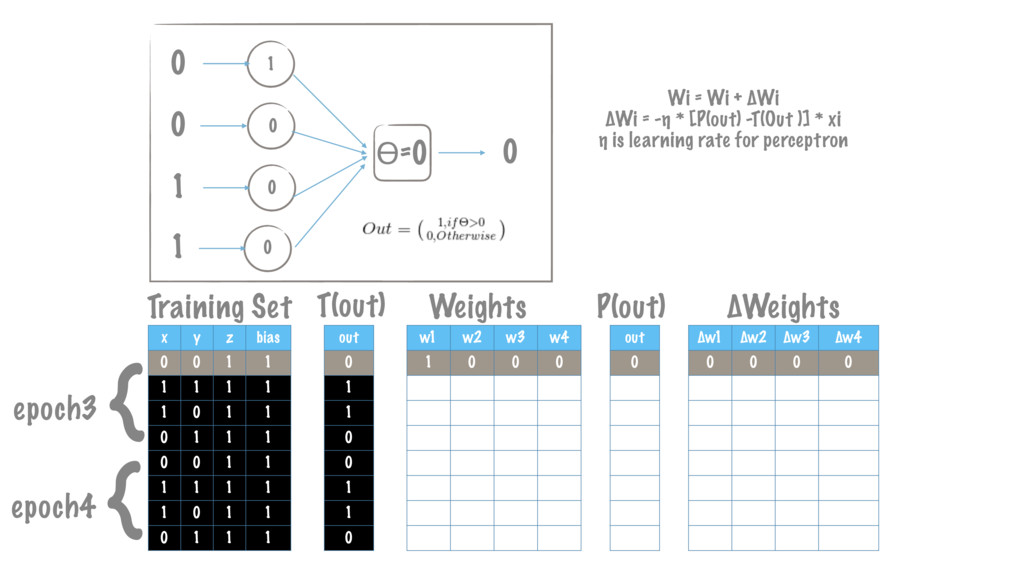
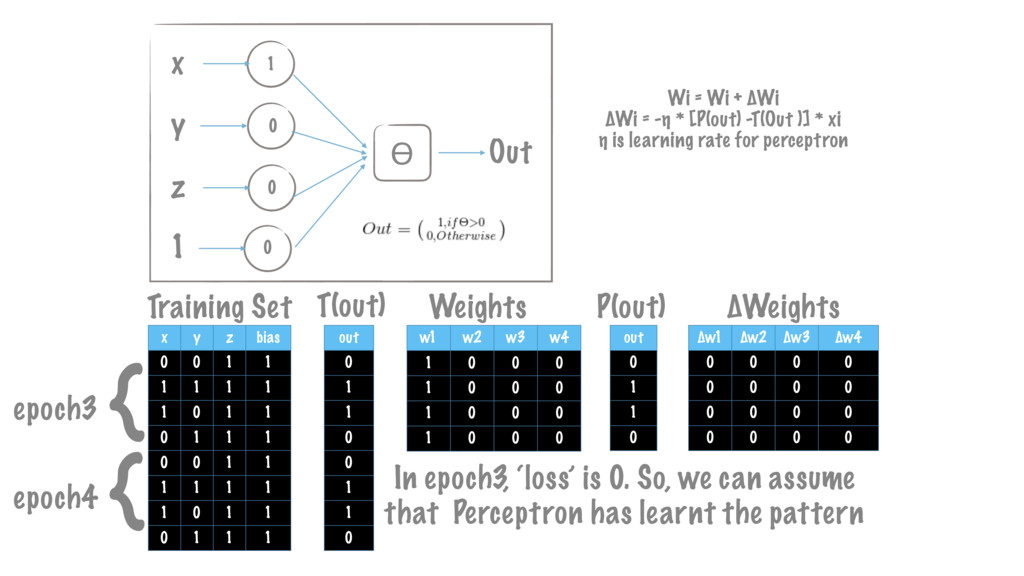
    1 1 1 0 1 1 0 1 1 1 0 0 1 1 1 1 1 1 1 0 1 1 0 1 1 1 ∆w1 ∆w2 ∆w3 ∆w4 0 0 0 0 0 0 0 0 1 0 1 1 0 0 0 0 0 0 -1 -1 0 0 0 0 0 0 0 0 0 0 0 0 w1 w2 w3 w4 1 0 0 0 0 0 0 0 0 0 0 0 1 0 1 1 1 0 1 1 1 0 0 0 1 0 0 0 1 0 0 0 out 0 0 0 1 1 1 1 0 Training Set Weights P(out) ∆Weights out 0 1 1 0 0 1 1 0 T(out) { epoch3 1 ϴ=0 0 0 0 0 0 0 1 1 Wi = Wi + ∆Wi ∆Wi = -η * [P(out) -T(Out )] * xi η is learning rate for perceptron { epoch4
  16. x y z bias 0 0 1 1 1 1

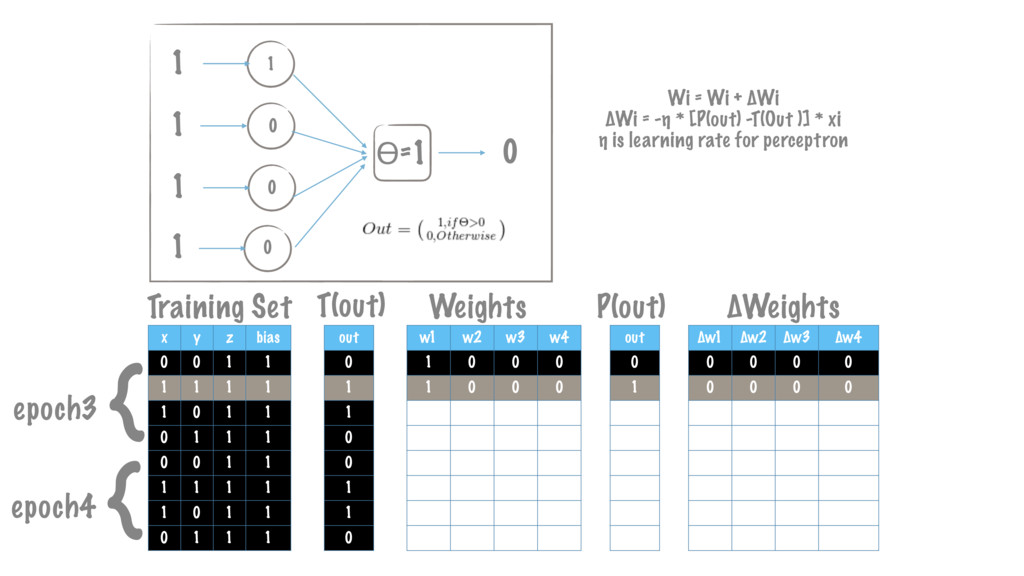
    1 1 1 0 1 1 0 1 1 1 0 0 1 1 1 1 1 1 1 0 1 1 0 1 1 1 ∆w1 ∆w2 ∆w3 ∆w4 0 0 0 0 0 0 0 0 1 0 1 1 0 0 0 0 0 0 -1 -1 0 0 0 0 0 0 0 0 0 0 0 0 w1 w2 w3 w4 1 0 0 0 1 0 0 0 0 0 0 0 1 0 1 1 1 0 1 1 1 0 0 0 1 0 0 0 1 0 0 0 out 0 1 0 1 1 1 1 0 Training Set Weights P(out) ∆Weights out 0 1 1 0 0 1 1 0 T(out) { epoch3 1 ϴ=1 0 0 0 0 1 1 1 1 Wi = Wi + ∆Wi ∆Wi = -η * [P(out) -T(Out )] * xi η is learning rate for perceptron { epoch4
  17. x y z bias 0 0 1 1 1 1

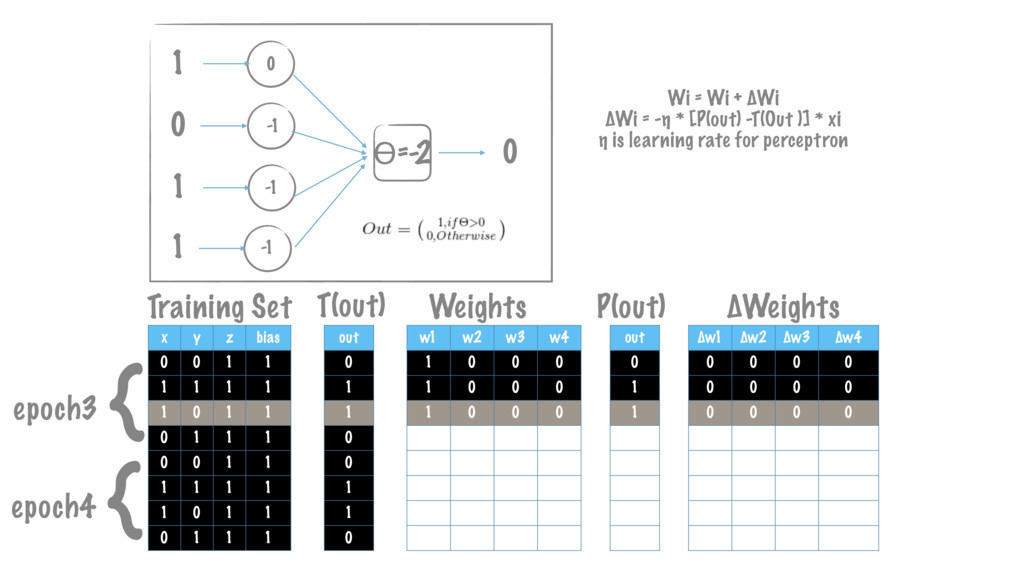
    1 1 1 0 1 1 0 1 1 1 0 0 1 1 1 1 1 1 1 0 1 1 0 1 1 1 ∆w1 ∆w2 ∆w3 ∆w4 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 -1 -1 0 0 0 0 0 0 0 0 0 0 0 0 w1 w2 w3 w4 1 0 0 0 1 0 0 0 1 0 0 0 1 0 1 1 1 0 1 1 1 0 0 0 1 0 0 0 1 0 0 0 out 0 1 1 1 1 1 1 0 Training Set Weights P(out) ∆Weights out 0 1 1 0 0 1 1 0 T(out) { epoch3 0 ϴ=-2 0 -1 -1 -1 1 0 1 1 Wi = Wi + ∆Wi ∆Wi = -η * [P(out) -T(Out )] * xi η is learning rate for perceptron { epoch4
  18. x y z bias 0 0 1 1 1 1

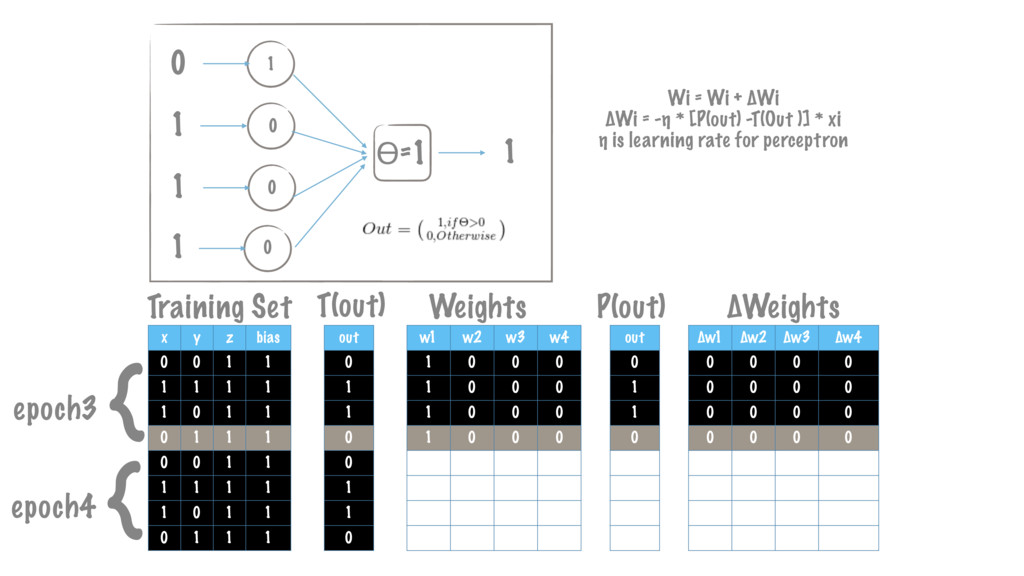
    1 1 1 0 1 1 0 1 1 1 0 0 1 1 1 1 1 1 1 0 1 1 0 1 1 1 ∆w1 ∆w2 ∆w3 ∆w4 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 -1 -1 0 0 0 0 0 0 0 0 0 0 0 0 w1 w2 w3 w4 1 0 0 0 1 0 0 0 1 0 0 0 1 0 0 0 1 0 1 1 1 0 0 0 1 0 0 0 1 0 0 0 out 0 1 1 0 1 1 1 0 Training Set Weights P(out) ∆Weights out 0 1 1 0 0 1 1 0 T(out) { epoch3 1 ϴ=1 1 0 0 0 0 1 1 1 Wi = Wi + ∆Wi ∆Wi = -η * [P(out) -T(Out )] * xi η is learning rate for perceptron { epoch4
  19. ∆w1 ∆w2 ∆w3 ∆w4 0 0 0 0 0 0

    0 0 0 0 0 0 0 0 0 0 w1 w2 w3 w4 1 0 0 0 1 0 0 0 1 0 0 0 1 0 0 0 out 0 1 1 0 Training Set Weights P(out) ∆Weights T(out) 1 ϴ Out 0 0 0 x y z 1 Wi = Wi + ∆Wi ∆Wi = -η * [P(out) -T(Out )] * xi η is learning rate for perceptron { epoch3 Wi = Wi + ∆Wi ∆Wi = -η * [P(out) -T(Out )] * xi η is learning rate for perceptron x y z bias 0 0 1 1 1 1 1 1 1 0 1 1 0 1 1 1 0 0 1 1 1 1 1 1 1 0 1 1 0 1 1 1 out 0 1 1 0 0 1 1 0 In epoch3, ‘loss’ is 0. So, we can assume that Perceptron has learnt the pattern { epoch4
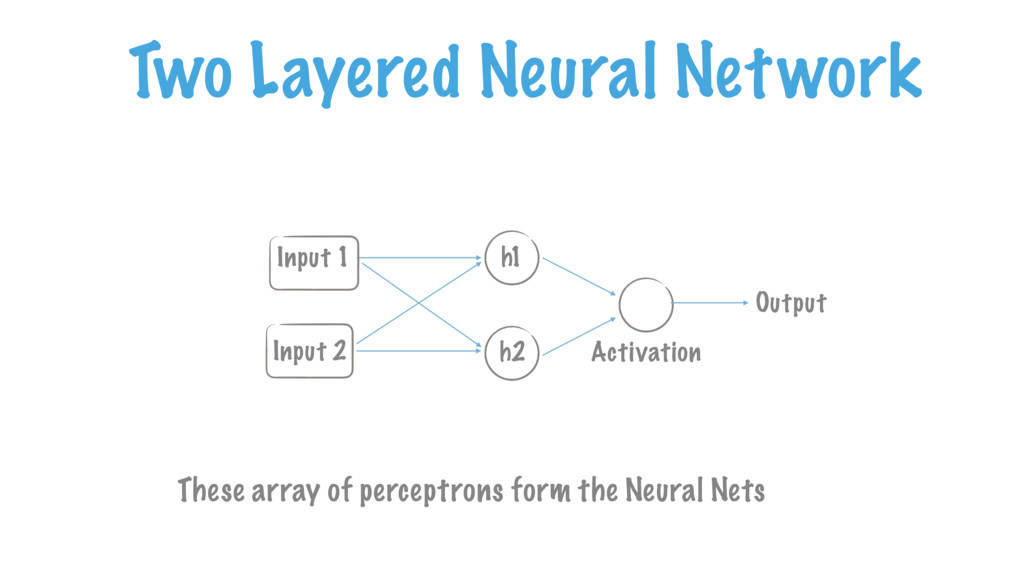
  20. Two Layered Neural Network These array of perceptrons form the

    Neural Nets h1 h2 Input 1 Input 2 Output Activation
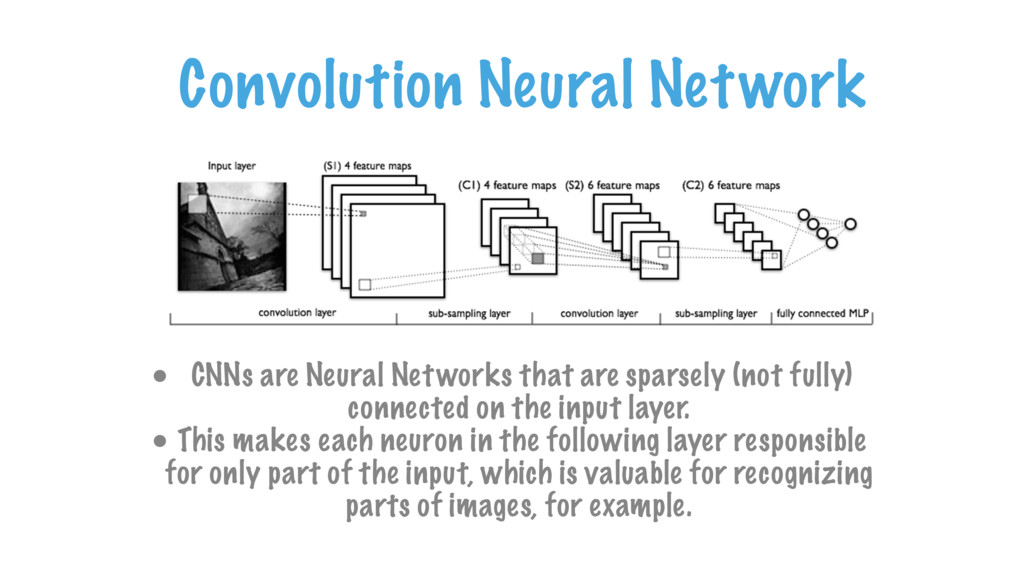
  21. Convolution Neural Network • CNNs are Neural Networks that are

    sparsely (not fully) connected on the input layer. • This makes each neuron in the following layer responsible for only part of the input, which is valuable for recognizing parts of images, for example.
  22. Convolutional Neural Network •Convolutional Neural Networks are very similar to

    ordinary Neural Networks •The architecture of a CNN is designed to take advantage of the 2D structure of an input image
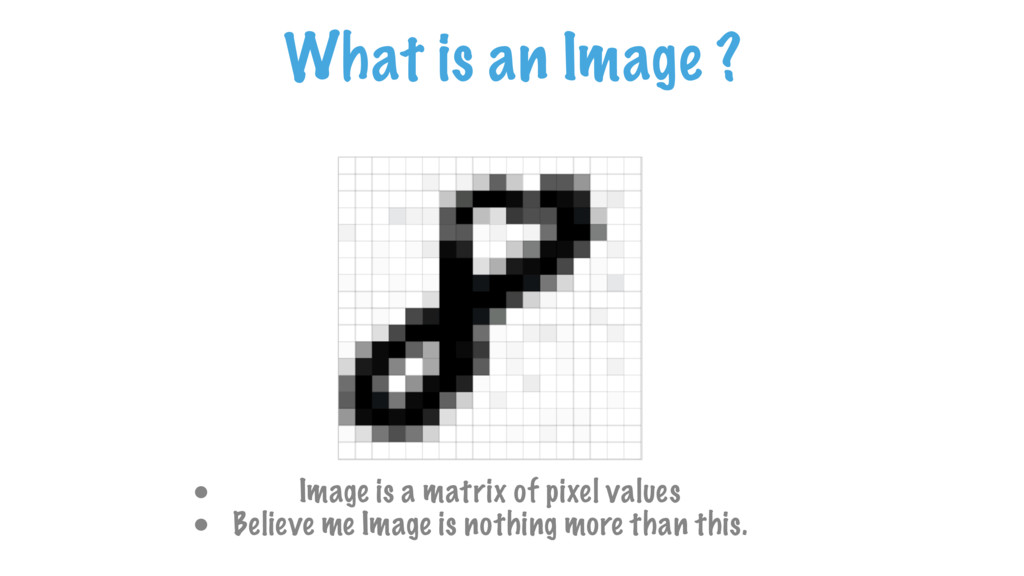
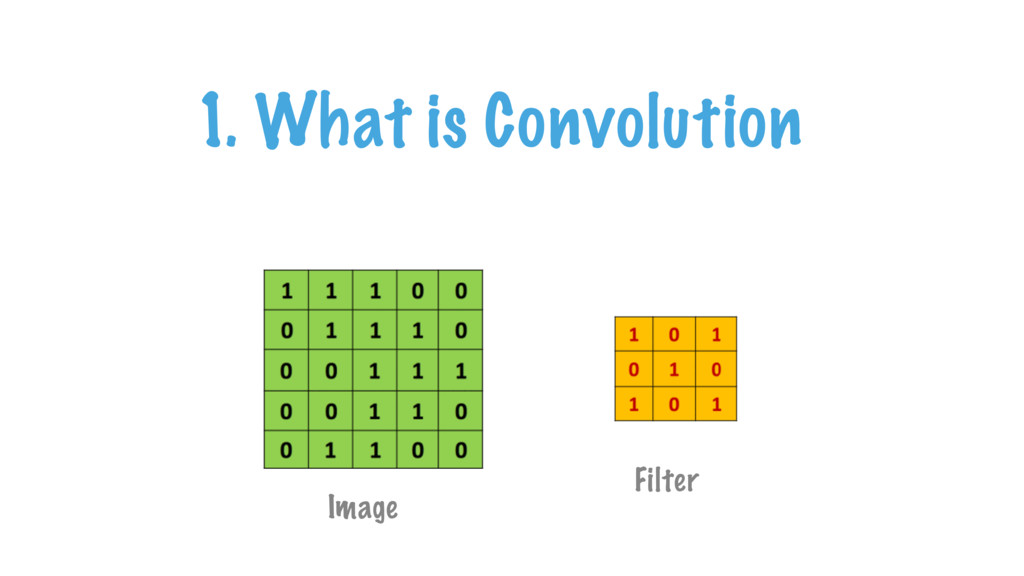
  23. What is an Image ? • Image is a matrix

    of pixel values • Believe me Image is nothing more than this.
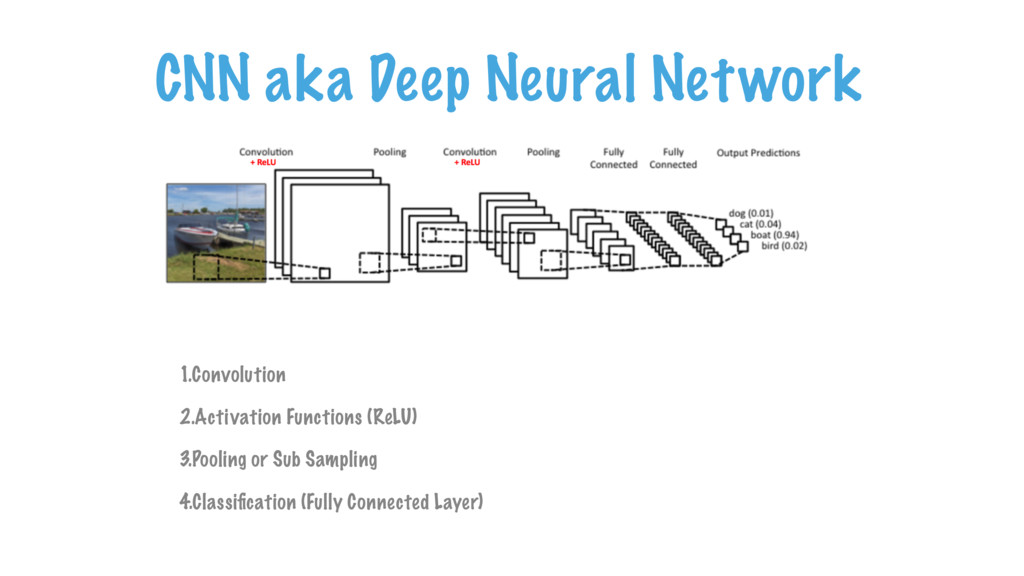
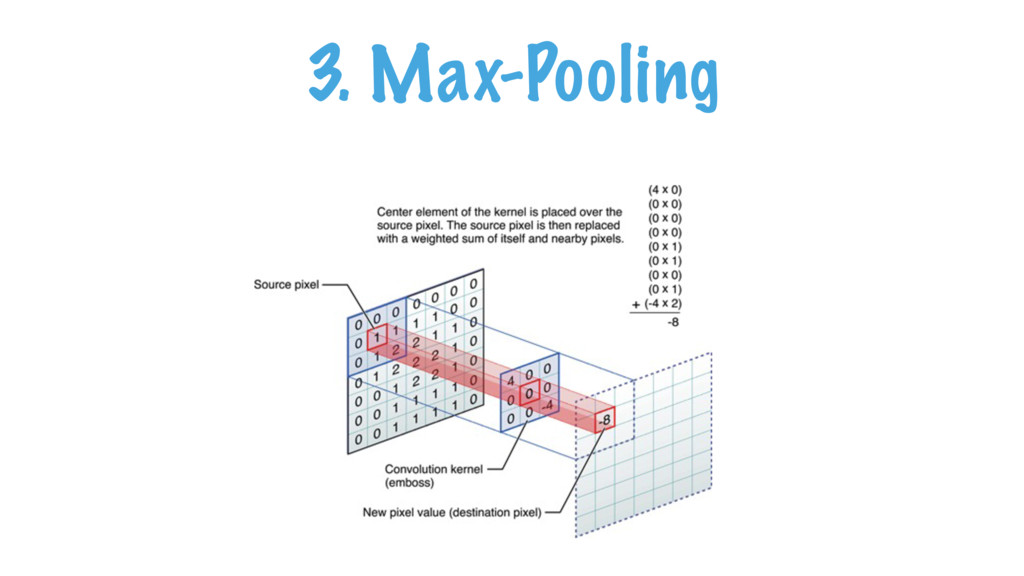
  24. CNN aka Deep Neural Network 1.Convolution 2.Activation Functions (ReLU) 3.Pooling

    or Sub Sampling 4.Classification (Fully Connected Layer)
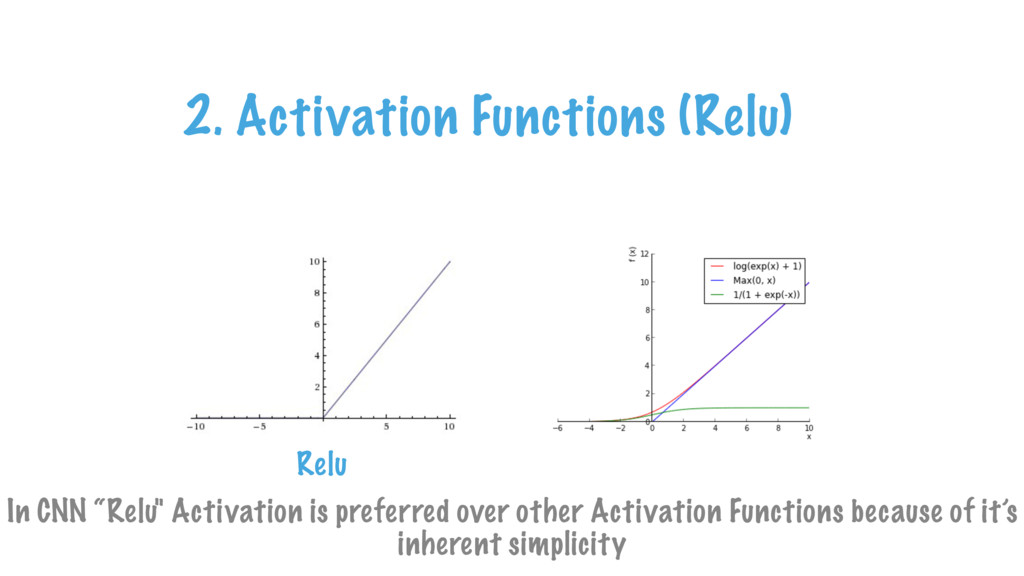
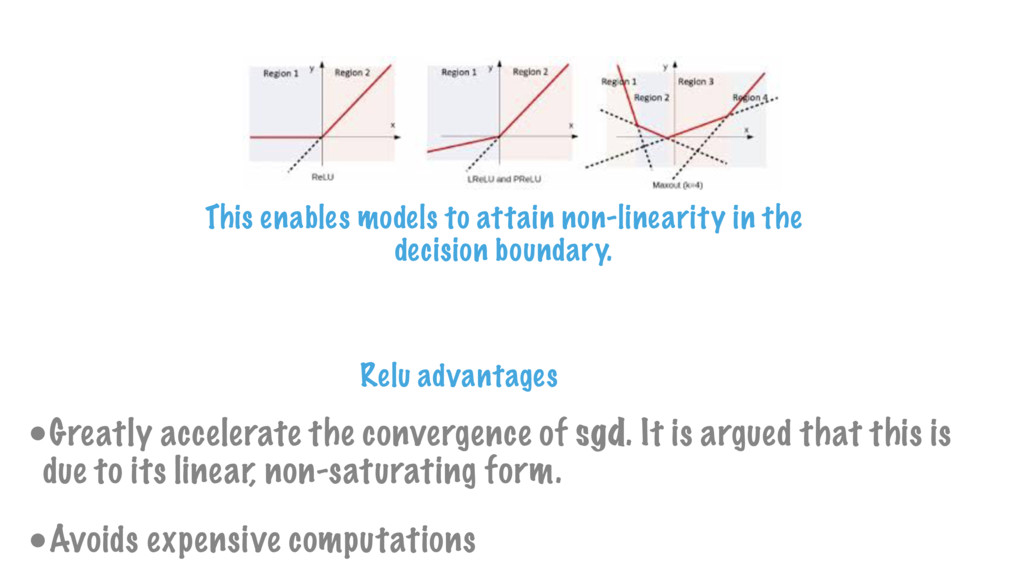
  25. 2. Activation Functions (Relu) Relu In CNN “Relu" Activation is

    preferred over other Activation Functions because of it’s inherent simplicity
  26. This enables models to attain non-linearity in the decision boundary.

    •Greatly accelerate the convergence of sgd. It is argued that this is due to its linear, non-saturating form. •Avoids expensive computations Relu advantages
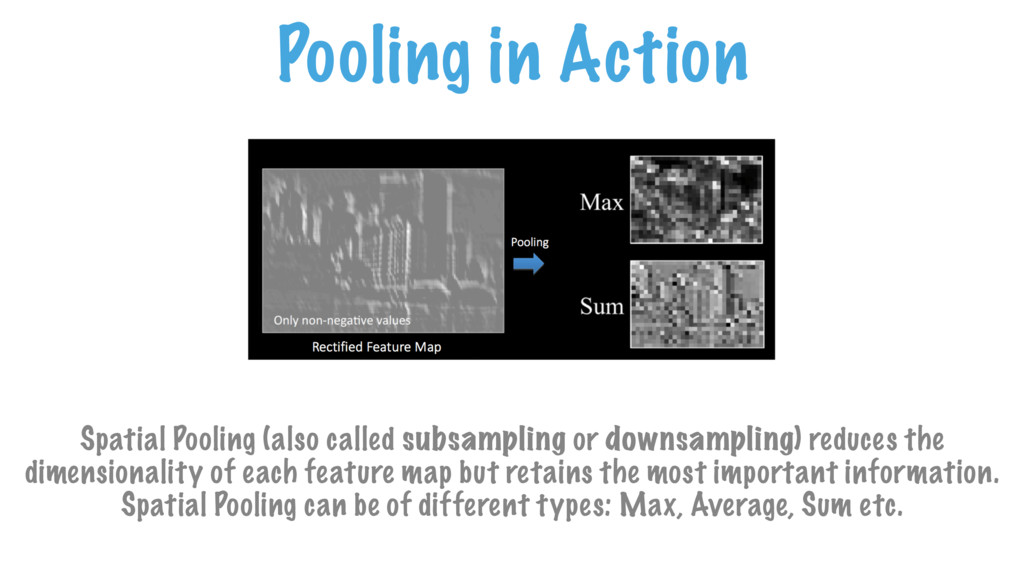
  27. Pooling in Action Spatial Pooling (also called subsampling or downsampling)

    reduces the dimensionality of each feature map but retains the most important information. Spatial Pooling can be of different types: Max, Average, Sum etc.
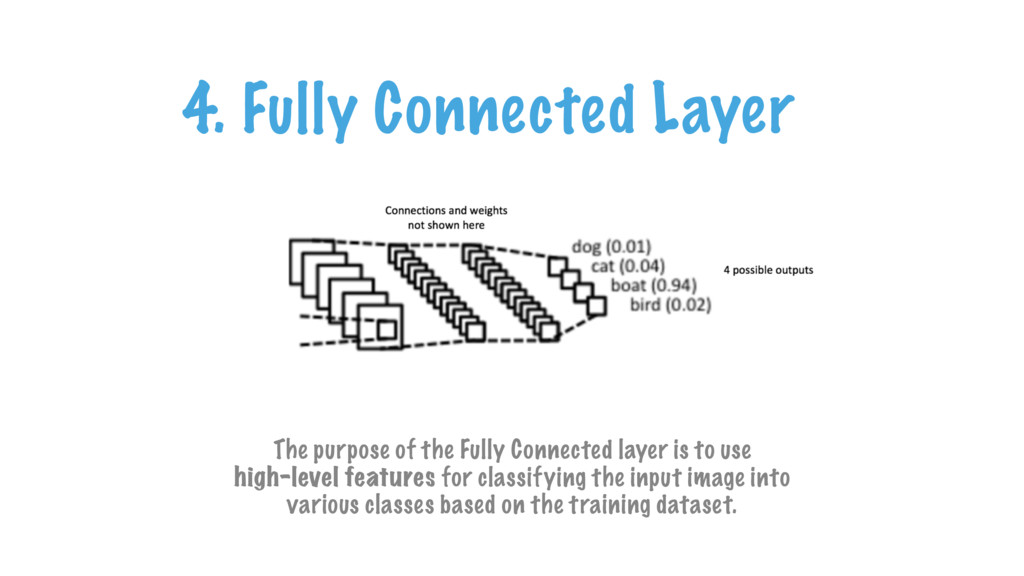
  28. The purpose of the Fully Connected layer is to use

    high-level features for classifying the input image into various classes based on the training dataset. 4. Fully Connected Layer
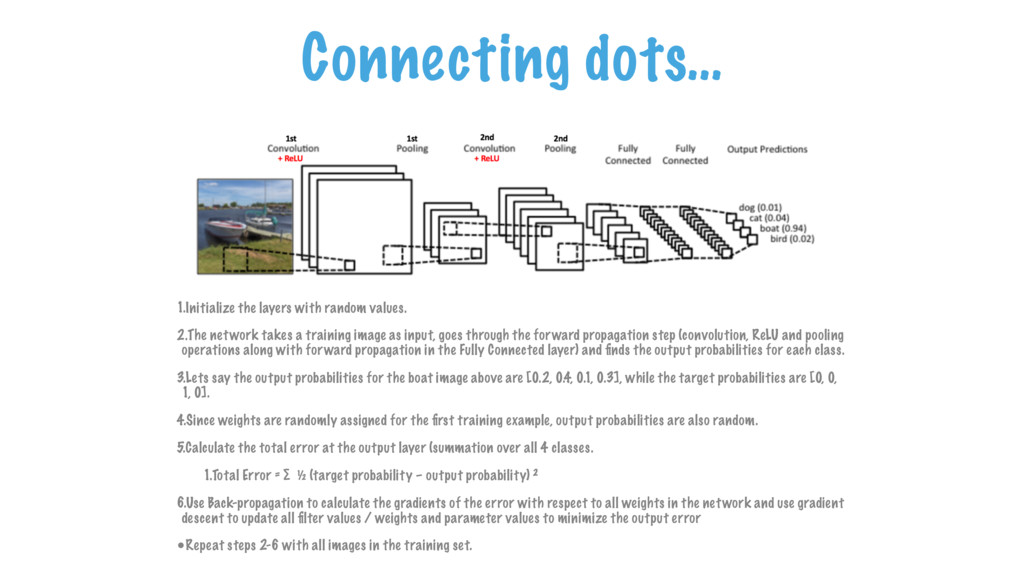
  29. Connecting dots… 1.Initialize the layers with random values. 2.The network

    takes a training image as input, goes through the forward propagation step (convolution, ReLU and pooling operations along with forward propagation in the Fully Connected layer) and finds the output probabilities for each class. 3.Lets say the output probabilities for the boat image above are [0.2, 0.4, 0.1, 0.3], while the target probabilities are [0, 0, 1, 0]. 4.Since weights are randomly assigned for the first training example, output probabilities are also random. 5.Calculate the total error at the output layer (summation over all 4 classes. 1.Total Error = ∑ ½ (target probability – output probability) ² 6.Use Back-propagation to calculate the gradients of the error with respect to all weights in the network and use gradient descent to update all filter values / weights and parameter values to minimize the output error •Repeat steps 2-6 with all images in the training set.
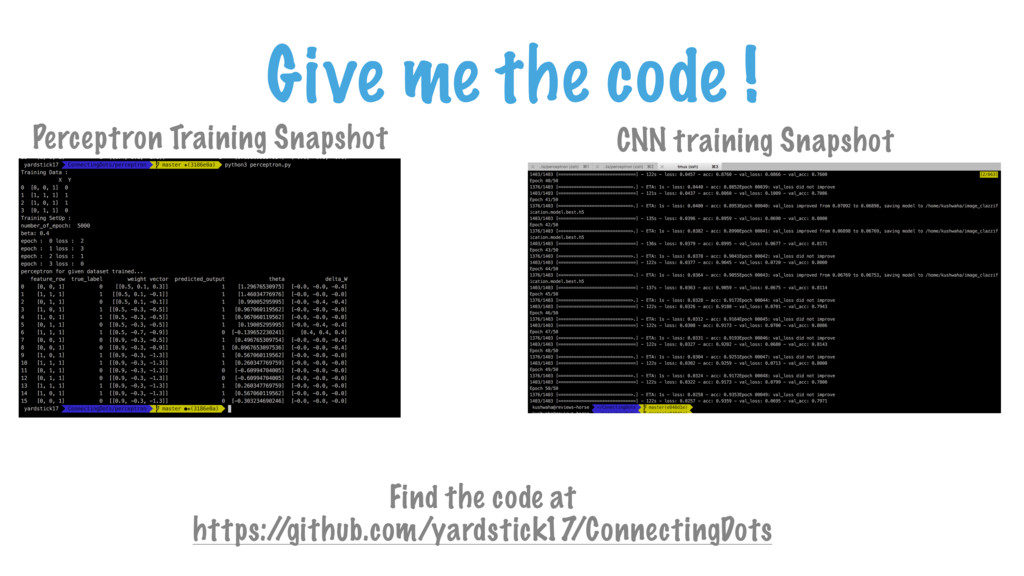
  30. Give me the code ! Find the code at https:/

    /github.com/yardstick17 /ConnectingDots Perceptron Training Snapshot CNN training Snapshot