Upgrade to Pro — share decks privately, control downloads, hide ads and more …

Kubeflow 進行分散式深度學習訓練之作業排程瓶頸

Sponsored · SiteGround - Reliable hosting with speed, security, and support you can count on. →
Frank Lin
August 17, 2019

Kubeflow 進行分散式深度學習訓練之作業排程瓶頸

COSCUP 2019

Frank Lin

August 17, 2019

Transcript

34 slides
  1. 林林義洋 Frank Lin C O S C U P 2019

    | SDN x Cloud Native x Golang Kubeflow 進⾏行行分散式深度學習訓練 之作業排程瓶頸
  2. 2 About Me • Master degree as CSIE, PU. •

    AI Research Center in CGU. • COSCUP 2018 Photography Volunteer (Team Leader). @yylin1([email protected]) https://yylin.io 林林義洋 Frank Lin
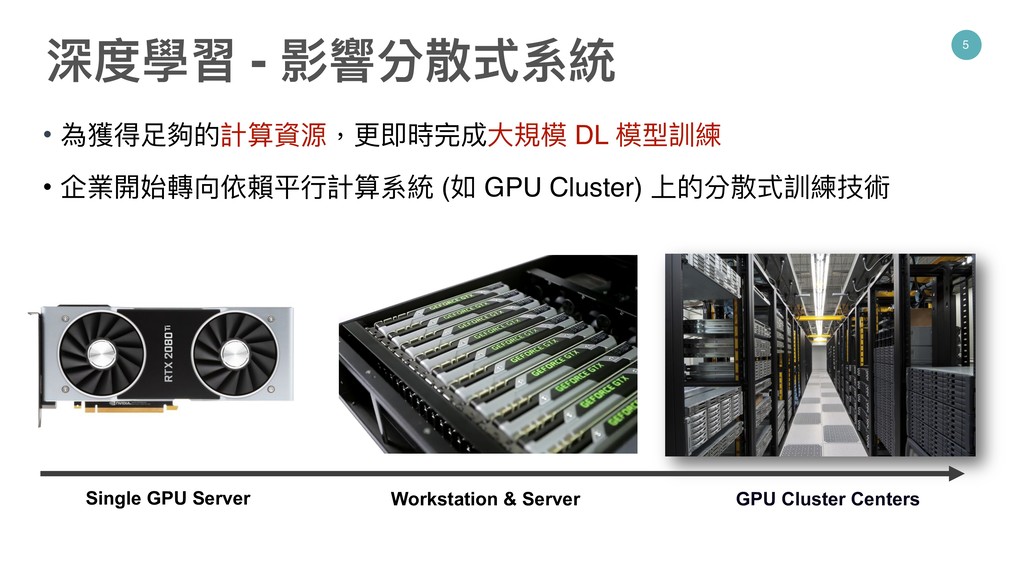
  3. 5 • 為獲得⾜足夠的計算資源,更更即時完成⼤大規模 DL 模型訓練 • 企業開始轉向依賴平⾏行行計算系統 (如 GPU Cluster)

    上的分散式訓練技術 深度學習 - 影響分散式系統 Single GPU Server Workstation & Server GPU Cluster Centers
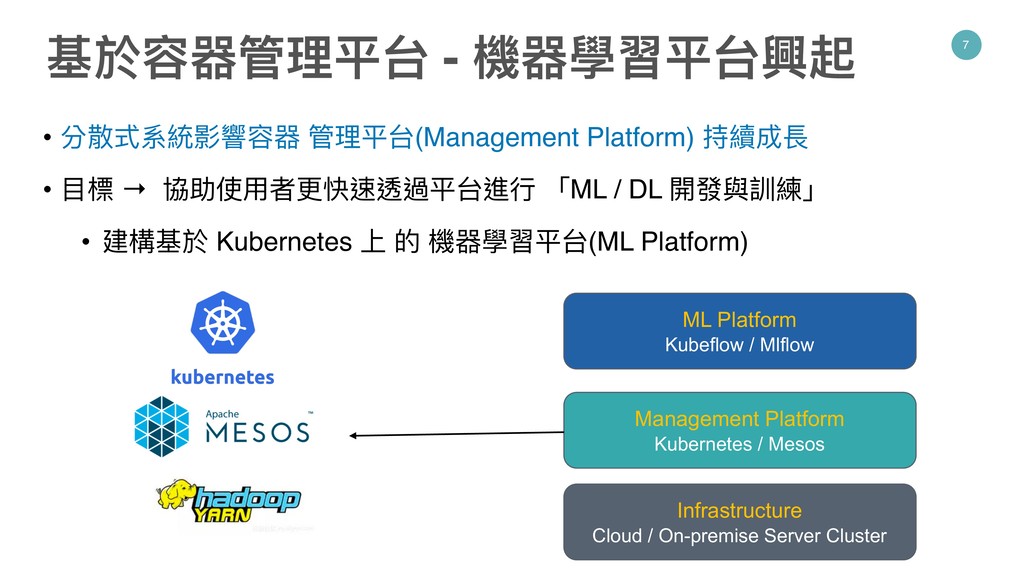
  4. • 分散式系統影響容器 管理理平台(Management Platform) 持續成長 • ⽬目標 → 協助使⽤用者更更快速透過平台進⾏行行 「ML

    / DL 開發與訓練」 • 建構基於 Kubernetes 上 的 機器學習平台(ML Platform) 基於容器管理理平台 - 機器學習平台興起 7 Infrastructure Cloud / On-premise Server Cluster Management Platform Kubernetes / Mesos ML Platform Kubeflow / Mlflow
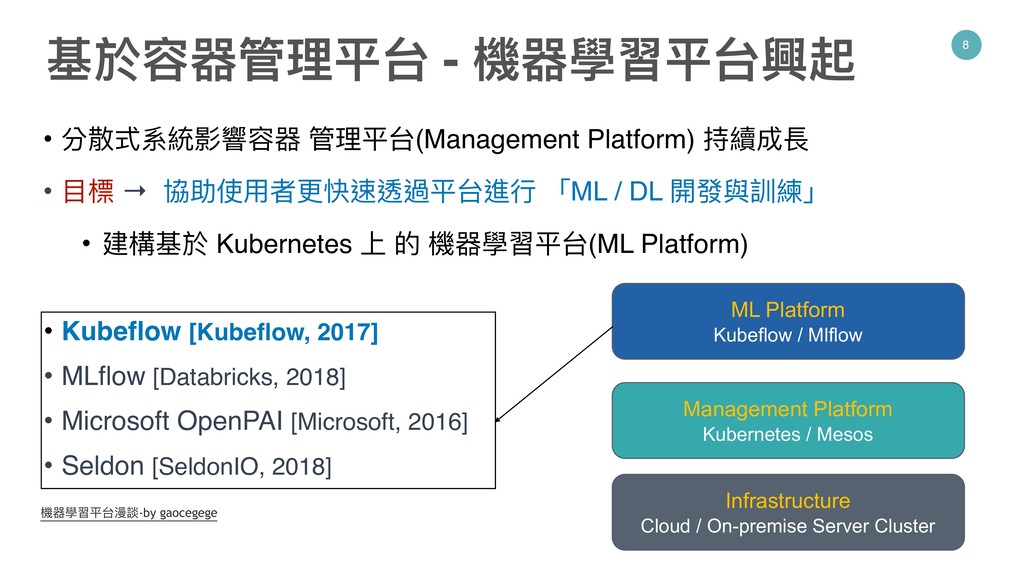
  5. • 分散式系統影響容器 管理理平台(Management Platform) 持續成長 • ⽬目標 → 協助使⽤用者更更快速透過平台進⾏行行 「ML

    / DL 開發與訓練」 • 建構基於 Kubernetes 上 的 機器學習平台(ML Platform) 基於容器管理理平台 - 機器學習平台興起 8 Infrastructure Cloud / On-premise Server Cluster Management Platform Kubernetes / Mesos ML Platform Kubeflow / Mlflow • Kubeflow [Kubeflow, 2017] • MLflow [Databricks, 2018] • Microsoft OpenPAI [Microsoft, 2016] • Seldon [SeldonIO, 2018] 機器學習平台漫談-by gaocegege
  6. 10

  7. 叢集資源分配⾯面臨臨挑戰 • 眾多⾼高性能伺服器配置昂貴硬體設施 : CPU、Memory 、GPU • 如何有效透過平台管理理 作業(Job) 分配,提⾼高整體系統使⽤用率和成本效益

    • ⽬目標: 有效管理理分散式 DL 作業運⾏行行於叢集環境 排程(Scheduler) 策略略研究 • 預設排程策略略,無法應⽤用於 分散式 DL 作業訓練 與 不同應⽤用場域 • 減少分散式溝通造成的網路路瓶頸 • 使作業獲得⾜足夠的計算資源,並更更即時完成⼤大規模 DL 模型訓練 11
  8. 13 • 分散式發展初期 MPI 、Hadoop、Spark 以及 Parameter Server 架構,都曾廣 泛應⽤用於機器學習處理理訓練任務

    • 現今針對 DL 分散式框架不斷發展,像開源社區活躍的熱⾨門框架包含:
 
 • 開發者在透過 Parameter Server 分散式架構下的⽀支持,設置⼀一次性作業(Job) 來來運⾏行行分散式 DL 任務(Task) 運⾏行行 DL 框架分散式發展
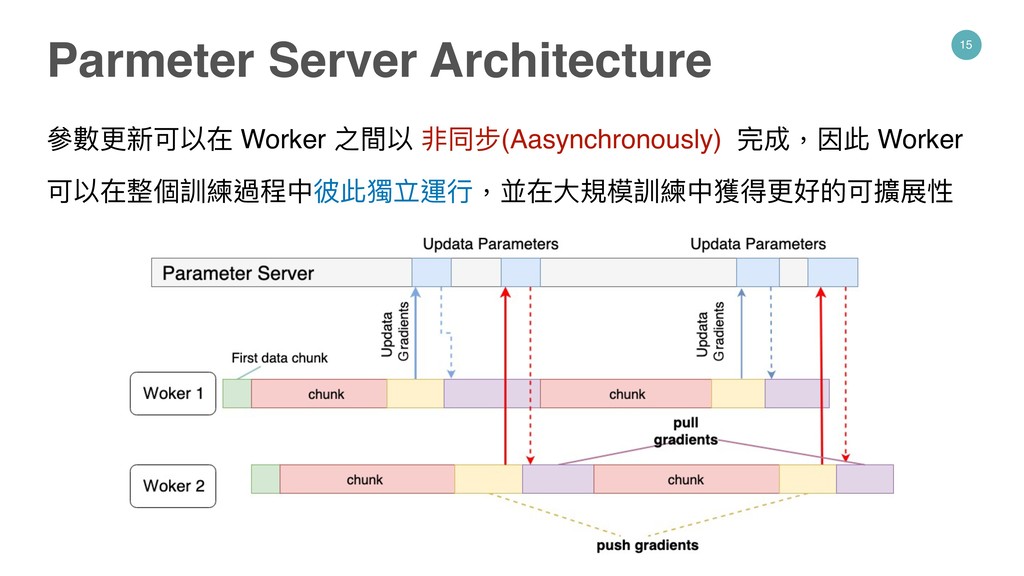
  9. 14 Parameter Server (PS) : • 負責維護⼀一個完整的全域共享參參數(Global Parameters),並將當前值(Value) 發送給每 個

    Worker 進⾏行行平⾏行行訓練 Worker : • 獲得從 PS 發送的域值(Value)來來計算每次迭 代(iteration)訓練 最 後 將 W o r k e r 訓 練 過 後 所 獲 得 新 的 梯 度 (Gradients),發送到 PS 並更更新參參數,即完成同步 更更新參參數的訓練流程 Parmeter Server Architecture Ref: Large Scale Distributed Deep Networks - NIPS Proceedings Parmeter Server Architecture
  10. Tensorflow 分散式訓練 17 tf.train.ClusterSpec({ "worker": [ "worker0.example.com:2222", "worker1.example.com:2222", "worker2.example.com:2222" ],

    "ps": [ "ps0.example.com:2222", "ps1.example.com:2222" ]}) 進⾏行行分佈式訓練配置過程,繁瑣的節點配置將成為 ML Developer 的負擔
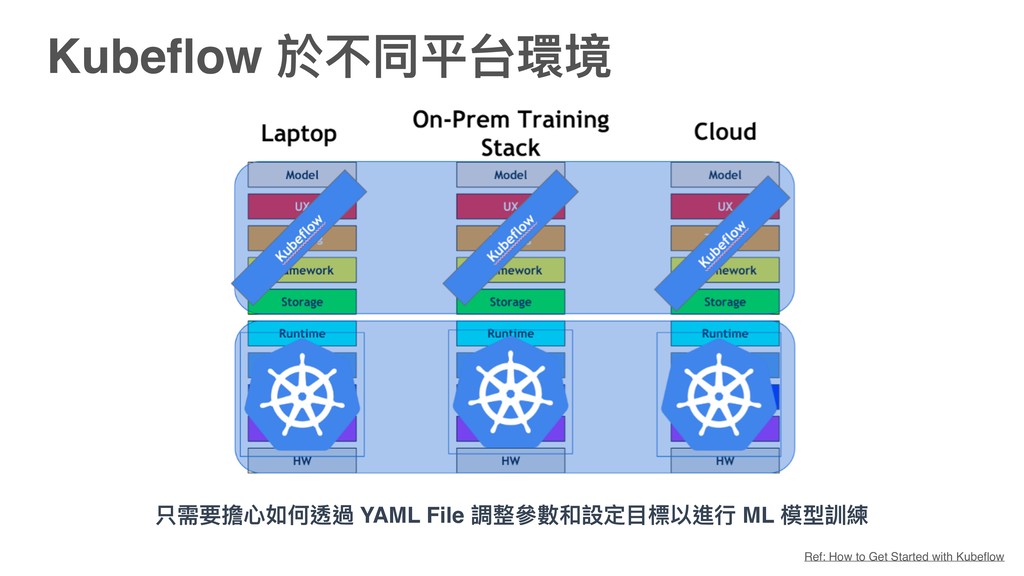
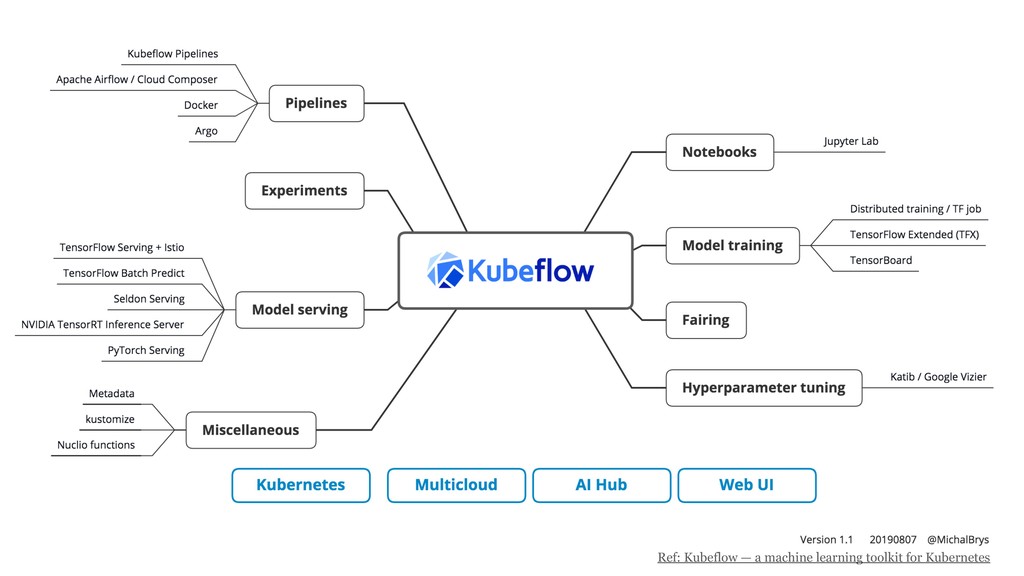
  11. What is Kubeflow? Kubeflow 是⼀一項基於 Kubernetes上 ML Workflow 開源專案。主要概念念是簡 化運⾏行行部署並整合

    ML 相關應⽤用 - 從原始資料到⽣生產訓練服務需求,提供⼀一整 套流⽔水線整合與多項不同應⽤用組件的平台。 • ⽬目標不是在於重建其他服務,⽽而是提供⼀一個最佳開發系統,來來部署到任何集群中,有效確 保ML 在集群之間移動性,並輕鬆將任務擴展任何叢集 • 由於使⽤用 Kubernetes 來來做為基礎,因此只要有 Kubernetes 的地⽅方,都能夠運⾏行行部署 Kubeflow
  12. 20 Make it Easy for Everyone to Develop, Deploy and

    Manage Portable, Distributed ML on Kubernetes # MESSION
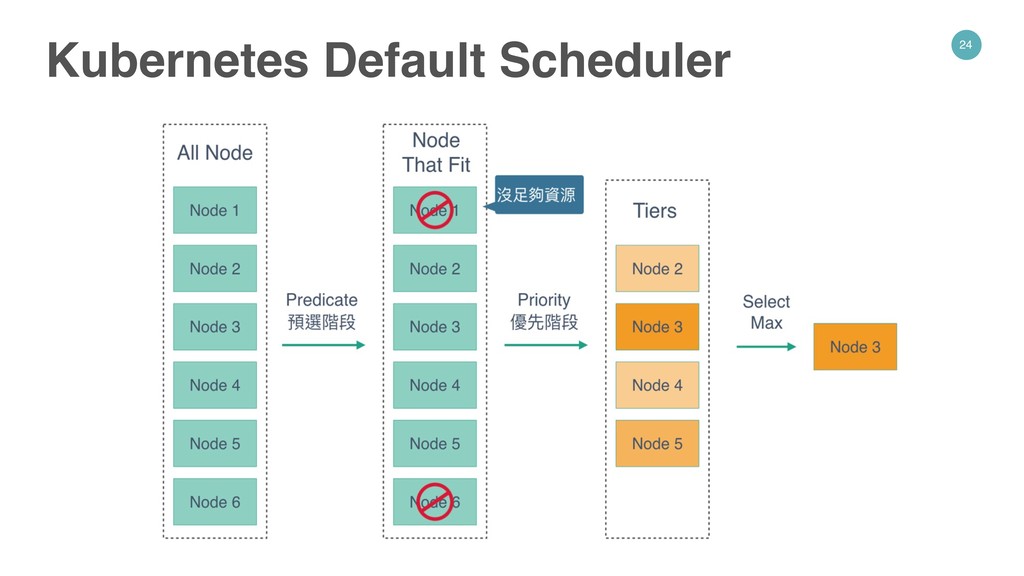
  13. 25 • 分散式 DL 訓練作業過程,具有很強的任務依賴性 • 預設 k8s 排程處於 Pod

    Level,並且它傾向於在所有節點上均勻分佈 Pod資源 • 經由網路路跨多節點更更新數據,可能會妨礙分散式訓練的性能, 且並不提供任何 資源分配優化或⼯工作⽣生命週期管理理能⼒力力 Default Scheduler 對於分散式 DL 瓶頸
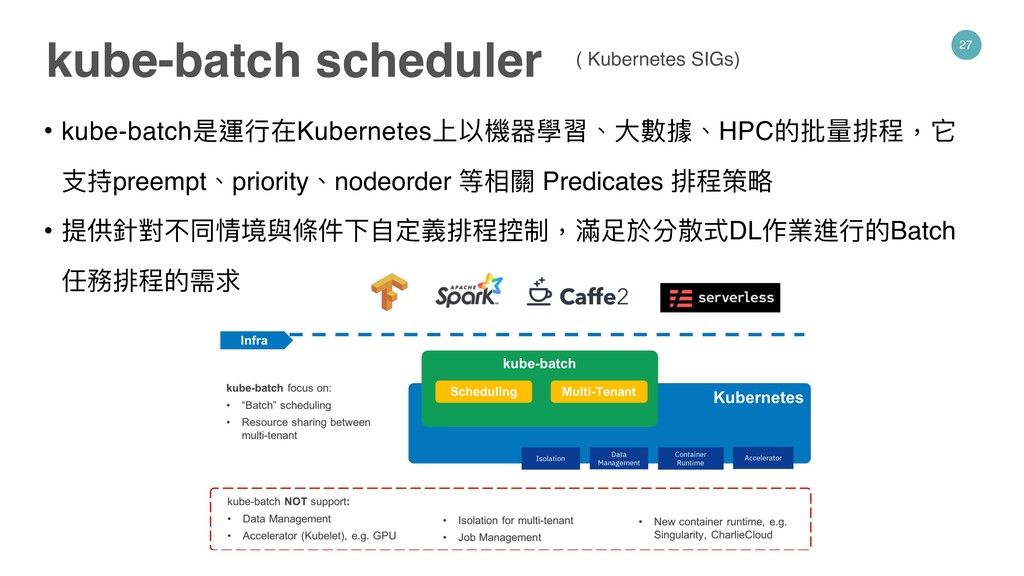
  14. Cache Backfill Reclaim Preempt Allocate Actions Kube-batch Plugins drf gang

    predict priority nodeorder proportion Session jobOrderFnc queueOrderFuns Open/Close Session … Jobs Nodes
 Queues Register Allocate Snapshot Bind/Evict Bind/Evict Watch: Pod, Node, Queue, Pod Group 28 kube-batch Architecture Pic: Kube-batch 在vivo AI 計算平台的應⽤用 API Server Github: Backfill and Starvation Prevention 實現排程機制 (mechanism) 實現排程策略略 (policy)
  15. 29 Queue 隊列列機制,同個隊列列的任務會依次運⾏行行 不同隊列列直接可以設置優先級,優先級 ⾼高的隊列列中的任務會優先得到調度 Gang scheduling 依據總作業資源,同時能運⾏行行所有 「All 任務(Task)」實現所有任務群組

    Action & Plugin kube-batch 增強配置排程需求 actions: "reclaim, allocate, backfill, preempt" tiers: - plugins: - name: priority - name: gang - name: conformance - plugins: - name: drf - name: predicates arguments: predicate.MemoryPressureEnable: true predicate.DiskPressureEnable: true predicate.PIDPressureEnable: true - name: proportion - name: nodeorder @Jack Lin - How to schedule a job with gang-scheduling
  16. 30 • 分散式訓練作業透過⾃自定義作業描述⽂文件(Job Description YAML File) 來來規範 • 在 YAML

    中描述 分散式訓練作業,包含任務數量量、參參數配置資源限制(例例如: GPU執⾏行行數量量) 分散式DL作業運⾏行行系統流程
  17. 31 apiVersion: "kubeflow.org/v1beta1" kind: "TFJob" metadata: name: "gang-scheduling" namespace: "kubeflow"

    spec: tfReplicaSpecs: Worker: replicas: 1 template: metadata: annotations: scheduling.k8s.io/group-name: "gang-scheduling" spec: schedulerName: kube-batch nodeSelector: node: "p100" containers: - args: - python - tf_cnn_benchmarks.py - --batch_size=32 - --model=inception3 - --variable_update=parameter_server - --flush_stdout=true - --num_gpus=1 - --local_parameter_device=cpu - --device=gpu - --data_format=NHWC - name: tensorflow image: yylin1/tf-benchmarks-gpu:latest resources: limits: nvidia.com/gpu: 2 workingDir: /opt/tf-benchmarks/scripts/tf_cnn_benchmarks restartPolicy: Never PS: replicas: 1 template: metadata: annotations: scheduling.k8s.io/group-name: "gang-scheduling" spec: schedulerName: kube-batch nodeSelector: node: “p100" containers: - args: - python - tf_cnn_benchmarks.py - --batch_size=32 - --model=inception3 - --variable_update=parameter_server - --flush_stdout=true - --num_gpus=1 - --local_parameter_device=cpu - --device=gpu - --data_format=NHWC - name: tensorflow image: yylin1/tf-benchmarks-cpu:latest resources: limits: cpu: 1 workingDir: /opt/tf-benchmarks/scripts/tf_cnn_benchmarks restartPolicy: Never • Gang Scheduler • Tack placement • Job Proirity
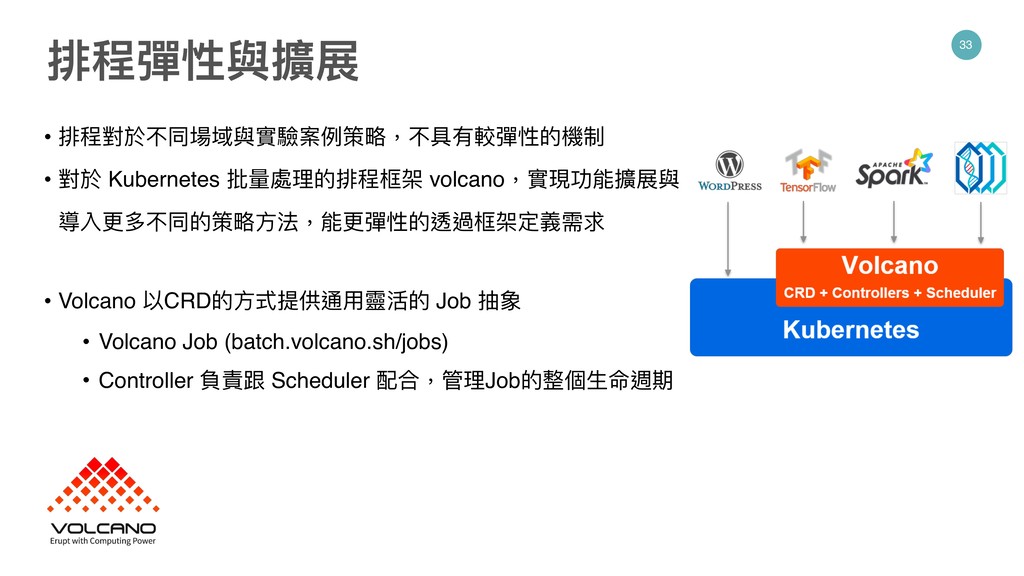
  18. • 排程對於不同場域與實驗案例例策略略,不具有較彈性的機制 • 對於 Kubernetes 批量量處理理的排程框架 volcano,實現功能擴展與 導入更更多不同的策略略⽅方法,能更更彈性的透過框架定義需求 • Volcano

    以CRD的⽅方式提供通⽤用靈活的 Job 抽象 • Volcano Job (batch.volcano.sh/jobs) • Controller 負責跟 Scheduler 配合,管理理Job的整個⽣生命週期 33 排程彈性與擴展

More Decks by Frank Lin

Other Decks in Technology