Dickten (@pe_d) • CEO of a development company (DCS) • Lot's of development for market research – Marcus Ross (@zahlenhelfer) • Trainer + consultant for database systems / BI Who are we?
of structured informaXon, e.g. – Web server log files – Flight data – Purchase data • Most of the Xme: simply structured • But: insane amount of records ("big")
than a single system can efficiently store / process • "efficiently" (Xme) depends on the use case (e.g. real Xme analysis for fraud detecXon) • "efficiently" (cost): Database system for Petabytes of data could get extremely expensive
50 years to 21 days => store data redundantly (e.g. in 3 different places) • Splihng a computaXon to 1,000 computaXons can be difficult • Only works if every machine only needs a small subset of the data ("data locality") to do its job. MTBF (mean Xme between failure) = average life Xme, e.g. 500K hours for a hard disk
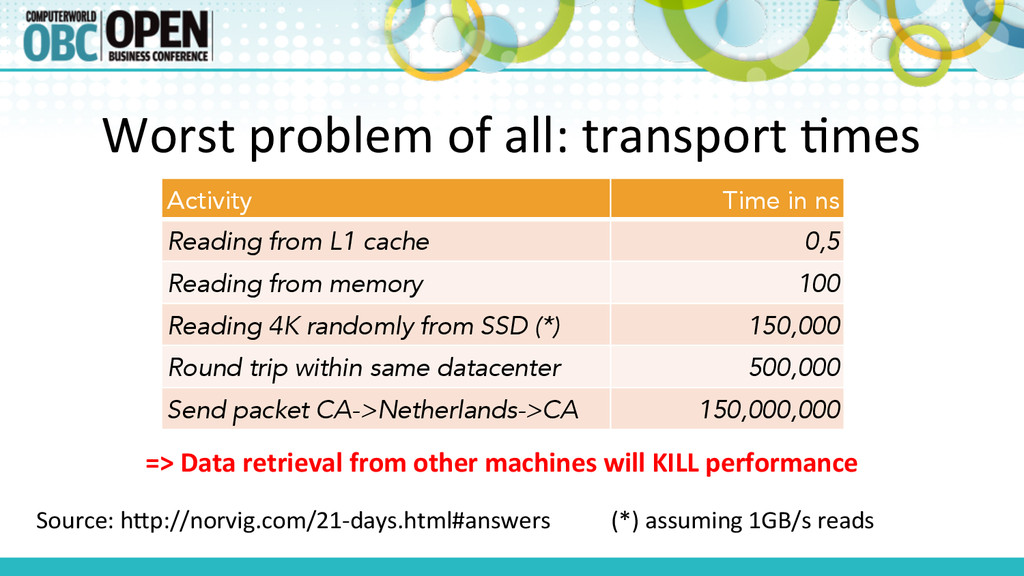
ns Reading from L1 cache 0,5 Reading from memory 100 Reading 4K randomly from SSD (*) 150,000 Round trip within same datacenter 500,000 Send packet CA->Netherlands->CA 150,000,000 Source: hjp://norvig.com/21-‐days.html#answers (*) assuming 1GB/s reads => Data retrieval from other machines will KILL performance
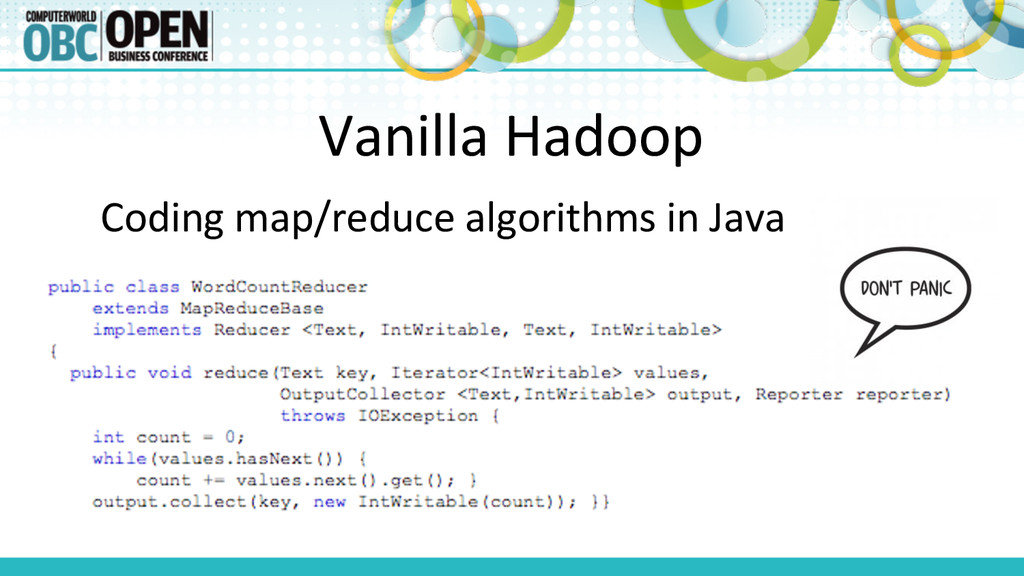
data mulXple Xmes (HDFS) and keep track of failing machines • Hadoop will split up work to many machines (map/reduce) • Hadoop delegates work to machines which already have the data needed for the job
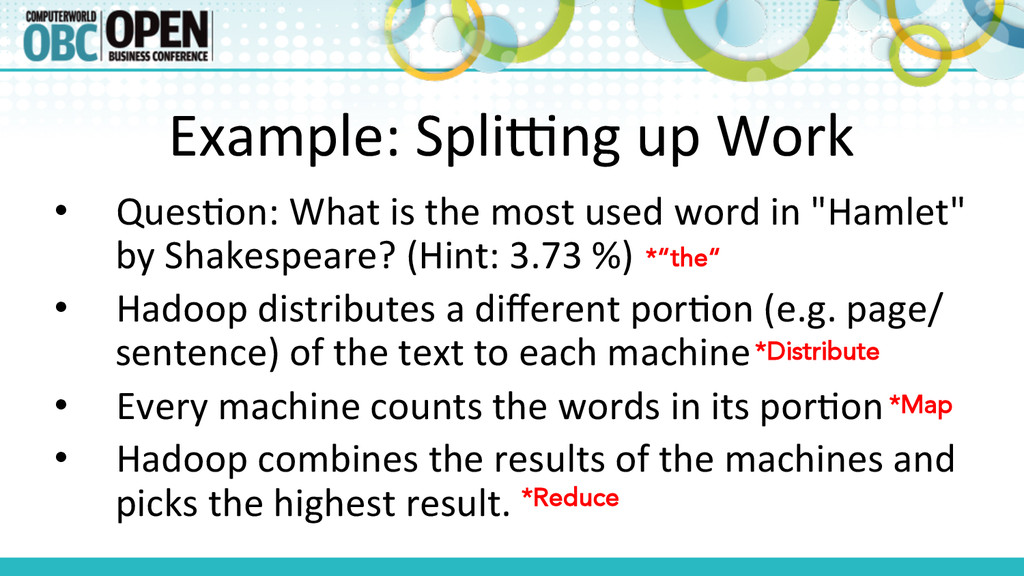
most used word in "Hamlet" by Shakespeare? (Hint: 3.73 %) • Hadoop distributes a different porXon (e.g. page/ sentence) of the text to each machine • Every machine counts the words in its porXon • Hadoop combines the results of the machines and picks the highest result. *Map *Reduce *Distribute *“the“
Yahoo, now Apache project • "Pig LaXn" language is translated to map/reduce • Basic idea: "data flow" – the data is transformed step-‐by-‐ step using built-‐in/self-‐wrijen steps (e.g. filter, group-‐by, join, foreach...). The output of each step can be used as input for the next step (using variables) • Similar to interacXve shells/read–eval–print loop tools
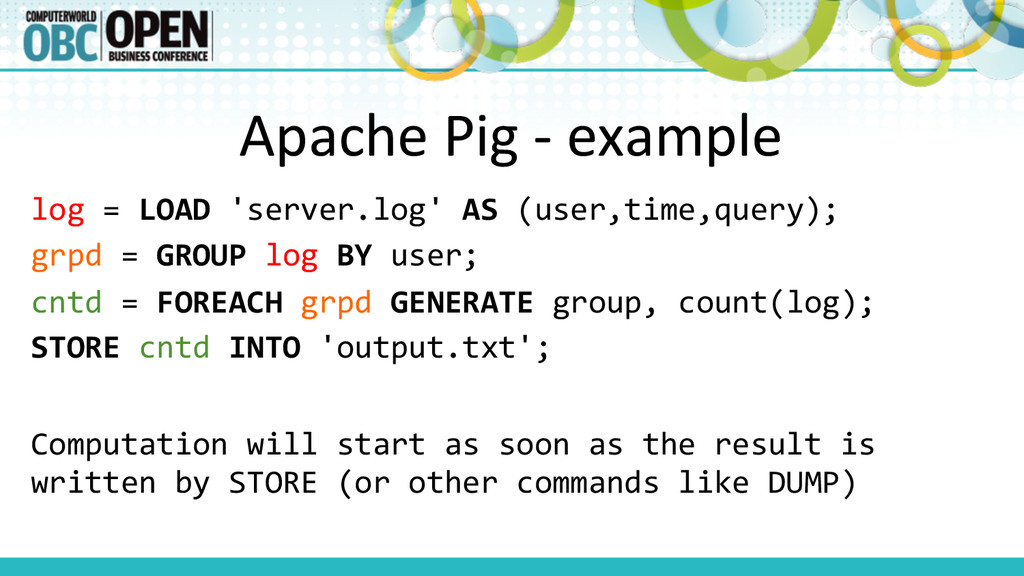
(user,time,query); grpd = GROUP log BY user; cntd = FOREACH grpd GENERATE group, count(log); STORE cntd INTO 'output.txt'; Computation will start as soon as the result is written by STORE (or other commands like DUMP)
now Apache. An SQL-‐like query language (HiveQL) for Hadoop. Can be extended with map/reduce code wrijen in Java Similar to SQL (but not intended for ad-‐hoc queries)
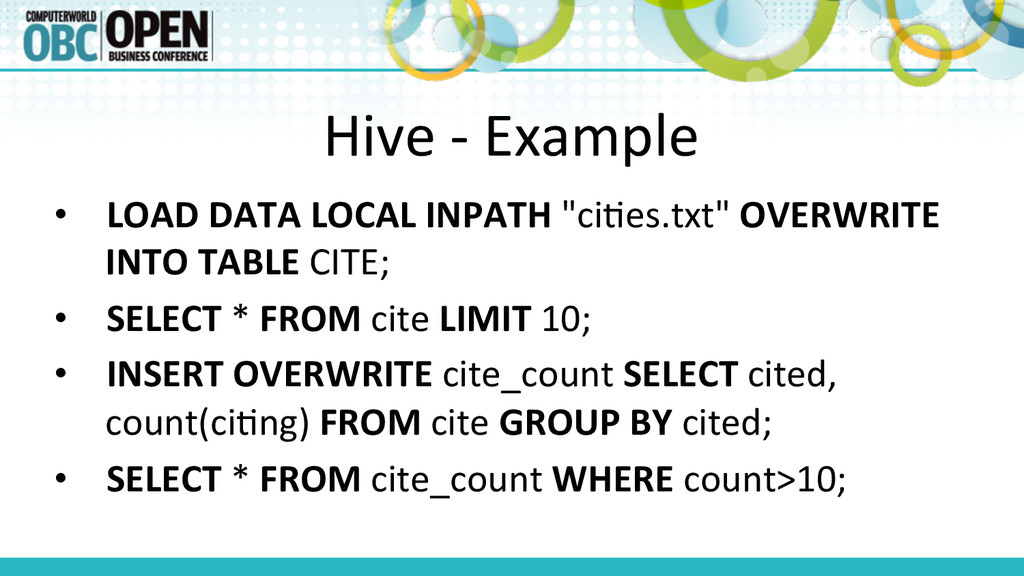
OVERWRITE INTO TABLE CITE; • SELECT * FROM cite LIMIT 10; • INSERT OVERWRITE cite_count SELECT cited, count(ciXng) FROM cite GROUP BY cited; • SELECT * FROM cite_count WHERE count>10;
• CollaboraXve filtering (recommendaXon) • Clustering (grouping of enXXes based on similar characterisXcs) • ClassificaXon (clustering in pre-‐ exisXng groups) (mostly) based on Hadoop. Apache Mahout hjps://twijer.com/JulianHi/status/457668218753392642/photo/1
available service for efficiently collecXng, aggregaXng, and moving large amounts of log data. (some kind of ETL) • It uses three parts: – Agent (receive data from an applicaXon/log) – Processor (intermediate processing) – Collector (write data to permanent storage) • Use it to have a framework for import instead of develop an importer for each source
– ConfiguraXon service – SynchronizaXon service – Naming registry for large distributed systems • Its architecture supports high-‐availability through redundant services • ZooKeeper is used by companies like Rackspace, Yahoo! and eBay
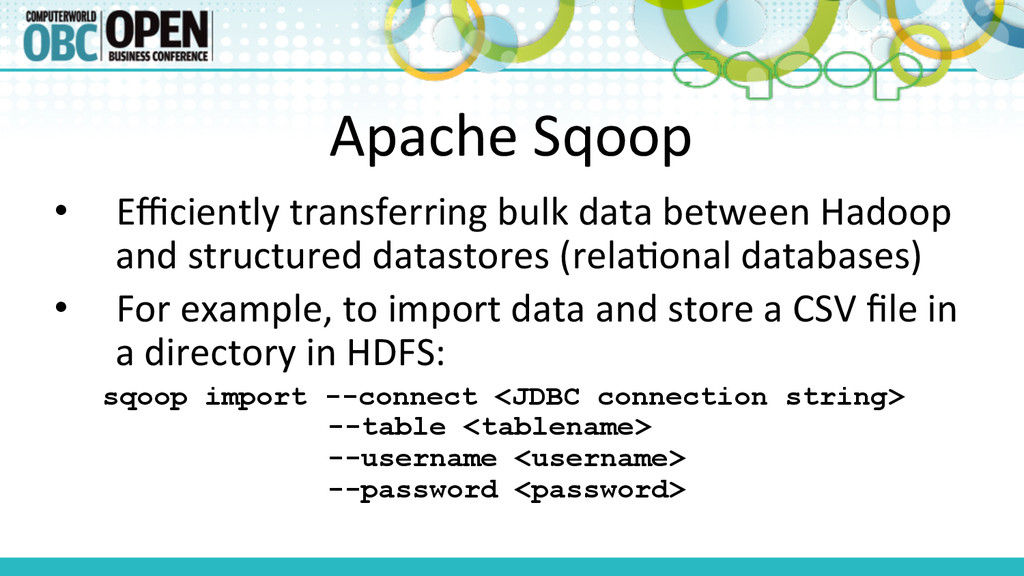
Hadoop and structured datastores (relaXonal databases) • For example, to import data and store a CSV file in a directory in HDFS: sqoop import --connect <JDBC connection string> --table <tablename> --username <username> --password <password>
access for Big Data • This project's goal is to host very large tables • Use it for Billions of rows X millions of columns • Hosted on clusters of commodity hardware • It´s a distributed, versioned, non-‐relaXonal database modeled a~er Google's Bigtable • It provides Bigtable-‐like capabiliXes on top of Hadoop/HDFS.
manage Apache Hadoop jobs. • Oozie Workflow jobs are Directed Acyclical Graphs (DAGs) of acXons. • Oozie Coordinator jobs are recurrent Oozie Workflow jobs triggered by Xme (frequency) and data availabilty.
data! • Hadoop and RDBMS will coexist • Ecosystem reduces development costs/Xme • MulXple flavors of Hadoop: – Cloud / Hosted / On Premise – Ready to use-‐DistribuXons


 zahlenhelfer
 csswizardry
 knwoop
 junya_okura
 tkito
 ren8k
 manabuseki
 rfdnxbro
 maguroalternative
 kazatohiei
 minorun365
 yuutosi
 asonas
 cromwellryan
 kimpetersen
 maltzj
 greggifford
 mfonobong
 sergeychernyshev
 bkeepers
 nmsamuel
 skipperchong
 varn
 tammyeverts